Search Results: "cts"

26 April 2022

Tim Retout: Exploring StackRox

At the end of March, the source code to StackRox was released, following the 2021 acquisition by Red Hat. StackRox is a Kubernetes security tool which is now badged as Red Hat Advanced Cluster Security (RHACS), offering features such as vulnerability management, validating cluster configurations against CIS benchmarks, and some runtime behaviour analysis. In fact, it s such a diverse range of features that I have trouble getting my head round it from the product page or even the documentation. Source code is available via the StackRox organisation on GitHub, and the most obviously interesting repositories seem to be: My initial curiosity has been around the collector , to better understand what runtime behaviour the tool can actually pick up. I was intrigued to find that the actual kernel component is a patched version of Falco s kernel module/eBPF probes; a few features are disabled compared to Falco, e.g. page faults and signal events. There s a list of supported syscalls in driver/syscall_table.c, which seems to have drifted slightly or be slightly behind the upstream Falco version? In particular I note the absence of io_uring, but given RHACS is mainly deployed on Linux 4.18 at the moment (RHEL 8) this is probably a non-issue. (But relevant if anyone were to run it on newer kernels.) That s as far as I ve got for now. Red Hat are making great efforts to reach out to the community; there s a Slack channel, and office hours recordings, and a community hub to explore further. It s great to see new free software projects created through acquisition in this way - I m not sure I remember seeing a comparable example.

Steve Kemp: Porting a game from CP/M to the ZX Spectrum 48k

Back in April 2021 I introduced a simple text-based adventure game, The Lighthouse of Doom, which I'd written in Z80 assembly language for CP/M systems. As it was recently the 40th Anniversary of the ZX Spectrum 48k, the first computer I had, and the reason I got into programming in the first place, it crossed my mind that it might be possible to port my game from CP/M to the ZX Spectrum. To recap my game is a simple text-based adventure game, which you can complete in fifteen minutes, or less, with a bunch of Paw Patrol easter-eggs. My code is largely table-based, having structures that cover objects, locations, and similar state-things. Most of the code involves working with those objects, with only a few small platform-specific routines being necessary: My feeling was that I could replace the use of those CP/M functions with something custom, and I'd have done the 99% of the work. Of course the devil is always in the details. Let's start. To begin with I'm lucky in that I'm using the pasmo assembler which is capable of outputting .TAP files, which can be loaded into ZX Spectrum emulators. I'm not going to walk through all the code here, because that is available within the project repository, but here's a very brief getting-started guide which demonstrates writing some code on a Linux host, and generating a TAP file which can be loaded into your favourite emulator. As I needed similar routines I started working out how to read keyboard input, clear the screen, and output messages which is what the following sample will demonstrate.. First of all you'll need to install the dependencies, specifically the assembler and an emulator to run the thing:
# apt install pasmo spectemu-x11
Now we'll create a simple assembly-language file, to test things out - save the following as hello.z80:
    ; Code starts here
    org 32768
    ; clear the screen
    call cls
    ; output some text
    ld   de, instructions                  ; DE points to the text string
    ld   bc, instructions_end-instructions ; BC contains the length
    call 8252
    ; wait for a key
    ld hl,0x5c08        ; LASTK
    ld a,255
    ld (hl),a
wkey:
    cp (hl)             ; wait for the value to change
    jr z, wkey
    ; get the key and save it
    ld a,(HL)
    push af
    ; clear the screen
    call cls
    ; show a second message
    ld de, you_pressed
    ld bc, you_pressed_end-you_pressed
    call 8252
    ;; Output the ASCII character in A
    ld a,2
    call 0x1601
    pop af
    call 0x0010
    ; loop forever.  simple demo is simple
endless:
    jr endless
cls:
    ld a,2
    call 0x1601  ; ROM_OPEN_CHANNEL
    call 0x0DAF  ; ROM_CLS
    ret
instructions:
    defb 'Please press a key to continue!'
instructions_end:
you_pressed:
    defb 'You pressed:'
you_pressed_end:
end 32768
Now you can assemble that into a TAP file like so:
$ pasmo --tapbas hello.z80 hello.tap
The final step is to load it in the emulator:
$ xspect -quick-load -load-immed -tap hello.tap
The reason I specifically chose that emulator was because it allows easily loading of a TAP file, without waiting for the tape to play, and without the use of any menus. (If you can tell me how to make FUSE auto-start like that, I'd love to hear!) I wrote a small number of "CP/M emulation functions" allowing me to clear the screen, pause, prompt for input, and output text, which will work via the primitives available within the standard ZX Spectrum ROM. Then I reworked the game a little to cope with the different screen resolution (though only minimally, some of the text still breaks lines in unfortunate spots): The end result is reasonably playable, even if it isn't quite as nice as the CP/M version (largely because of the unfortunate word-wrapping, and smaller console-area). So now my repository contains a .TAP file which can be loaded into your emulator of choice, available from the releases list. Here's a brief teaser of what you can expect:
Outstanding bugs? Well the line-input is a bit horrid, and unfortunately this was written for CP/M accessed over a terminal - so I'd assumed a "standard" 80x25 resolution, which means that line/word-wrapping is broken in places. That said it didn't take me too long to make the port, and it was kinda fun.

Reproducible Builds: Supporter spotlight: Google Open Source Security Team (GOSST)

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fourth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. If you are a supporter of the Reproducible Builds project (of whatever size) and would like to be featured here, please let get in touch with us at contact@reproducible-builds.org. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent one about ARDC. However, today, we ll be talking with Meder Kydyraliev of the Google Open Source Security Team (GOSST).
Chris Lamb: Hi Meder, thanks for taking the time to talk to us today. So, for someone who has not heard of the Google Open Source Security Team (GOSST) before, could you tell us what your team is about? Meder: Of course. The Google Open Source Security Team (or GOSST ) was created in 2020 to work with the open source community at large, with the goal of making the open source software that everyone relies on more secure.
Chris: What kinds of activities is the GOSST involved in? Meder: The range of initiatives that the team is involved in recognizes the diversity of the ecosystem and unique challenges that projects face on their security journey. For example, our sponsorship of sos.dev ensures that developers are rewarded for security improvements to open source projects, whilst the long term work on improving Linux kernel security tackles specific kernel-related vulnerability classes. Many of the projects GOSST is involved with aim to make it easier for developers to improve security through automated assessment (Scorecards and Allstar) and vulnerability discovery tools (OSS-Fuzz, ClusterFuzzLite, FuzzIntrospector), in addition to contributing to infrastructure to make adopting certain best practices easier. Two great examples of best practice efforts are Sigstore for artifact signing and OSV for automated vulnerability management.
Chris: The usage of open source software has exploded in the last decade, but supply-chain hygiene and best practices has seemingly not kept up. How does GOSST see this issue and what approaches is it taking to ensure that past and future systems are resilient? Meder: Every open source ecosystem is a complex environment and that awareness informs our approaches in this space. There are, of course, no silver bullets , and long-lasting and material supply-chain improvements requires infrastructure and tools that will make lives of open source developers easier, all whilst improving the state of the wider software supply chain. As part of a broader effort, we created the Supply-chain Levels for Software Artifacts framework that has been used internally at Google to protect production workloads. This framework describes the best practices for source code and binary artifact integrity, and we are engaging with the community on its refinement and adoption. Here, package managers (such as PyPI, Maven Central, Debian, etc.) are an essential link in the software supply chain due to their near-universal adoption; users do not download and compile their own software anymore. GOSST is starting to work with package managers to explore ways to collaborate together on improving the state of the supply chain and helping package maintainers and application developers do better all with the understanding that many open source projects are developed in spare time as a hobby! Solutions like this, which are the result of collaboration between GOSST and GitHub, are very encouraging as they demonstrate a way to materially strengthen software supply chain security with readily available tools, while also improving development workflows. For GOSST, the problem of supply chain security also covers vulnerability management and solutions to make it easier for everyone to discover known vulnerabilities in open source packages in a scalable and automated way. This has been difficult in the past due to lack of consistently high-quality data in an easily-consumable format. To address this, we re working on infrastructure (OSV.dev) to make vulnerability data more easily accessible as well as a widely adopted and automation friendly data format.
Chris: How does the Reproducible Builds effort help GOSST achieve its goals? Meder: Build reproducibility has a lot of attributes that are attractive as part of generally good build hygiene . As an example, hermeticity, one of requirements to meet SLSA level 4, makes it much easier to reason about the dependencies of a piece of software. This is an enormous benefit during vulnerability or supply chain incident response. On a higher level, however, we always think about reproducibility from the viewpoint of a user and the threats that reproducibility protects them from. Here, a lot of progress has been made, of course, but a lot of work remains to make reproducibility part of everyone s software consumption practices.
Chris: So if someone wanted to know more about GOSST or follow the team s work, where might they go to look? Meder: We post regular updates on Google s Security Blog and on the Linux hardening mailing list. We also welcome community participation in the projects we work on! See any of the projects linked above or OpenSSF s GitHub projects page for a list of efforts you can contribute to directly if you want to get involved in strengthening the open source ecosystem.
Chris: Thanks for taking the time to talk to us today. Meder: No problem. :)


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

20 April 2022

Russell Coker: Android Without Play

A while ago I was given a few reasonably high-end Android phones to give away. I gave two very nice phones to someone who looks after refugees so a couple of refugee families could make video calls to relatives. The third phone is a Huawei Nova 7i [1] which doesn t have the Google Play Store. The Nova 7i is a ridiculously powerful computer (8G of RAM in a phone!!!) but without the Google Play Store it s not much use to the average phone user. It has the HuaWei App Gallery which isn t as bad as most of the proprietary app stores of small players in the Android world, it has SnapChat, TikTok, Telegram, Alibaba, WeChat, and Grays auction (an app I didn t even know existed) along with many others. It also links to ApkPure (apparently a 3rd party app installer that obtains APK files for major commercial apps) for Facebook among others. The ApkPure thing might be Huawei outsourcing the violation of Facebook terms of service. For the moment I ve decided to only use free software on this phone and use my old phone for non-free stuff (Facebook, LinkedIn, etc). The eventual aim is that I can only carry a phone with free software for normal use and carry a second phone if I m active on LinkedIn or something. My recollection is that when I first got the phone (almost 2 years ago) it didn t have such a range of apps. The first thing to install was f-droid [2] as the app repository. F-droid has a repository of thousands of free software Android apps as well as some apps that are slightly less free which are tagged appropriately. You can install the F-Droid app from the web site. As an aside I had to go to settings and enable force old index format to get the list of packages, I don t know why as other phones had worked without it. Here are the F-Droid apps I installed: Future Plans The current main things I m missing are a calendar, a contact list, and a shared note taking system (like Google Keep). For calendaring and a contact list the CalDAV and CardDAV protocols seem best. The most common implementation on the server side appears to be DAViCal [5]. The Nextcloud system supports CalDAV, CardDAV, web editing of notes and documents (including LibreOffice if you install that plugin) [6]. But it is huge and demands write access to all it s own code (bad for security), and it s not packaged for Debian. Also in my tests it gave me an error 401 when I tried to authenticate to it from the Android Nextcloud client. I ve seen a positive review about Radicale, a simple CalDAV and CardDAV server that doesn t need a database [7]. I prefer the Unix philosophy of keeping things simple with file storage unless there s a real need for anything else. I don t think that anything I ever do with calendaring will require the PostgreSQL database that DAViCal uses. I ll give Radicale a go for CalDAV and CardDAV, but I still need something for shared notes (shopping lists etc). Suggestions welcome. Current Status Lack of a contacts list is a major loss of functionality in a phone. I could store contacts in the phone memory or on the SIM, but I would still have to get all my old contacts in there and also getting something half working reduces motivation for getting it working properly. Lack of a calendar is also a problem, again I could work around that by exporting all my Google calendars as iCal URLs but I d rather get it working correctly. The lack of shared notes may be a harder problem to solve given the failure of Nextcloud. For that I would consider just having the keep.google.com web site always open in Mozilla at least in the short term. At the moment I require two phones, my new Android phone without Google and the old one for my contacts list etc. Hopefully in a week or so I ll have my new phone doing contacts, calendaring, and notes. Then my old phone will just be for proprietary apps which I don t need most of the time and I can leave it at home when I don t need that sort of thing.

19 April 2022

Bits from Debian: ITP Prizren Platinum Sponsor of DebConf22

itplogo We are very pleased to announce that ITP - Innovation and Training Park Prizren has committed to supporting DebConf22 as a Platinum sponsor. Also, ITP Prizren will host the Conference for all 15 days! The ITP Prizren intends to be a changing and boosting element in the area of ICT, agro-food and creatives industries, through the creation and management of a favourable environment and efficient services for SMEs, exploiting different kinds of innovations that can contribute to Kosovo to improve its level of development in industry and research, bringing benefits to the economy and society of the country as a whole. ITP Prizren is a focal point in the Balkan region for innovation, business and skills development, and a source of innovative and successful ideas. With this commitment as Platinum Sponsor, ITP Prizren is contributing to make possible our annual conference, and directly supporting the progress of Debian and Free Software, helping to strengthen the community that continues to collaborate on Debian projects throughout the rest of the year. Thank you very much ITP Prizren, for your support of DebConf22! Become a sponsor too! DebConf22 will take place from July 17th to 24th, 2022 at the Innovation and Training Park (ITP) in Prizren, Kosovo, and will be preceded by DebCamp, from July 10th to 16th. And DebConf22 is still accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf22 website at https://debconf22.debconf.org/sponsors/become-a-sponsor. DebConf22 banner open registration

Steve McIntyre: Firmware - what are we going to do about it?

TL;DR: firmware support in Debian sucks, and we need to change this. See the "My preference, and rationale" Section below. In my opinion, the way we deal with (non-free) firmware in Debian is a mess, and this is hurting many of our users daily. For a long time we've been pretending that supporting and including (non-free) firmware on Debian systems is not necessary. We don't want to have to provide (non-free) firmware to our users, and in an ideal world we wouldn't need to. However, it's very clearly no longer a sensible path when trying to support lots of common current hardware. Background - why has (non-free) firmware become an issue? Firmware is the low-level software that's designed to make hardware devices work. Firmware is tightly coupled to the hardware, exposing its features, providing higher-level functionality and interfaces for other software to use. For a variety of reasons, it's typically not Free Software. For Debian's purposes, we typically separate firmware from software by considering where the code executes (does it run on a separate processor? Is it visible to the host OS?) but it can be difficult to define a single reliable dividing line here. Consider the Intel/AMD CPU microcode packages, or the U-Boot firmware packages as examples. In times past, all necessary firmware would normally be included directly in devices / expansion cards by their vendors. Over time, however, it has become more and more attractive (and therefore more common) for device manufacturers to not include complete firmware on all devices. Instead, some devices just embed a very simple set of firmware that allows for upload of a more complete firmware "blob" into memory. Device drivers are then expected to provide that blob during device initialisation. There are a couple of key drivers for this change: Due to these reasons, more and more devices in a typical computer now need firmware to be uploaded at runtime for them to function correctly. This has grown: At the beginning of this timeline, a typical Debian user would be able to use almost all of their computer's hardware without needing any firmware blobs. It might have been inconvenient to not be able to use the WiFi, but most laptops had wired ethernet anyway. The WiFi could always be enabled and configured after installation. Today, a user with a new laptop from most vendors will struggle to use it at all with our firmware-free Debian installation media. Modern laptops normally don't come with wired ethernet now. There won't be any usable graphics on the laptop's screen. A visually-impaired user won't get any audio prompts. These experiences are not acceptable, by any measure. There are new computers still available for purchase today which don't need firmware to be uploaded, but they are growing less and less common. Current state of firmware in Debian For clarity: obviously not all devices need extra firmware uploading like this. There are many devices that depend on firmware for operation, but we never have to think about them in normal circumstances. The code is not likely to be Free Software, but it's not something that we in Debian must spend our time on as we're not distributing that code ourselves. Our problems come when our user needs extra firmware to make their computer work, and they need/expect us to provide it. We have a small set of Free firmware binaries included in Debian main, and these are included on our installation and live media. This is great - we all love Free Software and this works. However, there are many more firmware binaries that are not Free. If we are legally able to redistribute those binaries, we package them up and include them in the non-free section of the archive. As Free Software developers, we don't like providing or supporting non-free software for our users, but we acknowledge that it's sometimes a necessary thing for them. This tension is acknowledged in the Debian Free Software Guidelines. This tension extends to our installation and live media. As non-free is officially not considered part of Debian, our official media cannot include anything from non-free. This has been a deliberate policy for many years. Instead, we have for some time been building a limited parallel set of "unofficial non-free" images which include non-free firmware. These non-free images are produced by the same software that we use for the official images, and by the same team. There are a number of issues here that make developers and users unhappy:
  1. Building, testing and publishing two sets of images takes more effort.
  2. We don't really want to be providing non-free images at all, from a philosophy point of view. So we mainly promote and advertise the preferred official free images. That can be a cause of confusion for users. We do link to the non-free images in various places, but they're not so easy to find.
  3. Using non-free installation media will cause more installations to use non-free software by default. That's not a great story for us, and we may end up with more of our users using non-free software and believing that it's all part of Debian.
  4. A number of users and developers complain that we're wasting their time by publishing official images that are just not useful for a lot (a majority?) of users.
We should do better than this. Options The status quo is a mess, and I believe we can and should do things differently. I see several possible options that the images team can choose from here. However, several of these options could undermine the principles of Debian. We don't want to make fundamental changes like that without the clear backing of the wider project. That's why I'm writing this...
  1. Keep the existing setup. It's horrible, but maybe it's the best we can do? (I hope not!)
  2. We could just stop providing the non-free unofficial images altogether. That's not really a promising route to follow - we'd be making it even harder for users to install our software. While ideologically pure, it's not going to advance the cause of Free Software.
  3. We could stop pretending that the non-free images are unofficial, and maybe move them alongside the normal free images so they're published together. This would make them easier to find for people that need them, but is likely to cause users to question why we still make any images without firmware if they're otherwise identical.
  4. The images team technically could simply include non-free into the official images, and add firmware packages to the input lists for those images. However, that would still leave us with problem 3 from above (non-free generally enabled on most installations).
  5. We could split out the non-free firmware packages into a new non-free-firmware component in the archive, and allow a specific exception only to allow inclusion of those packages on our official media. We would then generate only one set of official media, including those non-free firmware packages. (We've already seen various suggestions in recent years to split up the non-free component of the archive like this, for example into non-free-firmware, non-free-doc, non-free-drivers, etc. Disagreement (bike-shedding?) about the split caused us to not make any progress on this. I believe this project should be picked up and completed. We don't have to make a perfect solution here immediately, just something that works well enough for our needs today. We can always tweak and improve the setup incrementally if that's needed.)
These are the most likely possible options, in my opinion. If you have a better suggestion, please let us know! I'd like to take this set of options to a GR, and do it soon. I want to get a clear decision from the wider Debian project as to how to organise firmware and installation images. If we do end up changing how we do things, I want a clear mandate from the project to do that. My preference, and rationale Mainly, I want to see how the project as a whole feels here - this is a big issue that we're overdue solving. What would I choose to do? My personal preference would be to go with option 5: split the non-free firmware into a special new component and include that on official media. Does that make me a sellout? I don't think so. I've been passionately supporting and developing Free Software for more than half my life. My philosophy here has not changed. However, this is a complex and nuanced situation. I firmly believe that sharing software freedom with our users comes with a responsibility to also make our software useful. If users can't easily install and use Debian, that helps nobody. By splitting things out here, we would enable users to install and use Debian on their hardware, without promoting/pushing higher-level non-free software in general. I think that's a reasonable compromise. This is simply a change to recognise that hardware requirements have moved on over the years. Further work If we do go with the changes in option 5, there are other things we could do here for better control of and information about non-free firmware:
  1. Along with adding non-free firmware onto media, when the installer (or live image) runs, we should make it clear exactly which firmware packages have been used/installed to support detected hardware. We could link to docs about each, and maybe also to projects working on Free re-implementations.
  2. Add an option at boot to explicitly disable the use of the non-free firmware packages, so that users can choose to avoid them.
Acknowledgements Thanks to people who reviewed earlier versions of this document and/or made suggestions for improvement, in particular:

17 April 2022

Matthew Garrett: The Freedom Phone is not great at privacy

The Freedom Phone advertises itself as a "Free speech and privacy first focused phone". As documented on the features page, it runs ClearOS, an Android-based OS produced by Clear United (or maybe one of the bewildering array of associated companies, we'll come back to that later). It's advertised as including Signal, but what's shipped is not the version available from the Signal website or any official app store - instead it's this fork called "ClearSignal".

The first thing to note about ClearSignal is that the privacy policy link from that page 404s, which is not a great start. The second thing is that it has a version number of 5.8.14, which is strange because upstream went from 5.8.10 to 5.9.0. The third is that, despite Signal being GPL 3, there's no source code available. So, I grabbed jadx and started looking for differences between ClearSignal and the upstream 5.8.10 release. The results were, uh, surprising.

First up is that they seem to have integrated ACRA, a crash reporting framework. This feels a little odd - in the absence of a privacy policy, it's unclear what information this gathers or how it'll be stored. Having a piece of privacy software automatically uploading information about what you were doing in the event of a crash with no notification other than a toast that appears saying "Crash Report" feels a little dubious.

Next is that Signal (for fairly obvious reasons) warns you if your version is out of date and eventually refuses to work unless you upgrade. ClearSignal has dealt with this problem by, uh, simply removing that code. The MacOS version of the desktop app they provide for download seems to be derived from a release from last September, which for an Electron-based app feels like a pretty terrible idea. Weirdly, for Windows they link to an official binary release from February 2021, and for Linux they tell you how to use the upstream repo properly. I have no idea what's going on here.

They've also added support for network backups of your Signal data. This involves the backups being pushed to an S3 bucket using credentials that are statically available in the app. It's ok, though, each upload has some sort of nominally unique identifier associated with it, so it's not trivial to just download other people's backups. But, uh, where does this identifier come from? It turns out that Clear Center, another of the Clear family of companies, employs a bunch of people to work on a ClearID[1], some sort of decentralised something or other that seems to be based on KERI. There's an overview slide deck here which didn't really answer any of my questions and as far as I can tell this is entirely lacking any sort of peer review, but hey it's only the one thing that stops anyone on the internet being able to grab your Signal backups so how important can it be.

The final thing, though? They've extended Signal's invitation support to encourage users to get others to sign up for Clear United. There's an exposed API endpoint called "get_user_email_by_mobile_number" which does exactly what you'd expect - if you give it a registered phone number, it gives you back the associated email address. This requires no authentication. But it gets better! The API to generate a referral link to send to others sends the name and phone number of everyone in your phone's contact list. There does not appear to be any indication that this is going to happen.

So, from a privacy perspective, going to go with things being some distance from ideal. But what's going on with all these Clear companies anyway? They all seem to be related to Michael Proper, who founded the Clear Foundation in 2009. They are, perhaps unsurprisingly, heavily invested in blockchain stuff, while Clear United also appears to be some sort of multi-level marketing scheme which has a membership agreement that includes the somewhat astonishing claim that:

Specifically, the initial focus of the Association will provide members with supplements and technologies for:

9a. Frequency Evaluation, Scans, Reports;

9b. Remote Frequency Health Tuning through Quantum Entanglement;

9c. General and Customized Frequency Optimizations;


- there's more discussion of this and other weirdness here. Clear Center, meanwhile, has a Chief Physics Officer? I have a lot of questions.

Anyway. We have a company that seems to be combining blockchain and MLM, has some opinions about Quantum Entanglement, bases the security of its platform on a set of novel cryptographic primitives that seem to have had no external review, has implemented an API that just hands out personal information without any authentication and an app that appears more than happy to upload all your contact details without telling you first, has failed to update this app to keep up with upstream security updates, and is violating the upstream license. If this is their idea of "privacy first", I really hate to think what their code looks like when privacy comes further down the list.

[1] Pointed out to me here

comment count unavailable comments

14 April 2022

Reproducible Builds: Supporter spotlight: Amateur Radio Digital Communications (ARDC)

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about the project and the work that we do. This is the third instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. If you are a supporter of the Reproducible Builds project (of whatever size) and would like to be featured here, please let get in touch with us at contact@reproducible-builds.org. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation. Today, however, we ll be talking with Dan Romanchik, Communications Manager at Amateur Radio Digital Communications (ARDC).
Chris Lamb: Hey Dan, it s nice to meet you! So, for someone who has not heard of Amateur Radio Digital Communications (ARDC) before, could you tell us what your foundation is about? Dan: Sure! ARDC s mission is to support, promote, and enhance experimentation, education, development, open access, and innovation in amateur radio, digital communication, and information and communication science and technology. We fulfill that mission in two ways:
  1. We administer an allocation of IP addresses that we call 44Net. These IP addresses (in the 44.0.0.0/8 IP range) can only be used for amateur radio applications and experimentation.
  2. We make grants to organizations whose work aligns with our mission. This includes amateur radio clubs as well as other amateur radio-related organizations and activities. Additionally, we support scholarship programs for people who either have an amateur radio license or are pursuing careers in technology, STEM education and open-source software development projects that fit our mission, such as Reproducible Builds.
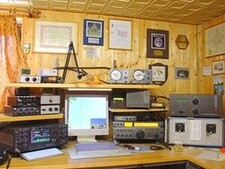
Chris: How might you relate the importance of amateur radio and similar technologies to someone who is non-technical? Dan: Amateur radio is important in a number of ways. First of all, amateur radio is a public service. In fact, the legal name for amateur radio is the Amateur Radio Service, and one of the primary reasons that amateur radio exists is to provide emergency and public service communications. All over the world, amateur radio operators are prepared to step up and provide emergency communications when disaster strikes or to provide communications for events such as marathons or bicycle tours. Second, amateur radio is important because it helps advance the state of the art. By experimenting with different circuits and communications techniques, amateurs have made significant contributions to communications science and technology. Third, amateur radio plays a big part in technical education. It enables students to experiment with wireless technologies and electronics in ways that aren t possible without a license. Amateur radio has historically been a gateway for young people interested in pursuing a career in engineering or science, such as network or electrical engineering. Fourth and this point is a little less obvious than the first three amateur radio is a way to enhance international goodwill and community. Radio knows no boundaries, of course, and amateurs are therefore ambassadors for their country, reaching out to all around the world. Beyond amateur radio, ARDC also supports and promotes research and innovation in the broader field of digital communication and information and communication science and technology. Information and communication technology plays a big part in our lives, be it for business, education, or personal communications. For example, think of the impact that cell phones have had on our culture. The challenge is that much of this work is proprietary and owned by large corporations. By focusing on open source work in this area, we help open the door to innovation outside of the corporate landscape, which is important to overall technological resiliency.
Chris: Could you briefly outline the history of ARDC? Dan: Nearly forty years ago, a group of visionary hams saw the future possibilities of what was to become the internet and requested an address allocation from the Internet Assigned Numbers Authority (IANA). That allocation included more than sixteen million IPv4 addresses, 44.0.0.0 through 44.255.255.255. These addresses have been used exclusively for amateur radio applications and experimentation with digital communications techniques ever since. In 2011, the informal group of hams administering these addresses incorporated as a nonprofit corporation, Amateur Radio Digital Communications (ARDC). ARDC is recognized by IANA, ARIN and the other Internet Registries as the sole owner of these addresses, which are also known as AMPRNet or 44Net. Over the years, ARDC has assigned addresses to thousands of hams on a long-term loan (essentially acting as a zero-cost lease), allowing them to experiment with digital communications technology. Using these IP addresses, hams have carried out some very interesting and worthwhile research projects and developed practical applications, including TCP/IP connectivity via radio links, digital voice, telemetry and repeater linking. Even so, the amateur radio community never used much more than half the available addresses, and today, less than one third of the address space is assigned and in use. This is one of the reasons that ARDC, in 2019, decided to sell one quarter of the address space (or approximately 4 million IP addresses) and establish an endowment with the proceeds. This endowment now funds ARDC s a suite of grants, including scholarships, research projects, and of course amateur radio projects. Initially, ARDC was restricted to awarding grants to organizations in the United States, but is now able to provide funds to organizations around the world.
Chris: How does the Reproducible Builds effort help ARDC achieve its goals? Dan: Our aspirational goals include: We think that the Reproducible Builds efforts in helping to ensure the safety and security of open source software closely align with those goals.
Chris: Are there any specific success stories that ARDC is particularly proud of? Dan: We are really proud of our grant to the Hoopa Valley Tribe in California. With a population of nearly 2,100, their reservation is the largest in California. Like everywhere else, the COVID-19 pandemic hit the reservation hard, and the lack of broadband internet access meant that 130 children on the reservation were unable to attend school remotely. The ARDC grant allowed the tribe to address the immediate broadband needs in the Hoopa Valley, as well as encourage the use of amateur radio and other two-way communications on the reservation. The first nation was able to deploy a network that provides broadband access to approximately 90% of the residents in the valley. And, in addition to bringing remote education to those 130 children, the Hoopa now use the network for remote medical monitoring and consultation, adult education, and other applications. Other successes include our grants to:
Chris: ARDC supports a number of other existing projects and initiatives, not all of them in the open source world. How much do you feel being a part of the broader free culture movement helps you achieve your aims? Dan: In general, we find it challenging that most digital communications technology is proprietary and closed-source. It s part of our mission to fund open source alternatives. Without them, we are solely reliant, as a society, on corporate interests for our digital communication needs. It makes us vulnerable and it puts us at risk of increased surveillance. Thus, ARDC supports open source software wherever possible, and our grantees must make a commitment to share their work under an open source license or otherwise make it as freely available as possible.
Chris: Thanks so much for taking the time to talk to us today. Now, if someone wanted to know more about ARDC or to get involved, where might they go to look? To learn more about ARDC in general, please visit our website at https://www.ampr.org. To learn more about 44Net, go to https://wiki.ampr.org/wiki/Main_Page. And, finally, to learn more about our grants program, go to https://www.ampr.org/apply/
For more about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

13 April 2022

Antoine Beaupr : Tuning my wifi radios

After listening to an episode of the 2.5 admins podcast, I realized there was some sort of low-hanging fruit I could pick to better tune my WiFi at home. You see, I'm kind of a fraud in WiFi: I only started a WiFi mesh in Montreal (now defunct), I don't really know how any of that stuff works. So I was surprised to hear one of the podcast host say "it's all about airtime" and "you want to reduce the power on your access points" (APs). It seemed like sound advice: better bandwidth means less time on air, means less collisions, less latency, and less power also means less collisions. Worth a try, right?

Frequency So the first thing I looked at was WifiAnalyzer to see if I had any optimisation I could do there. Normally, I try to avoid having nearby APs on the same frequency to avoid collisions, but who knows, maybe I had messed that up. And turns out I did! Both APs were on "auto" for 5GHz, which typically means "do nothing or worse". 5GHz is really interesting, because, in theory, there are LOTS of channels to pick from, it goes up to 196!! And both my APs were on 36, what gives? So the first thing I did was to set it to channel 100, as there was that long gap in WifiAnalyzer where no other AP was. But that just broke 5GHz on the AP. The OpenWRT GUI (luci) would just say "wireless not associated" and the ESSID wouldn't show up in a scan anymore. At first, I thought this was a problem with OpenWRT or my hardware, but I could reproduce the problem with both my APs: a TP-Link Archer A7 v5 and a Turris Omnia (see also my review). As it turns out, that's because that range of the WiFi band interferes with trivial things like satellites and radar, which make the actually very useful radar maps look like useless christmas trees. So those channels require DFS to operate. DFS works by first listening on the frequency for a certain amount of time (1-2 minute, but could be as high as 10) to see if there's something else transmitting at all. So typically, that means they just don't operate at all in those bands, especially if you're near any major city which generally means you are near a weather radar that will transmit on that band. In the system logs, if you have such a problem, you might see this:
Apr  9 22:17:39 octavia hostapd: wlan0: DFS-CAC-START freq=5500 chan=100 sec_chan=1, width=0, seg0=102, seg1=0, cac_time=60s
Apr  9 22:17:39 octavia hostapd: DFS start_dfs_cac() failed, -1
... and/or this:
Sat Apr  9 18:05:03 2022 daemon.notice hostapd: Channel 100 (primary) not allowed for AP mode, flags: 0x10095b NO-IR RADAR
Sat Apr  9 18:05:03 2022 daemon.warn hostapd: wlan0: IEEE 802.11 Configured channel (100) not found from the channel list of current mode (2) IEEE 802.11a
Sat Apr  9 18:05:03 2022 daemon.warn hostapd: wlan0: IEEE 802.11 Hardware does not support configured channel
Here, it clearly says RADAR (in all caps too, which means it's really important). NO-IR is also important, I'm not sure what it means but it could be that you're not allowed to transmit in that band because of other local regulations. There might be a way to workaround those by changing the "region" in the Luci GUI, but I didn't mess with that, because I figured that other devices will have that already configured. So using a forbidden channel might make it more difficult for clients to connect (although it's possible this is enforced only on the AP side). In any case, 5GHz is promising, but in reality, you only get from channel 36 (5.170GHz) to 48 (5.250GHz), inclusively. Fast counters will notice that is exactly 80MHz, which means that if an AP is configured for that hungry, all-powerful 80MHz, it will effectively take up all 5GHz channels at once. This, in other words, is as bad as 2.4GHz, where you also have only two 40MHz channels. (Really, what did you expect: this is an unregulated frequency controlled by commercial interests...) So the first thing I did was to switch to 40MHz. This gives me two distinct channels in 5GHz at no noticeable bandwidth cost. (In fact, I couldn't find hard data on what the bandwidth ends up being on those frequencies, but I could still get 400Mbps which is fine for my use case.)

Power The next thing I did was to fiddle with power. By default, both radios were configured to transmit as much power as they needed to reach clients, which means that if a client gets farther away, it would boost its transmit power which, in turns, would mean the client would still connect to instead of failing and properly roaming to the other AP. The higher power also means more interference with neighbors and other APs, although that matters less if they are on different channels. On 5GHz, power was about 20dBm (100 mW) -- and more on the Turris! -- when I first looked, so I tried to lower it drastically to 5dBm (3mW) just for kicks. That didn't work so well, so I bumped it back up to 14 dBm (25 mW) and that seems to work well: clients hit about -80dBm when they get far enough from the AP, which gets close to the noise floor (and where the neighbor APs are), which is exactly what I want. On 2.4GHz, I lowered it down even further, to 10 dBm (10mW) since it's better at going through wells, I figured it would need less power. And anyways, I rather people use the 5GHz APs, so maybe that will act as an encouragement to switch. I was still able to connect correctly to the APs at that power as well.

Other tweaks I disabled the "Allow legacy 802.11b rates" setting in the 5GHz configuration. According to this discussion:
Checking the "Allow b rates" affects what the AP will transmit. In particular it will send most overhead packets including beacons, probe responses, and authentication / authorization as the slow, noisy, 1 Mb DSSS signal. That is bad for you and your neighbors. Do not check that box. The default really should be unchecked.
This, in particular, "will make the AP unusable to distant clients, which again is a good thing for public wifi in general". So I just unchecked that box and I feel happier now. I didn't make tests to see the effect separately however, so this is mostly just a guess.

8 April 2022

Reproducible Builds: Reproducible Builds in March 2022

Welcome to the March 2022 report from the Reproducible Builds project! In our monthly reports we outline the most important things that we have been up to over the past month.
The in-toto project was accepted as an incubating project within the Cloud Native Computing Foundation (CNCF). in-toto is a framework that protects the software supply chain by collecting and verifying relevant data. It does so by enabling libraries to collect information about software supply chain actions and then allowing software users and/or project managers to publish policies about software supply chain practices that can be verified before deploying or installing software. CNCF foundations hosts a number of critical components of the global technology infrastructure under the auspices of the Linux Foundation. (View full announcement.)
Herv Boutemy posted to our mailing list with an announcement that the Java Reproducible Central has hit the milestone of 500 fully reproduced builds of upstream projects . Indeed, at the time of writing, according to the nightly rebuild results, 530 releases were found to be fully reproducible, with 100% reproducible artifacts.
GitBOM is relatively new project to enable build tools trace every source file that is incorporated into build artifacts. As an experiment and/or proof-of-concept, the GitBOM developers are rebuilding Debian to generate side-channel build metadata for versions of Debian that have already been released. This only works because Debian is (partial) reproducible, so one can be sure that that, if the case where build artifacts are identical, any metadata generated during these instrumented builds applies to the binaries that were built and released in the past. More information on their approach is available in README file in the bomsh repository.
Ludovic Courtes has published an academic paper discussing how the performance requirements of high-performance computing are not (as usually assumed) at odds with reproducible builds. The received wisdom is that vendor-specific libraries and platform-specific CPU extensions have resulted in a culture of local recompilation to ensure the best performance, rendering the property of reproducibility unobtainable or even meaningless. In his paper, Ludovic explains how Guix has:
[ ] implemented what we call package multi-versioning for C/C++ software that lacks function multi-versioning and run-time dispatch [ ]. It is another way to ensure that users do not have to trade reproducibility for performance. (full PDF)

Kit Martin posted to the FOSSA blog a post titled The Three Pillars of Reproducible Builds. Inspired by the shock of infiltrated or intentionally broken NPM packages, supply chain attacks, long-unnoticed backdoors , the post goes on to outline the high-level steps that lead to a reproducible build:
It is one thing to talk about reproducible builds and how they strengthen software supply chain security, but it s quite another to effectively configure a reproducible build. Concrete steps for specific languages are a far larger topic than can be covered in a single blog post, but today we ll be talking about some guiding principles when designing reproducible builds. [ ]
The article was discussed on Hacker News.
Finally, Bernhard M. Wiedemann noticed that the GNU Helloworld project varies depending on whether it is being built during a full moon! (Reddit announcement, openSUSE bug report)

Events There will be an in-person Debian Reunion in Hamburg, Germany later this year, taking place from 23 30 May. Although this is a Debian event, there will be some folks from the broader Reproducible Builds community and, of course, everyone is welcome. Please see the event page on the Debian wiki for more information. Bernhard M. Wiedemann posted to our mailing list about a meetup for Reproducible Builds folks at the openSUSE conference in Nuremberg, Germany. It was also recently announced that DebConf22 will take place this year as an in-person conference in Prizren, Kosovo. The pre-conference meeting (or Debcamp ) will take place from 10 16 July, and the main talks, workshops, etc. will take place from 17 24 July.

Misc news Holger Levsen updated the Reproducible Builds website to improve the documentation for the SOURCE_DATE_EPOCH environment variable, both by expanding parts of the existing text [ ][ ] as well as clarifying meaning by removing text in other places [ ]. In addition, Chris Lamb added a Twitter Card to our website s metadata too [ ][ ][ ]. On our mailing list this month:

Distribution work In Debian this month:
  • Johannes Schauer Marin Rodrigues posted to the debian-devel list mentioning that he exploited the property of reproducibility within Debian to demonstrate that automatically converting a large number of packages to a new internal source version did not change the resulting packages. The proposed change could therefore be applied without causing breakage:
So now we have 364 source packages for which we have a patch and for which we can show that this patch does not change the build output. Do you agree that with those two properties, the advantages of the 3.0 (quilt) format are sufficient such that the change shall be implemented at least for those 364? [ ]
In openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Tooling diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 207, 208 and 209 to Debian unstable, as well as made the following changes to the code itself:
  • Update minimum version of Black to prevent test failure on Ubuntu jammy. [ ]
  • Updated the R test fixture for the 4.2.x series of the R programming language. [ ]
Brent Spillner also worked on adding graceful handling for UNIX sockets and named pipes to diffoscope. [ ][ ][ ]. Vagrant Cascadian also updated the diffoscope package in GNU Guix. [ ][ ] reprotest is the Reproducible Build s project end-user tool to build the same source code twice in widely different environments and checking whether the binaries produced by the builds have any differences. This month, Santiago Ruano Rinc n added a new --append-build-command option [ ], which was subsequently uploaded to Debian unstable by Holger Levsen.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Replace a local copy of the dsa-check-running-kernel script with a packaged version. [ ]
    • Don t hide the status of offline hosts in the Jenkins shell monitor. [ ]
    • Detect undefined service problems in the node health check. [ ]
    • Update the sources.lst file for our mail server as its still running Debian buster. [ ]
    • Add our mail server to our node inventory so it is included in the Jenkins maintenance processes. [ ]
    • Remove the debsecan package everywhere; it got installed accidentally via the Recommends relation. [ ]
    • Document the usage of the osuosl174 host. [ ]
Regular node maintenance was also performed by Holger Levsen [ ], Vagrant Cascadian [ ][ ][ ] and Mattia Rizzolo.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Jacob Adams: The Unexpected Importance of the Trailing Slash

For many using Unix-derived systems today, we take for granted that /some/path and /some/path/ are the same. Most shells will even add a trailing slash for you when you press the Tab key after the name of a directory or a symbolic link to one. However, many programs treat these two paths as subtly different in certain cases, which I outline below, as all three have tripped me up in various ways1.

POSIX and Coreutils Perhaps the trickiest use of the trailing slash in a distinguishing way is in POSIX2 which states:
When the final component of a pathname is a symbolic link, the standard requires that a trailing <slash> causes the link to be followed. This is the behavior of historical implementations3. For example, for /a/b and /a/b/, if /a/b is a symbolic link to a directory, then /a/b refers to the symbolic link, and /a/b/ refers to the directory to which the symbolic link points.
This leads to some unexpected behavior. For example, if you have the following structure of a directory dir containing a file dirfile with a symbolic link link pointing to dir. (which will be used in all shell examples throughout this article):
$ ls -lR
.:
total 4
drwxr-xr-x 2 jacob jacob 4096 Apr  3 00:00 dir
lrwxrwxrwx 1 jacob jacob    3 Apr  3 00:00 link -> dir
./dir:
total 0
-rw-r--r-- 1 jacob jacob 0 Apr  3 00:12 dirfile
On Unixes such as MacOS, FreeBSD or Illumos4, you can move a directory through a symbolic link by using a trailing slash:
$ mv link/ otherdir
$ ls
link	otherdir
On Linux5, mv will not rename the indirectly referenced directory and not the symbolic link, when given a symbolic link with a trailing slash as the source to be renamed. despite the coreutils documentation s claims to the contrary6, instead failing with Not a directory:
$ mv link/ other
mv: cannot move 'link/' to 'other': Not a directory
$ mkdir otherdir
$ mv link/ otherdir
mv: cannot move 'link/' to 'otherdir/link': Not a directory
$ mv link/ otherdir/
mv: cannot move 'link/' to 'otherdir/link': Not a directory
$ mv link otherdirlink
$ ls -l otherdirlink
lrwxrwxrwx 1 jacob jacob 3 Apr  3 00:13 otherdirlink -> dir
This is probably for the best, as it is very confusing behavior. There is still one advantage the trailing slash has when using mv, even on Linux, in that is it does not allow you to move a file to a non-existent directory, or move a file that you expect to be a directory that isn t.
$ mv dir/dirfile nonedir/
mv: cannot move 'dir/dirfile' to 'nonedir/': Not a directory
$ touch otherfile
$ mv otherfile/ dir
mv: cannot stat 'otherfile/': Not a directory
$ mv otherfile dir
$ ls dir
dirfile  otherfile
However, Linux still exhibits some confusing behavior of its own, like when you attempt to remove link recursively with a trailing slash:
rm -rvf link/
Neither link nor dir are removed, but the contents of dir are removed:
removed 'link/dirfile'
Whereas if you remove the trailing slash, you just remove the symbolic link:
$ rm -rvf link
removed 'link'
While on MacOS, FreeBSD or Illumos4, rm will also remove the source directory:
$ rm -rvf link
link/dirfile
link/
$ ls
link
The find and ls commands, in contrast, behave the same on all three operating systems. The find command only searches the contents of the directory a symbolic link points to if the trailing slash is added:
$ find link -name dirfile
$ find link/ -name dirfile
link/dirfile
The ls command acts similarly, showing information on just a symbolic link by itself unless a trailing slash is added, at which point it shows the contents of the directory that it links to:
$ ls -l link
lrwxrwxrwx 1 jacob jacob 3 Apr  3 00:13 link -> dir
$ ls -l link/
total 0
-rw-r--r-- 1 jacob jacob 0 Apr  3 00:13 dirfile

rsync The command rsync handles a trailing slash in an unusual way that trips up many new users. The rsync man page notes:
You can think of a trailing / on a source as meaning copy the contents of this directory as opposed to copy the directory by name , but in both cases the attributes of the containing directory are transferred to the containing directory on the destination.
That is to say, if we had two folders a and b each of which contained some files:
$ ls -R .
.:
a  b
./a:
a1  a2
./b:
b1  b2
Running rsync -av a b moves the entire directory a to directory b:
$ rsync -av a b
sending incremental file list
a/
a/a1
a/a2
sent 181 bytes  received 58 bytes  478.00 bytes/sec
total size is 0  speedup is 0.00
$ ls -R b
b:
a  b1  b2
b/a:
a1  a2
While running rsync -av a/ b moves the contents of directory a to b:
$ rsync -av a/ b
sending incremental file list
./
a1
a2
sent 170 bytes  received 57 bytes  454.00 bytes/sec
total size is 0  speedup is 0.00
$ ls b
a1  a2	b1  b2

Dockerfile COPY The Dockerfile COPY command also cares about the presence of the trailing slash, using it to determine whether the destination should be considered a file or directory. The Docker documentation explains the rules of the command thusly:
COPY [--chown=<user>:<group>] <src>... <dest>
If <src> is a directory, the entire contents of the directory are copied, including filesystem metadata. Note: The directory itself is not copied, just its contents. If <src> is any other kind of file, it is copied individually along with its metadata. In this case, if <dest> ends with a trailing slash /, it will be considered a directory and the contents of <src> will be written at <dest>/base(<src>). If multiple <src> resources are specified, either directly or due to the use of a wildcard, then <dest> must be a directory, and it must end with a slash /. If <dest> does not end with a trailing slash, it will be considered a regular file and the contents of <src> will be written at <dest>. If <dest> doesn t exist, it is created along with all missing directories in its path.
This means if you had a COPY command that moved file to a nonexistent containerfile without the slash, it would create containerfile as a file with the contents of file.
COPY file /containerfile
container$ stat -c %F containerfile
regular empty file
Whereas if you add a trailing slash, then file will be added as a file under the new directory containerdir:
COPY file /containerdir/
container$ stat -c %F containerdir
directory
Interestingly, at no point can you copy a directory completely, only its contents. Thus if you wanted to make a directory in the new container, you need to specify its name in both the source and the destination:
COPY dir /dirincontainer
container$ stat -c %F /dirincontainer
directory
Dockerfiles do also make good use of the trailing slash to ensure they re doing what you mean by requiring a trailing slash on the destination of multiple files:
COPY file otherfile /othercontainerdir
results in the following error:
When using COPY with more than one source file, the destination must be a directory and end with a /
  1. I m sure there are probably more than just these three cases, but these are the three I m familiar with. If you know of more, please tell me about them!.
  2. Some additional relevant sections are the Path Resolution Appendix and the section on Symbolic Links.
  3. The sentence This is the behavior of historical implementations implies that this probably originated in some ancient Unix derivative, possibly BSD or even the original Unix. I don t really have a source on that though, so please reach out if you happen to have any more knowledge on what this refers to.
  4. I tested on MacOS 11.6.5, FreeBSD 12.0 and OmniOS 5.11 2
  5. unless the source is a directory trailing slashes give -ENOTDIR
  6. In fairness to the coreutils maintainers, it seems to be true on all other Unix platforms, but it probably deserves a mention in the documentation when Linux is the most common platform on which coreutils is used. I should submit a patch.

6 April 2022

Bits from Debian: Infomaniak Platinum Sponsor of DebConf22

infomaniaklogo We are very pleased to announce that Infomaniak has committed to support DebConf22 as a Platinum sponsor. This is the fourth year in a row that Infomaniak is sponsoring The Debian Conference with the higher tier! Infomaniak is Switzerland's largest web-hosting company, also offering backup and storage services, solutions for event organizers, live-streaming and video on demand services. It wholly owns its datacenters and all elements critical to the functioning of the services and products provided by the company (both software and hardware). With this commitment as Platinum Sponsor, Infomaniak contributes to make possible our annual conference, and directly supports the progress of Debian and Free Software helping to strengthen the community that continues to collaborate on Debian projects throughout the rest of the year. Thank you very much Infomaniak, for your support of DebConf22! Become a sponsor too! DebConf22 will take place from July 17th to 24th, 2022 at the Innovation and Training Park (ITP) in Prizren, Kosovo, and will be preceded by DebCamp, from July 10th to 16th. And DebConf22 is still accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf22 website at https://debconf22.debconf.org/sponsors/become-a-sponsor. DebConf22 banner open registration

5 April 2022

Dirk Eddelbuettel: RcppArmadillo 0.11.0.0.0 on CRAN: Upstream Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra aiming towards a good balance between speed and ease of use with a syntax deliberately close to a Matlab. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 972 other packages on CRAN, downloaded over 24 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 465 times according to Google Scholar. This release brings a new upstream release 11.0.0. We tested this very rigorously via three different RC release each of which got a full reverse-dependencies run (for which results are always logged here). The full set of changes (since the last CRAN release 0.10.8.1.0) follows.

Changes in RcppArmadillo version 0.11.0.0 (2022-04-04)
  • Upgraded to Armadillo release 11.0.0 (Creme Brulee)
    • added variants of inv() and inv_sympd() that provide rcond (reciprocal condition number)
    • expanded inv() and inv_sympd() with options inv_opts::tiny and inv_opts::allow_approx
    • stricter handling of singular matrices by inv() and inv_sympd()
    • stricter handling of non-sympd matrices by inv() and inv_sympd()
    • stricter handling of non-finitie matrices by pinv()
    • more robust handling of rank deficient matrices by solve()
    • faster handling of diagonal matrices by rcond()
    • changed eigs_sym() and eigs_gen() to use higher quality RNG
    • quantile() and median() will now throw an exception if given matrices/vectors have NaN elements
    • workaround for yet another bug in Intel MKL
  • Until May 2022, protect correction to Field behavior via define of RCPP_ARMADILLO_FIX_Field
  • If a LAPACK installation with missing complex routines is found (as e.g. Ubuntu using 3.9.0) then the LAPACK unit test is skipped.

Changes in RcppArmadillo version 0.10.8.2.0 (2022-02-01)
  • Upgraded to Armadillo release 10.8.2 (Realm Raider)
    • fix potential speed regression in pinv() and rank()

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 April 2022

Arturo Borrero Gonz lez: Wikimedia Toolforge and Grid Engine

Logos This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez. One of the most important and successful products provided by the Wikimedia Cloud Services team at the Wikimedia Foundation is Toolforge, a hosting service commonly known in the industry as Platform as a Service (PaaS). In particular, it is a platform that allows users and developers to run and use a variety of applications with the ultimate goal of helping the Wikimedia mission from the technical side. Toolforge is powered by two different backend engines, Kubernetes and Grid Engine. The two backends have traditionally offered different features for tool developers. But as time moves forward we ve learnt that Kubernetes is the future. Explaining why is the purpose of this blog post: we want to share more information and reasoning behind this mindset. There are a number of reasons that make Grid Engine poorly suitable to remain as execution backend in Toolforge: As mentioned above, our desire is to cover all our grid-like needs with Kubernetes, a technology which has several benefits: The relationship between Toolforge and Grid Engine has been interesting over the years. The grid has been used for quite a lot of time, we have plenty of documentation and established good practices. On the other hand, the grid is hard to maintain, imposes a heavy burden on the WMCS team and is a technology we must eventually discontinue. How to accommodate the two realities is a refreshing challenge, one that we hope to tackle together in the near future. A tradeoff exists here, but it is clear to us which option is best. So we will work on deprecating and removing Grid Engine and migrating use cases into Kubernetes. This deprecation, however, will be done with care, as we know our technical community relies on the grid for some import Toolforge tools. And some of these workflows will need some adaptation in order to be fully supported on Kubernetes. Stay tuned for more information on present and next works surrounding the Wikimedia Toolforge service. The next blog post will share more concrete details. This post was originally published in the Wikimedia Tech blog, authored by Arturo Borrero Gonzalez.
1 April 2022

Dirk Eddelbuettel: RInside 0.2.17

A new release 0.2.17 of RInside arrived on CRAN and in Debian today. This is the first release in two years since the 0.2.16 release. RInside provides a set of convenience classes which facilitate embedding of R inside of C++ applications and programs, using the classes and functions provided by Rcpp. This release brings a minor update for R 4.2.0, due out later this month, and kindly provided by Tomas Kalibera. It updates one function declaration; we wrapped some conditioning around so that RInside continues to build with older releases too. Besides that minor updates were made to continuous integration and some of the package files. The short list of changes since the last release were:

Changes in RInside version 0.2.17 (2022-03-31)
  • A Windows-only patch for R 4.2.0 kindly provided by Tomas Kalibera was applied, and also conditioned on R (>= 4.2.0)
  • Continuous Integration setup was updated and now uses r-ci.
  • Several updates were made to README.md (badges etc) and DESCRIPTION

My CRANberries also provides a short report with changes from the previous release. More information is on the RInside page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page, or to issues tickets at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Antoine Beaupr : Salvaged my first Debian package

I finally salvaged my first Debian package, python-invoke. As part of ITS 964718, I moved the package from the Openstack Team to the Python team. The Python team might not be super happy with it, because it's breaking some of its rules, but at least someone (ie. me) is actively working (and using) the package.

Wait what People not familiar with Debian will not understand anything in that first paragraph, so let me expand. Know-it-all Debian developers (you know who you are) can skip to the next section. Traditionally, the Debian project (my Linux-based operating system of choice) has prided itself on the self-managed, anarchistic organisation of its packaging. Each package maintainer is the lord of their little kingdom. Some maintainers like to accumulate lots of kingdoms to rule over. (Yes, it really doesn't sound like anarchism when you put it like that. Yes, it's complicated: there's a constitution and voting involved. And yes, we're old.) Therefore, it's really hard to make package maintainers do something they don't want. Typically, when things go south, someone makes a complaint to the Debian Technical Committee (CTTE) which is established by the Debian constitution to resolve such conflicts. The committee is appointed by the Debian Project leader, elected each year (and there's an election coming up if you haven't heard). Typically, the CTTE will then vote and formulate a decision. But here's the trick: maintainers are still free to do whatever they want after that, in a sense. It's not like the CTTE can just break down doors and force maintainers to type code. (I won't go into the details of the why of that, but it involves legal issues and, I think, something about the Turing halting problem. Or something like that.) Anyways. The point is all that is super heavy and no one wants to go there... (Know-it-all Debian developers, I know you are still reading this anyways and disagree with that statement, but please, please, make it true.) ... but sometimes, packages just get lost. Maintainers get distracted, or busy with something else. It's not that they want to abandon their packages. They love their little fiefdoms. It's just there was a famine or a war or something and everyone died, and they have better things to do than put up fences or whatever. So clever people in Debian found a better way of handling such problems than waging war in the poor old CTTE's backyard. It's called the Package Salvaging process. Through that process, a maintainer can propose to take over an existing package from another maintainer, if a certain set of condition are met and a specific process is followed. Normally, taking over another maintainer's package is basically a war declaration, rarely seen in the history of Debian (yes, I do think it happened!), as rowdy as ours is. But through this process, it seems we have found a fair way of going forward. The process is basically like this:
  1. file a bug proposing the change
  2. wait three weeks
  3. upload a package making the change, with another week delay
  4. you now have one more package to worry about
Easy right? It actually is! Process! It's magic! It will cure your babies and resurrect your cat!

So how did that go? It went well! The old maintainer was actually fine with the change because his team wasn't using the package anymore anyways. He asked to be kept as an uploader, which I was glad to oblige. (He replied a few months after the deadline, but I wasn't in a rush anyways, so that doesn't matter. It was polite for him to answer, even if, technically, I was already allowed to take it over.) What happened next is less shiny for me though. I totally forgot about the ITS, even after the maintainer reminded me of its existence. See, the thing is the ITS doesn't show up on my dashboard at all. So I totally forgot about it (yes, twice). In fact, the only reason I remembered it was that got into the process of formulating another ITS (1008753, trocla) and I was trying to figure out how to write the email. Then I remembered: "hey wait, I think I did this before!" followed by "oops, yes, I totally did this before and forgot for 9 months". So, not great. Also, the package is still not in a perfect shape. I was able to upload the upstream version that was pending 1.5.0 to clear out the ITS, basically. And then there's already two new upstream releases to upload, so I pushed 1.7.0 to experimental as well, for good measure. Unfortunately, I still can't enable tests because everything is on fire, as usual. But at least my kingdom is growing.

Appendix Just in case someone didn't notice the hyperbole, I'm not a monarchist promoting feudalism as a practice to manage a community. I do not intend to really "grow my kingdom" and I think the culture around "property" of "packages" is kind of absurd in Debian. I kind of wish it would go away. (Update: It has also been pointed out that I might have made Debian seem more confrontational than it actually is. And it's kind of true: most work and interactions in Debian actually go fine, it's only a minority of issues that degenerate into conflicts. It's just that they tend to take up a lot of space in the community, and I find that particularly draining. And I think think our "package ownership" culture is part of at least some of those problems.) Team maintenance, the LowNMU process, and low threshold adoption processes are all steps in the good direction, but they are all opt in. At least the package salvaging process is someone a little more ... uh... coercive? Or at least it allows the community to step in and do the right thing, in a sense. We'll see what happens with the coming wars around the recent tech committee decision, which are bound to touch on that topic. (Hint: our next drama is called "usrmerge".) Hopefully, LWN will make a brilliant article to sum it up for us so that I don't have to go through the inevitable debian-devel flamewar to figure it out. I already wrecked havoc on the #debian-devel IRC channel asking newbie questions so I won't stir that mud any further for now. (Update: LWN, of course, did make an article about usrmerge in Debian. I will read it soon and can then tell you know if it's brilliant, but they are typically spot on.)

31 March 2022

Russell Coker: AMT/MEBX on Debian

I ve just been playing with Intel s Active Management Technology (AMT) [1] which is also known as Management Engine Bios Extension (MEBX). Firstly a disclaimer, using this sort of technology gives remote access to your system at a level that allows in some ways overriding the OS. If this gets broken then you have big problems. Also all the code that matters is non-free. Please don t comment on this post saying that AMT is bad, take it as known that it has issues and that people are forced to use it anyway. I tested this out on a HP Z420 workstation. The first thing it to enable AMT via Intel MEBX , the default password is admin . On first use you are compelled to set a new password which must be 8+ characters containing upper and lower case, number, and punctuation characters. The Debian package amtterm (which needs the package libsoap-lite-perl ) has basic utilities for AMT. The amttool program connects to TCP port 16992 and the amtterm program connects to TCP port 16994. Note that these programs seem a little rough, you can get Perl errors (as opposed to deliberate help messages) if you enter bad command-line parameters. They basically work but could do with some improvement. If you use DHCP for the IP address the DHCP hostname will be DESKTOP-$AssetID and you can find the IP address by requesting an alert be sent to the sysadmin. Here are some examples of amttool usage:
# get AMT info
AMT_PASSWORD="$PASS" amttool $IP
# reset the system and redirect BIOS messages to serial over lan
AMT_PASSWORD="$PASS" amttool reset bios
# access serial over lan console
amtterm -p "$PASS" $IP
The following APT configuration enables the Ubuntu package wsmancli which had some features not in any Debian packages last time I checked.
deb http://us.archive.ubuntu.com/ubuntu/ bionic-updates universe
deb http://us.archive.ubuntu.com/ubuntu/ bionic universe
This Cyberciti article has information on accessing KVM over AMT [2], I haven t tried to do that yet.

Russell Coker: Links March 2022

Anarcat wrote a great blog post about switching from OpenNTP to Chrony which gives a good overview of how NTP works and how accurate the different versions are [1]. Bleeping Computer has an amusing article about criminals who copied a lot of data from NVidia servers including specs of their latest products [2], they are threatening to release all the data if NVidia doesn t stop crippling their GPUs to make them unsuitable for crypto currency mining. I don t support these criminals, but I think NVidia should allow people who buy hardware to use their property as they choose. If cryptocurrency miners buy all the NVidia products then NVidia still makes the sales, they could even auction them to make more money. NPR has a disturbing article about the way execution by lethal injection works in the US [3]. It seems that most people die in an extremely unpleasant way. It makes the North Korean execution by anti-aircraft gun seem civilised. The DirtyPipe vulnerability is the latest serious security issue in the Linux kernel [4]. The report of how it was discovered is very interesting and should be read by all sysadmins. SE Linux will not save you from this as the vulnerability allows writing to read-only files like /etc/passwd. Politico has an insightful analysis of Putin, it s not good news he wants to conquer all territory that had ever been part of a Russian empire at any time in history [5]. The Guardian has an informative article about the EU s attempts to debunk Russian propaganda about Covid19 [6]. Fortunately the sanctions are reducing Russia s ability to do such things now. The Guardian has in interesting article about a project to use literary analysis to predict wars [7]. Funded by the German military but funding was cut after it was proven to work. The Fact Act is a proposal by David Brin for political changes in the US to involve scientists and statisticians in an official advisory role in the legislative process [8], it s an idea with a lot of potential. Technology Review has an interesting interview with the leader of the NSA s Research Directorate [9]. In 2008 the EFF posted a long and informative article about the RIAA s war against music fans [10]. I had followed a lot of the news about this when it was happening, but I still learnt some things from this article that I hadn t known at the time. Also considering past legal battles in the context of the current situation is useful. As an aside all the music I want to listen to is now on YouTube and youtube-dl works really well for me. The 1952 edition of Psychiatry: Journal of Interpersonal Relations has an interesting article On Cooling the Mark Out [11] which starts about how criminal gangs engaged in fraud try to make their victims come to terms with the loss in a way that doesn t involve the police. But it goes on to cover ways of dealing with loss of status in general. The layout is hacky with words broken by hyphens in the middle of lines as it appears to have been scanned from paper, converted to MS-Word, and from there to PDF. But it s worth it. The Internet Heist by Cory Doctorow is an insightful series of 3 articles about the MPAA (MAFIAA) attempts to take over all TV distribution in the US [12]. Wired has an interesting exerpt from the book Spies, Lies, and Algorithms: The History and Future of American Intelligence , by Amy B. Zegart [13]. Interesting summary of the open source intelligence systems (which have nothing to do with open source as free software). But it would be interesting to have an open source intelligence organisation along similar lines to open source software. The guy who tracks billionaire s private jets is an example of this.

30 March 2022

Bits from Debian: Lenovo Platinum Sponsor of DebConf22

lenovologo We are very pleased to announce that Lenovo has committed to supporting DebConf22 as a Platinum sponsor. This is the fourth year in a row that Lenovo is sponsoring The Debian Conference with the higher tier! As a global technology leader manufacturing a wide portfolio of connected products, including smartphones, tablets, PCs and workstations as well as AR/VR devices, smart home/office and data center solutions, Lenovo understands how critical open systems and platforms are to a connected world. With this commitment as Platinum Sponsor, Lenovo is contributing to make possible our annual conference, and directly supporting the progress of Debian and Free Software, helping to strengthen the community that continues to collaborate on Debian projects throughout the rest of the year. Thank you very much Lenovo, for your support of DebConf22! Become a sponsor too! DebConf22 will take place from July 17th to 24th, 2022 at the Innovation and Training Park (ITP) in Prizren, Kosovo, and will be preceded by DebCamp, from July 10th to 16th. And DebConf22 is still accepting sponsors! Interested companies and organizations may contact the DebConf team through sponsors@debconf.org, and visit the DebConf22 website at https://debconf22.debconf.org/sponsors/become-a-sponsor. DebConf22 banner open registration

28 March 2022

Russell Coker: Reading Glasses

About 4 years ago at a routine eye check the optometrist recommended that I get reading glasses. Apparently I m old enough that my eyes are losing their ability to focus at different distances to having different glasses for close and remote objects (EG reading and driving) is necessary for good vision. The optometrist asked me the distance that I use for reading and I indicated a distance that is good for books and phones (about 20cm). So I got a pair of glasses that worked well for that but didn t work well for the vast majority of my close work which is computer monitors. I found that I could use my reading glasses with my laptop when lying in bed if I had the laptop on my chest with the keyboard touching my chin, which is a reasonable position for watching TV but not for much else. About 2 years ago I had another eye check which determined that the glasses for long distance were good and got reading glasses designed for objects about 80cm away which worked well for monitors and were usable for watching TV. Recently I accidentally broke my newer pair of reading glasses and discovered that the older pair now works for distances of about a meter. So it appears that I have become significantly more long sighted over the last 4 years.

Next.

Previous.