Search Results: "tar"

25 January 2024

Dimitri John Ledkov: Ubuntu Livepatch service now supports over 60 different kernels
Linux kernel getting a livepatch whilst running a marathon. Generated with AI.
Livepatch service eliminates the need for unplanned maintenance windows for high and critical severity kernel vulnerabilities by patching the Linux kernel while the system runs. Originally the service launched in 2016 with just a single kernel flavour supported.Over the years, additional kernels were added: new LTS releases, ESM kernels, Public Cloud kernels, and most recently HWE kernels too.Recently livepatch support was expanded for FIPS compliant kernels, Public cloud FIPS compliant kernels, and as well IBM Z (mainframe) kernels. Bringing the total of kernel flavours support to over 60 distinct kernel flavours supported in parallel. The table of supported kernels in the documentation lists the supported kernel flavours ABIs, the duration of individual build's support window, supported architectures, and the Ubuntu release. This work was only possible thanks to the collaboration with the Ubuntu Certified Public Cloud team, engineers at IBM for IBM Z (s390x) support, Ubuntu Pro team, Livepatch server & client teams.It is a great milestone, and I personally enjoy seeing the non-intrusive popup on my Ubuntu Desktop that a kernel livepatch was applied to my running system. I do enable Ubuntu Pro on my personal laptop thanks to the free Ubuntu Pro subscription for individuals.What's next? The next frontier is supporting ARM64 kernels. The Canonical kernel team has completed the gap analysis to start supporting Livepatch Service for ARM64. Upstream Linux requires development work on the consistency model to fully support livepatch on ARM64 processors. Livepatch code changes are applied on a per-task basis, when the task is deemed safe to switch over. This safety check depends mostly on kernel stacktraces. For these checks, CONFIG_HAVE_RELIABLE_STACKTRACE needs to be available in the upstream ARM64 kernel. (see The Linux Kernel Documentation). There are preliminary patches that enable reliable stacktraces on ARM64, however these turned out to be problematic as there are lots of fix revisions that came after the initial patchset that AWS ships with 5.10. This is a call for help from any interested parties. If you have engineering resources and are interested in bringing Livepatch Service to your ARM64 platforms, please reach out to the Canonical Kernel team on the public Ubuntu Matrix, Discourse, and mailing list. If you want to chat in person, see you at FOSDEM next weekend.

Joachim Breitner: GHC Steering Committee Retrospective

After seven years of service as member and secretary on the GHC Steering Committee, I have resigned from that role. So this is a good time to look back and retrace the formation of the GHC proposal process and committee. In my memory, I helped define and shape the proposal process, optimizing it for effectiveness and throughput, but memory can be misleading, and judging from the paper trail in my email archives, this was indeed mostly Ben Gamari s and Richard Eisenberg s achievement: Already in Summer of 2016, Ben Gamari set up the ghc-proposals Github repository with a sketch of a process and sent out a call for nominations on the GHC user s mailing list, which I replied to. The Simons picked the first set of members, and in the fall of 2016 we discussed the committee s by-laws and procedures. As so often, Richard was an influential shaping force here.

Three ingredients For example, it was him that suggested that for each proposal we have one committee member be the Shepherd , overseeing the discussion. I believe this was one ingredient for the process effectiveness: There is always one person in charge, and thus we avoid the delays incurred when any one of a non-singleton set of volunteers have to do the next step (and everyone hopes someone else does it). The next ingredient was that we do not usually require a vote among all members (again, not easy with volunteers with limited bandwidth and occasional phases of absence). Instead, the shepherd makes a recommendation (accept/reject), and if the other committee members do not complain, this silence is taken as consent, and we come to a decision. It seems this idea can also be traced back on Richard, who suggested that once a decision is requested, the shepherd [generates] consensus. If consensus is elusive, then we vote. At the end of the year we agreed and wrote down these rules, created the mailing list for our internal, but publicly archived committee discussions, and began accepting proposals, starting with Adam Gundry s OverloadedRecordFields. At that point, there was no secretary role yet, so how I did become one? It seems that in February 2017 I started to clean-up and refine the process documentation, fixing bugs in the process (like requiring authors to set Github labels when they don t even have permissions to do that). This in particular meant that someone from the committee had to manually handle submissions and so on, and by the aforementioned principle that at every step there ought to be exactly one person in change, the role of a secretary followed naturally. In the email in which I described that role I wrote:
Simon already shoved me towards picking up the secretary hat, to reduce load on Ben.
So when I merged the updated process documentation, I already listed myself secretary . It wasn t just Simon s shoving that put my into the role, though. I dug out my original self-nomination email to Ben, and among other things I wrote:
I also hope that there is going to be clear responsibilities and a clear workflow among the committee. E.g. someone (possibly rotating), maybe called the secretary, who is in charge of having an initial look at proposals and then assigning it to a member who shepherds the proposal.
So it is hardly a surprise that I became secretary, when it was dear to my heart to have a smooth continuous process here. I am rather content with the result: These three ingredients single secretary, per-proposal shepherds, silence-is-consent helped the committee to be effective throughout its existence, even as every once in a while individual members dropped out.

Ulterior motivation I must admit, however, there was an ulterior motivation behind me grabbing the secretary role: Yes, I did want the committee to succeed, and I did want that authors receive timely, good and decisive feedback on their proposals but I did not really want to have to do that part. I am, in fact, a lousy proposal reviewer. I am too generous when reading proposals, and more likely mentally fill gaps in a specification rather than spotting them. Always optimistically assuming that the authors surely know what they are doing, rather than critically assessing the impact, the implementation cost and the interaction with other language features. And, maybe more importantly: why should I know which changes are good and which are not so good in the long run? Clearly, the authors cared enough about a proposal to put it forward, so there is some need and I do believe that Haskell should stay an evolving and innovating language but how does this help me decide about this or that particular feature. I even, during the formation of the committee, explicitly asked that we write down some guidance on Vision and Guideline ; do we want to foster change or innovation, or be selective gatekeepers? Should we accept features that are proven to be useful, or should we accept features so that they can prove to be useful? This discussion, however, did not lead to a concrete result, and the assessment of proposals relied on the sum of each member s personal preference, expertise and gut feeling. I am not saying that this was a mistake: It is hard to come up with a general guideline here, and even harder to find one that does justice to each individual proposal. So the secret motivation for me to grab the secretary post was that I could contribute without having to judge proposals. Being secretary allowed me to assign most proposals to others to shepherd, and only once in a while myself took care of a proposal, when it seemed to be very straight-forward. Sneaky, ain t it?

7 Years later For years to come I happily played secretary: When an author finished their proposal and public discussion ebbed down they would ping me on GitHub, I would pick a suitable shepherd among the committee and ask them to judge the proposal. Eventually, the committee would come to a conclusion, usually by implicit consent, sometimes by voting, and I d merge the pull request and update the metadata thereon. Every few months I d summarize the current state of affairs to the committee (what happened since the last update, which proposals are currently on our plate), and once per year gathered the data for Simon Peyton Jones annually GHC Status Report. Sometimes some members needed a nudge or two to act. Some would eventually step down, and I d sent around a call for nominations and when the nominations came in, distributed them off-list among the committee and tallied the votes. Initially, that was exciting. For a long while it was a pleasant and rewarding routine. Eventually, it became a mere chore. I noticed that I didn t quite care so much anymore about some of the discussion, and there was a decent amount of naval-gazing, meta-discussions and some wrangling about claims of authority that was probably useful and necessary, but wasn t particularly fun. I also began to notice weaknesses in the processes that I helped shape: We could really use some more automation for showing proposal statuses, notifying people when they have to act, and nudging them when they don t. The whole silence-is-assent approach is good for throughput, but not necessary great for quality, and maybe the committee members need to be pushed more firmly to engage with each proposal. Like GHC itself, the committee processes deserve continuous refinement and refactoring, and since I could not muster the motivation to change my now well-trod secretarial ways, it was time for me to step down. Luckily, Adam Gundry volunteered to take over, and that makes me feel much less bad for quitting. Thanks for that! And although I am for my day job now enjoying a language that has many of the things out of the box that for Haskell are still only language extensions or even just future proposals (dependent types, BlockArguments, do notation with ( foo) expressions and Unicode), I m still around, hosting the Haskell Interlude Podcast, writing on this blog and hanging out at ZuriHac etc.

24 January 2024

Dirk Eddelbuettel: RApiDatetime 0.0.9 on CRAN: Maintenance

A new maintenance release of our RApiDatetime package is now on CRAN RApiDatetime provides a number of entry points for C-level functions of the R API for Date and Datetime calculations. The functions asPOSIXlt and asPOSIXct convert between long and compact datetime representation, formatPOSIXlt and Rstrptime convert to and from character strings, and POSIXlt2D and D2POSIXlt convert between Date and POSIXlt datetime. Lastly, asDatePOSIXct converts to a date type. All these functions are rather useful, but were not previously exported by R for C-level use by other packages. Which this package aims to change. This release responds to a CRAN request to clean up empty macros and sections in Rd files. Moreover, because the windows portion of the corresponding R-internal code underwent some changes, our (#ifdef conditional) coverage here is a little behind and created a warning under the newer UCRT setup. So starting with this release we are back to OS_type: unix meaning there will not be any Windows builds at CRAN. If you would like that to change, and ideally can work in the Windows portion, do not hesitate to get in touch. Details of the release follow based on the NEWS file.

Changes in RApiDatetime version 0.0.9 (2024-01-23)
  • Replace auto-generated stale RApitDatetime-package.Rd with macro-filled stanza to satisfy CRAN request.

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Thomas Lange: FAI 6.2 released

After more than one a year, a new minor FAI version is available, but it includes some interesting new features. Here a the items from the NEWS file: fai (6.2) unstable; urgency=low In the past the command fai-cd was only used for creating installation ISOs, that could be used from CD or USB stick. Now it possible to create a live ISO. Therefore you create your live chroot environment using 'fai dirinstall' and then convert it to a bootable live ISO using fai-cd. See man fai-cd(8) for an example. Years ago I had the idea to use the remaining disk space on an USB stick after copying an ISO onto it. I've blogged about this recently: https://blog.fai-project.org/posts/extending-iso-images/ The new FAI version includes the tool mk-data-partition for adding a data partition to the ISO itself or to an USB stick. FAI detects this data partition, mounts it to /media/data and can then use various configurations from it. You may want to copy your own set of .deb packages or your whole FAI config space to this partition. FAI now automatically searches this partition for usable FAI configuration data and packages. FAI will install all packages from pkgs/<CLASSNAME> if the equivalent class is defined. Setting FAI_CONFIG_SRC=detect:// now looks into the data partition for the subdirectory 'config' and uses this as the config space. So it's now possible to modify an existing ISO (that is read-only) and make changes to the config space. If there's no config directory in the data partition FAI uses the default location on the ISO. The tool fai-kvm, which starts virtual machines can now boot an ISO not only as CD but also as USB stick. Sometimes users want to adjust the list of disks before the partitioning is startet. Therefore FAI provides several new functions including You can select individual disks by their model name or even the serial number. Two new FAI flags were added (tmux and screen) that make it easy to run FAI inside a tmux or screen session. And finally FAI uses systemd. Yeah! This technical change was waiting since 2015 in a merge request from Moritz 'Morty' Str be, that would enable using systemd during the installation. Before FAI still was using old-style SYSV init scripts and did not started systemd. I didn't tried to apply the patch, because I was afraid that it would need much time to make it work. But then in may 2023 Juri Grabowski just gave it a try at MiniDebConf Hamburg, and voil it just works! Many, many thanks to Moritz and Juri for their bravery. The whole changelog can be found at https://tracker.debian.org/media/packages/f/fai/changelog-6.2 New ISOs for FAI are also available including an example of a Xfce desktop live ISO: https://fai-project.org/fai-cd/ The FAIme service for creating customized installation ISOs will get its update later. The new packages are available for bookworm by adding this line to your sources.list: deb https://fai-project.org/download bookworm koeln

22 January 2024

Paul Tagliamonte: Writing a simulator to check phased array beamforming

Interested in future updates? Follow me on mastodon at @paul@soylent.green. Posts about hz.tools will be tagged #hztools.

If you're on the Fediverse, I'd very much appreciate boosts on my toot!
While working on hz.tools, I started to move my beamforming code from 2-D (meaning, beamforming to some specific angle on the X-Y plane for waves on the X-Y plane) to 3-D. I ll have more to say about that once I get around to publishing the code as soon as I m sure it s not completely wrong, but in the meantime I decided to write a simple simulator to visually check the beamformer against the textbooks. The results were pretty rad, so I figured I d throw together a post since it s interesting all on its own outside of beamforming as a general topic. I figured I d write this in Rust, since I ve been using Rust as my primary language over at zoo, and it s a good chance to learn the language better.
This post has some large GIFs

It make take a little bit to load depending on your internet connection. Sorry about that, I'm not clever enough to do better without doing tons of complex engineering work. They may be choppy while they load or something. I tried to compress an ensmall them, so if they're loaded but fuzzy, click on them to load a slightly larger version.
This post won t cover the basics of how phased arrays work or the specifics of calculating the phase offsets for each antenna, but I ll dig into how I wrote a simple simulator and how I wound up checking my phase offsets to generate the renders below.

Assumptions I didn t want to build a general purpose RF simulator, anything particularly generic, or something that would solve for any more than the things right in front of me. To do this as simply (and quickly all this code took about a day to write, including the beamforming math) I had to reduce the amount of work in front of me. Given that I was concerend with visualizing what the antenna pattern would look like in 3-D given some antenna geometry, operating frequency and configured beam, I made the following assumptions: All anetnnas are perfectly isotropic they receive a signal that is exactly the same strength no matter what direction the signal originates from. There s a single point-source isotropic emitter in the far-field (I modeled this as being 1 million meters away 1000 kilometers) of the antenna system. There is no noise, multipath, loss or distortion in the signal as it travels through space. Antennas will never interfere with each other.

2-D Polar Plots The last time I wrote something like this, I generated 2-D GIFs which show a radiation pattern, not unlike the polar plots you d see on a microphone. These are handy because it lets you visualize what the directionality of the antenna looks like, as well as in what direction emissions are captured, and in what directions emissions are nulled out. You can see these plots on spec sheets for antennas in both 2-D and 3-D form. Now, let s port the 2-D approach to 3-D and see how well it works out.

Writing the 3-D simulator As an EM wave travels through free space, the place at which you sample the wave controls that phase you observe at each time-step. This means, assuming perfectly synchronized clocks, a transmitter and receiver exactly one RF wavelength apart will observe a signal in-phase, but a transmitter and receiver a half wavelength apart will observe a signal 180 degrees out of phase. This means that if we take the distance between our point-source and antenna element, divide it by the wavelength, we can use the fractional part of the resulting number to determine the phase observed. If we multiply that number (in the range of 0 to just under 1) by tau, we can generate a complex number by taking the cos and sin of the multiplied phase (in the range of 0 to tau), assuming the transmitter is emitting a carrier wave at a static amplitude and all clocks are in perfect sync.
 let observed_phases: Vec<Complex> = antennas
.iter()
.map( antenna   
let distance = (antenna - tx).magnitude();
let distance = distance - (distance as i64 as f64);
((distance / wavelength) * TAU)
 )
.map( phase  Complex(phase.cos(), phase.sin()))
.collect();
At this point, given some synthetic transmission point and each antenna, we know what the expected complex sample would be at each antenna. At this point, we can adjust the phase of each antenna according to the beamforming phase offset configuration, and add up every sample in order to determine what the entire system would collectively produce a sample as.
 let beamformed_phases: Vec<Complex> = ...;
let magnitude = beamformed_phases
.iter()
.zip(observed_phases.iter())
.map( (beamformed, observed)  observed * beamformed)
.reduce( acc, el  acc + el)
.unwrap()
.abs();
Armed with this information, it s straight forward to generate some number of (Azimuth, Elevation) points to sample, generate a transmission point far away in that direction, resolve what the resulting Complex sample would be, take its magnitude, and use that to create an (x, y, z) point at (azimuth, elevation, magnitude). The color attached two that point is based on its distance from (0, 0, 0). I opted to use the Life Aquatic table for this one. After this process is complete, I have a point cloud of ((x, y, z), (r, g, b)) points. I wrote a small program using kiss3d to render point cloud using tons of small spheres, and write out the frames to a set of PNGs, which get compiled into a GIF. Now for the fun part, let s take a look at some radiation patterns!

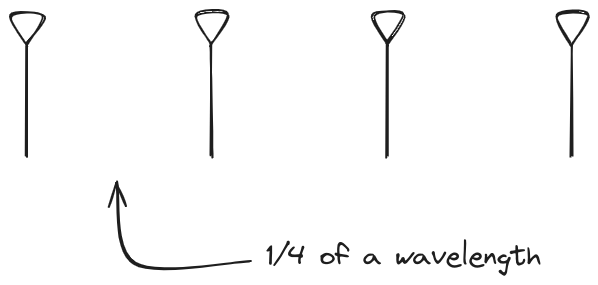
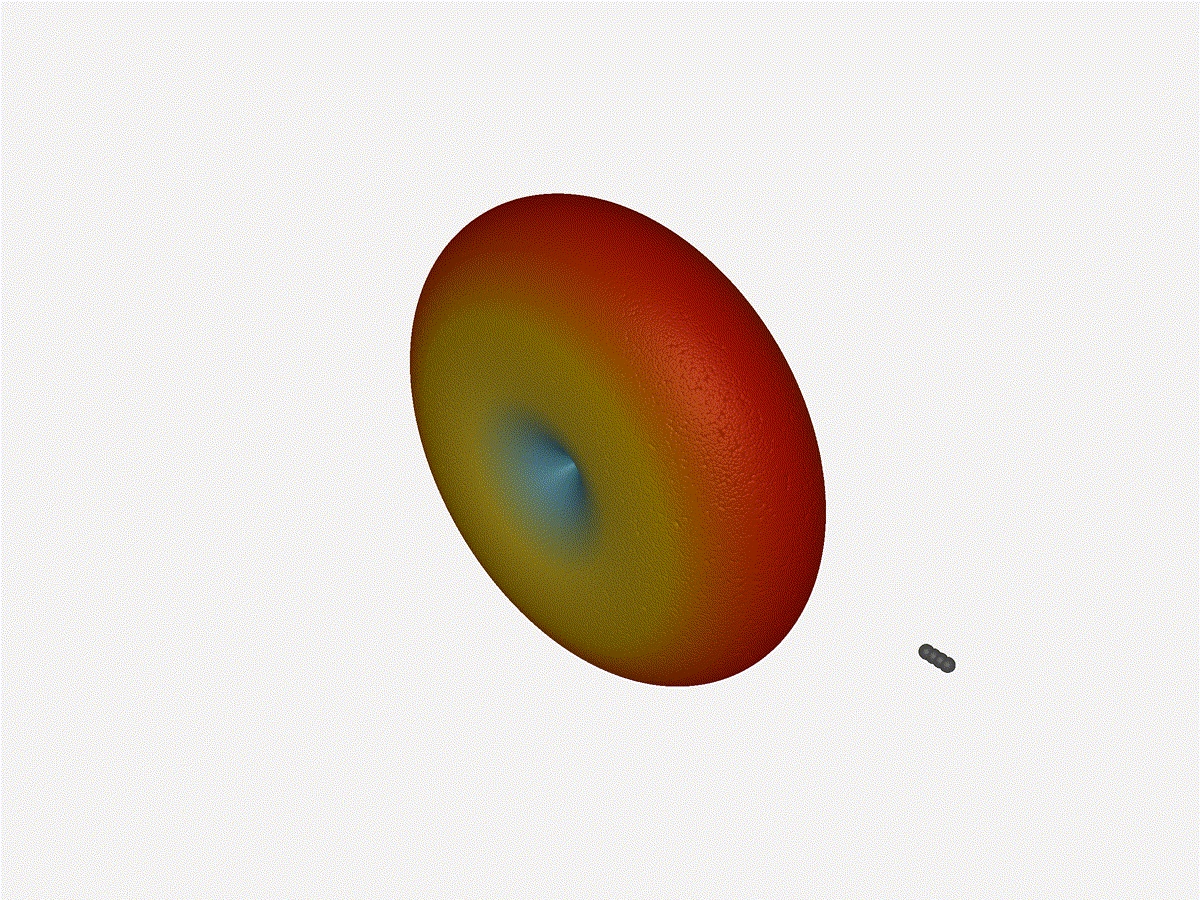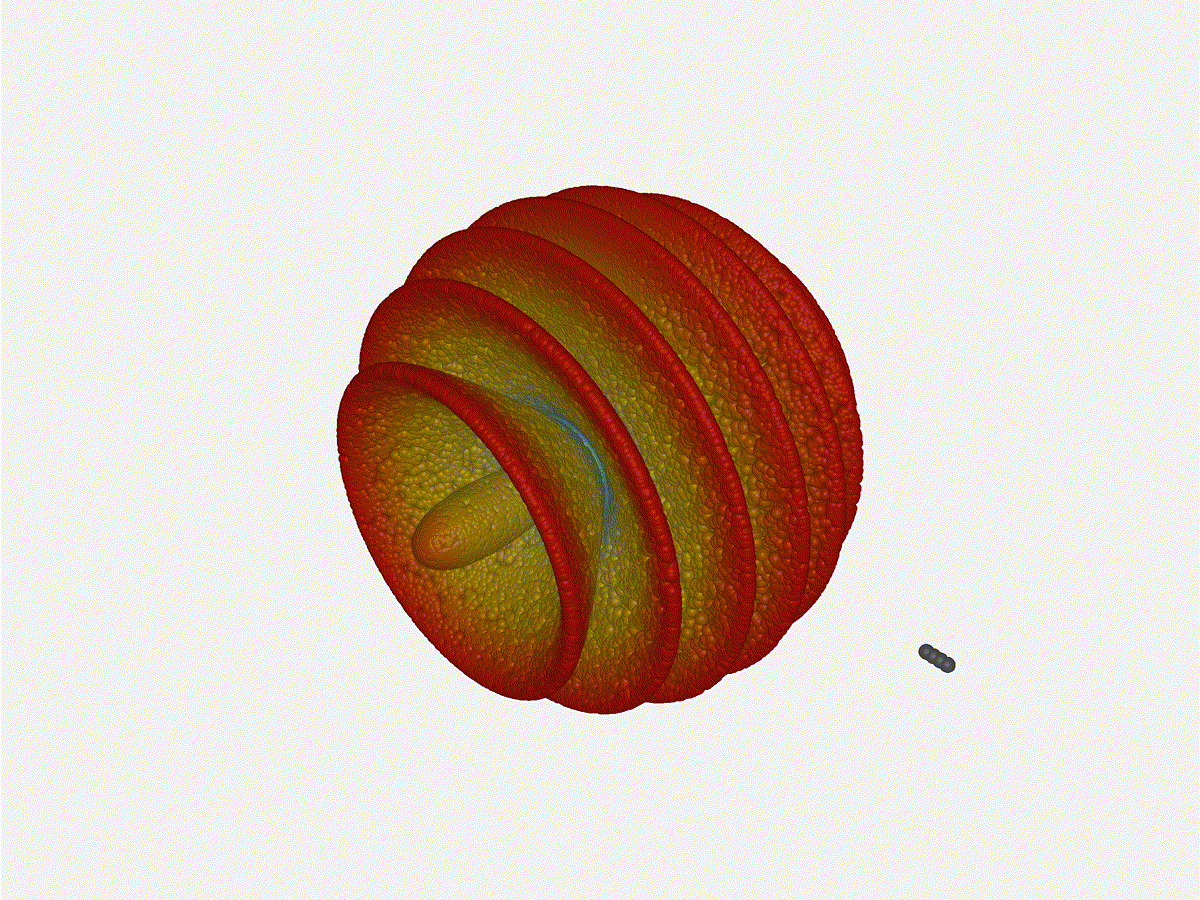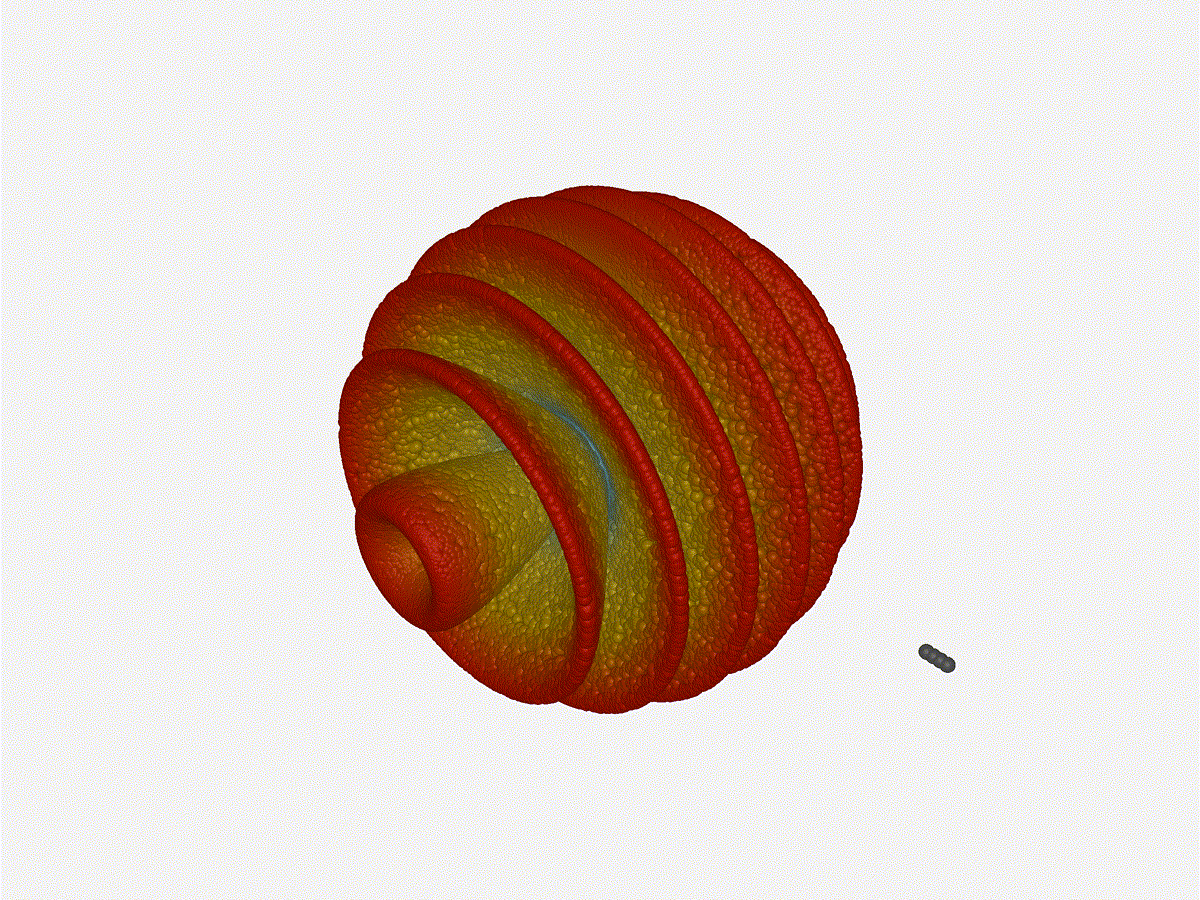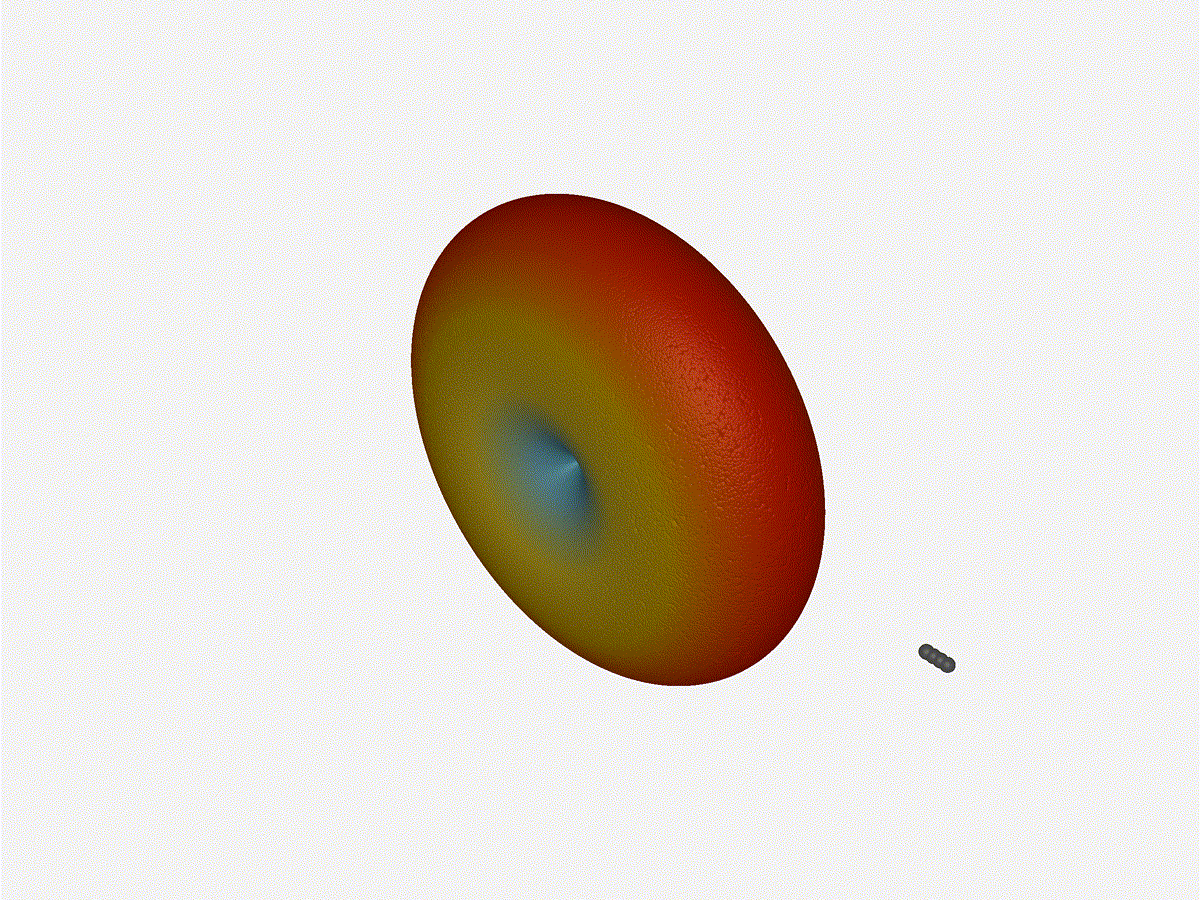
1x4 Phased Array The first configuration is a phased array where all the elements are in perfect alignment on the y and z axis, and separated by some offset in the x axis. This configuration can sweep 180 degrees (not the full 360), but can t be steared in elevation at all. Let s take a look at what this looks like for a well constructed 1x4 phased array: And now let s take a look at the renders as we play with the configuration of this array and make sure things look right. Our initial quarter-wavelength spacing is very effective and has some outstanding performance characteristics. Let s check to see that everything looks right as a first test. Nice. Looks perfect. When pointing forward at (0, 0), we d expect to see a torus, which we do. As we sweep between 0 and 360, astute observers will notice the pattern is mirrored along the axis of the antennas, when the beam is facing forward to 0 degrees, it ll also receive at 180 degrees just as strong. There s a small sidelobe that forms when it s configured along the array, but it also becomes the most directional, and the sidelobes remain fairly small.
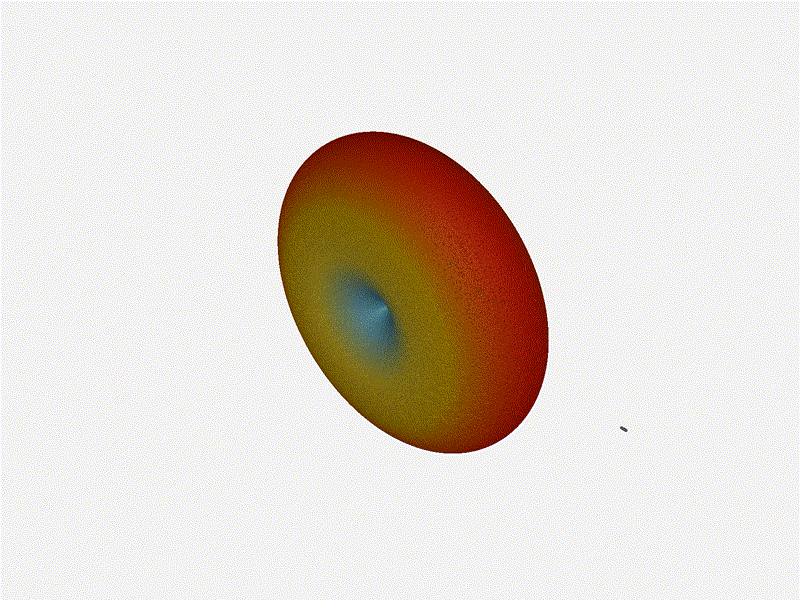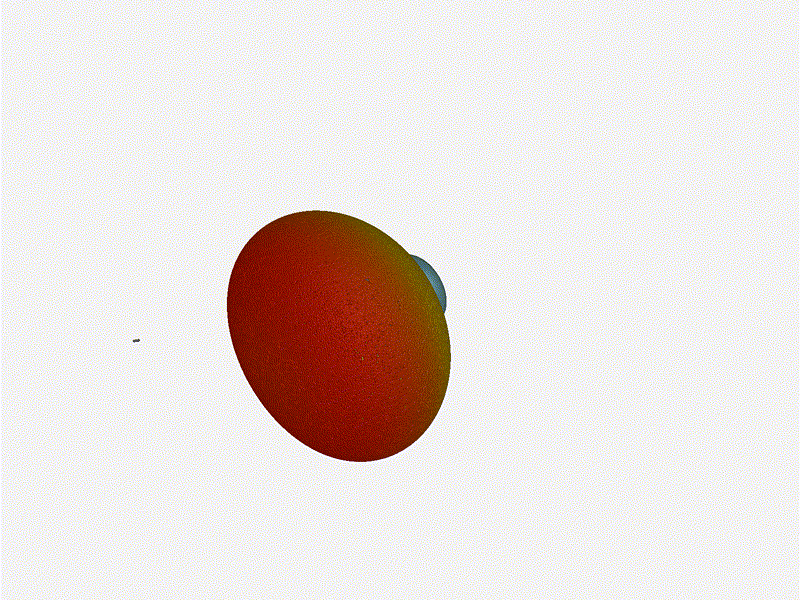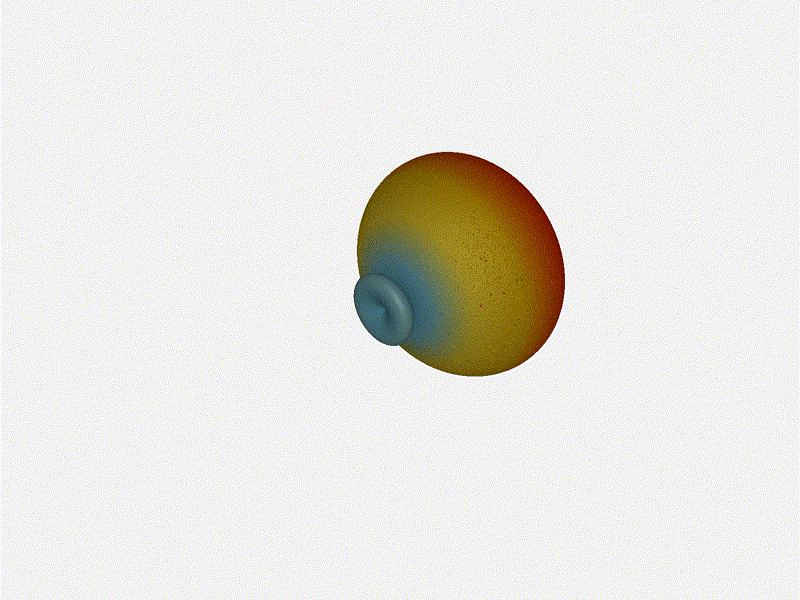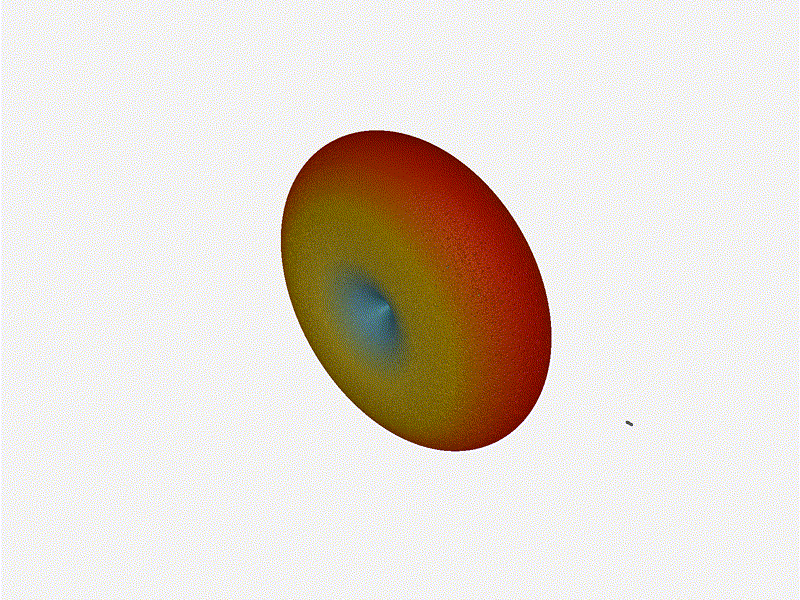
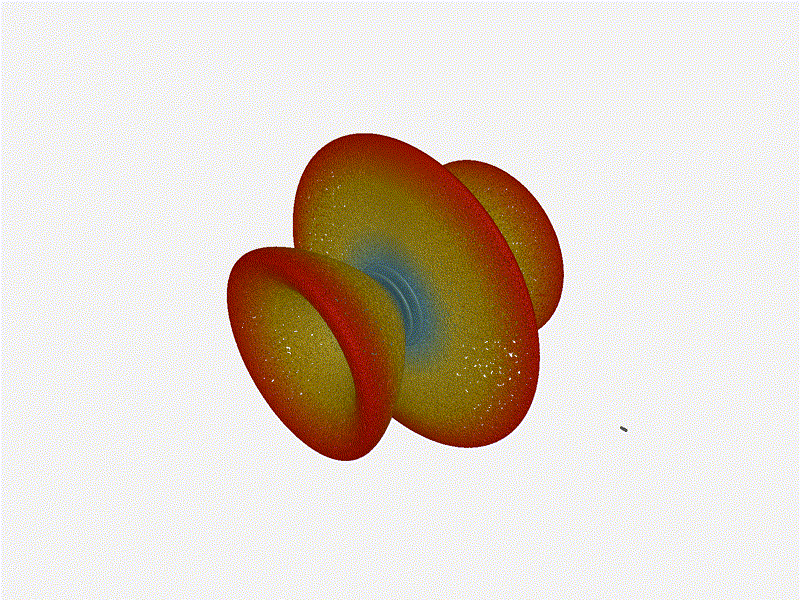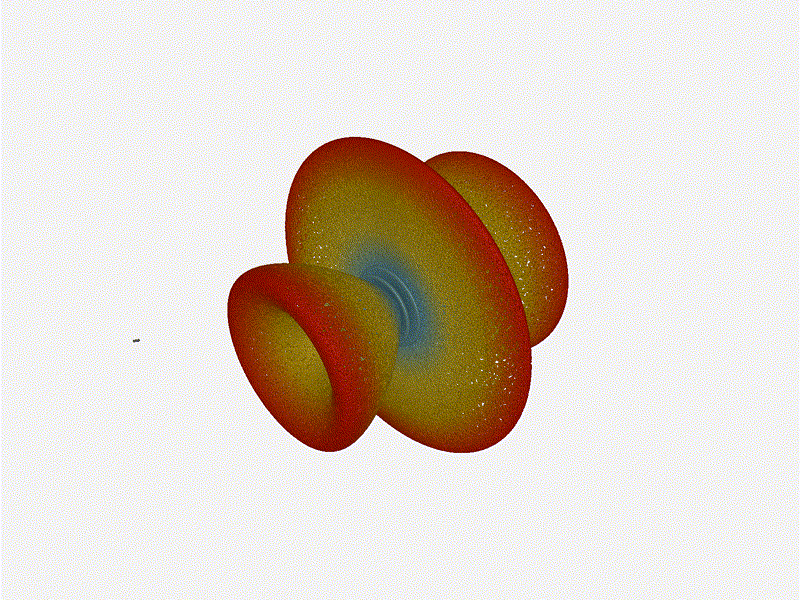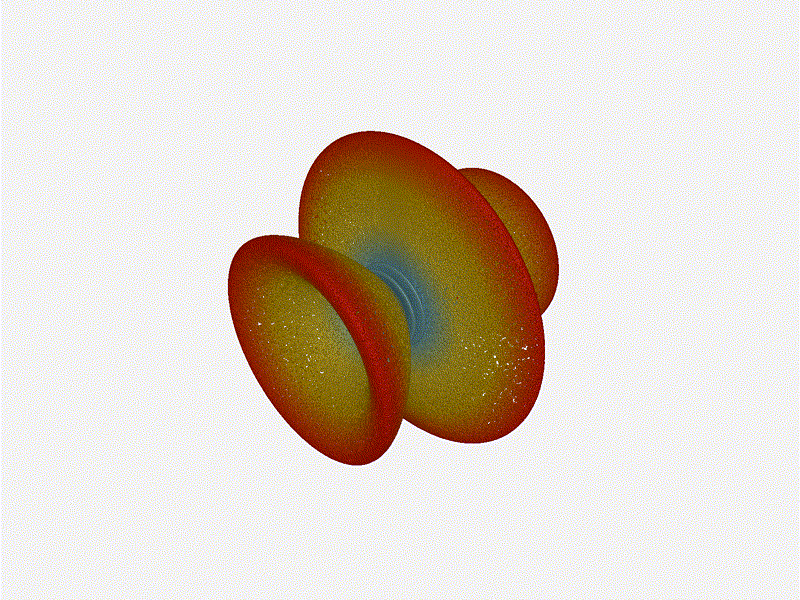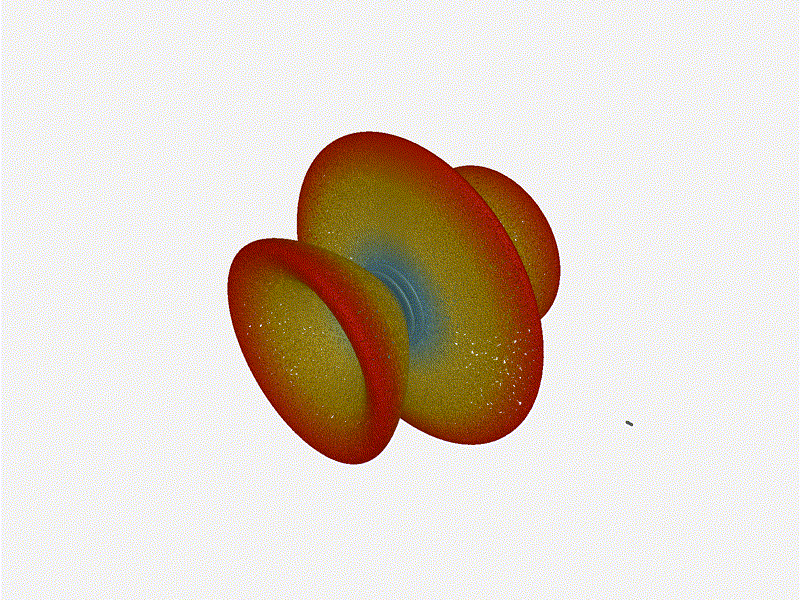
Long compared to the wavelength (1 ) Let s try again, but rather than spacing each antenna of a wavelength apart, let s see about spacing each antenna 1 of a wavelength apart instead. The main lobe is a lot more narrow (not a bad thing!), but some significant sidelobes have formed (not ideal). This can cause a lot of confusion when doing things that require a lot of directional resolution unless they re compensated for.
Going from ( to 5 ) The last model begs the question - what do things look like when you separate the antennas from each other but without moving the beam? Let s simulate moving our antennas but not adjusting the configured beam or operating frequency. Very cool. As the spacing becomes longer in relation to the operating frequency, we can see the sidelobes start to form out of the end of the antenna system.

2x2 Phased Array The second configuration I want to try is a phased array where the elements are in perfect alignment on the z axis, and separated by a fixed offset in either the x or y axis by their neighbor, forming a square when viewed along the x/y axis. Let s take a look at what this looks like for a well constructed 2x2 phased array: Let s do the same as above and take a look at the renders as we play with the configuration of this array and see what things look like. This configuration should suppress the sidelobes and give us good performance, and even give us some amount of control in elevation while we re at it. Sweet. Heck yeah. The array is quite directional in the configured direction, and can even sweep a little bit in elevation, a definite improvement from the 1x4 above.
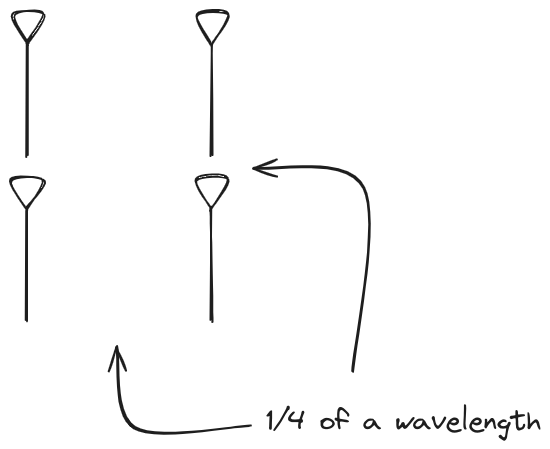
Long compared to the wavelength (1 ) Let s do the same thing as the 1x4 and take a look at what happens when the distance between elements is long compared to the frequency of operation say, 1 of a wavelength apart? What happens to the sidelobes given this spacing when the frequency of operation is much different than the physical geometry? Mesmerising. This is my favorate render. The sidelobes are very fun to watch come in and out of existence. It looks absolutely other-worldly.
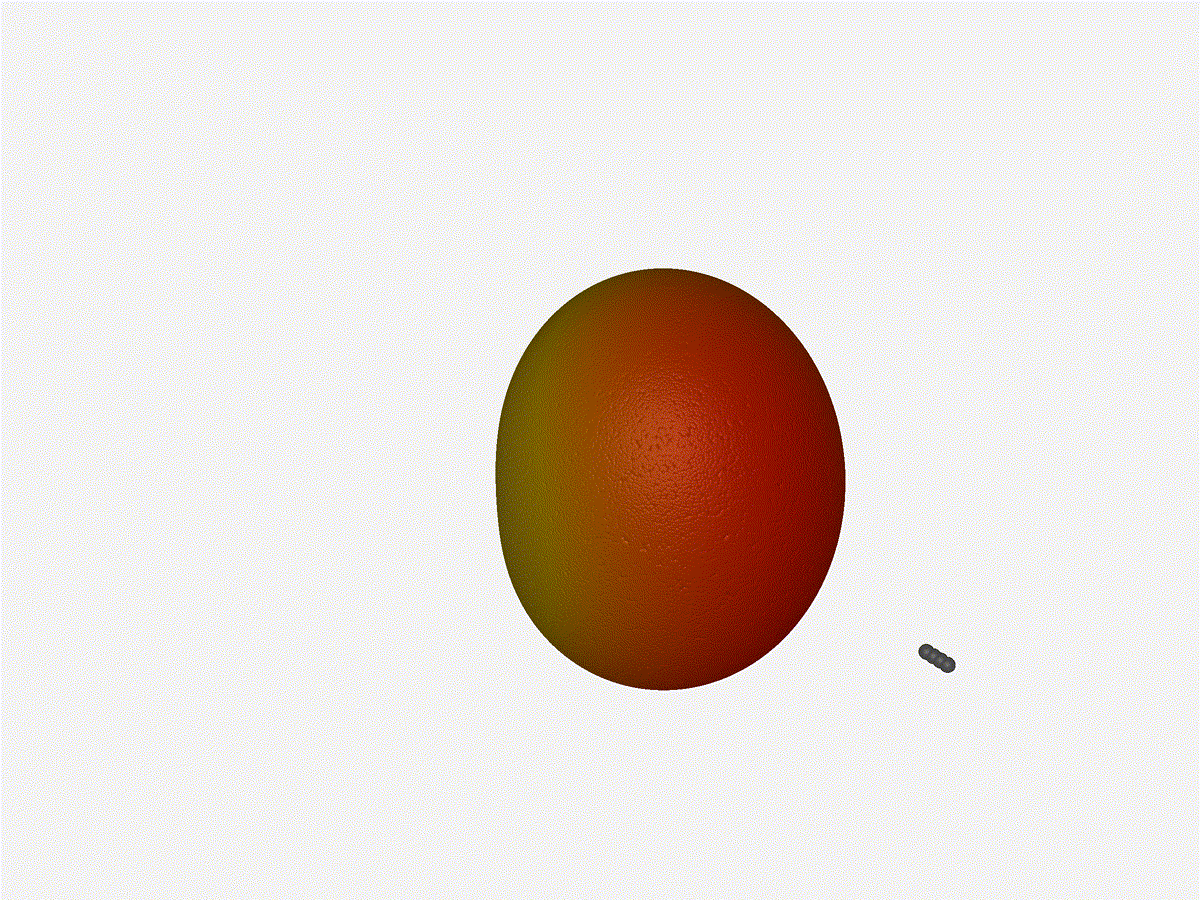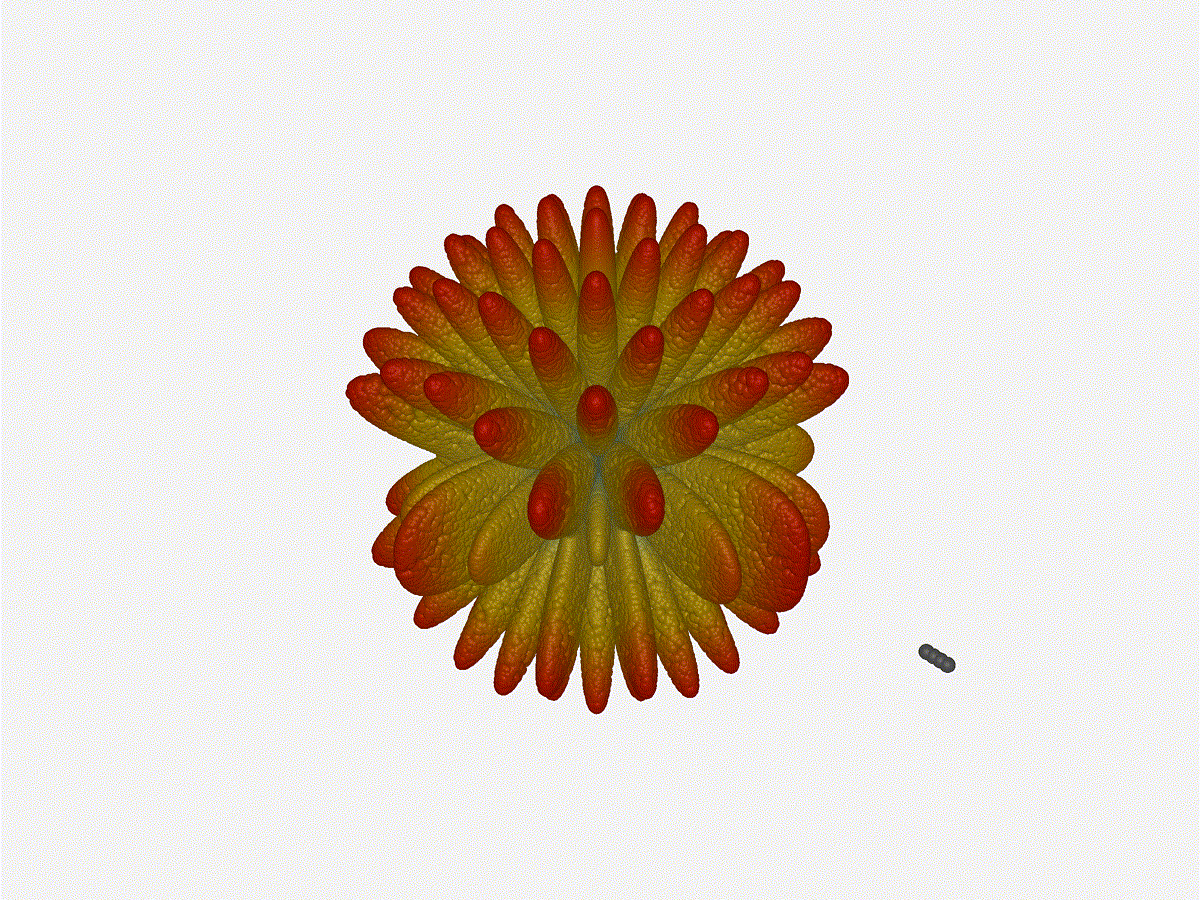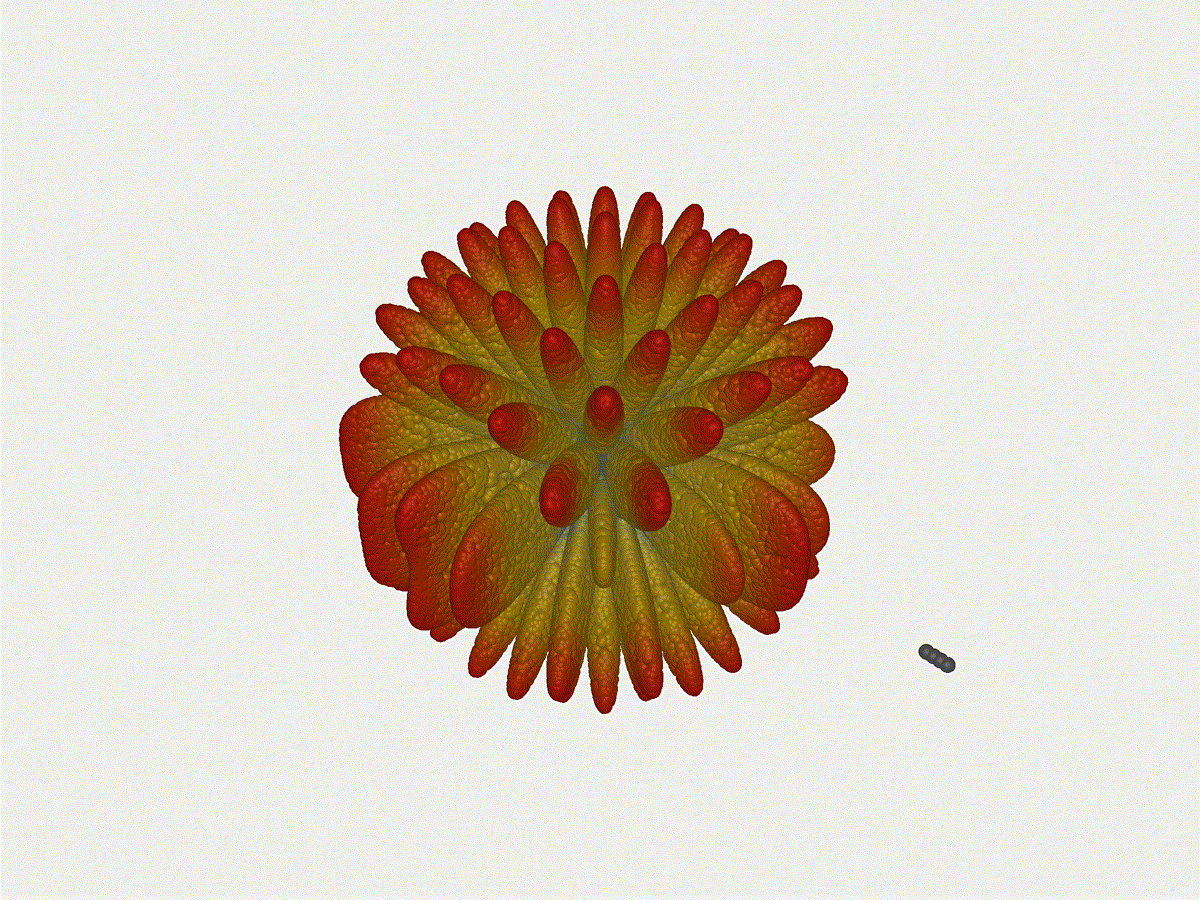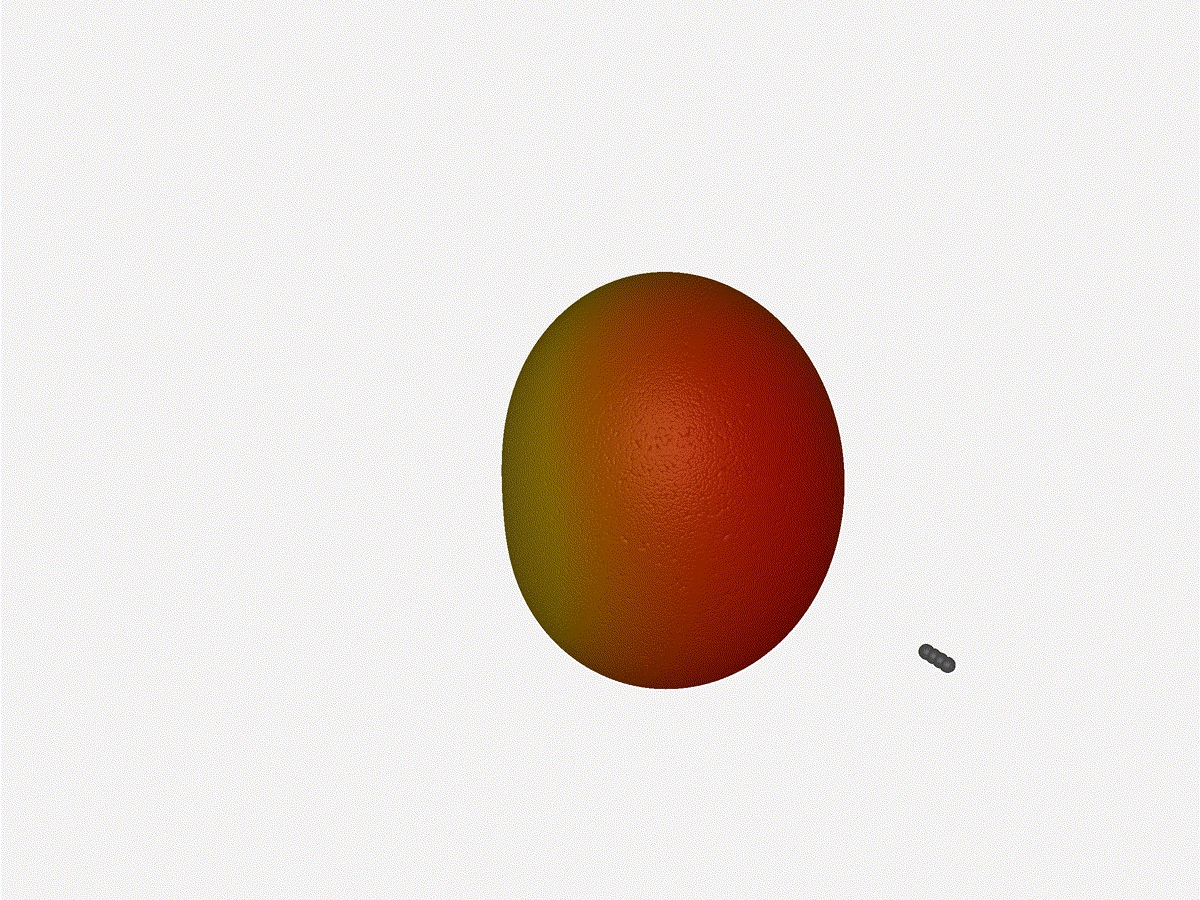
Going from ( to 5 ) Finally, for completeness' sake, what do things look like when you separate the antennas from each other just as we did with the 1x4? Let s simulate moving our antennas but not adjusting the configured beam or operating frequency. Very very cool. The sidelobes wind up turning the very blobby cardioid into an electromagnetic dog toy. I think we ve proven to ourselves that using a phased array much outside its designed frequency of operation seems like a real bad idea.

Future Work Now that I have a system to test things out, I m a bit more confident that my beamforming code is close to right! I d love to push that code over the line and blog about it, since it s a really interesting topic on its own. Once I m sure the code involved isn t full of lies, I ll put it up on the hztools org, and post about it here and on mastodon.

Russell Coker: Storage Trends 2024

It has been less than a year since my last post about storage trends [1] and enough has changed to make it worth writing again. My previous analysis was that for <2TB only SSD made sense, for 4TB SSD made sense for business use while hard drives were still a good option for home use, and for 8TB+ hard drives were clearly the best choice for most uses. I will start by looking at MSY prices, they aren't the cheapest (you can get cheaper online) but they are competitive and they make it easy to compare the different options. I'll also compare the cheapest options in each size, there are more expensive options but usually if you want to pay more then the performance benefits of SSD (both SATA and NVMe) are even more appealing. All prices are in Australian dollars and of parts that are readily available in Australia, but the relative prices of the parts are probably similar in most countries. The main issue here is when to use SSD and when to use hard disks, and then if SSD is chosen which variety to use. Small Storage For my last post the cheapest storage devices from MSY were $19 for a 128G SSD, now it s $24 for a 128G SSD or NVMe device. I don t think the Australian dollar has dropped much against foreign currencies, so I guess this is partly companies wanting more profits and partly due to the demand for more storage. Items that can t sell in quantity need higher profit margins if they are to have them in stock. 500G SSDs are around $33 and 500G NVMe devices for $36 so for most use cases it wouldn t make sense to buy anything smaller than 500G. The cheapest hard drive is $45 for a 1TB disk. A 1TB SATA SSD costs $61 and a 1TB NVMe costs $79. So 1TB disks aren t a good option for any use case. A 2TB hard drive is $89. A 2TB SATA SSD is $118 and a 2TB NVMe is $145. I don t think the small savings you can get from using hard drives makes them worth using for 2TB. For most people if you have a system that s important to you then $145 on storage isn t a lot to spend. It seems hardly worth buying less than 2TB of storage, even for a laptop. Even if you don t use all the space larger storage devices tend to support more writes before wearing out so you still gain from it. A 2TB NVMe device you buy for a laptop now could be used in every replacement laptop for the next 10 years. I only have 512G of storage in my laptop because I have a collection of SSD/NVMe devices that have been replaced in larger systems, so the 512G is essentially free for my laptop as I bought a larger device for a server. For small business use it doesn t make sense to buy anything smaller than 2TB for any system other than a router. If you buy smaller devices then you will sometimes have to pay people to install bigger ones and when the price is $145 it s best to just pay that up front and be done with it. Medium Storage A 4TB hard drive is $135. A 4TB SATA SSD is $319 and a 4TB NVMe is $299. The prices haven t changed a lot since last year, but a small increase in hard drive prices and a small decrease in SSD prices makes SSD more appealing for this market segment. A common size range for home servers and small business servers is 4TB or 8TB of storage. To do that on SSD means about $600 for 4TB of RAID-1 or $900 for 8TB of RAID-5/RAID-Z. That s quite affordable for that use. For 8TB of less important storage a 8TB hard drive costs $239 and a 8TB SATA SSD costs $899 so a hard drive clearly wins for the specific case of non-RAID single device storage. Note that the U.2 devices are more competitive for 8TB than SATA but I included them in the next section because they are more difficult to install. Serious Storage With 8TB being an uncommon and expensive option for consumer SSDs the cheapest price is for multiple 4TB devices. To have multiple NVMe devices in one PCIe slot you need PCIe bifurcation (treating the PCIe slot as multiple slots). Most of the machines I use don t support bifurcation and most affordable systems with ECC RAM don t have it. For cheap NVMe type storage there are U.2 devices (the enterprise form of NVMe). Until recently they were too expensive to use for desktop systems but now there are PCIe cards for internal U.2 devices, $14 for a card that takes a single U.2 is a common price on AliExpress and prices below $600 for a 7.68TB U.2 device are common that s cheaper on a per-TB basis than SATA SSD and NVMe! There are PCIe cards that take up to 4*U.2 devices (which probably require bifurcation) which means you could have 8+ U.2 devices in one not particularly high end PC for 56TB of RAID-Z NVMe storage. Admittedly $4200 for 56TB is moderately expensive, but it s in the price range for a small business server or a high end home server. A more common configuration might be 2*7.68TB U.2 on a single PCIe card (or 2 cards if you don t have bifurcation) for 7.68TB of RAID-1 storage. For SATA SSD AliExpress has a 6*2.5 hot-swap device that fits in a 5.25 bay for $63, so if you have 2*5.25 bays you could have 12*4TB SSDs for 44TB of RAID-Z storage. That wouldn t be much cheaper than 8*7.68TB U.2 devices and would be slower and have less space. But it would be a good option if PCIe bifurcation isn t possible. 16TB SATA hard drives cost $559 which is almost exactly half the price per TB of U.2 storage. That doesn t seem like a good deal. If you want 16TB of RAID storage then 3*7.68TB U.2 devices only costs about 50% more than 2*16TB SATA disks. In most cases paying 50% more to get NVMe instead of hard disks is a good option. As sizes go above 16TB prices go up in a more than linear manner, I guess they don t sell much volume of larger drives. 15.36TB U.2 devices are on sale for about $1300, slightly more than twice the price of a 16TB disk. It s within the price range of small businesses and serious home users. Also it should be noted that the U.2 devices are designed for enterprise levels of reliability and the hard disk prices I m comparing to are the cheapest available. If NAS hard disks were compared then the price benefit of hard disks would be smaller. Probably the biggest problem with U.2 for most people is that it s an uncommon technology that few people have much experience with or spare parts for testing. Also you can t buy U.2 gear at your local computer store which might mean that you want to have spare parts on hand which is an extra expense. For enterprise use I ve recently been involved in discussions with a vendor that sells multiple petabyte arrays of NVMe. Apparently NVMe is cheap enough that there s no need to use anything else if you want a well performing file server. Do Hard Disks Make Sense? There are specific cases like comparing a 8TB hard disk to a 8TB SATA SSD or a 16TB hard disk to a 15.36TB U.2 device where hard disks have an apparent advantage. But when comparing RAID storage and counting the performance benefits of SSD the savings of using hard disks don t seem to be that great. Is now the time that hard disks are going to die in the market? If they can t get volume sales then prices will go up due to lack of economy of scale in manufacture and increased stock time for retailers. 8TB hard drives are now more expensive than they were 9 months ago when I wrote my previous post, has a hard drive price death spiral already started? SSDs are cheaper than hard disks at the smallest sizes, faster (apart from some corner cases with contiguous IO), take less space in a computer, and make less noise. At worst they are a bit over twice the cost per TB. But the most common requirements for storage are small enough and cheap enough that being twice as expensive as hard drives isn t a problem for most people. I predict that hard disks will become less popular in future and offer less of a price advantage. The vendors are talking about 50TB hard disks being available in future but right now you can fit more than 50TB of NVMe or U.2 devices in a volume less than that of a 3.5 hard disk so for storage density SSD can clearly win. Maybe in future hard disks will be used in arrays of 100TB devices for large scale enterprise storage. But for home users and small businesses the current sizes of SSD cover most uses. At the moment it seems that the one case where hard disks can really compare well is for backup devices. For backups you want large storage, good contiguous write speeds, and low prices so you can buy plenty of them. Further Issues The prices I ve compared for SATA SSD and NVMe devices are all based on the cheapest devices available. I think it s a bit of a market for lemons [2] as devices often don t perform as well as expected and the incidence of fake products purporting to be from reputable companies is high on the cheaper sites. So you might as well buy the cheaper devices. An advantage of the U.2 devices is that you know that they will be reliable and perform well. One thing that concerns me about SSDs is the lack of knowledge of their failure cases. Filesystems like ZFS were specifically designed to cope with common failure cases of hard disks and I don t think we have that much knowledge about how SSDs fail. But with 3 copies of metadata BTFS or ZFS should survive unexpected SSD failure modes. I still have some hard drives in my home server, they keep working well enough and the prices on SSDs keep dropping. But if I was buying new storage for such a server now I d get U.2. I wonder if tape will make a comeback for backup. Does anyone know of other good storage options that I missed?

20 January 2024

Gunnar Wolf: A deep learning technique for intrusion detection system using a recurrent neural networks based framework

This post is a review for Computing Reviews for A deep learning technique for intrusion detection system using a recurrent neural networks based framework , a article published in Computer Communications
So let s assume you already know and understand that artificial intelligence s main building blocks are perceptrons, that is, mathematical models of neurons. And you know that, while a single perceptron is too limited to get interesting information from, very interesting structures neural networks can be built with them. You also understand that neural networks can be trained with large datasets, and you can get them to become quite efficient and accurate classifiers for data comparable to your dataset. Finally, you are interested in applying this knowledge to defensive network security, particularly in choosing the right recurrent neural network (RNN) framework to create an intrusion detection system (IDS). Are you still with me? Good! This paper might be right for you! The paper builds on a robust and well-written introduction and related work sections to arrive at explaining in detail what characterizes a RNN, the focus of this work, among other configurations also known as neural networks, and why they are particularly suited for machine learning (ML) tasks. RNNs must be trained for each problem domain, and publicly available datasets are commonly used for such tasks. The authors present two labeled datasets representing normal and hostile network data, identified according to different criteria: NSL-KDD and UNSW-NB15. They proceed to show a framework to analyze and compare different RNNs and run them against said datasets, segmented for separate training and validation phases, compare results, and finally select the best available model for the task measuring both training speed as well as classification accuracy. The paper is quite heavy due to both its domain-specific terminology many acronyms are used throughout the text and its use of mathematical notation, both to explain specific properties of each of the RNN types and for explaining the preprocessing carried out for feature normalization and selection. This is partly what led me to start the first paragraph by assuming that we, as readers, already understand a large body of material if we are to fully follow the text. The paper does begin by explaining its core technologies, but quickly ramps up and might get too technical for nonexpert readers. It is undeniably an interesting and valuable read, showing the state of the art in IDS and ML-assisted technologies. It does not detail any specific technology applying its findings, but we will probably find the information conveyed here soon enough in industry publications.

Niels Thykier: Making debputy: Writing declarative parsing logic

In this blog post, I will cover how debputy parses its manifest and the conceptual improvements I did to make parsing of the manifest easier. All instructions to debputy are provided via the debian/debputy.manifest file and said manifest is written in the YAML format. After the YAML parser has read the basic file structure, debputy does another pass over the data to extract the information from the basic structure. As an example, the following YAML file:
manifest-version: "0.1"
installations:
  - install:
      source: foo
      dest-dir: usr/bin
would be transformed by the YAML parser into a structure resembling:
 
  "manifest-version": "0.1",
  "installations": [
      
       "install":  
         "source": "foo",
         "dest-dir": "usr/bin",
        
      
  ]
 
This structure is then what debputy does a pass on to translate this into an even higher level format where the "install" part is translated into an InstallRule. In the original prototype of debputy, I would hand-write functions to extract the data that should be transformed into the internal in-memory high level format. However, it was quite tedious. Especially because I wanted to catch every possible error condition and report "You are missing the required field X at Y" rather than the opaque KeyError: X message that would have been the default. Beyond being tedious, it was also quite error prone. As an example, in debputy/0.1.4 I added support for the install rule and you should allegedly have been able to add a dest-dir: or an as: inside it. Except I crewed up the code and debputy was attempting to look up these keywords from a dict that could never have them. Hand-writing these parsers were so annoying that it demotivated me from making manifest related changes to debputy simply because I did not want to code the parsing logic. When I got this realization, I figured I had to solve this problem better. While reflecting on this, I also considered that I eventually wanted plugins to be able to add vocabulary to the manifest. If the API was "provide a callback to extract the details of whatever the user provided here", then the result would be bad.
  1. Most plugins would probably throw KeyError: X or ValueError style errors for quite a while. Worst case, they would end on my table because the user would have a hard time telling where debputy ends and where the plugins starts. "Best" case, I would teach debputy to say "This poor error message was brought to you by plugin foo. Go complain to them". Either way, it would be a bad user experience.
  2. This even assumes plugin providers would actually bother writing manifest parsing code. If it is that difficult, then just providing a custom file in debian might tempt plugin providers and that would undermine the idea of having the manifest be the sole input for debputy.
So beyond me being unsatisfied with the current situation, it was also clear to me that I needed to come up with a better solution if I wanted externally provided plugins for debputy. To put a bit more perspective on what I expected from the end result:
  1. It had to cover as many parsing errors as possible. An error case this code would handle for you, would be an error where I could ensure it sufficient degree of detail and context for the user.
  2. It should be type-safe / provide typing support such that IDEs/mypy could help you when you work on the parsed result.
  3. It had to support "normalization" of the input, such as
           # User provides
           - install: "foo"
           # Which is normalized into:
           - install:
               source: "foo"
4) It must be simple to tell  debputy  what input you expected.
At this point, I remembered that I had seen a Python (PYPI) package where you could give it a TypedDict and an arbitrary input (Sadly, I do not remember the name). The package would then validate the said input against the TypedDict. If the match was successful, you would get the result back casted as the TypedDict. If the match was unsuccessful, the code would raise an error for you. Conceptually, this seemed to be a good starting point for where I wanted to be. Then I looked a bit on the normalization requirement (point 3). What is really going on here is that you have two "schemas" for the input. One is what the programmer will see (the normalized form) and the other is what the user can input (the manifest form). The problem is providing an automatic normalization from the user input to the simplified programmer structure. To expand a bit on the following example:
# User provides
- install: "foo"
# Which is normalized into:
- install:
    source: "foo"
Given that install has the attributes source, sources, dest-dir, as, into, and when, how exactly would you automatically normalize "foo" (str) into source: "foo"? Even if the code filtered by "type" for these attributes, you would end up with at least source, dest-dir, and as as candidates. Turns out that TypedDict actually got this covered. But the Python package was not going in this direction, so I parked it here and started looking into doing my own. At this point, I had a general idea of what I wanted. When defining an extension to the manifest, the plugin would provide debputy with one or two definitions of TypedDict. The first one would be the "parsed" or "target" format, which would be the normalized form that plugin provider wanted to work on. For this example, lets look at an earlier version of the install-examples rule:
# Example input matching this typed dict.
#    
#       "source": ["foo"]
#       "into": ["pkg"]
#    
class InstallExamplesTargetFormat(TypedDict):
    # Which source files to install (dest-dir is fixed)
    sources: List[str]
    # Which package(s) that should have these files installed.
    into: NotRequired[List[str]]
In this form, the install-examples has two attributes - both are list of strings. On the flip side, what the user can input would look something like this:
# Example input matching this typed dict.
#    
#       "source": "foo"
#       "into": "pkg"
#    
#
class InstallExamplesManifestFormat(TypedDict):
    # Note that sources here is split into source (str) vs. sources (List[str])
    sources: NotRequired[List[str]]
    source: NotRequired[str]
    # We allow the user to write  into: foo  in addition to  into: [foo] 
    into: Union[str, List[str]]
FullInstallExamplesManifestFormat = Union[
    InstallExamplesManifestFormat,
    List[str],
    str,
]
The idea was that the plugin provider would use these two definitions to tell debputy how to parse install-examples. Pseudo-registration code could look something like:
def _handler(
    normalized_form: InstallExamplesTargetFormat,
) -> InstallRule:
    ...  # Do something with the normalized form and return an InstallRule.
concept_debputy_api.add_install_rule(
  keyword="install-examples",
  target_form=InstallExamplesTargetFormat,
  manifest_form=FullInstallExamplesManifestFormat,
  handler=_handler,
)
This was my conceptual target and while the current actual API ended up being slightly different, the core concept remains the same.
From concept to basic implementation Building this code is kind like swallowing an elephant. There was no way I would just sit down and write it from one end to the other. So the first prototype of this did not have all the features it has now. Spoiler warning, these next couple of sections will contain some Python typing details. When reading this, it might be helpful to know things such as Union[str, List[str]] being the Python type for either a str (string) or a List[str] (list of strings). If typing makes your head spin, these sections might less interesting for you. To build this required a lot of playing around with Python's introspection and typing APIs. My very first draft only had one "schema" (the normalized form) and had the following features:
  • Read TypedDict.__required_attributes__ and TypedDict.__optional_attributes__ to determine which attributes where present and which were required. This was used for reporting errors when the input did not match.
  • Read the types of the provided TypedDict, strip the Required / NotRequired markers and use basic isinstance checks based on the resulting type for str and List[str]. Again, used for reporting errors when the input did not match.
This prototype did not take a long (I remember it being within a day) and worked surprisingly well though with some poor error messages here and there. Now came the first challenge, adding the manifest format schema plus relevant normalization rules. The very first normalization I did was transforming into: Union[str, List[str]] into into: List[str]. At that time, source was not a separate attribute. Instead, sources was a Union[str, List[str]], so it was the only normalization I needed for all my use-cases at the time. There are two problems when writing a normalization. First is determining what the "source" type is, what the target type is and how they relate. The second is providing a runtime rule for normalizing from the manifest format into the target format. Keeping it simple, the runtime normalizer for Union[str, List[str]] -> List[str] was written as:
def normalize_into_list(x: Union[str, List[str]]) -> List[str]:
    return x if isinstance(x, list) else [x]
This basic form basically works for all types (assuming none of the types will have List[List[...]]). The logic for determining when this rule is applicable is slightly more involved. My current code is about 100 lines of Python code that would probably lose most of the casual readers. For the interested, you are looking for _union_narrowing in declarative_parser.py With this, when the manifest format had Union[str, List[str]] and the target format had List[str] the generated parser would silently map a string into a list of strings for the plugin provider. But with that in place, I had covered the basics of what I needed to get started. I was quite excited about this milestone of having my first keyword parsed without handwriting the parser logic (at the expense of writing a more generic parse-generator framework).
Adding the first parse hint With the basic implementation done, I looked at what to do next. As mentioned, at the time sources in the manifest format was Union[str, List[str]] and I considered to split into a source: str and a sources: List[str] on the manifest side while keeping the normalized form as sources: List[str]. I ended up committing to this change and that meant I had to solve the problem getting my parser generator to understand the situation:
# Map from
class InstallExamplesManifestFormat(TypedDict):
    # Note that sources here is split into source (str) vs. sources (List[str])
    sources: NotRequired[List[str]]
    source: NotRequired[str]
    # We allow the user to write  into: foo  in addition to  into: [foo] 
    into: Union[str, List[str]]
# ... into
class InstallExamplesTargetFormat(TypedDict):
    # Which source files to install (dest-dir is fixed)
    sources: List[str]
    # Which package(s) that should have these files installed.
    into: NotRequired[List[str]]
There are two related problems to solve here:
  1. How will the parser generator understand that source should be normalized and then mapped into sources?
  2. Once that is solved, the parser generator has to understand that while source and sources are declared as NotRequired, they are part of a exactly one of rule (since sources in the target form is Required). This mainly came down to extra book keeping and an extra layer of validation once the previous step is solved.
While working on all of this type introspection for Python, I had noted the Annotated[X, ...] type. It is basically a fake type that enables you to attach metadata into the type system. A very random example:
# For all intents and purposes,  foo  is a string despite all the  Annotated  stuff.
foo: Annotated[str, "hello world"] = "my string here"
The exciting thing is that you can put arbitrary details into the type field and read it out again in your introspection code. Which meant, I could add "parse hints" into the type. Some "quick" prototyping later (a day or so), I got the following to work:
# Map from
#      
#        "source": "foo"  # (or "sources": ["foo"])
#        "into": "pkg"
#      
class InstallExamplesManifestFormat(TypedDict):
    # Note that sources here is split into source (str) vs. sources (List[str])
    sources: NotRequired[List[str]]
    source: NotRequired[
        Annotated[
            str,
            DebputyParseHint.target_attribute("sources")
        ]
    ]
    # We allow the user to write  into: foo  in addition to  into: [foo] 
    into: Union[str, List[str]]
# ... into
#      
#        "source": ["foo"]
#        "into": ["pkg"]
#      
class InstallExamplesTargetFormat(TypedDict):
    # Which source files to install (dest-dir is fixed)
    sources: List[str]
    # Which package(s) that should have these files installed.
    into: NotRequired[List[str]]
Without me (as a plugin provider) writing a line of code, I can have debputy rename or "merge" attributes from the manifest form into the normalized form. Obviously, this required me (as the debputy maintainer) to write a lot code so other me and future plugin providers did not have to write it.
High level typing At this point, basic normalization between one mapping to another mapping form worked. But one thing irked me with these install rules. The into was a list of strings when the parser handed them over to me. However, I needed to map them to the actual BinaryPackage (for technical reasons). While I felt I was careful with my manual mapping, I knew this was exactly the kind of case where a busy programmer would skip the "is this a known package name" check and some user would typo their package resulting in an opaque KeyError: foo. Side note: "Some user" was me today and I was super glad to see debputy tell me that I had typoed a package name (I would have been more happy if I had remembered to use debputy check-manifest, so I did not have to wait through the upstream part of the build that happened before debhelper passed control to debputy...) I thought adding this feature would be simple enough. It basically needs two things:
  1. Conversion table where the parser generator can tell that BinaryPackage requires an input of str and a callback to map from str to BinaryPackage. (That is probably lie. I think the conversion table came later, but honestly I do remember and I am not digging into the git history for this one)
  2. At runtime, said callback needed access to the list of known packages, so it could resolve the provided string.
It was not super difficult given the existing infrastructure, but it did take some hours of coding and debugging. Additionally, I added a parse hint to support making the into conditional based on whether it was a single binary package. With this done, you could now write something like:
# Map from
class InstallExamplesManifestFormat(TypedDict):
    # Note that sources here is split into source (str) vs. sources (List[str])
    sources: NotRequired[List[str]]
    source: NotRequired[
        Annotated[
            str,
            DebputyParseHint.target_attribute("sources")
        ]
    ]
    # We allow the user to write  into: foo  in addition to  into: [foo] 
    into: Union[BinaryPackage, List[BinaryPackage]]
# ... into
class InstallExamplesTargetFormat(TypedDict):
    # Which source files to install (dest-dir is fixed)
    sources: List[str]
    # Which package(s) that should have these files installed.
    into: NotRequired[
        Annotated[
            List[BinaryPackage],
            DebputyParseHint.required_when_multi_binary()
        ]
    ]
Code-wise, I still had to check for into being absent and providing a default for that case (that is still true in the current codebase - I will hopefully fix that eventually). But I now had less room for mistakes and a standardized error message when you misspell the package name, which was a plus.
The added side-effect - Introspection A lovely side-effect of all the parsing logic being provided to debputy in a declarative form was that the generated parser snippets had fields containing all expected attributes with their types, which attributes were required, etc. This meant that adding an introspection feature where you can ask debputy "What does an install rule look like?" was quite easy. The code base already knew all of this, so the "hard" part was resolving the input the to concrete rule and then rendering it to the user. I added this feature recently along with the ability to provide online documentation for parser rules. I covered that in more details in my blog post Providing online reference documentation for debputy in case you are interested. :)
Wrapping it up This was a short insight into how debputy parses your input. With this declarative technique:
  • The parser engine handles most of the error reporting meaning users get most of the errors in a standard format without the plugin provider having to spend any effort on it. There will be some effort in more complex cases. But the common cases are done for you.
  • It is easy to provide flexibility to users while avoiding having to write code to normalize the user input into a simplified programmer oriented format.
  • The parser handles mapping from basic types into higher forms for you. These days, we have high level types like FileSystemMode (either an octal or a symbolic mode), different kind of file system matches depending on whether globs should be performed, etc. These types includes their own validation and parsing rules that debputy handles for you.
  • Introspection and support for providing online reference documentation. Also, debputy checks that the provided attribute documentation covers all the attributes in the manifest form. If you add a new attribute, debputy will remind you if you forget to document it as well. :)

In this way everybody wins. Yes, writing this parser generator code was more enjoyable than writing the ad-hoc manual parsers it replaced. :)

Thomas Koch: Know your tools - simple backup with rsync

Posted on June 9, 2022
I ve been using rsync for years and still did not know its full powers. I just wanted a quick and dirty simple backup but realised that rsnapshot is not in Debian anymore. However you can do much of rsnapshot with rsync alone nowadays. The --link-dest option (manpage) solves the part of creating hardlinks to a previous backup (found here). So my backup program becomes this shell script in ~/backups/backup.sh:
#!/bin/sh
SERVER="$ 1 "
BACKUP="$ HOME /backups/$ SERVER "
SNAPSHOTS="$ BACKUP /snapshots"
FOLDER=$(date --utc +%F_%H-%M-%S)
DEST="$ SNAPSHOTS /$ FOLDER "
LAST=$(ls -d1 $ SNAPSHOTS /????-??-??_??-??-?? tail -n 1)
rsync \
  --rsh="ssh -i $ BACKUP /sshkey -o ControlPath=none -o ForwardAgent=no" \
  -rlpt \
  --delete --link-dest="$ LAST " \
  $ SERVER ::backup "$ DEST "
The script connects to rsync in daemon mode as outlined in section USING RSYNC-DAEMON FEATURES VIA A REMOTE-SHELL CONNECTION in the rsync manpage. This allows to reference a module as the source that is defined on the server side as follows:
[backup]
path = /
read only = true
exclude from = /srv/rsyncbackup/excludelist
uid = root
gid = root
The important bit is the read only setting that protects the server against somebody with access to the ssh key to overwrit files on the server via rsync and thus gaining full root access. Finally the command prefix in ~/.ssh/authorized_keys runs rsync as daemon with sudo and the specified config file:
command="sudo rsync --config=/srv/rsyncbackup/config --server --daemon ."
The sudo setup is left as an exercise for the reader as mine is rather opinionated. Unfortunately I have not managed to configure systemd timers in the way I wanted and therefor opened an issue: Allow retry of timer triggered oneshot services with failed conditions or asserts . Any help there is welcome!

18 January 2024

Russell Coker: LicheePi 4A (RISC-V) First Look

I Just bought a LicheePi 4A RISC-V embedded computer (like a RaspberryPi but with a RISC-V CPU) for $322.68 from Aliexpress (the official site for buying LicheePi devices). Here is the Sipheed web page about it and their other recent offerings [1]. I got the version with 16G of RAM and 128G of storage, I probably don t need that much storage (I can use NFS or USB) but 16G of RAM is good for VMs. Here is the Wiki about this board [2]. Configuration When you get one of these devices you should make setting up ssh server your first priority. I found the HDMI output to be very unreliable. The first monitor I tried was a Samsung 4K monitor dating from when 4K was a new thing, the LicheePi initially refused to operate at a resolution higher than 1024*768 but later on switched to 4K resolution when resuming from screen-blank for no apparent reason (and the window manager didn t support this properly). On the Dell 4K monitor I use on my main workstation it sometimes refused to talk to it and occasionally worked. I got it running at 1920*1080 without problems and then switched it to 4K and it lost video sync and never talked to that monitor again. On my Desklab portabable 4K monitor I got it to display in 4K resolution but only the top left 1/4 of the screen displayed. The issues with HDMI monitor support greatly limit the immediate potential for using this as a workstation. It doesn t make it impossible but would be fiddly at best. It s quite likely that a future OS update will fix this. But at the moment it s best used as a server. The LicheePi has a custom Linux distribution based on Ubuntu so you want too put something like the following in /etc/network/interfaces to make it automatically connect to the ethernet when plugged in:
auto end0
iface end0 inet dhcp
Then to get sshd to start you have to run the following commands to generate ssh host keys that aren t zero bytes long:
rm /etc/ssh/ssh_host_*
systemctl restart ssh.service
It appears to have wifi hardware but the OS doesn t recognise it. This isn t a priority for me as I mostly want to use it as a server. Performance For the first test of performance I created a 100MB file from /dev/urandom and then tried compressing it on various systems. With zstd -9 it took 16.893 user seconds on the LicheePi4A, 0.428s on my Thinkpad X1 Carbon Gen5 with a i5-6300U CPU (Debian/Unstable), 1.288s on my E5-2696 v3 workstation (Debian/Bookworm), 0.467s on the E5-2696 v3 running Debian/Unstable, 2.067s on a E3-1271 v3 server, and 7.179s on the E3-1271 v3 system emulating a RISC-V system via QEMU running Debian/Unstable. It s very impressive that the QEMU emulation is fast enough that emulating a different CPU architecture is only 3.5* slower for this test (or maybe 10* slower if it was running Debian/Unstable on the AMD64 code)! The emulated RISC-V is also more than twice as fast as real RISC-V hardware and probably of comparable speed to real RISC-V hardware when running the same versions (and might be slightly slower if running the same version of zstd) which is a tribute to the quality of emulation. One performance issue that most people don t notice is the time taken to negotiate ssh sessions. It s usually not noticed because the common CPUs have got faster at about the same rate as the algorithms for encryption and authentication have become more complex. On my i5-6300U laptop it takes 0m0.384s to run ssh -i ~/.ssh/id_ed25519 localhost id with the below server settings (taken from advice on ssh-audit.com [3] for a secure ssh configuration). On the E3-1271 v3 server it is 0.336s, on the QMU system it is 28.022s, and on the LicheePi it is 0.592s. By this metric the LicheePi is about 80% slower than decent x86 systems and the QEMU emulation of RISC-V is 73* slower than the x86 system it runs on. Does crypto depend on instructions that are difficult to emulate?
HostKey /etc/ssh/ssh_host_ed25519_key
KexAlgorithms -ecdh-sha2-nistp256,ecdh-sha2-nistp384,ecdh-sha2-nistp521,diffie-hellman-group14-sha256
MACs -umac-64-etm@openssh.com,hmac-sha1-etm@openssh.com,umac-64@openssh.com,umac-128@openssh.com,hmac-sha2-256,hmac-sha2-512,hmac-sha1
I haven t yet tested the performance of Ethernet (what routing speed can you get through the 2 gigabit ports?), emmc storage, and USB. At the moment I ve been focused on using RISC-V as a test and development platform. My conclusion is that I m glad I don t plan to compile many kernels or anything large like LibreOffice. But that for typical development that I do it will be quite adequate. The speed of Chromium seems adequate in basic tests, but the video output hasn t worked reliably enough to do advanced tests. Hardware Features Having two Gigabit Ethernet ports, 4 USB-3 ports, and Wifi on board gives some great options for using this as a router. It s disappointing that they didn t go with 2.5Gbit as everyone seems to be doing that nowadays but Gigabit is enough for most things. Having only a single HDMI port and not supporting USB-C docks (the USB-C port appears to be power only) limits what can be done for workstation use and for controlling displays. I know of people using small ARM computers attached to the back of large TVs for advertising purposes and that isn t going to be a great option for this. The CPU and RAM apparently uses a lot of power (which is relative the entire system draws up to 2A at 5V so the CPU would be something below 5W). To get this working a cooling fan has to be stuck to the CPU and RAM chips via a layer of thermal stuff that resembles a fine sheet of blu-tack in both color and stickyness. I am disappointed that there isn t any more solid form of construction, to mount this on a wall or ceiling some extra hardware would be needed to secure this. Also if they just had a really big copper heatsink I think that would be better. 80386 CPUs with similar TDP were able to run without a fan. I wonder how things would work with all USB ports in use. It s expected that a USB port can supply a minimum of 2.5W which means that all the ports could require 10W if they were active. Presumably something significantly less than 5W is available for the USB ports. Other Devices Sipheed has a range of other devices in the works. They currently sell the LicheeCluster4A which support 7 compute modules for a cluster in a box. This has some interesting potential for testing and demonstrating cluster software but you could probably buy an AMD64 system with more compute power for less money. The Lichee Console 4A is a tiny laptop which could be useful for people who like the 7 laptop form factor, unfortunately it only has a 1280*800 display if it had the same resolution display as a typical 7 phone I would have bought one. The next device that appeals to me is the soon to be released Lichee Pad 4A which is a 10.1 tablet with 1920*1200 display, Wifi6, Bluetooth 5.4, and 16G of RAM. It also has 1 USB-C connection, 2*USB-3 sockets, and support for an external card with 2*Gigabit ethernet. It s a tablet as a laptop without keyboard instead of the more common larger phone design model. They are also about to release the LicheePadMax4A which is similar to the other tablet but with a 14 2240*1400 display and which ships with a keyboard to make it essentially a laptop with detachable keyboard. Conclusion At this time I wouldn t recommend that this device be used as a workstation or laptop, although the people who want to do such things will probably do it anyway regardless of my recommendations. I think it will be very useful as a test system for RISC-V development. I have some friends who are interested in this sort of thing and I can give them VMs. It is a bit expensive. The Sipheed web site boasts about the LicheePi4 being faster than the RaspberryPi4, but it s not a lot faster and the RaspberryPi4 is much cheaper ($127 or $129 for one with 8G of RAM). The RaspberryPi4 has two HDMI ports but a limit of 8G of RAM while the LicheePi has up to 16G of RAM and two Gigabit Ethernet ports but only a single HDMI port. It seems that the RaspberryPi4 might win if you want a cheap low power desktop system. At this time I think the reason for this device is testing out RISC-V as an alternative to the AMD64 and ARM64 architectures. An open CPU architecture goes well with free software, but it isn t just people who are into FOSS who are testing such things. I know some corporations are trying out RISC-V as a way of getting other options for embedded systems that don t involve paying monopolists. The Lichee Console 4A is probably a usable tiny laptop if the resolution is sufficient for your needs. As an aside I predict that the tiny laptop or pocket computer segment will take off in the near future. There are some AMD64 systems the size of a phone but thicker that run Windows and go for reasonable prices on AliExpress. Hopefully in the near future this device will have better video drivers and be usable as a small and quiet workstation. I won t rule out the possibility of making this my main workstation in the not too distant future, all it needs is reliable 4K display and the ability to decode 4K video. It s performance for web browsing and as an ssh client seems adequate, and that s what matters for my workstation use. But for the moment it s just for server use.

17 January 2024

Colin Watson: Task management

Now that I m freelancing, I need to actually track my time, which is something I ve had the luxury of not having to do before. That meant something of a rethink of the way I ve been keeping track of my to-do list. Up to now that was a combination of things like the bug lists for the projects I m working on at the moment, whatever task tracking system Canonical was using at the moment (Jira when I left), and a giant flat text file in which I recorded logbook-style notes of what I d done each day plus a few extra notes at the bottom to remind myself of particularly urgent tasks. I could have started manually adding times to each logbook entry, but ugh, let s not. In general, I had the following goals (which were a bit reminiscent of my address book): I didn t do an elaborate evaluation of multiple options, because I m not trying to come up with the best possible solution for a client here. Also, there are a bazillion to-do list trackers out there and if I tried to evaluate them all I d never do anything else. I just wanted something that works well enough for me. Since it came up on Mastodon: a bunch of people swear by Org mode, which I know can do at least some of this sort of thing. However, I don t use Emacs and don t plan to use Emacs. nvim-orgmode does have some support for time tracking, but when I ve tried vim-based versions of Org mode in the past I ve found they haven t really fitted my brain very well. Taskwarrior and Timewarrior One of the other Freexian collaborators mentioned Taskwarrior and Timewarrior, so I had a look at those. The basic idea of Taskwarrior is that you have a task command that tracks each task as a blob of JSON and provides subcommands to let you add, modify, and remove tasks with a minimum of friction. task add adds a task, and you can add metadata like project:Personal (I always make sure every task has a project, for ease of filtering). Just running task shows you a task list sorted by Taskwarrior s idea of urgency, with an ID for each task, and there are various other reports with different filtering and verbosity. task <id> annotate lets you attach more information to a task. task <id> done marks it as done. So far so good, so a redacted version of my to-do list looks like this:
$ task ls
ID A Project     Tags                 Description
17   Freexian                         Add Incus support to autopkgtest [2]
 7   Columbiform                      Figure out Lloyds online banking [1]
 2   Debian                           Fix troffcvt for groff 1.23.0 [1]
11   Personal                         Replace living room curtain rail
Once I got comfortable with it, this was already a big improvement. I haven t bothered to learn all the filtering gadgets yet, but it was easy enough to see that I could do something like task all project:Personal and it d show me both pending and completed tasks in that project, and that all the data was stored in ~/.task - though I have to say that there are enough reporting bells and whistles that I haven t needed to poke around manually. In combination with the regular backups that I do anyway (you do too, right?), this gave me enough confidence to abandon my previous text-file logbook approach. Next was time tracking. Timewarrior integrates with Taskwarrior, albeit in an only semi-packaged way, and it was easy enough to set that up. Now I can do:
$ task 25 start
Starting task 00a9516f 'Write blog post about task tracking'.
Started 1 task.
Note: '"Write blog post about task tracking"' is a new tag.
Tracking Columbiform "Write blog post about task tracking"
  Started 2024-01-10T11:28:38
  Current                  38
  Total               0:00:00
You have more urgent tasks.
Project 'Columbiform' is 25% complete (3 of 4 tasks remaining).
When I stop work on something, I do task active to find the ID, then task <id> stop. Timewarrior does the tedious stopwatch business for me, and I can manually enter times if I forget to start/stop a task. Then the really useful bit: I can do something like timew summary :month <name-of-client> and it tells me how much to bill that client for this month. Perfect. I also started using VIT to simplify the day-to-day flow a little, which means I m normally just using one or two keystrokes rather than typing longer commands. That isn t really necessary from my point of view, but it does save some time. Android integration I left Android integration for a bit later since it wasn t essential. When I got round to it, I have to say that it felt a bit clumsy, but it did eventually work. The first step was to set up a taskserver. Most of the setup procedure was OK, but I wanted to use Let s Encrypt to minimize the amount of messing around with CAs I had to do. Getting this to work involved hitting things with sticks a bit, and there s still a local CA involved for client certificates. What I ended up with was a certbot setup with the webroot authenticator and a custom deploy hook as follows (with cert_name replaced by a DNS name in my house domain):
#! /bin/sh
set -eu
cert_name=taskd.example.org
found=false
for domain in $RENEWED_DOMAINS; do
    case "$domain" in
        $cert_name)
            found=:
            ;;
    esac
done
$found   exit 0
install -m 644 "/etc/letsencrypt/live/$cert_name/fullchain.pem" \
    /var/lib/taskd/pki/fullchain.pem
install -m 640 -g Debian-taskd "/etc/letsencrypt/live/$cert_name/privkey.pem" \
    /var/lib/taskd/pki/privkey.pem
systemctl restart taskd.service
I could then set this in /etc/taskd/config (server.crl.pem and ca.cert.pem were generated using the documented taskserver setup procedure):
server.key=/var/lib/taskd/pki/privkey.pem
server.cert=/var/lib/taskd/pki/fullchain.pem
server.crl=/var/lib/taskd/pki/server.crl.pem
ca.cert=/var/lib/taskd/pki/ca.cert.pem
Then I could set taskd.ca on my laptop to /usr/share/ca-certificates/mozilla/ISRG_Root_X1.crt and otherwise follow the client setup instructions, run task sync init to get things started, and then task sync every so often to sync changes between my laptop and the taskserver. I used TaskWarrior Mobile as the client. I have to say I wouldn t want to use that client as my primary task tracking interface: the setup procedure is clunky even beyond the necessity of copying a client certificate around, it expects you to give it a .taskrc rather than having a proper settings interface for that, and it only seems to let you add a task if you specify a due date for it. It also lacks Timewarrior integration, so I can only really use it when I don t care about time tracking, e.g. personal tasks. But that s really all I need, so it meets my minimum requirements. Next? Considering this is literally the first thing I tried, I have to say I m pretty happy with it. There are a bunch of optional extras I haven t tried yet, but in general it kind of has the vim nature for me: if I need something it s very likely to exist or easy enough to build, but the features I don t use don t get in my way. I wouldn t recommend any of this to somebody who didn t already spend most of their time in a terminal - but I do. I m glad people have gone to all the effort to build this so I didn t have to.

16 January 2024

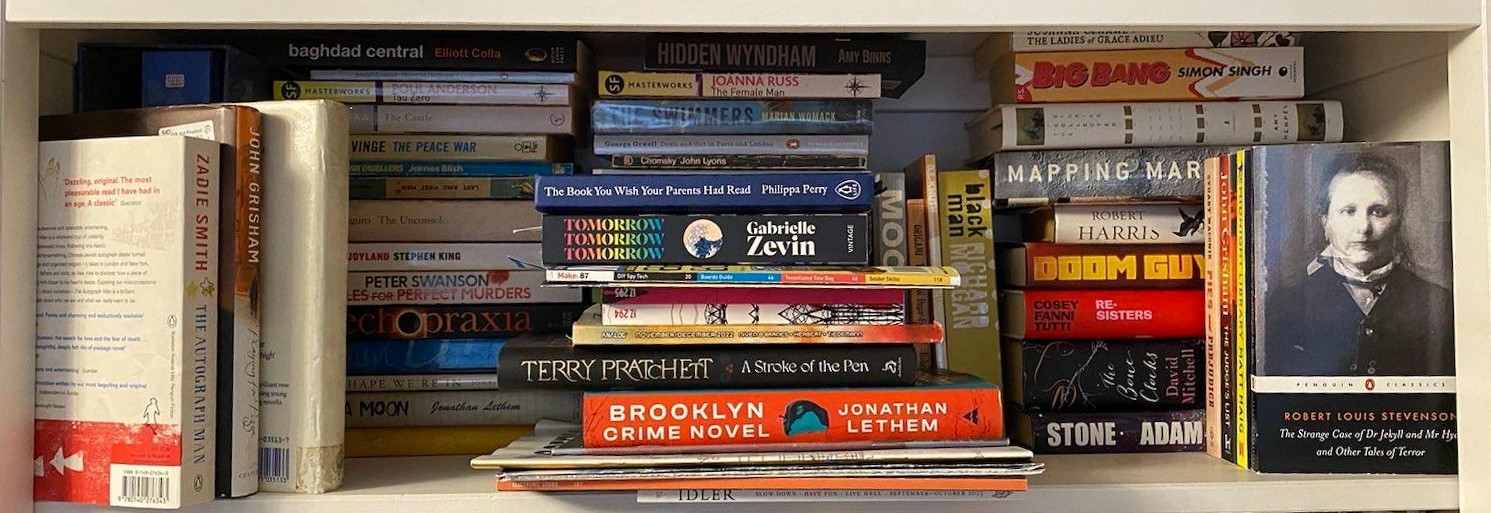
Jonathan Dowland: Reading hack

My to-read shelf My to-read shelf
This year, with respect to my ever-growing reading backlog, I'm going to try something new: when I acquire a new book, I'm going to try to read at least a few pages of it immediately. My theory is this will help me to have a better idea of what to expect when I come to pick the next book to start, later on. A few pages may not be very representative of a full book (In "How to read a Novel: A User's Guide John Sullivan suggests reading 69 pages before giving up on a book), but it may be better than nothing. I'll report back if it seems to work.

Thomas Koch: Missing memegen

Posted on May 1, 2022
Back at $COMPANY we had an internal meme-site. I had some reputation in my team for creating good memes. When I watched Episode 3 of Season 2 from Yes Premier Minister yesterday, I really missed a place to post memes. This is the full scene. Please watch it or even the full episode before scrolling down to the GIFs. I had a good laugh for some time. With Debian, I could just download the episode from somewhere on the net with youtube-dl and easily create two GIFs using ffmpeg, with and without subtitle:
ffmpeg  -ss 0:5:59.600 -to 0:6:11.150 -i Downloads/Yes.Prime.Minister.S02E03-1254485068289.mp4 tmp/tragic.gif
ffmpeg  -ss 0:5:59.600 -to 0:6:11.150 -i Downloads/Yes.Prime.Minister.S02E03-1254485068289.mp4 \
        -vf "subtitles=tmp/sub.srt:force_style='Fontsize=60'" tmp/tragic_with_subtitle.gif
And this sub.srt file:
1
00:00:10,000 --> 00:00:12,000
Tragic.
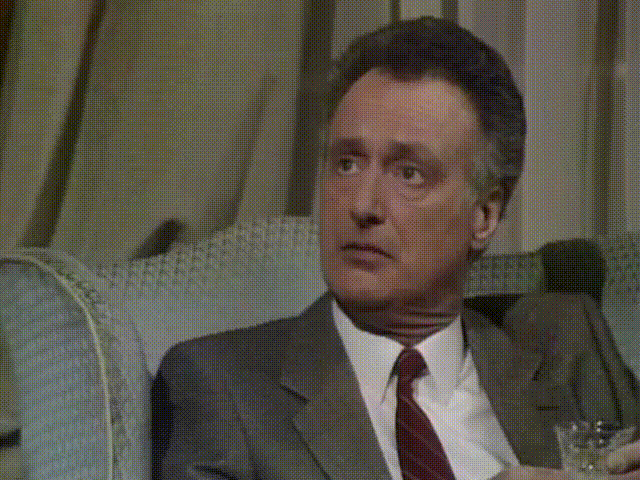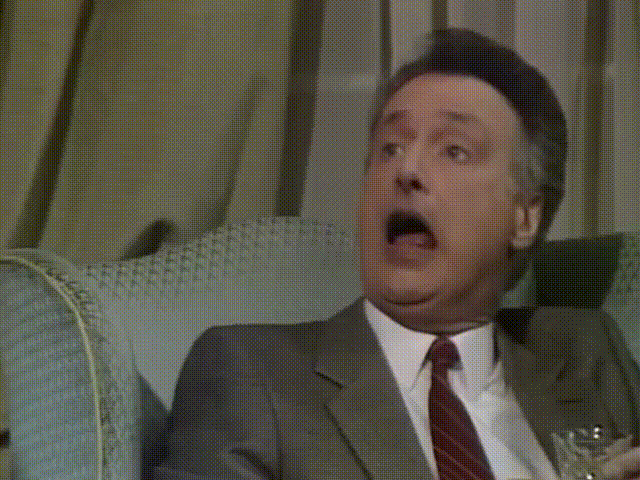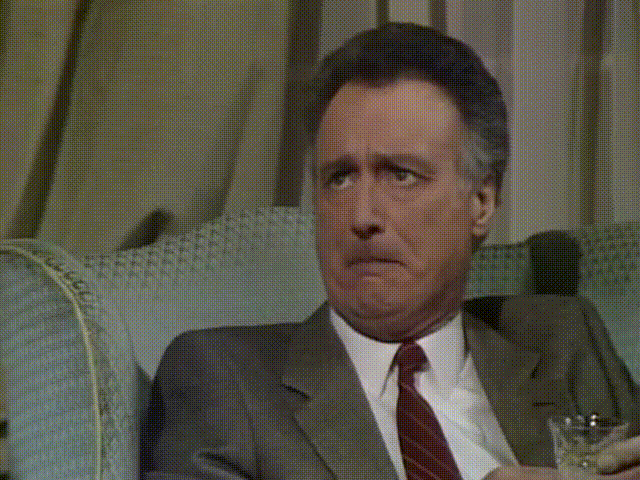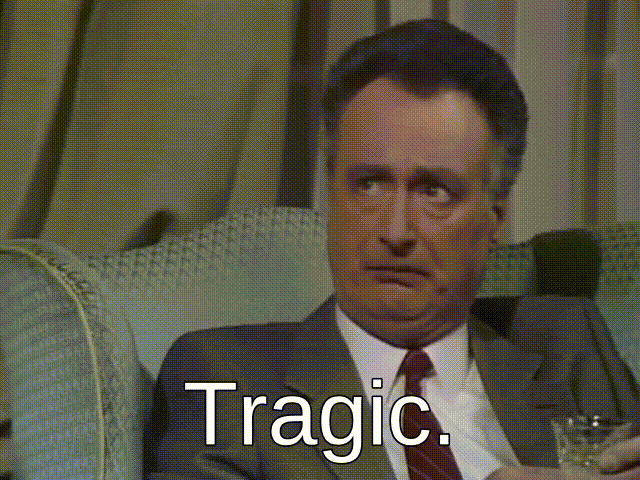
I believe, one needs to install the libavfilter-extra variant to burn the subtitle in the GIF. Some space to hide the GIFs. The Premier Minister just learned, that his predecessor, who was about to publish embarassing memories, died of a sudden heart attack: I can t actually think of a meme with this GIF, that the internal thought police community moderation would not immediately take down. For a moment I thought that it would be fun to have a Meme-Site for Debian members. But it is probably not the right time for this. Maybe somebody likes the above GIFs though and wants to use them somewhere.

Russ Allbery: Review: Making Money

Review: Making Money, by Terry Pratchett
Series: Discworld #36
Publisher: Harper
Copyright: October 2007
Printing: November 2014
ISBN: 0-06-233499-9
Format: Mass market
Pages: 473
Making Money is the 36th Discworld novel, the second Moist von Lipwig book, and a direct sequel to Going Postal. You could start the series with Going Postal, but I would not start here. The post office is running like a well-oiled machine, Adora Belle is out of town, and Moist von Lipwig is getting bored. It's the sort of boredom that has him picking his own locks, taking up Extreme Sneezing, and climbing buildings at night. He may not realize it, but he needs something more dangerous to do. Vetinari has just the thing. The Royal Bank of Ankh-Morpork, unlike the post office before Moist got to it, is still working. It is a stolid, boring institution doing stolid, boring things for rich people. It is also the battleground for the Lavish family past-time: suing each other and fighting over money. The Lavishes are old money, the kind of money carefully entangled in trusts and investments designed to ensure the family will always have money regardless of how stupid their children are. Control of the bank is temporarily in the grasp of Joshua Lavish's widow Topsy, who is not a true Lavish, but the vultures are circling. Meanwhile, Vetinari has grand city infrastructure plans, and to carry them out he needs financing. That means he needs a functional bank, and preferably one that is much less conservative. Moist is dubious about running a bank, and even more reluctant when Topsy Lavish sees him for exactly the con artist he is. His hand is forced when she dies, and Moist discovers he has inherited her dog, Mr. Fusspot. A dog that now owns 51% of the Royal Bank and therefore is the chairman of the bank's board of directors. A dog whose safety is tied to Moist's own by way of an expensive assassination contract. Pratchett knew he had a good story with Going Postal, so here he runs the same formula again. And yes, I was happy to read it again. Moist knows very little about banking but quite a lot about pretending something will work until it does, which has more to do with banking than it does with running a post office. The bank employs an expert, Mr. Bent, who is fanatically devoted to the gold standard and the correctness of the books and has very little patience for Moist. There are golem-related hijinks. The best part of this book is Vetinari, who is masterfully manipulating everyone in the story and who gets in some great lines about politics.
"We are not going to have another wretched empire while I am Patrician. We've only just got over the last one."
Also, Vetinari processing dead letters in the post office was an absolute delight. Making Money does have the recurring Pratchett problem of having a fairly thin plot surrounded by random... stuff. Moist's attempts to reform the city currency while staying ahead of the Lavishes is only vaguely related to Mr. Bent's plot arc. The golems are unrelated to the rest of the plot other than providing a convenient deus ex machina. There is an economist making water models in the bank basement with an Igor, which is a great gag but has essentially nothing to do with the rest of the book. One of the golems has been subjected to well-meaning older ladies and 1950s etiquette manuals, which I thought was considerably less funny (and somewhat creepier) than Pratchett did. There are (sigh) clowns, which continue to be my least favorite Ankh-Morpork world-building element. At least the dog was considerably less annoying than I was afraid it was going to be. This grab-bag randomness is a shame, since I think there was room here for a more substantial plot that engaged fully with the high weirdness of finance. Unfortunately, this was a bit like the post office in Going Postal: Pratchett dives into the subject just enough to make a few wry observations and a few funny quips, and then resolves the deeper issues off-camera. Moist tries to invent fiat currency, because of course he does, and Pratchett almost takes on the gold standard, only to veer away at the last minute into vigorous hand-waving. I suspect part of the problem is that I know a little bit too much about finance, so I kept expecting Pratchett to take the humorous social commentary a couple of levels deeper. On a similar note, the villains have great potential that Pratchett undermines by adding too much over-the-top weirdness. I wish Cosmo Lavish had been closer to what he appears to be at the start of the book: a very wealthy and vindictive man (and a reference to Cosimo de Medici) who doesn't have Moist's ability to come up with wildly risky gambits but who knows considerably more than he does about how banking works. Instead, Pratchett gives him a weird obsession that slowly makes him less sinister and more pathetic, which robs the book of a competent antagonist for Moist. The net result is still a fun book, and a solid Discworld entry, but it lacks the core of the best series entries. It felt more like a skit comedy show than a novel, but it's an excellent skit comedy show with the normal assortment of memorable Pratchettisms. Certainly if you've read this far, or even if you've only read Going Postal, you'll want to read Making Money as well. Followed by Unseen Academicals. The next Moist von Lipwig book is Raising Steam. Rating: 8 out of 10

15 January 2024

Russ Allbery: Review: The Library of Broken Worlds

Review: The Library of Broken Worlds, by Alaya Dawn Johnson
Publisher: Scholastic Press
Copyright: June 2023
ISBN: 1-338-29064-9
Format: Kindle
Pages: 446
The Library of Broken Worlds is a young-adult far-future science fantasy. So far as I can tell, it's stand-alone, although more on that later in the review. Freida is the adopted daughter of Nadi, the Head Librarian, and her greatest wish is to become a librarian herself. When the book opens, she's a teenager in highly competitive training. Freida is low-wetware, without the advanced and expensive enhancements of many of the other students competing for rare and prized librarian positions, which she makes up for by being the most audacious. She doesn't need wetware to commune with the library material gods. If one ventures deep into their tunnels and consumes their crystals, direct physical communion is possible. The library tunnels are Freida's second home, in part because that's where she was born. She was created by the Library, and specifically by Iemaja, the youngest of the material gods. Precisely why is a mystery. To Nadi, Freida is her daughter. To Quinn, Nadi's main political rival within the library, Freida is a thing, a piece of the library, a secondary and possibly rogue AI. A disruptive annoyance. The Library of Broken Worlds is the sort of science fiction where figuring out what is going on is an integral part of the reading experience. It opens with a frame story of an unnamed girl (clearly Freida) waking the god Nameren and identifying herself as designed for deicide. She provokes Nameren's curiosity and offers an Arabian Nights bargain: if he wants to hear her story, he has to refrain from killing her for long enough for her to tell it. As one might expect, the main narrative doesn't catch up to the frame story until the very end of the book. The Library is indeed some type of library that librarians can search for knowledge that isn't available from more mundane sources, but Freida's personal experience of it is almost wholly religious and oracular. The library's material gods are identified as AIs, but good luck making sense of the story through a science fiction frame, even with a healthy allowance for sufficiently advanced technology being indistinguishable from magic. The symbolism and tone is entirely fantasy, and late in the book it becomes clear that whatever the material gods are, they're not simple technological AIs in the vein of, say, Banks's Ship Minds. Also, the Library is not solely a repository of knowledge. It is the keeper of an interstellar peace. The Library was founded after the Great War, to prevent a recurrence. It functions as a sort of legal system and grand tribunal in ways that are never fully explained. As you might expect, that peace is based more on stability than fairness. Five of the players in this far future of humanity are the Awilu, the most advanced society and the first to leave Earth (or Tierra as it's called here); the Mah m, who possess the material war god Nameren of the frame story; the Lunars and Martians, who dominate the Sol system; and the surviving Tierrans, residents of a polluted and struggling planet that is ruthlessly exploited by the Lunars. The problem facing Freida and her friends at the start of the book is a petition brought by a young Tierran against Lunar exploitation of his homeland. His name is Joshua, and Freida is more than half in love with him. Joshua's legal argument involves interpretation of the freedom node of the treaty that ended the Great War, a node that precedent says gives the Lunars the freedom to exploit Tierra, but which Joshua claims has a still-valid originalist meaning granting Tierrans freedom from exploitation. There is, in short, a lot going on in this book, and "never fully explained" is something of a theme. Freida is telling a story to Nameren and only explains things Nameren may not already know. The reader has to puzzle out the rest from the occasional hint. This is made more difficult by the tendency of the material gods to communicate only in visions or guided hallucinations, full of symbolism that the characters only partly explain to the reader. Nonetheless, this did mostly work, at least for me. I started this book very confused, but by about the midpoint it felt like the background was coming together. I'm still not sure I understand the aurochs, baobab, and cicada symbolism that's so central to the framing story, but it's the pleasant sort of stretchy confusion that gives my brain a good workout. I wish Johnson had explained a few more things plainly, particularly near the end of the book, but my remaining level of confusion was within my tolerances. Unfortunately, the ending did not work for me. The first time I read it, I had no idea what it meant. Lots of baffling, symbolic things happened and then the book just stopped. After re-reading the last 10%, I think all the pieces of an ending and a bit of an explanation are there, but it's absurdly abbreviated. This is another book where the author appears to have been finished with the story before I was. This keeps happening to me, so this probably says something more about me than it says about books, but I want books to have an ending. If the characters have fought and suffered through the plot, I want them to have some space to be happy and to see how their sacrifices play out, with more detail than just a few vague promises. If much of the book has been puzzling out the nature of the world, I would like some concrete confirmation of at least some of my guesswork. And if you're going to end the book on radical transformation, I want to see the results of that transformation. Johnson does an excellent job showing how brutal the peace of the powerful can be, and is willing to light more things on fire over the course of this book than most authors would, but then doesn't offer the reader much in the way of payoff. For once, I wish this stand-alone turned out to be a series. I think an additional book could be written in the aftermath of this ending, and I would definitely read that novel. Johnson has me caring deeply about these characters and fascinated by the world background, and I'd happily spend another 450 pages finding out what happens next. But, frustratingly, I think this ending was indeed intended to wrap up the story. I think this book may fall between a few stools. Science fiction readers who want mysterious future worlds to be explained by the end of the book are going to be frustrated by the amount of symbolism, allusion, and poetic description. Literary fantasy readers, who have a higher tolerance for that style, are going to wish for more focused and polished writing. A lot of the story is firmly YA: trying and failing to fit in, developing one's identity, coming into power, relationship drama, great betrayals and regrets, overcoming trauma and abuse, and unraveling lies that adults tell you. But this is definitely not a straight-forward YA plot or world background. It demands a lot from the reader, and while I am confident many teenage readers would rise to that challenge, it seems like an awkward fit for the YA marketing category. About 75% of the way in, I would have told you this book was great and you should read it. The ending was a let-down and I'm still grumpy about it. I still think it's worth your attention if you're in the mood for a sink-or-swim type of reading experience. Just be warned that when the ride ends, I felt unceremoniously dumped on the pavement. Content warnings: Rape, torture, genocide. Rating: 7 out of 10

14 January 2024

Debian Brasil: MiniDebConf BH 2024 - abertura de inscri o e chamada de atividades

MiniDebConf BH 2024 Est aberta a inscri o de participantes e a chamada de atividades para a MiniDebConf Belo Horizonte 2024 e para o FLISOL - Festival Latino-americano de Instala o de Software Livre. Veja abaixo algumas informa es importantes: Data e local da MiniDebConf e do FLISOL A MiniDebConf acontecer de 27 a 30 de abril no Campus Pampulha da UFMG - Universidade Federal de Minas Gerais. No dia 27 (s bado) tamb m realizaremos uma edi o do FLISOL - Festival Latino-americano de Instala o de Software Livre, evento que acontece no mesmo dia em v rias cidades da Am rica Latina. Enquanto a MiniDebConf ter atividades focados no Debian, o FLISOL ter atividades gerais sobre Software Livre e temas relacionados como linguagem de programa o, CMS, administra o de redes e sistemas, filosofia, liberdade, licen as, etc. Inscri o gratuita e oferta de bolsas Voc j pode realizar a sua inscri o gratuita para a MiniDebConf Belo Horizonte 2024. A MiniDebConf um evento aberto a todas as pessoas, independente do seu n vel de conhecimento sobre Debian. O mais importante ser reunir a comunidade para celebrar um dos maiores projeto de Software Livre no mundo, por isso queremos receber desde usu rios(as) inexperientes que est o iniciando o seu contato com o Debian at Desenvolvedores(as) oficiais do projeto. Ou seja, est o todos(as) convidados(as)! Este ano estamos ofertando bolsas de hospedagem e passagens para viabilizar a vinda de pessoas de outras cidades que contribuem para o Projeto Debian. Contribuidores(as) n o oficiais, DMs e DDs podem solicitar as bolsas usando o formul rio de inscri o. Tamb m estamos ofertando bolsas de alimenta o para todos(as) os(as) participantes, mesmo n o contribuidores(as), e pessoas que moram na regi o de BH. Os recursos financeiros s o bastante limitados, mas tentaremos atender o m ximo de pedidos. Se voc pretende pedir alguma dessas bolsas, acesse este link e veja mais informa es antes de realizar a sua inscri o: A inscri o (sem bolsas) poder ser feita at a data do evento, mas temos uma data limite para o pedido de bolsas de hospedagem e passagens, por isso fique atento(a) ao prazo final: at 18 de fevereiro. Como estamos usando mesmo formul rio para os dois eventos, a inscri o ser v lida tanto para a MiniDebConf quanto para o FLISOL. Para se inscrever, acesse o site, v em Criar conta. Criei a sua conta (preferencialmente usando o Salsa) e acesse o seu perfil. L voc ver o bot o de Se inscrever. https://bh.mini.debconf.org Chamada de atividades Tamb m est aberta a chamada de atividades tanto para MiniDebConf quanto para o FLISOL. Para mais informa es, acesse este link. Fique atento ao prazo final para enviar sua proposta de atividade: at 18 de fevereiro. Contato Qualquer d vida, mande um email para contato@debianbrasil.org.br Organiza o Debian Brasil Debian Debian MG DCC

13 January 2024

Valhalla's Things: Mini Books

Posted on January 13, 2024
Tags: madeof:atoms, craft:bookbinding
Two coptic bound small books, seen from the top with the pages somewhat open. One has purple and orange triangles on the cover, the other one waves in two shades of greenish blue. In 2022 I read a post on the fediverse by somebody who mentioned that they had bought on a whim a cute tiny book years ago, and that it had been a companion through hard times. Right now I can t find the post, but it was pretty aaaaawwww. Two coptic bound small books, seen from the front. One of the covers is covered in grey paper, the other one is cardboard that has been spray-painted copper. At the same time, I had discovered Coptic binding, and I wanted to do some exercise to let my hands learn it, but apparently there is a limit to the number of notebooks and sketchbooks a person needs (I m not 100% sure I actually believe this, but I ve heard it is a thing). A coptic bound small book, seen from the front. The cover is made of white cernit, with thin lines painted in gold acrylic to form a sort of B shape. So I decided to start making minibooks with the intent to give them away: I settled (mostly) on the A8 size, and used a combination of found materials, leftovers from bigger projects and things I had in the Stash. As for paper, I ve used a variety of the ones I have that are at the very least good enough for non-problematic fountain pen inks. Two coptic bound small books, seen from the front. The covers are covered in grey paper with a piece of light blue lace on top. Thanks to the small size, and the way coptic binding works, I ve been able to play around with the covers, experimenting with different styles beyond the classic bookbinding cloth / paper covered cardboard, including adding lace, covering food box cardboard with gesso and decorating it with acrylic paints, embossing designs by gluing together two layers of cardboard, one of which has holes, making covers completely out of cernit, etc. Some of these I will probably also use in future full-scale projects, but it s nice to find out what works and what doesn t on a small scale. Two coptic bound small books, seen from the front. The covers are covered in grey paper, and they are half-covered by a piece of off-white tulle, cut on a diagonal. One of the two books has a cat eye embossed and painted in gold. Now, after a year of sporadically making these I have to say that the making went quite well: I enjoyed the making and the creativity in making different covers. The giving away was a bit more problematic, as I didn t really have a lot of chances to do so, so I believe I still have most of them. In 2024 I ll try to look for more opportunities (and if you live nearby and want one or a few feel free to ask!)

Freexian Collaborators: Debian Contributions: LXD/Incus backend bug, /usr-merge updates, gcc-for-host, and more! (by Utkarsh Gupta)

Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

LXD/Incus backend bug in autopkgtest by Stefano Rivera While working on the Python 3.12 transition, Stefano repeatedly ran into a bug in autopkgtest when using LXD (or in the future Incus), that caused it to hang when running cython s multi-hour autopkgtests. After some head-banging, the bug turned out to be fairly straightforward: LXD didn t shut down on receiving a SIGTERM, so when a testsuite timed out, it would hang forever. A simple fix has been applied.

/usr-merge, by Helmut Grohne Thanks to Christian Hofstaedtler and others, the effort is moving into a community effort and the work funded by Freexian becomes more difficult to separate from non-funded work. In particular, since the community fully handled all issues around lost udev rules, dh_installudev now installs rules to /usr. The story around diversions took another detour. We learned that conflicts do not reliably prevent concurrent unpack and the reiterated mitigation for molly-guard triggered this. After a bit of back and forth and consultation with the developer mailing list, we concluded that avoiding the problematic behavior when using apt or an apt-based upgrader combined with a loss mitigation would be good enough. The involved packages bfh-container, molly-guard, progress-linux-container and systemd have since been uploaded to unstable and the matter seems finally solved except that it doesn t quite work with sysvinit yet. The same approach is now being proposed for the diversions of zutils for gzip. We thank involved maintainers for their timely cooperation.

gcc-for-host, by Helmut Grohne Since forever, it has been difficult to correctly express a toolchain build dependency. This can be seen in the Build-Depends of the linux source package for instance. While this has been solved for binutils a while back, the patches for gcc have been unfinished. With lots of constructive feedback from gcc package maintainer Matthias Klose, Helmut worked on finalizing and testing these patches. Patch stacks are now available for gcc-13 and gcc-14 and Matthias already included parts of them in test builds for Ubuntu noble. Finishing this work would enable us to resolve around 1000 cross build dependency satisfiability issues in unstable.

Miscellaneous contributions
  • Stefano continued work on the Python 3.12 transition, including uploads of cython, pycxx, numpy, python-greenlet, twisted, foolscap and dh-python.
  • Stefano reviewed and selected from a new round of DebConf 24 bids, as part of the DebConf Committee. Busan, South Korea was selected.
  • For debian-printing Thorsten uploaded hplip to unstable to fix a /usr-merge bug and cups to Bookworm to fix bugs related to printing in color.
  • Utkarsh helped newcomers in mentoring and reviewing their packaging; eg: golang-github-prometheus-community-pgbouncer-exporter.
  • Helmut sent patches for 42 cross build failures unrelated to the gcc-for-host work.
  • Helmut continues to maintain rebootstrap. In December, blt started depending on libjpeg and this poses a dependency loop. Ideally, Python would stop depending on blt. Also linux-libc-dev having become Multi-Arch: foreign poses non-trivial issues that are not fully resolved yet.
  • Enrico participated in /usr-merge discussions with Helmut.

11 January 2024

Reproducible Builds: Reproducible Builds in December 2023

Welcome to the December 2023 report from the Reproducible Builds project! In these reports we outline the most important things that we have been up to over the past month. As a rather rapid recap, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries (more).
Reproducible Builds: Increasing the Integrity of Software Supply Chains awarded IEEE Software Best Paper award In February 2022, we announced in these reports that a paper written by Chris Lamb and Stefano Zacchiroli was now available in the March/April 2022 issue of IEEE Software. Titled Reproducible Builds: Increasing the Integrity of Software Supply Chains (PDF). This month, however, IEEE Software announced that this paper has won their Best Paper award for 2022.
Reproducibility to affect package migration policy in Debian In a post summarising the activities of the Debian Release Team at a recent in-person Debian event in Cambridge, UK, Paul Gevers announced a change to the way packages are migrated into the staging area for the next stable Debian release based on its reproducibility status:
The folks from the Reproducibility Project have come a long way since they started working on it 10 years ago, and we believe it s time for the next step in Debian. Several weeks ago, we enabled a migration policy in our migration software that checks for regression in reproducibility. At this moment, that is presented as just for info, but we intend to change that to delays in the not so distant future. We eventually want all packages to be reproducible. To stimulate maintainers to make their packages reproducible now, we ll soon start to apply a bounty [speedup] for reproducible builds, like we ve done with passing autopkgtests for years. We ll reduce the bounty for successful autopkgtests at that moment in time.
Speranza: Usable, privacy-friendly software signing Kelsey Merrill, Karen Sollins, Santiago Torres-Arias and Zachary Newman have developed a new system called Speranza, which is aimed at reassuring software consumers that the product they are getting has not been tampered with and is coming directly from a source they trust. A write-up on TechXplore.com goes into some more details:
What we have done, explains Sollins, is to develop, prove correct, and demonstrate the viability of an approach that allows the [software] maintainers to remain anonymous. Preserving anonymity is obviously important, given that almost everyone software developers included value their confidentiality. This new approach, Sollins adds, simultaneously allows [software] users to have confidence that the maintainers are, in fact, legitimate maintainers and, furthermore, that the code being downloaded is, in fact, the correct code of that maintainer. [ ]
The corresponding paper is published on the arXiv preprint server in various formats, and the announcement has also been covered in MIT News.
Nondeterministic Git bundles Paul Baecher published an interesting blog post on Reproducible git bundles. For those who are not familiar with them, Git bundles are used for the offline transfer of Git objects without an active server sitting on the other side of a network connection. Anyway, Paul wrote about writing a backup system for his entire system, but:
I noticed that a small but fixed subset of [Git] repositories are getting backed up despite having no changes made. That is odd because I would think that repeated bundling of the same repository state should create the exact same bundle. However [it] turns out that for some, repositories bundling is nondeterministic.
Paul goes on to to describe his solution, which involves forcing git to be single threaded makes the output deterministic . The article was also discussed on Hacker News.

Output from libxlst now deterministic libxslt is the XSLT C library developed for the GNOME project, where XSLT itself is an XML language to define transformations for XML files. This month, it was revealed that the result of the generate-id() XSLT function is now deterministic across multiple transformations, fixing many issues with reproducible builds. As the Git commit by Nick Wellnhofer describes:
Rework the generate-id() function to return deterministic values. We use
a simple incrementing counter and store ids in the 'psvi' member of
nodes which was freed up by previous commits. The presence of an id is
indicated by a new "source node" flag.
This fixes long-standing problems with reproducible builds, see
https://bugzilla.gnome.org/show_bug.cgi?id=751621
This also hardens security, as the old implementation leaked the
difference between a heap and a global pointer, see
https://bugs.chromium.org/p/chromium/issues/detail?id=1356211
The old implementation could also generate the same id for dynamically
created nodes which happened to reuse the same memory. Ids for namespace
nodes were completely broken. They now use the id of the parent element
together with the hex-encoded namespace prefix.
Community updates There were made a number of improvements to our website, including Chris Lamb fixing the generate-draft script to not blow up if the input files have been corrupted today or even in the past [ ], Holger Levsen updated the Hamburg 2023 summit to add a link to farewell post [ ] & to add a picture of a Post-It note. [ ], and Pol Dellaiera updated the paragraph about tar and the --clamp-mtime flag [ ]. On our mailing list this month, Bernhard M. Wiedemann posted an interesting summary on some of the reasons why packages are still not reproducible in 2023. diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including processing objdump symbol comment filter inputs as Python byte (and not str) instances [ ] and Vagrant Cascadian extended diffoscope support for GNU Guix [ ] and updated the version in that distribution to version 253 [ ].
Challenges of Producing Software Bill Of Materials for Java Musard Balliu, Benoit Baudry, Sofia Bobadilla, Mathias Ekstedt, Martin Monperrus, Javier Ron, Aman Sharma, Gabriel Skoglund, C sar Soto-Valero and Martin Wittlinger (!) of the KTH Royal Institute of Technology in Sweden, have published an article in which they:
deep-dive into 6 tools and the accuracy of the SBOMs they produce for complex open-source Java projects. Our novel insights reveal some hard challenges regarding the accurate production and usage of software bills of materials.
The paper is available on arXiv.

Debian Non-Maintainer campaign As mentioned in previous reports, the Reproducible Builds team within Debian has been organising a series of online and offline sprints in order to clear the huge backlog of reproducible builds patches submitted by performing so-called NMUs (Non-Maintainer Uploads). During December, Vagrant Cascadian performed a number of such uploads, including: In addition, Holger Levsen performed three no-source-change NMUs in order to address the last packages without .buildinfo files in Debian trixie, specifically lorene (0.0.0~cvs20161116+dfsg-1.1), maria (1.3.5-4.2) and ruby-rinku (1.7.3-2.1).
Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework (available at tests.reproducible-builds.org) in order to check packages and other artifacts for reproducibility. In December, a number of changes were made by Holger Levsen:
  • Debian-related changes:
    • Fix matching packages for the [R programming language](https://en.wikipedia.org/wiki/R_(programming_language). [ ][ ][ ]
    • Add a Certbot configuration for the Nginx web server. [ ]
    • Enable debugging for the create-meta-pkgs tool. [ ][ ]
  • Arch Linux-related changes
    • The asp has been deprecated by pkgctl; thanks to dvzrv for the pointer. [ ]
    • Disable the Arch Linux builders for now. [ ]
    • Stop referring to the /trunk branch / subdirectory. [ ]
    • Use --protocol https when cloning repositories using the pkgctl tool. [ ]
  • Misc changes:
    • Install the python3-setuptools and swig packages, which are now needed to build OpenWrt. [ ]
    • Install pkg-config needed to build Coreboot artifacts. [ ]
    • Detect failures due to an issue where the fakeroot tool is implicitly required but not automatically installed. [ ]
    • Detect failures due to rename of the vmlinuz file. [ ]
    • Improve the grammar of an error message. [ ]
    • Document that freebsd-jenkins.debian.net has been updated to FreeBSD 14.0. [ ]
In addition, node maintenance was performed by Holger Levsen [ ] and Vagrant Cascadian [ ].

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Matthias Klumpp: Wayland really breaks things Just for now?

This post is in part a response to an aspect of Nate s post Does Wayland really break everything? , but also my reflection on discussing Wayland protocol additions, a unique pleasure that I have been involved with for the past months1.

Some facts Before I start I want to make a few things clear: The Linux desktop will be moving to Wayland2 this is a fact at this point (and has been for a while), sticking to X11 makes no sense for future projects. From reading Wayland protocols and working with it at a much lower level than I ever wanted to, it is also very clear to me that Wayland is an exceptionally well-designed core protocol, and so are the additional extension protocols (xdg-shell & Co.). The modularity of Wayland is great, it gives it incredible flexibility and will for sure turn out to be good for the long-term viability of this project (and also provides a path to correct protocol issues in future, if one is found). In other words: Wayland is an amazing foundation to build on, and a lot of its design decisions make a lot of sense! The shift towards people seeing Linux more as an application developer platform, and taking PipeWire and XDG Portals into account when designing for Wayland is also an amazing development and I love to see this this holistic approach is something I always wanted! Furthermore, I think Wayland removes a lot of functionality that shouldn t exist in a modern compositor and that s a good thing too! Some of X11 s features and design decisions had clear drawbacks that we shouldn t replicate. I highly recommend to read Nate s blog post, it s very good and goes into more detail. And due to all of this, I firmly believe that any advancement in the Wayland space must come from within the project.

But! But! Of course there was a but coming  I think while developing Wayland-as-an-ecosystem we are now entrenched into narrow concepts of how a desktop should work. While discussing Wayland protocol additions, a lot of concepts clash, people from different desktops with different design philosophies debate the merits of those over and over again never reaching any conclusion (just as you will never get an answer out of humans whether sushi or pizza is the clearly superior food, or whether CSD or SSD is better). Some people want to use Wayland as a vehicle to force applications to submit to their desktop s design philosophies, others prefer the smallest and leanest protocol possible, other developers want the most elegant behavior possible. To be clear, I think those are all very valid approaches. But this also creates problems: By switching to Wayland compositors, we are already forcing a lot of porting work onto toolkit developers and application developers. This is annoying, but just work that has to be done. It becomes frustrating though if Wayland provides toolkits with absolutely no way to reach their goal in any reasonable way. For Nate s Photoshop analogy: Of course Linux does not break Photoshop, it is Adobe s responsibility to port it. But what if Linux was missing a crucial syscall that Photoshop needed for proper functionality and Adobe couldn t port it without that? In that case it becomes much less clear on who is to blame for Photoshop not being available. A lot of Wayland protocol work is focused on the environment and design, while applications and work to port them often is considered less. I think this happens because the overlap between application developers and developers of the desktop environments is not necessarily large, and the overlap with people willing to engage with Wayland upstream is even smaller. The combination of Windows developers porting apps to Linux and having involvement with toolkits or Wayland is pretty much nonexistent. So they have less of a voice.
A quick detour through the neuroscience research lab I have been involved with Freedesktop, GNOME and KDE for an incredibly long time now (more than a decade), but my actual job (besides consulting for Purism) is that of a PhD candidate in a neuroscience research lab (working on the morphology of biological neurons and its relation to behavior). I am mostly involved with three research groups in our institute, which is about 35 people. Most of us do all our data analysis on powerful servers which we connect to using RDP (with KDE Plasma as desktop). Since I joined, I have been pushing the envelope a bit to extend Linux usage to data acquisition and regular clients, and to have our data acquisition hardware interface well with it. Linux brings some unique advantages for use in research, besides the obvious one of having every step of your data management platform introspectable with no black boxes left, a goal I value very highly in research (but this would be its own blogpost). In terms of operating system usage though, most systems are still Windows-based. Windows is what companies develop for, and what people use by default and are familiar with. The choice of operating system is very strongly driven by application availability, and WSL being really good makes this somewhat worse, as it removes the need for people to switch to a real Linux system entirely if there is the occasional software requiring it. Yet, we have a lot more Linux users than before, and use it in many places where it makes sense. I also developed a novel data acquisition software that even runs on Linux-only and uses the abilities of the platform to its fullest extent. All of this resulted in me asking existing software and hardware vendors for Linux support a lot more often. Vendor-customer relationship in science is usually pretty good, and vendors do usually want to help out. Same for open source projects, especially if you offer to do Linux porting work for them But overall, the ease of use and availability of required applications and their usability rules supreme. Most people are not technically knowledgeable and just want to get their research done in the best way possible, getting the best results with the least amount of friction.
KDE/Linux usage at a control station for a particle accelerator at Adlershof Technology Park, Germany, for reference (by 25years of KDE)3

Back to the point The point of that story is this: GNOME, KDE, RHEL, Debian or Ubuntu: They all do not matter if the necessary applications are not available for them. And as soon as they are, the easiest-to-use solution wins. There are many facets of easiest : In many cases this is RHEL due to Red Hat support contracts being available, in many other cases it is Ubuntu due to its mindshare and ease of use. KDE Plasma is also frequently seen, as it is perceived a bit easier to onboard Windows users with it (among other benefits). Ultimately, it comes down to applications and 3rd-party support though. Here s a dirty secret: In many cases, porting an application to Linux is not that difficult. The thing that companies (and FLOSS projects too!) struggle with and will calculate the merits of carefully in advance is whether it is worth the support cost as well as continuous QA/testing. Their staff will have to do all of that work, and they could spend that time on other tasks after all. So if they learn that porting to Linux not only means added testing and support, but also means to choose between the legacy X11 display server that allows for 1:1 porting from Windows or the new Wayland compositors that do not support the same features they need, they will quickly consider it not worth the effort at all. I have seen this happen. Of course many apps use a cross-platform toolkit like Qt, which greatly simplifies porting. But this just moves the issue one layer down, as now the toolkit needs to abstract Windows, macOS and Wayland. And Wayland does not contain features to do certain things or does them very differently from e.g. Windows, so toolkits have no way to actually implement the existing functionality in a way that works on all platforms. So in Qt s documentation you will often find texts like works everywhere except for on Wayland compositors or mobile 4. Many missing bits or altered behavior are just papercuts, but those add up. And if users will have a worse experience, this will translate to more support work, or people not wanting to use the software on the respective platform.

What s missing?

Window positioning SDI applications with multiple windows are very popular in the scientific world. For data acquisition (for example with microscopes) we often have one monitor with control elements and one larger one with the recorded image. There is also other configurations where multiple signal modalities are acquired, and the experimenter aligns windows exactly in the way they want and expects the layout to be stored and to be loaded upon reopening the application. Even in the image from Adlershof Technology Park above you can see this style of UI design, at mega-scale. Being able to pop-out elements as windows from a single-window application to move them around freely is another frequently used paradigm, and immensely useful with these complex apps. It is important to note that this is not a legacy design, but in many cases an intentional choice these kinds of apps work incredibly well on larger screens or many screens and are very flexible (you can have any window configuration you want, and switch between them using the (usually) great window management abilities of your desktop). Of course, these apps will work terribly on tablets and small form factors, but that is not the purpose they were designed for and nobody would use them that way. I assumed for sure these features would be implemented at some point, but when it became clear that that would not happen, I created the ext-placement protocol which had some good discussion but was ultimately rejected from the xdg namespace. I then tried another solution based on feedback, which turned out not to work for most apps, and now proposed xdg-placement (v2) in an attempt to maybe still get some protocol done that we can agree on, exploring more options before pushing the existing protocol for inclusion into the ext Wayland protocol namespace. Meanwhile though, we can not port any application that needs this feature, while at the same time we are switching desktops and distributions to Wayland by default.

Window position restoration Similarly, a protocol to save & restore window positions was already proposed in 2018, 6 years ago now, but it has still not been agreed upon, and may not even help multiwindow apps in its current form. The absence of this protocol means that applications can not restore their former window positions, and the user has to move them to their previous place again and again. Meanwhile, toolkits can not adopt these protocols and applications can not use them and can not be ported to Wayland without introducing papercuts.

Window icons Similarly, individual windows can not set their own icons, and not-installed applications can not have an icon at all because there is no desktop-entry file to load the icon from and no icon in the theme for them. You would think this is a niche issue, but for applications that create many windows, providing icons for them so the user can find them is fairly important. Of course it s not the end of the world if every window has the same icon, but it s one of those papercuts that make the software slightly less user-friendly. Even applications with fewer windows like LibrePCB are affected, so much so that they rather run their app through Xwayland for now. I decided to address this after I was working on data analysis of image data in a Python virtualenv, where my code and the Python libraries used created lots of windows all with the default yellow W icon, making it impossible to distinguish them at a glance. This is xdg-toplevel-icon now, but of course it is an uphill battle where the very premise of needing this is questioned. So applications can not use it yet.

Limited window abilities requiring specialized protocols Firefox has a picture-in-picture feature, allowing it to pop out media from a mediaplayer as separate floating window so the user can watch the media while doing other things. On X11 this is easily realized, but on Wayland the restrictions posed on windows necessitate a different solution. The xdg-pip protocol was proposed for this specialized usecase, but it is also not merged yet. So this feature does not work as well on Wayland.

Automated GUI testing / accessibility / automation Automation of GUI tasks is a powerful feature, so is the ability to auto-test GUIs. This is being worked on, with libei and wlheadless-run (and stuff like ydotool exists too), but we re not fully there yet.

Wayland is frustrating for (some) application authors As you see, there is valid applications and valid usecases that can not be ported yet to Wayland with the same feature range they enjoyed on X11, Windows or macOS. So, from an application author s perspective, Wayland does break things quite significantly, because things that worked before can no longer work and Wayland (the whole stack) does not provide any avenue to achieve the same result. Wayland does break screen sharing, global hotkeys, gaming latency (via no tearing ) etc, however for all of these there are solutions available that application authors can port to. And most developers will gladly do that work, especially since the newer APIs are usually a lot better and more robust. But if you give application authors no path forward except use Xwayland and be on emulation as second-class citizen forever , it just results in very frustrated application developers. For some application developers, switching to a Wayland compositor is like buying a canvas from the Linux shop that forces your brush to only draw triangles. But maybe for your avant-garde art, you need to draw a circle. You can approximate one with triangles, but it will never be as good as the artwork of your friends who got their canvases from the Windows or macOS art supply shop and have more freedom to create their art.

Triangles are proven to be the best shape! If you are drawing circles you are creating bad art! Wayland, via its protocol limitations, forces a certain way to build application UX often for the better, but also sometimes to the detriment of users and applications. The protocols are often fairly opinionated, a result of the lessons learned from X11. In any case though, it is the odd one out Windows and macOS do not pose the same limitations (for better or worse!), and the effort to port to Wayland is orders of magnitude bigger, or sometimes in case of the multiwindow UI paradigm impossible to achieve to the same level of polish. Desktop environments of course have a design philosophy that they want to push, and want applications to integrate as much as possible (same as macOS and Windows!). However, there are many applications out there, and pushing a design via protocol limitations will likely just result in fewer apps.

The porting dilemma I spent probably way too much time looking into how to get applications cross-platform and running on Linux, often talking to vendors (FLOSS and proprietary) as well. Wayland limitations aren t the biggest issue by far, but they do start to come come up now, especially in the scientific space with Ubuntu having switched to Wayland by default. For application authors there is often no way to address these issues. Many scientists do not even understand why their Python script that creates some GUIs suddenly behaves weirdly because Qt is now using the Wayland backend on Ubuntu instead of X11. They do not know the difference and also do not want to deal with these details even though they may be programmers as well, the real goal is not to fiddle with the display server, but to get to a scientific result somehow. Another issue is portability layers like Wine which need to run Windows applications as-is on Wayland. Apparently Wine s Wayland driver has some heuristics to make window positioning work (and I am amazed by the work done on this!), but that can only go so far.

A way out? So, how would we actually solve this? Fundamentally, this excessively long blog post boils down to just one essential question: Do we want to force applications to submit to a UX paradigm unconditionally, potentially loosing out on application ports or keeping apps on X11 eternally, or do we want to throw them some rope to get as many applications ported over to Wayland, even through we might sacrifice some protocol purity? I think we really have to answer that to make the discussions on wayland-protocols a lot less grueling. This question can be answered at the wayland-protocols level, but even more so it must be answered by the individual desktops and compositors. If the answer for your environment turns out to be Yes, we want the Wayland protocol to be more opinionated and will not make any compromises for application portability , then your desktop/compositor should just immediately NACK protocols that add something like this and you simply shouldn t engage in the discussion, as you reject the very premise of the new protocol: That it has any merit to exist and is needed in the first place. In this case contributors to Wayland and application authors also know where you stand, and a lot of debate is skipped. Of course, if application authors want to support your environment, you are basically asking them now to rewrite their UI, which they may or may not do. But at least they know what to expect and how to target your environment. If the answer turns out to be We do want some portability , the next question obviously becomes where the line should be drawn and which changes are acceptable and which aren t. We can t blindly copy all X11 behavior, some porting work to Wayland is simply inevitable. Some written rules for that might be nice, but probably more importantly, if you agree fundamentally that there is an issue to be fixed, please engage in the discussions for the respective MRs! We for sure do not want to repeat X11 mistakes, and I am certain that we can implement protocols which provide the required functionality in a way that is a nice compromise in allowing applications a path forward into the Wayland future, while also being as good as possible and improving upon X11. For example, the toplevel-icon proposal is already a lot better than anything X11 ever had. Relaxing ACK requirements for the ext namespace is also a good proposed administrative change, as it allows some compositors to add features they want to support to the shared repository easier, while also not mandating them for others. In my opinion, it would allow for a lot less friction between the two different ideas of how Wayland protocol development should work. Some compositors could move forward and support more protocol extensions, while more restrictive compositors could support less things. Applications can detect supported protocols at launch and change their behavior accordingly (ideally even abstracted by toolkits). You may now say that a lot of apps are ported, so surely this issue can not be that bad. And yes, what Wayland provides today may be enough for 80-90% of all apps. But what I hope the detour into the research lab has done is convince you that this smaller percentage of apps matters. A lot. And that it may be worthwhile to support them. To end on a positive note: When it came to porting concrete apps over to Wayland, the only real showstoppers so far5 were the missing window-positioning and window-position-restore features. I encountered them when porting my own software, and I got the issue as feedback from colleagues and fellow engineers. In second place was UI testing and automation support, the window-icon issue was mentioned twice, but being a cosmetic issue it likely simply hurts people less and they can ignore it easier. What this means is that the majority of apps are already fine, and many others are very, very close! A Wayland future for everyone is within our grasp!  I will also bring my two protocol MRs to their conclusion for sure, because as application developers we need clarity on what the platform (either all desktops or even just a few) supports and will or will not support in future. And the only way to get something good done is by contribution and friendly discussion.

Footnotes
  1. Apologies for the clickbait-y title it comes with the subject
  2. When I talk about Wayland I mean the combined set of display server protocols and accepted protocol extensions, unless otherwise clarified.
  3. I would have picked a picture from our lab, but that would have needed permission first
  4. Qt has awesome platform issues pages, like for macOS and Linux/X11 which help with porting efforts, but Qt doesn t even list Linux/Wayland as supported platform. There is some information though, like window geometry peculiarities, which aren t particularly helpful when porting (but still essential to know).
  5. Besides issues with Nvidia hardware CUDA for simulations and machine-learning is pretty much everywhere, so Nvidia cards are common, which causes trouble on Wayland still. It is improving though.

Next.

Previous.