Search Results: "ag"

16 May 2013

Michael Vogt: git fast-import apt

Due to popular demand I moved debian apt and python-apt from bzr to git today. Moving was pretty painless:
$ git init
$ bzr fast-export --export-marks=marks.bzr -b debian/sid /path/to/debian-sid   git fast-import --export-marks=marks.git
And then a fast-import for the debian-wheezy and debian-experimental branches too. Then a
$ git gc --aggressive
(thanks to Guillem Jover for pointing this out) and that was it. The branches are available at:

Scott Kitterman: New ipaddress module in python3.3

Back in 2010 I packaged Google s ipaddr module because I needed a light weight IP address manipulation library that supported both IPv4 and IPv6 and (at the time) python-subnettree was IPv4 only. Well, ipaddr is all grown up now and included in python3.3 as the ipaddress manipulation module in the standard library. You can find details, as well as some description of the differences, in PEP 3144. I just converted one package that I m upstream for to use either ipaddr (for python2.6/2.7/3.2) or ipaddress instead of some custom code. It turned out to be pretty easy to make it work with either. Other than the name, the only difference I ran into was the removal of the common, generic IPAddress and IPNetwork functions that are replaced by ip_address and ip_network.
-import ipaddr
+try:
+ import ipaddress
+except ImportError:
+ import ipaddr as ipaddress

- address = ipaddr.IPAddress(ip)
- if isinstance(address, ipaddr.IPv4Address):
+ try:
+ address = ipaddress.ip_address(ip)
+ except AttributeError:
+ address = ipaddress.IPAddress(ip)
+ if isinstance(address, ipaddress.IPv4Address):
Currently, python3-ipaddr has no reverse-dependencies in the archive (python-ipaddr does). Once python3.2 is dropped from Jessie, I think I ll drop the python3-ipaddr binary on the assumption people newly coding for python3.3 should use ipaddress. The python-ipaddr module will stick around for use with python2.7.

DebConf team: DebConf13 registration extended and DebConf12 Final Report (Posted by Didier Raboud)

Dear all,
Going to DebConf13!
DebConf13 sponsorship application date extended As communicated through the debconf-announce@lists.debconf.org mailing list, the deadline to apply for DebConf13 sponsorship has been extended to the end of this week, May 19th. If you intend to attend DebConf13 in August and would like to apply for sponsored registration, now is the time to register in Penta! After this deadline you will no longer be able to apply for sponsored food, accomodation or travel. Please refer to the announcement and to the registration documentation for details. Please contact us on the debconf-discuss mailing list if you have any questions. DebConf12 final report The DebConf team is also happy to announce the release of the DebConf12 Final Report. It s a 39-page document which gives the reader an idea about the conference as a whole. It includes descriptions of talks, DebCamp and Debian Day activities, personal impressions, attendee and budgeting numbers, the work of various teams, social events and so on. If you attended Debconf12, the report may refresh some of your memories and bring you closer to the organization team work. If not, it will certainly encourage you to be part of future Debian events. We thank the Universidad Centroamericana, the Government of Nicaragua, Google and all other DebConf12 sponsors for their support that made the event possible. The DebConf team

Vincent Sanders: True art selects and paraphrases, but seldom gives a verbatim translation

In my professional life I am sometimes required to provide technical support to one of our salesmen. I find this an interesting change in pace though sometimes challenging.

Occasionally I fail to clearly convey the solution we are trying to sell because of my tendency to focus on detail the customer probably does not need to understand but I think is the interesting part of the problem.

Conversely sometimes the sales people gloss over important technology choices which have a deeper impact on the overall solution. I was recently in such a situation where as part of a larger project the subject of internationalisation (you can see why it gets abbreviated to i18n) was raised.

I had little direct personal experience with handling this within a project workflow so could not give any guidance but the salesman recommended the Transifex service as he had seen it used before, indicated integration was simple and we moved onto the next topic.

Unfortunately previous experience tells me that sometime in the near future someone is going to ask me hard technical questions about i18n and possibly how to integrate Transifex into their workflow (or at least give a good estimate on the work required).
LearningBeing an engineer I have few coping strategies available for situations when I do not know how something works. The approach I best know how to employ is to give myself a practical crash course and write up what I learned...so I did.

I proceeded to do all the usual things you do when approaching something unfamiliar (wikipedia, google, colleagues etc.) and got a basic understanding of internationalisation and localisation and how they fit together.

This enabled me to understand that the Transifex workflow proposed only covered the translation part of the problem and that, as Aldrich observed in my title quote, there is an awful lot more to translation than I suspected.
PlatformsMy research indicated that there are numerous translation platforms available for both open source and commercial projects and Transifex is one of many solutions.

Although the specific platform used was Transifex most of these observations apply to all these other platforms. The main lesson though is that all platforms are special snowflakes and once a project invests effort and time into one platform it will result in the dreaded lock in. The effort to move to another platform afterwards is at least as great as the initial implementation.

It became apparent to me that all of these services, regardless of their type, boil down to a very simple data structure. They appear to be a trivial table of Key:Language:Value wrapped in a selection of tools to perform format conversions and interfaces to manipulate the data.

There may be facilities to attach additional metadata to the table such as groupings for specific sets of keys (often referred to as resources) or translator hints to provide context but the fundamental operation is common.

The pseudo workflow is:
The first three steps are almost always performed together by the uploading of a resource file containing an initial set of translations in the "default" language and due to the world being the way it is this is almost always english (some services are so poorly tested with other defaults they fail if this is not the case!)

The platforms I looked at generally follow this pattern with a greater or lesser degree of freedom in what the keys are, how the groupings into resources are made and the languages that can be used. The most common issue with these platforms (especially open source ones) is that the input convertors will only accept a very limited number of formats and often restricted to just GNU gettext PO files. This means that to use those platforms a project would have to be able to convert any internal resources into gettext translatable format.

The prevalence of the PO format pushes assumptions into almost every platform I examined, mainly that a resource is for a single language translation and that the Key (msgid in gettext terms) is the untranslated default language string in the C locale.

The Transifex service does at least allow for the Key values to be arbitrary although the resources are separated by language.

Even assuming a project uses gettext PO files and UTF-8 character encoding (and please can we kill every other character encoding and move the whole world to UTF-8) the tools to integrate the import/export into the project must be written.

A project must decide some pretty important policies, including:
These are project policy decisions and, as I discovered, just as difficult to answer as the technical challenges.

Armed with my basic understanding it was time to move on and see how the transifex platform could be integrated into a real project workflow.
ImplementingProof of conceptMy first exercise was to take a trivial command line tool, use xgettext to generate a PO file and add the relevant libintl calls to produce gettext internationalised tool.

A transifex project was created and the english po file uploaded as the initial resource. A french language was added and the online editor used to provide translations for some strings. The PO resource file for french was exported and the tool executed with LANGUAGE=fr and the french translation seen.

This proved the trivial workflow was straightforward to implement. It also provided insight into the need to automate the process as the manual website operation would soon become exceptionally tedious and error prone.
Something more usefulTo get a better understanding of a real world workflow I needed a project that:
I selected the NetSurf web browser as it best fit this list.

Internally NetSurf keeps all the translated messages in a simple associative array this is serialised to an equally straightforward file named FatMessages. The file is UTF-8 encoded with keys separated from values by a colon. The Key is constrained to be ASCII characters with no colons and is structured as language.toolkit.identifier and is unique on identifier part alone.

This file is processed at build time into a simple identifier:value dictionary for each language and toolkit.

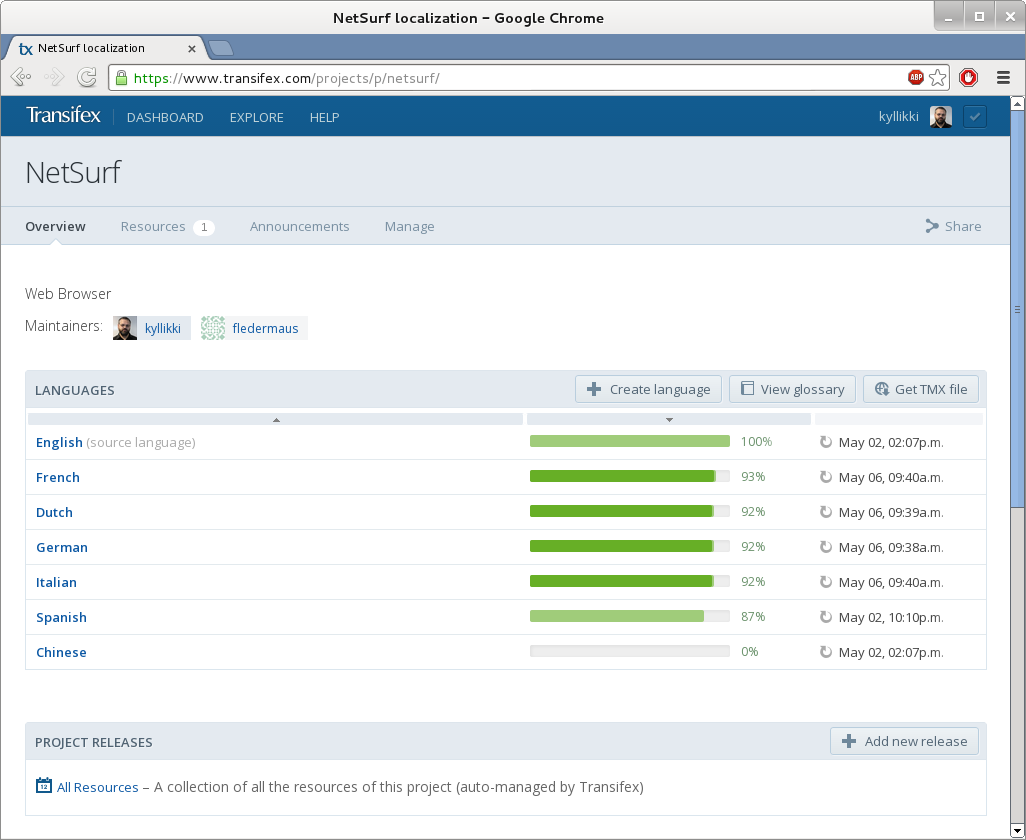
Transifex can import several resource formats similar to this, after experimenting with YAML and Android Resource format I immediately discovered a problem, the services import and export routines were somewhat buggy.

These routines coped ok with simple use cases but having more complex characters such as angle brackets and quotation marks in the translated strings would completely defeat the escaping mechanisms employed by both these formats (through entity escaping in android resource format XML is problematic anyway)

Finally the Java property file format was used (with UTF-8 encoding) which while having bugs in the import and export escaping these could at least be worked around. The existing tool that was used to process the FatMessages file was rewritten to cope with generating different output formats and a second tool to merge the java property format resources.

To create these two tools I enlisted the assistance of my colleague Vivek Dasmohapatra as his Perl language skills exceeded my own. He eventually managed to overcome the format translation issues and produce correct input and output.
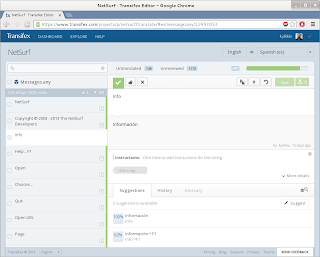
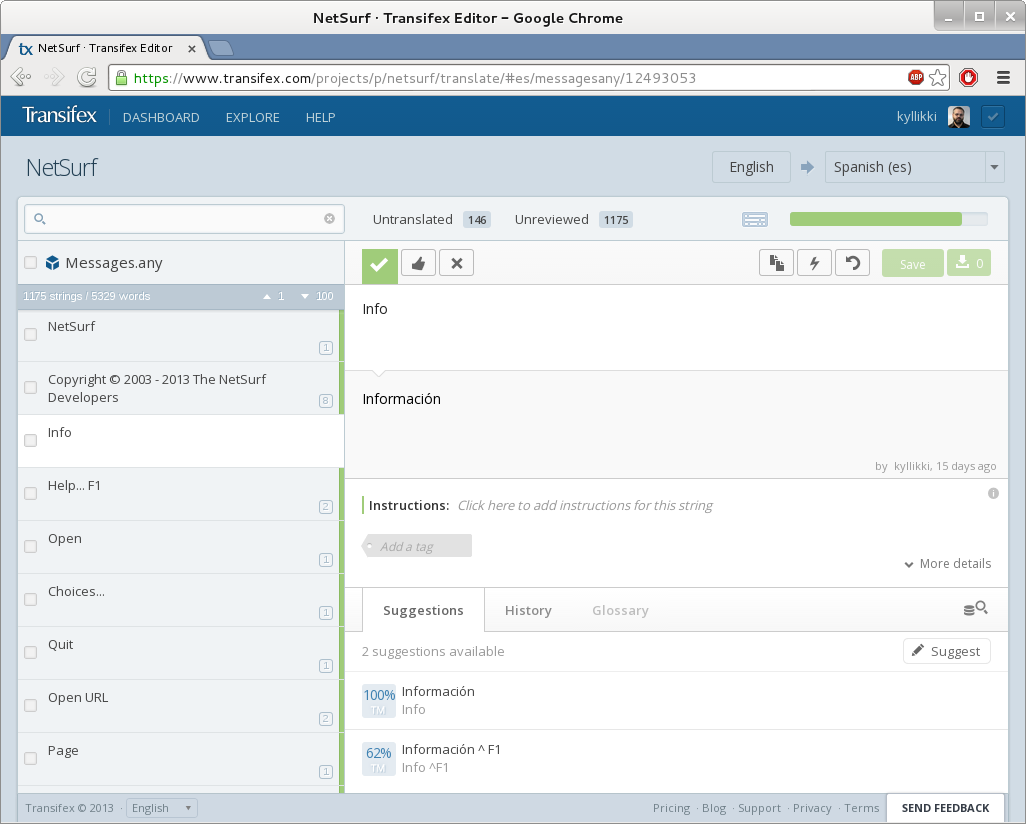
I used the Transifex platforms free open source product, created a new project and configured it for free machine translation from the Microsoft service, all of which is pretty clearly documented by Transifex.

Once this was done the messages file was split up tinto resources for the supported languages and uploaded to the transifex system.

I manually marked all the uploaded translations as "verified" and then added a few machine translations to a couple of languages. I also created spanish as a new language and machine translated most of the keys.

The resources for each language were then downloaded and merged and the resulting FatMessages file checked for differences and verified only the changes I expected appeared.

I quickly determined that manually downloading the language resources every time was not going to work with any form of automation, so I wrote a perl script to retrieve the resources automatically (might be useful for other projects too).

Once these tools were written and integrated into the build system I could finally make an evaluation as to how successful this exercise had been.
ConclusionsThe main things I learned from this investigation were:

Overall I think the final observation has to be that integrating translation services is not a straightforward operation and each project has unique challenges and requirements which reduce the existing platforms to compromise solutions.

Wouter Verhelst: Single-stepping init systems

The Linux init systems are a bit in flux at the moment. That is, they're in flux in Debian; outside Debian, most other distributions have stepped away from sysvinit and towards something else (systemd, openrc, or upstart). I've not been a proponent of any switch, though I understand the reasoning, and it probably makes sense for us to switch at some point. But yesterday, the fact that this customer's system was running sysvinit and not systemd or upstart saved me quite a bit. There's a server. It has one quadcore processor. For reasons that I won't go into here, the customer wants an extra quadcore processor to be added to the system. After having done so, I power on the system... only to see it power itself off at some point during boot. I did notice some kernel messages fly by just moments before the system would power itself off, but it was impossible for me to read them. So what did I do? That last bit is, obviously, a bit of an ugly workaround; the better way to fix this issue would have been to debug what the actual issue was, and implement a proper fix. However, I didn't have time for that (the fact that there was need for a second quadcore chip explains how much this system is in use), and the workaround was acceptable for the customer. It is not the first time that this ability to single-step the init system has saved me. The fact that sysvinit is so simplistic is what makes this possible, and I consider that one of its most important features. Recently, I came into contact with a distribution that uses systemd as its init system (in casu, Arch Linux). I had made a mistake in configuration; I had installed and enabled a graphical login system, but had no xterm or similar available, and had done something else wrong through which I couldn't get a regular shell on the console anymore, either. To fix this, I tried doing something like the above (running with init=/bin/bash and single-stepping the init system), but found that doing so with systemd is nigh impossible. In the end, I knew what exactly the problem was and could disable automatically starting the login manager through removing a symlink, but it brought home the issue that debugging a similar issue when running systemd rather than sysvinit might be a lot harder to do. We'll see what the future brings.
Daniel Pocock: Debian to rescue Skype users?

Last year at DebConf12 and the Paris mini-DebConf I mentioned some of the sophisticated techniques that the likes of Microsoft and Facebook are using to monitor their customers. So when Skype was busted spying on the content of chat messages, it was no surprise for many people in the Debian community. People are already rushing to find alternatives like XMPP and Jitsi. Debian 7 has been released just in time, with powerful features like TURN support that finally allow users to make free calls and chats with seamless NAT traversal. Sadly, Debian's built-in VoIP/RTC client, Empathy, only uses Google's TURN servers and not native Debian servers, but hopefully a solution will come soon, but it is easy enough to install Jitsi instead and configure it to use any of the free TURN server software on Debian. It should be emphasized that Skype does not just spy on URLs in chat - it has simply been possible to detect this form of spying by detecting when the URL is accessed. Microsoft has taken out various patents for secretive monitoring of Internet phone calls and the analysis of speech patterns to detect both the content and emotions during a conversation. This allows them to get a very thorough analysis of the state of mind of every user at almost every moment and fine-tune the type of advertising and branding that is delivered to that person through conventional means and also through biased news' reporting and other means.

Daniel Pocock: Debian to rescue Skype users?

Last year at DebConf12 and the Paris mini-DebConf I mentioned some of the sophisticated techniques that the likes of Microsoft and Facebook are using to monitor their customers. So when Skype was busted spying on the content of chat messages, it was no surprise for many people in the Debian community. People are already rushing to find alternatives like XMPP and Jitsi. Debian 7 has been released just in time, with powerful features like TURN support that finally allow users to make free calls and chats with seamless NAT traversal. Sadly, Debian's built-in VoIP/RTC client, Empathy, only uses Google's TURN servers and not native Debian servers, but hopefully a solution will come soon, but it is easy enough to install Jitsi instead and configure it to use any of the free TURN server software on Debian. It should be emphasized that Skype does not just spy on URLs in chat - it has simply been possible to detect this form of spying by detecting when the URL is accessed. Microsoft has taken out various patents for secretive monitoring of Internet phone calls and the analysis of speech patterns to detect both the content and emotions during a conversation. This allows them to get a very thorough analysis of the state of mind of every user at almost every moment and fine-tune the type of advertising and branding that is delivered to that person through conventional means and also through biased news' reporting and other means.

Russ Allbery: Review: Asimov's, July 2011

Review: Asimov's Science Fiction, July 2011
Editor: Sheila Williams
Issue: Volume 35, No. 7
ISSN: 1065-2698
Pages: 112
Williams's editorial is a mildly interesting piece about story titles. Silverberg's column is a more interesting (and rather convincing) rebuttal of the joke that fiction authors are "professional liars," combined with an examination of a fake and fantastic 14th travelogue that (at least in Silverberg's telling) was widely believed at the time. The precis of Silverberg's argument is that lying requires an intent to deceive, which is a property of deceptive memoir writers but not of fiction authors. Di Filippo's review column, as usual, is devoted almost entirely to esoterica, although I was moderately interested to hear of Stableford's continued work on translating early French SF. None of it seems compelling enough to go buy, but good translations of early works seem like a good thing to have in the world. "Day 29" by Chris Beckett: The conceit of this novelette is an interstellar travel system akin to a transporter that allows near-instantaneous travel between worlds. The drawback is that all memories from somewhere between 40 and 29 days before transit up until transit are wiped. The progatonist is a data analyst who is about to travel, and therefore by agency rule is required to stop doing work on day 40 before transmission since he can't be held legally liable for anything he has no recollection of doing. (I would like to say that I find this implausible, since one could always keep records, but it's exactly the sort of ass-covering regulation that a human resources department would come up with.) The premise is quite interesting: what do you do during that period that you're going to forget? Beckett wisely mixes Stephen's current waiting period on the colony world with his diary of his original waiting period on Earth the first time he went through the transmission process, and the latter adds greatly to the reader's appreciation of the weirdness of the forgotten interval. Unfortunately, this is a story more about psychological exploration than about plot, and Stephen just isn't very interesting. The telepathic but possibly nonsentient aliens add weirdness but not much else, and the ending of the story provided little sense of closure or conclusion for me. A good idea, but not the execution I wanted. (5) "Pug" by Theodora Goss: Since I grew up with a pug, I have a soft spot for a story featuring one; sadly, though, this story has insufficient pug in it. This is a quiet fantasy (Asimov's calls it SF, presumably on the basis of parallel worlds and a hypothesized scientific explanation, but it reads like fantasy to me) featuring Victorian girls, including one with a bad heart. They discover a hidden door to other versions of their world and do some minor exploration. There's little or nothing in the way of plot; the story is more of an attempt to capture a mood. It's mildly diverting, but I wish it had gone somewhere more substantial. (5) "Dunyon" by Kristine Kathryn Rusch: A Rusch story is often the highlight of an issue, and this is no exception. The protagonist is the owner of a bar in a space station that's become a combination of a refugee camp and a slum. War and chaos have created desperate people, most of whom are attempting to find some way to resources and get out of the bottom of society. The story is about a rumor: a mythical system named Dunyon that's safe and far away. And it's about how people react to that rumor. There's nothing particularly surprising about the direction the story goes (it's fairly short), but Rusch is always a good storyteller. (7) "The Music of the Sphere" by Norman Spinrad: I've had mixed feelings about Spinrad's fiction (and some of his essays), but I liked this story, despite its implausibility. It's set in the near future, featuring an expert in cetaceans and dolphin perception and a composer obsessed with both loud music and classical musical style. Just from that description, you can probably predict much of the story, but I thought it had some neat ideas about dolphins, whales, and alternate perception and aesthetics. (Note: neat, not necessarily biologically plausible.) Enjoyable. (6) "Bring on the Rain" by Josh Roseman: In a change of pace from the rest of the issue, this is a post-apocalyptic story of caravans of wheeled ships traversing a scorched and ruined landscape in search of weather systems and rain. The feel is of an inverted Waterworld, but with more emphasis on military tactics and cooperating fleets. The transposition of fleet maneuvers to huge ground vehicles adds some extra fun. The plot has little to do with the background and is a fairly stock military adventure scenario, but it's reasonably well-told. The story feels like an excerpt from a larger military-SF-inspired adventure, but the length keeps the quantity of tactics and maneuvering below the threshold where I would get bored. (6) "Twelvers" by Leah Cypess: This is a sharp and occasionally mean story of adolescent cruelty and alienation. Darla is a "twelver," a child who was carried an extra three months in the womb using newly-invented medical technology because of a belief in the advantages this would bring in later life. Unfortunately for all those who used this technique, what it also brought was a preternatural calm and an unusual reaction to emotions. Darla finds it almost impossible to get upset at anything, and that, of course, prompts the cruelty and abuse of other children. Most of the story is a description of that abuse, leading up to Darla stumbling into a nasty solution to her immediate problem. It's all very believable (well, apart from the motivating biology), but I didn't enjoy reading about it, and I'm certainly not convinced that the ending will lead to anything good. (5) "The Messenger" by Bruce McAllister: This is a very short time travel story, where time travel is used to try to unwind old family pain. This world follows the unalterable history model: no changes to the past are possible, and anything you do in the past has already happened. The mechanics are mostly avoided. Instead, McAllister concentrates on his mother, his father, and their complex relationship. I would have needed a bit more background on the characters to care enough about them for the story to be fully effective, but while the heartstring-pulling is kind of obvious, it's still a solid story. (6) "The Copenhagen Interpretation" by Paul Cornell: This is the most ingenious of the stories in this issue. It's set in a future world that extends what seemed to me to be pre-World-War-I great power politics, although there may be a hint of the Cold War. Great nations have reached a careful balance of power, and spies and secret services work to sustain that balance. The progatonist is one of those agents, making use of advanced technology like space folds in the service of a cause that he doesn't entirely believe in. Cornell mixes in mental conditioning, artificial people, space travel, and even aliens (maybe) in a taut thriller plot that, for me, gained a great deal from the unexplained strangeness of its background. If you like diving into the deep end and following a fast-moving plot against a background of strangeness, this is the sort of SF you'll enjoy. (7) Rating: 6 out of 10

15 May 2013

Russ Allbery: WebAuth 4.5.3

Good news: we finally tracked down the intermittant redirect looping bug so that I could fix it! Bad news: it was also a security vulnerability. Thankfully, it was fairly specific: you had to be using FastCGI for the login page and you also had to be using the $REMUSER_REDIRECT option. But in those situations, WebAuth versions from 4.4.1 through 4.5.2 could potentially leak authentication state from one user to another. The full scenario is somewhat tedious to explain, but the short version is that, in 4.4.1, I switched over to using a single persistent CGI::Application object instead of re-creating it for each request. This takes better advantage of FastCGI. However, CGI::Application doesn't reset header properties between requests, and while we mostly did that internally, there was one specific case around REMOTE_USER redirects where we didn't. For more details, including a patch for those who don't want to upgrade, see the security advisory. WebAuth 4.5.3 has been released with only this fix relative to 4.5.2. You can get the latest release from the official WebAuth distribution site or from my WebAuth distribution pages.

Lisandro Damián Nicanor Pérez Meyer: Qt 4.8.4 in experimental.

Since a few days we have Qt 4.8.4 (4:4.8.4+dfsg-3) in some archs of the experimental Debian archive. This release allows Qt4 to coexist with Qt5 while avoiding FTBFSs of current Qt4 packages in the archive.

So if you maintain a Qt4 app and want to check how it works with 4.8.4, you should be ready to go.

Benjamin Mako Hill: Sounds Like a Map

Colored visualization of the puzzle. I love maps something that became clear to me when I was looking at the tag cloud of my bookmarks a few years back. One of my favorite blogs (now a book) is Frank Jabobs Strange Maps. So it s no coincidence that a number of my favorite MIT Mystery Hunt puzzles are map based. Trying to connect the two worlds, I sent Jacobs a write-up of the hunt and of a particularly strange sound-based map puzzle called White Noise that I worked with Don Armstrong to solve in the 2006 hunt. While I wasn t paying attention, Jacobs did a very nice writeup of my writeup of the puzzle for Strange Maps!

Craig Small: itools is back

My last post I said that I had to remove my internet query tools due to some bugs that were a concern. Some of the code was hard to maintain and probably had holes and I had noticed that it looped at times. I m happy to say that I have restored some of those tools now, still located at http://enc.com.au/itools This code is completely re-written in Python using the TurboGears toolkit which means it is a lot cleaner in how it works and how it looks. Some of the lookup tables use a database rather than an array for ease of updating and querying. The downside is the backends will take time. It currently only does nslookup queries and whois only works for IPv4 addresses. The domain name queries will be a while off as these are the most complicated to handle. To give you an idea, all IPv4 and IPv6 address information comes from 5 sources with two formats while domain names come from over 200 sources with about 40 formats. This means the information from Regional Internet Registries will be done first.

Bastian Venthur: How to get the most precise time, comparable between processes in Python?

Let s consider the following scenario: I have two Python processes receiving the same events and I have to measure the delay between when process A received the event and when process B received it, as precisely as possible (i.e. less than 1ms). Using Python 2.7 and a Unix system you can use the time.time method which provides the time in seconds since Epoch and has a typical resolution of a fraction of a ms on Unix. You can use it on different processes and still compare the results, since both processes receive the time since Epoch, a defined and fixed time in the past. On Windows time.time also provides the time since Epoch, but the resolution is in the range of 10ms, which is not suitable for my application. There is also time.clock which is super precise on Windows, and much less precise on Unix. The mayor drawback is that it returns the time since the process started or since the first call of time.clock within that processes. This means you cannot compare the results of time.clock between two processes as they are not calibrated to a common t-zero. I had high hopes for Python 3.3 where the time module was revamped and I was reading about time.monotonic and time.perf_counter. Especially time.perf_counter looked like it would suit my needs as the documentation said it provides the highest available resolution for the system and was system-wide , in contrast to for example the new time.process_time which was process_wide . Unfortunately it turned out that time.perf_counter acts similar to time.clock on Python 2.7 as it provides you with the time since the process started or the first time the method was called within the process. The results of time.monotonic are comparable between processes, but again not precise enough on Windows. Here is a small script which demonstrates how the times provided by time.clock and time.perf_counter are not comparable between processes. It starts two processes and lets both of them print out the output of the timer to stdout. In the output the times should be monotonically increasing. Since I let process 2 sleep for one second before calling the timer method for the first time, the output of this process is usually one second smaller when using time.clock or time.perf_counter.
#!/usr/bin/env python
from multiprocessing import Process
import time
timers = ['clock', 'time', 'monotonic', 'perf_counter']
def proc(timer):
    timer = getattr(time, timer)
    time.sleep(1)
    for i in range(3):
        print('P2  time '.format(time=timer()))
        time.sleep(1)
if __name__ == '__main__':
    for t in timers:
        print("Using  timer ".format(timer=t))
        p = Process(target=proc, args=(t,))
        timer = getattr(time, t)
        p.start()
        for i in range(3):
            print('P1  time '.format(time=timer()))
            time.sleep(1)
        p.join()
The result when running on Windows with Python 3.3:
$ python timertest.py
Using clock
P1 6.146032526480321e-06
P1 0.9926582847820045
P2 2.9612702173041547e-05
P1 1.9941743992602412
P2 1.0008579302676737
P2 2.0022709590185346
Using time
P1 1368614235.509732
P1 1368614236.511172
P2 1368614236.601301
P1 1368614237.512612
P2 1368614237.602741
P2 1368614238.604181
Using monotonic
P1 484.636
P1 485.63800000000003
P2 485.738
P1 486.639
P2 486.73900000000003
P2 487.741
Using perf_counter
P1 12.390910576623565
P1 13.39050745276285
P2 7.542858100680394e-06
P1 14.39190763071843
P2 1.0014012954160376
P2 2.0041399116368144
So as far as I see it, there is no way of getting comparable times between two processes on Windows with more precision than 10ms. Is that correct or am I missing something?

Ian Wienand: Debugging puppetmaster with Foreman

This is a little note for anyone trying to get some debugging out of the puppetmaster when deploying with Foreman. The trick, much as it is, is that Foreman is running puppet via Apache; so if you're trying to start a puppet master daemon outside that it won't be able to bind to port 8140. You thus want to edit the config file Apache is using to launch puppet /etc/puppet/rack/config.ru. It's probably pretty obvious what's happening when you look in there; simply add
ARGV << "--debug"
and you will start to get debugging output. One issue is that this goes to syslog (/var/log/messages) by default and is a lot of output; so much so that it might get throttled. Although you can certainly reconfigure your syslog daemon to split out puppet logs, an easier way is to just skip syslog while you're debugging. Don't be fooled by config options; simply add
ARGV << "--logdest" << "/var/log/puppet/puppet-master.debug"
to the same file to get the logs going to a separate file. Don't forget to restart Apache so the changes stick.

Russ Allbery: WebAuth 4.5.2

Last weekend, I spent several hours carefully going over some of the WebLogin code to try to track down a weird bug that we ran into in our UAT environment. The bad part is that I didn't find it, although restarting Apache made it disappear. The good part is that I found a bunch of other bugs that would have been troublesome later. This release is just a WebLogin bug fix release, cleaning up those issues plus a few other things we've found in testing for our upcoming production upgrade. Specifically, there's now a way to preserve remember_login across a failed login attempt, clearing of failed login attempts after a successful one works properly, cookies are set correctly on the error page, and WebLogin no longer erroneously clears cookies when redirecting to check for cookie support. You can get the latest release from the official WebAuth distribution site or from my WebAuth distribution pages.

Daniel Kahn Gillmor: OpenPGP User ID Comments considered harmful

Most OpenPGP User IDs look like this:

Jane Q. Public <jane@example.org>
This is clean, clear, and unambiguous. However, some tools (gpg, enigmail among others) ask the user to provide a "Comment:" field when they are choosing a new User ID (e.g. when making a new key). These UI prompts are evil. The savvy user knows to avoid entering anything in this field, so that they can end up with a User ID like the one above. The user who provides something here (perhaps even something inconsequential like "I like strawberries", due to not being sure what should go in this little box) will instead end up with a User ID like:
Jane Q. Public (I like strawberries) <jane@example.org>
This is bad. This means that Jane is asking the people who certify her key+userid to certify whether she actually likes strawberries (how could they know? what if she changes her mind? should they revoke their certifications?) and anywhere that she is referred to by name will include this mention of strawberries. This is not Jane's identity, and it doesn't belong in an OpenPGP User ID packet. Furthermore, since User IDs are atomic, if Jane wants to change the comment field (but leave her name and e-mail address the same), she will instead need to create a new User ID, publish it, get everyone who has certified her old key+userid to certify the key+newuserid, and then revoke the old one. It is difficult already to help people understand and participate in the certification network that forms that backbone of OpenPGP's so-called "web of trust". These bogus comment fields make an already-difficult task harder. And all because of strawberries! Tools like enigmail and gpg should not expose the "Comment:" field to users who are generating keys or choosing new User IDs. If they feel it absolutely must be present for some weird corner case that 0.1% of their users will have, they could require that the user enters some sort of "expert mode" before prompting the user to do something that is likely to be a mistake. There is almost no legitimate reason for anyone to use this field. Let's go through some examples of this people use, taken from some examples i have lying around (identifying marks have been changed to protect the innocent who were duped by this bad UI choice, but you can probably find them on the public keyserver network if you want to hunt around):
domain repetition
John Q. Public (Debian) <johnqpublic@debian.org>
We know you're with debian already from the @debian.org address. If this is in contrast to your other address (johnqpublic@example.org) so that people know where to send you debian-related e-mail, this is still not necessary. Lest you think i'm just calling out debian developers, people with @ubuntu.com addresses and (Ubuntu) comments (as well as @example.edu addresses and (Example University) comments and @example.com addresses and (Example Corp) comments) are out there too.
nicknames already evident
John Q. Public (Johnny) <johnqpublic@example.net>
John Q. Public (wackydude) <wackydude@example.net>
Again, the information these comments are providing offers no clear disambiguation from the info already contained in the name and e-mail address, and just muddies the water about what the people who certify this identity should actually be trying to verify before they make their certification.
"Work"
John Q. Public (Work) <johnqpublic@example.com>
if John's correspondents know that he works for Example Corp, then "Work" isn't helpful to them, because they already know this as the address that they're writing to him with. If they don't know that, then they probably aren't writing to him at work, so they don't need this comment either. The same problem appears (for example) with literal comments of (School) next to their @example.edu address.
This is my nth try at this crazy system!
John Q. Public (This is my second key) <johnqpublic@example.com>
John Q. Public (This is my primary key) <johnqpublic@example.com>
John Q. Public (No wait really use this one) <johnqpublic@example.com>
OpenPGP is confusing, and it can be tricky to get it right. We all know :) This is still not part of John's identity. If you want to designate a key as your preferred key, keep it up-to-date, get people to certify it, and revoke or expire your old keys. People who care can look at the timestamps on your keys and tell which ones are the most recent ones. You do have a revocation certificate for your key handy just in case you lose it, right?
Don't use this key
John Q. Public (Old key, do not use) <johnqpublic@example.com>
John Q. Public (Please only use this through September 2004) <johnqpublic@example.com>
This kind of sentiment is better expressed by revoking the key in question or setting an expiration time on the key or User ID self-sig directly. This sentiment is not part of John's identity, and shouldn't be included as though it were.
"none"
John Q. Public (none) <johnqpublic@example.com>
sigh. This is clearly someone getting mixed up by the UI.
I use strong crypto!
John Q. Public (3092 bits of RSA) <johnqpublic@example.com>
This comment refers to the strength of the key material, or the algorithms preferred by the user. Since the User ID is associated with the key material already, people who care about this information can get it from the key directly. This is also not part of the user's actual identity.
"no comment"
John Q. Public (no comment) <johnqpublic@example.com>
This is actually not uncommon (some keyservers reply "too many matches!"). It shows that the user is witty and can think on their feet (at least once), but it is still not part of the user's identity.
But wait (i hear you say)! I have a special case that actually is a legitimate use of the comment field that cannot be expressed in OpenPGP in any other way! I'm sure that such cases exist. I've even seen one or two of them. The fact that one or two cases exist does not excuse the fact that that overwhelming majority of these comments in OpenPGP User IDs are a mistake, caused only by bad UI design that prompts people to put something (anything!) in the empty box (or on the command prompt, depending on your preference). And this mistake is one of the thousand papercuts that inhibits the robust growth of the OpenPGP certification network that some people call the "web of trust". Let's avoid them so we can focus on the other 999 papercuts. Please don't use comments in your OpenPGP User ID. And if you make a user interface for OpenPGP that prompts the user to decide on a new User ID, please don't include a prompt for "Comment" unless the user has already certified that they are really and truly a special special snowflake. Thanks!Tags: openpgp, ui

14 May 2013

Petter Reinholdtsen: Second alpha release of Debian Edu / Skolelinux based on Debian Wheezy

The Debian Edu / Skolelinux project is making great progress and made its second Wheezy based release today. This is the release announcement: New features for Debian Edu 7.0.0 alpha1 released 2013-05-14 This is the release notes for for Debian Edu / Skolelinux 7.0.0 edu alpha1, based on <ahref>Debian with codename "Wheezy". About Debian Edu and Skolelinux Debian Edu, also known as Skolelinux, is a Linux distribution based on Debian providing an out-of-the box environment of a completely configured school network. Immediatly after installation a school server running all services needed for a school network is set up just waiting for users and machines being added via GOsa , a comfortable Web-UI. A netbooting environment is prepared using PXE, so after initial installation of the main server from CD, DVD or USB stick all other machines can be installed via the network. This is the first test release based on Wheezy (which currently is not released yet). Basically this is an updated and slightly improved version compared to the Squeeze release. Software updates Other changes Known issues Where to get it To download the multiarch netinstall CD release you can use The MD5SUM of this image is: 685ed76c1aa8e44b12d3fde21faf450b The SHA1SUM of this image is: 6c874de157024da13e115bab29c068080a11ec4c How to report bugs http://wiki.debian.org/DebianEdu/HowTo/ReportBugs

Russ Allbery: backport 1.30

Debian wheezy has been released (yay!), so I've updated my backport script to backport to wheezy by default and shuffled the meanings of stable and oldstable. The whole script badly needs a rewrite and needs to become more configuration-driven, but I sadly don't have the time at the moment, so will have to make do with this. If anyone else is using it, you can get the latest copy from my scripts page. Also done: suite names changed for local Stanford repositories. jessie added to our local Debian mirroring. reprepro pull rules changed accordingly. All local build chroots updated, with new ones created for wheezy and wheezy-backports. Still to do: update suite names and pull rules for the eyrie.org Debian repository (which isn't used much any more). Delete the old per-service lenny-based distributions, since we've gotten everything off of lenny that cared about them. Add a new jessie build chroot to our local build servers. Update our FAI installation to build wheezy by default and to use a wheezy NFS root. reprepro makes this whole process so massively easier than it was with debarchiver.

Steve Kemp: Some good, some bad

Today my main machine was down for about 8 hours. Oops. That meant when I got home, after a long and dull train journey, I received a bunch of mails from various hosts each saying: Slaughter is my sysadmin utility which pulls policies/recipies from a central location and applies them to the local host. Slaughter has a bunch of different transports, which are the means by which policies and files are transferred from the remote "central host" to the local machine. Since git is supported I've now switched my policies to be fetched from the master github repository. This means: In other news I've fettled with lumail a bit this week, but I'm basically doing nothing until I've pondered my way out of the hole I've dug myself into. Like mutt lumail has the notion of "limiting" the display of things: Unfortunately the latter has caused an annoying, and anticipated, failure case. If you open a folder and cause it to only show unread messages all looks good. Until you read a message. At which point it is no longer allowed to be displayed, so it disappears. Since you were reading a message the next one is opened instead. WHich then becomes marked as read, and no longer should be displayed, because we've said "show me new/unread-only messages please". The net result is if you show only unread messages and make the mistake of reading one .. you quickly cycle through reading all of them, and are left with an empty display. As each message in turn is opened, read, and marked as non-new. There are solutions, one of which I documented on the issue. But this has a bad side-effect that message navigation is suddenly complicated in ways that are annoying. For the moment I'm mulling the problem over and I will only make trivial cleanup changes until I've got my head back in the game and a good solution that won't cause me more pain.

Ben Hutchings: That perf root exploit (CVE-2013-2094)

There's some exploit code going around that will let you get root on a range of Linux kernel versions by using a bug in the perf_event_open() syscall. The fix for this is in 3.2.45 and various other stable updates. As a workaround, until it's in Debian stable, you can set sysctl kernel.perf_event_paranoid=2. This blocks the exploit I've seen, but it is still possible to get around this restriction. Red Hat has a SystemTap script that should provide more complete mitigation. The debuginfo packages for Debian kernels are named e.g. linux-image-3.2.0-4-amd64-dbg. They are only provided for some architectures and flavours. Updated: Added the CVE ID. Added SystemTap information.

Next.

Previous.