Search Results: "cts"

24 June 2022

Reproducible Builds: Supporter spotlight: Hans-Christoph Steiner of the F-Droid project

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fifth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent ones about ARDC, the Google Open Source Security Team (GOSST) and Jan Nieuwenhuizen on Bootstrappable Builds, GNU Mes and GNU Guix. Today, however, we will be talking with Hans-Christoph Steiner from the F-Droid project.

Chris: Welcome, Hans! Could you briefly tell me about yourself? Hans: Sure. I spend most of my time trying to private communications software usable by everyone, designing interactive software with a focus on human perceptual capabilities and building networks with free software. I ve been involved in Debian since approximately 2008 and became an official Debian developer in 2011. In the little time left over from that, I sometimes compose music with computers from my home in Austria.
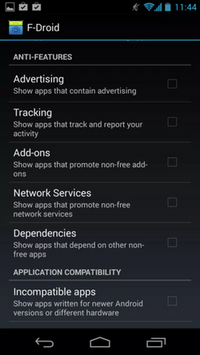
Chris: For those who have not heard of it before, what is the F-Droid project? Hans: F-Droid is a community-run app store that provides free software applications for Android phones. First and foremost our goal is to represent our users. In particular, we review all of the apps that we distribute, and these reviews not only check for whether something is definitely free software or not, we additionally look for ethical problems with applications as well issues that we call Anti-Features . Since the project began in 2010, F-Droid now offers almost 4,000 free-software applications. F-Droid is also a app store kit as well, providing all the tools that are needed to operate an free app store of your own. It also includes complete build and release tools for managing the process of turning app source code into published builds.
Chris: How exactly does F-Droid differ from the Google Play store? Why might someone use F-Droid over Google Play? Hans: One key difference to the Google Play Store is that F-Droid does not ship proprietary software by default. All apps shipped from f-droid.org are built from source on our own builders. This is partly because F-Droid is backed by the free software community; that is, people who have engaged in the free software community long before Android was conceived, and, in particular, share many if not all of its values. Using F-Droid will therefore feel very familiar to anyone familiar with a modern Linux distribution.
Chris: How do you describe reproducibility from the F-Droid point of view? Hans: All centralised software repositories are extremely tempting targets for exploitation by malicious third parties, and the kinds of personal or otherwise sensitive data on our phones only increase this risk. In F-Droid s case, not only could the software we distribute be theoretically replaced with nefarious copies, the build infrastructure that generates that software could be compromised as well. F-Droid having reproducible builds is extremely important as it allows us to verify that our build systems have not been compromised and distributing malware to our users. In particular, if an independent build infrastructure can produce precisely the same results from a build, then we can be reasonably sure that they haven t been compromised. Technically-minded users can also validate their builds on their own systems too, further increasing trust in our build infrastructure. (This can be performed using fdroid verify command.) Our signature & trust scheme means that F-Droid can verify that an app is 100% free software whilst still using the developer s original .APK file. More details about this may be found in our reproducibility documentation and on the page about our Verification Server.
Chris: How do you see F-Droid fitting into the rest of the modern security ecosystem? Hans: Whilst F-Droid inherits all of the social benefits of free software, F-Droid takes special care to respect your privacy as well we don t attempt to track your device in any way. In particular, you don t need an account to use the F-Droid client, and F-Droid doesn t send any device-identifying information to our servers other than its own version number. What is more, we mark all apps in our repository that track you, and users can choose to hide any apps that has been tagged with a specific Anti-Feature in the F-Droid settings. Furthermore, any personal data you decide to give us (such as your email address when registering for a forum account) goes no further than us as well, and we pledge that it will never be used for anything beyond merely maintaining your account.
Chris: What would fully reproducible mean to F-Droid? What it would look like if reproducibility was a solved problem ? Or, rather, what would be your ultimate reproducibility goals? Hans: In an ideal world, every application submitted to F-Droid would not only build reproducibly, but would come with a cryptographically-signed signature from the developer as well. Then we would only distribute an compiled application after a build had received a number of matching signatures from multiple, independent third parties. This would mean that our users were not placing their trust solely in software developers machines, and wouldn t be trusting our centralised build servers as well.
Chris: What are the biggest blockers to reaching this state? Are there any key steps or milestones to get there? Hans: Time is probably the main constraint to reaching this goal. Not only do we need system administrators on an ongoing basis but we also need to incorporate reproducibly checks into our Continuous Integration (CI) system. We are always looking for new developers to join our effort, as well as learning about how to better bring them up to speed. Separate to this, we often experience blockers with reproducibility-related bugs in the Android build tooling. Luckily, upstreams do ultimately address these issues, but in some cases this has taken three or four years to reach end-users and developers. Unfortunately, upstream is not chiefly concerned with the security aspects of reproducibility builds; they care more about how it can minimise and optimise download size and speed.
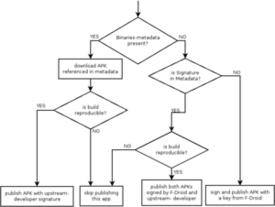
Chris: Are you tracking any statistics about reproducibility in F-Droid over time? If so, can you share them? Does F-Droid track statistics about its own usage? Hans: To underline a topic touched on above, F-Droid is dedicated to preserving the privacy of its users; we therefore do not record usage statistics. This is, of course, in contrast to other application stores. However, we are in a position to track whether packages in F-Droid are reproducible or not. As in: what proportion of APKs in F-Droid have been independently verified over time? Unfortunately, due to time constraints, we do not yet automatically publish charts for this. We do publish some raw data that is related, though, and we naturally welcome contributions of visualizations based on any and all of our data. The All our APIs page on our wiki is a good place to start for someone wanting to contribute, everything about reproducible F-Droid apps is available in JSON format, what s missing are apps or dashboards making use of the available raw data.
Chris: Many thanks for this interview, Hans, and for all of your work on F-Droid and elsewhere. If someone wanted to get in touch or learn more about the project, where might someone go? Hans: The best way to find out about F-Droid is, of course, the main F-Droid homepage, but we are also on Twitter @fdroidorg. We have many avenues to participate and to learn more! We have an About page on our website and a thriving forum. We also have part of our documentation specifically dedicated to reproducible builds.


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.


Russ Allbery: Review: A Dead Djinn in Cairo

Review: A Dead Djinn in Cairo, by P. Dj l Clark
Publisher: Tordotcom
Copyright: May 2016
ASIN: B01DJ0NALI
Format: Kindle
Pages: 47
Fatma el-Sha'arawi is a special investigator with the Egyptian Ministry of Alchemy, Enchantments, and Supernatural Entities in an alternate 1912 Egypt. In Fatma's world, the mystic al-Jahiz broke through to the realm of the djinn in the late 1800s, giving Egypt access to magic and the supernatural and the djinn access to Egypt. It is now one of the great powers of the world, able to push off the Europeans and control its own politics. This is a Tor.com original novelette, so you can read it on-line for free or drop $2 on a Kindle version for convenience. It's the first story in the "Dead Djinn" universe, in which Clark has also written a novella and a novel (the latter of which won the Nebula Award for best novel in 2022). There are three things here I liked. Fatma is a memorable character, both for her grumpy demeanor as a rare female investigator having to put up with a sexist pig of a local police liaison, and for her full British attire (including a bowler hat) and its explanation. (The dynamics felt a bit modern for a story set in 1912, but not enough to bother me.) The setting is Arabian-inspired fantasy, which is a nice break from the normal European or Celtic stuff. And there are interesting angels (Fatma: "They're not really angels"), which I think have still-underused potential, particularly when they can create interesting conflicts with Coptic Christianity and Islam. Clark's version are energy creatures of some sort inside semi-mechanical bodies with visuals that reminded me strongly of Diablo III (which in this context is a compliment). I'm interested to learn more about them, although I hope there's more going on than the disappointing explanation we get at the end of this story. Other than those elements, there's not much here. As hinted by the title, the story is structured as a police investigation and Fatma plays the misfit detective. But there's no real mystery; the protagonists follow obvious clue to obvious clue to obvious ending. The plot structure is strictly linear and never surprised me. Aasim is an ass, which gives Fatma something to react to but never becomes real characterization. The world-building is the point, but most of it is delivered in infodumps, and the climax is a kind-of-boring fight where the metaphysics are explained rather than discovered. I'm possibly being too harsh. There's space for novelettes that tell straightforward stories without the need for a twist or a sting. But I admit I found this boring. I think it's because it's not tight enough to be carried by the momentum of a simple plot, and it's also not long enough for either the characters or the setting to breathe and develop. The metaphysics felt rushed and the characterization cramped. I liked Siti and the dynamic between Siti and Fatma at the end of the story, but there wasn't enough of it. As a world introduction, it does its job, and the non-European fantasy background is interesting enough that I'd be willing to read more, even without the incentive of reading all award winning novels. But "A Dead Djinn in Cairo" doesn't do more than its job. It might be worth skipping (I'll have to read the subsequent works to know for certain), but it won't take long to read and the price is right. Followed by The Haunting of Tram Car 015. Rating: 6 out of 10

23 June 2022

Raphaël Hertzog: Freexian s report about Debian Long Term Support, May 2022

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding Two [1, 2] projects are in the pipeline now. Tryton project is in a final phase. Gradle projects is fighting with technical difficulties. In May, we put aside 2233 EUR to fund Debian projects. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In May, 14 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In May we released 49 DLAs. The security tracker currently lists 71 packages with a known CVE and the dla-needed.txt file has 65 packages needing an update. The number of paid contributors increased significantly, we are pleased to welcome our latest team members: Andreas R nnquist, Dominik George, Enrico Zini and Stefano Rivera. It is worth pointing out that we are getting close to the end of the LTS period for Debian 9. After June 30th, no new security updates will be made available on security.debian.org. We are preparing to overtake Debian 10 Buster for the next two years and to make this process as smooth as possible. But Freexian and its team of paid Debian contributors will continue to maintain Debian 9 going forward for the customers of the Extended LTS offer. If you have Debian 9 servers to keep secure, it s time to subscribe! You might not have noticed, but Freexian formalized a mission statement where we explain that our purpose is to help improve Debian. For this, we want to fund work time for the Debian developers that recently joined Freexian as collaborators. The Extended LTS and the PHP LTS offers are built following a model that will help us to achieve this if we manage to have enough customers for those offers. So consider subscribing: you help your organization but you also help Debian! Thanks to our sponsors Sponsors that joined recently are in bold.

21 June 2022

John Goerzen: Lessons of Social Media from BBSs

In the recent article The Internet Origin Story You Know Is Wrong, I was somewhat surprised to see the argument that BBSs are a part of the Internet origin story that is often omitted. Surprised because I was there for BBSs, and even ran one, and didn t really consider them part of the Internet story myself. I even recently enjoyed a great BBS documentary and still didn t think of the connection on this way. But I think the argument is a compelling one.
In truth, the histories of Arpanet and BBS networks were interwoven socially and materially as ideas, technologies, and people flowed between them. The history of the internet could be a thrilling tale inclusive of many thousands of networks, big and small, urban and rural, commercial and voluntary. Instead, it is repeatedly reduced to the story of the singular Arpanet.
Kevin Driscoll goes on to highlight the social aspects of the modem world , how BBSs and online services like AOL and CompuServe were ways for people to connect. And yet, AOL members couldn t easily converse with CompuServe members, and vice-versa. Sound familiar?
Today s social media ecosystem functions more like the modem world of the late 1980s and early 1990s than like the open social web of the early 21st century. It is an archipelago of proprietary platforms, imperfectly connected at their borders. Any gateways that do exist are subject to change at a moment s notice. Worse, users have little recourse, the platforms shirk accountability, and states are hesitant to intervene.
Yes, it does. As he adds, People aren t the problem. The problem is the platforms. A thought-provoking article, and I think I ll need to buy the book it s excerpted from!

20 June 2022

Petter Reinholdtsen: My free software activity of late (2022)

I guess it is time to bring some light on the various free software and open culture activities and projects I have worked on or been involved in the last year and a half. First, lets mention the book releases I managed to publish. The Cory Doctorow book "Hvordan knuse overv kningskapitalismen" argue that it is not the magic machine learning of the big technology companies that causes the surveillance capitalism to thrive, it is the lack of trust busting to enforce existing anti-monopoly laws. I also published a family of dictionaries for machinists, one sorted on the English words, one sorted on the Norwegian and the last sorted on the North S mi words. A bit on the back burner but not forgotten is the Debian Administrators Handbook, where a new edition is being worked on. I have not spent as much time as I want to help bring it to completion, but hope I will get more spare time to look at it before the end of the year. With my Debian had I have spent time on several projects, both updating existing packages, helping to bring in new packages and working with upstream projects to try to get them ready to go into Debian. The list is rather long, and I will only mention my own isenkram, openmotor, vlc bittorrent plugin, xprintidle, norwegian letter style for latex, bs1770gain, and recordmydesktop. In addition to these I have sponsored several packages into Debian, like audmes. The last year I have looked at several infrastructure projects for collecting meter data and video surveillance recordings. This include several ONVIF related tools like onvifviewer and zoneminder as well as rtl-433, wmbusmeters and rtl-wmbus. In parallel with this I have looked at fabrication related free software solutions like pycam and LinuxCNC. The latter recently gained improved translation support using po4a and weblate, which was a harder nut to crack that I had anticipated when I started. Several hours have been spent translating free software to Norwegian Bokm l on the Weblate hosted service. Do not have a complete list, but you will find my contributions in at least gnucash, minetest and po4a. I also spent quite some time on the Norwegian archiving specification Noark 5, and its companion project Nikita implementing the API specification for Noark 5. Recently I have been looking into free software tools to do company accounting here in Norway., which present an interesting mix between law, rules, regulations, format specifications and API interfaces. I guess I should also mention the Norwegian community driven government interfacing projects Mimes Br nn and Fiksgatami, which have ended up in a kind of limbo while the future of the projects is being worked out. These are just a few of the projects I have been involved it, and would like to give more visibility. I'll stop here to avoid delaying this post. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

19 June 2022

Dirk Eddelbuettel: #38: Faster Feedback Systems

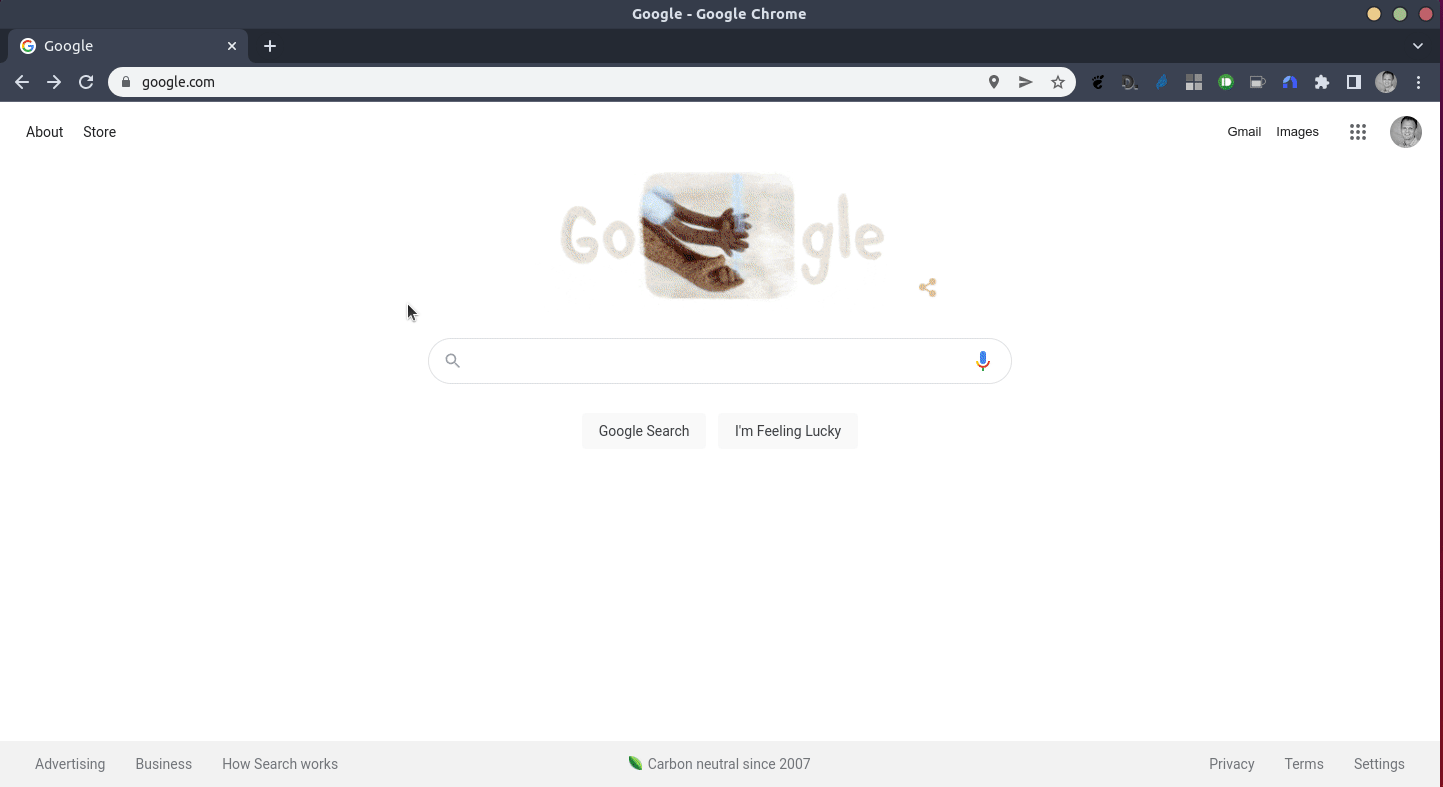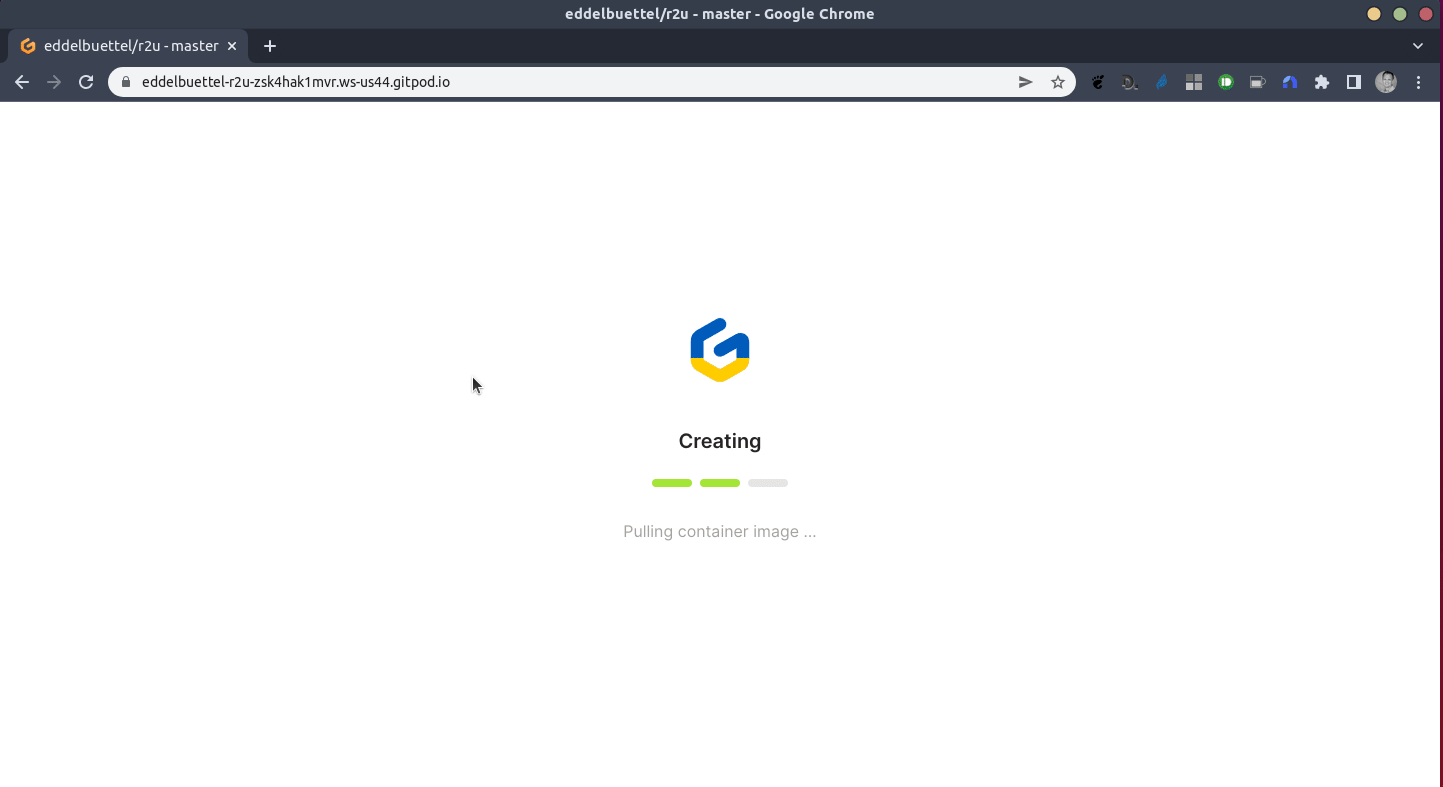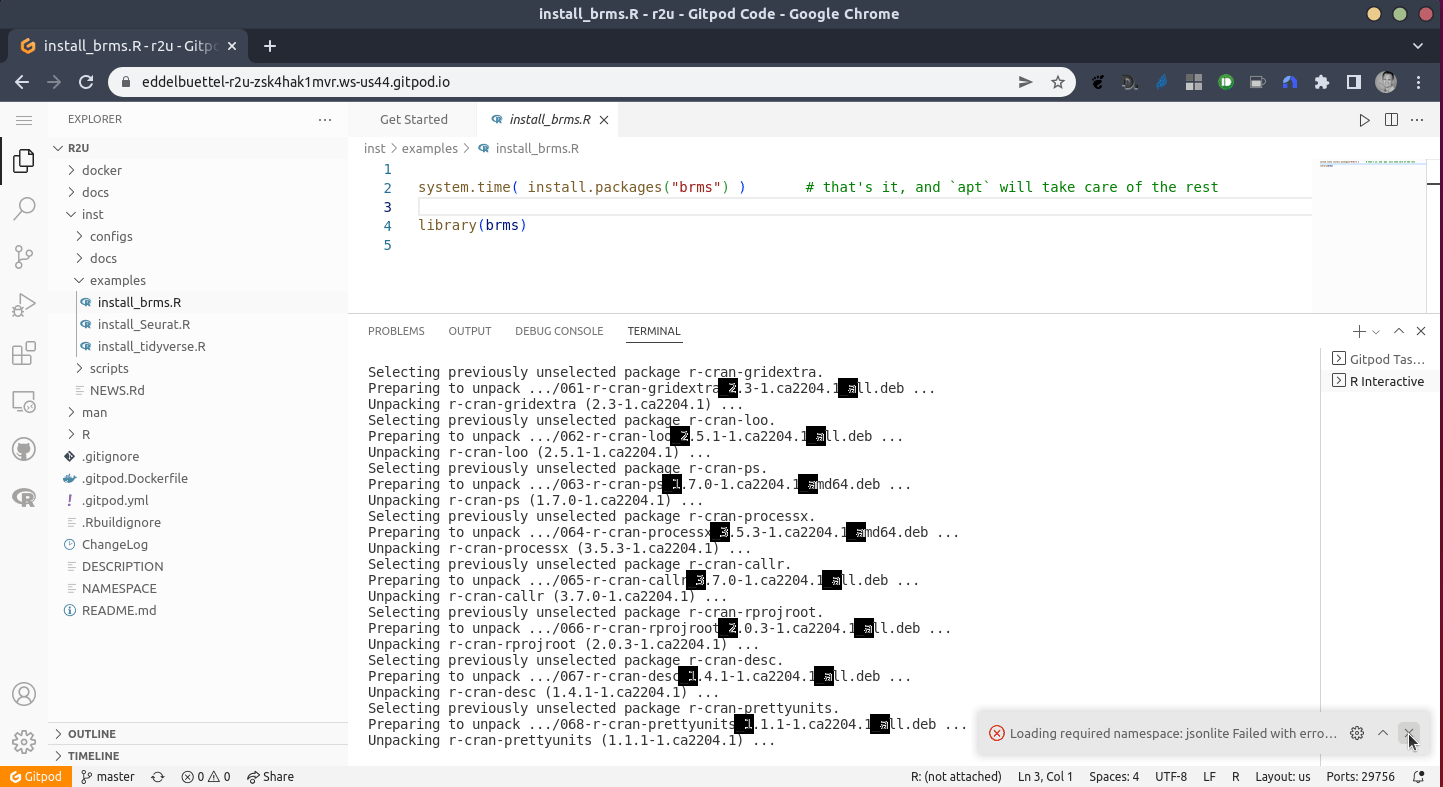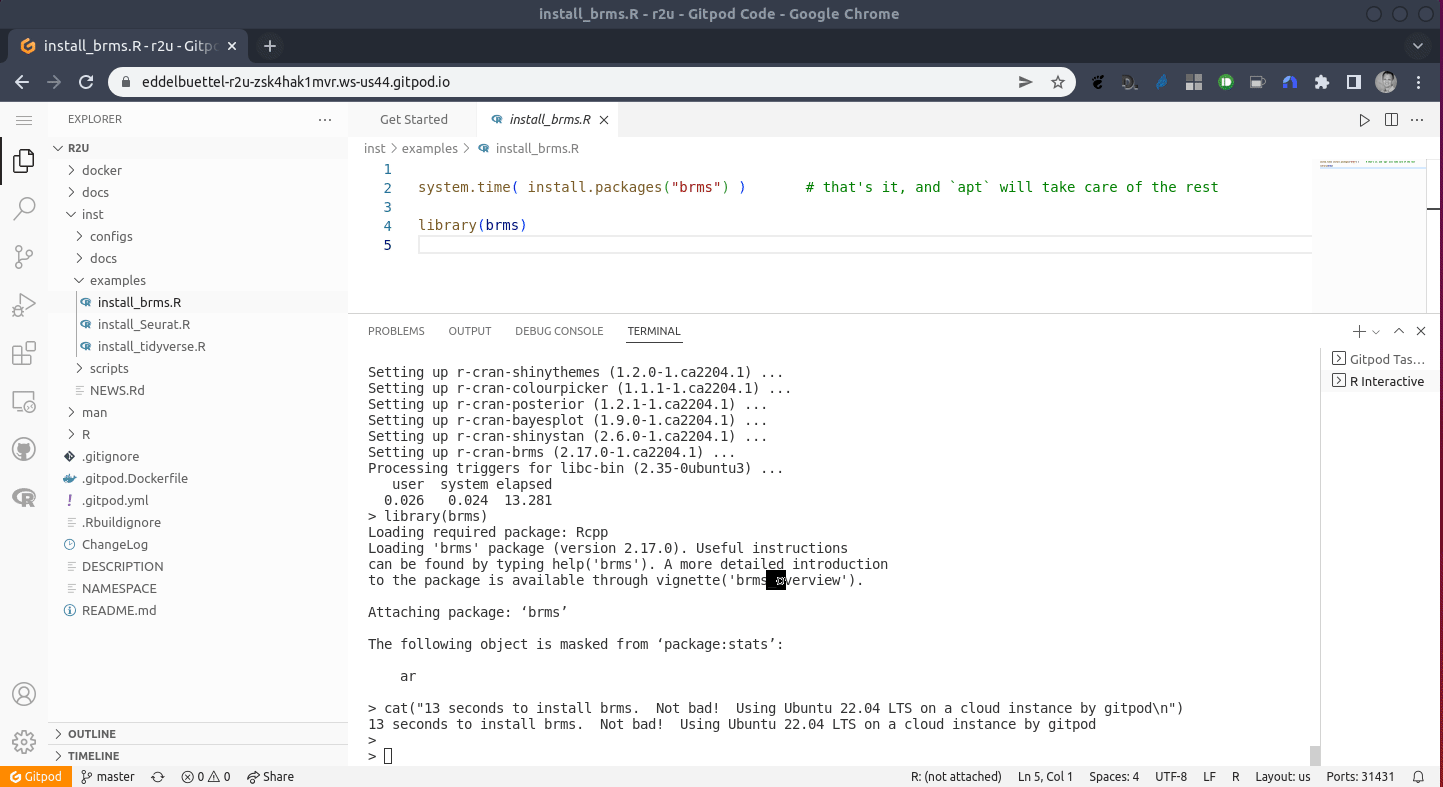
Engineers build systems. Good engineers always stress and focus efficiency of these systems. Two recent examples of engineering thinking follow. One was in a video / podcast interview with Martin Thompson (who is a noted high-performance code expert) I came across recently. The overall focus of the hour-long interview is on managing software complexity . Around minute twenty-two, the conversation turns to feedback loops and systems, and a strong preference for simple and fast systems for more immediate feedback. An important topic indeed. The second example connects to this and permeates many tweets and other writings by Erik Bernhardsson. He had an earlier 2017 post on Optimizing for iteration speed , as well as a 17 May 2022 tweet on minimizing feedback loop size, another 28 Mar 2022 tweet reply on shorter feedback loops, then a 14 Feb 2022 post on problems with slow feedback loops, as well as a 13 Jan 2022 post on a priority for tighter feedback loops, and lastly a 23 Jul 2021 post on fast feedback cycles. You get the idea: Erik really digs faster feedback loops. Nobody likes to wait: immediatecy wins each time. A few years ago, I had touched on this topic with two posts on how to make (R) package compilation (and hence installation) faster. One idea (which I still use whenever I must compile) was in post #11 on caching compilation. Another idea was in post #13: make it faster by not doing it, in this case via binary installation which skip the need for compilation (and which is what I aim for with, say, CI dependencies). Several subsequent posts can be found by scrolling down the r^4 blog section: we stressed the use of the amazing Rutter PPA c2d4u for CRAN binaries (often via Rocker containers, the (post #28) promise of RSPM, and the (post #29) awesomeness of bspm. And then in the more recent post #34 from last December we got back to a topic which ties all these things together: Dependencies. We quoted Mies van der Rohe: Less is more. Especially when it comes to dependencies as these elongate the feedback loop and thereby delay feedback. Our most recent post #37 on r2u connects these dots. Access to a complete set of CRAN binaries with full-dependency resolution accelerates use and installation. This of course also covers testing and continuous integration. Why wait minutes to recompile the same packages over and over when you can install the full Tidyverse in 18 seconds or the brms package and all it needs in 13 seconds as shown in the two gifs also on the r2u documentation site. You can even power up the example setup of the second gif via this gitpod link giving you a full Ubuntu 22.04 session in your browser to try this: so go forth and install something from CRAN with ease! The benefit of a system such our r2u CRAN binaries is clear: faster feedback loops. This holds whether you work with few or many dependencies, tiny or tidy. Faster matters, and feedback can be had sooner. And with the title of this post we now get a rallying cry to advocate for faster feedback systems: FFS .
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

John Goerzen: Pipes, deadlocks, and strace annoyingly fixing them

This is a complex tale I will attempt to make simple(ish). I ve (re)learned more than I cared to about the details of pipes, signals, and certain system calls and the solution is still elusive. For some time now, I have been using NNCP to back up my files. These backups are sent to my backup system, which effectively does this to process them (each ZFS send is piped to a shell script that winds up running this):
gpg -q -d   zstdcat -T0   zfs receive -u -o readonly=on "$STORE/$DEST"
This processes tens of thousands of zfs sends per week. Recently, having written Filespooler, I switched to sending the backups using Filespooler over NNCP. Now fspl (the Filespooler executable) opens the file for each stream and then connects it to what amounts to this pipeline:
bash -c 'gpg -q -d 2>/dev/null   zstdcat -T0'   zfs receive -u -o readonly=on "$STORE/$DEST"
Actually, to be more precise, it spins up the bash part of it, reads a few bytes from it, and then connects it to the zfs receive. And this works well almost always. In something like 1/1000 of the cases, it deadlocks, and I still don t know why. But I can talk about the journey of trying to figure it out (and maybe some of you will have some ideas). Filespooler is written in Rust, and uses Rust s Command system. Effectively what happens is this:
  1. The fspl process has a File handle, which after forking but before invoking bash, it dup2 s to stdin.
  2. The connection between bash and zfs receive is a standard Unix pipe.
I cannot get the problem to duplicate when I run the entire thing under strace -f. So I am left trying to peek at it from the outside. What happens if I try to attach to each component with strace -p? So the plot thickens! Why would connecting to zstdcat and zfs receive cause them to actually change behavior? strace works by using the ptrace system call, and ptrace in a number of cases requires sending SIGSTOP to a process. In a complicated set of circumstances, a system call may return EINTR when a SIGSTOP is received, with the idea that the system call should be retried. I can t see, from either zstdcat or zfs, if this is happening, though. So I thought, how about having Filespooler manually copy data from bash to zfs receive in a read/write loop instead of having them connected directly via a pipe? That is, there would be two pipes going there: one where Filespooler reads from the bash command, and one where it writes to zfs. If nothing else, I could instrument it with debugging. And so I did, and I found that when it deadlocked, it was deadlocking on write but with no discernible pattern as to where or when. So I went back to directly connected. In analyzing straces, I found a Rust bug which I reported in which it is failing to close the read end of a pipe in the parent post-fork. However, having implemented a workaround for this, it doesn t prevent the deadlock so this is orthogonal to the issue at hand. Among the two strange things here are things returning to normal when I attach strace to zstdcat, and things crashing when I attach strace to zfs. I decided to investigate the latter. It turns out that the ZFS code that is reading from stdin during zfs receive is in the kernel module, not userland. Here is the part that is triggering the imcomplete stream error:
                int err = zfs_file_read(fp, (char *)buf + done,
                    len - done, &resid);
                if (resid == len - done)  
                        /*
                         * Note: ECKSUM or ZFS_ERR_STREAM_TRUNCATED indicates
                         * that the receive was interrupted and can
                         * potentially be resumed.
                         */
                        err = SET_ERROR(ZFS_ERR_STREAM_TRUNCATED);
                 
resid is an output parameter with the number of bytes remaining from a short read, so in this case, if the read produced zero bytes, then it sets that error. What s zfs_file_read then? It boils down to a thin wrapper around kernel_read(). This winds up calling __kernel_read(), which calls read_iter on the pipe, which is pipe_read(). That s where I don t have the knowledge to get into the weeds right now. So it seems likely to me that the problem has something to do with zfs receive. But, what, and why does it only not work in this one very specific situation, and only so rarely? And why does attaching strace to zstdcat make it all work again? I m indeed puzzled! Update 2022-06-20: See the followup post which identifies this as likely a kernel bug and explains why this particular use of Filespooler made it easier to trigger.

18 June 2022

Bastian Venthur: blag is now available in Debian

Last year, I wrote my own blog-aware static site generator in Python. I called it blag named after the blag of the webcomic xkcd. Now I finally got around packaging- and uploading blag to Debian. It passed the NEW queue and is now part of the distribution. That means if you re using Debian, you can install it via:
sudo aptitude install blag
Ubuntu will probably follow soon. For every other system, blag is also available on PyPI:
pip install blag
To get started, you can
mkdir blog && cd blog
blag quickstart                        # fill out some info
nvim content/hello-world.md            # write some content
blag build                             # build the website
Blag is aware of articles and pages: the difference is that articles are part of the blog and will be added to the atom feed, the archive and aggregated in the tag pages. Pages are just rendered out to HTML. Articles and pages can be freely mixed in the content directory, what differentiates an article from a page is the existence of the dade metadata element:
title: My first article
description: Short description of the article
date: 2022-06-18 23:00
tags: blogging, markdown
## Hello World!
Lorem ipsum.
[...]
blag also comes with a dev-server that rebuilds the website automatically on every change detected, you can start it using:
blag serve
The default theme looks quite ugly, and you probably want to create your own styling to make it more beautiful. The process is not very difficult if you re familiar with jinja templating. Help on that can be found in the Templating section of the online documentation, the offline version in the blag-doc package, or the man page, respectively. Speaking of the blag-doc package: packaging it was surprisingly tricky, and it also took me a lot of trial and error to realize that dh_sphinxdocs alone does not automatically put the generated html output into the appropriate package, you rather have to list them in the package.docs-file (i.e. blag-doc.docs) so dh_installdocs can install them properly.

17 June 2022

Antoine Beaupr : Matrix notes

I have some concerns about Matrix (the protocol, not the movie that came out recently, although I do have concerns about that as well). I've been watching the project for a long time, and it seems more a promising alternative to many protocols like IRC, XMPP, and Signal. This review may sound a bit negative, because it focuses on those concerns. I am the operator of an IRC network and people keep asking me to bridge it with Matrix. I have myself considered just giving up on IRC and converting to Matrix. This space is a living document exploring my research of that problem space. The TL;DR: is that no, I'm not setting up a bridge just yet, and I'm still on IRC. This article was written over the course of the last three months, but I have been watching the Matrix project for years (my logs seem to say 2016 at least). The article is rather long. It will likely take you half an hour to read, so copy this over to your ebook reader, your tablet, or dead trees, and lean back and relax as I show you around the Matrix. Or, alternatively, just jump to a section that interest you, most likely the conclusion.

Introduction to Matrix Matrix is an "open standard for interoperable, decentralised, real-time communication over IP. It can be used to power Instant Messaging, VoIP/WebRTC signalling, Internet of Things communication - or anywhere you need a standard HTTP API for publishing and subscribing to data whilst tracking the conversation history". It's also (when compared with XMPP) "an eventually consistent global JSON database with an HTTP API and pubsub semantics - whilst XMPP can be thought of as a message passing protocol." According to their FAQ, the project started in 2014, has about 20,000 servers, and millions of users. Matrix works over HTTPS but over a special port: 8448.

Security and privacy I have some concerns about the security promises of Matrix. It's advertised as a "secure" with "E2E [end-to-end] encryption", but how does it actually work?

Data retention defaults One of my main concerns with Matrix is data retention, which is a key part of security in a threat model where (for example) an hostile state actor wants to surveil your communications and can seize your devices. On IRC, servers don't actually keep messages all that long: they pass them along to other servers and clients as fast as they can, only keep them in memory, and move on to the next message. There are no concerns about data retention on messages (and their metadata) other than the network layer. (I'm ignoring the issues with user registration, which is a separate, if valid, concern.) Obviously, an hostile server could log everything passing through it, but IRC federations are normally tightly controlled. So, if you trust your IRC operators, you should be fairly safe. Obviously, clients can (and often do, even if OTR is configured!) log all messages, but this is generally not the default. Irssi, for example, does not log by default. IRC bouncers are more likely to log to disk, of course, to be able to do what they do. Compare this to Matrix: when you send a message to a Matrix homeserver, that server first stores it in its internal SQL database. Then it will transmit that message to all clients connected to that server and room, and to all other servers that have clients connected to that room. Those remote servers, in turn, will keep a copy of that message and all its metadata in their own database, by default forever. On encrypted rooms those messages are encrypted, but not their metadata. There is a mechanism to expire entries in Synapse, but it is not enabled by default. So one should generally assume that a message sent on Matrix is never expired.

GDPR in the federation But even if that setting was enabled by default, how do you control it? This is a fundamental problem of the federation: if any user is allowed to join a room (which is the default), those user's servers will log all content and metadata from that room. That includes private, one-on-one conversations, since those are essentially rooms as well. In the context of the GDPR, this is really tricky: who is the responsible party (known as the "data controller") here? It's basically any yahoo who fires up a home server and joins a room. In a federated network, one has to wonder whether GDPR enforcement is even possible at all. But in Matrix in particular, if you want to enforce your right to be forgotten in a given room, you would have to:
  1. enumerate all the users that ever joined the room while you were there
  2. discover all their home servers
  3. start a GDPR procedure against all those servers
I recognize this is a hard problem to solve while still keeping an open ecosystem. But I believe that Matrix should have much stricter defaults towards data retention than right now. Message expiry should be enforced by default, for example. (Note that there are also redaction policies that could be used to implement part of the GDPR automatically, see the privacy policy discussion below on that.) Also keep in mind that, in the brave new peer-to-peer world that Matrix is heading towards, the boundary between server and client is likely to be fuzzier, which would make applying the GDPR even more difficult. Update: this comment links to this post (in german) which apparently studied the question and concluded that Matrix is not GDPR-compliant. In fact, maybe Synapse should be designed so that there's no configurable flag to turn off data retention. A bit like how most system loggers in UNIX (e.g. syslog) come with a log retention system that typically rotate logs after a few weeks or month. Historically, this was designed to keep hard drives from filling up, but it also has the added benefit of limiting the amount of personal information kept on disk in this modern day. (Arguably, syslog doesn't rotate logs on its own, but, say, Debian GNU/Linux, as an installed system, does have log retention policies well defined for installed packages, and those can be discussed. And "no expiry" is definitely a bug.

Matrix.org privacy policy When I first looked at Matrix, five years ago, Element.io was called Riot.im and had a rather dubious privacy policy:
We currently use cookies to support our use of Google Analytics on the Website and Service. Google Analytics collects information about how you use the Website and Service. [...] This helps us to provide you with a good experience when you browse our Website and use our Service and also allows us to improve our Website and our Service.
When I asked Matrix people about why they were using Google Analytics, they explained this was for development purposes and they were aiming for velocity at the time, not privacy (paraphrasing here). They also included a "free to snitch" clause:
If we are or believe that we are under a duty to disclose or share your personal data, we will do so in order to comply with any legal obligation, the instructions or requests of a governmental authority or regulator, including those outside of the UK.
Those are really broad terms, above and beyond what is typically expected legally. Like the current retention policies, such user tracking and ... "liberal" collaboration practices with the state set a bad precedent for other home servers. Thankfully, since the above policy was published (2017), the GDPR was "implemented" (2018) and it seems like both the Element.io privacy policy and the Matrix.org privacy policy have been somewhat improved since. Notable points of the new privacy policies:
  • 2.3.1.1: the "federation" section actually outlines that "Federated homeservers and Matrix clients which respect the Matrix protocol are expected to honour these controls and redaction/erasure requests, but other federated homeservers are outside of the span of control of Element, and we cannot guarantee how this data will be processed"
  • 2.6: users under the age of 16 should not use the matrix.org service
  • 2.10: Upcloud, Mythic Beast, Amazon, and CloudFlare possibly have access to your data (it's nice to at least mention this in the privacy policy: many providers don't even bother admitting to this kind of delegation)
  • Element 2.2.1: mentions many more third parties (Twilio, Stripe, Quaderno, LinkedIn, Twitter, Google, Outplay, PipeDrive, HubSpot, Posthog, Sentry, and Matomo (phew!) used when you are paying Matrix.org for hosting
I'm not super happy with all the trackers they have on the Element platform, but then again you don't have to use that service. Your favorite homeserver (assuming you are not on Matrix.org) probably has their own Element deployment, hopefully without all that garbage. Overall, this is all a huge improvement over the previous privacy policy, so hats off to the Matrix people for figuring out a reasonable policy in such a tricky context. I particularly like this bit:
We will forget your copy of your data upon your request. We will also forward your request to be forgotten onto federated homeservers. However - these homeservers are outside our span of control, so we cannot guarantee they will forget your data.
It's great they implemented those mechanisms and, after all, if there's an hostile party in there, nothing can prevent them from using screenshots to just exfiltrate your data away from the client side anyways, even with services typically seen as more secure, like Signal. As an aside, I also appreciate that Matrix.org has a fairly decent code of conduct, based on the TODO CoC which checks all the boxes in the geekfeminism wiki.

Metadata handling Overall, privacy protections in Matrix mostly concern message contents, not metadata. In other words, who's talking with who, when and from where is not well protected. Compared to a tool like Signal, which goes through great lengths to anonymize that data with features like private contact discovery, disappearing messages, sealed senders, and private groups, Matrix is definitely behind. (Note: there is an issue open about message lifetimes in Element since 2020, but it's not at even at the MSC stage yet.) This is a known issue (opened in 2019) in Synapse, but this is not just an implementation issue, it's a flaw in the protocol itself. Home servers keep join/leave of all rooms, which gives clear text information about who is talking to. Synapse logs may also contain privately identifiable information that home server admins might not be aware of in the first place. Those log rotation policies are separate from the server-level retention policy, which may be confusing for a novice sysadmin. Combine this with the federation: even if you trust your home server to do the right thing, the second you join a public room with third-party home servers, those ideas kind of get thrown out because those servers can do whatever they want with that information. Again, a problem that is hard to solve in any federation. To be fair, IRC doesn't have a great story here either: any client knows not only who's talking to who in a room, but also typically their client IP address. Servers can (and often do) obfuscate this, but often that obfuscation is trivial to reverse. Some servers do provide "cloaks" (sometimes automatically), but that's kind of a "slap-on" solution that actually moves the problem elsewhere: now the server knows a little more about the user. Overall, I would worry much more about a Matrix home server seizure than a IRC or Signal server seizure. Signal does get subpoenas, and they can only give out a tiny bit of information about their users: their phone number, and their registration, and last connection date. Matrix carries a lot more information in its database.

Amplification attacks on URL previews I (still!) run an Icecast server and sometimes share links to it on IRC which, obviously, also ends up on (more than one!) Matrix home servers because some people connect to IRC using Matrix. This, in turn, means that Matrix will connect to that URL to generate a link preview. I feel this outlines a security issue, especially because those sockets would be kept open seemingly forever. I tried to warn the Matrix security team but somehow, I don't think this issue was taken very seriously. Here's the disclosure timeline:
  • January 18: contacted Matrix security
  • January 19: response: already reported as a bug
  • January 20: response: can't reproduce
  • January 31: timeout added, considered solved
  • January 31: I respond that I believe the security issue is underestimated, ask for clearance to disclose
  • February 1: response: asking for two weeks delay after the next release (1.53.0) including another patch, presumably in two weeks' time
  • February 22: Matrix 1.53.0 released
  • April 14: I notice the release, ask for clearance again
  • April 14: response: referred to the public disclosure
There are a couple of problems here:
  1. the bug was publicly disclosed in September 2020, and not considered a security issue until I notified them, and even then, I had to insist
  2. no clear disclosure policy timeline was proposed or seems established in the project (there is a security disclosure policy but it doesn't include any predefined timeline)
  3. I wasn't informed of the disclosure
  4. the actual solution is a size limit (10MB, already implemented), a time limit (30 seconds, implemented in PR 11784), and a content type allow list (HTML, "media" or JSON, implemented in PR 11936), and I'm not sure it's adequate
  5. (pure vanity:) I did not make it to their Hall of fame
I'm not sure those solutions are adequate because they all seem to assume a single home server will pull that one URL for a little while then stop. But in a federated network, many (possibly thousands) home servers may be connected in a single room at once. If an attacker drops a link into such a room, all those servers would connect to that link all at once. This is an amplification attack: a small amount of traffic will generate a lot more traffic to a single target. It doesn't matter there are size or time limits: the amplification is what matters here. It should also be noted that clients that generate link previews have more amplification because they are more numerous than servers. And of course, the default Matrix client (Element) does generate link previews as well. That said, this is possibly not a problem specific to Matrix: any federated service that generates link previews may suffer from this. I'm honestly not sure what the solution is here. Maybe moderation? Maybe link previews are just evil? All I know is there was this weird bug in my Icecast server and I tried to ring the bell about it, and it feels it was swept under the rug. Somehow I feel this is bound to blow up again in the future, even with the current mitigation.

Moderation In Matrix like elsewhere, Moderation is a hard problem. There is a detailed moderation guide and much of this problem space is actively worked on in Matrix right now. A fundamental problem with moderating a federated space is that a user banned from a room can rejoin the room from another server. This is why spam is such a problem in Email, and why IRC networks have stopped federating ages ago (see the IRC history for that fascinating story).

The mjolnir bot The mjolnir moderation bot is designed to help with some of those things. It can kick and ban users, redact all of a user's message (as opposed to one by one), all of this across multiple rooms. It can also subscribe to a federated block list published by matrix.org to block known abusers (users or servers). Bans are pretty flexible and can operate at the user, room, or server level. Matrix people suggest making the bot admin of your channels, because you can't take back admin from a user once given.

The command-line tool There's also a new command line tool designed to do things like:
  • System notify users (all users/users from a list, specific user)
  • delete sessions/devices not seen for X days
  • purge the remote media cache
  • select rooms with various criteria (external/local/empty/created by/encrypted/cleartext)
  • purge history of theses rooms
  • shutdown rooms
This tool and Mjolnir are based on the admin API built into Synapse.

Rate limiting Synapse has pretty good built-in rate-limiting which blocks repeated login, registration, joining, or messaging attempts. It may also end up throttling servers on the federation based on those settings.

Fundamental federation problems Because users joining a room may come from another server, room moderators are at the mercy of the registration and moderation policies of those servers. Matrix is like IRC's +R mode ("only registered users can join") by default, except that anyone can register their own homeserver, which makes this limited. Server admins can block IP addresses and home servers, but those tools are not easily available to room admins. There is an API (m.room.server_acl in /devtools) but it is not reliable (thanks Austin Huang for the clarification). Matrix has the concept of guest accounts, but it is not used very much, and virtually no client or homeserver supports it. This contrasts with the way IRC works: by default, anyone can join an IRC network even without authentication. Some channels require registration, but in general you are free to join and look around (until you get blocked, of course). I have seen anecdotal evidence (CW: Twitter, nitter link) that "moderating bridges is hell", and I can imagine why. Moderation is already hard enough on one federation, when you bridge a room with another network, you inherit all the problems from that network but without the entire abuse control tools from the original network's API...

Room admins Matrix, in particular, has the problem that room administrators (which have the power to redact messages, ban users, and promote other users) are bound to their Matrix ID which is, in turn, bound to their home servers. This implies that a home server administrators could (1) impersonate a given user and (2) use that to hijack the room. So in practice, the home server is the trust anchor for rooms, not the user themselves. That said, if server B administrator hijack user joe on server B, they will hijack that room on that specific server. This will not (necessarily) affect users on the other servers, as servers could refuse parts of the updates or ban the compromised account (or server). It does seem like a major flaw that room credentials are bound to Matrix identifiers, as opposed to the E2E encryption credentials. In an encrypted room even with fully verified members, a compromised or hostile home server can still take over the room by impersonating an admin. That admin (or even a newly minted user) can then send events or listen on the conversations. This is even more frustrating when you consider that Matrix events are actually signed and therefore have some authentication attached to them, acting like some sort of Merkle tree (as it contains a link to previous events). That signature, however, is made from the homeserver PKI keys, not the client's E2E keys, which makes E2E feel like it has been "bolted on" later.

Availability While Matrix has a strong advantage over Signal in that it's decentralized (so anyone can run their own homeserver,), I couldn't find an easy way to run a "multi-primary" setup, or even a "redundant" setup (even if with a single primary backend), short of going full-on "replicate PostgreSQL and Redis data", which is not typically for the faint of heart.

How this works in IRC On IRC, it's quite easy to setup redundant nodes. All you need is:
  1. a new machine (with it's own public address with an open port)
  2. a shared secret (or certificate) between that machine and an existing one on the network
  3. a connect block on both servers
That's it: the node will join the network and people can connect to it as usual and share the same user/namespace as the rest of the network. The servers take care of synchronizing state: you do not need to worry about replicating a database server. (Now, experienced IRC people will know there's a catch here: IRC doesn't have authentication built in, and relies on "services" which are basically bots that authenticate users (I'm simplifying, don't nitpick). If that service goes down, the network still works, but then people can't authenticate, and they can start doing nasty things like steal people's identity if they get knocked offline. But still: basic functionality still works: you can talk in rooms and with users that are on the reachable network.)

User identities Matrix is more complicated. Each "home server" has its own identity namespace: a specific user (say @anarcat:matrix.org) is bound to that specific home server. If that server goes down, that user is completely disconnected. They could register a new account elsewhere and reconnect, but then they basically lose all their configuration: contacts, joined channels are all lost. (Also notice how the Matrix IDs don't look like a typical user address like an email in XMPP. They at least did their homework and got the allocation for the scheme.)

Rooms Users talk to each other in "rooms", even in one-to-one communications. (Rooms are also used for other things like "spaces", they're basically used for everything, think "everything is a file" kind of tool.) For rooms, home servers act more like IRC nodes in that they keep a local state of the chat room and synchronize it with other servers. Users can keep talking inside a room if the server that originally hosts the room goes down. Rooms can have a local, server-specific "alias" so that, say, #room:matrix.org is also visible as #room:example.com on the example.com home server. Both addresses refer to the same room underlying room. (Finding this in the Element settings is not obvious though, because that "alias" are actually called a "local address" there. So to create such an alias (in Element), you need to go in the room settings' "General" section, "Show more" in "Local address", then add the alias name (e.g. foo), and then that room will be available on your example.com homeserver as #foo:example.com.) So a room doesn't belong to a server, it belongs to the federation, and anyone can join the room from any serer (if the room is public, or if invited otherwise). You can create a room on server A and when a user from server B joins, the room will be replicated on server B as well. If server A fails, server B will keep relaying traffic to connected users and servers. A room is therefore not fundamentally addressed with the above alias, instead ,it has a internal Matrix ID, which basically a random string. It has a server name attached to it, but that was made just to avoid collisions. That can get a little confusing. For example, the #fractal:gnome.org room is an alias on the gnome.org server, but the room ID is !hwiGbsdSTZIwSRfybq:matrix.org. That's because the room was created on matrix.org, but the preferred branding is gnome.org now. As an aside, rooms, by default, live forever, even after the last user quits. There's an admin API to delete rooms and a tombstone event to redirect to another one, but neither have a GUI yet. The latter is part of MSC1501 ("Room version upgrades") which allows a room admin to close a room, with a message and a pointer to another room.

Spaces Discovering rooms can be tricky: there is a per-server room directory, but Matrix.org people are trying to deprecate it in favor of "Spaces". Room directories were ripe for abuse: anyone can create a room, so anyone can show up in there. It's possible to restrict who can add aliases, but anyways directories were seen as too limited. In contrast, a "Space" is basically a room that's an index of other rooms (including other spaces), so existing moderation and administration mechanism that work in rooms can (somewhat) work in spaces as well. This enables a room directory that works across federation, regardless on which server they were originally created. New users can be added to a space or room automatically in Synapse. (Existing users can be told about the space with a server notice.) This gives admins a way to pre-populate a list of rooms on a server, which is useful to build clusters of related home servers, providing some sort of redundancy, at the room -- not user -- level.

Home servers So while you can workaround a home server going down at the room level, there's no such thing at the home server level, for user identities. So if you want those identities to be stable in the long term, you need to think about high availability. One limitation is that the domain name (e.g. matrix.example.com) must never change in the future, as renaming home servers is not supported. The documentation used to say you could "run a hot spare" but that has been removed. Last I heard, it was not possible to run a high-availability setup where multiple, separate locations could replace each other automatically. You can have high performance setups where the load gets distributed among workers, but those are based on a shared database (Redis and PostgreSQL) backend. So my guess is it would be possible to create a "warm" spare server of a matrix home server with regular PostgreSQL replication, but that is not documented in the Synapse manual. This sort of setup would also not be useful to deal with networking issues or denial of service attacks, as you will not be able to spread the load over multiple network locations easily. Redis and PostgreSQL heroes are welcome to provide their multi-primary solution in the comments. In the meantime, I'll just point out this is a solution that's handled somewhat more gracefully in IRC, by having the possibility of delegating the authentication layer.

Delegations If you do not want to run a Matrix server yourself, it's possible to delegate the entire thing to another server. There's a server discovery API which uses the .well-known pattern (or SRV records, but that's "not recommended" and a bit confusing) to delegate that service to another server. Be warned that the server still needs to be explicitly configured for your domain. You can't just put:
  "m.server": "matrix.org:443"  
... on https://example.com/.well-known/matrix/server and start using @you:example.com as a Matrix ID. That's because Matrix doesn't support "virtual hosting" and you'd still be connecting to rooms and people with your matrix.org identity, not example.com as you would normally expect. This is also why you cannot rename your home server. The server discovery API is what allows servers to find each other. Clients, on the other hand, use the client-server discovery API: this is what allows a given client to find your home server when you type your Matrix ID on login.

Performance The high availability discussion brushed over the performance of Matrix itself, but let's now dig into that.

Horizontal scalability There were serious scalability issues of the main Matrix server, Synapse, in the past. So the Matrix team has been working hard to improve its design. Since Synapse 1.22 the home server can horizontally scale to multiple workers (see this blog post for details) which can make it easier to scale large servers.

Other implementations There are other promising home servers implementations from a performance standpoint (dendrite, Golang, entered beta in late 2020; conduit, Rust, beta; others), but none of those are feature-complete so there's a trade-off to be made there. Synapse is also adding a lot of feature fast, so it's an open question whether the others will ever catch up. (I have heard that Dendrite might actually surpass Synapse in features within a few years, which would put Synapse in a more "LTS" situation.)

Latency Matrix can feel slow sometimes. For example, joining the "Matrix HQ" room in Element (from matrix.debian.social) takes a few minutes and then fails. That is because the home server has to sync the entire room state when you join the room. There was promising work on this announced in the lengthy 2021 retrospective, and some of that work landed (partial sync) in the 1.53 release already. Other improvements coming include sliding sync, lazy loading over federation, and fast room joins. So that's actually something that could be fixed in the fairly short term. But in general, communication in Matrix doesn't feel as "snappy" as on IRC or even Signal. It's hard to quantify this without instrumenting a full latency test bed (for example the tools I used in the terminal emulators latency tests), but even just typing in a web browser feels slower than typing in a xterm or Emacs for me. Even in conversations, I "feel" people don't immediately respond as fast. In fact, this could be an interesting double-blind experiment to make: have people guess whether they are talking to a person on Matrix, XMPP, or IRC, for example. My theory would be that people could notice that Matrix users are slower, if only because of the TCP round-trip time each message has to take.

Transport Some courageous person actually made some tests of various messaging platforms on a congested network. His evaluation was basically:
  • Briar: uses Tor, so unusable except locally
  • Matrix: "struggled to send and receive messages", joining a room takes forever as it has to sync all history, "took 20-30 seconds for my messages to be sent and another 20 seconds for further responses"
  • XMPP: "worked in real-time, full encryption, with nearly zero lag"
So that was interesting. I suspect IRC would have also fared better, but that's just a feeling. Other improvements to the transport layer include support for websocket and the CoAP proxy work from 2019 (targeting 100bps links), but both seem stalled at the time of writing. The Matrix people have also announced the pinecone p2p overlay network which aims at solving large, internet-scale routing problems. See also this talk at FOSDEM 2022.

Usability

Onboarding and workflow The workflow for joining a room, when you use Element web, is not great:
  1. click on a link in a web browser
  2. land on (say) https://matrix.to/#/#matrix-dev:matrix.org
  3. offers "Element", yeah that's sounds great, let's click "Continue"
  4. land on https://app.element.io/#/room%2F%23matrix-dev%3Amatrix.org and then you need to register, aaargh
As you might have guessed by now, there is a specification to solve this, but web browsers need to adopt it as well, so that's far from actually being solved. At least browsers generally know about the matrix: scheme, it's just not exactly clear what they should do with it, especially when the handler is just another web page (e.g. Element web). In general, when compared with tools like Signal or WhatsApp, Matrix doesn't fare so well in terms of user discovery. I probably have some of my normal contacts that have a Matrix account as well, but there's really no way to know. It's kind of creepy when Signal tells you "this person is on Signal!" but it's also pretty cool that it works, and they actually implemented it pretty well. Registration is also less obvious: in Signal, the app confirms your phone number automatically. It's friction-less and quick. In Matrix, you need to learn about home servers, pick one, register (with a password! aargh!), and then setup encryption keys (not default), etc. It's a lot more friction. And look, I understand: giving away your phone number is a huge trade-off. I don't like it either. But it solves a real problem and makes encryption accessible to a ton more people. Matrix does have "identity servers" that can serve that purpose, but I don't feel confident sharing my phone number there. It doesn't help that the identity servers don't have private contact discovery: giving them your phone number is a more serious security compromise than with Signal. There's a catch-22 here too: because no one feels like giving away their phone numbers, no one does, and everyone assumes that stuff doesn't work anyways. Like it or not, Signal forcing people to divulge their phone number actually gives them critical mass that means actually a lot of my relatives are on Signal and I don't have to install crap like WhatsApp to talk with them.

5 minute clients evaluation Throughout all my tests I evaluated a handful of Matrix clients, mostly from Flathub because almost none of them are packaged in Debian. Right now I'm using Element, the flagship client from Matrix.org, in a web browser window, with the PopUp Window extension. This makes it look almost like a native app, and opens links in my main browser window (instead of a new tab in that separate window), which is nice. But I'm tired of buying memory to feed my web browser, so this indirection has to stop. Furthermore, I'm often getting completely logged off from Element, which means re-logging in, recovering my security keys, and reconfiguring my settings. That is extremely annoying. Coming from Irssi, Element is really "GUI-y" (pronounced "gooey"). Lots of clickety happening. To mark conversations as read, in particular, I need to click-click-click on all the tabs that have some activity. There's no "jump to latest message" or "mark all as read" functionality as far as I could tell. In Irssi the former is built-in (alt-a) and I made a custom /READ command for the latter:
/ALIAS READ script exec \$_->activity(0) for Irssi::windows
And yes, that's a Perl script in my IRC client. I am not aware of any Matrix client that does stuff like that, except maybe Weechat, if we can call it a Matrix client, or Irssi itself, now that it has a Matrix plugin (!). As for other clients, I have looked through the Matrix Client Matrix (confusing right?) to try to figure out which one to try, and, even after selecting Linux as a filter, the chart is just too wide to figure out anything. So I tried those, kind of randomly:
  • Fractal
  • Mirage
  • Nheko
  • Quaternion
Unfortunately, I lost my notes on those, I don't actually remember which one did what. I still have a session open with Mirage, so I guess that means it's the one I preferred, but I remember they were also all very GUI-y. Maybe I need to look at weechat-matrix or gomuks. At least Weechat is scriptable so I could continue playing the power-user. Right now my strategy with messaging (and that includes microblogging like Twitter or Mastodon) is that everything goes through my IRC client, so Weechat could actually fit well in there. Going with gomuks, on the other hand, would mean running it in parallel with Irssi or ... ditching IRC, which is a leap I'm not quite ready to take just yet. Oh, and basically none of those clients (except Nheko and Element) support VoIP, which is still kind of a second-class citizen in Matrix. It does not support large multimedia rooms, for example: Jitsi was used for FOSDEM instead of the native videoconferencing system.

Bots This falls a little aside the "usability" section, but I didn't know where to put this... There's a few Matrix bots out there, and you are likely going to be able to replace your existing bots with Matrix bots. It's true that IRC has a long and impressive history with lots of various bots doing various things, but given how young Matrix is, there's still a good variety:
  • maubot: generic bot with tons of usual plugins like sed, dice, karma, xkcd, echo, rss, reminder, translate, react, exec, gitlab/github webhook receivers, weather, etc
  • opsdroid: framework to implement "chat ops" in Matrix, connects with Matrix, GitHub, GitLab, Shell commands, Slack, etc
  • matrix-nio: another framework, used to build lots more bots like:
    • hemppa: generic bot with various functionality like weather, RSS feeds, calendars, cron jobs, OpenStreetmaps lookups, URL title snarfing, wolfram alpha, astronomy pic of the day, Mastodon bridge, room bridging, oh dear
    • devops: ping, curl, etc
    • podbot: play podcast episodes from AntennaPod
    • cody: Python, Ruby, Javascript REPL
    • eno: generic bot, "personal assistant"
  • mjolnir: moderation bot
  • hookshot: bridge with GitLab/GitHub
  • matrix-monitor-bot: latency monitor
One thing I haven't found an equivalent for is Debian's MeetBot. There's an archive bot but it doesn't have topics or a meeting chair, or HTML logs.

Working on Matrix As a developer, I find Matrix kind of intimidating. The specification is huge. The official specification itself looks somewhat digestable: it's only 6 APIs so that looks, at first, kind of reasonable. But whenever you start asking complicated questions about Matrix, you quickly fall into the Matrix Spec Change specification (which, yes, is a separate specification). And there are literally hundreds of MSCs flying around. It's hard to tell what's been adopted and what hasn't, and even harder to figure out if your specific client has implemented it. (One trendy answer to this problem is to "rewrite it in rust": Matrix are working on implementing a lot of those specifications in a matrix-rust-sdk that's designed to take the implementation details away from users.) Just taking the latest weekly Matrix report, you find that three new MSCs proposed, just last week! There's even a graph that shows the number of MSCs is progressing steadily, at 600+ proposals total, with the majority (300+) "new". I would guess the "merged" ones are at about 150. That's a lot of text which includes stuff like 3D worlds which, frankly, I don't think you should be working on when you have such important security and usability problems. (The internet as a whole, arguably, doesn't fare much better. RFC600 is a really obscure discussion about "INTERFACING AN ILLINOIS PLASMA TERMINAL TO THE ARPANET". Maybe that's how many MSCs will end up as well, left forgotten in the pits of history.) And that's the thing: maybe the Matrix people have a different objective than I have. They want to connect everything to everything, and make Matrix a generic transport for all sorts of applications, including virtual reality, collaborative editors, and so on. I just want secure, simple messaging. Possibly with good file transfers, and video calls. That it works with existing stuff is good, and it should be federated to remove the "Signal point of failure". So I'm a bit worried with the direction all those MSCs are taking, especially when you consider that clients other than Element are still struggling to keep up with basic features like end-to-end encryption or room discovery, never mind voice or spaces...

Conclusion Overall, Matrix is somehow in the space XMPP was a few years ago. It has a ton of features, pretty good clients, and a large community. It seems to have gained some of the momentum that XMPP has lost. It may have the most potential to replace Signal if something bad would happen to it (like, I don't know, getting banned or going nuts with cryptocurrency)... But it's really not there yet, and I don't see Matrix trying to get there either, which is a bit worrisome.

Looking back at history I'm also worried that we are repeating the errors of the past. The history of federated services is really fascinating:. IRC, FTP, HTTP, and SMTP were all created in the early days of the internet, and are all still around (except, arguably, FTP, which was removed from major browsers recently). All of them had to face serious challenges in growing their federation. IRC had numerous conflicts and forks, both at the technical level but also at the political level. The history of IRC is really something that anyone working on a federated system should study in detail, because they are bound to make the same mistakes if they are not familiar with it. The "short" version is:
  • 1988: Finnish researcher publishes first IRC source code
  • 1989: 40 servers worldwide, mostly universities
  • 1990: EFnet ("eris-free network") fork which blocks the "open relay", named Eris - followers of Eris form the A-net, which promptly dissolves itself, with only EFnet remaining
  • 1992: Undernet fork, which offered authentication ("services"), routing improvements and timestamp-based channel synchronisation
  • 1994: DALnet fork, from Undernet, again on a technical disagreement
  • 1995: Freenode founded
  • 1996: IRCnet forks from EFnet, following a flame war of historical proportion, splitting the network between Europe and the Americas
  • 1997: Quakenet founded
  • 1999: (XMPP founded)
  • 2001: 6 million users, OFTC founded
  • 2002: DALnet peaks at 136,000 users
  • 2003: IRC as a whole peaks at 10 million users, EFnet peaks at 141,000 users
  • 2004: (Facebook founded), Undernet peaks at 159,000 users
  • 2005: Quakenet peaks at 242,000 users, IRCnet peaks at 136,000 (Youtube founded)
  • 2006: (Twitter founded)
  • 2009: (WhatsApp, Pinterest founded)
  • 2010: (TextSecure AKA Signal, Instagram founded)
  • 2011: (Snapchat founded)
  • ~2013: Freenode peaks at ~100,000 users
  • 2016: IRCv3 standardisation effort started (TikTok founded)
  • 2021: Freenode self-destructs, Libera chat founded
  • 2022: Libera peaks at 50,000 users, OFTC peaks at 30,000 users
(The numbers were taken from the Wikipedia page and Netsplit.de. Note that I also include other networks launch in parenthesis for context.) Pretty dramatic, don't you think? Eventually, somehow, IRC became irrelevant for most people: few people are even aware of it now. With less than a million users active, it's smaller than Mastodon, XMPP, or Matrix at this point.1 If I were to venture a guess, I'd say that infighting, lack of a standardization body, and a somewhat annoying protocol meant the network could not grow. It's also possible that the decentralised yet centralised structure of IRC networks limited their reliability and growth. But large social media companies have also taken over the space: observe how IRC numbers peak around the time the wave of large social media companies emerge, especially Facebook (2.9B users!!) and Twitter (400M users).

Where the federated services are in history Right now, Matrix, and Mastodon (and email!) are at the "pre-EFnet" stage: anyone can join the federation. Mastodon has started working on a global block list of fascist servers which is interesting, but it's still an open federation. Right now, Matrix is totally open, but matrix.org publishes a (federated) block list of hostile servers (#matrix-org-coc-bl:matrix.org, yes, of course it's a room). Interestingly, Email is also in that stage, where there are block lists of spammers, and it's a race between those blockers and spammers. Large email providers, obviously, are getting closer to the EFnet stage: you could consider they only accept email from themselves or between themselves. It's getting increasingly hard to deliver mail to Outlook and Gmail for example, partly because of bias against small providers, but also because they are including more and more machine-learning tools to sort through email and those systems are, fundamentally, unknowable. It's not quite the same as splitting the federation the way EFnet did, but the effect is similar. HTTP has somehow managed to live in a parallel universe, as it's technically still completely federated: anyone can start a web server if they have a public IP address and anyone can connect to it. The catch, of course, is how you find the darn thing. Which is how Google became one of the most powerful corporations on earth, and how they became the gatekeepers of human knowledge online. I have only briefly mentioned XMPP here, and my XMPP fans will undoubtedly comment on that, but I think it's somewhere in the middle of all of this. It was co-opted by Facebook and Google, and both corporations have abandoned it to its fate. I remember fondly the days where I could do instant messaging with my contacts who had a Gmail account. Those days are gone, and I don't talk to anyone over Jabber anymore, unfortunately. And this is a threat that Matrix still has to face. It's also the threat Email is currently facing. On the one hand corporations like Facebook want to completely destroy it and have mostly succeeded: many people just have an email account to register on things and talk to their friends over Instagram or (lately) TikTok (which, I know, is not Facebook, but they started that fire). On the other hand, you have corporations like Microsoft and Google who are still using and providing email services because, frankly, you still do need email for stuff, just like fax is still around but they are more and more isolated in their own silo. At this point, it's only a matter of time they reach critical mass and just decide that the risk of allowing external mail coming in is not worth the cost. They'll simply flip the switch and work on an allow-list principle. Then we'll have closed the loop and email will be dead, just like IRC is "dead" now. I wonder which path Matrix will take. Could it liberate us from these vicious cycles? Update: this generated some discussions on lobste.rs.

  1. According to Wikipedia, there are currently about 500 distinct IRC networks operating, on about 1,000 servers, serving over 250,000 users. In contrast, Mastodon seems to be around 5 million users, Matrix.org claimed at FOSDEM 2021 to have about 28 million globally visible accounts, and Signal lays claim to over 40 million souls. XMPP claims to have "millions" of users on the xmpp.org homepage but the FAQ says they don't actually know. On the proprietary silo side of the fence, this page says
    • Facebook: 2.9 billion users
    • WhatsApp: 2B
    • Instagram: 1.4B
    • TikTok: 1B
    • Snapchat: 500M
    • Pinterest: 480M
    • Twitter: 397M
    Notable omission from that list: Youtube, with its mind-boggling 2.6 billion users... Those are not the kind of numbers you just "need to convince a brother or sister" to grow the network...

16 June 2022

Dirk Eddelbuettel: RcppArmadillo 0.11.2.0.0 on CRAN: New Upstream

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 991 other packages on CRAN, downloaded over 25 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 476 times according to Google Scholar. This release brings a second upstream fix by Conrad in the release series 11.*. We once again tested this very rigorously via a complete reverse-depedency check (for which results are always logged here). It so happens that CRAN then had a spurious error when re-checking on upload, and it took a fews days to square this as everybody remains busy but the release prepared on June 10 is now on CRAN. The full set of changes (since the last CRAN release 0.11.1.1.0) follows.

Changes in RcppArmadillo version 0.11.2.0.0 (2022-06-10)
  • Upgraded to Armadillo release 11.2 (Classic Roast)
    • faster handling of sparse submatrix column views by norm(), accu(), nonzeros()
    • extended randu() and randn() to allow specification of distribution parameters
    • internal refactoring, leading to faster compilation times

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

13 June 2022

Edward Betts: Fixing spelling in GitHub repos using codespell

Codespell is a spell checker specifically designed for finding misspellings in source code. I've been using it to correct spelling mistakes in GitHub repos sine 2016. Most spell checkers use a list of valid words and highlighting any word in a document that is not in the word list. This method doesn't work for source code because code contains abbreviations and words joined together without spaces, a spell checker will generate too many false positives. Codespell uses a different approach, instead of a list of valid words it has a dictionary of common misspellings. Currently the codespell dictionary includes 34,466 known misspellings. I've contributed 300 misspellings to the dictionary. Whenever I find an interesting open source project I run codespell to check for spelling mistakes. Most projects have spelling mistakes and I can send a pull request to fix them. In 2019 Microsoft made the Windows calculator open source and uploaded it to GitHub. I used codespell to find some spelling mistakes, sent them a pull request and they accepted it. A great source for GitHub repos to spell check is Hacker News. Let's have a look.
Hacker News has a link to forum software called Flarum. I can use codespell to look for spelling mistakes. When I'm looking for errors in a GitHub repo I don't fork the project until I know there is a spelling mistake to fix.
edward@x1c9 ~/spelling> git clone git@github.com:flarum/flarum.git
Cloning into &aposflarum&apos...
remote: Enumerating objects: 1338, done.
remote: Counting objects: 100% (42/42), done.
remote: Compressing objects: 100% (23/23), done.
remote: Total 1338 (delta 21), reused 36 (delta 19), pack-reused 1296
Receiving objects: 100% (1338/1338), 725.02 KiB   1.09 MiB/s, done.
Resolving deltas: 100% (720/720), done.
edward@x1c9 ~/spelling> cd flarum/
edward@x1c9 ~/spelling/flarum (master)> codespell -q3
./public/web.config:13: sensitve ==> sensitive
edward@x1c9 ~/spelling/flarum (master)> gh repo fork
  Created fork EdwardBetts/flarum
? Would you like to add a remote for the fork? Yes
  Added remote origin
edward@x1c9 ~/spelling/flarum (master)> git checkout -b spelling
Switched to a new branch &aposspelling&apos
edward@x1c9 ~/spelling/flarum (spelling)> codespell -q3
./public/web.config:13: sensitve ==> sensitive
edward@x1c9 ~/spelling/flarum (spelling)> codespell -q3 -w
FIXED: ./public/web.config
edward@x1c9 ~/spelling/flarum (spelling)> git commit -am "Correct spelling mistakes"
[spelling bbb04c7] Correct spelling mistakes
 1 file changed, 1 insertion(+), 1 deletion(-)
edward@x1c9 ~/spelling/flarum (spelling)> git push -u origin
Enumerating objects: 7, done.
Counting objects: 100% (7/7), done.
Delta compression using up to 8 threads
Compressing objects: 100% (4/4), done.
Writing objects: 100% (4/4), 360 bytes   360.00 KiB/s, done.
Total 4 (delta 3), reused 0 (delta 0), pack-reused 0
remote: Resolving deltas: 100% (3/3), completed with 3 local objects.
remote: 
remote: Create a pull request for &aposspelling&apos on GitHub by visiting:
remote:      https://github.com/EdwardBetts/flarum/pull/new/spelling
remote: 
To github.com:EdwardBetts/flarum.git
 * [new branch]      spelling -> spelling
branch &aposspelling&apos set up to track &aposorigin/spelling&apos.
edward@x1c9 ~/spelling/flarum (spelling)> gh pr create 
Creating pull request for EdwardBetts:spelling into master in flarum/flarum
? Title Correct spelling mistakes
? Choose a template Open a blank pull request
? Body <Received>
? What&aposs next? Submit
https://github.com/flarum/flarum/pull/81
edward@x1c9 ~/spelling/flarum (spelling)> 
That worked. I found one spelling mistake, the word "sensitive" was spelled wrong. I forked the repo, fixed the spelling mistake and submitted the fix as a pull request.
The maintainer of Flarum accepted my pull request. Fixing spelling mistakes in Bootstrap helped me unlocked the Mars 2020 Contributor achievements on GitHub.
Why not try running codespell on your own codebase? You'll probably find some spelling mistakes to fix.

12 June 2022

Russ Allbery: Review: The Shattered Sphere

Review: The Shattered Sphere, by Roger MacBride Allen
Series: Hunted Earth #2
Publisher: Tor
Copyright: July 1994
Printing: September 1995
ISBN: 0-8125-3016-0
Format: Mass market
Pages: 491
The Shattered Sphere is a direct sequel to The Ring of Charon and spoils everything about the plot of the first book. You don't want to start here. Also be aware that essentially everything you can read about this book will spoil the major plot driver of The Ring of Charon in the first sentence. I'm going to review the book without doing that, but it's unlikely anyone else will try. The end of the previous book stabilized matters, but in no way resolved the plot. The Shattered Sphere opens five years later. Most of the characters from the first novel are joined by some new additions, and all of them are trying to make sense of a drastically changed and far more dangerous understanding of the universe. Humanity has a new enemy, one that's largely unaware of humanity's existence and able to operate on a scale that dwarfs human endeavors. The good news is that humans aren't being actively attacked. The bad news is that they may be little more than raw resources, stashed in a safe spot for future use. That is reason enough to worry. Worse are the hints of a far greater danger, one that may be capable of destruction on a scale nearly beyond human comprehension. Humanity may be trapped between a sophisticated enemy to whom human activity is barely more noticeable than ants, and a mysterious power that sends that enemy into an anxious panic. This series is an easily-recognized example of an in-between style of science fiction. It shares the conceptual bones of an earlier era of short engineer-with-a-wrench stories that are full of set pieces and giant constructs, but Allen attempts to add the characterization that those books lacked. But the technique isn't there; he's trying, and the basics of characterization are present, but with none of the emotional and descriptive sophistication of more recent SF. The result isn't bad, exactly, but it's bloated and belabored. Most of the characterization comes through repetition and ham-handed attempts at inner dialogue. Slow plotting doesn't help. Allen spends half of a nearly 500 page novel on setup in two primary threads. One is mostly people explaining detailed scientific theories to each other, mixed with an attempt at creating reader empathy that's more forceful than effective. The other is a sort of big dumb object exploration that failed to hold my attention and that turned out to be mostly irrelevant. Key revelations from that thread are revealed less by the actions of the characters than by dumping them on the reader in an extended monologue. The reading goes quickly, but only because the writing is predictable and light on interesting information, not because the plot is pulling the reader through the book. I found myself wishing for an earlier era that would have cut about 300 pages out of this book without losing any of the major events. Once things finally start happening, the book improves considerably. I grew up reading large-scale scientific puzzle stories, and I still have a soft spot for a last-minute scientific fix and dramatic set piece even if the descriptive detail leaves something to be desired. The last fifty pages are fast-moving and satisfying, only marred by their failure to convince me that the humans were required for the plot. The process of understanding alien technology well enough to use it the right way kept me entertained, but I don't understand why the aliens didn't use it themselves. I think this book falls between two stools. The scientific mysteries and set pieces would have filled a tight, fast-moving 200 page book with a minimum of characterization. It would have been a throwback to an earlier era of science fiction, but not a bad one. Allen instead wanted to provide a large cast of sympathetic and complex characters, and while I appreciate the continued lack of villains, the writing quality is not sufficient to the task. This isn't an awful book, but the quality bar in the genre is so much higher now. There are better investments of your reading time available today. Like The Ring of Charon, The Shattered Sphere reaches a satisfying conclusion but does not resolve the series plot. No sequel has been published, and at this point one seems unlikely to materialize. Rating: 5 out of 10

6 June 2022

Reproducible Builds: Reproducible Builds in May 2022

Welcome to the May 2022 report from the Reproducible Builds project. In our reports we outline the most important things that we have been up to over the past month. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.

Repfix paper Zhilei Ren, Shiwei Sun, Jifeng Xuan, Xiaochen Li, Zhide Zhou and He Jiang have published an academic paper titled Automated Patching for Unreproducible Builds:
[..] fixing unreproducible build issues poses a set of challenges [..], among which we consider the localization granularity and the historical knowledge utilization as the most significant ones. To tackle these challenges, we propose a novel approach [called] RepFix that combines tracing-based fine-grained localization with history-based patch generation mechanisms.
The paper (PDF, 3.5MB) uses the Debian mylvmbackup package as an example to show how RepFix can automatically generate patches to make software build reproducibly. As it happens, Reiner Herrmann submitted a patch for the mylvmbackup package which has remained unapplied by the Debian package maintainer for over seven years, thus this paper inadvertently underscores that achieving reproducible builds will require both technical and social solutions.

Python variables Johannes Schauer discovered a fascinating bug where simply naming your Python variable _m led to unreproducible .pyc files. In particular, the types module in Python 3.10 requires the following patch to make it reproducible:
--- a/Lib/types.py
+++ b/Lib/types.py
@@ -37,8 +37,8 @@ _ag = _ag()
 AsyncGeneratorType = type(_ag)
 
 class _C:
-    def _m(self): pass
-MethodType = type(_C()._m)
+    def _b(self): pass
+MethodType = type(_C()._b)
Simply renaming the dummy method from _m to _b was enough to workaround the problem. Johannes bug report first led to a number of improvements in diffoscope to aid in dissecting .pyc files, but upstream identified this as caused by an issue surrounding interned strings and is being tracked in CPython bug #78274.

New SPDX team to incorporate build metadata in Software Bill of Materials SPDX, the open standard for Software Bill of Materials (SBOM), is continuously developed by a number of teams and committees. However, SPDX has welcomed a new addition; a team dedicated to enhancing metadata about software builds, complementing reproducible builds in creating a more secure software supply chain. The SPDX Builds Team has been working throughout May to define the universal primitives shared by all build systems, including the who, what, where and how of builds:
  • Who: the identity of the person or organisation that controls the build infrastructure.
  • What: the inputs and outputs of a given build, combining metadata about the build s configuration with an SBOM describing source code and dependencies.
  • Where: the software packages making up the build system, from build orchestration tools such as Woodpecker CI and Tekton to language-specific tools.
  • How: the invocation of a build, linking metadata of a build to the identity of the person or automation tool that initiated it.
The SPDX Builds Team expects to have a usable data model by September, ready for inclusion in the SPDX 3.0 standard. The team welcomes new contributors, inviting those interested in joining to introduce themselves on the SPDX-Tech mailing list.

Talks at Debian Reunion Hamburg Some of the Reproducible Builds team (Holger Levsen, Mattia Rizzolo, Roland Clobus, Philip Rinn, etc.) met in real life at the Debian Reunion Hamburg (official homepage). There were several informal discussions amongst them, as well as two talks related to reproducible builds. First, Holger Levsen gave a talk on the status of Reproducible Builds for bullseye and bookworm and beyond (WebM, 210MB): Secondly, Roland Clobus gave a talk called Reproducible builds as applied to non-compiler output (WebM, 115MB):

Supply-chain security attacks This was another bumper month for supply-chain attacks in package repositories. Early in the month, Lance R. Vick noticed that the maintainer of the NPM foreach package let their personal email domain expire, so they bought it and now controls foreach on NPM and the 36,826 projects that depend on it . Shortly afterwards, Drew DeVault published a related blog post titled When will we learn? that offers a brief timeline of major incidents in this area and, not uncontroversially, suggests that the correct way to ship packages is with your distribution s package manager .

Bootstrapping Bootstrapping is a process for building software tools progressively from a primitive compiler tool and source language up to a full Linux development environment with GCC, etc. This is important given the amount of trust we put in existing compiler binaries. This month, a bootstrappable mini-kernel was announced. Called boot2now, it comprises a series of compilers in the form of bootable machine images.

Google s new Assured Open Source Software service Google Cloud (the division responsible for the Google Compute Engine) announced a new Assured Open Source Software service. Noting the considerable 650% year-over-year increase in cyberattacks aimed at open source suppliers, the new service claims to enable enterprise and public sector users of open source software to easily incorporate the same OSS packages that Google uses into their own developer workflows . The announcement goes on to enumerate that packages curated by the new service would be:
  • Regularly scanned, analyzed, and fuzz-tested for vulnerabilities.
  • Have corresponding enriched metadata incorporating Container/Artifact Analysis data.
  • Are built with Cloud Build including evidence of verifiable SLSA-compliance
  • Are verifiably signed by Google.
  • Are distributed from an Artifact Registry secured and protected by Google.
(Full announcement)

A retrospective on the Rust programming language Andrew bunnie Huang published a long blog post this month promising a critical retrospective on the Rust programming language. Amongst many acute observations about the evolution of the language s syntax (etc.), the post beings to critique the languages approach to supply chain security ( Rust Has A Limited View of Supply Chain Security ) and reproducibility ( You Can t Reproduce Someone Else s Rust Build ):
There s some bugs open with the Rust maintainers to address reproducible builds, but with the number of issues they have to deal with in the language, I am not optimistic that this problem will be resolved anytime soon. Assuming the only driver of the unreproducibility is the inclusion of OS paths in the binary, one fix to this would be to re-configure our build system to run in some sort of a chroot environment or a virtual machine that fixes the paths in a way that almost anyone else could reproduce. I say almost anyone else because this fix would be OS-dependent, so we d be able to get reproducible builds under, for example, Linux, but it would not help Windows users where chroot environments are not a thing.
(Full post)

Reproducible Builds IRC meeting The minutes and logs from our May 2022 IRC meeting have been published. In case you missed this one, our next IRC meeting will take place on Tuesday 28th June at 15:00 UTC on #reproducible-builds on the OFTC network.

A new tool to improve supply-chain security in Arch Linux kpcyrd published yet another interesting tool related to reproducibility. Writing about the tool in a recent blog post, kpcyrd mentions that although many PKGBUILDs provide authentication in the context of signed Git tags (i.e. the ability to verify the Git tag was signed by one of the two trusted keys ), they do not support pinning, ie. that upstream could create a new signed Git tag with an identical name, and arbitrarily change the source code without the [maintainer] noticing . Conversely, other PKGBUILDs support pinning but not authentication. The new tool, auth-tarball-from-git, fixes both problems, as nearly outlined in kpcyrd s original blog post.

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb prepared and uploaded versions 212, 213 and 214 to Debian unstable. Chris also made the following changes:
  • New features:
    • Add support for extracting vmlinuz Linux kernel images. [ ]
    • Support both python-argcomplete 1.x and 2.x. [ ]
    • Strip sticky etc. from x.deb: sticky Debian binary package [ ]. [ ]
    • Integrate test coverage with GitLab s concept of artifacts. [ ][ ][ ]
  • Bug fixes:
    • Don t mask differences in .zip or .jar central directory extra fields. [ ]
    • Don t show a binary comparison of .zip or .jar files if we have observed at least one nested difference. [ ]
  • Codebase improvements:
    • Substantially update comment for our calls to zipinfo and zipinfo -v. [ ]
    • Use assert_diff in test_zip over calling get_data with a separate assert. [ ]
    • Don t call re.compile and then call .sub on the result; just call re.sub directly. [ ]
    • Clarify the comment around the difference between --usage and --help. [ ]
  • Testsuite improvements:
    • Test --help and --usage. [ ]
    • Test that --help includes the file formats. [ ]
Vagrant Cascadian added an external tool reference xb-tool for GNU Guix [ ] as well as updated the diffoscope package in GNU Guix itself [ ][ ][ ].

Distribution work In Debian, 41 reviews of Debian packages were added, 85 were updated and 13 were removed this month adding to our knowledge about identified issues. A number of issue types have been updated, including adding a new nondeterministic_ordering_in_deprecated_items_collected_by_doxygen toolchain issue [ ] as well as ones for mono_mastersummary_xml_files_inherit_filesystem_ordering [ ], extended_attributes_in_jar_file_created_without_manifest [ ] and apxs_captures_build_path [ ]. Vagrant Cascadian performed a rough check of the reproducibility of core package sets in GNU Guix, and in openSUSE, Bernhard M. Wiedemann posted his usual monthly reproducible builds status report.

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:

Reproducible builds website Chris Lamb updated the main Reproducible Builds website and documentation in a number of small ways, but also prepared and published an interview with Jan Nieuwenhuizen about Bootstrappable Builds, GNU Mes and GNU Guix. [ ][ ][ ][ ] In addition, Tim Jones added a link to the Talos Linux project [ ] and billchenchina fixed a dead link [ ].

Testing framework The Reproducible Builds project runs a significant testing framework at tests.reproducible-builds.org, to check packages and other artifacts for reproducibility. This month, the following changes were made:
  • Holger Levsen:
    • Add support for detecting running kernels that require attention. [ ]
    • Temporarily configure a host to support performing Debian builds for packages that lack .buildinfo files. [ ]
    • Update generated webpages to clarify wishes for feedback. [ ]
    • Update copyright years on various scripts. [ ]
  • Mattia Rizzolo:
    • Provide a facility so that Debian Live image generation can copy a file remotely. [ ][ ][ ][ ]
  • Roland Clobus:
    • Add initial support for testing generated images with OpenQA. [ ]
And finally, as usual, node maintenance was also performed by Holger Levsen [ ][ ].

Misc news On our mailing list this month:

Contact If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

3 June 2022

Petter Reinholdtsen: LinuxCNC translators life just got a bit easier

Back in oktober last year, when I started looking at the LinuxCNC system, I proposed to change the documentation build system make life easier for translators. The original system consisted of independently written documentation files for each language, with no automated way to track changes done in other translations and no help for the translators to know how much was left to translated. By using the po4a system to generate POT and PO files from the English documentation, this can be improved. A small team of LinuxCNC contributors got together and today our labour finally payed off. Since a few hours ago, it is now possible to translate the LinuxCNC documentation on Weblate, alongside the program itself. The effort to migrate the documentation to use po4a has been both slow and frustrating. I am very happy we finally made it. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Rapha&#235;l Hertzog: Freexian s report about Debian Long Term Support, April 2022

A Debian LTS logo
Like each month, have a look at the work funded by Freexian s Debian LTS offering. Debian project funding Two projects are currently in the pipeline: Gradle enterprise and Tryton update. Progress is quite slow on the Gradle one, there are technical difficulties. The tryton one was stalled because the developer had not enough time but seems to progress smoothly in the last weeks. In April, we put aside 2635 EUR to fund Debian projects. We re looking forward to receive more projects from various Debian teams! Learn more about the rationale behind this initiative in this article. Debian LTS contributors In April, 11 contributors have been paid to work on Debian LTS, their reports are available: Evolution of the situation In April we released 30 DLAs and we were glad to welcome a new customer with Alter Way. The security tracker currently lists 72 packages with a known CVE and the dla-needed.txt file has 71 packages needing an update. It is worth pointing out that we are getting close to the end of the LTS period for Debian 9. After June 30th, no new security updates will be made available on security.debian.org. But Freexian and its team of paid Debian contributors will continue to maintain Debian 9 going forward for the customers of the Extended LTS offer. If you have Debian 9 servers to keep secure, it s time to subscribe! You might not have noticed, but Freexian formalized a mission statement where we explain that our purpose is to help improve Debian. For this, we want to fund work time for the Debian developers that recently joined Freexian as collaborators. The Extended LTS and the PHP LTS offers are built following a model that will help us to achieve this if we manage to have enough customers for those offers. So consider subscribing: you help your organization but you also help Debian! Thanks to our sponsors Sponsors that joined recently are in bold.

Reproducible Builds (diffoscope): diffoscope 215 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 215. This version includes the following changes:
[ Chris Lamb ]
* Bug fixes:
  - Also catch IndexError (in addition to ValueError) when parsing .pyc
    files. (Closes: #1012258)
  - Strip "sticky" etc. from "x.deb: sticky Debian binary package [ ]".
    Thanks to David Pr vot for the report. (Closes: #1011635)
  - Correctly package diffoscope's scripts/ directory, fixing the extraction
    of vmlinuz kernel images. (Closes: reproducible-builds/diffoscope#305)
  - Correct the logic for supporting different versions of argcomplete in
    debian/rules.
* New features:
  - Support both PyPDF 1.x and 2.x.
* Codebase improvements:
  - Don't call re.compile and then call .sub on the result; just call
    re.sub directly.
  - Clarify the logic around the difference between --usage and --help.
* Testsuite improvements:
  - Integrate test coverage with GitLab's concept of artifacts.
  - Re-enable Gnumeric tests as its now available again.
  - Test --help and --usage, and additionally test that --help includes
    the programmatically-generated file format list as well.
[ Holger Levsen ]
* Bump Standards Version field in debian/control to 4.6.1.
You find out more by visiting the project homepage.

1 June 2022

Russ Allbery: Review: The Seeress of Kell

Review: The Seeress of Kell, by David Eddings
Series: The Malloreon #5
Publisher: Del Rey
Copyright: May 1991
Printing: May 1992
ISBN: 0-345-37759-1
Format: Mass market
Pages: 374
The Seeress of Kell is the conclusion of the five-book Malloreon series and a direct sequel to Sorceress of Darshiva. You do not want to begin the series here (or, to be honest, at all). We have finally finished the relaxed tour of Mallorea, the second continent of Eddings's remarkably small two-continent world. The heroes have gathered all of their required companions and are headed for Kell, where the seeress Cyradis awaits. From there, they and the new Child of Dark must find their way to the Place Which Is No More for the final confrontation. By "find," I mean please remain seated with your hands, arms, feet, and legs inside the vehicle. The protagonists have about as much to do with the conclusion of this series as the passengers of a roller coaster have control over its steering. I am laughing at my younger self, who quite enjoyed this series (although as I recall found it a bit repetitive) and compared it favorably to the earlier Belgariad series. My memory kept telling me that the conclusion of the series was lots of fun. Reader, it was not. It was hilariously bad. Both of Eddings's first two series, but particularly this one, take place in a fantasy world full of true prophecy. The conceit of the Malloreon in particular (this is a minor spoiler for the early books, but not one that I think interferes with enjoyment) is that there are two competing prophecies that agree on most events but are in conflict over a critical outcome. True prophecy creates an agency problem: why have protagonists if everything they do is fixed in prophecy? The normal way to avoid that is to make the prophecy sufficiently confusing and the mechanism by which it comes true sufficiently subtle that everyone has to act as if there is no prophecy, thus reducing the role of the prophecy to foreshadowing and a game the author plays with the reader. What makes the Malloreon interesting (and I mean this sincerely) is that Eddings instead leans into the idea of a prophecy as an active agent leading the protagonists around by the nose. As a meta-story commentary on fantasy stories, this can be quite entertaining, and it helps that the prophecy appears as a likable character of sorts in the book. The trap that Eddings had mostly avoided before now is that this structure can make the choices of the protagonists entirely pointless. In The Seeress of Kell, he dives head-first into the trap and then pulls it shut behind him. The worst part is Ce'Nedra, who once again spends an entire book either carping at Garion in ways that are supposed to be endearing (but aren't) or being actively useless. The low point is when she is manipulated into betraying the heroes, costing them a significant advantage. We're then told that, rather than being a horrific disaster, this is her important and vital role in the story, and indeed the whole reason why she was in the story at all. The heroes were too far ahead of the villains and were in danger of causing the prophecy to fail. At that point, one might reasonably ask why one is bothering reading a novel instead of a summary of the invented history that Eddings is going to tell whether his characters cooperate or not. The whole middle section of the book is like this: nothing any of the characters do matters because everything is explicitly destined. That includes an extended series of interludes following the other main characters from the Belgariad, who are racing to catch up with the main party but who will turn out to have no role of significance whatsoever. I wouldn't mind this as much if the prophecy were more active in the story, given that it's the actual protagonist. But it mostly disappears. Instead, the characters blunder around doing whatever seems like a good idea at the time, while Cyradis acts like a bizarre sort of referee with a Calvinball rule set and every random action turns out to be the fulfillment of prophecy in the most ham-handed possible way. Zandramas, meanwhile, is trying to break the prophecy, which would have been a moderately interesting story hook if anyone (Eddings included) thought she were potentially capable of doing so. Since no one truly believes there's any peril, this turns into a series of pointless battles the reader has no reason to care about. All of this sets up what has been advertised since the start of the series as a decision between good and evil. Now, at the least minute, Eddings (through various character mouthpieces) tries to claim that the decision is not actually between good and evil, but is somehow beyond morality. No one believes this, including the narrator and the reader, making all of the philosophizing a tedious exercise in page-turning. To pull off a contention like that, the author has to lay some sort of foundation to allow the reader to see the supposed villain in multiple lights. Eddings does none of that, instead emphasizing how evil she is at every opportunity. On top of that, this supposed free choice on which the entire universe rests and for which all of history was pointed depends on someone with astonishing conflicts of interest. While the book is going on about how carefully the prophecy is ensuring that everyone is in the right place at the right time so that no side has an advantage, one side is accruing an absurdly powerful advantage. And the characters don't even seem to realize it! The less said about the climax, the better. Unsurprisingly, it was completely predictable. Also, while I am complaining, I could never get past how this entire series starts off with and revolves around an incredibly traumatic and ongoing event that has no impact whatsoever on the person to whom the trauma happens. Other people are intermittently upset or sad, but not only is that person not harmed, they act, at the end of this book, as if the entire series had never happened. There is one bright spot in this book, and ironically it's the one plot element that Eddings didn't make blatantly obvious in advance and therefore I don't want to spoil it. All I'll say is that one of the companions the heroes pick up along the way turns out to be my favorite character of the series, plays a significant role in the interpersonal dynamics between the heroes, and steals every scene that she's in by being more sensible than any of the other characters in the story. Her story, and backstory, is emotional and moving and is the best part of this book. Otherwise, not only is the plot a mess and the story structure a failure, but this is also Eddings at his most sexist and socially conservative. There is an extended epilogue after the plot resolution that serves primarily as a showcase of stereotypes: baffled men having their habits and preferences rewritten by their wives, cast-iron gender roles inside marriage, cringeworthy jokes, and of course loads and loads of children because that obviously should be everyone's happily ever after. All of this happens to the characters rather than being planned or actively desired, continuing the theme of prophecy and lack of agency, although of course they're all happy about it (shown mostly via grumbling). One could write an entire academic paper on the tension between this series and the concept of consent. There were bits of the Malloreon that I enjoyed, but they were generally in spite of the plot rather than because of it. I do like several of Eddings's characters, and in places I liked the lack of urgency and the sense of safety. But I think endings still have to deliver some twist or punch or, at the very least, some clear need for the protagonists to take an action other than stand in the right room at the right time. Eddings probably tried to supply that (I can make a few guesses about where), but it failed miserably for me, making this the worst book of the series. Unless like me you're revisiting this out of curiosity for your teenage reading habits (and even then, consider not), avoid. Rating: 3 out of 10

31 May 2022

Russell Coker: Links May 2022

dontkillmyapp.com is a web site about Android phone vendors who make their phones kill your apps when you don t want them to [1]. One of the many reasons why Pine and Purism offer the promise of better phones. This blog post about the Librem 5 camera is interesting [2]. Currently the Librem 5 camera isn t very usable for me as I just want to point and shoot, but it apparently works well for experts. Taking RAW photos is a good feature that I d like to have in all my camera phones. The Russian government being apparently unaware of the Streisand Effect has threatened Wikipedia for publishing facts about the war against Ukraine [3]. We all should publicise this as much as possible. The Wikipedia page is The 2022 Russian Invasion of Ukraine [4]. The Jerusalem Post has an interesting article about whether Mein Kampf should be published and studied in schools [5]. I don t agree with the conclusions about studying that book in schools, but I think that the analysis of the situation in that article is worth reading. One of the issues I have with teaching Mein Kampf and similar books is the quality of social studies teaching at the school I attended, I m pretty sure that teaching Mein Kampf in any way at that school would just turn out more neo-Nazis. Maybe better schools (IE not Christian private schools) could have productive classes about Mein Kampf Vanity Fair has an interesting article about the history of the private jet [6]. Current Affairs has an unusually informative article about why blockchain currencies should die in a fire [7]. The Nazi use of methamphetamine is well known, but Time has an insightful article about lesser known aspects of meth use [8]. How they considered meth as separate from the drugs they claimed were for the morally inferior is interesting. George Monbiot wrote an insightful article comparing the 2008 bank collapse to the current system of unstable food supplies [9]. JWZ wrote an insightful blog post about Following the Money regarding the push to reopen businesses even though the pandemic is far from over [10]. His conclusion is that commercial property owners are pushing the governments to give them more money. PsyPost has an interesting article on the correlation between watching Fox News and lacking knowledge of science and of society [11]. David Brin wrote an interesting paper about Disputation and how that can benefit society [12]. I think he goes too far in some of his claims, but he has interesting points. The overall idea of a Disputation arena for ideas is a really good one. I previously had a similar idea on a much smaller scale of having debates via Wiki [13].

30 May 2022

Bits from Debian: Debian welcomes its new Outreachy interns

Outreachy logo Debian continues participating in Outreachy, and we're excited to announce that Debian has selected two interns for the Outreachy May 2022 - August 2022 round. Israel Galadima and Michael Ikwuegbu will work on Improve yarn package manager integration with Debian, mentored by Akshay S Dinesh and Pirate Praveen.
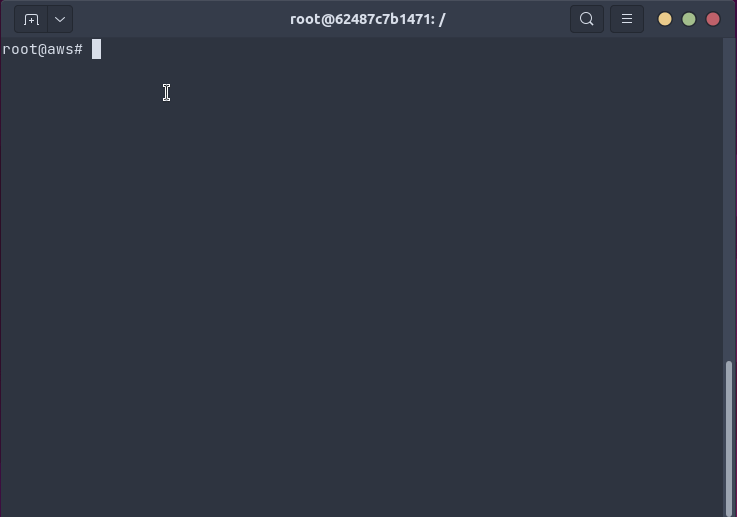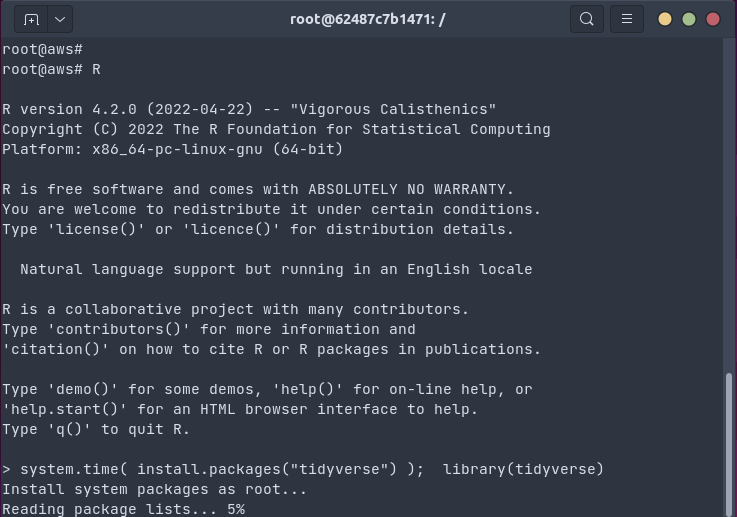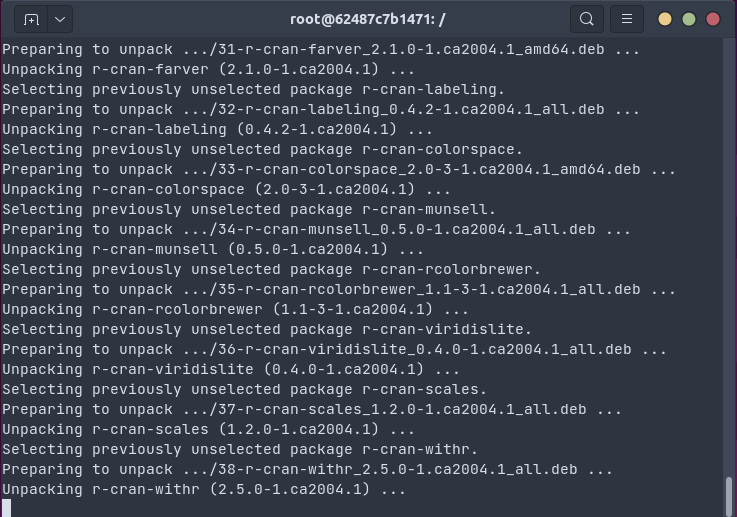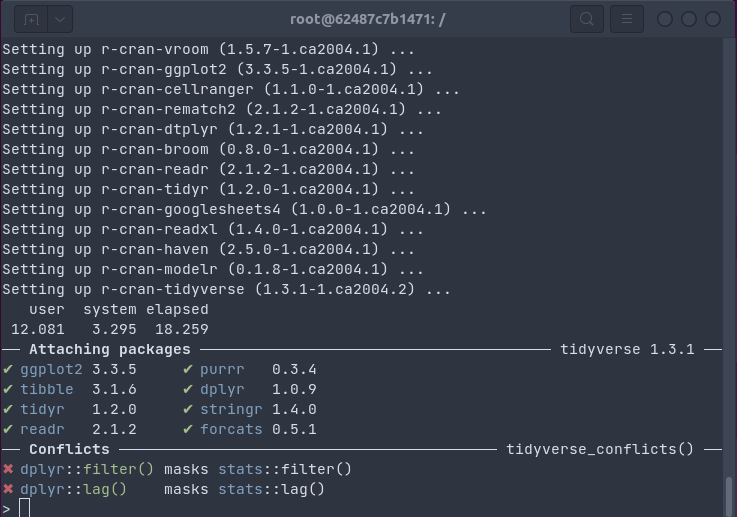
Congratulations and welcome to Israel Galadima and Michael Ikwuegbu! From the official website: Outreachy provides three-month internships for people from groups traditionally underrepresented in tech. Interns work remotely with mentors from Free and Open Source Software (FOSS) communities on projects ranging from programming, user experience, documentation, illustration and graphical design, to data science. The Outreachy programme is possible in Debian thanks to the efforts of Debian developers and contributors who dedicate their free time to mentor students and outreach tasks, and the Software Freedom Conservancy's administrative support, as well as the continued support of Debian's donors, who provide funding for the internships. Join us and help extend Debian! You can follow the work of the Outreachy interns reading their blogs (they are syndicated in Planet Debian), and chat with us in the #debian-outreach IRC channel and mailing list.

29 May 2022

Russ Allbery: Review: Kleptopia

Review: Kleptopia, by Tom Burgis
Publisher: Harper
Copyright: 2020
Printing: September 2021
ISBN: 0-06-323613-3
Format: Kindle
Pages: 340
Kleptopia is a nonfiction chronicle of international financial corruption and money laundering told via a focus on the former Soviet republic of Kazakhstan. The primary characters are a British banker named Nigel Wilkins (at the start of the story, the head of compliance in the London office of the Swiss bank BSI), a group of businessmen from Kyrgyzstan and Uzbekistan called the Trio, and a Kazakh oligarch and later political dissident named Mukhtar Ablyazov, although the story spreads beyond them. It is partly a detailed example of what money laundering looks like in practice: where the money comes from, who has it, what they want to do with it, who they hire to move it, and what countries welcome it. But it is more broadly about the use of politics for financial plunder, and what stories we tell about the results. The title of this book feels a bit like clickbait, and I was worried it would be mostly opinion and policy discussion. It is the exact opposite. Tom Burgis is an investigations correspondent at the Financial Times, and this is a detailed piece of investigative journalism (backed by a hundred pages of notes and detailed attributions). Burgis has a clear viewpoint and expresses it when it seems relevant, but the vast majority of this book is the sort of specific account of people, dates, times, and events that one would expect from a full-length investigative magazine piece, except maintained at book length. Even aside from the subject matter, I love that writing like this exists. It's often best in magazines, newspapers, and on-line articles for timeliness, since book publishing is slow, but some subjects require the length of a book. Burgis is the sort of reporter who travels the world to meet with sources in person, and who, before publication, presents his conclusions to everyone mentioned for their rebuttals (many of which are summarized or quoted in detail in the notes so that the reader can draw their own credibility conclusions). Whether or not one agrees with his specific conclusions or emphasis, we need more of this sort of journalism in the world. I knew essentially nothing about Kazakhstan or its politics before reading this book. I also had not appreciated the degree to which exploitation of natural resources is the original source of the money for international money laundering. In both Kazakhstan and Africa (a secondary setting for this book), people get rich largely because of things dug or pumped out of the ground. That money, predictably, does not go to the people doing the hard work of digging and pumping, who work in appalling conditions and are put down with violence if they try to force change. (In one chapter, Burgis tells the harrowing and nightmarish story of Roza Tuletayeva, a striker at the oil field in Zhanaozen.) It's gathered up by the already rich and politically connected, who gained control of former state facilities during the post-Soviet collapse and then maintained their power with violence and corruption. And once they have money, they try to convert it into holdings in European banks, London real estate, and western corporations. The primary thing I will remember from this book is the degree to which oligarchs rely on being able to move between two systems. They make their money in unstable or authoritarian countries with high degrees of political corruption and violence, and are adept at navigating that world (although sometimes it turns on them; more on that in a moment). But they don't want to leave their money in that world. Someone else could betray them, undermine them, or gain the ear of the local dictator. They rely instead on western countries with strong property rights, stable financial institutions, and vast legal systems devoted to protecting the wealth of people who are already rich. In essence, they play both rule sets against each other: make money through techniques that would be illegal in London, and then move their money to London so that the British government and legal system will protect it against others who are trying to do the same. What they get out of this is obvious. What London gets out of it is another theme of this book: it's a way for a lot of people to share the wealth without doing any of the crimes. Money laundering is a very lossy activity. Lots of money falls out of the cart along the way, where it is happily scooped up by bankers, lawyers, accountants, public relations consultants, and the rest of the vast machinery of theoretically legitimate business. Everyone wins, except the people the money is being stolen from in the first place. (And the planet; Burgis doesn't talk much about the environment, but I found the image of one-way extraction of irreplaceable natural resources haunting and disturbing.) Donald Trump does make an appearance here, although not as significant of one as I was expecting given the prominent appearance of Trump crony Felix Sater. Trump is part of the machinery that allows oligarch money to become legally-protected business investment, but it's also clear from Burgis's telling that he is (at least among the money flows Burgis is focused on) a second-tier player with delusions of grandeur. He's more notable for his political acumen and ability to craft media stories than his money-laundering skills. The story-telling is a third theme of this book. The electorate of the societies into which oligarchs try to move their money aren't fond of crime, mob activity, political corruption, or authoritarian exploitation of workers. If public opinion turns sufficiently strongly against specific oligarchs, the normally friendly mechanisms of law and business regulation may have to take action. The primary defense of laundered money is hiding its origins sufficiently that it's too hard to investigate or explain to a jury, but there are limits to how completely the money can hide given that oligarchs still want to spend it. They need to tell a story about how they are modernizing businessmen, aghast at the lingering poor conditions of their home countries but working earnestly to slowly improve them. And they need to defend those stories against people who might try to draw a clearer link between them and criminal activity. The competing stories between dissident oligarch Mukhtar Ablyazov and the Kazakh government led by Nursultan Nazarbayev are a centerpiece of this book. Ablyazov is in some sense a hero of the story, someone who attempted to expose the corruption of Nazerbayev's government and was jailed by Nazerbayev for corruption in retaliation. But Burgis makes clear the tricky fact that Ablyazov likely is guilty of at least some (and possibly a lot) of the money laundering of which he was accused. It's a great illustration of the perils of simple good or bad labels when trying to understand this world from the outside. All of these men are playing similar games, and all of them are trying to tell stories where they are heroes and their opponents are corrupt thieves. And yet, there is not a moral equivalency. Ablyazov is not a good person, but what Nazerbayev attempted to do to his family is appalling, far worse than anything Ablyazov did, and the stories about Ablyazov that have prevailed to date in British courts are not an attempt to reach the truth. The major complaint that I have about Kleptopia is that this is a highly complex story with a large number of characters, but Burgis doesn't tell it in chronological order. He jumps forward and backward in time to introduce new angles of the story, and I'm not sure that was the right structural choice. Maybe a more linear story would have been even more confusing, but I got lost in the chronology at several points. Be prepared to put in some work as a reader in keeping the timeline straight. I also have to warn that this is not in any way a hopeful book. Burgis introduces Nigel Wilkins and his quixotic quest to expose the money laundering activities of European banks early in the book. In a novel that would set up a happy ending in which Wilkins brings down the edifice, or at least substantial portions of it. We do not live in a novel, sadly. Kleptopia is not purely depressing, but by and large the bad guys win. This is not a history of corruption that we've exposed and overcome. It's a chronicle of a problem that is getting worse, and that the US and British governments are failing to address. Burgis's publishers successfully defended a libel suit in British courts brought by the Eurasian Natural Resources Corporation, the primary corporate entity of the Trio who are the primary villains of this book. I obviously haven't done my own independent research, but after reading this book, including the thorough notes, this looks to me like the type of libel suit that should serve as an advertisement for its target. I can't say I enjoyed reading this, particularly at the end when the arc becomes clear. Understanding how little governments and institutions care about stopping money laundering is not a pleasant experience. But it's an important book, well and vividly told (except for the chronology), and grounded in solid investigative journalism. Recommended; I'm glad I read it. Rating: 7 out of 10

Next.

Previous.