Search Results: "tach"

2 October 2008

Russell Coker: How Many Singularities?

There is a lot of discussion and speculation about The Singularity. The term seems to be defined by Ray Kurzweil’s book “The Singularity Is Near” [1] which focuses on a near-future technological singularity defined by significant increases in medical science (life extension and methods to increase mental capacity) and an accelerating rate of scientific advance. In popular culture the idea that there will only be one singularity seems to be well accepted, so the discussion is based on when it will happen. One of the definitions for a singularity is that it is a set of events that change society in significant ways such that predictions are impossible - based on the concept of the Gravitational Singularity (black hole) [2]. Science fiction abounds with stories about what happens after someone enters a black hole, so the concept of a singularity not being a single event (sic) is not unknown, but it seems to me that based on our knowledge of science no-one considers there to be a black hole with multiple singularities - not even when confusing the event horizon with the singularity. If we consider a singularity to merely consist of a significant technological change (or set of changes) that change society in ways that could not have been predicted (not merely changes that were not predicted) then it seems that there have been several already, here are the ones that seem to be likely candidates: 0) The development of speech was a significant change for our species (and a significant change OF our species). Maybe we should consider that to be singularity 0 as hominids that can’t speak probably can’t be considered human. 1) The adoption of significant tool use and training children in making and using tools (as opposed to just letting them learn by observation) made a significant change to human society. I don’t think that with the knowledge available to bands of humans without tools it would have been possible to imagine that making stone axes and spears would enable them to dominate the environment and immediately become the top of the food chain. In fact as pre-tool hominids were generally not near the top of the food chain they probably would have had difficulty imagining being rulers of the world. I’m sure that it led to an immediate arms race too. 2) The development of agriculture was a significant change to society that seems to have greatly exceeded the expectations that anyone could have had at the time. I’m sure that people started farming as merely a way of ensuring that the next time they migrated to an area there was food available (just sowing seeds along traditional migration routes for a hunter-gatherer existence). They could not have expected that the result would be a significant increase in the ability to support children and a significant increase in the number of people who could be sustained by a given land area, massive population growth, new political structures to deal with greater population density, and then wiping out hunter-gatherer societies in surrounding regions. It seems likely to me that the mental processes needed to predict the actions of a domestic animal (in terms of making it a friend, worker, or docile source of food) differ from those needed to predict the actions of other humans (who’s mental processes are similar) and from those needed to predict the actions of prey that is being hunted (you only need to understand enough to kill it). 3) The invention of writing allowed the creation of larger empires through better administration. All manner of scientific and political development was permitted by writing. 4) The work of Louis Pasteur sparked a significant development in biology which led to much greater medical technology [3]. This permitted much greater population densities (both in cities and in armies) without the the limitation of significant disease problems. It seems that among other things the world-wars depended on developments in preventing disease which were linked to Louis’ work. Large populations densely congregated in urban areas permit larger universities and a better exchange of knowledge which permitted further significant developments in technology. It seems unlikely that a population suffering the health problems that were common in 1850 could have simultaneously supported large-scale industrial warfare and major research projects such as the Manhattan Project. 5) The latest significant change in society has been the development of the Internet and mobile phones. Mobile phones were fairly obvious in concept, but have made structural changes to society. For example I doubt that hand-writing is going to be needed to any great extent in the future [4], the traditional letter has disappeared, and “Dates” are now based on “I’ll call your mobile when I’m in the area” instead of meeting at a precise time - but this is the trivial stuff. Scientific development and education have dramatically increased due to using the Internet and business now moves a lot faster due to mobile phones. It seems that nowadays any young person who doesn’t want to be single and unemployed needs to have either a mobile phone or Internet access - and preferably both. When mobile phones were first released I never expected that almost everyone would feel compelled to have one, and when I first started using the Internet in 1992 I never expected it to have the rich collaborative environment of Wikipedia, blogging, social networking, etc (I didn’t imagine anything much more advanced than file exchange and email). Of these changes the latest (Internet and mobile phones) seems at first glance to be the least significant - but let’s not forget that it’s still an ongoing process. The other changes became standard parts of society long ago. So it seems that we could count as many as six singularities, but it seems that even the most conservative count would have three singularities (tool use, agriculture, and writing). It seems to me that the major factors for a singularity are an increased population density (through couples being able to support more children, through medical technology extending the life expectancy, through greater food supplies permitting more people to live in an area, or through social structures which manage the disputes that arise when there is a great population density) and increased mental abilities (which includes better education and communication). Research into education methods is continuing, so even without genetically modified humans, surgically connecting computers to human brains, or AI we can expect intelligent beings with a significant incremental advance over current humans in the near future. Communications technology is continually being improved, with some significant advances in the user-interfaces. Even if we don’t get surgically attached communications devices giving something similar to “telepathy” (which is not far from current technology), there are possibilities for significant increments in communication ability through 3D video-conferencing, better time management of communication (inappropriate instant communication destroys productivity), and increased communication skills (they really should replace some of the time-filler subjects at high-school with something useful like how to write effective diagrams). It seems to me that going from the current situation of something significantly less than one billion people with current (poor) education and limited communications access (which most people don’t know how to use properly) to six billion people with devices that are more user-friendly and powerful than today’s computers and mobile phones combined with better education as to how to use them has the potential to increase the overall rate of scientific development by more than an order of magnitude. This in itself might comprise a singularity depending on the criteria you use to assess it. Of course that would take at least a generation to implement, a significant advance in medical technology or AI could bring about a singularity much sooner. But I feel safe in predicting that people who expect the world to remain as it is forever will be proven wrong yet again, and I also feel safe in predicting that most of them will still be alive to see it. I believe that we will have a technological singularity (which will be nothing like the “rapture” which was invented by some of the most imaginative interpretations of the bible). I don’t believe that it will be the final singularity unless we happen to make our species extinct (in which case there will most likely be another species to take over the Earth and have it’s own singularities).

1 October 2008

Axel Beckert: NSLU2 in a Tux Case

It started harmless when Thomas asked on Linux User Group Switzerland mailing list if someone knows a tux-shaped alarm clock. But the topic of that thread quickly moved to two other things in tux shape: the Tux Droid, a device similar to the Nabaztag, but needs a Linux host with USB, and ACME Systems’ Tux-Server, a ETRAX CRIS based Foxboard inside a tux-shaped case. We found out that Telion, the Swiss importer for Foxboards, also imports ACME Systems’ Tux Case — although the Tux Case is not mentioned on their website. Even better: They had a few old Tux Cases in stock which don’t fit anymore on current Foxboards since the position of the power socket changed. (So only one hole in the case was missing.) And they wanted to get rid of them quite fast: They offered us the Tux Cases for 10 CHF (6€) each instead of 28 CHF each (17€) if we buy all of them. Of course we couldn’t reject this offer and bought all five remaining cases. Another part of the thread was about performance. Although ETRAX CRIS is used by its inventor AXIS in many of its products (they’re famous for the Linux based web-cams) many were not sure if the board’s performance would be sufficient for their ideas. Another disadvantage of the ETRAX CRIS architecture is that no mainstream Linux distribution supports it. Another point was the Foxboard’s price (169€, ca. 268 CHF). Bones just mentioned that an NSLU2 costs only about 100 CHF (60€). Probably on IRC someone (probably Bones, too) wondered if it’s possible to fit a NSLU2 into such a quite inexpensive Tux Case. We took Wikipedia’s picture of the NSLU2 board, compared the size of the USB ports on that picture, compared them with real-life USB ports and found out the size of the board that way. And when I got my Tux-Case I noticed that the NSLU2 board really could fit into the Tux-Case. Since I’m already building a bigger NAS-like home server, I have no use for another, much slower NAS. But since I more or less gave up the also ARM-based Thecus N4100, another ARM-based machine in my hardware collection wouldn’t be bad. So it didn’t took long and the idea was born to build the NSLU2 board into a Tux-Case and let the website tux.ethz.ch run on it. (I inherited its administration from Beat and it’s currently just a virtual host on one of our webservers.) Then it would be a server named Tux, serving Tuxes, looking like a Tux and running Tux’ operating system Linux. :-) I ordered an NSLU2 at Brack for 117.60 CHF (ca. 70€). Played around with the original firmware for a moment, but it’s horrible from a security point of view: You can’t even change the admin password (default: “admin”) if no USB harddisk is attached. And no, a USB stick doesn’t suffice. So I didn’t wait long and tried to install Debian’s “armel” (ARM, Little Endian) port on it. But the NSLU2 refused the “new firmware” with the error message “Upgrade: no enough free space.”. While this is not in the Debian specific NSLU2 FAQ, it is mentioned in the general troubleshooting FAQ. As described in there, first upgrading to the most recent firmware version and then uploading the Debian installer worked fine. After I had successfully installed Debian Lenny on a pqi 4 GB USB sticked into the NSLU2 and verified that everything is working fine, I opened the NSLU2 case and checked if it really would fit into a Tux Case. It does, but very, very close. You’ll have to drill some holes and the ethernet socket will stick out Tux’s shoulder, but everything else should fit perfectly after a few mounting parts inside the Tux Case have been removed. As a proof of concept I laid the NSLU2 board on the Tux Case’s back:
Pictures taken with my Nokia E51
So later the LEDs will be in Tux’ one shoulder while the network socket will be in his other shoulder. And the USB stick will be inside his paunch via a USB hub.

28 September 2008

Romain Francoise: Emacs: now with built-in daemon

Emacs CVS has an interesting new feature: it now accepts a --daemon command line option which makes it start up as a Unix daemon; it detaches from the controlling terminal, starts up a new process session, goes to the background, starts an Emacs server and just waits for connections. The user can then use emacsclient to create new frames (console or graphical) for the background Emacs, using the new multi-tty abilities of Emacs 23. Since frame creation is virtually instantaneous, this makes the editor start up much faster than in the usual case (and a lot more so if you have an extensive configuration). Also, if your X session goes down, the editor is still running in the background with your buffers and applications, safe from harm. Very neat! (Get it from the usual place if you run Debian.)

(Note: this new --daemon mode is a cleaner replacement for the old screen-based preload-emacs script that was distributed with the multi-tty branch.)

27 September 2008

Christine Spang: finally found a decent DAP

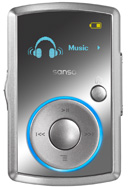
I recently bought a 4GB Sansa Clip to solve the problem where once-a-week or so I want portable music or podcasts and don’t have any: namely, at the gym, occasionally when walking somewhere, and on trains and buses. I’ve been looking for something exactly like this for ages—small, attachable for use during exercise, enough space for a few hours of music/audio, OGG support, and not necessarily much more than that. Basically, an iPod Shuffle that plays OGG and doesn’t involve dealing with Apple. For the longest of time, this was pie-in-the-sky nonexistant. After a few weeks of using the Clip, I’m extremely pleased so far. The battery life is much longer than I’d ever want to listen to music for continuously (they claim 15 hours, and I haven’t gotten it down to less than half charge yet). It’s light in the hand but not too flimsy in feel, the clip makes it easy to attach to e.g. shorts, the interface is easy to use, and the sound quality is good. After upgrading to the latest firmware, it plays OGG as well as MP3. Both Rhymthbox and Banshee work for transferring files to it. I think my biggest complaint so far would be that the audio jack doesn’t fit in as securely as it could, which sometimes manifests as sound skipping and can be fixed by making sure the headphones are completely plugged in. Seriously, it was funny when my Walkman skipped during runs in 2003, but I hope I’m past that phase of life at this point. At any rate, it doesn’t happen all that often, so it’s more of a minor annoyance than anything. And well, the firmware isn’t free—but hey, can’t have everything.

23 September 2008

Zak B. Elep: Broken Comment Posting Fixed; New #olpc-ph Grassroots Group

Thanks to Wolfger for pointing out an HTTP 500 while trying to greet me by comment. :D I totally forgot about upgrading Net::Akismet to the new version that comes with my patch, as described previously. All the while I was thinking Net::Akismet was doing too good of a job keeping out comment spam, when it may as well have kept out all comments :( But its my fault, really. Among other things, Jerome has finally started a new grassroots group for the OLPC effort here in the Philippines, fresh from the success at the recently-concluded SFD. There's now an IRC channel up too, with logs available locally (text-only, until I can set up a web and fileserver frontend.) I'm personally interested on running a port of Inferno and perhaps help out on the TODOs for it.

17 September 2008

Jordi Mallach: Mouth Freedom

Today I got the brackets attached to my lower jaw teeth removed. What I'm experiencing now is something like mouth freedom. I mean, I can even move my tongue around my mouth painlessly!

16 September 2008

Russell Coker: RSS Aggregation Software

The most commonly installed software for aggregating RSS feeds seems to be Planet and Venus (two forks of the same code base). The operation is that a cron job runs the Python program which syndicates a list of RSS feeds and generates a static web page. Of course the problems start if you have many feeds as polling each of them (even the ones that typically get updated at most once a week) can take a while. My experience with adding moderate numbers of feeds (such as all the feeds used by Planet Debian [1]) is that it can take as much as 30 minutes to poll them all - which will be a problem if you want frequent updates. Frequent polling is not always desired, it means more network load and a greater incidence of transient failures. Any error in updating a feed is (in a default configuration) going to result in an error message being displayed by Planet, which in a default configuration will result in cron sending an email to the sysadmin. Even with an RSS feed being checked every four hours (which is what I do for my personal Planet installations) it can still be annoying to get the email when someone’s feed is offline for a day. Now while there is usually no benefit in polling every 15 minutes (the most frequent poll time that is commonly used) there is one good reason for doing it if you can only poll. The fact that some people want to click reload on the Planet web page every 10 minutes to look for new posts is not a good reason (it’s like looking in the fridge every few minutes and hoping that something tasty will appear). The good reason for polling frequently is to allow timely retraction of posts. It’s not uncommon for bloggers to fail to adequately consider the privacy implications of their posts (let’s face it - professional journalists have a written code of ethics about this, formal training, an editorial board, and they still get it wrong on occasion - it’s not easy). So when a mistake is made about what personal data should be published in a blog post it’s best for everyone if the post can be amended quickly. The design of Planet is that when a post disappears from the RSS feed then it also disappears from the Planet web page, I believe that this was deliberately done for the purpose of removing such posts. The correct solution to the problem of amending or removing posts is to use the “Update Services” part of the blog server configuration to have it send an XML RPC to the syndication service. That can give an update rapidly (in a matter of seconds) without any polling. I believe that a cron job is simply the wrong design for a modern RSS syndication service. This is no criticism of Planet (which has been working well for years for many people) but is due to the more recent requirements of more blogs, more frequent posting, and greater importance attached to blogs. I believe that the first requirement for a public syndication service is that every blogger gets to specify the URL of their own feed to save the sysadmin the effort of doing routine URL changes. It should be an option to have the server act on HTTP 301 codes and record the new URL in the database. Then the sysadmin would only have to manage adding new bloggers (approving them after they have created an account through a web-based interface) and removing bloggers. The problem of polling frequency can be mostly solved by using RPC pings to inform the server of new posts if the RPC mechanism supports removing posts. If removing posts is not supported by the RPC then every blog which has an active post would have to be polled frequently. This would reduce the amount of polling considerably, for example there are 319 blogs that are currently syndicated on Planet Debian, there are 60 posts in the feed, and those posts were written by 41 different people. So if the frequent polling to detect article removal was performed for active articles, given the fact that you poll the bloggers feed URL not the article that would only mean 41 polls instead of 319 - reducing the polling by a factor of more than 7! Now even with support for RPC pings there is still a need to poll feeds. One issue is that feeds may experience temporary technical difficulty in sending the RPC as we don’t want to compel the authors of blog software to try and make the ping as reliable a process as sending email (if that was the requirement then a ping via email might be the best solution). The polling frequency could be implemented on a per-blog basis based on the request of the blogger and the blog availability and posting frequency. Someone who’s blog has been down for a day (which is not uncommon when considering a population of 300 bloggers) could have their blog polled on a daily basis. Apart from that the polling frequency could be based on the time since the last post. It seems to be a general pattern that hobby bloggers (who comprise the vast majority of bloggers syndicated in Planet installations) often go for weeks at a time with no posts and then release a series of posts when they feel inspired. In terms of software which meats these requirements, the nearest option seems to be the the Advogato software mod_virgule [2]. Advogato [3] supports managing accounts with attached RSS feeds and also supports ranking blogs for a personalised view. A minor modification of that code to limit who gets to have their blog archived, and fixing it so that a modified post only has the latest version stored (not both versions as Advogato does) would satisfy some of these requirements. One problem is that Advogato’s method of syndicating blogs is to keep an entire copy of each blog (and all revisions). This goes against the demands of many bloggers who demand that Planet installations not keep copies of their content for a long period and not have any permanent archives. Among other things if there are two copies of a blog post then Google might get the wrong idea as to which is the original. Does anyone know of a system which does better than Advogato in meeting these design criteria?

14 September 2008

Neil Williams: oh dear - aspire one mail

Linpus Lite (or maybe just aspire one mail) is only going to last a few more days on this aspire1, it's beginning to annoy me:
Update
sylpheed has now replaced aspire mail. OK, I still use aspire mail for calendar and addressbook stuff (for now), but sylpheed is a much better email client.

  1. aspire one mail has no GnuPG support

  2. aspire one mail has no non-HTML composition support. No, really, it doesn't even send plain text alongside the HTML. email sent from the aspire to myself comes in as an attachment in other email clients! (i.e. spam)


So, I would have to investigate a different email client but then there are niggles with Linpus itself:
  1. the aspire default kernel build lacks the pl2303 kernel module so that I can't use the aspire to control my balloon3 board over usb serial

  2. intermittent problem with network manager forgetting WPA passphrases


Testing continues - probably resulting in installing Lenny at the end of this week. Some of these things might be fixable using pages like taoofmac and Reg Hardware.
Unfortunately, the problem with usbserial means that I'll have to take two laptops if I want to demonstrate the balloon3 board in places.
I also don't seem to be able to locate any copyright files which makes me nervous. Maybe it's just a lack of knowledge of Fedora (at least not since FC5).

11 September 2008

Kai Hendry: Linux computing on your arm

Using 3G I played with a friend’s Atom based EEEPC yesterday. The EEEPC is an amazing achievement considering it’s comparable to the Thinkpad X61, yet it’s a fifth of the price in the UK. I like the idea of carrying an EEEPC as I’m a bit nervous about losing my $$$ Thinkpad when I am out and about. If it just runs a kiosk like browser, with a HSPDA 3G modem, it would be very handy. I wouldn’t sob as much if it got stolen. In other news: I upgraded my beloved slug to lenny which I use as a NAS at home, only to get bitten by a serious NFS permission issue in Debian. Urgh. Update: Thinkpad lovers rejoice. Lenovo has released the EEEPC rival SL300, which seems like half the price of the X61.

10 September 2008

Russell Coker: Efficiency of Cooling Servers

One thing I had wondered was why home air-conditioning systems are more efficient than air-conditioning systems for server rooms. I received some advice on this matter from the manager of a small server room (which houses about 30 racks of very powerful and power hungry servers). The first issue is terminology, the efficiency of a “chiller” is regarded as the number of Watts of heat energy removed divided by the number of Watts of electricity consumed by the chiller. For example when using a 200% efficient air cooling plant, a 100W light bulb is rated as being a 150W heat source. 100W to Heat it, 50W from the cooling plant to cool it. For domestic cooling I believe that 300% is fairly common for modern “split systems” (it’s the specifications for the air-conditioning on my house and the other air-conditioners on display had similar ratings). For high-density server rooms with free air cooling I have been told that a typical efficiency range is between 80% and 110%! So it’s possible to use MORE electricity on cooling than on running the servers! One difficulty in cooling a server room is that the air often can’t flow freely (unlike a big open space such as the lounge room of your house). Another is the range of temperatures and the density of heat production in some parts (a 2RU server can dissipate 1000W of heat in a small space). These factors can be minimised by extracting hot air at the top and/or rear of racks and forcing cold air in the bottom and/or the front and by being very careful when planning where to place equipment. HP offers some services related to designing a server room to increase cooling efficiency, one of the services is using computational fluid dynamics to simulate the air-flow in the server-room [1]! CFD is difficult and expensive (the complete package from HP for a small server room costs more than some new cars), I believe that the fact that it is necessary for correct operation of some server rooms is an indication of the difficulty of the problem. The most effective ways of cooling servers involve tight coupling of chillers and servers. This often means using chilled water or another liquid to extract the heat. Chilled water refrigeration systems largely remove the problem of being unable to extract the heat from the right places, but instead you have some inefficiency in pumping the water and the servers are fixed in place. I have not seen or heard of chilled water being used for 2RU servers (I’m not saying that it doesn’t get used or that it wouldn’t make sense - merely that I haven’t seen it). When installing smaller servers (2RU and below) there is often a desire to move them and attaching a chilled-water cooling system would make such a move more difficult and expensive. When a server weighs a ton or more then you aren’t going to move it in a hurry (big servers have to be mostly disassembled before the shell can be moved, and the shell might require the efforts of four men to move it). Another issue related to water cooling is the weight. Managing a moderate amount of water involves a lot of heavy pipes (a leak would be really bad) and the water itself can weigh a lot. A server room that is based around 20Kg servers might have some issues with the extra weight of water cooling (particularly the older rooms), but a server room designed for a single rack that weighs a ton can probably cope. I have been told that the cooling systems for low density server rooms are typically as efficient as those used for houses, and may even be more efficient. I expect that when designing an air-conditioner the engineering trade-offs when designing for home use favor low purchase price. But someone who approves the purchase of an industrial cooling system will be more concerned about the overall cost of operations and will be prepared to spend some extra money up-front and recover it over the course of a few years. The fact that server rooms run 24*7 also gives more opportunity to recover the money spent on the purchase (my home A-C system runs for about 3 months a year for considerably less than 24 hours a day). So it seems that the way to cool servers efficiently is to have low density server rooms (to the largest extent possible). One step towards this goal would be to have servers nearer the end users. For example having workgroup servers near the workgroup (instead of in the server room). Of course physical security of those servers would be more challenging - but if all the users have regular desktop PCs that can be easily 0wned then having the server for them in the same room probably doesn’t make things any worse. Modern tower servers are more powerful than rack mounted servers that were available a few years ago while also being very quiet. A typical rack-mounted server is not something you would want near your desk, but one of the quiet tower servers works quite well.

8 September 2008

Holger Levsen: We had joy we had fun we had changelogs in the sun

In an hour the online part of this combined embedded+fai meeting in Badajoz in Extremadura, Spain, will sadly be over, but the sadness will hopefully be compensated by good food (yes, the food at the last dinner was great) and more fun! To me it were three intensive days (plus some two half days of intense travelling) which were really productive. This post is a summary of what I did here, to document how useful these meetings are. I'm only one person out of 18, who did some Debian work here, much more stuff was done, most of it I probably didnt even notice, as 14 people where working on embedded stuff, which I mostly ignored... ;-) That said, I think it was still very nice to have this meeting together, a.) because I'm quite interested in embedded stuff and b.) because the embedded crowd is a fun one to hang around with!

Right now I'm quite tired so that I dont fully remember what I have done on the first day :) It included uploading the DebConf7 mpeg videos which will now be used by Miguel Gea to create DVDs from those, so that he gets familar with the toolchain, so that he then can do the DebConf8 DVDs once those videos are (fully) ready. That will still take some time though, but hopefully not too long.

Unlike DebConf8 I also brought my fancy new fonera2 with me, in the hope to give it to someone to work on emdebian support for it. This is quite a longer road, as currently uclibc is not part of Debian, but thats only one step in this puzzle. Much to my joy Per Andersson took the opportunity to play with it and now took it home with him to document how to run Debian on it. I'm looking forward to see progress on this in the future ;-) Update: uclibc support is only needed for running Debian from the 4mb flash it has. But since it also has an usbport one can attach some storage there and run a full Debian system, just like on the nslug, which also has 32mb of RAM.

Unfortunatly I basically forgot about the FSG-3 I also took with me (which was for good reasons, one the second and third day I mostly did FAI work), but then I remembered 90min before the end, which was really too late. Narf. But Riku had a short look at it and told me one thing I didn't knew before: (at least) arm(el) kernels need to have the cpu id set in the kernel and the debian kernels don't have that, as they are build for more than one cpu type, so one has to prepend an arm assembler code instruction before running the kernel... I'm curious to do this soon :-)

But I have more hardware news to tell: C sar G mez Mart n (thanks for organizing this meeting, too!!!1) gave me back my OLPC laptop which I borrowed to him quite some time ago, so he could use it for a talk he gave at a university in Extremadura, so now I finally could give Andres Salomon new debian image for the XO a try. It was really nice to finally see a nice Debian gnome desktop on the device :-)

Today the FAI group, that was Sebastian, Michael, Thomas and me, also took a break to visit the Alcazaba de Badajoz (built around 1100, so roughly 900 years ago) which is an amazing building (thats why I linked to the spanish wikipedia entry as it has nicer pictures), from where you can see most of the city. I've been to Badajoz at least three times now and I'm really glad I finally did that, it's only 5min away from the office where the meeting was held and I highly recommend it to anyone going here.

Oh, and last and definitly not least I did a lot of work on FAI too. Besides discussing stuff which will hit planet after I posted this (hah! Michael already posted it, though without proper credit, so I will do a repost) I mostly reviewed changes and patches and discussed bugs, I didn't develop many patches myself (well, except one for the changelog..) but I've read every change at least twice, once as a commit msg and once in a full review. Plus many patches I read more often... all in all I think FAI is now in an great shape for lenny (which was the only thing we worked on during the weekend, we discussed some future plans, but work was only done for lenny), except that we want to another upload (with only documentation changes) after the upcoming one (which has quite some documentation changes already, but also some RC+important and some trivial bugfixes).

As you might have guessed, I started this entry on saturday and am finishing it now. According to the topic of the #extremadura2008 channel, which we created to coordinate between the groups, we also fixed 7 RC bugs (or 8? one should really document the bug numbers and not the number of bugs..) affecting lenny and 3 more which are only relevant to sid. Which is not as many as I would have liked to be fixed, but then, it wasn't a ("traditional") bug squashing party either. Which makes me wonder, are there any planned in the coming weeks?

So all in all I think this meeting was really very productive. Plus, I also enjoyed a special half an hour of real holidays: on saturday we had to leave lunch without having a chance to have a coffee afterwards, so I stumbled into a random cafe on the way to the venue. Turned out it was a very nice one, where due to its nice interiour I managed to reflect on life, 42 and all the rest almost immediatly. A totally unexpected but needed break. I wont say more here, because the thoughts and memories are really mostly relevant for me, but I'm really happy I found that space. DebConf8 and this meeting both were really fun, but I really didnt have a minute to reflect things. 30 minutes to do that is definitly not enough, but it was a good start. Now I just need to find another opportunity to continue with it. I hope this will happen before the next Extremadura meeting ;-)

3 September 2008

Martin-Éric Racine: another Tux bites the dust

At the dayjob, we've been evaluating various OS options for a customer project. Without going into details, it involves installing embedded software on a ThinCan for a special usage case. The basic needs are simple: graphic environment to run a custom application (OS neutral), plus a few drivers for hardware attached to the ThinCan. That's it. Nothing to excited about. Comparing various team members' proposals to implement the OS base was the real shocker: no matter how optimized the software base and compiler options, no matter which build environment was used (Thin Station, Open Embedded, Gentoo, etc.), we couldn't get a performance that was remotely usable: Then came the proposal from our team's lone Windows guy: XP Embedded. Booted in less than 10 seconds, has a graphical environment that is usable out of the box and integrating the customer's application was a breeze. Heck, the demo is practically a finished product already and took just a couple of hours to assemble! To make matters worse, the total we'd be paying in licensing fees, for all the Windows components we choose, would amount to far less than what it would cost to polish either of the Free Software -based proposals. Before anyone goes and puts on their asbestos suit, I'm already aware that the point of Free Software is to keep people employed and to make the community at large benefit from everyone's code improvements by contributing patches to upstream. Please keep in mind that, in contrast, business requirements are to get results at a reasonable cost, reasonably fast and to produce a well-polished product. The Free Software community has finally conquered the challenges of the desktop and was already on the server ages ago, but we ain't quite there yet on embedded devices, I'm afraid. While I personally refuse to run anything else than Ubuntu on my laptop, let's face it, in the above case, the savings in time=money were obvious and the resulting product quality, even at demo stage, spoke for itself. Thus, another Tux bit the dust.

2 September 2008

David Welton: Babies, Parents and Home Offices - Advice?

I'm back to working at home after completing a recent contract, much faster than the client expected, I'm proud to say, as I was able to leverage some open source software to do exactly what they needed. While I love being able to see Helen and Ilenia more during the day, it also brings up that old question of Adam Smith's: the division of labor. It's pretty difficult to concentrate at all with a baby in the house, despite having an office with a door. When she's noisy, she's really noisy, and there's nothing like the yowl of an unhappy baby to get a parent's attention, even if he's not the one currently taking care of her. Also, perhaps most importantly: she's adorable and full of smiles for me, and loves to play... as do I, certainly more so than working! Since she won't take a bottle yet (well, I did succeed once, but it's not easily repeatable), my wife is still the one Helen's primarily attached to, but even so, needs some time when I take care of the baby so she can do her stuff too. I'm curious what sorts of arrangements other people have worked out? Fortunately, one option would simply be to spend the time with Ilenia and Helen and forget about work for the most part, but that's pretty extreme. It's not as if I don't have computer time, but the biggest problem is the constant interruptions, which make it difficult to do more than read and write a little bit. Serious coding requiring concentration is pretty much only for late at night or early mornings these days.

30 August 2008

Andreas Barth: stale vs incomplete: xen vs kvm

Currently, I'm together with Marc Brockschmidt evaluating which virtualization to use on our new server. We want that our virtual systems feel like real systems, and we want an open source solution. So, vserver and the like is out of the game, as well as VMware. The two remaining solutions we looked at are Xen and kvm. Xen has of course the advantage of the matured. Also, we have experience with running xen servers - and with the issues that can happen, like the chances to disconnect dom0 from xend, and then reboot the server the hard way. However, the most serious disadvantage is that development has practically stalled with the 2.6.18-kernel. Of course, even of today one could install a new server based on Etch, but that doesn't really feel right. There is some development ongoing to run domUs with newer kernels (like in Lenny), but there isn't currently any new kernel available for dom0. kvm is a more recent addition to the virtualization camp, and is basically "qemu on steroids". All looks rather promising, development happens with the recent kernels. However, kvm lacks a few features of e.g. Xen. This includes the ability to reboot dom0 (and the hardware) and just let the domUs survive. Or to have a nice management script where one could just say "xm shutdown $domU", and have basically the power button be pressed on the virtual machine. Or to just attach and detach to the virtual console whenever one wants. Nothing of that is impossible with kvm, one could attach the command-terminal to some pipe, and the linux console to some other, and attach and distach via own scripts. But - all of that should be expected to be available from some solution that calls itself enterprise ready. (And - writing own scripts has always the possibility to make own mistakes.) However, among all the worst possible issue is that kvm is underdocumented (or rather: There are lots of different places where some parts of the documentation is hidden - including the great remark in the man page "The other options are similar to those of qemu."). So, what to do? Invest more time into a solution that seems like a dead end. Or put up with the incompletness of another solution?

29 August 2008

Wouter Verhelst: Debconf8, and the m68k meeting in Kiel

As I start this blog post, I'm on the train between Amersfoort and Osnabr ck, on my way to Kiel, where there'll be a meeting of the m68k porters, kindly organized by m68k kernel maintainer Christian Steigies. I took the 8:40 train in Mechelen this morning, and if all goes well, I'll be arriving in Kiel at 17:22 tonight. Some train trip... but I certainly prefer that to any flight. Anyway. The days of Debconf were very nice. Debconf is a lot of things to me. Travel. Hacking. Mao, evolving into a drinking game. Beer. Attending talks. Giving talks. Meeting people. Face-to-face non-flaming. Gesturing for an extra knife at luunch. Hangover. Whiskey. Talking to the person next to you—over IRC. Getting killed before knowing what the rules of the assassins game are. Filing bugreports in person. Pictures. Kilts. Streaming video. Not being sick, hopefully. Name badges. Flying. Sleeping. Yes, sleeping. Most of all, though, this year, Debconf was just great. Thanks. You know who you are. After debconf, I flew to Buenos Aires, where I slept for one night in a Youth Hostel somewhere downtown. They were affordable, but the bed wasn't great—the mattress sorely needed replacement. Since I had a day in BA, and since there were apparently not enough people on the schedule, I'd agreed to hold a talk, and came up with the idea of a 'debian secrets' talk—about Debian-specific commands, such as dpkg-divert and update-alternatives etc—so that people could learn how to use their Debian system more efficiently. As I was sitting in Andreas' talk, who was right before me on the schedule, suddenly Dag walked up to me and said hi. This was unexpected; Dag is a fellow Belgian, who's involved with the CentOS project, and who maintains a positively huge RPM repository at his site—if you maintain an RPM-based system somewhere, you'll probably know about that site. So while I recognized him, I immediately wondered what he was doing there. Turned out he was invited to hold a talk at the Free Software event to which Debianday was attached (and which would not start for another day or two), and that when he saw my name on the schedule, he decided to attend. Fun. He learned a thing or two from my talk, and was talking later about writing some tools for RPM-based systems that would perform the same or similar functionality implemented by some of the Debian tools I talked about. Great. We had a picture together (in front of the DebConf banner—hah) that I still should upload, and then went out for lunch together with some other CentOS guys. The talk itself seems to have been well-received, and I'm glad about that; I only gave it because there was a need for more talks, not because I felt confident I was very knowledgeable about that subject. In fact, I did have to ask on the debconf-discuss mailinglist for some input (which I received) so that I could make sure the talk would actually be useful to people. That helped a lot, I guess. After that, we played some mao in the lobby of the DebianDay venue. While doing so, I overheard Dag talking about CentOS, advocating it to some of the people there, which I must say felt pretty weird on a Debian event. Not that there's anything wrong with it, of course. Except that Dag was supposed to be writing his talk slides. How did that work out, Dag? ;-) Eventually, I got in a cab to the EZE airport, and flew home. That wasn't fully without issue, but I did get there. And now, I've been, eh, overloaded. Still have to follow up on a question a customer asked me, but I've barely been home or at the office, just enough to sleep really. Should do something about that, I guess... Two days ago, I also managed to forget my camera somewhere. For 12 hours, I was worried, even though I had a pretty good idea of where it was; but since I'm getting quite good at taking pictures now, and since I really like doing so as well, I really didn't want to lose my camera. Fortunately, when I called this morning to the place where I thought I'd lost it, they told me it'd been found, and where to get it. In other words, it's safe, it's taken care of, Philip went to get it, and I just need to arrange to get it when I get back. Which is a relief. Let's not be so stupid anymore in the future... Finishing up now, a day later, and I'm at Christian's office, playing with his and my coldfire board. As it happens, it appears that Freescale has brought out a new BSP for these boards, so that's nice. Let's see whether we can get those to boot again...

27 August 2008

Pablo Lorenzzoni: Paul Graham and his start-up funding company

I first read about Y Combinator while browsing Paul Graham s website. I am a huge fan of his and have tried many times to bring him to Brazil for FISL (unsuccessfully so far). By that time I was updating a lecture of mine where I quote something from his Hackers and Painters essay and sudenly I noted an YC link on the left, and decided to click to learn what was that. Y Combinator is a venture capital firm to help start-ups. It was built on the concept that not much money is needed for first-stage start-ups ( from idea to company , as they call it). Quite a concept! I lost track of it until yesterday, when I read this blog post summarizing one of its events for start-ups. I found it amazing how far it came in such little time. They ve already funded about 100 start-ups, some of them really interesting. Of those presented in that post, Posterous is one I found most interesting. They create instant blogs just by sending emails to some address. There s no sign-up procedure Just send the email with any attachments and voil . There you have: a new blog. Many others are really interesting (PollEveryWhere, IDidWork, Frogmetrics, just to name a few), so I really suggest reading that post. I think Y Combinator is another great idea from Paul Graham, and I will be following it more closely, as a way to keep myself updated Who knows maybe I can get them to come to FISL to present that! ;-)

23 August 2008

Daniel Burrows: Package Management Sudoku 2

I got several emails in reply to my previous post on representing Sudoku problems as package dependencies. Several people asked about the algorithm that aptitude uses to solve these problems. A slightly out-of-date discussion package management and the aptitude algorithm can be found at http://people.debian.org/~dburrows/model.pdf. One question was interesting enough to deserve a follow-up blog post: Wolf T. referred to the page http://norvig.com/sudoku.html and asked how long it would take aptitude aptitude to solve the hard Sudoku problems on that page. He suspected that aptitude would do basic constraint propagation and then be forced to exhaustively search all the possible solutions to the problem. In brief: the answer is that it doesn't work by default, but not for the reason he suggested, and you can make it work with a few command-line arguments. In order to try this out you'll need a new version of the Sudoku reducer that can parse the problems on that Web page: debsudoku2.py. If I do a straight conversion of one of those problems and then run it through aptitude, it goes spinning off and never comes back. But aptitude is coded to avoid exhaustive searches; otherwise it couldn't solve dependency problems in reasonable amounts of time. In this particular situation, though, aptitude is clearly performing an exhaustive search; here's one series of status outputs:
open: 5124; closed: 4993; defer: 0; conflict: 374
Resolving dependencies...
open: 10090; closed: 9942; defer: 0; conflict: 398
Resolving dependencies...
open: 14726; closed: 14888; defer: 0; conflict: 440
Resolving dependencies...
Here open is the number of partial solutions that aptitude wants to examine, and closed is the number that it's already examined. aptitude isn't making progress here and it isn't finding solutions; in fact, it's creating, on average, about two new partial solutions for every one it examines. Why is aptitude doing this? Its resolver isn't a brute-force algorithm; in fact, it looks remarkably like the Sudoku solver discussed at http://norvig.com/sudoku.html. On each step, aptitude takes a partial solution, picks one dependency, and resolves it by installing or removing a package. This is pretty much equivalent to filling in one not-filled-in cell; in fact, in the conflicts Sudoku reduction, it's exactly equivalent. There is one difference, though, and it stems from a difference in the problem domains of Sudoku and package management:
Not all dependency resolutions are created equal.
In Sudoku, any solution to the puzzle will do. Not so in package management; solving a dependency problem by removing every package on the system will produce a formally correct answer and a very unhappy user. Even results that are not utterly disastrous could be annoying to the user, so the resolver needs to somehow aim for good answers. The page on Sudoku solvers suggests sticking to whatever value you placed in a cell, unless that doesn't lead to any solutions at all. This is technically known as a depth-first search. The problem with taking this approach when resolving package dependencies is that an apparently safe choice can end up requiring undesirable actions later on (like removing large swathes of the system). For this reason, aptitude tries to strike a balance between sticking to its current line of reasoning, and abandoning it when it seems to be turning out badly (this makes it a form of best-first search). On typical Debian archives, the package relationships are simple enough that it's OK if aptitude does this from time to time; it makes the search a little more thorough (thus costly), but the ability to back out of questionable branches is very valuable. But it looks like when aptitude is applied to Sudoku puzzles, it has trouble settling on a single series of choices. It keeps thinking that the solutions are getting worse, so it backs up and tries another branch, but they don't look any better over there, so it backs up and tries another branch, and so on. The option Aptitude::ProblemResolver::StepScore sets how hard aptitude will try to stick to the same line of reasoning. Its default value is 70, which is reasonable for package archives, but turning it up to a large value such as 10000 will cause aptitude to use a straight depth-first search, just like the Sudoku page recommends:
$ aptitude -s -o 'aptitude::problemresolver::stepscore=10000' -o 'aptitude::auto-install=false' install puzzle
Setting auto-install to false is a workaround for another odd corner case/bug that happens to bite this Sudoku problem: for technical reasons, doing this lets aptitude know that it should avoid solutions that cancel the installation of puzzle. Otherwise you have to sit there telling it no for a bunch of solutions you aren't interested in. Future versions of aptitude will probably provide a way to explicitly give hints to the resolver. With these options, aptitude was able to solve the hard Sudoku puzzles that I gave it in anywhere from fifteen seconds to a minute and 47 seconds. In contrast, the straight Sudoku solver does 30 problems in a second. Why is aptitude so slow? Based on skimming debug traces and looking at the run-time behavior, I conjecture that there are several reasons:
  1. The aptitude search algorithm is very heavyweight. In the case where it takes over a minute, it only actually examines about 5,000 possible solutions. I don't know exactly where all this time is going, but I do know that the resolver does a lot of work on each step, for instance to try and detect dead ends that it hasn't reached yet. This is the conflicts counter that appears while the resolver is running. This pays off tremendously in terms of allowing aptitude to skip huge amounts of work (it may be why aptitude can solve Sudoku puzzles at all!), but it means that the resolver takes a long time for each potential solution it looks at.
  2. The Sudoku page suggests taking the cell with the fewest number of possible entries as the choice. I distinctly remember writing code to do this in aptitude, but it looks like I threw it out at some point or never committed it. I don't see why it should be any worse than the current approach, though (which is to pick an arbitrary dependency); maybe it just got misplaced at some point. Implementing this behavior decreased the time required to solve one puzzle from a minute and 45 seconds to just under a minute; I've committed this change to the post-lenny branch.
  3. The Sudoku resolver has the advantage of being able to very quickly identify illegal moves. aptitude's resolver can learn this information, but it takes time and it can't apply Sudoku-specific optimizations. For instance, the Sudoku solver knows exactly which values can be placed in a given cell at any time. aptitude has to actually consider each of the cells that's available as a possibility and prove to itself that, e.g., 4 and 6 can't be written in the same cell at the same time. And although it can learn this information, it takes time to do so and it takes time to see whether any of the past conflicts that it remembers are present in a given solution.
As I noted above, I've already checked in one change to the resolver's behavior. It might also be worth seeing what happens with a massive increase in StepScore, so I've pegged it at 10000 on my computer to see whether the results I get are noticeably worse. The third item above -- the fact that aptitude needs to do more work to understand which packages can't be installed -- is interesting. The Sudoku solver is very proactive about this: it keeps track at all times of which cell values are legal, and updates these sets every time it transitions. In contrast, aptitude constantly re-checks all the possible moves it could make to see which ones are currently legal. I think that the resolver's speed could be boosted a little by doing the following:
  1. Cache the currently legal solutions of each dependency at the time it's inserted into the queue.
  2. When a new search node is generated by resolving a dependency, drop the formerly legal moves that are knocked out (for instance, by installing a different version of the same package).
  3. Come up with a quick way of re-testing new conflicts (the global list of dead-ends) so that search nodes that are already in the queue can be checked against the conflicts that were added since they were queued.
These changes won't make aptitude able to solve problems that it couldn't solve before, or at least not very many of them, but they should make the resolver faster on every problem it encounters. However, I don't think I want to actually implement them. It would be tricky to confirm that the resolver got faster on real dependency problems (since it's normally almost instantaneous), the changes would make the resolver code more complex and fragile (less readable, less maintainable), and there's a real chance of breaking something. Unless there are cases where the resolver is currently too slow on real package archives that don't involve an exponential blowup, I'm going to shelve the idea for now.

19 August 2008

Daniel Burrows: Package Management Sudoku

Update: There are more notes on how aptitude performs as a Sudoku solver here. Russell Coker recently wrote a post entitled Ownership of the Local SE Linux Policy. This post has nothing to do with the substance of his post, which is a discussion of how distributions should configure SELinux by default. I know nothing about SELinux, but something that Russell said in passing caught my attention:
I am not aware of the Debian package dependencies (or those of any other distribution) being about to represent that the postfix package depends on selinux-policy-default-postfix if and only if the selinux-policy-default package is installed. Please note that I am not suggesting that we add support for such things, a package management system that can solve Sudoku based on package dependency rules is not something that I think would be useful or worth having.
(emphasis added) As it happens, a little-known fact about the Debian packaging system is that you can, in fact, describe Sudoku puzzles in it! Note for the impatient: If you want to skip all this talk and jump to the code, see debsudoku.py. For those of you who, like me, are not Sudoku-heads, here's a quick summary of the rules (for the common case of a game with 3 blocks):
  1. The game is played by filling in a 9-by-9 grid with numbers between 1 and 9, inclusive. The board is divided into 9 3-by-3 blocks of grid cells in the obvious way.
  2. All the cells in a column must contain different numbers.
  3. All the cells in a row must contain different numbers.
  4. All the cells in a block must contain different numbers.
There are many ways that you could convert a Sudoku problem into a Debian package archive, but here's a particularly simple one that is close to my summary of the rules. Create 9 * 9 * 9 = 729 packages, named cellR.C-V where R stands for row, C for column, and V for value. Each of these packages represents writing the value V in the cell (R, C). To describe the relationships of each cell to the other cells in the problem, we can create several virtual packages: Converting these requirements to package dependencies is quite straightforward. For the package cellR.C-V, in block row BR and block column BC, we add these lines to the package's definition:
Provides: cellR.C, blockBR.BC-V, rowR-V, colC-V
Conflicts: cellR.C, blockBR.BC-V, rowR-V, colC-V
For instance, the cell at (5, 8) will get these provides/conflicts for V=2:
Provides: cell5.8, block2.3-2, row5-2, col8-2
Conflicts: cell5.8, block2.3-2, row5-2, col8-2
This relies on the fact that self-conflicts are ignored (see Debian Policy section 7.4). To actually describe the puzzle we want to solve, we need to add another package that requires two things:
  1. Every cell contains a value.
  2. The cells that the problem fixes have their fixed values.
For instance,
Package: puzzle
Depends: cell1.1, cell1.2, ..., cell5.9-3, cell6.1, ....
if we want to require that the cell at (5, 9) contains the value 3. Proof-of-concept As a proof-of-concept, I have written a hacky Python script, named debsudoku.py, that can convert ksudoku saved games into Packages files suitable for use with apt-get or aptitude. In fact, it has two modes: conflicts, which implements the conversion described above, and depends, which implements a different but logically equivalent conversion using only Depends instead of Conflicts. To use the script, save a ksudoku board without doing any work on it, then run
python debsudoku.py /path/to/the/ksudoku/board
I've only done minimal testing on this, so don't use it to fly airplanes (in fact, please don't use any Sudoku player to fly airplanes), but I did use it, in combination with aptitude, to solve a single ksudoku puzzle. Real-world evaluation Interestingly, in a test with an easy puzzle generated by ksudoku, aptitude was able to solve the puzzle in just a few seconds when it was expressed with the conflicts reduction, but failed to find a solution at all using depends (I stopped it after several minutes). I think this is due to how the depends reduction is performed. Take rows: instead of generating conflicts between cells in a row, it requires that each row contain every number between 1 and 9. The problem with this is that aptitude's resolver functions poorly when there are non-obvious conflicts in the dependency structure. It will decide to try a combination of packages that can't be installed together, but it won't realize it. As a result of this, it ends up trying many possible combinations of packages. For instance, it might try to place the number 3 in both (2, 5) and (5, 5). There is no dependency outlawing this in the depends reduction, so aptitude will happily continue trying to resolve dependencies. Since it has used 3 twice in the fifth column, it will not be able to find any way to resolve all the dependencies that state that all the numbers between 1 and 9 appear in the 5th column, but it lacks the higher-level reasoning that would allow it to break out; it will end up trying many or most of the possible ways of filling cells in before it gives up on the offending re-use of 3. Luckily, real-world package archives (what the aptitude resolver is designed to run on) don't usually look like this.

18 August 2008

loldebian - Can I has a RC bug?: Maximiliano Curia, LOLed by Diegote


Maximiliano Curia, LOLed by Diegote

Maximiliano Curia, LOLed by Diegote

17 August 2008

Obey Arthur Liu: Going to London - Cambridge

I’ll be in Great Britain next week. I’ll come to the Debian Party 2008 in Cambridge on Saturday 23rd August and will be back to London to visit ’till Wednesday 27th August. I’m staying by myself in a nice little hotel in Bloomsbury. It will be very interesting to meet Debian people and probably do some pitching for my Aptitude GTK project which is making nice progress. aptitude-20080817-1 I’ve never been to London before. In fact, I’ve been once when very young and all that I can remember is that the hot dogs seemed nice :). I’m currently reading the Lonely Planet book about London and filling my program. Hi, London!

Next.

Previous.