The eight release of the binb package,
and first in two years, is now on CRAN and in r2u. binb regroups
four rather nice themes for writing LaTeX Beamer
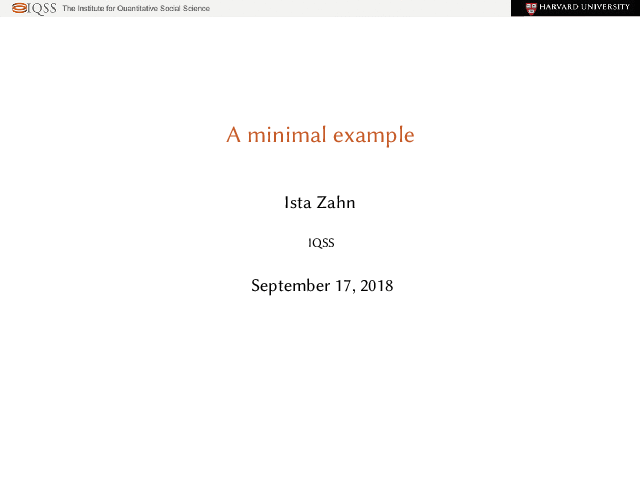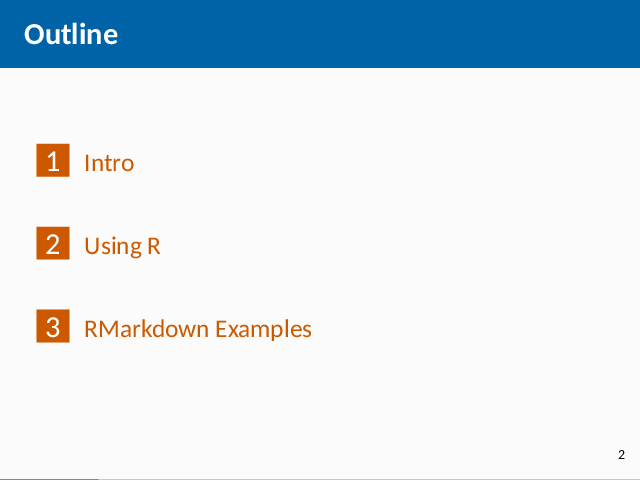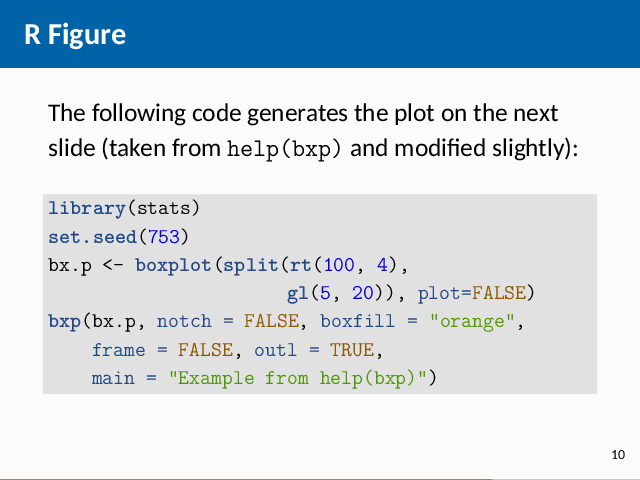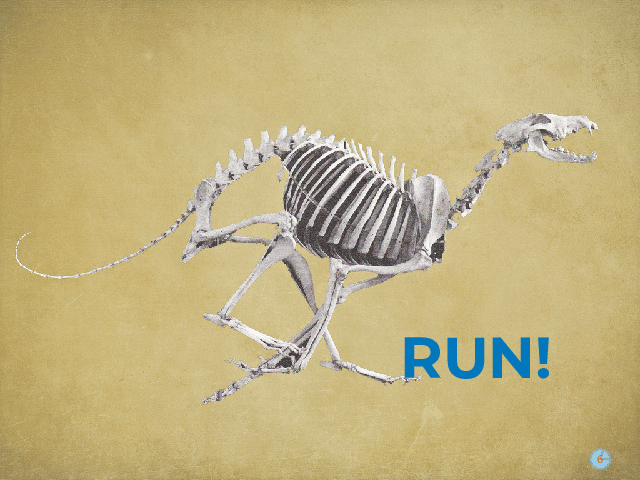
presentations much more easily in (R)Markdown. As a teaser,
a quick demo combining all four themes is
available; documentation and examples are in the package.
This release contains regular internal updates to continuous
integration, URLs reference and switch to Authors@R. The trigger for the
release, though, was a small updated need when very recent
pandoc versions (as shipped with RStudio) are used which
require a new variable declaration in the LaTeX template files in order
to process uncaptioned tables. The summary of changes follows.
Changes in binb
version 0.0.8 (2026-05-01)
Small updates to documentation URLs and continuous
integration
The package now uses Authors@R in DESCRIPTION
Newer pandoc versions are accommodated by adding a required
counter variable in the latex template file
On the 7th of September 2025, my friend Dione and I had a day trip to Vienna the capital of Austria. We were attending a conference in Budapest, Hungary, which is 250 km from Vienna. So, it was a good opportunity to visit Vienna.
We took a morning train from Budapest to Vienna and got back to Budapest by night. However, booking these tickets turned out to be a bit complicated. There were many websites to book the train ticket Hungarian Railways, Austrian Railways, and third-party sites such as Omio. All these websites had different prices for the same ticket.
I booked the tickets from the Hungarian Railways website as it was the cheapest. The train from Budapest to Vienna was 13, operated by Eurocity. Also, I had to pay 2 for the seat reservation on top. The train from Vienna to Budapest operated by Railjet was 21, along with 2 extra for reservation again making it 23. The tickets for the two-way journey added up to 38.
The cost of these tickets varied depending on when one purchses them: the sooner you purchase, the lower the price. I bought my tickets 15 days ahead of the date of journey and paid just 38. In contrast, Dione booked just one day before her trip and paid around 100 for her tickets.
As for the seat reservation, long-distance trains in Europe usually require paying extra for the seat reservation. This ensures that you get your preferred seat, such as a window seat or an aisle seat. Nevertheless, you will get a seat on long-distance trains because they do not sell more tickets than there are seats. Therefore, you will get a seat without reservation as well. However, we reserved our seats so that we can sit together. This helped us more in the return part of the journey from Vienna to Budapest which was more crowded than the train we took from Budapest to Vienna in the morning.
On another note, reservation is mandatory on some trains in Europe, but ours wasn t one of them. In addition, people also use rail passes, so an extra charge is required on top for reserving the seats for pass holders. On the other hand, local trains do not require seat reservations in general.
Our train s scheduled departure was at 08:55 from the Budapest Kelenfold station. We reached the train station 40 minutes before the train s scheduled departure. The Kelenfold station had free Wi-Fi, which was handy because I didn t have a local SIM.
A departures board at Budapest Kelenfold station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
This is platform number 15 of Budapest Kelenfold station where we boarded our train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Our train arrived on time. I tried to find our coach number but could not find the numbers written anywhere on the side of the coach. Luckily, we were helped by a fellow passenger who directed me to look at the doors, where the numbers were mentioned clearly!
Then we got into our compartment and took our respective seats. Our tickets were checked twice - once while the train was in Hungary and the other when in Austria. Showing the PDF of the train ticket on our mobile to the ticket inspector was good enough for the purpose. Austria and Hungary are a part of the open transit Schengen area, which means this was the extent of the border control checks we had to go through.
Interior of our Budapest to Vienna train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The train also had free Wi-Fi, albeit with poor connection at times. There were no eatery options inside the train.
We deboarded at the Wien Hauptbahnhof station in Vienna. The journey was 250 km and took 2.5 hours, reaching Vienna at 11:25, which was the scheduled time.
This blue colored train was the one we took for our Budapest to Vienna journey. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
An BB train standing at a platform of Vienna train station. BB is the national carrier of Austria. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Wien Hauptbahnhof train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
At the station, we bought a 24-hour public transport pass from a ticket machine for 8. The pass includes unlimited access to all the public transport in Vienna for 24 hours. My pass was valid from the 7th of September at 11:34 to the 8th of September at 11:33. A single public transport ticket (from anywhere to anywhere) costs 2.4. A single ticket of 2.4 can be used once on any public transport in Vienna trams, metros, and buses.
Therefore, the pass is a good deal if you are going to take at least four public transport trips in a day. Unlike the public transport pass I got in Budapest, the pass in Vienna was anonymous and not tied to the rider s name.
My public transport pass in Vienna.
We wanted to visit the Sch nbrunn Palace. The palace was reachable by subway. In order to get to the subway station, we started by going outside the station. But it was not outside. So we came back inside the station building and realized that the subway was underground.
We took the subway and deboarded at the Sch nbrunn subway station the closest one to the palace. The ride was smooth; the train was pretty silent.
By the way, like Budapest, there were no AFC gates for boarding the subway in Vienna. The stations had ticket validators instead, where you are supposed to validate your tickets before getting into the subway.
Instead of AFC gates, Vienna has ticket validators as in the picture. You need to tap your ticket in the validator before boarding the subway. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
These validators are in place to ensure that you use your ticket only once. Unlike AFC gates, which are present in metros of most of the countries I have been to, the ticket validators don t act as a physical barrier to enter the boarding area.
If you board the metro without validating your ticket, you will be facing hefty fines upon getting caught. I have heard that the fine is around 100. On the other hand, if you have a public transport pass like we did, then you don t need to validate it before boarding.
In addition, there were no annoying security checks either, unlike in Indian cities. In the Delhi metro, for example, you would need to scan your bags and pass through a security check before getting to the AFC gates.
Vienna subway. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Now back to the story, after alighting at the Sch nbrunn subway station, we walked to the Sch nbrunn Palace. One can roam around outside the palace and click pictures for free. To go inside, however, requires buying tickets. The tickets for the palace can be booked in advance on the internet. We didn t take the tickets in advance, as we decided to visit the palace at the last moment.
So we went to the ticket counter and found out that we needed to wait for 1 hour 40 minutes before going inside if we took the tickets at that moment. In addition, one ticket costs 44 (around 4000 Indian rupees). Since we had to return to Budapest in the evening and only had a few hours in the city, we decided not to go inside the palace. Instead, we clicked a few pictures outside the palace.
Sch nbrunn Palace. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The Sch nbrunn Palace is a UNESCO World Heritage Site and is a historically significant place. It servedas one of the residences of the powerful Habsburg dynasty. The palace looked so good that my friend Dione said, It seemed like the palace was built yesterday . This remark applied to other parts of Vienna we went to. For example, the subway stations also seemed like they were built yesterday.
A street near Sch nbrunn Palace. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Now, we wanted to go someplace to grab a bite. I asked my friend Urbec for suggestions on where to go. They suggested we visit the steps named Strudlhofstiege, which had the added benefit of being in a neighborhood with good bakeries and buildings.
So, we took the subway and deboarded at the Ro auer L nde station, followed by walking around a kilometer to reach the stairs.
Ro auer L nde subway station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Platform of the Ro auer L nde subway station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
The The Strudlhofstiege steps. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
On the way, we were also looking for a place to eat. Unfortunately, it was Sunday, and Vienna closes on Sunday. That means most of the shops including bakeries and caf s are closed. Only places like railway stations have shops open on Sundays.
By the way, walking around in the streets of Vienna was a treat. The streets were not crowded (as it was not exactly a touristy neighborhood) and had good pedestrian infrastructure, with clean streets and separate cycling tracks. The buildings were also beautiful.
A random street in Vienna.
Another street in Vienna.
After some walking, we found a restaurant open. I grabbed the menu to check the prices. A lady at the shop asked me what I was doing, and I told her that I was browsing the menu. She said that the menu was in German. I don t know how she knew that we didn t know German, but it seemed like a racist thing to be told.
We roamed around further and found a caf by the name of Blue Orange, where we ordered coffee and croissants. When we got our order, the waiter told us that they were having some issues, so they wouldn t charge us for the croissant if it wasn t good.
A picture of Blue Orange caf . Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
My friend and I took a bite, and both of us didn t like the croissant. After some time, the waiter came to us and asked whether the croissant was okay, to which we said no. Therefore, they didn t charge us for the croissant. This was the first time something like this happened to me. It felt like I was in a different world. I added a small tip at the end for this gesture, which I had to put in a jar at the counter.
The cappuccino I ordered was 4.50, while the espresso that Dione ordered was 3.60. The croissant would have been 3.60. I remember Paris having cheaper croissants!
Then when the waiter brought our drinks out, they automatically gave me the espresso and Dione the cappuccino. Dione found this funny because there is a stereotype in her country (Australia) that men drink strong black coffee, and women drink milky drinks like cappuccinos. She found it interesting that this stereotype seems to exist in Austrian culture too.
We hopped on a tram to reach the nearest subway station and went to the Wien Hauptbahnhof station to have something before we caught our return train to Budapest.
Trams in Vienna. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
At the station, I had Esterhazyschnitten and Punschkrapfen (thanks, Urbec, for the suggestion). The lady at the shop warned me that punschkrapfen had alcohol in it, to which I said okay.
Esterhazyschnitten was a cake made of almonds, while punschkrapfen was a jam-filled sponge cake, soaked in rum. Esterhazyschnitten was my favorite out of the two. The punschkrapfen was too sweet for my taste.
Punschkrapfen. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Esterhazyschnitten. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
While the station was well-built, there were a couple of things about the Wien Hauptbahnhof station that we didn t like. There were no seats inside the station, so we had to eat outside the building. Also, the toilets needed to be paid for. It costs 50 cents to use the toilets at this station.
The Vienna train station had departure boards all over the place. So, we went to the platform our train was to arrive on.
Departure boards in Vienna displaying information about the trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
Platform and tracks at Wien Hauptbahnhof station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
When our train arrived, we had some difficulty locating our compartment. This train was operated by a different company (Railjet) than the one we took in the morning (Eurocity) from Budapest to Vienna, and we were able to locate the coach numbers using the digital board at the station. Each compartment had a digital board next to it on the station displaying the coach number. However, that wasn t the problem. Even after reading the coach numbers and trying to find ours, it didn t appear where we expected in the sequence.
When we were not able to find our coach for a while, we asked a ticket inspector of the train who was standing on the platform. He directed us towards the front side of the train. So we started running to the front side as we didn t know how long the train stops.
As we ran toward our coach, we found out that the engine of the back train was connected with the last compartment of the train at the front. At that point, we realized that the train was a combination of two trains. At a later station, the train on the back side parted ways and went towards Vienna Airport.
Interior of the train we took from Vienna to Budapest. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
This is the train we took for our return journey from Vienna to Budapest. It is standing on a platform in Budapest Kelenfold station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
We had a smooth journey and reached Budapest a couple of hours later.
Vienna is a beautiful city; we enjoyed being there, and we would like to visit the city again!
That s it for now. Signing off. See you in the next one!
Credits: Thanks to Dione and Badri for proofreading.
What We Are Seeking is a bit hard to classify beyond science
fiction. I think I would call it anthropological science fiction, but it's
also a first contact story and a planetary colony story. It is a
standalone novel (well, so far as I know; see later in the review for
caveats). This is Cameron Reed's second novel after the excellent and
memorable cyberpunk novel The Fortunate
Fall, first published in 1996 under Reed's former name of Raphael
Carter.
John Maraintha is a doctor from the world of Essius. He took what he
thought was a temporary job on the Free Ship Edgar's Folly, where
he's endured considerable culture shock. As the novel opens, John learns
that the colonists on Scythia have requested a translator to talk to one
of the native life forms, and a doctor since they're down to only one.
John will be that doctor. The captain has decided, and by the rules of the
free ships, John does not get a choice in the matter.
The Scythian colony is about four hundred people, now located in a desert
climate since the complex native life forms destroyed their previous
settlement. The colonists are a split between Ischnurans and Zandaheans,
two other human civilizations from the scatter of colony worlds left after
Earth embraced AIs (aiyis here) and turned inward. Both of those groups
marry, something John considers a moral abomination. Neither of them seem
likely to understand Essian sexual ethics. More devastatingly, John had
intended to spend some time as a ship doctor and then return home to a new
place in Essian society. Once he lands on Scythia, the chances of that are
gone; it is highly unlikely any ship would pick him up again and take him
home.
I have been trying to find the right books to compare What We Are
Seeking with ever since I read it. The best I've come up with are Ursula
K. Le Guin (particularly The
Dispossessed), Eleanor Arnason's A Woman
of the Iron People, and Becky Chambers's To Be Taught, If Fortunate. The start of the book felt like an
intentional revisiting of an earlier era of science fiction, with somewhat
updated science and politics, but the last half of the book, where the
action picks up considerably, is a meditation on gender, social systems,
religion, and small-group politics. All of that is mixed with biological
exploration and a first-contact story with some quite-alien aliens.
This is the sort of novel where the protagonist's culture is as foreign to
the reader as any of the other cultures he counters, so the reader is
assembling several jigsaw puzzles at once. John is dropped into an
established colony with its own social norms and established hierarchies.
The one other outsider, the translator Sudharma Jain, is, as his name
implies, a Jain who keeps very strict religious observances. Half of the
colony is from something akin to a fundamentalist Christian religious sect
that practices patriarchy and strict marriage codes. The other half is
more gently sexist (but still sexist) and has its own tradition of a third
gender that becomes central to the story. John, meanwhile, is a strong
believer in the Essian approach to social organization: Any two partners
of any gender freely have sex by mutual consent and without obligation,
and family is based solely on blood relations. These beliefs do not fit
comfortably together, even when people are trying (as they mostly do) to
be welcoming.
The first half of this book is very slow. This gives all of the characters
space to breathe and become comfortable, and the characterization is
superb, but it is a book to start when you're in the mood for something
slow and observational. There is a plot that gradually becomes apparent,
or rather there are several plots that are intertwined, but tension and
urgency are mostly reserved for the second half of the book. Instead, the
book opens with a lot of close observation of alien flora and fauna and
the untangling of subtle social dynamics among the Scythians.
There is also a visitor from earth, much to the distress of the Scythians.
Earth presence means the ships will not return and the colony may be cut
off from any sort of technological resupply. Despite speaking a common
language, that visitor is as mutually alien to the other groups as they
are to the native flora. Her life is fully integrated with aiyis, giving
her essentially godlike powers and the ability to turn off inconvenient
emotions and disregard anything she doesn't want to see. What she and the
Earth aiyis are doing on the planet is one of the early mysteries.
The dialogue in this book is truly excellent. Each characters has their
own voice, there are fascinating digressions on different words that lead
to tidbits of world-building, and some of the culture-specific idioms are
delightful.
"I'm making a mess of this. None of that matters. Let me fall out the
window and come in the door again. This is how my story ought to
start:"
The challenges for the characters in this story are slow but deep ones:
belonging and self-definition, the conflict between cultural tradition and
personal circumstance, and the sacrifices required to live with small
groups in situations where civil war is viscerally attractive. It has one
of the most comprehensive and fascinating treatments of transgender issues
that I've read in science fiction. Its commentary on current politics is
subtle and estranged in the way that science fiction does best, but still
pointed and satisfying. And, well, there are passages like this that I
absolutely adore:
"I wouldn't go that far. It could be they are right, the universe we
see exists because a mind like ours created it at least, a mind
enough like ours that we can say it wants one thing and not another,
and when it acts it does so with intent. That's as good an idea as
any. But it is certainly not plausible that such a being believes that
people everywhere should marry, or that men should never visit men, or
no one should become a jess. Look at what they have created. The
universe could have been nothing at all, or one atom of hydrogen
floating in a void, or a diamond crystal infinite in all directions,
if their mind cared for simplicity or tidiness. Instead we have stars
and planets and black holes and nebulas. It could have all been cold
and dead, but there is life. They could have made one species for each
world, or just a few, which could have stayed the same forever, but
instead we have millions and millions, all of which are changing every
moment, varying among themselves and boiling off in all directions.
Such a god is like an artist who fills up a library of sketchbooks
with their drawings of strange creatures, and when every scrap of
paper in the place is used up, goes back with a different color ink
and scribbles over them again. They are obsessed with variation they
gorge themselves with it and never grow full. Do you really think a
mind like that could want us all to live in the same way?"
I had one problem with this book, though, and for me it was a big one:
There is no ending. Reed effectively builds tension, gets me caring about
all of the characters, sets up several problems, starts down a path
towards resolution, and then the book just... ends.
Long-time readers of my reviews will know that I'm a denouement fanatic. I
want the scouring of the shire, I want the chapter set in the happily ever
after, I want the catharsis of an ending. This made me so grumpy!
To be clear, this is not sequel bait (at least so far as I can tell). I
can write a philosophical defense of the ending. The types of problems and
lives that Reed set up don't have clear endings; this is, to some extent,
the point. We muddle through, and then those who come after us muddle
through some more, and the cumulative effect is called human civilization.
And there is some denouement; Reed doesn't leave the reader at a
cliffhanger or anything that egregious.
But still, I wanted the happy ending, even though that was unrealistic for
the style of story this is, because I'm a happy ending reader. This is not
an ending sort of book; it's the sort of book where I get a sinking
feeling at the 95% mark because there aren't enough pages left for the
number of remaining unresolved problems. I've gotten less annoyed in the
days since I finished the book, and I can appreciate the thematic point
made by how the book ends, but I still feel like it's worth an advance
warning if you're a reader like I am.
I would be delighted by a sequel, but it didn't feel like that was the
intent.
Apart from that, this was both excellent and rather unlike a lot of
current science fiction. I think the closest comparison I can make among
recent novels I've read is Sue Burke's Semiosis. What We Are Seeking has a similar sort of
world-building, but I liked these characters so much more. It felt like a
classic literary science fiction novel, but very much written in 2026.
Highly recommended, just beware of the lack of closure.
Content notes: Sexism, homophobia, stomach illness, and some religious
abuse.
Rating: 8 out of 10
A new maintenance release 0.4.27 of RProtoBuf
arrived on CRAN today. RProtoBuf
provides R with bindings for the
Google Protocol Buffers
( ProtoBuf ) data encoding and serialization library used and
released by Google, and deployed very widely in numerous projects as a
language and operating-system agnostic protocol. The new release is also
already as a binary via r2u.
This release adjusts to a change upstream. Luca Billi noticed that upstream
removed some fields from FieldDescriptor, filed and issue
and followed up with a spotless PR. No other changes.
The following section from the NEWS.Rd file has all details and
links.
Changes in
RProtoBuf version 0.4.27 (2026-04-26)
Adjust to FieldDescriptor API changes in ProtoBuf 3.4
(Luca Billi in #114
fixing #113)
The SpacemiT K1 is a rather
interesting RISC-V SoC, found for instance on boards like the Banana Pi
BPI-F3 board. It's one
of those platforms that looked promising on paper, but took a bit of time
before things really started to move upstream. Things have clearly accelerated
over the last few months.
Linux 7.0 brings, among other things PCIe support, making the board quite
capable as a development board. SD card,
CPU thermal sensor
and cpufreq
support are already in the pipe.
Unfortunately the situation is less advanced on the firmware side. There is
only very basic support
for the SpacemiT K1 in U-Boot for the second stage,
and initial SPL support has been
posted on the
mailing list, but has not yet been merged. In practice, this means you still
have to rely on the vendor U-Boot,
which is based on the rather old 2022.10 release.
On the other hand, OpenSBI
does have upstream support for the SpacemiT K1, however it is not compatible
with the vendor U-Boot, mostly due to device tree differences.
This can be addressed by applying a few patches to the vendor U-Boot, which I have
published in a git tree in the
k1-bl-v2.2.y-opensbi branch (technically this can also be handled on the
OpenSBI side, but I prefer using a vanilla upstream OpenSBI version). The first
two patches update the configuration to get closer to the upstream U-Boot
defaults, and to enable some configuration options for the Milk-V Jupiter board,
which stores its firmware in SPI NOR flash, instead of eMMC for the Banana Pi
BPI-F3. The following patches update the device tree by adding extra compatible
entries to several devices, as expected by the upstream kernel and OpenSBI
(thanks to Troy Mitchell for the hint about the UART change) and update the CPU
riscv,isa properties. Finally an additional patch adds the
SpacemiT P1 PMIC to the device
tree, which is required for the OpenSBI reboot patchset I recently
posted
(this is currently done only for the Banana Pi BPI-F3 and Milk-V Jupiter boards, but
extending it to other boards should be straightforward).
Building this U-Boot version is as simple as running this command in the source directory:
makek1_defconfig&&make
On a Banana Pi BPI-F3 board, the resulting U-Boot can be flashed with:
Building upstream OpenSBI is also fairly simple, and can be done by running this command in the source directory:
makePLATFORM=generic
On a Banana Pi BPI-F3 board, the resulting OpenSBI can be flashed with:
ddif=fw_dynamic.itbof=/dev/mmcblk0p2
Note that the vendor U-Boot version is patched to install OpenSBI in a separate
partition instead of embedding, as the upstream U-Boot does. While this works
well on the Banana Pi BPI-F3, the corresponding partition in the Milk-V Jupiter
SPI NOR flash is too small for the upstream OpenSBI version, and can't be
easily resized without breaking compatibility. To address this, the branch
k1-bl-v2.2.y-opensbi-embedded contains an additional patch (a bit hackish I
admit) to somehow restore the upstream approach. The build process remains
simple, first build OpenSBI with the following command:
makePLATFORM=generic
Then build U-Boot, specifying the patch to the just built OpenSBI firmware:
This combined U-Boot/OpenSBI can also be used on a Banana Pi BPI-F3, using the
same flashing procedure as above, while skipping the OpenSBI part (although
running it won't cause any issue, it will simply be unused).
All of this is admittedly a bit hackish, but enabling the use of upstream
OpenSBI is already one step forward. Hopefully, in a few months, we will be
able to rely entirely on upstream U-Boot.
Leonardo and I are happy to
announce another maintenance release 0.1.4 of our dtts package
which has been on CRAN for four
years now. dtts builds upon
our nanotime
package as well as the beloved data.table to bring
high-performance and high-resolution indexing at the
nanosecond level to data frames. dtts aims to
offers the time-series indexing versatility of xts (and zoo) to the immense
power of data.table while
supporting highest nanosecond resolution.
This release, not unlike yesterday s
release of nanotime, is driven by recent changes in the bit64 package which
underlies it. Michael,
who now maintains it, had sent in two PRs to prepare for these changes.
I updated continuous integration, and switched to Authors@R, and that
pretty much is the release. The short list of changes follows.
Changes in version 0.1.4
(2026-04-23)
Continuous integration has received some routine updates
Adapt align() column names with changes in
'data.table' (Michael Chirico in #20)
Narrow imports to functions used for packages 'bit64',
'data.table' and 'nanotime' (Michael Chirico in #21)
Courtesy of my CRANberries, there
is also a [diffstat repor]tbsdiffstat
for this release. Questions, comments, issue tickets can be brought to
the GitHub repo.
Over the past few weeks I ve been developing and using a personal command-line
tool called gwt (Git Worktree) to manage Git repositories using worktrees.
This article explains what the tool does, how it evolved, and how I used
GitHub Copilot CLI to develop it (in
fact the idea of building the script was also to test the tool).
The Problem: Managing Multiple BranchesI was working on a project with multiple active branches, including orphans; the
regular branches are for fixes or features, while the orphans are used to keep
copies of remote documents or store processed versions of those documents.
The project also uses a special orphan branch that contains the scripts and the
CI/CD configuration to store and process the external documents (it is on a
separate branch to avoid mixing its operation with the main project code).
The plan is trigger a pipeline against the special branch from remote projects
to create or update the doc branch for it in our git repository, retrieving
artifacts from the remote projects to get the files and put them on an orphan
branch (initially I added new commits after each update, but I changed the
system to use force pushes and keep only one commit, as the history is not
really needed).
The original documents have to be changed, so, after ingesting them, we run a
script that modifies them and adds or updates another branch with the processed
version; the contents of that branch are used by the main branch build process
(there we use git fetch and git archive to retrieve its contents).
When working on the scripts to manage the orphan branches I discovered the
worktree feature of git, a
functionality that allows me to keep multiple branches checked out in parallel
using a single .git folder, removing the need to use git switch and git
stash when changing between branches (until now I ve been a heavy user of those
commands).
Reading about it I found that a lot of people use worktrees with the help of a
wrapper script to simplify the management. After looking at one or two posts
and the related scripts I decided to create my own using a specific directory
structure to simplify things.
That s how I started to work on the gwt script; as I also wanted to test
copilot I decided to build it using its help (I have a pro license at work and
wanted to play with the cli version instead of integrated into an editor, as I
didn t want to learn a lot of new keyboard shortcuts).
The gwt Philosophy: Opinionated and Transparentgwt enforces a simple, filesystem-visible model:
Exactly one bare repository named bare.git (treated as an implementation
detail)
One worktree directory per branch where the directory name matches the
branch name
Single responsibility: gwt doesn t try to be a general git wrapper; it
only handles operations that map cleanly to this layout
The repository structure looks like this:
my-repo/
+-- bare.git/           # the Git repository (internal)
+-- main/               # worktree for branch "main"
+-- feature/api/        # worktree for branch "feature/api"
+-- fix/docs/           # worktree for branch "fix/docs"
+-- orphan-history/     # worktree for the "orphan-history" branch
The tool follows five core design principles:
Explicit over clever: Git commands are not hidden or reinterpreted
Transparent execution: Every operation is printed before it happens
Safe, preview-first operations: Destructive commands default to preview,
confirmation, then apply
Shell-agnostic core: The script never changes the caller s working
directory (shell wrappers handle that)
Opinionated but minimal: Only commands that fit the layout model are
included
Core CommandsThe script provides these essential commands:
gwt init <url> Clone a repository and set up the gwt layout
gwt convert <dir> Convert an existing Git checkout to the gwt layout
gwt add [--orphan] <branch> [<base>] Create a new worktree (optionally
orphaned)
gwt remove <branch> Remove a worktree and unregister it (asks the user to
remove the local branch too, useful when removing already merged branches)
gwt rename <old> <new> Rename a branch AND its worktree directory
gwt list List all worktrees
gwt default [<branch>] Get or set the default branch
gwt current Print the current worktree or branch name
Except init and convert all of the commands work inside a directory
structure that follows the gwt layout, which looks for the bare.git folder to
find the root folder of the structure.
As I don t want to hide which commands are really used by the wrapper, all git
and filesystem operations pass through a single run shell function that prints
each command before executing it. This gives complete visibility into what the
tool is doing.
Also, destructive operations (remove, rename) default to preview mode:
The user sees exactly what will happen, can verify it s correct, and only then
confirm execution.
Incremental Development with CopilotThe gwt script has grown from 597 lines in its original version (git-wt) to
1,111 lines when writing the first draft of this post.
This growth happened through incremental, test-driven development, with each
feature being refined based on real usage patterns.
What follows is a little history of the script evolution written with the help
of git log.
Initial versionFirst I wrote a design document and asked copilot to create the initial
version of the git-wt script with the original core commands.
I started to use the tool with a remote repostory (I made copies of the branches
in some cases to avoid missing work) and fixed bugs (trivial ones with neovim,
larger ones asking copilot to fix the issues for me, so I had less typing to
do).
First command updateOne of the first commands I had to enhance was rename:
as I normally use branches with / on their name and my tool checks out the
worktrees using the branch name as the path inside the gwt root folder
(i.e. a fix/rename branch creates the fix directory and checks the branch
inside the fix/rename folder) the rename command had to clean up the empty
parent directories
when renaming a worktree we move the folders and fix the references using the
worktree repair command to make things work locally, but the rename also
affects the remote branch reference, to avoid surprises the command unsets the
remote branch reference so it can be pushed again using the new name (of
course, the user is responsible of managing the old remote branch, as the
gwt can t guess what it should do with it).
Integration with the shellAs I use zsh with the Powerlevel10k
theme I asked copilot to help me add visual elements to the prompt when
working with gwt folders, something that I would have never tried without
help, as it would have required a lot of digging on my part on how to do it, as
I never looked into it.
The initial version of the code was on an independent file that I sourced from
my .zshrc file and it prints on the right part of the prompt
when we are inside a gwt folder (note that if the folder is a worktree we see
the existing git integration text right before it, so we have the previous
behavior and we see that it is a gwt friendly repo) and if we are on the root
folder or the bare.git folder we see gwt or bare
(I added the text because there are no git promts on those folders).
I also asked copilot to create zsh autocompletion functions (I only use
zsh, so I didn t add autocompletion for other shells). The good thing here is
that I wouldn t have done that manually, as it would have required some reading
to get it right, but the output of copilot worked and I can update things
using it or manually if I need to.
One thing I was missing from the script was the possibility of changing the
working directory easily, so I wrote a gwt wrapper function for zsh that
intercepts commands that require shell cooperation (changing the working
directory) and delegates everything else to the core script.
Currently the function supports the following enhanced commands:
cd [<branch>]: change into a worktree or the default one if missing
convert <dir>: convert a checkout, then cd into the initial worktree
add [--orphan] <branch> [<base>]: create a worktree, then cd into it on success
rename <old> <new>: rename a worktree, then cd into it if we were inside it
Note that the cd command will not work on other shells or if the user does not
load my wrapper, but the rest will still work without the working directory
changes.
Renaming the commandAs I felt that git-wt was a long name I renamed the tool to gwt, I could
have done it by hand, but using copilot I didn t have to review all files by
myself and it did it right (note that I have it configured to always ask me
before doing changes, as it sometimes tries to do something I don t want and I
like to check its changes as I have the files in git repos, I manually add
the files when I like the status and if the cli output is not clear I allow it
to apply it and check the effects with git diff so I can validate or revert
what was done).
The convert commandAfter playing with one repo I added the convert subcommand for migrating
existing checkouts, it seemed a simple task at first, but it took multiple
iterations to get it right, as I found multiple issues while testing (in fact I
did copies of the existing checkouts to be able to re-test each update, as some
of the iterations broke them).
The version of the function when this post was first edited had the following
comment explaining what it does:
# ---------------------------------------------------------------------------
# convert - convert an existing checkout into the gwt layout
# ---------------------------------------------------------------------------
#
# Must be run from the parent directory of <dir>.
#
# Steps:
#   1. Read branch from the checkout's HEAD
#   2. Rename <dir> to <dir>.wt.tmp (sibling, same filesystem)
#   3. Create <dir>/ as the new gwt root
#   4. Move <dir>.wt.tmp/.git to <dir>/bare.git; set core.bare = true
#   5. Fix fetch refspec (bare clone default maps refs directly, no remotes/)
#   6. Add a --no-checkout worktree so git wires up the metadata and
#      creates <dir>/<branch>/.git (the only file in that dir)
#   7. Move that .git file into the real working tree (<dir>.wt.tmp)
#   8. Remove the now-empty placeholder directory
#   9. Move the real working tree into place as <dir>/<branch>
#  10. Reset the index to HEAD so git status is clean
#      (--no-checkout leaves the index empty)
#  11. Create <dir>/.git -> bare.git symlink so plain git commands work
#      from the root without --git-dir
#
# The .git file ends up at the same absolute path git recorded in step 5,
# so no worktree repair is needed. Working tree files are never modified.
The .git link was added when I noticed that I could run commands that don t
need the checked out files on the root of the gwt structure, which is handy
sometimes (i.e. a git fetch or a git log, that shows the log of the branch
marked as default).
After playing with commands that used the bare.git folder I updated the init
and convert commands to keep the origin refs, ensuring that the remote
tracking works correctly.
Improving the add commandWhile playing with the tool on more repos I noticed that I also had to enhance
the add command to better handle worktree creation, depending on my needs.
Right now the tool supports the following use cases:
if the branch exists locally or on origin, it just checks it out.
if the branch does not exist, we create it using the given base branch or,
if no base is given, the current worktree (if we are in the root folder or
bare.git the command fails).
as I needed it for my project, I added a --orphan option to be able to
create orphan branches directly.
Moving to a single fileEventually I decided to make the tool self contained; I removed the design
document (I moved the content to comments on the top of the script and details
to comments on each function definition) and added a pair of commands to print
the code to source for the p10k and zsh integration (autocompletion &
functions), leaving everything in a single file.
Now my .zshrc file adds the following to source both things:
# After loading the p10k configuration
if type gwt >/dev/null 2>&1; then
  source <(gwt p10k)
fi
[...]
# After loading autocompletion
if type gwt >/dev/null 2>&1; then
  source <(gwt zsh)
fi
VersioningAs I modified the script I found interesting to use CalVer-based versioning (the
version variable has the format YYYY.mm.dd-r#) so I added a subcommand to show
its value or bump it using the current date and computing the right revision
number.
About the use of copilotAlthough I ve never been a fan of AI tools I have to admit that the copilot
CLI has been very useful for building the tool:
Rapid prototyping: Each commit represented a small feature or fix that I
could implement, test immediately in my actual workflow, and iterate on based
on the result
Edge case handling: Rather than trying to anticipate every scenario
upfront, I could ask Copilot how to handle edge cases as they appeared in real
usage
Script refinement: Questions like "how do I clean up empty directories
after a rename" or "how do I detect if I m inside a specific worktree" were
quickly answered with working code
Shell integration: The Zsh wrapper and completion system grew from simple
prototypes to sophisticated features, with each iteration informed by how I
actually used the tool
For example, the convert command started as a simple rename operation, but
evolved to also create a .git symlink and intelligently handle various
migration scenarios all because I used it repeatedly and refined the
implementation each time.
Self-Contained and Opinionatedgwt is deliberately opinionated:
Zsh & Powerlevel10k Integration: The tool includes built-in Zsh shell
integration, accessed via source <(gwt zsh) and supports adding a prompt
segment when using p10k, as described earlier.
Directory Structure: The bare.git directory name is non-negotiable. This
is how gwt discovers the repository root from any subdirectory, and how the
tool knows whether a directory is a gwt repository. The simplicity of this
marker means the discovery mechanism is foolproof and requires no
configuration.
No Configuration Files: gwt deliberately has no configuration. There are
no .gwtrc files or config directories. This makes it portable; the tool
works the same way everywhere, and repositories can be shared across systems
without synchronizing configuration.
From Script to SystemWhat started as a small helper script for managing worktrees has become a
complete system:
Core script (gwt): 1,111 lines of pure shell, no external dependencies
Shell integration: Zsh functions and completions
Prompt integration: Powerlevel10k segment
Documentation: Built-in help and design philosophy documentation
The script is self-contained, everything needed for the tool to work is in a
single file.
This makes it trivial to update (just replace the script) or audit
(no hidden dependencies).
Development with AI supportDeveloping gwt with copilot taught me some things:
Incremental refinement works well for small tools: Each iteration informed
the next, resulting in a tool that handles real use cases elegantly
Transparency is a feature: Making operations visible builds confidence and
is easier to debug
Opinionated tools can be powerful: By constraining the problem space (one
bare repo, one worktree per branch), the solution becomes simpler and more
robust
Shell integration matters: The same core commands are easier to use when
they can automatically change directories and provide completions
Real-world testing is essential: I wouldn t have discovered the need for
automatic directory cleanup or context-aware cd behavior without actually
using the tool daily
What was next?The tool is stable and handles my daily workflow well, so my guess is that I
would keep using it and fixing issues if or when I found them, but I do not plan
to include additional features unless I find a use case that justifies it (i.e.
I never added support for some of the worktree subcommands, as it is easier to
use the git versions if I ever needed them).
What really happenedWhile editing this post I discovered that I needed to add another command to it
and fixed a bug (see below).
With those changes and the inclusion of a license and copyright notice (just in
case I distribute it at some point) now the script is 1,217 lines long instead
of the 1,111 it had when I started to write this entry.
Submodule SupportWhen I converted this blog repository to the gwt format and tried to preview
the post using docker compose, it failed because the worktree I was on didn t
have the Git submodule initialized.
My blog theme is included on the repository as a submodule, and when I used
gwt to check out different branches in worktrees, the submodule was not
initialized in the new worktrees.
This led me to add new internal function and a gwt submodule command to
handle submodule initialization; the internal function is called from convert
and add (when converting a repo or adding a worktree) and the public command
is useful to update the submodules on existing branches.
Path Handling with Branch Names Containing SlashesThe second discovery was a bug in how the tool handled branch names containing
slashes (e.g., feature/new-api, docs/user-guide), the worktree directories
are created with the branch name as the path, so a branch like feature/new-api
would create two nested folders (feature and new-api inside it).
However, there was a mismatch in how the zsh wrapper function resolved
worktree paths (initially it used shell parameter expansion, i.e.
rel="$ cwd#"$REPO_ROOT"/ "), versus how the core script calculated them,
causing the cd command to fail or navigate to the wrong location when branch
names contained slashes.
The fix involved ensuring consistent path resolution throughout the script and
wrapper (now it uses a function that processes the git worktree list output),
so that gwt cd feature/new-api correctly navigates to the worktree directory
regardless of path depth.
Conclusiongwt is a tool that solves a real problem: managing multiple Git branches
simultaneously without context-switching overhead.
I m sure I m going to keep using it for my projects, as it simplifies some
workflows, although I ll also use switch and stash in some cases, but I like
the use of multiple worktrees in parallel.
In fact I converted this blog repository checkout to the gwt format to work on
a separate branch as it felt the right approach even if I m the only one using
the repo now, and it helped me improve the tool, as explained before.
Also, it was a good example of how to use AI tools like copilot to develop a
simple tool and keep it evolving while using it.
In any case, although I find the copilot useful and has saved me time, I don t
trust it to work without supervision, it worked well, but got stuck some times
and didn t do the things as I wanted in multiple occasions.
I also have an additional problem now I ve been reading about it, but I
don t really know which models to use or how the premium requests are computed
(I ve only been playing with it since last month and I ran out of requests the
last day of the month on purpose, just to see what happened it stops working
;).
On my work machine I ve been using a specific user account with a GitHub
Copilot Business subscription and I only used the Anthropic Claude Sonnet 4.6
model and with my personal account I configured the Anthropic Claude Haiku 4.5
model, but I ve only used that to create the initial draft of this post (I ended
up rewriting most of it manually anyway) and to review the final version (I m
not a native speaker and it was useful for finding typos and improving the style
in some parts).
I guess I ll try other models with copilot in the future and check other
command line tools like aider or
claude-code, but probably only using
free accounts unless I get a payed account at work, as I have with GitHub
Copilot.
To be fair, what I will love to be able to do is to use local models (aider can
do it), but the machines I have are not powerful enough. I tried to run a simple
test and it felt really slow, but when I have the time or the need I ll try
again, just in case.
Another minor update 0.3.14 for our nanotime
package is now on CRAN, and has
compiled for r2u (and
will have to wait to be uploaded to Debian until dependency bit64 has been
updated there). nanotime
relies on the RcppCCTZ
package (as well as the RcppDate
package for additional C++ operations) and offers efficient high(er)
resolution time parsing and formatting up to nanosecond resolution,
using the bit64
package for the actual integer64 arithmetic. Initially
implemented using the S3 system, it has benefitted greatly from a
rigorous refactoring by Leonardo who not only rejigged
nanotime internals in S4 but also added new S4 types for
periods, intervals and durations.
This release has been driven almost entirely by Michael, who took over as
bit64 maintainer
and has been making changes there that have an effect on us
downstream . He reached out with a number of PRs which (following
occassional refinement and smoothing) have all been integrated. There
are no user-facing changes, or behavioural changes or enhancements, in
this release.
The NEWS snippet below has the fuller details.
Changes in version 0.3.14
(2026-04-22)
Tests were refactored to use NA_integer64_ (Michael
Chirico in #149 and
Dirk in #156)
nanoduration was updated for changes in nanotime 4.8.0 (Michael Chirico in #152 fixing
#151)
Use of as.integer64(keep.names=TRUE) has been
refactored (Michael Chirico in #154 fixing
#153)
In tests, nanotime is attached after
bit64; this still needs a better fix (Michael
Chirico in #155)
The package now has a hard dependency on the just released bit64 version 4.8.0 (or later)
Vertical rhythm aligns lines to a consistent spacing cadence down the page. It
creates a predictable flow for the eye to follow. Thanks to the rlh CSS unit,
vertical rhythm is now easier to implement for text.1 But illustrations
and tables can disrupt the layout. The amateur typographer in me wants to follow
Bringhurst s wisdom:
Headings, subheads, block quotations, footnotes, illustrations, captions and
other intrusions into the text create syncopations and variations against the
base rhythm of regularly leaded lines. These variations can and should add
life to the page, but the main text should also return after each variation
precisely on beat and in phase.
Robert Bringhurst, The Elements of Typographic Style
Text
Three factors govern vertical rhythm: font size, line height and
margin or padding. Let s set our baseline with an 18-pixel font and a 1.5
line height:
CSS Values and Units Module Level 4 defines the rlh unit, equal to the
computed line height of the root element. All browsers support it since
2023.2 Use it to insert vertical spaces or to fix the line height
when altering font size:3
We can check the result by overlaying a grid4 on the content:
Using CSS rlh unit to set vertical space works well for text. You can display the grid using Ctrl+Shift+G.
If a child element uses a font with taller intrinsic metrics, it may stretch
the line s box beyond the configured line height.5 A workaround
is to reduce the line height to 1. The glyphs overflow but don t push the line
taller.
code,kbdline-height:1;
Responsive images
Responsive images are difficult to align on the grid because we don t know their
height. CSS Rhythmic Sizing Module Level 1 introduces the block-step
property to adjust the height of an element to a multiple of a step unit. But
most browsers don t support it yet.
With JavaScript, we can add padding around the image so it does not disturb
the vertical rhythm:
The image is snapped to the grid thanks to the additional padding computed with JavaScript. 216 is divisible by 27, our line height in this example.
As the image is responsive, its height can change. We need to wrap a resize
observer around the adjust() function:
Tables
Table cells could set 1rlh as their height but they would feel constricted.
Using 2rlh wastes too much space. Instead, we use incremental leading: we
align one in every five lines.
To align the elements after the table, we need to add some padding. We can
either reuse the JavaScript code from images or use a few lines of CSS that
count the regular rows and compute the missing vertical padding:
A header cell has twice the padding of a regular cell. With two regular rows,
the total padding is 2 2 0.2+2 0.4=1.6. We need to add 0.4rlh to reach
2rlh of extra vertical padding across the table.
One line out of five is aligned to the grid. Additional padding is added after the table to not break the vertical rhythm. 405 is divisible by 27, our line height in this example.
None of this is necessary. But once you start looking, you can t unsee it. Until
browsers implement CSS Rhythmic Sizing, a
bit of CSS wizardry and a touch of JavaScript is enough to pull it off. The main
text now returns after each intrusion precisely on beat and in phase.
For broader compatibility, you can replace 2rlh with
calc(var(--line-height) * 2rem) and set the --line-height custom
property in the :root pseudo-class. I wrote a simple PostCSS
plugin for this purpose.
It would have been nicer to compute the line height with
calc(round(up, calc(2.4rem / 1rlh), 0) * 1rlh). Unfortunately, typed
arithmetic is not supported by Firefox yet. Moreover, browsers support
round() only since 2024. Instead, I coded a PostCSS
plugin for this as well.
The following CSS code defines a grid tracking the line height:
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1263 other packages on CRAN, downloaded 45.7 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 683 times according
to Google Scholar.
This versions updates to the 15.2.5 and 15.2.6 upstream Armadillo releases from,
respectively, two and five days ago. The package has already been
updated for Debian, and built for
r2u. When we ran the
reverse-dependency check for 15.2.5 at the end of last week, one package
failed. I got in touch with the authors, filed an issue, poked some
more, isolated the one line that caused an example to fail and right
then 15.2.6 came out fixing just that. It was after all an upstream
issue. We used to ran these checks before Conrad made a release, he now
skips this and hence needed a quick follow-up release. It can
happen.
The other big change is that this R package release phases out the
dual support for both C++14 or newer (as in current Armadillo) along with a C++11
fallback for more slowly updating packages. I am happy to say that after
over eight months of this managed transition (during which CRAN expulsed some laggard
packages that were not moving in from C++11) we are now at all packages
using C++14 or newer which is nice. And I will take this as an
opportunity to stress that one can in fact manage a disruptive API
change this way as we just demonstrated. Sadly, R Core does not seem to
have gotten that message and rollout of this package was also still a
little delayed because of the commotion created by the last minute API
changes preceding the R 4.6.0 release later this week.
Smaller changes in the package are a switch in pdf vignette
production to the Rcpp::asis() driver, and a
higher-precision computation in rmultinom() (matching a
change made in R-devel during last week in its use of Kahan summation).
All detailed changes since the last CRAN release follow.
Changes in
RcppArmadillo version 15.2.6-1 (2026-04-20)
Upgraded to Armadillo release 15.2.6 (Medium Roast Deluxe)
Ensure internally computed tolerances are not NaN
The rmultinom deploys 'Kahan summation' as R-devel
does now.
Changes
in RcppArmadillo version 15.2.5-1 [github-only] (2026-04-18)
Upgraded to Armadillo release 15.2.5 (Medium Roast Deluxe)
Fix for handling NaN elements in .is_zero()
Fix for handling NaN in tolerance and conformance checks
Faster handling of diagonal views and submatrices with one
row>
Sunset the C++11 fallback of including Armadillo 14.6.3 (#504
closing #503)
The vignettes have refreshed bibliographies, and are now built
using the Rcpp::asis vignette builder (#506)
One rmultinom test is skipped under R-devel which
has switched to a higher precisions calc
I recently released version 0.3.0 of my recipe manager application Kookbook find it in git in KDE Invent or as released tarballs in https://download.kde.org/stable/kookbook/
Changes since last time is more or less Minor bugfixes and a Qt6 port nothing as such noteworthy unless you aim to get rid of Qt5 on your system.
so what is kookbook?
It is a simple recipe viewer that works with semi-structured markdown. More details can be seen in the quite old 0.1.0 announcement
At some point I should do a 10 recipe example collection, but my personal collection is in danish, so I m not sure it is going to be useful. Unless someone will donate me some handfuls of pre-formatted recipes, I will happily announce it.
Collision Course is the sixth novel in the Class 5 science fiction
series and the first that doesn't use the Dark X naming convention.
There are lots of spoilers in this story for the earlier books, but you
don't have to remember all the details of previous events. Like the
novella, Dark Ambitions, this novel
returns to Rose, Sazo, and Dav instead of introducing another Earth woman
and Class 5 ship.
In Dark Class, Ellie discovered an
interesting artifact of a previously-unknown space-faring civilization.
Rose, Sazo, and Dav are on their way to make first contact when, during a
routine shuttle flight between the Class 5 and Dav's Grih military ship,
Rose is abducted. The aliens they came to contact have an aggressive,
leverage-based negotiating strategy. They're also in the middle of a
complicated war with more sides than are readily apparent.
What I liked most about Dark Horse, the
first book of this series and our introduction to Rose, was the revealed
ethical system and a tense plot that hinged primarily on establishing
mutual trust when there were excellent reasons for the characters to not
trust each other. As the series has continued, I think the plots have
become more complicated but the ethical dilemmas and revealing moments of
culture shock have become less common. That is certainly true of
Collision Course; this is science fiction as thriller, with a
complex factional conflict, a lot of events, more plot reversals than the
earlier books, but also less ethics and philosophy.
I'm not sure if this is a complaint. I kind of miss the ethics and
philosophy, but Diener also hasn't had much new to say for the past few
books. The plot of Collision Course is quite satisfyingly twisty
for a popcorn-style science fiction series. I was kept guessing about the
merits of some of the factions quite late into the book, although
admittedly I was in the mood for light entertainment and was not trying
too hard to figure out where the book was going. I did read nearly the
entire book in one sitting and stayed up until 2am to finish it, which is
a solid indication that something Diener was doing worked.
I do have quibbles, though. One is that the ending is a bit unsatisfying.
Like Sazo, I was getting quite annoyed at the people capturing (and
recapturing) Rose and would have enjoyed somewhat more decisive
consequences. Also, and here I have to be vague to avoid spoilers, I was
expecting a bit more of a redemption arc for one of the players in the
multi-sided conflict. The ending I did get was believable but rather sad,
and I wish Diener had either chosen a different outcome (this is light
happily-ever-after science fiction, after all) or wrestled more directly
with the implications. There were a bit too many "wait, one more thing"
ending reversals and not quite enough emotional payoff for me.
The other quibble is that Collision Course was a bit too damsel in
distress for this series. Rose is pregnant, which Diener uses throughout
the book as a way to raise the stakes of the plot and also make Rose more
annoyed but also less capable than she was in her earlier novel. Both Sazo
and Dav are in full heroic rescue mode, and while Diener still ensures
Rose is primarily responsible for her own fate, there is some "military
men attempt to protect the vulnerable woman" here. One of the things I
like about this series is that it does not use that plot, so while the
balance between Rose rescuing herself and other people rescuing her is
still tilted towards Rose, I would have liked this book more if Rose were
in firmer control of events.
I will mostly ignore the fact that a human and a Grih sexually reproducing
makes little to no biological sense, since Star Trek did similar
things routinely and it's an established genre trope. But I admit that it
still annoys me a bit that the alien hunk is essentially human except that
he's obsessed with Rose's singing and has pointy ears. Diener cares about
Rose's pregnancy a lot more than I did, which added to my mild grumpiness
at how often it came up.
Overall, this was fine. I prefer a bit more of a protagonist discovering
how powerful she is by making ingenious use of the ethical dilemmas her
captors have trapped themselves in, and a bit less of Rose untangling a
complicated political situation by getting abducted by every player
serially, but it still kept the pages turning. Any book that is
sufficiently engrossing for me to read straight through is working at some
level. Collision Course was highly readable, undemanding, and
distracting, which is what I was looking for when I read it. I would put
it about middle of pack in the series. If Rose's pregnancy is more
interesting to you than it was to me, that might push it a bit higher.
If you have gotten this far in the series, you will probably enjoy this,
although it does feel like Diener is running out of new things to say
about this universe. That's unfortunate given the number of threads about
AI sentience and rights that could still be followed, but I think tracing
them properly would require more philosophical meat than Diener intends
for these books. Which is why the next book I grabbed was a Culture novel.
Currently this is the final book in the Class 5 series, but there is no
inherent reason why Diener couldn't write more of them.
Rating: 7 out of 10
A while ago, CommBank started asking for MFA confirmation on its mobile app for every NetBank login on a browser. Previously, there was an option to use SMS for MFA, which isn t as secure as I would like, but it was at least usable. Since I m switching away from Android to Mobian and won t be able to use the CommBank app for much longer, I applied for a physical NetCode token.
The hardware is made by Digipass and looks disposable. It is a small, battery powered gadget with a screen and a button. When pressed, it shows a temporary NetCode for authentication. Such a NetCode is required both for NetBank logins and approving online transactions.
The letter that came with it has the wrong link for activation, the correct link is under NetBank -> Settings -> NetCode (under the Security section)
To apply for a physical token, call the NetBank team, mention you can t use the app and need a physical NetCode token, and make sure they actually submit your request for a token. It took me 2 calls to get them to ship me a token. The hardware is free of charge but can only be applied for via phone call; unfortunately staff members at my local branch are unable to do anything in relation to NetBank. I was told privately by a CommBank employee that they are deprecating the hardware token in favor of the mobile app, I hope that won t happen anytime soon, or that they add support for passkeys before they do. The last time I checked, the CommBank app was LineageOS-friendly, but I don t want to configure WayDroid just to do online banking.
PayID, the thing that allows you to receive payment via a phone number or email address, is not compatible with the hardware token, and existing PayID will be silently deactivated if you use hardware token. This looks to be an artificial restriction; I don t see why it has to be this way.
Regular CommBank mobile app sessions will also be de-activated once the hardware token is activated (I was told so but my sessions weren t deactivated until I wiped my Android phone), and you won t be able to sign into mobile app again until you manually disable the NetCode token.
Online banking has been getting progressively more invasive and anti-user over the last decade, from demanding remote attestation to requiring real time location data, each time locking certain features when those demands are not satisfied; all based on the flawed assumptions that everyone owns a phone running a certain flavor of iOS or Android, and has it ready all the time. I m not sure what can be done to reverse this trend, but on the personal level I will use NetBank less and go back to cash.
It s true processing data from software defined radios can be a bit
complex
which tends to keep all but the most grizzled experts and bravest
souls from playing with it. While I wouldn t describe myself as either, I will
say that I ve stuck with it for longer than most would have expected of me.
One of the biggest takeaways I have from my adventures with software defined
radio is that there s a lot of cool crossover opportunity between RF and
nearly every other field of engineering.
Fairly early on, I decided on a very light metadata scheme to track SDR
captures, called rfcap. rfcap has withstood my test
of time, and I can go back to even my earliest captures and still make sense of
what they are IQ format, capture frequencies, sample rates, etc. A huge
part of this was the simplicity of the scheme (fixed-lengh header, byte-aligned
to supported capture formats), which made it roughly as easy to work with as a
raw file of IQ samples.
However, rfcap has a number of downsides. It s only a single, fixed-length
header. If the frequency of operation changed during the capture, that change
is not represented in the capture information. It s not possible to easily
represent mulit-channel coherent IQ streams, and additional metadata is
condemned to adjacent text files.
ARF (Archive of RF)
A few years ago, I needed to finally solve some of these shortcomings and tried
to see if a new format would stick. I sat down and wrote out my design goals
before I started figuring out what it looked like.
First, whatever I come up with must be capable of being streamed and processed
while being streamed. This includes streaming across the network or merely
written to disk as it s being created. No post-processing required. This is
mostly an artifact of how I ve built all my tools and how I intereact with my
SDRs. I use them extensively over the network (both locally, as well
as remotely by friends across my widerlan). This decision sometimes even
prompts me to do some crazy things from time
to time.
I need actual, real support for multiple IQ channels from my multi-channel SDRs
(Ettus, Kerberos/Kracken SDR, etc) for playing with things like
beamforming.
My new format must be capable of storing
multiple streams in a single capture file, rather than a pile of files in
a directory (and hope they re aligned).
Finally, metadata must be capable of being stored in-band. The initial set of
metadata I needed to formalize in-stream were Frequency Changes and
Discontinuities. Since then, ARF has grown a few more.
After getting all that down, I opted to start at what I thought the simplest
container would look like,
TLV
(tag-length-value) encoded packets. This is a fairly well trodden path,
and used by a bunch of existing protocols
weallknow
and
love.
Each ARF file (or stream) was a set of
encoded packets (sometimes called data units in other specs). This means that
unknown packet types may be skipped (since the length is included) and
additional data can be added after the existing fields without breaking
existing decoders.
Heads up!
Once this is posted, I'm not super likely to update this page. Once this
goes out, the latest stable copy of the ARF spec is maintained at
draft-tagliamonte-arf-00.txt.
This page may quickly become out of date, so if you're actually interested in
implementing this, I've put a lot of effort into making the draft
comprehensive, and I plan to maintain it as I edit the format.
Unlike a traditional TLV structure, I opted to add flags to the top-level
packet. This gives me a bit of wiggle room down the line, and gives me a
feature that I like from ASN.1 a critical bit. The critical bit indicates
that the packet must be understood fully by implementers, which allows future
backward incompatible changes by marking a new packet type as critical. This
would only really be done if something meaningfully changed the interpretation
of the backwards compatible data to follow.
Flag
Description
0x01
Critical (tag must be understood)
Within each Packet is a tag field. This tag indicates how the contents of the
value field should be interpreted.
In order to help with checking the basic parsing and encoding of this format,
the following is an example packet which should parse without error.
 00, // tag (0; no subpacket is 0 yet)
 00, // flags (0; no flags)
 00, 00 // length (0; no data)
 // data would go here, but there is none
Additionally, throughout the rest of the subpackets, there are a few unique and
shared datatypes. I document them all more clearly in the draft, but to quickly
run through them here too:
UUID
This field represents a globally unique idenfifer, as defined by RFC 9562, as
16 raw bytes.
Frequency
Data encoded in a Frequency field is stored as microhz (1 Hz is stored as
1000000, 2 Hz is stored as 2000000) as an unsigned 64 bit integer. This has a
minimum value of 0 Hz, and a maximum value of 18446744073709551615 uHz, or just
above 18.4 THz. This is a bit of a tradeoff, but it s a set of issues that I
would gladly contend with rather than deal with the related issues with storing
frequency data as a floating point value downstream. Not a huge factor, but as
an aside, this is also how my current generation SDR processing code (sparky)
stores Frequency data internally, which makes conversion between the two
natural.
IQ samples
ARF supports IQ samples in a number of different formats. Part of the idea here
is I want it to be easy for capturing programs to encode ARF for a specific
radio without mandating a single iq format representation. For IQ types with
a scalar value which takes more than a single byte, this is always paired
with a Byte Order field, to indicate if the IQ scalar values are little or
big endian.
ID
Name
Description
0x01
f32
interleaved 32 bit floating point scalar values
0x02
i8
interleaved 8 bit signed integer scalar values
0x03
i16
interleaved 16 bit signed integer scalar values
0x04
u8
interleaved 8 bit unsigned integer scalar values
0x05
f64
interleaved 64 bit floating point scalar values
0x06
f16
interleaved 16 bit floating point scalar values
Header
Each ARF file must start with a specific Header packet. The header contains
information about the ARF stream writ large to follow. Header packets are
always marked as critical .
magic
flags
start
guid
site guid
#st
In order to help with checking the basic parsing and encoding of this format,
the following is an example header subpacket (when encoded or decoded this
will be found inside an ARF packet as described above) which should parse
without error, with known values.
Stream Header
Immediately after the arf Header, some number of Stream Headers
follow. There must be exactly the same number of Stream Header packets as are
indicated by the num streams field of the Header. This has the nice effect of
enabling clients to read all the stream headers without requiring buffering of
unread packets from the stream.
id
flags
fmt
bo
rate
freq
guid
site
In order to help with checking the basic parsing and encoding of this format,
the following is an example stream header subpacket (when encoded or decoded
this will be found inside an ARF packet as described above) which should parse
without error, with known values.
Samples
Block of IQ samples in the format indicated by this stream s format and
byte_order field sent in the related Stream Header.
id
iq samples
In order to help with checking the basic parsing and encoding of this format,
the following is an samples subpacket (when encoded or decoded
this will be found inside an ARF packet as described above). The IQ values
here are notional (and are either 2 8 bit samples, or 1 16 bit sample,
depending on what the related Stream Header was).
01, // id
ab, cd, ab, cd, // iq samples
Frequency Change
The center frequency of the IQ stream has changed since the
Stream Header or last Frequency Change
has been sent. This is useful to capture IQ streams that are jumping
around in frequency during the duration of the capture, rather than
starting and stopping them.
id
frequency
In order to help with checking the basic parsing and encoding of this format,
the following is a frequency change subpacket (when encoded or decoded
this will be found inside an ARF packet as described above).
01, // id
00, 00, b5, e6, 20, f4, 80, 00 // frequency (200 MHz)
Discontinuity
Since the last Samples packet for this stream, samples have been dropped
or not encoded to this stream. This can be used for a stream that has
dropped samples for some reason, a large gap (radio was needed for something
else), or communicating iq snippits .
id
In order to help with checking the basic parsing and encoding of this format,
the following is a discontinuity subpacket (when encoded or decoded this will
be found inside an ARF packet as described above).
01, // id
Location
Up-to-date location as of this moment of the IQ stream, usually from a GPS.
This allows for in-band geospatial information to be marked in the IQ stream.
This can be used for all sorts of things (detected IQ packet snippits aligned
with a time and location or a survey of rf noise in an area)
The sys field indicates the Geodetic system to be used for the provided
latitude, longitude and elevation fields. The full list of supported
geodetic systems is currently just WGS84, but in case something meaningfully
changes in the future, it d be nice to migrate forward.
Unfortunately, being a bit of a coward here, the accuracy field is a bit of a
cop-out. I d really rather it be what we see out of kinematic state estimation
tools like a kalman filter, or at minimum, some sort of ellipsoid. This is
neither of those - it s a perfect sphere of error where we pick the largest
error in any direction and use that. Truthfully, I can t be bothered to model
this accurately, and I don t want to contort myself into half-assing something
I know I will half-ass just because I know better.
In order to help with checking the basic parsing and encoding of this format,
the following is a location subpacket (when encoded or decoded this will be
found inside an ARF packet as described above).
Vendor Extension
In addition to the fields I put in the spec, I expect that I may need custom
packet types I can t think of now. There s all sorts of useful data that could
be encoded into the stream, so I d rather there be an officially sanctioned
mechanism that allows future work on the spec without constraining myself.
Just an example, I ve used a custom subpacket to create test vectors, the data
is encoded into a Vendor Extension, followed by the IQ for the modulated
packet. If the demodulated data and in-band original data don t match, we ve
regressed. You could imagine in-band speech-to-text, antenna rotator azimuth
information, or demodulated digital sideband data (like FM HDR data) too. Or
even things I can t even think of!
id
data
In order to help with checking the basic parsing and encoding of this format,
the following is a vendor extension subpacket (when encoded or decoded this
will be found inside an ARF packet as described above).
Tradeoffs
The biggest tradeoff that I m not entirely happy with is limiting the length
of a packet to u16 65535 bytes. Given the u8 sample header, this limits us
to 8191 32 bit sample pairs at a time. I wound up believing that the overhead in
terms of additional packet framing is worth it because always encoding 4
byte lengths felt like overkill, and a dynamic length scheme ballooned
codepaths in the decoder that I was trying to keep as easy to change as
possible as I worked with the format.
The nineteenth release of the qlcal package
arrivied at CRAN just now, and
has already been built for r2u. This version
synchronises with QuantLib 1.42
released this week.
qlcal
delivers the calendaring parts of QuantLib. It is provided (for the R
package) as a set of included files, so the package is self-contained
and does not depend on an external QuantLib library (which can be
demanding to build). qlcal covers
over sixty country / market calendars and can compute holiday lists, its
complement (i.e. business day lists) and much more. Examples
are in the README at the repository, the package page,
and course at the CRAN package
page.
This releases updates to the 2025 holidays for China, Singapore, and
Taiwan.
The full details from NEWS.Rd follow.
Changes in version 0.1.1
(2026-04-15)
Synchronized with QuantLib 1.42 released two days ago
Calendar updates for China, Singapore, Taiwan
Courtesy of my CRANberries, there
is a diffstat report for this
release. See the project page
and package documentation for more details, and more examples.
Debusine projects in Google s Summer of Code
While Freexian initiated Debusine, and is investing a lot of resources in the
project, we manage it as a true free software project that can and should have a
broader community.
We always had documentation for new contributors
and we aim to be reactive with them when they interact via the issue tracker or
via merge requests. We decided to put those intentions under stress tests by
proposing five projects
for Google s Summer of Code as part of Debian s participation in that program.
Given that at least 11 candidates managed to get their merge request accepted in
the last 30 days (interacting with the development team is part of the
pre-requisites to apply to Google Summer of Code projects these days), the
contributing experience must not be too bad. If you want to try it out, we
maintain a list of quick fixes
that are accessible to newcomers. And as always, we welcome your
feedback!
Debian CI: incus backend and upgrade to Bootstrap 5, by Antonio Terceiro
debci 3.14 was released on March 4th, with a followup 3.14.1 release with
regression fixes a few days afterwards. Those releases were followed by new
development and maintenance work that will provide extra capabilities and
stability to the platform.
This month saw the initial version of an incus backend
land in Debian CI. The transition into the new backend will be done carefully so
as to not disrupt testing migration. Each package will be running jobs with
both the current lxc backend and with incus. Packages that have the same result
on both backends will be migrated over, and packages that exhibit different
results will be investigated further, resulting in bug reports and/or other
communication with the maintainers.
On the frontend side, the code has been ported to Bootstrap 5
over from the now ancient Bootstrap 3. This need has been
originally reported back in 2024
based on the lack of security support for Bootstrap 3. Beyond improving
maintainability, this upgrade also enables support for dark mode in debci,
which is still work in progress.
Both updates mentioned in this section will be available in a following debci
release.
Salsa CI maintenance by Santiago Ruano Rinc n et al.
Santiago reviewed some Salsa CI issues and reviewed associated merge requests.
For example, he investigated a regression (#545),
introduced by the move to sbuild,
on the use of extra repositories configured as .source files; and reviewed the
MR (!712)
that fixes it.
Also, there were conflicts with changes made in debci 3.14
and debci 3.14.1
(those updates are mentioned above), and different people have contributed to
fix the subsequent issues, in a long-term way. This includes Rapha l who
proposed MR !707
and who also suggested Antonio to merge the Salsa CI patches to avoid similar
errors in the future. This happened shortly after.
Those fixes finally required the unrelated MR !709,
which will prevent similar problems when building images.
To identify bugs related to the autopkgtest support in the backport suites as
early as possible, Santiago proposed MR !708.
Finally, Santiago, in collaboration with Emmanuel Arias also had exchanges with
GSoC candidates for the Salsa CI project,
including the contributions they have made as merge requests. It is important to
note that there are several very good candidates interested in participating.
Thanks a lot to them for their work so far!
Miscellaneous contributions
Rapha l reported a zim bug
affecting Debian Unstable users, which was already fixed in git apparently. He
could thus cherry-pick the fix and update the package
in Debian Unstable.
Carles submitted translation errors in the debian-installer Weblate.
Carles, using po-debconf-manager,
improved Catalan translations: reviewed and submitted 3 packages. Also improved
error handling when forking or submitting an MR if the fork already existed.
Carles kept improving check-relations:
code base related general improvements (added strict typing, enabled pre-commit).
Also added DebPorts support, virtual packages support and added commands for
reporting missing relations and importing bugs from bugs.debian.org.
Antonio handled miscellaneous Salsa support requests.
Stefano and Santiago continued to help with DebConf 26 preparations.
Stefano reviewed some contributions to debian-reimbursements and handled admin
for reimbursements.debian.net.
Stefano attended the Debian Technical Committee meeting.
Helmut sent 8 patches for cross build failures.
Building on the work of postmarketOS,
Helmut managed to cross build systemd for musl in rebootstrap and sent several
patches in the process.
Helmut reviewed several MRs of Johannes Schauer Marin Rodrigues expanding
support for DPKG_ROOT to support installing hurd.
Helmut incorporated a final round of feedback for the Multi-Arch documentation
in Debian policy, which finally made it into unstable
together with documentation of Build-Profiles.
In order to fix python-memray, Helmut
NMUed libunwind
generally disabling C++ exception support as being an incompatible duplication
of the gcc implementation. Unfortunately, that ended up breaking suricata on riscv64.
After another NMU,
python-memray finally migrated.
Thorsten uploaded new upstream versions of epson-inkjet-printer-escpr and
sane-airscan. He also fixed a packaging bug in printer-driver-oki. As of
systemd 260.1-1 the configuration of lpadmin has been added to the sysusers.d
configuration. All printing packages can now simply depend on the
systemd-sysusers package and don t have to take care of its creation in
maintainer scripts anymore.
In collaboration with Emmanuel Arias, Santiago had exchanges with GSoC
candidates and reviewed the proposals of the
Linux livepatching GSoC 2026 project.
Colin upgraded tango and pytango to new upstream releases and packaged
pybind11-stubgen (needed for pytango), thanks to a Freexian customer. Tests of
reproducible builds revealed that pybind11-stubgen didn t generate imports in a
stable order; this is now fixed upstream.
Lucas fixed CVE-2025-67733
and CVE-2026-21863
affecting src:valkey in unstable and testing. Also reviewed the same fixes
targeting stable proposed by Peter Wienemann.
Faidon worked with upstream and build-dep Debian maintainers on resolving
blockers in order to bring pyHanko into Debian, starting with the adoption of
python-pyhanko-certvalidator. pyHanko is a suite for signing and stamping PDF
files, and one of the few libraries that can be leveraged to sign PDFs with
eIDAS Qualified Electronic Signatures.
Anupa co-organized MiniDebConf Kanpur
and attended the event with many others from all across India. She handled the
accommodation arrangements along with the registration team members, worked on
the budget and expenses. She was also a speaker at the event.
Lucas helped with content review/schedule for the
MiniDebConf Campinas. Thanks Freexian for
being a Gold sponsor!
Lucas organized and took part in a one-day in-person sprint to work on
Ruby 3.4 transition. It was held in a coworking space in Brasilia - Brazil on
April 6th. There were 5 DDs and they fixed multiple packages FTBFSing against
Ruby 3.4 (coming to unstable soon hopefully). Lucas has been postponing a blog
post about this sprint since then :-)
A maintenance release 0.3.13 of the anytime
package arrived on CRAN today,
sticking with the roughly yearly schedule we have now. Binaries for r2u have been built
already. The package is fairly feature-complete, and code and
functionality remain mature and stable.
anytime
is a very focused package aiming to do just one thing really
well: to convert anything in integer, numeric, character,
factor, ordered, input format to either POSIXct (when called as
anytime) or Date objects (when called as
anydate) and to do so without requiring a format
string as well as accomodating different formats in one input
vector. See the anytime page,
the GitHub repo
for a few examples, the nice pdf
vignette, and the beautiful documentation site
for all documentation.
This release was triggered by a bizarre bug seen on elementary os 8.
For reason anytime was
taking note on startup where it runs, and used a small and simply piece
of code reading /etc/os-release when it exists. We assumed
sane content, but this particular operating system and releases managed
to have a duplicate entry throwing us spanner. So now this code is
robust to duplicates, and no longer executed on each startup but as
needed which is a net improvement. We also switched the vignette to
being deployed by the new Rcpp::asis() driver.
The short list of changes follows.
Changes in anytime
version 0.3.13 (2026-04-14)
Continuous integration has received minor updates
The vignette now use the Rcpp::asis() driver, and
references have been refreshed
Stateful 'where are we running' detection is now more robust, and
has been moved from running on each startup to a cached 'as needed'
case
At last, I can run my own large language model artificial idiocy
generator at home on a Debian testing host using Debian packages
directly from the Debian archive. After months of polishing the
llama.cpp,
whisper.cpp and
ggml packages, and their
dependencies, I was very happy to see today that they all entered
Debian testing this morning. Several release-critical issues in
dependencies have been blocking the migration for the last few weeks,
and now finally the last one of these has been fixed. I would like to
extend a big thanks to everyone involved in making this happen.
I've been running home-build editions of whisper.cpp and llama.cpp
packages for a while now, first building from the upstream Git
repository and later, as the Debian packaging progressed, from the
relevant Salsa Git repositories for the ROCM packages, GGML,
whisper.cpp and llama.cpp. The only snag with the official Debian
packages is that the JavaScript chat client web pages are slightly
broken in my setup, where I use a reverse proxy to make my home server
visible on the public Internet while the included web pages only want
to communicate with localhost / 127.0.0.1. I suspect it might be
simple to fix by making the JavaScript code dynamically look up the
URL of the current page and use that to determine where to find the
API service, but until someone fixes
BTS report #1128381, I
just have to edit
/usr/share/llama.cpp-tools/llama-server/themes/simplechat/simplechat.js
every time I upgrade the package. I start my server like this on my
machine with a nice AMD GPU (donated to me as a Debian developer by
AMD two years ago, thank you very much):
It only takes a few minutes to load the model for the first time
and prepare a nice API server for me at
https://my.reverse.proxy.example.com:8080/v1/, available
(note, this sets up the server up without authentication; use a
reverse proxy with authentication if you need it) for all the API
clients I care to test. I switch models regularly to test different
new ones, the Qwen3-Coder one just happen to be the one I use at the
moment. Perhaps these packages is something for you to have fun with
too?
As usual, if you use Bitcoin and want to show your support of my
activities, please send Bitcoin donations to my address
15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.
I ve been using the Furilabs FLX1s phone [1] as my daily driver for 6 weeks, it s a decent phone, not as good as I hoped but good enough to use every day and rely on for phone calls about job interviews etc. I intend to keep using it as my main phone and as a platform to improve phone software in Debian as you really can t effectively find bugs unless you use the platform for important tasks.
Support Problems
I previously wrote about the phone after I received it without a SIM caddy on the 13th of Jan. I had a saga with support about this, on the 16th of Jan one support person said that they would ship it immediately but didn t provide a tracking number or any indication of when it would arrive. On the 5th of Feb I contacted support again and asked how long it would be, the new support person seemed to have no record of my previous communication but said that they would send it. On the 17th of Feb I made another support request including asking for a way of direct communication as the support email came from an address that wouldn t accept replies, I was asked for a photo showing where the problem is. The support person also said that they might have to send a replacement phone!
The last support request I sent included my disappointment at the time taken to resolve the issue and the proposed solution of replacing the entire phone (why have two international shipments of a fragile and expensive phone when a single letter with a cheap SIM caddy would do?). I didn t receive a reply but the SIM caddy arrived on the 2nd of Mar. Here is a pic of the SIM caddy and the package it came in:
One thing that should be noted is that some of the support people seemed to be very good at their jobs and they were all friendly. It was the system that failed here, turning a minor issue of a missing part into a 6 week saga.
Furilabs needs to do the following to address this issue:
Make it possible to reply directly to a message from a support person. Accept email with a custom subject to sort it, give a URL for a web form, anything. Collating discussions with a customer allows giving better support while taking less time for the support people.
Have someone monitor every social media address that is used by the company. When someone sends a support request in a public Mastodon post it indicates that something has gone wrong and you want to move quickly to resolve it.
Take care of the little things, like sending a tracking number for every parcel. If it s something too small for a parcel (the SIM caddy could have fit in a regular letter) then just tell the customer what date it was posted and where it was posted from so they have some idea of when it will arrive.
This is not just a single failure of Furilabs support, it s a systemic failure of their processes.
Problems I Will Fix Unless Someone Beats Me to it
Here are some issues I plan to work on.
Smart Watch Support
I need to port one of the smart watch programs to Debian. Also I want to make one of them support the Colmi P80 [2].
A smart watch significantly increases the utility of a phone even though IMHO they aren t doing nearly all the things that they could and should do. When we get Debian programs talking to the PineTime it will make a good platform for development of new smart phone and OS features.
Nextcloud
I have ongoing issues of my text Nextcloud installation on a Debian VM not allowing connection from the Linux desktop app (as packaged in Debian) and from the Android client (from f-droid). The desktop client works with a friend s Nextcloud installation on Ubuntu so I may try running it on an Ubuntu VM I run while waiting for the Debian issue to get resolved. There was a bug recently fixed in Nextcloud that appears related so maybe the next release will fix it.
For the moment I ve been running without these features and I call and SMS people from knowing their number or just returning calls. Phone calls generally aren t very useful for me nowadays except when applying for jobs. If I could deal with recruiters and hiring managers via video calls then I would consider just not having a phone number.
Wifi IPv6
Periodically IPv6 support just stops working, I can t ping the gateway. I turn wifi off and on again and it works. This might be an issue with my wifi network configuration. This might be an issue with the way I have configured my IPv6 networking, although that problem doesn t happen with any of my laptops.
Chatty Sorting
Chatty is the program for SMS that is installed by default (part of the phosh/phoc setup), it also does Jabber. Version 0.8.7 is installed which apparently has some Furios modifications and it doesn t properly support sorting SMS/Jabber conversations. Version 0.8.9 from Debian sorts in the same way as most SMS and Jabber programs with the most recent at the top. But the Debian version doesn t support Jabber (only SMS and Matrix). When I went back to the Furilabs version of Chatty it still sorted for a while but then suddenly stopped. Killing Chatty (not just closing the window and reopening it) seems to make it sort the conversations sometimes.
Problems for Others to Fix
Here are the current issues I have starting with the most important.
Important
The following issues seriously reduce the usability of the device.
Hotspot
The Wifi hotspot functionality wasn t working for a few weeks, this Gitlab issue seems to match it [3]. It started working correctly for a day and I was not sure if an update I applied fixed the bug or if it s some sort of race condition that worked for this boot and will return next time I reboot it. Later on I rebooted it and found that it s somewhat random whether it works or now.
Also while it is mostly working it seemed to stop working about every 25 minutes or so and I had to turn it off and on again to get it going.
On another day it went to a stage where it got repeated packet loss when I pinged the phone as a hotspot from my laptop. A pattern of 3 ping responses and 3 Destination Host Unreachable messages was often repeated.
I don t know if this is related to the way Android software is run in a container to access the hardware.
4G Reliability
Sometimes 4G connectivity has just stopped, sometimes I can stop and restart the 4G data through software to fix it and sometimes I need to use the hardware switch. I haven t noticed this for a week or two so there is a possibility that one fix addressed both Hotspot and 4G.
One thing that I will do is setup monitoring to give an alert on the phone if it can t connect to the Internet. I don t want it to just quietly stop doing networking stuff and not tell me!
On-screen Keyboard
The compatibility issues of the GNOME and KDE on-screen keyboards are getting me. I use phosh/phoc as the login environment as I want to stick to defaults at first to not make things any more difficult than they need to be. When I use programs that use QT such as Nheko the keyboard doesn t always appear when it should and it forgets the setting for word completion (which means spelling correction).
The spelling correction system doesn t suggest replacing dont with don t which is really annoying as a major advantage for spelling checkers on touch screens is inserting an apostrophy. An apostrophy takes at least 3* longer than a regular character and saving that delay makes a difference to typing speed.
The spelling correction doesn t correct two words run together.
Medium Priority
These issues are ongoing annoyances.
Delay on Power Button
In the best case scenario this phone has a much slower response to pressing the power button than the Android phones I tested (Huawei Mate 10 Pro and Samsung Galaxy Note 9) and a much slower response than my recollection of the vast majority of Android phones I ve ever used. For testing pressing buttons on the phones simultaneously resulted in the Android phone screens lighting up much sooner. Something like 200ms vs 600ms I don t have a good setup to time these things but it s very obvious when I test.
In a less common case scenario (the phone having been unused for some time) the response can be something like 5 seconds. The worst case scenario is something in excess of 20 seconds.
For UI designers, if you get multiple press events from a button that can turn the screen on/off please make your UI leave the screen on and ignore all the stacked events. Having the screen start turning on and off repeatedly when the phone recovers and processes all the button presses isn t good, especially when each screen flash takes half a second.
Notifications
Touching on a notification for a program often doesn t bring it to the foreground. I haven t yet found a connection between when it does and when it doesn t.
Also the lack of icons in the top bar on the screen to indicate notifications is annoying, but that seems to be an issue of design not the implementation.
Charge Delay
When I connect the phone to a power source there is a delay of about 22 seconds before it starts to charge. Having it miss 22 seconds of charge time is no big deal, having to wait 22 seconds to be sure it s charging before leaving it is really annoying. Also the phone makes an audible alert when it gets to 0% charge which woke me up one night when I had failed to push the USB-C connector in hard enough. This phone requires a slightly deeper connector than most phones so with some plugs it s easy to not quite insert them far enough.
Torch aka Flash
The light for the torch or flash for camera is not bright at all. In a quick test staring into the light from 40cm away wasn t unpleasant compared to my Huawei Mate 10 Pro which has a light bright enough that it hurts to look at it from 4 meters away.
Because of this photos at night are not viable, not even when photographing something that s less than a meter away.
The torch has a brightness setting which doesn t seem to change the brightness, so it seems likely that this is a software issue and the brightness is set at a low level and the software isn t changing it.
Audio
When I connect to my car the Lollypop player starts playing before the phone directs audio to the car, so the music starts coming from the phone for about a second. This is an annoying cosmetic error. Sometimes audio playing pauses for no apparent reason.
It doesn t support the phone profile with Bluetooth so phone calls can t go through the car audio system. Also it doesn t always connect to my car when I start driving, sometimes I need to disable and enable Bluetooth to make it connect.
When I initially set the phone up Lollypop would send the track name when playing music through my car (Nissan LEAF) Bluetooth connection, after an update that often doesn t happen so the car doesn t display the track name or whether the music is playing but the pause icon works to pause and resume music (sometimes it does work).
About 30 seconds into a phone call it switches to hands-free mode while the icon to indicate hands-free is not highlighted, so I have to press the hands-free button twice to get it back to normal phone mode.
Low Priority
I could live with these things remaining as-is but it s annoying.
Ticket Mode
There is apparently some code written to display tickets on screen without unlocking. I want to get this working and store screen-caps of the Android barcode screens of the different loyalty cards so I can scan them without unlocking. My threat model does not include someone trying to steal my phone to get a free loaf of bread on the bakery loyalty program.
Camera
The camera app works with both the back and front cameras, which is nice, and sadly based on my experience with other Debian phones it s noteworthy. The problem is that it takes a long time to take a photo, something like a second after the button is pressed long enough for you to think that it just silently took a photo and then move the phone.
The UI of the furios-camera app is also a little annoying, when viewing photos there is an icon at the bottom left of the screen for a video camera and an icon at the bottom right with a cross. Which every time makes me think record videos and leave this screen not return to taking photos and delete current photo . I can get used to the surprising icons, but being so slow is a real problem.
GUI App Installation
The program for managing software doesn t work very well. It said that there were two updates for Mesa package needed, but didn t seem to want to install them. I ran flatpak update as root to fix that. The process of selecting software defaults to including non-free, and most of the available apps are for desktop/laptop with no way to search for phone/tablet apps.
Generally I think it s best to just avoid this and use apt and flatpak directly from the command-line. Being able to ssh to my phone from a desktop or laptop is good!
Android Emulation
The file /home/furios/.local/share/andromeda/data/system/uiderrors.txt is created by the Andromeda system which runs Android apps in a LXC container and appears to grow without end. After using the phone for a month it was 3.5G in size. The disk space usage isn t directly a problem, out of the 110G storage space only 17G is used and I don t have a need to put much else on it, even if I wanted to put backups of /home from my laptop on it when travelling that would still leave plenty of free space. But that sort of thing is a problem for backing up the phone and wasting 3.5G out of 110G total is a fairly significant step towards breaking the entire system.
Also having lots of logging messages from a subsystem that isn t even being used is a bad sign.
I just tried using it and it doesn t start from either the settings menu or from the f-droid icon. Android isn t that important to me as I want to get away from the proprietary app space so I won t bother trying this any more.
Unfixable Problems
Unlocking
After getting used to fingerprint unlocking going back to a password is a pain. I think that the hardware isn t sufficient for modern quality face recognition that can t be fooled by a photo and there isn t fingerprint hardware.
When I first used an Android phone using a pin to unlock didn t seem like a big deal, but after getting used to fingerprint unlock it s a real drag to go without. This is a real annoyance when doing things like checking Wikipedia while watching TV.
This phone would be significantly improved with a fingerprint sensor or a camera that worked well enough for face unlock.
Plasma Mobile
According to Reddit Plasma Mobile (KDE for phones) doesn t support Halium and can never work on this phone because of it [4]. This is one of a number of potential issues with the phone, running on hardware that was never designed for open OSs is always going to have issues.
Wifi MAC Address
The MAC keeps changing on reboot so I can t assign a permanent IPv4 address to the phone. It appears from the MAC prefix of 00:08:22 that the network hardware is made in InPro Comm which is well known for using random addresses in the products it OEMs. They apparently have one allocation of 2^24 addresses and each device randomly chooses a MAC from that range on boot.
In the settings for a Wifi connection the Identity tab has a field named Cloned Address which can be set to Stable for SSID that prevents it from changing and allows a static IP address allocation from DHCP. It s not ideal but it works.
Network Manager can be configured to have a permanent assigned MAC address for all connections or for just some connections. In the past for such things I have copied MAC addresses from ethernet devices that were being discarded and used them for such things. For the moment the Stable for SSID setting does what I need but I will consider setting a permanent address at some future time.
Docks
Having the ability to connect to a dock is really handy. The PinePhonePro and Librem5 support it and on the proprietary side a lot of Samsung devices do it with a special desktop GUI named Dex and some Huawei devices also have a desktop version of the GUI. It s unfortunate that this phone can t do it.
The Good Things
It s good to be able to ssh in to my phone, even if the on-screen keyboard worked as well as the Android ones it would still be a major pain to use when compared to a real keyboard. The phone doesn t support connecting to a dock (unlike Samsung phones I ve used for which I found Dex to be very useful with a 4K monitor and proper keyboard) so ssh is the best way to access it.
This phone has very reliable connections to my home wifi. I ve had ssh sessions from my desktop to my phone that have remained open for multiple days. I don t really need this, I ve just forgotten to logout and noticed days later that the connection is still running. None of the other phones running Debian could do that.
Running the same OS on desktop and phone makes things easier to test and debug.
Having support for all the things that Linux distributions support is good. For example none of the Android music players support all the encodings of audio that comes from YouTube so to play all of my music collection on Android I would need to transcode most of them which means either losing quality, wasting storage space, or both. While Lollypop plays FLAC0, mp3, m4a, mka, webm, ogg, and more.
Conclusion
This is a step towards where I want to go but it s far from the end goal.
The PinePhonePro and Librem5 are more open hardware platforms which have some significant benefits. But the battery life issues make them unusable for me.
Running Mobian on a OnePlus 6 or Droidian on a Note 9 works well for the small tablet features but without VoLTE. While the telcos have blocked phones without VoLTE data devices still work so if recruiters etc would stop requiring phone calls then I could make one of them an option.
The phone works well enough that it could potentially be used by one of my older relatives. If I could ssh in to my parents phones when they mess things up that would be convenient.
I ve run this phone as my daily driver since the 3rd of March and it has worked reasonably well. 6 weeks compared to my previous use of the PinePhonePro for 3 days. This is the first time in 15 years that a non-Android phone has worked for me personally. I have briefly used an iPhone 7 for work which basically did what it needed to do, it was at the bottom of the pile of unused phones at work and I didn t want to take a newer iPhone that could be used by someone who s doing more than the occasional SMS or Slack message.
So this is better than it might have been, not as good as I hoped, but a decent platform to use it while developing for it.

 The eight release of the
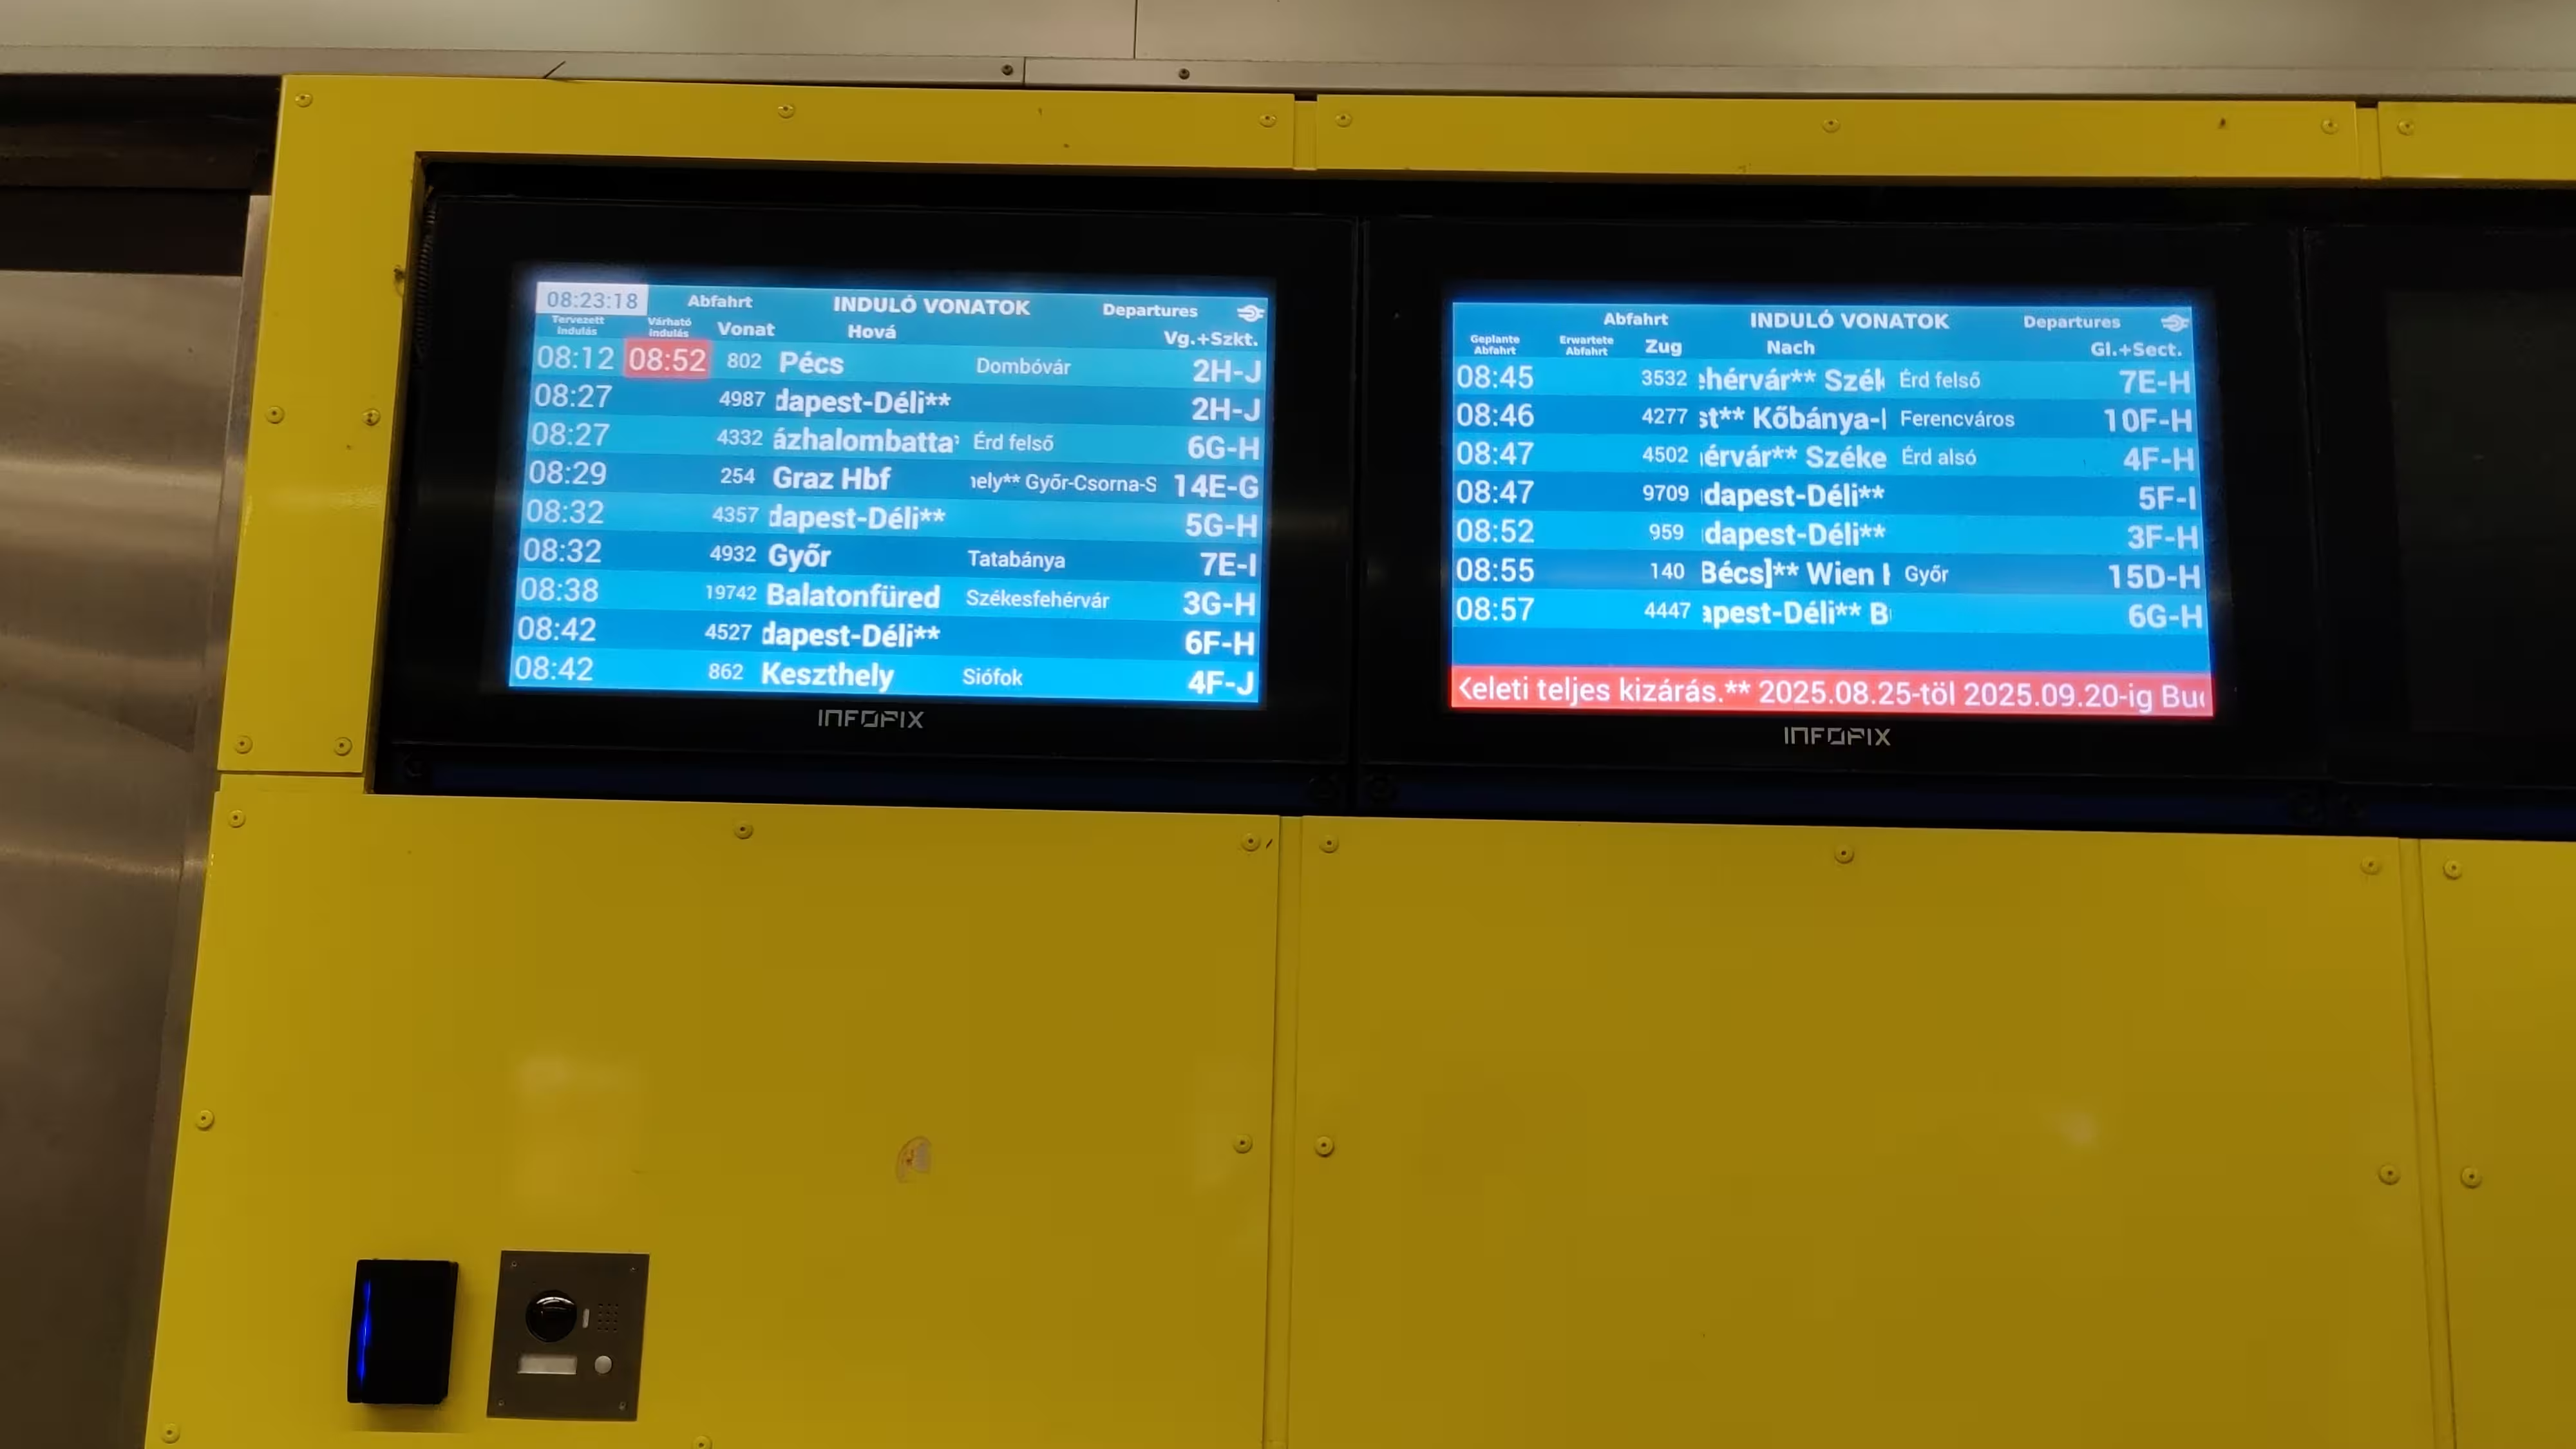 A departures board at Budapest Kelenfold station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
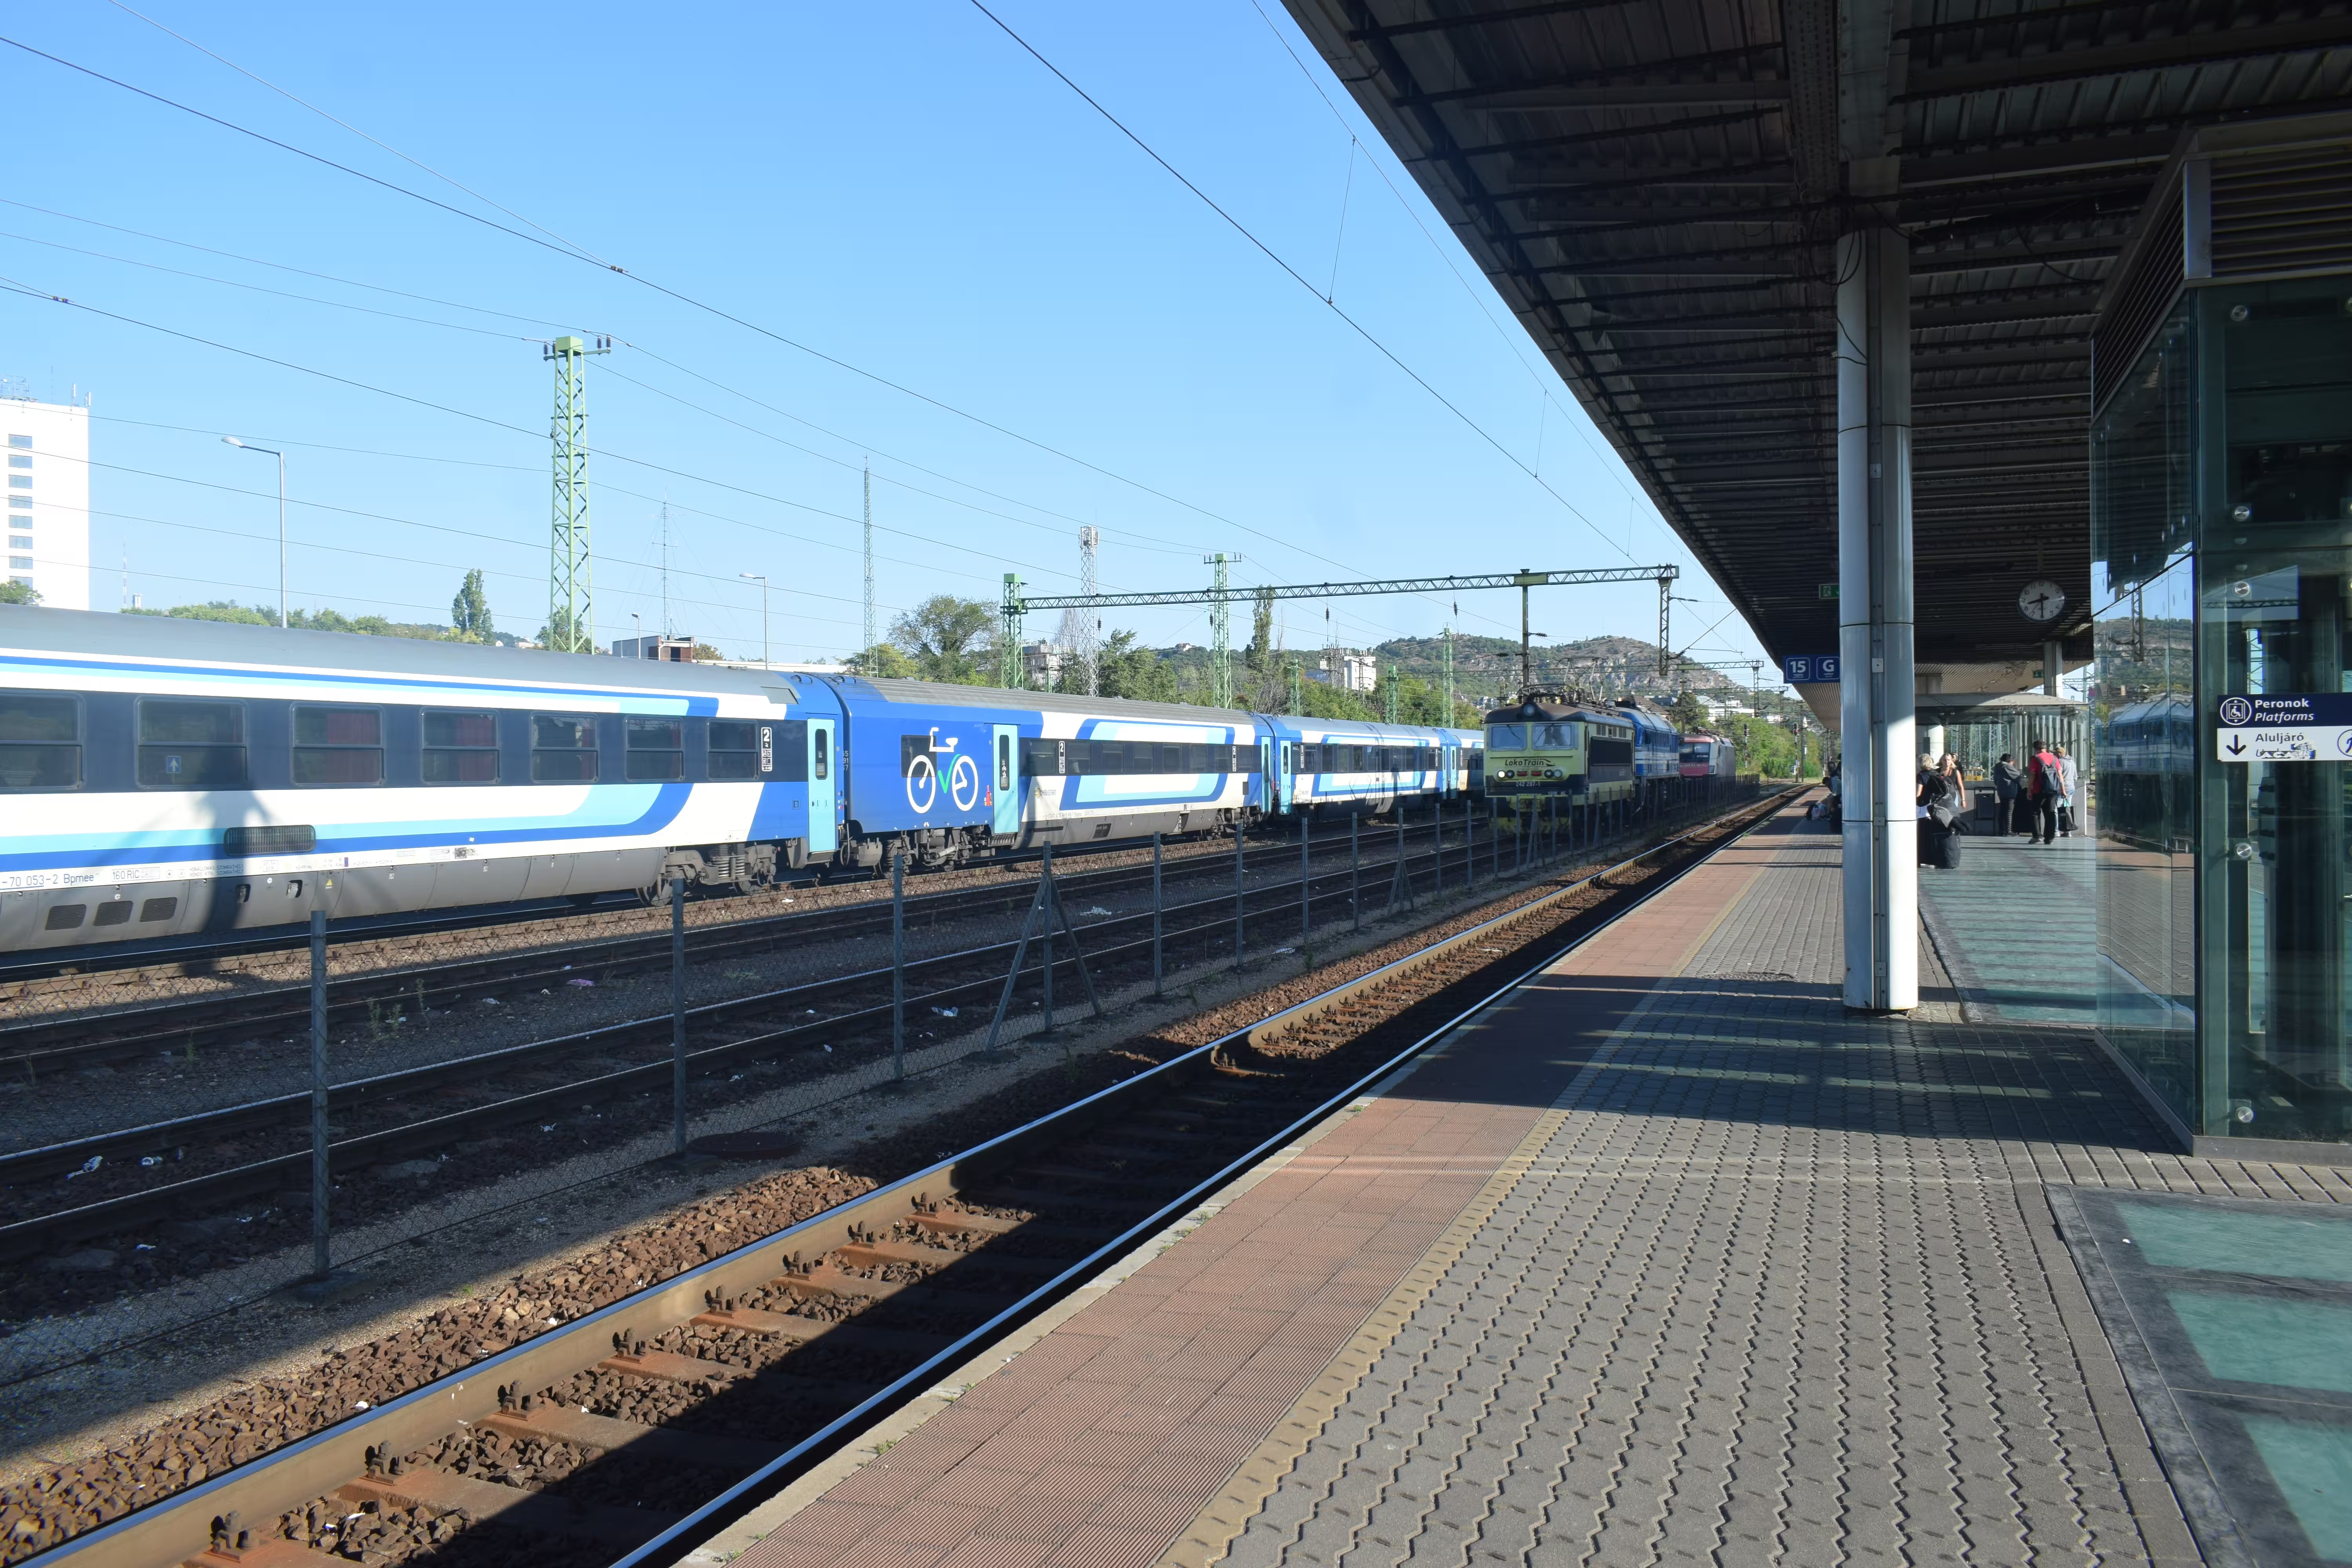 This is platform number 15 of Budapest Kelenfold station where we boarded our train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
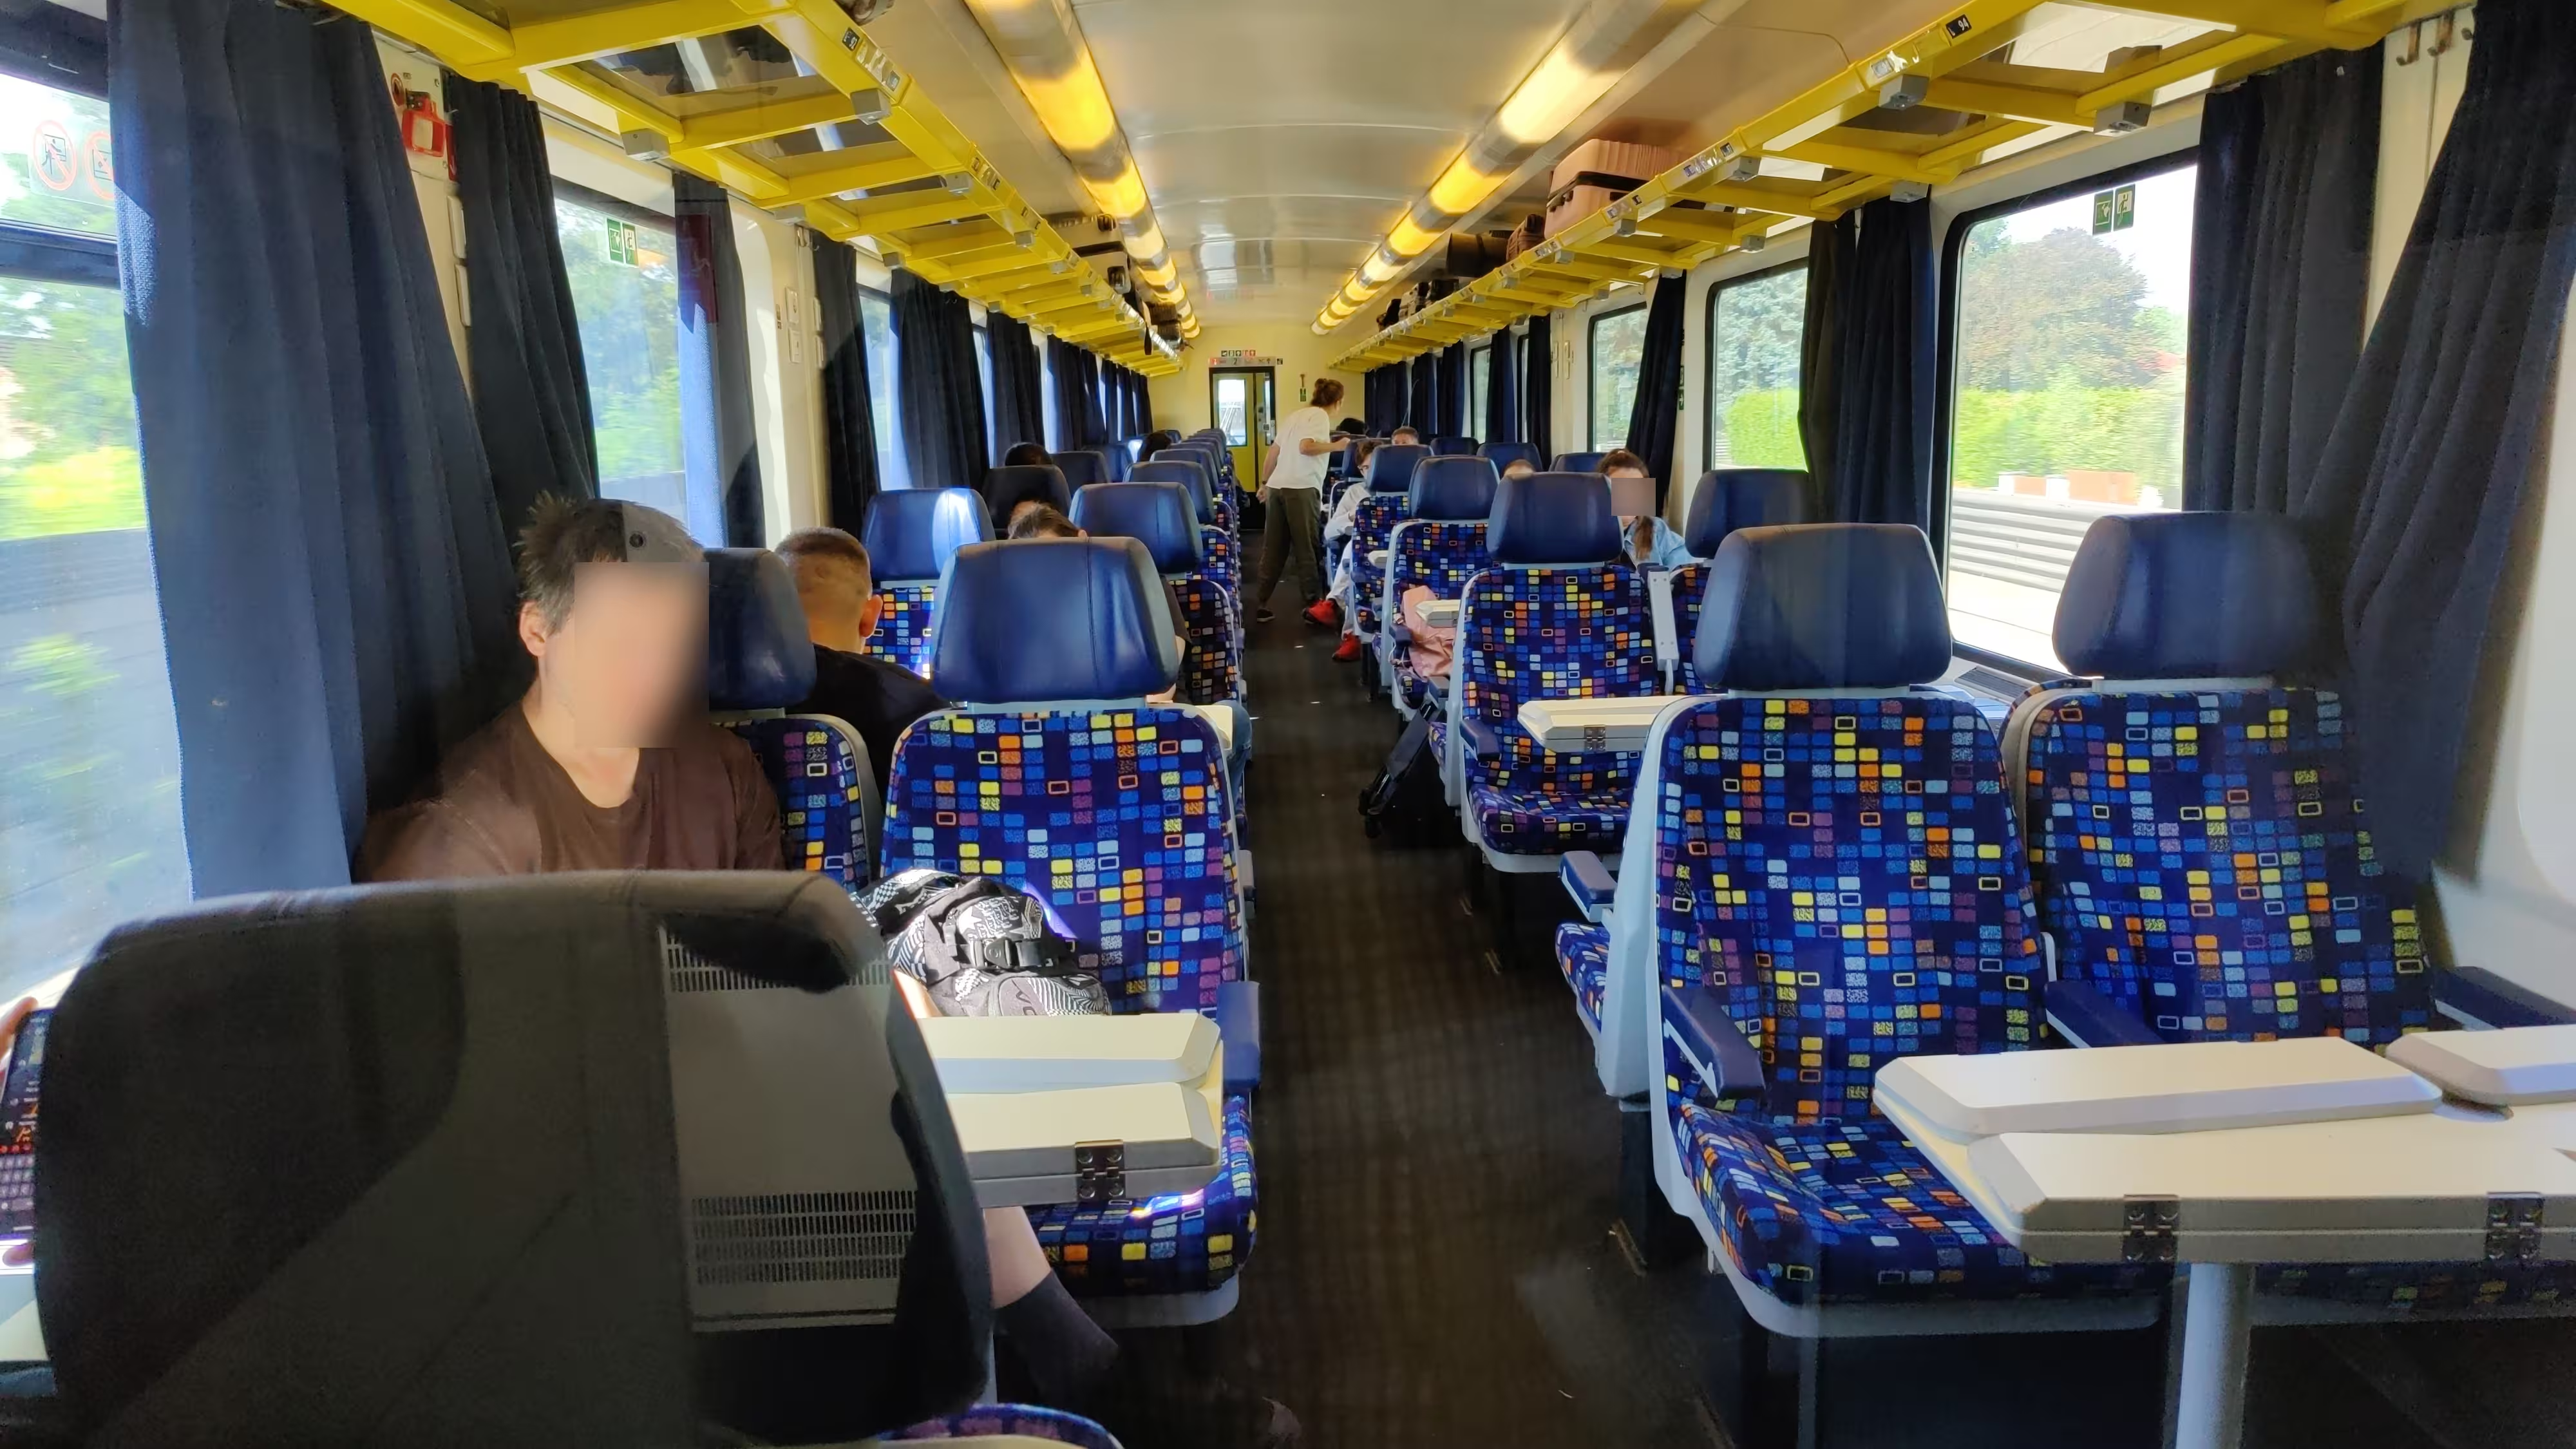 Interior of our Budapest to Vienna train. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
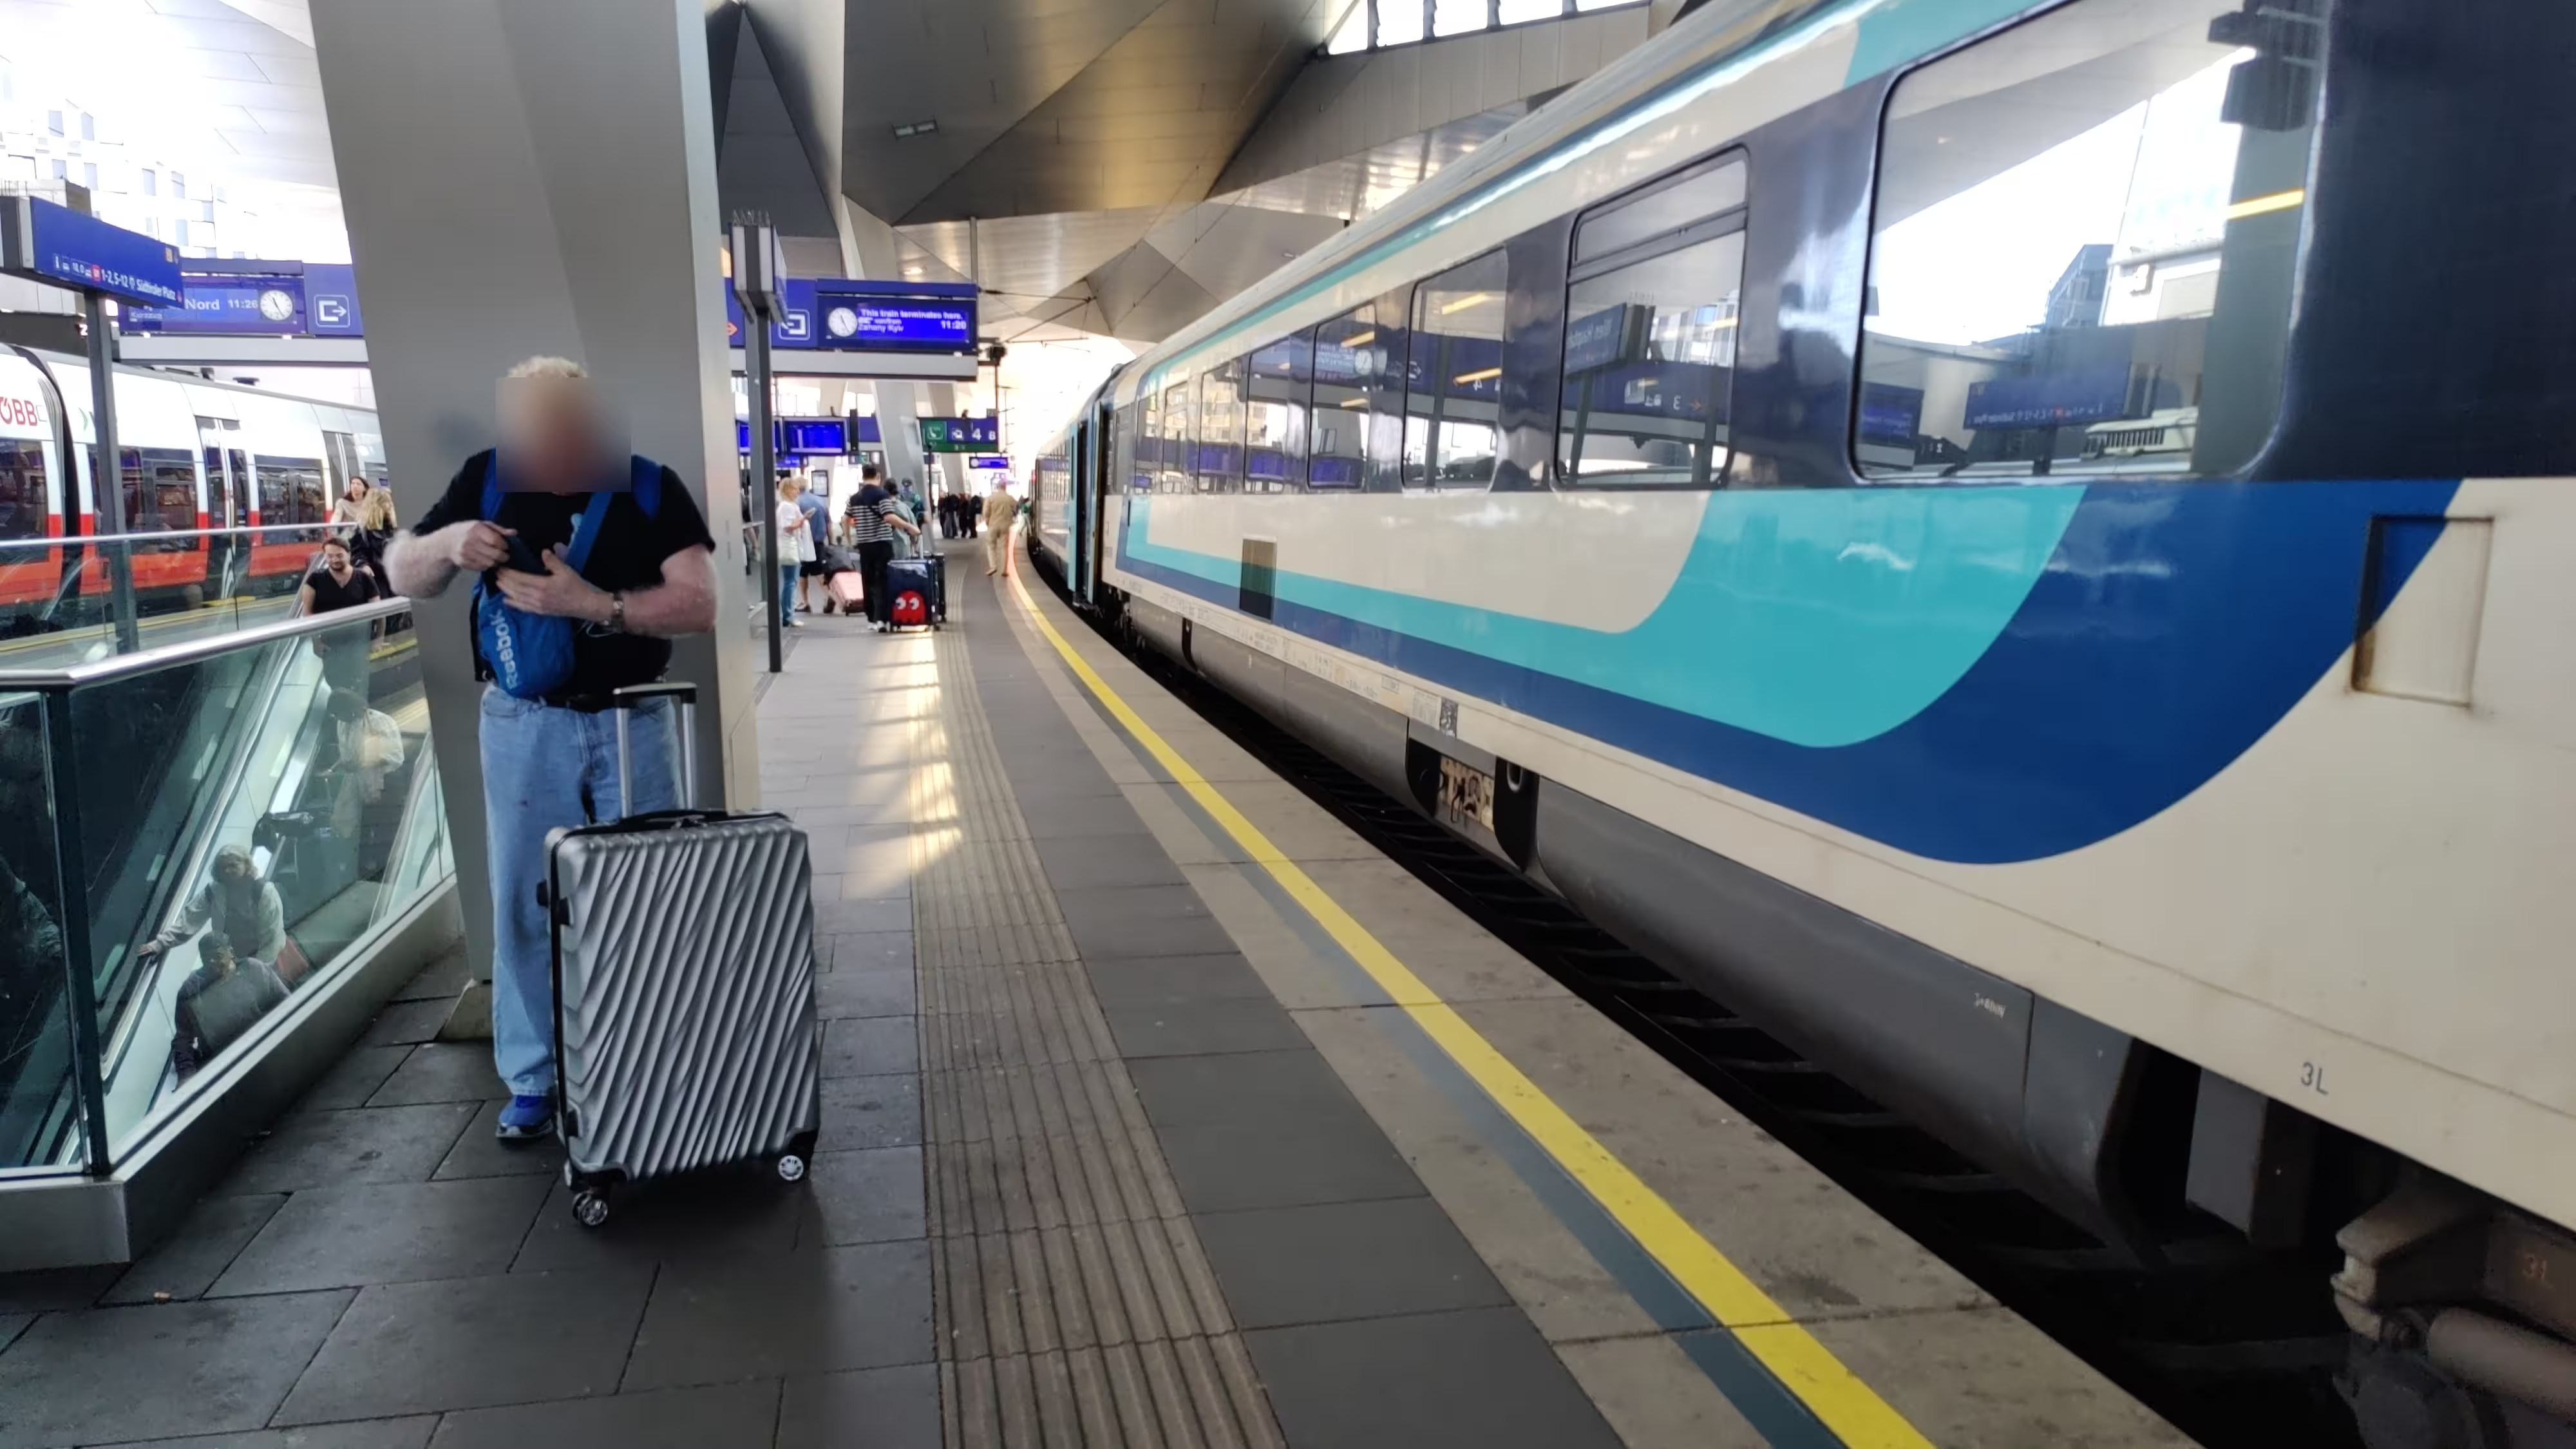 This blue colored train was the one we took for our Budapest to Vienna journey. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
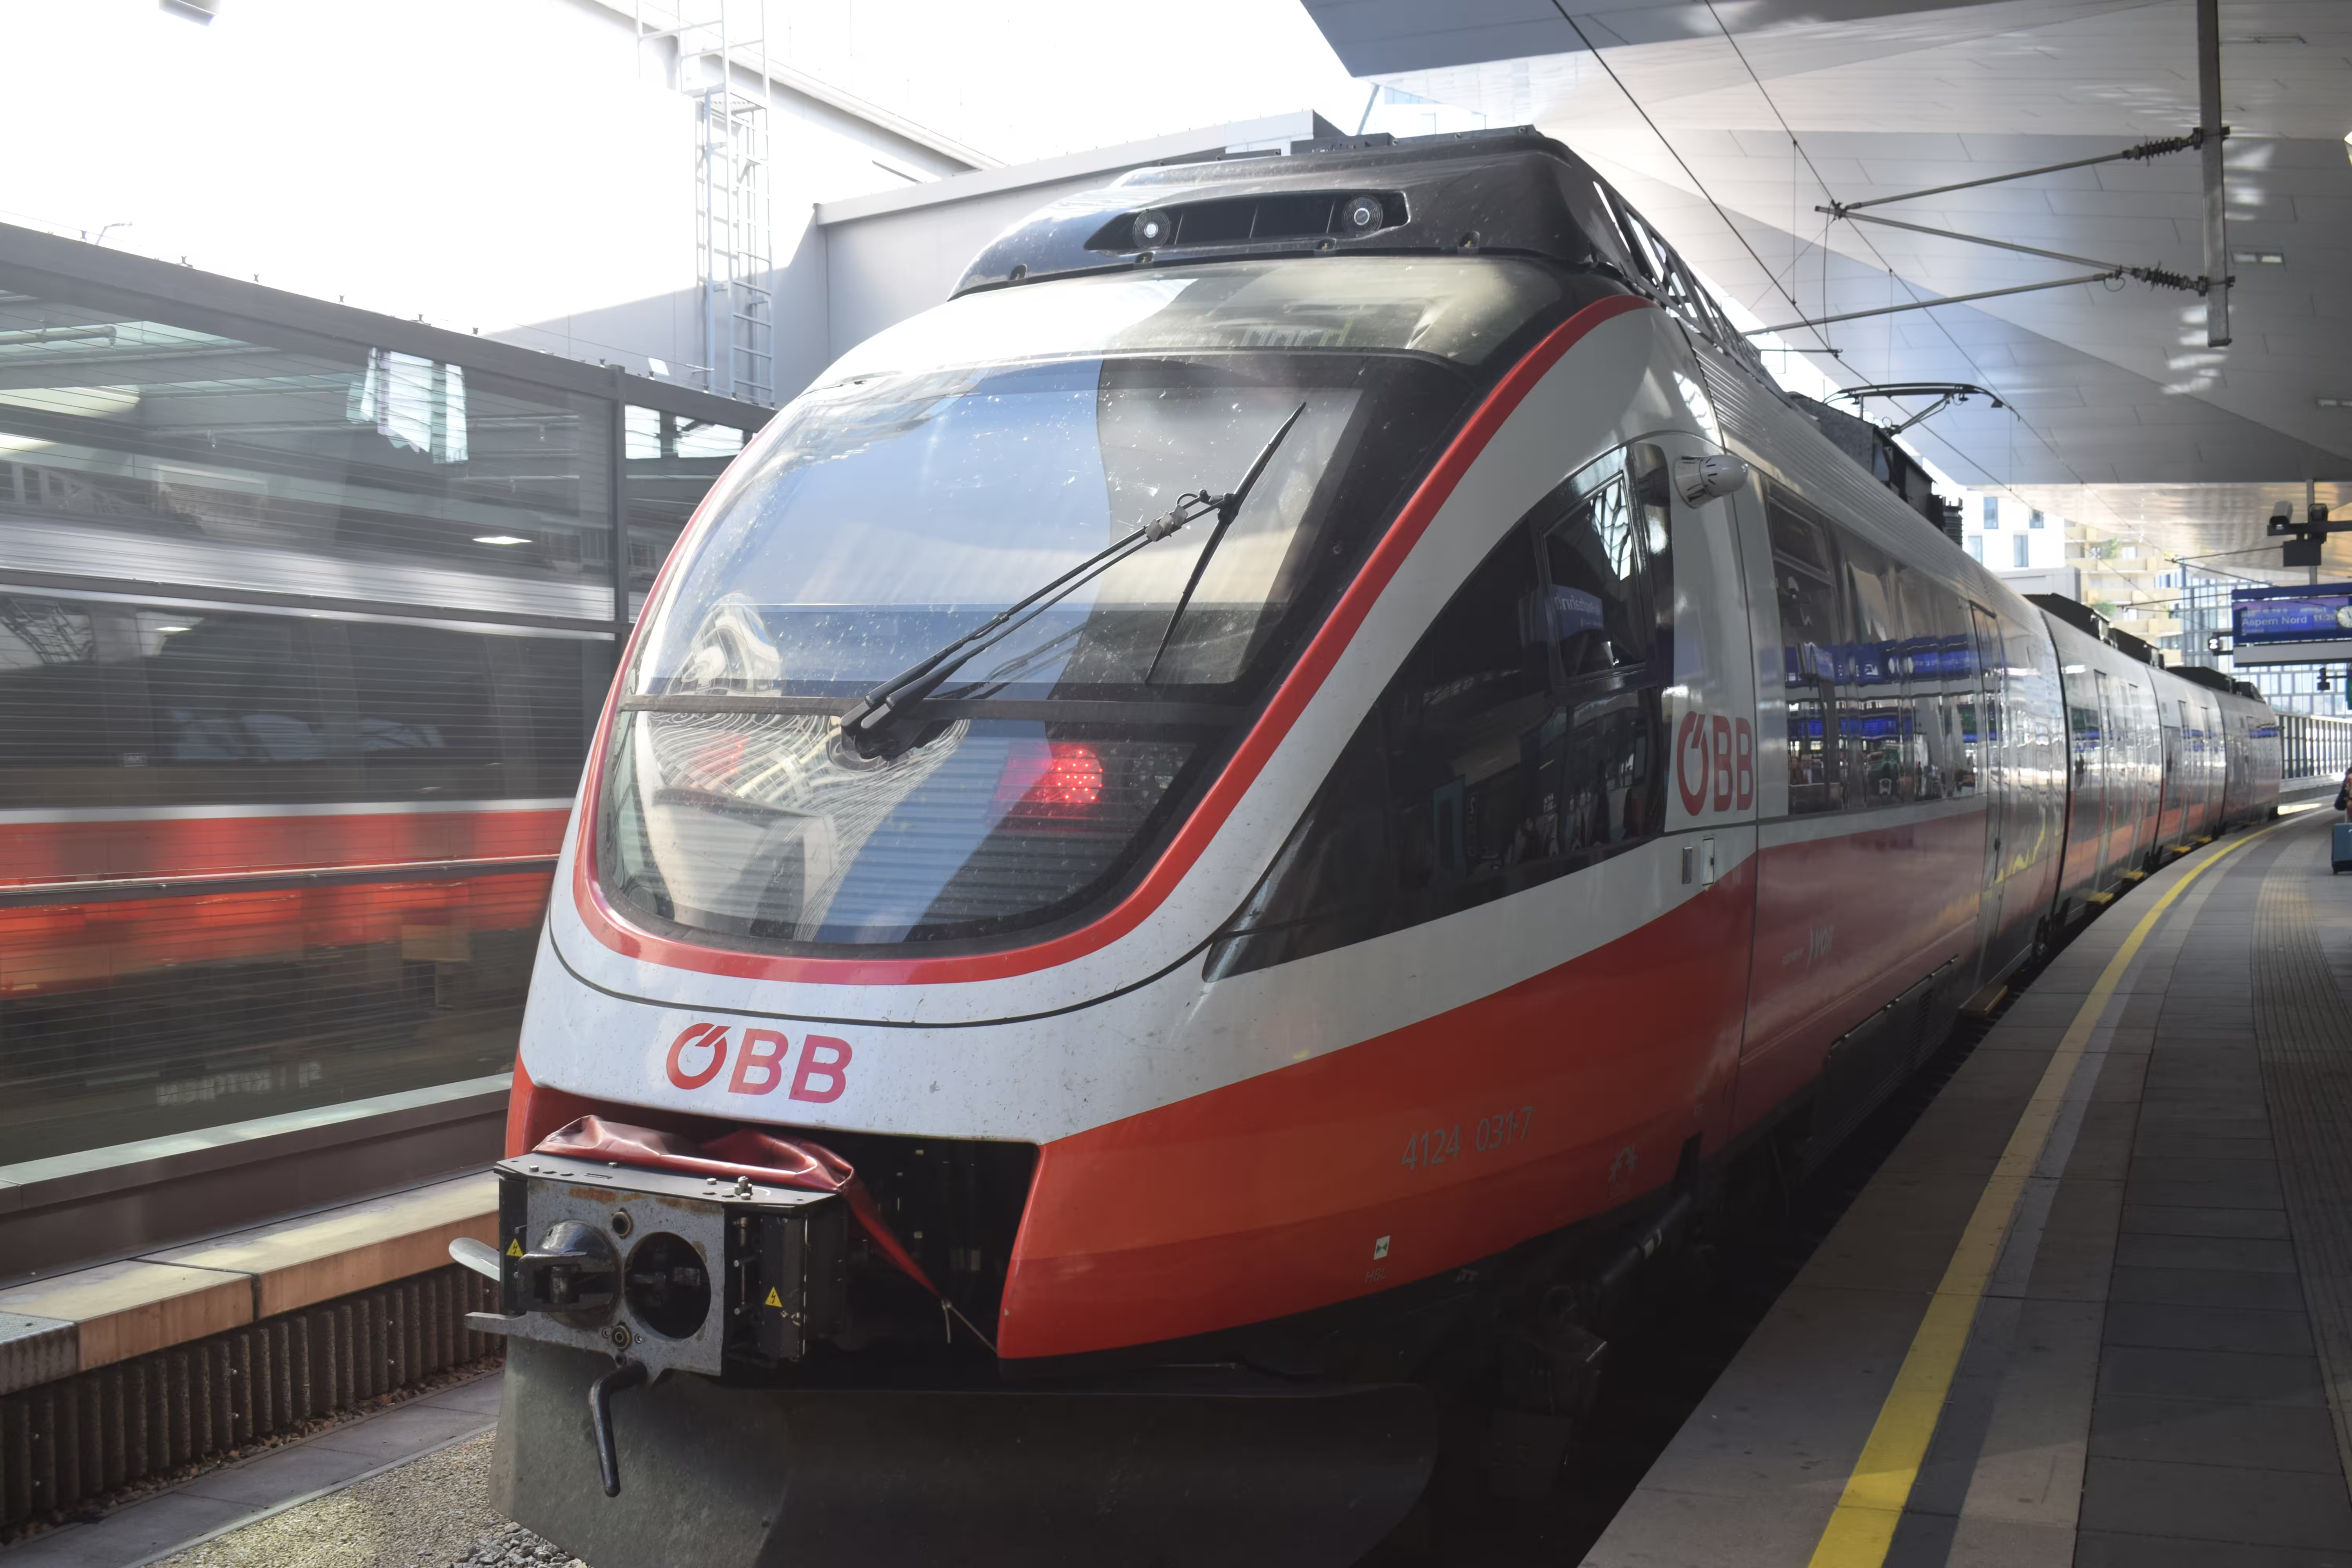 An BB train standing at a platform of Vienna train station. BB is the national carrier of Austria. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
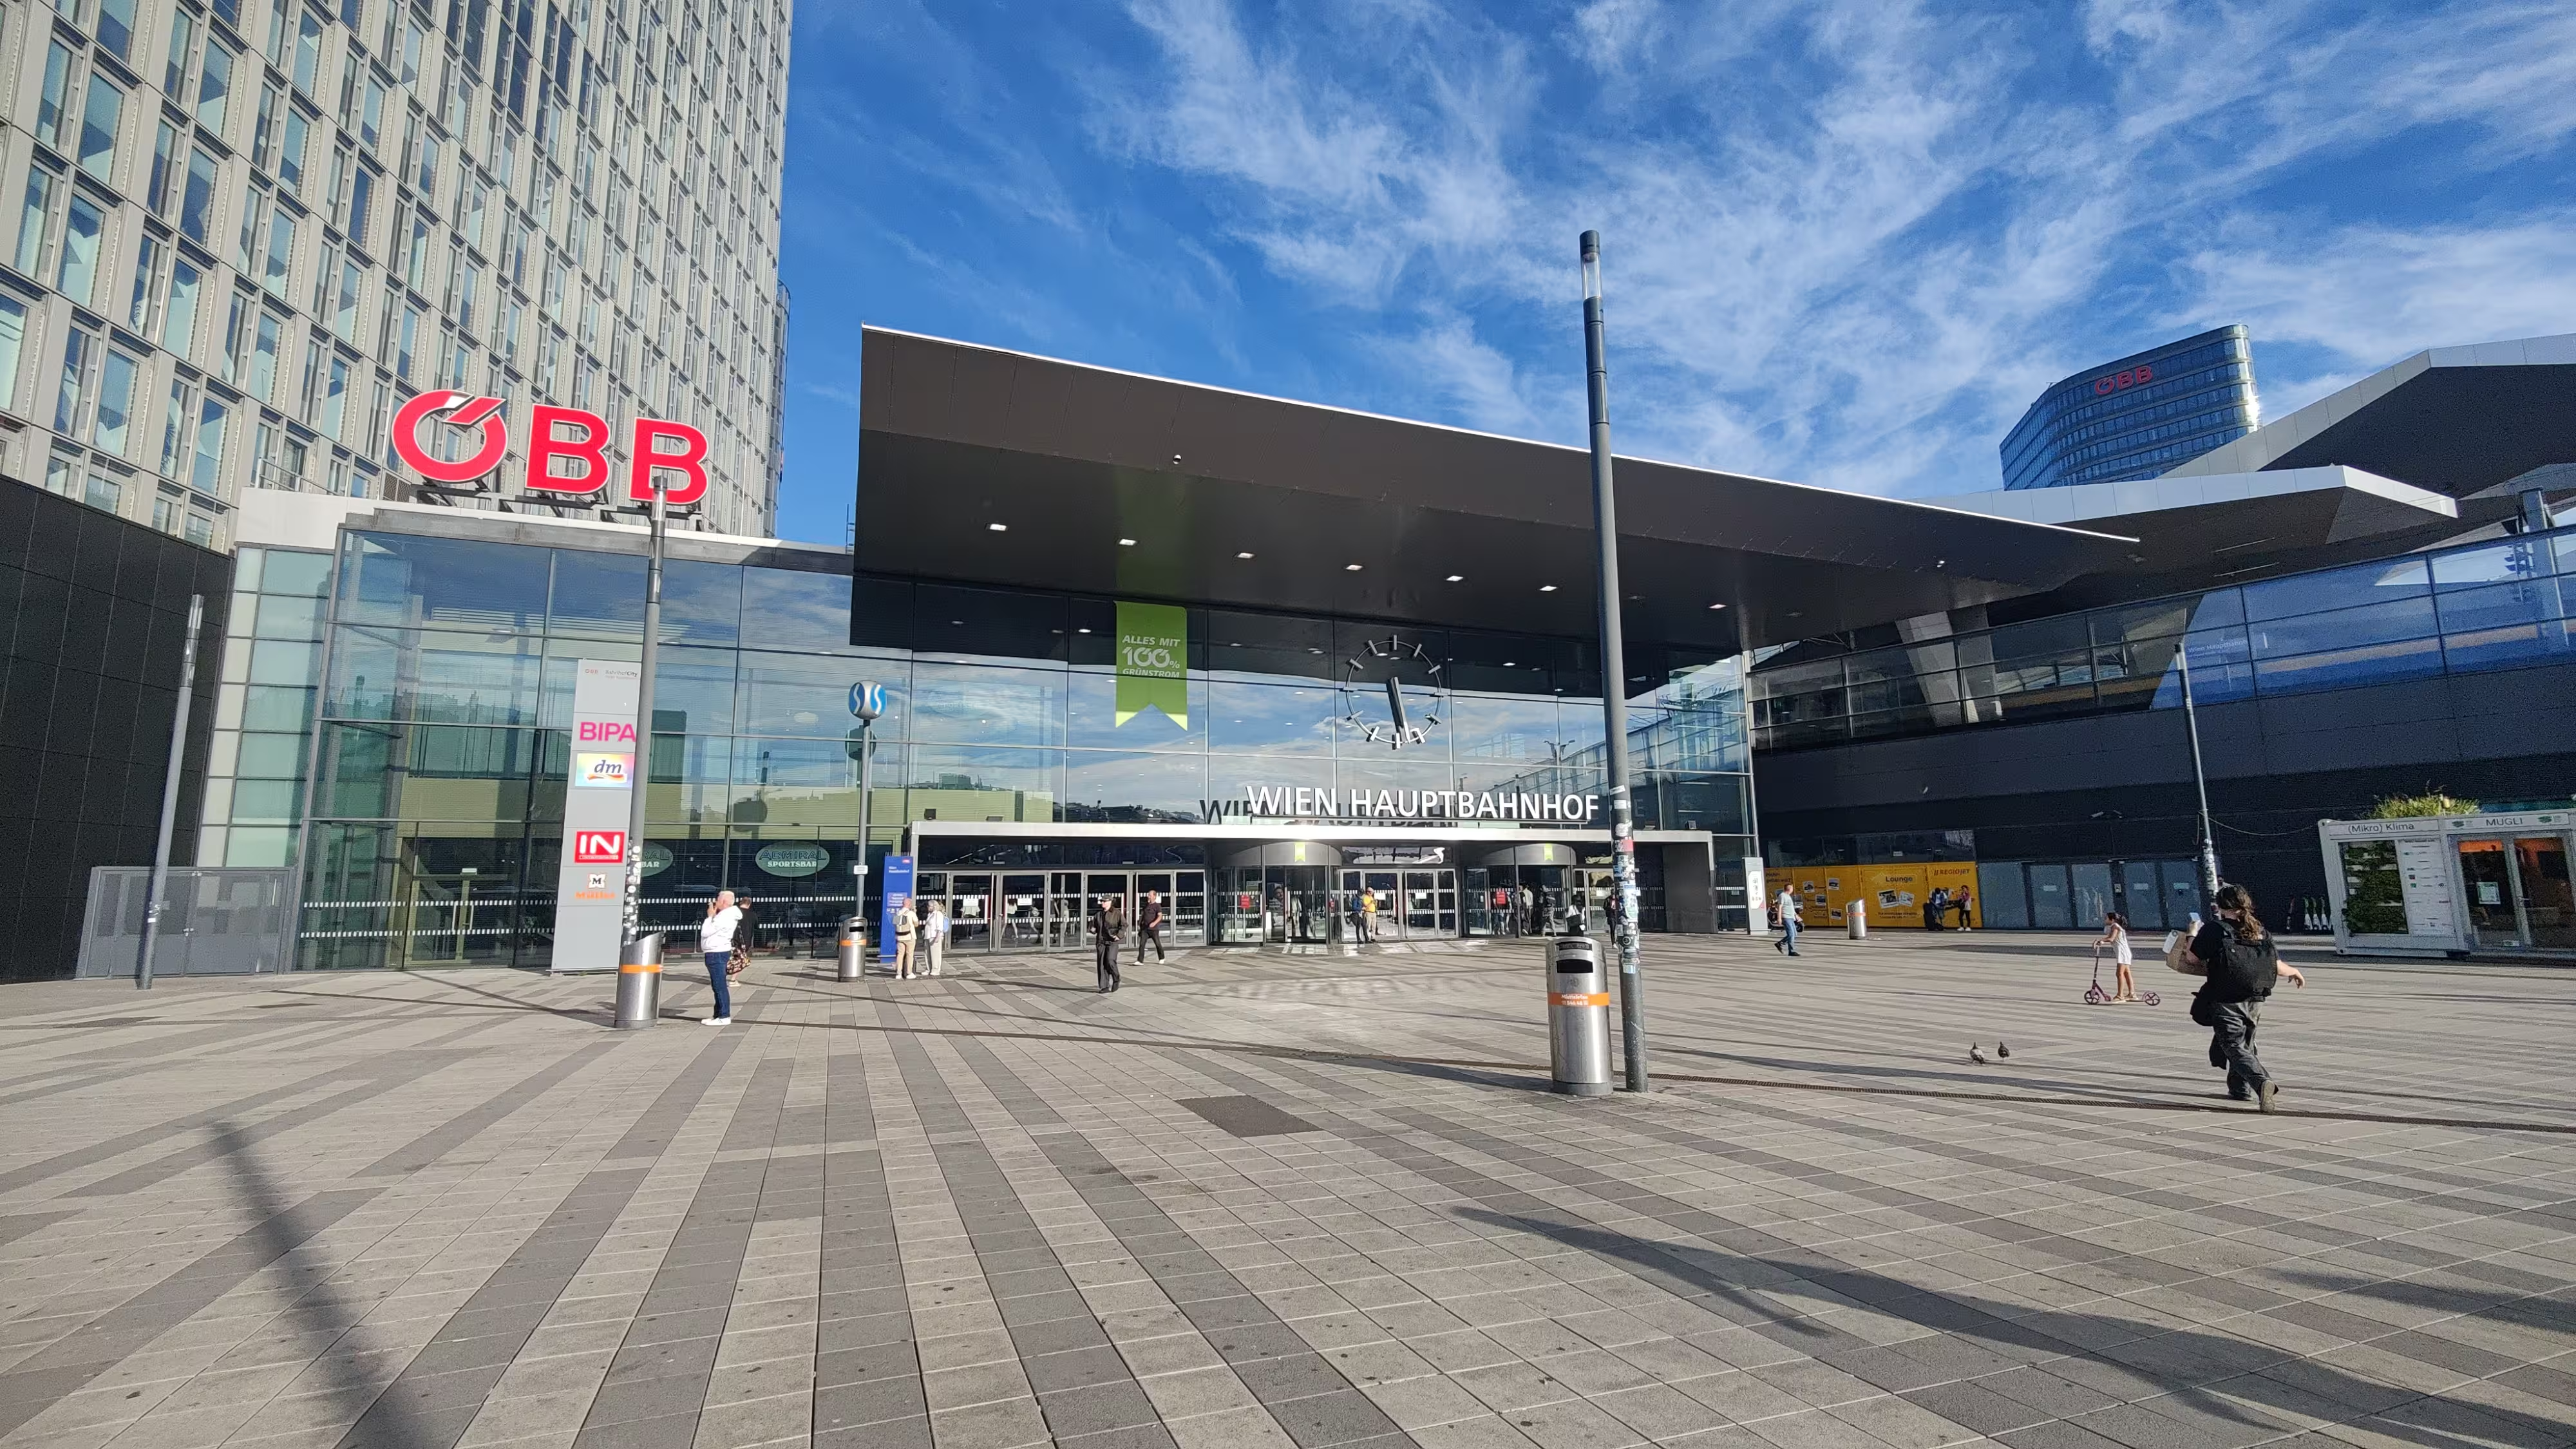 Wien Hauptbahnhof train station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
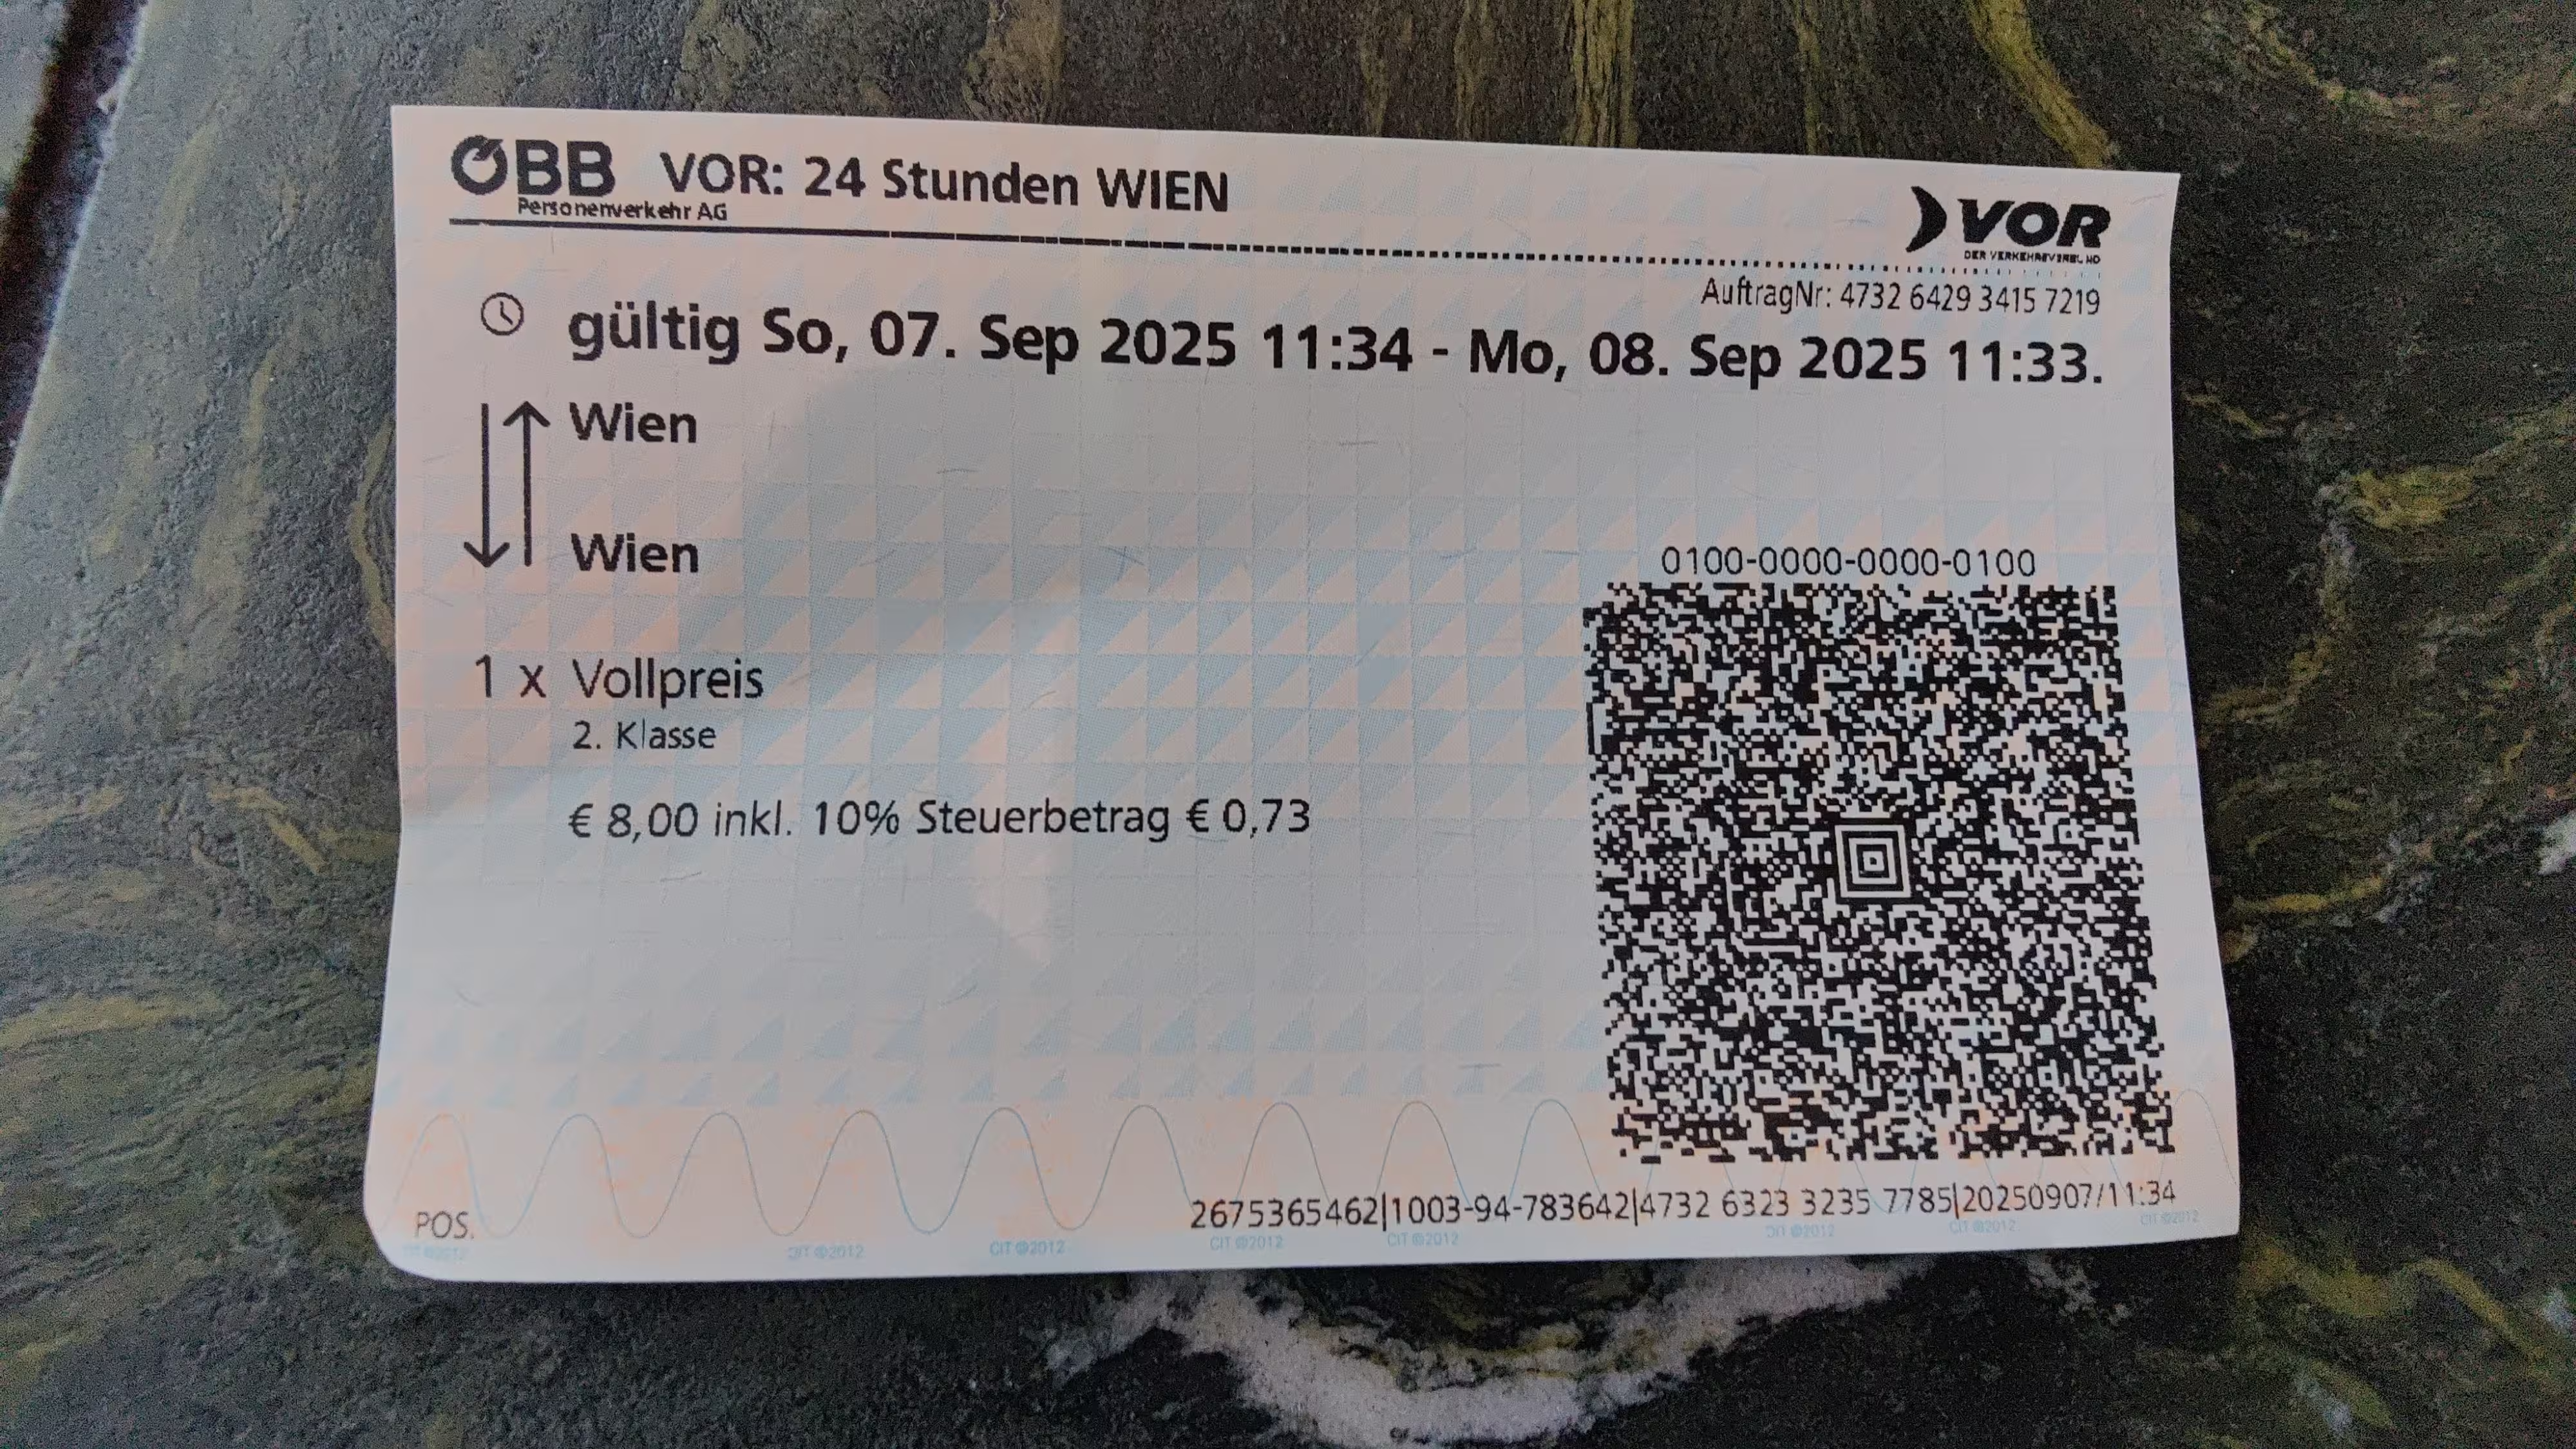 My public transport pass in Vienna.
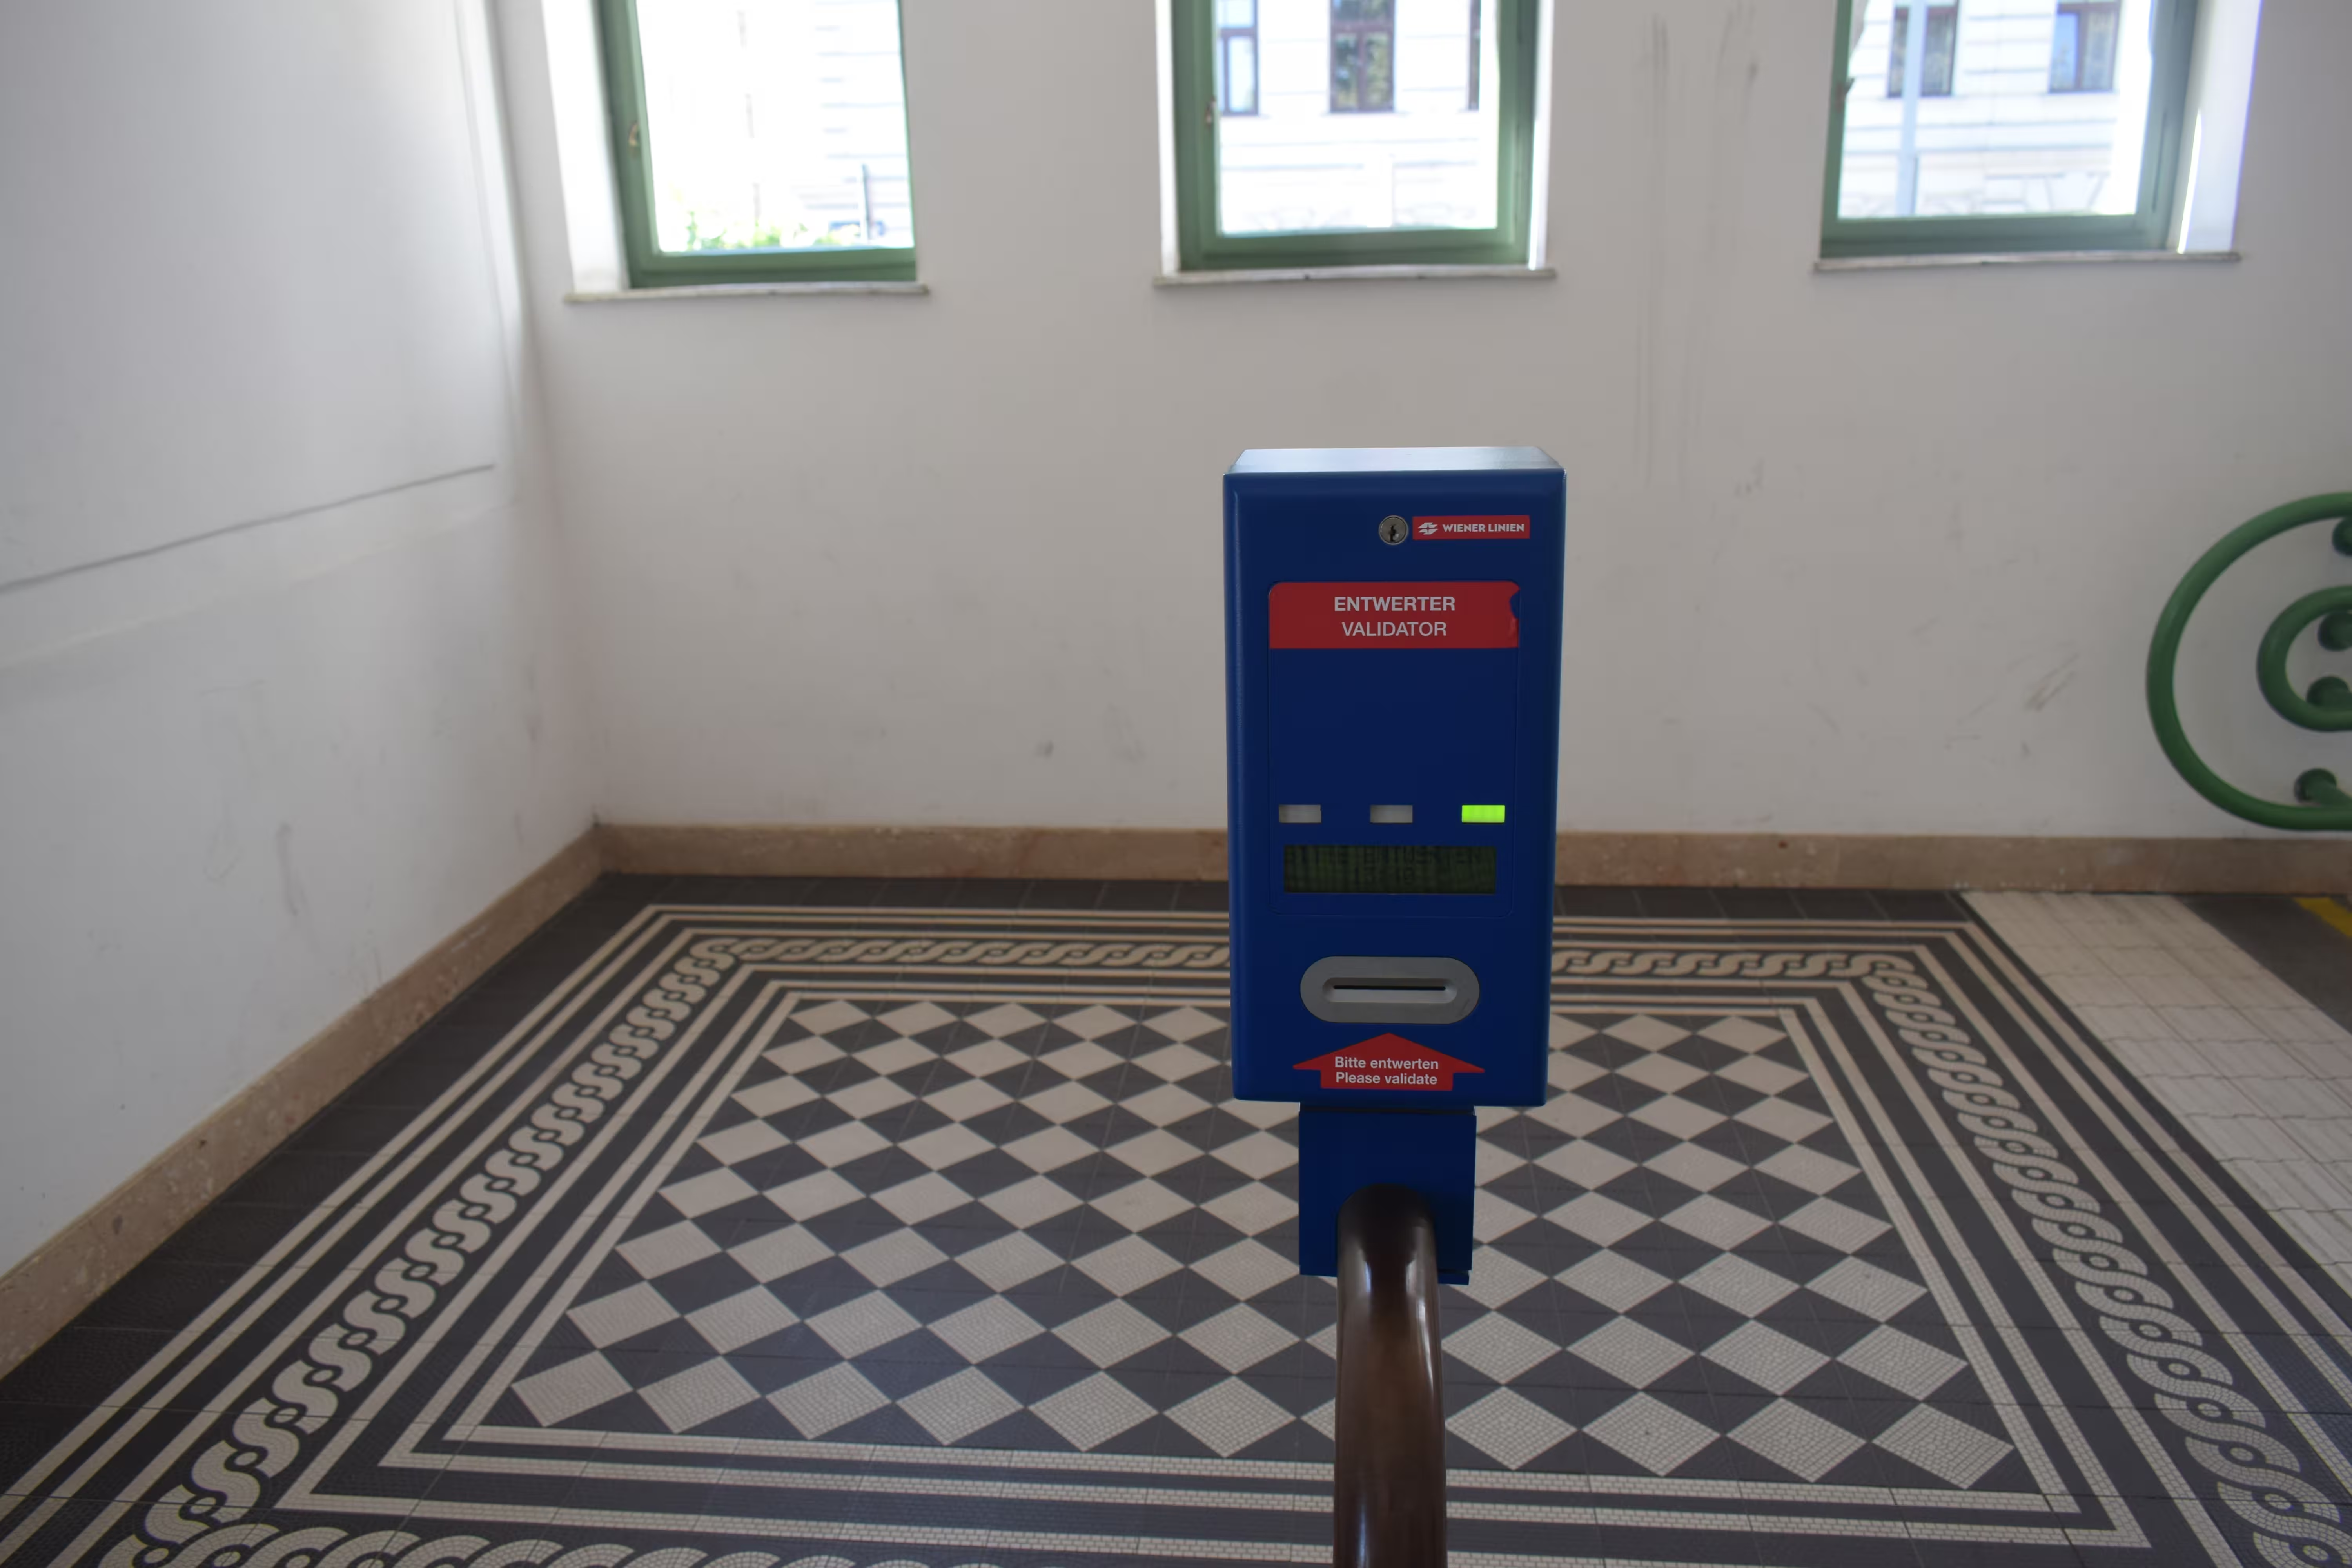 Instead of AFC gates, Vienna has ticket validators as in the picture. You need to tap your ticket in the validator before boarding the subway. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
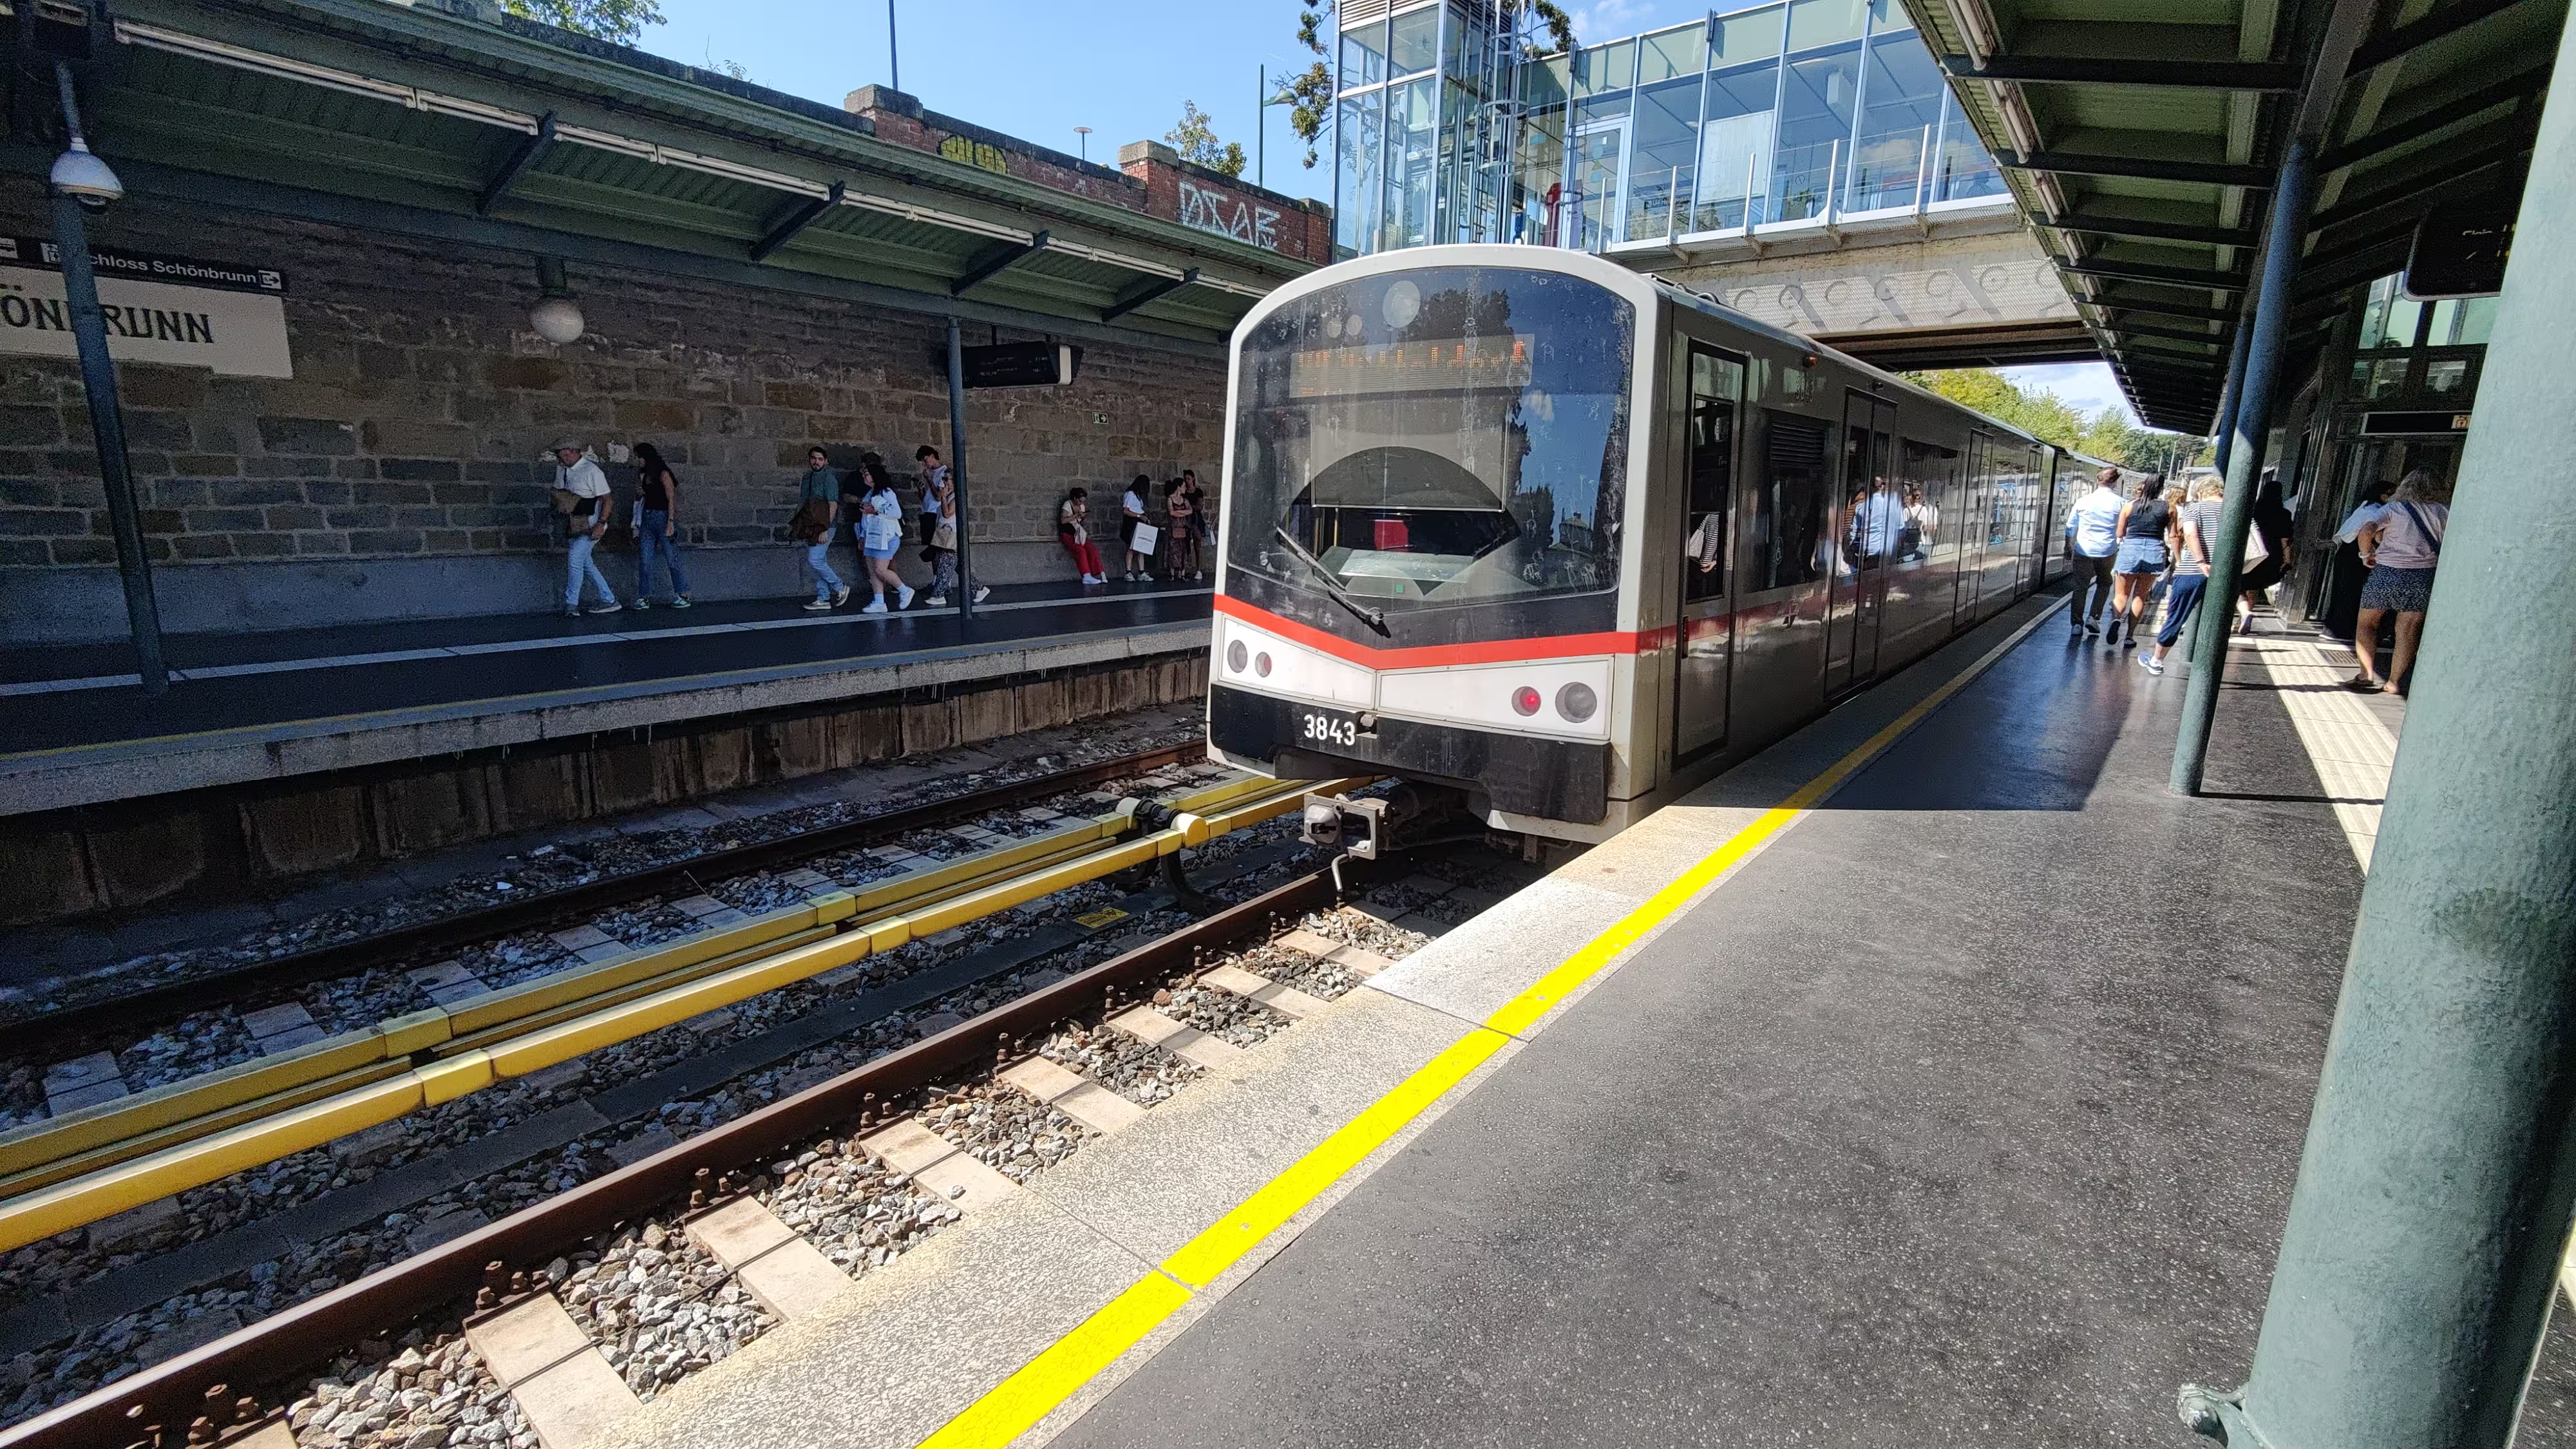 Vienna subway. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
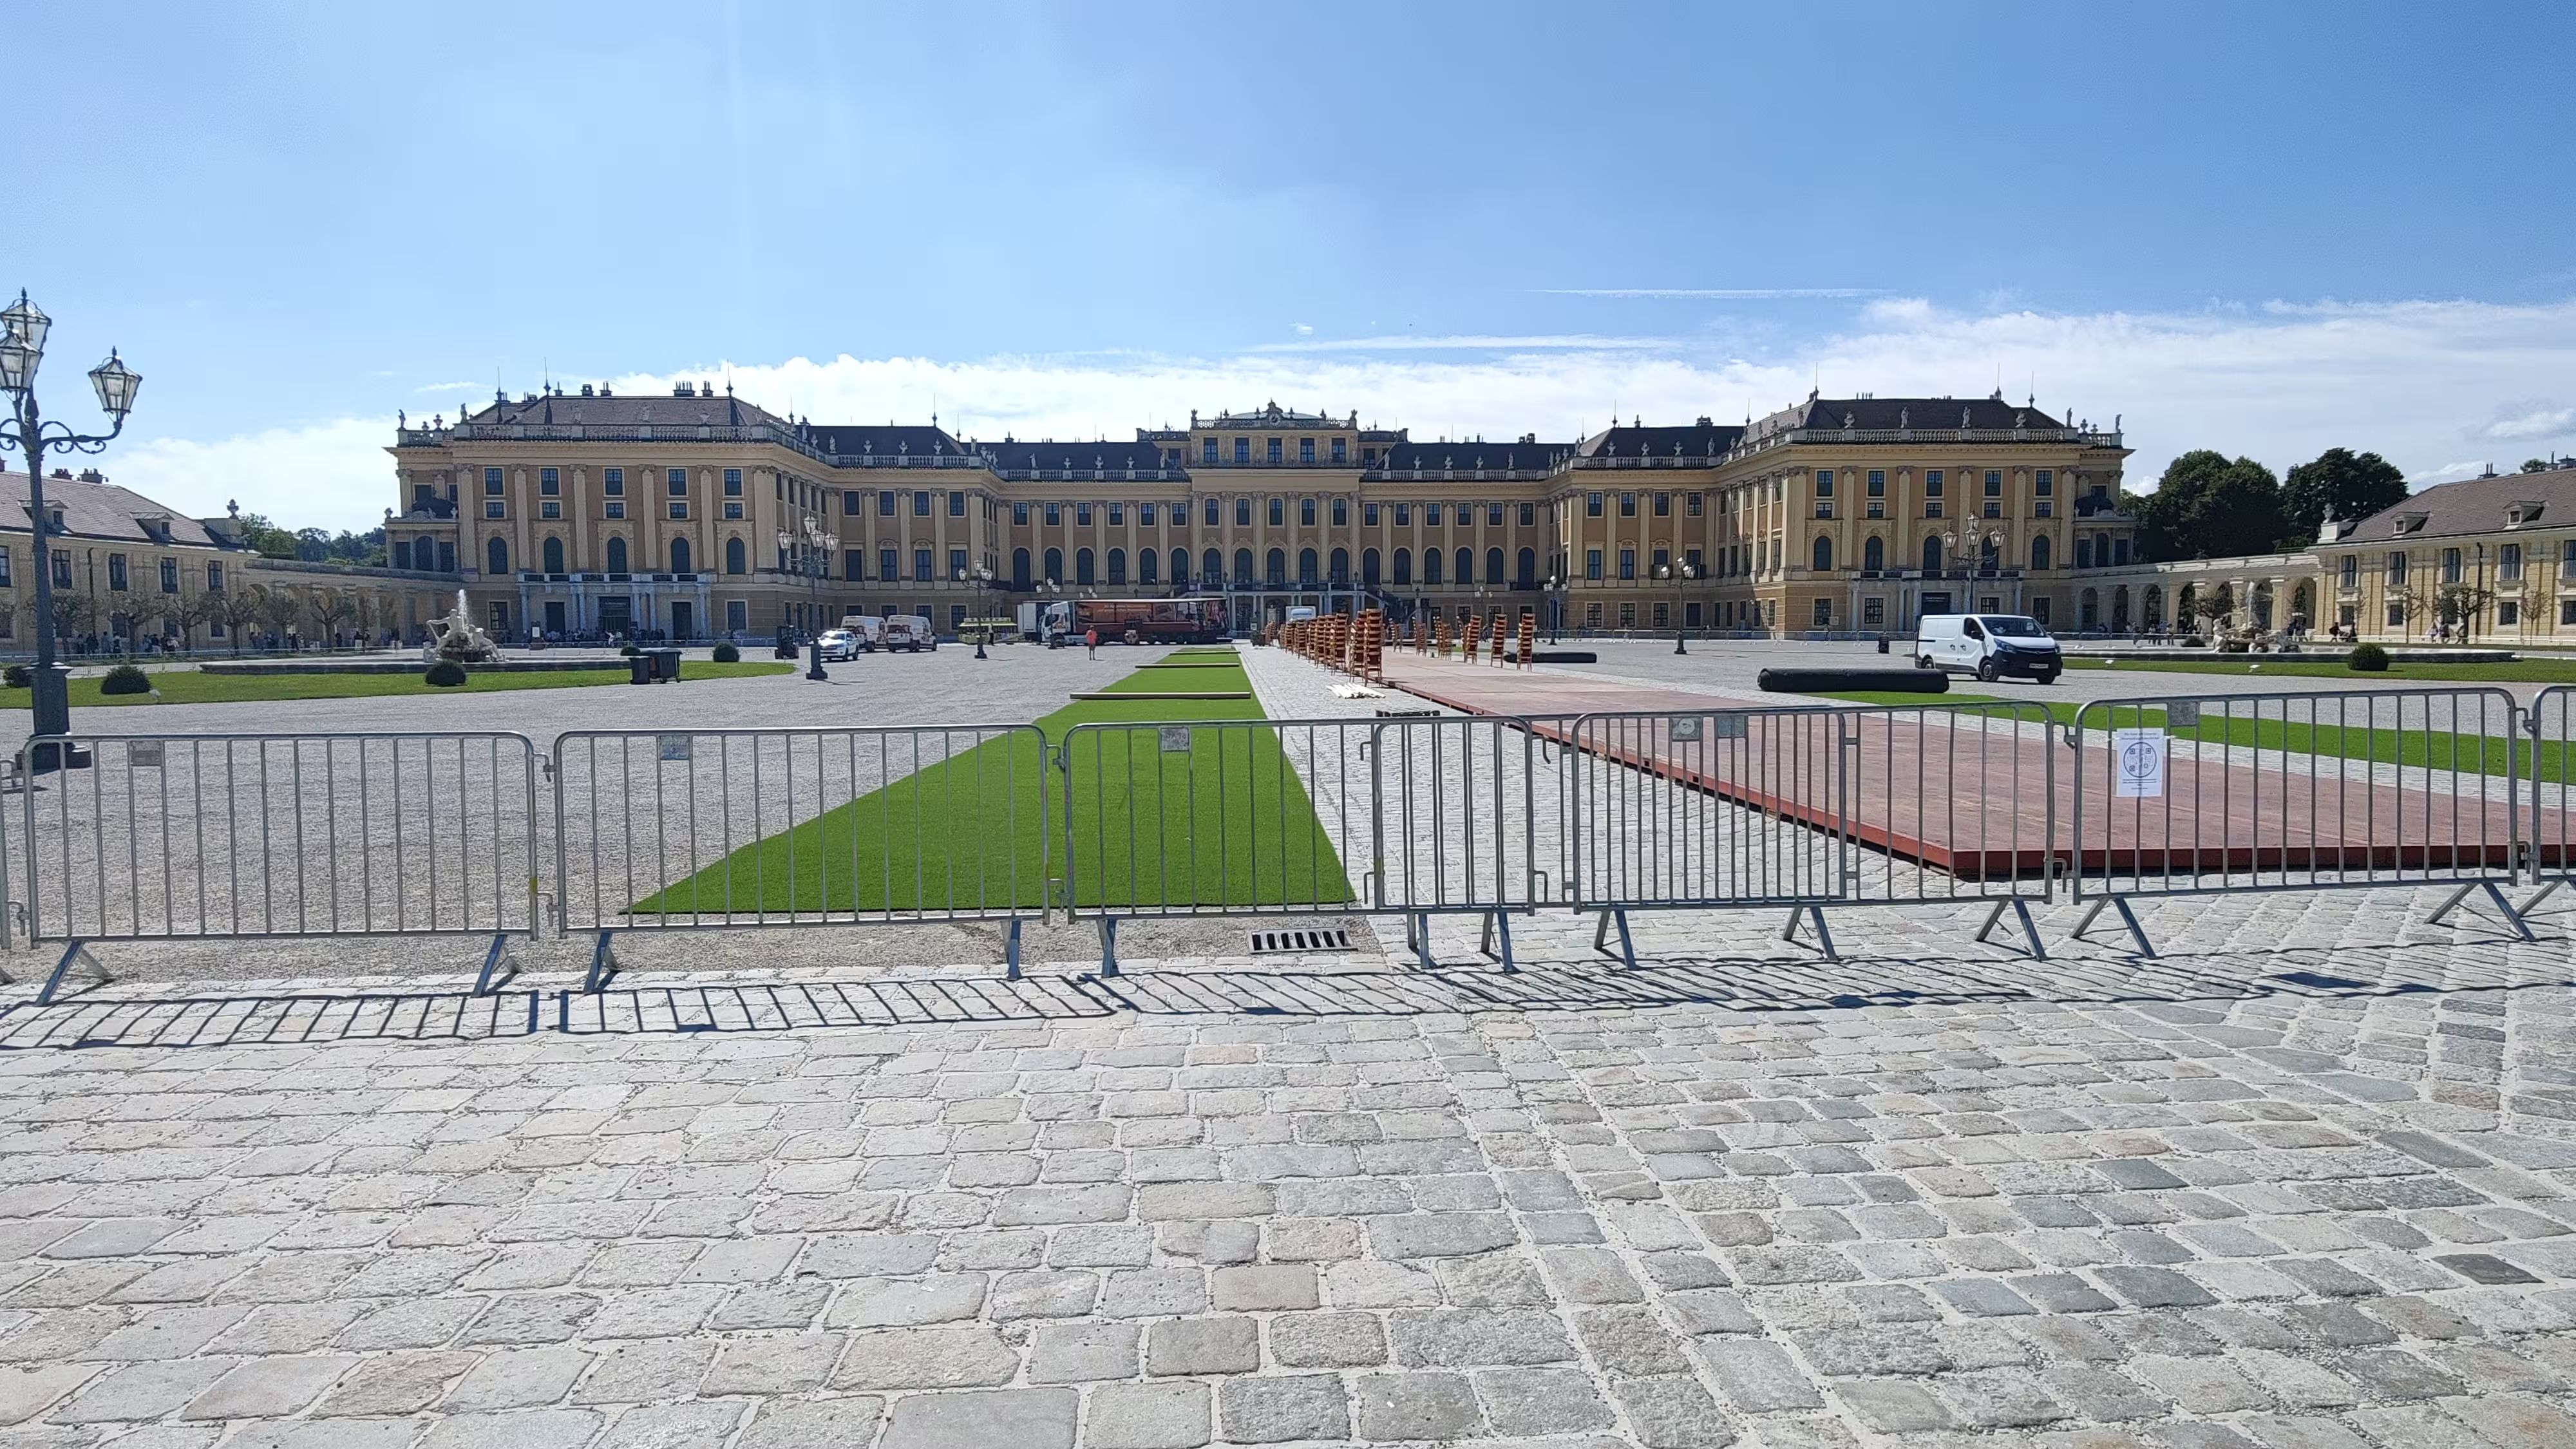 Sch nbrunn Palace. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
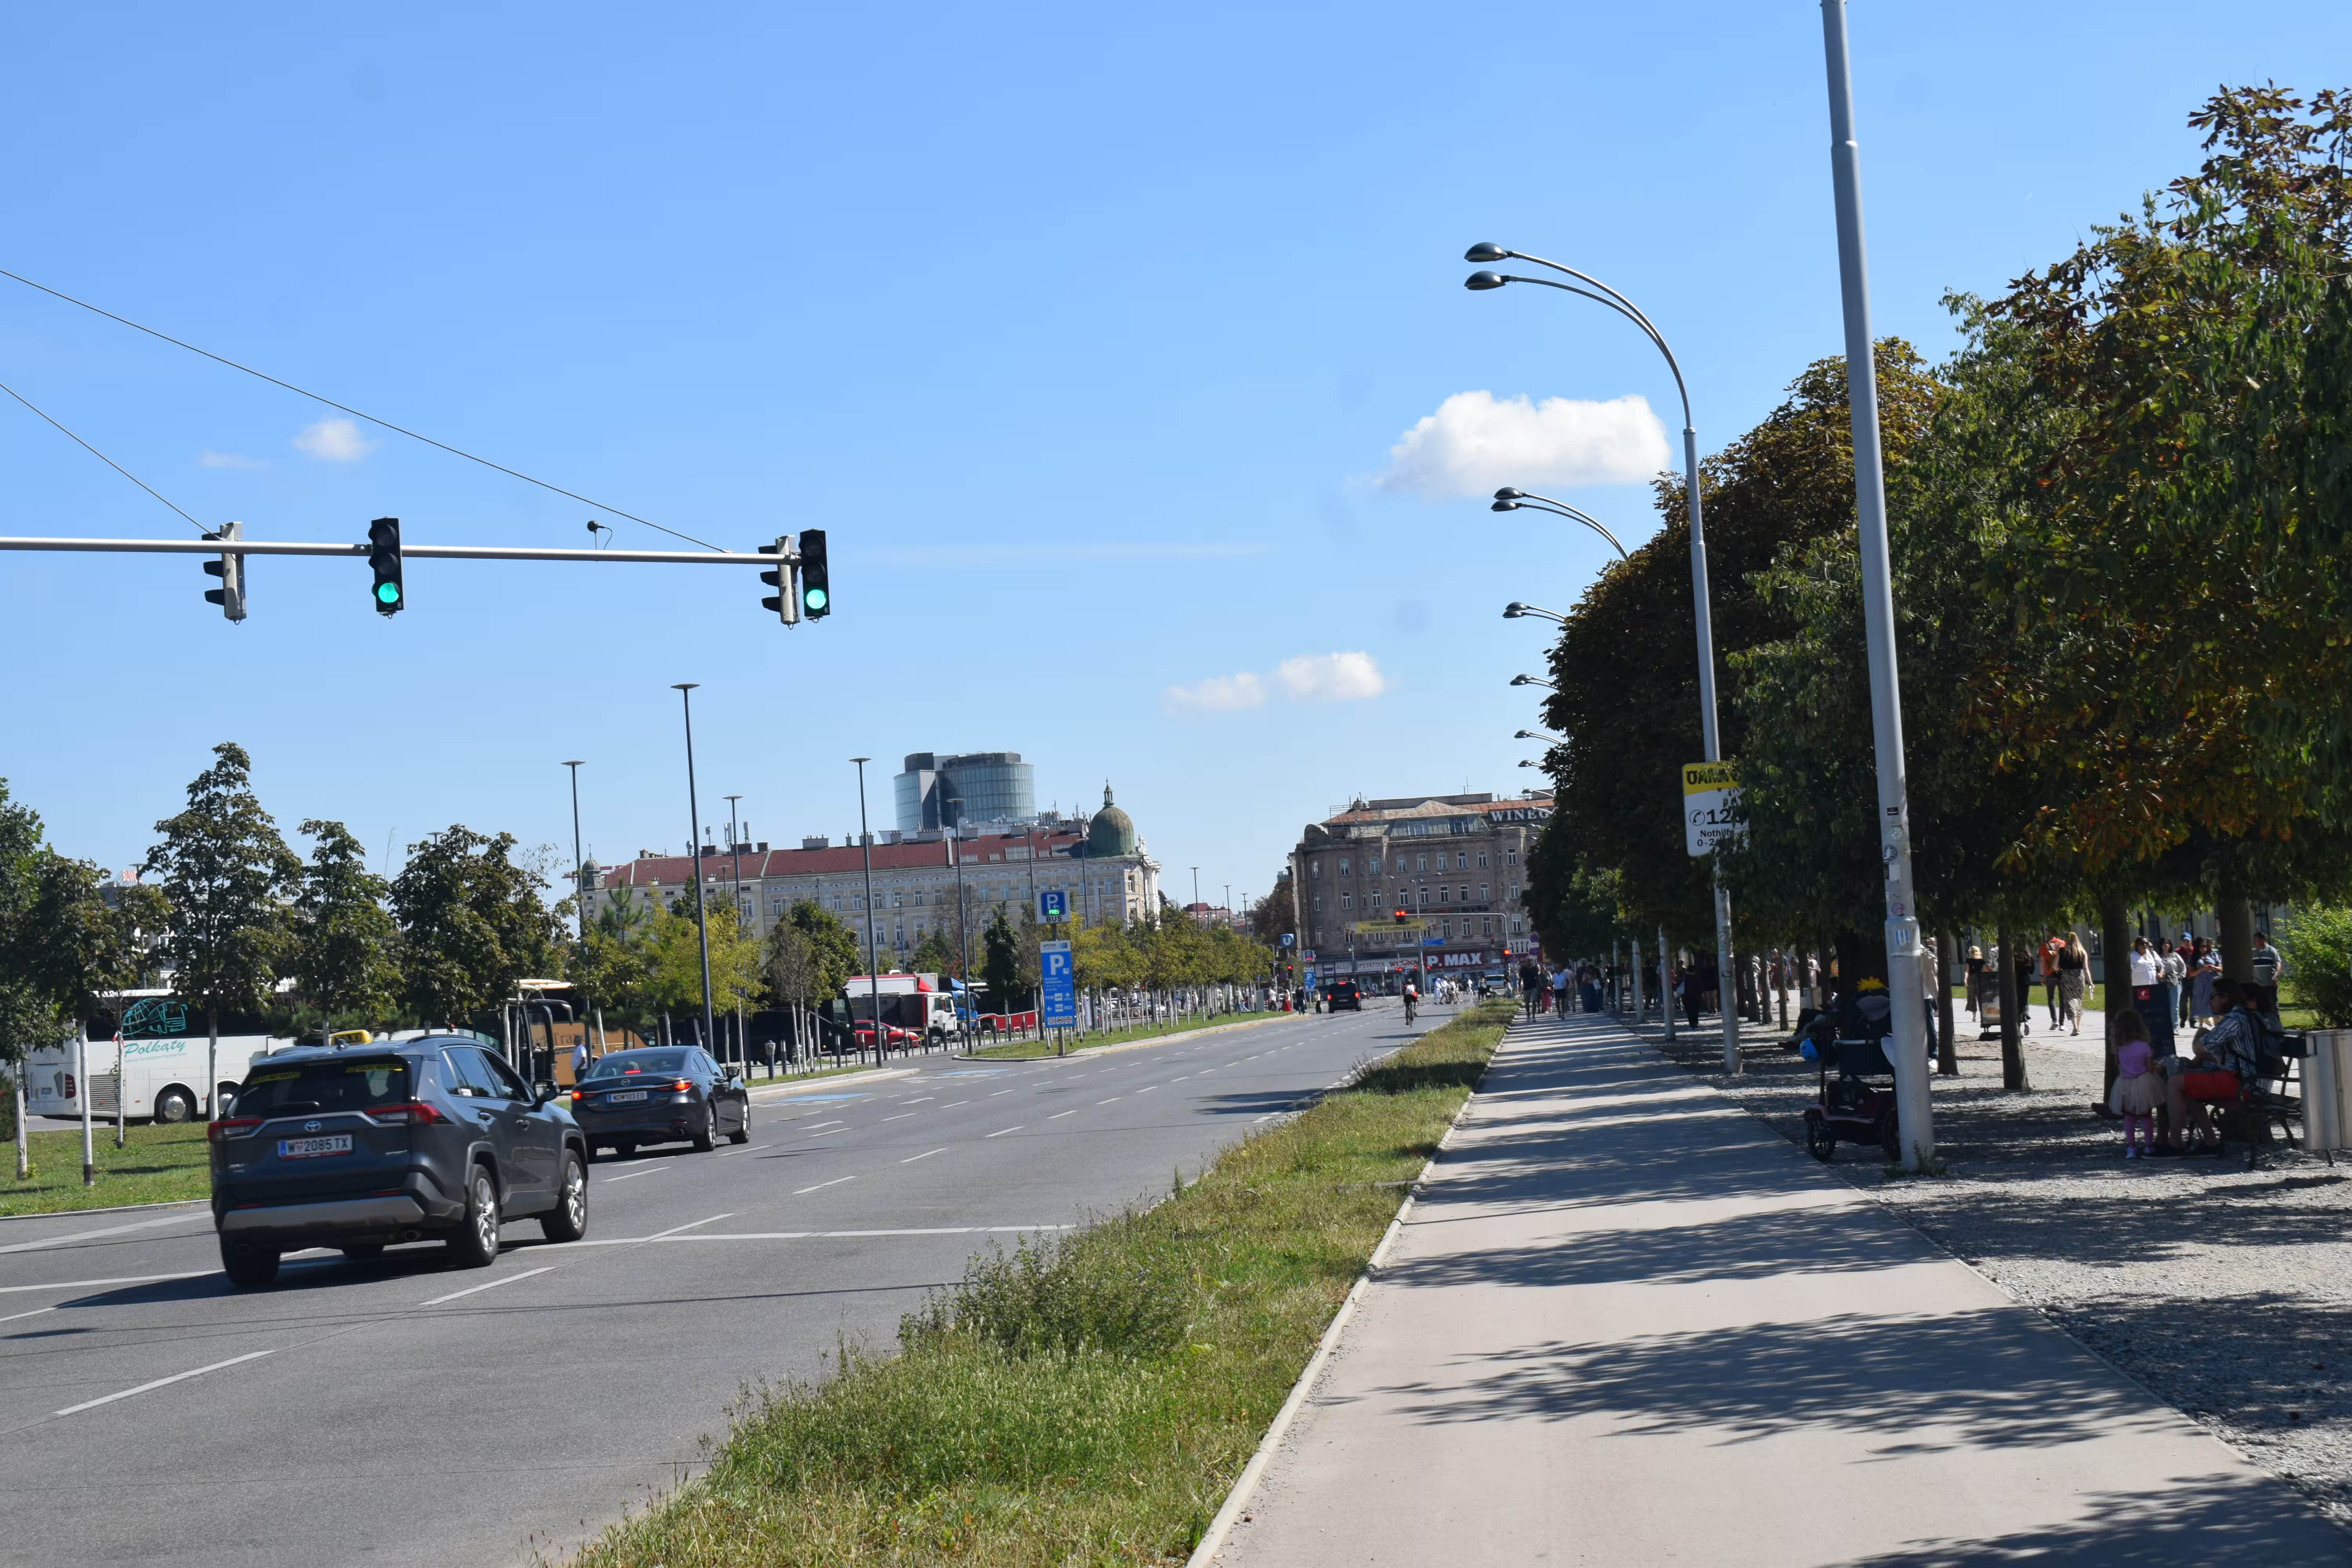 A street near Sch nbrunn Palace. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
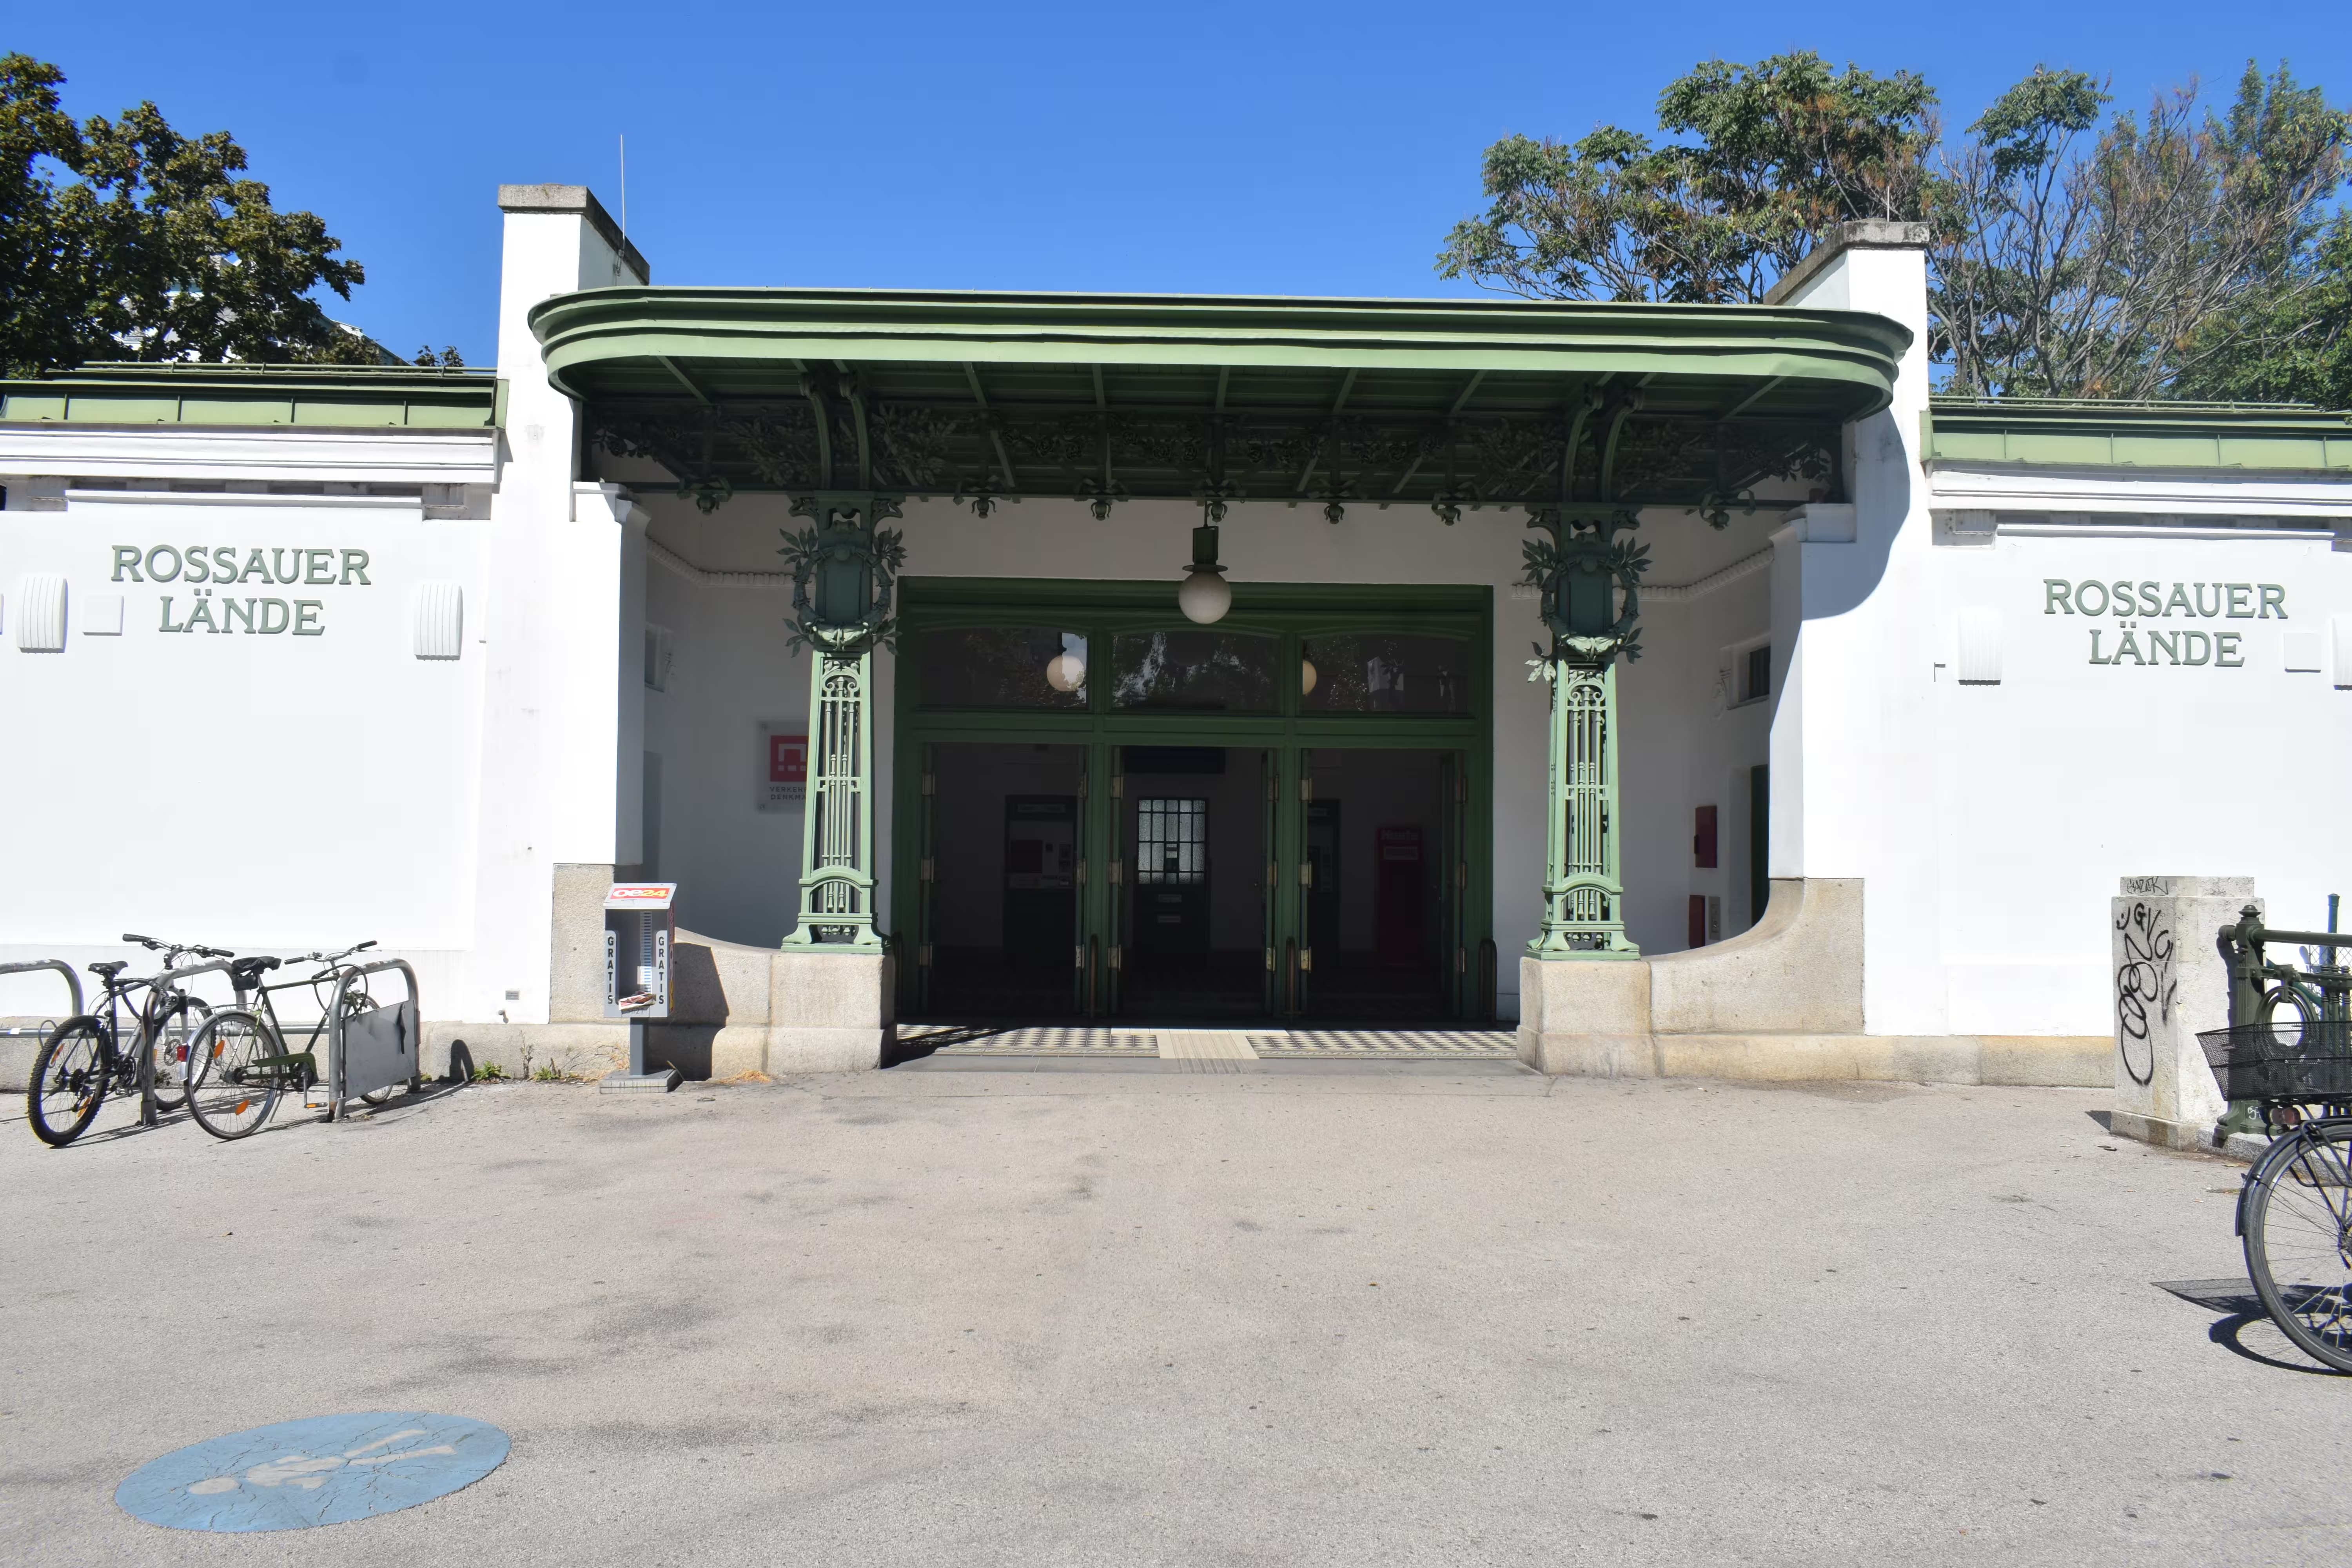 Ro auer L nde subway station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
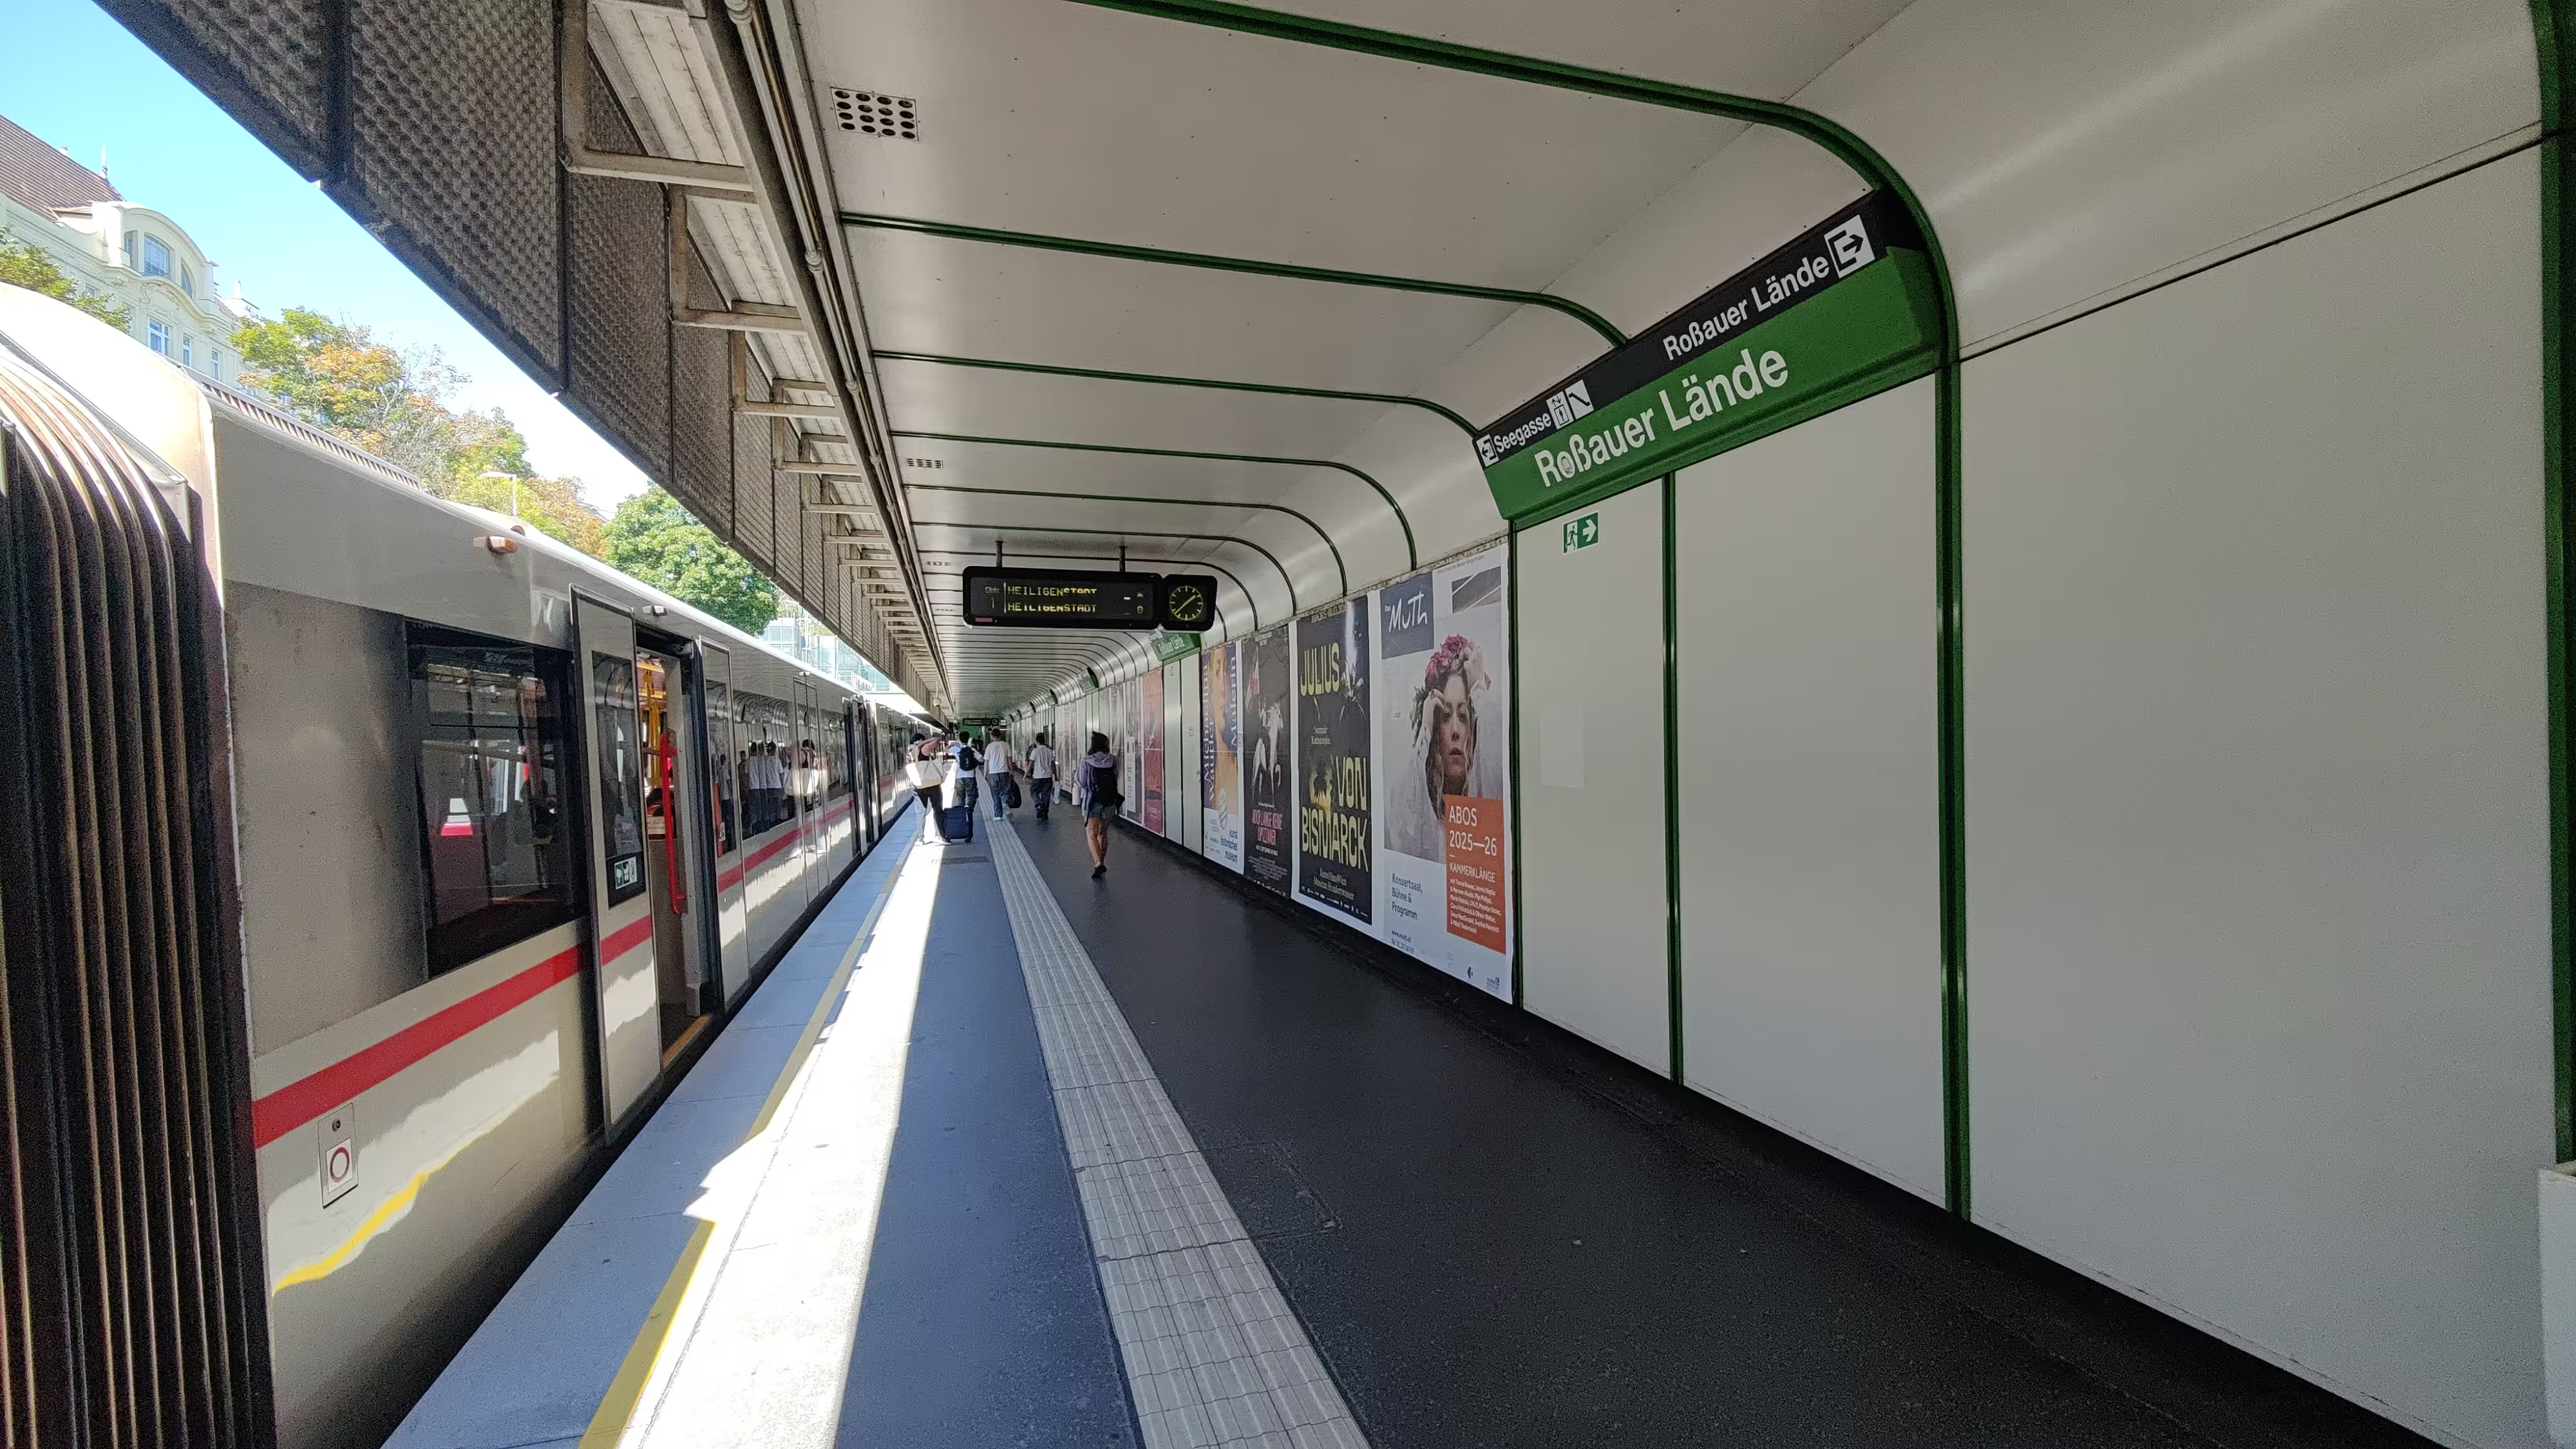 Platform of the Ro auer L nde subway station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
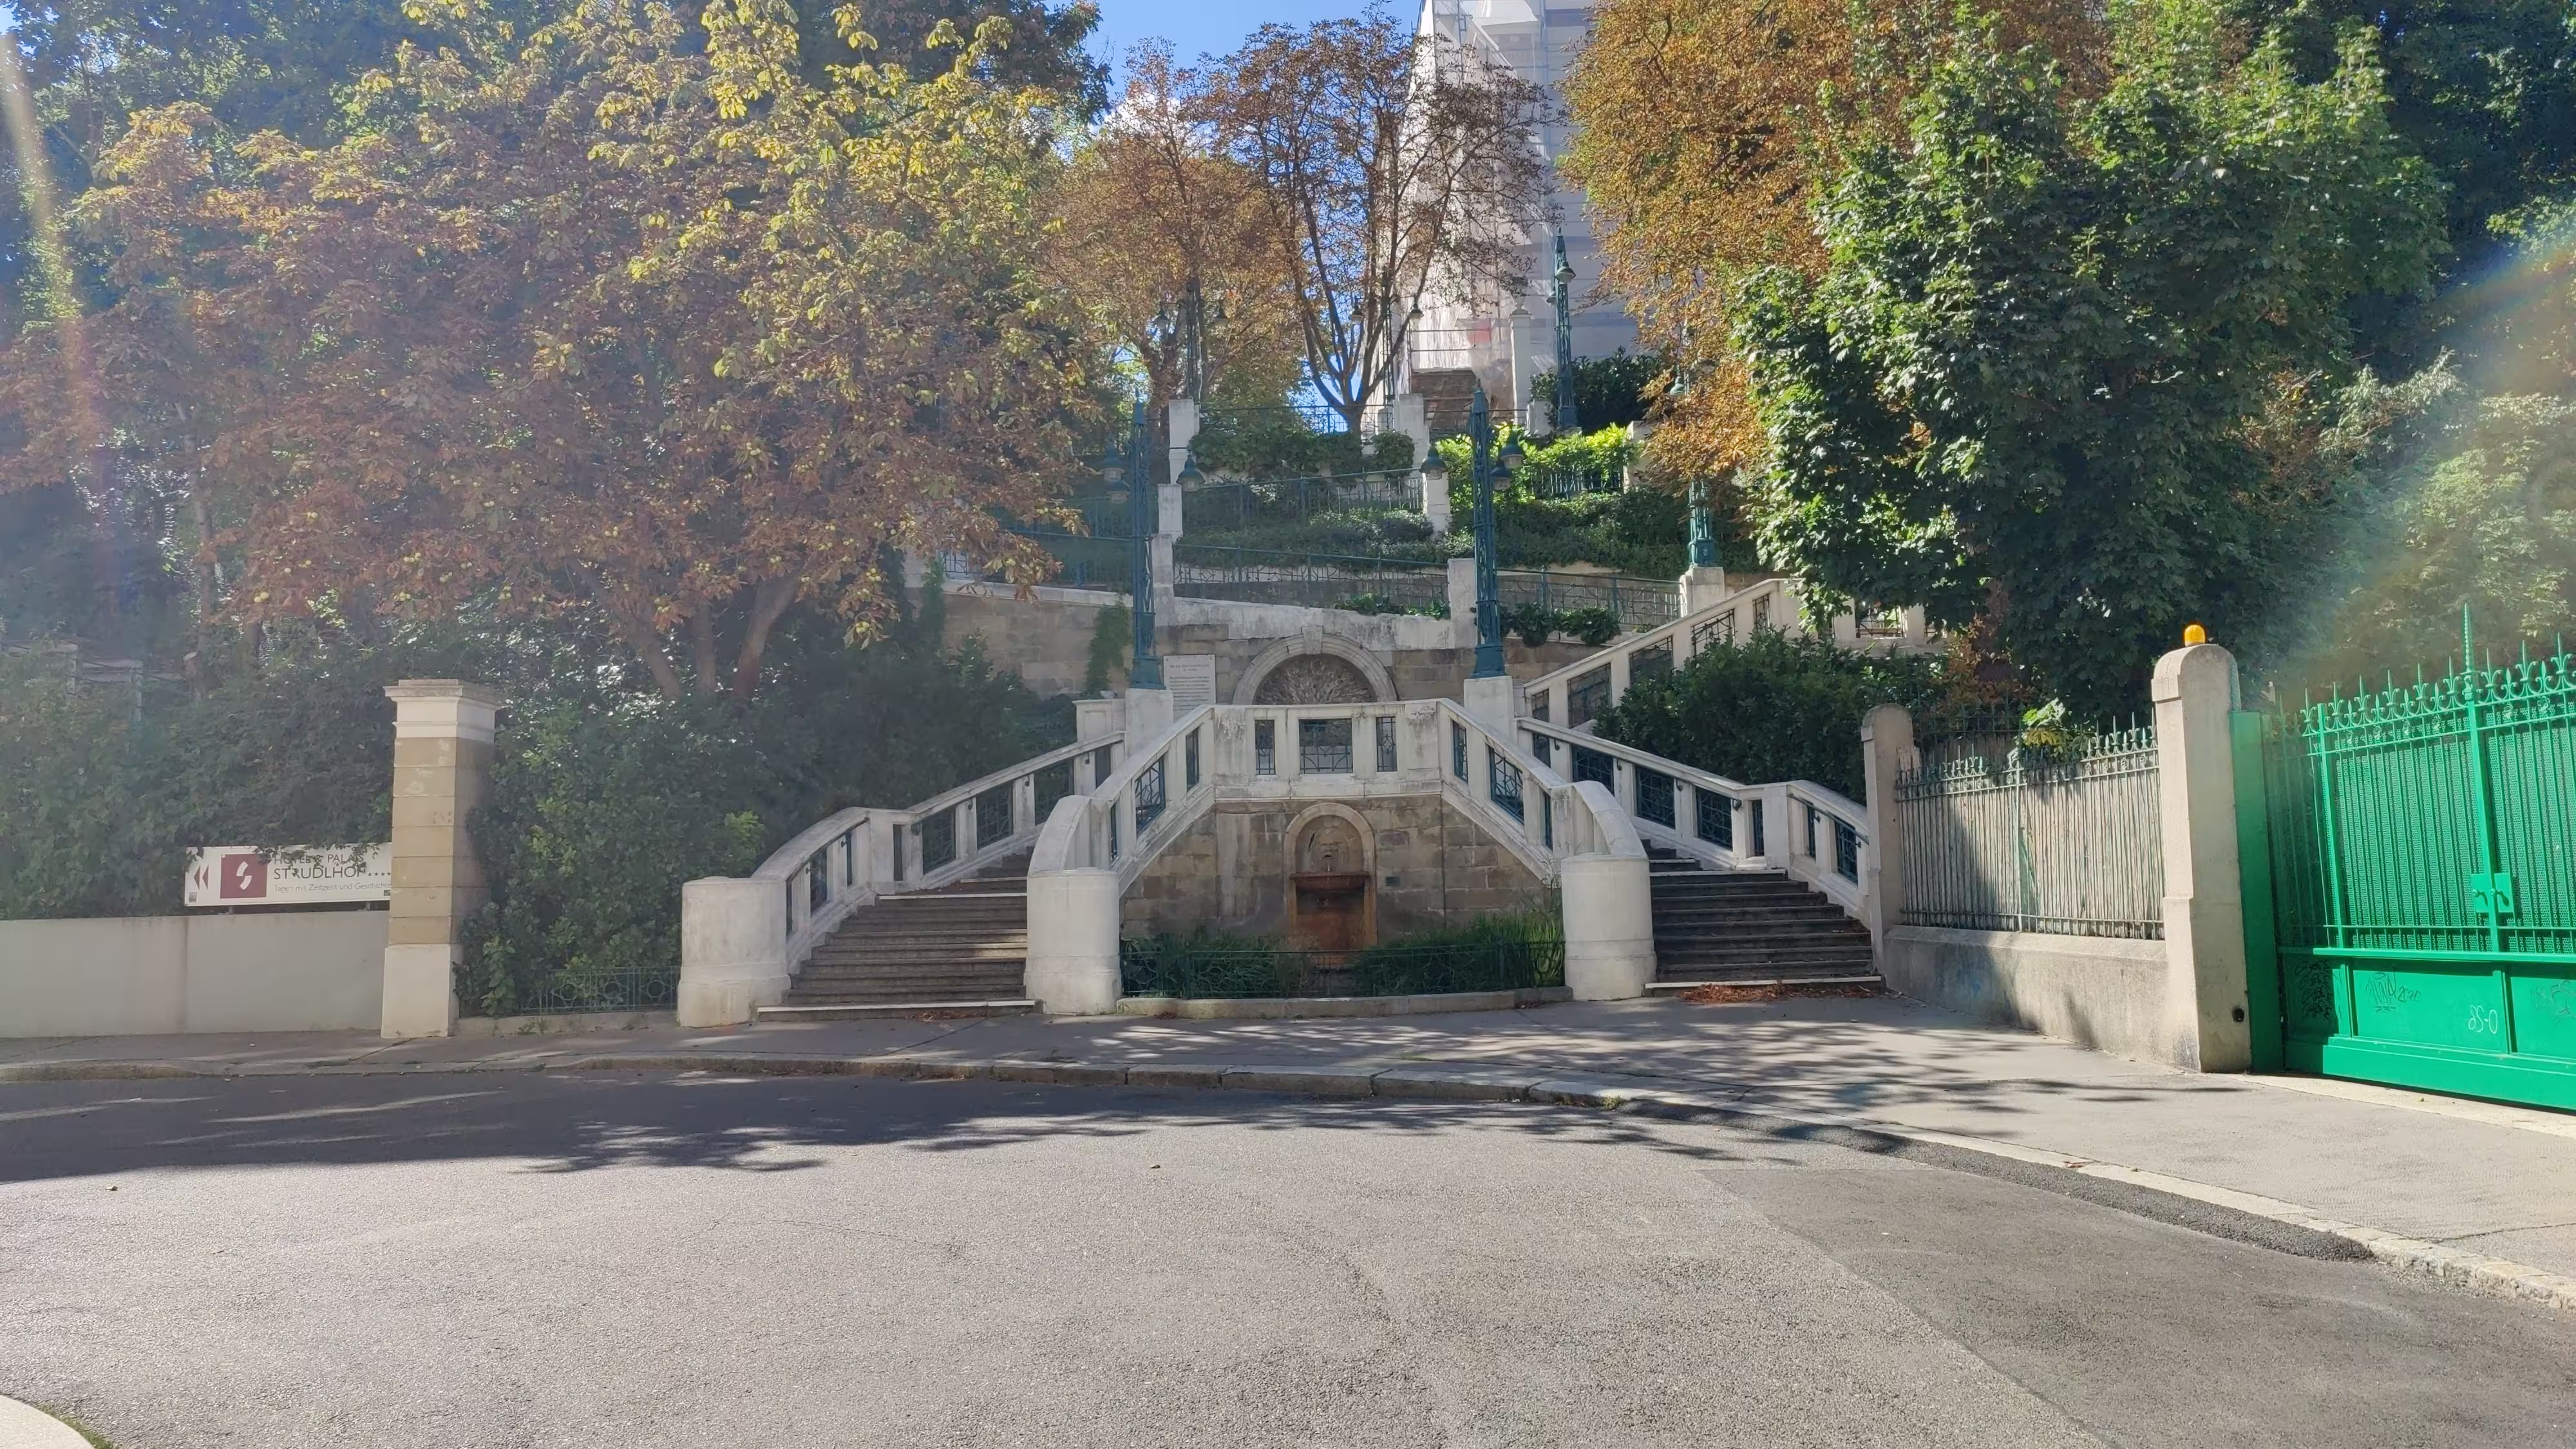 The The Strudlhofstiege steps. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
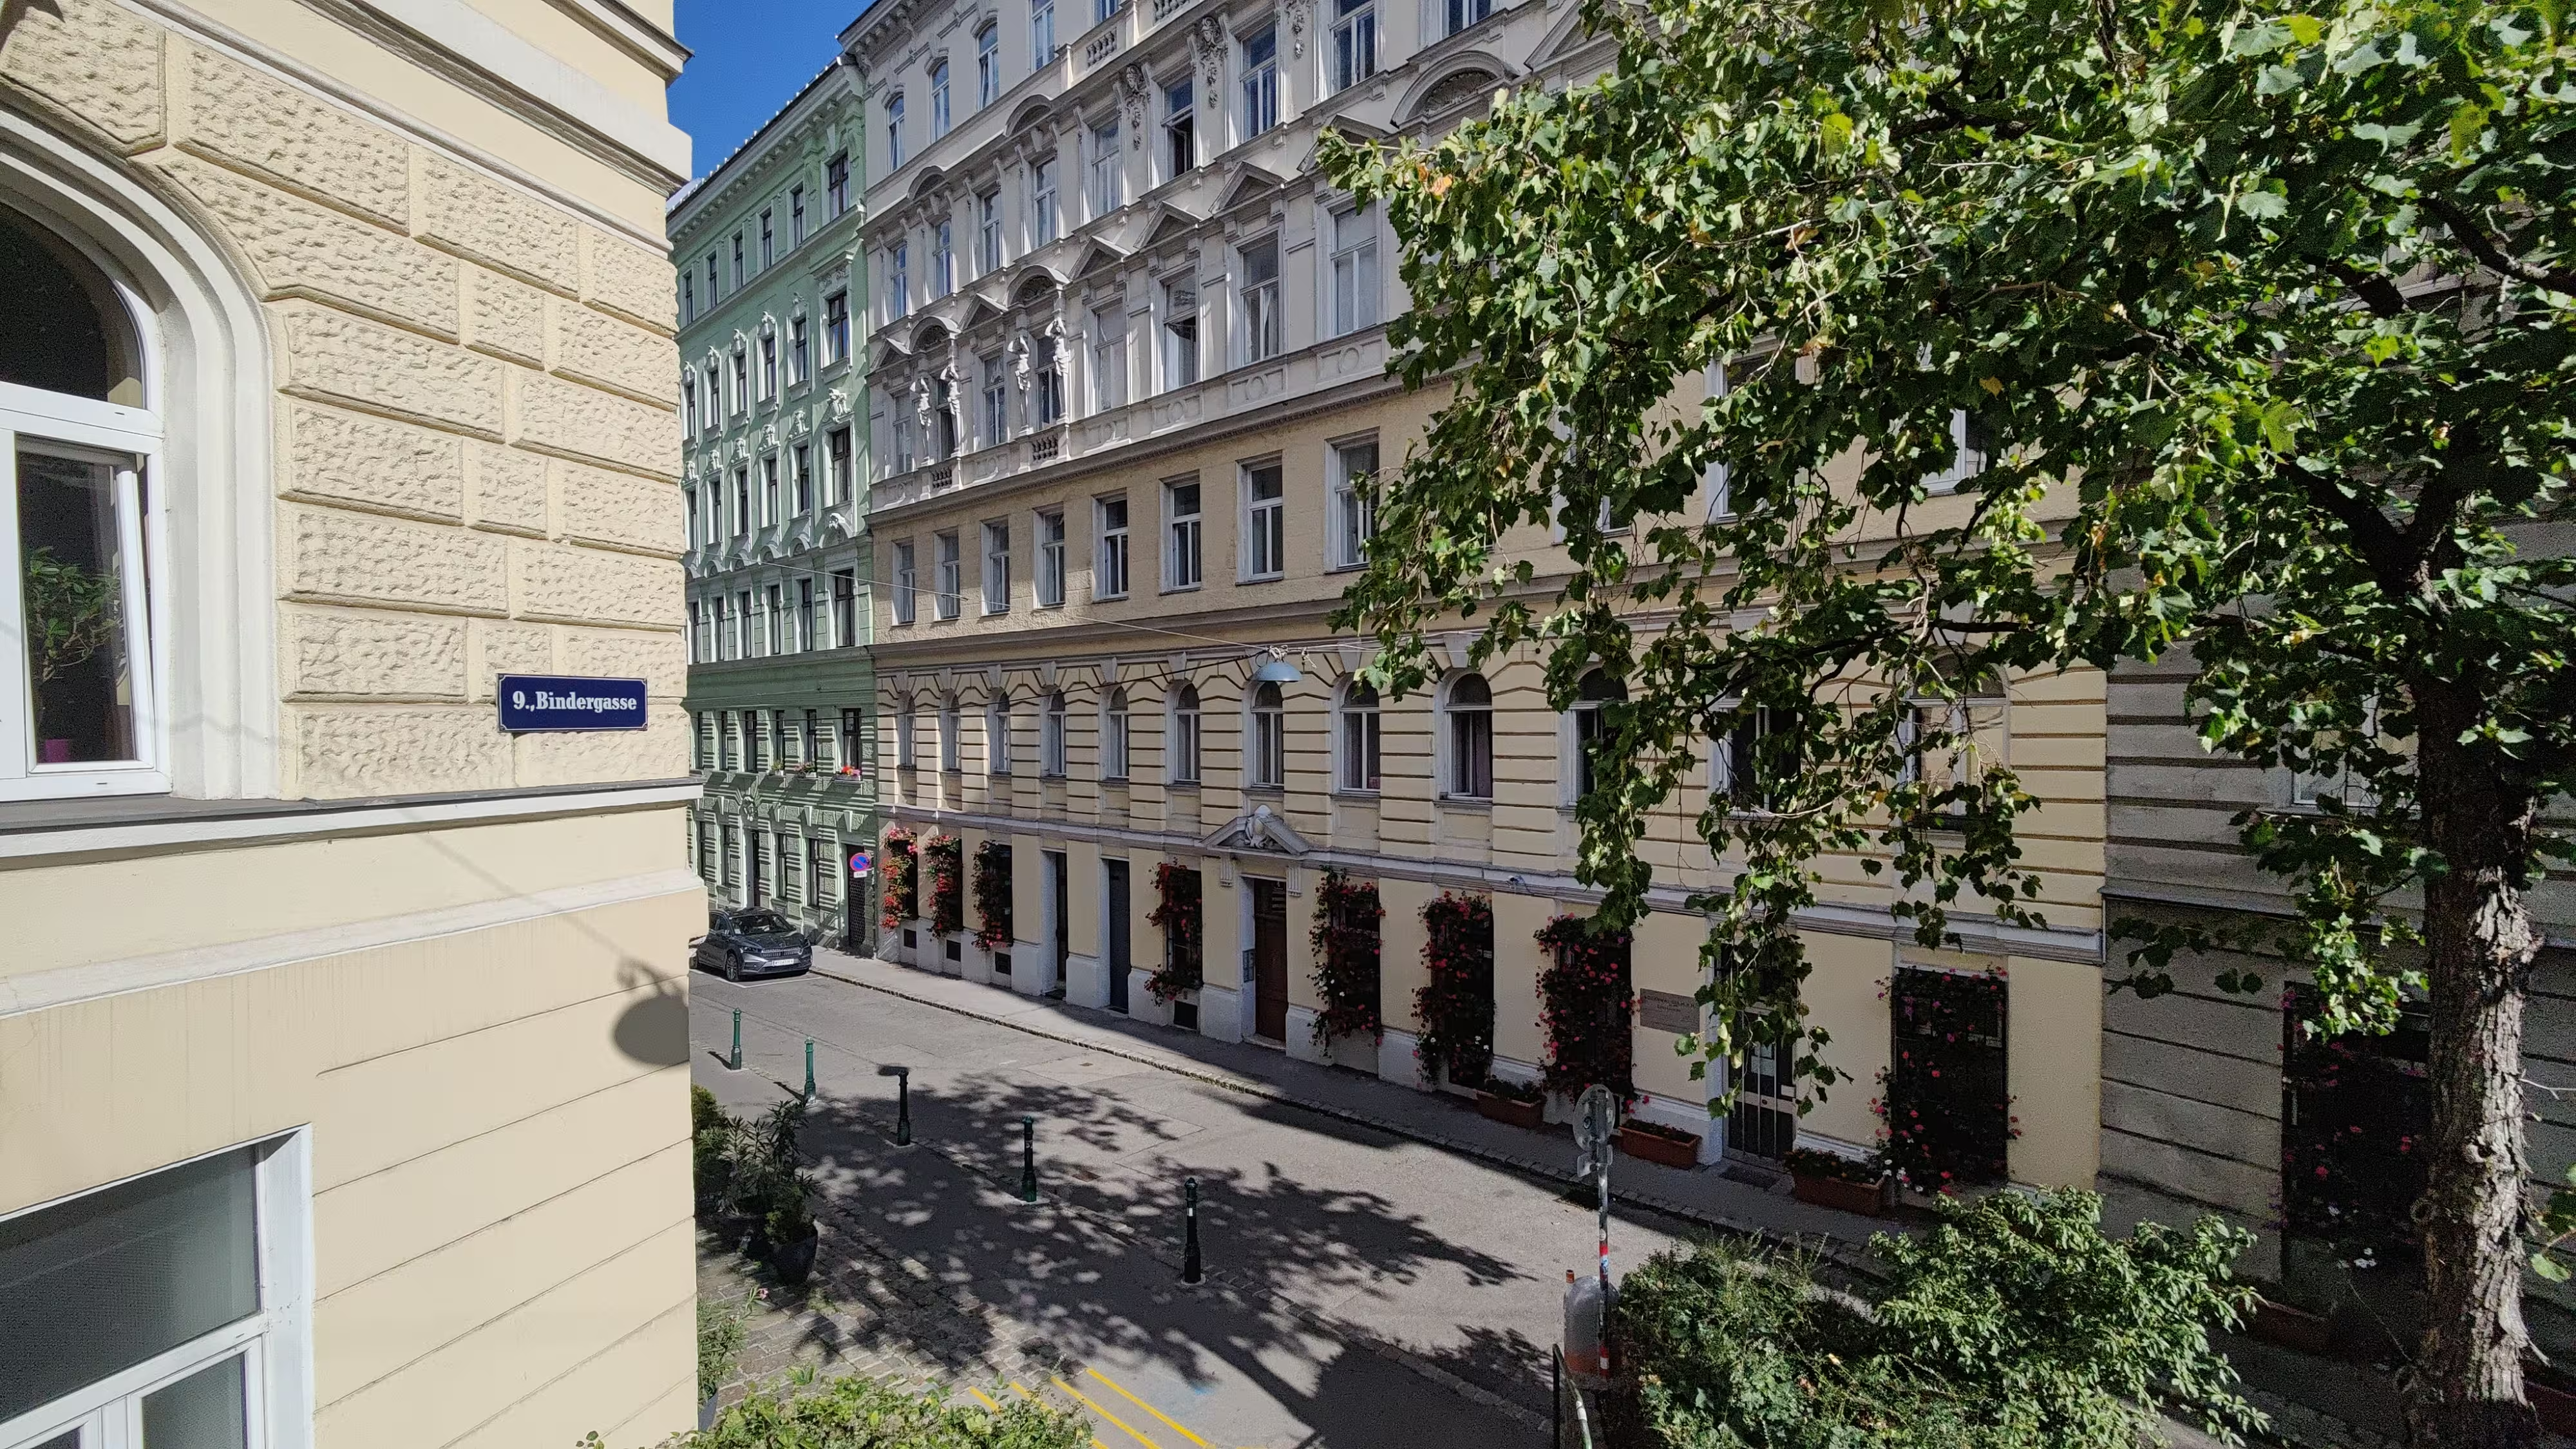 A random street in Vienna.
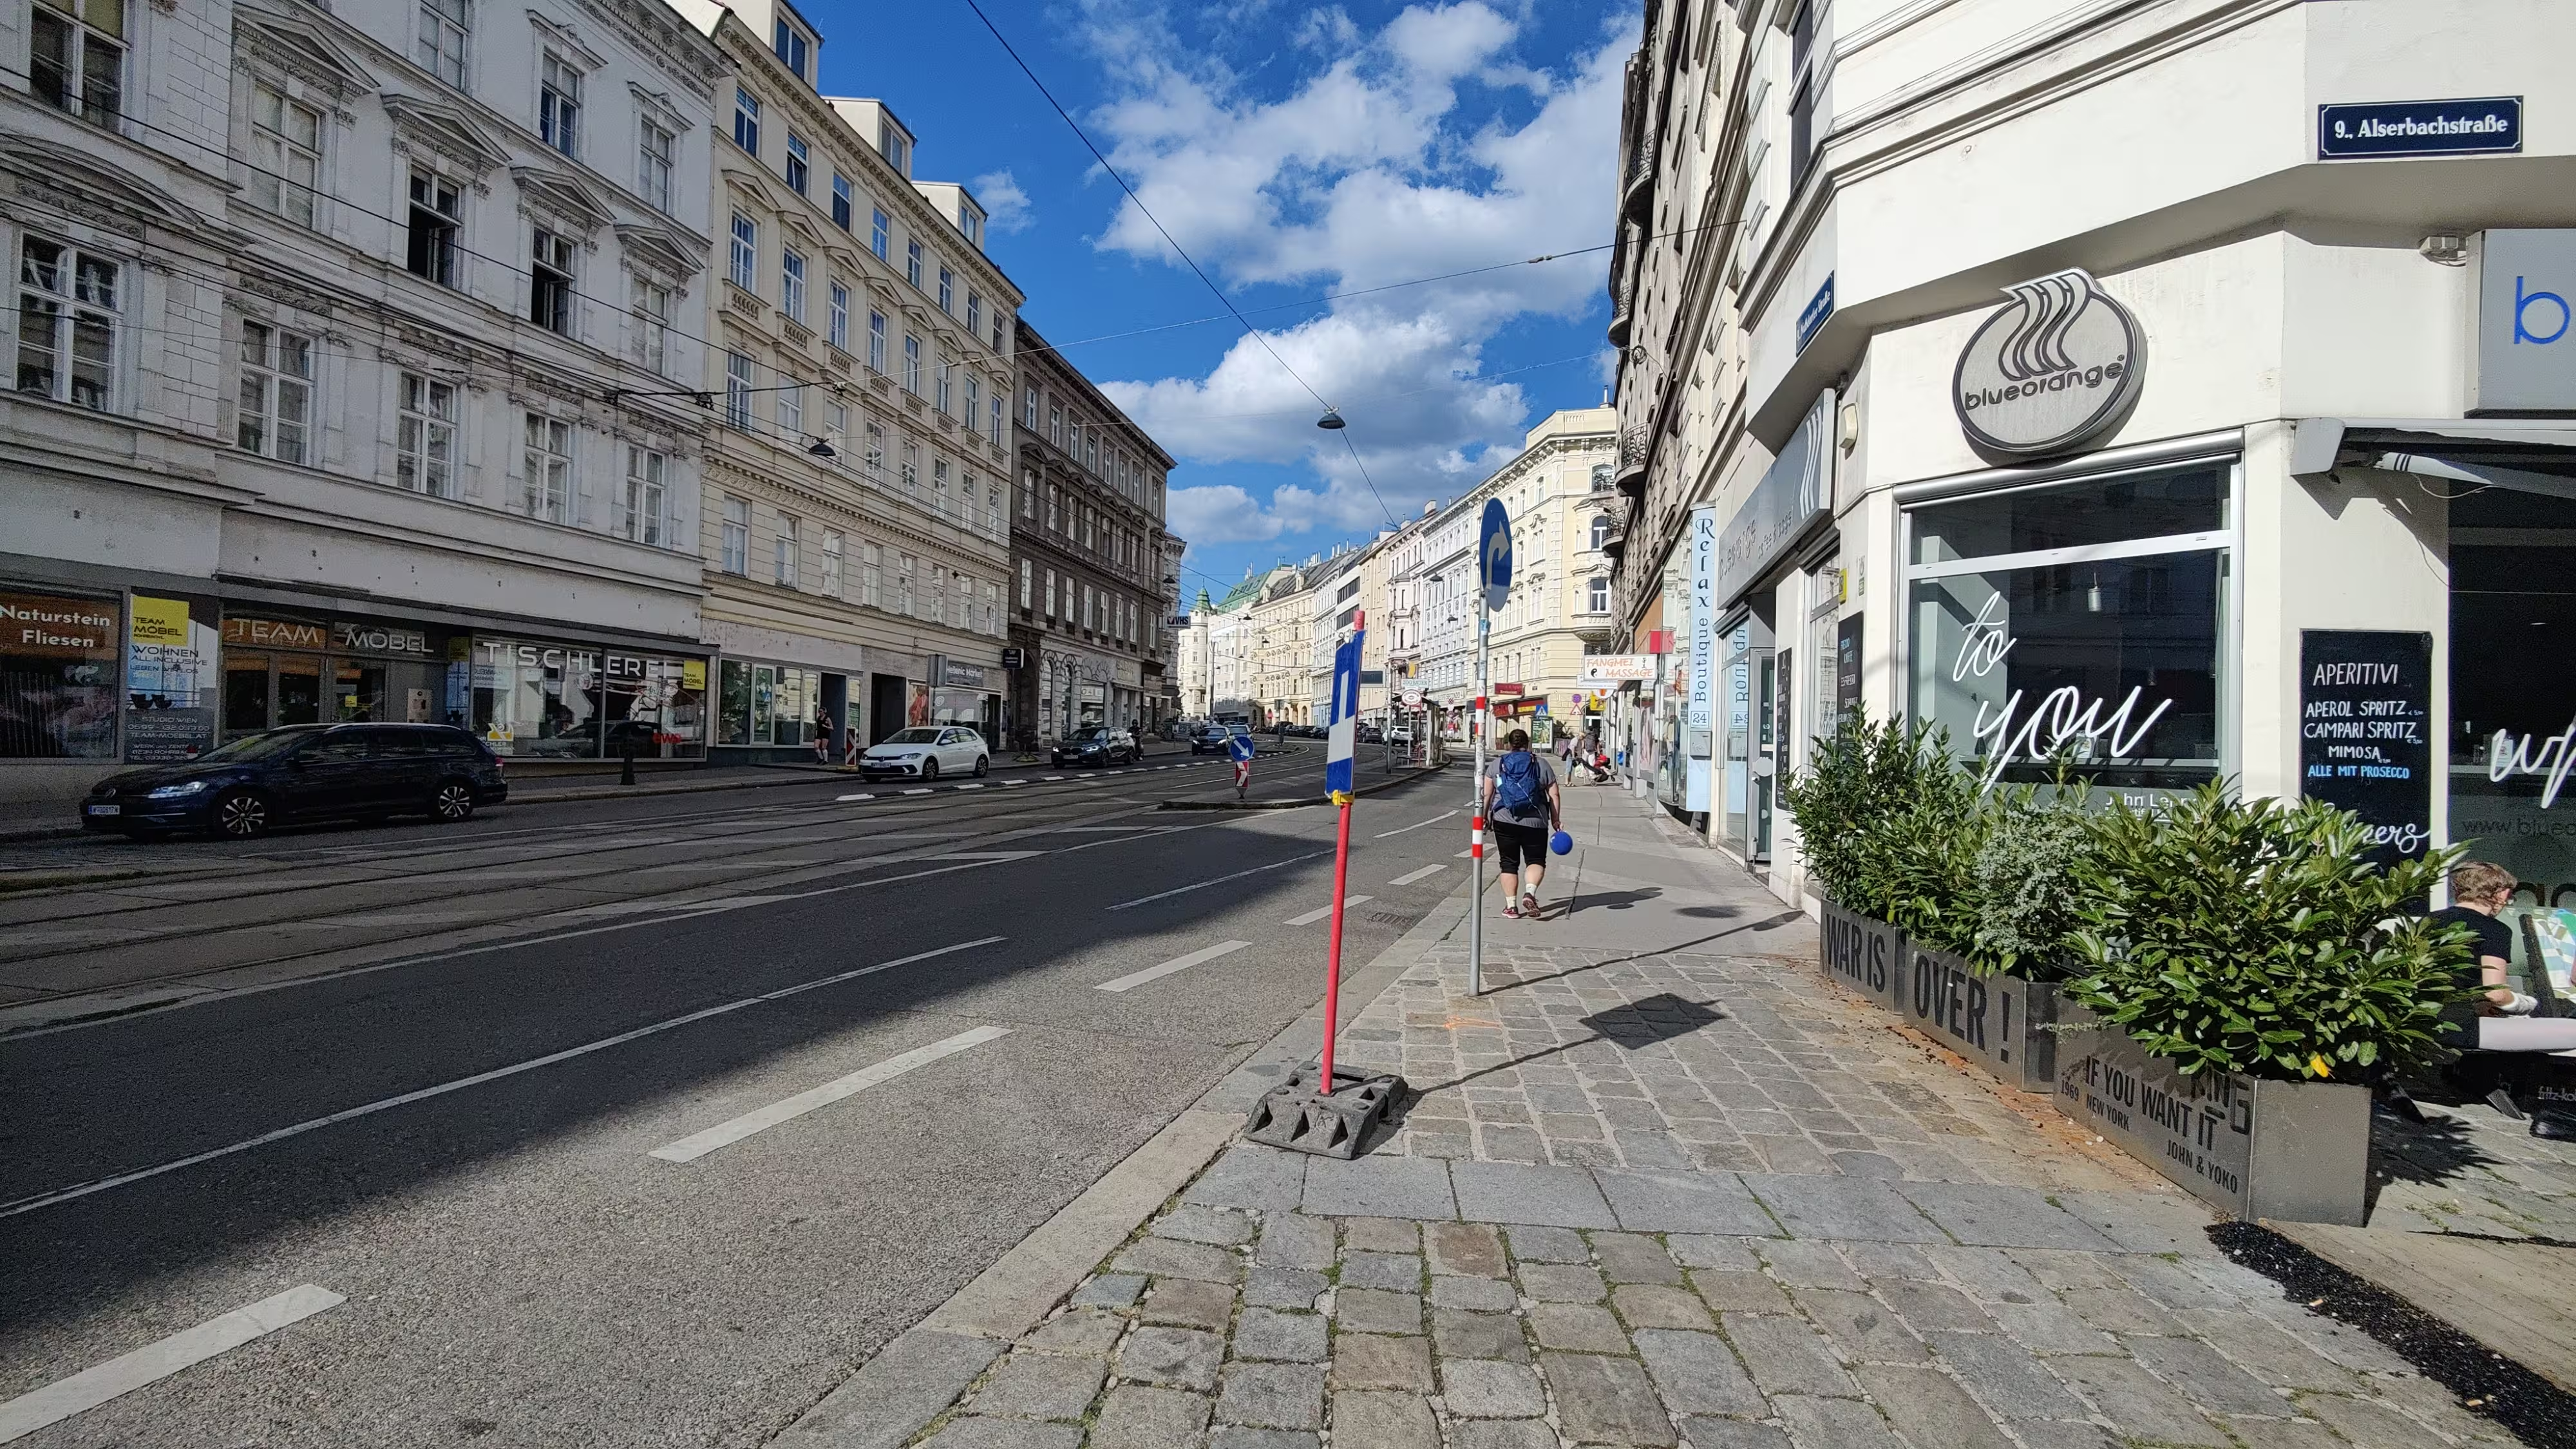 Another street in Vienna.
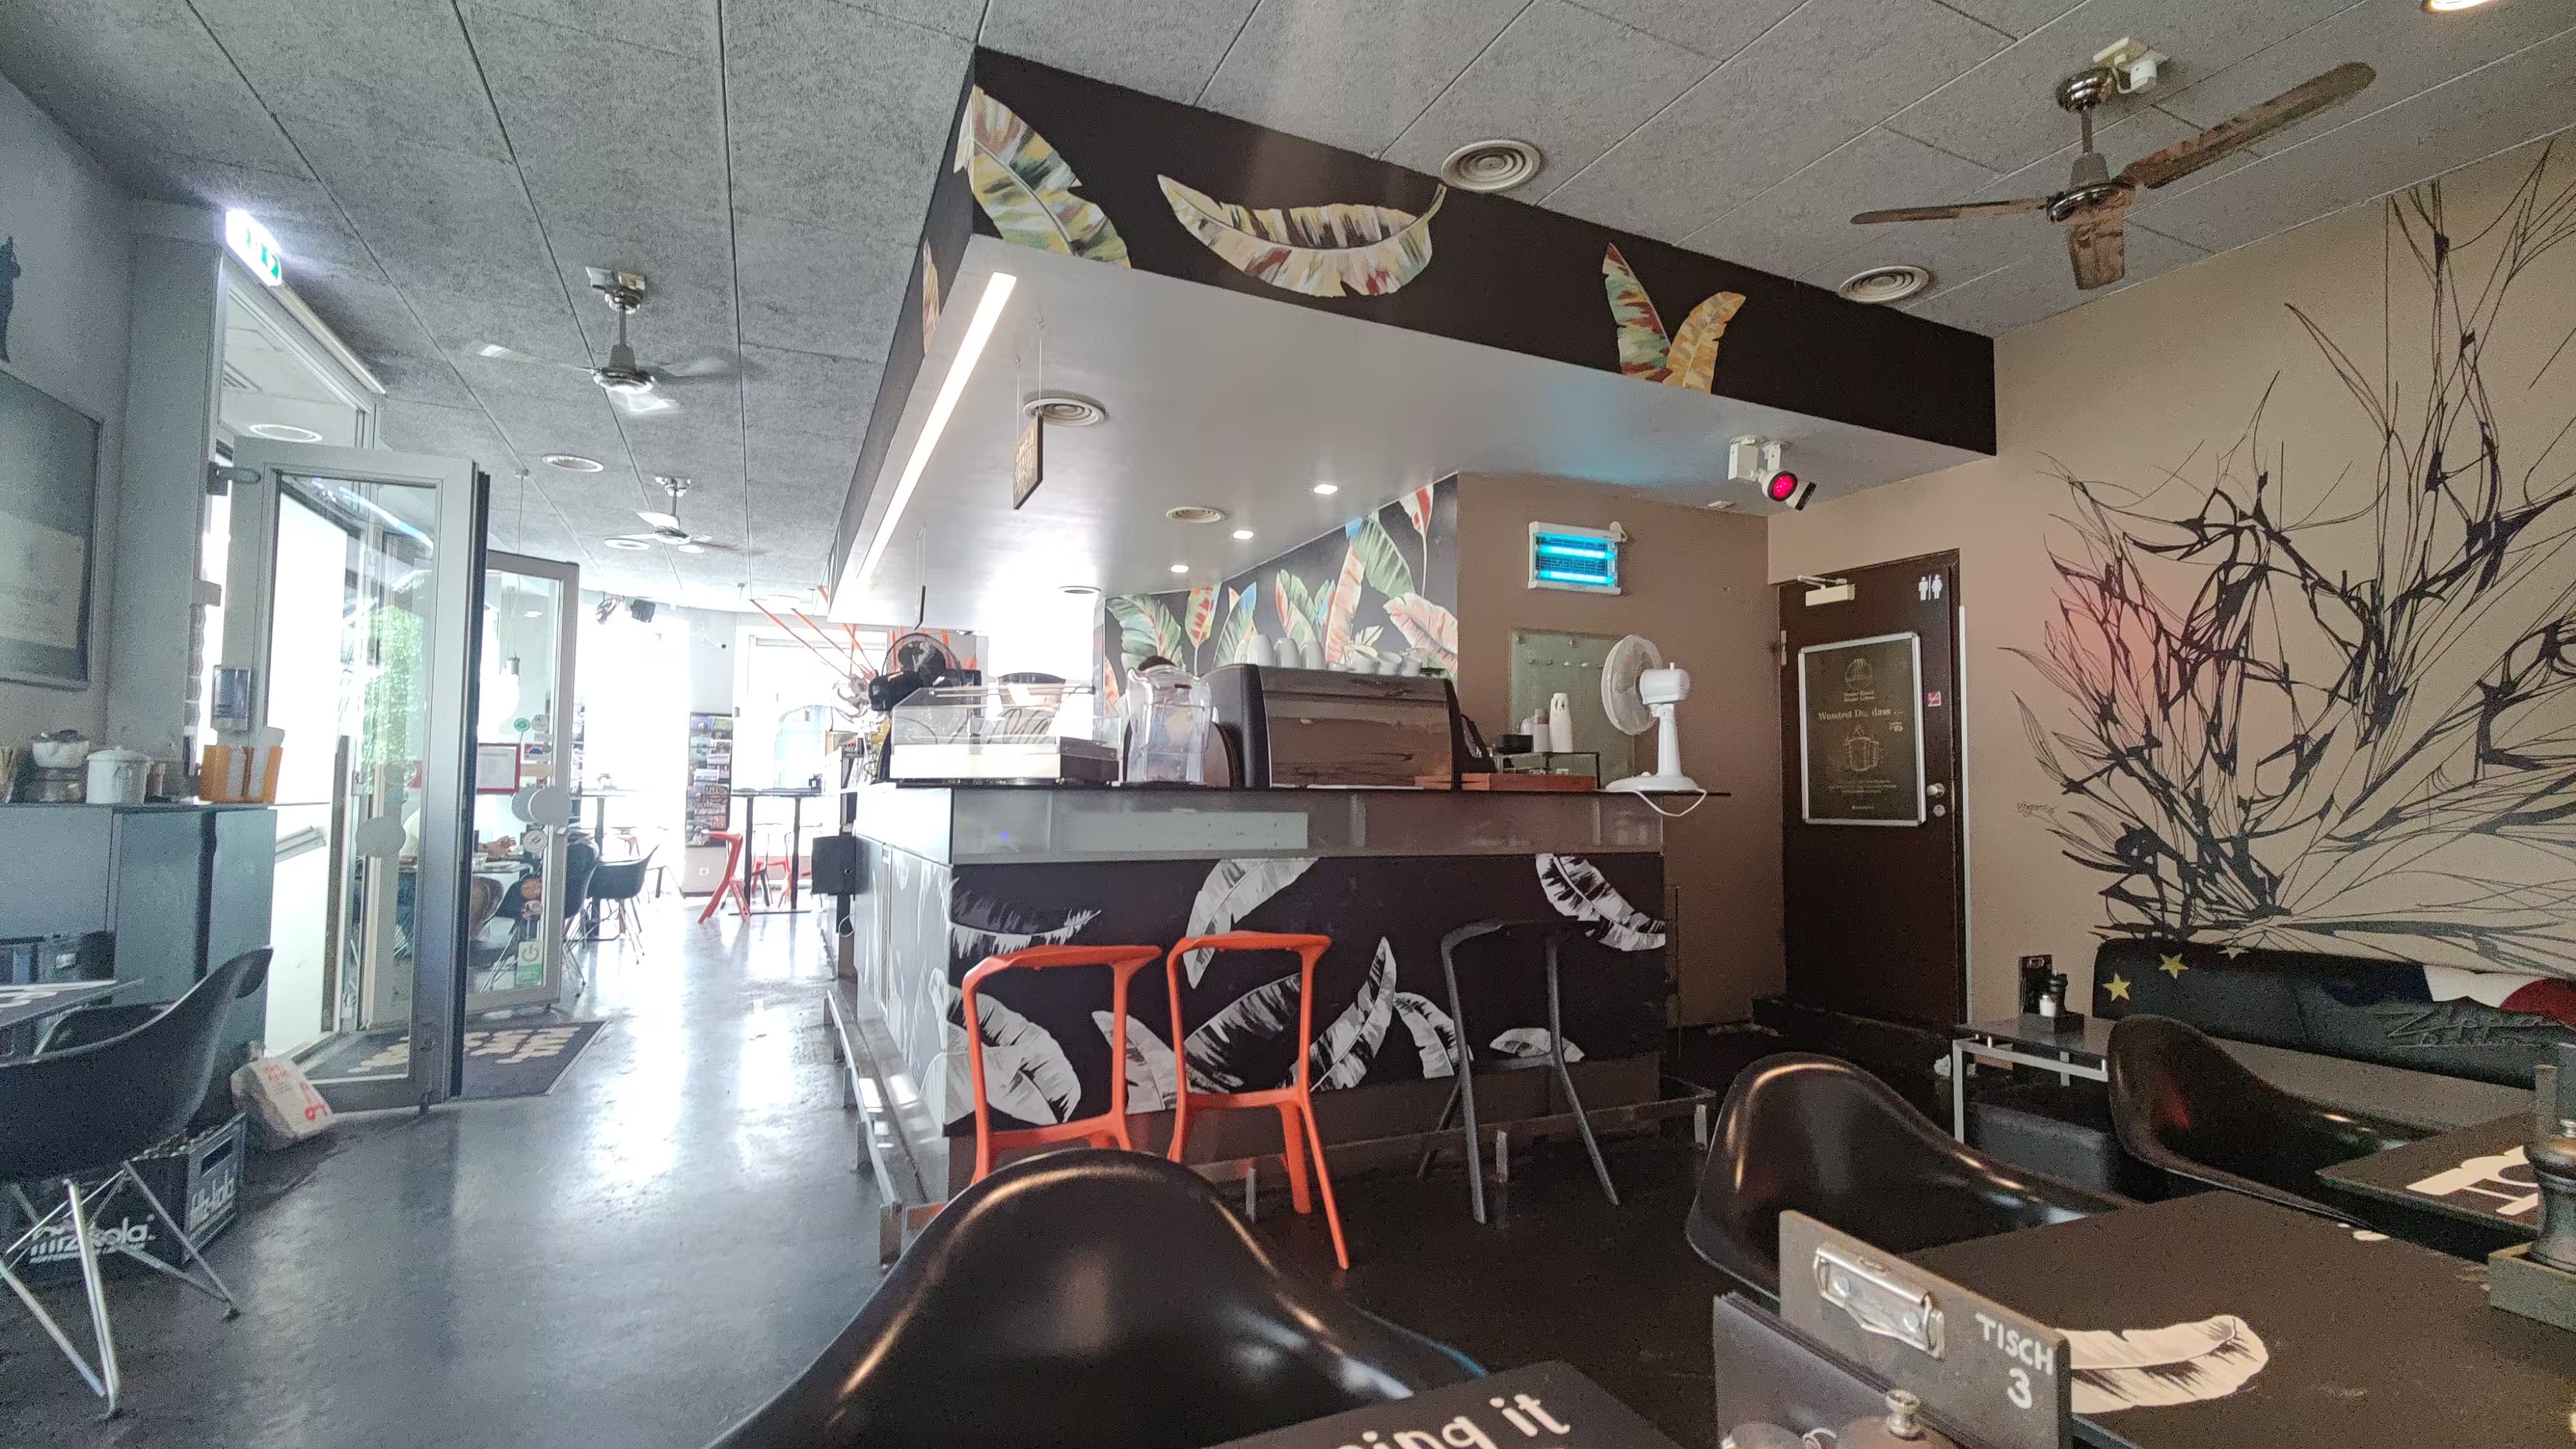 A picture of Blue Orange caf . Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
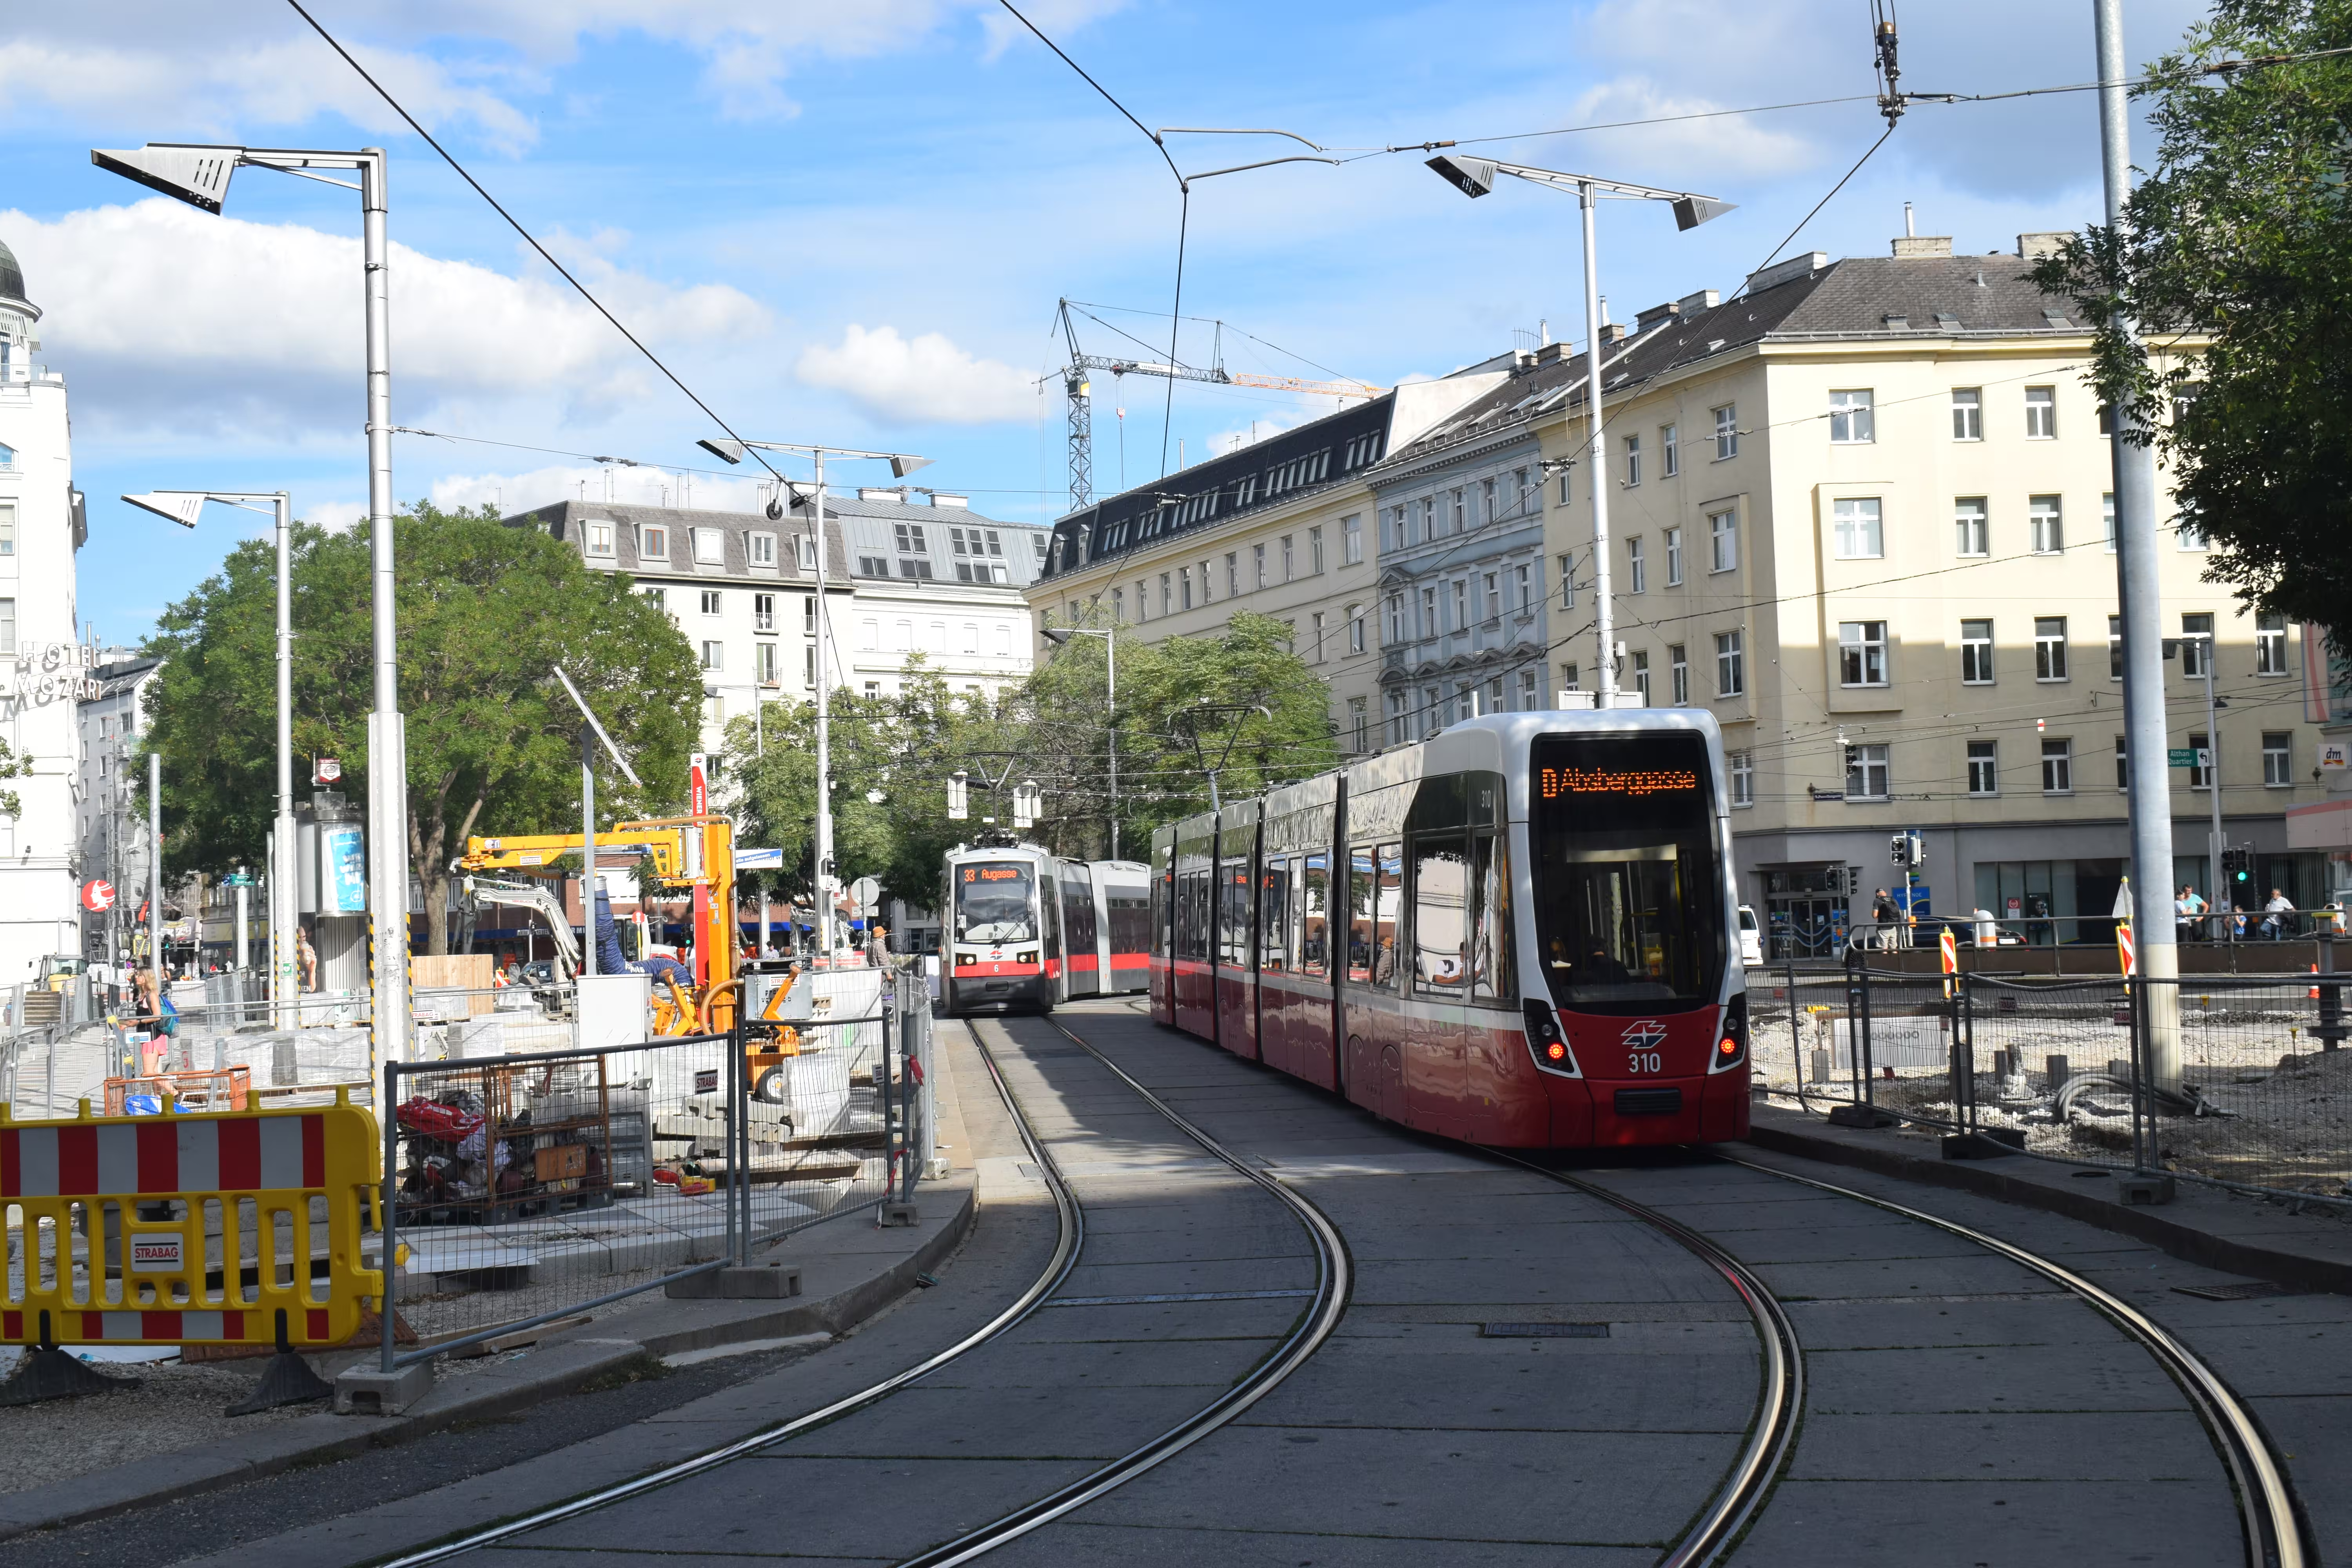 Trams in Vienna. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
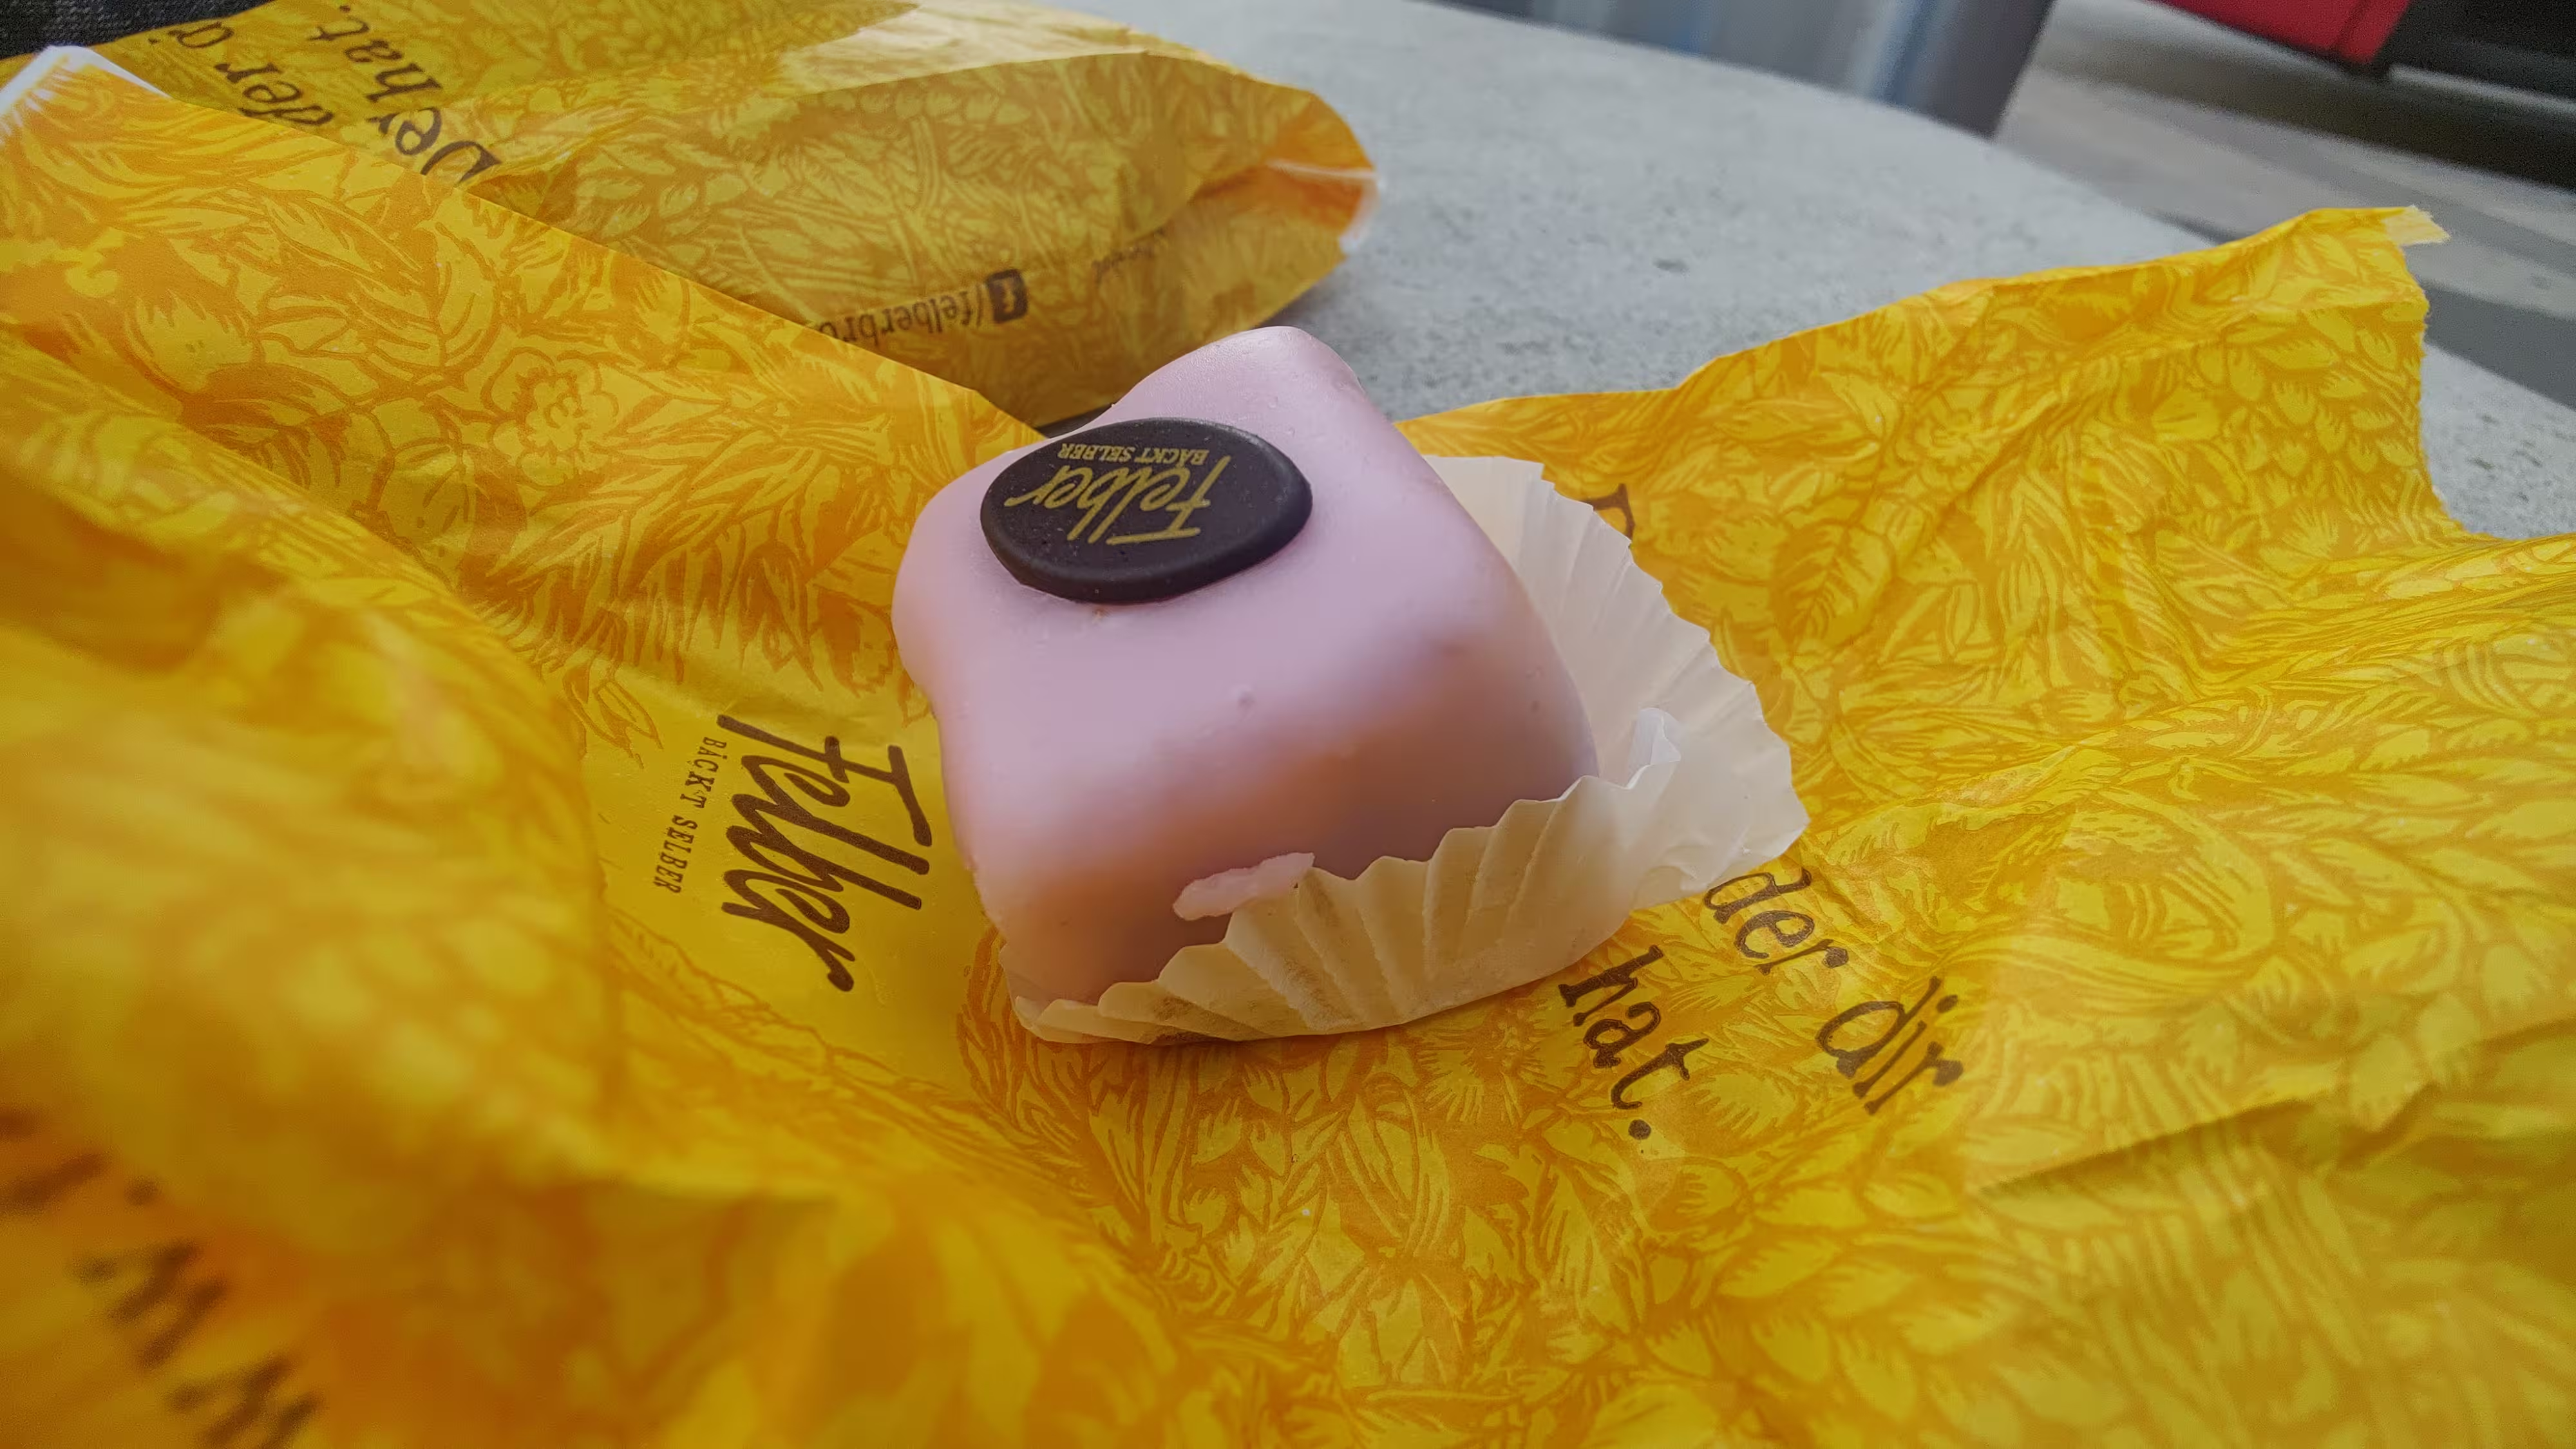 Punschkrapfen. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
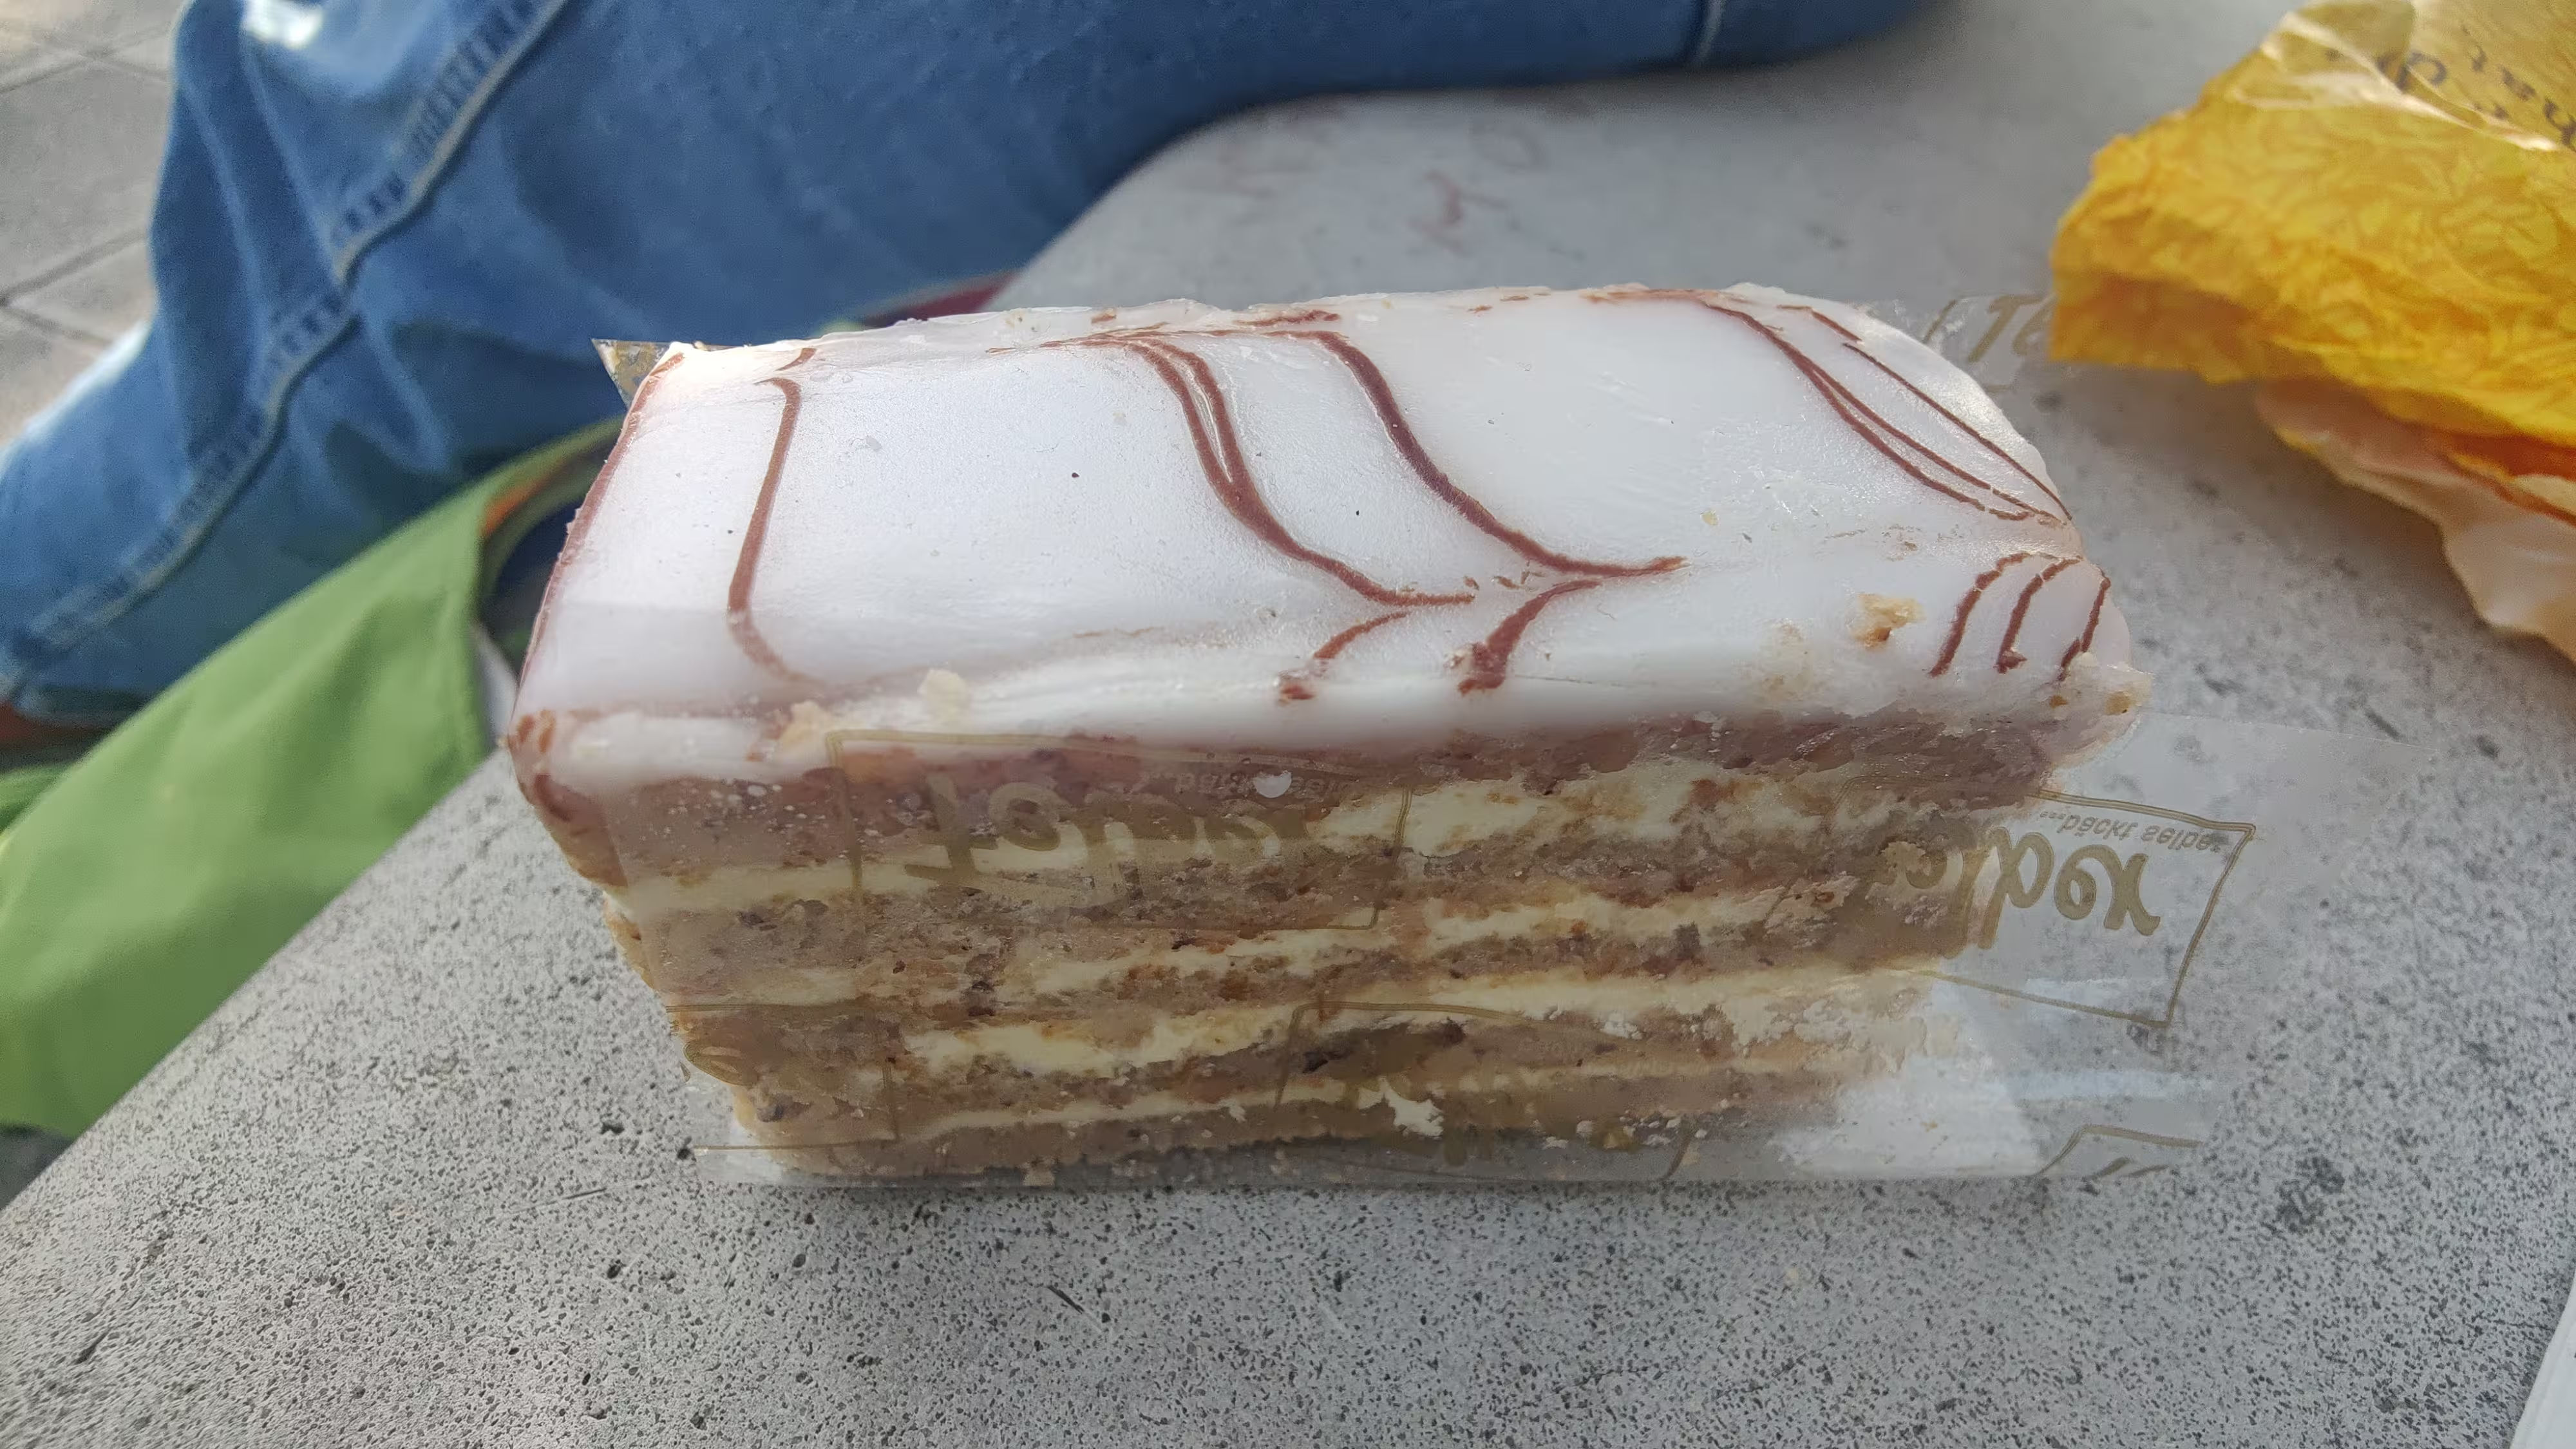 Esterhazyschnitten. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
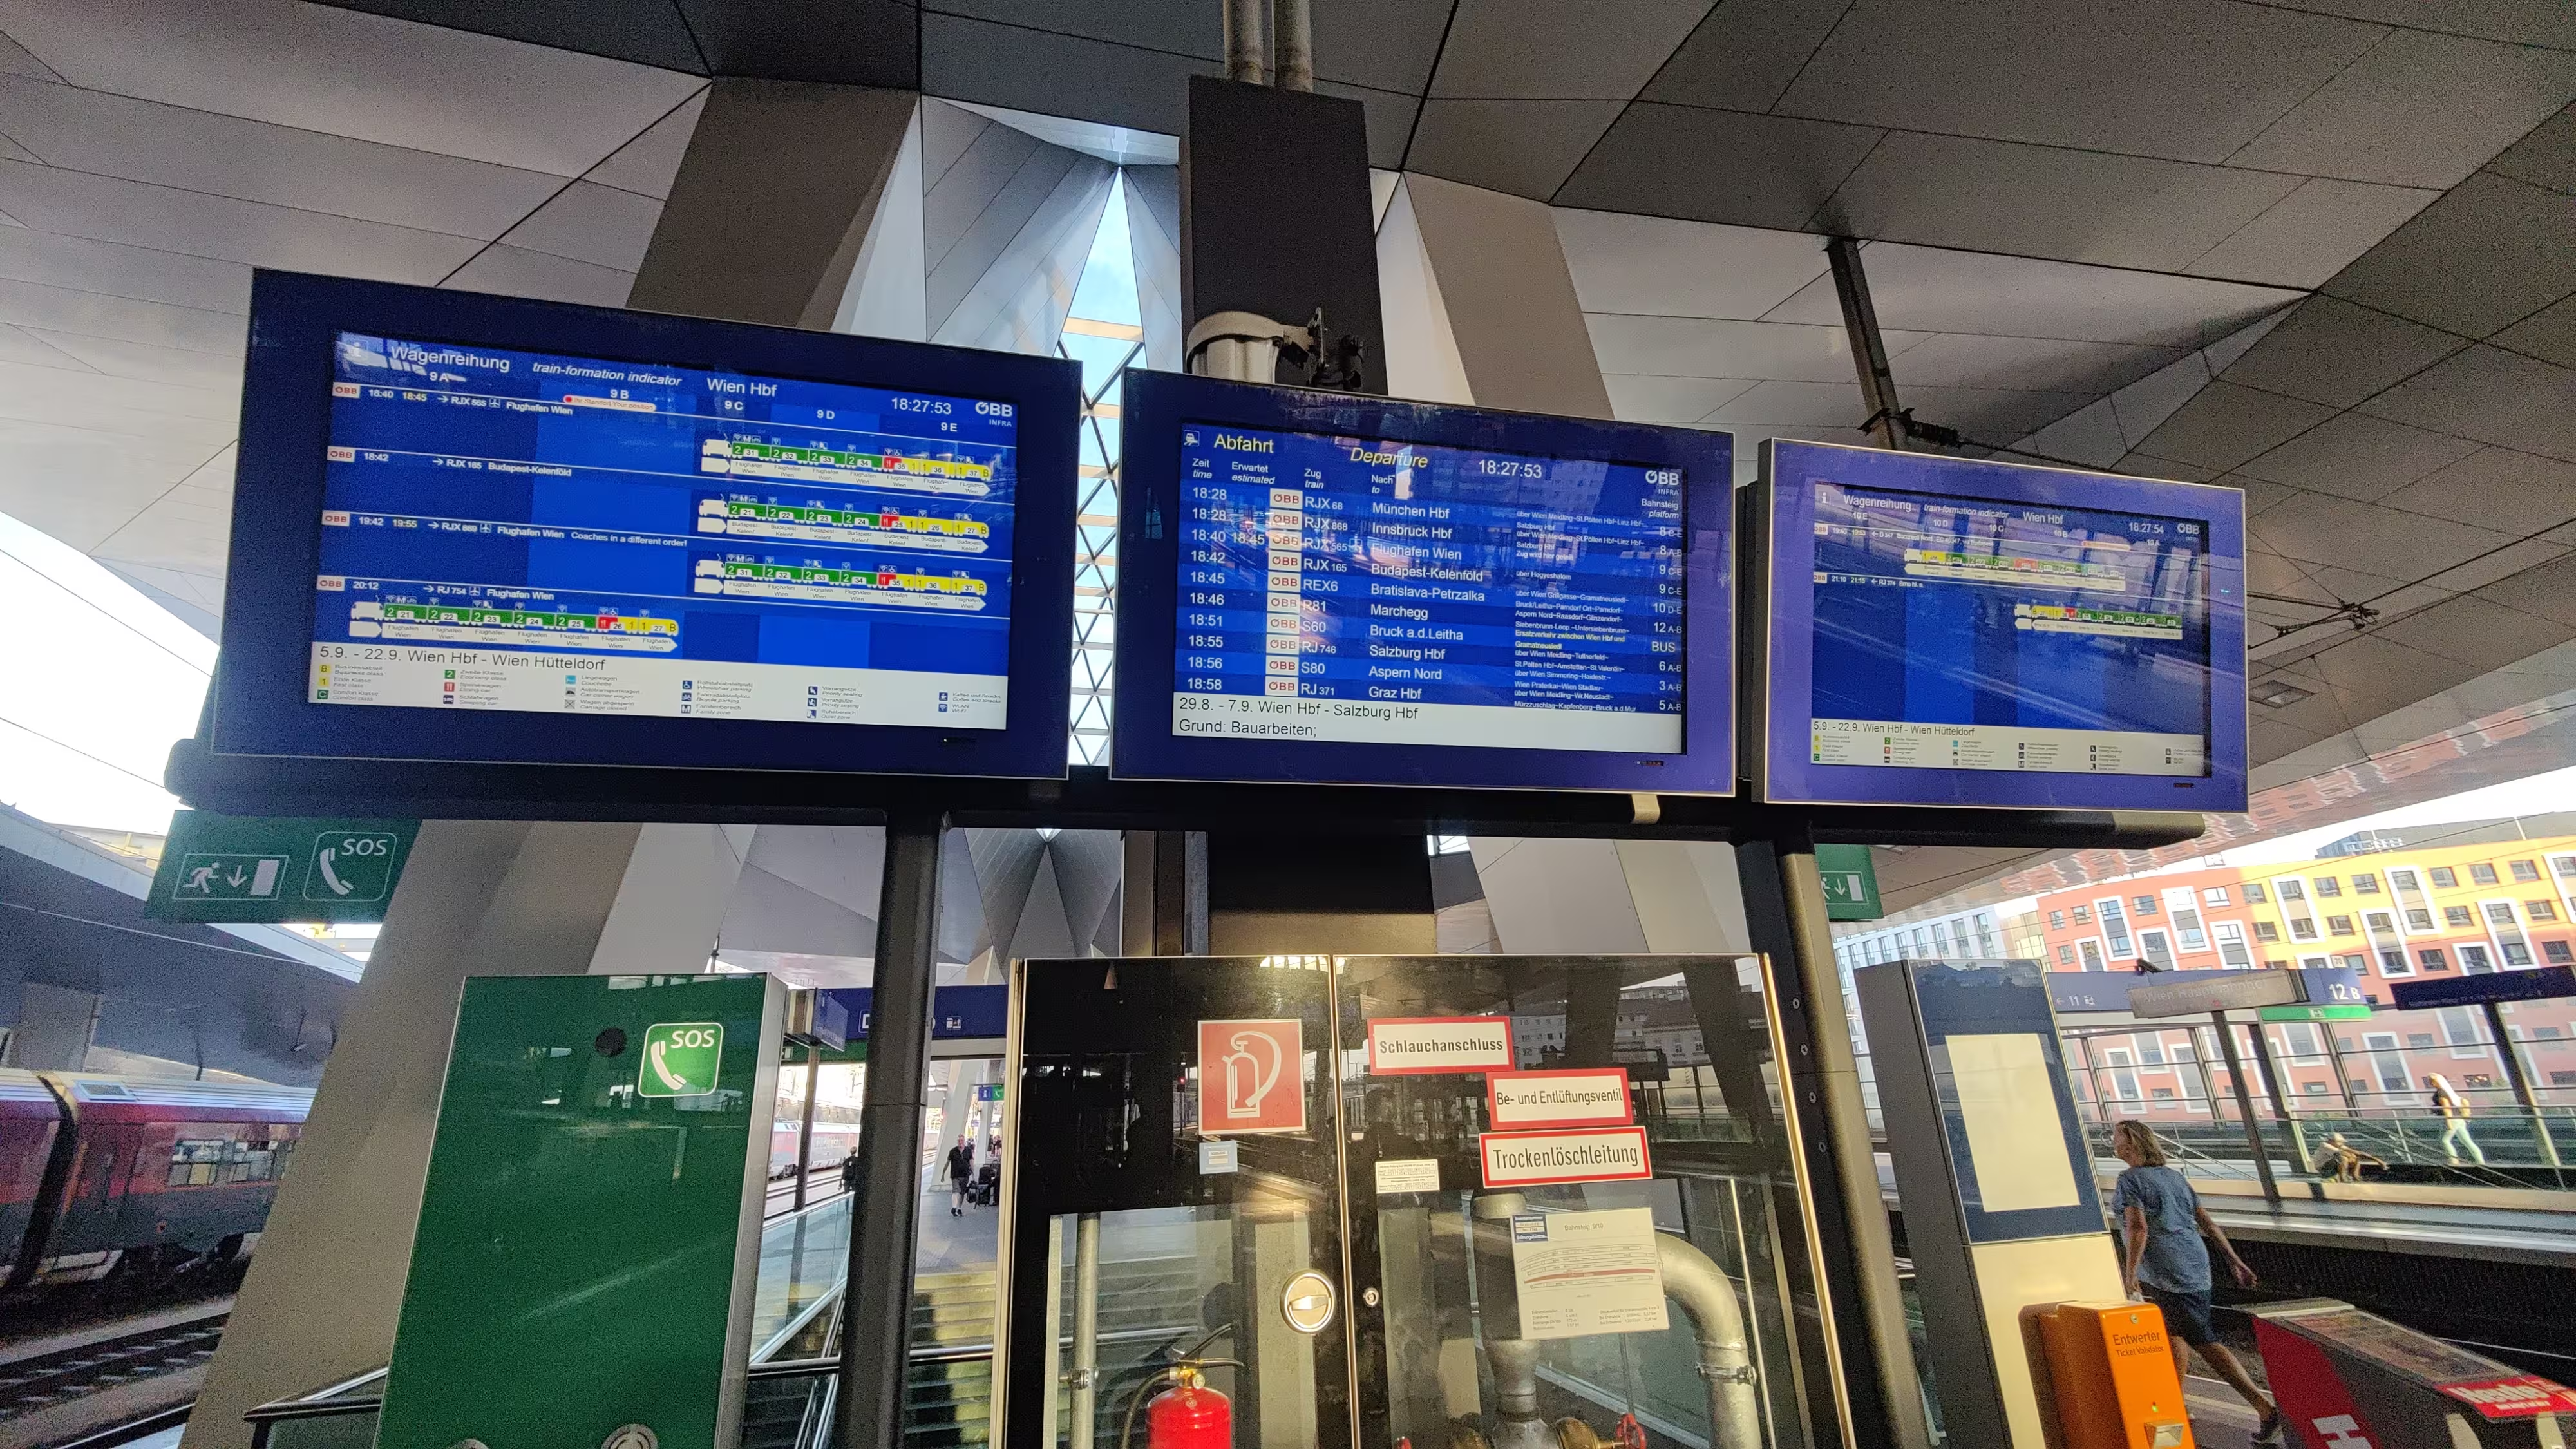 Departure boards in Vienna displaying information about the trains. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
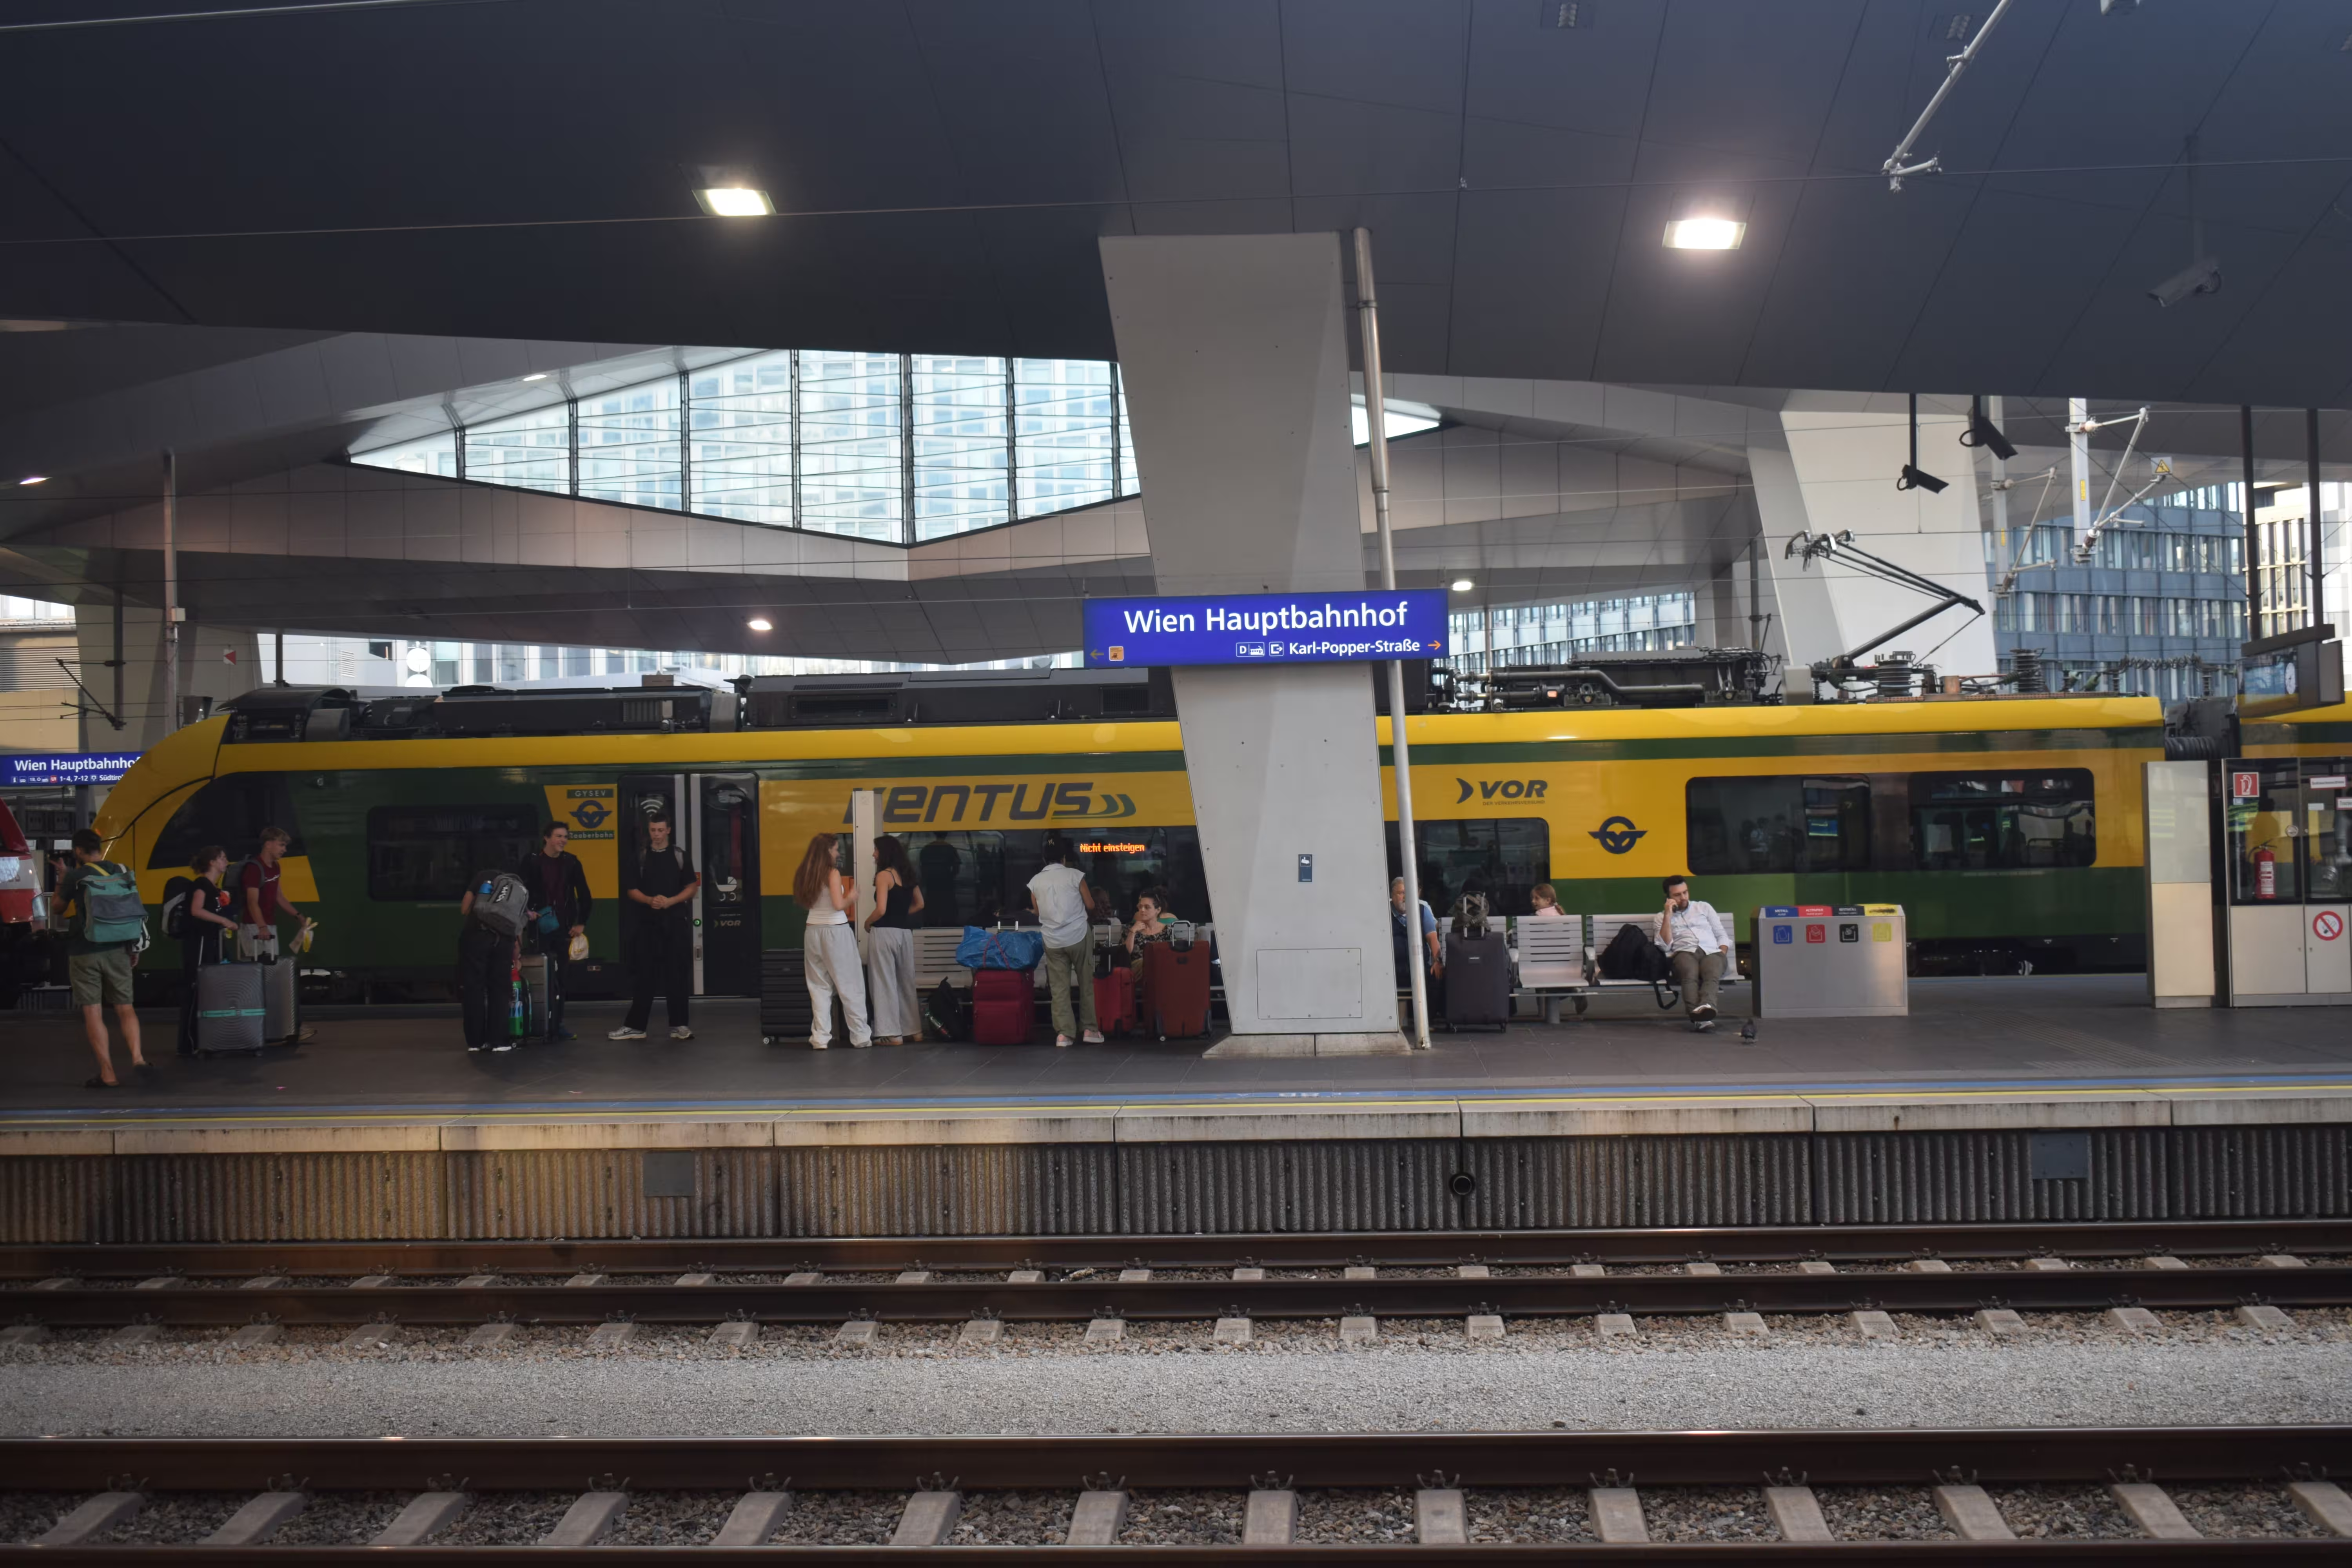 Platform and tracks at Wien Hauptbahnhof station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
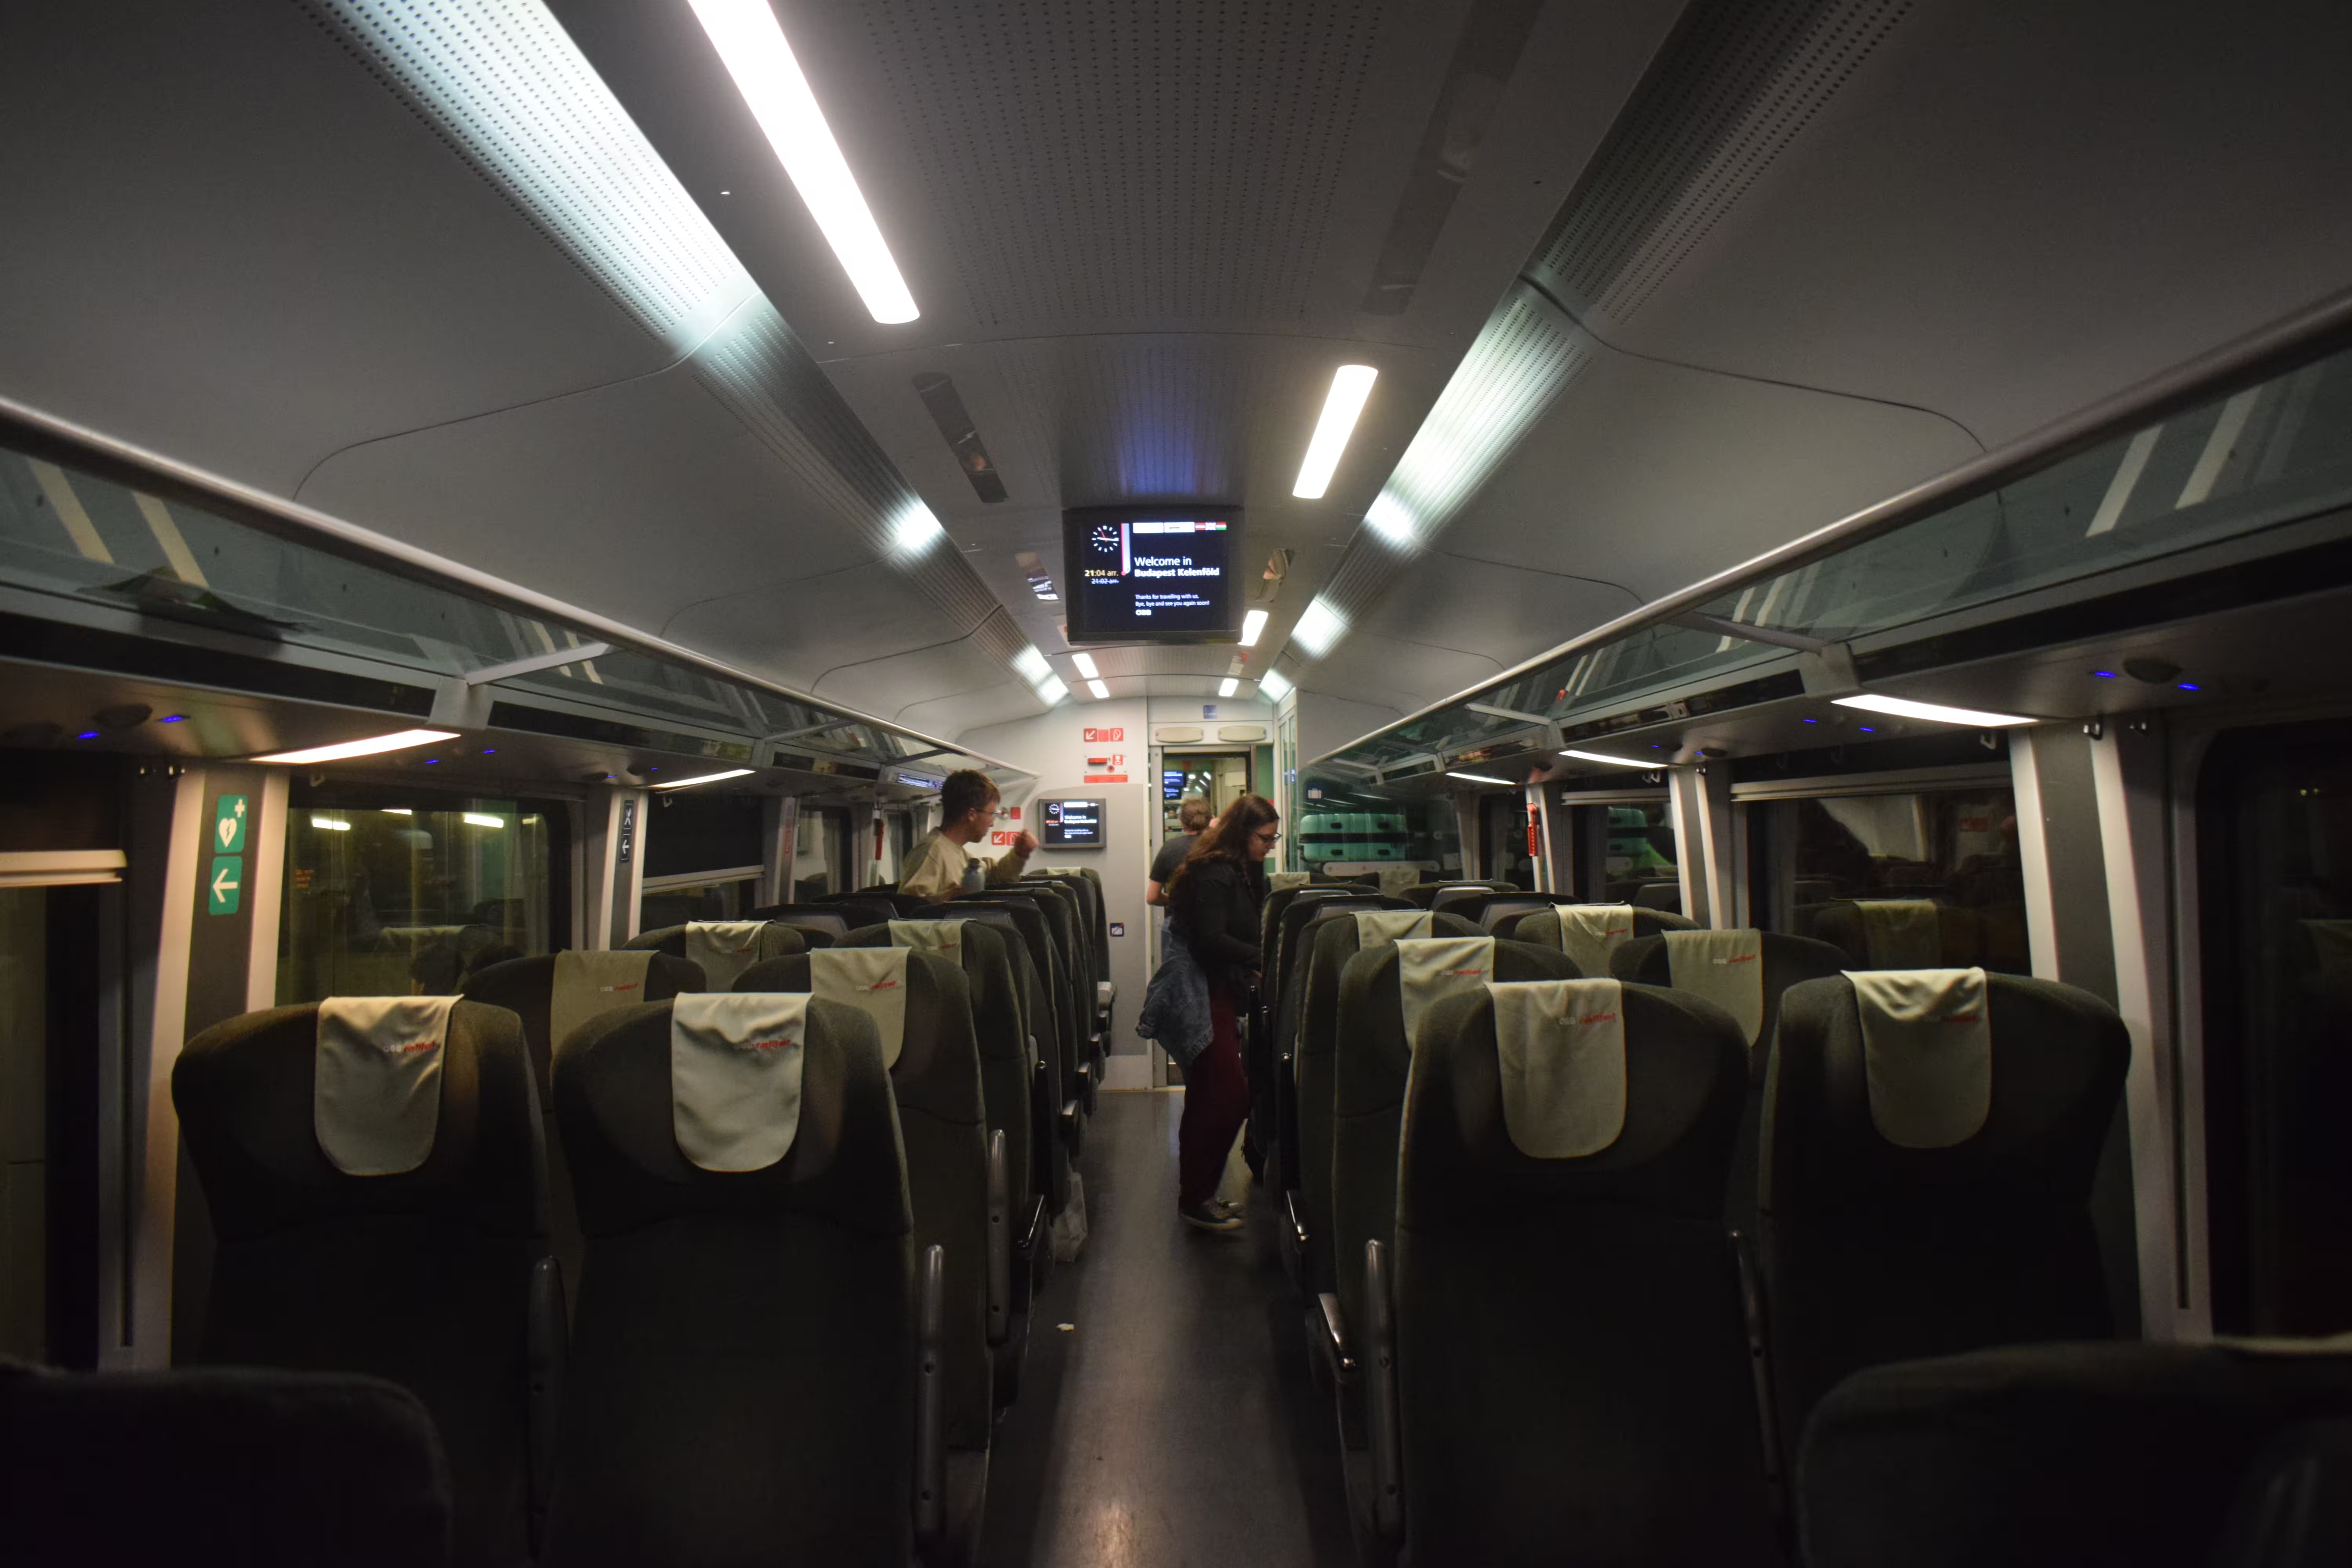 Interior of the train we took from Vienna to Budapest. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
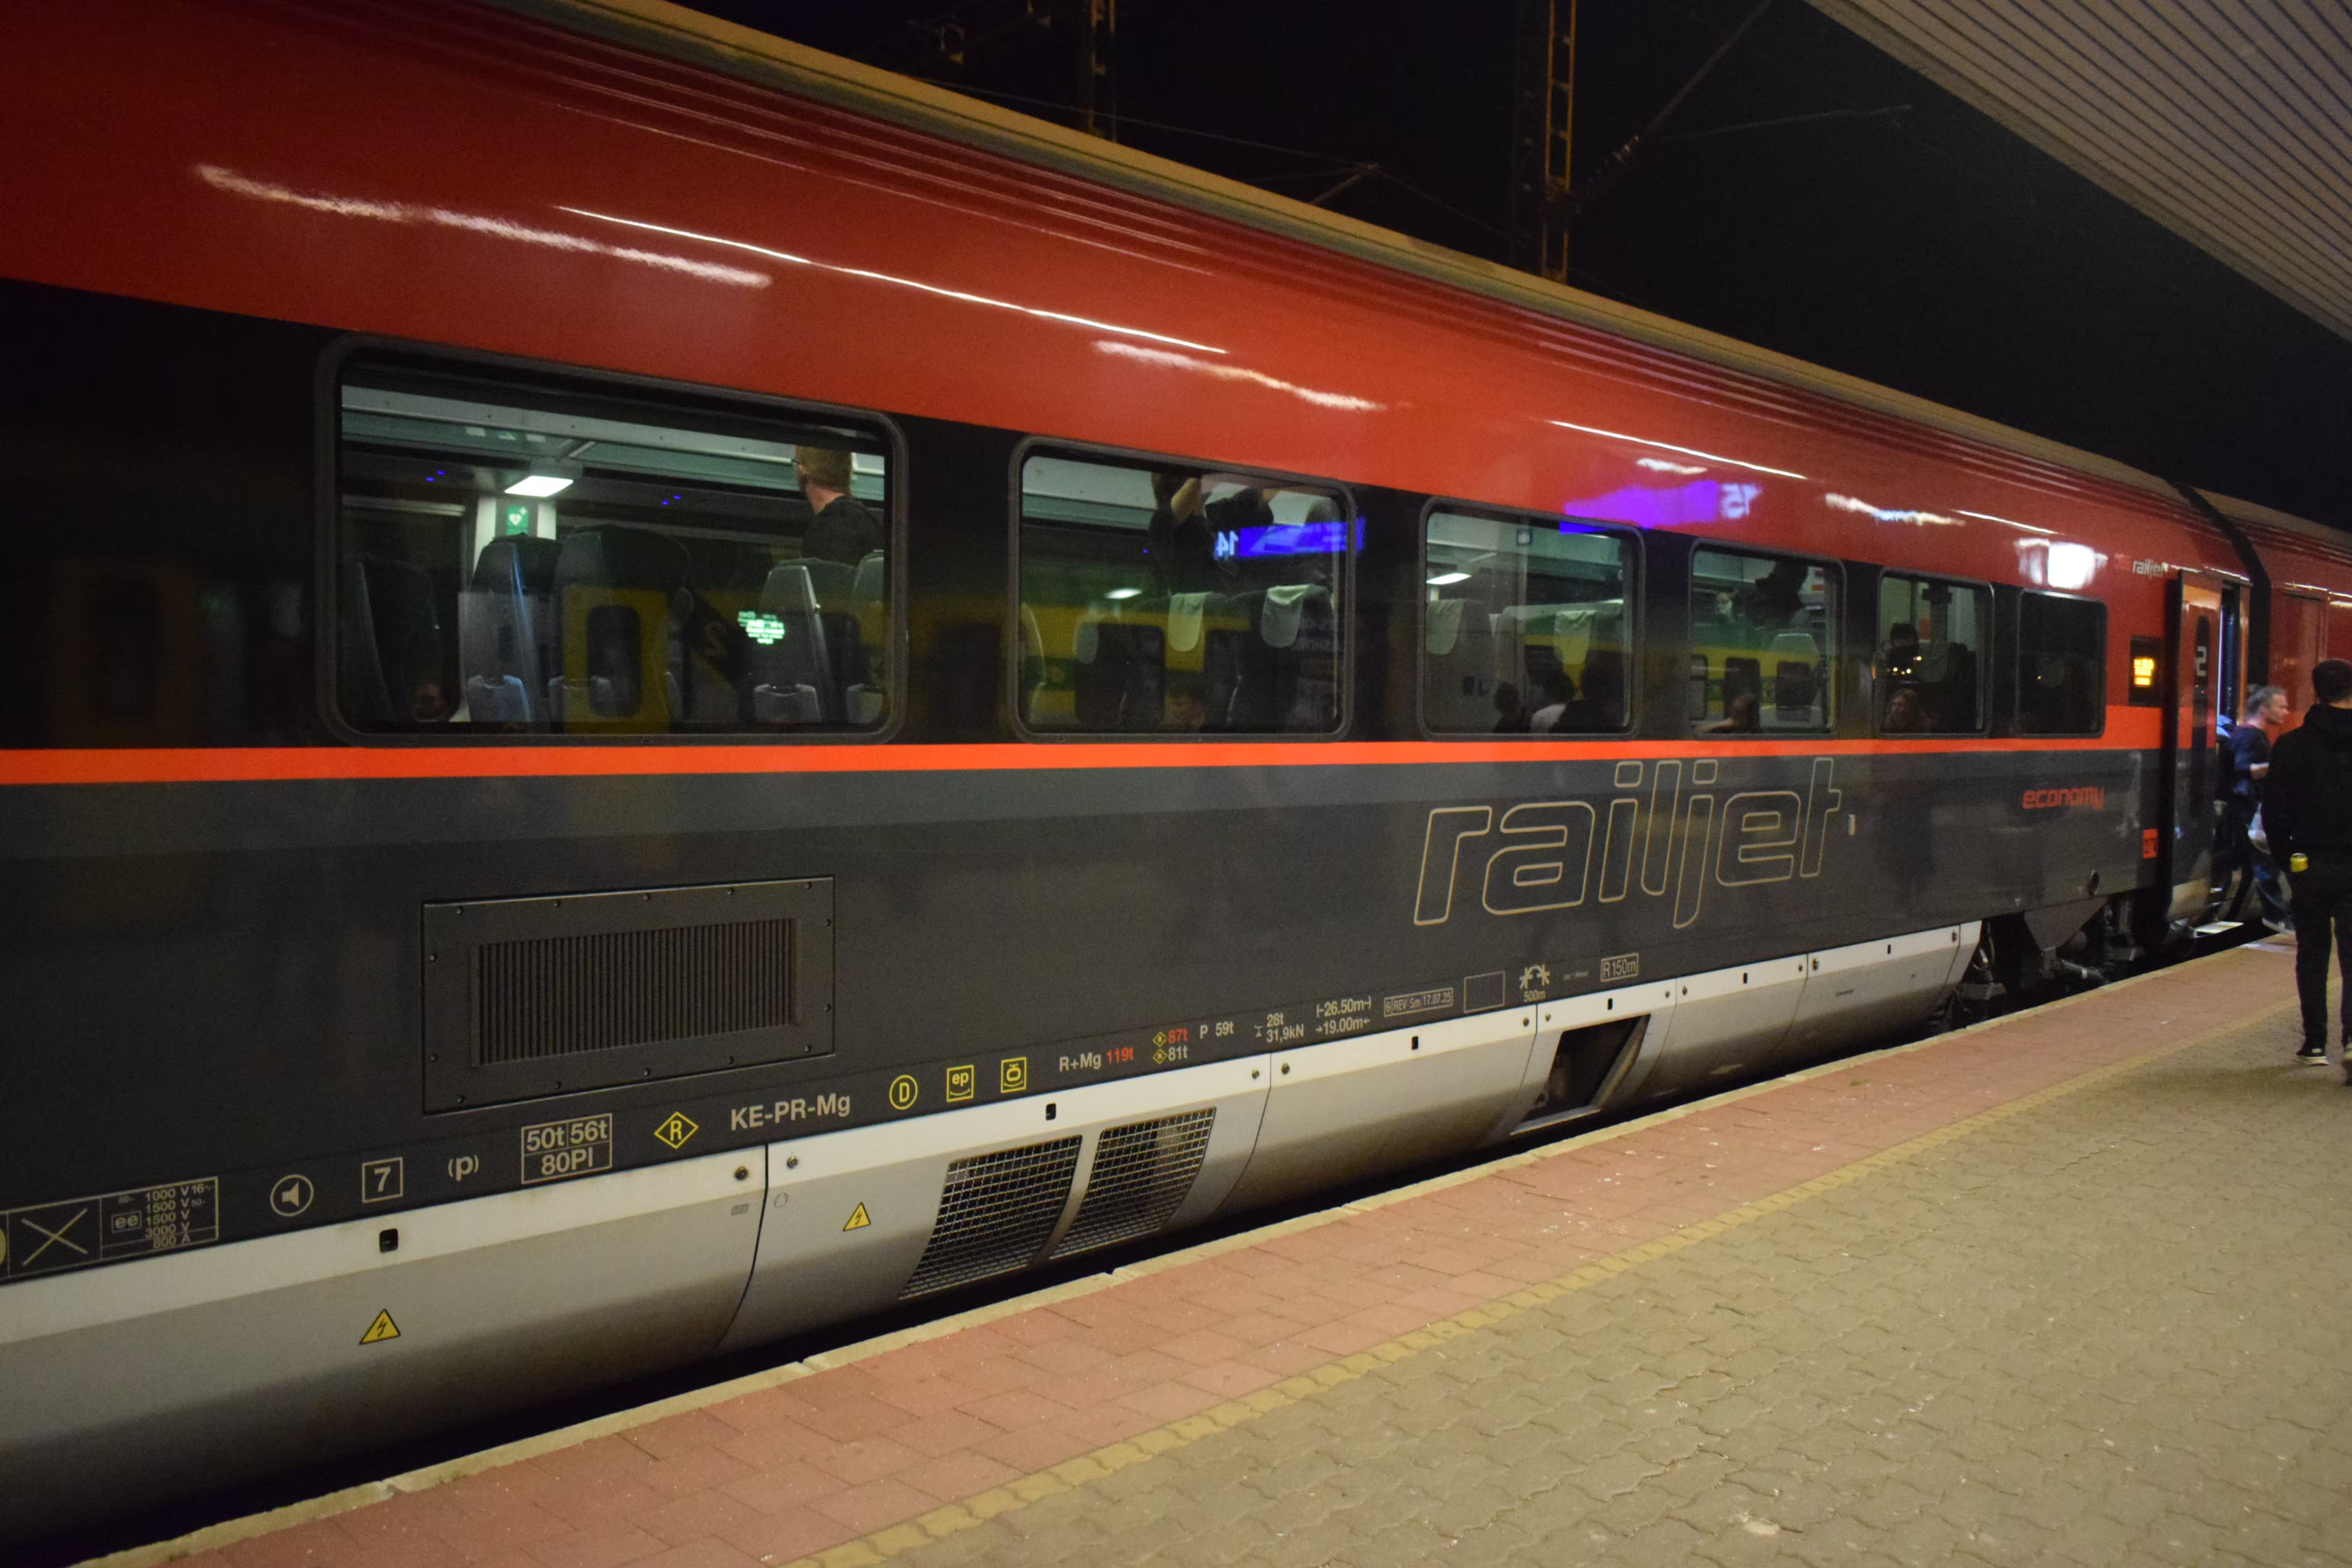 This is the train we took for our return journey from Vienna to Budapest. It is standing on a platform in Budapest Kelenfold station. Photo by Ravi Dwivedi, released under CC-BY-SA 4.0.
 The


 I recently released version 0.3.0 of my recipe manager application Kookbook find it in git in
 At some point I should do a 10 recipe example collection, but my personal collection is in danish, so I m not sure it is going to be useful. Unless someone will donate me some handfuls of pre-formatted recipes, I will happily announce it.