Search Results: "will"

5 June 2009

Stefano Zacchiroli: turbogears 2 packaging - take 3

TurboGears 2 packaging - (another) status update Brief status update on TG2 packaging. As expected, this week has been very busy and I'm writing the update offline on a train, but nevertheless I've good news to share: ... the last item above would theoretically mean that TG2 is already usable, but it is not the case due to the infamous #507909 which breaks both TG2 and TG1 in unstable (the latter was working in Lenny, and I had to resort to a Lenny chroot for a recent course I've taught about web development). In short, turbojson is in unstable, in spite of the lack of several of its dependencies, making impossible any import of it. ..., stay tuned, keep faith, bear with me, almost there, ... etc.

Joachim Breitner: Third place in AI programming contest

My contribution to the programming contest held by the German FreiesMagazin got a third place out of 13 submissions. This is quite good, considering that I only wrote a small wrapper around the generic game-tree Haskell library by Colin Adams, and hardly gave any serious thought into the problem.All entires are available for download. I have annotated the table containing the results with the line count as given by ohcount:
W D L Points Language Code lines
1. Kroschinsky 904 242 54 2954 Python 589
2. Schulz 858 263 79 2837 Python 544
3. Breitner 837 281 82 2792 Haskell 264
4. Jackermeier 754 306 140 2568 Perl 183
5. Roth 574 338 288 2060 C++ 1731
6. Eitel 567 355 278 2056 Ruby 352
7. Reichel 342 328 530 1354 Python 266
8. Zimmermann 303 400 497 1309 Java 1070
9. Apensiv 190 353 657 923 Perl 410
10. Maraun 150 300 750 750 C++ 690
11. Golemo 131 319 750 712 Python 104
12. Ziegelwanger 120 337 743 697 C++ 868
13. Fuest 32 254 914 350 Python 645
Note that the line count for my haskell program includes the game-tree library, which I bundled in my submission. Without it, it s 156 lines of code I had to write, which is second best in the code golf category.If you look at the timing statistics, you will see that my program took the longest. When the contest was started, the timelimit was one minute per round which I of course tried to use as much as possibly, by increasing the search tree depth. Later into the contest, the rules were changed to limit it to one minute for a whole game, and that long-running programs will get points deducted. I did some minor changes based on a profiling run, but did otherwise not care too much about performance. I would have tried to improve the runtime by using Haskell s good ability for parallelization. But when I asked on what kind of machine the code will be run, but they would not tell me. They said that this is a hobby programmer s contest where allowing for parallelization were not fair, so I did not work in that direction.All in all it was a positive experience, showing of Haskell s qualities as a language that you can quickly get good results with.

Julian Andres Klode: python-apt 0.7.91 released


As I promised, I released python-apt 0.7.91 today. This version provides a new API, with real classes in apt_pkg, new names which conform to PEP 8 conventions, and it supports new language features such as the with statement. Old code should still continue to work, if it does not and it is using only public interfaces, report a bug against python-apt or send an email. I can not guarantee that all the names will be kept like they are at the moment (it s a pre-release), but there should not be many more changes needed. The series will hit Ubuntu Karmic later this month, and the final 0.8.0 release is going to be shipped in the final Karmic release. If you want to help with python-apt, consider to write some examples of what can be done with python-apt, and some tutorials for the documentation. You can also check for spelling mistakes and alike. If you want, you can also contribute code. See the documentation (in the package, or online) for guidelines on how to contribute. You can get the 0.7.91 release from Debian experimental, and you can view the documentation online at http://apt.alioth.debian.org/python-apt-doc-exp/. And of course, a short example:
with cache.actiongroup(): # apt.Cache 'cache'
    for package in my_selected_packages:
        package.mark_install() # New PEP 8 names, previously named markInstall()
Posted in Debian, Ubuntu

David Moreno: @debianproject is now @debian!

Thanks to Jamie, who used to have the name registered and now handed it over, Twitter Debian's Twitter username is now @debian (go follow Jamie now!). If you were already following @debianproject, nothing will change. Having @debian on Twitter is actually kind of awesome!

Martin Michlmayr: Corporate participation in open source communities

Someone recently asked me a few question about corporate participation in open source communities and I thought I'd share my thoughts on this topic here. Are there differences between an open source project done for a corporation and one done for personal reasons? There are many different ways to run an open source project, led by a corporation or by someone else. Some projects that are run by corporations have few outside contributors. This is often the case with projects that require copyright assignment (i.e. contributors have to assign their copyright to the corporation). These projects may not gain all the benefits of a true open source community, such as outside contributions or high levels of peer review. However, they may still be very successful projects and may have high levels of quality. Projects done by a corporation may have better planning and may have more resources than other projects. When a corporation, especially a large one, starts or becomes involves in a project it can also give credibility to the project and attract a lot of interest to the project. This means that projects done by corporations may have a bigger impact and might also be more visible in terms of publicity. How do corporations successfully utilize an open source community? Corporations can benefit from an open source community in many ways. For example, they can often find people who will review their code or make code contributions. If people become excited about what the corporation does, they might also spread the word and create viral marketing for the corporation. Establishing a community around one's project is often also a good way to identify people to hire since you already have experience working with them and know their capabilities. How do open source communities successfully utilize their corporate relationships? Corporations can make several unique contributions. For example, large corporations can use their name to attract attention to a project and give it credibility. Furthermore, corporations have some capabilities that personal contributors often don't have access. They may have special testing equipment (such as servers with thousands of CPUs or hard drives) or access to a testing lab where a professional usability test can be done. Finally, corporations can sponsor developer conferences, which are typically very effective means for the community to come together and work on activities together. It is important for projects to remember that corporations are not charities and that they will invest in an open source project for a reason. Therefore, they have to ensure that the corporation will get tangible outcomes from their involvement or sponsorship, otherwise they may not stay involved in the long run. What are the risks for a corporation when working with an open source community? One risk is that the code (or other form of contribution) is not accepted. However, this is a risk any contributor to a project faces. Before making any sort of contribution, it is therefore important to become familiar with the project and its culture. Every project has their own "do's" and "don'ts" that have to be followed. Another risk is that a corporation will invest in a community project that later on is abandoned by the community. However, in this case, the corporation could take the lead and continue to maintain the project. What are the risks for an open source community when working with a corporation? One potential risk is that the corporation will assert too much control over the project. It's important for projects to ensure that the community as a whole has influence over the direction of a project rather than one particular player. Are certain certifications needed in order for someone to participate in open source projects for a corporation? Certifications are not needed to get involved in or start a project. However, it is important to become familiar with the open source community and the project one wants to contribute to. A good first step is to read the book Producing Open Source Software by Karl Fogel which is available online. As a next step, the community in which someone wants to get involved in should be studied, for example by reading the mailing list archives. This will help to become familiar with the culture of a project as well as the mechanisms to contribute to the project. How do open source communities communicate and collaborate with corporations? In the best case, employees from corporations would interact in the project like any other contributor. That is, they should use the existing communication channels, such as mailing lists, IRC or developer gatherings. Many companies are good at working "with the community" but the ideal scenario is for a company to be part of the community and to work "in the community", just like other contributors. This is the most effective way for them to make changes to the code and project. Of course, not every corporation will get involved in a project directly. That's why it makes sense for projects to collaborate with corporations in other ways. For example, projects can talk directly to companies to get samples of their hardware in order to add support for them in their software. Projects can also work directly with corporations to find out how their project can better meet the needs of enterprise users.

Andrew Pollock: [tech] Software controlling the power to USB Woot! lights

I've had a few enquiries from my blog post about trying to control dumb USB-powered lights. I thought I'd just write something up to save myself replying to any more emails. Yes, it's doable. Finding a USB hub that will do it is another story. From my own research, I found someone else who was doing something with USB-powered devices (I can't remember what now), and he had been using a what is now a Linksys ProConnect USB 4-Port Hub USB 2.0 I'd first tried a couple of random cheap hubs from Fry's with no success (fortunately I was able to return them) before I determined that the Linksys one would definitely work. The downside of the Linksys hub is it requires external power. It was also one of the more expensive USB hubs on the market. One of my co-workers, who is an Electrical Engineer by education, said that the USB spec requires the functionality that I wanted, but most chip manufacturers had cut a corner in the interests of cost saving. The Linksys hub uses an NEC chipset. Every other hub that I could get my hands on had a Genesys Logic chipset, and did not work. You can tell if you've got a winner by the output of lsusb -v. If the hub characteristics include "Per-port power switching", you're in business. To do the actual port powering on and off, I'm using a setuid-root hub-ctrl, wrapped with a small shell script, which has the USB ID of the hub and the port number the lights are plugged into hard-coded in it. In my searching, I found also that it may be possible to do with Python, but I did not invest the time trying to find out.

René Mayorga: June and July two events to attend, DebConf and ECSL

and http://ecsl.sl-centroamerica.org/ Being a lot time without any post but finally I see the things more clear, I changed my $paid-job on March, I leave my sysadmin job on a midle-range local ISP, to go on a sort of similar job in another one, more big company, first I though that this will give me more spare time but I was wrong, at least for the first months, but at this time I m finally getting enough time to rest, but not enough time to devote to some Debian tasks(but things will change!!). but looks like everything is going better, I get my $paid-job permission to go to DebConf, and I will also attending just 2 days to ECSL; ECSL is Encuentro Centroamericano de Software Libre , it is actually the first gathering with people related to Free Software communities on this small area(Central America), we expect about 100 people from Central America, Mexico, and some other places, this is could be a nice opportunity to create efforts on a region that is having political and social efforts to integrate all countries in a political/social block. So, see you all at C ceres and Gunnar, see you on ECSL at Estel :)

4 June 2009

Sandro Tosi: Bts-link support Google Code issue tracker

Since this afternoon, bts-link is able to interact with Google Code issue tracker.

So, if you're upstream code & bugs are maintainer there and what to keep them monitored, just drop us an email to the devel mailing list (see link above).

You can also write us if your tool uses another upstream issue tracking still not managed by bts-link and we will see what we can do.

Sam Hartman: Kerberos 1.7

MIT Kerberos 1.7 is released. I think this release really takes MIT Kerberos forward both for end sites and for system integrators. There are a lot of code quality improvements and bug fixes. For sites, this release allows changes to flow from one KDC to another on an ongoing basis rather than waiting for periodic refreshes. In addition, the domain-realm referral project allows information mapping hosts to domains to be configured in one place rather than on each client. I already wrote about Active Directory enhancements. Painless Security was also involved in a project to secure Kerberos against offline dictionary attacks. I m very happy that this project made the 1.7 release. To be truly useful, it will require integration from OS vendors into PAM modules and the like. I ll discuss my plans for doing that in Debian in a future post. Despite a lot of new features, initial signs are that 1.7 is going to be a relatively stable release. It has been in Debian unstable for over a month and at this point is working quite well.

Steve Langasek: Configuring-an-old-Debian-system

Chris, Please note that the method you recommend for activating libpam-cracklib only applies to lenny and earlier; it's obsolete for the upcoming squeeze release (and in Ubuntu 8.10 and later), where libpam-cracklib is integrated with pam-auth-update and will be autoconfigured. Running your sed command on a squeeze system will break pam-auth-update integration, and cause the admin headaches going forward if they ever have occasion to use anything other than pam_unix for authentication. So for a squeeze system, this should be:
apt-get install libpam-cracklib
... and you're done! Actually, the package defaults in squeeze are stronger than what you've listed: libpam-cracklib will set minlen=8 by default (instead of the uselessly-weak minlen=6), and coming soon, pam_unix should default to sha512 instead of md5 for password hashing.

Russell Coker: Linux Rate-Limiting of an ADSL Link

After great pain I ve got tc working on some Linux routers. The difficulty with limiting an ADSL link is that the ADSL modem has significant buffers and the link between the Linux machine and the modem is significantly faster than the ADSL upstream channel. This means that the transmission speed needs to be artificially limited, a speed of about 95% the maximum channel speed is often recommended. As ADSL upstream speed often varies (at least in my experience) that means that you must limit the transmission speed to 95% of the lowest speed that you expect to see - which of course means a significant drop in performance when the ADSL link is performing well. I use the HTB queuing discipline to limit the transmission rate. My transmission speed varies between 550kbit and 680kbit in my rough tests. So I start by limiting the overall device performance to 550kbit. Then I have three different classes with IDs 1:10, 1:20, and 1:30 with rates of 64kbit, 480kbit, and 128kbit respectively. It is often recommended that the inferior classes have a total bandwidth allowance that is equal to the allowance for the overall link, but I have the three inferior classes allocated with 672kbit - I think that this will work as it will be quite rare that all classes will be in operation at the same time and fairly unlikely that I will ever have all three classes running at maximum speed. I will be interested to see any comments about this, I might have misunderstood the issues related to this. Each class has a SFQ queue discipline associated with it for fair queuing within the class. It might be a bit of overkill, I expect to only have one data channel in operation on the VOIP class so it probably does no good there and my usage pattern is such that if the 480kbit connection is anywhere near busy then it s due to a single large transfer. But with the power of a P3 CPU applied to the task of routing at ADSL speeds it really doesn t matter if some CPU time is wasted. Then the tc filter lines associate iptables marks with the classes. Now this is only a tiny fraction of what tc can do. But I think that this basic configuration with the rate limits changed will suit many ADSL router configurations, it may not be an ideal configuration for most ADSL routers but it will probably be a viable configuration that will be better than having no traffic shaping. Below is the shell script that I am using: #!/bin/bash -e DEV=ppp0 tc qdisc del dev $DEV parent root handle 1:0 2> /dev/null true
tc qdisc add dev $DEV parent root handle 1:0 htb default 30 # limit the rate to slightly lower than DSL line speed
tc class add dev $DEV parent 1:0 classid 1:1 htb rate 550kbit prio 1 # sub classes for each traffic type
# 10 is VOIP, 20 is default, 30 is the test network
tc class add dev $DEV parent 1:1 classid 1:10 htb rate 64kbit burst 6k prio 2
tc class add dev $DEV parent 1:1 classid 1:20 htb rate 480kbit burst 12k prio 3
tc class add dev $DEV parent 1:1 classid 1:30 htb rate 128kbit burst 12k prio 4 # use an sfq under each class to share the bandwidth
tc qdisc add dev $DEV parent 1:10 handle 10: sfq
tc qdisc add dev $DEV parent 1:20 handle 20: sfq
tc qdisc add dev $DEV parent 1:30 handle 30: sfq tc filter add dev $DEV parent 1: protocol ip prio 1 handle 1 fw classid 1:10
tc filter add dev $DEV parent 1: protocol ip prio 2 handle 2 fw classid 1:20
tc filter add dev $DEV parent 1: protocol ip prio 3 handle 3 fw classid 1:30 iptables -t mangle -F POSTROUTING
iptables -t mangle -A POSTROUTING -j MARK --set-mark 2
iptables -t mangle -A POSTROUTING -p tcp --sport 22 -j MARK --set-mark 3
iptables -t mangle -A POSTROUTING -d $VOIPSERVER -j MARK --set-mark 1

3 June 2009

Pablo Lorenzzoni: Keysigning Party at FISL10

We ll be holding a Keysigning Party at FISL10. This will be a good opportunity to renew my key, given I ve been using it since 2001 and it s an old 1024 DSA key. I have to thank An bal Monsalve Salazar and Alexander Wirt for sharing their expertise in organizing this kind of event. More information on the KSP can be obtained from the announcement.

Chris Lamb: Checklist for configuring a Debian system

In the spirit of Thomas Limoncelli's Time Management for System Administrators, this is my checklist for setting up a new Debian system. I have added a few notes to the original list to justify their existence and to provide some background information. Whilst you should avoid performing repetitive interactive configuration and defer to the multitude of tools designed for this task, constructing and sharing a checklist can still be an instructive step. It can also be useful in situations where a machine has already been partly configured for you.

Software
  • /etc/apt/sources.list

    • Choose a sensible primary mirror
    • Ensure use of release codenames (eg. "lenny") instead of synonyms
    • Confirm security mirror is enabled
    • Remove references to contrib and non-free
  • Disable installation of Recommends:

    echo 'APT::Install-Recommends "0";' > /etc/apt/apt.conf.d/90recommends
    
  • Ensure we are up to date security-wise:

    apt-get update && apt-get dist-upgrade
    
  • Setup and configure locales first to avoid annoying Perl warnings. Don't choose All locales; you almost certainly don't want that.

    apt-get install locales
    dpkg-reconfigure -plow locales
    
  • Install some essential utilities:

    apt-get install vim-nox ntp openssh-server screen most tree bzip2 unzip moreutils dnsutils htop pwgen telnet manpages manpages-dev vrms acl gawk strace curl tcpdump
    
Users
  • Before we create any real users, we configure PAM to reject weak passwords. Custom banned passwords can be added to the dictionary by editing /usr/share/dict/cracklib and running update-cracklib.

    apt-get install libpam-cracklib
    sed -i -e 's ^password # \0 ' /etc/pam.d/common-password
    echo 'password required    pam_cracklib.so retry=3 minlen=6 difok=3' >> /etc/pam.d/common-password
    echo 'password required    pam_unix.so use_authtok nullok md5' >> /etc/pam.d/common-password
    
    (Edit: Please read this response from Steve Langasek regarding this modification on squeeze and Ubuntu 8.10)
  • Configure sudo. I prefer to create a new group instead of re-using adm as that is already used by logfiles.

    addgroup rootusers
    adduser myuser
    adduser myuser rootusers
    apt-get install sudo
    echo 'User_Alias ROOTUSERS  = %rootusers' >> /etc/sudoers
    echo 'ROOTUSERS, root     ALL=(ALL) ALL' >> /etc/sudoers
    
Mail relay Email remains the primary method to asynchronously inform the system adminstrator that their attention is required. It is assumed that the machine will not handle your day-to-day email (or indeed accept any external mail) but will instead simply forward it elsewhere. We also assume a preference for Exim, but the configurion for Postfix is almost identical.
  • First, install the mail packages:

    apt-get install exim4-daemon-light bsd-mailx
    dpkg-reconfigure exim4-config
    
  • During the Exim configuration, choose Internet site and follow all the defaults, ensuring that you only listen on 127.0.0.1 and you are not relaying mail for any other domains.

  • We then configure forwarding to another email address so we don't have to continually poll this machine for issues:

    echo 'root: you@example.com' >> /etc/aliases
    newaliases
    
  • Finally, we test mail delivery:

    echo "Test 1 from $(hostname)"   mail root -s "Test 1 from $(hostname)"
    
The d-i manual has some further advice on this, including the use of "smarthosts".
Miscellaneous
  • Stop Emacs creating backup files everywhere:

    mkdir -p /etc/emacs/site-start.d
    echo '(setq backup-inhibited t)' > /etc/emacs/site-start.d/10no-backup.el
    
  • Configure Munin:

    apt-get install munin-node
    echo 'allow ^123\.123\.123\.123$' >> /etc/munin/munin-node.conf
    /etc/init.d/munin-node restart
    
    For baroque network configurations, you can generate the regular expression line with this script.
  • Configure molly-guard, a tool for preventing accidental shutdowns. As molly-guard cannot detect shutdowns initiated within a combination of GNU screen and SSH, we configure it to always query the hostname:

    apt-get install molly-guard
    echo "ALWAYS_QUERY_HOSTNAME=true" >> /etc/molly-guard/rc
    
  • Monitor disk S.M.A.R.T. attributes:

    apt-get install hddtemp smartmontools
    sed -i 's ^#start_smartd=yes start_smartd=yes ' /etc/default/smartmontools
    /etc/init.d/smartmontools start
    
  • Setup backups - I'm quite partial to backupninja because it automates most of the tedious SSH configuration. I adjust the time of the backup to when I'm likely to be around to fix issues and cut down on email noise by not reporting successful backups:

    apt-get install backupninja hwinfo debconf-utils rdiff-backup
    sed -i -e 's ^when = everyday at 01:00 when = everyday at 9:30 ' /etc/backupninja.conf
    sed -i -e 's ^reportsuccess = yes reportsuccess = no ' /etc/backupninja.conf
    ninjahelper
    
  • Filesystems

    • In /etc/fstab, check noatime is enabled on all filesystems, and acl where needed.
    • Use tune2fs to adjust how much of the disk is reserved for the superuser - the default of 5% is excessive for large volumes.
  • Reboot. You should be prompted by molly-guard before your computer restarts.

Aigars Mahinovs: Google Wave

So, the latest buzz on the web is all about Google Wave. I would urge everyone developing stuff for the Internet and technological people depending on the Internet for their daily work, to watch that introductory video. The concept is frankly mind-blowing. If this is done right and embraced by all the right people, Google Wave could be the new platform concept that could be used to create new generation of email, instant messaging, collaboration software (CMS, wiki, Sharepoint, workflow, ), blogging software and forum software and do all that while integrating back with current technologies, like Twitter and RSS feeds. It remains to be seen what parts will be open source and federated and what parts will remain Google-only services. For example, I am convinced that Spelly the spellchecker bot and Rozy the automatic translation bot will be hard to impossible to federate. This being Google, it is practically a given that the code will be good, but a bit hard to understand and contribute to. Management of the free software community and proprietary community relations will likely be the key to the success of this technology. I love the technology itself - imagine that you have a web blog. The blog software makes each your blog post a wave. When people leave comments on the post, these comments show up in your email inbox. You can reply to people right from there. By default your replies will show up on your blog and also show up in the email inboxes of the commenter, but you also have the option to mark your reply private and only send it to the commenter. Also it looks to be possible to choose to host all the data yourself or to make Google host all your blog and comment data and make your blog just be a frame where this data is displayed in, possibly allowing you to use very, very minimal system resources to maintain the blog even in a case of Slashdotting. I hate blogs without comments, let s replace them all. I would also love to see replacements to Microsoft Exchange and Microsoft Sharepoint be built using Wave technology with a full support to ODF if possible. Imagine collaborative document editing in OpenOffice using this technology in the backend. It would be one huge project, but it should be possible. Companies currently pay hundreds of thousands of dollars to set up MS Exchange+Sharepoint+Active Directory to be able to simply share documents in their Intranet and see who edited a document (no live editing, no change tracking). It is possible to make a much better product with ODF and Google Wave and it is possible to earn a bunch of money supporting such a product for companies that need support contracts. If it would be possible to licence spellchecking and translation services from Google in a way where a box is installed in customers data centre and the data to be spellchecked and translated never leaves that data centre, then I believe that people would be willing to pay for this superior spellchecking and translation experience. We need open source products that people can depend on. We also need ways for business people to sell services with an easily visible added value so that they can make money and contribute their developer work hours back to the open source projects. We (the free software community) have great ways to get a positive feedback loop with users that can develop software, but when our users have no interest in developing anything, the feedback loop breaks and free software growth slows down. There is a lot of untapped potential in this area - we just need to find a way to convert needs and demands of non-developers into code. I m gonna stop this rant before it diverges even further off topic, but the main point is - go watch the Google Wave demo, read the tech specs and think how you could integrate that into your free software project. Useful wave discussions (will update as I find more):

Bastian Venthur: Debconf 11 in Berlin?

This is just a quick note for everyone who is interested: Yesterday we had a small meeting discussing the plan to bring Debconf 11 to Berlin, Germany. There will be an official meeting regarding this topic at this year s LinuxTag. The meeting will probably take place on Friday the 26th of June at a conference room. Everyone is invited to join the discussion. PS: I also have a shiny new key, the fingerprint is 8795 AF2E 4A1A 4EFB A068 A449 8E88 9544 D985 000D. The old key will be revoked in a couple of months.

2 June 2009

Matthew Palmer: Local HTML docs for Prototype

Having (temporarily) flung myself back into a bit of professional Rails app development, I'm doing a JS-heavy site (just to maximise the WTF factor). Since I'm Old Skool, I'm going with Prototype, as it's the javascript library I'm least unfamiliar with. The problem, though, is that I do about a fifth of my work on the train, where I don't have access to the Internet, and the Prototype people haven't seen fit to provide a downloadable version of the docs in HTML. There's a PDF[1], (which lacks any sort of hyperlinking (how very 1990s) and whose page numbering in the TOC doesn't match up to the PDF page numbers), and a CHM which has hyperlinks that don't work half the time. Apart from that, all the docs are online-only, and not very scraping-friendly (wget --mirror doesn't rewrite links correctly when you're also mangling the filenames for local-friendly access -- patch in the making if I can be arsed). So, long story short, I need a non-traditional way to get myself some local docs. Turns out it isn't as hard as it sounds, as evidenced by the below command list:

	git clone git clone git://github.com/sstephenson/prototype.git
	cd prototype
	git submodule init
	git submodule update
	sudo gem install treetop
	rake doc:build
This will peg your CPU for an inordinate amount of time (a smidge over 10 minutes for me; -j 3 would have made things a lot quicker), but you'll end up with a doc/index.html which has some useful stuff in it. It'll look nothing like what's on the website, but it's something, and should be enough to keep me going on those long, lonely train journeys.
1. which looks like someone should be expecting a C&D from O'Reilly for look and feel, unless it's a semi-sooper-sekrit O'Reilly production that they don't want to put their name to directly.

Christian Perrier: On localization

An old friend is ranting about localization. I first considered not really reaction to Joey's post, mostly because he has very true points...and particularly when he has about the same reaction than mine about a recent post in ou mailing lists. So, I will stick to react to one part of Joey's post...the one I consider really inaccurate. "everyone uses the software in English anyway" Really, Joey, really, that's completely untrue. Of course, I do live in a country that very well known (or at least that has the reputation) for being deeply ignorant in English language. But, really....*all* computers I see around me, both in my personal life *and in my professionnal life* are nearly completely localized. It's probably now well know that I spend most of my professionnal time....providing desktop systems (or managing the people who provide them) to users in ONERA, "the French Aerospace Lab". That means about 2000 users in a scientific environment where the use of English is much more developed than the average environment. Most of these users speak a fairly decent English and are perfectly able to understand that language in some way. About 80% of these systems are Windows-based and 20% are Linux-based. Probably more than 95% of them are localized in French. Even on Windows systems, we mostly integrate free software. And for *each* of them, the most important feature we need, besides software being free, is it to be localized in French. I bet our friends from Extremadura can say the same. The success of Linux-based free systems there also happened because the software is available in Spanish. And, of course, there are tons of similar stories and counter-examples (M nchen, Bhutan, Venezuela, etc.). So, really, please don't spread out that idea. Oh, yes, geeks *do* use their software in English (and, even here, I need to be convinced if I remember well what I saw at conferences in Germany or Spain, for instance). And, yes, it's very well widespread among geeks that using software in English is "better" or "easier". Which I indeed always fight and will fight until I die..:-). We certainly agree that these l10n needs put a high load on development and sometimes slow it down. and, for sure, we sometimes need to make a balance and I really thank you for giving me the credit to try doing that balance. Anyway, all this (including your rant) had to be said and it's interesting to have that small discussion (I just should not start writing down a blog entry at 23:00...:-)) See you soon, hopefully, Joey !

Joey Hess: on localization and progress

In this post I will say some things about localization that I've never felt it was politic to say before. (It still isn't, but what the hey.) But I first want to mention that one of the reasons Christian Perrier is awesome is because he manages to steer projects in ways that avoid (most of) the problems below, and because he has managed to scale rather impressively far. But not far enough that these things haven't gotten under my skin. So, I hate localization. Hate, hate, hate. I wish it would die. I wish everyone spoke the same language. I hate that we have to be politically correct about it, to the point that even if everyone does speak English (hello, Denmark?), we still have to worry about localization into their native language. I especially hate that, after we waste time and resources doing that, everyone uses the software in English anyway (hello, most of Europe). I hate that the typical best effort localization of software is typically so incomplete that it's not actually usable by people who really do need the translation. Either because "best effort" == 80% translated, which is sometimes worse than 0%, or because the documentation doesn't get translated too. And that even with what we consider a complete translation, there are still all sorts of English bits that nobody would ever consider translating. Such as the names of commands, of command-line switches, of markup keywords and configuration files. I hate that translating software and documentation always involves bolting an enormous, nasty build system onto its side, and that the bulk of translations always greatly outweighs the size of the code. I hate that these systems constantly produce deltas that I have to avoid cluttering my commits with. I hate the expectation that every programmer somehow become an expert in internationalization, rather than letting them devote their time to something they're good at. But none of that is what really bothers me about localization. What really, really bothers me is that I often see the need to localize code inhibiting that code becoming better. Just two examples: (PS, I also hate that we have to keep "l10n" and "i18n" straight, and that the words are so unwieldly in this f5g modern English that we represent them based on their length.)
Biella Coleman: (Pobre) Shorty va ser sinbolico


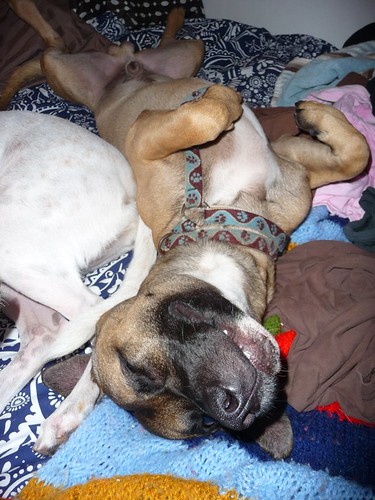
shorty, originally uploaded by the biella.
As part of my reading bonanza, I am currently reading and enjoying Ellen Ullman s The Bug. She has a short section on puns and programmers which I like:

Puns, I would say, represented a human being s pent-up need for ambiguity. That a word could signify two things at once! And these double meanings could be simultaneously understood! What a relief from the flat-line understanding of a programmer s conversation with the machine! p. 59
Last night, I heard a Spanish pun that I particularly liked, having to do with my sister s dog, Shorty who is an odd creature (being a mix of Pit Bull, which is for certain, and legend goes, Chihuahua) will be as of the end of the day > sinbolico. I bet the Spanish speakers know what is happening to Shorty today. Anyone want to take a guess?

Biella Coleman: (Pobre) Shorty va ser sinbolico


shorty, originally uploaded by the biella.
As part of my reading bonanza, I am currently reading and enjoying Ellen Ullman s The Bug. She has a short section on puns and programmers which I like:

Puns, I would say, represented a human being s pent-up need for ambiguity. That a word could signify two things at once! And these double meanings could be simultaneously understood! What a relief from the flat-line understanding of a programmer s conversation with the machine! p. 59
Last night, I heard a Spanish pun that I particularly liked, having to do with my sister s dog, Shorty who is an odd creature (being a mix of Pit Bull, which is for certain, and legend goes, Chihuahua) will be as of the end of the day > sinbolico. I bet the Spanish speakers know what is happening to Shorty today. Anyone want to take a guess?

Next.

Previous.