Search Results: "ag"

3 September 2013

Julien Danjou: Announcing The Hacker Guide to Python

I've been hacking on Python for a lot of years now, on various project. For the last two years, I've beenheavily involved in OpenStack, which makes an heavy usage of Python. Once you start working with a hundred of hackers, on several software and libraries representing more than half a million source lines of Python, things change. The scalability, testing and deployment problems inherent to a cloud platform meddle with everything in designing components. During these two years working on OpenStack development, I've learned a lot on Python from astounding Python hackers. From general architecture and design principles to various tips and tricks of the language. It seemed to me like a good opportunity to share what I learnt doing so with others so you can benefit from it in other projects. I've started working a book, entitled "The Hacker Guide to Python", where I will try to share what I learnt while working with Python. The book is still a work in progress at this stage, but if you'd like to get in touch and keep updated on its advancement, you can subscribe in the following form or from the book homepage.
The Hacker Guide to Python
A book I'm writing that will be launched soon, talking about designing Python applications, state of the art, and various Python tips. If you want to be the first to hear about the launch, subscribe now.

Miriam Ruiz: pySioGame: Educational activities and games for kids

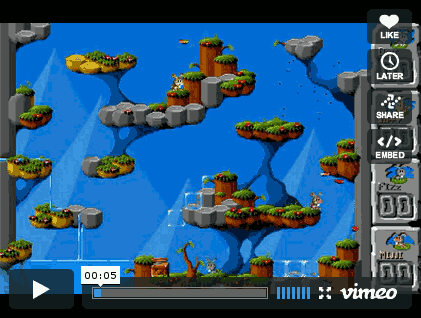
I discovered pySioGame for the first time in the first half of 2012, and even though it was still in a beta state, I liked it a lot. pySioGame is essentially a set of educational activities and games for kids. pySioGame was initially developed by its author -Ireneusz Imiolek- for his son, but he soon decided to make it Free Software. And I m glad that he did, because it s a very cute application. Even though -in it s author s own words- it s hard to put age range on this kind of games, it is primarily targeted to children from as young as 3 years old, up to about 10 years old. The activities included, many of which are grid based, cover topics like maths, reading, writing, painting, and memory activities, among others. I was finally able to upload pySioGame to Debian during the DebConf, and it has very recently hit the archive. I m convinced that pySioGame is soon going to be one of the references among the free programs for small kids, among titles such as GCompris, ChildsPlay, PySyCache, or Bouncy. Or, even though it s not in the archives, Omnitux. Finally, to whet your appetite, here is the link to a video, and there go some screenshots:

2 September 2013

Daniel Pocock: Australia's Labor Party exposed spying on their own members

Australia's Labor Party claims to represent the little guy, advocating the interests of a wide slice of the population over the interests of those who might supposedly exploit them. In this latest blog I'll look at just how the Victorian state branch of the party is emulating the more sinister elements of monitoring and control that you would typically expect from marketers, spammers and the NSA. It makes you wonder, if they do this to their own members, how can Australia's government ever hope to rein in spammers or other undesirable practices? Europe has tried cookie laws and the right to be forgotten, while the ALP has taken these developments almost as a guide to exploiting their own most valuable resource, their membership. The email version of invisible ink Straight out of an email attempting to recruit party members to the federal election campaign, we find that the ALP's logo itself has been turned into a sinister tracking mechanism. Looking underneath the logo, there is a hidden tracking number attached to every message:
http://gallery.mailchimp.com/3021e68df9a7200135725c633/images/Email_Header_ThisisLabor.jpg
There it is, that big long code 3021e68df9a7200135725c633. On it's own, you may think this number can't do much harm. Think again. After all, as the filename says, "ThisisLabor". Reaching the grass roots by long distance email When a party member sees any of the images in the email or clicks any of the links, their email software or web browser sends a HTTP request to the ALP's outsourced tracking server in the United States. Here is an example of what that request may contain:
TCP Headers:
  SOURCE IP ADDRESS: 198.51.100.56
HTTP headers:
  GET /3021e68df9a7200135725c633/images/Email_Header_ThisisLabor.jpg
  HTTP/1.1
  Host: gallery.mailchimp.com
  User-Agent: Mozilla/5.0 (X11; Linux x86_64; rv:17.0) Gecko/20130515 Firefox/17.0 Iceweasel/17.0.6
  Accept: text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8
  Accept-Language: en-US,en;q=0.5
  Accept-Encoding: gzip, deflate
  X-Forwarded-For: 192.168.1.54
  Connection: keep-alive
These codes are all transmitted from the recipient of the email back to the ALP. Notice the tracking number is in the very first line of the HTTP request? These codes send many details to the tracking server. Just what is revealed?
  • What time the message was read
  • How many times the message was opened
  • Whether the message was read on multiple computers (perhaps it was forwarded)
  • The IP addresses reveal which network was used.
    • For people reading email at work or on wifi, the IP address reveals the name of the employer, it can be easily looked up in this public database. Here is an example querying one of the ALPs own IP addresses, 203.24.72.2
    • For people using an internet connection at home, the IP address reveals the service provider. There is more to it though: if one party member regularly visits another party member and uses their wifi, they will both appear to be using the same IP address and the party will be able to deduce that there is a connection between these two people.
  • The web browser name and version and the operating system name and version.
  • The language normally used on the computer
Crunching the numbers You may think that nobody would be interested in all that data or that it is even too much data for anybody to easily study. Think again. The ALP has outsourced processing of this data to an offshore firm that specializes in bulk email, MailChimp. After lecturing everybody about the dangers of outsourcing, the ALP has literally sold the farm (their own membership data) - to a foreign marketing company. Here are some of the claims MailChimp make on their web site:
"Dig even deeper with Subscriber Activity Reports, which give you a real time report for every subscriber s email activities: when they opened, what they clicked, and when they came back for more. You can even generate a list of people who didn t open, and send them a modified campaign."
That's right: if ALP members don't read their emails fast enough, they will send even more of them. Just who has access to this data? Well, the scope is quite broad. According to these rules, it is not only the dubious officials in the party's state office, but Labor Party regulations also list a whole lot of other officials who have access to some subset of the data: branch and FEA district committees, policy committees and maybe some trade union officials too. Once you start to contemplate this, it becomes apparent that the probability of somebody profiling members at an individual level is very real. On the other hand, those rules clearly do not permit the state branch to process the member's data offshore. Double whammy In fact, even MailChimp is further outsourcing the data. When receiving an image from the booby-trapped link in the email, we receive a response like this:
HTTP/1.1 200 OK
Content-Type: image/jpeg
Content-Length: 407474
Connection: keep-alive
Date: Wed, 10 Jul 2013 06:25:55 GMT
Last-Modified: Tue,  03 Sep 2013 04:05:37 GMT
ETag: "df9a7200135725c6331369a22"
Accept-Ranges: bytes
Server: AmazonS3
Age: 62097
Via: 1.0 e71fe855f29513f54a41e213fe653fb1.cloudfront.net (CloudFront)
X-Cache: Hit from cloudfront
X-Amz-Cf-Id: S2V2aW4gUnVkZCBpcyBhIGJhZCBib3kuCg==
which contains more tracking numbers and clearly indicates that the data is being processed in the massive AmazonS3 (a.k.a Amazon online bookstore) cloud platform. Thanks to cloud computing, there is considerable scope for cross-referencing records across other web sites. The IP address becomes a magic key, allowing a range of sinister forces to join the dots at the click of a button and profile the whole private and professional identity of any individual ALP member. Googling ALP members It doesn't stop there however, after following these links a victim will eventually end up on one of the ALP's own web pages. Looking through the HTML code underneath http://www.viclabor.com.au is very easy, in most web browsers, you can just press Control-U to see what is hidden away in the shadows. Buried in the code, I found this little gem:
  var _gaq = _gaq   [];
  _gaq.push(['_setAccount', 'UA-35325645-1']);
  _gaq.push(['_trackPageview']);
  (function()  
    var ga = document.createElement('script'); ga.type = 'text/javascript'; ga.async = true;
    ga.src = ('https:' == document.location.protocol ? 'https://ssl' : 'http://www') + '.google-analytics.com/ga.js';
    var s = document.getElementsByTagName('script')[0]; s.parentNode.insertBefore(ga, s);
   )();
This may be even scarier: it's a JavaScript code that channels all access to the ALP web site into an outsourced tracking system provided by Google. Google can now cross-reference ALP members against their Gmail accounts, their friends and the topics they search for to further profile the type of advertising they should be exposed to. Google, like any private company, has a loyalty to its shareholders and the laws of the country where it is domiciled. Will that coincide with the best interests of ALP members in Victoria? Australia's other parties: samples needed Do you have similar communications from Australia's other political parties? Please send them to me and I'll be happy to examine them for similar shortcomings.

Steve Kemp: So that forum?

So that forum I mentioned? I've setup a test-installation at: What does this forum offer? A cross between hacker news and reddit. If the admin of the forums enables it you can create arbitrary tags, and then view them. For example: It's also very fast, and reasonably easy to customize. Which is good, because the current layout is nasty. Things I like: Not much more to say really; except I've setup a test install and if you wish to login/register and post spam feel free.

Francesca Ciceri: Gems from DebConf13 talks

"I think that we need to be better at accepting mistakes. It's OK to not know everything, it's OK to not be perfect right from the start, but it's better to be vocal about things you don't know, things you are unsure, than to just hide it under the carpet and hope nobody will notice."
Lucas Nussbaum, Bits from the DPL "This is my definition for a team: waking up in the morning and realizing that somebody else has solved your problem from yesterday."
Andreas Tille, How to attract new developers for your team
While working on English subtitles for DC13 talks, you can stumble upon some real gems. The subtitling work is progressing nicely: four talks have now subtitles available (you can find them here), thanks to the work of Daniel, Gunnar and myself (as well as the reviews from Justin, Andreas and Michael!). In the meanwhile we created an alioth group and a related repository for the sub team, and there are several subtitles in progress! How can you help?

Dmitrijs Ledkovs: My Debian Activities: Multiarch & upstart on kFreeBSD hacking

Looks like there is a recent trend to publicize one's debian activities, so I thought I should join in =) Not so sure if MDA acronym would work for these types of posts...
MultiarchI have been working on multi-arching additional libraries. In particular I am working on multiarching boost libraries. At the moment boost1.53 multiarched libraries are uploaded in the experimental, and I am still working out the quirks with those. At the same time I have submitted a patch to multiarch libicu-dev, which has been accepted by the maintainer and is currently waiting in new queue. This brings us closer to multiarching all of boost libraries. But as it has been pointed out at the Multiarch BOF at Debconf'13, one doesn't have to wait for dependencies (be it libs or lib-devs) to be Multiarched before multi-arching your own library. If you do it right (put all or arch-specifi headers in multiarch location, and place libraries in multiarch location, split utilities into a separate package), you can go and multiarch your libraries ahead of time. Maybe it's time to default to debhelper 9 in dh-make, and default to multiarch locations for all libraries?

Boost also has libraries which depend on mpi, and at the moment that's not multiarched. I'm not sure if there are additional considerations there given the support for alternative mpi implementations in Debian.

Boost also depends on libpython. At the moment it's shipping libboost_python-py2.7.so & libbost-py3.3.so, with a libboost_python.so symlink to libbost_python-py2.7.so. I do wonder if it's a sensible approach, or should the boosty_python library be simply shipped in arch specific & python implementation specific paths e.g. /usr/lib/pythonX.Y/config-X.Y$(abi_tag)-$(DEB_HOST_MULTIARCH)/ that way we'll be able to support python debug interpreter in python_boost. I guess I should seek expert opinion on other multiarch wizards.

In addition to boost, I've now started looking at qmake and how it handles multiarch. At the moment, it doesn't handle it much. All paths are statically copied around and hard-coded in each module qmake provides. I have now been working at abusing qmake's $$system to call into dpkg-architecture, and actually choose native or cross compiler & adjust settings and paths to Qt libraries. There are a couple of bugs to fix, but I should be able to propose a "debian-multiarch" qmake spec soon. Such that in calls dpkg-architecture & properly adjust compilers & locations for the DEB_HOST. qmake by the way has its quirks. For example all variable assignments seemed to default to be "by value" & not "by reference" (i.e. upon assignment all variables on the right hand side get expanded and the literal string is stored, instead of storing $(prefix)/lib/$(arch), and evaluating that later.) Hence my current qmakespec is less elegant than I hoped.
upstart on kFreeBSDFreeBSD 9.2 and up have implemented the wait6 and with it waitid is also exposed. At the moment there are some differences between glibc and FreeBSD waitid usage. I am not well versed in glibc, FreeBSD and POSIX, but the bug at hand & POSIX reference lead me to believe that POSIX is slightly ambiguous about it.

Why is waitid support is interesting? Well, kFreeBSD/libc maintainer in Debian is working on exposing it with/after (e)glibc2.18 is in Debian, which will remove one more blocker from porting Upstart to kFreeBSD. To this extend, I have in the mean time setup FreeBSD & kFreeBSD virtual machines and got libnih to compile on both (sans waitid on kFreeBSD). One of the optional upstart's features is to use inotify to spot & reload configuration files, at the moment I haven't ported that functionality to use native kevent/kqueues (EVFILT_AIO) instead I have cheated and packaged for Debian the Google Summer of Code 2011 project libinotify-kevent which provides inotify compatible API, implemented with kevent. Which is kind of the reverse strategy of libkqueue and/or libevent. It would be interesting to see kernels and/or those libraries to unify/standartise on common APIs. Unfortunately, it still seems like using native API for each kernel is best to avoid dependencies and leverage all features and semantics. Nonetheless I did package it for now. To further progress with actually porting upstart, I'd like to get my hands at (e)glibc 2.18 compiled for kFreeBSD with waitid patches. I got pointers to the patches, but I haven't yet succeeded at compiling (e)glibc with those applied. So no upstart booting kFreeBSD VM yet, but rather work in progress. It's quite fun. It's been years since I have touched a FreeBSD boxes and it's first time me using kFreeBSD. The semantics, differences and benefits of each do shine and it's a promising platform.
Multiarch on kFreeBSD?
Given the excellent multiarch implementation on Debian and sophisticated Linux Emulation Layer on FreeBSD kernel, I was half expecting the following to work:
  • on kFreeBSD enable linux i386/amd64 repository
  • apt-get install hello:i386
  • $ hello
But unfortunately this confused kFreeBSD, since it didn't find ELF tags and linker didn't seem to load the right libraries any more =( Not sure if this issue has been raised before, but I think it would be awesome if FreeBSD Linux Emulation Layer worked transparently on Debian/kFreeBSD multiarch system.

B lint R czey: Faketime gets nanosecond timestamps, speeds up games, testing

I was playing with faketime the last few days mainly to implement features needed by ReproducibleBuilds, which is an initiative in Debian for providing binary packages that can be regenerated with the exact same content. Some build steps place timestamps in the resulting binaries, thus we may have to make time perceived by the build process move at a deterministic rate starting from a predetermined point in time.
This is why faketime got support for advancing time with each time(), gettimeofday(), etc. call. Another approach would be recording timestamps perceived by the first build and replaying them in the same order to successive builds. If the build is deterministic apart from the timestamps, this should result in the same binary package for each build.
While playing with faketime I could not resist implementing a few things which may not have been absolutely important for reproducible builds, but were so much fun. The nanosecond resolution of timestamps made games playable at slower or faster speeds making very hard games easier or easy games harder. Jump n'bump just became insanely funny at 200% speed:

jumpnbump-video-screen

faketime -f "+0 x2" jumpnbump Speeding up sleep()-s can also be useful in daily work. If your application calls sleep() often it may significantly slow down testing, but faketime is now able to shorten sleeps, too, speeding up testing such applications!

1 September 2013

Jamie McClelland: If you don't know what a quine is, consider yourself lucky

rhatto just asked me to approve a change in keygringer's license from AGPLv3+ to GPLv3+ citing a discussion about a Berkeley DB's switch to AGPLv3. For some reason, a reference to a quine caught my eye. If you don't know what a quine is, I suggest you remain ignorant. I won't even provide the Wikipedia link. A quick web search suggests that it's quite possible to write one in bash. I hope to be productive again some day.

Eddy Petrișor: Integrating Beyond Compare with Semanticmerge

Note: This post will probably not be on the liking of those who think free software is always preferable to closed source software, so if you are such a person, please take this article as an invitation to implement better open source alternatives that can realistically compete with the closed source applications I am mentioning here. I am not going to mention here where the open source alternatives are not up to the same level as the commercial tools, I'll leave that for the readers or for another article.


Semanticmerge is a merge tool that attempts to do the right thing when it comes to merging source code. It is language aware and it currently supports Java and C#. Just today the creators of the software have started working on the support for C.

Recently they added Debian packages, so I installed it on my system. For open source development Codice Software, the creators of Semanticmerge, offers free licenses, so I decided to ask for one today, and, although is Sunday, I received an answer and I will get my license on Monday.

When a method is moved from one place to another and changed in a conflicting way in two parallel development lines, Semanticmerge can isolate the offending method and can pass all its incarnations (base, source and destination or, if you prefer, base, mine and theirs) to a text based merge tool to allow the developer to decide how to resolve the merge. On Linux, the Semanticmerge samples are using kdiff3 as the text-based merge tool, which is nice, but I don't use kdiff3, I use Meld, another open source visual tool for merges and comparisons.


OTOH, Beyond Compare is a merge and compare tool made by Scooter Software which provides a very good text based 3-way merge with a 3 sources + 1 result pane, and can compare both files and directories. Two of its killer features is having the ability split differences into important and non-important ones according to the syntax of the compared/merged files, and the ability to easily change or add to the syntax rules in a very user-friendly way. This allows to easily ignore changes in comments, but also basic refactoring such as variable renaming, or other trivial code-wide changes, which allows the developer to focus on the important changes/differences during merges or code reviews.

Syntax support for usual file formats like C, Java, shell, Perl etc. is built in (but can be modified, which is a good thing) and new file types with their syntaxes can be added via the GUI from scratch or based on existing rules.

I evaluated Beyond Compare at my workplace and we decided it would be a good investment to purchases licenses for it for the people in our department.


Having these two software separate is good, but having them integrated with each other would be even better. So I decided I would try to see how it can be done. I installed Beyond compare on my system, too and looked through the examples


The first thing I discovered is that the main assumption of Semanticmerge developers was that the application would be called via the SCM when merges are to be done, so passing lots of parameters would not be problem. I realised that when I saw how one of the samples' starting script invoked semantic merge:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java -edt="kdiff3 \"#sourcefile\" \"#destinationfile\"" -emt="kdiff3 \"#basefile\" \"#sourcefile\" \"#destinationfile\" --L1 \"#basesymbolic\" --L2 \"#sourcesymbolic\" --L3 \"#destinationsymbolic\" -o \"#output\"" -e2mt="kdiff3 \"#sourcefile\" \"#destinationfile\" -o \"#output\""
Can you see the problem? It seems Semanticmerge has no persistent knowledge of the user preferences with regards to the text-based merge tool and exports the issue to the SCM, at the price of overcomplicating the command line. I already mentioned this issue in my license request mail and added the issue and my fix suggestion in their voting system of features to be implemented.

The upside was that by comparing the command line for kdiff3 invocations, the kdiff3 documentation and, by comparison, the Beyond Compare SCM integration information, I could deduce what is the command line necessary for Semanticmerge to use Beyond Compare as an external merge and diff tool.

The -edt, -emt and -e2mt options are the ones which specify how the external diff tool, external 3-way merge tool and external 2-way merge tool is to be called. Once I understood that, I split the problem in its obvious parts, each invocation had to be mapped, from kdiff3 options to beyond compare options, adding the occasional bell and whistle, if possible.

The parts to figure out, ordered by compexity, were:

  1. -edt="kdiff3 \"#sourcefile\" \"#destinationfile\"

  2. -e2mt="kdiff3 \"#sourcefile\" \"#destinationfile\" -o \"#output\""

  3. -emt="kdiff3 \"#basefile\" \"#sourcefile\" \"#destinationfile\" --L1 \"#basesymbolic\" --L2 \"#sourcesymbolic\" --L3 \"#destinationsymbolic\" -o \"#output\""

Semantic merge integrates with kdiff3 in diff mode via the -edt option. This was easy to map to Beyond Compare, I just replaced kdiff3 with bcompare:
-edt="bcompare \"#sourcefile\" \"#destinationfile\""
Integration for 2-way merges was also quite easy, the mapping to Beyond Compare was:
-e2mt="bcompare \"#sourcefile\" \"#destinationfile\" -savetarget=\"#output\""
For the 3-way merge I was a little confused because the Beyond Compare documentation and options were inconsistent between Windows and Linux. On Windows, for some of the SCMs, the options that set the titles for the panes are '/title1', '/title2', '/title3' and '/title4' (way too descriptive for my taste /sarcasm), but for some others are '/lefttitle', '/centertitle', '/righttitle', '/outputtitle', while on Linux the options are the more explicit kind, but with a '-' instead of a '/'.

The basic things were easy, ordering the parameters in the 'source, destination, base, output' instead of kdiff3's 'base, source, destination, -o ouptut', so I wanted to add the bells and whistles, since it really makes more sense for the developer to see something like 'Destination: [method] readOptions' instead of '/tmp/tmp4327687242.tmp', and because that's exactly what is necessary for Semanticmerge when merging methods, since on conflicts the various versions of the functions are placed in temporary files which don't mean anything.

So, after some digging into the examples from Beyond Compare and kdiff3 documentation, I ended up with:
-emt="bcompare \"#sourcefile\" \"#destinationfile\" \"#basefile\" \"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic' -centertitle='#basesymbolic' -outputtitle='merge result'"

Sadly, I wasn't able to identify the symbolic name for the output, so I added the hard coded 'merge result'. If Codice people would like to help with with this information (or if it exists), I would be more than willing to do update the information and do the necessary changes.

Then I added the bells and whistles for the -edt and -e2mt options, so I ended up with an even more complicated command line. The end result was this monstrosity:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java -edt="bcompare \"#sourcefile\" \"#destinationfile\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic'" -emt="bcompare \"#sourcefile\" \"#destinationfile\" \"#basefile\" \"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic' -centertitle='#basesymbolic' -outputtitle='merge result'" -e2mt="bcompare \"#sourcefile\" \"#destinationfile\" -savetarget=\"#output\" -lefttitle='#sourcesymbolic' -righttitle='#destinationsymbolic'"
So when I 3-way merge a function I get something like this (sorry for high resolution, lower resolutions don't do justice to the tools):


I don't expect this post to remain relevant for too much time, because after sending my feedback to Codice, they were open to my suggestion to have persistent settings for the external tool integration, so, in the future, the command line could probably be as simple as:
semanticmergetool -s=$sm_dir/src.java -b=$sm_dir/base.java -d=$sm_dir/dst.java -r=/tmp/semanticmergetoolresult.java
And the integration could be done via the GUI, while the command line can become a way to override the defaults.

Gregor Herrmann: RC bugs 2013/35

& another week of perl (5.18) related bugs has gone by:

Raphaël Hertzog: My Free Software Activities in August 2013

This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (47.50 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. Package Tracking System There are only 2-3 weeks left in the summer of code project dedicated to rewrite the package tracking system. We have come a long way during August check it out yourself in pts.debian.net. The rewrite doesn t have all the features of the old PTS yet, but I opted to keep some of the easy and less interesting features for others to re-implement. Instead I asked Marko to work in the coming weeks on new features that will bring more value, like the possibility to have user accounts with the possibility to easily review and tweak all your subscriptions on the web, and like the possibility to subscribe to groups of packages (i.e. those managed by a team). Our main problem right now is that exim has a pretty poor default behavior of forking hundreds of processes if you get hundreds of mails (in a batch) to an address that delivers via a pipe (postfix is saner, it serializes the deliveries on pipes). The new PTS is much more modular and its memory footprint is bigger (about 3 times more for the process that delivers mails, 30Mb instead of 10Mb), and in such a situation we managed to run out of memory for now we worked around the situation with an exim setting that queues mails once the load gets too high but it s a poor workaround IMO. We could obviously implement our own queue and a daemon but I d like to avoid this. So who knows how to tell exim to behave? :-) On the positive side, Marko has gotten some feedback from people who like the new PTS and are using it daily already. And several persons have expressed their interest to work on the new codebase already. On my side, I created a package so that it s easy to deploy for derivatives. In this process, I revamped the way we manage the Django settings (for development and for production). The package is not finished yet, but it s mostly usable already. But I still want to do some cleanup/refactoring in the models before others start deploying it. We must also enable South to make it possible to upgrade easily afterwards. DebConf 13 in Vaumarcus From August 10th to 17th, I was attending DebConf 13. It matched the only week of vacation that my wife had this summer so we went there with the whole family (that is with a 3 years old son, and 6 months old one). Thus I could not immerse myself in Debconf and missed all the nice things that happen outside of the talk rooms. I picked 3-4 interesting talks per day and I spent the rest with my family. On the positive side, I was pleased that my wife could meet (or at least see) some other Debian people. She knows quite a few (of you) by name because I have been telling her Debian stories for years now Debian France Debian France sold quite some merchandise during Debconf but I didn t take care of that. It was supervised by Sylvestre Ledru but fortunately he got the help of multiple persons, both to bring everything there, to sell it, and to bring back the rest. The good news of the month is that the upstream author of galette published a new version with all the features that we ordered him a few months ago. We send now automatic reminders to members who must renew their subscription, we have automatic update of our accounting books (in a ledger file in a git repository) when we people donate or pay their subscription via the paypal form on our website. I was so pleased to finally have this that I took some hours to finalize the packaging of galette, so that it could be uploaded to Debian. It s now waiting in the NEW queue. I also spent multiple hours to write the python script that is executed by galette and that updates the accounting files. Misc Debian stuff Debian Packaging. I did two uploads of logidee-tools to fix bugs #718671 and #718836. I created a package for Dolibarr a PHP-based CRM and ERP software (it doesn t do accounting however), it s sitting in the NEW queue for almost a month already. I forwarded #719000 to the upstream Publican developers. I filed #720393 to request a new upstream version of libphp-mailer. git-multimail. After its deployment on Alioth last month, Niels Thykier reported me a case where it lead to bounces, I filed this as a new upstream ticket and in fact I fixed it myself a few days after. I got the fixed version installed on Alioth. dpkg. I investigated why the the automatic builds of dpkg were no longer happening and asked Michael Prokop if he could install a newer version of gettext in the build chroot. He told me that he would need a backport for that so I asked Santiago Vila if he was willing to provide it and he kindly accepted. A few days after, the package was in backports and I m now again running the latest dpkg out of git thanks to the nice service provided by Michael. Misc discussions. The thread about user planets drifted into a discussion of how to avoid promotional posts on such planets and in that context someone again brought up the Debian Machine Usage Policy as a way to shut down any kind of (self-)promotional content on planet if there s money involved. This always irritates me and this time I opted to ask James Troup about the origin of that clause in the DMUP. So who is willing to work with DSA to fix the DMUP so that people stop abusing it in contexts where it doesn t make sense? I also participated in some discussions concerning dgit. I like the ideas behind the tool, but I m saddened by the behavior of Ian Jackson. I helped him to fill his gap of knowledge about new sources formats but he keeps on bashing about the 3.0 (quilt) source format both in the manual page and in the output of the program. He believes that dgit is no longer an experiment but the truth is that it s still a poorly commented Perl script doing lots of hackish things. Kali Linux Between Debconf and all, I haven t done much for Kali except a couple of fixes. There s a nice story of how I tracked a bug in live-installer on the Kali blog. That fix has been committed to Debian. I also improved live-build to include xfsprogs/jfsutils on the ISO image when you include the debian-installer (so that you don t end up in problems when you pick JFS or XFS as file systems for your installation). Thanks See you next month for a new summary of my activities.

One comment Liked this article? Click here. My blog is Flattr-enabled.

Paul Tagliamonte: Recent life in paultagland

I ve been pretty absent from the net over the last 3 weeks, (and for the first time in well over a year, I missed a week of blogging) I ve been pretty busy with real-life-stuff, nothing ultra interesting to report, I ve been working away with the ftpteam more (as I m sure some of you have noticed), and doing Hy work when I can. Nothing major on either front yet :)

Ritesh Raj Sarraf: Laptop Mode Tools 1.64

I just released Laptop Mode Tools @ version 1.64. And am pleased to introduce the new graphical utility to toggle individual power saving modules in the package. The GUI is written using the PyQT Toolkit and the options in the GUI are generated at runtime, based on the list of available power saving modules. Apart from the GUI configuration tool, this release also includes some bug fixes:
  • Don't touch USB Controller power settings. The individual devices, when plugged in, while on battery, inherit the power settings from the USB controller
  • start-stop-programs: add support for systemd. Thanks to Alexander Mezin
  • Replace hardcoded path to udevadm with "which udevadm". Thanks to Alexander Mezin
  • Honor .conf files only. Thanks to Sven K hler
  • Make '/usr/lib' path configurable. This is especially useful for systems that use /usr/lib64, or /lib64 directly. Thanks to Nicolas Braud-Santoni
  • Don't call killall with the -g argument. Thanks to Murray Campbell
  • Fix RPM Spec file build errors
The Debian package will follow soon. I don't intend to introduce a new package for the GUI tool because the source is hardly 200 lines. So the dependencies (pyqt packages) will go as Recommeds or Suggests

AddThis:

Categories:

Keywords:

Andrew Pollock: [life] My first Bridge to Brisbane

One of the goals I set for myself on returning to Brisbane was running in the Bridge to Brisbane. The City2South run ended up being a longer distance, sooner, so I only stuck with the Bridge to Brisbane so I could say I'd done it. The added variable was I had Zoe, and I was pushing her in a jogging stroller. I did a couple of practice runs up the bridge with Zoe in the weeks leading up to the run. Mostly to get her used to it, and for me to get a feel for what the incline was like. I found I had the stamina to easily do the bridge, but ran out of steam on the return leg. No big deal, I didn't need to do that for the real run. I did a poor job of publicising that I was doing the run, so I didn't end up raising a whole lot of money for my chosen charity, beyondblue, because I had the added variable of Zoe. I knew I had to get her up early to get to the start line in time, and I wasn't sure if she was going to be cooperative or not, or whether she'd have a tantrum half way through the run and I'd have to stop, so I didn't feel good about taking money from people for running a run that I wasn't sure I could complete. My main concern had been getting to the starting line in time. I wanted to take the train from Morningside to Murarrie and then walk to the start line (about 10 minutes) because that way I could take the train back to Morningside from the finish to collect the car and not have to worry about trying to get back to the start. That meant I'd have to get Zoe up before 5am to get to the station, and if she didn't cooperate, I'd miss the train, and it'd all be over. Fortunately, my cousin Renata offered to drop us off, and we did a complicated car switcharoo, which involved her leaving my car at Morningside station for me after dropping us off at Murarrie. Now that I've seen the road closure situation, I feel pretty confident that I could have just driven to Murarrie and ditched the car somewhere there. Interestingly, a train that was packed to the rafters with people was arriving at the station at the time we arrived to leave Renata's car there. I'm not sure if it was the 5:07am train running late, or if I'd mis-interpreted the timetable and there was a later train we could have more comfortably made without Renata's assistance. Anyway, we uneventfully got to Murarrie station by about 5:40am, and walked to the start. It was ridiculously packed. People as far as the eye could see. Apparently there were 29,479 entrants and 24,596 finishers in the 10km run, so that explains it. I was seeded in the "joggers" group, which was a fair way back from the start line, and as it was, technically had to walk around some massive barrier to get in with the runners, but I snuck in the side after the pack started moving. Zoe was really, really good for the whole run. I couldn't have asked for her to be better behaved, really. She was wanting a cuddle at the top of the bridge, and claimed she wanted to go to the toilet the first time she saw some portable toilets, but easily talked out of both. My strategy of having a broad array of snacks for her to eat during the run worked well to keep her happy, and the course was heavily packed the entire way, so she had plenty to look at. It was a nice father/daughter thing to do for Fathers Day. My official time was 57:28, which I'm extremely happy with, given the conditions I ran under. I was going to be happy with anything under an hour. My personal best for 10km (not that course) is 51:52 I'm very grateful to those people who did donate some money on short notice. I've managed to raise $180, which is better than nothing. Now that I've done the run, and seen how it works, I'm game to try it again next year, and I'm game to do more 10km runs with Zoe. My running overall has been going very well, and so I think it's time to step things up a bit and I've decided to set myself a goal of running the half-marathon in the Gold Coast Marathon next year.

Russ Allbery: Review: An Artificial Night

Review: An Artificial Night, by Seanan McGuire
Series: October Daye #3
Publisher: DAW
Copyright: September 2010
ISBN: 1-101-44276-X
Format: Kindle
Pages: 368
This is the third book of the October Daye series, following A Local Habitation. It could be read out of order, as each chapter of Toby's story so far is somewhat standalone, but I wouldn't recommend it. You'd miss the character development and the background behind several friendships. As with the previous book review, a caveat: I am reviewing this book four months after finishing it, rather than the normal couple of weeks, so apologies in advance for any thinness or inaccuracies. The first sign that something is about to go seriously wrong in Toby's life this time is a visitor. She says her name is May Daye, and apparently she's Toby's Fetch: a duplicate in nearly every respect except personality, manifested to guide someone to their death. Their imminent death. The second sign is that her best friend's children are kidnapped. The children who treat her like an aunt. And the cause of that kidnapping is far, far beyond the level of power that Toby could be expected to deal with. I have profound mixed feelings about this book. On one hand, McGuire further expands Toby's web of connections and shows us more of Toby's friends and their background, and that's becoming my favorite part of this series. She introduces May, who I think is a great character: at first apparently much different than Toby, but with a similarity beneath surface impressions that one notices more over time. And I thought the climax of the story, once we finally got there, was very moving and well-done. Also, I just love the way that McGuire uses children's rhymes and doggerel throughout this series as a magical element, and that's particularly well-handled here. Due to the nature of the antagonist, McGuire has a good excuse to bring that front and center, and the process of familiar rhymes expanding into deep magical rules was a fun intellectual experience. Best of all, the Luidaeg plays a significant role in the story again. The Luidaeg is, hands down, my favorite character in McGuire's constructed universe, and she becomes even more so over the course of this story. Her complex relationship with Toby is clearly blossoming into a friendship that's surprising both of them deeply, but a friendship that has to play by an odd set of rules (like so much else in Toby's life). I loved her here. Seeing someone that difficult and abrupt show unexpected emotional depths is one of the story elements I enjoy the most. The problem, though, is that quite a lot of An Artificial Night is very, very dark. And by that, I don't mean that there is a lot of tension, or that Toby is struggling against monsterous things, although both of those statements are also true. Rather, Toby is not only out of her league but ends up in some viciously nasty situations, and they persist for rather more of this book than I would have preferred. Putting one's protagonist through hell has a long tradition in urban fantasy, but I found the level of sheer helplessness that Toby struggled through to be a bit more than I wanted to read about. It was too reminiscent of events from Toby's background (as discussed in Rosemary and Rue) that I still don't like to think about. There is, of course, an eventual payoff, as dark as the interim events seem. One knows that, given the genre and given that this is an ongoing series, and even just given the nature of stories. But as much as I like the growing cast of this series, and adored the scenes with the Luidaeg, I found parts of this journey to be deeply disturbing, and not in an enjoyable dramatic tension sort of way. I don't mind protagonists being seriously hurt (although it's not my favorite plot), or even some amount of despair, but this went beyond that. I think McGuire was going for a story about sacrifice and self-definition, about trying even when one can't possibly win, and I can appreciate the narrative arc. But parts of the book were simply awful to read for me. I'm therefore not quite sure what to say in terms of a recommendation. I'm still reading the series, and will definitely read the next book. I think my reaction is somewhat idiosyncratic; the events here will probably not bother others as much as they bothered me. And I can't disagree with their dramatic effectiveness, or with the way that McGuire builds conflict out of the rules of fairy and is building Toby into a stronger and more capable person than she ever thought she could be. But there were still spots where I wished I were reading a different book. Hopefully the next book in the series will be that book I wanted to read. Followed by Late Eclipses. Rating: 6 out of 10

Russ Allbery: Review: Redshirts

Review: Redshirts, by John Scalzi
Publisher: Tor
Copyright: June 2012
ISBN: 1-4299-6360-3
Format: Kindle
Pages: 317
The next few reviews deserve a small apology in advance. Normally, I try to write reviews within a few weeks, or at most a month, after reading a book, while it's still fresh in my mind. This is particularly important since I read a lot and sometimes don't have a good memory for specific detail. But this summer has made it completely impossible to keep to any sort of regular writing schedule. As a result, this book, and the subjects of the next few reviews that follow, are books that I read four months ago and am reviewing from memory. Hopefully, I'll still get the details right. Ensign Andrew Dahl is one of the newest crew members of the Universal Union Capital Ship Intrepid. It's his first posting, just out of the Academy. He's one of five new ensigns, expecting a normal tour of duty (albeit with the pride of being on a capital ship of the fleet). But very shortly after arriving on the ship, Andrew and and the other new ensigns discover that something is very... strange. The casualty rate on the ship is surprisingly high (as foreshadowed in a prologue). The other crew members avoid the bridge crew, and particularly away missions, with startling effectiveness (and desperation). And things regularly happen on the ship that, for lack of a better description, simply make no sense. Redshirts starts off as a very obvious Star Trek parody. So obvious, in fact, that it's eyeroll-inducing. The prologue reads exactly like a section of a Star Trek episode written by a third-rate hack, leavened with some of the humor that readers of Scalzi's blog have come to expect. But it's obvious that Scalzi is doing this intentionally, and it doesn't take long before the subject of the book shifts. It's a Star Trek parody that functions much more like a Star Trek parody than any universe should, to the degree that it becomes obvious to the characters. And the characters, despite being straight from central casting, are clearly not expecting their universe to act that way and find this extremely strange. By far the best part of this book is the second quarter: the characters have been introduced, they're starting to figure out what's going on, and they have to do so while dodging away-team duty (or trying to survive it) and participating in the ridiculous plot contrivances that keep occurring. Scalzi mixes a feeling of serious consequences with wry humor and handles the mix deftly. I was both laughing and eagerly reading to see what comes next. The last half of the book, though, has problems. How many problems the reader perceives will, I think, depend on how hard one thinks about the situation Scalzi has set up, or how much one has thought about similar constructs in the past. But I'm afraid the setup does not survive serious scrutiny in ways that, for me at least, seriously damaged my ability to engage with the story. I'm going to avoid saying explicitly where Scalzi goes with this plot, since it is a spoiler (although it's commonly mentioned in discussions of this book on the Internet). But it happens to be an idea that some friends of mine and I pounded on for years in some of our role-playing scenarios, poking at the corners and implications, and subsequently gave up on because it doesn't work for storytelling. The idea is compelling, and on first glance seems like a great story seed. But it's too large. The problem with really big ideas with huge implications is that they can change the nature of a story so much that there's no longer any point of commonality for the reader and the entire nature of story falls apart. And I think that's what happens here. Scalzi handles the deeper implications of the concept by, essentially, ignoring them. He focuses on one narrow set of implications for one specific set of people, largely skips over any discussion of anything larger, and tries a pivot from wry humor (and a bit of slapstick) into serious emotional depth. For me, in part because I'm so familiar with the concept, none of this really worked. The implications of the discovery that drives this story are so much broader and so much more significant than the characters seem to admit that it threw me right out of the story. The ethical implications are absolutely paralyzing, to the point that I don't think you can write a coherent story about them, but ignoring them doesn't work either. It's the kind of discovery that requires action of some kind beyond the attempt by the characters to go back to what they consider a normal life, even if I have a hard time imagining what that action could be. To be fair, he does try to salvage this in the first epilogue, which is all about the implications of his idea and its effects. But it's still too small. That epilogue just barely touches on the implications on a single person, but if one thinks a bit longer, one starts coming up with more and more implications for all of society, for how we talk about story, for how we raise children, for nearly every form of creativity. Implications that involve nasty concepts like slavery and mind control and murder and the nature of consent in ways that are very difficult to avoid. I think Scalzi's attempts at serious emotional connection, including in the other two attached epilogues (which are perspective-shifting close focuses on some of the characters), also suffer from his world setup, but in a different way. The characters are simply too bland to sustain the level of emotional connection he's striving for. They're bland for a very specific reason that is entirely justified by the story that Scalzi is handling, and the implications of that for the primary protagonist were, I thought, one of the best-handled moments of the book. But they're still bland, which undermines the attempted pivot. All that being said, this is not a bad book. Parts of it, particularly the second quarter, are excellent. And even when I wasn't engaging with the characters, Scalzi's writing on a paragraph level is snappy and often quite funny. The first epilogue in particular is hilarious, even if I think it was too limited in the scope of implications that it considers and a bit too meta in where it goes with those implications. And the story is a fun romp, with drama and humor and tension and a fairly satisfying ending. Everyone's a bit too bland and earnest when Scalzi isn't being funny, but he's funny enough that I didn't mind that much. Despite the relatively low rating, I actually recommend this book. If you don't dive into the metaphysical implications, it's a lot of fun, and if you've thought a lot about this particular set of metaphysical implications, it's somewhat satisfying to argue with (and to internally point out all of the hard questions that Scalzi is skipping over). It's particularly fun if you've watched a lot of Star Trek, since Scalzi gets some of the absurdities note-perfect. But be aware that the character reactions to Scalzi's concept don't hold up to much scrutiny. Rating: 7 out of 10

31 August 2013

Chris Lamb: Decrypting the Caesar cipher using shell

In cryptography, a Caesar cipher, also known as Caesar's cipher, the shift cipher, Caesar's code or Caesar shift, is one of the simplest and most widely known encryption techniques. It is a type of substitution cipher in which each letter in the plaintext is replaced by a letter some fixed number of positions down the alphabet. [...]
#!/bin/sh
IN="MJHVIZN ZPIO YJHPN"
for I in $(seq 25); do
    echo $I $IN   tr $(printf %$ I s   tr ' ' '.')\A-Z A-ZA-Z
done
This outputs:
1 NKIWJAO AQJP ZKIQO
2 OLJXKBP BRKQ ALJRP
3 PMKYLCQ CSLR BMKSQ
4 QNLZMDR DTMS CNLTR
5 ROMANES EUNT DOMUS
6 SPNBOFT FVOU EPNVT
7 TQOCPGU GWPV FQOWU
8 URPDQHV HXQW GRPXV
9 VSQERIW IYRX HSQYW
10 WTRFSJX JZSY ITRZX
11 XUSGTKY KATZ JUSAY
12 YVTHULZ LBUA KVTBZ
13 ZWUIVMA MCVB LWUCA
14 AXVJWNB NDWC MXVDB
15 BYWKXOC OEXD NYWEC
16 CZXLYPD PFYE OZXFD
17 DAYMZQE QGZF PAYGE
18 EBZNARF RHAG QBZHF
19 FCAOBSG SIBH RCAIG
20 GDBPCTH TJCI SDBJH
21 HECQDUI UKDJ TECKI
22 IFDREVJ VLEK UFDLJ
23 JGESFWK WMFL VGEMK
24 KHFTGXL XNGM WHFNL
25 LIGUHYM YOHN XIGOM
The only line which makes sense is 5 ROMANES EUNT DOMUS, giving us our solution.

Chris Lamb: Decrypting the Caesar cipher using shell

In cryptography, a Caesar cipher, also known as Caesar's cipher, the shift cipher, Caesar's code or Caesar shift, is one of the simplest and most widely known encryption techniques. It is a type of substitution cipher in which each letter in the plaintext is replaced by a letter some fixed number of positions down the alphabet. [...]
#!/bin/sh
IN="MJHVIZN ZPIO YJHPN"
for I in $(seq 25); do
    echo $I $IN   tr $(printf %$ I s   tr ' ' '.')\A-Z A-ZA-Z
done
This outputs:
1 NKIWJAO AQJP ZKIQO
2 OLJXKBP BRKQ ALJRP
3 PMKYLCQ CSLR BMKSQ
4 QNLZMDR DTMS CNLTR
5 ROMANES EUNT DOMUS
6 SPNBOFT FVOU EPNVT
7 TQOCPGU GWPV FQOWU
8 URPDQHV HXQW GRPXV
9 VSQERIW IYRX HSQYW
10 WTRFSJX JZSY ITRZX
11 XUSGTKY KATZ JUSAY
12 YVTHULZ LBUA KVTBZ
13 ZWUIVMA MCVB LWUCA
14 AXVJWNB NDWC MXVDB
15 BYWKXOC OEXD NYWEC
16 CZXLYPD PFYE OZXFD
17 DAYMZQE QGZF PAYGE
18 EBZNARF RHAG QBZHF
19 FCAOBSG SIBH RCAIG
20 GDBPCTH TJCI SDBJH
21 HECQDUI UKDJ TECKI
22 IFDREVJ VLEK UFDLJ
23 JGESFWK WMFL VGEMK
24 KHFTGXL XNGM WHFNL
25 LIGUHYM YOHN XIGOM
The only line which makes sense is 5 ROMANES EUNT DOMUS, giving us our solution.

Christian Perrier: DebConf 13: running outcome

This DebConf has been the first one where I ran every day. That proved to be kinda hard on some mornings, but I found a way to circumvent that by proposing group runs at the end of the relevant days. In total, I managed to run 12 days in a row, for a grand total of 186.88km, in 21h22', for a total height difference of 6972m. In short, I nearly climbed Mount Aconcagua, Americas highest peak..:-) Most of these runs were quite slow ones and rather "short" ones (around 15km), because of the nature of the paths around (nearly impossible to find something flat except by running around the football field). The longest run was for the DayTrip, with about 25km in about 4 hours (including some pauses) and 1600m height difference. I'm definitely working on my moutain running skills more than marathon and other kind of "speed" races. That followed a great results for my last race, the "EDF Cenis Tour" 50km trail race in Lanslebourg, French Alps, where I completed the race in 6h38, nearly the sametime than Mont-Blanc marathon, 1 month earlier....which was 8 kilometers shorter. I'm apparently ready for very long distance mountain races, now, as it seems. Thanks you DebConf 13 organizers for choosing such a great locations for us, crazy runners. And, despite that, my next running goal is a "classical" marathon, the Toulouse marathon in late October, where I expect breaking the 3h30 barrier, that would indeed be a qualifier for the Boston Marathon, one of my dreams for the future (and, yes, it is still a dream, despite this year's events).

Christian Perrier: DebConf 13: hacking outcome

I *did* some hacking at DebConf, as usual. For once, I had no TODO list: after all, I never complete these, so why make one? Still, I participated to discussions around samba packaging, mostly animated by Ivo De Decker and I think we're making good progress towards samba 4.x packages. The road is long, quite complicated, but we now have a stronger team, with a very active Ivo, Jeroen Dekkers who officially joined, Steve Langasek who still cherishes one of his pet packages (and even branched in our git with the Ubuntu packages). Great work and thanks to Ivo for pushing this forward. I also worked quite actively on the migration of fonts packages to git (I now reached the point where I'm more comfortable with git than SVN, yes, everything can happen). These packages were modernized at the same time and checked for new upstream versions (I have to say that few of these fonts had new upstream versions, indeed). We unfortunately found no time to have a good font BoF in Vaumarcus, indeed...but I'm not sure we would have many things to say. The work is done and done well, in this team. Some progress was made, also, for restoring a working "monolithic" build of D-I. This build gathers together all udebs from unstable, which means it offers a D-I image that uses ALL udebs from nustable.....which is not the default of other images. This would be very helpful for translators who want to check their work as soon as possible. In the future, with a Jenkins task that would build each package at each commit and then build a monolithic image, we could have a way to provide a tes snapshot of D-I git repos.....which could help catching more bugs (or more of my stupid mistakes). So, in general, I consider this a quite successful DebConf when it comes at "real" production.

Next.

Previous.