Search Results: "tar"

18 March 2009

Pablo Lorenzzoni: PubSub with XMPP4R-Simple

As I already told you, I am using XMPP4R-Simple in an internal project. For this, I d have to add PubSub capabilities to it, and I did when I decided to get serious with git. Today I committed a version with integration of various patches by other forks I found on GitHub plus a lot of improvements on PubSub functions. With this version it s simple to use PubSub like this:

require 'xmpp4r-simple'
# Simple function just to parse an event
require 'time'
def parse_event(event)
  item = event.children[0]
  node = item.node
  time = nil; item.each_element("//published")    e  time = Time.parse(e.text)  
  text = nil; item.each_element("//body")    e  text = e.text  
  return   :item => item, :node => node, :time => time, :text => text  
end
# Create the clients
im1 = Jabber::Simple.new "im1@example.com", "password" 
im2 = Jabber::Simple.new "im2@example.com", "password" 
# im1 creates a node
im1.create_node("/some/node")
# im2 subscribe to that node
im2.pubsubscribe_to("/some/node")
# We'll start a simple thread to get the events coming from that node to im2
Thread.new   loop  
  sleep 1 while ! im2.received_events?
  im2.received_events    event 
    h = parse_event(event)
    puts ">>> Got an event from node # h[:node]  published at # h[:time]  with text # h[:text] " 
   
 
# Now im1 just publishes anything to that node.
im1.publish_atom_item("/some/node", "This is my node", "This is the content of my node")
# The thread should capture the event and run puts on the hash from parsing.
PubSub is great, isn t it?

MJ Ray: SPI March 2009

The monthly board meeting of SPI will take place on irc.oftc.net #spi tonight (Wed 18 March) at 20:00 UTC. Members may have seen that the meeting announcement was posted, but a bit late and with a misleading subject line. This month, the record-keeping looks like it will catch up to present-day, with a small hole still from Neil McGovern s time as secretary. The current treasurer and secretary have also posted their reports before the meeting only the president is missing this month. There s some bank house-keeping and another new associated project under discussion: OpenWRT. There seemed to be a little confusion about whether it had been waiting for a legal opinion or not and some controversy about whether SPI recognises a liaison or a decision-maker. Once again, I may still be travelling and without a stable network connection during the meeting, or I might have made it home by then. Either way, watch the comments below this article for a link to the summary when posted.

Biella Coleman: Hyperparenting: The Ethnography

I have a long list (it exists only in my head unfortunately) of various ethnographic projects I would like to conduct. I might start the real list soon but in the meantime, I will just through the half-baked ideas here and perhaps it will inspire others to take it on. I am currently reading a fantastic book, The Case Against Perfection, and am on a section on hyperparenting and well, while I think at a common sense level we know what psychological havoc such controlled parenting can cause, I think an ethnography of some of the practices and institutions of hyperparenting would, nonetheless, make for a fascinating read. If anyone knows of anything that even resembles this, do drop me a line. Update: Not exactly an ethnography but certainly fun to read.

Biella Coleman: Hyperparenting: The Ethnography

I have a long list (it exists only in my head unfortunately) of various ethnographic projects I would like to conduct. I might start the real list soon but in the meantime, I will just through the half-baked ideas here and perhaps it will inspire others to take it on. I am currently reading a fantastic book, The Case Against Perfection, and am on a section on hyperparenting and well, while I think at a common sense level we know what psychological havoc such controlled parenting can cause, I think an ethnography of some of the practices and institutions of hyperparenting would, nonetheless, make for a fascinating read. If anyone knows of anything that even resembles this, do drop me a line. Update: Not exactly an ethnography but certainly fun to read.

Jon Dowland: crypted lvm question

On my primary desktop machine at home, I have several volumes encrypted using dm-crypt/luks and mounted as part of my login thanks to pam-mount. On one hard drive is my main home directory and some small supplementary filesystems. On another hard drive I have several crypted volumes used for backing up my home partition but also other devices. This setup is largely transparent to me: all of the filesystems are individually unlocked and mounted as part of my login. It is however a bit messy to have so many small crypted filesystems (using the same passphrase) and the login is delayed a fair while too. What would be preferable would be to have one encrypted volume that was unlocked by my PAM keyphrase but which provided several sub-volumes which were mounted individually and had separate sizes, etc. It might be possible to achieve this by having the volume exported by dm-crypt be itself a LVM physical volume. Does this sound sane to anyone? Is there a better way to achieve the same thing? I could remove the first volume group and have a disk partition feed directly into dm-crypt but I would lose some flexibility (there are some things I backup but don't encrypt, such as my music collection, and now and then I need a large scratchpad). I'm not sure how well putting a VG ontop of a LV for a different VG would work, I'm also not sure how happy the LVM code would be with a VG appearing and disappearing (In practise, I log in once a month or so, so it wouldn't happen that often).

Wouter Verhelst: Dear lazyweb,

Having used a powerbook as my primary machine for about four years, I'm not very up-to-date on Intel-specific hardware, such as ACPI, these days. When at conferences or similar, I often see people who've configured their laptops so that acpid would start an alarm when the battery's almost flat. Now that I have an HP laptop again, which does ACPI, I'd like to do the same; but I can't seem to figure out how this is configured. That is to say, when my laptop's battery is flat, it just switches off. No alarm. Needless to say, this is is rather annoying, and searching through the 56 files in /etc/acpi hasn't resulted in success so far. Any hints would be greatly appreciated.

Biella Coleman: Expectations

Expectations: A little over a week ago I participated in a camp/event/conference/ that threw together 12 different networked based-groups/phenomenon/organizations. They got to do what many often can t do: spend some time working face-to-face as well as thinking about about questions of un(organizational) growth/ungrowth. Some of us spent some time learning about the nature of networked coordinations and organizations from these groups. There is a lot I could write about but, in part because I was in Amsterdam for a week, I am now playing serious catch up, but there are a few things that really struck me both of which relate to expectations, which I thought worth jotting down. Generally present were the following types of groups: open source projects (such as Blender), tech-oriented activist projects (Dyne), non-tech oriented projects (such as Free Dimensional), artistic-tech projects (such as GOTO10), artistic projects (Upgrade), academic-activist (Edu Factory) and others which are harder to classify (such as Gender Changes, and FLOSS Manuals). One thing that came out during the plenary sessions, which is when we got together as a large group to debate and discuss, is that technically oriented open source projects are at times singled out for not being inclusive. That is, people pointed out that most projects expect you to contribute technically in order to participate (and don t necessarily offer people the training/capacity so you can participate). I have heard a version of this many many and many times before and find it to be a curious (and generally unproductive) accusation, though I understand why the confusions arises. I say confusion because most of these projects are not overtly set up to be inclusive/technically pedagogical, and this is perhaps the key point they don t purport to be though many folks think this is part of their overall message/mission. Because these free software projects are open source, this, for some, somehow automatically translates into the political projects of inclusivity (that is, training folks so that they can become part of this world). And yet some other projects, such as Edu Factory and GoTo10, which are run as tight-knit of collectives, are rarely accused of not being inclusive. Why should this be? I raise this mostly because I find it interesting, pointing to the way certain terms or phrases (Freedom, Openness) combined with the visibility of FLOSS projects, automatically generate other expectations and meanings even if they don t actually exist. I also raise it because I think it is an unfair expectation to have of these communities only in so far as most of them are full of folks busy hacking up technology and this in and of itself, as I have written about before is worthwhile politically. And yet If one wants to make them more inclusive, then one can go ahead and bring into being such a project for most of them are quite open to various initiatives to enlarge the scope of participation. These projects can be internal to projects or external to them. That is, self-initiative goes a long way in this world, and has helped changed the terrain of participation and inclusivity and I am sure will continue to do so. Which brings me to my second point about expectations. Many people complain that open source is not easy to use. While this was entirely, 1000% true prior to 1998, every passing day makes this statement harder to stand by. I imagine in another 10 years, there will be many many programs that are as usable for the novice user as proprietary software. They had to play serious catch-up and I think have done a decent job. In some regards, all that was and is needed is time because time has already shown that usability has improved leaps and bounds. And yet there is still something odd about the accusations, which my friend tulpje but in the following way One would never accuse the Zapatistas for not having their military might/shit together like the US army, so why accuse open source for not being the mightiest software our there?) While I actually think that free software has already and will continue to give proprietary firms a run for their money in a way that a rag-tag guerrilla army can t do with a national army, it is nonetheless important to couch one s responses and accusations in terms of the constraints and realities of these projects. That said, I still think such expectations reflect important hopes and desires. They show us just how profoundly free software/open source has, simply by virtue of its existence, inspired many to follow suite politically, turning to FLOSS as a beacon of possibility.

Biella Coleman: Expectations

Expectations: A little over a week ago I participated in a camp/event/conference/ that threw together 12 different networked based-groups/phenomenon/organizations. They got to do what many often can t do: spend some time working face-to-face as well as thinking about about questions of un(organizational) growth/ungrowth. Some of us spent some time learning about the nature of networked coordinations and organizations from these groups. There is a lot I could write about but, in part because I was in Amsterdam for a week, I am now playing serious catch up, but there are a few things that really struck me both of which relate to expectations, which I thought worth jotting down. Generally present were the following types of groups: open source projects (such as Blender), tech-oriented activist projects (Dyne), non-tech oriented projects (such as Free Dimensional), artistic-tech projects (such as GOTO10), artistic projects (Upgrade), academic-activist (Edu Factory) and others which are harder to classify (such as Gender Changes, and FLOSS Manuals). One thing that came out during the plenary sessions, which is when we got together as a large group to debate and discuss, is that technically oriented open source projects are at times singled out for not being inclusive. That is, people pointed out that most projects expect you to contribute technically in order to participate (and don t necessarily offer people the training/capacity so you can participate). I have heard a version of this many many and many times before and find it to be a curious (and generally unproductive) accusation, though I understand why the confusions arises. I say confusion because most of these projects are not overtly set up to be inclusive/technically pedagogical, and this is perhaps the key point they don t purport to be though many folks think this is part of their overall message/mission. Because these free software projects are open source, this, for some, somehow automatically translates into the political projects of inclusivity (that is, training folks so that they can become part of this world). And yet some other projects, such as Edu Factory and GoTo10, which are run as tight-knit of collectives, are rarely accused of not being inclusive. Why should this be? I raise this mostly because I find it interesting, pointing to the way certain terms or phrases (Freedom, Openness) combined with the visibility of FLOSS projects, automatically generate other expectations and meanings even if they don t actually exist. I also raise it because I think it is an unfair expectation to have of these communities only in so far as most of them are full of folks busy hacking up technology and this in and of itself, as I have written about before is worthwhile politically. And yet If one wants to make them more inclusive, then one can go ahead and bring into being such a project for most of them are quite open to various initiatives to enlarge the scope of participation. These projects can be internal to projects or external to them. That is, self-initiative goes a long way in this world, and has helped changed the terrain of participation and inclusivity and I am sure will continue to do so. Which brings me to my second point about expectations. Many people complain that open source is not easy to use. While this was entirely, 1000% true prior to 1998, every passing day makes this statement harder to stand by. I imagine in another 10 years, there will be many many programs that are as usable for the novice user as proprietary software. They had to play serious catch-up and I think have done a decent job. In some regards, all that was and is needed is time because time has already shown that usability has improved leaps and bounds. And yet there is still something odd about the accusations, which my friend tulpje but in the following way One would never accuse the Zapatistas for not having their military might/shit together like the US army, so why accuse open source for not being the mightiest software our there?) While I actually think that free software has already and will continue to give proprietary firms a run for their money in a way that a rag-tag guerrilla army can t do with a national army, it is nonetheless important to couch one s responses and accusations in terms of the constraints and realities of these projects. That said, I still think such expectations reflect important hopes and desires. They show us just how profoundly free software/open source has, simply by virtue of its existence, inspired many to follow suite politically, turning to FLOSS as a beacon of possibility.

Michal Čihař: Gammu test version 1.23.91

Welcome back on weekly schedule of Gammu releases. The biggest change in this release is in SMSD and RunOnReceive scripting support, which has been improved and now can contain any arbitrary command. Besides that support for vNote format has been added for backups/restores and some minor bugs were fixed. Full list of changes follows: You can download from usual place: http://cihar.com/gammu/, Debian users will find packages in experimental soon, SUSE, Fedora and Mandriva users can check experimental repository in OpenSuse Build Service.

Sandro Tosi: Changing job

Two days ago I resigned (effecting immediately) from my current job, since I received an interesting proposal for a position at Dada.net.

To make a long story short, I decided to accept it (starting from April 1st, hoping it's not a joke :D ) and I'll be working as QA assistant.

The colleagues are young, the env seems stimulating and challenging, and the position is cool: all the basis are there for a great outcome, we'll see in some weeks if it's true :)

Wish me good luck!

17 March 2009

Ondřej Čertík: Newtonian Mechanics with SymPy

Luke Peterson from UC Davis came to visit me in Reno and we spent the last weekend hacking on the Python Dynamics package that uses SymPy to calculate equations of motion for basically any rigid body system.

On Friday we did some preliminary work, mostly on the paper, Luke showed me his rolling torus demo that he did with the proprietary autolev package. We set ourselves a goal to get this implemented in SymPy by the time Luke leaves and then we went to the Atlantis casino together with my boss Pavel and other guys from the Desert Research Institute and I had my favourite meal here, a big burger, fries and a beer.

On Saturday we started to code and had couple lines of the autolev torus script working. Then we went on the bike ride from Reno to California. I took some pictures with Luke's iphone:


Those mountains are in California and we went roughly to the snow line level and back:

This is Nevada side:


That was fun. Then we worked hard and by the evening we had a dot product and a cross product working, so we went to an Irish pub to have couple beers and I had my burger as usual.

On Sunday we spent the whole day and evening coding and we got the equations of motion working. On Monday we worked very hard again:


and fixed some remaining nasty bugs. I taught Luke to use git, so our code is at: http://github.com/hazelnusse/pydy, for the time being we call it pydy and after we polish everything, we'll probably put it into sympy/physics/pydy.py. If you run rollingtorus.py, you get this plot of the trajectory of the torus in a plane:

It's basically if you throw a coin on the table, e.g. this model takes into account moments of inertia, yaw (heading), lean, spin and the x-y motion in the plane. Depending on the initial conditions, you can get many different trajectories, e.g for example:

or:


This is very exciting, as the code is very short, and most of the things that Luke needs are needed for all the other applications of sympy, e.g. a good printing of equations and vectors (both in the terminal and in latex), C code generation, fast handling of expressions, nice ipython terminal for experimentation, plotting, etc.

Together with the atomic physics package that we started to develop with Brian sympy will soon be able to cover some basic areas of physics. Other areas are general relativity (there is some preliminary code in examples/advanced/relativity.py) and quantum field theory and Feynman diagrams - for that we need someone enthusiastic that needs this for his/her research --- if you are interested, drop me an email, you can come to Reno (or work remotely) and we can get it done.

My vision is that sympy should be able to handle all areas of physics, e.g. it needs good assumptions (if you want to help out, please help us test Fabian's patches here), then faster core, we have a pretty good optional Cython core here, so we'll be merging it after the new assumptions are in place. Then sympy should have basic modules for most areas in physics so that one can get started really quickly. From our experience so far in sympy/physics, those modules will not be big, as most of the functionality is not module specific.

Ross Burton: Sound Juicer "Don't Go Back To Dalston" 2.26.0

Sound Juicer "Don't Go Back To Dalston" 2.26.0 has been released. Tarballs are available on burtonini.com, or from the GNOME FTP servers. Only translation updates this time, sorry.

Christian Perrier: Bug #520000

Mark Purcell reported bug #520000 on Monday March 16th, against the gsm-utils package. Bug #510000 was reported as of Dec 28th 2008. So, it took us 2.5 months for 10,000 bugs. This is still slower than our rate of 10,000 bugs/2 months but more than the pace we had for 500000-510000. Of course, in the meantime, we released lenny on Feb 14th and, therefore, the development started again and, with development, new bugs come in. To illustrate this, one will notice that bug #515000 was reported on Feb 12th. So, it took 46 days for the first 5,000 bugs and then only 32 for the remainder 5,000. In short, we're probably back to our pace of 10,000 bugs in two months. In case someone cares, the first bug reported after the release of Lenny is #515247, reported by Robin Kluth against the gvfs package. It followed the release of lenny by 25 minutes and 14 seconds. That bug isn't fixed yet but is already reported upstream.

Christian Perrier: News of samba packages

The first version of samba packages (2:3.3.1-1) that is different from the version in lenny (2:3.2.5-4) entered testing this week-end. The first update of samba packages that's aimed for lenny has also been accepted for the next point release of Lenny, through stabe-proposed-updates. This is version 2:3.2.5-4lenny1. It fixes two important bugs discovered after the release of lenny that potentially affect many users and were fixed upstream in post-3.2.5 releases In the constant tracking of a very active upstream, I also uploaded packages for 3.3.2 in unstable. That was quite a straightforward process, of course helped by Steve Langasek, who is a constant active support in the maintenance of samba packages. I really like the team we're having now, with Steve being very picky and motivated by quality and /me doing most of the nasty repetitive work to try saving his time for more important tasks..:-) The next plan is updating packages on backports.org. Having 3.3.1 packages in testing now allows us to upload them in lenny-backports which should be good for lenny users who want to track upstream. Finally, my proposal for a talk about "Packaging Samba for Debian and derivatives" has been accepted at Samba XP, the annual conference of Samba developers and users in G ttingen, Germany. For the first time, I'll be a speaker at this conference which I attend yearly since...it exists. My "german pilgrimage" of the year in Northern/Central Germany... Ah, and I'm still preparing for the Paris Marathon, in 3 weeks now, which I will run with Ralf Treinen and No l K the. I feel in good shape for this as, this week-end, while I promised myself to "not run for too long", I just ran 19km and felt this was a quite "short" run. Still not in the performances of Dirk who mentions that 1h36 for a semi is "good for someone who didn't train that much during winter"...but I think I'll never reach that level of performance. I should have started running long distance 20 years ago for this, I'm afraid.

16 March 2009

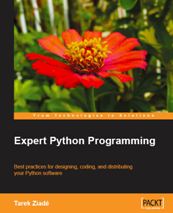
Michal Čihař: Expert Python Programming

The book Expert Python Programming comes with subtitle Best practices for designing, coding, and distributing your Python software. Well this seems to be quite broad area to be covered by a single book, but the book really tries to cover all topics at least in some form of overview and pointing user to other documentation sources. Expert Python Programming In first chapter you can find information about installing Python on various platforms. As the book seems to be targeted to more experienced users, this chapter seems to be a bit useless, but author decided to give a chance also to users, who do not know the basics. Next chapters describe best practices for writing Python code, which was the most interesting part for me. I use Python several years, but I never really found time time to properly look at using decorators, generators and other "recently" introduced language features. Second chapter nicely covers these and I really appreciated that I got idea for what decorators can be used. Third chapter into class level and describes how to use metaclasses, attributes, constructors and other things you can face on class level. Fourth moves the topic to even more abstract way and in short summarises PEP 8 best coding practices. Here we leave solid ground of writing code and we move to more abstract areas of managing projects, testing, documenting and distributing software. It begins with description of distutils and setuptools in chapters five and six, where you will find basic information about distributing your software. Seventh chapter covers zc.buildout, which can help you with setting up and deploying applications in way Zope and Plone do. Next chapter is not really related to Python, it just describes advantages of version control. The most Python related part is using Mercurial VCS, which is written in Python, but you can of course use it for managing any project. Next tree chapters are devoted to project development in general, describing management of the project, generating documentation for project using Sphinx (what actually made me into starting documentation for python-gammu in it) and test-driven development practices. Now comes again two more interesting chapters describing optimization of Python code, giving the best advice not to optimize unless you are sure it is needed ;-). But it also goes more deeper and describes benchmarking procedures, how to debug memory usage and some basic tips for general things which might improve performance. Last chapter is some kind of extra in the book and to me it looks it was added just to use buzzwords design patters, but well it is there and it covers few design patterns which might be useful in Python like singleton or more advanced version of it called borg. In general this book covers quite wide range of topics, what can be seen as biggest advantage and disadvantage. You will get basic overview of creating Python project using modern methods (test driven development, design patters, best practices for Python code), but you can not expect it will go into much deep details. The book can extend your knowledge of development in Python, but you should carefully check examples with errata, because otherwise several of them will fail. I'm not that good at spotting problems in written English (as you can probably see in this post), but I spotted several errors in code and I think more careful editor work on the book would improve my feelings a bit. Also I personally would prefer much deeper look into some topics and skipping the others, but one book can not fit all ;-).

James Morrison: Recent Bands

13 Mar 2009
White Swan, Black Swan: nice vocals, I only caught a couple songs

The Donkeys
Decent band, fun to listen to. A good whale joke:
Two whales are sitting at a bar
one says to the other [long whale noises]
The other says, "man you are trashed."

Quick to get on stage and play

Phosphoressence
Good country rock band. Slow to start playing and some assholes decided to pop into the front of the crowd, they were tall so they blocked a bunch of peoples view. Then they gained an extra 3 people and started moving backwards. For once someone actually got inside my bubble.

7 Mar 2008 -- Red Devil Lounge
* "Three of" (good luck googling these guys) -- very good
* A, b, and C -- not good, the lead singers voice cracked a lot, they did look like they should be in the movie "That thing you do" (my first date was at this movie).
* Moonlight Sexy -- ok, Andy didn't like these guys
* Marcy Playground -- Great!

14 Mar 2008 -- Writers with drinks
S.G Browne with Breathers: A zombie's lament. The chapter he read was really funny. I think this was the best part of the night. The host was also really good, but the host could be described as slightly scripted talking out of her ass.

Theodore Ts'o: Don t fear the fsync!

After reading the comments on my earlier post, Delayed allocation and the zero-length file problem as well as some of the comments on the Slashdot story as well as the Ubuntu bug, it s become very clear to me that there are a lot of myths and misplaced concerns about fsync() and how best to use it. I thought it would be appropriate to correct as many of these misunderstandings about fsync() in one comprehensive blog posting. As the Eat My Data presentation points out very clearly, the only safe way according that POSIX allows for requesting data written to a particular file descriptor be safely stored on stable storage is via the fsync() call. Linux s close(2) man page makes this point very clearly:
A successful close does not guarantee that the data has been successfully saved to disk, as the kernel defers writes. It is not common for a file system to flush the buffers when the stream is closed. If you need to be sure that the data is physically stored use fsync(2).
Why don t application programmers follow these sage words? These three reasons are most often given as excuses:
  1. (Perceived) performance problems with fsync()
  2. The application only needs atomicity, but not durability
  3. The fsync() causing the hard drive to spin up unnecessarily in laptop_mode
Let s examine each of these excuses one at a time, to see how valid they really are. (Perceived) performance problems with fsync() Most of the bad publicity with fsync() originated with the now infamous problem with Firefox 3.0 that showed up about a year ago in May, 2008. What happened with Firefox 3.0 was that the primary user interface thread called the sqllite library each time the user clicked on a link to go to a new page. The sqllite library called fsync(), which in ext3 s data=ordered mode, caused a large, visible latency which was visible to the user if there was a large file copy happening by another process. Nearly all of the reported delays was a few seconds, which would be expected; normally there isn t that much dirty data that needs to be flushed out on a Linux system, even if it is even very busy. For example, consier the example of a laptop downloading an .iso image from a local file server; if the laptop has the exclusive link of a 100 megabit/second ethernet link, and the server has the .iso file in cache, or has a nice fast RAID array so it is not the bottleneck, then in the best case, the laptop will be able to download data at the rate of 10-12 MB/second. Assuming the default 5 second commit interval, that means that in the worst case, there will be at most 60 megabytes which must be written out before the commit can proceed. A reasonably modern 7200 rpm laptop drive can write between 60 and 70 MB/second. (The Seagate Momentus 7200.4 laptop drive is reported to be able to deliver 85-104 MB/second, but I can t find it for sale anywhere for love or money.) In this example, an fsync() will trigger a commit and might need to take a second while the download is going on; perhaps half a second if you have a really fast 7200 rpm drive, and maybe 2-3 seconds if you have a slow 5400 rpm drive. (Jump to Sidebar: What about those 30 second fsync reports?) Obviously, you can create workloads that aren t bottlenecked on the maximum ethernet download speed, or the speed of reading from a local disk drive; for example, dd if=/dev/zero of=big-zero-file will create a very large number of dirty pages that must be written to the hard drive at the next commit or fsync() call. It s important to remember though, fsync() doesn t create any extra I/O (although it may remove some optimization opportunities to avoid double writes); fsync() just pushes around when the I/O gets done, and whether it gets done synchronously or asynchronously. If you create a large number of pages that need to be flushed to disk, sooner or later it will have a significant and unfortunate effect on your system s performance. Fsync() might make things more visible, but if the fsync() is done off the main UI thread, the fact that fsync() triggers a commit won t actually disturb other processes doing normal I/O; in ext3 and ext4, we start a new transaction to take care of new file system operations while the committing transction completes. The final observation I ll make is that part of the problem is that Firefox as an application wants to make a huge number of updates to state files and was concerned about not losing that information even in the face of a crash. Every application writer should be asking themselves whether this sort of thing is really necessary. For example, doing some quick measurements using ext4, I determined that Firefox was responsible for 2.54 megabytes written to the disk for each web page visited by the user (and this doesn t include writes to the Firefox cache; I symlinked the cache directory to a tmpfs directory mounted on /tmp to reduce the write load to my SSD). So these 2.54 megabytes is just for Firefox s cookie cache and Places database to maintain its Awesome bar . Is that really worth it? If you visit 400 web pages in a day, that s 1GB of writes to your SSD, and if you write more than 20GB/day, the Intel SSD will enable its write endurance management feature which slows down the performance of the drive. In light of that, exactly how important is it to update those darned sqllite databases after every web click? What if Firefox saved a list of URL s that has been visited, and only updated every 30 or 60 minutes, instead? Is it really that every last web page that you browse be saved if the system crashes? An fsync() call every 15, 30, or 60 minutes, done by a thread which doesn t block the application s UI, would have never been noticed and would have not started the firestorm on Firefox s bugzilla #421482. Very often, after a little thinking, a small change in the application is all that s necessary for to really optimize the application s fsync() usage. (Skip over the sidebar if you ve already read it). Sidebar: What about those 30 second fsync reports? If you read through the Firefox s bugzilla entry, you ll find reports of fsync delays of 30 seconds or more. That tale has grown in the retelling, and I ve seen some hyperbolic claims of five minute delays. Where did that come from? Well, if you look that those claims, you ll find they were using a very read-heavy workload, and/or they were using the ionice command to set a real-time I/O priority. For example, something like ionice -c 1 -n 0 tar cvf /dev/null big-directory . This will cause some significant delays, first of all because ionice -c 1 causes the process to have a real-time I/O priority, such that any I/O requests issued by that process will be serviced before all others. Secondly, even without the real-time I/O priority, the I/O scheduler naturally prioritizes reads as higher priority than writes because normally processes are waiting for reads to complete, but writes are normally asynchronous. This is not at all realistic workload, and it is even more laughable that some people thought this might be an accurate representation of the I/O workload of a kernel compile. These folks had never tried the experiment, or measured how much I/O goes on during a kernel compile. If you try it, you ll find that a kernel compile sucks up a lot of CPU, and doesn t actually do that much I/O. (In fact, that s why an SSD only speeds up a kernel compile by about 20% or so, and that s in a completely cold cache case. If the commonly used include files are already in the system s page cache, the performance improvement of the SSD is much less.) Jump back to reading Performance problems with fsync. The atomicity not durability argument One argument that has commonly been made on the various comment streams is that when replacing a file by writing a new file and the renaming file.new to file , most applications don t need a guarantee that new contents of the file are committed to stable store at a certain point in time; only that either the new or the old contents of the file will be present on the disk. So the argument is essentially that the sequence: is too expensive, since it provides atomicity and durability , when in fact all the application needed was atomicity (i.e., either the new or the old contents of foo should be present after a crash), but not durability (i.e., the application doesn t need to need the new version of foo now, but rather at some intermediate time in the future when it s convenient for the OS). This argument is flawed for two reasons. First of all, the squence above exactly provides desired atomicity without durability . It doesn t guarantee which version of the file will appear in the event of an unexpected crash; if the application needs a guarantee that the new version of the file will be present after a crash, it s necessary to fsync the containing directory. Secondly, as we discussed above, fsync() really isn t that expensive, even in the case of ext3 and data=ordered; remember, fsync() doesn t create extra I/O s, although it may introduce latency as the application waits for some of the pending I/O s to complete. If the application doesn t care about exactly when the new contents of the file will be committed to stable store, the simplest thing to do is to execute the above sequence (open-write-fsync-close-rename) in a separate, asynchronous thread. And if the complaint is that this is too complicated, it s not hard to put this in a library. For example, there is currently discussion on the gtk-devel-list on adding the fsync() call to g_file_set_contents(). Maybe if someone asks nicely, the glib developers will add an asynchronous version of this function which runs g_file_set_contents() in a separate thread. Voila! Avoiding hard drive spin-ups with laptop_mode Finally, as Nathaniel Smith said in Comment #111 of of my previous post:
The problem is that I don t, really, want to turn off fsync s, because I like my data. What I want to do is to spin up the drive as little as possible while maintaining data consistency. Really what I want is a knob that says I m willing to lose up to minutes of work, but no more . We even have that knob (laptop mode and all that), but it only works in simple cases.
This is a reasonable concern, and the way to fix this is to enhance laptop_mode in the Linux kernel. Bart Samwel, the author and maintainer of laptop_mode, actually discussed this idea with me last month at FOSDEM. Laptop_mode already adjusts /proc/sys/vm/dirty_expire_centisecs and /proc/sys/vm/dirty_writeback_centisecs based on the configuration parameter MAX_LOST_WORK_SECONDS, and it also adjusts the file system commit time (for ext3; it needs to be taught to do the same thing for ext4, which is a simple patch) to MAX_LOST_WORK_SECONDS as well. All that is necessary is a kernel patch to allow laptop_mode to disable fsync() calls, since the kernel knows that it is in laptop_mode, and it notices that the disk has spun up, it will sync out everything to disk, since once the energy has been spent to spin up the hard drive, we might as well write everything in memory that needs to be written out right away. Hence, a patch which allows fsync() calls to be disabled while in laptop_mode should do pretty much everything Nate has asked. I need to check to see if laptop_mode does this already, but if it doesn t force a file system commit when it detects that the hard drive has been spun up, it should obviously do this as well. (In addition to having a way to globally disable fsync() s, it may also be useful to have a way to selectively disable fsync() s on a per-process basis, or on the flip side, exempt some process from a global fsync-disable flag. This may be useful if there are some system daemons that really do want to wake up the hard drive and once the hard drive is spinning, naturally everything else that needs to pushed out to stable store should be immediately written.) With this relatively minor change to the kernel s support of laptop_mode, it should be possible to achieve the result that Nate desires, without needing force applications to worry about this issue; applications should be able to just simply use fsync() without fear. Summary As we ve seen, the reasons most people think fsync() should be avoided really don t hold water. The fsync() call really is your friend, and it s really not the villain that some have made it out to be. If used intelligently, it can provide your application with a portable way of assuring that your data has been safely written to stable store, without causing a user-visible latency in your application. The problem is getting people to not fear fsync(), understand fsync(), and then learning the techniques to use fsync() optimally. So just as there has been a Don t fear the penguin campaign, maybe we also need to have a Don t fear the fsync() campaign. All we need is a friendly mascot and logo for a Don t fear the fsync() campaign. Anybody want to propose an image? We can make some T-shirts, mugs, bumper stickers Related posts (automatically generated):
  1. Delayed allocation and the zero-length file problem A recent Ubuntu bug has gotten slashdotted, and has started...

15 March 2009

Joerg Jaspert: Section changes, Content Files and some more

And there we have done it - new sections in the archive. Read more about it in my d-d-a post and the whole set of affected packages is also available - and updated slightly, as some small things slipped through. The whole process was less painful than feared. After some discussion, started a few weeks ago we finally went and coordinated the change today. There was no reliable and good way for changes that large, so we had to create our own way. (The last section changes had been done ages ago). Mike provided a little python script which was able to parse our input file with the section matches against our database, so we ended up with a list we could possibly feed back into the database. Except, not really. Thanks to various things the list generated needed some manual work (which I also managed to fuck up a little), but after that was done we were ready to go. And while Mark told the wanna-build admins about the new sections (for some reason our buildd network cares about sections) and prepared a patch for our policy, I prepared the mail for the d-d-a list. Then we all had a break, as a dinstall was still running, and we did not want to break that. The actual changes then took only a few seconds, sending the mail to d-d-a took longer, thankyou gnupg. :) I wonder how much afterwork this will generate. There are at least the policy changes, lintian, the packages control files to adjust. Also some websites, where Frank already changed packages.debian.org to know about the new names. (Before he fixed up me forgetting some PHP packages to move. This way all of the active ftpteam members did something in it :) ).
In other news, we are currently stress-testing our ftp-master host a little. Well, not really, it could take more, but right now we are scanning the full archive once, importing all filenames from all our Debian packages. The goal is to get projectb larger. Err, no, actually we do want to get rid of apt-ftparchive, as that is one of the worst tools in our dinstall runs. It is slow as hell in the mode it has to run for us, making up a large part of our runtime. Step 1 to get rid of it is to generate the content files on our own, and before we can do that we have to import them all Which means we have to unpack every binary package once, reading in all filenames to store them in our database. Thats a lot of data. Currently the associations table, which is nothing more than 4 integers per row, takes up 972MB, and import is still running. (The index on the binary pkg id in this table alone has 700MB). And this table does nothing more than linking the binary package to the filename and filepath. Which are two extra tables, with the filenames having only 87MB, the path entries only taking up 30MB. Yes, anyone using databases will tell me thats not much, and it really isn t that much. It s just that the largest table before this import had 120MB in it. And some of the others used more space for their indexes than for the actual data. :) Anyway, this is only step one on our way to get rid of the slowness apt-ftparchive is. When the contents all work as we want them, the next step will be to get rid of it generating Packages/Sources files. Which means we have some more data to store in projectb. And after that - we also intend to do a Contents file for our source. Each and every source file listed. Guess we really will end up with some more large tables. :) The final goal and main reason why we do this is to save us at least 60 minutes runtime per dinstall run. My own guess is that Contents alone will get us about 20 minutes down. No, before someone wants to yell at me - apt-ftparchive can t be changed as much to make this possible and keep using it. Not in the way the generate option works. It has the disadvantage that it scans the files after they are installed in their pool/ location and stores that in its own database . This approach has to negative points:
The title says some more, so here is some more: We aren t only working on what I wrote above. There is also work on changing our database access. Historically dak used the pg module to do database work. While the module itself does work, the way its used isn t really the best one. Way too much groundwork everywhere. Not nearly as much of the nice things used people say python could have. So another largish work area is getting rid of pg. Migrating to psycopg2. And putting a proper OO class around it, which in the end hopefully hides those dark details from the application. And to achieve even more sanity, we (well, honestly, Mark) are looking into SQL Alchemy usage. (We also considered storm from Canonical, but that sucks when you take a look at its documentation. (Which documentation?). SQLA won there easily.) While I m ranting: WTF are people neglecting their docs that much? Ever tried looking at the documentation for psycopg2? Forget it. No, a db api compliance test suite is NOT documentation. If there would be any better python module to connect to postgres, I would veto the usage of psycopg2, but there doesn t seem to be one. Sucks.

Gustavo Noronha Silva: WebKitGTK+ 1.1.3 released! =D

No, you re not reading it wrong but what about 1.1.2? , you ask. Well, we made a small mistake with the soversion there (if mistakes regarding soversion are ever small, that is =/), so we had to quickly release a fixed up version before packages start showing up for distributions with an incorrect library soname. Apologies. With this release we have a shiny new website at http://webkitgtk.org/, hosted by Igalia and designed by Christian Dywan, who s one of the contributors to WebKitGTK+ s code. This new release sports many interesting features and fixes. You may remember me talking about the download support initially contributed by Collabora, which I was fixing up and pushing for inclusion. Well, it is now available, and already implemented in Epiphany 2.27.0. Christian Dywan tells me he won t let Midori stay behind Epiphany on this one, so expect support for downloading correctly integrated in Midori as well. Some more pet peeves got fixed with this release, such as scrolling with keys such as space bar, home, end, not behaving the way people expect. We also found more improvements which are in order for libsoup, and we ll be pushing them, even though we have added small workarounds to WebKitGTK+ itself for the time being. We have added proper logging support for our port, providing a WEBKIT_BUILD environment variable. Documentation on how to use this will follow soonish, but for now you can look at the LoggingGTK.cpp file to know what values you can add to that variable. Also notice that only debug builds use logging to its full extent! WebKitGTK+ 1.1.1 has now hit Debian experimental, by the way, and I plan to have 1.1.3 uploaded early this week. An epiphany-webkit package based on 2.27 is in the works, and should be in soon, too. There seems to be lots of interest in having a PPA for Ubuntu, as well, so we may see that happening soonish. We plan to get more testing this way, and be able to uncover and fix more bugs, so that we can get a rock solid release ready in time for GNOME 2.28.
Davide Viti: 74 bugs

In a previous post I've talked about a bug affecting the ttf-dejavu package; I've extended the test to all font files in the Debian archive and come up with the following numbers: of the 192 packages containg at least one TrueType font file, 74 are affected by the digits width problem for a total of 672 ttf files. Result are available here The bug can be reproduced with pango-view (ttf-tmuni was chosen in this example):
perl -e 'for my $i (0..9) print "$i" x 80; print "\n"; '  > sample.txt
pango-view --font="Tibetan Machine Uni" --waterfall --dpi=72 -q -o out.png sample.txt
Comments are welcome before I start filing the bugreports

Next.

Previous.