Search Results: "ag"

2 October 2013

Jan Wagner: Nagios Plugins 1.5 released

Today the Nagios Plugins Development Team released the long awaited version 1.5 of the Nagios Plugins. It contains several bug-fixes as well as new features. The project moved to a new home at nagios-plugins.org, the SCM and issue tracker moved to github. If you want to contribute to the project, please have a look into the updated development documentation. Many thanks guys, you rock! The package was uploaded already into Debian unstable and it should hit the Backports repository soon. If you are impatiently, you could install the package from our repository.

Axel Beckert: How to make wget honour Content-Disposition headers

Download links often point to CGI scripts which actually generate (or just fetch, i.e. proxy) the actual file to be downloaded, e.g. URLs like http://www.example.com/download.cgi?file=foobar.txt. Most of such CGI scripts send the real file name in the Content-Disposition header as specified in the MIME Specification. All browsers I know (well, at least those I use regularily :-) handle that perfectly and propose the file name sent in the Content-Disposition header as file name for saving the downloaded name which is usually exactly what I want. All browsers do that, , just not my favourite commandline download tool GNU Wget Downloading the above URL with wget would look like this with default settings:
$ wget 'http://www.example.com/download.cgi?file=foobar.txt'
--2013-10-02 16:04:16--  http://www.example.com/download.cgi?file=foobar
Resolving www.example.com (www.example.com)... 93.184.216.119, 2606:2800:220:6d:26bf:1447:1097:aa7
Connecting to www.switch.ch (www.example.com) 2606:2800:220:6d:26bf:1447:1097:aa7 :80... connected.
HTTP request sent, awaiting response... 200 OK
Length: 2020 (2.0K) [text/plain]
Saving to:  download.cgi?file=foobar.txt'
100%[============================================>] 2,020       --.-K/s   in 0s
2013-10-02 16:04:24 (12.5 MB/s) -  download.cgi?file=foobar.txt' saved [2020/2020]
Meh! But luckily Wget can do that, it s just not enabled by default because it s an experimental and possibly buggy feature, at least according to the man page. Well, works for me! :-) You can easily enabled it by default for either your user or the whole system by placing the following line in your ~/.wgetrc or /etc/wgetrc:
content-disposition = on
Given the CGI script sends an appropriate Content-Disposition header, the above output now looks like this:
$ wget 'http://www.example.com/download.cgi?file=foobar.txt'
--2013-10-02 16:04:16--  http://www.example.com/download.cgi?file=foobar
Resolving www.example.com (www.example.com)... 93.184.216.119, 2606:2800:220:6d:26bf:1447:1097:aa7
Connecting to www.switch.ch (www.example.com) 2606:2800:220:6d:26bf:1447:1097:aa7 :80... connected.
HTTP request sent, awaiting response... 200 OK
Length: 2020 (2.0K) [text/plain]
Saving to:  foobar.txt'
100%[============================================>] 2,020       --.-K/s   in 0s
2013-10-02 16:04:24 (12.5 MB/s) -  foobar.txt' saved [2020/2020]
Now Wget does what I mean! You can also set this as flag on the commandline, but typing wget --content-disposition everytime is surely not what I want. ;-)

Chris Lamb: Readers-writers lock in eventlet

The problem: You want to have a critical section of code where concurrent read operations are permitted but exclusive access for write operations multiple readers may read data in parallel but only a single writer is allowed to write data at any one time. Here's an implementation using the eventlet library:
from eventlet import greenthread, hubs
class ReadWriteLock(object):
    """
    Usage::
        lock = ReadWriteLock()
        with lock.reader():
            do_read_ops()
        with lock.writer():
            do_write_ops()
    """
    def __init__(self):
        self.counter = 0
        self._read_waiters = set()
        self._write_waiters = set()
    def reader(self):
        return self.Reader(self)
    def writer(self):
        return self.Writer(self)
    class Base(object):
        def __init__(self, parent):
            self.parent = parent
        def _acquire(self, waiters):
            waiters.add(greenthread.getcurrent())
            try:
                while self.parent.counter != 0:
                    hubs.get_hub().switch()
            finally:
                waiters.discard(greenthread.getcurrent())
        def _exit(self):
            for waiters, fn in (
                (self.parent._read_waiters, lambda x: x >= 0),
                (self.parent._write_waiters, lambda x: x == 0),
            ):
                if not waiters:
                    continue
                hubs.get_hub().schedule_call_global(
                    0, self._release, waiters, fn,
                )
        def _release(self, waiters, fn):
            if waiters and fn(self.parent.counter):
                waiters.pop().switch()
    class Reader(Base):
        def __enter__(self):
            if self.parent.counter < 0:
                self._acquire(self.parent._read_waiters)
            self.parent.counter += 1
        def __exit__(self, *args, **kwargs):
            self.parent.counter -= 1
            self._exit()
    class Writer(Base):
        def __enter__(self):
            if self.parent.counter != 0:
                self._acquire(self.parent._write_waiters)
            self.parent.counter -= 1
        def __exit__(self, *args, **kwargs):
            self.parent.counter += 1
            self._exit()

Matthew Palmer: A vim-outliner cheatsheet

Being a bit of a vim-outliner fanatic, but having an inability to remember all of the various key combos, is a sad place to be. Having lived there for far too long, I finally got up the energy to learn enough Inkscape to produce my very own vim-outliner cheatsheet. One more thing I can ,,x

1 October 2013

Gunnar Wolf: Piracy and culture circulation: #encirc13

This week's lesson on the Arte y cultura en circulaci n: crear y compartir en tiempos digitales course talks about piracy and the circulation of culture, a topic that over time has been debated over and over. And a topic, yes, that can always lead to interesting discussions. This time, we are requested to choose one among ten ideas among the media groups' discourse on what piracy is and means for the "cultural industry". There are tons of material written already on several of those ten lines (i.e. piracy disincentivates creativity, or two that can be seen as two faces of the same argument, If a consumer can have free access to cultural products, he will stop spending his money on them and Every time a consumer has access to an illegal copy, the industry loses a sale), and some are quite obvious (i.e. Piracy makes job positions be lost... Just look at the amount of people the unauthorized distribution industry feeds! Or possibly, Piracy is a prosper industry that gives money to people distributing illegal products Of course, that is true. The problem is, what causes said products to be illegal to begin with? Should they be so?). Some other ideas talk about harsher penalties and ways to punish illegal copying in order to drive actors out of that sector (and into the... void?) So, I chose item #4: Cultural products have a high cost because their production is complex (and a tag could be made, linking complex with expensive). I think this item can lead to a long discussion as to what does this complexity and cost mean. Some cultural products do require quite a bit of investment, yes. Others don't. How do content producers make the jump to produce expensive works? If I am a new programmer/artist/writer/screenplayer/whatever, most likely, my products will be not very complex or expensive. I will start small. And if I excel at my work, somebody will look at me and, in some way, become my patron, my sponsor. Being a sponsor might mean that, based on the results of my good work, I could get hired as a software developer at a large company, or an editorial company would buy the patrimonial rights of my book/music (be it for a fixed fee or for a percentage of sales), or whatever. But the leap is not made quantically A newcomer to the cultural scene will at first, most likely, have a hard time selling his products. At first, it takes convincing just getting people to take a shot at looking at your work ( Hey, please take a look at my program and tell me what you think about it! , Would you be interested in listening to my latest song? And those two are by far ahead of the first attempts where the interactions would more likely be Turn off that $#^#!^ computer, it's well past bedtime or stop murdering that guitar, I'm having a headache ). Maybe the toughest part is to get people to agree to read/hear your work. And there, you start into a continuum Selling your CDs while performing on the street, then getting to play to a bar, then getting somebody to want to produce (maybe even "discover"!) you. Publish some short stories in your school magazine, then in a "From our audience" section in a larger magazine, then a collective book, your self-published book, yet-unwritten books by contract... The same story over and over again, in each different field. Ok, yes, but... This logic succession still leaves space for the Important Producers with the Mighty Big Pockets for the most wanted/largest productions, right? And were unauthorized distribution (piracy) to be the norm (as it currently is, dare I say), wouldn't they stop producing an important portion of cultural works? I'd be tempted to say so. However, a different actor comes into play. When Mighty Big Pockets comes into play, they no longer worry only about getting money from each cultural creation, but from all derived uses of it. And the cultural creation industry (when seen as an industry) goes very much hand in hand with the advertising, marketing industries They end up blending with each other. So, the biggest best sellers will most likely have a hit from illegal copiers. Books are still a great business, but hey An even better business is (usually) movie making. And when you make a movie out of a great story, you will surely link some advertising into it (or at the very least, push advertising/product pushing campaigns to go after it). And there, illegal distribution actually helps the money circle to grow stronger. In the early 1990s, the link between dinosaurs and carbonated drinks was a top seller (because Pepsi was a Jurassic Park sponsor). Although I have always loathed the madness around the World Cups (and basically anything that involves football of any kind), I can perfectly remember several of the theme songs for most of the world cups played during my lifetime. So, in short... No. Illegal distribution does marginally little harm to the money income to the cultural business, at any level. And where it does get some direct harm, it increases the money flux given the auxiliary channels.

Michal &#268;iha&#345;: Trip to Switzerland

After I was at DebConf 13, we took opportunity and made short trip through Switzerland. Even the DebConf itself brought some nice opportunities to take pictures, especially in the morning: Then there was a day trip to Creux du Van, which is a wonderful location: After DebConf, we've traveled to visit our friend and made some trips. The one I really enjoyed was around Luzerne and to mount Pilatus: An while being in north of Switzerland, we simply had to see Rheinfall:

Filed under: English Photography Travelling 0 comments Flattr this!

Michael Casadevall: Spanish or Bust: Attaining fluency in 90 days or else ...

"How do you have an adventure?"

"You take a stupid idea, and follow through ..."

Perhaps, I've truly lost my mind for once, but I've decided to embark on a personal project to try and achieve some fluency in Spanish in just 90 days, and posting it to the internet to try and keep me honest and on track towards doing so. I will post future updates as I go, and would welcome help from anyone who would be interested in helping!

The cost of failure: being forced to praise Wndows 8 in a future video, and run it for one week on my laptop.


(I apologize for the quality, but I finally managed to find the nerve to record myself doing this, and just uploaded before I lost it again)


30 September 2013

Sylvain Le Gall: OUnit 2.0, official release

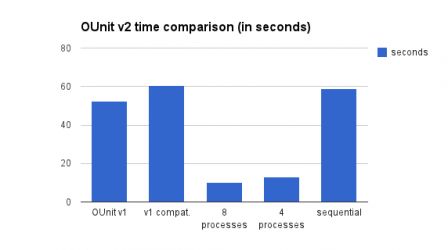
After 1.5 month of work, I am proud to officialy release OUnit 2.0.0. This is a major rewrite of OUnit to include various feature that I think was missing from OUnit1. The very good news is that the port of the OASIS test suite has proven that this new version of OUnit can drastically improve the running time of a test suite. OUnit is a unit test framework for OCaml. It allows one to easily create unit-tests for OCaml code. It is based on HUnit, a unit testing framework for Haskell. It is similar to JUnit, and other XUnit testing frameworks. Download OUnit v2.0.0 Documentation of v2.0.0 Website The basic features: Migration path OUnit 2.0.0 still provides the OUnit module which is exactly the same as the last OUnit 1.X version. This way, you are not forced to migrate. However, this means that you will gain no advantage of the new release and even some slowdown due to increase complexity of the code. Though, I strongly recommend to upgrade to OUnit2. Here is a checklist to do the migration: The OASIS test suite migration In order to check that everything was working correctly, I have migrated the OASIS test suite to OUnit2. This is a big test suite (210 test cases) and it includes quite big sequences of tests (end to end tests from calling oasis setup to compiling and installing the results). This was really time consuming and I wish to see a significant speedup for the tests with OUnit2. You can see the result in term of code of the full migration here. Here are the results on my Intel Core i7 920/SSD: OUnit v2 benchmark The migration was quite heavy because this test suite had a big design problem. It uses in-place modification of the test data. I think I pick this design because I thought this was a good idea to decrease the running time. As a matter of fact, this was a huge mistake, that keeps popping failed test cases because one of the previous tests was failing. I have refactored all this and now we start by copying the test data into a temporary directory, which ensure that everything is always starting from pristine test data. During the redesign, I have decided to reduce the number of tests by merging some of them. This should have no big impact on the running time, although this is not as pure 1:1 comparison with OUnit v1. Although it is still testing exactly the same thing. This explain the loss of ~50 tests, which in fact has been merged in other tests. The overall speedup is 4x compared to OUnit v1, when using processes. However there is a 12% increase compared to OUnit v1 for sequential and a 15% increase when using OUnit v1 compatibility layer. While this is not very good score, I hope this is small enough to compensate the huge win of being able to run tests in parallel with processes. And now the magic ! At this point, if you read carefully the numbers, you would have noticed that there is a 4.5x decrease in speed when you compare sequential and 4 processes for OUnit2. Since we are only actively testing in 4 shards, it looks strange. I don't expect a super-linear speedup due to the use of processes. I have checked that every tests was indeed running and found no solutions to this mystery. Right now, I think this is due to the fact that we are running less tests in more processes which should lighten the load of the GC (which may not trigger at all). I am not sure about this explanation and will welcome any bug report which shows a problem in the implementation of either sequential or processes runner. Although, this is great. Help still wanted If you find any bugs with OUnit v2, this is the time to submit a bug. OUnit BTS If you want to try to fix bugs by yourself, please checkout the latest version of OUnit:
 $> darcs get http://forge.ocamlcore.org/anonscm/darcs/ounit/ounit
Patches always welcome.

Dirk Eddelbuettel: RcppArmadillo 0.3.920.1

Along with the Rcpp 0.10.5 release yesterday, a new minor release 0.3.920.1 of RcppArmadillo came out. It is based on Conrad's Armadillo 3.920.0 plus a minor fix, and uses some of the new Rcpp features. Both package is now on CRAN and also in Debian. This releases contains both a nice set of new Armadillo features as well as some nice additions to RcppArmadillo, due again mostly to Romain. Some of the changes tie into the changes changes in Rcpp 0.10.5 as for example the ability to pass const and const ref more efficiently (and we seem to have forgotten an entry in the NEWS file). The complete list of changes is below.
Changes in RcppArmadillo version 0.3.920.1 (2013-09-27)
  • Upgraded to Armadillo release Version 3.920.1 (Agencia Nacional Stasi)
    • faster .zeros()
    • faster round(), exp2() and log2() when using C++11
    • added signum function: sign()
    • added move constructors when using C++11
    • added 2D fast Fourier transform: fft2()
    • added .tube() for easier extraction of vectors and subcubes from cubes
    • added specification of a fill type during construction of Mat, Col, Row and Cube classes, eg. mat X(4, 5, fill::zeros)
  • Initial implementation of wrap<subview>
  • Improved implementation of as<>() and wrap() for sparse matrices
  • Converted main vignette from LaTeX style minted to lstlisting which permits builds on CRAN; removed set BuildVignettes: FALSE.
Courtesy of CRANberries, there is also a diffstat report for the most recent release As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

Michal &#268;iha&#345;: Enca 1.15

Enca 1.15 has been just released. It does not bring any new features, just a little of cleanup and officially moves it's code to GitHub. If you don't know Enca, it is an Extremely Naive Charset Analyser. It detects character set and encoding of text files and can also convert them to other encodings using either a built-in converter or external libraries and tools like libiconv, librecode, or cstocs. Full list of changes for 1.15 release: Still enca is in maintenance mode only and I have no intentions to write new features. However there is no limitation to other contributors :-). You can download from http://cihar.com/software/enca/.

Filed under: Enca English 2 comments Flattr this!

29 September 2013

Dirk Eddelbuettel: Rcpp 0.10.5

A new version of Rcpp is now on the CRAN network for GNU R; binaries for Debian have been uploaded as well. Once more, this release brings a large number of exciting changes to Rcpp. Some concern usability, some bring new features, some increase performance; see below for the detailed list. We have now released three updates on a quarterly cycle; if we keep this up the next version ought to be ready at the end of December. As in the past, we tested the release rather rigorously by checking against all packages I could (relatively easily) built on my server: this time it successfully passed \code R CMD check for all 107 packages I can build locally out of a total of 136 packages. (Two failed: one for an error in \code Makevars , and one for the need of an X11 server during tests; this may get addressed in the in test script next time). As all of these 107 packages passed, we do not expect any issues with dependent packages. Should there be issues we would appreciate a note, preferably with reproducible code, to the rcpp-devel mailing list. The complete NEWS entry for 0.10.4 is below; more details are in the ChangeLog file in the package and on the Rcpp Changelog page.
Changes in Rcpp version 0.10.5 (2013-09-28)
  • Changes in R code:
    • New R function demangle that calls the DEMANGLE macro.
    • New R function sizeof to query the byte size of a type. This returns an object of S3 class bytes that has a print method showing bytes and bits.
  • Changes in Rcpp API:
    • Add defined(__sun) to lists of operating systems to test for when checking for lack of backtrace() needed for stack traces.
    • as<T*>, as<const T*>, as<T&> and as<const T&> are now supported, when T is a class exposed by modules, i.e. with RCPP_EXPOSED_CLASS
    • DoubleVector as been added as an alias to NumericVector
    • New template function is<T> to identify if an R object can be seen as a T. For example is<DataFrame>(x). This is a building block for more expressive dispatch in various places (modules and attributes functions).
    • wrap can now handle more types, i.e. types that iterate over std::pair<const KEY, VALUE> where KEY can be converted to a String and VALUE is either a primitive type (int, double) or a type that wraps. Examples :
      • std::map<int, double> : we can make a String from an int, and double is primitive
      • boost::unordered_map<double, std::vector<double> >: we can make a String from a double and std::vector<double> can wrap itself
      Other examples of this are included at the end of the wrap unit test file (runit.wrap.R and wrap.cpp).
    • wrap now handles containers of classes handled by modules. e.g. if you expose a class Foo via modules, then you can wrap vector<Foo>, ... An example is included in the wrap unit test file.
    • RcppLdFlags(), often used in Makevars files of packages using Rcpp, is now exported from the package namespace.
  • Changes in Attributes:
    • Objects exported by a module (i.e. by a RCPP_MODULE call in a file that is processed by sourceCpp) are now directly available in the environment. We used to make the module object available, which was less useful.
    • A plugin for openmp has been added to support use of OpenMP.
    • Rcpp::export now takes advantage of the more flexible as<>, handling constness and referenceness of the input types. For users, it means that for the parameters of function exported by modules, we can now use references, pointers and const versions of them. The file Module.cpp file has an example.
    • No longer call non-exported functions from the tools package
    • No longer search the inline package as a fallback when loading plugins for the the Rcpp::plugins attribute.
  • Changes in Modules:
    • We can now expose functions and methods that take T& or const T& as arguments. In these situations objects are no longer copied as they used to be.
  • Changes in sugar:
    • is_na supports classes DatetimeVector and DateVector
  • Changes in Rcpp documentation:
    • The vignettes have been moved from inst/doc/ to the vignettes directory which is now preferred.
    • The appearance of the vignettes has been refreshed by switching to the Bistream Charter font, and microtype package.
  • Deprecation of RCPP_FUNCTION_*:
    • The macros from the preprocessor_generated.h file have been deprecated. They are still available, but they print a message in addition to their expected behavior.
    • The macros will be permanently removed in the first Rcpp release after July 2014.
    • Users of these macros should start replacing them with more up-to-date code, such as using 'Rcpp attributes' or 'Rcpp modules'.
Thanks to CRANberries, you can also look at a diff to the previous release 0.10.4. As always, even fuller details are on the Rcpp Changelog page and the Rcpp page which also leads to the downloads, the browseable doxygen docs and zip files of doxygen output for the standard formats. A local directory has source and documentation too. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page

Ian Campbell: qcontrol 0.5.2

I've just released qcontrol 0.5.2. Changes since the last release: Get it from gitorious or http://www.hellion.org.uk/qcontrol/releases/0.5.2/. The Debian package will be uploaded shortly.

Andreas Metzler: Exim 4.82rc1 in experimental

Exim 4.82rc1 is available in experimental. See NewStuff in upstream GIT for a list of newly added features.

Joachim Breitner: Heidelberg Laureates Forum 2013

During the last week I was attending the first Heidelberg Laureates Forum as one of the lucky 200 accepted young scientists. The HFL is a (from now on hopefully yearly) event that brings together Fields Medalists, Abel Prize laureates and Turing Award winners with young scientists (undergraduates, Ph.D. students and postdocs) from both fields in the city of Heidelberg. The extremely well organized week consisted of lectures from the laureates, some workshops held by postdocs, excursions and plenty of good food. Videos of the lectures are available (but don t work on Linux, at least not for me ), and I have shot a few pictures of the event as well. I believe that my favourite lectures where Michael Atiyah s Advice to a Young Mathematician , Vladimir Voevodsky s Univalent Foundations of Mathematics , William Morton Kahan s Desperately Needed Remedies for the Undebuggability of Large-Scale Floating-Point Computations in Science and Engineering and Alan Kay s Putting Turing to Work . Where are all the functional programmers? During that event, one gets to talk to many other math and computer scientists researchers; sometimes just Where are you from? and What do you do? , sometimes long discussions. Unfortunately, I hardly found one who is into functional programming language research is that only because the event was parallel to ICFP (which I really would have liked to attend as well), or is functional programming really just about 1% of all computer science? What is a proof? My other research interest lies in interactive theorem proving, especially using Isabelle. Of course that is a topic that one can discuss with almost everyone at that event, including the mathematicians. The reactions were rather mixed: On the one end of the spectrum, some mathematicians seriously doubt that they would ever trust a computer to check proofs and that it would ever be efficient enough to use. Others would not mind having a button that tells whether their paper written in LaTeX is correct , but were not keen to invest time or thought into making the proof readable by the computer. And then there were some (but very few!) who had not heard of theorem proving before and were very excited by the prospect of being able to obtain certainty about their proofs immediately and without having to bother other scientists with it. During the mathematician s panel discussions, where I posed the question Do you see value in or even a need for machine-checked proofs in mathematics. , Efim Zelmanov (Fields Medal 1994) said a proof is what other mathematicians see as a proof . I found this attitude a bit surprising for me, a proof has always been a rigorous derivation within a formal system (say, ZFC set theory), and what we write in papers is a (less formal) description of the actual proof, whose existence we believe in. Therefore I was very happy to see Vladimir Voevodsky give a very committed talk about Univalent Foundations and how using that as the language for mathematics will allow more of mathematics to be cast in a formal, machine-checked form. I got the chance to discuss this with him in person, as I wanted to hear his option on Isabelle, and especially on the usefulness of the style of structured proof that Isar provides, and which is closer to the style of proofs that mathematicians use in papers. He said that he enjoyed writing his proof in the style required in Type Theory and in Coq, and that maybe mathematicians should and will adjust to the language of the system, while I believe that a structured proof languages like Isar, independent of the underlying logic (HOL in this case; which is insufficient to form a base for all of abstract mathematics), is a very useful feature and that proof assistants should adjust to the mathematicians.
We also briefly discussed the idea of mine to work with theorem provers already with motivated students in high schools, e.g. in math clubs, and found that simple proofs about arithmetic of natural numbers could be feasible here, without being too trivial. All in all a very rewarding and special week, and I can only recommend to try to attend one of the next forums, if possible.

Petter Reinholdtsen: Finally, Debian Edu Wheezy is released today!

A few hours ago, the announcement for the first stable release of Debian Edu Wheezy went out from the Debian publicity team. The complete announcement text can be found at the Debian News section, translated to several languages. Please check it out. There is one minor known problem that we will fix very soon. One can not install a amd64 Thin Client Server using PXE, as the /var/ partition is too small. A workaround is to extend the partition (use lvresize + resize2fs in tty 2 while installing).

MJ Ray: Send updates to live cycling news reports to the speech synth

The BBC coverage of the UCI Women Road Race World Championship wasn t starting until 3pm, BBC Radio 5 Live had football and Sports Extra was playing an advert loop (really BBC?), Eurosport wasn t covering the race at all, RAI Sport 2 had coverage which was fine while I was watching the TV, but my Italian isn t good enough to follow the commentary and I wanted to get some other stuff done. So the obvious thing is to have the computer watch for changes to the great http://live.cyclingnews.com/ ticker and read them out, right? Well, it was to me. Here s the script I used:
#!/usr/bin/rc
# Send updates to live cycling news reports to the speech synth
# initialise
url=http://live.cyclingnews.com/
if (~ $1 *:*)  
  url=$1
 
last=""
while (true)  
    # download the update and strip html - if you don't have html2text try
    # sed -e '1,/<ol/d;s/<br[^>]*>/n/g;s/<[^>]*>//g;s/ / /g;s/[[:space:]]*$//'
    next= () curl -s $url   html2text -width 9999   sed -e 's/^ *[0-9]*. //'  
    # look for some added lines in the update section - timezone will need changing for non-European races
    say= () diff -u < echo $last  < echo $next  
        sed -ne '/^+/!d;s///;s/**//g;/ CES*T/,/^ *$/p'   head -9  
    # feed them to the speech synth in reverse order
    echo $say '
      Race Update'   tac   spd-say -e
    # update variables, pause and loop
    last=$next
    # set this to a prime number over 60, like 61, 67, 71, 73, 79, 83, 89
    sleep 67
 
Any questions, comments or improvements? I could have done more, like not saying Race Update even when there was no update, but I wanted to start listening as soon as possible!

28 September 2013

Steve Kemp: Some thoughts ..

It has taken just over two weeks for blogspam to reject 1 million SPAM comments. I'm not sure how paranoid I should be about false-positives now, (I accept false-negatives easily enough). Using node.js is pretty good for making toy servers, and on that basis here's another toy server: This is a small server which is designed to accept HTTP-POSTs containing a payload of a message, these are stored and later retrieved. Seems like a simple thing, right? Imagine how it is used:
root@server1:~# record-log Upgraded mysql
root@server2:~# record-log Tweaked /etc/sysctl.conf
root@server3:~# record-log Added user 'bob'
root@server3:~# record-log Added user 'steve'
Later:
root@server3:~# get-recent
1.2.3.4 2013-09-28T08:08:09.211Z
root:Added user 'bob'
1.2.3.4 2013-09-28T08:08:10.211Z
root:Added user 'steve'
In short it makes it easy to record "activity", and later retrieve it. A host can only fetch the entries it stored, but if you've got access to the remote server then you can get all logs. I suspect a more standard solution is to use syslog-ng, and logger, or similar. But it is a cute hack and I suspect if you've the discipline to record actions then this is actually reasonably useful.

Daniel Kahn Gillmor: RIP Cookiepuss

Yesterday, i said a sad goodbye to an old friend at ABC No Rio. Cookiepuss was a steadfast companion in my volunteer shifts at the No Rio computer center, a cranky yet gregarious presence. I met her soon after moving to New York, and have hung out with her nearly every week for years. [Cookiepuss -- No Dogs No Masters] She had the run of the building at ABC No Rio, and was friends with all sorts of people. She was known and loved by punks and fine artists, by experimental musicians and bike mechanics, computer geeks and librarians, travelers and homebodies, photographers, screenprinters, anarchists, community organizers, zinesters, activists, performers, and weirdos of all stripes. For years, she received postcards from all over the world, including several from people who had never even met her in person. In her younger days, she was a ferocious mouser, and even as she shrank with age and lost some of her teeth she remained excited about food. She was an inveterate complainer; a pants-shredder; a cat remarkably comfortable with dirt; a welcoming presence to newcomers and a friendly old curmudgeon who never seemed to really hold a grudge even when i had to do horrible things like help her trim her nails. After a long life, she died having said her goodbyes, and surrounded by people who loved her. I couldn't have asked for better, but I miss her fiercely.

27 September 2013

Erich Schubert: Big Data madness and reality

"Big Data" has been hyped a lot, and due to this now is burning down to get some reality checking. It's been already overdue, but it is now happening.
I have seen a lot of people be very excited about NoSQL databases; and these databases do have their use cases. However, you just cannot put everything into NoSQL mode and expect it to just work. That is why we have recently seen NewSQL databases, query languages for NoSQL databases etc. - and in fact, they all move towards relational database management again.
Sound new database systems seem to be mostly made up of three aspects: in-memory optimization instead of optimizing for on-disk operation (memory just has become a lot cheaper the last 10 years), the execution of queries on the servers that store the actual data (you may want to call this "stored procedures" if you like SQL, or "map-reduce" if you like buzzwords), and optimized memory layouts (many of the benefits of "colum store" databases come from having a single, often primitive, datatype for the full column to scan, instead of alternating datatypes in records.

However, here is one point you need to consider:
is your data actually this "big"? Big as in: Google scale.
I see people use big data and Hadoop a lot when they just shouldn't. I see a lot of people run Hadoop in a VM on their laptop. Ouch.
The big data technologies are not a one-size-fits-all solution. They are the supersize-me solution, and supersize just does not fit every task.
When you look at the cases where Hadoop is really successful, it is mostly in keeping the original raw data, and enabling people to re-scan the full data again when e.g. their requirements changed. This is where Hadoop is really good at: managing 100 TB of data, and allowing you to quickly filter out the few GB that you really need for your current task.
For the actual analysis - or when you don't have 100 TB, and a large cluster anyway - then just don't try to hadoopify everything.
Here is a raw number from a current experiment. I have a student work on indexing image data; he is implementing some state of the art techniques. For these, a large number of image features are extracted, and then clustering is used to find "typical" features to improve image search.
The benchmarking image set is 56 GB (I have others with 2 TB to use next). The subset the student is currently processing is 13 GB. Extracting 2.3 million 128 dimensional feature vectors reduces this to about 1.4 GB. As you can see, the numbers drop quickly.
State of the art seems to be to load the data into Hadoop, and run clustering (actually, this is more of a vector quantization than clustering) into 1000 groups. Mahout is the obvious candidate to run this on Hadoop.
However, as I've put a lot of effort into the data mining software ELKI, I considered also to try processing it in ELKI.
By cutting the data into 10 MB blocks, Mahout/Hadoop can run the clustering in 52x parallel mappers. k-Means is an iterative algorithm, so it needs multiple processes. I have fixed the number of iterations to 10, which should produce a good enough approximation for my use cases.
K-means is embarrassingly parallel, so one would expect the cluster to really shine at this task. Well, here are some numbers:

So what is happening? Why is ELKI beating Mahout by a factor of 10x?
It's (as always) a mixture of a number of things:
Let me emphasize this: I'm not saying, Hadoop/Mahout is bad. I'm saying: this data set is not big enough to make Mahout beneficial.

Conclusions: As long as your data fits into your main memory and takes just a few hours to compute, don't go for Hadoop.
It will likely be faster on a single node by avoiding the overhead associated with (current) distributed implementations.
Sometimes, it may also be a solution to use the cluster only for preparing the data, then get it to a powerful workstation, and analyze it there. We did do this with the images: for extracting the image features, we used a distributed implementation (not on Hadoop, but on a dozen PCs).
I'm not saying it will stay that way. I have plans for starting "Project HELKI", aka "ELKI on Hadoop". Because I do sometimes hit the barrier of what I can compute on my 8 core CPU in an "reasonable" amount of time. And of course, Mahout will improve over time, and hopefully lose some of its "Java boxing" weight.
But before trying to run everything on a cluster, always try to run it on a single node first. You can still figure out how to scale up later, once you really know what you need.
And last but not least, consider whether scaling up really makes sense. K-means results don't really get better with a larger data set. They are averages, and adding more data will likely only change the last few digits. Now if you have an implementation that doesn't pay attention to numerical issues, you might end up with more numerical error than you gained from that extra data.
In fact, k-means can effectively be accelerated by processing a sample first, and only refining this on the full data set then. And: sampling is the most important "big data" approach. In particular when using statistical methods, consider whether more data can really be expected to improve your quality.
Better algorithms: K-means is a very crude heuristic. It optimizes the sum of squared deviations, which may be not too meaningful for your problem. It is not very noise tolerant, either. And there are thousands of variants. For example bisecting k-means, which no longer is embarrassingly parallel (i.e. it is not as easy to implement on MapReduce), but took just 7 minutes doing 20 iterations for each split. The algorithm can be summarized as starting with k=2, then always splitting the largest cluster in two until you have the desired k. For many use cases, this result will be just as good as the full k-means result.
Don't get me wrong. There are true big data problems. Web scale search, for example. Or product and friend recommendations at Facebook scale. But chances are that you don't have this amount of data. Google probably doesn't employ k-means at that scale either. (actually, Google runs k-means on 5 mio keypoints for vector quantization; which, judging my experience here, can still be done one a single host; in particular with hierarchical approaches such as bisecting k-means)
Don't choose the wrong tool for the wrong problem!

Petter Reinholdtsen: Videos about the Freedombox project - for inspiration and learning

The Freedombox project have been going on for a while, and have presented the vision, ideas and solution several places. Here is a little collection of videos of talks and presentation of the project. A larger list is available from the Freedombox Wiki. On other news, I am happy to report that Freedombox based on Debian Jessie is coming along quite well, and soon both Owncloud and using Tor should be available for testers of the Freedombox solution. :) In a few weeks I hope everything needed to test it is included in Debian. The withsqlite package is already in Debian, and the plinth package is pending in NEW. The third and vital part of that puzzle is the metapackage/setup framework, which is still pending an upload. Join us on IRC (#freedombox on irc.debian.org) and the mailing list if you want to help make this vision come true.

Next.

Previous.