Search Results: "zed"

5 March 2017

Shirish Agarwal: To say or not to say

Voltaire For people who are visually differently-abled, the above reads To learn who rules over you, simply find out who you are not allowed to criticize Voltaire wrote this either in late 16th century or early 17th century and those words were as apt in those times, as it is in these turbulent times as well. Update 05/03 According to @bla these words are attributable to a neo-nazi and apparently a child abuser. While I don t know the context in which it was shared, it describes the environment in which we are perfectly. Please see his comment for a link and better understanding. The below topic requires a bit of maturity, so if you are easily offended, feel free not to read further. While this week-end I was supposed to share about the recent Science Day celebrations that we did last week Science Day celebrations at GMRT Would explore it probably next week. This week the attempt is to share thoughts which had been simmering at the back of my mind for more than 2 weeks or more and whose answers are not clear to me. My buttons were pressed when Martin f. Kraft shared about a CoC violation and the steps taken therein. While it is easy to say with 20:20 hind-sight to say that the gentleman acted foolishly, I don t really know the circumstances to pass the judgement so quickly. In reality, while I didn t understand the joke in itself, I have to share some background by way of anecdotes as to why it isn t so easy for me to give a judgement call. a. I don t know the topics chosen by stand-up comedians in other countries, in India, most of the stand-up acts are either about dating or sex or somewhere in-between, which is lovingly given the name Leela (dance of life) in Indian mythology. I have been to several such acts over the years at different events, different occasions and 99.99% of the time I would see them dealing with pedophilia, necrophilia and all sorts of deviants in sexuality and people laughing wildly, but couple of times when the comedian shared the term sex with people, educated, probably more than a few world-travelled middle to higher-middle class people were shocked into silence. I had seen this not in once but 2-3 times in different environments and was left wondering just couple of years back Is sex such a bad word that people get easily shocked ? Then how is it that we have 1.25 billion + people in India. There had to be some people having sex. I don t think that all 1.25 billion people are test-tube babies. b. This actually was what lead to my quandary last year when my sharing of My Experience with Debian which I had carefully prepared for newbies, seeing seasoned debian people, I knew my lame observations wouldn t cut ice with them and hence had to share my actual story which involved a bit of porn. I was in two minds whether or not to say it till my eyes caught a t-shirt on which it was said We make porn or something to that effect. That helped me share my point. c. Which brings me to another point, it seems it is becoming increasingly difficult to talk about anything either before apologizing to everyone and not really knowing who will take offence at what and what the repercussions might be. In local sharings, I always start with a blanket apology that if I say something that offends you, please let me know afterwards so I can work on it. As the term goes You can t please everyone and that is what happens. Somebody sooner or later would take offence at something and re-interpret it in ways which I had not thought of. Charlie Chaplin - King of self-deprecating humor From the little sharings and interactions I have been part of, I find people take offence at the most innocuous things. For instance, one of the easy routes of not offending anyone is to use self-deprecating humour (or so I thought) either of my race, caste, class or even my issues with weight and each of the above would offend somebody. Charlie Chaplin didn t have those problems. If somebody is from my caste, I m portraying the caste in a certain light, a certain slant. If I m talking about weight issues, then anybody who is like me (fat) feels that the world is laughing at them rather than at me or they will be discriminated against. While I find the last point a bit valid, it leaves with me no tools and no humour. I neither have the observational powers or the skills that Kapil Sharma has and have to be me. While I have no clue what to do next, I feel the need to also share why humour is important in any sharing.- a. Break When any speaker uses humour, the idea is to take a break from a serious topic. It helps to break the monotony of the talk especially if the topic is full of jargon talk and new concepts. A small comedic relief brings the attendees attention back to the topic as it tends to wander in a long monotonous talk. b. Bridge Some of the better speakers use one or more humourous anecdote to explain and/or bridge the chasm between two different concepts. Some are able to produce humour on the fly while others like me have to rely on tried and tested methods. There is one another thing as well, humour is seems to be a mixture of social, cultural and political context and its very easy to have it back-fired upon you. For instance, I attempted humour on refugees, probably not the best topic to try humour in the current political climate, and predictably, it didn t go down well. I had to share and explain about Robin Williams slightly dark yet humorous tale in Moscow on the Hudson The film provides comedy and pathos in equal measure. You are left identifying with Vladimir Ivanoff (Robin Williams character) especially in the last scene where he learns of his grand-mother dying and he remembers her and his motherland, Russia and plays a piece on his saxophone as a tribute both to his grand-mother and the motherland. Apparently, in the height of the cold war, if a Russian defected to United States (land of Satan and other such terms used) you couldn t return to Russia. The movie, seen some years back left a deep impact on me. For all the shortcomings and ills that India has, even if I could, would and could I be happy anywhere else ? The answers are not so easy. With most NRI s (Non-Resident Indians) who emigrated for good did it not so much for themselves but for their children. So the children would hopefully have a better upbringing, better facilities, better opportunities than they would have got here. I talked to more than a few NRI s and while most of them give standardized answers, talking awhile and couple of beers or their favourite alcohol later, you come across deeply conflicted human beings whose heart is in India and their job, profession and money interests compel them to be in the country where they are serving. And Indian movies further don t make it easy for the Indian populace when trying to integrate into a new place. Some of the biggest hits of yesteryear s were about having the distinct Indian culture in their new country while the message of most countries is integration. I know of friends who are living in Germany who have to struggle through their German in order to be counted as a citizen, the same I guess is true of other countries as well, not just the language but the customs as well. They also probably struggle with learning more than one language and having an amalgamation of values which somehow they and their children have to make sense of. I was mildly shocked last week to learn that Mishi Choudary had to train people in the U.S. to differentiate between Afghan turban styles of wearing and the Punjabi style of wearing the turban. A simple search on Afghani turban and Punjabi turban reveals that there are a lot of differences between the two cultures. In fact, the way they talk, the way they walk, there are lots that differentiate the two cultures. The second shocking video was of an African-American man racially abusing an Indian-American girl. At first, I didn t believe it till I saw the video on facebook. My point through all that is it seems humour, that clean, simple exercise which brings a smile to you and uplifts the spirit doesn t seem to be as easy as it once was. Comments, suggestions, criticisms all are welcome.
Filed under: Miscellenous Tagged: #Elusive, #Fear, #hind-sight, #Humour, #immigrant, #integration, #Mishi Choudary, #refugee, #Robin Williams, #self-deprecating, #SFLC, #two-minds

4 March 2017

intrigeri: Contribute your skills to Debian in Paris, May 13-14 2017

(There is a French translation of this announcement.) Join us in Paris, on May 13-14 2017, and we will find a way in which you can help Debian with your current set of skills! You might even learn one or two things in passing (but you don't have to). Debian is a free operating system for your computer. An operating system is the set of basic programs and utilities that make your computer run. Debian comes with dozens of thousands of packages, precompiled software bundled up for easy installation on your machine. A number of other operating systems, such as Ubuntu and Tails, are based on Debian. The upcoming version of Debian, called Stretch, will be released later this year. We need you to help us make it awesome :) Whether you're a computer user, a graphics designer, or a bug triager, there are many ways you can contribute to this effort. We also welcome experience in consensus decision-making, anti-harassment teams, and package maintenance. No effort is too small and whatever you bring to this community will be appreciated. Here's what we will be doing: Goals and principles Before diving into the exact content of this event, a few words from the organization team. This is a work in progress, and a statement of intent. Not everything is organized and confirmed yet. We want to bring together a heterogeneous group of people. This goal will guide our handling of sponsorship requests, and will help us make decisions if more people want to attend than we can welcome properly. In other words: if you're part of a group that is currently under-represented in computer communities, we would like you to be able to attend. We are committed to providing a friendly, safe and welcoming environment for all, regardless of level of experience, gender, gender identity and expression, sexual orientation, disability, personal appearance, body size, race, ethnicity, age, religion, nationality, or other similar personal characteristic. Attending this event requires reading and respecting our Code of Conduct, that sets the standards in terms of behaviour for the whole event, including communication (public and private) before, while and after. There will be a team ready to act if you feel you have been or are being harassed or made uncomfortable by an attendee. We believe that money should not be a blocker for contributing to Debian. We will sponsor travel and find a place to sleep for as many enthusiastic attendees as possible. The space where this event will take place is accessible to wheelchairs. We are trying to organize a translation into (probably French) sign language. Vegan food should be provided for lunch. If you have any specific needs regarding food, please let us know when registering, and we will do our best. What we will be doing There will be a number of stations, i.e. physical space dedicated to people with a given set of skills, hosted by someone who is ready to make this space welcoming and productive. A few stations are already organized, and are described below. If you want to host a station yourself, or would like us to organize another one, please let us know. For example, you may want to assess the state of Debian Stretch for a specific field of interest, be it audio editing, office work, network auditing or whatever you are doing with Debian :) Test the upcoming version of Debian We will test Debian Stretch and gather feedback. We are particularly interested in: Experienced Debian contributors will be ready to relay this feedback to the relevant teams so it is put to good use. Hypra collaborators will be there to bring a focus on universal access technologies. Design and graphics Truth be told, Debian lacks people who are good at design and graphics. There are definitely a good number of low-hanging fruits that can be tackled in a week-end, either in Debian per-se, or in upstream) projects, or in Debian derivatives. This station will be hosted by Juliette Belin. She designed the themes for the last two versions of Debian. Triage Release Critical bugs Bugs flagged as Release Critical are blocking the release of the upcoming version of Debian. To fix them, it helps to make sure the bug report documents the up-to-date status of the bug, and of its resolution. One does not need to be a programmer to do this work! For example, you can try and reproduce bugs in software you use... or in software you will discover. This helps package maintainers better focus their work. This station will be hosted by Solveig. She has experience in bug triaging, in Debian and elsewhere. Cyril Brulebois, a long-time Debian developer, will provide support and advice upon request. Fix Release Critical bugs There will be a Bug Squashing Party. Where? When? How to register? See https://wiki.debian.org/BSP/2017/05/fr/Paris for the exact address and time. Please register by the end of March if you want to attend this event! If you have any questions, please get in touch with us.

2 March 2017

Joey Hess: what I would ask my lawyers about the new Github TOS

The Internet saw Github's new TOS yesterday and collectively shrugged. That's weird.. I don't have any lawyers, but the way Github's new TOS is written, I feel I'd need to consult with lawyers to understand how it might affect the license of my software if I hosted it on Github. And the license of my software is important to me, because it is the legal framework within which my software lives or dies. If I didn't care about my software, I'd be able to shrug this off, but since I do it seems very important indeed, and not worth taking risks with. If I were looking over the TOS with my lawyers, I'd ask these questions...
4 License Grant to Us
This seems to be saying that I'm granting an additional license to my software to Github. Is that right or does "license grant" have some other legal meaning? If the Free Software license I've already licensed my software under allows for everything in this "License Grant to Us", would that be sufficient, or would my software still be licenced under two different licences? There are violations of the GPL that can revoke someone's access to software under that license. Suppose that Github took such an action with my software, and their GPL license was revoked. Would they still have a license to my software under this "License Grant to Us" or not? "Us" is actually defined earlier as "GitHub, Inc., as well as our affiliates, directors, subsidiaries, contractors, licensors, officers, agents, and employees". Does this mean that if someone say, does some brief contracting with Github, that they get my software under this license? Would they still have access to it under that license when the contract work was over? What does "affiliates" mean? Might it include other companies? Is it even legal for a TOS to require a license grant? Don't license grants normally involve an intentional action on the licensor's part, like signing a contract or writing a license down? All I did was loaded a webpage in a browser and saw on the page that by loading it, they say I've accepted the TOS. (I then set about removing everything from Github.) Github's old TOS was not structured as a license grant. What reasons might they have for structuring this TOS in such a way? Am I asking too many questions only 4 words into this thing? Or not enough?
Your Content belongs to you, and you are responsible for Content you post even if it does not belong to you. However, we need the legal right to do things like host it, publish it, and share it. You grant us and our legal successors the right to store and display your Content and make incidental copies as necessary to render the Website and provide the Service.
If this is a software license, the wording seems rather vague compared with other software licenses I've read. How much wiggle room is built into that wording? What are the chances that, if we had a dispute and this came before a judge, that Github's laywers would be able to find a creative reading of this that makes "do things like" include whatever they want? Suppose that my software is javascript code or gets compiled to javascript code. Would this let Github serve up the javascript code for their users to run as part of the process of rendering their website?
That means you're giving us the right to do things like reproduce your content (so we can do things like copy it to our database and make backups); display it (so we can do things like show it to you and other users); modify it (so our server can do things like parse it into a search index); distribute it (so we can do things like share it with other users); and perform it (in case your content is something like music or video).
Suppose that Github modified my software, does not distribute the modified version, but converts it to javascipt code and distributes that to their users to run as part of the process of rendering their website. If my software is AGPL licensed, they would be in violation of that license, but doesn't this additional license allow them to modify and distribute my software in such a way?
This license does not grant GitHub the right to sell your Content or otherwise distribute it outside of our Service.
I see that "Service" is defined as "the applications, software, products, and services provided by GitHub". Does that mean at the time I accept the TOS, or at any point in the future? If Github tomorrow starts providing say, an App Store service, that necessarily involves distribution of software to others, and they put my software in it, would that be allowed by this or not? If that hypothetical Github App Store doesn't sell apps, but licenses access to them for money, would that be allowed under this license that they want to my software?
5 License Grant to Other Users Any Content you post publicly, including issues, comments, and contributions to other Users' repositories, may be viewed by others. By setting your repositories to be viewed publicly, you agree to allow others to view and "fork" your repositories (this means that others may make their own copies of your Content in repositories they control).
Let's say that company Foo does something with my software that violates its GPL license and the license is revoked. So they no longer are allowed to copy my software under the GPL, but it's there on Github. Does this "License Grant to Other Users" give them a different license under which they can still copy my software? The word "fork" has a particular meaning on Github, which often includes modification of the software in a repository. Does this mean that other users could modify my software, even if its regular license didn't allow them to modify it or had been revoked? How would this use of a platform-specific term "fork" be interpreted in this license if it was being analized in a courtroom?
If you set your pages and repositories to be viewed publicly, you grant each User of GitHub a nonexclusive, worldwide license to access your Content through the GitHub Service, and to use, display and perform your Content, and to reproduce your Content solely on GitHub as permitted through GitHub's functionality. You may grant further rights if you adopt a license.
This paragraph seems entirely innocious. So, what does your keen lawyer mind see in it that I don't? How sure are you about your answers to all this? We're fairly sure we know how well the GPL holds up in court; how well would your interpretation of all this hold up? What questions have I forgotten to ask?
And finally, the last question I'd be asking my lawyers: What's your bill come to? That much? Is using Github worth that much to me?

Antoine Beaupr : A short history of password hashers

These are notes from my research that led to the publication of the password hashers article. This article is more technical than the previous ones and compares the various cryptographic primitives and algorithms used in the various software I have reviewed. The criteria for inclusion on this list is fairly vague: I mostly included a password hasher if it was significantly different from the previous implementations in some way, and I have included all the major ones I could find as well.

The first password hashers Nic Wolff claims to be the first to have written such a program, all the way back in 2003. Back then the hashing algorithm was MD5, although Wolff has now updated the algorithm to use SHA-1 and still maintains his webpage for public use. Another ancient but unrelated implementation, is the Standford University Applied Cryptography's pwdhash software. That implementation was published in 2004 and unfortunately, that implementation was not updated and still uses MD5 as an hashing algorithm, but at least it uses HMAC to generate tokens, which makes the use of rainbow tables impractical. Those implementations are the simplest password hashers: the inputs are simply the site URL and a password. So the algorithms are, basically, for Wolff's:
token = base64(SHA1(password + domain))
And for Standford's PwdHash:
token = base64(HMAC(MD5, password, domain)))

SuperGenPass Another unrelated implementation that is still around is supergenpass is a bookmarklet that was created around 2007, originally using MD5 as well but now supports SHA512 now although still limited to 24 characters like MD5 (which needlessly limits the entropy of the resulting password) and still defaults MD5 with not enough rounds (10, when key derivation recommendations are more generally around 10 000, so that it's slower to bruteforce). Note that Chris Zarate, the supergenpass author, actually credits Nic Wolff as the inspiration for his implementation. Supergenpass is still in active development and is available for the browser (as a bookmarklet) or mobile (as an webpage). Supergenpass allows you to modify the password length, but also add an extra profile secret which adds to the password and generates a personalized identicon presumably to prevent phishing but it also introduces the interesting protection, the profile-specific secret only found later in Password Hasher Plus. So the Supergenpass algorithm looks something like this:
token = base64(SHA512(password + profileSecret + ":" + domain, rounds))

The Wijjo Password Hasher Another popular implementation is the Wijjo Password Hasher, created around 2006. It was probably the first shipped as a browser extension which greatly improved the security of the product as users didn't have to continually download the software on the fly. Wijjo's algorithm also improved on the above algorithms, as it uses HMAC-SHA1 instead of plain SHA-1 or HMAC-MD5, which makes it harder to recover the plaintext. Password Hasher allows you to set different password policies (use digits, punctuation, mixed case, special characters and password length) and saves the site names it uses for future reference. It also happens that the Wijjo Password Hasher, in turn, took its inspiration on different project, hashapass.com, created in 2006 and also based on HMAC-SHA-1. Indeed, hashapass "can easily be generated on almost any modern Unix-like system using the following command line pattern":
echo -n parameter \
  openssl dgst -sha1 -binary -hmac password \
  openssl enc -base64 \
  cut -c 1-8
So the algorithm here is obviously:
token = base64(HMAC(SHA1, password, domain + ":" + counter)))[:8]
... although in the case of Password Hasher, there is a special routine that takes the token and inserts random characters in locations determined by the sum of the values of the characters in the token.

Password Hasher Plus Years later, in 2010, Eric Woodruff ported the Wijjo Password Hasher to Chrome and called it Password Hasher Plus. Like the original Password Hasher, the "plus" version also keeps those settings in the extension and uses HMAC-SHA-1 to generate the password, as it is designed to be backwards-compatible with the Wijjo Password Hasher. Woodruff did add one interesting feature: a profile-specific secret key that gets mixed in to create the security token, like what SuperGenPass does now. Stealing the master password is therefore not enough to generate tokens anymore. This solves one security concern with Password Hasher: an hostile page could watch your keystrokes and steal your master password and use it to derive passwords on other sites. Having a profile-specific secret key, not accessible to the site's Javascript works around that issue, but typing the master password directly in the password field, while convenient, is just a bad idea, period. The final algorithm looks something like:
token = base64(HMAC(SHA1, password, base64(HMAC(SHA1, profileSecret, domain + ":" + counter))))
Honestly, that seems rather strange, but it's what I read from the source code, which is available only after decompressing the extension nowadays. I would have expected the simplest version:
token = base64(HMAC(SHA1, HMAC(SHA1, profileSecret, password), domain + ":" + counter))
The idea here would be "hide" the master password from bruteforce attacks as soon as possible... But maybe this is all equivalent. Regardless, Password Hasher Plus then takes the token and applies the same special character insertion routine as the Password Hasher.

LessPass Last year, Guillaume Vincent a french self-described "humanist and scuba diving fan" released the lesspass extension for Chrome, Firefox and Android. Lesspass introduces several interesting features. It is probably the first to include a commandline version. It also uses a more robust key derivation algorithm (PBKDF2) and takes into account the username on the site, allowing multi account support. The original release (version 1) used only 8192 rounds which is now considered too low. In the bug report it was interesting to note that LessPass couldn't do the usual practice of running the key derivation for 1 second to determine the number of rounds needed as the results need to be deterministic. At first glance, the LessPass source code seems clear and easy to read which is always a good sign, but of course, the devil is in the details. One key feature that is missing from Password Hasher Plus is the profile-specific seed, although it should be impossible, for a hostile web page to steal keystrokes from a browser extension, as far as I know. The algorithm then gets a little more interesting:
entropy = PBKDF2(SHA256, masterPassword, domain + username + counter, rounds, length)
where
    rounds=10000
    length=32
entropy is then used to pick characters to match the chosen profile. Regarding code readability, I got quickly confused by the PBKDF2 implementation: SubtleCrypto.ImportKey() doesn't seem to support PBKDF2 in the API, yet it's how it is used there... Is it just something to extract key material? We see later what looks like a more standard AES-based PBKDF2 implementation, but this code looks just strange to me. It could be me unfamilarity with newer Javascript coding patterns, however. There is also a lesspass-specific character picking routing that is also not base64, and different from the original Password Hasher algorithm.

Master Password A review of password hashers would hardly be complete without mentioning the Master Password and its elaborate algorithm. While the applications surrounding the project are not as refined (there is no web browser plugin and the web interface can't be easily turned into a bookmarklet), the algorithm has been well developed. Of all the password managers reviewed here, Master Password uses one of the strongest key derivation algorithms out there, scrypt:
key = scrypt( password, salt, cost, size, parallelization, length )
where
salt = "com.lyndir.masterpassword" + len(username) + name
cost = 32768
size = 8
parallelization = 2
length = 64
entropy = hmac-sha256(key, "com.lyndir.masterpassword" + len(domain) + domain + counter )
Master Password the uses one of 6 sets of "templates" specially crafted to be "easy for a user to read from a screen and type using a keyboard or smartphone" and "compatible with most site's password policies", our "transferable" criteria defined in the first passwords article. For example, the default template mixes vowels, consonants, numbers and symbols, but carefully avoiding possibly visibly similar characters like O and 0 or i and 1 (although it does mix 1 and l, oddly enough). The main strength of Master Password seems to be the clear definition of its algorithm (although Hashpass.com does give out OpenSSL commandline examples...), which led to its reuse in another application called freepass. The Master Password app also doubles as a stateful password manager...

Other implementations I have also considered including easypasswords, which uses PBKDF2-HMAC-SHA1, in my list of recommendations. I discovered only recently that the author wrote a detailed review of many more password hashers and scores them according to their relative strength. In the end, I ended up covering more LessPass since the design is very similar and LessPass does seem a bit more usable. Covering LessPass also allowed me to show the contrast and issues regarding the algorithm changes, for example. It is also interesting to note that the EasyPasswords author has criticized the Master Password algorithm quite severely:
[...] scrypt isn t being applied correctly. The initial scrypt hash calculation only depends on the username and master password. The resulting key is combined with the site name via SHA-256 hashing then. This means that a website only needs to break the SHA-256 hashing and deduce the intermediate key as long as the username doesn t change this key can be used to generate passwords for other websites. This makes breaking scrypt unnecessary[...]
During a discussion with the Master Password author, he outlined that "there is nothing "easy" about brute-force deriving a 64-byte key through a SHA-256 algorithm." SHA-256 is used in the last stage because it is "extremely fast". scrypt is used as a key derivation algorithm to generate a large secret and is "intentionnally slow": "we don't want it to be easy to reverse the master password from a site password". "But it' unnecessary for the second phase because the input to the second phase is so large. A master password is tiny, there are only a few thousand or million possibilities to try. A master key is 8^64, the search space is huge. Reversing that doesn't need to be made slower. And it's nice for the password generation to be fast after the key has been prepared in-memory so we can display site passwords easily on a mobile app instead of having to lock the UI a few seconds for every password." Finally, I considered covering Blum's Mental Hash (also covered here and elsewhere). This consists of an algorithm that can basically be ran by the human brain directly. It's not for the faint of heart, however: if I understand it correctly, it will require remembering a password that is basically a string of 26 digits, plus compute modulo arithmetics on the outputs. Needless to say, most people don't do modulo arithmetics every day...

22 February 2017

Antoine Beaupr : The case against password hashers

In previous articles, we have looked at how to generate passwords and did a review of various password managers. There is, however, a third way of managing passwords other than remembering them or encrypting them in a "vault", which is what I call "password hashing". A password hasher generates site-specific passwords from a single master password using a cryptographic hash function. It thus allows a user to have a unique and secure password for every site they use while requiring no storage; they need only to remember a single password. You may know these as "deterministic or stateless password managers" but I find the "password manager" phrase to be confusing because a hasher doesn't actually store any passwords. I do not think password hashers represent a good security tradeoff so I generally do not recommend their use, unless you really do not have access to reliable storage that you can access readily. In this article, I use the word "password" for a random string used to unlock things, but "token" to represent a generated random string that the user doesn't need to remember. The input to a password hasher is a password with some site-specific context and the output from a password hasher is a token.

What is a password hasher? A password hasher uses the master password and a label (generally the host name) to generate the site-specific password. To change the generated password, the user can modify the label, for example by appending a number. Some password hashers also have different settings to generate tokens of different lengths or compositions (symbols or not, etc.) to accommodate different site-specific password policies. The whole concept of password hashers relies on the concept of one-way cryptographic hash functions or key derivation functions that take an arbitrary input string (say a password) and generate a unique token, from which it is impossible to guess the original input string. Password hashers are generally written as JavaScript bookmarklets or browser plugins and have been around for over a decade. The biggest advantage of password hashers is that you only need to remember a single password. You do not need to carry around a password manager vault: there's no "state" (other than site-specific settings, which can be easily guessed). A password hasher named Master Password makes a compelling case against traditional password managers in its documentation:
It's as though the implicit assumptions are that everybody backs all of their stuff up to at least two different devices and backups in the cloud in at least two separate countries. Well, people don't always have perfect backups. In fact, they usually don't have any.
It goes on to argue that, when you lose your password: "You lose everything. You lose your own identity." The stateless nature of password hashers also means you do not need to use cloud services to synchronize your passwords, as there is (generally, more on that later) no state to carry around. This means, for example, that the list of accounts that you have access to is only stored in your head, and not in some online database that could be hacked without your knowledge. The downside of this is, of course, that attackers do not actually need to have access to your password hasher to start cracking it: they can try to guess your master key without ever stealing anything from you other than a single token you used to log into some random web site. Password hashers also necessarily generate unique passwords for every site you use them on. While you can also do this with password managers, it is not an enforced decision. With hashers, you get distinct and strong passwords for every site with no effort.

The problem with password hashers If hashers are so great, why would you use a password manager? Programs like LessPass and Master Password seem to have strong crypto that is well implemented, so why isn't everyone using those tools? Password hashing, as a general concept, actually has serious problems: since the hashing outputs are constantly compromised (they are sent in password forms to various possibly hostile sites), it's theoretically possible to derive the master password and then break all the generated tokens in one shot. The use of stronger key derivation functions (like PBKDF2, scrypt, or HMAC) or seeds (like a profile-specific secret) makes those attacks much harder, especially if the seed is long enough to make brute-force attacks infeasible. (Unfortunately, in the case of Password Hasher Plus, the seed is derived from Math.random() calls, which are not considered cryptographically secure.) Basically, as stated by Julian Morrison in this discussion:
A password is now ciphertext, not a block of line noise. Every time you transmit it, you are giving away potential clues of use to an attacker. [...] You only have one password for all the sites, really, underneath, and it's your secret key. If it's broken, it's now a skeleton-key [...]
Newer implementations like LessPass and Master Password fix this by using reasonable key derivation algorithms (PBKDF2 and scrypt, respectively) that are more resistant to offline cracking attacks, but who knows how long those will hold? To give a concrete example, if you would like to use the new winner of the password hashing competition (Argon2) in your password manager, you can patch the program (or wait for an update) and re-encrypt your database. With a password hasher, it's not so easy: changing the algorithm means logging in to every site you visited and changing the password. As someone who used a password hasher for a few years, I can tell you this is really impractical: you quickly end up with hundreds of passwords. The LessPass developers tried to facilitate this, but they ended up mostly giving up. Which brings us to the question of state. A lot of those tools claim to work "without a server" or as being "stateless" and while those claims are partly true, hashers are way more usable (and more secure, with profile secrets) when they do keep some sort of state. For example, Password Hasher Plus records, in your browser profile, which site you visited and which settings were used on each site, which makes it easier to comply with weird password policies. But then that state needs to be backed up and synchronized across multiple devices, which led LessPass to offer a service (which you can also self-host) to keep those settings online. At this point, a key benefit of the password hasher approach (not keeping state) just disappears and you might as well use a password manager. Another issue with password hashers is choosing the right one from the start, because changing software generally means changing the algorithm, and therefore changing passwords everywhere. If there was a well-established program that was be recognized as a solid cryptographic solution by the community, I would feel more confident. But what I have seen is that there are a lot of different implementations each with its own warts and flaws; because changing is so painful, I can't actually use any of those alternatives. All of the password hashers I have reviewed have severe security versus usability tradeoffs. For example, LessPass has what seems to be a sound cryptographic implementation, but using it requires you to click on the icon, fill in the fields, click generate, and then copy the password into the field, which means at least four or five actions per password. The venerable Password Hasher is much easier to use, but it makes you type the master password directly in the site's password form, so hostile sites can simply use JavaScript to sniff the master password while it is typed. While there are workarounds implemented in Password Hasher Plus (the profile-specific secret), both tools are more or less abandoned now. The Password Hasher homepage, linked from the extension page, is now a 404. Password Hasher Plus hasn't seen a release in over a year and there is no space for collaborating on the software the homepage is simply the author's Google+ page with no information on the project. I couldn't actually find the source online and had to download the Chrome extension by hand to review the source code. Software abandonment is a serious issue for every project out there, but I would argue that it is especially severe for password hashers. Furthermore, I have had difficulty using password hashers in unified login environments like Wikipedia's or StackExchange's single-sign-on systems. Because they allow you to log in with the same password on multiple sites, you need to choose (and remember) what label you used when signing in. Did I sign in on stackoverflow.com? Or was it stackexchange.com? Also, as mentioned in the previous article about password managers, web-based password managers have serious security flaws. Since more than a few password hashers are implemented using bookmarklets, they bring all of those serious vulnerabilities with them, which can range from account name to master password disclosures. Finally, some of the password hashers use dubious crypto primitives that were valid and interesting a decade ago, but are really showing their age now. Stanford's pwdhash uses MD5, which is considered "cryptographically broken and unsuitable for further use". We have seen partial key recovery attacks against MD5 already and while those do not allow an attacker to recover the full master password yet (especially not with HMAC-MD5), I would not recommend anyone use MD5 in anything at this point, especially if changing that algorithm later is hard. Some hashers (like Password Hasher and Password Plus) use a a single round of SHA-1 to derive a token from a password; WPA2 (standardized in 2004) uses 4096 iterations of HMAC-SHA1. A recent US National Institute of Standards and Technology (NIST) report also recommends "at least 10,000 iterations of the hash function".

Conclusion Forced to suggest a password hasher, I would probably point to LessPass or Master Password, depending on the platform of the person asking. But, for now, I have determined that the security drawbacks of password hashers are not acceptable and I do not recommend them. It makes my password management recommendation shorter anyway: "remember a few carefully generated passwords and shove everything else in a password manager". [Many thanks to Daniel Kahn Gillmor for the thorough reviews provided for the password articles.]
Note: this article first appeared in the Linux Weekly News. Also, details of my research into password hashers are available in the password hashers history article.

21 February 2017

Steinar H. Gunderson: 8-bit Y'CbCr ought to be enough for anyone?

If you take a random computer today, it's pretty much a given that it runs a 24-bit mode (8 bits of each of R, G and B); as we moved from palettized displays at some point during the 90s, we quickly went past 15- and 16-bit and settled on 24-bit. The reasons are simple; 8 bits per channel is easy to work with on CPUs, and it's on the verge of what human vision can distinguish, at least if you add some dither. As we've been slowly taking the CPU off the pixel path and replacing it with GPUs (which has specialized hardware for more kinds of pixels formats), changing formats have become easier, and there's some push to 10-bit (30-bit) deep color for photo pros, but largely, 8-bit per channel is where we are. Yet, I'm now spending time adding 10-bit input (and eventually also 10-bit output) to Nageru. Why? The reason is simple: Y'CbCr. Video traditionally isn't done in RGB, but in Y'CbCr; that is, a black-and-white signal (Y) and then two color-difference signals (Cb and Cr, roughly additional blueness and additional redness , respectively). We started doing this because it was convenient in analog TV (if you separate the two, black-and-white TVs can just ignore the color signal), but we kept doing it because it's very nice for reducing bandwidth: Human vision is much less sensitive to color than to brightness, so we can transfer the color channels in lower resolution and get away with it. (Also, a typical Bayer sensor can't deliver full color resolution anyway.) So most cameras and video codecs work in Y'CbCr, not RGB. Let's look at the implications of using 8-bit Y'CbCr, using a highly simplified model for, well, simplicity. Let's define Y = 1/3 (R + G + B), Cr = R - Y and Cb = B - Y. (The reverse transformation becomes R = Y + Cr, B = Y + Cb and G = 3Y - R - B.) This means that an RGB color such as pure gray ([127, 127, 127]) becomes [127, 0, 0]. All is good, and Y can go from 0 to 255, just like R, G and B can. A pure red ([255, 0, 0]) becomes [85, 170, 0], and a pure blue ([255, 0, 0]) becomes correspondingly [85, 0, 170]. But we can also have negative Cr and Cb values; a pure yellow ([0, 255, 255]) becomes [170, -170, 85], for instance. So we need to squeeze values from -170 to +170 into an 8-bit range, losing accuracy. Even worse, there are valid Y'CbCr triplets that don't correspond to meaningful RGB colors at all. For instance, Y'CbCr [255, 170, 0] would be RGB [425, 85, 255]; R is out of range! And Y'CbCr [255, -170, 0] would be RGB [85, -85, 255], that is, negative green. This isn't a problem for compression, as we can just avoid using those illegal colors with no loss of efficiency. But it means that the conversion in itself causes a loss; actually, if you do the maths on the real formulas (using the BT.601 standard), it turns out only 17% of the 24-bit Y'CbCr code words are valid! In other words, we lose about two and a half bits of data, and our 24 bits of accuracy have been reduced to 21.5. Or, to put it another way; 8-bit Y'CbCr is roughly equivalent to 7-bit RGB. Thus, pretty much all professional video uses 10-bit Y'CbCr. It's much more annoying to deal with (especially when you've got subsampling!), but if you're using SDI, there's not even any 8-bit version defined, so if you insist on 8-bit, you're taking data you're getting on the wire (whether you want it or not) and throwing 20% of it away. UHDTV standards (using HEVC) are also simply not defined for 8-bit; it's 10- and 12-bit only, even on the codec level. Parts of this is because UHDTV also supports HDR, so you have a wider RGB range than usual to begin with, and 8-bit would cause excessive banding. Using it on the codec level makes a lot of sense for another reason, namely that you reduce internal roundoff errors during processing by a lot; errors equal noise, and noise is bad for compression. I've seen numbers of 15% lower bitrate for H.264 at the same quality, although you also have to take into account that the encoeder also needs more CPU power that you could have used for a higher preset in 8-bit. I don't know how the tradeoff here works out, and you also have to take into account decoder support for 10-bit, especially when it comes to hardware. (When it comes to HEVC, Intel didn't get full fixed-function 10-bit support before Kaby Lake!) So indeed, 10-bit Y'CbCr makes sense even for quite normal video. It isn't a no-brainer to turn it on, though even though Nageru uses a compute shader to convert the 4:2:2 10-bit Y'CbCr to something the GPU can sample from quickly (ie., the CPU doesn't need to touch it), and all internal processing is in 16-bit floating point anyway, it still takes a nonzero amount of time to convert compared to just blasting through 8-bit, so my ultraportable probably won't make it anymore. (A discrete GPU has no issues at all, of course. My laptop converts a 720p frame in about 1.4 ms, FWIW.) But it's worth considering when you want to squeeze even more quality out of the system. And of course, there's still 10-bit output support to be written...

20 February 2017

Ritesh Raj Sarraf: Setting up appliances - the new way

I own a Fitbit Surge. But Fitibit chose to remain exclusive in terms of interoperability. Which means to make any sense out of the data that the watch gathers, you need to stick with what Fitbit mandates. Fair enough in today's trends. It also is part of their business model to restrict useful aspects of the report to Premium Membership. Again, fair enough in today's business' trends. But a nice human chose to write a bridge; to extract Fitbit data and feed into Google Fit. The project is written in Python, so you can get it to work on most common computer platforms. I never bothered to package this tool for Debian, because I never was sure when I'd throw away the Fitbit. But until that happens, I decided to use the tool to sync my data to Google Fit. Which led me to requirements.txt This project's requirement.txt lists versioned module dependencies, of which many modules in Debian, were either older or newer than what was mentioned in the requirements. To get the tool working, I installed it the pip way. 3 months later, something broke and I needed to revisit the installed modules. At that point, I realized that there's no such thing as: pip upgrade That further led me to dig on why anyone wouldn't add something so simple, because today, in the days of pip, snap, flatpak and dockers, Distributions are predicted to go obsolete and irrelevant. Users should get the SOURCES directly from the developers. But just looking at the date the bug was filed, killed my enthusiasm any further. So, without packaging for Debian, and without installing through pip, I was happy that my init has the ability to create confined and containerized environments, something that I could use to get the job done.
rrs@chutzpah:~$ sudo machinectl login fitbit
[sudo] password for rrs:
Connected to machine fitbit. Press ^] three times within 1s to exit session.
Debian GNU/Linux 9 fitbit pts/0
fitbit login: root
Last login: Fri Feb 17 12:44:25 IST 2017 on pts/1
The programs included with the Debian GNU/Linux system are free software;
the exact distribution terms for each program are described in the
individual files in /usr/share/doc/*/copyright.
Debian GNU/Linux comes with ABSOLUTELY NO WARRANTY, to the extent
permitted by applicable law.
root@fitbit:~# tail -n 25 /var/tmp/lxc/fitbit-google.log
synced calories - 1440 data points
------------------------------   2017-02-19  -------------------------
synced steps - 1440 data points
synced distance - 1440 data points
synced heart_rate - 38215 data points
synced weight - 0 logs
synced body_fat - 0 logs
synced calories - 1440 data points
------------------------------   2017-02-20  -------------------------
synced steps - 1270 data points
synced distance - 1270 data points
synced heart_rate - 32547 data points
synced weight - 0 logs
synced body_fat - 0 logs
synced calories - 1271 data points
Synced 7 exercises between : 2017-02-15 -- 2017-02-20
--------------------------------------------------------------------------
                                     Like it ?
star the repository : https://github.com/praveendath92/fitbit-googlefit
--------------------------------------------------------------------------
root@fitbit:~#

Categories:

Keywords:

Like:

15 February 2017

Antoine Beaupr : A look at password managers

As we noted in an earlier article, passwords are a liability and we'd prefer to get rid of them, but the current reality is that we do use a plethora of passwords in our daily lives. This problem is especially acute for technology professionals, particularly system administrators, who have to manage a lot of different machines. But it also affects regular users who still use a large number of passwords, from their online bank to their favorite social-networking site. Despite the remarkable memory capacity of the human brain, humans are actually terrible at recalling even short sets of arbitrary characters with the precision needed for passwords. Therefore humans reuse passwords, make them trivial or guessable, write them down on little paper notes and stick them on their screens, or just reset them by email every time. Our memory is undeniably failing us and we need help, which is where password managers come in. Password managers allow users to store an arbitrary number of passwords and just remember a single password to unlock them all. But there is a large variety of password managers out there, so which one should we be using? At my previous job, an inventory was done of about 40 different free-software password managers in different stages of development and of varying quality. So, obviously, this article will not be exhaustive, but instead focus on a smaller set of some well-known options that may be interesting to readers.

KeePass: the popular alternative The most commonly used password-manager design pattern is to store passwords in a file that is encrypted and password-protected. The most popular free-software password manager of this kind is probably KeePass. An important feature of KeePass is the ability to auto-type passwords in forms, most notably in web browsers. This feature makes KeePass really easy to use, especially considering it also supports global key bindings to access passwords. KeePass databases are designed for simultaneous access by multiple users, for example, using a shared network drive. KeePass has a graphical interface written in C#, so it uses the Mono framework on Linux. A separate project, called KeePassX is a clean-room implementation written in C++ using the Qt framework. Both support the AES and Twofish encryption algorithms, although KeePass recently added support for the ChaCha20 cipher. AES key derivation is used to generate the actual encryption key for the database, but the latest release of KeePass also added using Argon2, which was the winner of the July 2015 password-hashing competition. Both programs are more or less equivalent, although the original KeePass seem to have more features in general. The KeePassX project has recently been forked into another project now called KeePassXC that implements a set of new features that are present in KeePass but missing from KeePassX like:
  • auto-type on Linux, Mac OS, and Windows
  • database merging which allows multi-user support
  • using the web site's favicon in the interface
So far, the maintainers of KeePassXC seem to be open to re-merging the project "if the original maintainer of KeePassX in the future will be more active and will accept our merge and changes". I can confirm that, at the time of writing, the original KeePassX project now has 79 pending pull requests and only one pull request was merged since the last release, which was 2.0.3 in September 2016. While KeePass and derivatives allow multiple users to access the same database through the merging process, they do not support multi-party access to a single database. This may be a limiting factor for larger organizations, where you may need, for example, a different password set for different technical support team levels. The solution in this case is to use separate databases for each team, with each team using a different shared secret.

Pass: the standard password manager? I am currently using password-store, or pass, as a password manager. It aims to be "the standard Unix password manager". Pass is a GnuPG-based password manager that features a surprising number of features given its small size:
  • copy-paste support
  • Git integration
  • multi-user/group support
  • pluggable extensions (in the upcoming 1.7 release)
The command-line interface is simple to use and intuitive. The following, will, for example, create a pass repository, a 20 character password for your LWN account and copy it to the clipboard:
    $ pass init
    $ pass generate -c lwn 20
The main issue with pass is that it doesn't encrypt the name of those entries: if someone were to compromise my machine, they could easily see which sites I have access to simply by listing the passwords stored in ~/.password-store. This is a deliberate design decision by the upstream project, as stated by a mailing list participant, Allan Odgaard:
Using a single file per item has the advantage of shell completion, using version control, browse, move and rename the items in a file browser, edit them in a regular editor (that does GPG, or manually run GPG first), etc.
Odgaard goes on to point out that there are alternatives that do encrypt the entire database (including the site names) if users really need that feature. Furthermore, there is a tomb plugin for pass that encrypts the password store in a LUKS container (called a "tomb"), although it requires explicitly opening and closing the container, which makes it only marginally better than using full disk encryption system-wide. One could also argue that password file names do not hold secret information, only the site name and username, perhaps, and that doesn't require secrecy. I do believe those should be kept secret, however, as they could be used to discover (or prove) which sites you have access to and then used to perform other attacks. One could draw a parallel with the SSH known_hosts file, which used to be plain text but is now hashed so that hosts are more difficult to discover. Also, sharing a database for multi-user support will require some sort of file-sharing mechanism. Given the integrated Git support, this will likely involve setting up a private Git repository for your team, something which may not be accessible to the average Linux user. Nothing keeps you, however, from sharing the ~/.password-store directory through another file sharing mechanism like (say) Syncthing or Dropbox. You can use multiple distinct databases easily using the PASSWORD_STORE_DIR environment variable. For example, you could have a shell alias to use a different repository for your work passwords with:
    alias work-pass="PASSWORD_STORE_DIR=~/work-passwords pass"
Group support comes from a clever use of the GnuPG multiple-recipient encryption support. You simply have to specify multiple OpenPGP identities when initializing the repository, which also works in subdirectories:
    $ pass init -p Ateam me@example.com joelle@example.com
    mkdir: created directory '/home/me/.password-store/Ateam'
    Password store initialized for me@example.com, joelle@example.com
    [master 0e3dbe7] Set GPG id to me@example.com, joelle@example.com.
     1 file changed, 2 insertions(+)
     create mode 100644 Ateam/.gpg-id
The above will configure pass to encrypt the passwords in the Ateam directory for me@example.com and joelle@example.com. Pass depends on GnuPG to do the right thing when encrypting files and how those identities are treated is entirely delegated to GnuPG's default configuration. This could lead to problems if arbitrary keys can be injected into your key ring, which could confuse GnuPG. I would therefore recommend using full key fingerprints instead of user identifiers. Regarding the actual encryption algorithms used, in my tests, GnuPG 1.4.18 and 2.1.18 seemed to default to 256-bit AES for encryption, but that has not always been the case. The chosen encryption algorithm actually depends on the recipient's key preferences, which may vary wildly: older keys and versions may use anything from 128-bit AES to CAST5 or Triple DES. To figure out which algorithm GnuPG chose, you may want to try this pipeline:
    $ echo test   gpg -e -r you@example.com   gpg -d -v
    [...]
    gpg: encrypted with 2048-bit RSA key, ID XXXXXXX, created XXXXX
      "You Person You <you@example.com>"
    gpg: AES256 encrypted data
    gpg: original file name=''
    test
As you can see, pass is primarily a command-line application, which may make it less accessible to regular users. The community has produced different graphical interfaces that are either using pass directly or operate on the storage with their own GnuPG integration. I personally use pass in combination with Rofi to get quick access to my passwords, but less savvy users may want to try the QtPass interface, which should be more user-friendly. QtPass doesn't actually depend on pass and can use GnuPG directly to interact with the pass database; it is available for Linux, BSD, OS X, and Windows.

Browser password managers Most users are probably already using a password manager through their web browser's "remember password" functionality. For example, Chromium will ask if you want it to remember passwords and encrypt them with your operating system's facilities. For Windows, this encrypts the passwords with your login password and, for GNOME, it will store the passwords in the gnome-keyring storage. If you synchronize your Chromium settings with your Google account, Chromium will store those passwords on Google's servers, encrypted with a key that is stored in the Google Account itself. So your passwords are then only as safe as your Google account. Note that this was covered here in 2010, although back then Chromium didn't synchronize with the Google cloud or encrypt with the system-level key rings. That facility was only added in 2013. In Firefox, there's an optional, profile-specific master password that unlocks all passwords. In this case, the issue is that browsers are generally always open, so the vault is always unlocked. And this is for users that actually do pick a master password; users are often completely unaware that they should set one. The unlocking mechanism is a typical convenience-security trade-off: either users need to constantly input their master passwords to login or they don't, and the passwords are available in the clear. In this case, Chromium's approach of actually asking users to unlock their vault seems preferable, even though the developers actually refused to implement the feature for years. Overall, I would recommend against using a browser-based password manager. Even if it is not used for critical sites, you will end up with hundreds of such passwords that are vulnerable while the browser is running (in the case of Firefox) or at the whim of Google (in the case of Chromium). Furthermore, the "auto-fill" feature that is often coupled with browser-based password managers is often vulnerable to serious attacks, which is mentioned below. Finally, because browser-based managers generally lack a proper password generator, users may fail to use properly generated passwords, so they can then be easily broken. A password generator has been requested for Firefox, according to this feature request opened in 2007, and there is a password generator in Chrome, but it is disabled by default and hidden in the mysterious chrome://flags URL.

Other notable password managers Another alternative password manager, briefly mentioned in the previous article, is the minimalistic Assword password manager that, despite its questionable name, is also interesting. Its main advantage over pass is that it uses a single encrypted JSON file for storage, and therefore doesn't leak the name of the entries by default. In addition to copy/paste, Assword also supports automatically entering passphrases in fields using the xdo library. Like pass, it uses GnuPG to encrypt passphrases. According to Assword maintainer Daniel Kahn Gillmor in email, the main issue with Assword is "interaction between generated passwords and insane password policies". He gave the example of the Time-Warner Cable registration form that requires, among other things, "letters and numbers, between 8 and 16 characters and not repeat the same characters 3 times in a row". Another well-known password manager is the commercial LastPass service which released a free-software command-line client called lastpass-cli about three years ago. Unfortunately, the server software of the lastpass.com service is still proprietary. And given that LastPass has had at least two serious security breaches since that release, one could legitimately question whether this is a viable solution for storing important secrets. In general, web-based password managers expose a whole new attack surface that is not present in regular password managers. A 2014 study by University of California researchers showed that, out of five password managers studied, every one of them was vulnerable to at least one of the vulnerabilities studied. LastPass was, in particular, vulnerable to a cross-site request forgery (CSRF) attack that allowed an attacker to bypass account authentication and access the encrypted database.

Problems with password managers When you share a password database within a team, how do you remove access to a member of the team? While you can, for example, re-encrypt a pass database with new keys (thereby removing or adding certain accesses) or change the password on a KeePass database, a hostile party could have made a backup of the database before the revocation. Indeed, in the case of pass, older entries are still in the Git history. So access revocation is a problematic issue found with all shared password managers, as it may actually mean going through every password and changing them online. This fundamental problem with shared secrets can be better addressed with a tool like Vault or SFLvault. Those tools aim to provide teams with easy ways to store dynamic tokens like API keys or service passwords and share them not only with other humans, but also make them accessible to machines. The general idea of those projects is to store secrets in a central server and send them directly to relevant services without human intervention. This way, passwords are not actually shared anymore, which is similar in spirit to the approach taken by centralized authentication systems like Kerberos. If you are looking at password management for teams, those projects may be worth a look. Furthermore, some password managers that support auto-typing were found to be vulnerable to HTML injection attacks: if some third-party ad or content is able to successfully hijack the parent DOM content, it masquerades as a form that could fool auto-typing software as demonstrated by this paper that was submitted at USENIX 2014. Fortunately, KeePass was not vulnerable according to the security researchers, but LastPass was, again, vulnerable.

Future of password managers? All of the solutions discussed here assume you have a trusted computer you regularly have access to, which is a usage pattern that seems to be disappearing with a majority of the population. You could consider your phone to be that trusted device, yet a phone can be lost or stolen more easily than a traditional workstation or even a laptop. And while KeePass has Android and iOS ports, those do not resolve the question of how to share the password storage among those devices or how to back them up. Password managers are fundamentally file-based, and the "file" concept seems to be quickly disappearing, faster than we technologists sometimes like to admit. Looking at some relatives' use of computers, I notice it is less about "files" than images, videos, recipes, and various abstract objects that are stored in the "cloud". They do not use local storage so much anymore. In that environment, password managers lose their primary advantage, which is a local, somewhat offline file storage that is not directly accessible to attackers. Therefore certain password managers are specifically designed for the cloud, like LastPass or web browser profile synchronization features, without necessarily addressing the inherent issues with cloud storage and opening up huge privacy and security issues that we absolutely need to address. This is where the "password hasher" design comes in. Also known as "stateless" or "deterministic" password managers, password hashers are emerging as a convenient solution that could possibly replace traditional password managers as users switch from generic computing platforms to cloud-based infrastructure. We will cover password hashers and the major security challenges they pose in a future article.
Note: this article first appeared in the Linux Weekly News.

Antoine Beaupr : A look at password managers

As we noted in an earlier article, passwords are a liability and we'd prefer to get rid of them, but the current reality is that we do use a plethora of passwords in our daily lives. This problem is especially acute for technology professionals, particularly system administrators, who have to manage a lot of different machines. But it also affects regular users who still use a large number of passwords, from their online bank to their favorite social-networking site. Despite the remarkable memory capacity of the human brain, humans are actually terrible at recalling even short sets of arbitrary characters with the precision needed for passwords. Therefore humans reuse passwords, make them trivial or guessable, write them down on little paper notes and stick them on their screens, or just reset them by email every time. Our memory is undeniably failing us and we need help, which is where password managers come in. Password managers allow users to store an arbitrary number of passwords and just remember a single password to unlock them all. But there is a large variety of password managers out there, so which one should we be using? At my previous job, an inventory was done of about 40 different free-software password managers in different stages of development and of varying quality. So, obviously, this article will not be exhaustive, but instead focus on a smaller set of some well-known options that may be interesting to readers.

KeePass: the popular alternative The most commonly used password-manager design pattern is to store passwords in a file that is encrypted and password-protected. The most popular free-software password manager of this kind is probably KeePass. An important feature of KeePass is the ability to auto-type passwords in forms, most notably in web browsers. This feature makes KeePass really easy to use, especially considering it also supports global key bindings to access passwords. KeePass databases are designed for simultaneous access by multiple users, for example, using a shared network drive. KeePass has a graphical interface written in C#, so it uses the Mono framework on Linux. A separate project, called KeePassX is a clean-room implementation written in C++ using the Qt framework. Both support the AES and Twofish encryption algorithms, although KeePass recently added support for the ChaCha20 cipher. AES key derivation is used to generate the actual encryption key for the database, but the latest release of KeePass also added using Argon2, which was the winner of the July 2015 password-hashing competition. Both programs are more or less equivalent, although the original KeePass seem to have more features in general. The KeePassX project has recently been forked into another project now called KeePassXC that implements a set of new features that are present in KeePass but missing from KeePassX like:
  • auto-type on Linux, Mac OS, and Windows
  • database merging which allows multi-user support
  • using the web site's favicon in the interface
So far, the maintainers of KeePassXC seem to be open to re-merging the project "if the original maintainer of KeePassX in the future will be more active and will accept our merge and changes". I can confirm that, at the time of writing, the original KeePassX project now has 79 pending pull requests and only one pull request was merged since the last release, which was 2.0.3 in September 2016. While KeePass and derivatives allow multiple users to access the same database through the merging process, they do not support multi-party access to a single database. This may be a limiting factor for larger organizations, where you may need, for example, a different password set for different technical support team levels. The solution in this case is to use separate databases for each team, with each team using a different shared secret.

Pass: the standard password manager? I am currently using password-store, or pass, as a password manager. It aims to be "the standard Unix password manager". Pass is a GnuPG-based password manager that features a surprising number of features given its small size:
  • copy-paste support
  • Git integration
  • multi-user/group support
  • pluggable extensions (in the upcoming 1.7 release)
The command-line interface is simple to use and intuitive. The following, will, for example, create a pass repository, a 20 character password for your LWN account and copy it to the clipboard:
    $ pass init
    $ pass generate -c lwn 20
The main issue with pass is that it doesn't encrypt the name of those entries: if someone were to compromise my machine, they could easily see which sites I have access to simply by listing the passwords stored in ~/.password-store. This is a deliberate design decision by the upstream project, as stated by a mailing list participant, Allan Odgaard:
Using a single file per item has the advantage of shell completion, using version control, browse, move and rename the items in a file browser, edit them in a regular editor (that does GPG, or manually run GPG first), etc.
Odgaard goes on to point out that there are alternatives that do encrypt the entire database (including the site names) if users really need that feature. Furthermore, there is a tomb plugin for pass that encrypts the password store in a LUKS container (called a "tomb"), although it requires explicitly opening and closing the container, which makes it only marginally better than using full disk encryption system-wide. One could also argue that password file names do not hold secret information, only the site name and username, perhaps, and that doesn't require secrecy. I do believe those should be kept secret, however, as they could be used to discover (or prove) which sites you have access to and then used to perform other attacks. One could draw a parallel with the SSH known_hosts file, which used to be plain text but is now hashed so that hosts are more difficult to discover. Also, sharing a database for multi-user support will require some sort of file-sharing mechanism. Given the integrated Git support, this will likely involve setting up a private Git repository for your team, something which may not be accessible to the average Linux user. Nothing keeps you, however, from sharing the ~/.password-store directory through another file sharing mechanism like (say) Syncthing or Dropbox). You can use multiple distinct databases easily using the PASSWORD_STORE_DIR environment variable. For example, you could have a shell alias to use a different repository for your work passwords with:
    alias work-pass="PASSWORD_STORE_DIR=~/work-passwords pass"
Group support comes from a clever use of the GnuPG multiple-recipient encryption support. You simply have to specify multiple OpenPGP identities when initializing the repository, which also works in subdirectories:
    $ pass init -p Ateam me@example.com joelle@example.com
    mkdir: created directory '/home/me/.password-store/Ateam'
    Password store initialized for me@example.com, joelle@example.com
    [master 0e3dbe7] Set GPG id to me@example.com, joelle@example.com.
     1 file changed, 2 insertions(+)
     create mode 100644 Ateam/.gpg-id
The above will configure pass to encrypt the passwords in the Ateam directory for me@example.com and joelle@example.com. Pass depends on GnuPG to do the right thing when encrypting files and how those identities are treated is entirely delegated to GnuPG's default configuration. This could lead to problems if arbitrary keys can be injected into your key ring, which could confuse GnuPG. I would therefore recommend using full key fingerprints instead of user identifiers. Regarding the actual encryption algorithms used, in my tests, GnuPG 1.4.18 and 2.1.18 seemed to default to 256-bit AES for encryption, but that has not always been the case. The chosen encryption algorithm actually depends on the recipient's key preferences, which may vary wildly: older keys and versions may use anything from 128-bit AES to CAST5 or Triple DES. To figure out which algorithm GnuPG chose, you may want to try this pipeline:
    $ echo test   gpg -e -r you@example.com   gpg -d -v
    [...]
    gpg: encrypted with 2048-bit RSA key, ID XXXXXXX, created XXXXX
      "You Person You <you@example.com>"
    gpg: AES256 encrypted data
    gpg: original file name=''
    test
As you can see, pass is primarily a command-line application, which may make it less accessible to regular users. The community has produced different graphical interfaces that are either using pass directly or operate on the storage with their own GnuPG integration. I personally use pass in combination with Rofi to get quick access to my passwords, but less savvy users may want to try the QtPass interface, which should be more user-friendly. QtPass doesn't actually depend on pass and can use GnuPG directly to interact with the pass database; it is available for Linux, BSD, OS X, and Windows.

Browser password managers Most users are probably already using a password manager through their web browser's "remember password" functionality. For example, Chromium will ask if you want it to remember passwords and encrypt them with your operating system's facilities. For Windows, this encrypts the passwords with your login password and, for GNOME, it will store the passwords in the gnome-keyring storage. If you synchronize your Chromium settings with your Google account, Chromium will store those passwords on Google's servers, encrypted with a key that is stored in the Google Account itself. So your passwords are then only as safe as your Google account. Note that this was covered here in 2010, although back then Chromium didn't synchronize with the Google cloud or encrypt with the system-level key rings. That facility was only added in 2013. In Firefox, there's an optional, profile-specific master password that unlocks all passwords. In this case, the issue is that browsers are generally always open, so the vault is always unlocked. And this is for users that actually do pick a master password; users are often completely unaware that they should set one. The unlocking mechanism is a typical convenience-security trade-off: either users need to constantly input their master passwords to login or they don't, and the passwords are available in the clear. In this case, Chromium's approach of actually asking users to unlock their vault seems preferable, even though the developers actually refused to implement the feature for years. Overall, I would recommend against using a browser-based password manager. Even if it is not used for critical sites, you will end up with hundreds of such passwords that are vulnerable while the browser is running (in the case of Firefox) or at the whim of Google (in the case of Chromium). Furthermore, the "auto-fill" feature that is often coupled with browser-based password managers is often vulnerable to serious attacks, which is mentioned below. Finally, because browser-based managers generally lack a proper password generator, users may fail to use properly generated passwords, so they can then be easily broken. A password generator has been requested for Firefox, according to this feature request opened in 2007, and there is a password generator in Chrome, but it is disabled by default and hidden in the mysterious chrome://flags URL.

Other notable password managers Another alternative password manager, briefly mentioned in the previous article, is the minimalistic Assword password manager that, despite its questionable name, is also interesting. Its main advantage over pass is that it uses a single encrypted JSON file for storage, and therefore doesn't leak the name of the entries by default. In addition to copy/paste, Assword also supports automatically entering passphrases in fields using the xdo library. Like pass, it uses GnuPG to encrypt passphrases. According to Assword maintainer Daniel Kahn Gillmor in email, the main issue with Assword is "interaction between generated passwords and insane password policies". He gave the example of the Time-Warner Cable registration form that requires, among other things, "letters and numbers, between 8 and 16 characters and not repeat the same characters 3 times in a row". Another well-known password manager is the commercial LastPass service which released a free-software command-line client called lastpass-cli about three years ago. Unfortunately, the server software of the lastpass.com service is still proprietary. And given that LastPass has had at least two serious security breaches since that release, one could legitimately question whether this is a viable solution for storing important secrets. In general, web-based password managers expose a whole new attack surface that is not present in regular password managers. A 2014 study by University of California researchers showed that, out of five password managers studied, every one of them was vulnerable to at least one of the vulnerabilities studied. LastPass was, in particular, vulnerable to a cross-site request forgery (CSRF) attack that allowed an attacker to bypass account authentication and access the encrypted database.

Problems with password managers When you share a password database within a team, how do you remove access to a member of the team? While you can, for example, re-encrypt a pass database with new keys (thereby removing or adding certain accesses) or change the password on a KeePass database, a hostile party could have made a backup of the database before the revocation. Indeed, in the case of pass, older entries are still in the Git history. So access revocation is a problematic issue found with all shared password managers, as it may actually mean going through every password and changing them online. This fundamental problem with shared secrets can be better addressed with a tool like Vault or SFLvault. Those tools aim to provide teams with easy ways to store dynamic tokens like API keys or service passwords and share them not only with other humans, but also make them accessible to machines. The general idea of those projects is to store secrets in a central server and send them directly to relevant services without human intervention. This way, passwords are not actually shared anymore, which is similar in spirit to the approach taken by centralized authentication systems like Kerberos). If you are looking at password management for teams, those projects may be worth a look. Furthermore, some password managers that support auto-typing were found to be vulnerable to HTML injection attacks: if some third-party ad or content is able to successfully hijack the parent DOM content, it masquerades as a form that could fool auto-typing software as demonstrated by this paper that was submitted at USENIX 2014. Fortunately, KeePass was not vulnerable according to the security researchers, but LastPass was, again, vulnerable.

Future of password managers? All of the solutions discussed here assume you have a trusted computer you regularly have access to, which is a usage pattern that seems to be disappearing with a majority of the population. You could consider your phone to be that trusted device, yet a phone can be lost or stolen more easily than a traditional workstation or even a laptop. And while KeePass has Android and iOS ports, those do not resolve the question of how to share the password storage among those devices or how to back them up. Password managers are fundamentally file-based, and the "file" concept seems to be quickly disappearing, faster than we technologists sometimes like to admit. Looking at some relatives' use of computers, I notice it is less about "files" than images, videos, recipes, and various abstract objects that are stored in the "cloud". They do not use local storage so much anymore. In that environment, password managers lose their primary advantage, which is a local, somewhat offline file storage that is not directly accessible to attackers. Therefore certain password managers are specifically designed for the cloud, like LastPass or web browser profile synchronization features, without necessarily addressing the inherent issues with cloud storage and opening up huge privacy and security issues that we absolutely need to address. This is where the "password hasher" design comes in. Also known as "stateless" or "deterministic" password managers, password hashers are emerging as a convenient solution that could possibly replace traditional password managers as users switch from generic computing platforms to cloud-based infrastructure. We will cover password hashers and the major security challenges they pose in a future article.
Note: this article first appeared in the Linux Weekly News.

Daniel Stender: APT programming snippets for Debian system maintenance

The Python API for the Debian package manager APT is useful for writing practical system maintenance scripts, which are going beyond shell scripting capabilities. There are Python2 and Python3 libraries for that available as packages, as well as a documentation in the package python-apt-doc. If that s also installed, the documentation then could be found in /usr/share/doc/python-apt-doc/html/index.html, and there are also a couple of example scripts shipped into /usr/share/doc/python-apt-doc/examples. The libraries mainly consists of Python bindings for the libapt-inst and libapt-pkg C++ core libraries of the APT package manager, which makes it processing very fast. Debugging symbols are also available as packages (python ,3 -apt-dbg). The module apt_inst provides features like reading from binary packages, while apt_pkg resembles the functions of the package manager. There is also the apt abstraction layer which provides more convenient access to the library, like apt.cache.Cache() could be used to behave like apt-get:
from apt.cache import Cache
mycache = Cache()
mycache.update()                   # apt-get update
mycache.open()                     # re-open
mycache.upgrade(dist_upgrade=True) # apt-get dist-upgrade
mycache.commit()                   # apply

boil out selections As widely known, there is a feature of dpkg which helps to move a package inventory from one installation to another by just using a text file with a list of installed packages. A selections list containing all installed package could be easily generated with $ dpkg --get-selections > selections.txt. The resulting file then looks something similar like this:
$ cat selections.txt
0ad                                 install
0ad-data                            install
0ad-data-common                     install
a2ps                                install
abi-compliance-checker              install
abi-dumper                          install
abigail-tools                       install
accountsservice                     install
acl                                 install
acpi                                install
The counterpart for this operation (--set-selections) could be used to reinstall (add) the complete package inventory on another installation resp. computer (that needs superuser rights), like that s explained in the manpage dpkg(1). No problem so far. The problem is, if that list contains a package which couldn t be found in any of the package inventories which are set up in /etc/apt/sources.list(.d/) on the target system, dpkg stops the whole process:
# dpkg --set-selections < selections.txt
dpkg: warning: package not in database at line 524: google-chrome-beta
dpkg: warning: found unknown packages; this might mean the available database
is outdated, and needs to be updated through a frontend method
Thus, manually downloaded and installed wild packages from unofficial package sources are problematic for this approach, because the package installer simply doesn t know where to get them. Luckily, dpkg puts out the relevant package names, but instead of having them removed manually with an editor this little Python script for python3-apt automatically deletes any of these packages from a selections file:
#!/usr/bin/env python3
import sys
import apt_pkg
apt_pkg.init()
cache = apt_pkg.Cache()
infile = open(sys.argv[1])
outfile_name = sys.argv[1] + '.boiled'
outfile = open(outfile_name, "w")
for line in infile:
    package = line.split()[0]
    if package in cache:
        outfile.write(line)
infile.close()
outfile.close()
sys.exit(0)
The script takes one argument which is the name of the selections file which has been generated by dpkg. The low level module apt_pkg first has to been initialized with apt_pkg.init(). Then apt_pkg.Cache() can be used to instantiate a cache object (here: cache). That object is iterable, thus it s easy to not perform something if a package from that list couldn t be found in the database, like not copying the corresponding line into the outfile (.boiled), while the others are copied. The result then looks something like this:
$ diff selections.txt selections.txt.boiled 
3780d3779
< python-timemachine   install
4438d4436
< wlan-supercracker    install
That script might be useful also for moving from one distribution resp. derivative to another (like from Ubuntu to Debian). For productive use, open() should be of course secured against FileNotFound and IOError-s to prevent program crashs on such events.

purge rc-s Like also widely known, deinstalled packages leave stuff like configuration files, maintainer scripts and logs on the computer, to save that if the package gets reinstalled at some point in the future. That happens if dpkg has been used with -r/--remove instead of -P/--purge, which also removes these files which are left otherwise. These packages are then marked as rc in the package archive, like:
$ dpkg -l   grep ^rc
rc  firebird2.5-common          2.5.6.27020.ds4-3   amd64   common files for firebird 2.5 servers and clients
rc  firebird2.5-server-common   2.5.6.27020.ds4-3   amd64   common files for firebird 2.5 servers
rc  firebird3.0-common          3.0.1.32609.ds4-8   all     common files for firebird 3.0 server, client and utilities
rc  imagemagick-common          8:6.9.6.2+dfsg-2    all     image manipulation programs -- infrastructure dummy package
It could be purged over them afterwards to completely remove them from the system. There are several shell coding snippets to be found on the net for completing this job automatically, like this one here:
dpkg -l   grep "^rc"   sed  e "s/^rc //"  e "s/ .*$//"   \
xargs dpkg  purge
The first thing which is needed to handle this by a Python script is the information that in apt_pkg, the package state rc per default is represented by the code 5:
>>> testpackage = cache['firebird2.5-common']
>>> testpackage.current_state
5
For changing things in the database apt_pkg.DepCache() could be docked onto an cache object to manipulate the installation state of a package within, like marking it to be removed resp. purged:
>>> mydepcache = apt_pkg.DepCache(mycache)
>>> mydepcache.mark_delete(testpackage, True) # True = purge
>>> mydepcache.marked_delete(testpackage)
True
That s basically all which is needed for an old package purging maintenance script in Python 3, another iterator as package filter and there you go:
#!/usr/bin/env python3
import sys
import apt_pkg
from apt.progress.text import AcquireProgress
from apt.progress.base import InstallProgress
acquire = AcquireProgress()
install = InstallProgress()
apt_pkg.init()
cache = apt_pkg.Cache()
depcache = apt_pkg.DepCache(cache)
for paket in cache.packages:
    if paket.current_state == 5:
        depcache.mark_delete(paket, True)
depcache.commit(acquire, install)
The method DepCache.commit() applies the changes to the package archive at the end, and it needs apt_progress to perform. Of course this script needs superuser rights to run. It then returns something like this:
$ sudo ./rc-purge 
Reading package lists... Done
Building dependency tree
Reading state information... Done
Fetched 0 B in 0s (0 B/s)
custom fork found
got pid: 17984
got pid: 0
got fd: 4
(Reading database ... 701434 files and directories currently installed.)
Purging configuration files for libmimic0:amd64 (1.0.4-2.3) ...
Purging configuration files for libadns1 (1.5.0~rc1-1) ...
Purging configuration files for libreoffice-sdbc-firebird (1:5.2.2~rc2-2) ...
Purging configuration files for vlc-nox (2.2.4-7) ...
Purging configuration files for librlog5v5 (1.4-4) ...
Purging configuration files for firebird3.0-common (3.0.1.32609.ds4-8) ...
Purging configuration files for imagemagick-common (8:6.9.6.2+dfsg-2) ...
Purging configuration files for firebird2.5-server-common (2.5.6.27020.ds4-3)
It s not yet production ready (like there s an infinite loop if dpkg returns error code 1 like from can t remove non empty folder ). But generally, ATTENTION: be very careful with typos and other mistakes if you want to use that code snippet, a false script performing changes on the package database might destroy the integrity of your system, and you don t want that to happen.

detect wild packages Like said above, installed Debian packages might be called wild if they have been downloaded from somewhere on the net and installed manually, like that is done from time to time on many systems. If you want to remove that whole class of packages again for any reason, the question would be how to detect them. A characteristic element is that there is no source connected to such a package, and that could be detected by Python scripting using again the bindings for the APT libraries. The package object doesn t have an associated method to query its source, because the origin is always connected to a specific package version, like some specific version might have come from security updates for example. The current version of a package can be queried with DepCache.get_candidate_ver() which returns a complex apt_pkg.Version object:
>>> import apt_pkg
>>> apt_pkg.init()
>>> mycache = apt_pkg.Cache()
Reading package lists... Done
Building dependency tree
Reading state information... Done
>>> mydepcache = apt_pkg.DepCache(mycache)
>>> testpackage = mydepcache.get_candidate_ver(mycache['nano'])
>>> testpackage
<apt_pkg.Version object: Pkg:'nano' Ver:'2.7.4-1' Section:'editors'  Arch:'amd64' Size:484790 ISize:2092032 Hash:33578 ID:31706 Priority:2>
For version objects there is the method file_list available, which returns a list containing PackageFile() objects:
>>> testpackage.file_list
[(<apt_pkg.PackageFile object: filename:'/var/lib/apt/lists/httpredir.debian.org_debian_dists_testing_main_binary-amd64_Packages'  a=testing,c=main,v=,o=Debian,l=Debian arch='amd64' site='httpredir.debian.org' IndexType='Debian Package Index' Size=38943764 ID:0>, 669901L)]
These file objects contain the index files which are associated with a specific package source (a downloaded package index), which could be read out easily (using a for-loop because there could be multiple file objects):
>>> for files in testpackage.file_list:
...     print(files[0].filename)
/var/lib/apt/lists/httpredir.debian.org_debian_dists_testing_main_binary-amd64_Packages
That explains itself: the nano binary package on this amd64 computer comes from httpredir.debian.org/debian testing main. If a package is wild that means it was installed manually, so there is no associated index file to be found, but only /var/lib/dpkg/status (libcudnn5 is not in the official package archives but distributed by Nvidia as a .deb package):
>>> testpackage2 = mydepcache.get_candidate_ver(mycache['libcudnn5'])
>>> for files in testpackage2.file_list:
...     print(files[0].filename)
/var/lib/dpkg/status
The simple trick now is to find all packages which have only /var/lib/dpkg/status as associated system file (that doesn t refer to what packages contain), an not an index file representing a package source. There s a little pitfall: that s truth also for virtual packages. But virtual packages commonly don t have an associated version (python-apt docs: to check whether a package is virtual; that is, it has no versions and is provided at least once ), and that can be queried by Package.has_versions. A filter to find out any packages that aren t virtual packages, are solely associated to one system file, and that file is /var/lib/dpkg/status, then goes like this:
for package in cache.packages:
    if package.has_versions:
        version = mydepcache.get_candidate_ver(package)
        if len(version.file_list) == 1:
            if 'dpkg/status' in version.file_list[0][0].filename:
                print(package.name)
On my Debian testing system this puts out a quite interesting list. It lists all the wild packages like libcudnn5, but also packages which are recently not in testing because they have been temporarily removed by AUTORM due to release critical bugs. Then there s all the obsolete stuff which have been installed from the package archives once and then being forgotten like old kernel header packages ( obsolete packages in dselect). So this snippet brings up other stuff, too. Thus, this might be more experimental stuff so far, though.

13 February 2017

Vincent Sanders: The minority yields to the majority!

Deng Xiaoping (who succeeded Mao) expounded this view and obviously did not depend on a minority to succeed. In open source software projects we often find ourselves implementing features of interest to a minority of users to keep our software relevant to a larger audience.

As previously mentioned I contribute to the NetSurf project and the browser natively supports numerous toolkits for numerous platforms. This produces many challenges in development to obtain the benefits of a more diverse user base. As part of the recent NetSurf developer weekend we took the opportunity to review all the frontends to make a decision on their future sustainability.

Each of the nine frontend toolkits were reviewed in turn and the results of that discussion published. This task was greatly eased because we we able to hold the discussion face to face, over time I have come to the conclusion some tasks in open source projects greatly benefit from this form of interaction.

Netsurf running on windows showing this blog post
Coding and day to day discussions around it can be easily accommodated va IRC and email. Decisions affecting a large area of code are much easier with the subtleties of direct interpersonal communication. An example of this is our decision to abandon the cocoa frontend (toolkit used on Mac OS X) against that to keep the windows frontend.

The cocoa frontend was implemented by Sven Weidauer in 2011, unfortunately Sven did not continue contributing to this frontend afterwards and it has become the responsibility of the core team to maintain. Because NetSuf has a comprehensive CI system that compiles the master branch on every commit any changes that negatively affected the cocoa frontend were immediately obvious.

Thus issues with the compilation were fixed promptly but because these fixes were only ever compile tested and at some point the Mac OS X build environments changed resulting in an application that crashes when used. Despite repeatedly asking for assistance to fix the cocoa frontend over the last eighteen months no one had come forward.

And when the topic was discussed amongst the developers it quickly became apparent that no one had any objections to removing the cocoa support. In contrast the windows frontend, which despite having many similar issues to cocoa, we decided to keep. These were almost immediate consensus on the decision, despite each individual prior to the discussion not advocating any position.

This was a single example but it highlights the benefits of a disparate development team having a physical meeting from time to time. However this was not the main point I wanted to discuss, this incident highlights that supporting a feature only useful to a minority of users can have a disproportionate cost.

The cost of a feature for an open source project is usually a collection of several factors:
Developer time
Arguably the greatest resource of a project is the time its developers can devote to it. Unless it is a very large, well supported project like the Kernel or libreoffice almost all developer time is voluntary.
Developer focus
Any given developer is likely to work on an area of code that interests them in preference to one that does not. This means if a developer must do work which does not interest them they may loose focus and not work on the project at all.
Developer skillset
A given developer may not have the skillset necessary to work on a feature, this is especially acute when considering minority platforms which often have very, very few skilled developers available.
Developer access
It should be obvious that software that only requires commodity hardware and software to develop is much cheaper than that which requires special hardware and software. To use our earlier example the cocoa frontend required an apple computer running MAC OS X to compile and test, this resource was very limited and the project only had access to two such systems via remote desktop. These systems also had to serve as CI builders and required physical system administration as they could not be virtualized.
Support
Once a project releases useful software it generally gains users outside of the developers. Supporting users consumes developer time and generally causes them to focus on things other than code that interests them.

While most developers have enough pride in what they produce to fix bugs, users must always remember that the main freedom they get from OSS is they recived the code and can change it themselves, there is no requirement for a developer to do anything for them.
Resources
A project requires a website, code repository, wiki, CI systems etc. which must all be paid for. Netsurf for example is fortunate to have Pepperfish look after our website hosting at favorable rates, Mythic beasts provide exceptionally good rates for the CI system virtual machine along with hardware donations (our apple macs were donated by them) and Collabora for providing physical hosting for our virtual machine server.

Despite these incredibly good deals the project still spends around 200gbp (250usd) a year on overheads, these services obviously benefit the whole project including minority platforms but are generally donated by users of the more popular platforms.
The benefits of a feature are similarly varied:
Developer learning
A developer may implement a feature to allow them to learn a new technology or skill
Project diversity
A feature may mean the project gets built in a new environment which reveals issues or opportunities in unconnected code. For example the Debian OS is built on a variety of hardware platforms and sometimes reveals issues in software by compiling it on big endian systems. These issues are often underlying bugs that are causing errors which are simply not observed on a little endian platform.
More users
Gaining users of the software is often a benefit and although most OSS developers are contributing for personal reasons having their work appreciated by others is often a factor. This might be seen as the other side of the support cost.

In the end the maintainers of a project often have to consider all of these factors and more to arrive at a decision about a feature, especially those only useful to a minority of users. Such decisions are rarely taken lightly as they often remove another developers work and the question is often what would I think about my contributions being discarded?

As a postscript, if anyone is willing to pay the costs to maintain the NetSurf cocoa frontend I have not removed the code just yet.

Dirk Eddelbuettel: RcppTOML 0.1.1

Following up on the somewhat important RcppTOML 0.1.0 releaseas which brought RcppTOML to Windows, we have a first minor update 0.1.1. Two things changed: once again updated upstream code from Chase Geigle's cpptoml which now supports Date types too, and we added the ability to parse TOML from strings as opposed to only from files. TOML is a file format that is most suitable for configurations, as it is meant to be edited by humans but read by computers. It emphasizes strong readability for humans while at the same time supporting strong typing as well as immediate and clear error reports. On small typos you get parse errors, rather than silently corrupted garbage. Much preferable to any and all of XML, JSON or YAML -- though sadly these may be too ubiquitous now.
TOML is making good inroads with newer and more flexible projects such as the Hugo static blog compiler, or the Cargo system of Crates (aka "packages") for the Rust language.

Changes in version 0.1.1 (2017-xx-yy)
  • Synchronized multiple times with ccptoml upstream adding support for local datetime and local date and more (PR #9, #10, PR #11)
  • Dates are now first class types, some support for local versus UTC times was added (though it may be adviseable to stick with UTC)
  • Parsing from (R) character variables is now supported as well
  • Output from print.toml no longer prints extra newlines

Courtesy of CRANberries, there is a diffstat report for this release. More information and examples are on the RcppTOML page. Issues and bugreports should go to the GitHub issue tracker.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

12 February 2017

Shirish Agarwal: Density and accessibility

Around 2 decades back and a bit more I was introduced to computers. The top-line was 386DX which was mainly used as fat servers and some lucky institutions had the 386SX where IF we were lucky we could be able to play some games on it. I was pretty bad at Prince of Persia or most of the games of the era as most of the games depended on lightning reflexes which I didn t possess. Then 1997 happened and I was introduced to GNU/Linux but my love of/for games still continued even though I was bad at most of them. The only saving grace was turn-based RPG s (role-playing games) which didn t have permadeath, so you could plan your next move. Sometimes a wrong decision would lead to getting a place from where it was impossible to move further. As the decision was taken far far break which lead to the tangent, the only recourse was to replay the game which eventually lead to giving most of those kind of games. Then in/around 2000 Maxis came out with Sims. This was the time where I bought my first Pentium. I had never played a game which had you building stuff, designing stuff, no violence and the whole idea used to be about balancing priorities of trying to get new stuff, go to work, maintain relationships and still make sure you are eating, sleeping, have a good time. While I might have spent probably something close to 500 odd hours in the game or even more so, I spent the least amount of time in building the house. It used to be 4 4 when starting (you don t have much of in-game money and other stuff you wanted to buy as well) to 8 8 or at the very grand 12 12. It was only the first time I spent time trying to figure out where the bathroom should be, where the kitchen should, where the bedroom should be and after that I could do that blind-folded. The idea behind my house-design used to be simplicity, efficient (for my character). I used to see other people s grand creations of their houses and couldn t understand why they made such big houses. Now few days back, I saw few episodes of a game called Stranded Deep . The story, plot is simple. You, the player are going in a chartered plane and suddenly lightning strikes ( game trope as today s aircrafts are much better able to deal with lightning strikes) and our hero or heroine washes up on a beach with raft with the barest of possessions. Now the whole game is based upon him/her trying to survive, once you get the hang of the basic mechanics and you know what is to be done, you can do it. The only thing the game doesn t have is farming but as the game has unlimited procedural world, you just paddle or with boat motor go island hopping and take all that what you need. What was interesting to me was seeing a gamer putting so much time and passion in making a house. When I was looking at that video, I realized that maybe because I live in a dense environment, even the designs we make either of houses or anything else is more to try to get more and more people rather than making sure that people are happy which leads to my next sharing. Couple of days back, I read Virali Modi s account of how she was molested three times when trying to use Indian Railways. She made a petition on change.org While I do condemn the molestation as it s an affront against individual rights, freedom, liberty, free movement, dignity. Few of the root causes as pointed out by her, for instance the inability or non-preference to give differently-abled people the right to board first as well as awaiting to see that everybody s boarded properly before starting the train are the most minimum steps that Indian Railways could take without spending even a paise. The same could be told/shared about sensitizing people, although I have an idea of why does Indian Railway not employ women porters or women attendants for precisely this job. I accompanied a blind gentleman friend few times on Indian Railways and let me tell you, it was one of the most unpleasant experiences. The bogies which is given to them is similar or even less than what you see in unreserved compartments. The toilets were/are smelly, the gap between the station and the train was/is considerable for everybody from blind people, differently-abled people, elderly people as well. This is one of the causes of accidents which happen almost every day on Indian Railways. I also learnt that especially for blind people they are looking for a sort of low-frequency whistle/noise which tells them the disabled coupe/bogie/coach will come at a specific spot in the Station. In a platform which could have anything between 1500-2000 people navigating it wouldn t be easy. I don t know about other places but Indian Railway Stations need to learn a lot to make it a space for differently abled to navigate by themselves. Pune Station operates (originating or passing through) around 200 odd trains, with exceptions of all the specials and weekly trains that ply through, adding those would probably another 5-10 trains to the mix. Each train carries anywhere between 750-1000 odd people so roughly anywhere between 15-20 million pass through Pune Railway Station daily. Even if we take conservative estimates of around 5% of the public commuting from Pune, it would mean around 750,000 people travelling daily. Pune Railway Station has 6 stations and if I spread them equally it would come to around 100,000 people on one platform in 24 hours. Divide that equally by 24 hours and it comes to 4,160 people per hour. Now you take those figures and you see the Pune platforms are under severe pressure. I have normalized many figures. For instance, just like airports, even in railways, there are specific timings where more trains come and go. From morning 0500 hrs to late night 2300 hrs. there would be lot many trains, whereas the graveyard shifts would have windows where maintenance of tracks and personnel takes place. I dunno if people can comprehend 4000 odd people on the platform. Add to that you usually arrive at least an hour or two before a train departs even if you are a healthy person as Indian Railways has a habit of changing platforms of trains at the last minute. So if you a differently abled person with some luggage for a long-distance train, the problems just multiply. See drag accidents because of gap between railway bogies and platforms. The width of the entrance to the bogie is probably between 30-40 inches but the design is such that 5-10 inches are taken on each side. I remembered the last year, our current Prime Minister, Mr. Narendra Modi had launched Accessible Campaign with great fanfare and we didn t hear anything much after that. Unfortunately, the site itself has latency and accessibility issues, besides not giving any real advice even if a person wants to know what building norms should one follow if one wants to make an area accessible. This was easily seen by last year s audit in Delhi as well as other places. A couple of web-searches later, I landed up at a Canadian site to have some idea about the width of the wheelchair itself as well as additional room to manoeuvre. Unfortunately, the best or the most modern coaches/bogies that Indian Railways has to offer are the LHB Bogies/Coaches. Now while the Coaches/Bogies by themselves are a big improvement from the ICF Coaches which we still have and use, if you read the advice and directions shared on the Canadian site, the coaches are far from satisfactory for people who are wheel-chair bound. According to Government s own census records, 0.6% of the population have movement issues. Getting all the differently-abled people together, it comes between 2, 2.5% of the population which is quite a bit. If 2-3 people out of every 100 people are differently-abled then we need to figure out something for them.While I don t have any ideas as to how we could improve the surroundings, it is clear that we need the change. While I was thinking,dreaming,understanding some of the nuances inadvertently, my attention/memories shifted to my toilet experiences at both Mumbai and the Doha Airport. As had shared then, had been pleasantly surprised to see that both in Mumbai Airport as well as the Doha Airport, the toilets were pretty wide, a part of me was happy and a part of me was seeing the added space as wastefulness. With the understanding of needs of differently-abled people it started to make whole lot of sense. I don t remember if I had shared then or not. Although am left wondering where they go for loo in the aircraft. The regular toilets are a tight fit for obese people, I am guessing aircrafts have toilets for differently-abled people as well. Looking back at last year s conference, we had 2-3 differently-abled people. I am just guessing that it wouldn t have been a pleasant experience for them. For instance, where we were staying, at UCT it had stairs, no lifts so by default they probably were on ground-floor. Then where we were staying and where most of the talks were about a few hundred metres away and the shortest distance were by stairs, the round-about way was by road but had vehicles around so probably not safe that way as well. I am guessing they had to be dependant on other people to figure out things. There were so many places where there were stairs and no ramps and even if there were ramps they were probably a bit more than the 1:12 which is the advice given. I have heard that this year s venue is also a bit challenging in terms of accessibility for differently-abled people. I am clueless as to did differently-able find debconf16 in terms of accessibility or not ? A related query to that one, if a Debconf s final report mentions issues with accessibility, do the venues make any changes so that at some future date, differently-abled people would have a better time. I know of Indian institutions reluctance to change, to do expenditure, dunno how western countries do it. Any ideas, comments are welcome.
Filed under: Miscellenous Tagged: #386, #accessibility, #air-travel, #Computers, #differently-abled, #Railways, gaming

9 February 2017

Sven Hoexter: Limit host access based on LDAP groupOfUniqueNames with sssd

For CentOS 4 to CentOS 6 we used pam_ldap to restrict host access to machines, based on groupOfUniqueNames listed in an openldap. With RHEL/CentOS 6 RedHat already deprecated pam_ldap and highly recommended to use sssd instead, and with RHEL/CentOS 7 they finally removed pam_ldap from the distribution. Since pam_ldap supported groupOfUniqueNames to restrict logins a bigger collection of groupOfUniqueNames were created to restrict access to all kind of groups/projects and so on. But sssd is in general only able to filter based on an "ldap_access_filter" or use the host attribute via "ldap_user_authorized_host". That does not allow the use of "groupOfUniqueNames". So to allow a smoth migration I had to configure sssd in some way to still support groupOfUniqueNames. The configuration I ended up with looks like this:
[domain/hostacl]
autofs_provider = none 
ldap_schema = rfc2307bis
# to work properly we've to keep the search_base at the highest level
ldap_search_base = ou=foo,ou=people,o=myorg
ldap_default_bind_dn = cn=ro,ou=ldapaccounts,ou=foo,ou=people,o=myorg
ldap_default_authtok = foobar
id_provider = ldap
auth_provider = ldap
chpass_provider = none
ldap_uri = ldaps://ldapserver:636
ldap_id_use_start_tls = false
cache_credentials = false
ldap_tls_cacertdir = /etc/pki/tls/certs
ldap_tls_cacert = /etc/pki/tls/certs/ca-bundle.crt
ldap_tls_reqcert = allow
ldap_group_object_class = groupOfUniqueNames
ldap_group_member = uniqueMember
access_provider = simple
simple_allow_groups = fraappmgmtt
[sssd]
domains = hostacl
services = nss, pam
config_file_version = 2
Important side note: With current sssd versions you're more or less forced to use ldaps with a validating CA chain, though hostnames are not required to match the CN/SAN so far. Relevant are: In practise what we do is match the member of the groupOfUniqueNames to the sssd internal group representation. The best explanation about the several possible object classes in LDAP for group representation I've found so far is unfortunately in a german blog post. Another explanation is in the LDAP wiki. In short: within a groupOfUniqueNames you'll find a full DN, while in a posixGroup you usually find login names. Different kind of object class requires a different handling. Next step would be to move auth and nss functionality to sssd as well.

Vincent Bernat: Integration of a Go service with systemd

Unlike other programming languages, Go s runtime doesn t provide a way to reliably daemonize a service. A system daemon has to supply this functionality. Most distributions ship systemd which would fit the bill. A correct integration with systemd is quite straightforward. There are two interesting aspects: readiness & liveness. As an example, we will daemonize this service whose goal is to answer requests with nifty 404 errors:
package main
import (
    "log"
    "net"
    "net/http"
)
func main()  
    l, err := net.Listen("tcp", ":8081")
    if err != nil  
        log.Panicf("cannot listen: %s", err)
     
    http.Serve(l, nil)
 
You can build it with go build 404.go. Here is the service file, 404.service1:
[Unit]
Description=404 micro-service
[Service]
Type=notify
ExecStart=/usr/bin/404
WatchdogSec=30s
Restart=on-failure
[Install]
WantedBy=multi-user.target

Readiness The classic way for an Unix daemon to signal its readiness is to daemonize. Technically, this is done by calling fork(2) twice (which also serves other intents). This is a very common task and the BSD systems, as well as some other C libraries, supply a daemon(3) function for this purpose. Services are expected to daemonize only when they are ready (after reading configuration files and setting up a listening socket, for example). Then, a system can reliably initialize its services with a simple linear script:
syslogd
unbound
ntpd -s
Each daemon can rely on the previous one being ready to do its work. The sequence of actions is the following:
  1. syslogd reads its configuration, activates /dev/log, daemonizes.
  2. unbound reads its configuration, listens on 127.0.0.1:53, daemonizes.
  3. ntpd reads its configuration, connects to NTP peers, waits for clock to be synchronized2, daemonizes.
With systemd, we would use Type=fork in the service file. However, Go s runtime does not support that. Instead, we use Type=notify. In this case, systemd expects the daemon to signal its readiness with a message to an Unix socket. go-systemd package handles the details for us:
package main
import (
    "log"
    "net"
    "net/http"
    "github.com/coreos/go-systemd/daemon"
)
func main()  
    l, err := net.Listen("tcp", ":8081")
    if err != nil  
        log.Panicf("cannot listen: %s", err)
     
    daemon.SdNotify(false, "READY=1") //  
    http.Serve(l, nil)                //  
 
It s important to place the notification after net.Listen() (in ): if the notification was sent earlier, a client would get connection refused when trying to use the service. When a daemon listens to a socket, connections are queued by the kernel until the daemon is able to accept them (in ). If the service is not run through systemd, the added line is a no-op.

Liveness Another interesting feature of systemd is to watch the service and restart it if it happens to crash (thanks to the Restart=on-failure directive). It s also possible to use a watchdog: the service sends watchdog keep-alives at regular interval. If it fails to do so, systemd will restart it. We could insert the following code just before http.Serve() call:
go func()  
    interval, err := daemon.SdWatchdogEnabled(false)
    if err != nil   interval == 0  
        return
     
    for  
        daemon.SdNotify(false, "WATCHDOG=1")
        time.Sleep(interval / 3)
     
 ()
However, this doesn t add much value: the goroutine is unrelated to the core business of the service. If for some reason, the HTTP part gets stuck, the goroutine will happily continue to send keep-alives to systemd. In our example, we can just do a HTTP query before sending the keep-alive. The internal loop can be replaced with this code:
for  
    _, err := http.Get("http://127.0.0.1:8081") //  
    if err == nil  
        daemon.SdNotify(false, "WATCHDOG=1")
     
    time.Sleep(interval / 3)
 
In , we connect to the service to check if it s still working. If we get some kind of answer, we send a watchdog keep-alive. If the service is unavailable or if http.Get() gets stuck, systemd will trigger a restart. There is no universal recipe. However, checks can be split into two groups:
  • Before sending a keep-alive, you execute an active check on the components of your service. The keep-alive is sent only if all checks are successful. The checks can be internal (like in the above example) or external (for example, check with a query to the database).
  • Each component reports its status, telling if it s alive or not. Before sending a keep-alive, you check the reported status of all components (passive check). If some components are late or reported fatal errors, don t send the keep-alive.
If possible, recovery from errors (for example, with a backoff retry) and self-healing (for example, by reestablishing a network connection) is always better, but the watchdog is a good tool to handle the worst cases and avoid too complex recovery logic. For example, if a component doesn t know how to recover from an exceptional condition3, instead of using panic(), it could signal its situation before dying. Another dedicated component could try to resolve the situation by restarting the faulty component. If it fails to reach an healthy state in time, the watchdog timer will trigger and the whole service will be restarted.

  1. Depending on the distribution, this should be installed in /lib/systemd/system or /usr/lib/systemd/system. Check with the output of the command pkg-config systemd --variable=systemdsystemunitdir.
  2. This highly depends on the NTP daemon used. OpenNTPD doesn t wait unless you use the -s option. ISC NTP doesn t either unless you use the --wait-sync option.
  3. An example of an exceptional condition is to reach the limit on the number of file descriptors. Self-healing from this situation is difficult and it s easy to get stuck in a loop.

Iustin Pop: Solarized colour theme

Solarized A while back I was looking for some information on the web, and happened upon a blog post about the subject. I don't remember what I was looking for, but on the same blog, there was a screen shot of what I then learned was the Solarized theme. This caught my eye that I decided to try it myself ASAP. Up until last year, I've been using for many years the 'black on light yellow' xterm scheme. This is good during the day, but too strong during night, so on some machines I switched to 'white on black', but this was not entirely satisfying. The solarized theme promises to have consistent colours over both light and dark background, which would help to make my setups finally consistent, and extends to a number of programs. Amongst these, there are themes for mutt on both light and dark backgrounds using only 16 colours. This was good, as my current hand-built theme is based on 256 colours, and this doesn't work well in the Linux console. So I tried changing my terminal to the custom colours, played with it for about 10 minutes, then decided that its contrast is too low, bordering on unreadable. I switch to another desktop where I still had open an xterm using white-on-black, and this being at night my eyes immediately go 'no no no too high contrast'. In about ten minutes I got so used to it that the old theme was really really uncomfortable. There was no turning back now Interestingly, the light theme was not that much better than black-on-light-yellow, as that theme is already pretty well behaved. But I still migrated for consistency. Programs/configs Starting from the home page and the internet, I found resources for: 16 vs 256 colours The solarized theme/configuration can be done in two ways: Upstream recommends the custom ones, as they are precisely tuned, instead of using the approximated ones; honestly I don't know if they would make a difference. It's too bad upstream went silent a few years back, as technically it's possible to override also colours above 16 in the 256-colour palette, but in any case, each of the two options has its own cons: So either way it's not perfect. Desktop-wide consistency Also not perfect is that for proper consistent look, many more programs would have to be changed; but I don't see that happening in today's world. I've seen for example 3 or 4 Midnight Commander themes, but none of them were actually in the spirit of solarized, even though they were tweaked for solarized. Even between vim and emacs, which both have one canonical solarized theme, the look is close but not really the same (looking at the markdown source for this blog post: URLs, headers and spelling mistakes are all different), but this might be due not necessarily the theme itself. So no global theme consistency (I'd wish), but still, I find this much better on the eyes and not lower on readability after getting used to it. Thanks Ethan!

8 February 2017

Antoine Beaupr : Reliably generating good passwords

Passwords are used everywhere in our modern life. Between your email account and your bank card, a lot of critical security infrastructure relies on "something you know", a password. Yet there is little standard documentation on how to generate good passwords. There are some interesting possibilities for doing so; this article will look at what makes a good password and some tools that can be used to generate them. There is growing concern that our dependence on passwords poses a fundamental security flaw. For example, passwords rely on humans, who can be coerced to reveal secret information. Furthermore, passwords are "replayable": if your password is revealed or stolen, anyone can impersonate you to get access to your most critical assets. Therefore, major organizations are trying to move away from single password authentication. Google, for example, is enforcing two factor authentication for its employees and is considering abandoning passwords on phones as well, although we have yet to see that controversial change implemented. Yet passwords are still here and are likely to stick around for a long time until we figure out a better alternative. Note that in this article I use the word "password" instead of "PIN" or "passphrase", which all roughly mean the same thing: a small piece of text that users provide to prove their identity.

What makes a good password? A "good password" may mean different things to different people. I will assert that a good password has the following properties:
  • high entropy: hard to guess for machines
  • transferable: easy to communicate for humans or transfer across various protocols for computers
  • memorable: easy to remember for humans
High entropy means that the password should be unpredictable to an attacker, for all practical purposes. It is tempting (and not uncommon) to choose a password based on something else that you know, but unfortunately those choices are likely to be guessable, no matter how "secret" you believe it is. Yes, with enough effort, an attacker can figure out your birthday, the name of your first lover, your mother's maiden name, where you were last summer, or other secrets people think they have. The only solution here is to use a password randomly generated with enough randomness or "entropy" that brute-forcing the password will be practically infeasible. Considering that a modern off-the-shelf graphics card can guess millions of passwords per second using freely available software like hashcat, the typical requirement of "8 characters" is not considered enough anymore. With proper hardware, a powerful rig can crack such passwords offline within about a day. Even though a recent US National Institute of Standards and Technology (NIST) draft still recommends a minimum of eight characters, we now more often hear recommendations of twelve characters or fourteen characters. A password should also be easily "transferable". Some characters, like & or !, have special meaning on the web or the shell and can wreak havoc when transferred. Certain software also has policies of refusing (or requiring!) some special characters exactly for that reason. Weird characters also make it harder for humans to communicate passwords across voice channels or different cultural backgrounds. In a more extreme example, the popular Signal software even resorted to using only digits to transfer key fingerprints. They outlined that numbers are "easy to localize" (as opposed to words, which are language-specific) and "visually distinct". But the critical piece is the "memorable" part: it is trivial to generate a random string of characters, but those passwords are hard for humans to remember. As xkcd noted, "through 20 years of effort, we've successfully trained everyone to use passwords that are hard for human to remember but easy for computers to guess". It explains how a series of words is a better password than a single word with some characters replaced. Obviously, you should not need to remember all passwords. Indeed, you may store some in password managers (which we'll look at in another article) or write them down in your wallet. In those cases, what you need is not a password, but something I would rather call a "token", or, as Debian Developer Daniel Kahn Gillmor (dkg) said in a private email, a "high entropy, compact, and transferable string". Certain APIs are specifically crafted to use tokens. OAuth, for example, generates "access tokens" that are random strings that give access to services. But in our discussion, we'll use the term "token" in a broader sense. Notice how we removed the "memorable" property and added the "compact" one: we want to efficiently convert the most entropy into the shortest password possible, to work around possibly limiting password policies. For example, some bank cards only allow 5-digit security PINs and most web sites have an upper limit in the password length. The "compact" property applies less to "passwords" than tokens, because I assume that you will only use a password in select places: your password manager, SSH and OpenPGP keys, your computer login, and encryption keys. Everything else should be in a password manager. Those tools are generally under your control and should allow large enough passwords that the compact property is not particularly important.

Generating secure passwords We'll look now at how to generate a strong, transferable, and memorable password. These are most likely the passwords you will deal with most of the time, as security tokens used in other settings should actually never show up on screen: they should be copy-pasted or automatically typed in forms. The password generators described here are all operated from the command line. Password managers often have embedded password generators, but usually don't provide an easy way to generate a password for the vault itself. The previously mentioned xkcd cartoon is probably a common cultural reference in the security crowd and I often use it to explain how to choose a good passphrase. It turns out that someone actually implemented xkcd author Randall Munroe's suggestion into a program called xkcdpass:
    $ xkcdpass
    estop mixing edelweiss conduct rejoin flexitime
In verbose mode, it will show the actual entropy of the generated passphrase:
    $ xkcdpass -V
    The supplied word list is located at /usr/lib/python3/dist-packages/xkcdpass/static/default.txt.
    Your word list contains 38271 words, or 2^15.22 words.
    A 6 word password from this list will have roughly 91 (15.22 * 6) bits of entropy,
    assuming truly random word selection.
    estop mixing edelweiss conduct rejoin flexitime
Note that the above password has 91 bits of entropy, which is about what a fifteen-character password would have, if chosen at random from uppercase, lowercase, digits, and ten symbols:
    log2((26 + 26 + 10 + 10)^15) = approx. 92.548875
It's also interesting to note that this is closer to the entropy of a fifteen-letter base64 encoded password: since each character is six bits, you end up with 90 bits of entropy. xkcdpass is scriptable and easy to use. You can also customize the word list, separators, and so on with different command-line options. By default, xkcdpass uses the 2 of 12 word list from 12 dicts, which is not specifically geared toward password generation but has been curated for "common words" and words of different sizes. Another option is the diceware system. Diceware works by having a word list in which you look up words based on dice rolls. For example, rolling the five dice "1 4 2 1 4" would give the word "bilge". By rolling those dice five times, you generate a five word password that is both memorable and random. Since paper and dice do not seem to be popular anymore, someone wrote that as an actual program, aptly called diceware. It works in a similar fashion, except that passwords are not space separated by default:
    $ diceware
    AbateStripDummy16thThanBrock
Diceware can obviously change the output to look similar to xkcdpass, but can also accept actual dice rolls for those who do not trust their computer's entropy source:
    $ diceware -d ' ' -r realdice -w en_orig
    Please roll 5 dice (or a single dice 5 times).
    What number shows dice number 1? 4
    What number shows dice number 2? 2
    What number shows dice number 3? 6
    [...]
    Aspire O's Ester Court Born Pk
The diceware software ships with a few word lists, and the default list has been deliberately created for generating passwords. It is derived from the standard diceware list with additions from the SecureDrop project. Diceware ships with the EFF word list that has words chosen for better recognition, but it is not enabled by default, even though diceware recommends using it when generating passwords with dice. That is because the EFF list was added later on. The project is currently considering making the EFF list be the default. One disadvantage of diceware is that it doesn't actually show how much entropy the generated password has those interested need to compute it for themselves. The actual number depends on the word list: the default word list has 13 bits of entropy per word (since it is exactly 8192 words long), which means the default 6 word passwords have 78 bits of entropy:
    log2(8192) * 6 = 78
Both of these programs are rather new, having, for example, entered Debian only after the last stable release, so they may not be directly available for your distribution. The manual diceware method, of course, only needs a set of dice and a word list, so that is much more portable, and both the diceware and xkcdpass programs can be installed through pip. However, if this is all too complicated, you can take a look at Openwall's passwdqc, which is older and more widely available. It generates more memorable passphrases while at the same time allowing for better control over the level of entropy:
    $ pwqgen
    vest5Lyric8wake
    $ pwqgen random=78
    Theme9accord=milan8ninety9few
For some reason, passwdqc restricts the entropy of passwords between the bounds of 24 and 85 bits. That tool is also much less customizable than the other two: what you see here is pretty much what you get. The 4096-word list is also hardcoded in the C source code; it comes from a Usenet sci.crypt posting from 1997. A key feature of xkcdpass and diceware is that you can craft your own word list, which can make dictionary-based attacks harder. Indeed, with such word-based password generators, the only viable way to crack those passwords is to use dictionary attacks, because the password is so long that character-based exhaustive searches are not workable, since they would take centuries to complete. Changing from the default dictionary therefore brings some advantage against attackers. This may be yet another "security through obscurity" procedure, however: a naive approach may be to use a dictionary localized to your native language (for example, in my case, French), but that would deter only an attacker that doesn't do basic research about you, so that advantage is quickly lost to determined attackers. One should also note that the entropy of the password doesn't depend on which word list is chosen, only its length. Furthermore, a larger dictionary only expands the search space logarithmically; in other words, doubling the word-list length only adds a single bit of entropy. It is actually much better to add a word to your password than words to the word list that generates it.

Generating security tokens As mentioned before, most password managers feature a way to generate strong security tokens, with different policies (symbols or not, length, etc). In general, you should use your password manager's password-generation functionality to generate tokens for sites you visit. But how are those functionalities implemented and what can you do if your password manager (for example, Firefox's master password feature) does not actually generate passwords for you? pass, the standard UNIX password manager, delegates this task to the widely known pwgen program. It turns out that pwgen has a pretty bad track record for security issues, especially in the default "phoneme" mode, which generates non-uniformly distributed passwords. While pass uses the more "secure" -s mode, I figured it was worth removing that option to discourage the use of pwgen in the default mode. I made a trivial patch to pass so that it generates passwords correctly on its own. The gory details are in this email. It turns out that there are lots of ways to skin this particular cat. I was suggesting the following pipeline to generate the password:
    head -c $entropy /dev/random   base64   tr -d '\n='
The above command reads a certain number of bytes from the kernel (head -c $entropy /dev/random) encodes that using the base64 algorithm and strips out the trailing equal sign and newlines (for large passwords). This is what Gillmor described as a "high-entropy compact printable/transferable string". The priority, in this case, is to have a token that is as compact as possible with the given entropy, while at the same time using a character set that should cause as little trouble as possible on sites that restrict the characters you can use. Gillmor is a co-maintainer of the Assword password manager, which chose base64 because it is widely available and understood and only takes up 33% more space than the original 8-bit binary encoding. After a lengthy discussion, the pass maintainer, Jason A. Donenfeld, chose the following pipeline:
    read -r -n $length pass < <(LC_ALL=C tr -dc "$characters" < /dev/urandom)
The above is similar, except it uses tr to directly to read characters from the kernel, and selects a certain set of characters ($characters) that is defined earlier as consisting of [:alnum:] for letters and digits and [:graph:] for symbols, depending on the user's configuration. Then the read command extracts the chosen number of characters from the output and stores the result in the pass variable. A participant on the mailing list, Brian Candler, has argued that this wastes entropy as the use of tr discards bits from /dev/urandom with little gain in entropy when compared to base64. But in the end, the maintainer argued that reading "reading from /dev/urandom has no [effect] on /proc/sys/kernel/random/entropy_avail on Linux" and dismissed the objection. Another password manager, KeePass uses its own routines to generate tokens, but the procedure is the same: read from the kernel's entropy source (and user-generated sources in case of KeePass) and transform that data into a transferable string.

Conclusion While there are many aspects to password management, we have focused on different techniques for users and developers to generate secure but also usable passwords. Generating a strong yet memorable password is not a trivial problem as the security vulnerabilities of the pwgen software showed. Furthermore, left to their own devices, users will generate passwords that can be easily guessed by a skilled attacker, especially if they can profile the user. It is therefore essential we provide easy tools for users to generate strong passwords and encourage them to store secure tokens in password managers.
Note: this article first appeared in the Linux Weekly News.

Alberto Garc a: QEMU and the qcow2 metadata checks

When choosing a disk image format for your virtual machine one of the factors to take into considerations is its I/O performance. In this post I ll talk a bit about the internals of qcow2 and about one of the aspects that can affect its performance under QEMU: its consistency checks. As you probably know, qcow2 is QEMU s native file format. The first thing that I d like to highlight is that this format is perfectly fine in most cases and its I/O performance is comparable to that of a raw file. When it isn t, chances are that this is due to an insufficiently large L2 cache. In one of my previous blog posts I wrote about the qcow2 L2 cache and how to tune it, so if your virtual disk is too slow, you should go there first. I also recommend Max Reitz and Kevin Wolf s qcow2: why (not)? talk from KVM Forum 2015, where they talk about a lot of internal details and show some performance tests. qcow2 clusters: data and metadata A qcow2 file is organized into units of constant size called clusters. The cluster size defaults to 64KB, but a different value can be set when creating a new image: qemu-img create -f qcow2 -o cluster_size=128K hd.qcow2 4G Clusters can contain either data or metadata. A qcow2 file grows dynamically and only allocates space when it is actually needed, so apart from the header there s no fixed location for any of the data and metadata clusters: they can appear mixed anywhere in the file. Here s an example of what it looks like internally:
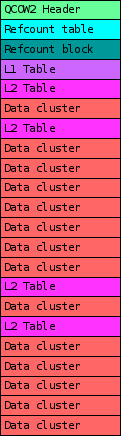
In this example we can see the most important types of clusters that a qcow2 file can have: Metadata overlap checks In order to detect corruption when writing to qcow2 images QEMU (since v1.7) performs several sanity checks. They verify that QEMU does not try to overwrite sections of the file that are already being used for metadata. If this happens, the image is marked as corrupted and further access is prevented. Although in most cases these checks are innocuous, under certain scenarios they can have a negative impact on disk write performance. This depends a lot on the case, and I want to insist that in most scenarios it doesn t have any effect. When it does, the general rule is that you ll have more chances of noticing it if the storage backend is very fast or if the qcow2 image is very large. In these cases, and if I/O performance is critical for you, you might want to consider tweaking the images a bit or disabling some of these checks, so let s take a look at them. There are currently eight different checks. They re named after the metadata sections that they check, and can be divided into the following categories:
  1. Checks that run in constant time. These are equally fast for all kinds of images and I don t think they re worth disabling.
    • main-header
    • active-l1
    • refcount-table
    • snapshot-table
  2. Checks that run in variable time but don t need to read anything from disk.
    • refcount-block
    • active-l2
    • inactive-l1
  3. Checks that need to read data from disk. There is just one check here and it s only needed if there are internal snapshots.
    • inactive-l2
By default all tests are enabled except for the last one (inactive-l2), because it needs to read data from disk. Disabling the overlap checks Tests can be disabled or enabled from the command line using the following syntax: -drive file=hd.qcow2,overlap-check.inactive-l2=on
-drive file=hd.qcow2,overlap-check.snapshot-table=off It s also possible to select the group of checks that you want to enable using the following syntax: -drive file=hd.qcow2,overlap-check.template=none
-drive file=hd.qcow2,overlap-check.template=constant
-drive file=hd.qcow2,overlap-check.template=cached
-drive file=hd.qcow2,overlap-check.template=all Here, none means that no tests are enabled, constant enables all tests from group 1, cached enables all tests from groups 1 and 2, and all enables all of them. As I explained in the previous section, if you re worried about I/O performance then the checks that are probably worth evaluating are refcount-block, active-l2 and inactive-l1. I m not counting inactive-l2 because it s off by default. Let s look at the other three: Conclusion The qcow2 consistency checks are useful to detect data corruption, but they can affect write performance. If you re unsure and you want to check it quickly, open an image with overlap-check.template=none and see for yourself, but remember again that this will only affect write operations. To obtain more reliable results you should also open the image with cache=none in order to perform direct I/O and bypass the page cache. I ve seen performance increases of 50% and more, but whether you ll see them depends a lot on your setup. In many cases you won t notice any difference. I hope this post was useful to learn a bit more about the qcow2 format. There are other things that can help QEMU perform better, and I ll probably come back to them in future posts, so stay tuned! Acknowledgments My work in QEMU is sponsored by Outscale and has been made possible by Igalia and the help of the rest of the QEMU development team.

7 February 2017

Carl Chenet: The Gitlab database incident and the Backup Checker project

The Gitlab.com database incident of 2017/01/31 and the resulting data loss reminded everyone (at least for the next days) how it s easy to lose data, even when you think all your systems are safe. Being really interested by the process of backing up data, I read with interest the report (kudos to the Gitlab company for being so transparent about it) and I was soooo excited to find the following sentence:
Regular backups seem to also only be taken once per 24 hours, though team-member-1 has not yet been able to figure out where they are stored. According to team-member-2 these don t appear to be working, producing files only a few bytes in size.
Whoa, guys! I m so sorry for you about the data loss, but from my point of view I was so excited to find a big FOSS company publicly admitting and communicating about a perfect use case for the Backup Checker project, a Free Software I ve been writing these last years. Data loss: nobody cares before, everybody cries after Usually people don t care about the backups. It s a serious business for web hosters and the backup team from big companies but otherwise and in other places, nobody cares. Usually everybody agrees about how backups are important but few people make them or install an automatized system to create backups and the day before, nobody verifies they are usable. The reason is obvious: it s totally boring, and in some cases e.g for large archives, difficult. Because verifying backups is boring for humans, I launched the Backup Checker project in order to automatize this task. Backup Checker offers a wide range of features, checking lots of different archives (tar. gz,bz2,xz , zip, tree of files and offer lots of different tests (hash sum, size equal, smaller/greater than , unix rights, ,). Have a look at the official documentation for a exhaustive list of features and possible tests. Automatize the controls of your backups with Backup Checker Checking your backups means to describe in a configuration file how a backup should be, e.g a gzipped database dump. You usually know about what size the archive is going to be, what the owner and the group owner should be. Even easier, with Backup Checker you can generate this list of criterias from an actual archive, and remove uneeded criterias to create a template you can re-use for different kind of archives. Ok, 2 minutes of your time for a real word example, I use an existing database sql dump in an tar.gz archive to automatically create the list describing this backup:
$ backupchecker -G database-dump.tar.gz
$ cat database-dump.list
[archive]
mtime  1486480274.2923253
[files]
database.sql  =7854803 uid 1000 gid 1000 owner chaica group chaica mode 644 type f mtime 1486480253.0
Now, just remove parameters too precise from this list to get a backup template. Here is a possible result:
[files]
database.sql  >6m uid 1000 gid 1000 mode 644 type f
We define here a template for the archive, meaning that the database.sql file in the archive should have a size greater than 6 megabytes, be owned by the user with the uid of 1000 and the group with a gid of 1000, this file should have the mode 644 and be a regular file. In order to use a template instead of the complete list, you also need to remove the sha512 from the .conf file. Pretty easy hmm? Ok, just for fun, lets replicate the part of the Gitlab.com database incident mentioned above and write an archive with an empty sql dump inside an archive:
$ touch /tmp/database.sql && \
tar zcvf /tmp/database-dump.tar.gz /tmp/database.sql && \
cp /tmp/database-dump.tar.gz .
Now we launch Backup Checker with the previously created template. If you didn t change the name of database-dump.list file, the command should only be:
$ backupchecker -C database-dump.conf
$ cat a.out 
WARNING:root:1 file smaller than expected while checking /tmp/article-backup-checker/database-dump.tar.gz: 
WARNING:root:database.sql size is 0. Should have been bigger than 6291456.
The automatized controls of Backup Checker trigger a warning in the log file. The empty sql dump has been identified inside the archive. A step further As you could read in this article, verifying some of your backups is not a time consuming task, given the fact you have a FOSS project dedicated to this task, with an easy way to realize a template of your backups and to use it. This article provided a really simple example of such a use case, the Backup Checker has lots of features to offer when verifying your backups. Read the official documentation for more complete descriptions of the available possibilities. Data loss, especially for projets storing user data is always a terrible event in the life of an organization. Lets try to learn from mistakes which could happen to anyone and build better backup systems. More information about the Backup Checker project

6 February 2017

Wouter Verhelst: FOSDEM 2017 is finished...

... but that doesn't mean the work is over. One big job that needs to happen after the conference is to review and release the video recordings that were made. With several hundreds of videos to be checked and only a handful of people with the ability to do so, review was a massive job that for the past three editions took several months; e.g., in 2016 the last video work was done in July, when the preparation of the 2017 edition had already started. Obviously this is suboptimal, and therefore another solution was required. After working on it for quite a while (in my spare time), I came up with SReview, a video review and transcoding system written in Perl. An obvious question that could be asked is why I wrote yet another system, though, and did not use something that already existed. The short answer to that is "because what's there did not exactly do what I wanted to". The somewhat longer answer also involves the fact that I felt like writing something from scratch. The full story, however, is this: there isn't very much out there, and what does exist is flawed in some ways. I am aware of three other review systems that are or were used by other conferences:
  1. A bunch of shell scripts that were written by the DebConf video team and hooked into the penta database. Nobody but DebConf ever used it. It allowed review via an NFS share and a webinterface, and required people to watch .dv files directly from the filesystem in a media player. For this and other reasons, it could only ever be used from the conference itself. If nothing else, that final limitation made it impossible for FOSDEM to use it, but even if that wasn't the case it was still too basic to ever be useful for a conference the size of FOSDEM.
  2. A review system used by the CCC "voc" team. I've never actually seen it in use, but I've heard people describe it. It involves a complicated setup of Samba servers, short MPEG transport stream segments, a FUSE filesystem, and kdenlive, which took someone several days to set up as an experiment back at DebConf15. Critically, important parts of it are also not licensed as free software, which to me rules it out for a tool in support of FOSDEM. Even if that wasn't the case, however, I'm still not sure it would be ideal; this system requires intimate knowledge of how it works from its user, which makes it harder for us to crowdsource the review to the speaker, as I had planned to.
  3. Veyepar. This one gets many things right, and we used it for video review at DebConf from DebConf14 onwards, as well as FOSDEM 2014 (but not 2015 or 2016). Unfortunately, it also gets many things wrong. Most of these can be traced back to the fact that Carl, as he freely admits, is not a programmer; he's more of a sysadmin type who also manages to cobble together a few scripts now and then. Some of the things it gets wrong are minor issues that would theoretically be fixable with a minimal amount of effort; others would be more involved. It is also severely underdocumented, and so as a result it is rather tedious for someone not very familiar with the system to be able to use it. On a more personal note, veyepar is also written in the wrong language, so while I might have spent some time improving it, I ended up starting from scratch.
Something all these systems have in common is that they try to avoid postprocessing as much as possible. This only makes sense; if you have to deal with loads and loads of video recordings, having to do too much postprocessing only ensures that it won't get done... Despite the issues that I have with it, I still think that veyepar is a great system, and am not ashamed to say that SReview borrows many ideas and concepts from it. However, it does things differently in some areas, too:
  1. A major focus has been on making the review form be as easy to use as possible. While there is still room for improvement (and help would certainly be welcome in that area from someone with more experience in UI design than me), I think the SReview review form is much easier to use than the veyepar one (which has so many options that it's pretty hard to understand sometimes).
  2. SReview assumes that as soon as there are recordings in a given room sufficient to fill all the time that a particular event in that room was scheduled for, the whole event is available. It will then generate a first rough cut, and send a notification to the speaker in question, as well as the people who organized the devroom. The reviewer will then almost certainly be required to request a second (and possibly third or fourth) cut, but I think the advantage of that is that it makes the review workflow be more intuitive and easier to understand.
  3. Where veyepar requires one or more instances of per-state scripts to be running (which will then each be polling the database and just start a transcode or cut or whatever script as needed), SReview uses a single "dispatch" script, which needs to be run once for the whole system (if using an external scheduler) or once per core that may be used (if not using an external scheduler), and which does all the database polling required. The use of an external scheduler seemed more appropriate, given that things like gridengine exist; gridengine is a job scheduler which allows one to submit a job to be ran on any node in a cluster, along with the resources that this particular job requires, and which will then either find an appropriate node to run the job on, or will put the job in a "pending" state until the required resources can be found. This allows me to more easily add extra encoding capacity when required, and allows me to also do things like allocate less resources to a particular part of the whole system, even while jobs are already running, without necessarily needing to abort jobs that might be using those resources.
The system seems to be working fine, although there's certainly still room for improvement. I'm thinking of using it for DebConf17 too, and will therefore probably work on improving it during DebCamp. Additionally, the experience of using it for FOSDEM 2017 has given me ideas of where to improve it further, so it can be used more easily by different parties, too. Some of these have been filed as issues against a "1.0" milestone on github, but others are only newly formed in my gray matter and will need some thinking through before they can be properly implemented. Certainly, it looks like this will be something that'll give me quite some fun developing further. In the mean time, if you're interested in the state of a particular video of FOSDEM 2017, have a look at the video overview page, which lists all talks along with their review/transcode status. Also, if you were a speaker or devroom organizer at FOSDEM 2017, please check your mailbox and review your talk! With your help, we should hopefully be able to release all our videos by the end of the week. Update (2017-02-06 17:18): clarified my position on the qualities of some of the other systems after feedback from people who were a bit disappointed by my description of them... and which was fair enough. Apologies. Update (2017-02-08 16:26): Fixes to the c3voc stuff after feedback from them.

Next.

Previous.