Search Results: "ana"

13 February 2023

Jonathan Dowland: A visit to Prusa Labs

.
.

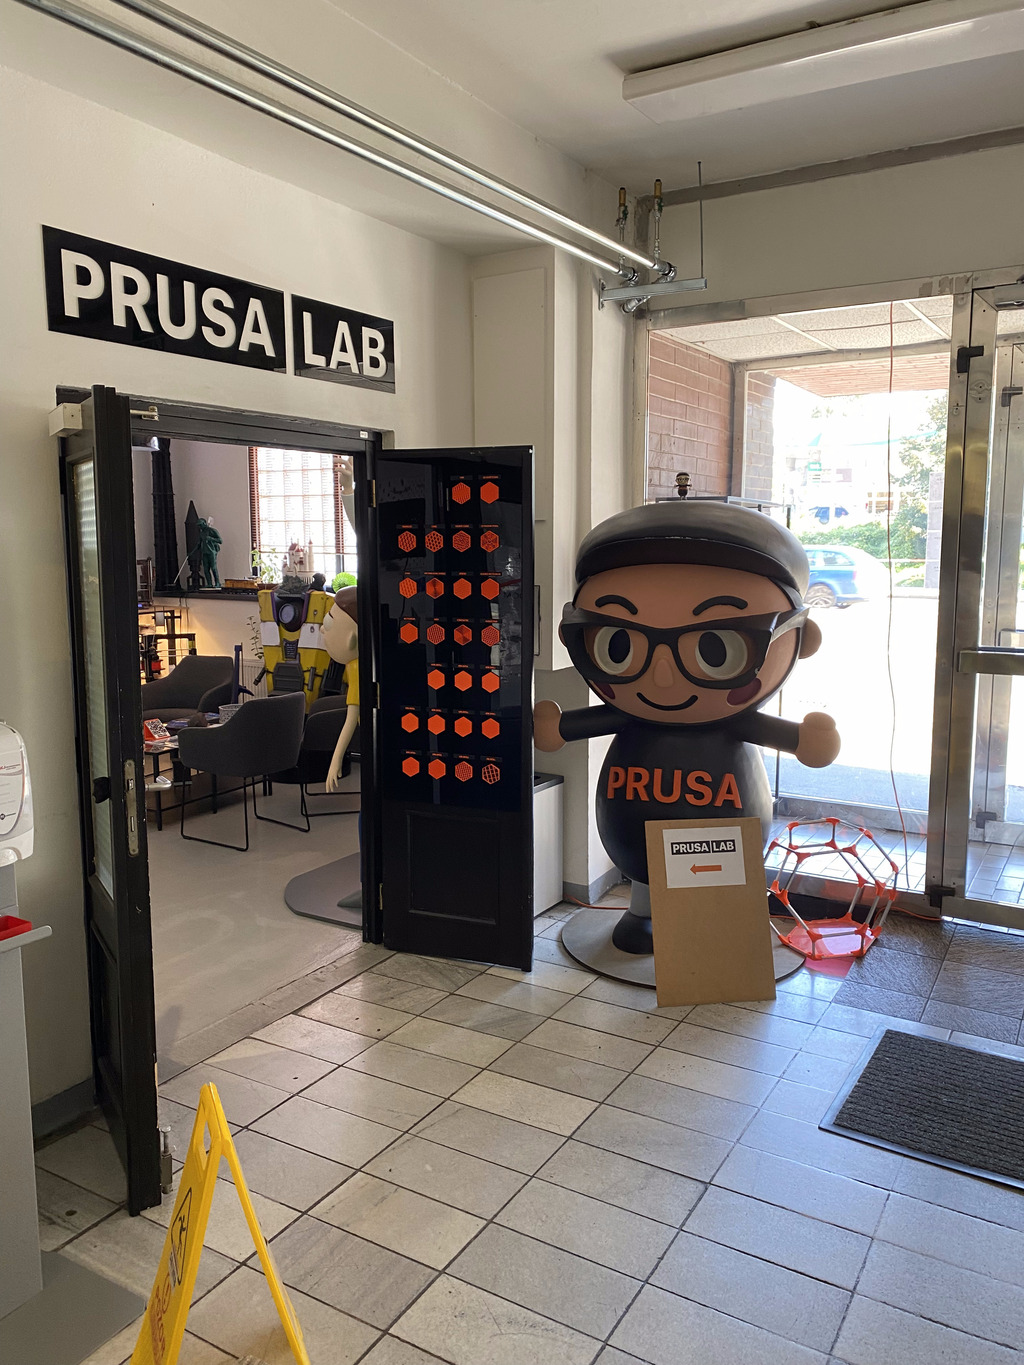
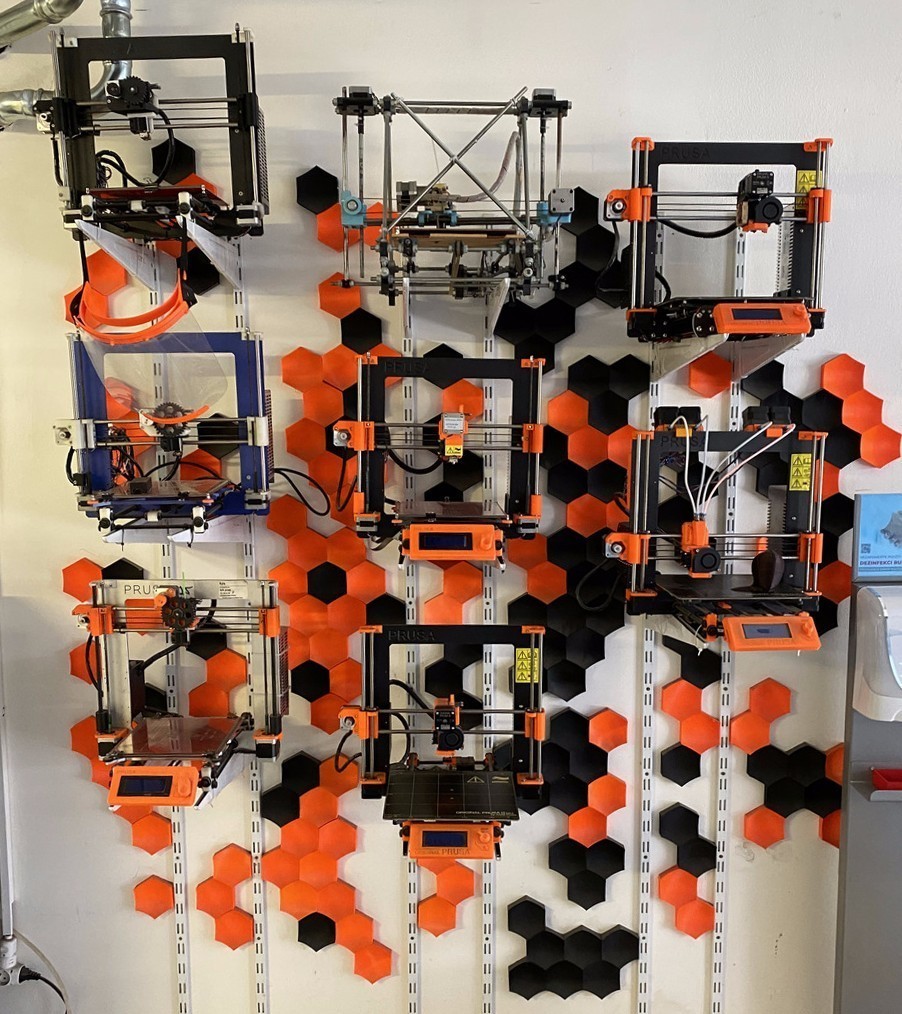
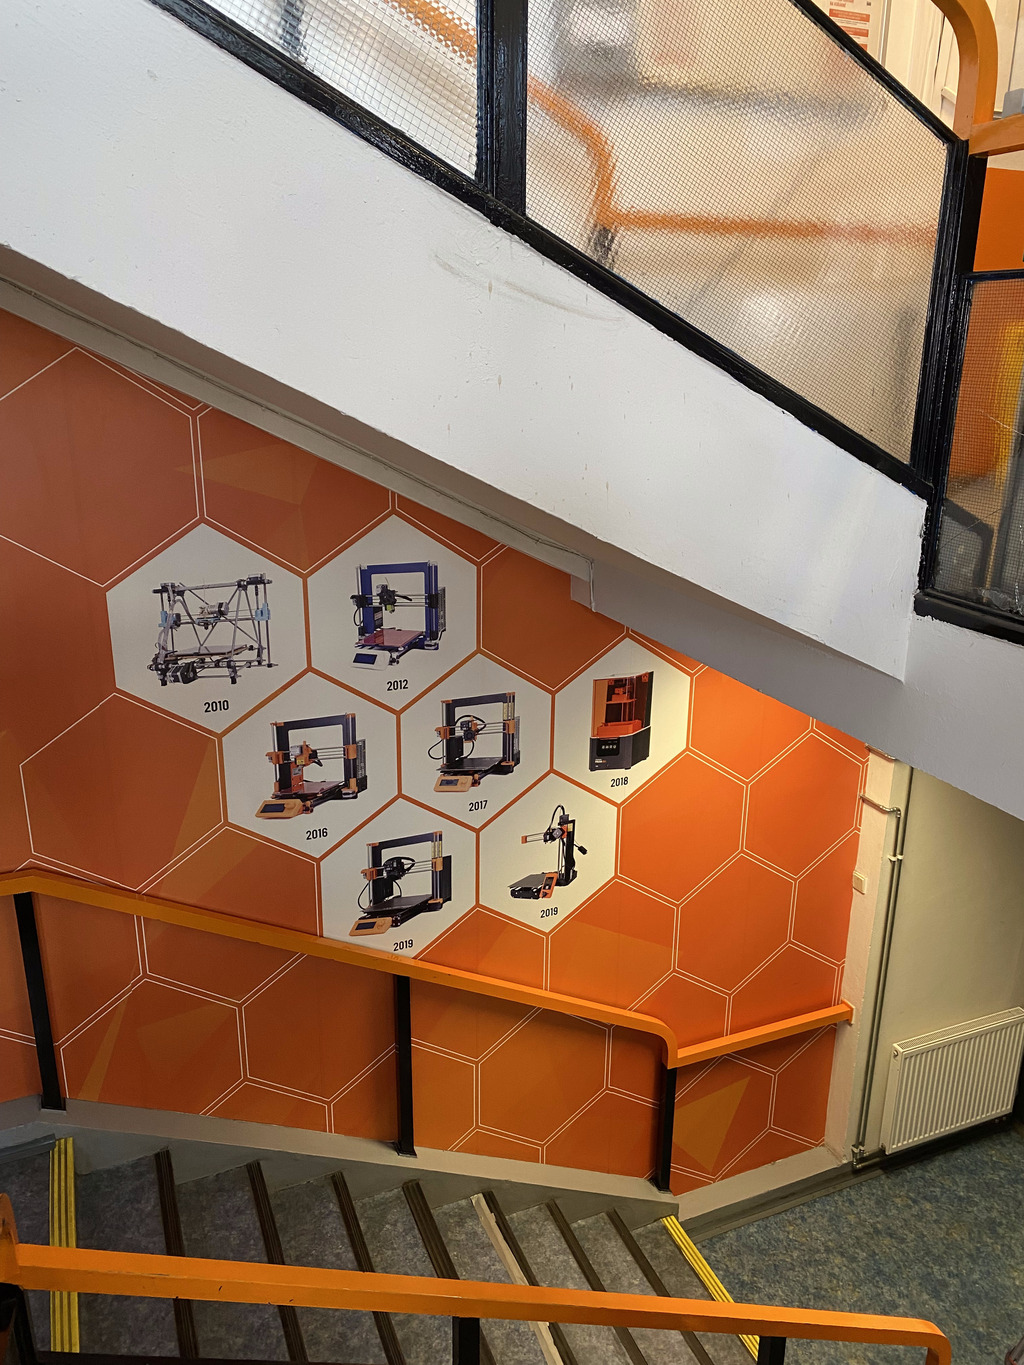
In September I was in Czechia for a Red Hat event. I ended up travelling via Prague, and had an unexpected extra day due to an airline strike causing my flight home to be cancelled. I took the opportunity to visit Prusa's offices/factory/Lab, and it was amazing! The Prusa team were all busy getting ready for the Prague Maker Faire that was happening the day afterwards.1 On arriving at the street which houses Prusa's Lab and Office buildings, the first thing that hit me was the smell. I find the melted-plastic smell of FDM printing (with PLA, at least) quite pleasant, and this was a super-condensed version of that, pumping out of their ground-floor windows. I started at the reception area on the ground floor. Outside reception there's a lovely sculpture representing the history of the development of the MK3S+.
The Reception The Reception
SLS Farm in the former Hack lab SLS Farm in the former Hack lab
History of the MK3S+ History of the MK3S+

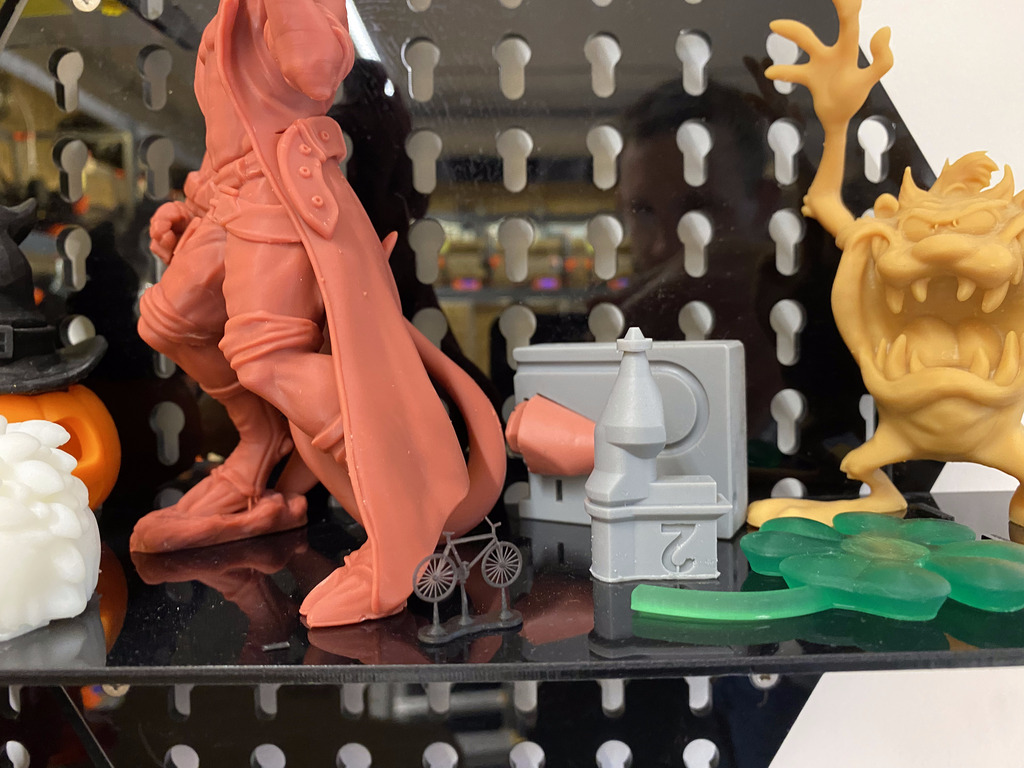
At the reception you have a small waiting area with shelves of demonstration prints and some spools of Prusament. From here, our kind guide first took us to a region on the ground floor that used to be (prior to COVID times) the public maker/hack lab. The lab contained two modest farms of printers: one of their flagship FDM printer, the MK3S+, and another of their SLS resin printers. A close up of some example resin models is pictured above. The bicycle was tiny: about the size of a thumbnail.
A Historic display A Historic display
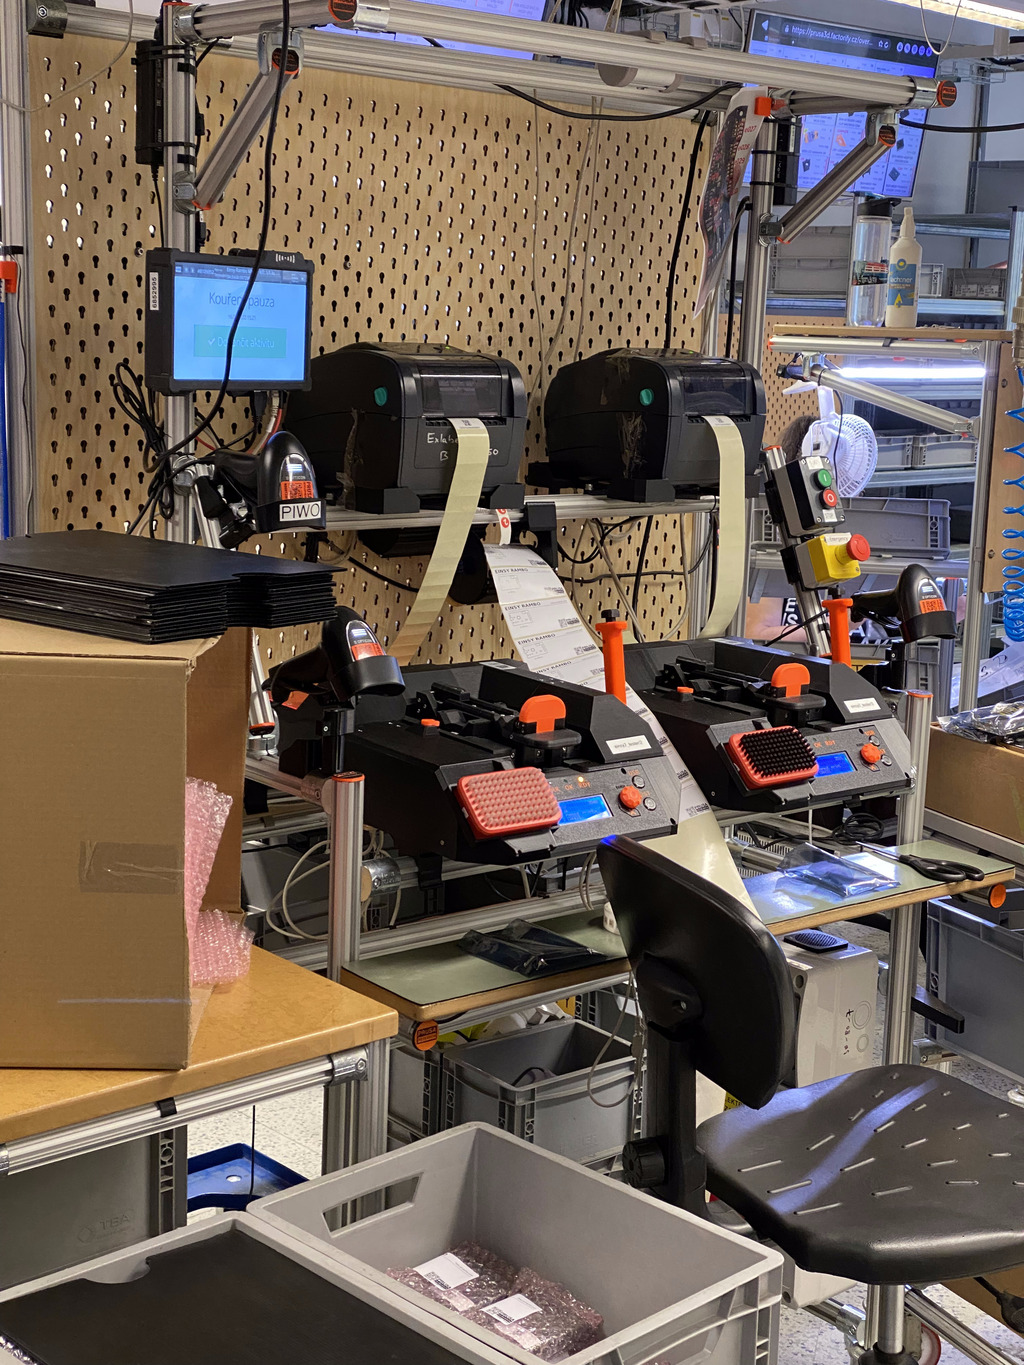
Bespoke QE equipment Bespoke QE equipment
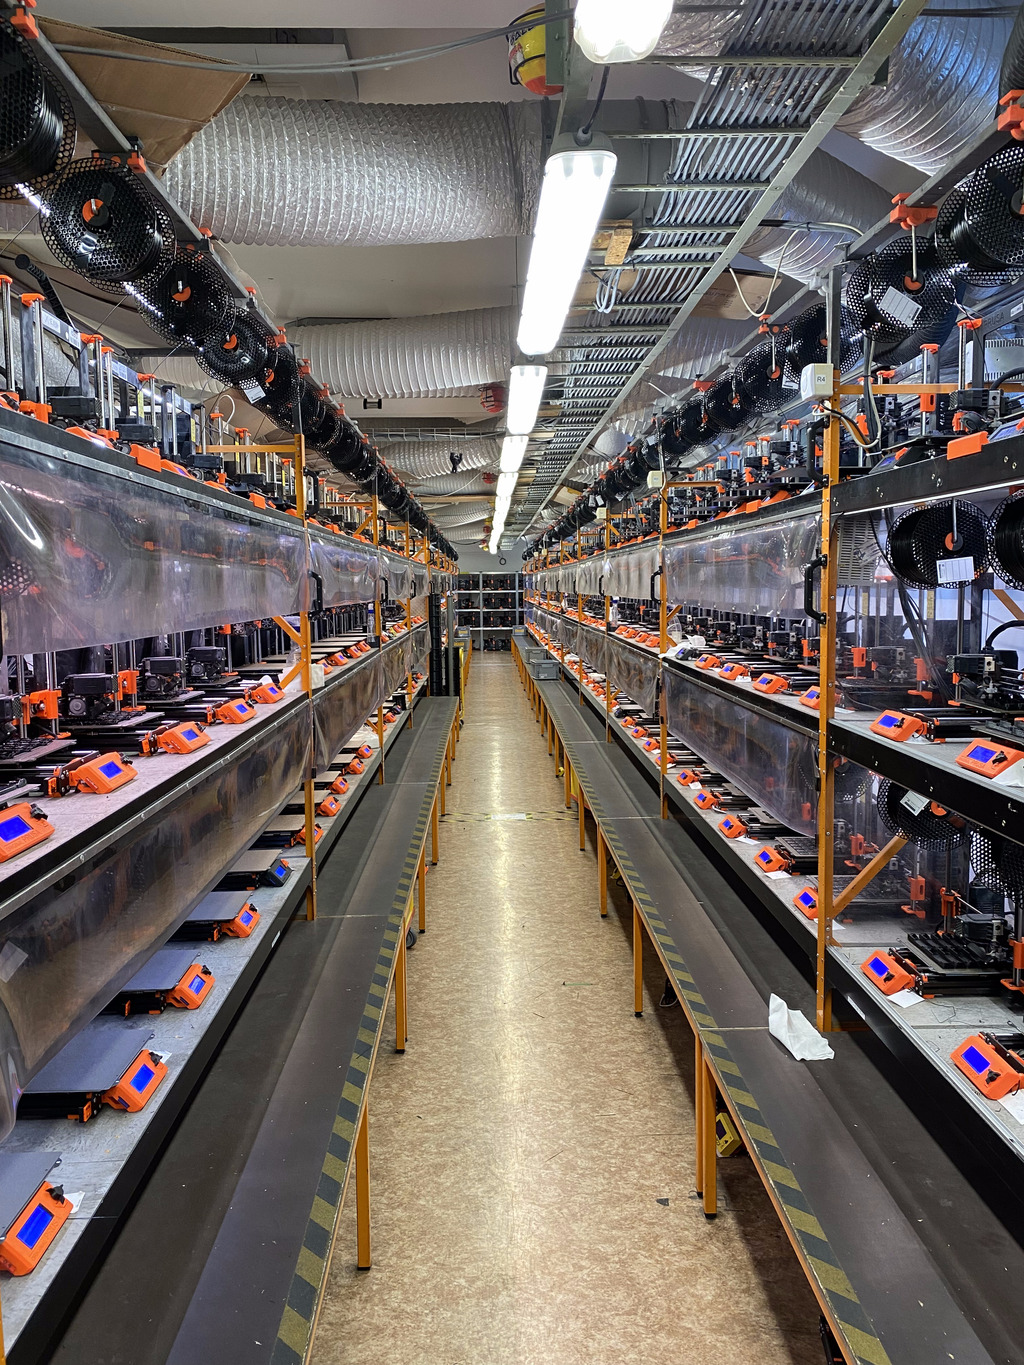
The MK3S+ Farm The MK3S+ Farm

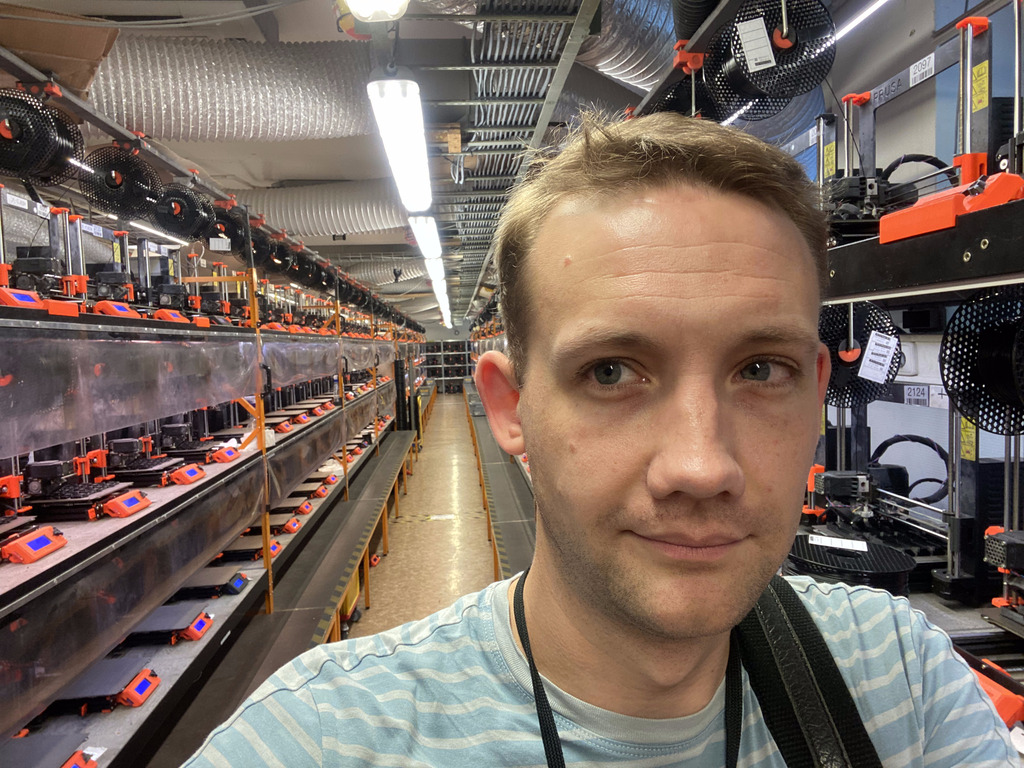
. Moi in the Farm
2KG orange PLA spools for the Farm 2KG orange PLA spools for the Farm
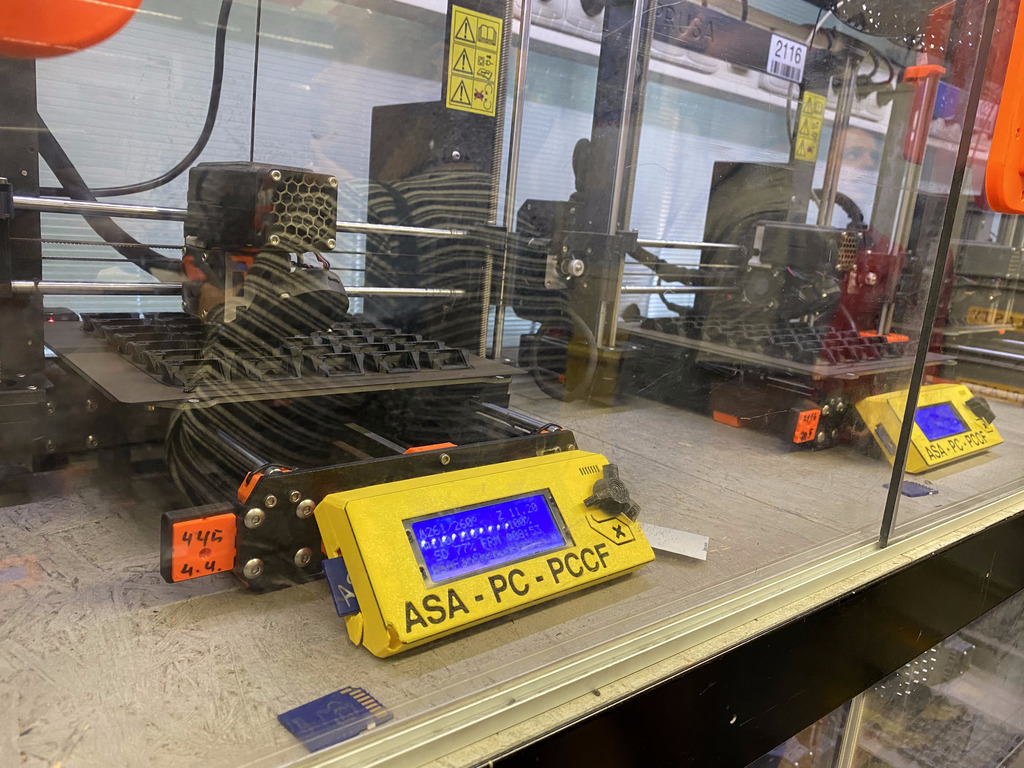
The rest of the ground floor area was full of heavy machinery and prototyping equipment. Onwards we went to the upstairs floors. Upstairs, past a nice graphic of Prusa's historic products, we visited the assembly and QE testing areas. They have a very organised system of parts buckets and some thorough QE processes, including some bespoke equipment that produces the "receipt" of tests and calibration that they provide for you in the box when you buy a 3D printer. After that, we visited the production Farm: a large room full of MK3S+ printers churning out parts for other printers. The noise was remarkable. The printers were running custom firmware to continually print the part they had been set for. Some of the printers were designated for printing with ASA: they were colour-coded (yellow controller surround) and within boxed regions to prevent the fumes causing problems. (picture at the top) Outside the room sat palettes of orange PETG plastic for the printer farm on 2KG spools (not a size they sell to the public just yet) The final part of the trip was outside, to the real farm: Prusa have a smallholding with Alpacas at the rear of their estate. Whilst we visited it, Josef Prusa himself turned up (in a snazzy looking custom colour Tesla) to feed the animals, say hello and pose for a picture. Overall, it was a fantastic visit. I'm very grateful to Air France for cancelling my flight home, and to Prusa Labs (in particular Luk ) for allowing me to come and say hello!

  1. I managed to squeeze that in too on my way to my rescheduled flight, although it was a rush visit and I don't have much to say or show from it. Suffice to say that it was lovely and bittersweet since the UK Maker Faire used to be hosted in my fair home city of Newcastle before they stopped.

Valhalla's Things: Cernit Sets for the Royal Game of UR

Posted on February 13, 2023
Some months ago I stumbled on the video where Irving Finkel teaches Tom Scott how to play the Royal Game of Ur and my takeout was:
  1. Irving Finkel is Gandalf or something;
  2. the game sounded quite fun!;
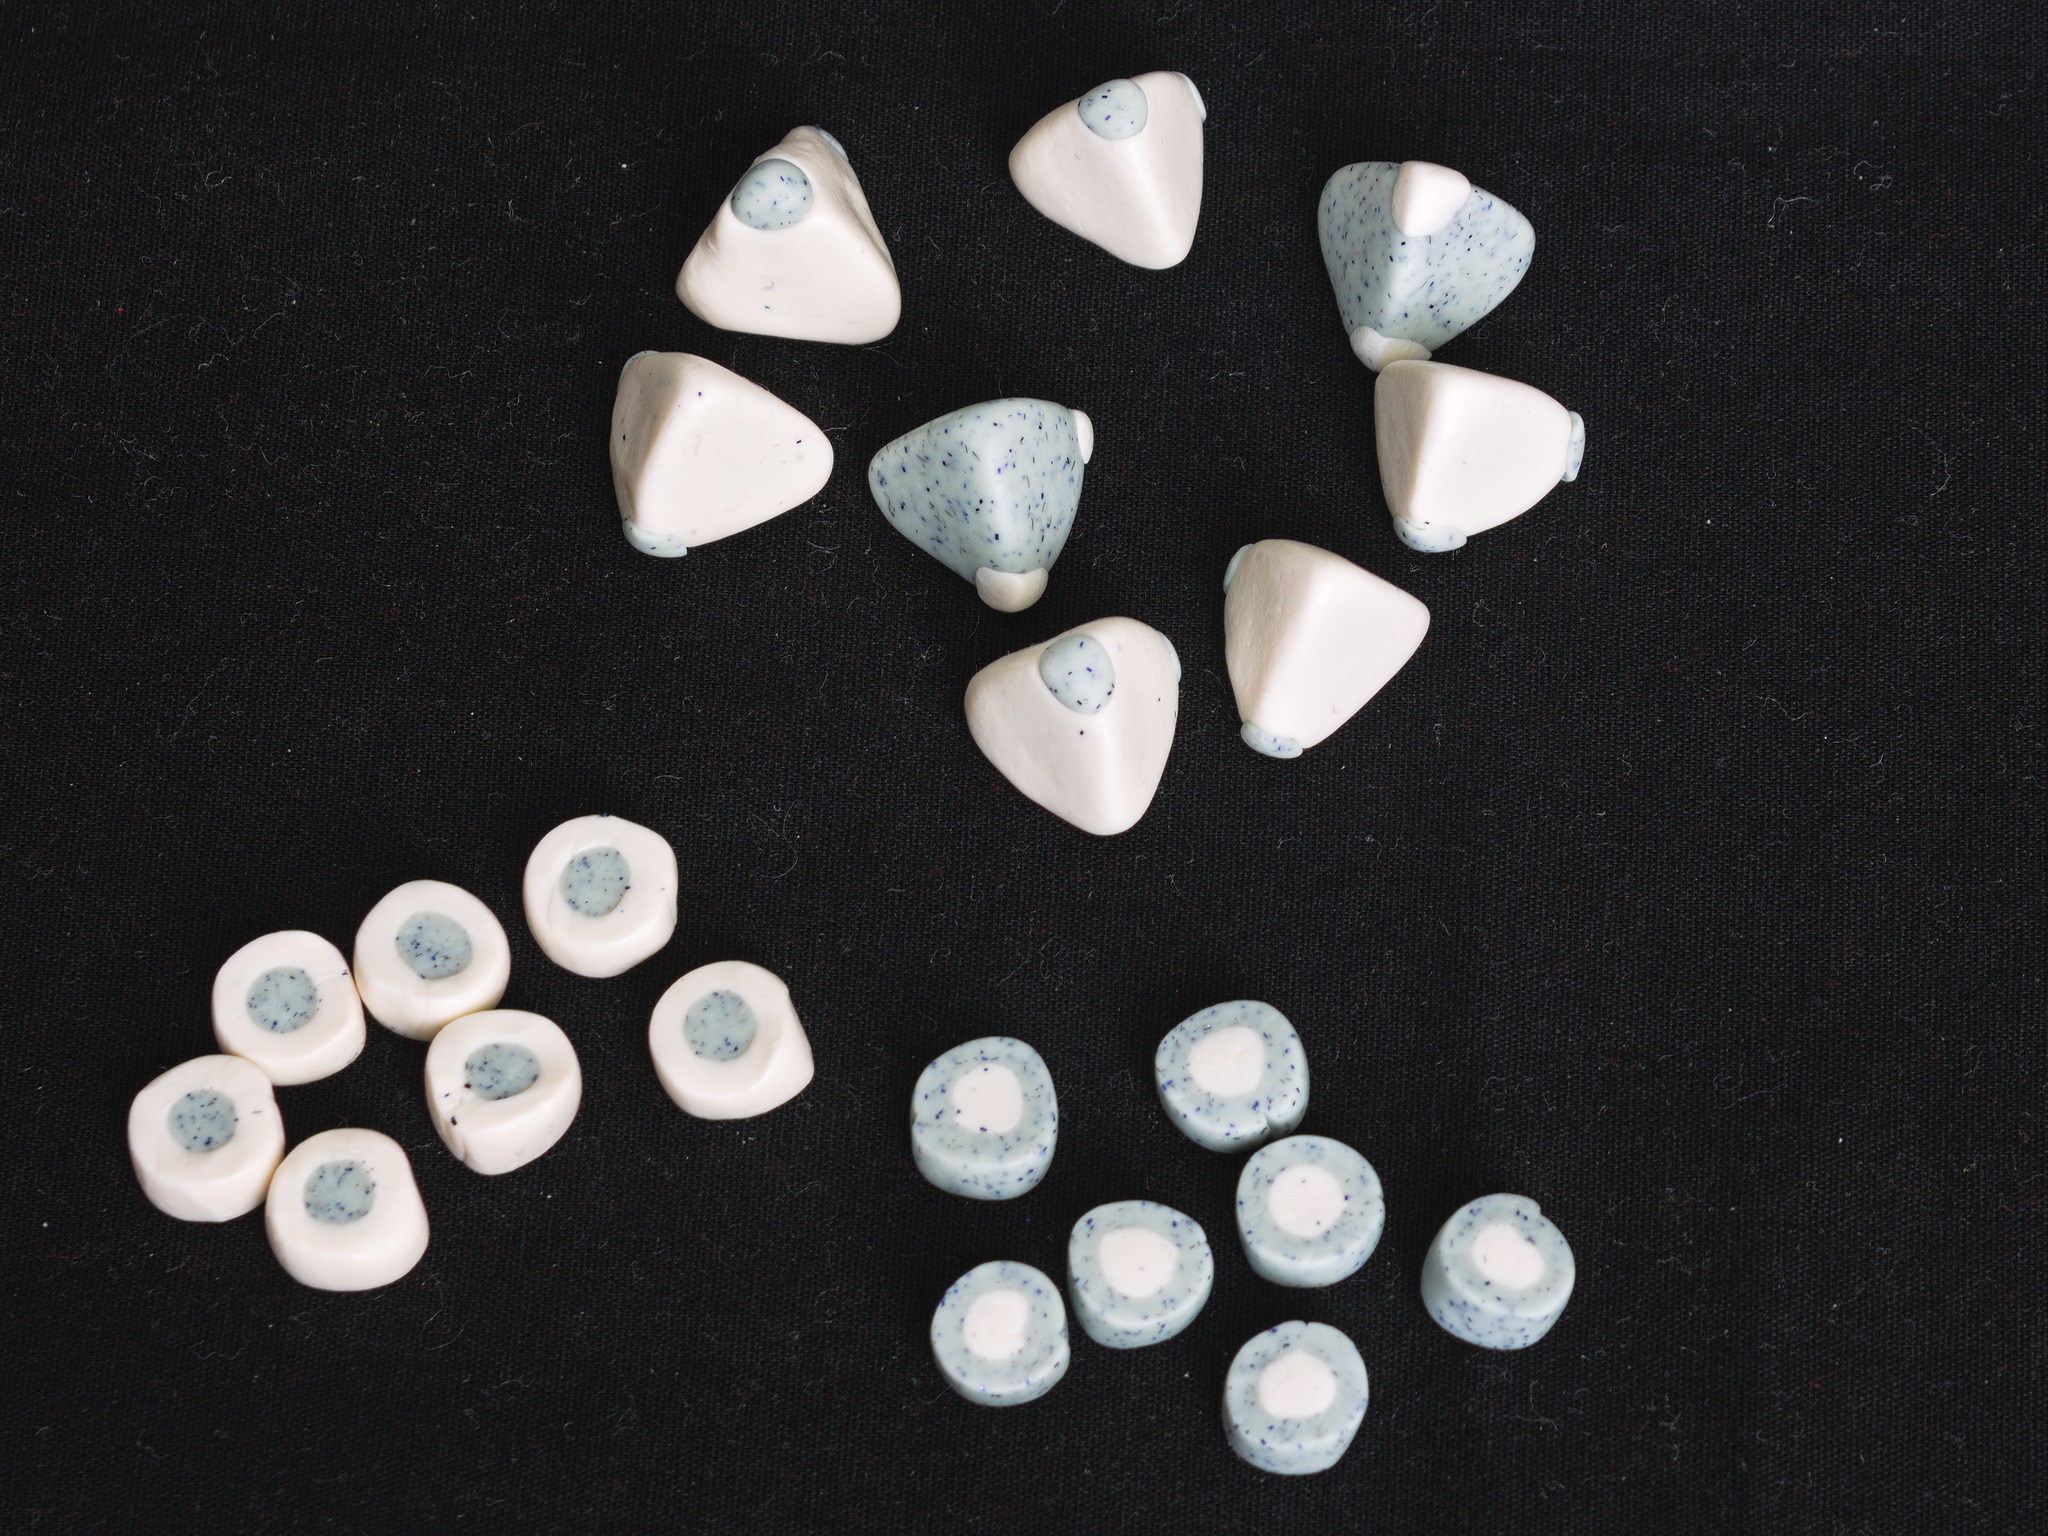
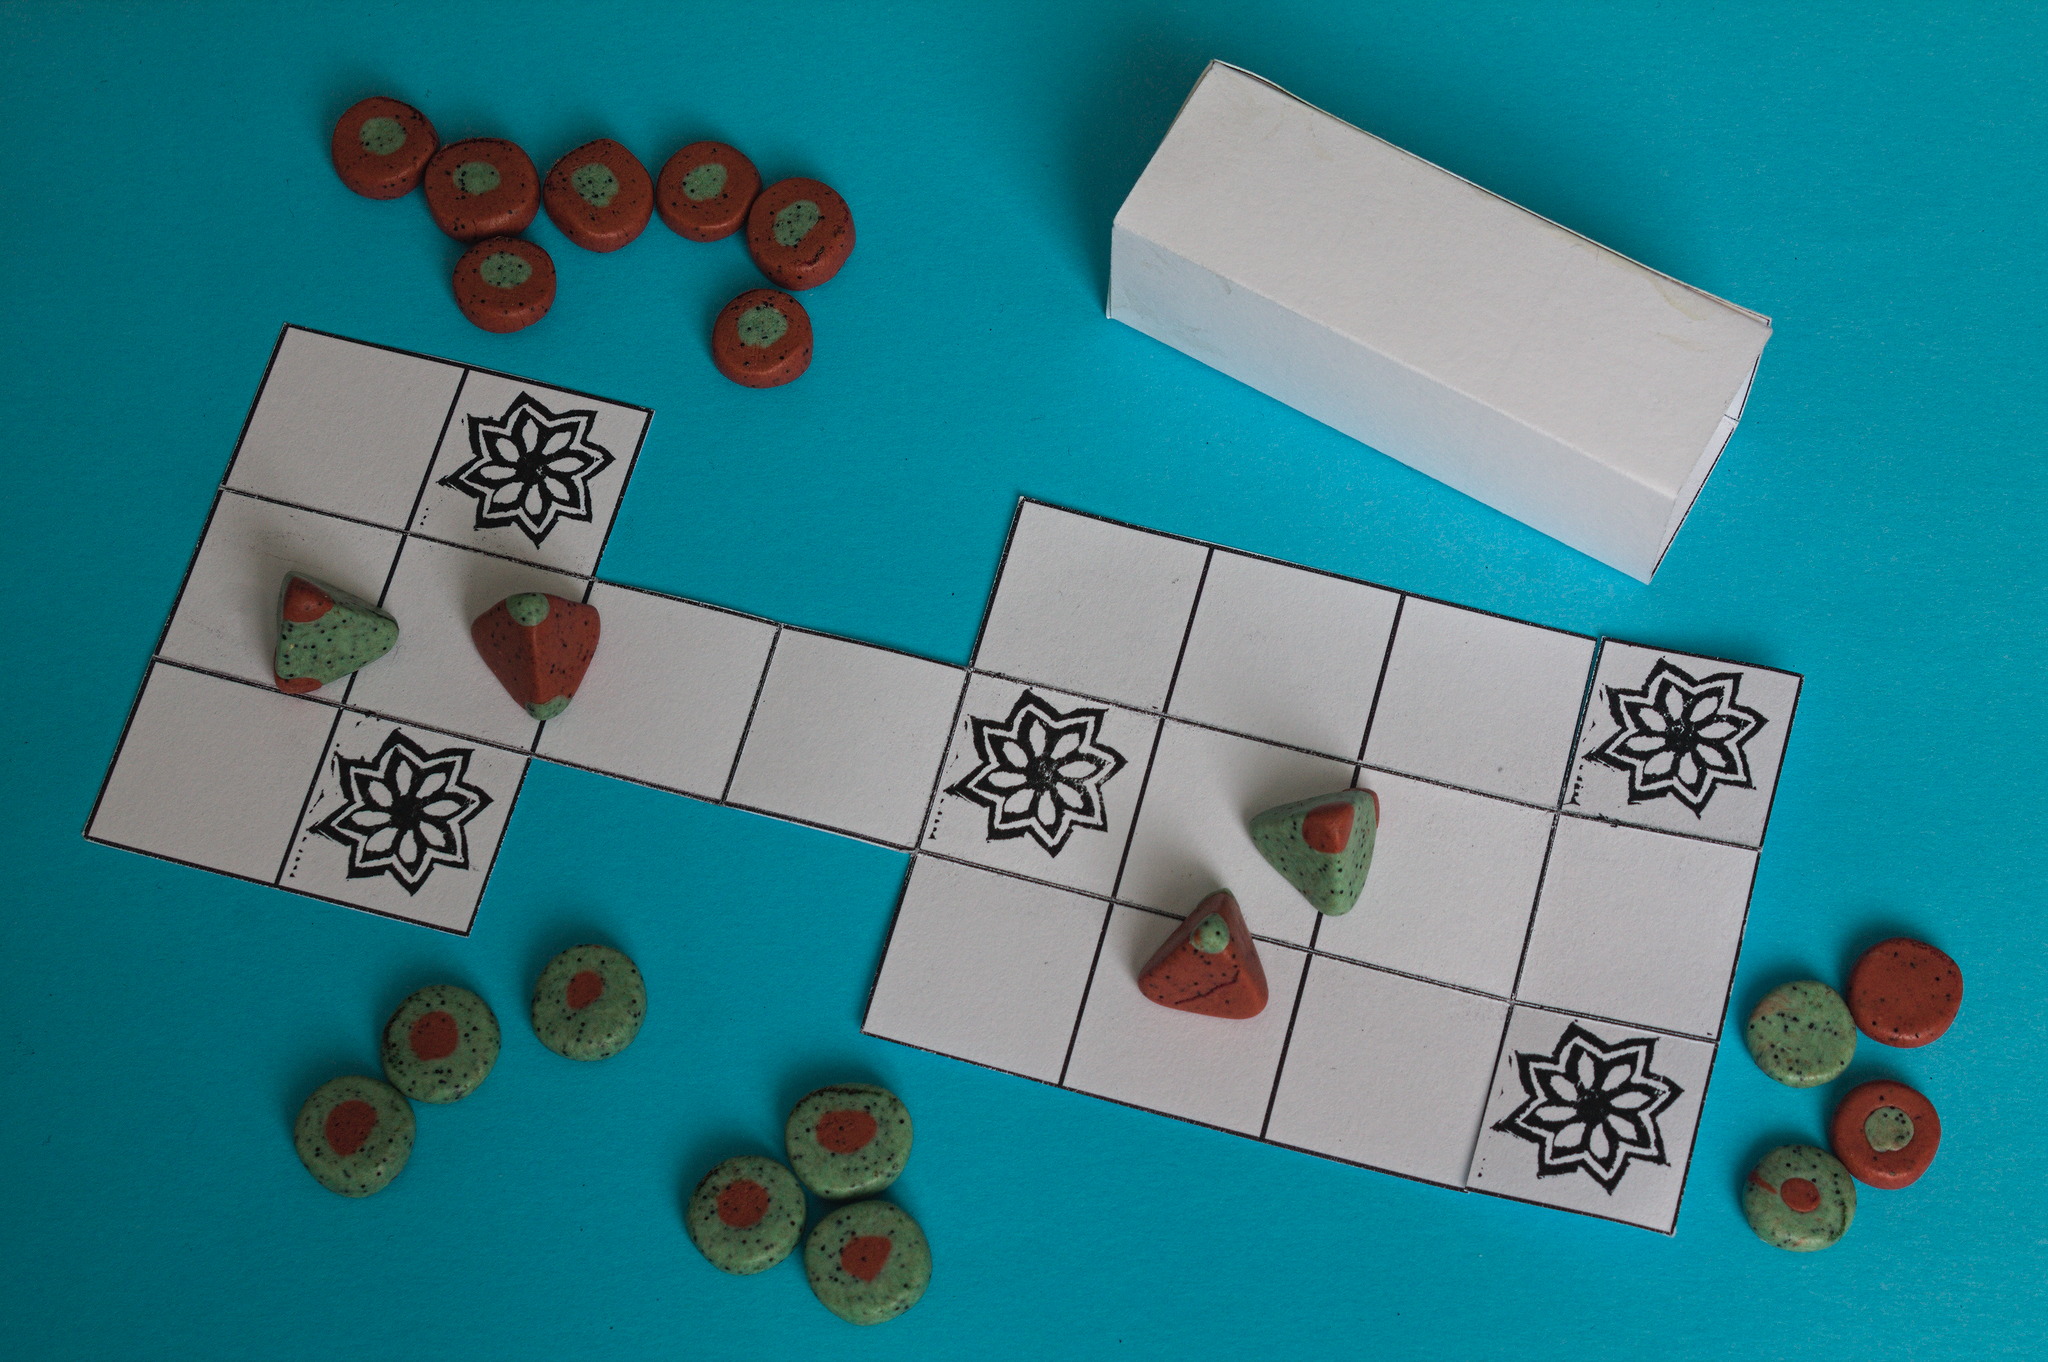
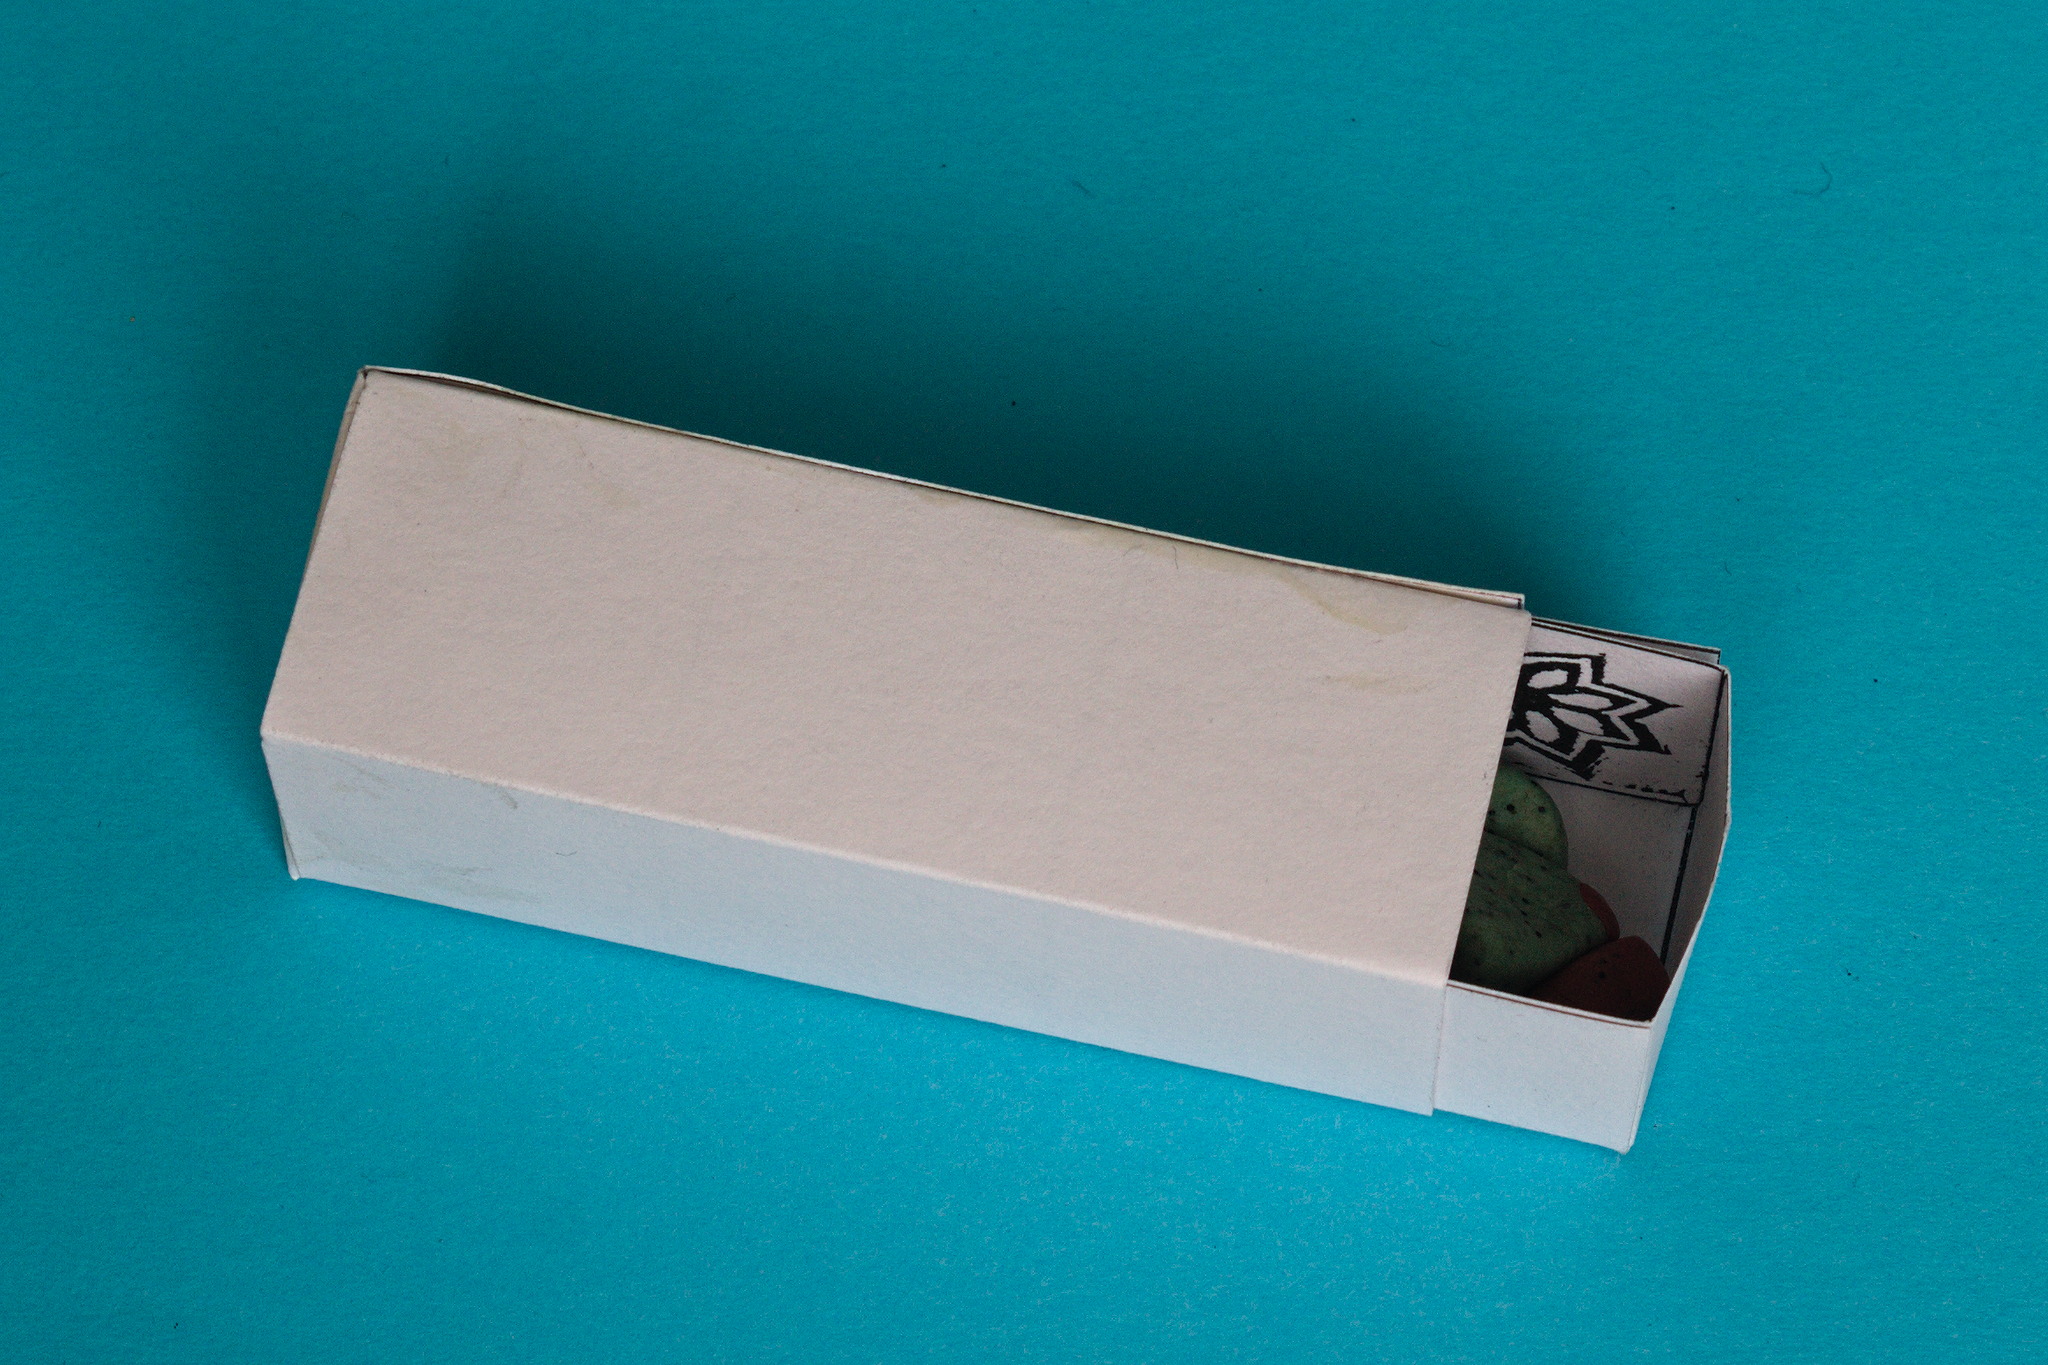
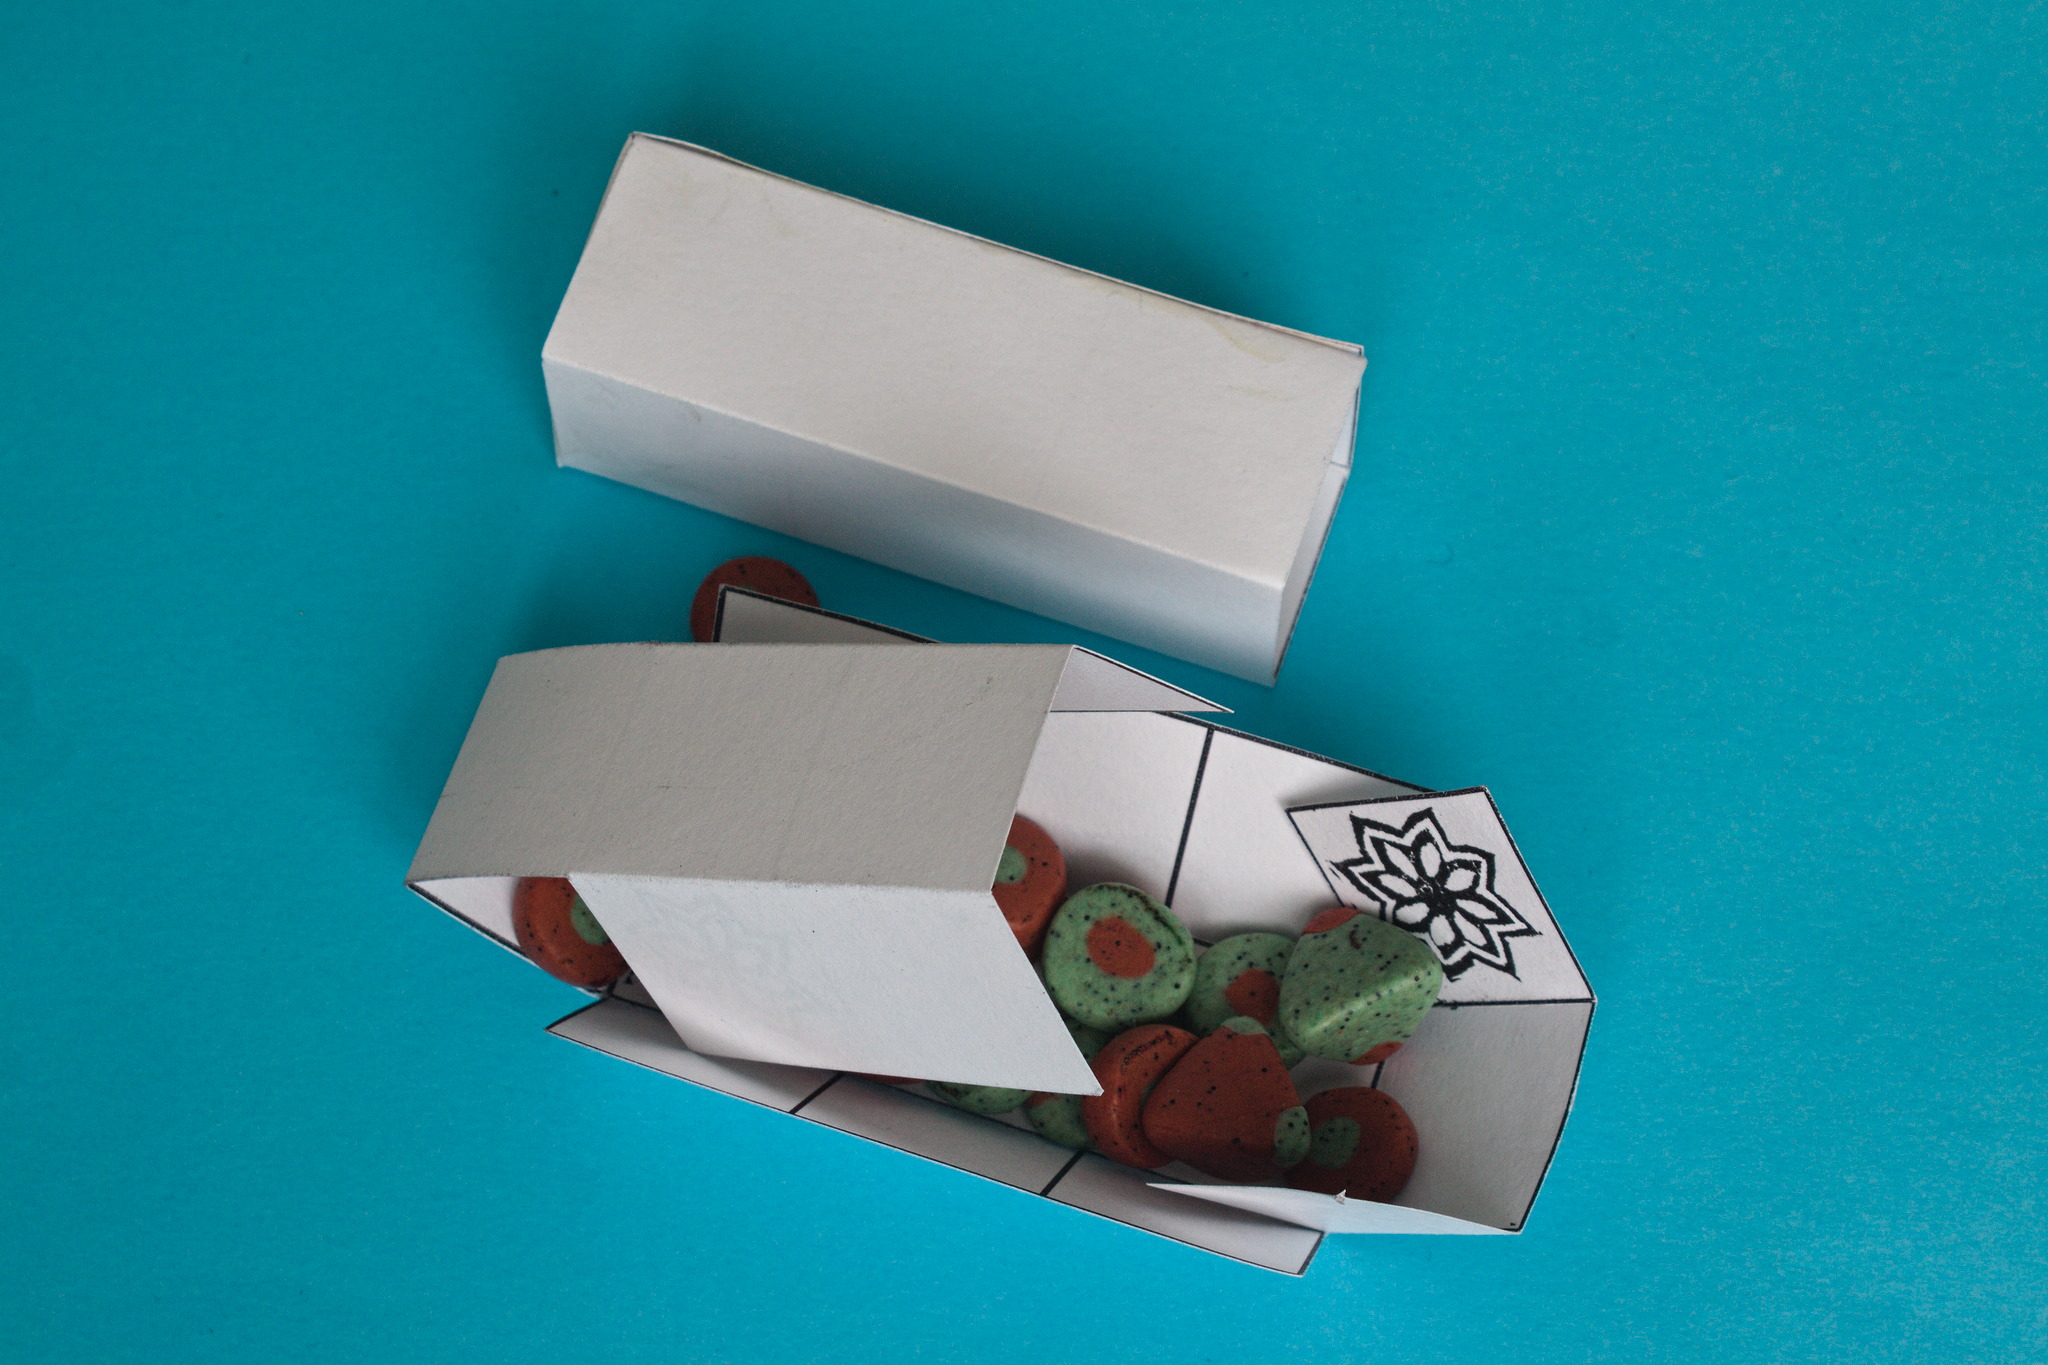
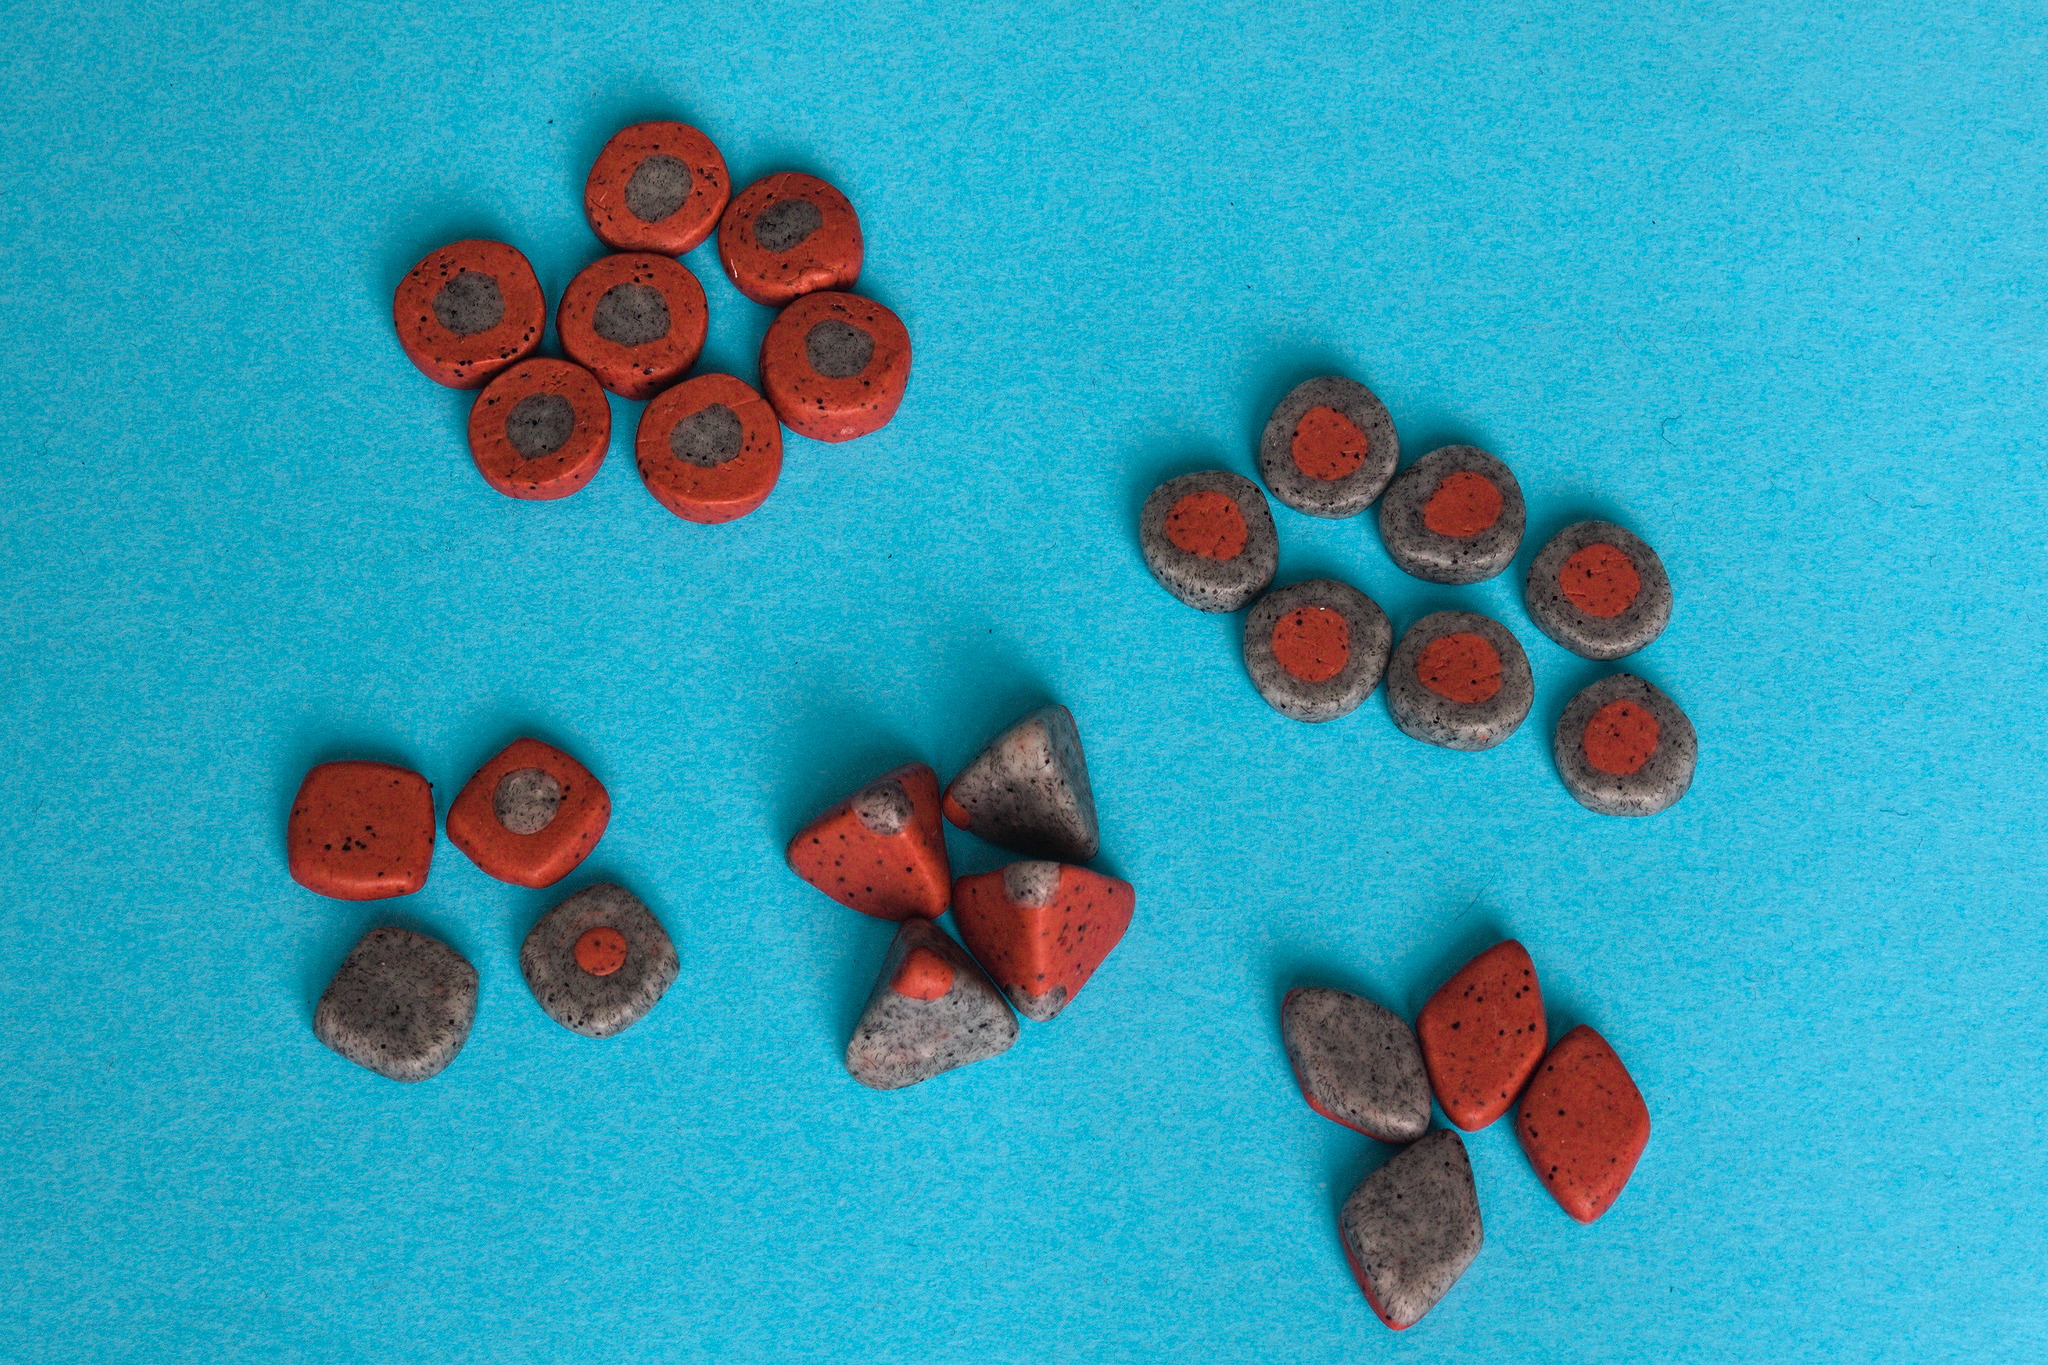
so I did the almost sensible thing, quickly drew a board with inkscape, printed it on 160 g/m paper and used my piecepack pieces to try a few games. two copies of a game board made of plain squares: a 3   4 squares area at the top, a 3   2 area at the bottom, connected by a 1   2 corridor in the middle. I say almost sensible, because rather than drawing the rosettes with inkscape I decided to carve a rubber stamp and use that to print them on the board (which is why the svgs on this page are missing them: if you print them you ll have to add the rosettes in some way). And if I had been a sensible person, that s where I would have stopped, since that s perfectly enough to play games and find out that it actually is quite a fun game, and one of our staples. As some of you probably know, I m not a sensible person. I also have quite a few blocks and half-blocks of cernit, and one day after I ve had used some, my hands were still moving and accidentally made some pyramidal dice, and a handful of tokens. Royal game of Ur pieces in marbled grey and white plastic: the tokens are small coins in one colour with a small circle of the other colour in the middle, the dice are tetrahedrons in one colour with two points marked in the other colour. And after baking and trying them I liked them, but they had not been planned in any way, and they were a bit too small for the board, so the next time I was using cernit I tried to make a new set. And while I was doing that I tried a new shape for the dice, as coins marked with a dot in the middle of one of the sides, because I don t really like tetrahedral dice. A set of red and green tokens, like the ones above, plus tetrahedron dice and four more coins with a dot of a different colour just on one side. Everything is on top of a board that folds up. And now, I realized this wasn t going to be my last set, and urgently felt the need for some container to keep them in and avoid missing pieces. (Yes, in the picture above one piece was already missing. While taking it I didn t realize it, and neither I did when picking up everything to put it away, getting the missing piece and storing it safely together with the rest of the set. It must have been hiding in plain sight nearby, but I will never know where.) Anyway, back to Inkscape, and to a board printed on scrap paper that I tried to fold up until I came up with a layout that folded up in a small drawer, and then I added a case to wrap around it to keep it closed. A white box, about 2.5 cm   2.5 cm   7.5 cm; a drawer is sliding out of one small end. The drawer from the box above, extracted to show it's made of a folded game of Ur board and contains a set with tokens and dice. I played around with the case until it was big enough to actually slide around the folded board, and this is the result, ready to be printed out on A4 paper, cut, folded and glued. (This takes most of the sheet, and I m not sure that the case would still fit around the board/drawer if printed with scaling, so if you want to print it on Letter paper I d recommend to move the pieces around.) two copies of the game board above, plus two cut / fold / glue boxes Now, the only problem left was that green isn t really my colour, and while I did like the stone effect of this set, I wasn t exactly pleased by the colour scheme. (why did I do it this way in the first place? probably because I was trying to use up old cernit blocks before opening new ones.) So, the only possible way out was to make yet another set, right? A set of red and grey tokens, tetrahedron dice, coins with one side marked with a dot that are square-ish rather than circular and four lozenge-shaped coins with each side of a different colour. I still used stone effect cernit, but this time in a red/grey scheme that knew I would have liked more, and while I was doing it I tried a few improvements on the randomization devices. The tetrahedral dice are still the same: they work, it s what they use in the replica sets, so I keep making them even if they re not my first choice. I ve changed the coins to make them almost square for two reasons, however: one is that the round one tended to roll away into inconvenient places when throwing them with emphasis, and the other one is to make it easier to recognise them from the tokens with no need to flip each one around before starting the game. The lozenges were a bit of a failure, instead. They work fine when thrown, but I don t think that there is a self-evident way to decide which side should be counted, and the only intuitive way I can think of (count the ones in the player s colour) would be unbalanced. Speaking of balance issues: of course the hand-modelled dice and coins aren t perfectly balanced but:
  • they don t feel obviously unbalanced;
  • both players use the same set, so any subtle unbalance isn t going to affect the chance of winning in an uneven way.
Maybe one day I will find a way to easily roll them a statistically significant number of times, collect data and analyze it to find out how imbalanced they are, but that s not going to happen with manual data collecting, and I m not really ready to go down the yak shaving filled road to automatize it. To wrap up: is it going to be the last set I make for the Royal Game of Ur? lol. Is it going to be the last cernit set I make this month? definitely yes, I now have one I m happy with, I m routinely playing with it and I m currently doing other crafts rather than cernit.

12 February 2023

Russell Coker: T320 iDRAC Failure and new HP Z640

The Dell T320 Almost 2 years ago I made a Dell PowerEdge T320 my home server [1]. It was a decent upgrade from the PowerEdge T110 II that I had used previously. One benefit of that system was that I needed more RAM and the PowerEdge T1xx series use unbuffered ECC RAM which is unreasonably expensive as well as the DIMMs tending to be smaller (no Load Reduced DIMMS) and only having 4 slots. As I had bought two T320s I put all the RAM in a single server getting a total of 96G and then put some cheap DIMMs in the other one and sold it with 48G. The T320 has all the server reliability features including hot-swap redundant PSUs and hot-swap hard drives. One thing it doesn t have redundancy on is the motherboard management system known as iDRAC. 3 days ago my suburb had a power outage and when power came back on the T320 gave an error message about a failure to initialise the iDRAC and put all the fans on maximum speed, which is extremely loud. When a T320 is running in a room that s not particularly hot and it doesn t have SAS disks it s a very quiet server, one of the quietest I ve ever owned. When it goes into emergency cooling mode due to iDRAC failure it s loud enough to be heard from the other end of the house with doors closed in between. Googling this failure gave a few possible answers. One was for some combinations of booting with the iDRAC button held down, turning off for a while and booting with the iDRAC button held down, etc (this didn t work). One was for putting a iDRAC firmware file on the SD card so iDRAC could automatically load it (which I tested even though I didn t have the flashing LED which indicates that it is likely to work, but it didn t do anything). The last was to enable serial console and configure the iDRAC to load new firmware via TFTP, I didn t get a iDRAC message from the serial console just the regular BIOS stuff. So it looks like I ll have to sell the T320 for parts or find someone who wants to run it in it s current form. Currently to boot it I have to press F1 a few times to bypass BIOS messages (someone on the Internet reported making a device to key-jam F1). Then when it boots it s unreasonably loud, but apparently if you are really keen you can buy fans that have temperature sensors to control their own speed and bypass the motherboard control. I d appreciate any advice on how to get this going. At this stage I m not going to go back to it but if I can get it working properly I can sell it for a decent price. The HP Z640 I ve replaced the T320 with a HP Z640 workstation with 32G of RAM which I had recently bought to play with Stable Diffusion. There were hundreds of Z640 workstations with NVidia Quadro M6000 GPUs going on eBay for under $400 each, it looked like a company that did a lot of ML work had either gone bankrupt or upgraded all their employees systems. The price for the systems was surprisingly cheap, at regular eBay prices it seems that the GPU and the RAM go for about the same price as the system. It turned out that Stable Diffusion didn t like the video card in my setup for unknown reasons but also that the E5-1650v3 CPU could render an image in 15 minutes which is fast enough to test it out but not fast enough for serious use. I had been planning to blog about that. When I bought the T320 server the DDR3 Registered ECC RAM it uses cost about $100 for 8*8G DIMMs, with 16G DIMMs being much more expensive. Now the DDR4 Registered ECC RAM used by my Z640 goes for about $120 for 2*16G DIMMs. In the near future I ll upgrade that system to 64G of RAM. It s disappointing that the Z640 only has 4 DIMM sockets per CPU so if you get a single-CPU version (as I did) and don t get the really expensive Load Reduced RAM then you are limited to 64G. So the supposed capacity benefit of going from DDR3 to DDR4 doesn t seem to apply to this upgrade. The Z640 I got has 4 bays for hot-swap SAS/SATA 2.5 SSD/HDDs and 2 internal bays for 3.5 hard drives. The T320 has 8*3.5 hot swap bays and I had 3 hard drives in them in a BTRFS RAID-10 configuration. Currently I ve got one hard drive attached via USB but that s obviously not a long-term solution. The 3 hard drives are 4TB, they have worked since 4TB was a good size. I have a spare 8TB disk so I could buy a second ($179 for a shingle HDD) to make a 8TB RAID-1 array. The other option is to pay $369 for a 4TB SSD (or $389 for a 4TB NVMe + $10 for the PCIe card) to keep the 3 device RAID-10. As tempting as 4TB SSDs are I ll probably get a cheap 8TB disk which will take capacity from 6TB to 8TB and I could use some extra 4TB disks for backups. I haven t played with the AMT/MEBX features on this system, I presume that they will work the same way as AMT/MEBX on the HP Z420 I ve used previously [2]. Update: HP has free updates for the BIOS etc available here [3]. Unfortunately it seems to require loading a kernel module supplied by HP to do this. This is a bad thing, kernel code that isn t in the mainline kernel is either of poor quality or isn t licensed correctly. I had to change my monitoring system to alert on temperatures over 100% of the high range while on the T320 I had it set at 95% of high and never got warnings. This is disappointing, enterprise class gear running in a reasonably cool environment (ambient temperature of about 22C) should be able to run all CPU cores at full performance without hitting 95% of the high temperature level.

11 February 2023

Vincent Bernat: Hacking the Geberit Sigma 70 flush plate

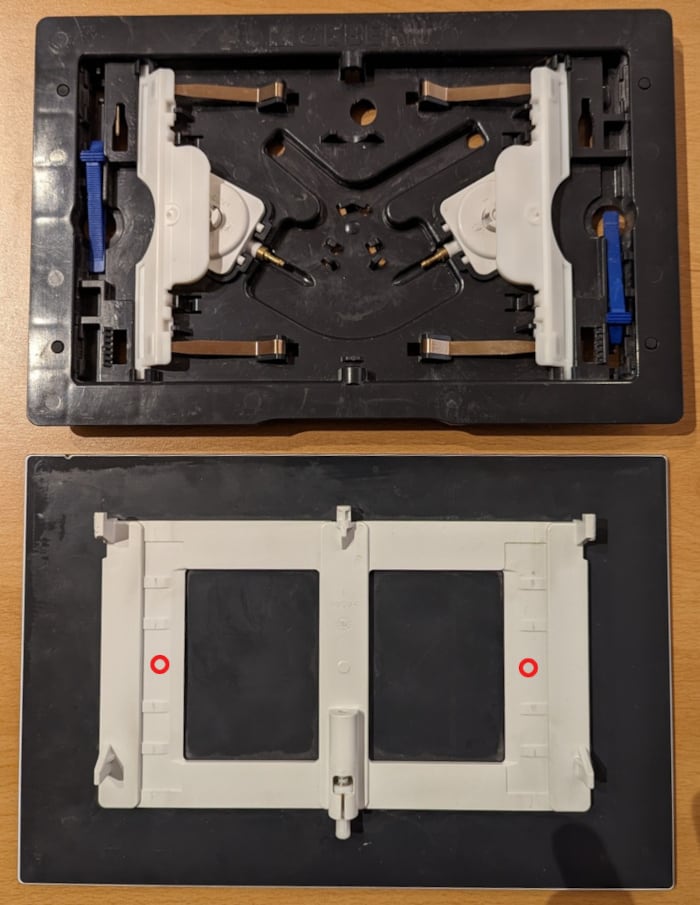
My toilet is equipped with a Geberit Sigma 70 flush plate. The sales pitch for this hydraulic-assisted device praises the ingenious mount that acts like a rocker switch. In practice, the flush is very capricious and has a very high failure rate. Avoid this type of mechanism! Prefer a fully mechanical version like the Geberit Sigma 20. After several plumbers, exchanges with Geberit s technical department, and the expensive replacement of the entire mechanism, I was still getting a failure rate of over 50% for the small flush. I finally managed to decrease this rate to 5% by applying two 8 mm silicone bumpers on the back of the plate. Their locations are indicated by red circles on the picture below:
Geberit Sigma 70 flush plate. Top: the mechanism that converts the mechanical press into a hydraulic impulse. Bottom: the back of the plate with the two places where to apply the bumpers.
Geberit Sigma 70 flush plate. Above: the mechanism installed on the wall. Below, the back of the glass plate. In red, the two places where to apply the silicone bumpers.
Expect to pay about 5 and as many minutes for this operation.

10 February 2023

Antoine Beaupr : Picking a USB-C dock and charger

Dear lazy web, help me pick the right hardware to make my shiny new laptop work better. I want a new USB-C dock and travel power supply.

Background I need advice on hardware, because my current setup in the office doesn't work so well. My new Framework laptop has four (4!) USB-C ports which is great, but it only has those ports (there's a combo jack, but I don't use it because it's noisy). So right now I have the following setup:
  • HDMI: monitor one
  • HDMI: monitor two
  • USB-A: Yubikey
  • USB-C: USB-C hub, which has:
    • RJ-45 network
    • USB-A keyboard
    • USB-A mouse
    • USB-A headset
... and I'm missing a USB-C port for power! So I get into this annoying situation where I need to actually unplug the USB-A Yubikey, unplug the USB-A expansion card, plug in the power for a while so it can charge, and then do that in reverse when I need the Yubikey again (which is: often). Another option I have is to unplug the headset, but I often need both the headset and the Yubikey at once. I also have a pair of earbuds that work in the combo jack, but, again, they are noticeably noisy. So this doesn't work. I'm thinking I should get a USB-C Dock of some sort. The Framework forum has a long list of supported docks in a "megathread", but I figured people here might have their own experience with docks and laptop/dock setups. So what should USB-C Dock should I get? Should I consider changing to a big monitor with a built-in USB-C dock and power? Ideally, i'd like to just walk in the office, put the laptop down and insert a single USB-C cable and be done with it. Does that even work with Wayland? I have read reports of Displaylink not working in Sway specifically... does that apply to any multi-monitor over a single USB-C cable setup? Oh, and what about travel options? Do you have a fancy small form factor USB-C power charger that you really like?

Current ideas Here are the devices I'm considering right now...

USB chargers The spec here is at least 65W USB-C with international plugs. I particularly like the TOFU, but I am not sure it will deliver... I found that weird little thing through this Twitter post from Benedict Reuschling, from this blog post, from 2.5 admins episode 127 (phew!). Update: I ordered a TOFU power station today (2023-02-20). I'm a little concerned about the power output (45W instead of 65W for the Framework charger), but I suspect it will not actually be a problem while traveling, since the laptop will keep its charge during the day and will charge at night... The device shipped 3 days later, with an estimated delivery time of 12 to 15 days, so expect this thing to take its sweet time landing on your desk.

USB Docks Specification:
  • must have 2 or more USB-A ports (3 is ideal, otherwise i need a new headset adapter)
  • at least one USB-C port, preferably more
  • works in Linux
  • 2 display support (or one big monitor?), ideally 2x4k for future-proofing, HDMI or Display-Port, ideally also with double USB-C/Thunderbolt for future-proofing
  • all on one USB-C wire would be nice
  • power delivery over the USB-C cable
  • not too big, preferably
Note that I move from 4 USB-A ports down to 2 or 3 because I can change the USB-A cable on my keyboard for USB-C. But that means I need a slot for a USB-C port on the dock of course. I also could live with one less USB-A cable if I find a combo jack adapter, but that would mean a noisy experience. Options found so far:
  • ThinkPad universal dock/40ay0090us): 300$USD, 65-100W, combo jack, 3x USB3.1, 2x USB2.0, 1x USB-C, 2x Display Port, 1x HDMI Port, 1x Gigabit Ethernet
  • Caldigit docks are apparently good, and the USB-C HDMI Dock seems like a good candidate (not on sale in there Canada shop), but leaves me wondering whether I want to keep my old analog monitors around and instead get proper monitors with USB-C inputs, and use something like Thunderbolt Element hub (230$USD). Update: I wrote Caldigit and they don't seem to have any Dock that would work for me, they suggest the TS3 plus which only has a single DP connector (!?). The USB-C HDMI dock is actually discontinued and they mentioned that they do have trouble with Linux in general.
  • I was also recommended OWC docks as well. update: their website is a mess, and live chat has confirmed they do not actually have any device that fits the requirement of two HDMI/DP outputs.
  • Anker also has docks (e.g. the Anker 568 USB-C Docking Station 11-in-1 looks nice, but holy moly 300$USD... Also, Anker docks are not all equal, I've heard reports of some of them being bad. Update: I reached out to Anker to clarify whether or not their docks will work on Linux and to advise on which dock to use, and their response is that they "do not recommend you use our items with Linux system". So I guess that settles it with Anker.
  • Cable Matters are promising, and their "USB-C Docking Station with Dual 4K HDMI and 80W Charging for Windows Computers might just actually work. It was out of stock on their website and Amazon but after reaching out to their support by email, they pointed out a product page that works in Canada.
Also: this post from Big Mess Of Wires has me worried that anything might work at all. It's where I had the Cable Matters reference however... Update: I ordered a this dock from Cable Matters from Amazon (reluctantly). It promises Linux support and checked all the boxes for me (4x USB-A, audio, network, 2xHDMI). It kind of works? I tested the USB-A ports, charging, networking, and the HDMI ports, all worked the first time. But! When I disconnect and reconnect the hub, the HDMI ports stop working. It s quite infuriating especially since there s very little diagnostics available. It s unclear how the devices show up on my computer, I can t even tell what device provides the HDMI connectors in lsbusb. I ve also seen the USB keyboard drop keypresses, which is also ... not fun. I suspect foul play inside Sway. And yeah, those things are costly! This one goes for 300$ a pop, not great. Update 2: Cable Matters support responded by simply giving me this hack that solved it at least for now. Just reverse the USB-C cable, and poof, everything works. Magic.

Your turn! So what's your desktop setup like? Do you have docks? a laptop? a desktop? did you build it yourself? Did you solder a USB-C port in the back of your neck and interface directly with the matrix and there's no spoon? Do you have a 4k monitor? Two? A 8k monitor that curves around your head in a fully immersive display? Do you work on a Occulus rift and only interface the world through 3d virtual reality, including terminal emulators? Thanks in advance!

9 February 2023

Sam Hartman: Building Carthage with Carthage

This is the second in a series of blog posts introducing Carthage, an Infrastructure as Code framework I ve been working on the last four years. In this post we ll talk about how we use Carthage to build the Carthage container images. We absolutely could have just used a Containerfile to do this; in fact I recently removed a hybrid solution that produced an artifact and then used a Containerfile to turn it into an OCI image. The biggest reason we don t use a Containerfile is that we want to be able to reuse the same infrastructure (installed software and configuration) across multiple environments. For example CarthageServerRole, a reusable Carthage component that install Carthage itself is used in several places:
  1. on raw hardware when we re using Carthage to drive a hypervisor
  2. As part of image building pipelines to build AMIs for Amazon Web Services
  3. Installed onto AWS instances built from the Debian AMI where we cannot use custom AMIs
  4. Installed onto KVM VMs
  5. As part of building the Carthage container images
So the biggest thing Carthage gives us is uniformity in how we set up infrastructure. We ve found a number of disadvantages of Containerfiles as well:
  1. Containerfiles mix the disadvantages of imperative and declarative formats. Like a declarative format they have no explicit control logic. It seems like that would be good for introspecting and reasoning about Containers. But all you get is the base image and a set of commands to build a container. For reasoning about common things like whether a container has a particular vulnerability or can be distributed under a particular license, that s not very useful. So we don t get much valuable introspection out of the declarative aspects, and all too often we see Containerfiles generated by Makefiles or other multi-level build-systems to get more logic or control flow.
  2. Containerfiles have limited facility for doing things outside the container. The disadvantage of this is that you end up installing all the software you need to build the container into the container itself (or having a multi-level build system). But for example if I want to use Ansible to configure a container, the easiest way to do that is to actually install Ansible into the container itself, even though Ansible has a large dependency chain most of which we won t need in the container. Yes, Ansible does have a number of connection methods including one for Buildah, but by the point you re using that, you re already using a multi-level build system and aren t really just using a Containerfile.
Okay, so since we re not going to just use a Containerfile, what do we do instead? We produce a CarthageLayout. A CarthageLayout is an object in the Carthage modeling language. The modeling language looks a lot like Python in fact it s even implemented using Python metaclasses and uses the Python parser. However, there are some key semantic differences and it may help to think of the modeling language as its own thing. Carthage layouts are typically contained in Carthage plugins. For example, the oci_images plugin is our focus today. Most of the work in that plugin is in layout.py, and the layout begins here:
class layout(CarthageLayout):
    add_provider(ConfigLayout)
    add_provider(carthage.ansible.ansible_log, str(_dir/"ansible.log"))
The add_provider calls are special, and we ll discuss them in a future post. For now, think of them as assignments in a more complex namespace than simple identifiers. But the heart of this layout is the CarthageImage class:
    class CarthageImage(PodmanImageModel, carthage_base.CarthageServerRole):
        base_image = injector_access('from_scratch_debian')
        oci_image_tag = 'localhost/carthage:latest'
        oci_image_command = ['/bin/systemd']
Most of the work of our image is done by inheritance. We inherit from the CarthageServerRole from the carthage_base plugin collection. A role is a reusable set of infrastructure that can be attached directly to a MachineModel. By inheriting from this role, we request the installation of the Carthage software. The role also supports copying in various dependencies; for example when Carthage is used to manage a cluster of machines, the layout corresponding to the cluster can automatically be copied to all nodes in the cluster. We do not need this feature to build the container image. The CarthageImage class sets its base image. Currently we are using our own base Debian image that we build with debootstrap and then import as a container image. In the fairly near future, we ll change that to:
        base_image =  debian:bookworm 
That will simply use the Debian image from Dockerhub. We are building our own base image for historical reasons and need to confirm that everything works before switching over. By setting oci_image_tag we specify where in the local images the resulting image will be stored. We also specify that this image boots systemd. We actually do want to do a bit of work on top of CarthageServerRole specific to the container image. To do that we use a Carthage feature called a Customization. There are various types of customization. For example MachineCustomization runs a set of tasks on a Machine that is booted and on the network. When building images, the most common type of customization is a FilesystemCustomization. For these, we have access to the filesystem, and we have some way of running a command in the context of the filesystem. We don t boot the filesystem as a machine unless we need to. (We might if the filesystem is a kvm VM or AWS instance for example). Carthage collects all the customizations in a role or image model. In the case of container image classes like PodmanImageModel, each customization is applied as an individual layer in the resulting container image. Roles and customizations are both reusable infrastructure. Roles typically contain customizations. Roles operate at the modeling layer; you might introspect a machine s model or an image s model to see what functionality (roles) it provides. In contrast, customizations operate at the implementation layer. They do specific things like move files around, apply Ansible roles or similar. Let s take a look at the customization applied for the Carthage container image (full code):

        class customize_for_oci(FilesystemCustomization):

            @setup_task("Remove Software")
            async def remove_software(self):
                await self.run_command("apt", "-y", "purge",
                                       "exim4-base",
                                       )

            @setup_task("Install service")
            async def install_service(self):
               # installs and activates a systemd unit
Then to pull it all together, we simply run the layout:
sudo PYTHONPATH=$(pwd) python3 ./bin/carthage-runner ./oci_images build
In the next post, we will dig more into how to make infrastructure reusable.

comment count unavailable comments

8 February 2023

Chris Lamb: Most anticipated films of 2023

Very few highly-anticipated movies appear in January and February, as the bigger releases are timed so they can be considered for the Golden Globes in January and the Oscars in late February or early March, so film fans have the advantage of a few weeks after the New Year to collect their thoughts on the year ahead. In other words, I'm not actually late in outlining below the films I'm most looking forward to in 2023...

Barbie No, seriously! If anyone can make a good film about a doll franchise, it's probably Greta Gerwig. Not only was Little Women (2019) more than admirable, the same could be definitely said for Lady Bird (2017). More importantly, I can't help feel she was the real 'Driver' behind Frances Ha (2012), one of the better modern takes on Claudia Weill's revelatory Girlfriends (1978). Still, whenever I remember that Barbie will be a film about a billion-dollar toy and media franchise with a nettlesome history, I recall I rubbished the "Facebook film" that turned into The Social Network (2010). Anyway, the trailer for Barbie is worth watching, if only because it seems like a parody of itself.

Blitz It's difficult to overstate just how important the aerial bombing of London during World War II is crucial to understanding the British psyche, despite it being a constructed phenomenon from the outset. Without wishing to underplay the deaths of over 40,000 civilian deaths, Angus Calder pointed out in the 1990s that the modern mythology surrounding the event "did not evolve spontaneously; it was a propaganda construct directed as much at [then neutral] American opinion as at British." It will therefore be interesting to see how British Grenadian Trinidadian director Steve McQueen addresses a topic so essential to the British self-conception. (Remember the controversy in right-wing circles about the sole Indian soldier in Christopher Nolan's Dunkirk (2017)?) McQueen is perhaps best known for his 12 Years a Slave (2013), but he recently directed a six-part film anthology for the BBC which addressed the realities of post-Empire immigration to Britain, and this leads me to suspect he sees the Blitz and its surrounding mythology with a more critical perspective. But any attempt to complicate the story of World War II will be vigorously opposed in a way that will make the recent hullabaloo surrounding The Crown seem tame. All this is to say that the discourse surrounding this release may be as interesting as the film itself.

Dune, Part II Coming out of the cinema after the first part of Denis Vileneve's adaptation of Dune (2021), I was struck by the conception that it was less of a fresh adaptation of the 1965 novel by Frank Herbert than an attempt to rehabilitate David Lynch's 1984 version and in a broader sense, it was also an attempt to reestablish the primacy of cinema over streaming TV and the myriad of other distractions in our lives. I must admit I'm not a huge fan of the original novel, finding within it a certain prurience regarding hereditary military regimes and writing about them with a certain sense of glee that belies a secret admiration for them... not to mention an eyebrow-raising allegory for the Middle East. Still, Dune, Part II is going to be a fantastic spectacle.

Ferrari It'll be curious to see how this differs substantially from the recent Ford v Ferrari (2019), but given that Michael Mann's Heat (1995) so effectively re-energised the gangster/heist genre, I'm more than willing to kick the tires of this about the founder of the eponymous car manufacturer. I'm in the minority for preferring Mann's Thief (1981) over Heat, in part because the former deals in more abstract themes, so I'd have perhaps prefered to look forward to a more conceptual film from Mann over a story about one specific guy.

How Do You Live There are a few directors one can look forward to watching almost without qualification, and Hayao Miyazaki (My Neighbor Totoro, Kiki's Delivery Service, Princess Mononoke Howl's Moving Castle, etc.) is one of them. And this is especially so given that The Wind Rises (2013) was meant to be the last collaboration between Miyazaki and Studio Ghibli. Let's hope he is able to come out of retirement in another ten years.

Indiana Jones and the Dial of Destiny Given I had a strong dislike of Indiana Jones and the Kingdom of the Crystal Skull (2008), I seriously doubt I will enjoy anything this film has to show me, but with 1981's Raiders of the Lost Ark remaining one of my most treasured films (read my brief homage), I still feel a strong sense of obligation towards the Indiana Jones name, despite it feeling like the copper is being pulled out of the walls of this franchise today.

Kafka I only know Polish filmmaker Agnieszka Holland through her Spoor (2017), an adaptation of Olga Tokarczuk's 2009 eco-crime novel Drive Your Plow Over the Bones of the Dead. I wasn't an unqualified fan of Spoor (nor the book on which it is based), but I am interested in Holland's take on the life of Czech author Franz Kafka, an author enmeshed with twentieth-century art and philosophy, especially that of central Europe. Holland has mentioned she intends to tell the story "as a kind of collage," and I can hope that it is an adventurous take on the over-furrowed biopic genre. Or perhaps Gregor Samsa will awake from uneasy dreams to find himself transformed in his bed into a huge verminous biopic.

The Killer It'll be interesting to see what path David Fincher is taking today, especially after his puzzling and strangely cold Mank (2020) portraying the writing process behind Orson Welles' Citizen Kane (1941). The Killer is said to be a straight-to-Netflix thriller based on the graphic novel about a hired assassin, which makes me think of Fincher's Zodiac (2007), and, of course, Se7en (1995). I'm not as entranced by Fincher as I used to be, but any film with Michael Fassbender and Tilda Swinton (with a score by Trent Reznor) is always going to get my attention.

Killers of the Flower Moon In Killers of the Flower Moon, Martin Scorsese directs an adaptation of a book about the FBI's investigation into a conspiracy to murder Osage tribe members in the early years of the twentieth century in order to deprive them of their oil-rich land. (The only thing more quintessentially American than apple pie is a conspiracy combined with a genocide.) Separate from learning more about this disquieting chapter of American history, I'd love to discover what attracted Scorsese to this particular story: he's one of the few top-level directors who have the ability to lucidly articulate their intentions and motivations.

Napoleon It often strikes me that, despite all of his achievements and fame, it's somehow still possible to claim that Ridley Scott is relatively underrated compared to other directors working at the top level today. Besides that, though, I'm especially interested in this film, not least of all because I just read Tolstoy's War and Peace (read my recent review) and am working my way through the mind-boggling 431-minute Soviet TV adaptation, but also because several auteur filmmakers (including Stanley Kubrick) have tried to make a Napoleon epic and failed.

Oppenheimer In a way, a biopic about the scientist responsible for the atomic bomb and the Manhattan Project seems almost perfect material for Christopher Nolan. He can certainly rely on stars to queue up to be in his movies (Robert Downey Jr., Matt Damon, Kenneth Branagh, etc.), but whilst I'm certain it will be entertaining on many fronts, I fear it will fall into the well-established Nolan mould of yet another single man struggling with obsession, deception and guilt who is trying in vain to balance order and chaos in the world.

The Way of the Wind Marked by philosophical and spiritual overtones, all of Terrence Malick's films are perfumed with themes of transcendence, nature and the inevitable conflict between instinct and reason. My particular favourite is his stunning Days of Heaven (1978), but The Thin Red Line (1998) and A Hidden Life (2019) also touched me ways difficult to relate, and are one of the few films about the Second World War that don't touch off my sensitivity about them (see my remarks about Blitz above). It is therefore somewhat Malickian that his next film will be a biblical drama about the life of Jesus. Given Malick's filmography, I suspect this will be far more subdued than William Wyler's 1959 Ben-Hur and significantly more equivocal in its conviction compared to Paolo Pasolini's ardently progressive The Gospel According to St. Matthew (1964). However, little beyond that can be guessed, and the film may not even appear until 2024 or even 2025.

Zone of Interest I was mesmerised by Jonathan Glazer's Under the Skin (2013), and there is much to admire in his borderline 'revisionist gangster' film Sexy Beast (2000), so I will definitely be on the lookout for this one. The only thing making me hesitate is that Zone of Interest is based on a book by Martin Amis about a romance set inside the Auschwitz concentration camp. I haven't read the book, but Amis has something of a history in his grappling with the history of the twentieth century, and he seems to do it in a way that never sits right with me. But if Paul Verhoeven's Starship Troopers (1997) proves anything at all, it's all in the adaption.

Antoine Beaupr : Major outage with Oricom uplink

The server that normally serves this page, all my email, and many more services was unavailable for about 24 hours. This post explains how and why.

What happened? Starting February 2nd, I started seeing intermittent packet loss on the network. Every hour or so, the link would go down for one or two minutes, then come back up. At first, I didn't think much of it because I was away and could blame the crappy wifi or the uplink I using. But when I came in the office on Monday, the service was indeed seriously degraded. I could barely do videoconferencing calls as they would cut out after about half an hour. I opened a ticket with my uplink, Oricom. They replied that it was an issue they couldn't fix on their end and would need someone on site to fix. So, the next day (Tuesday, at around 10EST) I called Oricom again, and they made me do a full modem reset, which involves plugging a pin in a hole for 15 seconds on the Technicolor TC4400 cable modem. Then the link went down, and it didn't come back up at all. Boom. Oricom then escalated this to their upstream (Oricom is a reseller of Videotron, who has basically the monopoly on cable in Qu bec) which dispatched a tech. This tech, in turn, arrived some time after lunch and said the link worked fine and it was a hardware issue. At this point, Oricom put a new modem in the mail and I started mitigation.

Mitigation

Website The first thing I did, weirdly, was trying to rebuild this blog. I figured it should be pretty simple: install ikiwiki and hit rebuild. I knew I had some patches on ikiwiki to deploy, but surely those are not a deal breaker, right? Nope. Turns out I wrote many plugins and those still don't ship with ikiwiki, despite having been sent upstream a while back, some years ago. So I deployed the plugins inside the .ikiwiki directory of the site in the hope of making things a little more "standalone". Unfortunately, that didn't work either because the theme must be shipped in the system-wide location: I couldn't figure out how to put it to have it bundled with the main repository. At that point I mostly gave up because I had spent too much time on this and I had to do something about email otherwise it would start to bounce.

Email So I made a new VM at Linode (thanks 2.5admins for the credits) to build a new mail server. This wasn't the best idea, in retrospect, because it was really overkill: I started rebuilding the whole mail server from scratch. Ideally, this would be in Puppet and I would just deploy the right profile and the server would be rebuilt. Unfortunately, that part of my infrastructure is not Puppetized and even if it would, well the Puppet server was also down so I would have had to bring that up first. At first, I figured I would just make a secondary mail exchanger (MX), to spool mail for longer so that I wouldn't lose it. But I decided against that: I thought it was too hard to make a "proper" MX as it needs to also filter mail while avoiding backscatter. Might as well just build a whole new server! I had a copy of my full mail spool on my laptop, so I figured that was possible. I mostly got this right: added a DKIM key, installed Postfix, Dovecot, OpenDKIM, OpenDMARC, glue it all together, and voil , I had a mail server. Oh, and spampd. Oh, and I need the training data, oh, and this and... I wasn't done and it was time to sleep. The mail server went online this morning, and started accepting mail. I tried syncing my laptop mail spool against it, but that failed because Dovecot generated new UIDs for the emails, and isync correctly failed to sync. I tried to copy the UIDs from the server in the office (which I had still access to locally), but that somehow didn't work either. But at least the mail was getting delivered and stored properly. I even had the Sieve rules setup so it would get sorted properly too. Unfortunately, I didn't hook that up properly, so those didn't actually get sorted. Thankfully, Dovecot can re-filter emails with the sieve-filter command, so that was fixed later. At this point, I started looking for other things to fix.

Web, again I figured I was almost done with the website, might as well publish it. So I installed the Nginx Debian package, got a cert with certbot, and added the certs to the default configuration. I rsync'd my build in /var/www/html and boom, I had a website. The Goatcounter analytics were timing out, but that was easy to turn off.

Resolution Almost at that exact moment, a bang on the door told me mail was here and I had the modem. I plugged it in and a few minutes later, marcos was back online. So this was a lot (a lot!) of work for basically nothing. I could have just taken the day off and wait for the package to be delivered. It would definitely have been better to make a simpler mail exchanger to spool the mail to avoid losing it. And in fact, that's what I eventually ended up doing: I converted the linode server in a mail relay to continue accepting mail with DNS propagates, but without having to sort the mail out of there... Right now I have about 200 mails in a mailbox that I need to move back into marcos. Normally, this would just be a simple rsync, but because both servers have accepted mail simultaneously, it's going to be simpler to just move those exact mails on there. Because dovecot helpfully names delivered files with the hostname it's running on, it's easy to find those files and transfer them, basically:
rsync -v -n --files-from=<(ssh colette.anarc.at find Maildir -name '*colette*' ) colette.anarc.at: colette/
rsync -v -n --files-from=<(ssh colette.anarc.at find Maildir -name '*colette*' ) colette/ marcos.anarc.at:
Overall, the outage lasted about 24 hours, from 11:00EST (16:00UTC) on 2023-02-07 to the same time today.

Future work I'll probably keep a mail relay to make those situations more manageable in the future. At first I thought that mail filtering would be a problem, but that happens post queue anyways and I don't bounce mail based on Spamassassin, so back-scatter shouldn't be an issue. I basically need Postfix, OpenDMARC, and Postgrey. I'm not even sure I need OpenDKIM as the server won't process outgoing mail, so it doesn't need to sign anything, just check incoming signatures, which OpenDMARC can (probably?) do. Thanks to everyone who supported me through this ordeal, you know who you are (and I'm happy to give credit here if you want to be deanonymized)!

6 February 2023

Reproducible Builds: Reproducible Builds in January 2023

Welcome to the first report for 2023 from the Reproducible Builds project! In these reports we try and outline the most important things that we have been up to over the past month, as well as the most important things in/around the community. As a quick recap, the motivation behind the reproducible builds effort is to ensure no malicious flaws can be deliberately introduced during compilation and distribution of the software that we run on our devices. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.


News In a curious turn of events, GitHub first announced this month that the checksums of various Git archives may be subject to change, specifically that because:
the default compression for Git archives has recently changed. As result, archives downloaded from GitHub may have different checksums even though the contents are completely unchanged.
This change (which was brought up on our mailing list last October) would have had quite wide-ranging implications for anyone wishing to validate and verify downloaded archives using cryptographic signatures. However, GitHub reversed this decision, updating their original announcement with a message that We are reverting this change for now. More details to follow. It appears that this was informed in part by an in-depth discussion in the GitHub Community issue tracker.
The Bundesamt f r Sicherheit in der Informationstechnik (BSI) (trans: The Federal Office for Information Security ) is the agency in charge of managing computer and communication security for the German federal government. They recently produced a report that touches on attacks on software supply-chains (Supply-Chain-Angriff). (German PDF)
Contributor Seb35 updated our website to fix broken links to Tails Git repository [ ][ ], and Holger updated a large number of pages around our recent summit in Venice [ ][ ][ ][ ].
Noak J nsson has written an interesting paper entitled The State of Software Diversity in the Software Supply Chain of Ethereum Clients. As the paper outlines:
In this report, the software supply chains of the most popular Ethereum clients are cataloged and analyzed. The dependency graphs of Ethereum clients developed in Go, Rust, and Java, are studied. These client are Geth, Prysm, OpenEthereum, Lighthouse, Besu, and Teku. To do so, their dependency graphs are transformed into a unified format. Quantitative metrics are used to depict the software supply chain of the blockchain. The results show a clear difference in the size of the software supply chain required for the execution layer and consensus layer of Ethereum.

Yongkui Han posted to our mailing list discussing making reproducible builds & GitBOM work together without gitBOM-ID embedding. GitBOM (now renamed to OmniBOR) is a project to enable automatic, verifiable artifact resolution across today s diverse software supply-chains [ ]. In addition, Fabian Keil wrote to us asking whether anyone in the community would be at Chemnitz Linux Days 2023, which is due to take place on 11th and 12th March (event info). Separate to this, Akihiro Suda posted to our mailing list just after the end of the month with a status report of bit-for-bit reproducible Docker/OCI images. As Akihiro mentions in their post, they will be giving a talk at FOSDEM in the Containers devroom titled Bit-for-bit reproducible builds with Dockerfile and that my talk will also mention how to pin the apt/dnf/apk/pacman packages with my repro-get tool.
The extremely popular Signal messenger app added upstream support for the SOURCE_DATE_EPOCH environment variable this month. This means that release tarballs of the Signal desktop client do not embed nondeterministic release information. [ ][ ]

Distribution work

F-Droid & Android There was a very large number of changes in the F-Droid and wider Android ecosystem this month: On January 15th, a blog post entitled Towards a reproducible F-Droid was published on the F-Droid website, outlining the reasons why F-Droid signs published APKs with its own keys and how reproducible builds allow using upstream developers keys instead. In particular:
In response to [ ] criticisms, we started encouraging new apps to enable reproducible builds. It turns out that reproducible builds are not so difficult to achieve for many apps. In the past few months we ve gotten many more reproducible apps in F-Droid than before. Currently we can t highlight which apps are reproducible in the client, so maybe you haven t noticed that there are many new apps signed with upstream developers keys.
(There was a discussion about this post on Hacker News.) In addition:
  • F-Droid added 13 apps published with reproducible builds this month. [ ]
  • FC Stegerman outlined a bug where baseline.profm files are nondeterministic, developed a workaround, and provided all the details required for a fix. As they note, this issue has now been fixed but the fix is not yet part of an official Android Gradle plugin release.
  • GitLab user Parwor discovered that the number of CPU cores can affect the reproducibility of .dex files. [ ]
  • FC Stegerman also announced the 0.2.0 and 0.2.1 releases of reproducible-apk-tools, a suite of tools to help make .apk files reproducible. Several new subcommands and scripts were added, and a number of bugs were fixed as well [ ][ ]. They also updated the F-Droid website to improve the reproducibility-related documentation. [ ][ ]
  • On the F-Droid issue tracker, FC Stegerman discussed reproducible builds with one of the developers of the Threema messenger app and reported that Android SDK build-tools 31.0.0 and 32.0.0 (unlike earlier and later versions) have a zipalign command that produces incorrect padding.
  • A number of bugs related to reproducibility were discovered in Android itself. Firstly, the non-deterministic order of .zip entries in .apk files [ ] and then newline differences between building on Windows versus Linux that can make builds not reproducible as well. [ ] (Note that these links may require a Google account to view.)
  • And just before the end of the month, FC Stegerman started a thread on our mailing list on the topic of hiding data/code in APK embedded signatures which has been made possible by the Android APK Signature Scheme v2/v3. As part of this, they made an Android app that reads the APK Signing block of its own APK and extracts a payload in order to alter its behaviour called sigblock-code-poc.

Debian As mentioned in last month s report, Vagrant Cascadian has been organising a series of online sprints in order to clear the huge backlog of reproducible builds patches submitted by performing NMUs (Non-Maintainer Uploads). During January, a sprint took place on the 10th, resulting in the following uploads: During this sprint, Holger Levsen filed Debian bug #1028615 to request that the tracker.debian.org service display results of reproducible rebuilds, not just reproducible CI results. Elsewhere in Debian, strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. This month, version 1.13.1-1 was uploaded to Debian unstable by Holger Levsen, including a fix by FC Stegerman (obfusk) to update a regular expression for the latest version of file(1) [ ]. (#1028892) Lastly, 65 reviews of Debian packages were added, 21 were updated and 35 were removed this month adding to our knowledge about identified issues.

Other distributions In other distributions:

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 231, 232, 233 and 234 to Debian:
  • No need for from __future__ import print_function import anymore. [ ]
  • Comment and tidy the extras_require.json handling. [ ]
  • Split inline Python code to generate test Recommends into a separate Python script. [ ]
  • Update debian/tests/control after merging support for PyPDF support. [ ]
  • Correctly catch segfaulting cd-iccdump binary. [ ]
  • Drop some old debugging code. [ ]
  • Allow ICC tests to (temporarily) fail. [ ]
In addition, FC Stegerman (obfusk) made a number of changes, including:
  • Updating the test_text_proper_indentation test to support the latest version(s) of file(1). [ ]
  • Use an extras_require.json file to store some build/release metadata, instead of accessing the internet. [ ]
  • Updating an APK-related file(1) regular expression. [ ]
  • On the diffoscope.org website, de-duplicate contributors by e-mail. [ ]
Lastly, Sam James added support for PyPDF version 3 [ ] and Vagrant Cascadian updated a handful of tool references for GNU Guix. [ ][ ]

Upstream patches The Reproducible Builds project attempts to fix as many currently-unreproducible packages as possible. This month, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project operates a comprehensive testing framework at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In January, the following changes were made by Holger Levsen:
  • Node changes:
  • Debian-related changes:
    • Only keep diffoscope s HTML output (ie. no .json or .txt) for LTS suites and older in order to save diskspace on the Jenkins host. [ ]
    • Re-create pbuilder base less frequently for the stretch, bookworm and experimental suites. [ ]
  • OpenWrt-related changes:
    • Add gcc-multilib to OPENWRT_HOST_PACKAGES and install it on the nodes that need it. [ ]
    • Detect more problems in the health check when failing to build OpenWrt. [ ]
  • Misc changes:
    • Update the chroot-run script to correctly manage /dev and /dev/pts. [ ][ ][ ]
    • Update the Jenkins shell monitor script to collect disk stats less frequently [ ] and to include various directory stats. [ ][ ]
    • Update the real year in the configuration in order to be able to detect whether a node is running in the future or not. [ ]
    • Bump copyright years in the default page footer. [ ]
In addition, Christian Marangi submitted a patch to build OpenWrt packages with the V=s flag to enable debugging. [ ]
If you are interested in contributing to the Reproducible Builds project, please visit the Contribute page on our website. You can get in touch with us via:

5 February 2023

Mike Gabriel: Call for translations: Lomiri / Ubuntu Touch 20.04

Prologue For over a year now, Fre(i)e Software GmbH (my company) is involved in Ubuntu Touch development. The development effort currently is handled by a mix of paid and voluntary developers/contributors under the umbrella of the UBports Foundation. We are approaching the official first release of Ubuntu Touch 20.04 with rapid pace. And, if you are a non-Englisch native speaker, we'd like to ask you for help... Read below. light+love
Mike (aka sunweaver at debian.org, Mastodon, IRC, etc.) Internationalization (i18n) of Ubuntu Touch 20.04 The UBports team has moved most of the translation workflows for localizing Ubuntu Touch over to Hosted Weblate: To contribute to the UBports projects you need to register here: The localization platform of all UBports / Lomiri components is sponsored by Hosted Weblate via their free hosting plan for Libre and Open Source Projects. Many thanks for providing this service. Translating Lomiri The translation components in the Lomiri project have already been set up and are ready for being updated by translators. Please expect some translation template changes for all those components to occur in the near future, but this should not hinder you from starting translation work right away. Translating Lomiri will bring the best i18n experience to Ubuntu Touch 20.04 end users for the core libraries and the pre-installed (so called) Core Apps. Translating Ubuntu Touch Apps For App Developers (apps that are not among the Core Apps) we will now offer a translation slot under the UBports project on hosted.weblate.org: If you are actively maintaining an Ubuntu Touch app, please ask for a translation component slot on hosted.weblate.org and we will set up your app's translation workflow for and with you. Using the translation service at Hosted Weblate is not a must for app developers, it's rather a service we offer to ease i18n work on Ubuntu Touch apps. Who to contact? To get translations for your app set up on Hosted Weblate, please get in touch with us on https://t.me/ubports, please highlight @sunweaver (Mike Gabriel), @BetaBreak (Raoul Kramer), @cibersheep and @Danfro with your request.

Jonathan Dowland: 2022 in reading

In 2022 I read 34 books (-19% on last year). In 2021 roughly a quarter of the books I read were written by women. I was determined to push that ratio in 2022, so I made an effort to try and only read books by women. I knew that I wouldn't manage that, but by trying to, I did get the ratio up to 58% (by page count). I'm not sure what will happen in 2023. My to-read pile has some back-pressure from books by male authors I postponed reading in 2022 (in particular new works by Christopher Priest and Adam Roberts). It's possible the ratio will swing back the other way, which would mean it would not be worth repeating the experiment. At least if the ratio is the point of the exercise. But perhaps it isn't: perhaps the useful outcome is more qualitative than quantitative. I tried to read some new (to me) authors. I really enjoyed Shirley Jackson (The Haunting of Hill House, We Have Always Lived In The Castle). I Struggled with Angela Carter's Heroes and Villains although I plan to return to her other work, in particular, The Bloody Chamber. I also got through Donna Tartt's The Secret History on the recommendation of a friend. I had to push through the first 15% or so but it turned out to be worth it.
a book cover for Shirley Jackson's 'We have always lived in the castle'
a book cover for Margaret Atwood's 'The Handmaid's Tale'
a book cover for Adam Roberts' 'The This'
a book cover for Emily St. John Mandel's 'Sea of Tranquility'

I finally read (and loved) The Handmaid's Tale, which I had never read despite loving Atwood. My top non-fiction book was The Nanny State Made Me by Stuart Maconie. I still read far more fiction than non-fiction. Or perhaps I'm not keeping track of non- fiction as well. I feel non-fiction requires a different approach to reading: not necessarily linear; it's not always important to read the whole book; it's often important to re-read sections. It might not make sense to consider them in the same bracket. My favourite novels this year were Sea of Tranquility by Emily St. John Mandel, a standalone sort-of sequel to The Glass House but in a very different genre; and The This by Adam Roberts, which was equally remarkable. The This has an interesting narrative device in the first third where a stream of tweets is presented in parallel with the main text. This works well, and does a good job of capturing the figurative river of tweet-like stuff that is woven into our lives at the moment. But I can't help but wonder how they tackle that in the audiobook.

Russell Coker: Wayland in Bookworm

We are getting towards the freeze for Debian/Bookworm so the current state of packages isn t going to change much before the release. Bugs will get fixed but missing features will mostly be missing until the next release. Anarcat wrote an excellent blog post about using Wayland with the Sway window manager [1]. It seems pretty good if you like Sway, but I like KDE and plan to continue using it. Several of the important utility programs referenced by Anarcat won t run with KDE/Wayland and give errors such as Compositor doesn t support wlr-output-management-unstable-v1 . One noteworthy thing about Wayland is the the Window manager and the equivalent to the X server are the same program so KDE has different Wayland code than Sway and doesn t support some features. The lack of these features limits my ability to manage multiple displays and therefore makes KDE/Wayland unsuitable for many laptop uses. My work laptop runs Ubuntu 22.04 with KDE and wouldn t correctly display on the pair of monitors on a USB-C dock that s the standard desktop configuration where I work. In my previous post about Wayland [2] I wrote about converting 2 of my systems to Wayland. Since then I had changed them back to X because of problems with supporting strange monitor configurations on laptops and also due to the KDE window manager crashing occasionally which terminates the session in Wayland but merely requires restarting the window manager in X. More recently I had a problem with the GPU in my main workstation sometimes not being recognised by the system (reporting no PCIe device), when I got a new one I couldn t get X to work with the error Cannot run in framebuffer mode. Please specify busIDs for all framebuffer devices so I tried Wayland again. Now in the later stage of the Bookworm development process it seems that the problem with the KDE window manager crashing has been solved or mitigates and there is a new problem of the plasmashell process crashing. As I can restart plasmashell without logging out that s much less annoying. So now my main workstation is running on Wayland with a slower GPU than I previously had while also giving a faster user experience so Wayland is providing a definite performance benefit. Maybe for Trixie (the next release of Debian after Bookworm) we should have a release goal of having full Wayland support in all the major GUI systems.

4 February 2023

Tim Retout: AlmaLinux and SBOMs

At CentOS Connect yesterday, Jack Aboutboul and Javier Hernandez presented a talk about AlmaLinux and SBOMs [video], where they are exploring a novel supply-chain security effort in the RHEL ecosystem. Now, I have unfortunately ignored the Red Hat ecosystem for a long time, so if you are in a similar position to me: CentOS used to produce debranded rebuilds of RHEL; but Red Hat changed the project round so that CentOS Stream now sits in between Fedora Rawhide and RHEL releases, allowing the wider community to try out/contribute to RHEL builds before their release. This is credited with making early RHEL point releases more stable, but left a gap in the market for debranded rebuilds of RHEL; AlmaLinux and Rocky Linux are two distributions that aim to fill that gap. Alma are generating and publishing Software Bill of Material (SBOM) files for every package; these are becoming a requirement for all software sold to the US federal government. What s more, they are sending these SBOMs to a third party (CodeNotary) who store them in some sort of Merkle tree system to make it difficult for people to tamper with later. This should theoretically allow end users of the distribution to verify the supply chain of the packages they have installed? I am currently unclear on the differences between CodeNotary/ImmuDB vs. Sigstore/Rekor, but there s an SBOM devroom at FOSDEM tomorrow so maybe I ll soon be learning that. This also makes me wonder if a Sigstore-based approach would be more likely to be adopted by Fedora/CentOS/RHEL, and whether someone should start a CentOS Software Supply Chain Security SIG to figure this out, or whether such an effort would need to live with the build system team to be properly integrated. It would be nice to understand the supply-chain story for CentOS and RHEL. As I write this, I m also reflecting that perhaps it would be helpful to explain what happens next in the SBOM consumption process; i.e. can this effort demonstrate tangible end user value, like enabling AlmaLinux to integrate with a vendor-neutral approach to vulnerability management? Aside from the value of being able to sell it to the US government!

2 February 2023

Matt Brown: 2023 Writing Plan

To achieve my goal of publishing one high-quality piece of writing per week this year, I ve put together a draft writing plan and a few organisational notes. Please let me know what you think - what s missing? what would you like to read more/less of from me? I aim for each piece of writing to generate discussion, inspire further writing, and raise my visibility and profile with potential customers and peers. Some of the writing will be opinion, but I expect a majority of it will take a learning by teaching approach - aiming to explain and present useful information to the reader while helping me learn more!

Topic Backlog The majority of my writing is going to fit into 4 series, allowing me to plan out a set of posts and narrative rather than having to come up with something novel to write about every week. To start with for Feb, my aim is to get an initial post in each series out the door. Long-term, it s likely that the order of posts will reflect my work focus (e.g. if I m spending a few weeks deep-diving into a particular product idea then expect more writing on that), but I will try and maintain some variety across the different series as well. This backlog will be maintained as a living page at https://www.mattb.nz/w/queue. Thoughts on SRE This series of posts will be pitched primarily at potential consulting customers who want to understand how I approach the development and operations of distributed software systems. Initial topics to cover include:
  • What is SRE? My philosophy on how it relates to DevOps, Platform Engineering and various other hot terms.
  • How SRE scales up and down in size.
  • My approach to managing oncall responsibilities, toil and operational work.
  • How to grow an SRE team, including the common futility of SRE transformations .
  • Learning from incidents, postmortems, incident response, etc.
Business plan drafts I have an ever-growing list of potential software opportunities and products which I think would be fun to build, but which generally don t ever leave my head due to lack of time to develop the idea, or being unable to convince myself that there s a viable business case or market for it. I d like to start sharing some very rudimentary business plan sketches for some of these ideas as a way of getting some feedback on my assessment of their potential. Whether that s confirmation that it s not worth pursuing, an expression of interest in the product, or potential partnership/collaboration opportunities - anything is better than the idea just sitting in my head. Initial ideas include:
  • Business oriented Mastodon hosting.
  • PDF E-signing - e.g. A Docusign competitor, but with a local twist through RealMe or drivers license validation.
  • A framework to enable simple, performant per-tenant at-rest encryption for SaaS products - stop the data leaks.
Product development updates For any product ideas that show merit and develop into a project, and particularly for the existing product ideas I ve already committed to exploring, I plan to document my product investigation and market research findings as a way of structuring and driving my learning in the space. To start with this will involve:
  • A series of explanatory posts diving into how NZ s electricity system works with a particular focus on how operational data that will be critical to managing a more dynamic grid flows (or doesn t flow!) today, and what opportunities or needs exist for generating, managing or distributing data that might be solvable with a software system I could build.
  • A series of product reviews and deep dives into existing farm management software and platforms in use by NZ farmers today, looking at the functionality they provide, how they integrate and generally testing the anecdotal feedback I have to date that they re clunky, hard to use and not well integrated.
  • For co2mon.nz the focus will be less on market research and more on exploring potential distribution channels (e.g. direct advertising vs partnership with air conditioning suppliers) and pricing models (e.g. buy vs rent).
Debugging walk-throughs Being able to debug and fix a system that you re not intimately familiar with is valuable skill and something that I ve always enjoyed, but it s also a skill that I observe many engineers are uncomfortable with. There s a set of techniques and processes that I ve honed and developed over the years for doing this which I think make the task of debugging an unfamiliar system more approachable. The idea, is that each post will take a problem or situation I ve encountered, from the initial symptom or problem report and walk through the process of how to narrow down and identify the trigger or root cause of the behaviour. Along the way, discussing techniques used, their pros and cons. In addition to learning about the process of debugging itself, the aim is to illustrate lessons that can be applied when designing and building software systems that facilitate and improve our experiences in the operational stage of a systems lifecycle where debugging takes place. Miscellaneous topics In addition the regular series above, stand-alone posts on the other topics may include:
  • The pros/cons I see of bootstrapping a business vs taking VC or other funding.
  • Thoughts on remote work and hiring staff.
  • AI - a confessional on how I didn t think it would progress in my lifetime, but maybe I was wrong.
  • Reflections on 15 years at Google and thoughts on subsequent events since my departure.
  • AWS vs GCP. Fight! Or with less click-bait, a level-headed comparison of the pros/cons I see in each platform.

Logistics

Discussion and comments A large part of my motivation for writing regularly is to seek feedback and generate discussion on these topics. Typically this is done by including comment functionality within the website itself. I ve decided not to do this - on-site commenting creates extra infrastructure to maintain, and limits the visibility and breadth of discussion to existing readers and followers. To provide opportunities for comment and feedback I plan to share and post notification and summarised snippets of selected posts to various social media platforms. Links to these social media posts will be added to each piece of writing to provide a path for readers to engage and discuss further while enabling the discussion and visibility of the post to grow and extend beyond my direct followers and subscribers. My current thinking is that I ll distribute via the following platforms:
  • Mastodon @matt@mastodon.nz - every post.
  • Twitter @xleem - selected posts. I m trying to reduce Twitter usage in favour of Mastodon, but there s no denying that it s still where a significant number of people and discussions are happening.
  • LinkedIn - probably primarily for posts in the business plan series, and notable milestones in the product development process.
In all cases, my aim will be to post a short teaser or summary paragraph that poses an question or relays an interesting fact to give some immediate value and signal to readers as to whether they want to click through rather than simply spamming links into the feed.

Feedback In addition to social media discussion I also plan to add a direct feedback path, particularly for readers who don t have time or inclination to participate in written discussion, by providing a simple thumbs up/thumbs down feedback widget to the bottom of each post, including those delivered via RSS and email.

Organisation To enable subscription to subsets of my writing (particularly for places like Planet Debian, etc where the more business focused content is likely to be off-topic), I plan to place each post into a set of categories:
  • Business
  • Technology
  • General
In addition to the categories, I ll also use more free-form tags to group writing with linked themes or that falls within one of the series described above.

1 February 2023

Simon Josefsson: Apt Archive Transparency: debdistdiff & apt-canary

I ve always found the operation of apt software package repositories to be a mystery. There appears to be a lack of transparency into which people have access to important apt package repositories out there, how the automatic non-human update mechanism is implemented, and what changes are published. I m thinking of big distributions like Ubuntu and Debian, but also the free GNU/Linux distributions like Trisquel and PureOS that are derived from the more well-known distributions. As far as I can tell, anyone who has the OpenPGP private key trusted by a apt-based GNU/Linux distribution can sign a modified Release/InRelease file and if my machine somehow downloads that version of the release file, my machine could be made to download and install packages that the distribution didn t intend me to install. Further, it seems that anyone who has access to the main HTTP server, or any of its mirrors, or is anywhere on the network between them and my machine (when plaintext HTTP is used), can either stall security updates on my machine (on a per-IP basis), or use it to send my machine (again, on a per-IP basis to avoid detection) a modified Release/InRelease file if they had been able to obtain the private signing key for the archive. These are mighty powers that warrant overview. I ve always put off learning about the processes to protect the apt infrastructure, mentally filing it under so many people rely on this infrastructure that enough people are likely to have invested time reviewing and improving these processes . Simultaneous, I ve always followed the more free-software friendly Debian-derived distributions such as gNewSense and have run it on some machines. I ve never put them into serious production use, because the trust issues with their apt package repositories has been a big question mark for me. The enough people part of my rationale for deferring this is not convincing. Even the simple question of is someone updating the apt repository is not easy to understand on a running gNewSense system. At some point in time the gNewSense cron job to pull in security updates from Debian must have stopped working, and I wouldn t have had any good mechanism to notice that. Most likely it happened without any public announcement. I ve recently switched to Trisquel on production machines, and these questions has come back to haunt me. The situation is unsatisfying and I looked into what could be done to improve it. I could try to understand who are the key people involved in each project, and may even learn what hardware component is used, or what software is involved to update and sign apt repositories. Is the server running non-free software? Proprietary BIOS or NIC firmware? Are the GnuPG private keys on disk? Smartcard? TPM? YubiKey? HSM? Where is the server co-located, and who has access to it? I tried to do a bit of this, and discovered things like Trisquel having a DSA1024 key in its default apt trust store (although for fairness, it seems that apt by default does not trust such signatures). However, I m not certain understanding this more would scale to securing my machines against attacks on this infrastructure. Even people with the best intentions, and the state of the art hardware and software, will have problems. To increase my trust in Trisquel I set out to understand how it worked. To make it easier to sort out what the interesting parts of the Trisquel archive to audit further were, I created debdistdiff to produce human readable text output comparing one apt archive with another apt archive. There is a GitLab CI/CD cron job that runs this every day, producing output comparing Trisquel vs Ubuntu and PureOS vs Debian. Working with these output files has made me learn more about how the process works, and I even stumbled upon something that is likely a bug where Trisquel aramo was imported from Ubuntu jammy while it contained a couple of package (e.g., gcc-8, python3.9) that were removed for the final Ubuntu jammy release. After working on auditing the Trisquel archive manually that way, I realized that whatever I could tell from comparing Trisquel with Ubuntu, it would only be something based on a current snapshot of the archives. Tomorrow it may look completely different. What felt necessary was to audit the differences of the Trisquel archive continously. I was quite happy to have developed debdistdiff for one purpose (comparing two different archives like Trisquel and Ubuntu) and discovered that the tool could be used for another purpose (comparing the Trisquel archive at two different points in time). At this time I realized that I needed a log of all different apt archive metadata to be able to produce an audit log of the differences in time for the archive. I create manually curated git-repositories with the Release/InRelease and the Packages files for each architecture/component of the well-known distributions Trisquel, Ubuntu, Debian and PureOS. Eventually I wrote scripts to automate this, which are now published in the debdistget project. At this point, one of the early question about per-IP substitution of Release files were lingering in my mind. However with the tooling I now had available, coming up with a way to resolve this was simple! Merely have apt compute a SHA256 checksum of the just downloaded InRelease file, and see if my git repository had the same file. At this point I started reading the Apt source code, and now I had more doubts about the security of my systems than I ever had before. Oh boy how the name Apt has never before felt more Apt?! Oh well, we must leave some exercises for the students. Eventually I realized I wanted to touch as little of apt code basis as possible, and noticed the SigVerify::CopyAndVerify function called ExecGPGV which called apt-key verify which called GnuPG s gpgv. By setting Apt::Key::gpgvcommand I could get apt-key verify to call another tool than gpgv. See where I m going? I thought wrapping this up would now be trivial but for some reason the hash checksum I computed locally never matched what was on my server. I gave up and started working on other things instead. Today I came back to this idea, and started to debug exactly how the local files looked that I got from apt and how they differed from what I had in my git repositories, that came straight from the apt archives. Eventually I traced this back to SplitClearSignedFile which takes an InRelease file and splits it into two files, probably mimicking the (old?) way of distributing both Release and Release.gpg. So the clearsigned InRelease file is split into one cleartext file (similar to the Release file) and one OpenPGP signature file (similar to the Release.gpg file). But why didn t the cleartext variant of the InRelease file hash to the same value as the hash of the Release file? Sadly they differ by the final newline. Having solved this technicality, wrapping the pieces up was easy, and I came up with a project apt-canary that provides a script apt-canary-gpgv that verify the local apt release files against something I call a apt canary witness file stored at a URL somewhere. I m now running apt-canary on my Trisquel aramo laptop, a Trisquel nabia server, and Talos II ppc64el Debian machine. This means I have solved the per-IP substitution worries (or at least made them less likely to occur, having to send the same malicious release files to both GitLab and my system), and allow me to have an audit log of all release files that I actually use for installing and downloading packages. What do you think? There are clearly a lot of work and improvements to be made. This is a proof-of-concept implementation of an idea, but instead of refining it until perfection and delaying feedback, I wanted to publish this to get others to think about the problems and various ways to resolve them. Btw, I m going to be at FOSDEM 23 this weekend, helping to manage the Security Devroom. Catch me if you want to chat about this or other things. Happy Hacking!

Julian Andres Klode: Ubuntu 2022v1 secure boot key rotation and friends

This is the story of the currently progressing changes to secure boot on Ubuntu and the history of how we got to where we are.

taking a step back: how does secure boot on Ubuntu work? Booting on Ubuntu involves three components after the firmware:
  1. shim
  2. grub
  3. linux
Each of these is a PE binary signed with a key. The shim is signed by Microsoft s 3rd party key and embeds a self-signed Canonical CA certificate, and optionally a vendor dbx (a list of revoked certificates or binaries). grub and linux (and fwupd) are then signed by a certificate issued by that CA In Ubuntu s case, the CA certificate is sharded: Multiple people each have a part of the key and they need to meet to be able to combine it and sign things, such as new code signing certificates.

BootHole When BootHole happened in 2020, travel was suspended and we hence could not rotate to a new signing certificate. So when it came to updating our shim for the CVEs, we had to revoke all previously signed kernels, grubs, shims, fwupds by their hashes. This generated a very large vendor dbx which caused lots of issues as shim exported them to a UEFI variable, and not everyone had enough space for such large variables. Sigh. We decided we want to rotate our signing key next time. This was also when upstream added SBAT metadata to shim and grub. This gives a simple versioning scheme for security updates and easy revocation using a simple EFI variable that shim writes to and reads from.

Spring 2022 CVEs We still were not ready for travel in 2021, but during BootHole we developed the SBAT mechanism, so one could revoke a grub or shim by setting a single EFI variable. We actually missed rotating the shim this cycle as a new vulnerability was reported immediately after it, and we decided to hold on to it.

2022 key rotation and the fall CVEs This caused some problems when the 2nd CVE round came, as we did not have a shim with the latest SBAT level, and neither did a lot of others, so we ended up deciding upstream to not bump the shim SBAT requirements just yet. Sigh. Anyway, in October we were meeting again for the first time at a Canonical sprint, and the shardholders got together and created three new signing keys: 2022v1, 2022v2, and 2022v3. It took us until January before they were installed into the signing service and PPAs setup to sign with them. We also submitted a shim 15.7 with the old keys revoked which came back at around the same time. Now we were in a hurry. The 22.04.2 point release was scheduled for around middle of February, and we had nothing signed with the new keys yet, but our new shim which we need for the point release (so the point release media remains bootable after the next round of CVEs), required new keys. So how do we ensure that users have kernels, grubs, and fwupd signed with the new key before we install the new shim?

upgrade ordering grub and fwupd are simple cases: For grub, we depend on the new version. We decided to backport grub 2.06 to all releases (which moved focal and bionic up from 2.04), and kept the versioning of the -signed packages the same across all releases, so we were able to simply bump the Depends for grub to specify the new minimum version. For fwupd-efi, we added Breaks. (Actually, we also had a backport of the CVEs for 2.04 based grub, and we did publish that for 20.04 signed with the old keys before backporting 2.06 to it.) Kernels are a different story: There are about 60 kernels out there. My initial idea was that we could just add Breaks for all of them. So our meta package linux-image-generic which depends on linux-image-$(uname -r)-generic, we d simply add Breaks: linux-image-generic ( 5.19.0-31) and then adjust those breaks for each series. This would have been super annoying, but ultimately I figured this would be the safest option. This however caused concern, because it could be that apt decides to remove the kernel metapackage. I explored checking the kernels at runtime and aborting if we don t have a trusted kernel in preinst. This ensures that if you try to upgrade shim without having a kernel, it would fail to install. But this ultimately has a couple of issues:
  1. It aborts the entire transaction at that point, so users will be unable to run apt upgrade until they have a recent kernel.
  2. We cannot even guarantee that a kernel would be unpacked first. So even if you got a new kernel, apt/dpkg might attempt to unpack it first and then the preinst would fail because no kernel is present yet.
Ultimately we believed the danger to be too large given that no kernels had yet been released to users. If we had kernels pushed out for 1-2 months already, this would have been a viable choice. So in the end, I ended up modifying the shim packaging to install both the latest shim and the previous one, and an update-alternatives alternative to select between the two: In it s post-installation maintainer script, shim-signed checks whether all kernels with a version greater or equal to the running one are not revoked, and if so, it will setup the latest alternative with priority 100 and the previous with a priority of 50. If one or more of those kernels was signed with a revoked key, it will swap the priorities around, so that the previous version is preferred. Now this is fairly static, and we do want you to switch to the latest shim eventually, so I also added hooks to the kernel install to trigger the shim-signed postinst script when a new kernel is being installed. It will then update the alternatives based on the current set of kernels, and if it now points to the latest shim, reinstall shim and grub to the ESP. Ultimately this means that once you install your 2nd non-revoked kernel, or you install a non-revoked kernel and then reconfigure shim or the kernel, you will get the latest shim. When you install your first non-revoked kernel, your currently booted kernel is still revoked, so it s not upgraded immediately. This has a benefit in that you will most likely have two kernels you can boot without disabling secure boot.

regressions Of course, the first version I uploaded had still some remaining hardcoded shimx64 in the scripts and so failed to install on arm64 where shimaa64 is used. And if that were not enough, I also forgot to include support for gzip compressed kernels there. Sigh, I need better testing infrastructure to be able to easily run arm64 tests as well (I only tested the actual booting there, not the scripts). shim-signed migrated to the release pocket in lunar fairly quickly, but this caused images to stop working, because the new shim was installed into images, but no kernel was available yet, so we had to demote it to proposed and block migration. Despite all the work done for end users, we need to be careful to roll this out for image building.

another grub update for OOM issues. We had two grubs to release: First there was the security update for the recent set of CVEs, then there also was an OOM issue for large initrds which was blocking critical OEM work. We fixed the OOM issue by cherry-picking all 2.12 memory management patches, as well as the red hat patches to the loader we take from there. This ended up a fairly large patch set and I was hesitant to tie the security update to that, so I ended up pushing the security update everywhere first, and then pushed the OOM fixes this week. With the OOM patches, you should be able to boot initrds of between 400M and 1GB, it also depends on the memory layout of your machine and your screen resolution and background images. So OEM team had success testing 400MB irl, and I tested up to I think it was 1.2GB in qemu, I ran out of FAT space then and stopped going higher :D

other features in this round
  • Intel TDX support in grub and shim
  • Kernels are allocated as CODE now not DATA as per the upstream mm changes, might fix boot on X13s

am I using this yet? The new signing keys are used in:
  • shim-signed 1.54 on 22.10+, 1.51.3 on 22.04, 1.40.9 on 20.04, 1.37~18.04.13 on 18.04
  • grub2-signed 1.187.2~ or newer (binary packages grub-efi-amd64-signed or grub-efi-arm64-signed), 1.192 on 23.04.
  • fwupd-signed 1.51~ or newer
  • various linux updates. Check apt changelog linux-image-unsigned-$(uname -r) to see if Revoke & rotate to new signing key (LP: #2002812) is mentioned in there to see if it signed with the new key.
If you were able to install shim-signed, your grub and fwupd-efi will have the correct version as that is ensured by packaging. However your shim may still point to the old one. To check which shim will be used by grub-install, you can check the status of the shimx64.efi.signed or (on arm64) shimaa64.efi.signed alternative. The best link needs to point to the file ending in latest:
$ update-alternatives --display shimx64.efi.signed
shimx64.efi.signed - auto mode
  link best version is /usr/lib/shim/shimx64.efi.signed.latest
  link currently points to /usr/lib/shim/shimx64.efi.signed.latest
  link shimx64.efi.signed is /usr/lib/shim/shimx64.efi.signed
/usr/lib/shim/shimx64.efi.signed.latest - priority 100
/usr/lib/shim/shimx64.efi.signed.previous - priority 50
If it does not, but you have installed a new kernel compatible with the new shim, you can switch immediately to the new shim after rebooting into the kernel by running dpkg-reconfigure shim-signed. You ll see in the output if the shim was updated, or you can check the output of update-alternatives as you did above after the reconfiguration has finished. For the out of memory issues in grub, you need grub2-signed 1.187.3~ (same binaries as above).

how do I test this (while it s in proposed)?
  1. upgrade your kernel to proposed and reboot into that
  2. upgrade your grub-efi-amd64-signed, shim-signed, fwupd-signed to proposed.
If you already upgraded your shim before your kernel, don t worry:
  1. upgrade your kernel and reboot
  2. run dpkg-reconfigure shim-signed
And you ll be all good to go.

deep dive: uploading signed boot assets to Ubuntu For each signed boot asset, we build one version in the latest stable release and the development release. We then binary copy the built binaries from the latest stable release to older stable releases. This process ensures two things: We know the next stable release is able to build the assets and we also minimize the number of signed assets. OK, I lied. For shim, we actually do not build in the development release but copy the binaries upward from the latest stable, as each shim needs to go through external signing. The entire workflow looks something like this:
  1. Upload the unsigned package to one of the following build PPAs:
  2. Upload the signed package to the same PPA
  3. For stable release uploads:
    • Copy the unsigned package back across all stable releases in the PPA
    • Upload the signed package for stable releases to the same PPA with ~<release>.1 appended to the version
  4. Submit a request to canonical-signing-jobs to sign the uploads. The signing job helper copies the binary -unsigned packages to the primary-2022v1 PPA where they are signed, creating a signing tarball, then it copies the source package for the -signed package to the same PPA which then downloads the signing tarball during build and places the signed assets into the -signed deb. Resulting binaries will be placed into the proposed PPA: https://launchpad.net/~ubuntu-uefi-team/+archive/ubuntu/proposed
  5. Review the binaries themselves
  6. Unembargo and binary copy the binaries from the proposed PPA to the proposed-public PPA: https://launchpad.net/~ubuntu-uefi-team/+archive/ubuntu/proposed-public. This step is not strictly necessary, but it enables tools like sru-review to work, as they cannot access the packages from the normal private proposed PPA.
  7. Binary copy from proposed-public to the proposed queue(s) in the primary archive
Lots of steps!

WIP As of writing, only the grub updates have been released, other updates are still being verified in proposed. An update for fwupd in bionic will be issued at a later point, removing the EFI bits from the fwupd 1.2 packaging and using the separate fwupd-efi project instead like later release series.

31 January 2023

Jonathan McDowell: Enabling retrogaming with Kodi on Debian

For some reason my son has started to be really into watching playthroughs of Mario and similar games on Youtube. I don t understand the appeal, but it s less distracting as background than Paw Patrol, so I m not complaining. He s not quite at the stage he s ready to play the games himself, but it s coming. So I figured it would be neat to sort out some retrogaming bits ready for when that happens. I already have a Kodi box underneath the TV; it doesn t get as much use these days as a lot of our viewing is through commercial streaming services, but it s got all of our DVDs ripped so is still useful. Recent version of Kodi have support for games as well, so I decided it would be perfect if I could tie in to that. However. The normal ways of doing this seems to be to download someone s pre-rolled setup, and I d much rather be able to get the bits I need from Debian, as that s what the machine is running (it does a few minor things other than Kodi). The best retrogaming environment out there seems to be RetroArch. It s available for Linux/OS X/Windows and RetroPie provides a nice easy standalone setup if you re not interested in the Kodi side. If you are then game.libretro provides a wrapper for libretro cores under Kodi. This seemed like the right track. Unfortunately RetroArch and related packages were in need of some love in Debian. So I ended up engaging in some yak shaving to try and get to where I wanted to be. First up was RetroArch itself, which was over 4 years out of date, at 1.7.3. It turned out that wanted an updated assets package which contains the necessary icons etc for the interface. RetroArch is only a frontend. To actually play games you need a suitable core. The first one I tried was genesisplusgx (I have fond memories of Sonic from the Master System era), which again was several years out of date. I pulled recent git (I wish folk would tag releases at least every now and then) and updated things. And successfully managed to play Sonic (badly, I am way out of practice). genesisplusgx is in non-free, due to a prohibition on commercial distribution. So it s not actually part of Debian. I switched my attention to libretro-bsnes-mercury, which would then allow SNES emulation and is part of main. Again, not to hard to update, some packaging cleanups, and I was playing Super Mario. Again, badly. That meant I knew I had working emulation with libretro cores. It was time to integrate with Kodi. That meant taking game.libretro, filing an ITP and doing a bunch of bits to get it ready to upload (including introducing a retroarch-dev binary package that contains the appropriate include files as part of retroarch). It sat in NEW for a while (including an initial reject because I d missed an attribution in the debian/copyright), and was accepted yesterday. There s a final piece of the puzzle, and that s the Kodi config that ties together the libretro core with game.libretro and presents the emulator to Kodi as a fully fledged add-on. The kodi-game folk have a neat tool, kodi-game-scripting which automates the heavy lifting of producing this config. I ve done some local modifications that make it bit more useful for producing config that can be embedded in the Debian libretro-* packages directly, which I should upload somewhere but it s all a bit rough n ready at present. It was enough to allow me to produce some kodi-game-libretro-bsnes-* packages as part of libretro-bsnes-mercury. With that complete, all the packages needed for playing SNES games under Kodi are now present in Debian. I need to upload libretro-bsnes-mercury to unstable (it went to experimental while waiting for kodi-game-libretro to be accepted), and kodi-game-libretro needs another source-only upload, but once that s done both should be in good shape to migrate to testing and be part of the upcoming bookworm release. What else is there to do? I d like to get Kodi config included in the other libretro packages that are already part of Debian. That s going to need the Controller Topology Project to be packaged so that the controller details are available (I was lucky in that the SNES controller is already part of the Kodi package). I need to work out if I can turn kodi-game-scripting into some sort of dh helper to help automate things. But I ve done some local testing with genesisplusgx and it works fine as expected. The other thing is that games are not yet first class citizens in Kodi; the normal browser interface you get for movies, music and TV shows is not available for games. Currently I ve been trying out the ROM Collection Browser though I find its automated scraping isn t as good as I d like. A friend has recommended the Advanced Emulator Launcher but I haven t taken a look at it. Either way I d like to ultimately get one of them packaged up as well, though not in time for bookworm. Anyway. My hope is that these updated and new packages prove useful to someone else. You can tell I m biased towards 90s era consoles, but if you ve enough CPU grunt there are a bunch of more recent cores available too. Big thanks to the Debian FTP Master team for letting these through NEW so close to release. And all the upstream devs - RetroArch is a great framework from my perspective as a user, and the Kodi Game folk have done massive amounts of work that made my life much easier when preparing things for Debian.

30 January 2023

Arturo Borrero Gonz lez: Debian and the adventure of the screen resolution

Post logo I read somewhere a nice meme about Linux: Do you want an operating system or do you want an adventure? I love it, because it is so true. What you are about to read is my adventure to set a usable screen resolution in a fresh Debian testing installation. The context is that I have two different Lenovo Thinkpad laptops with 16 screen and nvidia graphic cards. They are both installed with the latest Debian testing. I use the closed-source nvidia drivers (they seem to work better than the nouveau module). The desktop manager and environment that I use is lightdm + XFCE4. The monitor native resolution in both machines is very high: 3840x2160 (or 4K UHD if you will). The thing is that both laptops show an identical problem: when freshly installed with the Debian default config, the native resolution is in use. For a 16 screen laptop, this high resolution means that the font is tiny. Therefore, the raw native resolution renders the machine almost unusable. This is a picture of what you get by running htop in the console (tty1, the terminal you would get by hitting CTRL+ALT+F1) with the default install: Linux tty console with high resolution and tiny fonts Everything in the system is affected by this:
  1. the grub menu is unreadable. Thanksfully the right option is selected by default.
  2. the tty console, with the boot splash by systemd is unreadable as well. There are some colors, so you at least see some systemd stuff happening in green .
  3. when lightdm starts, the resolution keeps being very high. Can barely click the login button.
  4. when XFCE4 starts, it is a pain to navigate the menu and click the right buttons to set a more reasonable resolution.
The adventure begins after installing the system. Each of these four points must be fixed by hand by the user. XFCE4 Point #4 is the easiest. Navigate with the mouse pointer to the tiny Applications menu, then Settings, then Displays. This is more or less the same in every other desktop operating system. There are no further actions required to persist this setting. Thanks you XFCE4. lightdm Point #3, about lightdm, is more tricky to solve. It involves running xrandr when lightdm sets up the display. Nobody will tell you this trick. You have to search for it on the internet. Thankfully is a common problem, and a person who knows what to search for can find good results. The file /etc/lightdm/lightdm.conf needs to contain something like this:
[LightDM]
[Seat:*]
# set up correct display resolution
display-setup-script=sh -c -- "xrandr -s 1920x1080"
By the way, depending on your system hardware setup, you may also need an additional call to xrandr here. If you want to plug in an HDMI monitor, chances are you require something like xrandr --setprovideroutputsource NVIDIA-G0 modesetting && xrandr --auto to instruct the NVIDIA graphic card to work will with the kernel graphic system. In my case, one of my laptops require it, so I have:
[LightDM]
[Seat:*]
# don't ask me to type my username
greeter-hide-users=false
# set up correct display resolution, and prepare NVIDIA card for HDMI output
display-setup-script=sh -c "xrandr -s 1920x1080 && xrandr --setprovideroutputsource NVIDIA-G0 modesetting && xrandr --auto"
grub Point #1 about the grub menu is also not trivial to solve, but also widely known on the internet. Grub allows you to set arbitrary graphical modes. In Debian systems, adding something like GRUB_GFXMODE=1024x768 to /etc/default/grub and then running sudo update-grub should do the magic. console So we get to point #2 about the tty1 console. For months, I ve been investing my scarce personal time into trying to solve this annoyance. There are a lot of conflicting information about this on the internet. Plenty of misleading solutions, essays about framebuffer, kernel modeset, and other stuff I don t want to read just to get my tty1 in a readable status. People point in different directions, like using GRUB_GFXPAYLOAD_LINUX=keep in /etc/default/grub. Which is a good solution, but won t work: my best bet is that the kernel indeed keeps the resolution as told by grub, but the moment systemd loads the nvidia driver, it enables 4K in the display and the console gets the high resolution. Actually, for a few weeks, I blamed plymouth. Because the plymouth service is loaded early by systemd, it could be responsible for setting some of the display settings. It actually contains some (undocummented) DeviceScale configuration option that is seemingly aimed to integrate into high resolution scenarios. I played with it to no avail. Some folks from IRC suggested reconfiguring the console-font package. Back-then unknown to me. Running sudo dpkg-reconfigure console-font would indeed show a menu to select some preferences for the console, including font size. But apparently, a freshly installed system already uses the biggest possible, so this was a dead end. Other option I evaluted for a few days was touching the kernel framebuffer setting. I honestly don t understand this, and all the solutions pointing to use fbset didn t work for me anyways. This is the default framebuffer configuration in one of the laptops:
user@debian:~$ fbset -i

mode "3840x2160"
    geometry 3840 2160 3840 2160 32
    timings 0 0 0 0 0 0 0
    accel true
    rgba 8/16,8/8,8/0,0/0
endmode
Frame buffer device information:
    Name        : i915drmfb
    Address     : 0
    Size        : 33177600
    Type        : PACKED PIXELS
    Visual      : TRUECOLOR
    XPanStep    : 1
    YPanStep    : 1
    YWrapStep   : 0
    LineLength  : 15360
    Accelerator : No
Playing with these numbers, I was able to modify the geometry of the console, only to reduce the panel to a tiny square in the console display (with equally small fonts anyway). If it was possible to scale or resize the panel in other way, I was unable to understand how to do so by reading the associated docs. One day, out of despair, I tried disabling kernel modesetting (or KMS). It indeed got me a more readable tty1, only to prevent the whole graphic stack from starting, with Xorg complaining about the lack of kernel modeset. After lots of wasted time, I decided to blame the NVIDIA graphic card. Because why not: a closed source module in my system looks fishy. I registered in their official forum and wrote a message about my suspicion on the module, asking for advice on how to modify the driver default resolution. I was hoping that something like modprobe nvidia my_desired_resolution=1920x1080 could exist. Apparently not :-( I was about to give up. I had walked every corner of the known internet. I even tried summoning the ancient gods, I used ChatGPT. I asked the AI god for mercy, for a working solution to no avail. Then I decided to change the kind of queries I was issuing the search engines (don t ask me, I no longer remember). Eventually I landed in this askubuntu.com page. The question described the exact same problem I was experiencing. Finally, that was encouraging! I was not alone in my adventure after all! The solution section included a font size I hadn t seen before in my previous tests: 16x32. More excitement! I did all the steps. I installed the xfonts-terminus package, and in the file /etc/default/console-setup I put:
ACTIVE_CONSOLES="/dev/tty[1-6]"
CHARMAP="ISO-8859-15"
CODESET="guess"
FONTFACE="Terminus"
FONTSIZE="16x32"
VIDEOMODE=
Then I run setupcon from a tty, and the miracle happened! I finally got a bigger font in the tty1 console! Turned out a potential solution was about playing with console-setup, which I had tried wihtout success before. I m not even sure if the additional package was required. This is how my console looks now: Linux tty console with high resolution but not so tiny fonts The truth is the solution is satisfying only to a degree. I m a person with good eyesight and can work with these bit larger fonts. I m not sure if I can get larger fonts using this method, honestly. After some search, I discovered that some folks already managed to describe the problem in detail and filed a proper bug report in Debian, see #595696 opened more than 10 years ago. 2023 is the year of linux on the desktop Nope. I honestly don t see how this disconnected pile of settings can be all reconciled together. Can we please have a systemd-whatever that homogeinizes all of this mess? I m referring to grub + kernel drivers + console + lightdm + XFCE4. Next adventure When I lock the desktop (with CTRL+ALT+L) and close the laptop lid to suspend it, then reopen it, type the login info into the lightdm greeter, then the desktop environment never loads, black screen. I have already tried the first few search results without luck. Perhaps the nvidia card is to blame this time? Perhaps poorly coupled power management by the different system software pieces? Who knows what s going on here. This will probably be my next Debian desktop adventure.
Russell Coker: Links January 2023

The Intercept has an amusing and interesting article about senior Facebook employees testifying that they don t know where Facebook stores all it s data on users [1]. One lesson all programmers can learn from this is to document all these things in an orderly manner. Cory Doctorow wrote a short informative article about inflation from a modern monetary theory perspective [2]. Russ Allbery wrote an insightful blog post about effecive altruism and respect for disadvantaged people [3]. GiveDirectly sounds good. The Conversation has an interesting article about the Google and Apple app stores providing different versions of apps for users in different regions [4]. Apparently there are specific versions to comply with GDPR and versions that differ in adverts. The hope that GDPR would affect enough people to become essentially a world-wide standard was apparently overly optimistic. We need political lobbying in all countries for laws like the GDPR to force the app stores to give us the better versions of apps. Arya Voronova wrote an informative article about USB-C and extension or data blocker cables [5]. USB just keeps getting more horrible in technology while getting more useful in functionality. Laptops and phones catching fire will probably become more common in future. John McBride wrote an insightful article about the problems in the security of the software supply chain [6]. His main suggestion for addressing problems is If you are on a team that relies on some piece of open source software, allocate real engineering time to contributing , the problem with this is that real engineering time means real money and companies don t want to do that. Maybe having companies contribute moderate amounts of money to a foundation that hires people would be a viable option. Toms Guide has an interesting article describing problems with the Tesla [7]. It doesn t cover things like autopilot driving over children and bikers but instead covers issues of the user interface that make it less pleasant to drive and also remove concentration from the road. The BBC has an interesting article about the way mathematical skill is correlated with the way language is used to express numbers [8]. Every country with a lesser way of expressing numbers should switch to some variation of the East-Asian way. Science 2.0 has an interesting blog post about the JP Aerospace plans to use airships to get most of the way through the atmosphere and then a plane to get to orbit [9]. It s a wild idea but seems plausible. The idea of going to space in balloons seems considerably scarier to me than the current space craft. Interesting list of red team and physical entry gear with links to YouTube videos showing how to use them [10]. The Verge has an informative summary of the way Elon mismanaged Twitter after taking it over [11].

29 January 2023

Petter Reinholdtsen: Is the desktop recommending your program for opening its files?

Linux desktop systems have standardized how programs present themselves to the desktop system. If a package include a .desktop file in /usr/share/applications/, Gnome, KDE, LXDE, Xfce and the other desktop environments will pick up the file and use its content to generate the menu of available programs in the system. A lesser known fact is that a package can also explain to the desktop system how to recognize the files created by the program in question, and use it to open these files on request, for example via a GUI file browser. A while back I ran into a package that did not tell the desktop system how to recognize its files and was not used to open its files in the file browser and fixed it. In the process I wrote a simple debian/tests/ script to ensure the setup keep working. It might be useful for other packages too, to ensure any future version of the package keep handling its own files. For this to work the file format need a useful MIME type that can be used to identify the format. If the file format do not yet have a MIME type, it should define one and preferably also register it with IANA to ensure the MIME type string is reserved. The script uses the xdg-mime program from xdg-utils to query the database of standardized package information and ensure it return sensible values. It also need the location of an example file for xdg-mime to guess the format of.
#!/bin/sh
#
# Author: Petter Reinholdtsen
# License: GPL v2 or later at your choice.
#
# Validate the MIME setup, making sure motor types have
# application/vnd.openmotor+yaml associated with them and is connected
# to the openmotor desktop file.
retval=0
mimetype="application/vnd.openmotor+yaml"
testfile="test/data/real/o3100/motor.ric"
mydesktopfile="openmotor.desktop"
filemime="$(xdg-mime query filetype "$testfile")"
if [ "$mimetype" != "$filemime" ] ; then
    retval=1
    echo "error: xdg-mime claim motor file MIME type is $filemine, not $mimetype"
else
    echo "success: xdg-mime report correct mime type $mimetype for motor file"
fi
desktop=$(xdg-mime query default "$mimetype")
if [ "$mydesktopfile" != "$desktop" ]; then
    retval=1
    echo "error: xdg-mime claim motor file should be handled by $desktop, not $mydesktopfile"
else
    echo "success: xdg-mime agree motor file should be handled by $mydesktopfile"
fi
exit $retval
It is a simple way to ensure your users are not very surprised when they try to open one of your file formats in their file browser. As usual, if you use Bitcoin and want to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Next.

Previous.