Search Results: "nate"

29 June 2022

Aigars Mahinovs: Long travel in an electric car

Since the first week of April 2022 I have (finally!) changed my company car from a plug-in hybrid to a fully electic car. My new ride, for the next two years, is a BMW i4 M50 in Aventurine Red metallic. An ellegant car with very deep and memorable color, insanely powerful (544 hp/795 Nm), sub-4 second 0-100 km/h, large 84 kWh battery (80 kWh usable), charging up to 210 kW, top speed of 225 km/h and also very efficient (which came out best in this trip) with WLTP range of 510 km and EVDB real range of 435 km. The car also has performance tyres (Hankook Ventus S1 evo3 245/45R18 100Y XL in front and 255/45R18 103Y XL in rear all at recommended 2.5 bar) that have reduced efficiency. So I wanted to document and describe how was it for me to travel ~2000 km (one way) with this, electric, car from south of Germany to north of Latvia. I have done this trip many times before since I live in Germany now and travel back to my relatives in Latvia 1-2 times per year. This was the first time I made this trip in an electric car. And as this trip includes both travelling in Germany (where BEV infrastructure is best in the world) and across Eastern/Northen Europe, I believe that this can be interesting to a few people out there. Normally when I travelled this trip with a gasoline/diesel car I would normally drive for two days with an intermediate stop somewhere around Warsaw with about 12 hours of travel time in each day. This would normally include a couple bathroom stops in each day, at least one longer lunch stop and 3-4 refueling stops on top of that. Normally this would use at least 6 liters of fuel per 100 km on average with total usage of about 270 liters for the whole trip (or about 540 just in fuel costs, nowadays). My (personal) quirk is that both fuel and recharging of my (business) car inside Germany is actually paid by my employer, so it is useful for me to charge up (or fill up) at the last station in Gemany before driving on. The plan for this trip was made in a similar way as when travelling with a gasoline car: travelling as fast as possible on German Autobahn network to last chargin stop on the A4 near G rlitz, there charging up as much as reasonable and then travelling to a hotel in Warsaw, charging there overnight and travelling north towards Ionity chargers in Lithuania from where reaching the final target in north of Latvia should be possible. How did this plan meet the reality? Travelling inside Germany with an electric car was basically perfect. The most efficient way would involve driving fast and hard with top speed of even 180 km/h (where possible due to speed limits and traffic). BMW i4 is very efficient at high speeds with consumption maxing out at 28 kWh/100km when you actually drive at this speed all the time. In real situation in this trip we saw consumption of 20.8-22.2 kWh/100km in the first legs of the trip. The more traffic there is, the more speed limits and roadworks, the lower is the average speed and also the lower the consumption. With this kind of consumption we could comfortably drive 2 hours as fast as we could and then pick any fast charger along the route and in 26 minutes at a charger (50 kWh charged total) we'd be ready to drive for another 2 hours. This lines up very well with recommended rest stops for biological reasons (bathroom, water or coffee, a bit of movement to get blood circulating) and very close to what I had to do anyway with a gasoline car. With a gasoline car I had to refuel first, then park, then go to bathroom and so on. With an electric car I can do all of that while the car is charging and in the end the total time for a stop is very similar. Also not that there was a crazy heat wave going on and temperature outside was at about 34C minimum the whole day and hitting 40C at one point of the trip, so a lot of power was used for cooling. The car has a heat pump standard, but it still was working hard to keep us cool in the sun. The car was able to plan a charging route with all the charging stops required and had all the good options (like multiple intermediate stops) that many other cars (hi Tesla) and mobile apps (hi Google and Apple) do not have yet. There are a couple bugs with charging route and display of current route guidance, those are already fixed and will be delivered with over the air update with July 2022 update. Another good alterantive is the ABRP (A Better Route Planner) that was specifically designed for electric car routing along the best route for charging. Most phone apps (like Google Maps) have no idea about your specific electric car - it has no idea about the battery capacity, charging curve and is missing key live data as well - what is the current consumption and remaining energy in the battery. ABRP is different - it has data and profiles for almost all electric cars and can also be linked to live vehicle data, either via a OBD dongle or via a new Tronity cloud service. Tronity reads data from vehicle-specific cloud service, such as MyBMW service, saves it, tracks history and also re-transmits it to ABRP for live navigation planning. ABRP allows for options and settings that no car or app offers, for example, saying that you want to stop at a particular place for an hour or until battery is charged to 90%, or saying that you have specific charging cards and would only want to stop at chargers that support those. Both the car and the ABRP also support alternate routes even with multiple intermediate stops. In comparison, route planning by Google Maps or Apple Maps or Waze or even Tesla does not really come close. After charging up in the last German fast charger, a more interesting part of the trip started. In Poland the density of high performance chargers (HPC) is much lower than in Germany. There are many chargers (west of Warsaw), but vast majority of them are (relatively) slow 50kW chargers. And that is a difference between putting 50kWh into the car in 23-26 minutes or in 60 minutes. It does not seem too much, but the key bit here is that for 20 minutes there is easy to find stuff that should be done anyway, but after that you are done and you are just waiting for the car and if that takes 4 more minutes or 40 more minutes is a big, perceptual, difference. So using HPC is much, much preferable. So we put in the Ionity charger near Lodz as our intermediate target and the car suggested an intermediate stop at a Greenway charger by Katy Wroclawskie. The location is a bit weird - it has 4 charging stations with 150 kW each. The weird bits are that each station has two CCS connectors, but only one parking place (and the connectors share power, so if two cars were to connect, each would get half power). Also from the front of the location one can only see two stations, the otehr two are semi-hidden around a corner. We actually missed them on the way to Latvia and one person actually waited for the charger behind us for about 10 minutes. We only discovered the other two stations on the way back. With slower speeds in Poland the consumption goes down to 18 kWh/100km which translates to now up to 3 hours driving between stops. At the end of the first day we drove istarting from Ulm from 9:30 in the morning until about 23:00 in the evening with total distance of about 1100 km, 5 charging stops, starting with 92% battery, charging for 26 min (50 kWh), 33 min (57 kWh + lunch), 17 min (23 kWh), 12 min (17 kWh) and 13 min (37 kW). In the last two chargers you can see the difference between a good and fast 150 kW charger at high battery charge level and a really fast Ionity charger at low battery charge level, which makes charging faster still. Arriving to hotel with 23% of battery. Overnight the car charged from a Porsche Destination Charger to 87% (57 kWh). That was a bit less than I would expect from a full power 11kW charger, but good enough. Hotels should really install 11kW Type2 chargers for their guests, it is a really significant bonus that drives more clients to you. The road between Warsaw and Kaunas is the most difficult part of the trip for both driving itself and also for charging. For driving the problem is that there will be a new highway going from Warsaw to Lithuanian border, but it is actually not fully ready yet. So parts of the way one drives on the new, great and wide highway and parts of the way one drives on temporary roads or on old single lane undivided roads. And the most annoying part is navigating between parts as signs are not always clear and the maps are either too old or too new. Some maps do not have the new roads and others have on the roads that have not been actually build or opened to traffic yet. It's really easy to loose ones way and take a significant detour. As far as charging goes, basically there is only the slow 50 kW chargers between Warsaw and Kaunas (for now). We chose to charge on the last charger in Poland, by Suwalki Kaufland. That was not a good idea - there is only one 50 kW CCS and many people decide the same, so there can be a wait. We had to wait 17 minutes before we could charge for 30 more minutes just to get 18 kWh into the battery. Not the best use of time. On the way back we chose a different charger in Lomza where would have a relaxed dinner while the car was charging. That was far more relaxing and a better use of time. We also tried charging at an Orlen charger that was not recommended by our car and we found out why. Unlike all other chargers during our entire trip, this charger did not accept our universal BMW Charging RFID card. Instead it demanded that we download their own Orlen app and register there. The app is only available in some countries (and not in others) and on iPhone it is only available in Polish. That is a bad exception to the rule and a bad example. This is also how most charging works in USA. Here in Europe that is not normal. The normal is to use a charging card - either provided from the car maker or from another supplier (like PlugSufring or Maingau Energy). The providers then make roaming arrangements with all the charging networks, so the cards just work everywhere. In the end the user gets the prices and the bills from their card provider as a single monthly bill. This also saves all any credit card charges for the user. Having a clear, separate RFID card also means that one can easily choose how to pay for each charging session. For example, I have a corporate RFID card that my company pays for (for charging in Germany) and a private BMW Charging card that I am paying myself for (for charging abroad). Having the car itself authenticate direct with the charger (like Tesla does) removes the option to choose how to pay. Having each charge network have to use their own app or token bring too much chaos and takes too much setup. The optimum is having one card that works everywhere and having the option to have additional card or cards for specific purposes. Reaching Ionity chargers in Lithuania is again a breath of fresh air - 20-24 minutes to charge 50 kWh is as expected. One can charge on the first Ionity just enough to reach the next one and then on the second charger one can charge up enough to either reach the Ionity charger in Adazi or the final target in Latvia. There is a huge number of CSDD (Road Traffic and Safety Directorate) managed chargers all over Latvia, but they are 50 kW chargers. Good enough for local travel, but not great for long distance trips. BMW i4 charges at over 50 kW on a HPC even at over 90% battery state of charge (SoC). This means that it is always faster to charge up in a HPC than in a 50 kW charger, if that is at all possible. We also tested the CSDD chargers - they worked without any issues. One could pay with the BMW Charging RFID card, one could use the CSDD e-mobi app or token and one could also use Mobilly - an app that you can use in Latvia for everything from parking to public transport tickets or museums or car washes. We managed to reach our final destination near Aluksne with 17% range remaining after just 3 charging stops: 17+30 min (18 kWh), 24 min (48 kWh), 28 min (36 kWh). Last stop we charged to 90% which took a few extra minutes that would have been optimal. For travel around in Latvia we were charging at our target farmhouse from a normal 3 kW Schuko EU socket. That is very slow. We charged for 33 hours and went from 17% to 94%, so not really full. That was perfectly fine for our purposes. We easily reached Riga, drove to the sea and then back to Aluksne with 8% still in reserve and started charging again for the next trip. If it were required to drive around more and charge faster, we could have used the normal 3-phase 440V connection in the farmhouse to have a red CEE 16A plug installed (same as people use for welders). BMW i4 comes standard with a new BMW Flexible Fast Charger that has changable socket adapters. It comes by default with a Schucko connector in Europe, but for 90 one can buy an adapter for blue CEE plug (3.7 kW) or red CEE 16A or 32A plugs (11 kW). Some public charging stations in France actually use the blue CEE plugs instead of more common Type2 electric car charging stations. The CEE plugs are also common in camping parking places. On the way back the long distance BEV travel was already well understood and did not cause us any problem. From our destination we could easily reach the first Ionity in Lithuania, on the Panevezhis bypass road where in just 8 minutes we got 19 kWh and were ready to drive on to Kaunas, there a longer 32 minute stop before the charging desert of Suwalki Gap that gave us 52 kWh to 90%. That brought us to a shopping mall in Lomzha where we had some food and charged up 39 kWh in lazy 50 minutes. That was enough to bring us to our return hotel for the night - Hotel 500W in Strykow by Lodz that has a 50kW charger on site, while we were having late dinner and preparing for sleep, the car easily recharged to full (71 kWh in 95 minutes), so I just moved it from charger to a parking spot just before going to sleep. Really easy and well flowing day. Second day back went even better as we just needed an 18 minute stop at the same Katy Wroclawskie charger as before to get 22 kWh and that was enough to get back to Germany. After that we were again flying on the Autobahn and charging as needed, 15 min (31 kWh), 23 min (48 kWh) and 31 min (54 kWh + food). We started the day on about 9:40 and were home at 21:40 after driving just over 1000 km on that day. So less than 12 hours for 1000 km travelled, including all charging, bio stops, food and some traffic jams as well. Not bad. Now let's take a look at all the apps and data connections that a technically minded customer can have for their car. Architecturally the car is a network of computers by itself, but it is very secured and normally people do not have any direct access. However, once you log in into the car with your BMW account the car gets your profile info and preferences (seat settings, navigation favorites, ...) and the car then also can start sending information to the BMW backend about its status. This information is then available to the user over multiple different channels. There is no separate channel for each of those data flow. The data only goes once to the backend and then all other communication of apps happens with the backend. First of all the MyBMW app. This is the go-to for everything about the car - seeing its current status and location (when not driving), sending commands to the car (lock, unlock, flash lights, pre-condition, ...) and also monitor and control charging processes. You can also plan a route or destination in the app in advance and then just send it over to the car so it already knows where to drive to when you get to the car. This can also integrate with calendar entries, if you have locations for appointments, for example. This also shows full charging history and allows a very easy export of that data, here I exported all charging sessions from June and then trimmed it back to only sessions relevant to the trip and cut off some design elements to have the data more visible. So one can very easily see when and where we were charging, how much power we got at each spot and (if you set prices for locations) can even show costs. I've already mentioned the Tronity service and its ABRP integration, but it also saves the information that it gets from the car and gathers that data over time. It has nice aspects, like showing the driven routes on a map, having ways to do business trip accounting and having good calendar view. Sadly it does not correctly capture the data for charging sessions (the amounts are incorrect). Update: after talking to Tronity support, it looks like the bug was in the incorrect value for the usable battery capacity for my car. They will look into getting th eright values there by default, but as a workaround one can edit their car in their system (after at least one charging session) and directly set the expected battery capacity (usable) in the car properties on the Tronity web portal settings. One other fun way to see data from your BMW is using the BMW integration in Home Assistant. This brings the car as a device in your own smart home. You can read all the variables from the car current status (and Home Asisstant makes cute historical charts) and you can even see interesting trends, for example for remaining range shows much higher value in Latvia as its prediction is adapted to Latvian road speeds and during the trip it adapts to Polish and then to German road speeds and thus to higher consumption and thus lower maximum predicted remaining range. Having the car attached to the Home Assistant also allows you to attach the car to automations, both as data and event source (like detecting when car enters the "Home" zone) and also as target, so you could flash car lights or even unlock or lock it when certain conditions are met. So, what in the end was the most important thing - cost of the trip? In total we charged up 863 kWh, so that would normally cost one about 290 , which is close to half what this trip would have costed with a gasoline car. Out of that 279 kWh in Germany (paid by my employer) and 154 kWh in the farmhouse (paid by our wonderful relatives :D) so in the end the charging that I actually need to pay adds up to 430 kWh or about 150 . Typically, it took about 400 in fuel that I had to pay to get to Latvia and back. The difference is really nice! In the end I believe that there are three different ways of charging:
  • incidental charging - this is wast majority of charging in the normal day-to-day life. The car gets charged when and where it is convinient to do so along the way. If we go to a movie or a shop and there is a chance to leave the car at a charger, then it can charge up. Works really well, does not take extra time for charging from us.
  • fast charging - charging up at a HPC during optimal charging conditions - from relatively low level to no more than 70-80% while you are still doing all the normal things one would do in a quick stop in a long travel process: bio things, cleaning the windscreen, getting a coffee or a snack.
  • necessary charging - charging from a whatever charger is available just enough to be able to reach the next destination or the next fast charger.
The last category is the only one that is really annoying and should be avoided at all costs. Even by shifting your plans so that you find something else useful to do while necessary charging is happening and thus, at least partially, shifting it over to incidental charging category. Then you are no longer just waiting for the car, you are doing something else and the car magically is charged up again. And when one does that, then travelling with an electric car becomes no more annoying than travelling with a gasoline car. Having more breaks in a trip is a good thing and makes the trips actually easier and less stressfull - I was more relaxed during and after this trip than during previous trips. Having the car air conditioning always be on, even when stopped, was a godsend in the insane heat wave of 30C-38C that we were driving trough. Final stats: 4425 km driven in the trip. Average consumption: 18.7 kWh/100km. Time driving: 2 days and 3 hours. Car regened 152 kWh. Charging stations recharged 863 kWh. Questions? You can use this i4talk forum thread or this Twitter thread to ask them to me.

27 June 2022

Russ Allbery: Review: Light from Uncommon Stars

Review: Light from Uncommon Stars, by Ryka Aoki
Publisher: Tor
Copyright: 2021
ISBN: 1-250-78907-9
Format: Kindle
Pages: 371
Katrina Nguyen is an young abused transgender woman. As the story opens, she's preparing to run away from home. Her escape bag is packed with meds, clothes, her papers, and her violin. The note she is leaving for her parents says that she's going to San Francisco, a plausible lie. Her actual destination is Los Angeles, specifically the San Gabriel Valley, where a man she met at a queer youth conference said he'd give her a place to sleep. Shizuka Satomi is the Queen of Hell, the legendary uncompromising violin teacher responsible for six previous superstars, at least within the limited world of classical music. She's wealthy, abrasive, demanding, and intimidating, and unbeknownst to the rest of the world she has made a literal bargain with Hell. She has to deliver seven souls, seven violin players who want something badly enough that they'll bargain with Hell to get it. Six have already been delivered in spectacular fashion, but she's running out of time to deliver the seventh before her own soul is forfeit. Tamiko Grohl, an up-and-coming violinist from her native Los Angeles, will hopefully be the seventh. Lan Tran is a refugee and matriarch of a family who runs Starrgate Donut. She and her family didn't flee another unstable or inhospitable country. They fled the collapsing Galactic Empire, securing their travel authorization by promising to set up a tourism attraction. Meanwhile, she's careful to give cops free donuts and to keep their advanced technology carefully concealed. The opening of this book is unlikely to be a surprise in general shape. Most readers would expect Katrina to end up as Satomi's student rather than Tamiko, and indeed she does, although not before Katrina has a very difficult time. Near the start of the novel, I thought "oh, this is going to be hurt/comfort without a romantic relationship," and it is. But it then goes beyond that start into a multifaceted story about complexity, resilience, and how people support each other. It is also a fantastic look at the nuance and intricacies of being or supporting a transgender person, vividly illustrated by a story full of characters the reader cares about and without the academic abstruseness that often gets in the way. The problems with gender-blindness, the limitations of honoring someone's gender without understanding how other people do not, the trickiness of privilege, gender policing as a distraction and alienation from the rest of one's life, the complications of real human bodies and dysmorphia, the importance of listening to another person rather than one's assumptions about how that person feels it's all in here, flowing naturally from the story, specific to the characters involved, and never belabored. I cannot express how well-handled this is. It was a delight to read. The other wonderful thing Aoki does is set Satomi up as the almost supernaturally competent teacher who in a sense "rescues" Katrina, and then invert the trope, showing the limits of Satomi's expertise, the places where she desperately needs human connection for herself, and her struggle to understand Katrina well enough to teach her at the level Satomi expects of herself. Teaching is not one thing to everyone; it's about listening, and Katrina is nothing like Satomi's other students. This novel is full of people thinking they finally understand each other and realizing there is still more depth that they had missed, and then talking through the gap like adults. As you can tell from any summary of this book, it's an odd genre mash-up. The fantasy part is a classic "magician sells her soul to Hell" story; there are a few twists, but it largely follows genre expectations. The science fiction part involving Lan is unfortunately weaker and feels more like a random assortment of borrowed Star Trek tropes than coherent world-building. Genre readers should not come to this story expecting a well-thought-out science fiction universe or a serious attempt to reconcile metaphysics between the fantasy and science fiction backgrounds. It's a quirky assortment of parts that don't normally go together, defy easy classification, and are often unexplained. I suspect this was intentional on Aoki's part given how deeply this book is about the experience of being transgender. Of the three primary viewpoint characters, I thought Lan's perspective was the weakest, and not just because of her somewhat generic SF background. Aoki uses her as a way to talk about the refugee experience, describing her as a woman who brings her family out of danger to build a new life. This mostly works, but Lan has vastly more power and capabilities than a refugee would normally have. Rather than the typical Asian refugee experience in the San Gabriel valley, Lan is more akin to a US multimillionaire who for some reason fled to Vietnam (relative to those around her, Lan is arguably even more wealthy than that). This is also a refugee experience, but it is an incredibly privileged one in a way that partly undermines the role that she plays in the story. Another false note bothered me more: I thought Tamiko was treated horribly in this story. She plays a quite minor role, sidelined early in the novel and appearing only briefly near the climax, and she's portrayed quite negatively, but she's clearly hurting as deeply as the protagonists of this novel. Aoki gives her a moment of redemption, but Tamiko gets nothing from it. Unlike every other injured and abused character in this story, no one is there for Tamiko and no one ever attempts to understand her. I found that profoundly sad. She's not an admirable character, but neither is Satomi at the start of the book. At least a gesture at a future for Tamiko would have been appreciated. Those two complaints aside, though, I could not put this book down. I was able to predict the broad outline of the plot, but the specifics were so good and so true to characters. Both the primary and supporting cast are unique, unpredictable, and memorable. Light from Uncommon Stars has a complex relationship with genre. It is squarely in the speculative fiction genre; the plot would not work without the fantasy and (more arguably) the science fiction elements. Music is magical in a way that goes beyond what can be attributed to metaphor and subjectivity. But it's also primarily character story deeply rooted in the specific location of the San Gabriel valley east of Los Angeles, full of vivid descriptions (particularly of food) and day-to-day life. As with the fantasy and science fiction elements, Aoki does not try to meld the genre elements into a coherent whole. She lets them sit side by side and be awkward and charming and uneven and chaotic. If you're the sort of SF reader who likes building a coherent theory of world-building rules, you may have to turn that desire off to fully enjoy this book. I thought this book was great. It's not flawless, but like its characters it's not trying to be flawless. In places it is deeply insightful and heartbreakingly emotional; in others, it's a glorious mess. It's full of cooking and food, YouTube fame, the disappointments of replicators, video game music, meet-cutes over donuts, found family, and classical music drama. I wish we'd gotten way more about the violin repair shop and a bit less warmed-over Star Trek, but I also loved it exactly the way it was. Definitely the best of the 2022 Hugo nominees that I've read so far. Content warning for child abuse, rape, self-harm, and somewhat explicit sex work. The start of the book is rather heavy and horrific, although the author advertises fairly clearly (and accurately) that things will get better. Rating: 9 out of 10

24 June 2022

Reproducible Builds: Supporter spotlight: Hans-Christoph Steiner of the F-Droid project

The Reproducible Builds project relies on several projects, supporters and sponsors for financial support, but they are also valued as ambassadors who spread the word about our project and the work that we do. This is the fifth instalment in a series featuring the projects, companies and individuals who support the Reproducible Builds project. We started this series by featuring the Civil Infrastructure Platform project and followed this up with a post about the Ford Foundation as well as a recent ones about ARDC, the Google Open Source Security Team (GOSST) and Jan Nieuwenhuizen on Bootstrappable Builds, GNU Mes and GNU Guix. Today, however, we will be talking with Hans-Christoph Steiner from the F-Droid project.

Chris: Welcome, Hans! Could you briefly tell me about yourself? Hans: Sure. I spend most of my time trying to private communications software usable by everyone, designing interactive software with a focus on human perceptual capabilities and building networks with free software. I ve been involved in Debian since approximately 2008 and became an official Debian developer in 2011. In the little time left over from that, I sometimes compose music with computers from my home in Austria.
Chris: For those who have not heard of it before, what is the F-Droid project? Hans: F-Droid is a community-run app store that provides free software applications for Android phones. First and foremost our goal is to represent our users. In particular, we review all of the apps that we distribute, and these reviews not only check for whether something is definitely free software or not, we additionally look for ethical problems with applications as well issues that we call Anti-Features . Since the project began in 2010, F-Droid now offers almost 4,000 free-software applications. F-Droid is also a app store kit as well, providing all the tools that are needed to operate an free app store of your own. It also includes complete build and release tools for managing the process of turning app source code into published builds.
Chris: How exactly does F-Droid differ from the Google Play store? Why might someone use F-Droid over Google Play? Hans: One key difference to the Google Play Store is that F-Droid does not ship proprietary software by default. All apps shipped from f-droid.org are built from source on our own builders. This is partly because F-Droid is backed by the free software community; that is, people who have engaged in the free software community long before Android was conceived, and, in particular, share many if not all of its values. Using F-Droid will therefore feel very familiar to anyone familiar with a modern Linux distribution.
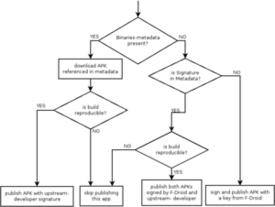
Chris: How do you describe reproducibility from the F-Droid point of view? Hans: All centralised software repositories are extremely tempting targets for exploitation by malicious third parties, and the kinds of personal or otherwise sensitive data on our phones only increase this risk. In F-Droid s case, not only could the software we distribute be theoretically replaced with nefarious copies, the build infrastructure that generates that software could be compromised as well. F-Droid having reproducible builds is extremely important as it allows us to verify that our build systems have not been compromised and distributing malware to our users. In particular, if an independent build infrastructure can produce precisely the same results from a build, then we can be reasonably sure that they haven t been compromised. Technically-minded users can also validate their builds on their own systems too, further increasing trust in our build infrastructure. (This can be performed using fdroid verify command.) Our signature & trust scheme means that F-Droid can verify that an app is 100% free software whilst still using the developer s original .APK file. More details about this may be found in our reproducibility documentation and on the page about our Verification Server.
Chris: How do you see F-Droid fitting into the rest of the modern security ecosystem? Hans: Whilst F-Droid inherits all of the social benefits of free software, F-Droid takes special care to respect your privacy as well we don t attempt to track your device in any way. In particular, you don t need an account to use the F-Droid client, and F-Droid doesn t send any device-identifying information to our servers other than its own version number. What is more, we mark all apps in our repository that track you, and users can choose to hide any apps that has been tagged with a specific Anti-Feature in the F-Droid settings. Furthermore, any personal data you decide to give us (such as your email address when registering for a forum account) goes no further than us as well, and we pledge that it will never be used for anything beyond merely maintaining your account.
Chris: What would fully reproducible mean to F-Droid? What it would look like if reproducibility was a solved problem ? Or, rather, what would be your ultimate reproducibility goals? Hans: In an ideal world, every application submitted to F-Droid would not only build reproducibly, but would come with a cryptographically-signed signature from the developer as well. Then we would only distribute an compiled application after a build had received a number of matching signatures from multiple, independent third parties. This would mean that our users were not placing their trust solely in software developers machines, and wouldn t be trusting our centralised build servers as well.
Chris: What are the biggest blockers to reaching this state? Are there any key steps or milestones to get there? Hans: Time is probably the main constraint to reaching this goal. Not only do we need system administrators on an ongoing basis but we also need to incorporate reproducibly checks into our Continuous Integration (CI) system. We are always looking for new developers to join our effort, as well as learning about how to better bring them up to speed. Separate to this, we often experience blockers with reproducibility-related bugs in the Android build tooling. Luckily, upstreams do ultimately address these issues, but in some cases this has taken three or four years to reach end-users and developers. Unfortunately, upstream is not chiefly concerned with the security aspects of reproducibility builds; they care more about how it can minimise and optimise download size and speed.
Chris: Are you tracking any statistics about reproducibility in F-Droid over time? If so, can you share them? Does F-Droid track statistics about its own usage? Hans: To underline a topic touched on above, F-Droid is dedicated to preserving the privacy of its users; we therefore do not record usage statistics. This is, of course, in contrast to other application stores. However, we are in a position to track whether packages in F-Droid are reproducible or not. As in: what proportion of APKs in F-Droid have been independently verified over time? Unfortunately, due to time constraints, we do not yet automatically publish charts for this. We do publish some raw data that is related, though, and we naturally welcome contributions of visualizations based on any and all of our data. The All our APIs page on our wiki is a good place to start for someone wanting to contribute, everything about reproducible F-Droid apps is available in JSON format, what s missing are apps or dashboards making use of the available raw data.
Chris: Many thanks for this interview, Hans, and for all of your work on F-Droid and elsewhere. If someone wanted to get in touch or learn more about the project, where might someone go? Hans: The best way to find out about F-Droid is, of course, the main F-Droid homepage, but we are also on Twitter @fdroidorg. We have many avenues to participate and to learn more! We have an About page on our website and a thriving forum. We also have part of our documentation specifically dedicated to reproducible builds.


For more information about the Reproducible Builds project, please see our website at reproducible-builds.org. If you are interested in ensuring the ongoing security of the software that underpins our civilisation and wish to sponsor the Reproducible Builds project, please reach out to the project by emailing contact@reproducible-builds.org.

Russ Allbery: Review: A Dead Djinn in Cairo

Review: A Dead Djinn in Cairo, by P. Dj l Clark
Publisher: Tordotcom
Copyright: May 2016
ASIN: B01DJ0NALI
Format: Kindle
Pages: 47
Fatma el-Sha'arawi is a special investigator with the Egyptian Ministry of Alchemy, Enchantments, and Supernatural Entities in an alternate 1912 Egypt. In Fatma's world, the mystic al-Jahiz broke through to the realm of the djinn in the late 1800s, giving Egypt access to magic and the supernatural and the djinn access to Egypt. It is now one of the great powers of the world, able to push off the Europeans and control its own politics. This is a Tor.com original novelette, so you can read it on-line for free or drop $2 on a Kindle version for convenience. It's the first story in the "Dead Djinn" universe, in which Clark has also written a novella and a novel (the latter of which won the Nebula Award for best novel in 2022). There are three things here I liked. Fatma is a memorable character, both for her grumpy demeanor as a rare female investigator having to put up with a sexist pig of a local police liaison, and for her full British attire (including a bowler hat) and its explanation. (The dynamics felt a bit modern for a story set in 1912, but not enough to bother me.) The setting is Arabian-inspired fantasy, which is a nice break from the normal European or Celtic stuff. And there are interesting angels (Fatma: "They're not really angels"), which I think have still-underused potential, particularly when they can create interesting conflicts with Coptic Christianity and Islam. Clark's version are energy creatures of some sort inside semi-mechanical bodies with visuals that reminded me strongly of Diablo III (which in this context is a compliment). I'm interested to learn more about them, although I hope there's more going on than the disappointing explanation we get at the end of this story. Other than those elements, there's not much here. As hinted by the title, the story is structured as a police investigation and Fatma plays the misfit detective. But there's no real mystery; the protagonists follow obvious clue to obvious clue to obvious ending. The plot structure is strictly linear and never surprised me. Aasim is an ass, which gives Fatma something to react to but never becomes real characterization. The world-building is the point, but most of it is delivered in infodumps, and the climax is a kind-of-boring fight where the metaphysics are explained rather than discovered. I'm possibly being too harsh. There's space for novelettes that tell straightforward stories without the need for a twist or a sting. But I admit I found this boring. I think it's because it's not tight enough to be carried by the momentum of a simple plot, and it's also not long enough for either the characters or the setting to breathe and develop. The metaphysics felt rushed and the characterization cramped. I liked Siti and the dynamic between Siti and Fatma at the end of the story, but there wasn't enough of it. As a world introduction, it does its job, and the non-European fantasy background is interesting enough that I'd be willing to read more, even without the incentive of reading all award winning novels. But "A Dead Djinn in Cairo" doesn't do more than its job. It might be worth skipping (I'll have to read the subsequent works to know for certain), but it won't take long to read and the price is right. Followed by The Haunting of Tram Car 015. Rating: 6 out of 10

20 June 2022

John Goerzen: Pipe Issue Likely a Kernel Bug

Saturday, I wrote in Pipes, deadlocks, and strace annoyingly fixing them about an issue where a certain pipeline seems to have a deadlock. I described tracing it into kernel code. Indeed, it appears to be kernel bug 212295, which has had a patch for over a year that has never been merged. After continuing to dig into the issue, I eventually reported it as a bug in ZFS. One of the ZFS people connected this to an older issue my searching hadn t uncovered. rincebrain summarized:
I believe, if I understand the bug correctly, it only triggers if you F_SETPIPE_SZ when the writer has put nonzero but not a full unit s worth in yet, which is why the world isn t on fire screaming about this you need to either have a very slow but nonzero or otherwise very strange write pattern to hit it, which is why it doesn t come up in, say, the CI or most of my testbeds, but my poor little SPARC (440 MHz, 1c1t) and Raspberry Pis were not so fortunate.
You might recall in Saturday s post that I explained that Filespooler reads a few bytes from the gpg/zstdcat pipeline before spawning and connecting it to zfs receive. I think this is the critical piece of the puzzle; it makes it much more likely to encounter the kernel bug. zfs receive is calls F_SETPIPE_SZ when it starts. Let s look at how this could be triggered: In the pre-Filespooler days, the gpg zstdcat zfs pipeline was all being set up at once. There would be no data sent to zfs receive until gpg had initialized and begun to decrypt the data, and then zstdcat had begun to decompress it. Those things almost certainly took longer than zfs receive s initialization, meaning that usually F_SETPIPE_SZ would have been invoked before any data entered the pipe. After switching to Filespooler, the particular situation here has Filespooler reading somewhere around 100 bytes from the gpg zstdcat part of the pipeline before ever invoking zfs receive. zstdcat generally emits more than 100 bytes at a time. Therefore, when Filespooler invokes zfs receive and hooks the pipeline up to it, it has a very high chance of there already being data in the pipeline when zfs receive uses F_SETPIPE_SZ. This means that the chances of encountering the conditions that trigger the particular kernel bug are also elevated. ZFS is integrating a patch to no longer use F_SETPIPE_SZ in zfs receive. I have applied that on my local end to see what happens, and hopefully in a day or two will know for sure if it resolves things. In the meantime, I hope you enjoyed this little exploration. It resulted in a new bug report to Rust as well as digging up an existing kernel bug. And, interestingly, no bugs in filespooler. Sometimes the thing that changed isn t the source of the bug!

19 June 2022

Dirk Eddelbuettel: #38: Faster Feedback Systems

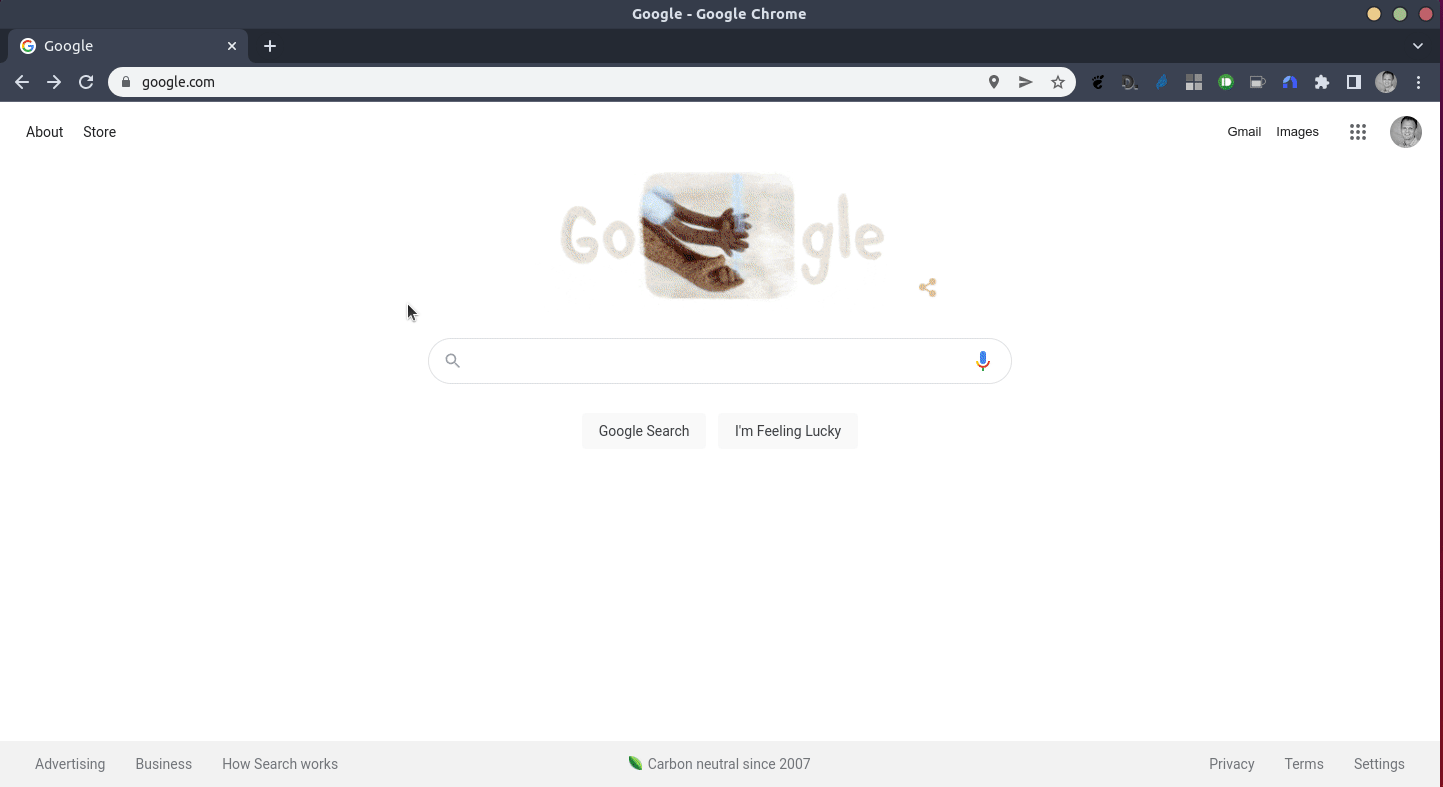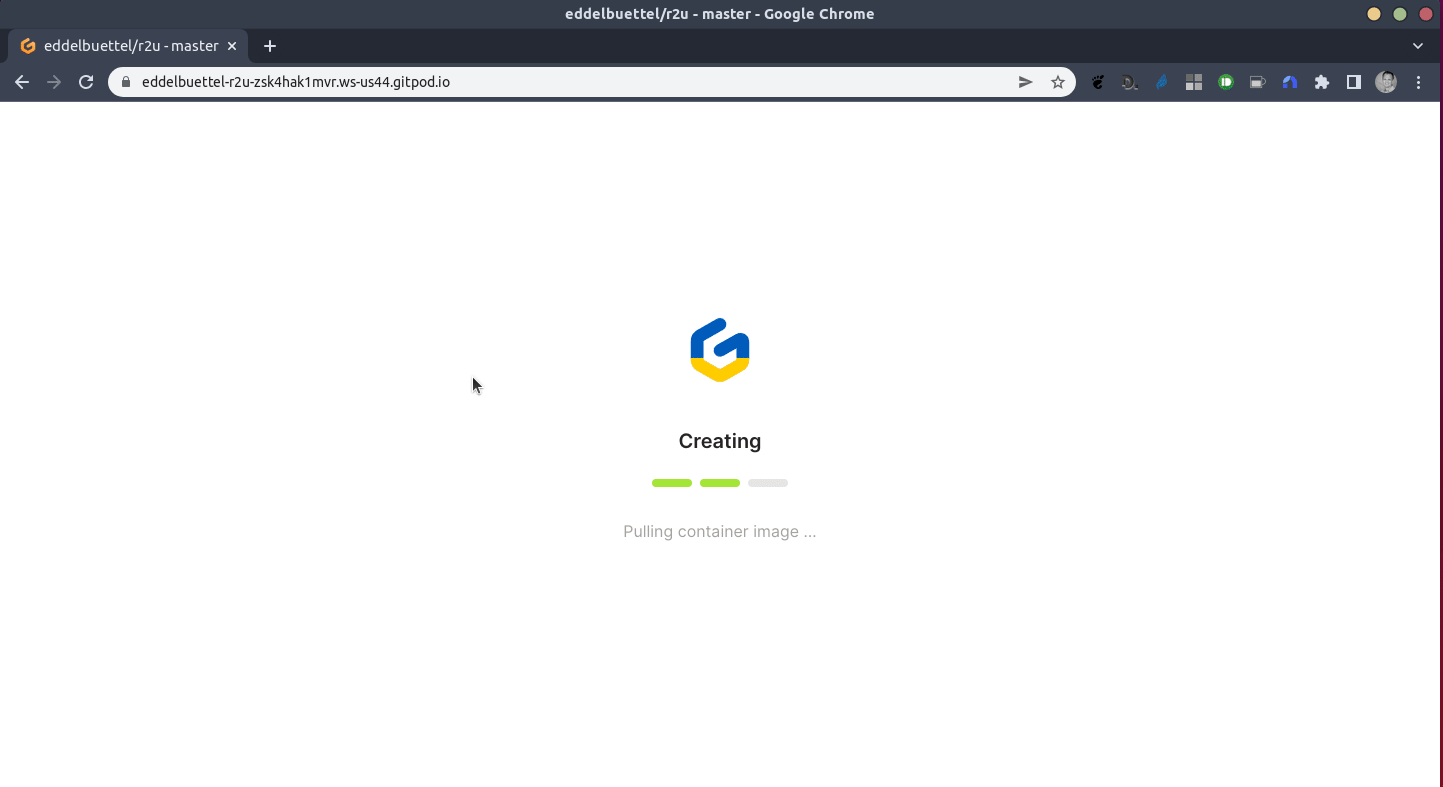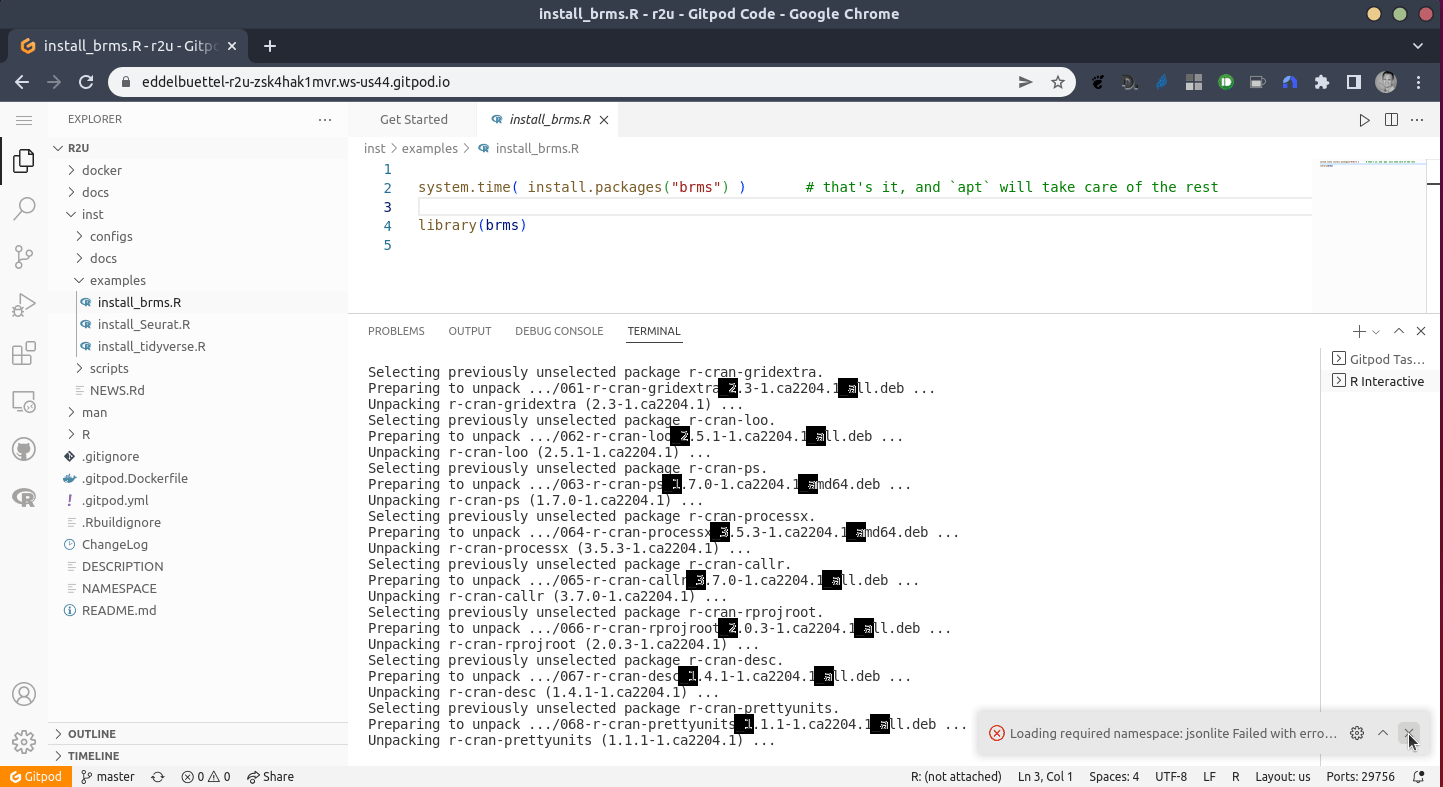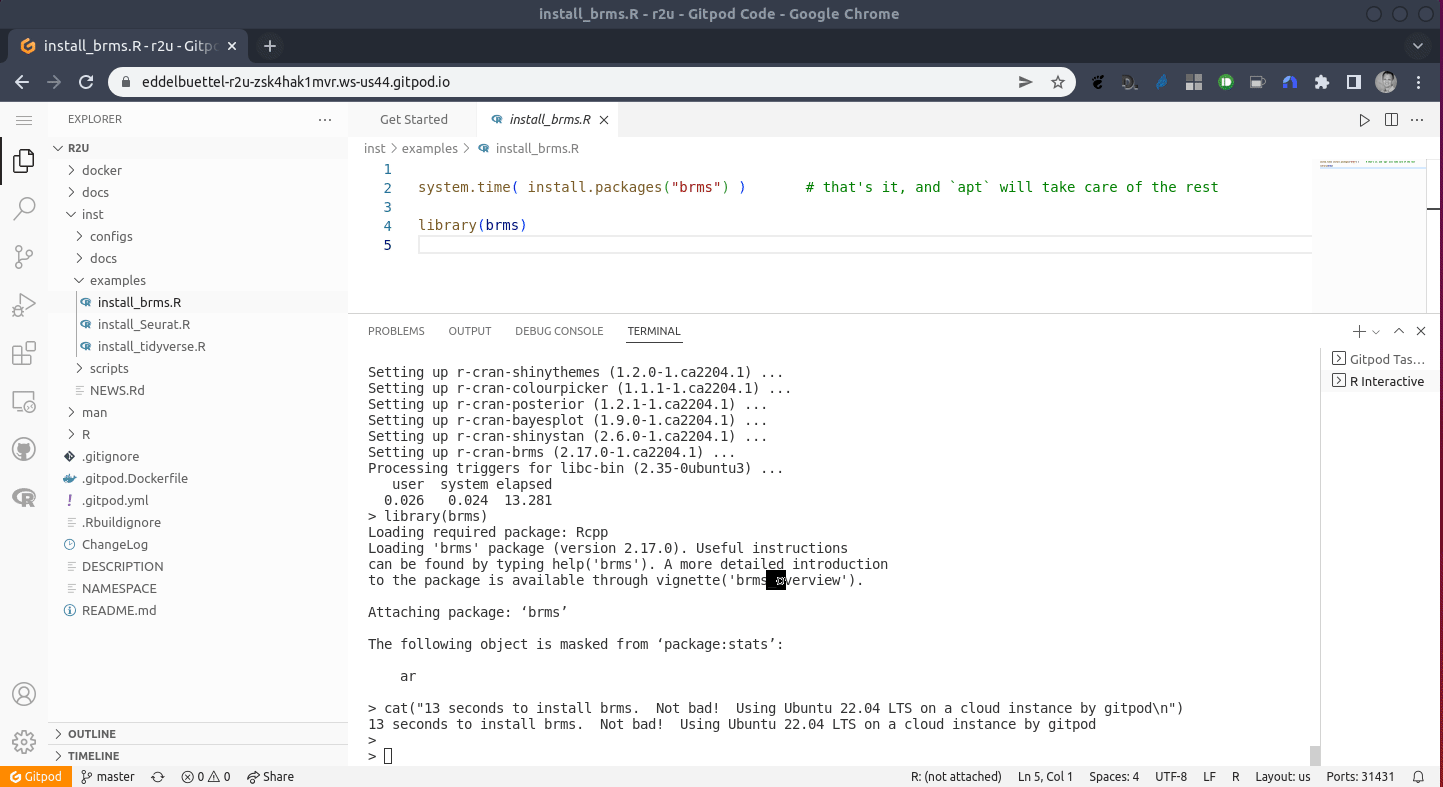
Engineers build systems. Good engineers always stress and focus efficiency of these systems. Two recent examples of engineering thinking follow. One was in a video / podcast interview with Martin Thompson (who is a noted high-performance code expert) I came across recently. The overall focus of the hour-long interview is on managing software complexity . Around minute twenty-two, the conversation turns to feedback loops and systems, and a strong preference for simple and fast systems for more immediate feedback. An important topic indeed. The second example connects to this and permeates many tweets and other writings by Erik Bernhardsson. He had an earlier 2017 post on Optimizing for iteration speed , as well as a 17 May 2022 tweet on minimizing feedback loop size, another 28 Mar 2022 tweet reply on shorter feedback loops, then a 14 Feb 2022 post on problems with slow feedback loops, as well as a 13 Jan 2022 post on a priority for tighter feedback loops, and lastly a 23 Jul 2021 post on fast feedback cycles. You get the idea: Erik really digs faster feedback loops. Nobody likes to wait: immediatecy wins each time. A few years ago, I had touched on this topic with two posts on how to make (R) package compilation (and hence installation) faster. One idea (which I still use whenever I must compile) was in post #11 on caching compilation. Another idea was in post #13: make it faster by not doing it, in this case via binary installation which skip the need for compilation (and which is what I aim for with, say, CI dependencies). Several subsequent posts can be found by scrolling down the r^4 blog section: we stressed the use of the amazing Rutter PPA c2d4u for CRAN binaries (often via Rocker containers, the (post #28) promise of RSPM, and the (post #29) awesomeness of bspm. And then in the more recent post #34 from last December we got back to a topic which ties all these things together: Dependencies. We quoted Mies van der Rohe: Less is more. Especially when it comes to dependencies as these elongate the feedback loop and thereby delay feedback. Our most recent post #37 on r2u connects these dots. Access to a complete set of CRAN binaries with full-dependency resolution accelerates use and installation. This of course also covers testing and continuous integration. Why wait minutes to recompile the same packages over and over when you can install the full Tidyverse in 18 seconds or the brms package and all it needs in 13 seconds as shown in the two gifs also on the r2u documentation site. You can even power up the example setup of the second gif via this gitpod link giving you a full Ubuntu 22.04 session in your browser to try this: so go forth and install something from CRAN with ease! The benefit of a system such our r2u CRAN binaries is clear: faster feedback loops. This holds whether you work with few or many dependencies, tiny or tidy. Faster matters, and feedback can be had sooner. And with the title of this post we now get a rallying cry to advocate for faster feedback systems: FFS .

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

17 June 2022

Antoine Beaupr : Matrix notes

I have some concerns about Matrix (the protocol, not the movie that came out recently, although I do have concerns about that as well). I've been watching the project for a long time, and it seems more a promising alternative to many protocols like IRC, XMPP, and Signal. This review may sound a bit negative, because it focuses on those concerns. I am the operator of an IRC network and people keep asking me to bridge it with Matrix. I have myself considered just giving up on IRC and converting to Matrix. This space is a living document exploring my research of that problem space. The TL;DR: is that no, I'm not setting up a bridge just yet, and I'm still on IRC. This article was written over the course of the last three months, but I have been watching the Matrix project for years (my logs seem to say 2016 at least). The article is rather long. It will likely take you half an hour to read, so copy this over to your ebook reader, your tablet, or dead trees, and lean back and relax as I show you around the Matrix. Or, alternatively, just jump to a section that interest you, most likely the conclusion.

Introduction to Matrix Matrix is an "open standard for interoperable, decentralised, real-time communication over IP. It can be used to power Instant Messaging, VoIP/WebRTC signalling, Internet of Things communication - or anywhere you need a standard HTTP API for publishing and subscribing to data whilst tracking the conversation history". It's also (when compared with XMPP) "an eventually consistent global JSON database with an HTTP API and pubsub semantics - whilst XMPP can be thought of as a message passing protocol." According to their FAQ, the project started in 2014, has about 20,000 servers, and millions of users. Matrix works over HTTPS but over a special port: 8448.

Security and privacy I have some concerns about the security promises of Matrix. It's advertised as a "secure" with "E2E [end-to-end] encryption", but how does it actually work?

Data retention defaults One of my main concerns with Matrix is data retention, which is a key part of security in a threat model where (for example) an hostile state actor wants to surveil your communications and can seize your devices. On IRC, servers don't actually keep messages all that long: they pass them along to other servers and clients as fast as they can, only keep them in memory, and move on to the next message. There are no concerns about data retention on messages (and their metadata) other than the network layer. (I'm ignoring the issues with user registration, which is a separate, if valid, concern.) Obviously, an hostile server could log everything passing through it, but IRC federations are normally tightly controlled. So, if you trust your IRC operators, you should be fairly safe. Obviously, clients can (and often do, even if OTR is configured!) log all messages, but this is generally not the default. Irssi, for example, does not log by default. IRC bouncers are more likely to log to disk, of course, to be able to do what they do. Compare this to Matrix: when you send a message to a Matrix homeserver, that server first stores it in its internal SQL database. Then it will transmit that message to all clients connected to that server and room, and to all other servers that have clients connected to that room. Those remote servers, in turn, will keep a copy of that message and all its metadata in their own database, by default forever. On encrypted rooms those messages are encrypted, but not their metadata. There is a mechanism to expire entries in Synapse, but it is not enabled by default. So one should generally assume that a message sent on Matrix is never expired.

GDPR in the federation But even if that setting was enabled by default, how do you control it? This is a fundamental problem of the federation: if any user is allowed to join a room (which is the default), those user's servers will log all content and metadata from that room. That includes private, one-on-one conversations, since those are essentially rooms as well. In the context of the GDPR, this is really tricky: who is the responsible party (known as the "data controller") here? It's basically any yahoo who fires up a home server and joins a room. In a federated network, one has to wonder whether GDPR enforcement is even possible at all. But in Matrix in particular, if you want to enforce your right to be forgotten in a given room, you would have to:
  1. enumerate all the users that ever joined the room while you were there
  2. discover all their home servers
  3. start a GDPR procedure against all those servers
I recognize this is a hard problem to solve while still keeping an open ecosystem. But I believe that Matrix should have much stricter defaults towards data retention than right now. Message expiry should be enforced by default, for example. (Note that there are also redaction policies that could be used to implement part of the GDPR automatically, see the privacy policy discussion below on that.) Also keep in mind that, in the brave new peer-to-peer world that Matrix is heading towards, the boundary between server and client is likely to be fuzzier, which would make applying the GDPR even more difficult. Update: this comment links to this post (in german) which apparently studied the question and concluded that Matrix is not GDPR-compliant. In fact, maybe Synapse should be designed so that there's no configurable flag to turn off data retention. A bit like how most system loggers in UNIX (e.g. syslog) come with a log retention system that typically rotate logs after a few weeks or month. Historically, this was designed to keep hard drives from filling up, but it also has the added benefit of limiting the amount of personal information kept on disk in this modern day. (Arguably, syslog doesn't rotate logs on its own, but, say, Debian GNU/Linux, as an installed system, does have log retention policies well defined for installed packages, and those can be discussed. And "no expiry" is definitely a bug.

Matrix.org privacy policy When I first looked at Matrix, five years ago, Element.io was called Riot.im and had a rather dubious privacy policy:
We currently use cookies to support our use of Google Analytics on the Website and Service. Google Analytics collects information about how you use the Website and Service. [...] This helps us to provide you with a good experience when you browse our Website and use our Service and also allows us to improve our Website and our Service.
When I asked Matrix people about why they were using Google Analytics, they explained this was for development purposes and they were aiming for velocity at the time, not privacy (paraphrasing here). They also included a "free to snitch" clause:
If we are or believe that we are under a duty to disclose or share your personal data, we will do so in order to comply with any legal obligation, the instructions or requests of a governmental authority or regulator, including those outside of the UK.
Those are really broad terms, above and beyond what is typically expected legally. Like the current retention policies, such user tracking and ... "liberal" collaboration practices with the state set a bad precedent for other home servers. Thankfully, since the above policy was published (2017), the GDPR was "implemented" (2018) and it seems like both the Element.io privacy policy and the Matrix.org privacy policy have been somewhat improved since. Notable points of the new privacy policies:
  • 2.3.1.1: the "federation" section actually outlines that "Federated homeservers and Matrix clients which respect the Matrix protocol are expected to honour these controls and redaction/erasure requests, but other federated homeservers are outside of the span of control of Element, and we cannot guarantee how this data will be processed"
  • 2.6: users under the age of 16 should not use the matrix.org service
  • 2.10: Upcloud, Mythic Beast, Amazon, and CloudFlare possibly have access to your data (it's nice to at least mention this in the privacy policy: many providers don't even bother admitting to this kind of delegation)
  • Element 2.2.1: mentions many more third parties (Twilio, Stripe, Quaderno, LinkedIn, Twitter, Google, Outplay, PipeDrive, HubSpot, Posthog, Sentry, and Matomo (phew!) used when you are paying Matrix.org for hosting
I'm not super happy with all the trackers they have on the Element platform, but then again you don't have to use that service. Your favorite homeserver (assuming you are not on Matrix.org) probably has their own Element deployment, hopefully without all that garbage. Overall, this is all a huge improvement over the previous privacy policy, so hats off to the Matrix people for figuring out a reasonable policy in such a tricky context. I particularly like this bit:
We will forget your copy of your data upon your request. We will also forward your request to be forgotten onto federated homeservers. However - these homeservers are outside our span of control, so we cannot guarantee they will forget your data.
It's great they implemented those mechanisms and, after all, if there's an hostile party in there, nothing can prevent them from using screenshots to just exfiltrate your data away from the client side anyways, even with services typically seen as more secure, like Signal. As an aside, I also appreciate that Matrix.org has a fairly decent code of conduct, based on the TODO CoC which checks all the boxes in the geekfeminism wiki.

Metadata handling Overall, privacy protections in Matrix mostly concern message contents, not metadata. In other words, who's talking with who, when and from where is not well protected. Compared to a tool like Signal, which goes through great lengths to anonymize that data with features like private contact discovery, disappearing messages, sealed senders, and private groups, Matrix is definitely behind. (Note: there is an issue open about message lifetimes in Element since 2020, but it's not at even at the MSC stage yet.) This is a known issue (opened in 2019) in Synapse, but this is not just an implementation issue, it's a flaw in the protocol itself. Home servers keep join/leave of all rooms, which gives clear text information about who is talking to. Synapse logs may also contain privately identifiable information that home server admins might not be aware of in the first place. Those log rotation policies are separate from the server-level retention policy, which may be confusing for a novice sysadmin. Combine this with the federation: even if you trust your home server to do the right thing, the second you join a public room with third-party home servers, those ideas kind of get thrown out because those servers can do whatever they want with that information. Again, a problem that is hard to solve in any federation. To be fair, IRC doesn't have a great story here either: any client knows not only who's talking to who in a room, but also typically their client IP address. Servers can (and often do) obfuscate this, but often that obfuscation is trivial to reverse. Some servers do provide "cloaks" (sometimes automatically), but that's kind of a "slap-on" solution that actually moves the problem elsewhere: now the server knows a little more about the user. Overall, I would worry much more about a Matrix home server seizure than a IRC or Signal server seizure. Signal does get subpoenas, and they can only give out a tiny bit of information about their users: their phone number, and their registration, and last connection date. Matrix carries a lot more information in its database.

Amplification attacks on URL previews I (still!) run an Icecast server and sometimes share links to it on IRC which, obviously, also ends up on (more than one!) Matrix home servers because some people connect to IRC using Matrix. This, in turn, means that Matrix will connect to that URL to generate a link preview. I feel this outlines a security issue, especially because those sockets would be kept open seemingly forever. I tried to warn the Matrix security team but somehow, I don't think this issue was taken very seriously. Here's the disclosure timeline:
  • January 18: contacted Matrix security
  • January 19: response: already reported as a bug
  • January 20: response: can't reproduce
  • January 31: timeout added, considered solved
  • January 31: I respond that I believe the security issue is underestimated, ask for clearance to disclose
  • February 1: response: asking for two weeks delay after the next release (1.53.0) including another patch, presumably in two weeks' time
  • February 22: Matrix 1.53.0 released
  • April 14: I notice the release, ask for clearance again
  • April 14: response: referred to the public disclosure
There are a couple of problems here:
  1. the bug was publicly disclosed in September 2020, and not considered a security issue until I notified them, and even then, I had to insist
  2. no clear disclosure policy timeline was proposed or seems established in the project (there is a security disclosure policy but it doesn't include any predefined timeline)
  3. I wasn't informed of the disclosure
  4. the actual solution is a size limit (10MB, already implemented), a time limit (30 seconds, implemented in PR 11784), and a content type allow list (HTML, "media" or JSON, implemented in PR 11936), and I'm not sure it's adequate
  5. (pure vanity:) I did not make it to their Hall of fame
I'm not sure those solutions are adequate because they all seem to assume a single home server will pull that one URL for a little while then stop. But in a federated network, many (possibly thousands) home servers may be connected in a single room at once. If an attacker drops a link into such a room, all those servers would connect to that link all at once. This is an amplification attack: a small amount of traffic will generate a lot more traffic to a single target. It doesn't matter there are size or time limits: the amplification is what matters here. It should also be noted that clients that generate link previews have more amplification because they are more numerous than servers. And of course, the default Matrix client (Element) does generate link previews as well. That said, this is possibly not a problem specific to Matrix: any federated service that generates link previews may suffer from this. I'm honestly not sure what the solution is here. Maybe moderation? Maybe link previews are just evil? All I know is there was this weird bug in my Icecast server and I tried to ring the bell about it, and it feels it was swept under the rug. Somehow I feel this is bound to blow up again in the future, even with the current mitigation.

Moderation In Matrix like elsewhere, Moderation is a hard problem. There is a detailed moderation guide and much of this problem space is actively worked on in Matrix right now. A fundamental problem with moderating a federated space is that a user banned from a room can rejoin the room from another server. This is why spam is such a problem in Email, and why IRC networks have stopped federating ages ago (see the IRC history for that fascinating story).

The mjolnir bot The mjolnir moderation bot is designed to help with some of those things. It can kick and ban users, redact all of a user's message (as opposed to one by one), all of this across multiple rooms. It can also subscribe to a federated block list published by matrix.org to block known abusers (users or servers). Bans are pretty flexible and can operate at the user, room, or server level. Matrix people suggest making the bot admin of your channels, because you can't take back admin from a user once given.

The command-line tool There's also a new command line tool designed to do things like:
  • System notify users (all users/users from a list, specific user)
  • delete sessions/devices not seen for X days
  • purge the remote media cache
  • select rooms with various criteria (external/local/empty/created by/encrypted/cleartext)
  • purge history of theses rooms
  • shutdown rooms
This tool and Mjolnir are based on the admin API built into Synapse.

Rate limiting Synapse has pretty good built-in rate-limiting which blocks repeated login, registration, joining, or messaging attempts. It may also end up throttling servers on the federation based on those settings.

Fundamental federation problems Because users joining a room may come from another server, room moderators are at the mercy of the registration and moderation policies of those servers. Matrix is like IRC's +R mode ("only registered users can join") by default, except that anyone can register their own homeserver, which makes this limited. Server admins can block IP addresses and home servers, but those tools are not easily available to room admins. There is an API (m.room.server_acl in /devtools) but it is not reliable (thanks Austin Huang for the clarification). Matrix has the concept of guest accounts, but it is not used very much, and virtually no client or homeserver supports it. This contrasts with the way IRC works: by default, anyone can join an IRC network even without authentication. Some channels require registration, but in general you are free to join and look around (until you get blocked, of course). I have seen anecdotal evidence (CW: Twitter, nitter link) that "moderating bridges is hell", and I can imagine why. Moderation is already hard enough on one federation, when you bridge a room with another network, you inherit all the problems from that network but without the entire abuse control tools from the original network's API...

Room admins Matrix, in particular, has the problem that room administrators (which have the power to redact messages, ban users, and promote other users) are bound to their Matrix ID which is, in turn, bound to their home servers. This implies that a home server administrators could (1) impersonate a given user and (2) use that to hijack the room. So in practice, the home server is the trust anchor for rooms, not the user themselves. That said, if server B administrator hijack user joe on server B, they will hijack that room on that specific server. This will not (necessarily) affect users on the other servers, as servers could refuse parts of the updates or ban the compromised account (or server). It does seem like a major flaw that room credentials are bound to Matrix identifiers, as opposed to the E2E encryption credentials. In an encrypted room even with fully verified members, a compromised or hostile home server can still take over the room by impersonating an admin. That admin (or even a newly minted user) can then send events or listen on the conversations. This is even more frustrating when you consider that Matrix events are actually signed and therefore have some authentication attached to them, acting like some sort of Merkle tree (as it contains a link to previous events). That signature, however, is made from the homeserver PKI keys, not the client's E2E keys, which makes E2E feel like it has been "bolted on" later.

Availability While Matrix has a strong advantage over Signal in that it's decentralized (so anyone can run their own homeserver,), I couldn't find an easy way to run a "multi-primary" setup, or even a "redundant" setup (even if with a single primary backend), short of going full-on "replicate PostgreSQL and Redis data", which is not typically for the faint of heart.

How this works in IRC On IRC, it's quite easy to setup redundant nodes. All you need is:
  1. a new machine (with it's own public address with an open port)
  2. a shared secret (or certificate) between that machine and an existing one on the network
  3. a connect block on both servers
That's it: the node will join the network and people can connect to it as usual and share the same user/namespace as the rest of the network. The servers take care of synchronizing state: you do not need to worry about replicating a database server. (Now, experienced IRC people will know there's a catch here: IRC doesn't have authentication built in, and relies on "services" which are basically bots that authenticate users (I'm simplifying, don't nitpick). If that service goes down, the network still works, but then people can't authenticate, and they can start doing nasty things like steal people's identity if they get knocked offline. But still: basic functionality still works: you can talk in rooms and with users that are on the reachable network.)

User identities Matrix is more complicated. Each "home server" has its own identity namespace: a specific user (say @anarcat:matrix.org) is bound to that specific home server. If that server goes down, that user is completely disconnected. They could register a new account elsewhere and reconnect, but then they basically lose all their configuration: contacts, joined channels are all lost. (Also notice how the Matrix IDs don't look like a typical user address like an email in XMPP. They at least did their homework and got the allocation for the scheme.)

Rooms Users talk to each other in "rooms", even in one-to-one communications. (Rooms are also used for other things like "spaces", they're basically used for everything, think "everything is a file" kind of tool.) For rooms, home servers act more like IRC nodes in that they keep a local state of the chat room and synchronize it with other servers. Users can keep talking inside a room if the server that originally hosts the room goes down. Rooms can have a local, server-specific "alias" so that, say, #room:matrix.org is also visible as #room:example.com on the example.com home server. Both addresses refer to the same room underlying room. (Finding this in the Element settings is not obvious though, because that "alias" are actually called a "local address" there. So to create such an alias (in Element), you need to go in the room settings' "General" section, "Show more" in "Local address", then add the alias name (e.g. foo), and then that room will be available on your example.com homeserver as #foo:example.com.) So a room doesn't belong to a server, it belongs to the federation, and anyone can join the room from any serer (if the room is public, or if invited otherwise). You can create a room on server A and when a user from server B joins, the room will be replicated on server B as well. If server A fails, server B will keep relaying traffic to connected users and servers. A room is therefore not fundamentally addressed with the above alias, instead ,it has a internal Matrix ID, which basically a random string. It has a server name attached to it, but that was made just to avoid collisions. That can get a little confusing. For example, the #fractal:gnome.org room is an alias on the gnome.org server, but the room ID is !hwiGbsdSTZIwSRfybq:matrix.org. That's because the room was created on matrix.org, but the preferred branding is gnome.org now. As an aside, rooms, by default, live forever, even after the last user quits. There's an admin API to delete rooms and a tombstone event to redirect to another one, but neither have a GUI yet. The latter is part of MSC1501 ("Room version upgrades") which allows a room admin to close a room, with a message and a pointer to another room.

Spaces Discovering rooms can be tricky: there is a per-server room directory, but Matrix.org people are trying to deprecate it in favor of "Spaces". Room directories were ripe for abuse: anyone can create a room, so anyone can show up in there. It's possible to restrict who can add aliases, but anyways directories were seen as too limited. In contrast, a "Space" is basically a room that's an index of other rooms (including other spaces), so existing moderation and administration mechanism that work in rooms can (somewhat) work in spaces as well. This enables a room directory that works across federation, regardless on which server they were originally created. New users can be added to a space or room automatically in Synapse. (Existing users can be told about the space with a server notice.) This gives admins a way to pre-populate a list of rooms on a server, which is useful to build clusters of related home servers, providing some sort of redundancy, at the room -- not user -- level.

Home servers So while you can workaround a home server going down at the room level, there's no such thing at the home server level, for user identities. So if you want those identities to be stable in the long term, you need to think about high availability. One limitation is that the domain name (e.g. matrix.example.com) must never change in the future, as renaming home servers is not supported. The documentation used to say you could "run a hot spare" but that has been removed. Last I heard, it was not possible to run a high-availability setup where multiple, separate locations could replace each other automatically. You can have high performance setups where the load gets distributed among workers, but those are based on a shared database (Redis and PostgreSQL) backend. So my guess is it would be possible to create a "warm" spare server of a matrix home server with regular PostgreSQL replication, but that is not documented in the Synapse manual. This sort of setup would also not be useful to deal with networking issues or denial of service attacks, as you will not be able to spread the load over multiple network locations easily. Redis and PostgreSQL heroes are welcome to provide their multi-primary solution in the comments. In the meantime, I'll just point out this is a solution that's handled somewhat more gracefully in IRC, by having the possibility of delegating the authentication layer.

Delegations If you do not want to run a Matrix server yourself, it's possible to delegate the entire thing to another server. There's a server discovery API which uses the .well-known pattern (or SRV records, but that's "not recommended" and a bit confusing) to delegate that service to another server. Be warned that the server still needs to be explicitly configured for your domain. You can't just put:
  "m.server": "matrix.org:443"  
... on https://example.com/.well-known/matrix/server and start using @you:example.com as a Matrix ID. That's because Matrix doesn't support "virtual hosting" and you'd still be connecting to rooms and people with your matrix.org identity, not example.com as you would normally expect. This is also why you cannot rename your home server. The server discovery API is what allows servers to find each other. Clients, on the other hand, use the client-server discovery API: this is what allows a given client to find your home server when you type your Matrix ID on login.

Performance The high availability discussion brushed over the performance of Matrix itself, but let's now dig into that.

Horizontal scalability There were serious scalability issues of the main Matrix server, Synapse, in the past. So the Matrix team has been working hard to improve its design. Since Synapse 1.22 the home server can horizontally scale to multiple workers (see this blog post for details) which can make it easier to scale large servers.

Other implementations There are other promising home servers implementations from a performance standpoint (dendrite, Golang, entered beta in late 2020; conduit, Rust, beta; others), but none of those are feature-complete so there's a trade-off to be made there. Synapse is also adding a lot of feature fast, so it's an open question whether the others will ever catch up. (I have heard that Dendrite might actually surpass Synapse in features within a few years, which would put Synapse in a more "LTS" situation.)

Latency Matrix can feel slow sometimes. For example, joining the "Matrix HQ" room in Element (from matrix.debian.social) takes a few minutes and then fails. That is because the home server has to sync the entire room state when you join the room. There was promising work on this announced in the lengthy 2021 retrospective, and some of that work landed (partial sync) in the 1.53 release already. Other improvements coming include sliding sync, lazy loading over federation, and fast room joins. So that's actually something that could be fixed in the fairly short term. But in general, communication in Matrix doesn't feel as "snappy" as on IRC or even Signal. It's hard to quantify this without instrumenting a full latency test bed (for example the tools I used in the terminal emulators latency tests), but even just typing in a web browser feels slower than typing in a xterm or Emacs for me. Even in conversations, I "feel" people don't immediately respond as fast. In fact, this could be an interesting double-blind experiment to make: have people guess whether they are talking to a person on Matrix, XMPP, or IRC, for example. My theory would be that people could notice that Matrix users are slower, if only because of the TCP round-trip time each message has to take.

Transport Some courageous person actually made some tests of various messaging platforms on a congested network. His evaluation was basically:
  • Briar: uses Tor, so unusable except locally
  • Matrix: "struggled to send and receive messages", joining a room takes forever as it has to sync all history, "took 20-30 seconds for my messages to be sent and another 20 seconds for further responses"
  • XMPP: "worked in real-time, full encryption, with nearly zero lag"
So that was interesting. I suspect IRC would have also fared better, but that's just a feeling. Other improvements to the transport layer include support for websocket and the CoAP proxy work from 2019 (targeting 100bps links), but both seem stalled at the time of writing. The Matrix people have also announced the pinecone p2p overlay network which aims at solving large, internet-scale routing problems. See also this talk at FOSDEM 2022.

Usability

Onboarding and workflow The workflow for joining a room, when you use Element web, is not great:
  1. click on a link in a web browser
  2. land on (say) https://matrix.to/#/#matrix-dev:matrix.org
  3. offers "Element", yeah that's sounds great, let's click "Continue"
  4. land on https://app.element.io/#/room%2F%23matrix-dev%3Amatrix.org and then you need to register, aaargh
As you might have guessed by now, there is a specification to solve this, but web browsers need to adopt it as well, so that's far from actually being solved. At least browsers generally know about the matrix: scheme, it's just not exactly clear what they should do with it, especially when the handler is just another web page (e.g. Element web). In general, when compared with tools like Signal or WhatsApp, Matrix doesn't fare so well in terms of user discovery. I probably have some of my normal contacts that have a Matrix account as well, but there's really no way to know. It's kind of creepy when Signal tells you "this person is on Signal!" but it's also pretty cool that it works, and they actually implemented it pretty well. Registration is also less obvious: in Signal, the app confirms your phone number automatically. It's friction-less and quick. In Matrix, you need to learn about home servers, pick one, register (with a password! aargh!), and then setup encryption keys (not default), etc. It's a lot more friction. And look, I understand: giving away your phone number is a huge trade-off. I don't like it either. But it solves a real problem and makes encryption accessible to a ton more people. Matrix does have "identity servers" that can serve that purpose, but I don't feel confident sharing my phone number there. It doesn't help that the identity servers don't have private contact discovery: giving them your phone number is a more serious security compromise than with Signal. There's a catch-22 here too: because no one feels like giving away their phone numbers, no one does, and everyone assumes that stuff doesn't work anyways. Like it or not, Signal forcing people to divulge their phone number actually gives them critical mass that means actually a lot of my relatives are on Signal and I don't have to install crap like WhatsApp to talk with them.

5 minute clients evaluation Throughout all my tests I evaluated a handful of Matrix clients, mostly from Flathub because almost none of them are packaged in Debian. Right now I'm using Element, the flagship client from Matrix.org, in a web browser window, with the PopUp Window extension. This makes it look almost like a native app, and opens links in my main browser window (instead of a new tab in that separate window), which is nice. But I'm tired of buying memory to feed my web browser, so this indirection has to stop. Furthermore, I'm often getting completely logged off from Element, which means re-logging in, recovering my security keys, and reconfiguring my settings. That is extremely annoying. Coming from Irssi, Element is really "GUI-y" (pronounced "gooey"). Lots of clickety happening. To mark conversations as read, in particular, I need to click-click-click on all the tabs that have some activity. There's no "jump to latest message" or "mark all as read" functionality as far as I could tell. In Irssi the former is built-in (alt-a) and I made a custom /READ command for the latter:
/ALIAS READ script exec \$_->activity(0) for Irssi::windows
And yes, that's a Perl script in my IRC client. I am not aware of any Matrix client that does stuff like that, except maybe Weechat, if we can call it a Matrix client, or Irssi itself, now that it has a Matrix plugin (!). As for other clients, I have looked through the Matrix Client Matrix (confusing right?) to try to figure out which one to try, and, even after selecting Linux as a filter, the chart is just too wide to figure out anything. So I tried those, kind of randomly:
  • Fractal
  • Mirage
  • Nheko
  • Quaternion
Unfortunately, I lost my notes on those, I don't actually remember which one did what. I still have a session open with Mirage, so I guess that means it's the one I preferred, but I remember they were also all very GUI-y. Maybe I need to look at weechat-matrix or gomuks. At least Weechat is scriptable so I could continue playing the power-user. Right now my strategy with messaging (and that includes microblogging like Twitter or Mastodon) is that everything goes through my IRC client, so Weechat could actually fit well in there. Going with gomuks, on the other hand, would mean running it in parallel with Irssi or ... ditching IRC, which is a leap I'm not quite ready to take just yet. Oh, and basically none of those clients (except Nheko and Element) support VoIP, which is still kind of a second-class citizen in Matrix. It does not support large multimedia rooms, for example: Jitsi was used for FOSDEM instead of the native videoconferencing system.

Bots This falls a little aside the "usability" section, but I didn't know where to put this... There's a few Matrix bots out there, and you are likely going to be able to replace your existing bots with Matrix bots. It's true that IRC has a long and impressive history with lots of various bots doing various things, but given how young Matrix is, there's still a good variety:
  • maubot: generic bot with tons of usual plugins like sed, dice, karma, xkcd, echo, rss, reminder, translate, react, exec, gitlab/github webhook receivers, weather, etc
  • opsdroid: framework to implement "chat ops" in Matrix, connects with Matrix, GitHub, GitLab, Shell commands, Slack, etc
  • matrix-nio: another framework, used to build lots more bots like:
    • hemppa: generic bot with various functionality like weather, RSS feeds, calendars, cron jobs, OpenStreetmaps lookups, URL title snarfing, wolfram alpha, astronomy pic of the day, Mastodon bridge, room bridging, oh dear
    • devops: ping, curl, etc
    • podbot: play podcast episodes from AntennaPod
    • cody: Python, Ruby, Javascript REPL
    • eno: generic bot, "personal assistant"
  • mjolnir: moderation bot
  • hookshot: bridge with GitLab/GitHub
  • matrix-monitor-bot: latency monitor
One thing I haven't found an equivalent for is Debian's MeetBot. There's an archive bot but it doesn't have topics or a meeting chair, or HTML logs.

Working on Matrix As a developer, I find Matrix kind of intimidating. The specification is huge. The official specification itself looks somewhat digestable: it's only 6 APIs so that looks, at first, kind of reasonable. But whenever you start asking complicated questions about Matrix, you quickly fall into the Matrix Spec Change specification (which, yes, is a separate specification). And there are literally hundreds of MSCs flying around. It's hard to tell what's been adopted and what hasn't, and even harder to figure out if your specific client has implemented it. (One trendy answer to this problem is to "rewrite it in rust": Matrix are working on implementing a lot of those specifications in a matrix-rust-sdk that's designed to take the implementation details away from users.) Just taking the latest weekly Matrix report, you find that three new MSCs proposed, just last week! There's even a graph that shows the number of MSCs is progressing steadily, at 600+ proposals total, with the majority (300+) "new". I would guess the "merged" ones are at about 150. That's a lot of text which includes stuff like 3D worlds which, frankly, I don't think you should be working on when you have such important security and usability problems. (The internet as a whole, arguably, doesn't fare much better. RFC600 is a really obscure discussion about "INTERFACING AN ILLINOIS PLASMA TERMINAL TO THE ARPANET". Maybe that's how many MSCs will end up as well, left forgotten in the pits of history.) And that's the thing: maybe the Matrix people have a different objective than I have. They want to connect everything to everything, and make Matrix a generic transport for all sorts of applications, including virtual reality, collaborative editors, and so on. I just want secure, simple messaging. Possibly with good file transfers, and video calls. That it works with existing stuff is good, and it should be federated to remove the "Signal point of failure". So I'm a bit worried with the direction all those MSCs are taking, especially when you consider that clients other than Element are still struggling to keep up with basic features like end-to-end encryption or room discovery, never mind voice or spaces...

Conclusion Overall, Matrix is somehow in the space XMPP was a few years ago. It has a ton of features, pretty good clients, and a large community. It seems to have gained some of the momentum that XMPP has lost. It may have the most potential to replace Signal if something bad would happen to it (like, I don't know, getting banned or going nuts with cryptocurrency)... But it's really not there yet, and I don't see Matrix trying to get there either, which is a bit worrisome.

Looking back at history I'm also worried that we are repeating the errors of the past. The history of federated services is really fascinating:. IRC, FTP, HTTP, and SMTP were all created in the early days of the internet, and are all still around (except, arguably, FTP, which was removed from major browsers recently). All of them had to face serious challenges in growing their federation. IRC had numerous conflicts and forks, both at the technical level but also at the political level. The history of IRC is really something that anyone working on a federated system should study in detail, because they are bound to make the same mistakes if they are not familiar with it. The "short" version is:
  • 1988: Finnish researcher publishes first IRC source code
  • 1989: 40 servers worldwide, mostly universities
  • 1990: EFnet ("eris-free network") fork which blocks the "open relay", named Eris - followers of Eris form the A-net, which promptly dissolves itself, with only EFnet remaining
  • 1992: Undernet fork, which offered authentication ("services"), routing improvements and timestamp-based channel synchronisation
  • 1994: DALnet fork, from Undernet, again on a technical disagreement
  • 1995: Freenode founded
  • 1996: IRCnet forks from EFnet, following a flame war of historical proportion, splitting the network between Europe and the Americas
  • 1997: Quakenet founded
  • 1999: (XMPP founded)
  • 2001: 6 million users, OFTC founded
  • 2002: DALnet peaks at 136,000 users
  • 2003: IRC as a whole peaks at 10 million users, EFnet peaks at 141,000 users
  • 2004: (Facebook founded), Undernet peaks at 159,000 users
  • 2005: Quakenet peaks at 242,000 users, IRCnet peaks at 136,000 (Youtube founded)
  • 2006: (Twitter founded)
  • 2009: (WhatsApp, Pinterest founded)
  • 2010: (TextSecure AKA Signal, Instagram founded)
  • 2011: (Snapchat founded)
  • ~2013: Freenode peaks at ~100,000 users
  • 2016: IRCv3 standardisation effort started (TikTok founded)
  • 2021: Freenode self-destructs, Libera chat founded
  • 2022: Libera peaks at 50,000 users, OFTC peaks at 30,000 users
(The numbers were taken from the Wikipedia page and Netsplit.de. Note that I also include other networks launch in parenthesis for context.) Pretty dramatic, don't you think? Eventually, somehow, IRC became irrelevant for most people: few people are even aware of it now. With less than a million users active, it's smaller than Mastodon, XMPP, or Matrix at this point.1 If I were to venture a guess, I'd say that infighting, lack of a standardization body, and a somewhat annoying protocol meant the network could not grow. It's also possible that the decentralised yet centralised structure of IRC networks limited their reliability and growth. But large social media companies have also taken over the space: observe how IRC numbers peak around the time the wave of large social media companies emerge, especially Facebook (2.9B users!!) and Twitter (400M users).

Where the federated services are in history Right now, Matrix, and Mastodon (and email!) are at the "pre-EFnet" stage: anyone can join the federation. Mastodon has started working on a global block list of fascist servers which is interesting, but it's still an open federation. Right now, Matrix is totally open, but matrix.org publishes a (federated) block list of hostile servers (#matrix-org-coc-bl:matrix.org, yes, of course it's a room). Interestingly, Email is also in that stage, where there are block lists of spammers, and it's a race between those blockers and spammers. Large email providers, obviously, are getting closer to the EFnet stage: you could consider they only accept email from themselves or between themselves. It's getting increasingly hard to deliver mail to Outlook and Gmail for example, partly because of bias against small providers, but also because they are including more and more machine-learning tools to sort through email and those systems are, fundamentally, unknowable. It's not quite the same as splitting the federation the way EFnet did, but the effect is similar. HTTP has somehow managed to live in a parallel universe, as it's technically still completely federated: anyone can start a web server if they have a public IP address and anyone can connect to it. The catch, of course, is how you find the darn thing. Which is how Google became one of the most powerful corporations on earth, and how they became the gatekeepers of human knowledge online. I have only briefly mentioned XMPP here, and my XMPP fans will undoubtedly comment on that, but I think it's somewhere in the middle of all of this. It was co-opted by Facebook and Google, and both corporations have abandoned it to its fate. I remember fondly the days where I could do instant messaging with my contacts who had a Gmail account. Those days are gone, and I don't talk to anyone over Jabber anymore, unfortunately. And this is a threat that Matrix still has to face. It's also the threat Email is currently facing. On the one hand corporations like Facebook want to completely destroy it and have mostly succeeded: many people just have an email account to register on things and talk to their friends over Instagram or (lately) TikTok (which, I know, is not Facebook, but they started that fire). On the other hand, you have corporations like Microsoft and Google who are still using and providing email services because, frankly, you still do need email for stuff, just like fax is still around but they are more and more isolated in their own silo. At this point, it's only a matter of time they reach critical mass and just decide that the risk of allowing external mail coming in is not worth the cost. They'll simply flip the switch and work on an allow-list principle. Then we'll have closed the loop and email will be dead, just like IRC is "dead" now. I wonder which path Matrix will take. Could it liberate us from these vicious cycles? Update: this generated some discussions on lobste.rs.

  1. According to Wikipedia, there are currently about 500 distinct IRC networks operating, on about 1,000 servers, serving over 250,000 users. In contrast, Mastodon seems to be around 5 million users, Matrix.org claimed at FOSDEM 2021 to have about 28 million globally visible accounts, and Signal lays claim to over 40 million souls. XMPP claims to have "millions" of users on the xmpp.org homepage but the FAQ says they don't actually know. On the proprietary silo side of the fence, this page says
    • Facebook: 2.9 billion users
    • WhatsApp: 2B
    • Instagram: 1.4B
    • TikTok: 1B
    • Snapchat: 500M
    • Pinterest: 480M
    • Twitter: 397M
    Notable omission from that list: Youtube, with its mind-boggling 2.6 billion users... Those are not the kind of numbers you just "need to convince a brother or sister" to grow the network...

16 June 2022

Dima Kogan: Ricoh GR IIIx 802.11 reverse engineering

I just got a fancy new camera: Ricoh GR IIIx. It's pretty great, and I strongly recommend it to anyone that wants a truly pocketable camera with fantastic image quality and full manual controls. One annoyance is the connectivity. It does have both Bluetooth and 802.11, but the only official method of using them is some dinky closed phone app. This is silly. I just did some reverse-engineering, and I now have a functional shell script to download the last few images via 802.11. This is more convenient than plugging in a wire or pulling out the memory card. Fortunately, Ricoh didn't bend over backwards to make the reversing difficult, so to figure it out I didn't even need to download the phone app, and sniff the traffic. When you turn on the 802.11 on the camera, it says stuff about essid and password, so clearly the camera runs its own access point. Not ideal, but it's good-enough. I connected, and ran nmap to find hosts and open ports: only port 80 on 192.168.0.1 is open. Pointing curl at it yields some error, so I need to figure out the valid endpoints. I downloaded the firmware binary, and tried to figure out what's in it:
dima@shorty:/tmp$ binwalk fwdc243b.bin
DECIMAL       HEXADECIMAL     DESCRIPTION
--------------------------------------------------------------------------------
3036150       0x2E53F6        Cisco IOS microcode, for "8"
3164652       0x3049EC        Certificate in DER format (x509 v3), header length: 4, sequence length: 5412
5472143       0x537F8F        Copyright string: "Copyright ("
6128763       0x5D847B        PARity archive data - file number 90
10711634      0xA37252        gzip compressed data, maximum compression, from Unix, last modified: 2022-02-15 05:47:23
13959724      0xD5022C        MySQL ISAM compressed data file Version 11
24829873      0x17ADFB1       MySQL MISAM compressed data file Version 4
24917663      0x17C369F       MySQL MISAM compressed data file Version 4
24918526      0x17C39FE       MySQL MISAM compressed data file Version 4
24921612      0x17C460C       MySQL MISAM compressed data file Version 4
24948153      0x17CADB9       MySQL MISAM compressed data file Version 4
25221672      0x180DA28       MySQL MISAM compressed data file Version 4
25784158      0x1896F5E       Cisco IOS microcode, for "\"
26173589      0x18F6095       MySQL MISAM compressed data file Version 4
28297588      0x1AFC974       MySQL ISAM compressed data file Version 6
28988307      0x1BA5393       MySQL ISAM compressed data file Version 3
28990184      0x1BA5AE8       MySQL MISAM index file Version 3
29118867      0x1BC5193       MySQL MISAM index file Version 3
29449193      0x1C15BE9       JPEG image data, JFIF standard 1.01
29522133      0x1C278D5       JPEG image data, JFIF standard 1.08
29522412      0x1C279EC       Copyright string: "Copyright ("
29632931      0x1C429A3       JPEG image data, JFIF standard 1.01
29724094      0x1C58DBE       JPEG image data, JFIF standard 1.01
The gzip chunk looks like what I want:
dima@shorty:/tmp$ tail -c+10711635 fwdc243b.bin> /tmp/tst.gz
dima@shorty:/tmp$ < /tmp/tst.gz gunzip   file -
/dev/stdin: ASCII cpio archive (SVR4 with no CRC)
dima@shorty:/tmp$ < /tmp/tst.gz gunzip > tst.cpio
OK, we have some .cpio thing. It's plain-text. I grep around it in, looking for GET and POST and such, and I see various URI-looking things at /v1/..... Grepping for that I see
dima@shorty:/tmp$ strings tst.cpio   grep /v1/
GET /v1/debug/revisions
GET /v1/ping
GET /v1/photos
GET /v1/props
PUT /v1/params/device
PUT /v1/params/lens
PUT /v1/params/camera
GET /v1/liveview
GET /v1/transfers
POST /v1/device/finish
POST /v1/device/wlan/finish
POST /v1/lens/focus
POST /v1/camera/shoot
POST /v1/camera/shoot/compose
POST /v1/camera/shoot/cancel
GET /v1/photos/ / 
GET /v1/photos/ / /info
PUT /v1/photos/ / /transfer
/v1/photos/<string>/<string>
/v1/photos/<string>/<string>/info
/v1/photos/<string>/<string>/transfer
/v1/device/finish
/v1/device/wlan/finish
/v1/lens/focus
/v1/camera/shoot
/v1/camera/shoot/compose
/v1/camera/shoot/cancel
/v1/changes
/v1/changes message received.
/v1/changes issue event.
/v1/changes new websocket connection.
/v1/changes websocket connection closed. reason( )
/v1/transfers, transferState( ), afterIndex( ), limit( )
Jackpot. I pointed curl at most of these, and they do interesting things. Generally they all spit out JSON. /v1/liveview sends out a sequence of JPEG images. The thing I care about is /v1/photos/DIRECTORY/FILE and /v1/photos/DIRECTORY/FILE/info. The result is a script I just wrote to connect to the camera, download N images, and connect back to the original access point: https://github.com/dkogan/ricoh-download Kinda crude, but works for now. I'll improve it with time. After I did this I found an old thread from 2015 where somebody was using an apparently-compatible camera, and wrote a fancier tool: https://www.pentaxforums.com/forums/184-pentax-k-s1-k-s2/295501-k-s2-wifi-laptop-2.html

Dirk Eddelbuettel: RcppArmadillo 0.11.2.0.0 on CRAN: New Upstream

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 991 other packages on CRAN, downloaded over 25 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 476 times according to Google Scholar. This release brings a second upstream fix by Conrad in the release series 11.*. We once again tested this very rigorously via a complete reverse-depedency check (for which results are always logged here). It so happens that CRAN then had a spurious error when re-checking on upload, and it took a fews days to square this as everybody remains busy but the release prepared on June 10 is now on CRAN. The full set of changes (since the last CRAN release 0.11.1.1.0) follows.

Changes in RcppArmadillo version 0.11.2.0.0 (2022-06-10)
  • Upgraded to Armadillo release 11.2 (Classic Roast)
    • faster handling of sparse submatrix column views by norm(), accu(), nonzeros()
    • extended randu() and randn() to allow specification of distribution parameters
    • internal refactoring, leading to faster compilation times

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

15 June 2022

Dirk Eddelbuettel: AsioHeaders 1.22.1-1 on CRAN

An updated version of the AsioHeaders package arrived at CRAN yesterday (in one of those pleasant fully-automated uploads and transitions). Asio provides a cross-platform C++ library for network and low-level I/O programming. It is also included in Boost but requires linking when used as part of Boost. This standalone version of Asio is a header-only C++ library which can be used without linking (just like our BH package with parts of Boost). This release brings a new upstream version, following a two-year period without updated. This was tickled by OpenSSL 3.0 header changes as seen in a package using both AsioHeaders and OpenSSL.

Changes in version 1.22.1-1 (2022-06-14)
  • Upgraded to Asio 1.22.1 (Dirk in #7 fixing #6).

Thanks to my CRANberries, there is also a diffstat report relative to the previous release. Comments and suggestions about AsioHeaders are welcome via the issue tracker at the GitHub GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

11 June 2022

Louis-Philippe V ronneau: Updating a rooted Pixel 3a

A short while after getting a Pixel 3a, I decided to root it, mostly to have more control over the charging procedure. In order to preserve battery life, I like my phone to stop charging at around 75% of full battery capacity and to shut down automatically at around 12%. Some Android ROMs have extra settings to manage this, but LineageOS unfortunately does not. Android already comes with a fairly complex mechanism to handle the charge cycle, but it is mostly controlled by the kernel and cannot be easily configured by end-users. acc is a higher-level "systemless" interface for the Android kernel battery management, but one needs root to do anything interesting with it. Once rooted, you can use the AccA app instead of playing on the command line to fine tune your battery settings. Sadly, having a rooted phone also means I need to re-root it each time there is an OS update (typically each week). Somehow, I keep forgetting the exact procedure to do this! Hopefully, I will be able to use this post as a reference in the future :) Note that these instructions might not apply to your exact phone model, proceed with caution! Extract the boot.img file This procedure mostly comes from the LineageOS documentation on extracting proprietary blobs from the payload.
  1. Download the latest LineageOS image for your phone.
  2. unzip the image to get the payload.bin file inside it.
  3. Clone the LineageOS scripts git repository: $ git clone https://github.com/LineageOS/scripts
  4. extract the boot image (requires python3-protobuf): $ mkdir extracted-payload $ python3 scripts/update-payload-extractor/extract.py payload.bin --output_dir extracted-payload
You should now have a boot.img file. Patch the boot image file using Magisk
  1. Upload the boot.img file you previously extracted to your device.
  2. Open Magisk and patch the boot.img file.
  3. Download the patched file back on your computer.
Flash the patched boot image
  1. Enable ADB debug mode on your phone.
  2. Reboot into fastboot mode. $ adb reboot fastboot
  3. Flash the patched boot image file: $ fastboot flash boot magisk_patched-foo.img
  4. Disable ADB debug mode on your phone.
Troubleshooting In an ideal world, you would do this entire process each time you upgrade to a new LineageOS version. Sadly, this creates friction and makes updating much more troublesome. To simplify things, you can try to flash an old patched boot.img file after upgrading, instead of generating it each time. In my experience, it usually works. When it does not, the device behaves weirdly after a reboot and things that require proprietary blobs (like WiFi) will stop working. If that happens:
  1. Download the latest LineageOS version for your phone.
  2. Reboot into recovery (Power + Volume Down).
  3. Click on "Apply Updates"
  4. Sideload the ROM: $ adb sideload lineageos-foo.zip

10 June 2022

Sam Hartman: Flailing to Replace Jack with Pipewire for DJ Audio

I could definitely use some suggestions here, both in terms of things to try or effective places to ask questions about Pipewire audio. The docs are improving, but are still in early stages. Pipewire promises to combine the functionality of PulseAudio and Jack. That would be great for me. I use Jack for my DJ work, and it s somewhat complicated and fragile. However, so far my attempts to replace Jack have been unsuccessful, and I might need to even use PulseAudio instead of Pipewire to get the DJ stuff working correctly. The Setup In the simplest setup I have a DJ controller. It s both a MIDI device and a sound card. It has 4 channel audio, but it s not typical surround sound. Two channels are the main speakers, and two channels are the headphones. Conceptually it might be better to model the controller as two sinks: one for the speakers and one for the headphones. At a hardware level they need to be one device for several reasons, especially including using a common clock. It s really important than only the main mix go out channel 1-2 (the speakers). Random beeps or sound from other applications going out the main speakers is disruptive and unprofessional. However, because I m blind, I need that sound. I especially need the output of Orca (my screen reader) and Emacspeak (another screen reader). So I need that output to go to the headphones. Under Pulse/Jack The DJ card is the Jack primary sound device (system:playback_1 through system:playback_4). I then use themodule-jack-sink Pulse module to connect Pulse to Jack. That becomes the default sink for Pulse, and I link front-left from that sink to system:playback_3. So, I get the system sounds and screen reader mixed into the left channel of my headphones and nowhere else. Enter Pipewire Initially Pipewire sees the DJ card as a 4-channel sound card and assumes it s surround4.0 (so front and rear left and right). It helpfully expands my stereo signal so that everything goes to the front and rear. So, exactly what I don t want to have happen happens: all my system sounds go out the main speakers (channel 1-2). It was easy to override Wireplumber s ALSA configuration and assign different channel positions. I tried assigning something like a1,a2,fl,fr hoping that Pipewire wouldn t mix things into aux channels that weren t part of the typical surround set. No luck. It did correctly reflect the channels in things like pacmd list sinks so my Pipewire config was being applied. But the sound was still wrong. * I tried turning off channelmix.upmix. That didn t help; that appears to be more about mixing stereo into center, rear and LFE. The basic approach of getting a stream to conform to the output node s channels appears to be hurting me here. I d love any ideas about how I can get this to work. I m sure it s simple I m just missing the right mental model or knowledge of how to configure things. Pipewire Not Talking to Jack I thought I could at least use Pipewire the same way I use Pulse. Namely, I can run a real jackd and connect up Pipewire to that server. According to the wiki, Pipewire can be a Jack client. It s disabled by default, because you need to make sure that Wireplumber is using the real Jack libraries rather than the Pipewire replacements. That s the case on Debian, so I enabled the feature. A Jack device appeared in wpctl status as did a Jack sink. Using jack_lsp on that device showed it was talking to the Jack server and connected to system:playback_*. Unfortunately, it doesn t work. The sink does not show up in pacmd list sinks, and pipewire-pulse gives an error about it not being ready. If I select it as the default sink in wpctl set-default I get no sound at all, at least from Pulse applications. Versions of things This is all on debian, approximately testing/bookworm or newer for the relevant libraries.

comment count unavailable comments

1 June 2022

Daniel Lange: Get Youtube Channel ID from username

Youtube has a really nice RSS feature that is extremely well hidden. If you postfix a Channel ID to

https://www.youtube.com/feeds/videos.xml?channel_id=<id goes here>
you get a really nice Atom 1.0 (~RSS) feed for your feedreader. Unfortunately the Channel ID is hard to find while you are navigating Youtube with usernames in the URL. E.g. https://www.youtube.com/c/TED is TED's channel, full of interesting and worth-to-watch content (and some assorted horse toppings, of course). But you have to read a lot of ugly HTML / JSON in that page to find and combine https://www.youtube.com/feeds/videos.xml?channel_id=UCAuUUnT6oDeKwE6v1NGQxug which is the related RSS feed. Jeff Keeling wrote a simple Youtube RSS Extractor that does well if you have a ../playlist?... or a .../channel/... URL but it will (currently) fail on user name channels or Youtube landing pages. So how do we get the Channel ID for a Youtube user we are interested to follow? Youtube has a great API but that is gated by API keys even for the most simple calls (that came only with v3 of the API but the previous version is depreciated since 2015)1:
dl@laptop:~$ curl 'https://www.googleapis.com/youtube/v3/channels?part=contentDetails&forUsername=DebConfVideos'

"error":
"code": 403,
"message": "The request is missing a valid API key.",
"errors": [

"message": "The request is missing a valid API key.",
"domain": "global",
"reason": "forbidden"

],
"status": "PERMISSION_DENIED"

Luckily we can throw the same (example) user name DebConfVideos at curl and grep:
dl@laptop:~$ curl -s "https://www.youtube.com/c/DebConfVideos/videos" grep -Po '"channelId":".+?"'
"channelId":"UC7SbfAPZf8SMvAxp8t51qtQ"
So https://www.youtube.com/feeds/videos.xml?channel_id=UC7SbfAPZf8SMvAxp8t51qtQ is the RSS feed for DebConfVideos. We can use individual Youtube video URLs as well. With the hack above, it'll work to find us the Chanel ID from a Youtube video URL: Working around the Youtube API restrictions to still make use of their RSS feed Now, some user pages may have multiple valid RSS feeds because they contain multiple channels. Remember the TED page from above? Well run:
dl@laptop:~$ curl -s "https://www.youtube.com/c/TED" grep -Po '"channelId":".+?"' cut -d \" -f 4 while read -r YTID ; do echo -n "Youtube-ID: $YTID " ; curl -s "https://www.youtube.com/feeds/videos.xml?channel_id=$YTID" grep -m 1 -P -o "(?<=<title>).+(?=</title>)" ; done
This will iterate through the Channel IDs found and show you the titles. That way you can assess which one you want to add to your feedreader. screenshot of the above You probably want the last Channel ID listed above, the non-selective "TED" one. And that's the one from the example above. Update 02.06.2022: smpl wrote in and has the much better solution for the most frequent use cases:
You can also use get a feed directly with a username:
https://www.youtube.com/feeds/videos.xml?user=<username>
The one I use most is the one for playlists (if creators remember to
use them).
https://www.youtube.com/feeds/videos.xml?playlist_id=<playlist id>
For the common case you don't even need the channel ID that way. But it is also conveniently given in a <yt:channelId> tag (or the topmost <id> tag) within the Atom XML document. Thanks, smpl!

  1. Actually it is even more complicated as some channels, like our DebConfVideos example, will only get you an incomplete result, cf. this StackOverflow entry. I.e. the forUsername iterator may not even work and the "best practice" seems to be mucking around with the search call.

31 May 2022

Russ Allbery: Review: Maskerade

Review: Maskerade, by Terry Pratchett
Series: Discworld #18
Publisher: Harper
Copyright: 1995
Printing: February 2014
ISBN: 0-06-227552-6
Format: Mass market
Pages: 360
Maskerade is the 18th book of the Discworld series, but you probably could start here. You'd miss the introduction of Granny Weatherwax and Nanny Ogg, which might be a bit confusing, but I suspect you could pick it up as you went if you wanted. This is a sequel of sorts to Lords and Ladies, but not in a very immediate sense. Granny is getting distracted and less interested in day-to-day witching in Lancre. This is not good; Granny is incredibly powerful, and bored and distracted witches can go to dark places. Nanny is concerned. Granny needs something to do, and their coven needs a third. It's not been the same since they lost their maiden member. Nanny's solution to this problem is two-pronged. First, they'd had their eye on a local girl named Agnes, who had magic but who wasn't interested in being a witch. Perhaps it was time to recruit her anyway, even though she'd left Lancre for Ankh-Morpork. And second, Granny needs something to light a fire under her, something that will get her outraged and ready to engage with the world. Something like a cookbook of aphrodisiac recipes attributed to the Witch of Lancre. Agnes, meanwhile, is auditioning for the opera. She's a sensible person, cursed her whole life by having a wonderful personality, but a part of her deep inside wants to be called Perdita X. Dream and have a dramatic life. Having a wonderful personality can be very frustrating, but no one in Lancre took either that desire or her name seriously. Perhaps the opera is somewhere where she can find the life she's looking for, along with another opportunity to try on the Perdita name. One thing she can do is sing; that's where all of her magic went. The Ankh-Morpork opera is indeed dramatic. It's also losing an astounding amount of money for its new owner, who foolishly thought owning an opera would be a good retirement project after running a cheese business. And it's haunted by a ghost, a very tangible ghost who has started killing people. I think this is my favorite Discworld novel to date (although with a caveat about the ending that I'll get to in a moment). It's certainly the one that had me laughing out loud the most. Agnes (including her Perdita personality aspect) shot to the top of my list of favorite Discworld characters, in part because I found her sensible personality so utterly relatable. She is fascinated by drama, she wants to be in the middle of it and let her inner Perdita goth character revel in it, and yet she cannot help being practical and unflappable even when surrounded by people who use far too many exclamation points. It's one thing to want drama in the abstract; it's quite another to be heedlessly dramatic in the moment, when there's an obviously reasonable thing to do instead. Pratchett writes this wonderfully. The other half of the story follows Granny and Nanny, who are unstoppable forces of nature and a wonderful team. They have the sort of long-standing, unshakable adult friendship between very unlike people that's full of banter and minor irritations layered on top of a deep mutual understanding and respect. Once they decide to start investigating this supposed opera ghost, they divvy up the investigative work with hardly a word exchanged. Planning isn't necessary; they both know each other's strengths. We've gotten a lot of Granny's skills in previous books. Maskerade gives Nanny a chance to show off her skills, and it's a delight. She effortlessly becomes the sort of friendly grandmother who blends in so well that no one questions why she's there, and thus manages to be in the middle of every important event. Granny watches and thinks and theorizes; Nanny simply gets into the middle of everything and talks to everyone until people tell her what she wants to know. There's no real doubt that the two of them are going to get to the bottom of anything they want to get to the bottom of, but watching how they get there is a delight. I love how Pratchett handles that sort of magical power from a world-building perspective. Ankh-Morpork is the Big City, the center of political power in most of the Discworld books, and Granny and Nanny are from the boondocks. By convention, that means they should either be awed or confused by the city, or gain power in the city by transforming it in some way to match their area of power. This isn't how Pratchett writes witches at all. Their magic is in understanding people, and the people in Ankh-Morpork are just as much people as the people in Lancre. The differences of the city may warrant an occasional grumpy aside, but the witches are fully as capable of navigating the city as they are their home town. Maskerade is, of course, a parody of opera and musicals, with Phantom of the Opera playing the central role in much the same way that Macbeth did in Wyrd Sisters. Agnes ends up doing the singing for a beautiful, thin actress named Christine, who can't sing at all despite being an opera star, uses a truly astonishing excess of exclamation points, and strategically faints at the first sign of danger. (And, despite all of this, is still likable in that way that it's impossible to be really upset at a puppy.) She is the special chosen focus of the ghost, whose murderous taunting is a direct parody of the Phantom. That was a sufficiently obvious reference that even I picked up on it, despite being familiar with Phantom of the Opera only via the soundtrack. Apart from that, though, the references were lost on me, since I'm neither a musical nor an opera fan. That didn't hurt my enjoyment of the book in the slightest; in fact, I suspect it's part of why it's in my top tier of Discworld books. One of my complaints about Discworld to date is that Pratchett often overdoes the parody to the extent that it gets in the way of his own (excellent) characters and story. Maybe it's better to read Discworld novels where one doesn't recognize the material being parodied and thus doesn't keep getting distracted by references. It's probably worth mentioning that Agnes is a large woman and there are several jokes about her weight in Maskerade. I think they're the good sort of jokes, about how absurd human bodies can be, not the mean sort? Pratchett never implies her weight is any sort of moral failing or something she should change; quite the contrary, Nanny considers it a sign of solid Lancre genes. But there is some fat discrimination in the opera itself, since one of the things Pratchett is commenting on is the switch from full-bodied female opera singers to thin actresses matching an idealized beauty standard. Christine is the latter, but she can't sing, and the solution is for Agnes to sing for her from behind, something that was also done in real opera. I'm not a good judge of how well this plot line was handled; be aware, going in, if this may bother you. What did bother me was the ending, and more generally the degree to which Granny and Nanny felt comfortable making decisions about Agnes's life without consulting her or appearing to care what she thought of their conclusions. Pratchett seemed to be on their side, emphasizing how well they know people. But Agnes left Lancre and avoided the witches for a reason, and that reason is not honored in much the same way that Lancre refused to honor her desire to go by Perdita. This doesn't seem to be malicious, and Agnes herself is a little uncertain about her choice of identity, but it still rubbed me the wrong way. I felt like Agnes got steamrolled by both the other characters and by Pratchett, and it's the one thing about this book that I didn't like. Hopefully future Discworld books about these characters revisit Agnes's agency. Overall, though, this was great, and a huge improvement over Interesting Times. I'm excited for the next witches book. Followed in publication order by Feet of Clay, and later by Carpe Jugulum in the thematic sense. Rating: 8 out of 10

30 May 2022

Daniel Lange: Work-around for randomly dropping WiFi connections on ChromeOS

The company got me a Chromebook for times when I want to ignore email and not get dragged into code reviews but still be available on IRC and chat. Nifty devices at great price points. I really like them. Chromebook logo These things are meant to be very consumer-style end-user devices. You log in with your Google account and everything works. Until it doesn't. Just setting it up caused the first issue: I was always thrown back to a black screen and then another login-screen despite having successfully logged in initially to create the "owner" user of the Chromebook. No error message, not useful UI feedback. Just logging in again and again and again. The issue is ... not having a GMail account associated with my Google account. Duh! So add a GMail.com address as the primary to your Google account and the initial setup completes. Of course you cannot delete that GMail.com association again because the owner user is linked to the email and not the account. Well, you can delete it but then you cannot configure "owner" items of your Chromebook any more. Great job, Google. Not. Identity management 101 fail. Kudos to Anurag Chawake for blogging about the issue. The Google support forum thead claims this is solved now. But it didn't work for me, so this may be needing to trickle down through ChromeOS releases or be deployed on more Google infra. Or whatever. We can't tell from outside the Googleplex as - of course - "Rebecca" sheds no light on what the identified "root cause" was: Google Forum answer Once I was able to login to the new Chromebook all worked fine until I started to use ssh sessions. These always hung for 30 seconds to 10 minutes and then resumed with lots of packets lost in between and the last minute or so coming in from buffering in a burst. This was easy to see in ping as well. The connection essentially dropped dead while the WiFi icon was continuing to show full signal strength. The logs did not show anything useful. These are really hard to access on ChromeOS (JSON format and no useful UI on the Chromebook itself, Google provides a viewer on Google Apps Toolbox but that requires uploading the logs). Better than no logs at all but not really nice. The ChromeOS bug tracker and its Google corporate counterpart are also not useful at this time. For reference:
Google ... Device users randomly disconnect from Wi-Fi network
Chromium ... Device users randomly disconnect from Wi-Fi network
Google ... Constant connect and disconnect from WiFi source post-update
Chromium ... Constant connect and disconnect from WiFi source post-update Playing around with the device on the network showed that it reduced sending power beyond being able to reach the access point any more. This is why disconnecting and re-connecting the WiFi fixes the issue for a few minutes, typically. Still, there is a better way: In crosh (the ChromeOS shell available when pressing Alt+Ctrl+T) type:
wifi_power_save disable
Crosh session screenshot This unfortunately only lasts until the next reboot but it does persist over suspend cycles (aka closing the lid).

29 May 2022

John Goerzen: Fast, Ordered Unixy Queues over NNCP and Syncthing with Filespooler

It seems that lately I ve written several shell implementations of a simple queue that enforces ordered execution of jobs that may arrive out of order. After writing this for the nth time in bash, I decided it was time to do it properly. But first, a word on the why of it all.

Why did I bother? My needs arose primarily from handling Backups over Asynchronous Communication methods in this case, NNCP. When backups contain incrementals that are unpacked on the destination, they must be applied in the correct order. In some cases, like ZFS, the receiving side will detect an out-of-order backup file and exit with an error. In those cases, processing in random order is acceptable but can be slow if, say, hundreds or thousands of hourly backups have stacked up over a period of time. The same goes for using gitsync-nncp to synchronize git repositories. In both cases, a best effort based on creation date is sufficient to produce a significant performance improvement. With other cases, such as tar or dar backups, the receiving cannot detect out of order incrementals. In those situations, the incrementals absolutely must be applied with strict ordering. There are many other situations that arise with these needs also. Filespooler is the answer to these.

Existing Work Before writing my own program, I of course looked at what was out there already. I looked at celeary, gearman, nq, rq, cctools work queue, ts/tsp (task spooler), filequeue, dramatiq, GNU parallel, and so forth. Unfortunately, none of these met my needs at all. They all tended to have properties like:
  • An extremely complicated client/server system that was incompatible with piping data over existing asynchronous tools
  • A large bias to processing of small web requests, resulting in terrible inefficiency or outright incompatibility with jobs in the TB range
  • An inability to enforce strict ordering of jobs, especially if they arrive in a different order from how they were queued
Many also lacked some nice-to-haves that I implemented for Filespooler:
  • Support for the encryption and cryptographic authentication of jobs, including metadata
  • First-class support for arbitrary compressors
  • Ability to use both stream transports (pipes) and filesystem-like transports (eg, rclone mount, S3, Syncthing, or Dropbox)

Introducing Filespooler Filespooler is a tool in the Unix tradition: that is, do one thing well, and integrate nicely with other tools using the fundamental Unix building blocks of files and pipes. Filespooler itself doesn t provide transport for jobs, but instead is designed to cooperate extremely easily with transports that can be written to as a filesystem or piped to which is to say, almost anything of interest. Filespooler is written in Rust and has an extensive Filespooler Reference as well as many tutorials on its homepage. To give you a few examples, here are some links:

Basics of How it Works Filespooler is intentionally simple:
  • The sender maintains a sequence file that includes a number for the next job packet to be created.
  • The receiver also maintains a sequence file that includes a number for the next job to be processed.
  • fspl prepare creates a Filespooler job packet and emits it to stdout. It includes a small header (<100 bytes in most cases) that includes the sequence number, creation timestamp, and some other useful metadata.
  • You get to transport this job packet to the receiver in any of many simple ways, which may or may not involve Filespooler s assistance.
  • On the receiver, Filespooler (when running in the default strict ordering mode) will simply look at the sequence file and process jobs in incremental order until it runs out of jobs to process.
The name of job files on-disk matches a pattern for identification, but the content of them is not significant; only the header matters. You can send job data in three ways:
  1. By piping it to fspl prepare
  2. By setting certain environment variables when calling fspl prepare
  3. By passing additional command-line arguments to fspl prepare, which can optionally be passed to the processing command at the receiver.
Data piped in is added to the job payload , while environment variables and command-line parameters are encoded in the header.

Basic usage Here I will excerpt part of the Using Filespooler over Syncthing tutorial; consult it for further detail. As a bit of background, Syncthing is a FLOSS decentralized directory synchronization tool akin to Dropbox (but with a much richer feature set in many ways).

Preparation First, on the receiver, you create the queue (passing the directory name to -q):
sender$ fspl queue-init -q ~/sync/b64queue
Now, we can send a job like this:
sender$ echo Hi   fspl prepare -s ~/b64seq -i -   fspl queue-write -q ~/sync/b64queue
Let s break that down:
  • First, we pipe Hi to fspl prepare.
  • fspl prepare takes two parameters:
    • -s seqfile gives the path to a sequence file used on the sender side. This file has a simple number in it that increments a unique counter for every generated job file. It is matched with the nextseq file within the queue to make sure that the receiver processes jobs in the correct order. It MUST be separate from the file that is in the queue and should NOT be placed within the queue. There is no need to sync this file, and it would be ideal to not sync it.
    • The -i option tells fspl prepare to read a file for the packet payload. -i - tells it to read stdin for this purpose. So, the payload will consist of three bytes: Hi\n (that is, including the terminating newline that echo wrote)
  • Now, fspl prepare writes the packet to its stdout. We pipe that into fspl queue-write:
    • fspl queue-write reads stdin and writes it to a file in the queue directory in a safe manner. The file will ultimately match the fspl-*.fspl pattern and have a random string in the middle.
At this point, wait a few seconds (or however long it takes) for the queue files to be synced over to the recipient. On the receiver, we can see if any jobs have arrived yet:
receiver$ fspl queue-ls -q ~/sync/b64queue
ID                   creation timestamp          filename
1                    2022-05-16T20:29:32-05:00   fspl-7b85df4e-4df9-448d-9437-5a24b92904a4.fspl
Let s say we d like some information about the job. Try this:
receiver$ $ fspl queue-info -q ~/sync/b64queue -j 1
FSPL_SEQ=1
FSPL_CTIME_SECS=1652940172
FSPL_CTIME_NANOS=94106744
FSPL_CTIME_RFC3339_UTC=2022-05-17T01:29:32Z
FSPL_CTIME_RFC3339_LOCAL=2022-05-16T20:29:32-05:00
FSPL_JOB_FILENAME=fspl-7b85df4e-4df9-448d-9437-5a24b92904a4.fspl
FSPL_JOB_QUEUEDIR=/home/jgoerzen/sync/b64queue
FSPL_JOB_FULLPATH=/home/jgoerzen/sync/b64queue/jobs/fspl-7b85df4e-4df9-448d-9437-5a24b92904a4.fspl
This information is intentionally emitted in a format convenient for parsing. Now let s run the job!
receiver$ fspl queue-process -q ~/sync/b64queue --allow-job-params base64
SGkK
There are two new parameters here:
  • --allow-job-params says that the sender is trusted to supply additional parameters for the command we will be running.
  • base64 is the name of the command that we will run for every job. It will:
    • Have environment variables set as we just saw in queue-info
    • Have the text we previously prepared Hi\n piped to it
By default, fspl queue-process doesn t do anything special with the output; see Handling Filespooler Command Output for details on other options. So, the base64-encoded version of our string is SGkK . We successfully sent a packet using Syncthing as a transport mechanism! At this point, if you do a fspl queue-ls again, you ll see the queue is empty. By default, fspl queue-process deletes jobs that have been successfully processed.

For more See the Filespooler homepage.
This blog post is also available as a permanent, periodically-updated page.

26 May 2022

Sergio Talens-Oliag: New Blog Config

As promised, on this post I m going to explain how I ve configured this blog using hugo, asciidoctor and the papermod theme, how I publish it using nginx, how I ve integrated the remark42 comment system and how I ve automated its publication using gitea and json2file-go. It is a long post, but I hope that at least parts of it can be interesting for some, feel free to ignore it if that is not your case
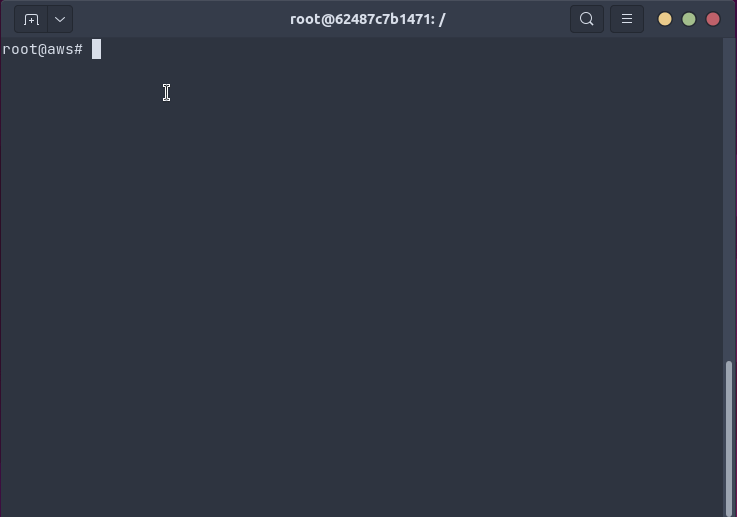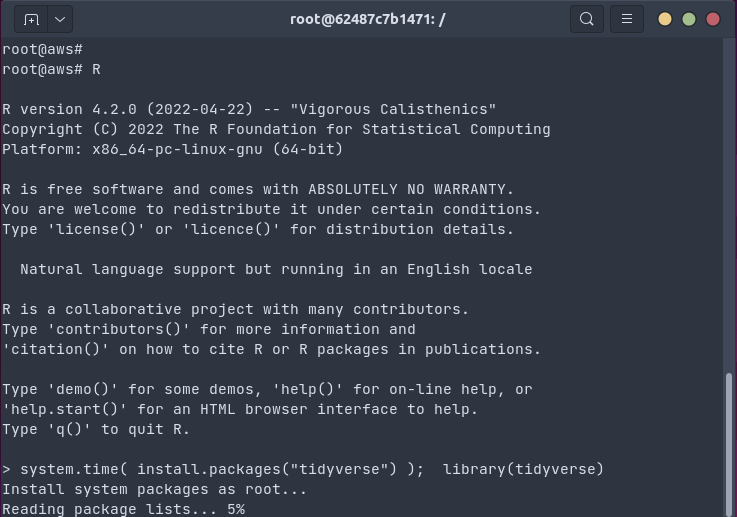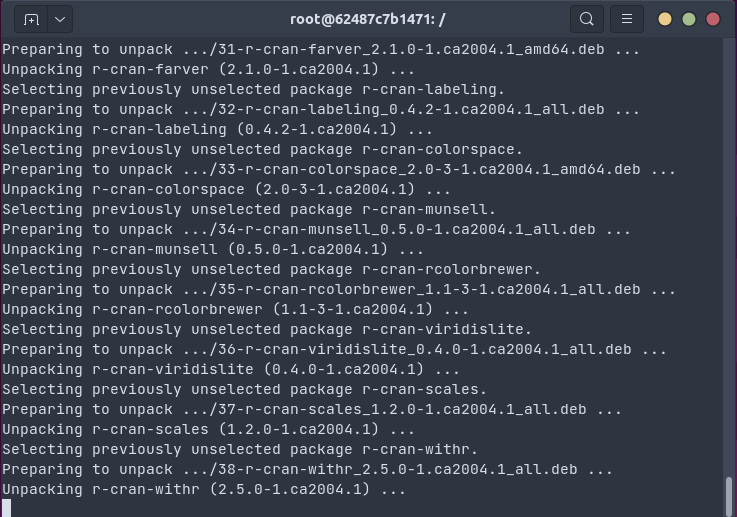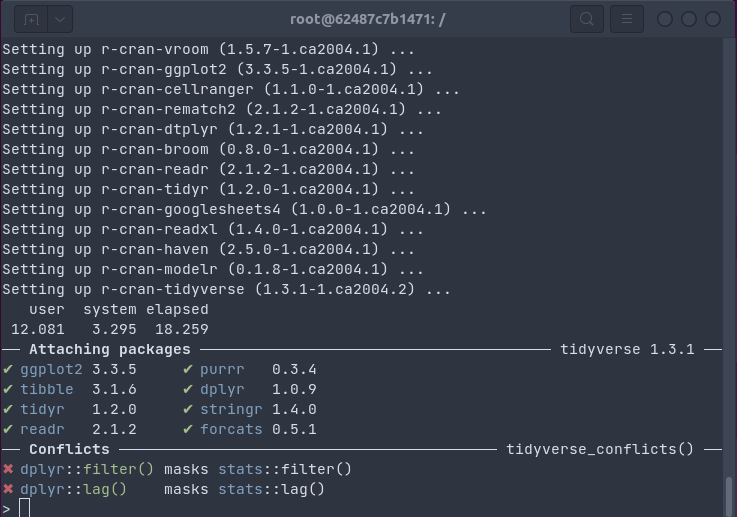
Hugo Configuration

Theme settingsThe site is using the PaperMod theme and as I m using asciidoctor to publish my content I ve adjusted the settings to improve how things are shown with it. The current config.yml file is the one shown below (probably some of the settings are not required nor being used right now, but I m including the current file, so this post will have always the latest version of it):
config.yml
baseURL: https://blogops.mixinet.net/
title: Mixinet BlogOps
paginate: 5
theme: PaperMod
destination: public/
enableInlineShortcodes: true
enableRobotsTXT: true
buildDrafts: false
buildFuture: false
buildExpired: false
enableEmoji: true
pygmentsUseClasses: true
minify:
  disableXML: true
  minifyOutput: true
languages:
  en:
    languageName: "English"
    description: "Mixinet BlogOps - https://blogops.mixinet.net/"
    author: "Sergio Talens-Oliag"
    weight: 1
    title: Mixinet BlogOps
    homeInfoParams:
      Title: "Sergio Talens-Oliag Technical Blog"
      Content: >
        ![Mixinet BlogOps](/images/mixinet-blogops.png)
    taxonomies:
      category: categories
      tag: tags
      series: series
    menu:
      main:
        - name: Archive
          url: archives
          weight: 5
        - name: Categories
          url: categories/
          weight: 10
        - name: Tags
          url: tags/
          weight: 10
        - name: Search
          url: search/
          weight: 15
outputs:
  home:
    - HTML
    - RSS
    - JSON
params:
  env: production
  defaultTheme: light
  disableThemeToggle: false
  ShowShareButtons: true
  ShowReadingTime: true
  disableSpecial1stPost: true
  disableHLJS: true
  displayFullLangName: true
  ShowPostNavLinks: true
  ShowBreadCrumbs: true
  ShowCodeCopyButtons: true
  ShowRssButtonInSectionTermList: true
  ShowFullTextinRSS: true
  ShowToc: true
  TocOpen: false
  comments: true
  remark42SiteID: "blogops"
  remark42Url: "/remark42"
  profileMode:
    enabled: false
    title: Sergio Talens-Oliag Technical Blog
    imageUrl: "/images/mixinet-blogops.png"
    imageTitle: Mixinet BlogOps
    buttons:
      - name: Archives
        url: archives
      - name: Categories
        url: categories
      - name: Tags
        url: tags
  socialIcons:
    - name: CV
      url: "https://www.uv.es/~sto/cv/"
    - name: Debian
      url: "https://people.debian.org/~sto/"
    - name: GitHub
      url: "https://github.com/sto/"
    - name: GitLab
      url: "https://gitlab.com/stalens/"
    - name: Linkedin
      url: "https://www.linkedin.com/in/sergio-talens-oliag/"
    - name: RSS
      url: "index.xml"
  assets:
    disableHLJS: true
    favicon: "/favicon.ico"
    favicon16x16:  "/favicon-16x16.png"
    favicon32x32:  "/favicon-32x32.png"
    apple_touch_icon:  "/apple-touch-icon.png"
    safari_pinned_tab:  "/safari-pinned-tab.svg"
  fuseOpts:
    isCaseSensitive: false
    shouldSort: true
    location: 0
    distance: 1000
    threshold: 0.4
    minMatchCharLength: 0
    keys: ["title", "permalink", "summary", "content"]
markup:
  asciidocExt:
    attributes:  
    backend: html5s
    extensions: ['asciidoctor-html5s','asciidoctor-diagram']
    failureLevel: fatal
    noHeaderOrFooter: true
    preserveTOC: false
    safeMode: unsafe
    sectionNumbers: false
    trace: false
    verbose: false
    workingFolderCurrent: true
privacy:
  vimeo:
    disabled: false
    simple: true
  twitter:
    disabled: false
    enableDNT: true
    simple: true
  instagram:
    disabled: false
    simple: true
  youtube:
    disabled: false
    privacyEnhanced: true
services:
  instagram:
    disableInlineCSS: true
  twitter:
    disableInlineCSS: true
security:
  exec:
    allow:
      - '^asciidoctor$'
      - '^dart-sass-embedded$'
      - '^go$'
      - '^npx$'
      - '^postcss$'
Some notes about the settings:
  • disableHLJS and assets.disableHLJS are set to true; we plan to use rouge on adoc and the inclusion of the hljs assets adds styles that collide with the ones used by rouge.
  • ShowToc is set to true and the TocOpen setting is set to false to make the ToC appear collapsed initially. My plan was to use the asciidoctor ToC, but after trying I believe that the theme one looks nice and I don t need to adjust styles, although it has some issues with the html5s processor (the admonition titles use <h6> and they are shown on the ToC, which is weird), to fix it I ve copied the layouts/partial/toc.html to my site repository and replaced the range of headings to end at 5 instead of 6 (in fact 5 still seems a lot, but as I don t think I ll use that heading level on the posts it doesn t really matter).
  • params.profileMode values are adjusted, but for now I ve left it disabled setting params.profileMode.enabled to false and I ve set the homeInfoParams to show more or less the same content with the latest posts under it (I ve added some styles to my custom.css style sheet to center the text and image of the first post to match the look and feel of the profile).
  • On the asciidocExt section I ve adjusted the backend to use html5s, I ve added the asciidoctor-html5s and asciidoctor-diagram extensions to asciidoctor and adjusted the workingFolderCurrent to true to make asciidoctor-diagram work right (haven t tested it yet).

Theme customisationsTo write in asciidoctor using the html5s processor I ve added some files to the assets/css/extended directory:
  1. As said before, I ve added the file assets/css/extended/custom.css to make the homeInfoParams look like the profile page and I ve also changed a little bit some theme styles to make things look better with the html5s output:
    custom.css
    /* Fix first entry alignment to make it look like the profile */
    .first-entry   text-align: center;  
    .first-entry img   display: inline;  
    /**
     * Remove margin for .post-content code and reduce padding to make it look
     * better with the asciidoctor html5s output.
     **/
    .post-content code   margin: auto 0; padding: 4px;  
  2. I ve also added the file assets/css/extended/adoc.css with some styles taken from the asciidoctor-default.css, see this blog post about the original file; mine is the same after formatting it with css-beautify and editing it to use variables for the colors to support light and dark themes:
    adoc.css
    /* AsciiDoctor*/
    table  
        border-collapse: collapse;
        border-spacing: 0
     
    .admonitionblock>table  
        border-collapse: separate;
        border: 0;
        background: none;
        width: 100%
     
    .admonitionblock>table td.icon  
        text-align: center;
        width: 80px
     
    .admonitionblock>table td.icon img  
        max-width: none
     
    .admonitionblock>table td.icon .title  
        font-weight: bold;
        font-family: "Open Sans", "DejaVu Sans", sans-serif;
        text-transform: uppercase
     
    .admonitionblock>table td.content  
        padding-left: 1.125em;
        padding-right: 1.25em;
        border-left: 1px solid #ddddd8;
        color: var(--primary)
     
    .admonitionblock>table td.content>:last-child>:last-child  
        margin-bottom: 0
     
    .admonitionblock td.icon [class^="fa icon-"]  
        font-size: 2.5em;
        text-shadow: 1px 1px 2px var(--secondary);
        cursor: default
     
    .admonitionblock td.icon .icon-note::before  
        content: "\f05a";
        color: var(--icon-note-color)
     
    .admonitionblock td.icon .icon-tip::before  
        content: "\f0eb";
        color: var(--icon-tip-color)
     
    .admonitionblock td.icon .icon-warning::before  
        content: "\f071";
        color: var(--icon-warning-color)
     
    .admonitionblock td.icon .icon-caution::before  
        content: "\f06d";
        color: var(--icon-caution-color)
     
    .admonitionblock td.icon .icon-important::before  
        content: "\f06a";
        color: var(--icon-important-color)
     
    .conum[data-value]  
        display: inline-block;
        color: #fff !important;
        background-color: rgba(100, 100, 0, .8);
        -webkit-border-radius: 100px;
        border-radius: 100px;
        text-align: center;
        font-size: .75em;
        width: 1.67em;
        height: 1.67em;
        line-height: 1.67em;
        font-family: "Open Sans", "DejaVu Sans", sans-serif;
        font-style: normal;
        font-weight: bold
     
    .conum[data-value] *  
        color: #fff !important
     
    .conum[data-value]+b  
        display: none
     
    .conum[data-value]::after  
        content: attr(data-value)
     
    pre .conum[data-value]  
        position: relative;
        top: -.125em
     
    b.conum *  
        color: inherit !important
     
    .conum:not([data-value]):empty  
        display: none
     
  3. The previous file uses variables from a partial copy of the theme-vars.css file that changes the highlighted code background color and adds the color definitions used by the admonitions:
    theme-vars.css
    :root  
        /* Solarized base2 */
        /* --hljs-bg: rgb(238, 232, 213); */
        /* Solarized base3 */
        /* --hljs-bg: rgb(253, 246, 227); */
        /* Solarized base02 */
        --hljs-bg: rgb(7, 54, 66);
        /* Solarized base03 */
        /* --hljs-bg: rgb(0, 43, 54); */
        /* Default asciidoctor theme colors */
        --icon-note-color: #19407c;
        --icon-tip-color: var(--primary);
        --icon-warning-color: #bf6900;
        --icon-caution-color: #bf3400;
        --icon-important-color: #bf0000
     
    .dark  
        --hljs-bg: rgb(7, 54, 66);
        /* Asciidoctor theme colors with tint for dark background */
        --icon-note-color: #3e7bd7;
        --icon-tip-color: var(--primary);
        --icon-warning-color: #ff8d03;
        --icon-caution-color: #ff7847;
        --icon-important-color: #ff3030
     
  4. The previous styles use font-awesome, so I ve downloaded its resources for version 4.7.0 (the one used by asciidoctor) storing the font-awesome.css into on the assets/css/extended dir (that way it is merged with the rest of .css files) and copying the fonts to the static/assets/fonts/ dir (will be served directly):
    FA_BASE_URL="https://cdnjs.cloudflare.com/ajax/libs/font-awesome/4.7.0"
    curl "$FA_BASE_URL/css/font-awesome.css" \
      > assets/css/extended/font-awesome.css
    for f in FontAwesome.otf fontawesome-webfont.eot \
      fontawesome-webfont.svg fontawesome-webfont.ttf \
      fontawesome-webfont.woff fontawesome-webfont.woff2; do
        curl "$FA_BASE_URL/fonts/$f" > "static/assets/fonts/$f"
    done
  5. As already said the default highlighter is disabled (it provided a css compatible with rouge) so we need a css to do the highlight styling; as rouge provides a way to export them, I ve created the assets/css/extended/rouge.css file with the thankful_eyes theme:
    rougify style thankful_eyes > assets/css/extended/rouge.css
  6. To support the use of the html5s backend with admonitions I ve added a variation of the example found on this blog post to assets/js/adoc-admonitions.js:
    adoc-admonitions.js
    // replace the default admonitions block with a table that uses a format
    // similar to the standard asciidoctor ... as we are using fa-icons here there
    // is no need to add the icons: font entry on the document.
    window.addEventListener('load', function ()  
      const admonitions = document.getElementsByClassName('admonition-block')
      for (let i = admonitions.length - 1; i >= 0; i--)  
        const elm = admonitions[i]
        const type = elm.classList[1]
        const title = elm.getElementsByClassName('block-title')[0];
    	const label = title.getElementsByClassName('title-label')[0]
    		.innerHTML.slice(0, -1);
        elm.removeChild(elm.getElementsByClassName('block-title')[0]);
        const text = elm.innerHTML
        const parent = elm.parentNode
        const tempDiv = document.createElement('div')
        tempDiv.innerHTML =  <div class="admonitionblock $ type ">
        <table>
          <tbody>
            <tr>
              <td class="icon">
                <i class="fa icon-$ type " title="$ label "></i>
              </td>
              <td class="content">
                $ text 
              </td>
            </tr>
          </tbody>
        </table>
      </div> 
        const input = tempDiv.childNodes[0]
        parent.replaceChild(input, elm)
       
     )
    and enabled its minified use on the layouts/partials/extend_footer.html file adding the following lines to it:
     - $admonitions := slice (resources.Get "js/adoc-admonitions.js")
        resources.Concat "assets/js/adoc-admonitions.js"   minify   fingerprint  
    <script defer crossorigin="anonymous" src="  $admonitions.RelPermalink  "
      integrity="  $admonitions.Data.Integrity  "></script>

Remark42 configurationTo integrate Remark42 with the PaperMod theme I ve created the file layouts/partials/comments.html with the following content based on the remark42 documentation, including extra code to sync the dark/light setting with the one set on the site:
comments.html
<div id="remark42"></div>
<script>
  var remark_config =  
    host:   .Site.Params.remark42Url  ,
    site_id:   .Site.Params.remark42SiteID  ,
    url:   .Permalink  ,
    locale:   .Site.Language.Lang  
   ;
  (function(c)  
    /* Adjust the theme using the local-storage pref-theme if set */
    if (localStorage.getItem("pref-theme") === "dark")  
      remark_config.theme = "dark";
      else if (localStorage.getItem("pref-theme") === "light")  
      remark_config.theme = "light";
     
    /* Add remark42 widget */
    for(var i = 0; i < c.length; i++) 
      var d = document, s = d.createElement('script');
      s.src = remark_config.host + '/web/' + c[i] +'.js';
      s.defer = true;
      (d.head   d.body).appendChild(s);
     
   )(remark_config.components   ['embed']);
</script>
In development I use it with anonymous comments enabled, but to avoid SPAM the production site uses social logins (for now I ve only enabled Github & Google, if someone requests additional services I ll check them, but those were the easy ones for me initially). To support theme switching with remark42 I ve also added the following inside the layouts/partials/extend_footer.html file:
 - if (not site.Params.disableThemeToggle)  
<script>
/* Function to change theme when the toggle button is pressed */
document.getElementById("theme-toggle").addEventListener("click", () =>  
  if (typeof window.REMARK42 != "undefined")  
    if (document.body.className.includes('dark'))  
      window.REMARK42.changeTheme('light');
      else  
      window.REMARK42.changeTheme('dark');
     
   
 );
</script>
 - end  
With this code if the theme-toggle button is pressed we change the remark42 theme before the PaperMod one (that s needed here only, on page loads the remark42 theme is synced with the main one using the code from the layouts/partials/comments.html shown earlier).

Development setupTo preview the site on my laptop I m using docker-compose with the following configuration:
docker-compose.yaml
version: "2"
services:
  hugo:
    build:
      context: ./docker/hugo-adoc
      dockerfile: ./Dockerfile
    image: sto/hugo-adoc
    container_name: hugo-adoc-blogops
    restart: always
    volumes:
      - .:/documents
    command: server --bind 0.0.0.0 -D -F
    user: $ APP_UID :$ APP_GID 
  nginx:
    image: nginx:latest
    container_name: nginx-blogops
    restart: always
    volumes:
      - ./nginx/default.conf:/etc/nginx/conf.d/default.conf
    ports:
      -  1313:1313
  remark42:
    build:
      context: ./docker/remark42
      dockerfile: ./Dockerfile
    image: sto/remark42
    container_name: remark42-blogops
    restart: always
    env_file:
      - ./.env
      - ./remark42/env.dev
    volumes:
      - ./remark42/var.dev:/srv/var
To run it properly we have to create the .env file with the current user ID and GID on the variables APP_UID and APP_GID (if we don t do it the files can end up being owned by a user that is not the same as the one running the services):
$ echo "APP_UID=$(id -u)\nAPP_GID=$(id -g)" > .env
The Dockerfile used to generate the sto/hugo-adoc is:
Dockerfile
FROM asciidoctor/docker-asciidoctor:latest
RUN gem install --no-document asciidoctor-html5s &&\
 apk update && apk add --no-cache curl libc6-compat &&\
 repo_path="gohugoio/hugo" &&\
 api_url="https://api.github.com/repos/$repo_path/releases/latest" &&\
 download_url="$(\
  curl -sL "$api_url"  \
  sed -n "s/^.*download_url\": \"\\(.*.extended.*Linux-64bit.tar.gz\)\"/\1/p"\
 )" &&\
 curl -sL "$download_url" -o /tmp/hugo.tgz &&\
 tar xf /tmp/hugo.tgz hugo &&\
 install hugo /usr/bin/ &&\
 rm -f hugo /tmp/hugo.tgz &&\
 /usr/bin/hugo version &&\
 apk del curl && rm -rf /var/cache/apk/*
# Expose port for live server
EXPOSE 1313
ENTRYPOINT ["/usr/bin/hugo"]
CMD [""]
If you review it you will see that I m using the docker-asciidoctor image as the base; the idea is that this image has all I need to work with asciidoctor and to use hugo I only need to download the binary from their latest release at github (as we are using an image based on alpine we also need to install the libc6-compat package, but once that is done things are working fine for me so far). The image does not launch the server by default because I don t want it to; in fact I use the same docker-compose.yml file to publish the site in production simply calling the container without the arguments passed on the docker-compose.yml file (see later). When running the containers with docker-compose up (or docker compose up if you have the docker-compose-plugin package installed) we also launch a nginx container and the remark42 service so we can test everything together. The Dockerfile for the remark42 image is the original one with an updated version of the init.sh script:
Dockerfile
FROM umputun/remark42:latest
COPY init.sh /init.sh
The updated init.sh is similar to the original, but allows us to use an APP_GID variable and updates the /etc/group file of the container so the files get the right user and group (with the original script the group is always 1001):
init.sh
#!/sbin/dinit /bin/sh
uid="$(id -u)"
if [ "$ uid " -eq "0" ]; then
  echo "init container"
  # set container's time zone
  cp "/usr/share/zoneinfo/$ TIME_ZONE " /etc/localtime
  echo "$ TIME_ZONE " >/etc/timezone
  echo "set timezone $ TIME_ZONE  ($(date))"
  # set UID & GID for the app
  if [ "$ APP_UID " ]   [ "$ APP_GID " ]; then
    [ "$ APP_UID " ]   APP_UID="1001"
    [ "$ APP_GID " ]   APP_GID="$ APP_UID "
    echo "set custom APP_UID=$ APP_UID  & APP_GID=$ APP_GID "
    sed -i "s/^app:x:1001:1001:/app:x:$ APP_UID :$ APP_GID :/" /etc/passwd
    sed -i "s/^app:x:1001:/app:x:$ APP_GID :/" /etc/group
  else
    echo "custom APP_UID and/or APP_GID not defined, using 1001:1001"
  fi
  chown -R app:app /srv /home/app
fi
echo "prepare environment"
# replace  % REMARK_URL %  by content of REMARK_URL variable
find /srv -regex '.*\.\(html\ js\ mjs\)$' -print \
  -exec sed -i "s % REMARK_URL % $ REMARK_URL  g"   \;
if [ -n "$ SITE_ID " ]; then
  #replace "site_id: 'remark'" by SITE_ID
  sed -i "s 'remark' '$ SITE_ID ' g" /srv/web/*.html
fi
echo "execute \"$*\""
if [ "$ uid " -eq "0" ]; then
  exec su-exec app "$@"
else
  exec "$@"
fi
The environment file used with remark42 for development is quite minimal:
env.dev
TIME_ZONE=Europe/Madrid
REMARK_URL=http://localhost:1313/remark42
SITE=blogops
SECRET=123456
ADMIN_SHARED_ID=sto
AUTH_ANON=true
EMOJI=true
And the nginx/default.conf file used to publish the service locally is simple too:
default.conf
server   
 listen 1313;
 server_name localhost;
 location /  
    proxy_pass http://hugo:1313;
    proxy_set_header Host $http_host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;
    proxy_set_header Upgrade $http_upgrade;
    proxy_set_header Connection "upgrade";
  
 location /remark42/  
    rewrite /remark42/(.*) /$1 break;
    proxy_pass http://remark42:8080/;
    proxy_set_header Host $http_host;
    proxy_set_header X-Real-IP $remote_addr;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header X-Forwarded-Proto $scheme;


Production setupThe VM where I m publishing the blog runs Debian GNU/Linux and uses binaries from local packages and applications packaged inside containers. To run the containers I m using docker-ce (I could have used podman instead, but I already had it installed on the machine, so I stayed with it). The binaries used on this project are included on the following packages from the main Debian repository:
  • git to clone & pull the repository,
  • jq to parse json files from shell scripts,
  • json2file-go to save the webhook messages to files,
  • inotify-tools to detect when new files are stored by json2file-go and launch scripts to process them,
  • nginx to publish the site using HTTPS and work as proxy for json2file-go and remark42 (I run it using a container),
  • task-spool to queue the scripts that update the deployment.
And I m using docker and docker compose from the debian packages on the docker repository:
  • docker-ce to run the containers,
  • docker-compose-plugin to run docker compose (it is a plugin, so no - in the name).

Repository checkoutTo manage the git repository I ve created a deploy key, added it to gitea and cloned the project on the /srv/blogops PATH (that route is owned by a regular user that has permissions to run docker, as I said before).

Compiling the site with hugoTo compile the site we are using the docker-compose.yml file seen before, to be able to run it first we build the container images and once we have them we launch hugo using docker compose run:
$ cd /srv/blogops
$ git pull
$ docker compose build
$ if [ -d "./public" ]; then rm -rf ./public; fi
$ docker compose run hugo --
The compilation leaves the static HTML on /srv/blogops/public (we remove the directory first because hugo does not clean the destination folder as jekyll does). The deploy script re-generates the site as described and moves the public directory to its final place for publishing.

Running remark42 with dockerOn the /srv/blogops/remark42 folder I have the following docker-compose.yml:
docker-compose.yml
version: "2"
services:
  remark42:
    build:
      context: ../docker/remark42
      dockerfile: ./Dockerfile
    image: sto/remark42
    env_file:
      - ../.env
      - ./env.prod
    container_name: remark42
    restart: always
    volumes:
      - ./var.prod:/srv/var
    ports:
      - 127.0.0.1:8042:8080
The ../.env file is loaded to get the APP_UID and APP_GID variables that are used by my version of the init.sh script to adjust file permissions and the env.prod file contains the rest of the settings for remark42, including the social network tokens (see the remark42 documentation for the available parameters, I don t include my configuration here because some of them are secrets).

Nginx configurationThe nginx configuration for the blogops.mixinet.net site is as simple as:
server  
  listen 443 ssl http2;
  server_name blogops.mixinet.net;
  ssl_certificate /etc/letsencrypt/live/blogops.mixinet.net/fullchain.pem;
  ssl_certificate_key /etc/letsencrypt/live/blogops.mixinet.net/privkey.pem;
  include /etc/letsencrypt/options-ssl-nginx.conf;
  ssl_dhparam /etc/letsencrypt/ssl-dhparams.pem;
  access_log /var/log/nginx/blogops.mixinet.net-443.access.log;
  error_log  /var/log/nginx/blogops.mixinet.net-443.error.log;
  root /srv/blogops/nginx/public_html;
  location /  
    try_files $uri $uri/ =404;
   
  include /srv/blogops/nginx/remark42.conf;
 
server  
  listen 80 ;
  listen [::]:80 ;
  server_name blogops.mixinet.net;
  access_log /var/log/nginx/blogops.mixinet.net-80.access.log;
  error_log  /var/log/nginx/blogops.mixinet.net-80.error.log;
  if ($host = blogops.mixinet.net)  
    return 301 https://$host$request_uri;
   
  return 404;
 
On this configuration the certificates are managed by certbot and the server root directory is on /srv/blogops/nginx/public_html and not on /srv/blogops/public; the reason for that is that I want to be able to compile without affecting the running site, the deployment script generates the site on /srv/blogops/public and if all works well we rename folders to do the switch, making the change feel almost atomic.

json2file-go configurationAs I have a working WireGuard VPN between the machine running gitea at my home and the VM where the blog is served, I m going to configure the json2file-go to listen for connections on a high port using a self signed certificate and listening on IP addresses only reachable through the VPN. To do it we create a systemd socket to run json2file-go and adjust its configuration to listen on a private IP (we use the FreeBind option on its definition to be able to launch the service even when the IP is not available, that is, when the VPN is down). The following script can be used to set up the json2file-go configuration:
setup-json2file.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
J2F_DIR="$BASE_DIR/json2file"
TLS_DIR="$BASE_DIR/tls"
J2F_SERVICE_NAME="json2file-go"
J2F_SERVICE_DIR="/etc/systemd/system/json2file-go.service.d"
J2F_SERVICE_OVERRIDE="$J2F_SERVICE_DIR/override.conf"
J2F_SOCKET_DIR="/etc/systemd/system/json2file-go.socket.d"
J2F_SOCKET_OVERRIDE="$J2F_SOCKET_DIR/override.conf"
J2F_BASEDIR_FILE="/etc/json2file-go/basedir"
J2F_DIRLIST_FILE="/etc/json2file-go/dirlist"
J2F_CRT_FILE="/etc/json2file-go/certfile"
J2F_KEY_FILE="/etc/json2file-go/keyfile"
J2F_CRT_PATH="$TLS_DIR/crt.pem"
J2F_KEY_PATH="$TLS_DIR/key.pem"
# ----
# MAIN
# ----
# Install packages used with json2file for the blogops site
sudo apt update
sudo apt install -y json2file-go uuid
if [ -z "$(type mkcert)" ]; then
  sudo apt install -y mkcert
fi
sudo apt clean
# Configuration file values
J2F_USER="$(id -u)"
J2F_GROUP="$(id -g)"
J2F_DIRLIST="blogops:$(uuid)"
J2F_LISTEN_STREAM="172.31.31.1:4443"
# Configure json2file
[ -d "$J2F_DIR" ]   mkdir "$J2F_DIR"
sudo sh -c "echo '$J2F_DIR' >'$J2F_BASEDIR_FILE'"
[ -d "$TLS_DIR" ]   mkdir "$TLS_DIR"
if [ ! -f "$J2F_CRT_PATH" ]   [ ! -f "$J2F_KEY_PATH" ]; then
  mkcert -cert-file "$J2F_CRT_PATH" -key-file "$J2F_KEY_PATH" "$(hostname -f)"
fi
sudo sh -c "echo '$J2F_CRT_PATH' >'$J2F_CRT_FILE'"
sudo sh -c "echo '$J2F_KEY_PATH' >'$J2F_KEY_FILE'"
sudo sh -c "cat >'$J2F_DIRLIST_FILE'" <<EOF
$(echo "$J2F_DIRLIST"   tr ';' '\n')
EOF
# Service override
[ -d "$J2F_SERVICE_DIR" ]   sudo mkdir "$J2F_SERVICE_DIR"
sudo sh -c "cat >'$J2F_SERVICE_OVERRIDE'" <<EOF
[Service]
User=$J2F_USER
Group=$J2F_GROUP
EOF
# Socket override
[ -d "$J2F_SOCKET_DIR" ]   sudo mkdir "$J2F_SOCKET_DIR"
sudo sh -c "cat >'$J2F_SOCKET_OVERRIDE'" <<EOF
[Socket]
# Set FreeBind to listen on missing addresses (the VPN can be down sometimes)
FreeBind=true
# Set ListenStream to nothing to clear its value and add the new value later
ListenStream=
ListenStream=$J2F_LISTEN_STREAM
EOF
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$J2F_SERVICE_NAME"
sudo systemctl start "$J2F_SERVICE_NAME"
sudo systemctl enable "$J2F_SERVICE_NAME"
# ----
# vim: ts=2:sw=2:et:ai:sts=2
Warning: The script uses mkcert to create the temporary certificates, to install the package on bullseye the backports repository must be available.

Gitea configurationTo make gitea use our json2file-go server we go to the project and enter into the hooks/gitea/new page, once there we create a new webhook of type gitea and set the target URL to https://172.31.31.1:4443/blogops and on the secret field we put the token generated with uuid by the setup script:
sed -n -e 's/blogops://p' /etc/json2file-go/dirlist
The rest of the settings can be left as they are:
  • Trigger on: Push events
  • Branch filter: *
Warning: We are using an internal IP and a self signed certificate, that means that we have to review that the webhook section of the app.ini of our gitea server allows us to call the IP and skips the TLS verification (you can see the available options on the gitea documentation). The [webhook] section of my server looks like this:
[webhook]
ALLOWED_HOST_LIST=private
SKIP_TLS_VERIFY=true
Once we have the webhook configured we can try it and if it works our json2file server will store the file on the /srv/blogops/webhook/json2file/blogops/ folder.

The json2file spooler scriptWith the previous configuration our system is ready to receive webhook calls from gitea and store the messages on files, but we have to do something to process those files once they are saved in our machine. An option could be to use a cronjob to look for new files, but we can do better on Linux using inotify we will use the inotifywait command from inotify-tools to watch the json2file output directory and execute a script each time a new file is moved inside it or closed after writing (IN_CLOSE_WRITE and IN_MOVED_TO events). To avoid concurrency problems we are going to use task-spooler to launch the scripts that process the webhooks using a queue of length 1, so they are executed one by one in a FIFO queue. The spooler script is this:
blogops-spooler.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
BIN_DIR="$BASE_DIR/bin"
TSP_DIR="$BASE_DIR/tsp"
WEBHOOK_COMMAND="$BIN_DIR/blogops-webhook.sh"
# ---------
# FUNCTIONS
# ---------
queue_job()  
  echo "Queuing job to process file '$1'"
  TMPDIR="$TSP_DIR" TS_SLOTS="1" TS_MAXFINISHED="10" \
    tsp -n "$WEBHOOK_COMMAND" "$1"
 
# ----
# MAIN
# ----
INPUT_DIR="$1"
if [ ! -d "$INPUT_DIR" ]; then
  echo "Input directory '$INPUT_DIR' does not exist, aborting!"
  exit 1
fi
[ -d "$TSP_DIR" ]   mkdir "$TSP_DIR"
echo "Processing existing files under '$INPUT_DIR'"
find "$INPUT_DIR" -type f   sort   while read -r _filename; do
  queue_job "$_filename"
done
# Use inotifywatch to process new files
echo "Watching for new files under '$INPUT_DIR'"
inotifywait -q -m -e close_write,moved_to --format "%w%f" -r "$INPUT_DIR"  
  while read -r _filename; do
    queue_job "$_filename"
  done
# ----
# vim: ts=2:sw=2:et:ai:sts=2
To run it as a daemon we install it as a systemd service using the following script:
setup-spooler.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
BASE_DIR="/srv/blogops/webhook"
BIN_DIR="$BASE_DIR/bin"
J2F_DIR="$BASE_DIR/json2file"
SPOOLER_COMMAND="$BIN_DIR/blogops-spooler.sh '$J2F_DIR'"
SPOOLER_SERVICE_NAME="blogops-j2f-spooler"
SPOOLER_SERVICE_FILE="/etc/systemd/system/$SPOOLER_SERVICE_NAME.service"
# Configuration file values
J2F_USER="$(id -u)"
J2F_GROUP="$(id -g)"
# ----
# MAIN
# ----
# Install packages used with the webhook processor
sudo apt update
sudo apt install -y inotify-tools jq task-spooler
sudo apt clean
# Configure process service
sudo sh -c "cat > $SPOOLER_SERVICE_FILE" <<EOF
[Install]
WantedBy=multi-user.target
[Unit]
Description=json2file processor for $J2F_USER
After=docker.service
[Service]
Type=simple
User=$J2F_USER
Group=$J2F_GROUP
ExecStart=$SPOOLER_COMMAND
EOF
# Restart and enable service
sudo systemctl daemon-reload
sudo systemctl stop "$SPOOLER_SERVICE_NAME"   true
sudo systemctl start "$SPOOLER_SERVICE_NAME"
sudo systemctl enable "$SPOOLER_SERVICE_NAME"
# ----
# vim: ts=2:sw=2:et:ai:sts=2

The gitea webhook processorFinally, the script that processes the JSON files does the following:
  1. First, it checks if the repository and branch are right,
  2. Then, it fetches and checks out the commit referenced on the JSON file,
  3. Once the files are updated, compiles the site using hugo with docker compose,
  4. If the compilation succeeds the script renames directories to swap the old version of the site by the new one.
If there is a failure the script aborts but before doing it or if the swap succeeded the system sends an email to the configured address and/or the user that pushed updates to the repository with a log of what happened. The current script is this one:
blogops-webhook.sh
#!/bin/sh
set -e
# ---------
# VARIABLES
# ---------
# Values
REPO_REF="refs/heads/main"
REPO_CLONE_URL="https://gitea.mixinet.net/mixinet/blogops.git"
MAIL_PREFIX="[BLOGOPS-WEBHOOK] "
# Address that gets all messages, leave it empty if not wanted
MAIL_TO_ADDR="blogops@mixinet.net"
# If the following variable is set to 'true' the pusher gets mail on failures
MAIL_ERRFILE="false"
# If the following variable is set to 'true' the pusher gets mail on success
MAIL_LOGFILE="false"
# gitea's conf/app.ini value of NO_REPLY_ADDRESS, it is used for email domains
# when the KeepEmailPrivate option is enabled for a user
NO_REPLY_ADDRESS="noreply.example.org"
# Directories
BASE_DIR="/srv/blogops"
PUBLIC_DIR="$BASE_DIR/public"
NGINX_BASE_DIR="$BASE_DIR/nginx"
PUBLIC_HTML_DIR="$NGINX_BASE_DIR/public_html"
WEBHOOK_BASE_DIR="$BASE_DIR/webhook"
WEBHOOK_SPOOL_DIR="$WEBHOOK_BASE_DIR/spool"
WEBHOOK_ACCEPTED="$WEBHOOK_SPOOL_DIR/accepted"
WEBHOOK_DEPLOYED="$WEBHOOK_SPOOL_DIR/deployed"
WEBHOOK_REJECTED="$WEBHOOK_SPOOL_DIR/rejected"
WEBHOOK_TROUBLED="$WEBHOOK_SPOOL_DIR/troubled"
WEBHOOK_LOG_DIR="$WEBHOOK_SPOOL_DIR/log"
# Files
TODAY="$(date +%Y%m%d)"
OUTPUT_BASENAME="$(date +%Y%m%d-%H%M%S.%N)"
WEBHOOK_LOGFILE_PATH="$WEBHOOK_LOG_DIR/$OUTPUT_BASENAME.log"
WEBHOOK_ACCEPTED_JSON="$WEBHOOK_ACCEPTED/$OUTPUT_BASENAME.json"
WEBHOOK_ACCEPTED_LOGF="$WEBHOOK_ACCEPTED/$OUTPUT_BASENAME.log"
WEBHOOK_REJECTED_TODAY="$WEBHOOK_REJECTED/$TODAY"
WEBHOOK_REJECTED_JSON="$WEBHOOK_REJECTED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_REJECTED_LOGF="$WEBHOOK_REJECTED_TODAY/$OUTPUT_BASENAME.log"
WEBHOOK_DEPLOYED_TODAY="$WEBHOOK_DEPLOYED/$TODAY"
WEBHOOK_DEPLOYED_JSON="$WEBHOOK_DEPLOYED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_DEPLOYED_LOGF="$WEBHOOK_DEPLOYED_TODAY/$OUTPUT_BASENAME.log"
WEBHOOK_TROUBLED_TODAY="$WEBHOOK_TROUBLED/$TODAY"
WEBHOOK_TROUBLED_JSON="$WEBHOOK_TROUBLED_TODAY/$OUTPUT_BASENAME.json"
WEBHOOK_TROUBLED_LOGF="$WEBHOOK_TROUBLED_TODAY/$OUTPUT_BASENAME.log"
# Query to get variables from a gitea webhook json
ENV_VARS_QUERY="$(
  printf "%s" \
    '(.             @sh "gt_ref=\(.ref);"),' \
    '(.             @sh "gt_after=\(.after);"),' \
    '(.repository   @sh "gt_repo_clone_url=\(.clone_url);"),' \
    '(.repository   @sh "gt_repo_name=\(.name);"),' \
    '(.pusher       @sh "gt_pusher_full_name=\(.full_name);"),' \
    '(.pusher       @sh "gt_pusher_email=\(.email);")'
)"
# ---------
# Functions
# ---------
webhook_log()  
  echo "$(date -R) $*" >>"$WEBHOOK_LOGFILE_PATH"
 
webhook_check_directories()  
  for _d in "$WEBHOOK_SPOOL_DIR" "$WEBHOOK_ACCEPTED" "$WEBHOOK_DEPLOYED" \
    "$WEBHOOK_REJECTED" "$WEBHOOK_TROUBLED" "$WEBHOOK_LOG_DIR"; do
    [ -d "$_d" ]   mkdir "$_d"
  done
 
webhook_clean_directories()  
  # Try to remove empty dirs
  for _d in "$WEBHOOK_ACCEPTED" "$WEBHOOK_DEPLOYED" "$WEBHOOK_REJECTED" \
    "$WEBHOOK_TROUBLED" "$WEBHOOK_LOG_DIR" "$WEBHOOK_SPOOL_DIR"; do
    if [ -d "$_d" ]; then
      rmdir "$_d" 2>/dev/null   true
    fi
  done
 
webhook_accept()  
  webhook_log "Accepted: $*"
  mv "$WEBHOOK_JSON_INPUT_FILE" "$WEBHOOK_ACCEPTED_JSON"
  mv "$WEBHOOK_LOGFILE_PATH" "$WEBHOOK_ACCEPTED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_ACCEPTED_LOGF"
 
webhook_reject()  
  [ -d "$WEBHOOK_REJECTED_TODAY" ]   mkdir "$WEBHOOK_REJECTED_TODAY"
  webhook_log "Rejected: $*"
  if [ -f "$WEBHOOK_JSON_INPUT_FILE" ]; then
    mv "$WEBHOOK_JSON_INPUT_FILE" "$WEBHOOK_REJECTED_JSON"
  fi
  mv "$WEBHOOK_LOGFILE_PATH" "$WEBHOOK_REJECTED_LOGF"
  exit 0
 
webhook_deployed()  
  [ -d "$WEBHOOK_DEPLOYED_TODAY" ]   mkdir "$WEBHOOK_DEPLOYED_TODAY"
  webhook_log "Deployed: $*"
  mv "$WEBHOOK_ACCEPTED_JSON" "$WEBHOOK_DEPLOYED_JSON"
  mv "$WEBHOOK_ACCEPTED_LOGF" "$WEBHOOK_DEPLOYED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_DEPLOYED_LOGF"
 
webhook_troubled()  
  [ -d "$WEBHOOK_TROUBLED_TODAY" ]   mkdir "$WEBHOOK_TROUBLED_TODAY"
  webhook_log "Troubled: $*"
  mv "$WEBHOOK_ACCEPTED_JSON" "$WEBHOOK_TROUBLED_JSON"
  mv "$WEBHOOK_ACCEPTED_LOGF" "$WEBHOOK_TROUBLED_LOGF"
  WEBHOOK_LOGFILE_PATH="$WEBHOOK_TROUBLED_LOGF"
 
print_mailto()  
  _addr="$1"
  _user_email=""
  # Add the pusher email address unless it is from the domain NO_REPLY_ADDRESS,
  # which should match the value of that variable on the gitea 'app.ini' (it
  # is the domain used for emails when the user hides it).
  # shellcheck disable=SC2154
  if [ -n "$ gt_pusher_email##*@"$ NO_REPLY_ADDRESS " " ] &&
    [ -z "$ gt_pusher_email##*@* " ]; then
    _user_email="\"$gt_pusher_full_name <$gt_pusher_email>\""
  fi
  if [ "$_addr" ] && [ "$_user_email" ]; then
    echo "$_addr,$_user_email"
  elif [ "$_user_email" ]; then
    echo "$_user_email"
  elif [ "$_addr" ]; then
    echo "$_addr"
  fi
 
mail_success()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$MAIL_LOGFILE" = "true" ]; then
    to_addr="$(print_mailto "$to_addr")"
  fi
  if [ "$to_addr" ]; then
    # shellcheck disable=SC2154
    subject="OK - $gt_repo_name updated to commit '$gt_after'"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" \
      <"$WEBHOOK_LOGFILE_PATH"
  fi
 
mail_failure()  
  to_addr="$MAIL_TO_ADDR"
  if [ "$MAIL_ERRFILE" = true ]; then
    to_addr="$(print_mailto "$to_addr")"
  fi
  if [ "$to_addr" ]; then
    # shellcheck disable=SC2154
    subject="KO - $gt_repo_name update FAILED for commit '$gt_after'"
    mail -s "$ MAIL_PREFIX $ subject " "$to_addr" \
      <"$WEBHOOK_LOGFILE_PATH"
  fi
 
# ----
# MAIN
# ----
# Check directories
webhook_check_directories
# Go to the base directory
cd "$BASE_DIR"
# Check if the file exists
WEBHOOK_JSON_INPUT_FILE="$1"
if [ ! -f "$WEBHOOK_JSON_INPUT_FILE" ]; then
  webhook_reject "Input arg '$1' is not a file, aborting"
fi
# Parse the file
webhook_log "Processing file '$WEBHOOK_JSON_INPUT_FILE'"
eval "$(jq -r "$ENV_VARS_QUERY" "$WEBHOOK_JSON_INPUT_FILE")"
# Check that the repository clone url is right
# shellcheck disable=SC2154
if [ "$gt_repo_clone_url" != "$REPO_CLONE_URL" ]; then
  webhook_reject "Wrong repository: '$gt_clone_url'"
fi
# Check that the branch is the right one
# shellcheck disable=SC2154
if [ "$gt_ref" != "$REPO_REF" ]; then
  webhook_reject "Wrong repository ref: '$gt_ref'"
fi
# Accept the file
# shellcheck disable=SC2154
webhook_accept "Processing '$gt_repo_name'"
# Update the checkout
ret="0"
git fetch >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Repository fetch failed"
  mail_failure
fi
# shellcheck disable=SC2154
git checkout "$gt_after" >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Repository checkout failed"
  mail_failure
fi
# Remove the build dir if present
if [ -d "$PUBLIC_DIR" ]; then
  rm -rf "$PUBLIC_DIR"
fi
# Build site
docker compose run hugo -- >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
# go back to the main branch
git switch main && git pull
# Fail if public dir was missing
if [ "$ret" -ne "0" ]   [ ! -d "$PUBLIC_DIR" ]; then
  webhook_troubled "Site build failed"
  mail_failure
fi
# Remove old public_html copies
webhook_log 'Removing old site versions, if present'
find $NGINX_BASE_DIR -mindepth 1 -maxdepth 1 -name 'public_html-*' -type d \
  -exec rm -rf   \; >>"$WEBHOOK_LOGFILE_PATH" 2>&1   ret="$?"
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Removal of old site versions failed"
  mail_failure
fi
# Switch site directory
TS="$(date +%Y%m%d-%H%M%S)"
if [ -d "$PUBLIC_HTML_DIR" ]; then
  webhook_log "Moving '$PUBLIC_HTML_DIR' to '$PUBLIC_HTML_DIR-$TS'"
  mv "$PUBLIC_HTML_DIR" "$PUBLIC_HTML_DIR-$TS" >>"$WEBHOOK_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -eq "0" ]; then
  webhook_log "Moving '$PUBLIC_DIR' to '$PUBLIC_HTML_DIR'"
  mv "$PUBLIC_DIR" "$PUBLIC_HTML_DIR" >>"$WEBHOOK_LOGFILE_PATH" 2>&1  
    ret="$?"
fi
if [ "$ret" -ne "0" ]; then
  webhook_troubled "Site switch failed"
  mail_failure
else
  webhook_deployed "Site deployed successfully"
  mail_success
fi
# ----
# vim: ts=2:sw=2:et:ai:sts=2

25 May 2022

Dirk Eddelbuettel: RcppAPT 0.0.9: Minor Update

A new version of the RcppAPT package with the R interface to the C++ library behind the awesome apt, apt-get, apt-cache, commands and their cache powering Debian, Ubuntu and the like arrived on CRAN earlier today. RcppAPT allows you to query the (Debian or Ubuntu) package dependency graph at will, with build-dependencies (if you have deb-src entries), reverse dependencies, and all other goodies. See the vignette and examples for illustrations. This release updates the code to the Apt 2.5.0 release this makes. It makes a cleaner distinction between public and private components of the API. We adjusted one access point to a pattern we already used, and while at it, simplified some of the transition from the pre-Apt 2.0.0 interface. No new features. The NEWS entries follow.

Changes in version 0.0.9 (2022-05-25)
  • Simplified and standardized to only use public API
  • No longer tests and accomodates pre-Apt 2.0 API

Courtesy of my CRANberries, there is also a diffstat report for this release. A bit more information about the package is available here as well as at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

22 May 2022

Russ Allbery: Review: On a Sunbeam

Review: On a Sunbeam, by Tillie Walden
Publisher: Tillie Walden
Copyright: 2016-2017
Format: Online graphic novel
Pages: 544
On a Sunbeam is a web comic that was published in installments between Fall 2016 and Spring 2017, and then later published in dead tree form. I read the on-line version, which is still available for free from its web site. It was nominated for an Eisner Award and won a ton of other awards, including the Los Angeles Times Book Prize. Mia is a new high school graduate who has taken a job with a construction crew that repairs old buildings (that are floating in space, but I'll get to that in a moment). Alma, Elliot, and Charlotte have been together for a long time; Jules is closer to Mia's age and has been with them for a year. This is not the sort of job one commutes to: they live together on a spaceship that travels to the job sites, share meals together, and are more of an extended family than a group of coworkers. It's all a bit intimidating for Mia, but Jules provides a very enthusiastic welcome and some orientation. The story of Mia's new job is interleaved with Mia's school experience from five years earlier. As a new frosh at a boarding school, Mia is obsessed with Lux, a school sport that involves building and piloting ships through a maze to capture orbs. Sent to the principal's office on the first day of school for sneaking into the Lux tower when she's supposed to be at assembly, she meets Grace, a shy girl with sparkly shoes and an unheard-of single room. Mia (a bit like Jules in the present timeline) overcomes Grace's reticence by being persistently outgoing and determinedly friendly, while trying to get on the Lux team and dealing with the typical school problems of bullies and in-groups. On a Sunbeam is science fiction in the sense that it seems to take place in space and school kids build flying ships. It is not science fiction in the sense of caring about technological extrapolation or making any scientific sense whatsoever. The buildings that Mia and the crew repair appear to be hanging in empty space, but there's gravity. No one wears any protective clothing or air masks. The spaceships look (and move) like giant tropical fish. If you need realism in your science fiction graphical novels, it's probably best not to think of this as science fiction at all, or even science fantasy despite the later appearance of some apparently magical or divine elements. That may sound surrealistic or dream-like, but On a Sunbeam isn't that either. It's a story about human relationships, found family, and diversity of personalities, all of which are realistically portrayed. The characters find their world coherent, consistent, and predictable, even if it sometimes makes no sense to the reader. On a Sunbeam is simply set in its own universe, with internal logic but without explanation or revealed rules. I kind of liked this approach? It takes some getting used to, but it's an excuse for some dramatic and beautiful backgrounds, and it's oddly freeing to have unremarked train tracks in outer space. There's no way that an explanation would have worked; if one were offered, my brain would have tried to nitpick it to the detriment of the story. There's something delightful about a setting that follows imaginary physical laws this unapologetically and without showing the author's work. I was, sadly, not as much of a fan of the art, although I am certain this will be a matter of taste. Walden mixes simple story-telling panels with sweeping vistas, free-floating domes, and strange, wild asteroids, but she uses a very limited color palette. Most panels are only a few steps away from monochrome, and the colors are chosen more for mood or orientation in the story (Mia's school days are all blue, the Staircase is orange) than for any consistent realism. There is often a lot of detail in the panels, but I found it hard to appreciate because the coloring confused my eye. I'm old enough to have been a comics reader during the revolution in digital coloring and improved printing, and I loved the subsequent dramatic improvement in vivid colors and shading. I know the coloring style here is an intentional artistic choice, but to me it felt like a throwback to the days of muddy printing on cheap paper. I have a similar complaint about the lettering: On a Sunbeam is either hand-lettered or closely simulates hand lettering, and I often found the dialogue hard to read due to inconsistent intra- and interword spacing or ambiguous letters. Here too I'm sure this was an artistic choice, but as a reader I'd much prefer a readable comics font over hand lettering. The detail in the penciling is more to my liking. I had occasional trouble telling some of the characters apart, but they're clearly drawn and emotionally expressive. The scenery is wildly imaginative and often gorgeous, which increased my frustration with the coloring. I would love to see what some of these panels would have looked like after realistic coloring with a full palette. (It's worth noting again that I read the on-line version. It's possible that the art was touched up for the print version and would have been more to my liking.) But enough about the art. The draw of On a Sunbeam for me is the story. It's not very dramatic or event-filled at first, starting as two stories of burgeoning friendships with a fairly young main character. (They are closely linked, but it's not obvious how until well into the story.) But it's the sort of story that I started reading, thought was mildly interesting, and then kept reading just one more chapter until I had somehow read the whole thing. There are some interesting twists towards the end, but it's otherwise not a very dramatic or surprising story. What it is instead is open-hearted, quiet, charming, and deeper than it looks. The characters are wildly different and can be abrasive, but they invest time and effort into understanding each other and adjusting for each other's preferences. Personal loss drives a lot of the plot, but the characters are also allowed to mature and be happy without resolving every bad thing that happened to them. These characters felt like people I would like and would want to get to know (even if Jules would be overwhelming). I enjoyed watching their lives. This reminded me a bit of a Becky Chambers novel, although it's less invested in being science fiction and sticks strictly to humans. There's a similar feeling that the relationships are the point of the story, and that nearly everyone is trying hard to be good, with differing backgrounds and differing conceptions of good. All of the characters are female or non-binary, which is left as entirely unexplained as the rest of the setting. It's that sort of book. I wouldn't say this is one of the best things I've ever read, but I found it delightful and charming, and it certainly sucked me in and kept me reading until the end. One also cannot argue with the price, although if I hadn't already read it, I would be tempted to buy a paper copy to support the author. This will not be to everyone's taste, and stay far away if you are looking for realistic science fiction, but recommended if you are in the mood for an understated queer character story full of good-hearted people. Rating: 7 out of 10

21 May 2022

Dirk Eddelbuettel: #37: Introducing r2u with 2 x 19k CRAN binaries for Ubuntu 22.04 and 20.04

One month ago I started work on a new side project which is now up and running, and deserving on an introductory blog post: r2u. It was announced in two earlier tweets (first, second) which contained the two (wicked) demos below also found at the documentation site. So what is this about? It brings full and complete CRAN installability to Ubuntu LTS, both the focal release 20.04 and the recent jammy release 22.04. It is unique in resolving all R and CRAN packages with the system package manager. So whenever you install something it is guaranteed to run as its dependencies are resolved and co-installed as needed. Equally important, no shared library will be updated or removed by the system as the possible dependency of the R package is known and declared. No other package management system for R does that as only apt on Debian or Ubuntu can and this project integrates all CRAN packages (plus 200+ BioConductor packages). It will work with any Ubuntu installation on laptop, desktop, server, cloud, container, or in WSL2 (but is limited to Intel/AMD chips, sorry Raspberry Pi or M1 laptop). It covers all of CRAN (or nearly 19k packages), all the BioConductor packages depended-upon (currently over 200), and only excludes less than a handful of CRAN packages that cannot be built.

Usage Setup instructions approaches described concisely in the repo README.md and documentation site. It consists of just five (or fewer) simple steps, and scripts are provided too for focal (20.04) and jammy (22.04).

Demos Check out these two demos (also at the r2u site):

Installing the full tidyverse in one command and 18 seconds

Installing brms and its depends in one command and 13 seconds (and show gitpod.io)

Integration via bspm The r2u setup can be used directly with apt (or dpkg or any other frontend to the package management system). Once installed apt update; apt upgrade will take care of new packages. For this to work, all CRAN packages (and all BioConductor packages depended upon) are mapped to names like r-cran-rcpp and r-bioc-s4vectors: an r prefix, the repo, and the package name, all lower-cased. That works but thanks to the wonderful bspm package by I aki car we can do much better. It connects R s own install.packages() and update.packages() to apt. So we can just say (as the demos above show) install.packages("tidyverse") or install.packages("brms") and binaries are installed via apt which is fantastic and it connects R to the system package manager. The setup is really only two lines and described at the r2u site as part of the setup.

History and Motivation Turning CRAN packages into .deb binaries is not a new idea. Albrecht Gebhardt was the first to realize this about twenty years ago (!!) and implemented it with a single Perl script. Next, Albrecht, Stefan Moeller, David Vernazobres and I built on top of this which is described in this useR! 2007 paper. A most excellent generalization and rewrite was provided by Charles Blundell in an superb Google Summer of Code contribution in 2008 which I mentored. Charles and I described it in this talk at useR! 2009. I ran that setup for a while afterwards, but it died via an internal database corruption in 2010 right when I tried to demo it at CRAN headquarters in Vienna. This peaked at, if memory serves, about 5k packages: all of CRAN at the time. Don Armstrong took it one step further in a full reimplemenation which, if I recall correctly, coverd all of CRAN and BioConductor for what may have been 8k or 9k packages. Don had a stronger system (with full RAID-5) but it also died in a crash and was never rebuilt even though he and I could have relied on Debian resources (as all these approaches focused on Debian). During that time, Michael Rutter created a variant that cleverly used an Ubuntu-only setup utilizing Launchpad. This repo is still going strong, used and relied-upon by many, and about 5k packages (per distribution) strong. At one point, a group consisting of Don, Michael, G bor Cs rdi and myself (as lead/PI) had financial support from the RConsortium ISC for a more general re-implementation , but that support was withdrawn when we did not have time to deliver. We should also note other long-standing approaches. Detlef Steuer has been using the openSUSE Build Service to provide nearly all of CRAN for openSUSE for many years. I aki car built a similar system for Fedora described in this blog post. I aki and I also have a arXiv paper describing all this.

Details Please see the the r2u site for all details on using r2u.

Acknowledgements The help of everybody who has worked on this is greatly appreciated. So a huge Thank you! to Albrecht, David, Stefan, Charles, Don, Michael, Detlef, G bor, I aki and whoever I may have omitted. Similarly, thanks to everybody working on R, CRAN, Debian, or Ubuntu it all makes for a superb system. And another big Thank you! goes to my GitHub sponsors whose continued support is greatly appreciated.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Next.

Previous.