Search Results: "ag"

9 January 2014

Russ Allbery: Review: Honeyed Words

Review: Honeyed Words, by J.A. Pitts
Series: Sarah Beauhall #2
Publisher: Tor
Copyright: July 2011
ISBN: 0-7653-2907-7
Format: Trade paperback
Pages: 412
Honeyed Words is a direct sequel to Black Blade Blues and probably doesn't make sense to read out of order. Sarah, Katie, their friends, and Katie's family are still recovering from the climactic events of Black Blade Blues and licking their wounds, but things are slowly looking up. Sarah is getting more comfortable openly expressing her sexuality, although there are still tensions, and her relationships are improving. The city of Vancouver also seems to be recovering. But major political shifts among the nonhuman races have echoes and ramifications, and after a kidnapped singer and a murdered dwarf, Sarah is pulled back into the turmoil. If you liked the world-building in Black Blade Blues, Honeyed Words is more of the same, but with more variety. Pitts adds elves to dwarves and dragons, shows considerably more of the supernatural world beneath the surface of human cities, and introduces Sarah to some new types of danger. There are a few more glimmers of the history of Sarah's sword and the nature of the gods in this universe, but still nothing conclusive. Pitts broadens the world-building rather than deepening it. But I liked the new characters. Teenage elves with obsessions make for great characters, and the demon who shows up about halfway through is delightful. As with the first book, this is mostly a story of things happening to Sarah while she tries to muddle through as best she can. There isn't much in the way of grand strategy or of seizing control of the plot. She just tries to do the right thing and gets lots of help from lots of friends. But the plot moves right along, and it's mixed with a healthy sense of normality that I find refreshing. She needs work as a blacksmith, she's trying to support a friend without having much money of her own, the living arrangements this forces are a bit of a strain for her own relationships, and her broken relationship with her family continues to lurk. Much urban fantasy is built around the premise of a regular person thrust into a fantasy world, but much of it then discards normal life once the supernatural starts. I think Pitts does a particularly good job of keeping his protagonist's life grounded in the ongoing mundane problems of living. It's also more fun to read about Sarah when she isn't quite as angstful. Over the course of Honeyed Words, she seems to be growing into a person who can accept who she is and feel secure about her place in the world. That's nice to see. The downside to this book is that, while it's full of quite a lot of stuff, not all of it coheres that horribly well. It has a certain "middle book" feel. The major plot resolves, but with some significant lingering consequences and something of a cliff-hanger last chapter. Most of the threads left open by the first book are still open here. There's character growth, and setup for some resolution, but not a lot of actual resolution. I still like this series, though. I like urban fantasy that isn't about vampires and werewolves; berserker blacksmiths and Norse legend has much more appeal, and I want to read more of it. Pitts's writing is a bit clunky and probably won't win many rewards, but it's serviceable and I think improving. If you enjoyed the first book, it's worth looking for this one as well. Followed by Forged in Fire. Rating: 7 out of 10

8 January 2014

Gunnar Wolf: [review] Packt's Instant Haml

Packt Publishing sent me Krzysztof Niki ski's Instant Haml to do a short blog review... Thing is, and those who read me know, I cannot write short reviews ;-) So lets see how this goes. Packt's Instant series First, as for the format this book follows and the series it fits in: They are very short books. I was the tech reviewer for their Instant Debian Build a Web Server , and when I opened it for the first time, I thought I had received only the first chapter. This series' motto is Short Fast Focused so, yes, the books are ~50 pages long, with ample margins and many big screenshots. I told the editors I was quite unsure about the value this kind of publications add, as they are very similar to online tutorials, but given they have so many books in this series (printed and electronic), there must be a market for them. They surely know their business better than me! There is one other detail regarding the publisher I'll stick in this section, although it is not specific to their Instant series: I do most of my reading in my Kindle. Packt seems to have chosen to specify a very small font for their texts. Besides the two books mentioned, I also have their Object Oriented JavaScript book. For all of the other books I read, I use the smallest font setting. Packt books in mobi format (what they present as Amazon format in their web site) are basically illegible without bumping up the font size through the roof. As I understand it, publishers should use industry-wide default sizes, and let the reader adjust their reading experience. Yes, books of technical nature (such as Packt's) often benefit from having more displayed information than what an ebook reader normally shows... But that's for me to decide! And no, this is not a Kindle-specific glitch: I also get a similar experience when opening it from Calibre. And as for the book... I am a long-time Haml convert/fan; I packaged its Ruby implementation for Debian (and should update it soon :-/ as new versions have appeared), the corresponding Emacs Lisp mode, and I use it for basically all of my static HTML sites and Ruby-based Web systems. Haml is a great templating language, meant to make dynamic HTML generation leaner and easier. It is a clean and elegant technology, and can clearly sell itself. And the project webpage has very good documentation, ranging from a short tutorial and a full API documentation for people to contribute to the project. The first part of this book, of course, covers the "why is Haml so great?" part, presenting the basic equivalences with HTML. In my opinion, the book could be structured a bit differently and would generate a stronger following. Why? Because, even given that Haml is greatly benefited from its Ruby integration and has many hooks to be tightly integrated in a Rails workflow, it can also be used by people who don't want to do Ruby. I have some static websites that are just a bunch of Haml files, compiled by a very simple Makefile and calling the haml command from the shell. I think there would be some value in presenting this invocation before learning how to call it from the Gems environment (i.e. bundle install). Using Haml as a standalone tool is only presented almost as an appendix ("Using HAML outside of Rails" section). Even more so if the author presents four different static-site solutions (probably more non-programmer-friendly than my trusty Makefile). Oh, and this little section uses the (old? obsolete?) uppercase HAML notation for the project's name instead of the now-standard Haml. Dirty screenshots About the screenshots presented in this first section (and I refer mainly to the scaffolding examples), they are meant to show how easy things are, but have an important stylistic mistake: Terminals with transparency might look cool (I hate using them, but then again I'm a very boring person when it comes to my computer habits ;-) ), but transparencies have no place in a book (be it printed or e-book), as the images appear very uncrisp. In the Kindle, they just seemed dirty Now that I'm browsing the PDF from my desktop, I see that the screenshot in "Step 1" has a photo of Earth from space behind the terminal, and even worse, in "Step 2" it is shown over a Web page detailing the installation! These elements are just distracting, and the text would be much cleaerer if it were presented typeset just as a regular code fragment. Opening many of those screenshots in the Kindle was plain useless. Editor integration It is perfectly clear from this text that the author strongly prefers Sublime Text, sometimes uses TextMate, and has just heard reports that Haml has some support in Vim, Rubymine, Emacs and Coda. Of course, devoting a full page (as it is for the first case) for each editor would be out of proportion for this size of book... I just felt the imbalance too big, specially given that most editors will sport approximately the same feature set. Text redundancy If the Instant series is about making short books, I would expect them to be loaded with easy to follow content (as they are), but free of repetition. I felt, however, a large chunk of step 1 of the "Quick start" chapter to be repeated with the the first section of the "Top 6 features" chapter. Yes, the second one adds some depth, but very little. Still, in the later parts of this "Top 6 features" chapter, a more thorough explanation could be used for the Filters, Multiline attributes/code/strings and helpers and extensions sections. It seems the author was on a hurry trying to get it finished, as it is barely explained Explaining a bit more deeply would surely benefit readers. Wrapping up Reading my review, I'm mostly talking about negative issues. IMO, the book is not excellent, but it is clearly not bad. Specially given it fits very well the format for which it was designed. There are many items that could be fixed, and I hope some of them can be fixed (i.e. the screenshots) before the book goes to print If I understand Packt's page correctly, it is currently only available as ebook, contrary to most of the Instant series' titles.

Pau Garcia i Quiles: FOSDEM Desktops DevRoom 2014: looking for volunteers for video recordings

Qt and KDE will be present at FOSDEM, the largest open-source event in Europe. One more year, we will be sharing the Desktops DevRoom with Gnome, Unity, Enlightenment, LXQt and Hawaii (a Qt Quick desktop environment). We recently published the schedule for the devroom, which will be also available in the printed booklet available at the front desk. fosdem-logo For the 2014 edition, the FOSDEM organization wants to achieve 100% recording of presentations. That means every presentation, in every room (devroom, lightning talk, main conference, etc) must be recorded. That s hundreds of talks. While the FOSDEM and devrooms organization teams comprise a lot of people, we are far too busy already with the organizative stuff and cannot spend time doing the actual recordings. Good thing is, you can help! Do you want to join the FOSDEM Video Team and receive the t-shirt? We are now looking for volunteer cameramen (and camerawomen, of course :-) ). FOSDEM will provide you with equipment and training, you only need to start recording, focus, make sure nobody gets between the camera and the speaker/stage, etc. You do NOT need to record the whole track, even one talk recording would help. More details on what will be required from you are available in this e-mail from Wouter. Please contact me (pgquiles at elpauer dot org) if you are interested in recording one or more presentations from the Desktops DevRoom.

Gunnar Wolf: Meeting with Chilean sysadmins

Meeting with Chilean sysadmins
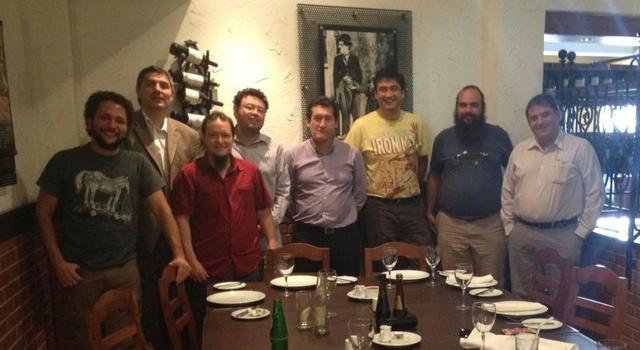
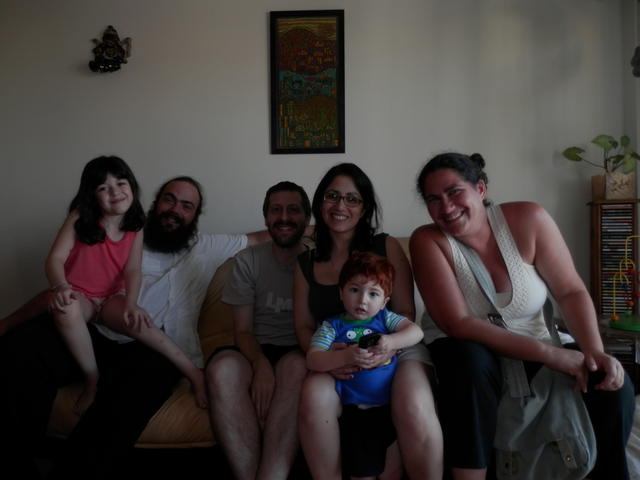
Ok, so I'm back in Mexico! This year, the best fare I found for travelling to spend the Winter^WSummer season with Regina's family had an oddity: I usually have a layover at either Santiago de Chile or Lima (Per ) of between 45 minutes and 2 hours, clearly less than enough to do anything. But this time, I had a massive 10 hours layover in Santiago. And spending 10 hours in an airport is far from fun. Specially when you have a good group of friends in town! I visited Chile in 2004 for Encuentro Linux (still before the time I had a digital camera: Those photos are all taken by Martin Michlmayr), and I have stayed in touch with a group of systems administrators since then. So, I mailed the list, and we managed to get eight people to have lunch together. In the order we appear in the photo: Some of them, even living in the same city, had never met in person before So, of course, we had a table reserved at the restaurant to the name of Dennis Ritchie. And having had nice, fun, sometimes-technical talks... Well, a tiny bit of his spirit was there. Of course, we can only trust he was there, as no Ouija boards were used and no null pointers were dereferenced (just to make sure not to disturb him). Victor Hugo and lvaro took me for a short Santiago city trip before lunch, we had a very nice time. Thanks! :-)

Jamie McClelland: New OpenPGP key

After playing around with How secure is my password, I dediced to start changing the handful of passwords I have committed to memory to being very long phrases rather than shorter, concentrated collections of random-seeming characters (another interesting blog post would be to understand the algorythm behind that site but for now I've just taken it at face value). Despite my usual practice of introducing new passphrases by changing my laptop login (which can always be reset if necessary), I went ahead and changed by GPG key instead to a new 50 character phrase. Fifteen minutes passed before I needed access to the key and... I couldn't repeat the passphrase. I tried to be clever. I opened a text file and typed in this passphrase over and over again, ultimately generating 49 unique typo-ridden versions of the passphrase. Then, I wrote a simple script that took each of these versions and generated additional versions by: In the end I had about 350,000 versions of my passphrase. None of them worked. What in the world did I type?? Could I just ask the NSA? In any event, my new OpenPGP key fingerprint is:
1F9C30CB3CFC5DA9987FA035A014C05A607B7535
Please note: I've changed the "real name" part of my User Id from "Jamie McClelland" to "James McClelland" becuase James is on my government issued id. I'll be working on collecting new signatures for the rest of my life. Some interesting information on how this made my life difficult:
Postscript: Thanks to Jordan Uggla, I was directed to passe-partout, a tool that can extract an RSA private key out of memory when ssh-agent is running with the key loaded. Since I am using the Monkeysphere, my OpenPGP key has an authentication-capable subkey, which is fed to an ssh-agent and used to grant me access to remote computers using ssh. After losing my passphrase, I was not able to access that subkey. With the help of pass-partout, and the fact that the subkey was loaded into ssh-agent before I lost the passphrase, I was able to extract the private RSA key from my ssh-agent and save it to a file. Then, I could restart my ssh-agent with my ''new'' authentication-capable OpenPGP subkey, thus allowing me to access servers that have granted me access via my new key and the handful of servers that still only grant me access via my old key.

Russell Coker: Dr Suelette Dreyfus LCA Keynote

Dr Suelette Dreyfus gave an interesting LCA keynote speech on Monday (it s online now for people who aren t attending LCA [1]). One of the interesting points she made was regarding the greater support for privacy protection in Germany, this is apparently due to so many German citizens having read their own Stasi files. The section of her talk about the technology that is being used against us today was very concerning. I wonder whether we should plan to move away from using any hardware or closed source software from the US, China, and probably most countries other than Germany. We really need to consider these issues at election time. I have previously blogged some rough ideas about having organisations such as Linux Australia poll parties to determine how well they represent the interests of citizens who use Linux [2]. I think that such things are even more important now. Steven Levy wrote an interesting summary of the situation for Wired [3]. At the end of her talk Suelette suggested that Aspies might be more likely to be whistle-blowers due to being unable to recognise the social signals about such things (IE managers say that they won t punish people for speaking out but most people recognise that to be lies). It s a plausible theory but I m worried that managers might decide to avoid hiring Aspies because of this. I wonder how many managers plan to have illegal activity as an option. But I guess that having criminals refuse to hire me wouldn t be such a bad thing.

7 January 2014

Vincent Sanders: Healthy discontent is the prelude to progress

Back in the mists of Internet time (2002) when spirits were brave, the stakes were high, men were real men, women were real women and small furry creatures from Alpha Centauri were real small furry creatures from Alpha Centauri there were few hosting options for a budding open source project.

Despite the meteoric rise of many dot com companies in the early noughties a project either had to go it alone by running everything themselves or pick from a small selection of companies that had not yet worked out how to turn free hosting into money.

One such company, arguably the first, was VA Research with their SourceForge system. Many projects used their platform including a small niche web browser called NetSurf. For years the service was great, there were rough edges but nothing awful.

Netsurf issue tracker in the new SourceForge interface
Over time the NetSurf projects requirements grew beyond what SourceForge could provide and service after service was migrated away eventually all that was left was the bug tracking system. This remained the state of affairs until mid 2013 when SourceForge forced a migration to their new platform which made them unsuitable for the projects use case.

Aside from the issue trackers questionable user interface SourceForge had started aggressively placing advertising throughout their platform. Some of the placements so inadvisable that projects started taking the decision to leave.

While I appreciate that SourceForge had to make money to provide a service they appear to have sown discontent within a large part of their user base without understanding that there are a number of alternatives solutions with a much less onerous funding model.

NetSurf used this as an opportunity to move the remaining issue tracking service to our own infrastructure. Rob Kendrick proceeded to evaluate several solutions and in December 2013 I finally found the time to migrate an XML dump of the old data from SourceForge into MantisBT.

Migrating data from one database into another via incompatible formats took me back to my roots. My early career started with programming tasks moving historical business data from ancient large systems which were about to be scrapped to modern Sparc based systems. Later I would be in a role where financial data needed to be retrieved from obsolete proprietary systems and moved into databases on x86 servers.

My experience in this field was not really stretched as it turns out that modern systems can process a few tens of megabytes in seconds rather than the days for a run in my youth! So some ugly perl scripts and a few hours later I had a nice shiny SQL database filled with NetSurfs bugs and MantisBT instance configured to use them.

NetSurf MantisBT instance showing most recently updated open bugs
Then came the hard bit, triaging all the open bugs, fixing up all the bugs submitted as an anonymous user but with email addresses in, removing duplicates and checking every open bug was still valid took almost two weeks of tedious drudge.

I set up an initial bug workflow within the system that the project developers are still fine tuning to better suit their needs but overall Mantis is proving a very flexible tool. The main deficiencies center around configuration for the projects useage, especially removing unused fields from filters and making the workflow more intuitive..

The resulting system is now getting bug reports submitted again where the sourceforge system had had three in the six months since the forced migration.

The issue tracker is once more a useful tool for the developers allowing us to focus on areas actually causing problems for our users and allowing us to see progress we are making fixing issues.

Overall this was a successful migration and provides a platform the NetSurf project can control where we can offer guarantees to our users about their personal information usage and having a clean rapid interface with no advertisements.

Craig Small: Trying out Prosody for XMPP

After reading Fran ois article about running your own XMPP server, I thought I d give it a go myself. A comment from Steven suggested that prosody would be a better and simpler alternative so I went with that. It is actually really simple with about 5 lines to add to the config, as well as firewall changes. The only trick is if you have a chained SSL certificate like mine you need to cat the certificate and the CA one together, otherwise you get SSL errors. So I m up and going with a XMPP contact the same as my email address which is csmall and then the domain enc.com.au
It just doesn t have anyone as contacts yet :( I ll be adding the DNS records for it shortly.

Dirk Eddelbuettel: RcppArmadillo 0.400

A new major release 4.000 of Armadillo came out out yesterday morning. This is a new stable release by Conrad with a new major number, and it brings a few nice changes as detailed below. I rolled up RcppArmadillo version 0.400 yesterday morning, and following a little bit of discussion this version is now on CRAN and in Debian. The complete list of changes is below.
Changes in RcppArmadillo version 0.4.000 (2014-01-05)
  • Upgraded to Armadillo release Version 4.000 (Feral Steamroller)
    • added eigen decompositions of sparse matrices: eigs_sym() and eigs_gen() [ but this requires linking against ARPACK which RcppArmadillo as a pure-template package does not do, and R is not linked against ARPACK either. ]
    • added eigen decomposition for pair of matrices: eig_pair()
    • added simpler forms of eig_gen()
    • added condition number of matrices: cond()
    • expanded find() to handle cubes
    • expanded subcube views to access elements specified in a vector
    • template argument for running_stat_vec expanded to accept vector types
    • more robust fast inverse of 4x4 matrices
    • faster divide-and-conquer decompositions are now used by default for eig_sym(), pinv(), princomp(), rank(), svd(), svd_econ()
    • the form inv(sympd(X)) no longer assumes that X is positive definite; use inv_sympd() instead
    • added MEX connector for interfacing Octave/Matlab with Armadillo matrices (contributed by George Yammine)
Courtesy of CRANberries, there is also a diffstat report for the most recent release As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

6 January 2014

Russ Allbery: remctl 3.7

remctl is the middleware layer that we use everywhere at Stanford. It's a simple GSS-API-authenticated network service that supports running commands with ACLs. There are client bindings available for a wide variety of programming languages. This release fixes a couple of irritating bugs: the client library leaked memory when remctl_set_ccache was used (which was affecting mod_webkdc from WebAuth), and Net::Remctl::Backend didn't validate argument counts correctly when one of the arguments came from standard input (which affected krb5-sync). I also worked around a bug in RHEL 5's Module::Build, and added sanity checking to Net::Remctl and related classes to ensure that the object argument wasn't undef. Also new in this release are support in the remctld server for systemd startup notification and socket activation, and (via the -Z) flag) support for upstart's expect stop synchronization method. This is mostly a "clearing the decks" release in advance of more significant work. The next release will replace the server event loop with libevent, in preparation for further improvements in how the server can handle persistent worker children. You can get the latest release from the remctl distribution page.

Raphaël Hertzog: My Free Software Activities in December 2013

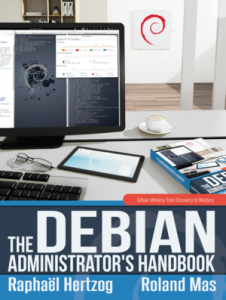
This is my monthly summary of my free software related activities. If you re among the people who made a donation to support my work (147.56 , thanks everybody!), then you can learn how I spent your money. Otherwise it s just an interesting status update on my various projects. The Debian Administrator s Handbook Cover of the Debian Administrator's Handbook (Wheezy edition)I spent a good chunk of December on the book. First finalizing the English version and getting it out (BTW, just for the launch, there s a 10% discount on the paperback that lasts only until January 9th!). Then working on updating the French translation. Eyrolles will publish a new edition of the French book based on this translation. Expect some further news about this during January! Debian France I contributed to many discussions within Debian France. Starting with a complaint that most events are organized in Paris, I proposed to map the location of Debian France members. We added new fields in the membership management page so that members can add their GPS coordinates and Fr d ric Decou made some experiments with Openstreetmap. Someone else (Kiriarat) volunteered to write the required glue code. A manual map is currently maintained on the website. Sample logo receivedIn the discussions about the setup of the Debian France shop, I suggested to update our logo with a nicer looking one. We got a few suggestions and after further discussions with Alexandre Delano and Sylvestre Ledru, we organized a small contest to entice designers to submit a logo proposal to us (the winner earns a set of Debian goodies). We got 46 proposals (see my favorite on the right)! The board is currently pre-selecting the logos and setting up the final vote for our members. The winner shall be announced at the end of the upcoming mini-debconf in Paris. I also continued the work to finalize new bylaws and new internal rules. They shall be adopted during the next general assembly which will happen during the mini-debconf. Misc Debian Work WordPress maintenance. I mentored Pablo Vasquez to do his first small contribution to the WordPress packaging. I really appreciate this but he s not yet ready to assume maintenance of a big package like WordPress on his own. I got multiple other offers of help and pinged them all while filing #733726 to coordinate the work on the new upstream version. But I got no reply :-( Handing over packages to new maintainers is hard Init system discussion. The technical committee has the hard task of picking the default init system that will replace the traditional System V init (see #727708). I followed this huge discussion closely and contributed a bit where I add something meaningful to say. Final decision is expected sometimes in January. FWIW, I share entirely Russ Allbery s point of view in those discussions. I have been running systemd on some of my computers for a few months already. Fixing lxc in stable. The lxc package in stable has a non-working debian template. I really dislike documenting that things are broken so instead of doing that in the Debian Administrator s Handbook, I opted to do something about it. I prepared a non maintainer upload for stable (see #680469 for the problem and #732358 for the stable update request). Misc stuff. I sponsored a tcpdf upload. I filed an enhancement request on Publican to have it keep processing instructions present in translations. I uploaded new versions of publican-librement and debian-handbook. I filed #732678 against git-buildpackage because it failed to properly call lintian when given the -A dpkg-buildpackage argument. Thanks See you next month for a new summary of my activities.

No comment Liked this article? Click here. My blog is Flattr-enabled.

Aurelien Jarno: Debian QEMU images updated

Following the release of Debian Wheezy, I have (finally) updated my set of Debian QEMU images for both Squeeze (6.0.8) and Wheezy (7.3). The following images are now available: Each of these directories contains a GPG signed README.txt file with the md5sums all files, detailed instructions how to run these images and especially the minimum QEMU version to use. The requirements to run the default desktop environment have increased a lot between Squeeze and Wheezy. An accelerated graphics card is now needed to be able to use Gnome (unless you use the fallback mode), which is not something provided by QEMU (actually there is now a QXL para-virtualized video card, but the driver is only in unstable). In addition GDM now needs more than 128MiB to start, while this is the default amount of memory provided for virtual machines. I have therefore decided to switch the default desktop environment on the Wheezy images to Xfce and the display manager to LightDM. Both Gnome and GDM are still installed on the images, and the original default can easily be restored using the following commands: Beside this the new images only contain minor changes. The filesystems have been tweaked to not run fsck after a certain amount of days, and locales-all and openssh-server are now installed in all images. For MIPS and MIPSEL, 64-bit kernels are now also installed and provided, so that it is possible to choose between a 32-bit or a 64-bit kernel (see the README.txt for more details). There is no Debian Wheezy SPARC image available, as QEMU does not fully support SPARC64 yet (it is actually possible to run it, but then the VM crashes often), and Debian Wheezy now only supports 64-bit kernels. I will also invest time to build an S390X image, but so far I haven t been successful on that. The following images are still available at the same location, though they haven t been updated:

Vincent Sanders: NetSurf Developer Workshop Redux

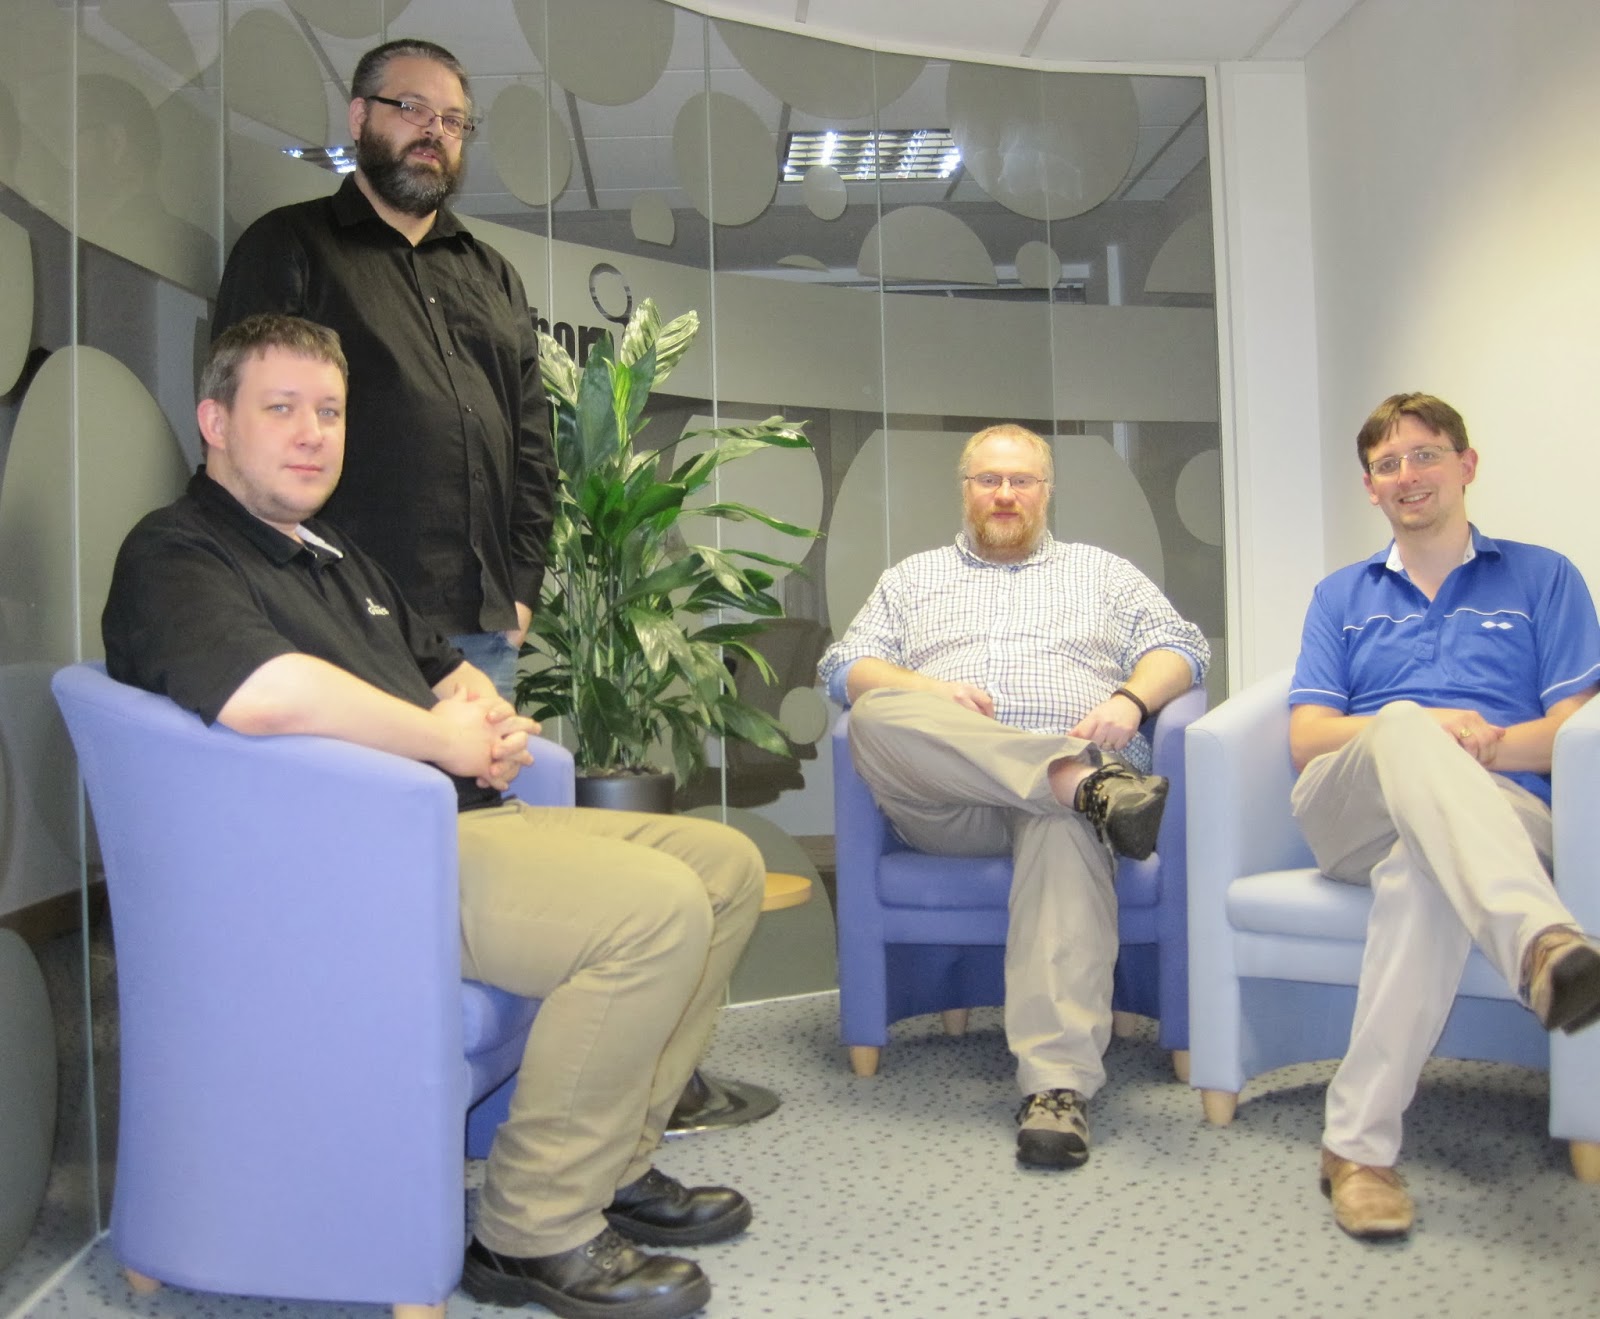
The NetSurf Developers bringing you alternative LOLcat viewing software since 2002Once again the NetSurf developers congregated in Cambridge at the Collabora offices where we were made welcome in a nice environment for the event.

Five developers managed to attend from around the UK Rob Kendrick, Vincent Sanders, Daniel Silverstone, John-Mark Bell and Michael Drake. We also had Chris Young and Fran ois Revol providing some bug fixes remotely.

This was the first time we had all met since the previous event towards the end of 2012 and we took full advantage of this to discuss a pretty extensive agenda in addition to the practical programming tasks.

From Friday lunchtime through to Sunday evening we managed 30 hours of work consisting of over 70 commits to over 100 files.

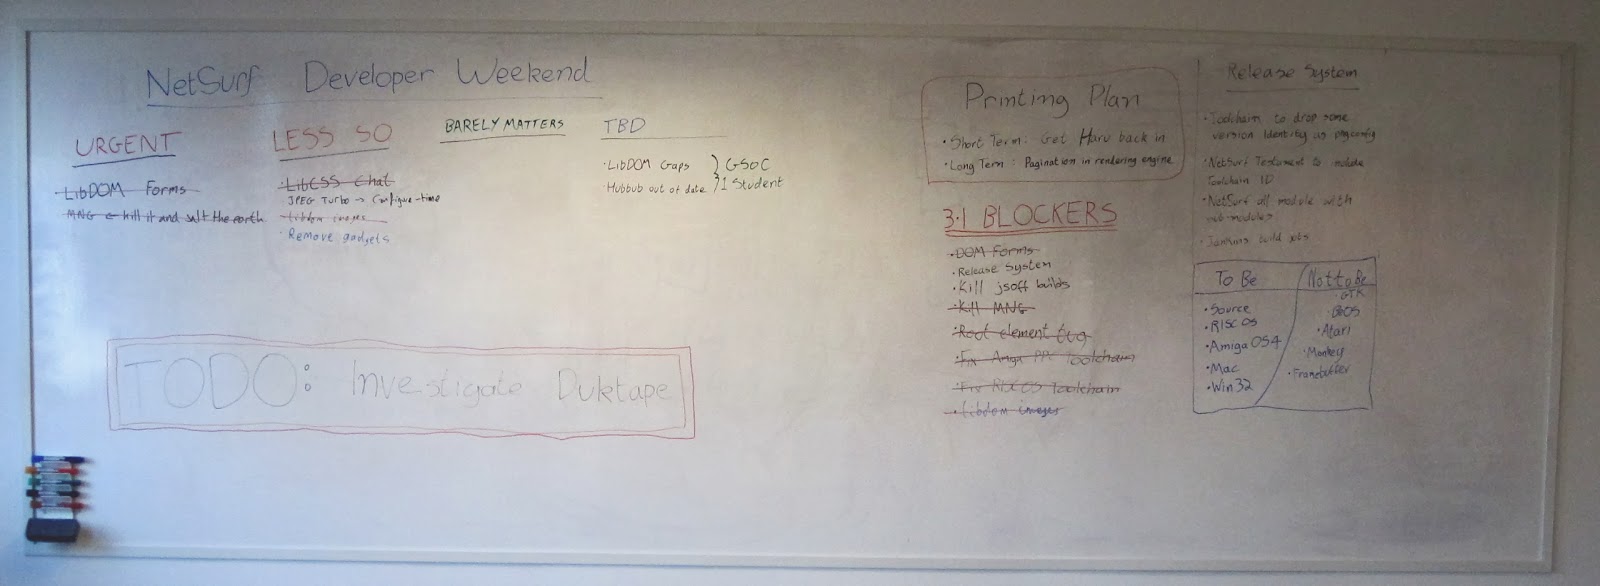
The whiteboard of our notes

Our main focus was working towards a 3.1 release which is scheduled for early April. Along with the source the release will have binary builds for RISC OS, AmigaOS, Windows and Mac OS X (x86 and ppc). Although the NetSurf project will not be directly releasing binaries for the GTK and Framebuffer frontends we will be ensuring the Debian packages are updated which is our prefered method of distribution for those targets.

We analysed the 3.0 release and formulated an improved process for the future. The 3.1 release will be generated automatically by the CI system ensuring constant results and removing the problems we encountered previously.

A set of release blocking issues was derived which we used as a task list during the workshop.The majority of these were completed including:
DOM based forms
Web forms are a feature Netsurf has supported for a long time and their implementation has not kept up with the rest of the browser. This is a long standing problem area which has resulted in numerous strange bugs with form submission. With this change the form system has been reworked to correctly operate directly from the DOM resulting in the squashing of a large number of bugs and a much improved user experience.

DOM based image loading
Up to now image fetching was performed only during the rendering of a page. With this change when the image link is placed into the DOM during the page parse it is scheduled to be fetched, this should give an improved user experience as images should be available earlier in a pages render.

Removal of MNG support
NetSurf has supported MNG since the 1.0 release, indeed the MNG library used to provide the PNG support too though we have long ago transitioned to libPNG. Alas the web has moved on and MNG has been largely forgotten, the libMNG library that performs the image decoding is old and generally unsupported specifically lacking security updates.

The build issues with libMNG (lack of pkg-config, reliance on libcms1 etc.) were causing maintenance issues in code nobody was actually using (there were crash bugs discovered during its removal!). Because of these issues it was decided to join the vast majority of browsers and remove support for this format.
The developers also addressed several issues with toolchain construction and a number of annoying usability bugs.

Plans for how to improve printing support we made. Initially we intend to fix the existing haru based pdf generation using this to print via pdf and in future have correct css styled page paginated printing render output.

The perennial issue of javascript was discussed however, while efforts to improve the existing support are ongoing, our usage of the spidermonkey library continues to raise various challenges including platform support and API changes between versions.

Due to these issues it has been suggested that we might add support for using the duktape JS engine instead, initial results are promising but given the size of the task of implementing an additional javascript engine binding further investigation is necessary before making a commitment.

Amongst the other discussions the group has also agreed that we will once again apply to be a GSoC organisation for a single student with some very focused projects:
  • Improving our HTML5 parser (hubbub)
  • Improving the DOM library implementing missing functionality.
While neither of these projects are as fashionable as some of our previous proposals they are well defined enough that as a group we believe we could offer enough support to the student to make their experience a pleasurable one and get the resulting code reviewed and merged promptly.

This event was very successful with a great deal achieved, the project is much more likely to be in a good shape to release 3.1 by April now and the meeting has given the developers a much welcomed boost.

I would like to extend the groups thanks to Robert McQueen for letting us use the Collabora offices, Dor e Carrier for organising all the administrative things and to Vivek Dasmohapatra for coming out on his Sunday afternoon to let us back in after locking ourselves out.


Julien Danjou: Databases integration testing strategies with Python

The Ceilometer project supports various database backend that can be used as storage. Among them are MongoDB, SQLite MySQL, PostgreSQL, HBase, DB2 All Ceilometer's code is unit tested, but when dealing with external storage services, one cannot be sure that the code is really working. You could be inserting data with an incorrect SQL statement, or in the wrong table. Only having the real database storage running and being used can tell you that.
Over the months, we developed integration testing on top of our unit testing to validate that our storage drivers are able to deal with real world databases. That is not really different from generic integration testing. Integration testing is about plugging all the pieces of your software all together and running. In what I call "database integration testing", the pieces will be both your software and the database system that you are going to rely on. The only difference here is that one of the module is not coming from the application itself but is an external project. The type of database that you use (RDBMS, NoSQL ) does not matter. Taking a step back, what I will describe here could also apply to a lot of other different software modules, even something that would not be a database sytem at all. Writing tests for integration Presumably, your Python application has unit tests. In order to test against a database back-end, you need to write a few specific classes of tests that will use the database subsystem for real. For example:
import unittest
import os
import sqlalchemy

class TestDB(unittest.TestCase):
def setUp(self):
url = os.getenv("DB_TEST_URL")
if not url:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(url)

This code will try to fetch the database URL to use from an environment variable, and then will rely on SQLAlchemy to create a database connection.
import unittest
import os
import sqlalchemy

import myapp

class TestDB(unittest.TestCase):
def setUp(self):
url = os.getenv("DB_TEST_URL")
if not url:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(url)

def test_foobar(self):
self.assertTrue(myapp.store_integer(self.engine, 42))

You can then add as many tests as you want using the connection stored in self.engine. If no test database URL is, the tests will be skipped; however that decision is up to you. You may want to have these tests always run and fail if they can't be run. In the setUp() method, you may also need to do more work, like create a database and delete a database.
import unittest
import os
import sqlalchemy

class TestDB(unittest.TestCase):
def setUp(self):
url = os.getenv("DB_TEST_URL")
if not url:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(url)
self.connection = self.engine.connect()
self.connection.execute("CREATE DATABASE testdb")

def tearDown(self):
self.connection.execute("DROP DATABASE testdb")

This will make sure that the database you need is clean and ready to be used to testing. Launching modules, a.k.a. databases
The main problem we encountered when building integration testing with databases, is to find a way to start them. Most users are used to start them system-wide with some sort of init script, but when running sandboxed tests, that is not really a good option. Browsing the documentation of each storage allowed us to find a way to start them in foreground and control them "interactively" via a shell script. The following is a script that you can use to run Python tests using nose and is heavily inspired by the one we wrote for Ceilometer.
#!/bin/bash
set -e

clean_exit()
local error_code="$?"
kill -9 $(jobs -p) >/dev/null 2>&1 true
rm -rf "PGSQL_DATA"
return $error_code


check_for_cmd ()
if ! which "$1" >/dev/null 2>&1
then
echo "Could not find $1 command" 1>&2
exit 1
fi


wait_for_line ()
while read line
do
echo "$line" grep -q "$1" && break
done < "$2"
# Read the fifo for ever otherwise process would block
cat "$2" >/dev/null &


check_for_cmd mongod

trap "clean_exit" EXIT

# Start PostgreSQL process for tests
PGSQL_DATA= mktemp -d /tmp/PGSQL-XXXXX
PGSQL_PATH= pg_config --bindir
PGSQL_PATH /initdb $ PGSQL_DATA
mkfifo $ PGSQL_DATA /out
$ PGSQL_PATH /postgres -F -k $ PGSQL_DATA -D $ PGSQL_DATA &> $ PGSQL_DATA /out &
# Wait for PostgreSQL to start listening to connections
wait_for_line "database system is ready to accept connections" $ PGSQL_DATA /out
export DB_TEST_URL="postgresql:///?host=$ PGSQL_DATA &dbname=template1"

# Run the tests
nosetests

If you use tox to automatize your test run, you can use this scripts (I call it run-test.sh) in your tox.ini file.
[testenv]
commands = toxinidir /run-tests.sh posargs

Most databases are able to be run in some sort of standalone mode where you can connect to them using a either a Unix domain socket, or a fixed port. Here are the snippet used in Ceilometer to run with MongoDB and MySQL:
# Start MongoDB process for tests
MONGO_DATA=$(mktemp -d /tmp/MONGODB-XXXXX)
MONGO_PORT=29000
mkfifo $ MONGO_DATA /out
mongod --maxConns 32 --nojournal --noprealloc --smallfiles --quiet --noauth --port $ MONGO_PORT --dbpath "$ MONGO_DATA " --bind_ip localhost &>$ MONGO_DATA /out &
# Wait for Mongo to start listening to connections
wait_for_line "waiting for connections on port $ MONGO_PORT " $ MONGO_DATA /out
export DB_TEST_URL="mongodb://localhost:$ MONGO_PORT /testdb"

# Start MySQL process for tests
MYSQL_DATA=$(mktemp -d /tmp/MYSQL-XXXXX)
mkfifo $ MYSQL_DATA /out
mysqld --datadir=$ MYSQL_DATA --pid-file=$ MYSQL_DATA /mysql.pid --socket=$ MYSQL_DATA /mysql.socket --skip-networking --skip-grant-tables &> $ MYSQL_DATA /out &
# Wait for MySQL to start listening to connections
wait_for_line "mysqld: ready for connections." $ MYSQL_DATA /out
export DB_TEST_URL="mysql://root@localhost/testdb?unix_socket=$ MYSQL_DATA /mysql.socket&charset=utf8"

The mechanism is always the same. We create a fifo with mkfifo, and then run the database daemon with the output redirected to that fifo. We then read from it until we find a line stating the the database is ready to be used. At that point, we can continue and start running the tests. You have to read continuously from the fifo, otherwise the process writing to it will block. We redirect the output to /dev/null, but you could also redirect it to a different log file, or not at all. One step further: using parallelism and scenarios The described approach is quite simple, as it only support one database type. When using an abstraction layer, such as SQLAlchemy, it would be a good idea to run all these tests against different RDBMS, such as MySQL and PostgreSQL for example. The snippet above allows to run both RDBMS in parallel, but the classic approach of unit tests does not allow that. Using one scenario for each database backend would be a great idea. To that end, you can use the testscenarios library.
import unittest
import os
import sqlalchemy
import testscenarios

load_tests = testscenarios.load_tests_apply_scenarios

class TestDB(unittest.TestCase):
scenarios = [
('mysql', dict(database_connection=os.getenv("MYSQL_TEST_URL")),
('postgresql', dict(database_connection=os.getenv("PGSQL_TEST_URL")),
]

def setUp(self):
if not self.database_connection:
self.skipTest("No database URL set")
self.engine = sqlalchemy.create_engine(self.database_connection)
self.connection = self.engine.connect()
self.connection.execute("CREATE DATABASE testdb")

def tearDown(self):
self.connection.execute("DROP DATABASE testdb")

$ python -m subunit.run test_scenario   subunit2pyunit
test_scenario.TestDB.test_foobar(mysql)
test_scenario.TestDB.test_foobar(mysql) ... ok
test_scenario.TestDB.test_foobar(postgresql)
test_scenario.TestDB.test_foobar(postgresql) ... ok

---------------------------------------------------------
Ran 2 tests in 0.061s

OK

To speed up tests run, you could also run the test in parallel. It can be intesting as you'll be able to spread the workload among a lot of different CPUs. However, note that it can require a different database for each test or a locking mechanism to be in place. It's likely that your tests won't be able to work altogether at the same time on only one database. (Both usage of scenarios and parallelism in testing will be covered in The Hacker's Guide to Python, in case you wonder.)
The Hacker's Guide to Python
A book I'm writing that will be launched soon, talking about designing Python applications, state of the art, and various Python tips. If you want to be the first to hear about the launch, subscribe now.

Gunnar Wolf: Pan Latin American Hashomer, 18 years later

Pan Latin American Hashomer, 18 years later
In 1994/1995, I spent probably the most unique and memorable year of my life with the people of several Zionist youth movements in Israel, working in a kibutz, learning in Jerusalem... In 1995, after most of my group returned to Mexico, I stuck with the newly arrived South American group of Hashomer Hatzair (plus some affiliates). We were 18-19. And 18-19 years later, here we are: Fabi n (from Buenos Aires) and Fabiana (from Montevideo), living in Buenos Aires, with two kids. Regina (from Paran ) and me (from Mexico), living in Mexico, no kids yet. Two couples. Three countries. Four cities. And a lovely evening. And the hopes to stay in touch, to meet every year when we come to visit Argentina.

Steve Kemp: A beginning is a very delicate time.

Recently I wrote about docker, after a brief diversion into using runit for service management, I then wrote about it some more. I'm currently setting up a new PXE-boot environment which uses docker for serving DHCP and TFTPD, which is my first "real" usage of any note. It is fun, although I now discover I'm not alone in using docker for this purpose. Otherwise life is good, and my blog-spam detection service recently broke through the 11 million-rejected-comment barrier. The Wordpress Plugin is seeing a fair amount of use, which is encouraging - but more reviews would be nice ;) I could write about work, I've not done that since changing job, but I'm waiting for something disruptive to happen first.. ObQuote: Dune. (film)

Russell Coker: Length of Conference Questions

After LCA last year I wrote about speaking stacks and conference questions [1]. In that post I did some rough calculations on the amount of conference time taken by questions and determined that anyone who asks one question per day at a conference such as LCA (with about 600 delegates) is going to be asking more than 1/600 of all questions. That doesn t necessarily mean that someone shouldn t ask more than one question in a day, but they should carefully consider whether their questions are adding value to other delegates. Another issue that I ve noticed is the length of questions which seems to be a separate problem and it seems that we should consider keynote speeches separately as they involve all delegates. The regular conference lectures involve 4 to 6 streams running in parallel which means that in aggregate more questions can be asked. LCA has one keynote for each day including the mini-conf days, so that s 5 keynote speeches in total. If each keynote has 20 minutes of question time (and most keynote speeches probably have less) then there s 100 minutes of question time for the entire conference. For a genuine question (IE not a statement) that is non-trivial (anything that has a yes/no answer probably isn t interesting to the whole audience) the answer is probably going to be about three times as long as the question. Given some overheads for applause etc that means that the amount of time spent asking questions would be something less than 20 minutes at keynote speeches over the entire conference. If every delegate asked one keynote-speech question in the entire conference then that 20 minutes of questions would allow each delegate to spend 2 seconds asking a question. If 10% of delegates each asked one question and no-one asked a second question then each question could take an average of 20 seconds. Given the acoustic issues of asking a question from the back of the hall it seems unlikely to get a speaking rate of much more than a word a second, so 20 seconds of speaking would be in the range of 25 words (one tweet) to 50 words (if you speak at the typical speed of audio books according to Wikipedia). I think that audio-book speed isn t going to work well so a question asked at a keynote speech should probably be of a length that would fit on twitter. So if a question wouldn t fit on twitter then maybe a blog post or a discussion after the lecture would be a more suitable option. Before Asking a Question I think that before asking a question at a keynote speech people should consider whether that question would fit on twitter. They should also consider whether it is strictly a question and whether it will be of interest to other delegates. If your question is significantly longer than something that would fit on twitter then the next thing to consider is whether you are more important than other delegates. Because when someone asks more or longer questions than other people it will be interpreted as an implicit I am more important than you statement by many other delegates. Some Disclaimers Firstly I m not making any suggestions here for people who run conferences. I m making suggestions for delegates who are considering how they should act. The next disclaimer is that the educational benefit of the conference has the priority. If you have a question that really helps other delegates learn something which takes a little longer to ask then that s OK. Finally I apply the same criteria to my own decisions. There were several questions I considered asking at the keynote this morning, but I decided that none of them met the criteria of being short enough and generally interesting enough. There is one issue I will discuss with the speaker privately and I ll probably write at least one blog post related to the lecture.

Russ Allbery: rra-c-util 5.1

The primary addition in this release is the Autoconf macros and header wrapper that I developed for lbcd to add systemd support. These are inspired by the code in systemd's daemon(7) man page but adjusted for my normal software conventions. This is just preliminary and doesn't yet stub out all of the functions, only the ones I've needed so far. Also in this release, I fixed a bug with process_start_fakeroot, and hence with remctld_start_fakeroot, introduced in the last release when I rewrote the TAP process management add-on. You can get the latest release from the rra-c-util distribution page.

5 January 2014

Jonathan Carter: Happy 2014!

So, it s 2014 and I still haven t migrated away from WordPress to using something fancy written in Python. But who cares? Life is great and I ve made good progress in lots of other areas :) I m getting fitter by the day, last year I joined a running club and I now play squash too, which is working so much better than just going to the gym. Also finally making progress with learning how to play guitar, another ancient goal of mine that had slow progress for a while. It helps that I now live on my own and can make noise whenever I want to. I m also going for lessons every Wednesday and have some plans to convert my spare room in to a music room. I ve also gotten into beer brewing. I attended Beerschool via Beerlab, my first batch of American Pale Ale is just about ready for bottling and I ll probably do that next weekend. What else? Well, this year I definitely want to be more focused in my free software contributions than in 2013. I want to get my Debian contributions flowing well again with the aim of becoming a Debian Maintainer. Also planning to go to Debconf in Portland, Oregon in August. Then there s LTSP which is working towards LTSP 6, which will see a huge shift in proper support for local processing and less on thin client support. Not sure how far my involvement will stretch there but I m certainly very interested and will do my best to make the LTSP hackfest later in the year. The next 2-3 months will need the most focus on Edubuntu. The 14.04 LTS release will be a big release and the single-sign-on directory infrastructure that will be released along with it will mark a big milestone for the project. Well, to anyone still reading my blog, have a great 2014!

Jon Dowland: 2013 In Fiction

I read a lot this year - I'll write more about that and reflections on goodreads in another post - but most of the things I read weren't published in 2013. (I should also write a bit about my thoughts on e-readers). However, it seems I have enough to write about 2013's novels to make a round-up post worthwhile, so here we go.
The Cuckoos Calling UK cover
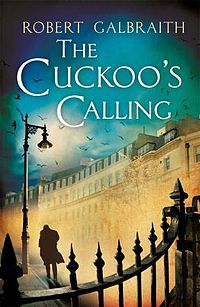
This year, crime author Robert Galbraith published his first novel The Cuckoo's Calling. I'd never have heard of it if Galbraith was not outed as an alias for Joanne "JK" Rowling. Clues that Rowling was working on a detective story exist as early as a Guardian preview article in 2012 for her last novel, The Casual Vacancy. Further hints, for me, that this was no first-time author were the taglines from Ian Rankin and Val McDermid on the cover, writers of a calibre I'd be surprised a new author could attract. However I don't know whether they were on the pre-unveiling cover or not. Rowling was upset be outed, having enjoyed the freedom to write without the baggage of expectation that she is subject to. I hope she's pleased: prior to her unmasking the novel was warmly received by the (admittedly relatively small) number of people who read it. And a very good novel it is too. It starts with a genre clich of a grizzled, meloncholy detective, Mr. Cormoran Strike, in an upstairs office with a neon light flickering through the window, but fleshes the story out both forwards - a client, a mysterious death - and backwards - how did Mr. Strike end up in that upstairs office - living out of it, no less? As is traditional for the genre there's a very clever twist. What I really enjoyed about Cormoran Strike was Galbraith/Rowling moving quickly from Chandler-esque everyman to a well fleshed-out, complex protagonist, intertwining the development of the character with the unfolding of the wider plot. I'm looking forward to the sequel, expected in 2014.
The Shining Girls UK cover
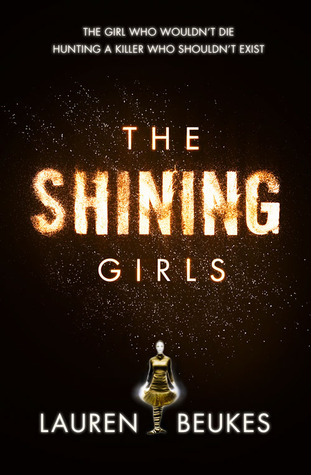
A second surprise favourite this year was Lauren Beukes' time-tripping crime story The Shining Girls. A monsterous murder of women somehow finds a room in Chicago that lets him travel through time (or perhaps the room finds him). He uses this facility to stalk and murder a set of Shining Girls: women who, for one reason or another, literally 'shine' in his perception of them. One such woman survives his first attack and decides to try and find out who attacked her, and why. The crimes are described in a brutal fashion which - from a distance - resemble the sometimes glorified violence for which crime fiction is sometimes criticised, but the focus of the story is very much on the victims: they are fully fleshed out characters and each death is felt by the reader as a genuine tragedy. I discovered Beukes when her earlier novel Zoo City was included in a Humble eBook bundle. On reading The Shining Girls I felt that the novel deserved to be more widely known than I would expect it to be trapped in the ghetto of genre fiction, so I was pleased to discover that the very mainstream Richard and Judy Book Club discovered it. In established author news, Terry Pratchett, having adopted speech recognition for writing (to combat his debilitating Alzheimer's) has seemingly managed to accelerate his rate of production and squeezed out at least two this year: The Long War with Stephen Baxter is the sequel to 2012's The Long Earth which I very much enjoyed, but it really felt like "difficult second novel" to me. Hopefully there'll be a third. Raising Steam, the 40th Discworld novel, was an enjoyable romp around the concept of steam trains, featuring the relatively new Moist von Lipwig who has managed to become one of my favourite Discworld characters. I can't think of much more to say about the novel, really. It's a Discworld novel, probably not the best introduction to the series for a new reader, but will give a reader familiar with the franchise everything they expect, and possibly no more. Iain Banks sadly died this year, shortly after the publication of his last novel, The Quarry. It's sat on my hardback shelf for the time being. I couldn't bring myself to read it in 2013. I did read his last SF offering from the year prior, The Hydrogen Sonata. Sadly, yet coincidentally, both of these books examine the nature of living and dying, The Quarry in particular from the point of view of a terminal cancer sufferer. I have a small backlog of unread Banks fiction which I want to take my time over with. Finally, whilst not really a book, I thoroughly enjoyed the BBC's 2013 adaptation of Neil Gaiman's Neverwhere. Natalie Dormer wrote a piece on the making of the drama which should serve as a good introduction. At the time of writing, most of the programmes have disappeared from iPlayer, but I would be surprised if this wasn't released commercially at some point.

Next.

Previous.