Search Results: "zed"

24 April 2017

Mike Gabriel: [Arctica Project] Release of nx-libs (version 3.5.99.6)

Introduction NX is a software suite which implements very efficient compression of the X11 protocol. This increases performance when using X applications over a network, especially a slow one. NX (v3) has been originally developed by NoMachine and has been Free Software ever since. Since NoMachine obsoleted NX (v3) some time back in 2013/2014, the maintenance has been continued by a versatile group of developers. The work on NX (v3) is being continued under the project name "nx-libs". Release Announcement On Friday, Apr 21st 2017, version 3.5.99.6 of nx-libs has been released [1]. As some of you might have noticed, the release announcements for 3.5.99.4 and 3.5.99.5 have never been posted / written, so this announcement lists changes introduced since 3.5.99.3. Credits There are alway many people to thank, so I won't mention all here. The person I need to mention here is Mihai Moldovan, though. He virtually is our QA manager, although not officially entitled. The feedback he gives on code reviews is sooo awesome!!! May you be available to our project for a long time. Thanks a lot, Mihai!!! Changes between 3.5.99.4 and 3.5.99.3 Changes between 3.5.99.5 and 3.5.99.4 Changes between 3.5.99.6 and 3.5.99.5 Change Log Lists of changes (since 3.5.99.3) can be obtained from here (3.5.99.3 -> .4), here (3.5.99.4 -> .5) and here (3.5.99.5 -> .6) Known Issues A list of known issues can be obtained from the nx-libs issue tracker [issues]. Binary Builds You can obtain binary builds of nx-libs for Debian (jessie, stretch, unstable) and Ubuntu (trusty, xenial) via these apt-URLs: Our package server's archive key is: 0x98DE3101 (fingerprint: 7A49 CD37 EBAE 2501 B9B4 F7EA A868 0F55 98DE 3101). Use this command to make APT trust our package server:
 wget -qO - http://packages.arctica-project.org/archive.key   sudo apt-key add -
The nx-libs software project brings to you the binary packages nxproxy (client-side component) and nxagent (nx-X11 server, server-side component). The nxagent Xserver can be used from remote sessions (via nxcomp compression library) or as a next Xserver. Ubuntu developers, please note: we have added nightly builds for Ubuntu latest to our build server. At the moment, you can obtain nx-libs builds for Ubuntu 16.10 (yakkety) and 17.04 (zenial) as nightly builds. References

19 April 2017

Antoine Beaupr : The rise of Linux-based networking hardware

Linux usage in networking hardware has been on the rise for some time. During the latest Netdev conference held in Montreal this April, people talked seriously about Linux running on high end, "top of rack" (TOR) networking equipment. Those devices have long been the realm of proprietary hardware and software companies like Cisco or Juniper, but Linux seems to be making some significant headway into the domain. According to Shrijeet Mukherjee, VP of Engineering at Cumulus Networks: "we are seeing a 28% adoption rate in the Fortune 50" companies. As someone who has worked in system administration and networking for over a decade, I was surprised by this: switches have always been black boxes of proprietary hardware that we barely get a shell into. But as more and more TOR hardware gets Linux support, some of that work trickles down outside of that niche. Are we really seeing the rise of Linux in high-end networking hardware?

Linux as the standard interface During his keynote at Netdev, Jesse Brandeburg explained that traffic is exploding on the Internet: "From 2006 to 2016 the compound annual growth rate was 78% of network traffic. So the network traffic is growing like crazy. In 2010 to 2023, it's going to grow by a thousand times." He also mentioned Intel was working on devices that could do up to 400 Gbps. In his talk, he argued that Linux has a critical place in the modern world by repeating the mantra that "everything is on the network, and the network runs Linux", but does it really? Through Android, Linux has become the most popular end-user device operating system and is also dominant on the server but what about the actual fabric of the network: the routers and switches that interconnect all those machines? Mukherjee, in his own keynote, argued that even though Linux has achieved dominance in the server and virtualization markets, there is a "discontinuity [...] at the boundary where the host and the network meet" and argued "that the host without the network will not survive". In other words, proprietary hardware and software in the network threaten free software in the server. Even though some manufacturers are already providing a "Linux interface" in their hardware, it is often only some sort of compatibility shell which might be compared with the Ubuntu compatibility layer in Windows: it's not a real Linux. Mukherjee pushed this idea further by saying that those companies are limiting themselves by not using the full Linux stack. He presented Linux as the "top vehicle for innovation" that provides a featureful network stack, citing VXLAN, eBPF, and Quagga as prime features used on switches. Mukherjee also praised the diversity of the user-space Linux ecosystem as something that commercial alternatives can't rival; he compared the faster Linux development to the commercial sector where similar top features stay in the beta stage for up to 3 years. Because of its dominance in the server market, consumers are expecting a Linux-like interface on their networking gear now, which means Linux could be the standard interface all providers strive toward. As a Debian developer, I can't help but smile at the thought; if there's one thing we have not been able to do among Linux distributions, it's pretty much standardize user space in a consistent interface. POSIX is old and incomplete, the FHS is showing its age, and most distributions have abandoned LSB. Yet, the idea is certainly enticing: there is a base set of tools and applications, especially for the Linux kernel, that are standardized: iproute2, ethtool, and iptables are generally consistent across distributions, even though each distribution has its own way of using them. Yet Linux is not dominant, why? Mukherjee identified the problem as "packaging issues" and listed a set of features he would like Linux to improve:
  • Standardization of the ethtool interface. The idea is to make ethtool a de-facto standard to manage switches and ports. Mukherjee gave the example that data centers spend more money on cables than any other hardware and explained that making it easier to identify cables is therefore a key functionality. Getting consistent interface naming was also a key problem identified by numerous participants at the conference. While systemd tried to fix this with the predictable network interface names specification, the interface names are not necessarily predictable across virtual machines or on special hardware; in fact, this was the topic of the first talk of the conference. ethtool also needs to support interfaces that run faster than 1 Gbps, something that still has limited support in Linux at the moment.
  • Scaling of the Linux bridge. Through the rise of "software defined networking", we are likely to see multi-switch virtual environments that need to scale to hundreds of interfaces and devices easily. This is something the Linux bridge was never designed to do and it's showing scalability issues. During the conference, there was hope that the new XDP and eBPF developments could help, but also concerns this would create yet another bridge layer inside the kernel.
Cumulus's goal seems to be to establish Linux as the industry standard for this new era of networking and it is not alone. Through its Open Compute project, Facebook is sharing open designs of data center products and, while we have yet to see commercial off-the-shelf (COTS) 24 and 48-port gigabit switches trickle down to the consumer market, the company is definitely deploying new hardware based on those specifications in its own data centers, and those devices are often based on Linux.

The Linux switch implementation So how exactly do switches work in Linux? The Linux kernel manipulates switches with three different operation structures: switchdev_ops, which we previously covered, ethtool_ops, and netdev_ops. Certain switches, however, also need distributed switch architecture (DSA) features to be properly handled. DSA is a more obscure part of the network stack that allows Linux to represent hardware switches or chains of switches using regular Linux tools like bridge, ifconfig, and so on. While switchdev is a new layer, DSA has been in the kernel since 2.6.28 in 2008. Originally developed to support Marvell switches, DSA is now a generic layer deployed in WiFi access points, set-top boxes, on-board flight entertainment systems, trains, and other industrial equipment. Switches that have an Ethernet controller need DSA, whereas the kernel can support switches without Ethernet controllers directly with switchdev drivers. The first years of DSA's development consisted only of basic maintenance but, in the last three years, DSA has seen a resurgence of contributions, as part of Linux networking push to support hardware offloading and network switches. Between 2014 and 2015, DSA added support for Broadcom hardware, wake on LAN, and hardware port bridging, among other features. DSA's development was parallel to swconfig, written by the OpenWrt project to support the small office and home office (SOHO) routers that the project is targeting. The main difference between swconfig and DSA is that DSA-supported switches show one network interface per port, whereas swconfig-configured switches show up as a single port, which limits the amount of information that can be extracted from the switch. For example, you cannot have per-port traffic statistics with swconfig. That limitation is what led to the creation of the switchdev framework, when swconfig was proposed (then refused) for inclusion in mainline. Another goal of switchdev was to support bridge hardware offloading and network interface card (NIC) virtualization. Also, whereas swconfig uses virtual LAN (VLAN) tagging to address ports, DSA enables the use of device-specific tagging headers to address different ports, which enables DSA to have better control over the switches. This allows, for example, DSA to do internet group management protocol (IGMP) snooping or implement the spanning tree protocol, whereas swconfig doesn't have those features. Some switches are actually connected to the host CPU through an Ethernet interface instead of regular PCI-Express interface, and DSA supports this as well. One advantage that remains in the swconfig approach is that it treats the internal switch as a simple external switch, and addresses ports with standard VLAN tags. This is something DSA could do, as well, but no one has bothered implementing this just yet. For now, DSA drivers use device-specific tagging mechanisms that limit the number of supported devices. Other areas of future improvement for DSA are better multi-chip support, IGMP snooping, and bonding, as well as firewall, NAT, and TC offloading.

Where is the freedom? Given all those technical improvements, you might rightfully wonder if your own wireless router or data center switch runs Linux. In recent years, we have seen more and more networking devices shipped with Linux and sometimes even OpenWrt (e.g. in the case of the Turris Omnia, which we previously covered), and especially on SOHO routers, but it sometimes means a crippled operating system that only offers you a proprietary web interface. But at least those efforts make it easier to deploy free operating systems on those devices. Based on my experience running OpenWrt on wireless routers to build the Montreal mesh network, deploying Linux on routers and switches has always been a manual process. The Ubiquiti hardware being used in the mesh network comes with an OpenWrt derivative, but it includes proprietary drivers and a proprietary web interface. To use the mesh networking protocol that was chosen, it was necessary to deploy custom OpenWrt images by hand. For years, it was a continuous struggle for OpenWrt developers to liberate generation after generation of proprietary hardware with companies like Cisco locking down the venerable WRT platform in 2006 and the US Federal Communications Commission (FCC) rules that forced TP-Link to block free software on its routers, a change that was later reverted. Most hardware providers are obviously not dedicated to software freedom: deploying Linux on their hardware is for them an economic, not political choice. As you might expect, a "Linux router" these days often means a closed device and operating system, using Linux as the only free component. I had the privilege of doing some reverse engineering on the SmartRG SR603n VDSL modem, which also doubles as a WiFi router and VoIP phone adapter. I was able to get a shell on that machine, and what I found was a custom operating system built on top of the Linux kernel. I wrote a detailed report about this two years ago and the situation then was pretty grim. Another experience I had was working over a decade in data centers, which tells an even worse story: most switches and routers there are not running free software at all. We have deployed HP ProCurve switches that provide free (as in beer) software updates and have struggled for years to find free (as in speech) software alternatives for those. We built our own routers using COTS server hardware, at a significant performance cost over the dedicated application-specific integrated circuits (ASICs) built into commercial routers, which do not offer us the trust and flexibility we were looking for. But Linux is definitely making some headway, and has been for a while. When we covered switchdev in February 2016, it was just getting started, but now vendors like Mellanox, Broadcom, Cumulus, and Intel are writing and shipping code using the framework. Cumulus, in particular, is developing a Debian-based distribution (Cumulus Linux) that it deploys for clients on targeted hardware. Most of the hardware in that list, however, is not actually open in the more radical sense: they are devices that can run free software but are not generally open-source hardware. There are some exceptions, but they sit at the higher end of the spectrum: most organizations probably don't need a 100 Gbps ports, let alone the 128 ports in the Backpack switch that Cumulus is shipping. How much this translates to actual freedom for the end-user is therefore questionable. While I have seen encouraging progress on the high end of the hardware spectrum at Netdev, I'm not sure this will translate into immediate wins in the data center or even for home users in the short term. In the long term, however, we will hopefully see some progress in Linux's rise in general-purpose networking hardware following its dominance in general-purpose computing.
The author would like to thank the Netdev organizers for travel assistance. Also, thanks to Andrew Lunn for a technical review of this article. Note: this article first appeared in the Linux Weekly News.

17 April 2017

Sylvain Beucler: Practical basics of reproducible builds 3

On my quest to generate reproducible standalone binaries for GNU FreeDink, I met new friends but currently lie defeated by an unexpected enemy... Episode 1: Episode 2:
First, the random build differences when using -Wl,--no-insert-timestamp were explained.
peanalysis shows random build dates:
$ reprotest 'i686-w64-mingw32.static-gcc hello.c -I /opt/mxe/usr/i686-w64-mingw32.static/include -I/opt/mxe/usr/i686-w64-mingw32.static/include/SDL2 -L/opt/mxe/usr/i686-w64-mingw32.static/lib -lmingw32 -Dmain=SDL_main -lSDL2main -lSDL2 -lSDL2main -Wl,--no-insert-timestamp -luser32 -lgdi32 -lwinmm -limm32 -lole32 -loleaut32 -lshell32 -lversion -o hello && chmod 700 hello && analysePE.py hello   tee /tmp/hello.log-$(date +%s); sleep 1' 'hello'
$ diff -au /tmp/hello.log-1*
--- /tmp/hello.log-1490950327   2017-03-31 10:52:07.788616930 +0200
+++ /tmp/hello.log-1523203509   2017-03-31 10:52:09.064633539 +0200
@@ -18,7 +18,7 @@
 found PE header (size: 20)
     machine: i386
     number of sections: 17
-    timedatestamp: -1198218512 (Tue Jan 12 05:31:28 1932)
+    timedatestamp: 632430928 (Tue Jan 16 09:15:28 1990)
     pointer to symbol table: 4593152 (0x461600)
     number of symbols: 11581 (0x2d3d)
     size of optional header: 224
@@ -47,7 +47,7 @@
     Win32VersionValue: 0
     size of image (memory): 4640768
     size of headers (offset to first section raw data): 1536
-    checksum (for drivers): 4927867
+    checksum (for drivers): 4922616
     subsystem: 3
         win32 console binary
     DllCharacteristics: 0
Stephen Kitt mentioned 2 simple patches (1 2) fixing uninitialized memory in binutils. These patches fix the variation and were submitted to MXE (pull request).
Next was playing with compiler support for SOURCE_DATE_EPOCH (which e.g. sets __DATE__ macros).
The FreeDink DFArc frontend historically displays a build date in the About box:
    "Build Date: %s\n", ..., __TDATE__
sadly support is only landing upstream in GCC 7 :/
I had to remove that date.
Now comes the challenging parts. All my tests with reprotest checked. I started writing a reproducible build environment based on Docker (git browse).
At first I could not run reprotest in the container, so I reworked it with SSH support, and reprotest validated determinism.
(I also generate a reproducible .zip archive, more on that later.) So far so good, but were the release identical when running reprotest successively on the different environments?
(reminder: this is a .exe build that is insensitive to varying path, hence consistent in a full reprotest)
$ sha256sum *.zip
189d0ca5240374896c6ecc6dfcca00905ae60797ab48abce2162fa36568e7cf1  freedink-109.0-bin-buildsh.zip
e182406b4f4d7c3a4d239eee126134ba5c0304bbaa4af3de15fd4f8bda5634a9  freedink-109.0-bin-docker.zip
e182406b4f4d7c3a4d239eee126134ba5c0304bbaa4af3de15fd4f8bda5634a9  freedink-109.0-bin-reprotest-docker.zip
37007f6ee043d9479d8c48ea0a861ae1d79fb234cd05920a25bb3db704828ece  freedink-109.0-bin-reprotest-null.zip
Ouch! Even though both the Docker and my host are running Stretch, there are differences.
For the two host builds (direct and reprotest), there is a subtle but simple difference: HOME.
HOME is invariably non-existant in reprotest, while my normal compilation environment has an existing home (duh!). This caused a subtle bug when cross-compiling with mingw and wine-binfmt:
  checking whether we are cross compiling... no
  checking whether we are cross compiling... yes
The respective binaries were very different notably due to a different config.h.
This can be fixed by specifying --build in addition to --host when calling ./configure. I suggested reprotest have one of the tests with a valid HOME (#860428).
Now comes the big one, after the fix I still got:
$ sha256sum *.zip
3545270ef6eaa997640cb62d66dc610a328ce0e7d412f24c8f18fdc7445907fd  freedink-109.0-bin-buildsh.zip
cc50ec1a38598d143650bdff66904438f0f5c1d3e2bea0219b749be2dcd2c3eb  freedink-109.0-bin-docker.zip
3545270ef6eaa997640cb62d66dc610a328ce0e7d412f24c8f18fdc7445907fd  freedink-109.0-bin-reprotest-chroot.zip
cc50ec1a38598d143650bdff66904438f0f5c1d3e2bea0219b749be2dcd2c3eb  freedink-109.0-bin-reprotest-docker.zip
3545270ef6eaa997640cb62d66dc610a328ce0e7d412f24c8f18fdc7445907fd  freedink-109.0-bin-reprotest-null.zip
There is consistency on my host, and consistency within docker, but both are different.
Moreover, all the .o files were identical, so something must have gone wrong when compiling the libs, that is MXE. After many checks it appears that libstdc++.a is different.
Just overwriting it gets me a consistent FreeDink release on all environments.
Still, when rebuilding it (make gcc), libstdc++.a always has the same environment-dependent checksum.
45f8c5d50a68aa9919ee3602a4e3f5b2bd0333bc8d781d7852b2b6121c8ba27b  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a  # host
6870b84f8e17aec4b5cf23cfe9c2e87e40d9cf59772a92707152361b6ebc1eb4  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a  # docker
The 2 libraries are much different, there's barely any blue in hexcompare. At that time, I realized that the Docker "official" Debian are not really official, as Joey explains.
Could it be that Docker maliciously tampered with the compiler as Ken Thompson warned in 1984?? Well before jumping to conclusion let's mix & match.
$ sudo env -i /usr/sbin/chroot chroot-docker/
$ exec bash -l
$ cd /opt/mxe
$ touch src/gcc.mk
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a 
6870b84f8e17aec4b5cf23cfe9c2e87e40d9cf59772a92707152361b6ebc1eb4  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
$ make gcc
[build]     gcc                    i686-w64-mingw32.static
[done]      gcc                    i686-w64-mingw32.static                                 2709464 KiB    7m2.039s
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a 
45f8c5d50a68aa9919ee3602a4e3f5b2bd0333bc8d781d7852b2b6121c8ba27b  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
# consistent with host builds
$ sudo tar -C chroot -c .   docker import - chroot-debootstrap
$ docker run -ti chroot-debootstrap /bin/bash
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
45f8c5d50a68aa9919ee3602a4e3f5b2bd0333bc8d781d7852b2b6121c8ba27b  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
$ touch src/gcc.mk
$ make gcc
[build]     gcc                    i686-w64-mingw32.static
[done]      gcc                    i686-w64-mingw32.static                                 2709412 KiB    7m6.608s
$ sha256sum /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
6870b84f8e17aec4b5cf23cfe9c2e87e40d9cf59772a92707152361b6ebc1eb4  /opt/mxe/usr/lib/gcc/i686-w64-mingw32.static/5.4.0/libstdc++.a
# consistent with docker builds
So, AFAICS when building with: then depending on whether running in a container or not we get a consistent but different libstdc++.a. This kind of issue is not detected with a simple reprotest build, as it only tests variations within a fixed build environment.
This is quite worrisome, I intend to use a container to control my build environment, but I can't guarantee that the container technology will be exactly the same 5 years from now. All my setup is simple and available for inspection at https://git.savannah.gnu.org/cgit/freedink.git/tree/autobuild/freedink-w32-snapshot/. I'd very much welcome enlightenment :)

16 April 2017

Antoine Beaupr : Montreal Bug Squashing Party report

Un sommaire de cet article est galement traduit vers le fran ais, merci!
Last friday, a group of Debian users, developers and enthusiasts met at Koumbit.org offices for a bug squashing party. We were about a dozen people of various levels: developers, hackers and users. I gave a quick overview of Debian packaging using my quick development guide, which proved to be pretty useful. I made a deb.li link (https://deb.li/quickdev) for people to be able to easily find the guide on their computers. Then I started going through a list of different programs used to do Debian packaging, to try and see the level of the people attending: So mostly skilled Debian users (they know apt-get source) but not used to packaging (they don't know about dpkg-buildpackage). So I went through the list again and explained how they all fit together and could be used to work on Debian packages in the context of a Debian release bug squashing party. This was the fastest crash course in Debian packaging I have ever given (and probably the first too) - going through those tools in about 30 minutes. I was happy to have the guide that people could refer to later in the back. The first question after the presentation was "how do we find bugs"? which led me to add links to the UDD bugs page and release-critical bugs page. I also explained the key links on top of the UDD page to find specific sets of bugs, and explained the useful "patch" filter that allows to select bugs with our without patch. I guess that maybe half of the people were able to learn new, or improve their skills to make significant contributions or test actual patches. Other learned how to hunt and triage bugs in the BTS. Update: sorry for the wording: all contributions were really useful, thanks and apologies to bug hunters!! I myself learned how to use sbuild thanks to the excellent sbuild wiki page which I improved upon. A friend was able to pick up sbuild very quickly and use it to build a package for stretch, which I find encouraging: my first experience with pbuilder was definitely not as good. I have therefore starting the process of switching my build chroots to sbuild, which didn't go so well on Jessie because I use a backported kernel, and had to use the backported sbuild as well. That required a lot of poking around, so I ended up just using pbuilder for now, but I will definitely switch on my home machine, and I updated the sbuild wiki page to give out more explanations on how to setup pbuilder. We worked on a bunch of bugs, and learned how to tag them as part of the BSP, which was documented in the BSP wiki page. It seems we have worked on about 11 different bugs which is a better average than the last BSP that I organized, so I'm pretty happy with that. More importantly, we got Debian people together to meet and talk, over delicious pizza, thanks to a sponsorship granted by the DPL. Some people got involved in the next DebConf which is also great. On top of fixing bugs and getting people involved in Debian, my third goal was to have fun, and fun we certainly had. I didn't work on as many bugs as I expected myself, achieving only one upload in the end, but since I was answering so many questions left and right, I felt useful and that is certainly gratifying. Organization was simple enough: just get a place, send invites and get food, and the rest is just sharing knowledge and answering questions. Thanks everyone for coming, and let's do this again soon!

Shirish Agarwal: single person cult-based political parties

Summer heat

Summer heat

I would like to start with sharing is the mercury has been shot in recent times to record temperatures. For instance, Pune has been recording temperatures between 41 and 43 degrees consistently. The result of that has been a massive reduction in volunteer activity on my part as well as some reduction in work activity. The body wants and needs to conserve energy. Even my mobile phone s lithium-ion battery becomes too hot and I have to turn it off in the crucial time from 12 17:00 hrs after which the weather cools down a bit. I am curious to know if I m the only one or there are others like me. I have seen quite a few construction, re-construction and renovation projects taking quite a hit by this incredible heat wave. If it isn t climate change then I don t know what is. And this is not limited to Pune but the whole of Western Maharashtra, Gujarat, Madhya Pradesh and quite a few parts of North India too. In Pune we are expecting it to hit 45 degrees pretty soon. And I don t see this ending anytime soon, at least till July when the rains comes and we have some relief from this weather. Balasaheb Thackeray, Founder Shiv Sena Balasaheb Thakre/Thackeray founded the Shiv Sena in/around 1966. While he was cartoonist by trade, most of his cartoons were anti-migrant in nature. The target was the urban, unemployed Marathi youth based mostly in Mumbai and the suburbs. The Shiv Sena vandalized properties run by South Indian businessman, Gujaratis. The Shiv Sena and Balasaheb Thackeray were also responsible in part due to the massive closure of cloth mills in South Mumbai. While the workers struggled to make ends meet, some whose wife and children died, fell into prostitution, drugs or whatever they could to make ends meet while the party and more important Mr. Balasahab Thackeray prospered. In spite of the many threats, there are and were many South Indians who prospered inspite of Shiv Sena s threats. Gujaratis on the other hand went back to Gujarat and now Surat rivals Mumbai. Another decade or so and Surat and not Mumbai would be the financial capital of India, the way Gujaratis are working towards it. Then in the 90 s people from U.P. and Bihar came in search of livelihood, again the same rhetoric and even attacks were done against people from U.P. and Bihar. The only thing that was missing for all these people is a domicile certificate which you can get only after living 15 years in Mumbai. The only thing that they and other political parties have been successful is murdering journalists. I m sad to report that Maharashtra, my home state has a very bad report card in preventing such murders. And it s both the State and the Centre who have to share the blame equally. Come to 2017 and Shiv Sena doesn t have a leg to stand on. Balasaheb Thackeray is no more, his son didn t inherit Balasaheb s fiery character and the nephew has now another outfit called Maha Navnirman Sena. Also, all those who were one-time outsiders are now residents of Mumbai (with the domicile certificate) and hence registered voters. There is another angle to it as well, Marathas for far too long thought that people they will elect from their community will do something from their community just like auto rickshaw drivers thought that educated unemployed youth from their community would be better than the agents who rip them off whenever they have some work in the local R.T.O. (Road Transport Office) . Similar to auto rickshaw drivers, the Marathas realized that none of the leaders whom they elected would ever do the work. This is why when last year there were huge Maratha rallies all over the state (peaceful demonstrations all around though). I just shared Pune as am most concerned with my city although similar rallies were held in Mumbai (Khargar), Nagpur, Solapur among other places that I know of. But as shown on youtube there was no central leadership (a.k.a. leaders) and still they were the most disciplined lot. While the Marathas may say one thing, in part they are also culprits of their own past. My interactions with few Marathas was that they are still smitten by what happened in the second and the third Anglo-Maratha War . It is sad because I do see them adding lot of value provided they keep a cool head as I have seen some do. Business or service is the game only for cooler heads. Things came to a head though about couple of weeks back when Mr. Ravindra Gaikwad, a Shiv Sena M.P. assaulted some elderly Air India Staff. While things have cooled down since then, it only belittles both the person and the party. If anything, Air India can be accused of being to gentleman like in the whole case. The only crime of its own making is it has been looted since the beginning by Indian MP s and their relatives with over-staffing and old age of the planes and being over-priced in an extremely price sensitive market. It doesn t have any low-cost options but all of that is another story altogether. Converse to this, the current Prime Minister, Mr. Narendra Modi and Malcolm Turnbull enjoyed the ride of the Delhi Metro. In Politics as well as in life, symbolism scores big. That showed where Mr. Modi s priorities lie and where Mr. Gaikwad s. In the end, the writing seems to be on the wall for not just the Shiv Sena but I would say all single-personality based parties. They need to widen both their political scope and activities and have prominent personalities with strong leadership taking the country along rather than being petty-minded.
Filed under: Miscellenous Tagged: #17th century, #Air India, #anti-migrant policy, #Indian Summer, #Maratha, #Maratha History, #Me Maratha, #Me Maratha rallies, #planet-debian

15 April 2017

Gunnar Wolf: On Dmitry Bogatov and empowering privacy-protecting tools

There is a thorny topic we have been discussing in nonpublic channels (say, the debian-private mailing list... It is impossible to call it a private list if it has close to a thousand subscribers, but it sometimes deals with sensitive material) for the last week. We have finally confirmation that we can bring this topic out to the open, and I expect several Debian people to talk about this. Besides, this information is now repeated all over the public Internet, so I'm not revealing anything sensitive. Oh, and there is a statement regarding Dmitry Bogatov published by the Tor project But I'll get to Tor soon. One week ago, the 25-year old mathematician and Debian Maintainer Dmitry Bogatov was arrested, accused of organizing riots and calling for terrorist activities. Every evidence so far points to the fact that Dmitry is not guilty of what he is charged of He was filmed at different places at the times where the calls for terrorism happened. It seems that Dmitry was arrested because he runs a Tor exit node. I don't know the current situation in Russia, nor his political leanings But I do know what a Tor exit node looks like. I even had one at home for a short while. What is Tor? It is a network overlay, meant for people to hide where they come from or who they are. Why? There are many reasons Uninformed people will talk about the evil wrongdoers (starting the list of course with the drug sellers or child porn distributors). People who have taken their time to understand what this is about will rather talk about people for whom free speech is not a given; journalists, political activists, whistleblowers. And also, about regular people Many among us have taken the habit of doing some of our Web surfing using Tor (probably via the very fine and interesting TAILS distribution The Amnesiac Incognito Live System), just to increase the entropy, and just because we can, because we want to preserve the freedom to be anonymous before it's taken away from us. There are many types of nodes in Tor; most of them are just regular users or bridges that forward traffic, helping Tor's anonymization. Exit nodes, where packets leave the Tor network and enter the regular Internet, are much scarcer Partly because they can be quite problematic to people hosting them. But, yes, Tor needs more exit nodes, not just for bandwidth sake, but because the more exit nodes there are, the harder it is for a hostile third party to monitor a sizable number of them for activity (and break the anonymization). I am coincidentially starting a project with a group of students of my Faculty (we want to breathe life again into LIDSOL - Laboratorio de Investigaci n y Desarrollo de Software Libre). As we are just starting, they are documenting some technical and social aspects of the need for privacy and how Tor works; I expect them to publish their findings in El Nigromante soon (which means... what? ), but definitively, part of what we want to do is to set up a Tor exit node at the university Well documented and with enough academic justification to avoid our network operation area ordering us to shut it down. Lets see what happens :) Anyway, all in all Dmitry is in for a heavy time. He has been detained pre-trial at least until June, and he faces quite serious charges. He has done a lot of good, specialized work for the whole world to benefit. So, given I cannot do more, I'm just speaking my mind here in this space. [Update] Dmitry's case has been covered in LWN. There is also a statement concerning the arrest of Dmitry Bogatov by the Debian project. This case is also covered at The Register.
14 April 2017

Laura Arjona Reina: Underestimating Debian

I had two issues in the last days that lead me a bit into panic until they got solved. In both cases the issue was external to Debian but I first thought that the problem was in Debian. I m not sure why I had those thoughts, I should be more confident in myself, this awesome operating system, and the community around it! The good thing is that I ll be more confident from now on, and I ve learned that hurry is not a good friend, and I should face my computer problems (and everything in life, probably) with a bit more patience (and backups). Issue 1: Corrupt ext partition in a laptop I have a laptop at home with dual boot Windows 7 + Debian 9 (Stretch). I rarely boot the Windows partition. When I do, I do whatever I need to do/test there, then install updates, and then shutdown the laptop or reboot in Debian to feel happy again when using computers. Some months ago I noticed that booting in Debian was not possible and I was left in an initramfs console that was suggesting to e2fsck /dev/sda6 (my Debian partition). Then I ran e2fsck, say a to fix all the issues found, and the system was booting properly. This issue was a bit scary-looking because of the e2fsck output making screen show random numbers and scrolling quickly for 1 or 2 minutes, until all the inodes or blocks or whatever were fixed. I thought about the disk being faulty, and ran badblocks, but faced the former boot issue again some time after, and then decided to change the disk (then I took the opportunity to make backups, and install a fresh Debian 9 Stretch in the laptop, instead of the Debian 8 stable that was running). The experience with Stretch has been great since then, but some days ago I faced the boot issue again. Then I realised that maybe the issue was appearing when I booted Debian right after using Windows (and this was why it was appearing not very often in my timeline  ). Then I payed more attention to the message that I was receiving in the console
Superblock checksum does not match superblock while trying to open /dev/sda6
 /dev/sda6:
 The superblock could not be read or does not describe a valid ext2/ext3/ext4
 filesystem. If the device is valid and it really contains an ext2/ext3/ext4
 filesystem (and not swap or ufs or something else), then the superblock
 is corrupt, and you might try running e2fsck with an alternate superblock:
 e2fsck -b 8193
 or
 e2fsck -b 32768
and searched about it, and also asked about it to my friends in the redeslibres XMPP chat room  I found this question in the AskUbuntu forum that was exactly my issue (I had ext2fsd installed in Windows). My friends in the XMPP room friendly yelled booo! at me for letting Windows touch my ext partitions (I apologised, it will never happen again!). I now consistently could reproduce the issue (boot Windows, then boot Debian, bang!: initramfs console, e2fsck, reboot Debian, no problem, boot Windows, boot Debian, again the problem, etc). I uninstalled the ext2fsd program and tried to reproduce the issue, and I couldn t reproduce it. So happy end. Issue 2: Accessing Android internal memory to backup files The other issue was with my tablet running Android 4.0.4. It was facing a charge issue, and I wanted to backup the files there before sending it to repair. I connected the tablet with USB to my laptop, and enabled USB debugging. The laptop recognized a MZ604 camera connected, but Dolphin (the file browser of my KDE Plasma desktop) could not show the files. I looked at the settings in the tablet to try to find the setting that allowed me to switch between camera/MTP when connecting with USB, but couldn t find it. I guessed that the tablet was correctly configured because I recall having made a backup some months ago, with no hassle (in Debian 8). I checked that my Debian (9) had installed the needed packages:
 ii kio-mtp 0.75+git20140304-2 amd64 access to MTP devices for applications using the KDE Platform
 ii libmtp-common 1.1.12-1 all Media Transfer Protocol (MTP) common files
 ii libmtp-runtime 1.1.12-1+b1 amd64 Media Transfer Protocol (MTP) runtime tools
 ii libmtp9:amd64 1.1.12-1+b1 amd64 Media Transfer Protocol (MTP) library
So I had no idea about what was going on. Then I suspected some problem in my Debian (maybe I was needing some driver for the Motorola tablet?) and booted Windows 7 to see what happened there. Windows detected a MZ604 device too, but couldn t access the files either (when clicking in the device, no folders were shown). I began to search the internet to see if there were some Motorola drivers out there, and then found the clue to enable the correct settings in the Android device: you need to go to Settings > Storage, and then press the 3-dots button that makes the Menu function, and then appears USB computer connection and there, you can enable Camera or MTP. Very hidden setting! I enabled MTP, and then I could see the folders and files in my Windows system (without need of installing any additional driver), and make my backup. And of course after rebooting and trying in Debian, it worked too. Some outcomes/conclusions Comments? You can comment on this post using this pump.io thread.
Filed under: My experiences and opinion Tagged: Android, Debian, English, KDE, Libre software for Windows

11 April 2017

Antoine Beaupr : A report from Netconf: Day 1

As is becoming traditional, two times a year the kernel networking community meets in a two-stage conference: an invite-only, informal, two-day plenary session called Netconf, held in Toronto this year, and a more conventional one-track conference open to the public called Netdev. I was invited to cover both conferences this year, given that Netdev was in Montreal (my hometown), and was happy to meet the crew of developers that maintain the network stack of the Linux kernel. This article covers the first day of the conference which consisted of around 25 Linux developers meeting under the direction of David Miller, the kernel's networking subsystem maintainer. Netconf has no formal sessions; although some people presented slides, interruptions are frequent (indeed, encouraged) and the focus is on hashing out issues that are blocked on the mailing list and getting suggestions, ideas, solutions, and feedback from their peers.

Removing ndo_select_queue() One of the first discussions that elicited a significant debate was the ndo_select_queue() function, a key component of the Linux polling system that determines when and how to send packets on a network interface (see netdev_pick_tx and friends). The general question was whether the use of ndo_select_queue() in drivers is a good idea. Alexander Duyck explained that Intel people were considering using ndo_select_queue() for receive/transmit queue matching. Intel drivers do not currently use the hook provided by the Linux kernel and it turns out no one is happy with ndo_select_queue(): the heuristics it uses don't really please anyone. The consensus (including from Duyck himself) seemed to be that it should just not be used anymore, or at least not used for that specific purpose. The discussion turned toward the wireless network stack, which uses it extensively, but for other purposes. Johannes Berg explained that the wireless stack uses ndo_select_queue() for traffic classification, for example to get voice traffic through even if the best-effort queue is backed up. The wireless stack could stop using it by doing flow control completely inside the wireless stack, which already uses the fq_codel flow-control mechanism for other purposes, so porting away from ndo_select_queue() seems possible there. The problem then becomes how to update all the drivers to change that behavior, which would be a lot of work. Still, it seems people are moving away from a generic ndo_select_queue() interface to stack-specific or even driver-specific (in the case of Intel) queue management interfaces.

refcount_t followup There was a followup discussion on the integration of the refcount_t type into the network stack, which we covered recently. This type is meant to be an in-kernel defense against exploits based on overflowing or underflowing an object's reference count. The consensus seems to be that having refcount_t used for debugging is acceptable, but it cannot be enabled by default. An issue that was identified is that the networking developers are fairly sure that introducing refcount_t would have a severe impact on performance, but they do not have benchmarks to prove it, something Miller identified as a problem that needs to be worked on. Miller then expressed some openness to the idea of having it as a kernel configuration option. A similar discussion happened, on the second day, regarding the KASan memory error detector which was covered when it was introduced in 2014. Eric Dumazet warned that there could be a lot of issues that cannot be detected by KASan because of the way the network stack often bypasses regular memory-allocation routines for performance reasons. He also noted that this can sometimes mean the stack may go over the regular 10% memory limit (the tcp_mem parameter, described in the tcp(7) man page) for certain operations, especially when rebuilding out of order packets with lots of parallel TCP connections. Therefore it was proposed that these special memory recycling tricks could be optionally disabled, at run or compile-time, to instrument proper memory tracking. Dumazet argued this was a situation similar to refcount_t in that we need a way to disable high performance to make the network stack easier to debug with KAsan. The problem with optional parameters is that they are often disabled in production or even by default, which, in turn, means that critical bugs cannot actually be found because the code paths are not tested. When I asked Dumazet about this, he explained that Google performs integration testing of new kernels before putting them in production, and those toggles could be enabled there to find and fix those bugs. But he agreed that certain code paths are then not tested until the code gets deployed in production. So it seems the status quo remains: security folks wants to improve the reliability of the kernel, but the network folks can't afford the performance cost. Yet it was clear in the discussions that the team cares about security issues and wants those issues to be fixed; the impact of some of the solutions is just too big.

Lightweight wireless management packet access Berg explained that some users need to have high-performance access to certain management frames in the wireless stack and wondered how to best expose those to user space. The wireless stack already allows users to clone a network interface in "monitor" mode, but this has a big performance cost, as the radiotap header needs to be constructed from scratch and the packet header needs to be copied. As wireless improves and the bandwidth rises to gigabit levels, this can become significant bottleneck for packet sniffers or reporting software that need to know precisely what's going on over the air outside of the regular access point client operation. It seems the proper way to do this is with an eBPF program. As Miller summarized, just add another API call that allows loading a BPF program into the kernel and then those users can use a BPF filtering point to get the statistics they need. This will require an extra hook in the wireless stack, but it seems like this is the way that will be taken to implement this feature.

VLAN 0 inconsistencies Hannes Frederic Sowa brought up the seemingly innocuous question of "how do we handle VLAN 0?" In theory, VLAN 0 means "no VLAN". But the Linux kernel currently handles this differently depending on whether the VLAN module is loaded and whether a VLAN 0 interface was created. Sometimes the VLAN tag is stripped, sometimes not. It turns out the semantics of this were accidentally changed last time there was a change here and this was originally working but is now broken. Sowa therefore got the go-ahead to fix this to make the behavior consistent again.

Loopy fun Then it came the turn of Jamal Hadi Salim, the maintainer of the kernel's traffic-control (tc) subsystem. The first issue he brought up is a problem in the tc REDIRECT action that can create infinite loops within the kernel. The problem can be easily alleviated when loops are created on the same interface: checks can be added that just drop packets coming from the same device and rate-limit logging to avoid a denial-of-service (DoS) condition. The more serious problem occurs when a packet is forwarded from (say) interface eth0 to eth1 which then promptly redirects it from eth1 back to eth0. Obviously, this kind of problem can only be created by a user with root access so, at first glance, those issues don't seem that serious: admins can shoot themselves in the foot, so what? But things become a little more serious when you consider the container case, where an untrusted user has root access inside a container and should have constrained resource limitations. Such a loop could allow this user to deploy an effective DoS attack against a whole group of containers running on the same machine. Even worse, this endless loop could possibly turn into a deadlock in certain scenarios, as the kernel could try to transmit the packet on the same device it originated from and block, progressively filling the queues and eventually completely breaking network access. Florian Westphal argued that a container can already create DoS conditions, for example by doing a ping flood. According to Salim, this whole problem was created when two bits used for tracking such packets were reclaimed from the skb structure used to represent packets in the kernel. Those bits were a simple TTL (time to live) field that was incremented on each loop and dropped after a pre-determined limit was reached, breaking infinite loops. Salim asked everyone if this should be fixed or if we should just forget about this issue and move on. Miller proposed to keep a one-behind state for the packet, fixing the simplest case (two interfaces). The general case, however, would requite a bitmap of all the interfaces to be scanned, which would impose a large overhead. Miller said an attempt to fix this should somehow be made. The root of the problem is that the network maintainers are trying to reduce the size of the skb structure, because it's used in many critical paths of the network stack. Salim's position is that, without the TTL fields, there is no way to fix the general case here, and this constitutes a security issue. So either the bits need to be brought back, or we need to live with the inherent DoS threat.

Dumping large statistics sets Another issue Salim brought up was the question of how to export large statistics sets from the kernel. It turns out that some use cases may end up dumping a lot of data. Salim mentioned a real-world tc use case that calls for reading six-million entries. The current netlink-based API provides a way to get only 20 entries at a time, which means it takes forever to dump the state of all those policy actions. Salim has a patch that changes the dump size be eight times the NLMSG_GOOD_SIZE, which improves performance by an order of magnitude already, although there are issues with checking the user-space buffer size there. But a more complete solution is needed. What Salim proposed was a way to ask only for the states that changed since the last dump was requested. He has a patch to add a last_access field to the netlink_callback structure used by netlink_dump() to output data; that raised the question of how to actually use that field. Since Salim fetches that data every five seconds, he figured he could just tell the kernel to return all the nodes that changed in that period. But then if the dump takes more than five seconds to complete, the next dump may be missing states that changed during the extra delay. An alternative mechanism would be for the user-space utility to keep the time stamp it requested and use that as a delta for the next dump. It turns out this is a larger problem than just tc. Dumazet mentioned this was an issue with fq_codel classes: he would even like to be able to dump those statistics faster than every five seconds. Roopa Prabhu mentioned that Cumulus also has similar problems dumping stats from bridges, so clearly a more generic solution is needed here. There is, however, a fundamental problem with dumping large statistics sets from the kernel: those statistics are constantly changing while the dump is created and unless versioning or locking mechanisms are used which would slow things down the data returned is bound to be only an approximation of reality. Salim promised to send a set of RFC patches to further discussions regarding this issue, but during the following Netdev conference, Berg published a patch to fix this ten-year-old issue, which brought cheers from the audience.
The author would like to thank the Netconf and Netdev organizers for travel to, and hosting assistance in, Toronto. Many thanks to Berg, Dumazet, Salim, and Sowa for their time taken for a technical review of this article. Note: this article first appeared in the Linux Weekly News.

Antoine Beaupr : A report from Netconf: Day 2

This article covers the second day of the informal Netconf discussions, held on on April 4, 2017. Topics discussed this day included the binding of sockets in VRF, identification of eBPF programs, inconsistencies between IPv4 and IPv6, changes to data-center hardware, and more. (See this article for coverage from the first day of discussions).

How to bind to specific sockets in VRF One of the first presentations was from David Ahern of Cumulus, who presented a few interesting questions for the audience. His first was the problem of binding sockets to a given interface. Right now, there are four different ways this can be done:
  • the old SO_BINDTODEVICE generic socket option (see socket(7))
  • the IP_PKTINFO, IP-specific socket option (see ip(7)), introduced in Linux 2.2
  • the IP_UNICAST_IF flag, introduced in Linux 3.3 for WINE
  • the IPv6 scope ID suffix, part of the IPv6 addressing standard
So there's a problem of having too many ways of doing the same thing, something that cannot really be fixed without breaking ABI compatibility. But even worse, conflicts between those options are not reported by the kernel so it's possible for a user to set up socket flags in a way that certain flags override others and there are no checks made or errors reported. It was agreed that the user should get some notification of conflicting changes here, at least. Furthermore, binding sockets to a specific VRF (Virtual Routing and Forwarding) device is not currently possible, so Ahern asked what the best way to do this would be, considering the many options available. A use case example is a UDP multicast socket that could be bound to a specific interface within a VRF. This is an old problem: Tom Herbert explained that there were previous discussions about making the bind() system call more programmable so that, for example, you could bind() a UDP socket to a discrete list of IP addresses or a subnet. So he identified this issue as a broader problem that should be addressed by making the interfaces more generic. Ahern explained that it is currently possible to bind sockets to the slave device of a VRF even though that should not be allowed. He also raised the question of how the kernel should tell which socket should be selected for incoming packets. Right now, there is a scoring mechanism for UDP sockets, but that cannot be used directly in this more general case. David Miller said that there are already different ways of specifying scope: there is the VRF layer and the namespace ("netns") layer. A long time ago, Miller reluctantly accepted the addition of netns keys everywhere, swallowing the performance cost to gain flexibility. He argued that a new key should not be added and instead existing infrastructure should be reused. Herbert argued this was exactly the reason why this should be simplified: "if we don't answer the question, people will keep on trying this". For example, one can use a VRF to limit listening addresses, but it gets complicated if we need a device for every address. It seems the consensus evolved towards using, IP_UNICAST_IF, added back in 2012, which is accessible for non-root users. It is currently limited to UDP and RAW sockets, but it could be extended for TCP.

XDP and eBPF program identification Ahern then turned to the problem of extracting BPF programs from the kernel. He gave the example of a simple cBPF (classic BPF) filter that checks for ARP packets. If the filter is read back from the kernel, the user gets a blob of binary data, which is hard to interpret. There is an kernel verifier that can show C-like output, but that is also difficult to interpret. Ahern then added annotations to his slide that showed what the original program actually does, which was a good demonstration of why such a feature is needed. Ahern explained that, at least for cBPF, it should be possible to recover the original plaintext, or at least something close to the original program. A first step would be to replace known constants (like 0x806 for ARP). Even with eBPF, it should be possible to improve the output. Alexei Starovoitov, the BPF maintainer, explained that it might make sense to start by returning information about the maps used by an eBPF program. Then more complex data structures could be inspected once we know their type. The first priority is to get simple debugging tools working but, in the long term, the goal is a full decompiler that can reconstruct instructions into a human-readable program. The question that remains is how to return this data. Ahern explained that right now the bpf() system call copies the data to a different file descriptor, but it could just fill in a buffer. Starovoitov argued for a file descriptor; that would allow the kernel to stream everything through the same descriptor instead of having many attach points. Netlink cannot be used for this because of its asynchronous nature. A similar issue regarding the way we identify express data path (XDP) programs (which are also written in BPF) was raised by Daniel Borkmann from Covalent. Miller explained that users will want ways to figure out which XDP program was installed, so XDP needs an introspection mechanism. We currently have SHA-1 identifiers that can be internally used to tell which binary is currently loaded but those are not exposed to user space. Starovoitov mentioned it is now just a boolean that shows if a program is loaded or not. A use case for this, on top of just trying to figure out which BPF program is loaded, is to actually fetch the source code of a BPF program that was deployed in the field for which the source was lost. It is still uncertain that it will be possible to extract an exact copy that could then be recompiled into the same program. Starovoitov added that he needed this in production to do proper reporting.

IPv4/IPv6 equivalency The last issue or set of issues that Ahern brought up was the question of inconsistencies between IPv4 and IPv6. It turns out that, because both protocols were (naturally) implemented separately, there are inconsistencies in how they are handled in the Linux kernel, which affect, among other things, the VRF framework. The first example he gave was the fact that IPv6 addresses added on the loopback interface generate unreachable routes in the main routing table, yet this doesn't happen with IPv4 addresses. Hannes Frederic Sowa explained this was part of the IPv6 specification: there are stronger restrictions on loopback interfaces in IPv6 than IPv4. Ahern explained that VRF loopback interfaces do not implement these restrictions and wanted to know if this was a problem. Another issue is that anycast routes are added to the wrong interface. This is apparently not specific to VRF: this was done "just because Java", and has been there from day one. It seems that the Java Virtual Machine builds its own routing table and assumes this behavior, so changing this would break every JVM out there, which is obviously not acceptable. Finally, Martin Kafai Lau asked if work should be done to merge the IPv4 and IPv6 FIB (forwarding information base) trees. The FIB tree is the data structure that represents routing tables in the Linux kernel. Miller explained that the two trees are not semantically equivalent: while IPv6 does source-address lookup and routing, IPv4 does not. We can't remove the source lookups from IPv6, because "people probably use that". According to Alexander Duyck, adding source tables to IPv4 would degrade performance to the level of IPv6 performance, which was jokingly referred to as an incentive to switch to IPv6. More seriously, Sowa argued that using the same compressed tree IPv4 uses in IPv6 could make sense. People may want to have source routing in IPv4 as well. Miller argued that the kernel is optimized for 32-bit addresses in IPv4, and conceded that it could be scaled to 64-bit subnets, but 128-bit addresses would be much harder. Sowa suggested that they could be limited to 64 bits, as global routes that are announced over BGP usually have such a limit, and more specific routes are usually at discrete prefixes like /65, /127 (for interconnect links) or /128 for (for point-to-point links). He expressed concerns over the reliability of such an implementation so, at this point, it is unlikely that the data structures could be merged. What is more likely is that the code path could be merged and simplified, while keeping the data structures separate.

Modules options substitutions The next issue that was raised was from Ji P rko, who asked how to pass configuration options to a driver before the driver is initialized. Some chips require that some settings be sent before the firmware is loaded, which leads to a weird situation where there is a need to address a device before it's actually recognized by the kernel. The question then can be summarized as to how to pass information to a device that doesn't exist yet. The answer seems to be that devlink could do this, as it has access to the full device tree and, therefore, to devices that can be addressed by (say) PCI identifiers. Then a possible devlink command could look something like:
    devlink dev pci/0000:03:00.0 option set foo bar
This idea raised a bunch of extra questions: some devices don't have a one-to-one mapping with the PCI bridge identifiers, for example, meaning that those identifiers cannot be used to access such devices. Another issue is that you may want to send multiple settings in a single transaction, which doesn't fit well in the devlink model. Miller then proposed to let the driver initialize itself to some state and wait for configuration to be sent when necessary. Another way would be to unregister the driver and re-register with the given configuration. Shrijeet Mukherjee explained that right now, Cumulus is doing this using horrible startup script magic by retrying and re-registering, but it would be nice to have a more standard way to do this.

Control over UAPI patches Another issue that came up was the problem of changes in the user-space API (UAPI) which break backward compatibility. P rko said that "we have to be more careful about those changes". The problem is that reviewers are not always available to make detailed reviews of such changes and may not notice API-breaking changes. P rko proposed creating a bot to check if a given patch introduces UAPI changes, changes in structs, or in netlink enums. Miller said he could block merges until discussions happen and that patchwork, which Miller uses to process patches from the mailing list, does some of this. He also pointed out there aren't enough test cases in the first place. Starovoitov argued UAPI isn't special, there are other ways of breaking backward compatibility. He expressed concerns that such a bot could create a false sense that everything is fine while a patch could break compatibility and not be detected. Miller countered that UAPI is special in that "we're stuck with it forever". He then went on to propose that, since there's a maintainer (or more) for each module, he can make sure that each maintainer explicitly approves changes to those modules.

Data-center hardware changes Starovoitov brought up the issue of a new type of hardware that is currently being deployed in data centers called a "multi-host NIC" (network interface card). It's a single NIC that is connected to multiple servers. Facebook, for example, uses this in its Yosemite platform that shoves twelve servers into a 2U rack mount, in three modules. Each module is made of four servers connected to the traditional switch fabric with a single NIC through PCI-Express. Mellanox and and Broadcom also have similar devices. One question is how to manage those devices. Since they are connected through a PCI-Express bus, Linux will see them as a NIC, yet they are also a little like switches, in that they interconnect multiple servers. Furthermore, the kernel security model assumes that a NIC is trusted, and gladly opens its own memory to NICs through DMA; this can become a huge security issue when the NIC is under the control of another server. This can especially become problematic if we consider that there could be TLS hardware offloading in the future with the introduction of in-kernel TLS stacks. The other problem is the question of reliability: since those devices are currently "dumb", they need to be managed just like a regular NIC. If the host managing the card crashes, it could disable a whole set of servers that rely on the same NIC. There could be an election process among the servers, but that complicates significantly what used to be a simple PCI connection. Mukherjee pointed out that the model Cisco uses for this is that the "smart NIC" is a "slave" of the main switch fabric. It's a daughter card, which makes it easier to manage from a network perspective. It is clear that Linux will need a way to represent those devices, probably through the newly introduced switchdev or DSA (distributed switch architecture), but it will be something to keep an eye on as density increases in the data center. There were many more discussions during Netconf, too many to cover here, but in the end, Miller thanked everyone for all the interesting topics as the participants dispersed for a day off to travel to Montreal to attend the following Netdev conference.
The author would like to thank the Netconf and Netdev organizers for travel to, and hosting assistance in, Toronto. Many thanks to Alexei Starovoitov for his time taken for a technical review of this article. Note: this article first appeared in the Linux Weekly News.

10 April 2017

Daniel Pocock: If Alan Turing was born today, would he be a Muslim?

Alan Turing's name and his work are well known to anybody with a theoretical grounding in computer science. Turing developed his theories well before anybody invented file sharing, overclocking or mass surveillance. In fact, Turing was largely working in the absence of any computers at all: the transistor was only invented in 1947 and the microchip, the critical innovation that has made computing both affordable and portable, only came in 1960, four years after Turing's death. To this day, the Turing Test remains a well known challenge in the field of Artificial Intelligence. The most prestigious prize in computing, the A.M. Turing Award from the ACM, equivalent to the Nobel Prize in other fields of endeavour, is named in Turing's honour. (This year's award is another British scientist, Sir Tim Berners-Lee, inventor of the World Wide Web).
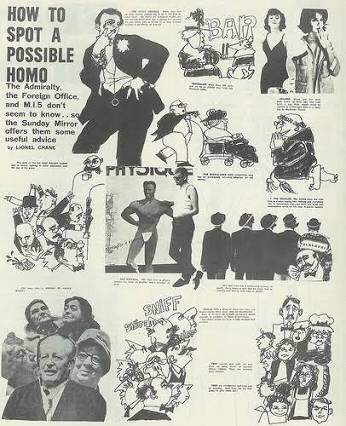
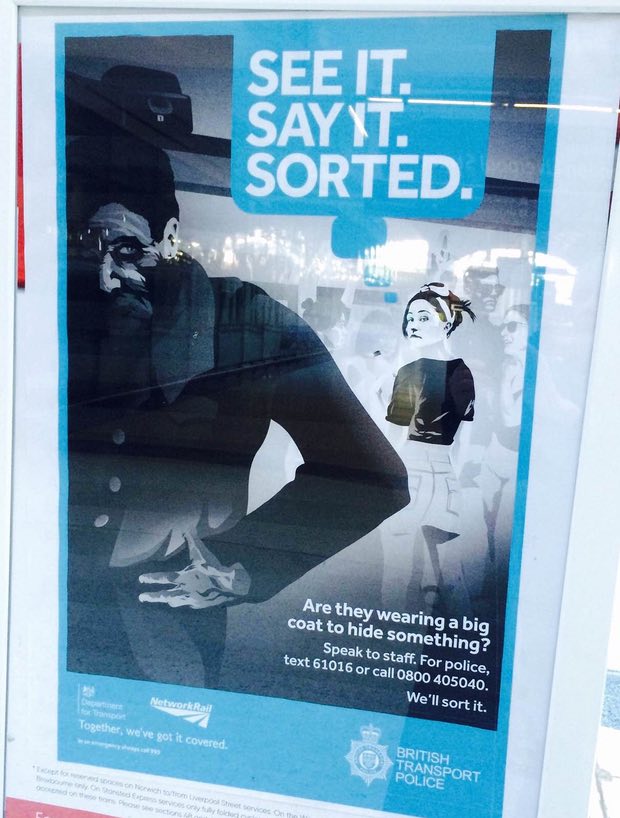
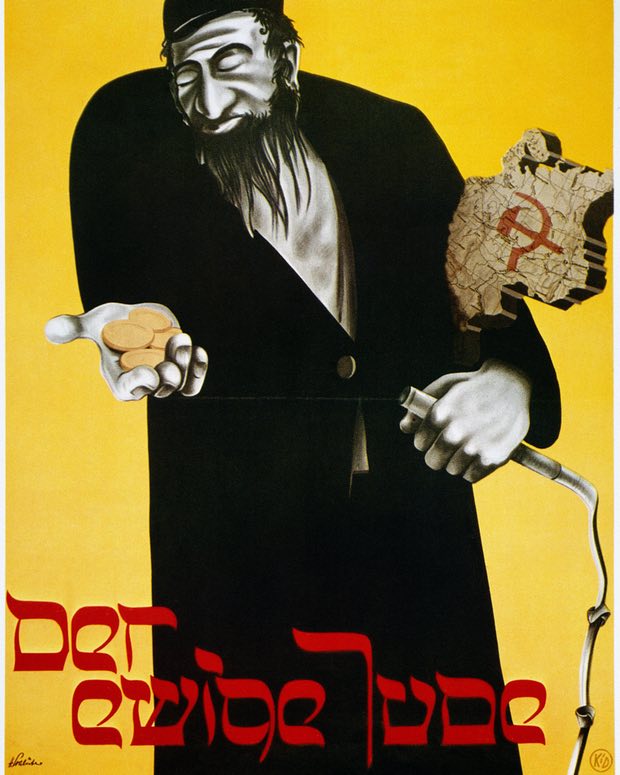
Potentially far more people know of Alan Turing for his groundbreaking work at Bletchley Park and the impact it had on cracking the Nazi's Enigma machines during World War 2, giving the allies an advantage against Hitler. While in his lifetime, Turing exposed the secret communications of the Nazis, in his death, he exposed something manifestly repugnant about his own society. Turing's challenges with his sexuality (or Britain's challenge with it) are just as well documented as his greatest scientific achievements. The 2014 movie The Imitation Game tells Turing's story, bringing together the themes from his professional and personal life. Had Turing chosen to flee British persecution by going abroad, he would be a refugee in the same sense as any person who crossed the seas to reach Europe today to avoid persecution elsewhere. Please prove me wrong In March, I blogged about the problem of racism that plagues Britain today. While some may have felt the tone of the blog was quite strong, I was in no way pleased to find my position affirmed by the events that occurred in the two days after the blog appeared. Two days and two more human beings (both immigrants and both refugees) subjected to abhorrent and unnecessary acts of abuse in Great Britain. Both cases appear to be fuelled directly by the evil that has been oozing out of number 10 Downing Street since they decided to have a referendum on "Brexit". What stands out about these latest crimes is not that they occurred (this type of thing has been going on for months now) but certain contrasts between their circumstances and to a lesser extent, the fact they occurred immediately after Theresa May formalized Britain's departure from the EU. One of the victims was almost beaten to death by a street gang, while the other was abused by men wearing uniforms. One was only a child, while the other is a mature adult who has been in the UK almost three decades, completely assimilated into British life, working and paying taxes. Both were doing nothing out of the ordinary at the time the abuse occurred: one had engaged in a conversation at a bus stop, the other was on a routine visit to a Government office. There is no evidence that either of them had done anything to provoke or invite the abhorrent treatment meted out to them by the followers of Theresa May and Nigel Farage. The first victim, on 30 March, was Stojan Jankovic, a refugee from Yugoslavia who has been in the UK for 26 years. He had a routine meeting at an immigration department office where he was ambushed, thrown in the back of a van and sent to rot in a prison cell by Theresa May's gestapo. On Friday, 31 March, it was Reker Ahmed, a 17 year old Kurdish-Iranian beaten to the brink of death by a crowd in south London. One of the more remarkable facts to emerge about these two cases is that while Stojan Jankovic was basically locked up for no reason at all, the street thugs who the police apprehended for the assault on Ahmed were kept in a cell for less than 48 hours and released again on bail. While the harmless and innocent Jankovic was eventually released after a massive public outcry, he spent more time locked up than that gang of violent criminals who beat Reker Ahmed. In other words, Theresa May and Nigel Farage's Britain has more concern for the liberty of violent criminals than somebody like Jankovic who has been working and paying taxes in the UK since before any of those street thugs were born. A deeper insight into Turing's fate With gay marriage having been legal in the UK for a number of years now, the rainbow flag flying at the Tate and Sir Elton John achieving a knighthood, it becomes difficult for people to relate to the world in which Turing and many other victims were collectively classified by their sexuality, systematically persecuted by the state and ultimately died far sooner than they should have. (Turing was only 41 when he died). In fact, the cruel and brutal forces that ripped Turing apart (and countless other victims too) haven't dissipated at all, they have simply shifted their target. The slanderous comments insinuating that immigrants "steal" jobs or that Islam is about terrorism are eerily reminiscent of suggestions that gay men abduct young boys or work as Soviet spies. None of these lies has any basis in fact, but repeat them often enough in certain types of newspaper and these ideas spread like weeds. In an ironic twist, Turing's groundbreaking work at Bletchley Park was founded on the contributions of Polish mathematicians, their own country having been the first casualty to Hitler, they were also both immigrants and refugees in Britain. Today, under the Theresa May/Nigel Farage leadership, Polish citizens have been subjected to regular vilification by the media and some have even been killed in the street. It is said that a picture is worth a thousand words. When you compare these two pieces of propaganda: a 1963 article in the Sunday Mirror advising people "How to spot a possible homo" and a UK Government billboard encouraging people to be on the lookout for people who look different, could you imagine the same type of small-minded and power-hungry tyrants crafting them, singling out a minority so as to keep the public's attention in the wrong place?
Many people have noticed that these latest UK Government posters portray foreigners, Muslims and basically anybody who is not white using a range of characteristics found in anti-semetic propaganda from the Third Reich: Do the people who create such propaganda appear to have any concern whatsoever for the people they hurt? How would Alan Turing have felt when he encountered propaganda like that from the Sunday Mirror? Do posters like these encourage us to judge people by their gifts in science, the arts or sporting prowess or do they encourage us to lump them all together based on their physical appearance? It is a basic expectation of scientific methodology that when you repeat the same experiment, you should get the same result. What type of experiment are Theresa May and Nigel Farage conducting and what type of result would you expect? Playing ping-pong with children If anybody has any doubt that this evil comes from the top, take a moment to contemplate the 3,000 children who were baited with the promise of resettlement from the Calais "jungle" camp into the UK under the Dubs amendment. When French authorities closed the "jungle" in 2016, the children were lured out of the camp and left with nowhere to go as Theresa May and French authorities played ping-pong with them. Given that the UK parliament had already agreed they should be accepted, was there any reason for Theresa May to dig her heels in and make these children suffer? Or was she just trying to prove her credentials as somebody who can bastardize migrants just the way Nigel Farage would do it? How do British politicians really view migrants? Parliamentarian Keith Vaz, former chair of the Home Affairs Select Committee (responsible for security, crime, prostitution and similar things) was exposed with young men from eastern Europe, encouraging them to take drugs before he ordered them "Take your shirt off. I'm going to attack you.". How many British MP's see foreigners this way? Next time you are groped at an airport security checkpoint, remember it was people like Keith Vaz and his committee who oversee those abuses, writing among other things that "The wider introduction of full-body scanners is a welcome development". No need to "take your shirt off" when these machines can look through it as easily as they can look through your children's underwear. According to the World Health Organization, HIV/AIDS kills as many people as the September 11 attacks every single day. Keith Vaz apparently had no concern for the possibility he might spread this disease any further: the media reported he doesn't use any protection in his extra-marital relationships. While Britain's new management continue to round up foreigners like Stojan Jankovic who have done nothing wrong, they chose not to prosecute Keith Vaz for his antics with drugs and prostitution. Who is Britain's next Alan Turing? Britain's next Alan Turing may not be a homosexual. He or she may have been a child turned away by Theresa May's spat with the French at Calais, a migrant bundled into a deportation van by the gestapo (who are just following orders) or perhaps somebody of Muslim appearance who is set upon by thugs in the street who have been energized by Nigel Farage. If you still have any uncertainty about what Brexit really means, this is it. A country that denies itself the opportunity to be great by subjecting itself to be ruled under the "divide and conquer" mantra of the colonial era. Throughout the centuries, Britain has produced some of the most brilliant scientists of their time. Newton, Darwin and Hawking are just some of those who are even more prominent than Turing, household names around the world. One can only wonder what the history books will have to say about Theresa May and Nigel Farage however. Next time you see a British policeman accosting a Muslim, whether it is at an airport, in a shopping centre, keeping Manchester United souvenirs or simply taking a photograph, spare a thought for Alan Turing and the era when homosexuals were their target of choice.
9 April 2017

Antoine Beaupr : Contribute your skills to Debian in Montreal, April 14 2017

Join us in Montreal, on April 14 2017, and we will find a way in which you can help Debian with your current set of skills! You might even learn one or two things in passing (but you don't have to). Debian is a free operating system for your computer. An operating system is the set of basic programs and utilities that make your computer run. Debian comes with dozens of thousands of packages, precompiled software bundled up for easy installation on your machine. A number of other operating systems, such as Ubuntu and Tails, are based on Debian. The upcoming version of Debian, called Stretch, will be released later this year. We need you to help us make it awesome :) Whether you're a computer user, a graphics designer, or a bug triager, there are many ways you can contribute to this effort. We also welcome experience in consensus decision-making, anti-harassment teams, and package maintenance. No effort is too small and whatever you bring to this community will be appreciated. Here's what we will be doing:
Goals and principles This is a work in progress, and a statement of intent. Not everything is organized and confirmed yet. We want to bring together a heterogeneous group of people. This goal will guide our handling of sponsorship requests, and will help us make decisions if more people want to attend than we can welcome properly. In other words: if you're part of a group that is currently under-represented in computer communities, we would like you to be able to attend. We are committed to providing a friendly, safe and welcoming environment for all, regardless of level of experience, gender, gender identity and expression, sexual orientation, disability, personal appearance, body size, race, ethnicity, age, religion, nationality, or other similar personal characteristic. Attending this event requires reading and respecting the Debian Code of Conduct, that sets the standards in terms of behaviour for the whole event, including communication (public and private) before, while and after. The space where this event will take place is unfortunately not accessible to wheelchairs. Food (including vegetarian options) should be provided for lunch. If you have any specific needs regarding food, please let us know when registering, and we will do our best.

What we will be doing This will be an informal session to confirm and fix bugs in Debian. If you have never worked with Debian packages, this is a good opportunity to learn about packaging and bugtracker usage. Bugs flagged as Release Critical are blocking the release of the upcoming version of Debian. To fix them, it helps to make sure the bug report documents the up-to-date status of the bug, and of its resolution. One does not need to be a programmer to do this work! For example, you can try and reproduce bugs in software you use... or in software you will discover. This helps package maintainers better focus their work. We will also try to actually fix bugs by testing patches and uploading fixes into Debian itself. Antoine Beaupr , a seasoned Debian developer, will be available to sponsor uploads and teach people about basic Debian packaging skills.

Where? When? How to register? See https://wiki.debian.org/BSP/2017/04/ca/Montreal for the exact address and time.

Michael Stapelberg: manpages.debian.org: what s new since the launch?

On 2017-01-18, I announced that https://manpages.debian.org had been modernized. Let me catch you up on a few things which happened in the meantime: The list above is not complete, but rather a selection of things I found worth pointing out to the larger public. There are still a few things I plan to work on soon, so stay tuned :).

4 April 2017

Matthias Klumpp: On Tanglu

It s time for a long-overdue blogpost about the status of Tanglu. Tanglu is a Debian derivative, started in early 2013 when the systemd debate at Debian was still hot. It was formed by a few people wanting to create a Debian derivative for workstations with a time-based release schedule using and showcasing new technologies (which include systemd, but also bundling systems and other things) and built in the open with a community using the similar infrastructure to Debian. Tanglu is designed explicitly to complement Debian and not to compete with it on all devices. Tanglu has achieved a lot of great things. We were the first Debian derivative to adopt systemd and with the help of our contributors we could kill a few nasty issues affecting it and Debian before it ended up becoming default in Debian Jessie. We also started to use the Calamares installer relatively early, bringing a modern installation experience additionally to the traditional debian-installer. We performed the usrmerge early, uncovering a few more issues which were fed back into Debian to be resolved (while workarounds were added to Tanglu). We also briefly explored switching from initramfs-tools to Dracut, but this release goal was dropped due to issues (but might be revived later). A lot of other less-impactful changes happened as well, borrowing a lot of useful ideas and code from Ubuntu (kudos to them!). On the infrastructure side, we set up the Debian Archive Kit (dak), managing to find a couple of issues (mostly hardcoded assumptions about Debian) and reporting them back to make using dak for distributions which aren t Debian easier. We explored using fedmsg for our infrastructure, went through a long and painful iteration of build systems (buildbot -> Jenkins -> Debile) before finally ending up with Debile, and added a set of own custom tools to collect archive QA information and present it to our developers in an easy to digest way. Except for wanna-build, Tanglu is hosting an almost-complete clone of basic Debian archive management tools. During the past year however, the project s progress slowed down significantly. For this, mostly I am to blame. One of the biggest challenges for a young project is to attract new developers and members and keep them engaged. A lot of the people coming to Tanglu and being interested in contributing were unfortunately no packagers and sometimes no developers, and we didn t have the manpower to individually mentor these people and teach them the necessary skills. People asking for tasks were usually asked where their interests were and what they would like to do to give them a useful task. This sounds great in principle, but in practice it is actually not very helpful. A curated list of junior jobs is a much better starting point. We also invested almost zero time in making our project known and create the necessary buzz and excitement that s actually needed to sustain a project like this. Doing more in the advertisement domain and help newcomers area is a high priority issue in the Tanglu bugtracker, which to the day is still open. Doing good alone isn t enough, talking about it is of crucial importance and that is something I knew about, but didn t realize the impact of for quite a while. As strange as it sounds, investing in the tech only isn t enough, community building is of equal importance. Regardless of that, Tanglu has members working on the project, but way too few to manage a project of this magnitude (getting package transitions migrated alone is a large task requiring quite some time while at the same time being incredibly boring :P). A lot of our current developers can only invest small amounts of time into the project because they have a lot of other projects as well. The other issue why Tanglu has problems is too much stuff being centralized on myself. That is a problem I wanted to rectify for a long time, but as soon as a task wasn t done in Tanglu because no people were available to do it, I completed it. This essentially increased the project s dependency on me as single person, giving it a really low bus factor. It not only centralizes power in one person (which actually isn t a problem as long as that person is available enough to perform tasks if asked for), it also centralizes knowledge on how to run services and how to do things. And if you want to give up power, people will need the knowledge on how to perform the specific task first (which they will never gain if there s always that one guy doing it). I still haven t found a great way to solve this it s a problem that essentially kills itself as soon as the project is big enough, but until then the only way to counter it slightly is to write lots of documentation. Last year I had way less time to work on Tanglu than the project deserves. I also started to work for Purism on their PureOS Debian derivative (which is heavily influenced by some of the choices we made for Tanglu, but with different focus that s probably something for another blogpost). A lot of the stuff I do for Purism duplicates the work I do on Tanglu, and also takes away time I have for the project. Additionally I need to invest a lot more time into other projects such as AppStream and a lot of random other stuff that just needs continuous maintenance and discussion (especially AppStream eats up a lot of time since it became really popular in a lot of places). There is also my MSc thesis in neuroscience that requires attention (and is actually in focus most of the time). All in all, I can t split myself and KDE s cloning machine remains broken, so I can t even use that ;-). In terms of projects there is also a personal hard limit of how much stuff I can handle, and exceeding it long-term is not very healthy, as in these cases I try to satisfy all projects and in the end do not focus enough on any of them, which makes me end up with a lot of half-baked stuff (which helps nobody, and most importantly makes me loose the fun, energy and interest to work on it). Good news everyone! (sort of) So, this sounded overly negative, so where does this leave Tanglu? Fact is, I can not commit the crazy amounts of time for it as I did in 2013. But, I love the project and I actually do have some time I can put into it. My work on Purism has an overlap with Tanglu, so Tanglu can actually benefit from the software I develop for them, maybe creating a synergy effect between PureOS and Tanglu. Tanglu is also important to me as a testing environment for future ideas (be it in infrastructure or in the make bundling nice! department). So, what actually is the way forward? First, maybe I have the chance to find a few people willing to work on tasks in Tanglu. It s a fun project, and I learned a lot while working on it. Tanglu also possesses some unique properties few other Debian derivatives have, like being built from source completely (allowing us things like swapping core components or compiling with more hardening flags, switching to newer KDE Plasma and GNOME faster, etc.). Second, if we do not have enough manpower, I think converting Tanglu into a rolling-release distribution might be the only viable way to keep the project running. A rolling release scheme creates much less effort for us than making releases (especially time-based ones!). That way, users will have a constantly updated and secure Tanglu system with machines doing most of the background work. If it turns out that absolutely nothing works and we can t attract new people to help with Tanglu, it would mean that there generally isn t much interest from the developer or user side in a project like this, so shutting it down or scaling it down dramatically would be the only option. But I do not think that this is the case, and I believe that having Tanglu around is important. I also have some interesting plans for it which will be fun to implement for testing  The only thing that had to stop is leaving our users in the dark on what is happening. Sorry for the long post, but there are some subjects which are worth writing more than 140 characters about  If you are interested in contributing to Tanglu, get in touch with us! We have an IRC channel #tanglu-devel on Freenode (go there for quicker responses!), forums and mailinglists, It looks like I will be at Debconf this year as well, so you can also catch me there! I might even talk about PureOS/Tanglu infrastructure at the conference.
3 April 2017

Vincent Fourmond: Variations around ls -lrt

I have been using almost compulsively ls -lrt for a long time now. As per the ls man page, this command lists the files of the current directory, with the latest files at the end, so that they are the ones that show up just above your next command-line. This is very convenient to work with, hmmm, not-so-well-organized directories, because it just shows what you're working on, and you can safely ignore the rest. Typical example is a big Downloads directory, for instance, but I use it everywhere. I quickly used alias lrt="ls -lrt" to make it easier, but... I though I might have as well a reliable way to directly use what I saw. So I came up with the following shell function (zsh, but probably works with most Bourne-like shells):
lrt()  
    ls -lrt "$@"
    lrt="$(ls -rt "$@"   tail -n1)"
 
This small function runs ls -lrt as usual, but also sets the $lrt shell variable to the latest file, so you can use it in your next commands ! Especially useful for complex file names. Demonstration:
22:05 vincent@ashitaka ~/Downloads lrt
[...]
-rw-r--r-- 1 vincent vincent   1490027 Apr  2 15:44 k.zip
-rw-r--r-- 1 vincent vincent    668566 Apr  3 22:05 1-s2.0-S0013468617305947-main.pdf
22:06 vincent@ashitaka ~/Downloads cp -v $lrt ~/nice-paper.pdf
'1-s2.0-S0013468617305947-main.pdf' -> '/home/vincent/nice-paper.pdf'
This saves typing the name of the 1-s2.0-S0013468617305947-main.pdf: in this case, automatic completion doesn't help much, since many files in my Downloads directory start with the same orefix... I hope this helps !

1 April 2017

Antoine Beaupr : My free software activities, February and March 2017

Looking into self-financing Before I begin, I should mention that I started tracking my time working on free software more systematically. I spend a lot of time on the computer, as regular readers of this blog might remember so I wanted to know exactly how much time was paid vs free work. I was already using org-mode's time clock system to keep track of my work hours, so I just extended this to my regular free software contributions, which also helps in writing those reports. It turns out that over 60% of my computer time is spent working on free software. That's huge! I was expecting something more along the range of 20 to 40% of my time. So I started thinking about ways of financing this work. I created a Patreon page but I'm hesitant into launching such a campaign: the only thing worse than "no patreon page" is "a patreon page with failed goals and no one financing it". So before starting such an effort, I'd like to get a feeling of what other people's experience with it are. I know that joeyh is close to achieving his goals, but I can't compare with the guy that invented git-annex or debhelper, so I'm concerned I wouldn't be able to raise the same level of funding. So any advice you have, feel free to contact me in private or in the comments. If you would be ready to fund my work, I'd love to know about it, obviously, but I guess I wouldn't get real numbers until I actually open up such a page... Now, onto the regular report.

Wallabako I spent a good chunk of time completing most of the things I had in mind for Wallabako, which I mentioned quickly in the previous report. Wallabako is now much easier to installed, with clearer instructions, an easier to use configuration file, more reliable synchronization and read status propagation. As usual the Wallabako README file has all the details. I've also looked at better integration with Koreader, the free software e-reader that forms the basis of the okreader free software distribution which has been able to port Debian to the Kobo e-readers, a project I am really excited about. This project has the potential of supporting Kobo readers beyond the lifetime that upstream grants it and removes a lot of proprietary software and spyware that ships with the Kobo readers. So I have made a few contributions to okreader and also on koreader, the ebook reader okreader is based on.

Stressant I rewrote stressant, my simple burn-in and stress-testing tool. After struggling in turn with Debirf, live-build, vmdebootstrap and even FAI, I just figured maybe it wasn't the best idea to try and reinvent that particular wheel: instead of reinventing how to build yet another Debian system build tool, maybe I should just reuse what's already there. It turns out there's a well known, succesful and fairly complete recovery system called Grml. It is a Debian Derivative, so all I needed to do was to stop procrastinating and actually write the actual stressant tool instead of just creating a distribution with a bunch of random tools shipped in. This allowed me to focus on which tools were the best to stress test different components. This selection ended up being: fio can also be used to overwrite disk drives with the proper options (--overwrite and --size=100%), although grml also ships with nwipe for wiping old spinning disks and hdparm to do a secure erase of SSD disks (whatever that's worth). Stressant still needs to be shipped with grml for this transition to be complete. In the meantime, I was able to configure the excellent public Gitlab CI service to provide ISO images with Stressant built-in as a stopgap measure. I also need to figure out a way to automate starting stressant from a boot menu to automate deployments on a larger scale, although because I have little need for the feature at this moment in time, this will likely wait for a sponsor to show up for this to be implemented. Still, stressant has useful features like the capability of sending logs by email using a fresh new implementation of the Python SMTPHandler (BufferedSMTPHandler) which waits for logging to complete before sending a single email. Another interesting piece of code in there is the NegateAction argparse handler that enables the use of "toggle flags" (e.g. --flag / --no-flag). I'm so happy with the code that I figure I could just share it here directly:
class NegateAction(argparse.Action):
    '''add a toggle flag to argparse

    this is similar to 'store_true' or 'store_false', but allows
    arguments prefixed with --no to disable the default. the default
    is set depending on the first argument - if it starts with the
    negative form (define by default as '--no'), the default is False,
    otherwise True.
    '''
    negative = '--no'
    def __init__(self, option_strings, *args, **kwargs):
        '''set default depending on the first argument'''
        default = not option_strings[0].startswith(self.negative)
        super(NegateAction, self).__init__(option_strings, *args,
                                           default=default, nargs=0, **kwargs)
    def __call__(self, parser, ns, values, option):
        '''set the truth value depending on whether
        it starts with the negative form'''
        setattr(ns, self.dest, not option.startswith(self.negative))
Short and sweet. I wonder why stuff like this is not in the standard library yet - maybe just because no one bothered yet? It'd be great to get feedback of more experienced Pythonistas on this one. I hope that my work on Stressant is complete. I get zero funding for this work, and have little use for it myself: I manage only a few machines and such a tool really shines when you regularly put new hardware online, which is (fortunately?) not my case anymore. I'd be happy, of course, to accompany organisations and people that wish to further develop and use such a tool. A short demo of stressant as well as detailed description of how it works is of course available in its README file.

Standard third party repositories After looking at improvements for the grml repository instructions, I realized there was no real "best practices" document on how to configure an Apt repository. Sure, there are tools like reprepro and others, but those hardly qualify as policy: they are very flexible and there are lots of ways to create insecure repositories or curl sh style instructions, which we of course generally want to avoid. While the larger problem of Unstrusted Debian packages remain generally unsolved (e.g. when you install any .deb file, it can get root on your system), it seemed to me one critical part of this problem was how to add a random third-party repository to your machine while limiting, as much as possible, what possible attackers could do with such a repository. In other words, to solve the more general problem of insecure .deb files, we also need to solve the distribution problem, otherwise fixing the .deb files themselves will be useless. This lead to the creation of standardized repository instructions that define:
  1. how to distribute the repository's public signing key (ie. over HTTPS)
  2. how to name suites and components (e.g. use stable and main unless you have a good reason, and explain yourself)
  3. recommend a healthy does of apt preferences pinning
  4. how to distribute keys (e.g. with a derive-archive-keyring package)
I've seen so many third party repositories get this wrong. For example, a lot of repositories recommend this type of command to intialize the OpenPGP trust path:
curl http://example.com/key.asc   apt-key add -
This has the following problems:
  • the key is transfered in plaintext and can easily be manipulated by an active attacker (e.g. a router on your path to the server or a neighbor in a Wifi cafe)
  • the key is added to the main trust root, which allows the key to authentify as the real Debian archive, therefore giving it all rights over all packages
  • since it's part of the global archive, it's difficult for a package to remove/add the key when a key rollover is necessary (and repositories generally don't provide a deriv-archive-keyring to do that process anyways)
An example of this are the Docker install instructions that, at least, manage to do this over HTTPS. Some other repositories don't even bother teaching people about the proper way of adding those keys. We settled for:
wget -O /usr/share/keyrings/deriv-archive-keyring.gpg https://deriv.example.net/debian/deriv-archive-keyring.gpg
That location was explicitly chosen to be out of the main trust directory, so that it needs to be explicitly added to the sources.list as well:
deb [signed-by=/usr/share/keyrings/deriv-archive-keyring.gpg] https://deriv.example.net/debian/ stable main
Similarly, we highly recommend users setup "apt pinning" to restrict what a given repository can do. Since pinning is so confusing, most people don't actually bother even configuring it and I have yet to see a single repo advise its users to configure those preferences, which are essential to limit what a repository can do. To keep configuration simple, we recommend this:
Package: *
Pin: origin deriv.example.net
Pin-Priority: 100
Obviously, for a single-package repository, the actual package name should be listed, e.g.:
Package: foo
Pin: origin deriv.example.net
Pin-Priority: 100
And the priority should probably be set to 1 unless you want to allow automatic upgrades. It is my hope that this design will get more traction in the years to come and become a de-facto standard that will be a key part in safely adding third party repositories. There is obviously much more work to be done to improve security when installing untrusted .deb files, and I encourage Debian developers to consider contributing to the UntrustedDebs discussions and particularly to the Teams/Dpkg/Spec/DeclarativePackaging work.

Signal R&D I spent a significant amount of time this month struggling with the Signal project on my phone. I'm still ambivalent on Signal: it's a centralized designed, too dependent on phone numbers, but I must admit they get a lot of things right and it's the only free-software platform that allows for easy-to-use, multi-platform videoconferencing that my family can use. I've been following Signal for a while: up until now, I had been using the LibreSignal rebuild of the official client, as it is distributed on a F-Droid repository. Because I try to avoid Google (proprietary) software on my phone, it's basically the only way I could even install Signal. Unfortunately, the repository is out of date and introduces another point of trust in the distribution model: now you not only need to trust the Signal authors to do the right thing, you also need to trust that F-Droid repo not to inject nasty code on your phone. I've therefore started a discussion about how Signal could be distributed outside of the Google Play Store. I'd like to think it's one of the things that led the Signal people to distribute an official copy of Signal outside of the playstore. After much struggling, I was able to upgrade to this official client and will be able to upgrade easily by just downloading the APK. (Do note that I ended up reinstalling and re-registering Signal, which unfortunately changed my secret keys.) I do hope Signal enters F-Droid one day, but it could take a while because it still doesn't work without Google services and barely works with MicroG, the free software alternative to the Google services clients. Moxie also set a list of requirements like crash reporting and statistics that need to be implemented on F-Droid's side before he agrees to the deployment, so this could take a while. I've also participated in the, ahem, discussion on the JWZ blog regarding a supposed vulnerability in Signal where it would leak previously unknown phone numbers to third parties. I reviewed the way the phone number is uploaded and, while it's possible to create a rainbow table of phone numbers (which are hashed with a truncated SHA-1 checksum), I couldn't verify the claims of other participants in the thread. For me, Signal still does the right thing with contacts, although I do question the way "read status" notifications get transmitted, but that belong in another bug report / blog post.

Debian Long Term Support (LTS) It's been more than a year working on Debian LTS, started by Raphael Hertzog at Freexian. I didn't work much in February so I had a lot of hours to catchup with, and was unfortunately unable to do so, partly because I was busy with other projects, and partly because my colleagues are doing a great job at resolving the most important issues. So one my concerns this month was finding work. It seemed that all the hard packages were either taken (e.g. my usual favorites, tiff and imagemagick, we done by others) or just too challenging (e.g. I don't feel quite comfortable tackling the LTS branch of the Linux kernel yet). I spent quite a bit of time trying to figure out what was wrong with pcre3, only to realise the "32" in the report was not about the architecture, but about the character width. Because of thise, I marked 4 CVEs (CVE-2017-7186, CVE-2017-7244, CVE-2017-7245, CVE-2017-7246) as "not-affected", since the 32-bith character support wasn't enabled in wheezy (or jessie, for that matter). I still spent some time trying to reproduce the issues, which require a compiler with an AddressSanitizer, something that was introduced in both Clang and GCC after Wheezy was released, which makes reproducing this fairly complicated... This allowed me to experiment more with Vagrant, however, and I have provided the Debian cloud team with a 32-bit Vagrant box that was merged in shortly after, although it doesn't show up yet in the official list of Debian images. Then I looked at the apparmor situation (CVE-2017-6507), Debian bug #858768). That was one tricky bug as well, since it's not a security issue in apparmor per se, but more an issue with things that assume a certain behavior from apparmor. I have concluded that Wheezy was not affected because there are no assumptions of proper isolation there - which are provided only starting from LXC 1.0 - and Docker is not in Wheezy. I also couldn't reproduce the issue on Jessie, but, as it turns out, the issue was sysvinit-specific, which is why I couldn't reproduce it under the default systemd configuration shipped with Jessie. I also looked at the various binutils security issues: as I reported on the mailing list, I didn't see anything serious enough in there to warrant a a security release and followed the lead of both the stable and Red Hat security teams by marking this "no-dsa". I similiarly reviewed the mp3splt security issues (specifically CVE-2017-5666) and was fairly puzzled by that issue, which seems to be triggered only the same address sanitization extensions than PCRE, although there was some pretty wild interplay with debugging flags in there. All in all, it seems we can't reproduce that issue in wheezy, but I do not feel confident enough in the results to push that issue aside for now. I finally uploaded the pending graphicsmagick issue (DLA-547-2), a regression update to fix a crash that was introduced in the previous release (DLA-547-1, mistakenly named DLA-574-1). Hopefully that release should clear up some of the confusion and fix the regression. I also released DLA-879-1 for the CVE-2017-6369 in firebird2.5 which was an interesting experiment: I couldn't reproduce the issue in a local VM. After following the Ubuntu setup tutorial, as I wasn't too familiar with the Firebird database until now (hint: the default username and password is sysdba/masterkey), I ended up assuming we were vulnerable and just backporting the patch after seeing the jessie folks push out a release just in case. I also looked at updating the ca-certificates package to deal with the pending WoSign/Startcom removal: I made an explicit list of the CAs that need to be removed after reviewing the Mozilla list. I also sent a patch for an unrelated issue where ca-certificates is writing to /usr/local (!!) in Debian bug #843722. I have also done some "meta" work in starting a discussion about fixing the missing DLA links in the tracker, as you will notice all of the above links lead to nowhere. Thanks to pabs, there are now some links but unfortunately there are about 500 DLAs missing from the website. We also discussed ways to Debian bug #859123, something which is currently a manual process. This is now in the hands of the excellent webmaster team. I have also filed a few missing security bugs (Debian bug #859135, Debian bug #859136), partly because I wanted to help the security team. But it turned out that I felt the script needed some improvements, so I submitted a patch to improve the script so it is easier to run.

Other projects As usual, there's the usual mixed bags of chaos: More stuff on Github...

Mike Hommey: Progress on git-cinnabar memory usage

This all started when I figured out that git-cinnabar was using crazy amounts of memory when cloning mozilla-central. That pointed to memory allocation patterns that triggered a suboptimal behavior in the glibc memory allocator, and, while overall, git-cinnabar wasn t really abusing memory all things considered, it happened to be realloc()ating way too much. It also turned out that recent changes on the master branch had made most uses of fast-import synchronous, making the whole process significantly slower. This is where we started from on 0.4.0: And on the master branch as of be75326: An interesting thing to note here is that the glibc allocator runaway memory use was, this time, more pronounced on 0.4.0 than on master. It was the opposite originally, but as I mentioned in the past ASLR is making it not happen exactly the same way each time. While I m here, one thing I failed to mention in the previous posts is that all these measurements were done by cloning a local mercurial clone of mozilla-central, served from localhost via HTTP to eliminate the download time from hg.mozilla.org. And while mozilla-central itself has received new changesets since the first post, the local clone has not been updated, such that all subsequent clone tests I did were cloning the exact same repository under the exact same circumstances. After last blog post, I focused on the low hanging fruits identified so far: And this is how things now look on the master branch as of 35c18e7: So where does that put us? On a more granular level: What this means is that there s still room for improvement. But at this point, I d rather focus on other things. Logging all the memory allocations with the python allocator disabled still resulted in a 6.5GB compressed log file, containing 2.6 billion calls to malloc, calloc, free and realloc (down from 2.7 billions in be75326). The number of allocator calls done by the git-remote-hg process is down to 2.25 billions (from 2.34 billion in be75326). Surprisingly, while more things were moved to the helper, it still made less allocations than in be75326: 345 millions, down from 363 millions. Presumably, this is because the number of commands processed by the fast-import code was reduced. Let s now take a look at the various metrics we analyzed previously (the horizontal axis represents the number of allocator calls that happened before the measurement): A few observations to make here: [*] The upper bound is the sum of all sizes ever given to malloc, calloc, realloc etc. and the lower bound is the same, but removing the size of allocations passed as input to realloc (in practical words, this pretends reallocs never happened and that the final size for a given reallocated pointer is the one that counts) So presumably, some of the changes led to more short-lived allocations. Considering python uses its own allocator for sizes smaller than 512 bytes, it s probably not so much of a problem. But let s look at the distribution of buffer sizes (including all sizes given to realloc). (Bucket size is 16 bytes) What is not completely obvious from the logarithmic scale is that, in fact, 98.4% of the allocations are less than 512 bytes with the current master (35c18e7), and they were 95.5% with be75326. Interestingly, though, in absolute numbers, there are less allocations smaller than 512 bytes in current master than in be75326 (1,194,268,071 vs 1,214,784,494). This suggests the extra allocations that happen during some phases are larger than that. There are clearly less allocations across the board (apart from very few exceptions), and close to an order of magnitude less allocations larger than 1MiB. In fact, widening the bucket size to 32KiB shows an order of magnitude difference (or close) for most buckets: An interesting thing to note is how some sizes are largely overrepresented in the data with buckets of 16 bytes, like 768, 1104, 2048, 4128, with other smaller bumps for e.g. 2144, 2464, 2832, 3232, 3696, 4208, 4786, 5424, 6144, 6992, 7920 While some of those are powers of 2, most aren t, and some of them may actually represent objects sized with a power of 2, but that have an extra PyObject overhead. While looking at allocation stats, I got to wonder what the lifetimes of those allocations looked like. So I scanned the allocator logs and measured the distance between when an allocation is made and when it is freed, ignoring reallocs. To give a few examples of what I mean, the following allocation for p gets a lifetime of 0:
void *p = malloc(42);
free(p);
The following a lifetime of 1:
void *p = malloc(42);
void *other = malloc(42);
free(p);
And the following a lifetime of 1 as well:
void *p = malloc(42);
p = realloc(p, 84);
free(p);
(that is, it is not counted as two malloc/free pairs) The further away the free is from the corresponding malloc, the larger the lifetime. And the largest the lifetime can ever be is the total number of allocator function calls minus two, in the hypothetical case the very first allocation is freed as the very last (minus two because we defined the lifetime as the distance). What comes out of this data: All in all, what the data shows is that we re definitely in a better place now than we used to be a few days ago, and that there is still work to do on the memory front, but: So at this point, I won t look any deeper into the memory usage of the git-remote-hg python process, and will instead focus on the planned metadata storage changes. They will allow to share the metadata more easily (allowing faster and more straightforward gecko-dev graft), and will allow to import manifests earlier, which, as mentioned already, will help reduce memory use, but, more importantly, will allow to do more actual work while downloading the data. On slow networks, this is crucial to make clones and pulls faster.

Francois Marier: Manually expanding a RAID1 array on Ubuntu

Here are the notes I took while manually expanding an non-LVM encrypted RAID1 array on an Ubuntu machine. My original setup consisted of a 1 TB drive along with a 2 TB drive, which meant that the RAID1 array was 1 TB in size and the second drive had 1 TB of unused capacity. This is how I replaced the old 1 TB drive with a new 3 TB drive and expanded the RAID1 array to 2 TB (leaving 1 TB unused on the new 3 TB drive).

Partition the new drive In order to partition the new 3 TB drive, I started by creating a temporary partition on the old 2 TB drive (/dev/sdc) to use up all of the capacity on that drive:
$ parted /dev/sdc
unit s
print
mkpart
print
Then I initialized the partition table and creating the EFI partition partition on the new drive (/dev/sdd):
$ parted /dev/sdd
unit s
mktable gpt
mkpart
Since I want to have the RAID1 array be as large as the smaller of the two drives, I made sure that the second partition (/home) on the new 3 TB drive had:
  • the same start position as the second partition on the old drive
  • the end position of the third partition (the temporary one I just created) on the old drive
I created the partition and flagged it as a RAID one:
mkpart
toggle 2 raid
and then deleted the temporary partition on the old 2 TB drive:
$ parted /dev/sdc
print
rm 3
print

Create a temporary RAID1 array on the new drive With the new drive properly partitioned, I created a new RAID array for it:
mdadm /dev/md10 --create --level=1 --raid-devices=2 /dev/sdd1 missing
and added it to /etc/mdadm/mdadm.conf:
mdadm --detail --scan >> /etc/mdadm/mdadm.conf
which required manual editing of that file to remove duplicate entries.

Create the encrypted partition With the new RAID device in place, I created the encrypted LUKS partition:
cryptsetup -h sha256 -c aes-xts-plain64 -s 512 luksFormat /dev/md10
cryptsetup luksOpen /dev/md10 chome2
I took the UUID for the temporary RAID partition:
blkid /dev/md10
and put it in /etc/crypttab as chome2. Then, I formatted the new LUKS partition and mounted it:
mkfs.ext4 -m 0 /dev/mapper/chome2
mkdir /home2
mount /dev/mapper/chome2 /home2

Copy the data from the old drive With the home paritions of both drives mounted, I copied the files over to the new drive:
eatmydata nice ionice -c3 rsync -axHAX --progress /home/* /home2/
making use of wrappers that preserve system reponsiveness during I/O-intensive operations.

Switch over to the new drive After the copy, I switched over to the new drive in a step-by-step way:
  1. Changed the UUID of chome in /etc/crypttab.
  2. Changed the UUID and name of /dev/md1 in /etc/mdadm/mdadm.conf.
  3. Rebooted with both drives.
  4. Checked that the new drive was the one used in the encrypted /home mount using: df -h.

Add the old drive to the new RAID array With all of this working, it was time to clear the mdadm superblock from the old drive:
mdadm --zero-superblock /dev/sdc1
and then change the second partition of the old drive to make it the same size as the one on the new drive:
$ parted /dev/sdc
rm 2
mkpart
toggle 2 raid
print
before adding it to the new array:
mdadm /dev/md1 -a /dev/sdc1

Rename the new array To change the name of the new RAID array back to what it was on the old drive, I first had to stop both the old and the new RAID arrays:
umount /home
cryptsetup luksClose chome
mdadm --stop /dev/md10
mdadm --stop /dev/md1
before running this command:
mdadm --assemble /dev/md1 --name=mymachinename:1 --update=name /dev/sdd2
and updating the name in /etc/mdadm/mdadm.conf. The last step was to regenerate the initramfs:
update-initramfs -u
before rebooting into something that looks exactly like the original RAID1 array but with twice the size.

Paul Wise: FLOSS Activities March 2017

Changes

Issues

Review

Administration
  • Debian systems: apply a patch to userdir-ldap, ask a local admin to reset a dead powerpc buildd, remove dead SH4 porterboxen from LDAP, fix perms on www.d.o OC static mirror, report false positives in an an automated abuse report, redirect 1 student to FAQs/support/DebianEdu, redirect 1 event organiser to partners/trademark/merchandise/DPL, redirect 1 guest account seeker to NM, redirect 1 @debian.org desirer to NM, redirect 1 email bounce to a changes@db.d.o user, redirect 2 people to the listmasters, redirect 1 person to Debian Pure Blends, redirect 1 user to a service admin and redirect 2 users to support
  • Debian packages site: deploy my ports/cruft changes
  • Debian wiki: poke at HP page history and advise a contributor, whitelist 13 email address, whitelist 1 domain, check out history of a banned IP, direct 1 hoster to DebConf17 sponsors team, direct 1 user to OpenStack packaging, direct 1 user to InstallingDebianOn and h-node.org, direct 2 users to different ways to help Debian and direct 1 emeritus DD on repository wiki page reorganisation
  • Debian QA: fix an issue with the PTS news, remove some debugging cruft I left behind, fix the usertags on a QA bug and deploy some code fixes
  • Debian mentors: security upgrades and service restarts
  • Openmoko: security upgrades and reboots

Communication

Sponsors The valgrind backport, samba and libthrift-perl bug reports were sponsored by my employer. All other work was done on a volunteer basis.

Keith Packard: DRM-lease-2

DRM leasing part deux (kernel side) I've stabilized the kernel lease implementation so that leases now work reliably, and don't require a reboot before running the demo app a second time. Here's whats changed:
  1. Reference counting is hard. I'm creating a new drm_master, which means creating a new file. There were a bunch of reference counting errors in my first pass; I've cleaned those up while also reducing the changes needed to the rest of the DRM code.
  2. Added a 'mask_lease' value to the leases -- this controls whether resources in the lease are hidden from the lessor, allowing the lessor to continue to do operations on the leased resources if it likes.
  3. Hacked the mutex locking assertions to not crash in normal circumstances. I'm now doing: BUG_ON(__mutex_owner(&master->dev->mode_config.idr_mutex) != current); to make sure the mutex is held by the current thread, instead of just making sure some thread holds the mutex. I have this memory of a better way to do this, but now I can't dig it up. Suggestions welcome, of course.
I'm reasonably pleased with the current state of the code, although I want to squash the patches together so that only the final state of the design is represented, rather than the series of hacks present now. Comments on #dri-devel I spent a bit of time on the #dri-devel IRC channel answering questions about the DRM-lease design and the changes above reflect that. One concern was about mode setting from two masters at the same time. Mode setting depends on a number of shared 'hidden' resources; things like memory fifos and the like. If either lessee or lessor wants to change the displayed modes, they may fail due to conflicts over these resources and not be able to recover easily. A related concern was that the current TEST/render/commit mechanism used by compositors may no longer be reliable as another master could change hidden resource usage between the TEST and commit operations. Daniel Vetter suggested allowing the lessor to 'exclude' lessee mode sets during this operation. One solution would be to have the lessor set the mode on the leased resources before ceding control of the objects, and once set, the lessee shouldn't perform additional mode setting operations. This would limit the flexibility in the lessee quite a bit as it wouldn't be able to pop up overlay planes or change resolution. Questions Let's review the questions from my last post, DRM-lease: Remaining Kernel Work The code is running, and appears stable. However, it's not quite done yet. Here's a list of remaining items that I know about:
  1. Changing leases should update sub-leases. When you reduce the resources in one lease, the kernel should walk any sub-leases and clear out resources which the lessor no longer has access to.
  2. Sending events when leases are created/destroyed. When a lease is created, if the mask_lease value is set, then the lessor should get regular events describing the effective change. Similarly, both lessor and lessee should get events when a lease is changed.
  3. Refactoring the patch series to squash intermediate versions of the new code.
Remaining Other Work Outside of the kernel, I'll be adding X support for this operation. Here's my current thinking: With that, I think this phase of the project will be wrapped up and it will be time to move on to actually hooking up a real HMD and hacking the VR code to use this new stuff. Seeing the code For those interested in seeing the state of the code so far, there's kernel, drm and kmscube repositories here:

31 March 2017

Holger Levsen: 20170331-pillow-fight

Pillow fight For some time I struggled how to tell this short story so it started with some trolls (clever, but still despiteful, or maybe just with too much energy) who made a pillow with a picture of the initial systemd author, Lennart Poettering, and put it on the sofas of the CCC Hamburg hackerspace Which I perceived as clever trolling, as it really was a harmless pillow, which one could use to innocently punch Lennart in the face, or rather not, as denial of this was easy and included, eg of course this pillow was also suitable for hugging! For some time, I didn't know how to react. Some clever person just turned the pillow cover upsidedown, so at least we had a white pillow instead. But still, I wanted a better reaction And then I met Lennart at devconf.cz in Brno and realized, that I would meet him again the following weekend in Brussels so on Saturday morning of FOSDEM 2017 I embarrassed Lennart (and myself) a little, but it was very much worth it! And so he signed it: To put this into perspective or why I think the original pillow was a bad idea: some people hate systemd, fine (though I do think systemd is a fine piece of software, but you can surely disagree about this), just, please keep in mind: "hate/fight the game, not the players".

Next.

Previous.