Search Results: "ag"

26 March 2014

Dirk Eddelbuettel: RProtoBuf 0.4.1

A new bug-fix release release 0.4.1 of RProtoBuf, is now on CRAN. RProtoBuf provides GNU R bindings for the Google Protocol Buffers ("Protobuf") data encoding library used and released by Google, and deployed as a language and operating-system agnostic protocol by numerous projects. Murray once more shouldered most of the actual burden and fixed a number of issues detailed below.
Changes in RProtoBuf version 0.4.1 (2014-03-25)
  • Document and add a test for the deprecated group functionality.
  • Add a CITATION file pointing to our arXiv.org preprint.
  • Fix a bug in the show method for EnumDescriptor types.
  • Import all top-level enums from imported .proto files.
  • Removed duplicate enum value type from the unit tests that caused problems with the most recent libprotobuf-2.5. (without option allow_alias).
CRANberries also provides a diff to the previous release. More information is at the RProtoBuf page which has a draft package vignette, a 'quick' overview vignette and a unit test summary vignette. Questions, comments etc should go to the rprotobuf mailing list off the RProtoBuf page at R-Forge.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

25 March 2014

Julien Danjou: The Hacker's Guide to Python released!

And done! It took me just 8 months to do this entire book project around Python. From the first day I started writing to today, where I finally publish and sell almost entirely myself this book. I'm really proud of what I've achieved so far, as this was something totally new to me. Doing all of that has been a great adventure, and I'll promise I'll write something about that later on. A making of. For now, you can enjoy reading the book and learn a bit more about Python. I really hope it'll help you bring your Python-fu to a new level, and help you build great projects! Go check it out, and since this is first day of sale, enjoy 20% off by using the offer code THGTP20.

Francesca Ciceri: A crafty roundup: projects from the last months

A quick roundup of things I made during the last months, following tutorials here and there. finished projects for babies 1: a soft bunny more or less based on this one 2: skelly man! You can find pattern and instructions on Chez Beeper Bebe's blog 3: bibs: the embroidered one is based on this pattern by Charlotte Lyons on SouleMama's blog, the other re-uses the same pattern but add a bird applique instead. finished projects for women 1, 4: my first try with the beautiful Weekender Bag ended with something else entirely: apparently, where euclidean geometry principles apply, cutting a piece of fabric 10 cm smaller will result in a bag 10 cm smaller!
Go figure! Fhtang! I'm happy anyway with the final result, but it resembles more a tote bag than a weekender one. I then made also a successful Weekender, but haven't taken a pic yet. If you try that pattern, you may find this blogpost helpful. 2: This is my try at copycatting this model without a pattern and didn't end very well.
However, a couple lessons learned: 3: Blouse with knit-stretchy stuff! (You love me when I speak technical, don't you?)
I did that without pattern, mostly using a similar top I have as inspiration/guide

Petter Reinholdtsen: Public Trusted Timestamping services for everyone

Did you ever need to store logs or other files in a way that would allow it to be used as evidence in court, and needed a way to demonstrate without reasonable doubt that the file had not been changed since it was created? Or, did you ever need to document that a given document was received at some point in time, like some archived document or the answer to an exam, and not changed after it was received? The problem in these settings is to remove the need to trust yourself and your computers, while still being able to prove that a file is the same as it was at some given time in the past. A solution to these problems is to have a trusted third party "stamp" the document and verify that at some given time the document looked a given way. Such notarius service have been around for thousands of years, and its digital equivalent is called a trusted timestamping service. The Internet Engineering Task Force standardised how such service could work a few years ago as RFC 3161. The mechanism is simple. Create a hash of the file in question, send it to a trusted third party which add a time stamp to the hash and sign the result with its private key, and send back the signed hash + timestamp. Both email, FTP and HTTP can be used to request such signature, depending on what is provided by the service used. Anyone with the document and the signature can then verify that the document matches the signature by creating their own hash and checking the signature using the trusted third party public key. There are several commercial services around providing such timestamping. A quick search for "rfc 3161 service" pointed me to at least DigiStamp, Quo Vadis, Global Sign and Global Trust Finder. The system work as long as the private key of the trusted third party is not compromised. But as far as I can tell, there are very few public trusted timestamp services available for everyone. I've been looking for one for a while now. But yesterday I found one over at Deutches Forschungsnetz mentioned in a blog by David M ller. I then found a good recipe on how to use the service over at the University of Greifswald. The OpenSSL library contain both server and tools to use and set up your own signing service. See the ts(1SSL), tsget(1SSL) manual pages for more details. The following shell script demonstrate how to extract a signed timestamp for any file on the disk in a Debian environment:
#!/bin/sh
set -e
url="http://zeitstempel.dfn.de"
caurl="https://pki.pca.dfn.de/global-services-ca/pub/cacert/chain.txt"
reqfile=$(mktemp -t tmp.XXXXXXXXXX.tsq)
resfile=$(mktemp -t tmp.XXXXXXXXXX.tsr)
cafile=chain.txt
if [ ! -f $cafile ] ; then
    wget -O $cafile "$caurl"
fi
openssl ts -query -data "$1" -cert   tee "$reqfile" \
      /usr/lib/ssl/misc/tsget -h "$url" -o "$resfile"
openssl ts -reply -in "$resfile" -text 1>&2
openssl ts -verify -data "$1" -in "$resfile" -CAfile "$cafile" 1>&2
base64 < "$resfile"
rm "$reqfile" "$resfile"
The argument to the script is the file to timestamp, and the output is a base64 encoded version of the signature to STDOUT and details about the signature to STDERR. Note that due to a bug in the tsget script, you might need to modify the included script and remove the last line. Or just write your own HTTP uploader using curl. :) Now you too can prove and verify that files have not been changed. But the Internet need more public trusted timestamp services. Perhaps something for Uninett or my work place the University of Oslo to set up?

Russell Coker: Nexus5 Armourdillo Hybrid Case

back of case showing both layersfront of casecase standshowing the mirror surface of the Nexus 5 I ve just been given an Armourdillo Hybrid case for the Nexus 5 [1] to review. The above pictures show the back of the case, the front of the case, the stand, and the front of the case with the screen blank. When I first photographed the case the camera focused on a reflection of the window, I include that picture for amusement and to demonstrate how reflective the phone screen is. This case is very hard, the green plastic is the soft inner layer which is still harder than the plastic in a typical gel case . The black part is polycarbonate which is very hard and also a little slippery. The case is designed with lots of bumps for grip (a little like the sole of a running shoe) so it s not likely to slip out of your hand. But the polycarbonate slides easily on plastic surfaces such as the dash of a car. It s fortunate that modern cars have lots of cup holders that can be used for holding a phone. I haven t dropped the phone since getting the new case, but I expect that the combination of a hard outer shell and a slightly softer inner shell (to cushion the impact) will protect it well. All the edges of the case extend above the screen so dropping the phone face down on a hard flat surface shouldn t cause any damage. The black part has a stand for propping the phone on it s side to watch a movie. The stand is very solid and is in the ideal position for use on soft surfaces such as a doona or pillow for watching TV in bed. Appearance This case is mostly designed to protect the phone and the bumps that are used for grip detract from the appearance IMHO. I think that the Ringke Fusion case for my Nexus 4 [2] looks much better, it s a trade-off between appearance and functionality. My main criteria for this case were good protection (better than a gel case) and small size (not one of the heavy waterproof cases). It was a bonus to get a green case for the Enlightened team in Ingress. NB Armourdillo also offers a blue case for the Resistance team in Ingress as well as other colors. MobileZap also have a number of other cases for the Nexus 5 [3].

Andrew Pollock: [life] Day 56, Kindergarten, rain, taxes

There was quite the torrential downpour overnight. It woke me up, and it woke Zoe up too, and at about 1:45am she ended up in bed with me. I think she managed to invent a new baby sleep position, where she was on my pillow, perpendicular to me along the bed head, and had somehow ejected the pillow that was on her side of the bed. We got up, with a slow start, and the weather was still looking a bit dicey, so Zoe wanted to go to Kindergarten by car. That actually meant we were the first ones there, because I'd been working to a timetable of leaving home by bike. One of the chickens was starting to hatch (and subsequently hatched around noon) so that was exciting. Funnily enough, Zoe had spent all morning telling me how she didn't want to go to Kindergarten, but by the time we got there, she didn't seem to mind being there all that much. After I got home from Kindergarten, I biked down to Bulimba to go to the bank to finalise opening my business bank accounts. I've since discovered that one can't do much without an ABN, I can't even get a cheque book, so I've sicked my accountant on that one for me. I got stuck into my US taxes some more today, and made a very satisfactory amount of progress on them. I think I should be able to finish them off in the next session I get to work on them. I felt like getting out of the house after that. It was looking quite like rain again, making picking up Zoe by bike out, so I ran a few errands in the car before getting to Kindergarten quite early. Zoe was fast asleep, but I let her have a long, slow wake up, and that made our departure much easier. She got to have a little hold of one of the baby chicks before we left. Today I learned that baby chicks smell absolutely divine. We got home, and Zoe did some self-directed craft for a bit, and then wanted to play hide and seek, so we did that and finally got around to looking at all of the Woolworths DreamWorks Heroes cards she's been collecting. I was disappointed to discover there's only a single card per pack, so that's going to mean I have to spend at least $840 on groceries, excluding duplicates, before we get all of them. I'm glad the checkout operators aren't sticking to the rules and are handing them out a little more generously than that. After that, we did a bit more rough and tumble play, and then it was time to start making dinner, so Zoe watched a DVD. We got dinner out of the way relatively early, so I practiced plaiting her hair (I've surprised myself with the half-decent job I can do) and then did bath time and bed time. Bed time was a little protracted (she didn't like her bedroom and wanted to sleep in my bed) but otherwise seems to have gone smoothly.

Sylvain Le Gall: Release of OASIS 0.4.3

I am happy to announce the release of OASIS v0.4.3. Logo OASIS small OASIS is a tool to help OCaml developers to integrate configure, build and install systems in their projects. It should help to create standard entry points in the source code build system, allowing external tools to analyse projects easily. This tool is freely inspired by Cabal which is the same kind of tool for Haskell. You can find the new release here and the changelog here. More information about OASIS in general on the OASIS website. Here is a quick summary of the important changes: Features: This new version closes 4 bugs, mostly related to parsing of _oasis. It also includes a lot of refactoring to improve the overall quality of OASIS code base. The big project for the next release will be to setup a Windows host for regular build and test on this platform. I plan to use WODI for this setup. I would like to thanks again the contributor for this release: David Allsopp, Martin Keegan and Jacques-Pascal Deplaix. Their help is greatly appreciated.

24 March 2014

Andrew Shadura: Tired of autotools? Try this: mk-configure

mk-configure is a project which tries to be autotools done right. Instead of supporting an exceedingly large number of platforms, modern and ancient, at costs of generated unreadable multi-kilobyte shell scripts, mk-configure aims at better support of less platforms, but those which are really in use today. One of the main differences of this project is that it avoids code generation as much as possible. The author of mk-configure, Aleksey Cheusov, a NetBSD hacker from Belarus, uses NetBSD make (bmake) and shell script snippets instead of monstrous libraries written in m4 interleaved with shell scripts. As the result, there s no need in a separate step of package configuration or bootstrapping the configure script, everything is done by just running bmake, or a convenience wrapper for it, mkcmake, which prepends a proper library path to bmake arguments, so you don t have to specify it yourself. Today, mk-configure is already powerful enough to be able replace autotools for most of the projects, and what is missing from it can be easily done by hacking the Makefile, which would otherwise be quite simple. Try it for your project, you may really like it. I already did. And report bugs.

Michael Prokop: kamailio-deb-jenkins: Open Source Jenkins setup for Debian Packaging

Kamailio is an Open Source SIP Server. Since beginning of March 2014 a new setup for Kamailio s Debian packages is available. Development of this setup is sponsored by Sipwise and I am responsible for its infrastructure part (Jenkins, EC2, jenkins-debian-glue). The setup includes support for building Debian packages for Debian 5 (lenny), 6 (squeeze), 7 (wheezy) and 8 (jessie) as well as Ubuntu 10.04 (lucid) and 12.04 (precise), all of them architectures amd64 and i386. My work is fully open sourced. Deployment instructions, scripts and configuration are available at kamailio-deb-jenkins, so if you re interested in setting up your own infrastructure for Continuous Integration with Debian/Ubuntu packages that s a very decent starting point. NOTE: I ll be giving a talk about Continuous Integration with Debian/Ubuntu packages at Linuxdays Graz/Austria on 5th of April. Besides kamailio-deb-jenkins I ll also cover best practices, Debian packaging, EC2 autoscaling,

Michael Prokop: Building Debian+Ubuntu packages on EC2

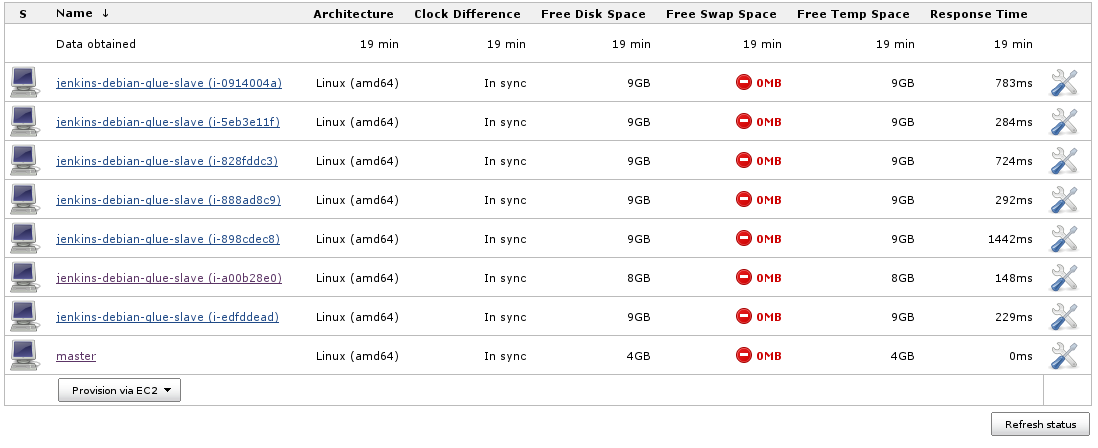
In a project I recently worked on we wanted to provide a jenkins-debian-glue based setup on Amazon s EC2 for building Debian and Ubuntu packages. The idea is to keep a not-so-strong powered Jenkins master up and running 24 7, while stronger machines serving as Jenkins slaves should be launched only as needed. The project setup in question is fully open sourced (more on that in a separate blog post), hereby I am documenting the EC2 setup in usage. Jenkins master vs. slave Debian source packages are generated on Jenkins master where a checkout of the Git repository resides. The Jenkins slaves do the actual workload by building the binary packages and executing piuparts (.deb package installation, upgrading, and removal testing tool) on the resulting binary packages. The Debian packages (source+binaries) are then provided back to Jenkins master and put into a reprepro powered Debian repository for public usage. Preparation The starting point was one of the official Debian AMIs (x86_64, paravirtual on EBS). We automatically deployed jenkins-debian-glue on the system which is used as Jenkins master (we chose a m1.small instance for our needs). We started another instance, slightly adjusted it to already include jenkins-debian-glue related stuff out-of-the-box (more details in section Reduce build time below) and created an AMI out of it. This new AMI ID can be configured for usage inside Jenkins by using the Amazon EC2 Plugin (see screenshot below). IAM policy Before configuring EC2 in Jenkins though start by adding a new user (or group) in AWS s IAM (Identity and Access Management) with a custom policy. This ensures that your EC2 user in Jenkins doesn t have more permissions than really needed. The following policy should give you a starting point (we restrict the account to allow actions only in the EC2 region eu-west-1, YMMV):
 
  "Version": "2012-10-17",
  "Statement": [
     
      "Action": [
        "ec2:CreateTags",
        "ec2:DescribeInstances",
        "ec2:DescribeImages",
        "ec2:DescribeKeyPairs",
        "ec2:GetConsoleOutput",
        "ec2:RunInstances",
        "ec2:StartInstances",
        "ec2:StopInstances",
        "ec2:TerminateInstances"
      ],
      "Effect": "Allow",
      "Resource": "*",
            "Condition":  
                "StringEquals":  
                    "ec2:Region": "eu-west-1"


  ]
 
Jenkins configuration Configure EC2 access with Access Key ID , Secret Access Key , Region and EC2 Key Pair s Private Key (for SSH login) inside Jenkins in the Cloud section on $YOUR_JENKINS_SERVER/configure. Finally add an AMI in the AMIs Amazon EC2 configuration section (adjust security-group as needed, SSH access is enough): As you can see the configuration also includes a launch script. This script ensures that slaves are set up as needed (provide all the packages and scripts that are required for building) and always get the latest configuration and scripts before starting to serve as Jenkins slave. Now your setup should be ready for launching Jenkins slaves as needed: NOTE: you can use the Instance Cap configuration inside the advanced Amazon EC2 Jenkins configuration section to place an upward limit to the number of EC2 instances that Jenkins may launch. This can be useful for avoiding surprises in your AWS invoices. :) Notice though that the cap numbers are calculated for all your running EC2 instances, so be aware if you have further machines running under your account, you might want to e.g. further restrict your IAM policy then. Reduce build time Using a plain Debian AMI and automatically installing jenkins-debian-glue and further jenkins-debian-glue-buildenv* packages on each slave startup would work but it takes time. That s why we created our own AMI which is nothing else than an official Debian AMI with the bootstrap.sh script (which is referred to in the screenshot above) already executed. All the necessary packages are pre-installed and also all the cowbuilder environments are already present then. From time to time we start the instance again to apply (security) updates and execute the bootstrap script with its &dash&dashupdate option to also have all the cowbuilder systems up2date. Creating a new AMI is a no-brainer and we can then use the up2date system for our Jenkins slaves, if something should break for whatever reason we can still fall back to an older known-to-be-good AMI. Final words How to set up your Jenkins jobs for optimal master/slave usage, multi-distribution support (Debian/Ubuntu) and further details about this setup are part of another blog post. Thanks to Andreas Granig, Victor Seva and Bernhard Miklautz for reading drafts of this.
Elena 'valhalla' Grandi: Moving away from google services, step N out of M

For years, I've used a gmail account to subscribe to public mailing lists because it was convenient, it had excellent spam filtering and since the lists were already available on google-indexed public archive I felt that there was no real privacy issue.
I already have a local copy of every message in the account, in case I lose access to it for some random reason, and my real contacts already know and use my other email address(es), so I'm not really worried about continuing to use gmail for this kind of traffic.

When I started contributing to Debian I also used that email address, because I was already subscribed to a few mailing lists under it, and it was going to end up being used on the BTS and other spam-attracting public places like that, but I was less happy with the choice.

Lately, however, gmail's spam filters have started to behave oddly, with lots of false positives including a number of messages from @debian.org addresses, and this basically removes the main reason why I was using gmail in the first place, so I'm seriously considering dropping it also for publicly indicized communications.

My first step, right before leaving for Barcelona was to create a couple other email addresses, one for mailing lists and the other for debian-related work, and add them to my gpg/OpenPGP key, so that any new signature on them from the conf would also include the new UIDs.

If you've received a badly signed message (thanks heirloom mailix for mangling stuff :) ) followed by an hopefully correctly signed one where I was asking you to sign new UIDs, and you were wondering, this is the reason.

Now that the new UIDs have been signed by a few DDs I'm going to start using the new address in Debian: I believe I have changed it everywhere I needed to, except for the maintainer/uploader field for my packages, where it will change on their next uploads.

As for mailing lists, I still don't know how to proceed: I could proceed in a systematic way, but I'm lazy and I will probably just change a few main subscriptions, use the new address for new subscriptions and then migrate the rest a few at a time, unless some other event happens and I'll have to hurriedly migrate everything or risk losing important messages. Even in the latter case, I don't need any information that is only stored on google's servers, so I won't will panic just a bit :)

Now, where did I put that documentation about xmpp servers?

Michal &#268;iha&#345;: GSoC 2014 applications for phpMyAdmin

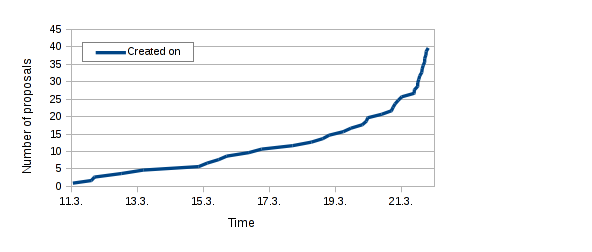
As usual, I look at the application stats for phpMyAdmin just after student application period of Google Summer of Code is over. First of all we got more proposals than in last years, this time there is way more students from India and discussions on mentors lists shows this is quite similar for other projects. Maybe it's just different timing which works better for students there, but there might be different reasons as well. There is also quite low number of spam or bogus proposals. Same as in past years, people leave the submission to the last moment, even though we encourage them to submit early so that they can adjust the application based on our feedback. Number of applications over time Anyway we're just working on evaluation and will finalize it in upcoming days. Of course you will know the results from Google on April 21st.

Filed under: English phpMyAdmin 0 comments Flattr this!

Steve Kemp: So I failed at writing some clustered code in Perl

Until this time next month I'll be posting code-based discussions only. Recently I've been wanting to explore creating clustered services, because clusters are definitely things I use professionally. My initial attempt was to write an auto-clustering version of memcached, because that's a useful tool. Writing the core of the service took an hour or so: At the point I was done the following code worked:
use KeyVal;
# Create an object, and set some values
my $obj = KeyVal->new( logfile => "/tmp/foo.log" );
$obj->incr( "steve" );
print $obj->get( "steve" ) # prints 2.
# Now replay the append-only log
my $replay = KeyVal->new( logfile => "/tmp/foo.log" );
$replay->replay();
print $replay->get( "steve" ) # prints 2.
In the first case we used the primitives to increment a value twice, and then fetch it. In the second case we used the logfile the first object created to replay all prior transactions, then output the value. Neat. The next step was to make it work over a network. Trivial. Finally I wanted to autodetect peers, and deploy replication. Each host would send out regular messages along the lines of "Do you have updates made since $time?". Any that did would replay the logfile from the given unixtime offset. However here I ran into problems. Peer discovery was supposed to be basic, and I figured I'd write something that did leader election by magic. Unfortunately Perls threading code is .. unpleasant: This failed. Majorly. Because you cannot launch the implementation of a class-method as a thread. Equally you cannot make a variable which is "complex" shared across threads. I wrote some demo code which works without packages and a shared singleton: The Ruby version, by contrast, is much more OO and neater. Meh. I've now shelved the project. My next, big, task was to make the network service utterly memcached compatible. That would have been fiddly, but not impossible. Right now I just use a simple line-based network protocol. I suspect I could have got what I wanted using EventMachine, or similar, but that's a path I've not yet explored, and I'm happy enough with that decision.

Andrew Pollock: [life] Day 55, Kindergarten, run, Debian

I got up this morning with the intent of knocking out a 10km run. I managed to last 8km today, so it's an improvement, but I don't know what's up with my running fitness at the moment. After that, I pretty much did Debian stuff all day. I managed an upload of dstat and found a potential security bug in another of my packages when I was trying to update it, so I raised that issue with the package's upstream. I also mostly sorted out opening a bank account for my company. I just have to visit the branch in person tomorrow. Sarah had indicated to me that Zoe had slept poorly last night, on top of a big weekend, and that I should probably pick her up in the car, so I drove to Kindergarten expecting to find her fast asleep and not take too kindly to being woken. Instead, she was wide awake, not having napped at all. The highlight of her day was they had some baby chickens at Kindergarten. They had four day-old hatchlings, with more eggs in an incubator. Megan wanted Zoe to have a coffee with her, so we stopped at the local coffee shop, with her Dad and little sister, for a babyccino on the way home. I had a pretty big weekend away, and didn't feel up to doing the grocery shopping yesterday afternoon when I got home, so we went to the supermarket on the way home to do the weekly grocery shop. After we got home, I got stuck into making dinner while Zoe watched TV. My girlfriend came around after work and joined us for dinner, and the three of us had a nice dinner together. Zoe started showing signs of being particularly tired during dinner, and was a bit uncooperative around bath time, but we got through it all, and I managed to get her down to bed a little bit early, and she fell asleep without too much trouble. It's a fairly warm night. Hopefully she'll sleep well.

Russ Allbery: Term::ANSIColor 4.03

This is a fairly small Perl module that provides a more convenient interface to the ANSI color escape sequences. The primary change in this release is interesting for me but not so much for anyone else. It's the first of my core Perl modules that I've converted to Module::Build and to the new Perl test infrastructure that's now maintained in rra-c-util. (Yes, I know that Module::Build is apparently going to be dropped from Perl core, but the package also generates a Makefile.PL for backward compatibility.) Starting with this release, all my subsequent package releases will start using the Lancaster Consensus environment variables to control whether to run non-default tests (namely AUTOMATED_TESTING, RELEASE_TESTING, and AUTHOR_TESTING). Hopefully this won't cause me too many problems. I'm currently setting AUTHOR_TESTING unconditionally, since I really want to see the results of those tests for all my code, but it's possible that will cause me too many problems with other people's code. (It would have been nice if the spec for AUTHOR_TESTING would let you set the value of the variable to the identity of the author whose tests you want run.) I like having all my release tests run by automated testing so that I can identify any problems with the code to conditionally skip them, so I enable all the release tests when AUTOMATED_TESTING is set. This is probably peculiar to me. The other changes in this release are all documentation and test suite fixes. There are no code changes in this release. Thanks to Olivier Mengu and David Steinbrunner for various bug reports. You can get the latest release from the Term::ANSIColor distribution page.

23 March 2014

Gregor Herrmann: RC bugs 2013/49 - 2014/12

since people keep talking to me about my RC bug fixing activities, I thought it might be time again for a short report. to be honest, I mostly stopped my almost daily work at some point in december, partly because the overall number of RC bugs affecting both testing & unstable is quite low (& therefore the number of easy-to-fix bugs), due to the auto-removal policy of the release team (kudos!). but I still kept track about RC bugs I worked on, & here's the list; as you can see, mostly pkg-perl bugs ps: the how-can-i-help package is a nice tool for finding RC bugs in packages you care about. install it if you haven't so far!
Dominique Dumont: Easier Lcdproc package upgrade with automatic configuration merge

Hello This blog explains how next lcdproc package provide easier upgrader with automatic configuration merge. Here s the current situation: lcdproc is shipped with several configuration files, including /etc/LCDd.conf. This file is modified upstream at every lcdproc release to bring configuration for new lcdproc drivers. On the other hand, this file is always customized to suit the specific hardware of the user s system. So upgrading a package will always lead to a conflict during upgrade. User will always be required to choose whether to use current version or upstream version. Next version of libconfig-model-lcdproc-perl will propose user whether to perform automatic merge of the configuration: upstream change are taken into account while preserving user change. The configuration upgrade shown is based on Config::Model can be applied to other package. Current lcdproc situation To function properly, lcdproc configuration must always be adapted to suit the user s hardware. On the following upgrade, upstream configuration is often updated so user will often be shown this question:
Configuration file '/etc/LCDd.conf'
 ==> Modified (by you or by a script) since installation.
 ==> Package distributor has shipped an updated version.
   What would you like to do about it ?  Your options are:
    Y or I  : install the package maintainer's version
    N or O  : keep your currently-installed version
      D     : show the differences between the versions
      Z     : start a shell to examine the situation
 The default action is to keep your current version.
*** LCDd.conf (Y/I/N/O/D/Z) [default=N] ?
This question is asked in the middle of an upgrade and can be puzzling for an average user. Next package with automatic merge Starting from lcdproc 0.5.6, the configuration merge is handled automatically by the packaging script with the help of Config::Model::Lcdproc. When lcdproc is upgraded to 0.5.6, the following changes are visible:
* lcdproc depends on libconfig-model-lcdproc-perl
* user is asked once by debconf whether to use automatic configuration upgrades or not.
* no further question are asked (no ucf style questions). For instance, here s an upgrade from lcdproc_0.5.5 to lcdproc_0.5.6:
$ sudo dpkg -i lcdproc_0.5.6-1_amd64.deb 
(Reading database ... 322757 files and directories currently installed.)
Preparing to unpack lcdproc_0.5.6-1_amd64.deb ...
Stopping LCDd: LCDd.
Unpacking lcdproc (0.5.6-1) over (0.5.5-3) ...
Setting up lcdproc (0.5.6-1) ...
Changes applied to lcdproc configuration:
- server ReportToSyslog: '' -> '1' # use standard value
update-rc.d: warning: start and stop actions are no longer supported; falling back to defaults
Starting LCDd: LCDd.
Processing triggers for man-db (2.6.6-1) ...
Note: the automatic upgrade currently applies only to LCDd.conf. The other configuration files of lcdproc are handled the usual way. Other benefits User will also be able to:
* check lcdproc configuration with sudo cme check lcdproc
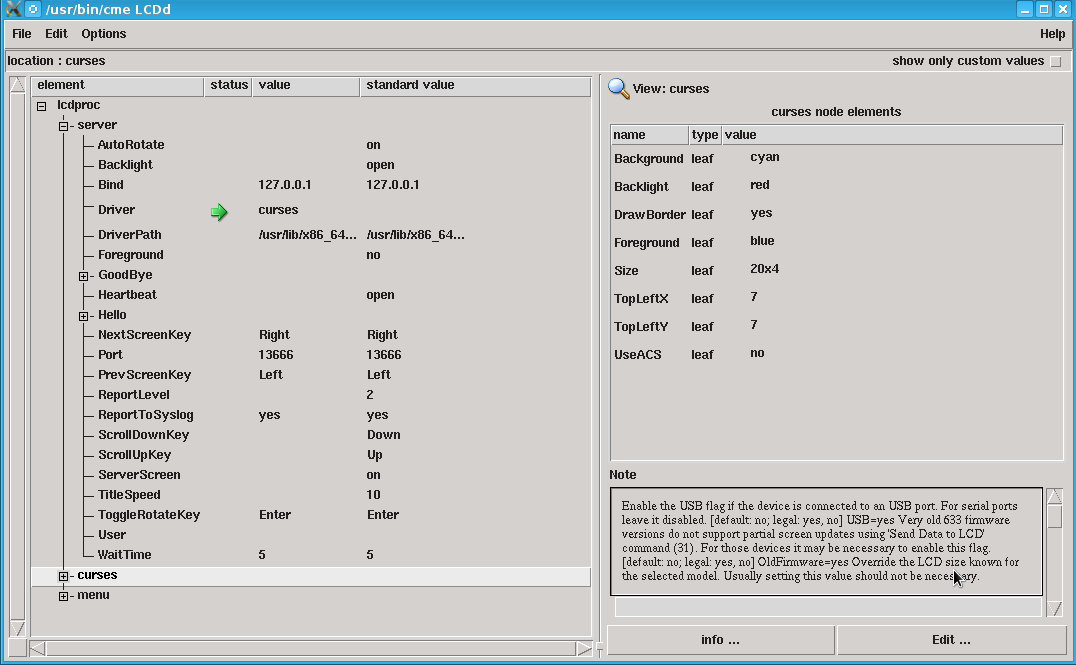
* edit the configuration with a GUI (see Managing Lcdproc configuration with cme for more details) Here s a screenshot of the GUI: GUI to edit lcdproc configuration More information * libconfig-model-lcdproc-perl package page. This package provides a configuration model for lcdproc.
* This blog explains how this model is generated from upstream LCDd.conf.
* How to adapt a package to perform configuration upgrade with Config::Model Next steps Automatic configuration merge can be applied to other packages. But my free time is already taken by the maintenance of Config::Model and the existing models, there s no room for me to take over another package. On the other hand, I will definitely help people who want to provide automatic configuration merge on their packages. Feel free to contact me on:
* config-model-user mailing list
* debian-perl mailing list (where Config::Model is often used to maintain debian package file with cme)
* #debian-perl IRC channel All the best
Tagged: config-model, configuration, debian, Perl, upgrade

Andrew Shadura: ifupdown and command status handling

In 2011, I first tried to fix a Debian bug #547587. The bug was about hook script result codes not being checked, so if a script fails, this isn t detected. Unfortunately, just checking the return code wasn t enough, as lots of scripts didn t care about their return code at all, so I had to unapply the patch. Now, after 2.5 years, I think it s time to try again, as most of the scripts have been fixed since then. At the same time, I ve changed error handling a little bit further: errors in any commands or scripts during interface configuration are considered fatal, but when interface is deconfigured, errors are ignored. However, this may change break configurations which depend on previous behaviour. Please report bugs if you find any.

Niels Thykier: Upcoming changes to Lintian (in 2.5.22)

The next version of Lintian, 2.5.22, is long overdue mostly because 2.5.21 FTBFS in sid. Besides fixing test failures, 2.5.22 also fixes: Besides bug fixes, we also added a couple of new features/nice changes: We just need to do some final tweaks and get the tag descriptions reviewed before we are ready to release the next version.

Russell Coker: Aldi Deserves an Award for Misleading Email

Aldi Mobile has made a significant change to their offerings. They previously had an offer of $35 for unlimited calls and 2.5G of data in a month for which they had to publicly apologise for misleading customers as 2500 minutes of calls a month (83 minutes per day) is no-where near unlimited [1]. They also had an offer of $15 for 2G of data. In an email about this Aldi said Many of our customers are using a lot less than what is included in our current $35 plan. So we will soon be introducing new Value Packs with more flexible options; meaning you only pay for what you really need and they start from just $10. . That is grossly misleading, if they offered new plans in addition to the old ones and allowed customers to choose the plan that is the best match then it would be useful to some customers. But removing the supposedly unlimited plan and the $15 for 2G of data option is removing affordable options for people who want to use their phones for lots of calls or very few calls but moderate amounts of data use. New Plans The base rate for calls on Aldi pre-paid is $0.12 per minute and $0.12 per SMS, consider every mention of minute in this section to be minute or SMS . The Aldi Newplans page [2] starts with a $10 per month plan which offers 100 minutes of calls which would be $12 at the previous rate of $0.12 per minute. That is OK value when compared to just using the pre-paid calls if you consistently use more than 83 minutes of calls per month. However if you don t use 84 minutes of calls (EG you don t speak much on the phone and use Google Hangouts instead of SMS) then it s not good value. Also the advertised data use is $5 per 100MB, which is way below what is needed for a typical user with an Android phone. My mother in law was barely able to stick within a limit of 300MB/month when that was her limit, but while using the Aldo 2G/month bolt-on she s increased her data usage. The smallest of the new plans costs $20 per month, it provides 300 minutes of calls and includes 300MB of data. For an extra $7 you can get another 300MB of data. For my mother in law it seems that the cheapest option on the new plans would be $27 per month, that would cover the 60 minutes of calls she might make and the 450MB of data she s probably using. That s significantly more expensive than her previous cost of $15 for 2G of data and $7.20 for calls and has the additional difficulty that I would have to be more involved in helping her avoid excessive data use. The 2G data bolt-on was really good for some of my relatives, when they use that and configure their phones not to update software over 3G they never had to ask me about any problems related to excess data use. So my mother in law is facing an extra $5 per month (or maybe more depending on data use) and more time spent calling me for tech support. The data bolt on that Aldi is going to offer in future is $30 for 3G of data to replace the previous offer of $15 for 2G of data. The cost will be unchanged for anyone who uses between 2G and 3G a month, for everyone who uses less than 2G or more than 3G the data bolt-on will cost more. There is simply no possibility for any Aldi data-only customer to save on data use. The only way someone who uses a moderate amount of data could save money is if they use more than 160 minutes of calls and less than 1G of data. Disclaimer My analysis above is based on interpreting the Aldi web site. As with most telcos they aren t trying to make things easy in this regard, it seems that the consensus of opinion among telcos is to use complex pricing to make it difficult to compare and reduce competitive pressure. I blame any inaccuracies in my analysis on the Aldi web site. Why Aldi Shouldn t Mislead Customers Aldi isn t primarily a mobile phone company, their main business is running a supermarket. The trust of customers is important to them, raising prices when competition goes away is one thing, but misleading customers about it is another. If Aldi were to honestly say now that Kogan Mobile no longer exists there is nothing forcing us to have low prices then I d have a lot more respect for their company and be more inclined to shop at their supermarket. It s a sad indictment of our society that I need to include a why lying is wrong section in such a blog post.

Next.

Previous.