Search Results: "spa"

12 July 2023

John Goerzen: Backing Up and Archiving to Removable Media: dar vs. git-annex

This is the fourth in a series about archiving to removable media (optical discs such as BD-Rs and DVD+Rs or portable hard drives). Here are the first three parts: I want to state at the outset that this is not a general review of dar or git-annex. This is an analysis of how those tools stack up to a particular use case. Neither tool focuses on this use case, and I note it is particularly far from the more common uses of git-annex. For instance, both tools offer support for cloud storage providers and special support for ssh targets, but neither of those are in-scope for this post. Comparison Matrix As part of this project, I made a comparison matrix which includes not just dar and git-annex, but also backuppc, bacula/bareos, and borg. This may give you some good context, and also some reference for other projects in this general space. Reviewing the Goals I identified some goals in part 1. They are all valid. As I have thought through the project more, I feel like I should condense them into a simpler ordered list, with the first being the most important. I omit some things here that both dar and git-annex can do (updates/incrementals, for instance; see the expanded goals list in part 1). Here they are:
  1. The tool must not modify the source data in any way.
  2. It must be simple to create or update an archive. Processes that require a lot of manual work, are flaky, or are difficult to do correctly, are unlikely to be done correctly and often. If it s easy to do right, I m more likely to do it. Put another way: an archive never created can never be restored.
  3. The chances of a successful restore by someone that is not me, that doesn t know Linux, and is at least 10 years in the future, should be maximized. This implies a simple toolset, solid support for dealing with media errors or missing media, etc.
  4. Both a partial point-in-time restore and a full restore should be possible. The full restore must, at minimum, provide a consistent directory tree; that is, deletions, additions, and moves over time must be accurately reflected. Preserving modification times is a near-requirement, and preserving hard links, symbolic links, and other POSIX metadata is a significant nice-to-have.
  5. There must be a strategy to provide redundancy; for instance, a way for one set of archive discs to be offsite, another onsite, and the two to be periodically swapped.
  6. Use storage space efficiently.
Let s take a look at how the two stack up against these goals. Goal 1: Not modifying source data With dar, this is accomplished. dar --create does not modify source data (and even has a mode to avoid updating atime) so that s done. git-annex normally does modify source data, in that it typically replaces files with symlinks into its hash-indexed storage directory. It can instead use hardlinks. In either case, you will wind up with files that have identical content (but may have originally been separate, non-linked files) linked together with git-annex. This would cause me trouble, as well as run the risk of modifying timestamps. So instead of just storing my data under a git-annex repo as is its most common case, I use the directory special remote with importtree=yes to sort of import the data in. This, plus my desire to have the repos sensible and usable on non-POSIX operating systems, accounts for a chunk of the git-annex complexity you see here. You wouldn t normally see as much complexity with git-annex (though, as you will see, even without the directory special remote, dar still has less complexity). Winner: dar, though I demonstrated a working approach with git-annex as well. Goal 2: Simplicity of creating or updating an archive Let us simply start by recognizing this: Both tools have a lot of power, but I must say, it is easier to wrap my head around what dar is doing than what git-annex is doing. Everything dar does is with files: here are the files to archive, here is an archive file, here is a detached (isolated) catalog. It is very straightforward. It took me far less time to develop my dar page than my git-annex page, despite having existing familiarity with both tools. As I pointed out in part 2, I still don t fully understand how git-annex syncs metadata. Unsolved mysteries from that post include why the two git-annex drives had no idea what was on the other drives, and why the export operation silenty did nothing. Additionally, for the optical disc case, I had to create a restricted-size filesystem/dataset for git-annex to write into in order to get the desired size limit. Looking at the optical disc case, dar has a lot of nice infrastructure built in. With pause and execute, it can very easily be combined with disc burning operations. slice will automatically limit the size of a given slice, regardless of how much disk space is free, meaning that the git-annex tricks of creating smaller filesystems/datasets are unnecessary with dar. To create an initial full backup with dar, you just give it the size of the device, and it will automatically split up the archive, with hooks to integrate for burning or changing drives. About as easy as you could get. With git-annex, you would run the commands to have it fill up the initial filesystem, then burn the disc (or remove the drive), then run the commands to create another repo on the second filesystem, and so forth. With hard drives, with git-annex you would do something similar; let it fill up a repo on a drive, and if it exits with a space error, swap in the next. With dar, you would slice as with an optical disk. Dar s slicing is less convenient in this case, though, as it assumes every drive is the same size and yours may not be. You could work around that by using a slice size no bigger than the smallest drive, and putting multiple slices on larger drives if need be. If a single drive is large enough to hold your entire data set, though, you need not worry about this with either tool. Here s a warning about git-annex: it won t store anything beneath directories named .git. My use case doesn t have many of those. If your use case does, you re going to have to figure out what to do about it. Maybe rename them to something else while the backup runs? In any case, it is simply a fact that git-annex cannot back up git repositories, and this cuts against being able to back up things correctly. Another point is that git-annex has scalability concerns. If your archive set gets into the hundreds of thousands of files, you may need to split it into multiple distinct git-annex repositories. If this occurs and it will in my case it may serve to dull the shine of some of git-annex s features such as location tracking. A detour down the update strategies path Update strategies get a little more complicated with both. First, let s consider: what exactly should our update strategy be? For optical discs, I might consider doing a monthly update. I could burn a disc (or more than one, if needed) regardless of how much data is going to go onto it, because I want no more than a month s data lost in any case. An alternative might be to spool up data until I have a disc s worth, and then write that, but that could possibly mean months between actually burning a disc. Probably not good. For removable drives, we re unlikely to use a new drive each month. So there it makes sense to continue writing to the drive until it s full. Now we have a choice: do we write and preserve each month s updates, or do we eliminate intermediate changes and just keep the most recent data? With both tools, the monthly burn of an optical disc turns out to be very similar to the initial full backup to optical disc. The considerations for spanning multiple discs are the same. With both tools, we would presumably want to keep some metadata on the host so that we don t have to refer to a previous disc to know what was burned. In the dar case, that would be an isolated catalog. For git-annex, it would be a metadata-only repo. I illustrated both of these in parts 2 and 3. Now, for hard drives. Assuming we want to continue preserving each month s updates, with dar, we could just write an incremental to the drive each month. Assuming that the size of the incremental is likely far smaller than the size of the drive, you could easily enough do this. More fancily, you could look at the free space on the drive and tell dar to use that as the size of the first slice. For git-annex, you simply avoid calling drop/dropunused. This will cause the old versions of files to accumulate in .git/annex. You can get at them with git annex commands. This may imply some degree of elevated risk, as you are modifying metadata in the repo each month, which with dar you could chmod a-w or even chattr +i the archive files once written. Hopefully this elevated risk is low. If you don t want to preserve each month s updates, with dar, you could just write an incremental each month that is based on the previous drive s last backup, overwriting the previous. That implies some risk of drive failure during the time the overwrite is happening. Alternatively, you could write an incremental and then use dar to merge it into the previous incremental, creating a new one. This implies some degree of extra space needed (maybe on a different filesystem) while doing this. With git-annex, you would use drop/dropunused as I demonstrated in part 2. The winner for goal 2 is dar. The gap is biggest with optical discs and more narrow with hard drives, thanks to git-annex s different options for updates. Still, I would be more confident I got it right with dar. Goal 3: Greatest chance of successful restore in the distant future If you use git-annex like I suggested in part 2, you will have a set of discs or drives that contain a folder structure with plain files in them. These files can be opened without any additional tools at all. For sheer ability to get at raw data, git-annex has the edge. When you talk about getting a consistent full restore without multiple copies of renamed files or deleted files coming back then you are going to need to use git-annex to do that. Both git-annex and dar provide binaries. Dar provides a win64 version on its Sourceforge page. On the author s releases site, you can find the win64 version in addition to a statically-linked x86_64 version for Linux. The git-annex install page mostly directs you to package managers for your distribution, but the downloads page also lists builds for Linux, Windows, and Mac OS X. The Linux version is dynamic, but ships most of its .so files alongside. The Windows version requires cygwin.dll, and all versions require you to also install git itself. Both tools are in package managers for Mac OS X, Debian, FreeBSD, and so forth. Let s just say that you are likely to be able to run either one on a future Windows or Linux system. There are also GUI frontends for dar, such as DARGUI and gdar. This can increase the chances of a future person being able to use the software easily. git-annex has the assistant, which is based on a different use case and probably not directly helpful here. When it comes to doing the actual restore process using software, dar provides the easier process here. For dealing with media errors and the like, dar can integrate with par2. While technically you could use par2 against the files git-annex writes, that s more cumbersome to manage to the point that it is likely not to be done. Both tools can deal reasonably with missing media entirely. I m going to give the edge on this one to git-annex; while dar does provide the easier restore and superior tools for recovering from media errors, the ability to access raw data as plain files without any tools at all is quite compelling. I believe it is the most critical advantage git-annex has, and it s a big one. Goal 4: Support high-fidelity partial and full restores Both tools make it possible to do a full restore reflecting deletions, additions, and so forth. Dar, as noted, is easier for this, but it is possible with git-annex. So, both can achieve a consistent restore. Part of this goal deals with fidelity of the restore: preserving timestamps, hard and symbolic links, ownership, permissions, etc. Of these, timestamps are the most important for me. git-annex can t do any of that. dar does all of it. Some of this can be worked around using mtree as I documented in part 2. However, that implies a need to also provide mtree on the discs for future users, and I m not sure mtree really exists for Windows. It also cuts against the argument that git-annex discs can be used without any tools. It is true, they can, but all you will get is filename and content; no accurate date. Timestamps are often highly relevant for everything from photos to finding an elusive document or record. Winner: dar. Goal 5: Supporting backup strategies with redundancy My main goal here is to have two separate backup sets: one that is offsite, and one that is onsite. Depending on the strategy and media, they might just always stay that way, or periodically rotate. For instance, with optical discs, you might just burn two copies of every disc and store one at each place. For hard drives, since you will be updating the content of them, you might swap them periodically. This is possible with both tools. With both tools, if using the optical disc scheme I laid out, you can just burn two identical copies of each disc. With the hard drive case, with dar, you can keep two directories of isolated catalogs, one for each drive set. A little identifier file on each drive will let you know which set to use. git-annex can track locations itself. As I demonstrated in part 2, you can make each drive its own repo, add all drives from a given drive set to a git-annex group. When initializing a drive, you tell git-annex what group it s a prt of. From then on, git-annex knows what content is in each group and will add whatever a given drive s group needs to that drive. It s possible to do this with both, but the winner here is git-annex. Goal 6: Efficient use of storage Here are situations in which one or the other will be more efficient: The winner depends on your particular situation. Other notes While not part of the goals above, dar is capable of using tapes directly. While not as common, they are often used in communities of people that archive lots of data. Conclusions Overall, dar is the winner for me. It is simpler in most areas, easier to get correct, and scales very well. git-annex does, however, have some quite compelling points. Being able to access files as plain files is huge, and its location tracking is nicer than dar s, even when using dar_manager. Both tools are excellent and I recommend them both and for more than the particular scenario shown here. Both have fantastic and responsive authors.

11 July 2023

Simon Josefsson: Coping with non-free software in Debian

A personal reflection on how I moved from my Debian home to find two new homes with Trisquel and Guix for my own ethical computing, and while doing so settled my dilemma about further Debian contributions. Debian s contributions to the free software community has been tremendous. Debian was one of the early distributions in the 1990 s that combined the GNU tools (compiler, linker, shell, editor, and a set of Unix tools) with the Linux kernel and published a free software operating system. Back then there were little guidance on how to publish free software binaries, let alone entire operating systems. There was a lack of established community processes and conflict resolution mechanisms, and lack of guiding principles to motivate the work. The community building efforts that came about in parallel with the technical work has resulted in a steady flow of releases over the years. From the work of Richard Stallman and the Free Software Foundation (FSF) during the 1980 s and early 1990 s, there was at the time already an established definition of free software. Inspired by free software definition, and a belief that a social contract helps to build a community and resolve conflicts, Debian s social contract (DSC) with the free software community was published in 1997. The DSC included the Debian Free Software Guidelines (DFSG), which directly led to the Open Source Definition.

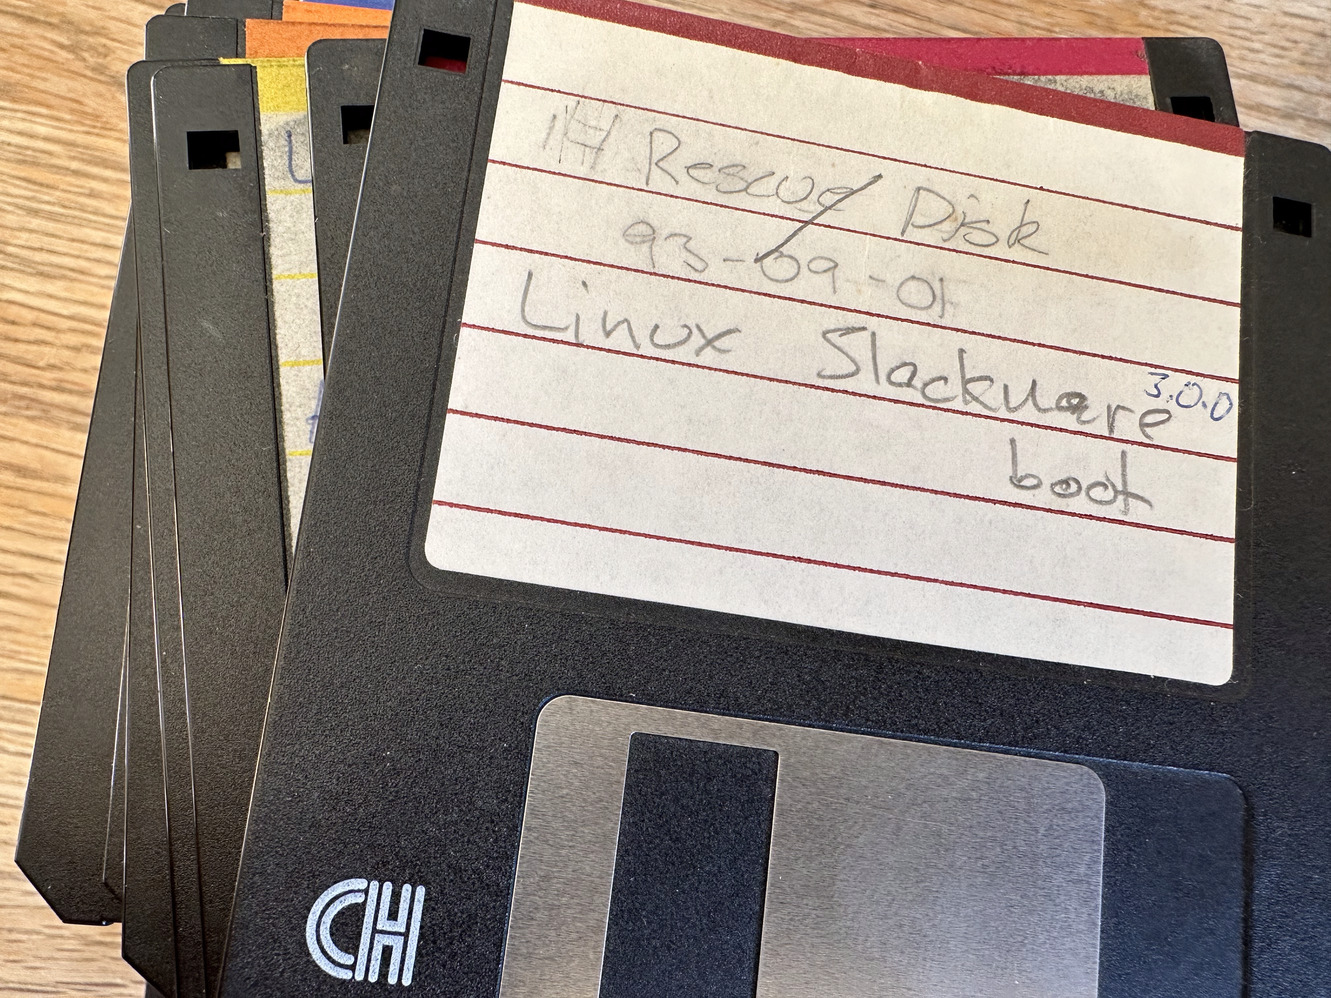
Slackware 3.5" disksOne of my earlier Slackware install disk sets, kept for nostalgic reasons.
I was introduced to GNU/Linux through Slackware in the early 1990 s (oh boy those nights calculating XFree86 modeline s and debugging sendmail.cf) and primarily used RedHat Linux during ca 1995-2003. I switched to Debian during the Woody release cycles, when the original RedHat Linux was abandoned and Fedora launched. It was Debian s explicit community processes and infrastructure that attracted me. The slow nature of community processes also kept me using RedHat for so long: centralized and dogmatic decision processes often produce quick and effective outcomes, and in my opinion RedHat Linux was technically better than Debian ca 1995-2003. However the RedHat model was not sustainable, and resulted in the RedHat vs Fedora split. Debian catched up, and reached technical stability once its community processes had been grounded. I started participating in the Debian community around late 2006. My interpretation of Debian s social contract is that Debian should be a distribution of works licensed 100% under a free license. The Debian community has always been inclusive towards non-free software, creating the contrib/non-free section and permitting use of the bug tracker to help resolve issues with non-free works. This is all explained in the social contract. There has always been a clear boundary between free and non-free work, and there has been a commitment that the Debian system itself would be 100% free. The concern that RedHat Linux was not 100% free software was not critical to me at the time: I primarily (and happily) ran GNU tools on Solaris, IRIX, AIX, OS/2, Windows etc. Running GNU tools on RedHat Linux was an improvement, and I hadn t realized it was possible to get rid of all non-free software on my own primary machine. Debian realized that goal for me. I ve been a believer in that model ever since. I can use Solaris, macOS, Android etc knowing that I have the option of using a 100% free Debian. While the inclusive approach towards non-free software invite and deserve criticism (some argue that being inclusive to non-inclusive behavior is a bad idea), I believe that Debian s approach was a successful survival technique: by being inclusive to and a compromise between free and non-free communities, Debian has been able to stay relevant and contribute to both environments. If Debian had not served and contributed to the free community, I believe free software people would have stopped contributing. If Debian had rejected non-free works completely, I don t think the successful Ubuntu distribution would have been based on Debian. I wrote the majority of the text above back in September 2022, intending to post it as a way to argue for my proposal to maintain the status quo within Debian. I didn t post it because I felt I was saying the obvious, and that the obvious do not need to be repeated, and the rest of the post was just me going down memory lane. The Debian project has been a sustainable producer of a 100% free OS up until Debian 11 bullseye. In the resolution on non-free firmware the community decided to leave the model that had resulted in a 100% free Debian for so long. The goal of Debian is no longer to publish a 100% free operating system, instead this was added: The Debian official media may include firmware . Indeed the Debian 12 bookworm release has confirmed that this would not only be an optional possibility. The Debian community could have published a 100% free Debian, in parallel with the non-free Debian, and still be consistent with their newly adopted policy, but chose not to. The result is that Debian s policies are not consistent with their actions. It doesn t make sense to claim that Debian is 100% free when the Debian installer contains non-free software. Actions speaks louder than words, so I m left reading the policies as well-intended prose that is no longer used for guidance, but for the peace of mind for people living in ivory towers. And to attract funding, I suppose. So how to deal with this, on a personal level? I did not have an answer to that back in October 2022 after the vote. It wasn t clear to me that I would ever want to contribute to Debian under the new social contract that promoted non-free software. I went on vacation from any Debian work. Meanwhile Debian 12 bookworm was released, confirming my fears. I kept coming back to this text, and my only take-away was that it would be unethical for me to use Debian on my machines. Letting actions speak for themselves, I switched to PureOS on my main laptop during October, barely noticing any difference since it is based on Debian 11 bullseye. Back in December, I bought a new laptop and tried Trisquel and Guix on it, as they promise a migration path towards ppc64el that PureOS do not. While I pondered how to approach my modest Debian contributions, I set out to learn Trisquel and gained trust in it. I migrated one Debian machine after another to Trisquel, and started to use Guix on others. Migration was easy because Trisquel is based on Ubuntu which is based on Debian. Using Guix has its challenges, but I enjoy its coherant documented environment. All of my essential self-hosted servers (VM hosts, DNS, e-mail, WWW, Nextcloud, CI/CD builders, backup etc) uses Trisquel or Guix now. I ve migrated many GitLab CI/CD rules to use Trisquel instead of Debian, to have a more ethical computing base for software development and deployment. I wish there were official Guix docker images around. Time has passed, and when I now think about any Debian contributions, I m a little less muddled by my disappointment of the exclusion of a 100% free Debian. I realize that today I can use Debian in the same way that I use macOS, Android, RHEL or Ubuntu. And what prevents me from contributing to free software on those platforms? So I will make the occasional Debian contribution again, knowing that it will also indirectly improve Trisquel. To avoid having to install Debian, I need a development environment in Trisquel that allows me to build Debian packages. I have found a recipe for doing this: # System commands:
sudo apt-get install debhelper git-buildpackage debian-archive-keyring
sudo wget -O /usr/share/debootstrap/scripts/debian-common https://sources.debian.org/data/main/d/debootstrap/1.0.128%2Bnmu2/scripts/debian-common
sudo wget -O /usr/share/debootstrap/scripts/sid https://sources.debian.org/data/main/d/debootstrap/1.0.128%2Bnmu2/scripts/sid
# Run once to create build image:
DIST=sid git-pbuilder create --mirror http://deb.debian.org/debian/ --debootstrapopts "--exclude=usr-is-merged" --basepath /var/cache/pbuilder/base-sid.cow
# Run in a directory with debian/ to build a package:
gbp buildpackage --git-pbuilder --git-dist=sid
How to sustainably deliver a 100% free software binary distributions seems like an open question, and the challenges are not all that different compared to the 1990 s or early 2000 s. I m hoping Debian will come back to provide a 100% free platform, but my fear is that Debian will compromise even further on the free software ideals rather than the opposite. With similar arguments that were used to add the non-free firmware, Debian could compromise the free software spirit of the Linux boot process (e.g., non-free boot images signed by Debian) and media handling (e.g., web browsers and DRM), as Debian have already done with appstore-like functionality for non-free software (Python pip). To learn about other freedom issues in Debian packaging, browsing Trisquel s helper scripts may enlight you. Debian s setback and the recent setback for RHEL-derived distributions are sad, and it will be a challenge for these communities to find internally consistent coherency going forward. I wish them the best of luck, as Debian and RHEL are important for the wider free software eco-system. Let s see how the community around Trisquel, Guix and the other FSDG-distributions evolve in the future. The situation for free software today appears better than it was years ago regardless of Debian and RHEL s setbacks though, which is important to remember! I don t recall being able install a 100% free OS on a modern laptop and modern server as easily as I am able to do today. Happy Hacking! Addendum 22 July 2023: The original title of this post was Coping with non-free Debian, and there was a thread about it that included feedback on the title. I do agree that my initial title was confrontational, and I ve changed it to the more specific Coping with non-free software in Debian. I do appreciate all the fine free software that goes into Debian, and hope that this will continue and improve, although I have doubts given the opinions expressed by the majority of developers. For the philosophically inclined, it is interesting to think about what it means to say that a compilation of software is freely licensed. At what point does a compilation of software deserve the labels free vs non-free? Windows probably contains some software that is published as free software, let s say Windows is 1% free. Apple authors a lot of free software (as a tangent, Apple probably produce more free software than what Debian as an organization produces), and let s say macOS contains 20% free software. Solaris (or some still maintained derivative like OpenIndiana) is mostly freely licensed these days, isn t it? Let s say it is 80% free. Ubuntu and RHEL pushes that closer to let s say 95% free software. Debian used to be 100% but is now slightly less at maybe 99%. Trisquel and Guix are at 100%. At what point is it reasonable to call a compilation free? Does Debian deserve to be called freely licensed? Does macOS? Is it even possible to use these labels for compilations in any meaningful way? All numbers just taken from thin air. It isn t even clear how this can be measured (binary bytes? lines of code? CPU cycles? etc). The caveat about license review mistakes applies. I ignore Debian s own claims that Debian is 100% free software, which I believe is inconsistent and no longer true under any reasonable objective analysis. It was not true before the firmware vote since Debian ships with non-free blobs in the Linux kernel for example.

10 July 2023

Shirish Agarwal: PLIO, Mum, Debconf, Pressure Cooker, RISC-V,

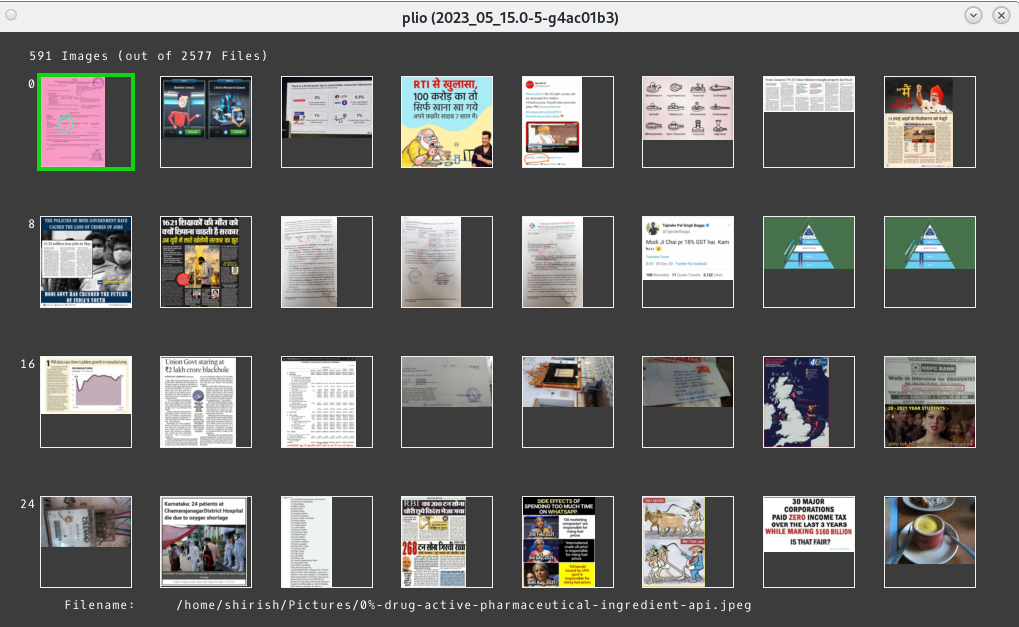
PLIO I have been looking for an image viewer that can view images via modification date by default. The newer, the better. Alas, most of the image viewers do not do that. Even feh somehow fails. What I need is default listing of images as thumbnails by modification date. I put it up on Unix Stackexchange couple of years ago. Somebody shared ristretto but that just gives listing and doesn t give the way I want it. To be more illustrative, maybe this may serve as a guide to what I mean.
There is an RFP for it. While playing with it, I also discovered another benefit of the viewer, a sort of side-benefit, it tells you if any images have gone corrupt or whatever and you get that info. on the CLI so you can try viewing that image with the path using another viewer or viewers before deleting them. One of the issues is there doesn t seem to be a magnify option by default. While the documentation says use the ^ key to maximize it, it doesn t maximize. Took me a while to find it as that isn t a key that I use most of the time. Ironically, that is the key used on the mobile quite a bit. Anyways, so that needs to be fixed. Sadly, it doesn t have creation date or modification date sort, although the documentation does say it does (at least the modification date) but it doesn t show at my end. I also got Warning: UNKNOWN command detected! but that doesn t tell me enough as to what the issue is. Hopefully the developer will fix the issues and it will become part of Debian as many such projects are. Compiling was dead easy even with gcc-12 once I got freeimage-dev.

Mum s first death anniversary I do not know where the year went by or how. The day went in a sort of suspended animation. The only thing I did was eat and sleep that day, didn t feel like doing anything. Old memories, even dreams of fighting with her only to realize in the dream itself it s fake, she isn t there anymore  Something that can never be fixed

Debconf Kochi I should have shared it few days ago but somehow slipped my mind. While it s too late for most people to ask for bursary for Debconf Kochi, if you are anywhere near Kochi in the month of September between the dates. September 3 to September 17 nearby Infopark, Kochi you could walk in and talk to people. This would be for people who either have an interest in free software, FOSS or Debian specific. For those who may not know, while Debian is a Linux Distribution having ports to other kernels as well as well as hardware. While I may not be able to provide the list of all the various flavors as well as hardware, can say it is quite a bit. For e.g. there is a port to RISC-V that was done few years back (2018). Why that is needed will be shared below. There is always something new to look forward in a Debconf.

Pressure Cooker and Potatoes This was asked to me in the last Debconf (2016) by few people. So as people are coming to India, it probably is a good time to sort of reignite the topic :). So a Pressure Cooker boils your veggies and whatnot while still preserving the nutrients. While there are quite a number of brands I would suggest either Prestige or Hawkins, I have had good experience with both. There are also some new pressure cookers that have come that are somewhat in the design of the Thai Wok. So if that is something that you are either comfortable with or looking for, you could look at that. One of the things that you have to be sort of aware of and be most particular is the pressure safety valve. Just putting up pressure cooker safety valve in your favorite search-engine should show you different makes and whatnot. While they are relatively cheap, you need to see it is not cracked, used or whatever. The other thing is the Pressure Cooker whistle as well. The easiest thing to cook are mashed potatoes in a pressure cooker. A pressure Cooker comes in Litres, from 1 Ltr. to 20 Ltr. The larger ones are obviously for hotels or whatnot. General rule of using Pressure cooker is have water 1/4th, whatever vegetable or non-veg you want to boil 1/2 and let the remaining part for the steam. Now the easiest thing to do is have wash the potatoes and put 1/4th water of the pressure cooker. Then put 1/2 or less or little bit more of the veggies, in this instance just Potatoes. You can put salt to or that can be done later. The taste will be different. Also, there are various salts so won t really go into it as spices is a rabbit hole. Anyways, after making sure that there is enough space for the steam to be built, Put the handle on the cooker and basically wait for 5-10 minutes for the pressure to be built. You will hear a whistling sound, wait for around 5 minutes or a bit more (depends on many factors, kind of potatoes, weather etc.) and then just let it cool off naturally. After 5-10 minutes or a bit more, the pressure will be off. Your mashed potatoes are ready for either consumption or for further processing. I am assuming gas, induction cooking will have its own temperature, have no idea about it, hence not sharing that. Pressure Cooker, first put on the heaviest settings, once it starts to whistle, put it on medium for 5-10 minutes and then let it cool off. The first time I had tried that, I burned the cooker. You understand things via trial and error.

Poha recipe This is a nice low-cost healthy and fulfilling breakfast called Poha that can be made anytime and requires at the most 10-15 minutes to prepare with minimal fuss. The main ingredient is Poha or flattened rice. So how is it prepared. I won t go into the details of quantity as that is upto how hungry people are. There are various kinds of flattened rice available in the market, what you are looking for is called thick Poha or zhad Poha (in Marathi). The first step is the trickiest. What do you want to do is put water on Poha but not to let it be soggy. There is an accessory similar to tea filter but forgot the name, it basically drains all the extra moisture and you want Poha to be a bit fluffy and not soggy. The Poha should breathe for about 5 minutes before being cooked. To cook, use a heavy bottomed skillet, put some oil in it, depends on what oil you like, again lot of variations, you can use ground nut or whatever oil you prefer. Then use single mustard seeds to check temperature of the oil. Once the mustard seeds starts to pop, it means it s ready for things. So put mustard seeds in, finely chopped onion, finely chopped coriander leaves, a little bit of lemon juice, if you want potatoes, then potatoes too. Be aware that Potatoes will soak oil like anything, so if you are going to have potatoes than the oil should be a bit more. Some people love curry leaves, others don t. I like them quite a bit, it gives a slightly different taste. So the order is
  1. Oil
  2. Mustard seeds (1-2 teaspoon)
  3. Curry leaves 5-10
  4. Onion (2-3 medium onions finely chopped, onion can also be used as garnish.)
  5. Potatoes (2-3 medium ones, mashed)
  6. Small green chillies or 1-2 Red chillies (if you want)
  7. Coriander Leaves (one bunch finely chopped)
  8. Peanuts (half a glass)
Make sure that you are stirring them quite a bit. On a good warm skillet, this should hardly take 5 minutes. Once the onions are slighly brown, you are ready to put Poha in. So put the poha, add turmeric, salt, and sugar. Again depends on number of people. If I made for myself and mum, usually did 1 teaspoon of salt, not even one fourth of turmeric, just a hint, it is for the color, 1 to 2 teapoons of sugar and mix them all well at medium flame. Poha used to be two or three glasses. If you don t want potato, you can fry them a bit separately and garnish with it, along with coriander, coconut and whatnot. In Kerala, there is possibility that people might have it one day or all days. It serves as a snack at anytime, breakfast, lunch, tea time or even dinner if people don t want to be heavy. The first few times I did, I did manage to do everything wrong. So, if things go wrong, let it be. After a while, you will find your own place. And again, this is just one way, I m sure this can be made as elaborate a meal as you want. This is just something you can do if you don t want noodles or are bored with it. The timing is similar. While I don t claim to be an expert in cooking in anyway or form, if people have questions feel free to ask. If you are single or two people, 2 Ltr. Pressure cooker is enough for most Indians, Westerners may take a slightly bit larger Pressure Cooker, maybe a 3 Ltr. one may be good for you. Happy Cooking and Experimenting  I have had the pleasure to have Poha in many ways. One of my favorite ones is when people have actually put tadka on top of Poha. You do everything else but in a slight reverse order. The tadka has all the spices mixed and is concentrated and is put on top of Poha and then mixed. Done right, it tastes out of this world. For those who might not have had the Indian culinary experience, most of which is actually borrowed from the Mughals, you are in for a treat. One of the other things I would suggest to people is to ask people where there can get five types of rice. This is a specialty of South India and a sort of street food. I know where you can get it Hyderabad, Bangalore, Chennai but not in Kerala, although am dead sure there is, just somehow have missed it. If asked, am sure the Kerala team should be able to guide. That s all for now, feeling hungry, having dinner as have been sharing about cooking.

RISC-V There has been lot of conversations about how India could be in the microprocesor spacee. The x86 and x86-64 is all tied up in Intel and AMD so that s a no go area. Let me elaborate a bit why I say that. While most of the people know that IBM was the first producers of transistors as well as microprocessors. Coincidentally, AMD and Intel story are similar in some aspects but not in others. For a long time Intel was a market leader and by hook or crook it remained a market leader. One of the more interesting companies in the 1980s was Cyrix which sold lot of low-end microprocessors. A lot of that technology also went into Via which became a sort of spiritual successor of Cyrix. It is because of Cyrix and Via that Intel was forced to launch the Celeron model of microprocessors.

Lawsuits, European Regulation For those who have been there in the 1990s may have heard the term Wintel that basically meant Microsoft Windows and Intel and they had a sort of monopoly power. While the Americans were sorta ok with it, the Europeans were not and time and time again they forced both Microsoft as well as Intel to provide alternatives. The pushback from the regulators was so great that Intel funded AMD to remain solvent for few years. The successes that we see today from AMD is Lisa Su s but there is a whole lot of history as well as bad blood between the two companies. Lot of lawsuits and whatnot. Lot of cross-licensing agreements between them as well. So for any new country it would need lot of cash just for licensing all the patents there are and it s just not feasible for any newcomer to come in this market as they would have to fork the cash for the design apart from manufacturing fab.

ARM Most of the mobiles today sport an ARM processor. At one time it meant Advanced RISC Machines but now goes by Arm Ltd. Arm itself licenses its designs and while there are lot of customers, you are depending on ARM and they can change any of the conditions anytime they want. You are also hoping that ARM does not steal your design or do anything else with it. And while people trust ARM, it is still a risk if you are a company.

RISC and Shakti There is not much to say about RISC other than this article at Register. While India does have large ambitions, executing it is far trickier than most people believe as well as complex and highly capital intensive. The RISC way could be a game-changer provided India moves deftly ahead. FWIW, Debian did a RISC port in 2018. From what I can tell, you can install it on a VM/QEMU and do stuff. And while RISC has its own niches, you never know what happens next.One can speculate a lot and there is certainly a lot of momentum behind RISC. From what little experience I have had, where India has failed time and time again, whether in software or hardware is support. Support is the key, unless that is not fixed, it will remain a dream  On a slightly sad note, Foxconn is withdrawing from the joint venture it had with Vedanta.

Michael Ablassmeier: Java timezone sheanigans

While running CI tests for a application that is implemented in C and Java, some configuration scripts set the current timezone. The C implemented parts catch the change just nicely, but the java related parts still report the default image timezone. A simple example:
import java.util.*;
import java.text.*;
class simpleTest
 
        public static void main(String args[])
         
           Calendar cal = Calendar.getInstance();
           System.out.println("TIME ZONE :"+ cal.getTimeZone().getDisplayName());
         
 
Result:
vagrant@vm:~$ sudo timedatectl set-timezone America/Aruba 
vagrant@vm:~$ timedatectl 
[..]
                Time zone: America/Aruba (AST, -0400)
[..]
vagrant@vm:~$ java test.java
TIME ZONE :Central European Standard Time
vagrant@vm:~$ ls -alh /etc/localtime 
lrwxrwxrwx 1 root root 35 Jul 10 14:41 /etc/localtime -> ../usr/share/zoneinfo/America/Aruba
It appears the Java implementation uses /etc/timezone as source, not /etc/localtime.
vagrant@vm:~$ echo America/Aruba   sudo tee /etc/timezone 
America/Aruba
vagrant@vm:~$ java test.java
TIME ZONE :Atlantic Standard Time
dpkg-reconfigure tzdata updates this file as well, so using timedatectl only won t be enough (at least not on Debian based systems which run java based applications.)

9 July 2023

Vasudev Kamath: Using LUKS-Encrypted USB Stick with TPM2 Integration

I use a LUKS-encrypted USB stick to store my GPG and SSH keys, which acts as a backup and portable key setup when working on different laptops. One inconvenience with LUKS-encrypted USB sticks is that you need to enter the password every time you want to mount the device, either through a Window Manager like KDE or using the cryptsetup luksOpen command. Fortunately, many laptops nowadays come equipped with TPM2 modules, which can be utilized to automatically decrypt the device and subsequently mount it. In this post, we'll explore the usage of systemd-cryptenroll for this purpose, along with udev rules and a set of scripts to automate the mounting of the encrypted USB. First, ensure that your device has a TPM2 module. You can run the following command to check:
sudo journalctl -k --grep=tpm2
The output should resemble the following:
Jul 08 18:57:32 bhairava kernel: ACPI: SSDT 0x00000000BBEFC000 0003C6 (v02
LENOVO Tpm2Tabl 00001000 INTL 20160422) Jul 08 18:57:32 bhairava kernel:
ACPI: TPM2 0x00000000BBEFB000 000034 (v03 LENOVO TP-R0D 00000830
PTEC 00000002) Jul 08 18:57:32 bhairava kernel: ACPI: Reserving TPM2 table
memory at [mem 0xbbefb000-0xbbefb033]
You can also use the systemd-cryptenroll command to check for the availability of a TPM2 device on your laptop:
systemd-cryptenroll --tpm2-device=list
The output will be something like following:
blog git:(master) systemd-cryptenroll --tpm2-device=list
PATH        DEVICE      DRIVER
/dev/tpmrm0 MSFT0101:00 tpm_tis
   blog git:(master)
Next, ensure that you have connected your encrypted USB device. Note that systemd-cryptenroll only works with LUKS2 and not LUKS1. If your device is LUKS1-encrypted, you may encounter an error while enrolling the device, complaining about the LUKS2 superblock not found. To determine if your device uses a LUKS1 header or LUKS2, use the cryptsetup luksDump <device> command. If it is LUKS1, the header will begin with:
LUKS header information for /dev/sdb1
Version:        1
Cipher name:    aes
Cipher mode:    xts-plain64
Hash spec:      sha256
Payload offset: 4096
Converting from LUKS1 to LUKS2 is a simple process, but for safety, ensure that you backup the header using the cryptsetup luksHeaderBackup command. Once backed up, use the following command to convert the header to LUKS2:
sudo cryptsetup convert --type luks2 /dev/sdb1
After conversion, the header will look like this:
Version:        2
Epoch:          4
Metadata area:  16384 [bytes]
Keyslots area:  2064384 [bytes]
UUID:           000b2670-be4a-41b4-98eb-9adbd12a7616
Label:          (no label)
Subsystem:      (no subsystem)
Flags:          (no flags)
The next step is to enroll the new LUKS key for the encrypted device using systemd-cryptenroll. Run the following command:
sudo systemd-cryptenroll --tpm2-device=/dev/tpmrm0 --tpm2-pcrs="0+7" /dev/sdb1
This command will prompt you to provide the existing key to unseal the device. It will then add a new random key to the volume, allowing it to be unlocked in addition to the existing keys. Additionally, it will bind this new key to PCRs 0 and 7, representing the system firmware and Secure Boot state. If there is only one TPM device on the system, you can use --tpm2-device=auto to automatically select the device. To confirm that the new key has been enrolled, you can dump the LUKS configuration and look for a systemd-tpm2 token entry, as well as an additional entry in the Keyslots section. To test the setup, you can use the /usr/lib/systemd/systemd-cryptsetup command. Additionally, you can check if the device is unsealed by using lsblk:
sudo /usr/lib/systemd/systemd-cryptsetup attach GPG_USB "/dev/sdb1" - tpm2-device=auto
lsblk
The lsblk command should display the unsealed and mounted device, like this:
NAME        MAJ:MIN RM   SIZE RO TYPE  MOUNTPOINTS
sda           8:0    0 223.6G  0 disk
 sda1        8:1    0   976M  0 part  /boot/efi
 sda2        8:2    0 222.6G  0 part
   root    254:0    0 222.6G  0 crypt /
sdb           8:16   1   7.5G  0 disk
 sdb1        8:17   1   7.5G  0 part
   GPG_USB 254:1    0   7.5G  0 crypt /media/vasudev/GPG_USB
Auto Mounting the device Now that we have solved the initial problem of unsealing the USB device using TPM2 instead of manually entering the key, the next step is to automatically mount the device upon insertion and remove the mapping when the device is removed. This can be achieved using the following udev rules:
ACTION=="add", KERNEL=="sd*", ENV DEVTYPE =="partition", ENV ID_BUS =="usb", ENV SYSTEMD_WANTS ="mount-gpg-usb@$env DEVNAME .service"
ACTION=="remove", KERNEL=="sd*", ENV DEVTYPE =="partition", ENV ID_BUS =="usb", RUN+="/usr/local/bin/umount_enc_usb.sh '%E ID_FS_UUID '"
When a device is added, a systemd service is triggered to mount the device at a specific location. Initially, I used a script with the RUN directive, but it resulted in an exit code of 32. This might be due to systemd-cryptsetup taking some time to return, causing udev to time out. To address this, I opted to use a systemd service instead. For device removal, even though the physical device is no longer present, the mapping may still remain, causing issues upon reinsertion. To resolve this, I created a script to close the luks mapping upon device removal. Below are the systemd service and script files: mount_enc_usb.sh:
#!/bin/bash
set -x
if [[ "$#" -ne 1 ]]; then
    echo "$(basename $0) <device>"
    exit 1
fi
device_uuid="$(blkid --output udev $1   grep ID_FS_UUID=   cut -d= -f2)"
if [[ "$device_uuid" == 000b2670-be4a-41b4-98eb-9adbd12a7616 ]]; then
    # Found our device, let's trigger systemd-cryptsetup
    /usr/lib/systemd/systemd-cryptsetup attach GPG_USB "$1" - tpm2-device=auto
    [[ -d /media/vasudev/GPG_USB ]]   (mkdir -p /media/vasudev/GPG_USB/ && chown vasudev:vasudev /media/vasudev/GPG_USB)
    mount /dev/mapper/GPG_USB /media/vasudev/GPG_USB
else
    echo "Not the interested device. Ignoring."
    exit 0
fi
umount_enc_usb.sh:
#!/bin/bash
if [[ "$#" -ne 1 ]]; then
  echo "$(basename $0) <fsuuid>"
  exit 1
fi
if [[ "$1" == "000b2670-be4a-41b4-98eb-9adbd12a7616" ]]; then
  # Our device is removed, let's close the luks mapping
  [[ -e /dev/mapper/GPG_USB ]] && cryptsetup luksClose /dev/mapper/GPG_USB
else
  echo "Not our device."
  exit 0
fi
mount-gpg-usb@.service:
[Unit]
Description=Mount the encrypted USB device service
[Service]
Type=simple
ExecStart=/usr/local/bin/mount_enc_usb.sh
With this setup, plugging in the USB device will automatically unseal and mount it, and upon removal, the luks mapping will be closed.

Note

This can be even done for LUKS2 encrypted root disk but will need some tweaking in initramfs.

8 July 2023

Dirk Eddelbuettel: #40: Another r2u Example Making Colab Easier

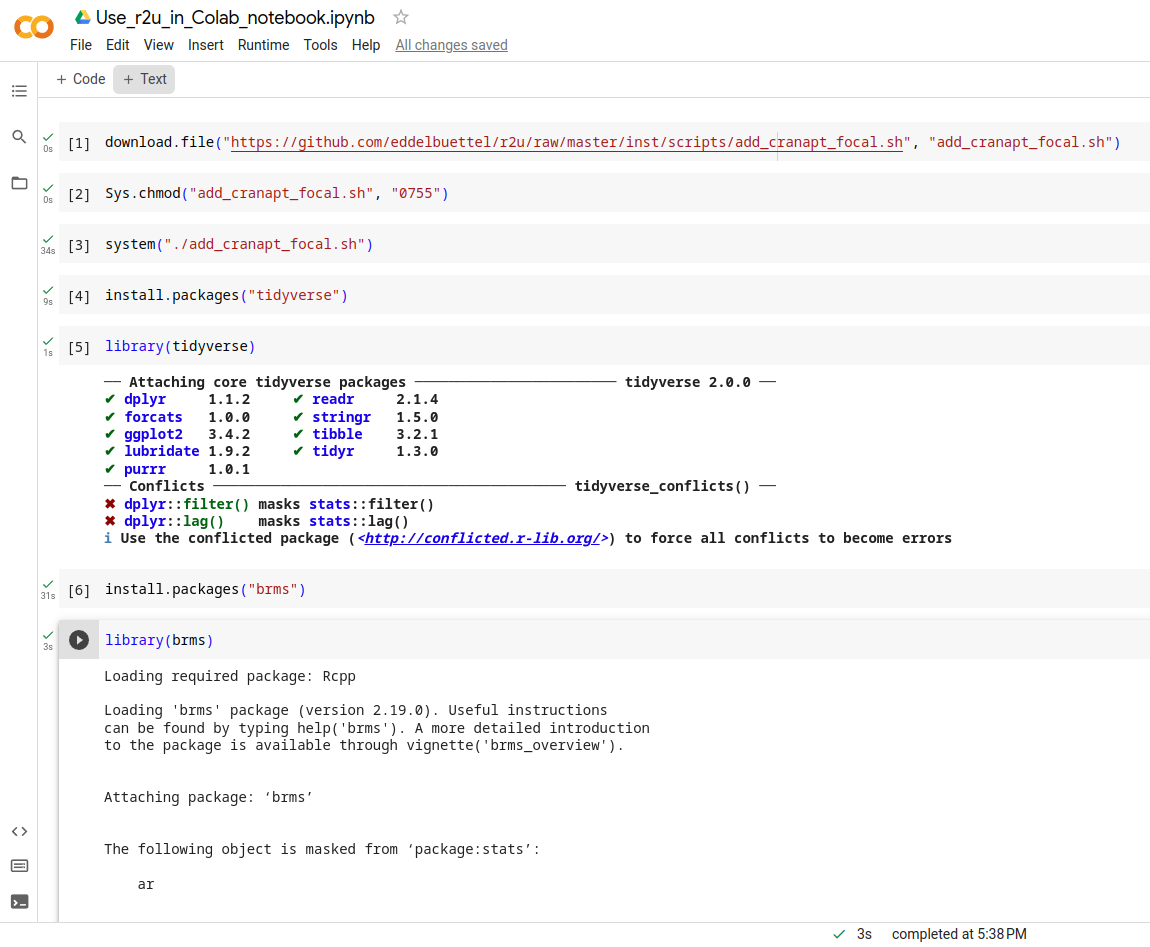
Welcome to the 40th post in the $R^4 series. This one will just be a very brief illustration of r2u use in what might be an unexpected place: Google Colab. Colab has a strong bent towards Jupyter and Python but has been supporting R compute kernels for some time (by changing what they call the runtime ). And with a little exploration one can identify these are (currently, as of July 2023) running Ubuntu 20.04 aka focal . Which is of course one of two system supported by our lovely r2u project (with the other being the newer 22.04 aka jammy ). And I mostly tweeted / tooted about r2u since the its introduction in #37. And gave basically just a mention in passing in faster feedback post #38 as well as the faster feedback in ci post #39). So a brief recap may be in order. In essence, r2u makes all of CRAN available as full-fledged Ubuntu binaries with complete and full dependencies which are then installed directly and quickly via apt. Which, to top it of, are accessed directly from R via install.packages() so no special knowledge or sauce needed. We often summarize it as fast, easy, reliable: what is not to like . And, as we established in a few minutes of probing, it also works in the focal -based Colab session. The screen shot shows the basic step of fetching the setup script (for plain Ubuntu focal system) from r2u, making it executable and running it. Total time: 34 seconds. And after that we see the pure magic of install.packages("tidyverse") installing all of it in nine seconds. Additionally, we add the brms package in thirty-one seconds cia install.packages("brms"). Both load just fine and echo their current values.
r2u on colab focal r2u on colab focal
The commands that are executed in that R session are just
download.file("https://github.com/eddelbuettel/r2u/raw/master/inst/scripts/add_cranapt_focal.sh",
              "add_cranapt_focal.sh")
Sys.chmod("add_cranapt_focal.sh", "0755")
system("./add_cranapt_focal.sh")
install.packages("tidyverse")
library(tidyverse)
install.packages("brms")
library(brms)
The timings are the Colab notebook are visible in the left margin. The lack of output makes debugging a little trickier so I still recommend to use r2u for first expploration via a Docker container as e.g. rocker/r2u:jammy. More information about r2u is at its site, and we answered some question in issues, and at stackoverflow. More questions are always welcome! If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Russell Coker: Sandboxing Phone Apps

As a follow up to Wayland [1]: A difficult problem with Linux desktop systems (which includes phones and tablets) is restricting application access so that applications can t mess with each other s data or configuration but also allowing them to share data as needed. This has been mostly solved for Android but that involved giving up all legacy Linux apps. I think that we need to get phones capable of running a full desktop environment and having Android level security on phone apps and regular desktop apps. My interest in this is phones running Debian and derivatives such as PureOS. But everything I describe in this post should work equally well for all full featured Linux distributions for phones such as Arch, Gentoo, etc and phone based derivatives of those such as Manjaro. It may be slightly less applicable to distributions such as Alpine Linux and it s phone derivative PostmarketOS, I would appreciate comments from contributors to PostmarketOS or Alpine Linux about this. I ve investigated some of the ways of solving these problems. Many of the ways of doing this involves namespaces. The LWN articles about namespaces are a good background to some of these technologies [2]. The LCA keynote lecture Containers aka crazy user space fun by Jess Frazelle has a good summary of some of the technology [3]. One part that I found particularly interesting was the bit about recognising the container access needed at compile time. This can also be part of recognising bad application design at compile time, it s quite common for security systems to flag bad security design in programs. Firejail To sandbox applications you need to have some method of restricting what they do, this means some combination of namespaces and similar features. Here s an article on sandboxing with firejail [4]. Firejail uses namespaces, seccomp-bpf, and capabilities to restrict programs. It allows bind mounts if run as root and if not run as root it can restrict file access by name and access to networking, system calls, and other features. It has a convenient learning mode that generates policy for you, so if you have a certain restricted set of tasks that an application is to perform you can run it once and then force it to do only the same operations in future. I recommend that everyone who is still reading at this point try out firejail. Here s an example of what you can do:
# create a profile
firejail --build=xterm.profile xterm
# now this run can only do what the previous run did
firejail --profile=xterm.profile xterm
Note that firejail is SETUID root so can potentially reduce system security and it has had security issues in the past. In spite of that it can be good for allowing a trusted user to run programs with less access to the system. Also it is a good way to start learning about such things. I don t think it s a good solution for what I want to do. But I won t rule out the possibility of using it at some future time for special situations. Bubblewrap I tried out firejail with the browser Epiphany (Debian package epiphany-browser) on my Librem5, but that didn t work as Epiphany uses /usr/bin/bwrap (bubblewrap) for it s internal sandboxing (here is an informative blog post about the history of bubblewrap AKA xdg-app-helper which was developed as part of flatpak [5]). The Epiphany bubblewrap sandbox is similar to the situation with Chrome/Chromium which have internal sandboxing that s incompatible with firejail. The firejail man page notes that it s not compatible with Snap, Flatpack, and similar technologies. One issue this raises is that we can t have a namespace based sandboxing system applied to all desktop apps with no extra configuration as some desktop apps won t work with it. Bubblewrap requires setting kernel.unprivileged_userns_clone=1 to run as non-root (IE provide the normal and expected functionality) which potentially reduces system security. Here is an example of a past kernel bug that was exploitable by creating a user namespace with CAP_SYS_ADMIN [6]. But it s the default in recent Debian kernels which means that the issues have been reviewed and determined to be a reasonable trade-off and also means that many programs will use the feature and break if it s disabled. Here is an example of how to use Bubblewrap on Debian, after installing the bubblewrap run the following command. Note that the new-session option (to prevent injecting characters in the keyboard buffer with TIOCSTI) makes the session mostly unusable for a shell.
bwrap --ro-bind /usr /usr --symlink usr/lib64 /lib64 --symlink usr/lib /lib --proc /proc --dev /dev --unshare-pid --die-with-parent bash
Here is an example of using Bubblewrap to sandbox the game Warzone2100 running with Wayland/Vulkan graphics and Pulseaudio sound.
bwrap --bind $HOME/.local/share/warzone2100 $HOME/.local/share/warzone2100 --bind /run/user/$UID/pulse /run/user/$UID/pulse --bind /run/user/$UID/wayland-0 /run/user/$UID/wayland-0 --bind /run/user/$UID/wayland-0.lock /run/user/$UID/wayland-0.lock --ro-bind /usr /usr --symlink usr/bin /bin --symlink usr/lib64 /lib64 --symlink usr/lib /lib --proc /proc --dev /dev --unshare-pid --dev-bind /dev/dri /dev/dri --ro-bind $HOME/.pulse $HOME/.pulse --ro-bind $XAUTHORITY $XAUTHORITY --ro-bind /sys /sys --new-session --die-with-parent warzone2100
Here is an example of using Bubblewrap to sandbox the Debian bug reporting tool reportbug
bwrap --bind /tmp /tmp --ro-bind /etc /etc --ro-bind /usr /usr --ro-bind /var/lib/dpkg /var/lib/dpkg --symlink usr/sbin /sbin --symlink usr/bin /bin --symlink usr/lib64 /lib64 --symlink usr/lib /lib --symlink /usr/lib32 /lib32 --symlink /usr/libx32 /libx32 --proc /proc --dev /dev --die-with-parent --unshare-ipc --unshare-pid reportbug
Here is an example shell script to wrap the build process for Debian packages. This needs to run with unshare-user and specifying the UID as 0 because fakeroot doesn t work in the container, I haven t worked out why but doing it through the container is a better method anyway. This script shares read-write the parent of the current directory as the Debian build process creates packages and metadata files in the parent directory. This will prevent the automatic signing scripts which is a feature not a bug, so after building packages you have to sign the .changes file with debsign. One thing I just learned is that the Debian build system Sbuild can use chroots for building packages for similar benefits [7]. Some people believe that sbuild is the correct way of doing it regardless of the chroot issue. I think it s too heavy-weight for most of my Debian package building, but even if I had been convinced I d still share the information about how to use bwrap as Debian is about giving users choice.
#!/bin/bash
set -e
BUILDDIR=$(realpath $(pwd)/..)
exec bwrap --bind /tmp /tmp --bind $BUILDDIR $BUILDDIR --ro-bind /etc /etc --ro-bind /usr /usr --ro-bind /var/lib/dpkg /var/lib/dpkg --symlink usr/bin /bin --symlink usr/lib64 /lib64 --symlink usr/lib /lib --proc /proc --dev /dev --die-with-parent --unshare-user --unshare-ipc --unshare-net --unshare-pid --new-session --uid 0 --gid 0 $@
Here is an informative blog post about using Bubblewrap with Seccomp (BPF) [8]. In a future post I ll write about how to get this sort of thing going but I ll just leave the URL here for people who want to do it on their own. The source for the flatpak-run program is the only example I could find of using Seccomp with Bubblewrap [9]. A lot of that code is worth copying for application sandboxing, maybe the entire program. Unshare The unshare command from the util-linux package has a large portion of the Bubblewrap functionality. The things that it doesn t do like creating a new session can be done by other utilities. Here is an example of creating a container with unshare and then using cgroups with it [10]. systemd --user Recent distributions have systemd support for running a user session, the Arch Linux Wiki has a good description of how this works [11]. The units for a user are .service files stored in /usr/lib/systemd/user/ (distribution provided), ~/.local/share/systemd/user/ (user installed applications in debian a link to ~/.config/systemd/user/), ~/.config/systemd/user/ (for manual user config), and /etc/systemd/user/ (local sysadmin provided) Here are some example commands for manipulating this:
# show units running for the current user
systemctl --user
# show status of one unit
systemctl --user status kmail.service
# add an environment variable to the list for all user units
systemctl --user import-environment XAUTHORITY
# start a user unit
systemctl --user start kmail.service
# analyse security for all units for the current user
systemd-analyze --user security
# analyse security for one unit
systemd-analyze --user security kmail.service
Here is a test kmail.service file I wrote to see what could be done for kmail, I don t think that kmail is the app most needing to be restricted it is in more need of being protected from other apps but it still makes a good test case. This service file took it from the default risk score of 9.8 (UNSAFE) to 6.3 (MEDIUM) even though I was getting the error code=exited, status=218/CAPABILITIES when I tried anything that used capabilities (apparently due to systemd having some issue talking to the kernel).
[Unit]
Description=kmail
[Service]
ExecStart=/usr/bin/kmail
# can not limit capabilities (code=exited, status=218/CAPABILITIES)
#CapabilityBoundingSet=~CAP_SYS_TIME CAP_SYS_PACCT CAP_KILL CAP_WAKE_ALARM CAP_DAC_OVERRIDE CAP_DAC_READ_SEARCH CAP_FOWNER CAP_IPC_OWNER CAP_LINUX_IMMUTABLE CAP_IPC_LOCK CAP_SYS_MODULE CAP_SYS_TTY_CONFIG CAP_SYS_BOOT CAP_SYS_CHROOT CAP_BLOCK_SUSPEND CAP_LEASE CAP_MKNOD CAP_CHOWN CAP_FSETID CAP_SETFCAP CAP_SETGID CAP_SETUID CAP_SETPCAP CAP_SYS_RAWIO CAP_SYS_PTRACE CAP_SYS_NICE CAP_SYS_RESOURCE CAP_NET_ADMIN CAP_NET_BIND_SERVICE CAP_NET_BROADCAST CAP_NET_RAW CAP_SYS_ADMIN CAP_SYSLOG
# also 218 for ProtectKernelModules PrivateDevices ProtectKernelLogs ProtectClock
# MemoryDenyWriteExecute stops it displaying message content (bad)
# needs @resources and @mount to startup
# needs @privileged to display message content
SystemCallFilter=~@cpu-emulation @debug @raw-io @reboot @swap @obsolete
SystemCallArchitectures=native
UMask=077
NoNewPrivileges=true
ProtectControlGroups=true
PrivateMounts=false
RestrictNamespaces=~user pid net uts mnt cgroup ipc
RestrictSUIDSGID=true
ProtectHostname=true
LockPersonality=true
ProtectKernelTunables=true
RestrictAddressFamilies=~AF_PACKET
RestrictRealtime=true
ProtectSystem=strict
ProtectProc=invisible
PrivateUsers=true
[Install]
When I tried to use the TemporaryFileSystem=%h directive (to make the home directory a tmpfs the most basic step in restricting what a regular user application can do) I got the error (code=exited, status=226/NAMESPACE) . So I don t think the systemd user setup competes with bubblewrap for restricting user processes. But if anyone else can start where I left off and go further then that will be interesting. Systemd-run The following shell script runs firefox as a dynamic user via systemd-run, running this asks for the root password and any mechanism for allowing that sort of thing opens potential security holes. So at this time while it s an interesting feature I don t think it is suitable for running regular applications on a phone or Linux desktop.
#!/bin/bash
# systemd-run Firefox with DynamicUser and home directory.
#
# Run as a non-root user.
# Or, run as root and change $USER below.
SANDBOX_MINIMAL=(
    --property=DynamicUser=1
    --property=StateDirectory=openstreetmap
    # --property=RootDirectory=/debian_sid
)
SANDBOX_X11=(
    # Sharing Xorg always defeats security, regardless of any sandboxing tech,
    # but the config is almost ready for Wayland, and there's Xephyr.
#    --property=LoadCredential=.ICEauthority:/home/$USER/.ICEauthority
    --property=LoadCredential=.Xauthority:/home/$USER/.Xauthority
    --property=Environment=DISPLAY=:0
)
SANDBOX_FIREFOX=(
    # hardware-accelerated rendering
    --property=BindPaths=/dev/dri
    # webcam
    # --property=SupplementaryGroups=video
)
systemd-run  \
    "$ SANDBOX_MINIMAL[@] "  "$ SANDBOX_X11[@] " "$ SANDBOX_FIREFOX[@] " \
    bash -c '
        export XAUTHORITY="$CREDENTIALS_DIRECTORY"/.Xauthority
        export ICEAUTHORITY="$CREDENTIALS_DIRECTORY"/.ICEauthority
        export HOME="$STATE_DIRECTORY"/home
        firefox --no-remote about:blank
    '
Qubes OS Here is an interesting demo video of QubesOS [12] which shows how it uses multiple VMs to separate different uses. Here is an informative LCA presentation about Qubes which shows how it asks the user about communication between VMs and access to hardware [13]. I recommend that everyone who hasn t seen Qubes in operation watch the first video and everyone who isn t familiar with the computer science behind it watch the second video. Qubes appears to be a free software equivalent to NetTop as far as I can tell without ever being able to use NetTop. I don t think Qubes is a good match for my needs in general use and it definitely isn t a good option for phones (VMs use excessive CPU on phones). But it s methods for controlling access have some ideas that are worth copying. File Access XDG Desktop Portal One core issue for running sandboxed applications is to allow them to access files permitted by the user but no other files. There are two main parts to this problem, the easier one is to have each application have it s own private configuration directory which can be addressed by bind mounts, MAC systems, running each application under a different UID or GID, and many other ways. The hard part of file access is to allow the application to access random files that the user wishes. For example I want my email program, IM program, and web browser to be able to save files and also to be able to send arbitrary files via email, IM, and upload to web sites. But I don t want one of those programs to be able to access all the files from the others if it s compromised. So only giving programs access to arbitrary files when the user chooses such a file makes sense. There is a package xdg-desktop-portal which provides a dbus interface for opening files etc for a sandboxed application [14]. This portal has backends for KDE, GNOME, and Wayland among others which allow the user to choose which file or files the application may access. Chrome/Chromium is one well known program that uses the xdg-desktop-portal and does it s own sandboxing. To use xdg-desktop-portal an application must be modified to use that interface instead of opening files directly, so getting this going with all Internet facing applications will take some work. But the documentation notes that the portal API gives a consistent user interface for operations such as opening files so it can provide benefits even without a sandboxed environment. This technology was developed for Flatpak and is now also used for Snap. It also has a range of APIs for accessing other services [15]. Flatpak Flatpack is a system for distributing containerised versions of applications with some effort made to improve security. Their development of bubblewrap and xdg-desktop-portal is really good work. However the idea of having software packaged with all libraries it needs isn t a good one, here s a blog post covering some of the issues [16]. The web site flatkill.org has been registered to complain about some Flatpak problems [17]. They have some good points about the approach that Flatpak project developers have taken towards some issues. They also make some points about the people who package software not keeping up to date with security fixes and not determining a good security policy for their pak. But this doesn t preclude usefully using parts of the technology for real security benefits. If parts of Flatpak like Bubblewrap and xdg-portal are used with good security policies on programs that are well packaged for a distribution then these issues would be solved. The Flatpak app author s documentation about package requirements [18] has an overview of security features that is quite reasonable. If most paks follow that then it probably isn t too bad. I reviewed the manifests of a few of the recent paks and they seemed to have good settings. In the amount of time I was prepared to spend investigating this I couldn t find evidence to support the Flatkill claim about Flatpaks granting obviously inappropriate permissions. But the fact that the people who run Flathub decided to put a graph of installs over time on the main page for each pak while making the security settings only available by clicking the Manifest github link, clicking on a JSON or YAML file, and then searching for the right section in that shows where their priorities lie. The finish-args section of the Flatpak manifest (the section that describes the access to the system) seems reasonably capable and not difficult for users to specify as well as being in common use. It seems like it will be easy enough to take some code from Flatpak for converting the finish-args into Bubblewrap parameters and then use the manifest files from Flathub as a starting point for writing application security policy for Debian packages. Snap Snap is developed by Canonical and seems like their version of Flatpak with some Docker features for managing versions, the Getting Started document is worth reading [19]. They have Connections between different snaps and the system where a snap registers a plug that connects to a socket which can be exposed by the system (EG the camera socket) or another snap. The local admin can connect and disconnect them. The connections design reminds me of the Android security model with permitting access to various devices. The KDE Neon extension [20] has been written to add Snap support to KDE. Snap seems quite usable if you have an ecosystem of programs using it which Canonical has developed. But it has all the overheads of loopback mounts etc that you don t want on a mobile device and has the security issues of libraries included in snaps not being updated. A quick inspection of an Ubuntu 22.04 system I run (latest stable release) has Firefox 114.0.2-1 installed which includes libgcrypt.so.20.2.5 which is apparently libgcrypt 1.8.5 and there are CVEs relating to libgcrypt versions before 1.9.4 and 1.8.x versions before 1.8.8 which were published in 2021 and updated in 2022. Further investigation showed that libgcrypt came from the gnome-3-38-2004 snap (good that it doesn t require all shared objects to be in the same snap, but that it has old versions in dependencies). The gnome-3-38-2004 snap is the latest version so anyone using the Snap of Firefox seems to have no choice but to have what appears to be insecure libraries. The strict mode means that the Snap in question has no system access other than through interfaces [21]. SE Linux and Apparmor The Librem5 has Apparmor running by default. I looked into writing Apparmor policy to prevent Epiphany from accessing all files under the home directory, but that would be a lot of work. Also at least one person has given up on maintaining an Epiphany profile for Apparmor because it changes often and it s sandbox doesn t work well with Apparmor [22]. This was not a surprise to me at all, SE Linux policy has the same issues as Apparmor in this regard. The Ubuntu Security Team Application Confinement document [23] is worth reading. They have some good plans for using AppArmor as part of solving some of these problems. I plan to use SE Linux for that. Slightly Related Things One thing for the future is some sort of secure boot technology, the LCA lecture Becoming a tyrant: Implementing secure boot in embedded devices [24] has some ideas for the future. The Betrusted project seems really interesting, see Bunnie s lecture about how to create a phone size security device with custom OS [25]. The Betrusted project web page is worth reading too [26]. It would be ironic to have a phone as your main PC that is the same size as your security device, but that seems to be the logical solution to several computing problems. Whonix is a Linux distribution that has one VM for doing Tor stuff and another VM for all other programs which is only allowed to have network access via the Tor VM [27]. Xpra does for X programs what screen/tmux do for text mode programs [28]. It allows isolating X programs from each other in ways that are difficult to impossible with a regular X session. In an ideal situation we could probably get the benefits we need with just using Wayland, but if there are legacy apps that only have X support this could help. Conclusion I think that currently the best option for confining desktop apps is Bubblewrap on Wayland. Maybe with a modified version of Flatpak-run to run it and with app modifications to use the xdg-portal interfaces as much as possible. That should be efficient enough in storage space, storage IO performance, memory use, and CPU use to run on phones while giving some significant benefits. Things to investigate are how much code from Flatpak to use, how to most efficiently do the configuration (maybe the Flatpak way because it s known and seems effective), how to test this (and have regression tests), and what default settings to use. Also BPF is a big thing to investigate.

7 July 2023

Dirk Eddelbuettel: Rcpp 1.0.11 on CRAN: Updates and Maintenance

rcpp logo The Rcpp Core Team is delighted to announce that the newest release 1.0.11 of the Rcpp package arrived on CRAN and in Debian earlier today. Windows and macOS builds should appear at CRAN in the next few days, as will builds in different Linux distribution and of course at r2u. The release was finalized three days ago, but given the widespread use and extended reverse dependencies at CRAN it usually takes a few days to be processed. This release continues with the six-months January-July cycle started with release 1.0.5 in July 2020. As a reminder, we do of course make interim snapshot dev or rc releases available via the Rcpp drat repo and strongly encourage their use and testing I run my systems with these versions which tend to work just as well, and are also fully tested against all reverse-dependencies. Rcpp has long established itself as the most popular way of enhancing R with C or C++ code. Right now, 2720 packages on CRAN depend on Rcpp for making analytical code go faster and further, along with 251 in BioConductor. On CRAN, 13.7% of all packages depend (directly) on Rcpp, and 59.6% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 72.5 million times. The two published papers (also included in the package as preprint vignettes) have, respectively, 1678 (JSS, 2011) and 259 (TAS, 2018) citations, while the the book (Springer useR!, 2013) has another 588. This release is incremental as usual, generally preserving existing capabilities faithfully while smoothing our corners and / or extending slightly, sometimes in response to changing and tightened demands from CRAN or R standards. The full list below details all changes, their respective PRs and, if applicable, issue tickets. Big thanks from all of us to all contributors!
Changes in Rcpp version 1.0.11 (2023-07-03)
  • Changes in Rcpp API:
    • Rcpp:::CxxFlags() now quotes only non-standard include path on linux (Lukasz in #1243 closing #1242).
    • Two unit tests no longer accidentally bark on stdout (Dirk and I aki in #1245).
    • Compilation under C++20 using clang++ and its standard library is enabled (Dirk in #1248 closing #1244).
    • Use backticks in a generated .Call() statement in RcppExports.R (Dirk #1256 closing #1255).
    • Switch to system2() to capture standard error messages in error cases (I aki in #1259 and #1261 fixing #1257).
  • Changes in Rcpp Documentation:
    • The CITATION file format has been updated (Dirk in #1250 fixing #1249).
  • Changes in Rcpp Deployment:
    • A test for qnorm now uses the more accurate value from R 4.3.0 (Dirk in #1252 and #1260 fixing #1251).
    • Skip tests with path issues on Windows (I aki in #1258).
    • Container deployment in continuous integrations was improved. (I aki and Dirk in #1264, Dirk in #1269).
    • Several files receives minor edits to please R CMD check from r-devel (Dirk in #1267).

Thanks to my CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2994 previous questions. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

5 July 2023

Reproducible Builds: Reproducible Builds Summit 2023 in Hamburg

We are glad to announce the upcoming Reproducible Builds Summit, set to take place from October 31st to November 2nd, 2023, in the vibrant city of Hamburg, Germany. This year, we are thrilled to host the seventh edition of this exciting event following the success of previous summits in various iconic locations around the world, including Venice (2022), Marrakesh (2019), Paris (2018), Berlin (2017), Berlin (2016) Athens (2015). If you re excited about joining us this year, please make sure to read the event page which has more details about the event and location. As in previous years, we will be sending invitations to all those who attended our previous summit events or expressed interest to do so. However also without receiving such a personal invitation please do email the organizers and we will find a way to accommodate you.

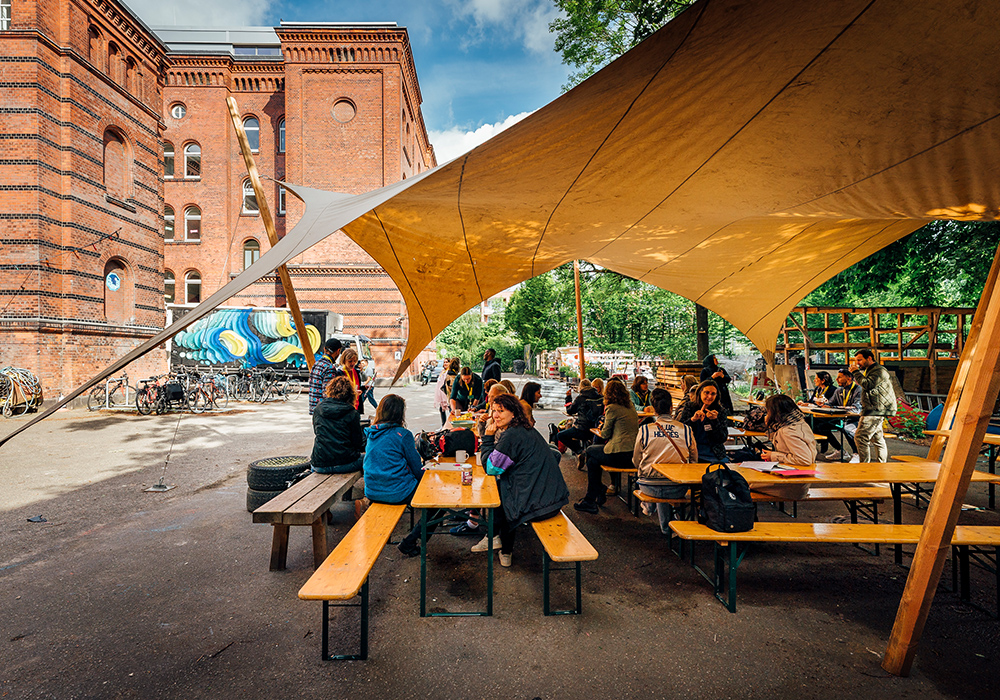
About the event The Reproducible Builds Summit is a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving. With your help, we will bring this space (and several other inside areas) into life:
The outside area at dock-europe (source: dock-europe.net)

Schedule Although the exact content of the meeting will be shaped by the participants, the main goals will include:
  • Update & exchange about the status of reproducible builds in various projects.
  • Improve collaboration both between and inside projects.
  • Expand the scope and reach of reproducible builds to more projects.
  • Work together and hack on solutions.
  • Establish space for more strategic and long-term thinking than is possible in virtual channels.
  • Brainstorm designs on tools enabling users to get the most benefits from reproducible builds.
  • Discuss how reproducible builds will be usable and meaningful to users and developers alike.
Logs and minutes will be published after the meeting.

Location & date
  • October 31st to November 2nd, 2023
  • Dock Europe, Zeiseweg 9, 22765, Hamburg, Germany.

Registration instructions Please reach out if you d like to participate in hopefully interesting, inspiring and intense technical sessions about reproducible builds and beyond! We look forward to what we anticipate to be an extraordinary event!

2 July 2023

Dirk Eddelbuettel: RcppAnnoy 0.0.21 on CRAN: Upstream Update

annoy image Another minor maintenance release, now at version 0.0.20, of RcppAnnoy has arrived on CRAN. RcppAnnoy is the Rcpp-based R integration of the nifty Annoy library by Erik Bernhardsson. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours originally developed to drive the Spotify music discovery algorithm. This release mainly updates the included copy of Annoy to version 1.7.3 which now provides a C++ namespace in the header API. So I sent a pair of PRs to uwot to update its (compiled) use, which James promptly merged. With that the CRAN update was once again seamless. Otherwise the package follows current custom by moving away from C++11 as a set compilation standard to be open for more modern C++ idioms. Here, this allows in particular for possible multithreaded indexing for which everything needed is in C++17. However, we did not turn multithreaded indexing on as the RNG use is such that the streams would differ leading to slightly different (if of course equivalent) results. Users can enable this by recompiling with the switch flipped, see src/Makevars.
Changes in version 0.0.21 (2023-07-02)
  • The build setup switched from C++11 to C++17 which offers threading support (which remains off by default to ensure consistent results)
  • Upstream code was update to Annoy 1.17.3, the switch to an explicit C++ namespace has been accomodated (Dirk in #75)

Courtesy of my CRANberries, there is also a diffstat report for this release. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

1 July 2023

Dirk Eddelbuettel: New Achievement Unlocked: Bugfix Patch into Stable Release Update

Last weekend was the bi-annual time to roll the main machine and server to the current Ubuntu release, now at 23.04. It must now have been fifteen or so years that I have used Ubuntu for my desktop / server (for reasons I may write about another time). And of course it all passed swimmingly as usual. [ And a small aside, if I may. Among all these upgrades, one of my favourite piece of tech trivia that may well be too little known remains the dedication of the PostgreSQL maintainers installing the new version, now PostgreSQL 15, seamlessly in parallel with the existing one, in my case PostgreSQL 14, keeping both running (!!) on two neighbouring ports (!!) so that there is no service disruption. So at some point, maybe this weekend, I will run the provided script to dump-and-restore to trigger the database migration at my convenience. Happy PostgreSQL on Debian/Ubuntu user since the late 1990s. It. Just. Works. ] [ Similarly, it is plainly amazeballs how apt orders and runs package updates to service to keep running for a maximum amount of time. This machine acts as e.g. a web server and it was up and running (as were other services) while thousands of package got updated/replaced. It is pretty amazing. Whereas on other platforms people still maintain the do not ever update anything we demonstrably offer the opposite here. Really not too shabby. ] This time, I had one small hickup. Emacs, now at version 28 bringing loads of niceties along, would not load. And the error soon lead to a post on the magit list where its indefatigable author Jonas Bernoulli suggested a rebuild (and hence re-compilation of the elisp files). Which I did, and which allowed a start of VM inside Emacs. So I was happy. But it allowed it only once for each VM package reinstall. Not good, and I remained curious. Some more digging lead to a breakthrough. A post and commit at the Fedora Project indicated that for just VM within Emacs, byte-compilation throws a spanner. Which one can work around by telling Emacs not to compile the files in the VM folder. So I applied that patch to the VM package in a local build et voil we have working VM. The world is clearly better when your email client of 25+ years just works. And feels snappier because everything under Emacs28 feels snappier! So I set this up properly and filed Debian Bug Report #1039105. To which Ian Jackson, the maintainer, replied a few days later nodding that he could reproduce. And that he concurred with the bug report, and was planning to update throughout. And lo and behold this morning s update reveals that this made into an update for the just-released Debian Bookworm. So yay. In all these years of Debian maintainership (somewhere between twentyfive and thirty) this may be my first bug report with patch going straight into a stable release. But of course, true and full credit goes of course to G ran Uddeborg for putting it up first for Fedora. Lovely how Open Source can work together. We really should do more, not less, of that. But I digress Anyway, in sum: If you try to use VM under the lovely Emacs 28, there is a fix, and if you use it with Debian Bookworm the fix should hit your mirrors soons. Ditto, methinks, for the next Ubuntu release. If you use it under Ubuntu now, the package is (elisp) text-only and can be safely installed on a derivative (which we do not enjoy in general but which is fine here). So enjoy! If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Bastian Venthur: dotenv-cli update

Thanks to Nicholas Guriev, dotenv-cli now uses exec instead of popen to create the new process on POSIX systems. As a refresher, dotenv-cli is a package that provides the dotenv command. dotenv reads the .env file from the current directory, puts the contents in the environment variables, and executes the given command with the extra environment variables set. dotenv comes in handy if you follow the 12 factor app methodology or just need to run a program locally with specific environment variables set. With this new change, when you call
dotenv my_awesome_tool
instead of forking a new process for my_awesome_tool, effectively creating a child process of dotenv, dotenv now uses exec to become the new process. This is a bit cleaner, as there is no longer a dotenv-process running that you don t actually care about, and less-error prone when trying to send signals such as SIGTERM to the processes that runs my_awesome_tool. Unfortunately, exec does not work properly under Windows, so here we still fall back to using popen. This new feature is available in version 3.2.0 which is available on PyPI and debian/unstable.

Paul Wise: FLOSS Activities June 2023

Focus This month I didn't have any particular focus. I just worked on issues in my info bubble.

Changes

Issues

Review
  • Spam: reported 29 Debian mailing list posts
  • Debian wiki: RecentChanges for the month
  • Debian BTS usertags: changes for the month
  • Debian screenshots:
    • approved lsd stockfish x86dis
    • rejected libselinux1 (photo), stockfish (mobile app), php-bcmath (selfie), chromium-browser/binutils-alpha-linux-gnu (medical photo), weboob-qt (QR code)

Administration
  • Debian QA services: deploy changes
  • Debian IRC: updated #debian-live admin list
  • Debian mentors: investigate reason for missing package
  • Debian wiki: unblock IP addresses, approve accounts

Communication

Sponsors The sptag work was sponsored. All other work was done on a volunteer basis.

30 June 2023

Shirish Agarwal: Motherboard battery, Framework, VR headsets, Steam

Motherboard Battery You know you have become too old when you get stumped and the solution is simple and fixed by the vendor. About a week back, I was getting CPU Fan Error. It s a 6 year old desktop so I figured that the fan or the ball bearings on the fan must have worn out. I opened up the cabinet and I could see both the on cpu fan was working coolly as well as the side fan was working without an issue. So I couldn t figure out what was the issue. I had updated the BIOS/UEFI number of years ago so that couldn t be an issue. I fiddled with the boot menu and was able to boot into Linux but it was a pain that I had to do every damn time. As it is, it takes almost 2-3 minutes for the whole desktop to be ready and this extra step was annoying. I had bought a Mid-tower cabinet while the motherboard so there were alternate connectors I could try but still the issue persisted. And this workaround was heart-breaking as you boot the BIOS/UEFI and fix the boot menu each time even though it had Debian Boot Launcher and couple of virtual ones provided by the vendor (Asus) and they were hardwired. So failing all, went to my vendor/support and asked if he could find out what the issue is. It costed me $10, he did all the same things I did but one thing more, he changed the battery (cost less than 1USD) and presto all was right with the world again. I felt like a fool but a deal is a deal so paid the gentleman for his services. Now can again use the desktop and at least know about what s happening in the outside world.

Framework Laptops I have been seeing quite a few teardowns of Framework Laptops on Youtube and love it. More so, now that they have AMD in their arsenal. I do hope they work on their pricing and logistics and soon we have it here competing with others. If the pricing isn t substantial then definitely would be one of the first ones to order. India is and remains a very cost-conscious market and more so with the runaway prices that we have been seeing. In fact, the last 3 years have been pretty bad for the overall PC market declining 30% YoY for the last 3 years while prices have gone through the roof. Apart from the pricing from the vendors, taxation has been another hit as the current Govt. has been taxing anywhere from 30-100% taxes on various PC, desktop and laptop components. Think have shared Graphic cards for instance have 100% Duty apart from other taxes. I don t see the market picking up at least in the 24 to 36 months. Most of this year and next year, both AMD and Intel are doing refreshes so while there would be some improvements (probably 10-15%) not earth-shattering for the wider market to sit up and take notice. Intel has proposed a 64-bit architecture (only) about couple of months back, more on that later. As far as the Indian market is concerned, if you want the masses, then have lappies at around 40-50k ($600 USD) and there would be a mass takeup, if you want to be a Lenovo or something like that, then around a lakh or INR 100k ($1200 USD) or be an Apple which is around 150k INR or around 2000 USD. There are some clues as to what their plans but for that you have to trawl their forums and the knowledgebase. Seems some people are using freight forwarders to get around the hurdles but Framework doesn t want to do any shortcuts for the same. Everybody seems to be working on Vertical stacking of chips, whether it is the Chinese, or Belgian s or even AMD and Intel who have their own spins to it, but most of these technologies are at least 3-4 years out in the future (or more). India is a big laggard in this space with having knowledge of 45nm which in Aviation speak one could say India knows how to build 707 (one of the first Boeing commercial passenger carrying aircraft) while today it is Boeing 777x or Airbus 350. I have shared in the past how the Tata s have been trying to collaborate with the Japanese and get at least their 25nm chip technology but nothing has come of it to date. The only somewhat o.k. news has been the chip testing and packaging plant by Micron to be made in Gujarat. It doesn t do anything for us although we would be footing almost 70% of the plant s capital expenditure and the maximum India will get 4k jobs. Most of these plants are highly automated as dust is their mortal enemy so even the 4k jobs announced seem far-fetched. It would probably be less than half once production starts if it happens  but that is probably a story for another time. Just as a parting shot, even memory vendors are going highly automated factory lines.

VR Headsets I was stuck by how similar or where VR is when I was watching Made in Finland. I don t want to delve much into the series but it is a fascinating one. I was very much taken by the character of Kari Kairamo or the actor who played the character of him and was very much disappointed with the sad ending the gentleman got. It is implicated in the series that the banks implicitly forced him to commit suicide. There is also a lot of chaos as is normal in a big company having many divisions. It s only when Jorma Olila takes over, the company sheds a lot of dead weight was cut off with mobiles having the most funding which they didn t have before. I was also fascinated when I experienced pride when Nokia shows off its 1011 mobile phone when at that time phones were actually like bricks. My first Nokia was number of years later, Nokia 1800 and have to say those phones outlasted a long time than today s Samsung s. If only Nokia had read the tea leaves right  Back to the topic though, I have been wearing glasses since the age of 5 year old. They weigh less than 10 grams and you still get a nose dent. And I know enough people, times etc. when people have got headaches and whatnot from glasses. Unless the VR headsets become that size and don t cost an arm and leg (or a kidney or a liver) it would have niche use. While 5G and 6G would certainly push more ppl to get it it probably would take a few more years before we have something that is simple and doesn t need too much to get it rolling. The series I mentioned above is already over it s first season but would highly recommend it. I do hope the second season happens quickly and we do come to know why and how Nokia missed the Android train and their curious turn to get to Microsoft which sorta sealed their fate

Steam I have been following Steam, Luthris and plenty of other launchers on Debian. There also seems to some sort of an idea that once MESA 23.1.x or later comes into Debian at some point we may get Steam 64-bit and some people are hopeful that we may get it by year-end. There are a plethora of statistics that can be used to find status of Gaming on Linux. This is perhaps the best one I got so far. Valve also has its own share of stats that it shows here. I am not going to go into much detail except the fact that lutris has been there on Debian sometime now. And as and when Steam does go fully 64-bit, whole lot of multilib issues could be finally put to rest. Interestingly, Intel has quietly also shared details of only a 64-bit architecture PC. From what I could tell, it simply boots into 16-bit and then goes into 64-bit bypassing the 32-bit. In theory, it should remove whole lot code, make it safer as well as faster. If rival AMD was to play along things could move much faster. Now don t get me wrong, 32-bit was good, but for it s time. I m sure at some point in time even 64-bit would have its demise, and we would jump to 128-bit. Of course, in reality we aren t anywhere close to even 48-bit, leave alone 64-bit. Superuser gives a good answer on that. We may be a decade or more before we exhaust that but for sure there will be need for better, faster hardware especially as we use more and more of AI for good and bad things. I am curious to see how it pans out and how it will affect (or not) FOSS gaming. FWIW, I used to peruse freegamer.blogspot.com which kinda ended in 2021 and now use Lee Reilly blog posts to know what is happening in github as far as FOSS games are concerned. There is also a whole thing about handhelds and gaming but that probably would require its own blog post or two. There are just too many while at the same time too few (legally purchasable in India) to have its own blog post, maybe sometime in Future. Best way to escape the world. Till later.

29 June 2023

C.J. Collier: Converting a windows install to a libvirt VM

Reduce the size of your c: partition to the smallest it can be and then turn off windows with the understanding that you will never boot this system on the iron ever again.
Boot into a netinst installer image (no GUI). hold alt and press left arrow a few times until you get to a prompt to press enter. Press enter. In this example /dev/sda is your windows disk which contains the c: partition
and /dev/disk/by-id/usb0 is the USB-3 attached SATA controller that you have your SSD attached to (please find an example attached). This SSD should be equal to or larger than the windows disk for best compatability. A photo of a USB-3 attached SATA controller To find the literal path names of your detected drives you can run fdisk -l. Pay attention to the names of the partitions and the sizes of the drives to help determine which is which. Once you have a shell in the netinst installer, you should maybe be able to run a command like the following. This will duplicate the disk located at if (in file) to the disk located at of (out file) while showing progress as the status.
dd if=/dev/sda of=/dev/disk/by-id/usb0 status=progress
If you confirm that dd is available on the netinst image and the previous command runs successfully, test that your windows partition is visible in the new disk s partition table. The start block of the windows partition on each should match, as should the partition size.
fdisk -l /dev/disk/by-id/usb0
fdisk -l /dev/sda
If the output from the first is the same as the output from the second, then you are probably safe to proceed. Once you confirm that you have made and tested a full copy of the blocks from your windows drive saved on your usb disk, nuke your windows partition table from orbit.
dd if=/dev/zero of=/dev/sda bs=1M count=42
You can press alt-f1 to return to the Debian installer now. Follow the instructions to install Debian. Don t forget to remove all attached USB drives. Once you install Debian, press ctrl-alt-f3 to get a root shell. Add your user to the sudoers group:
# adduser cjac sudoers
log out
# exit
log in as your user and confirm that you have sudo
$ sudo ls
Don t forget to read the spider man advice enter your password you ll need to install virt-manager. I think this should help:
$ sudo apt-get install virt-manager libvirt-daemon-driver-qemu qemu-system-x86
insert the USB drive. You can now create a qcow2 file for your virtual machine.
$ sudo qemu-img convert -O qcow2 \
/dev/disk/by-id/usb0 \
/var/lib/libvirt/images/windows.qcow2
I personally create a volume group called /dev/vg00 for the stuff I want to run raw and instead of converting to qcow2 like all of the other users do, I instead write it to a new logical volume.
sudo lvcreate /dev/vg00 -n windows -L 42G # or however large your drive was
sudo dd if=/dev/disk/by-id/usb0 of=/dev/vg00/windows status=progress
Now that you ve got the qcow2 file created, press alt-left until you return to your GDM session. The apt-get install command above installed virt-manager, so log in to your system if you haven t already and open up gnome-terminal by pressing the windows key or moving your mouse/gesture to the top left of your screen. Type in gnome-terminal and either press enter or click/tap on the icon. I like to run this full screen so that I feel like I m in a space ship. If you like to feel like you re in a spaceship, too, press F11. You can start virt-manager from this shell or you can press the windows key and type in virt-manager and press enter. You ll want the shell to run commands such as virsh console windows or virsh list When virt-manager starts, right click on QEMU/KVM and select New.
In the New VM window, select Import existing disk image
When prompted for the path to the image, use the one we created with sudo qemu-img convert above.
Select the version of Windows you want.
Select memory and CPUs to allocate to the VM.
Tick the Customize configuration before install box
If you re prompted to enable the default network, do so now.
The default hardware layout should probably suffice. Get it as close to the underlying hardware as it is convenient to do. But Windows is pretty lenient these days about virtualizing licensed windows instances so long as they re not running in more than one place at a time. Good luck! Leave comments if you have questions.
Russ Allbery: Review: Semiosis

Review: Semiosis, by Sue Burke
Series: Semiosis #1
Publisher: Tor
Copyright: February 2018
ISBN: 0-7653-9137-6
Format: Kindle
Pages: 333
Semiosis is a first-contact science fiction novel and the first half of a duology. It was Sue Burke's first novel. In the 2060s, with the Earth plagued by environmental issues, a group of utopians decided to found a colony on another planet. Their goal is to live in harmony with an unspoiled nature. They wrote a suitably high-minded founding document, the Constitution of the Commonwealth of Pax, and set out in cold sleep on an interstellar voyage. 158 years later, they awoke in orbit around a planet with a highly-developed ecology, which they named Pax. Two pods and several colonists were lost on landing, but the rest remained determined to follow through with their plan. Not that they had many alternatives. Pax does not have cities or technological mammalian life, just as they hoped. It does, however, have intelligent life. This novel struggled to win me over for reasons that aren't the fault of Burke's writing. The first is that it is divided into seven parts, each telling the story of a different generation. Intellectually, I like this technique for telling an anthropological story that follows a human society over time. But emotionally, I am a character reader first and foremost, and I struggle with books where I can't follow the same character throughout. It makes the novel feel more like a fix-up of short stories, and I'm not much of a short story reader. Second, this is one of those stories where a human colony loses access to its technology and falls back to a primitive lifestyle. This is a concept I find viscerally unpleasant and very difficult to read about. I don't mind reading stories that start at the lower technological level and rediscover lost technology, but the process of going backwards, losing knowledge, surrounded by breaking technology that can never be repaired, is disturbing at a level that throws me out of the story. It doesn't help that the original colonists chose to embrace that reversion. Some of this wasn't intentional some vital equipment was destroyed when they landed but a lot of it was the plan from the start. They are the type of fanatics who embrace a one-way trip and cannibalizing the equipment used to make it in order to show their devotion to the cause. I spent the first part of the book thinking the founding colonists were unbelievably foolish, but then they started enforcing an even more restrictive way of life on their children and that tipped me over into considering them immoral. This was the sort of political movement that purged all religion and political philosophy other than their one true way so that they could raise "uncorrupted" children. Burke does recognize how deeply abusive this is. The second part of the book, which focuses on the children of the initial colonists, was both my favorite section and had my favorite protagonist, precisely because someone put words to the criticisms that I'd been thinking since the start of the book. The book started off on a bad foot with me, but if it had kept up the momentum of political revolution and rethinking provided by the second part, it might have won me over. That leads to the third problem, though, which is the first contact part of the story. (If you've heard anything about this series, you probably know what the alien intelligence is, and even if not you can probably guess, but I'll avoid spoilers anyway.) This is another case where the idea is great, but I often don't get along with it as a reader. I'm a starships and AIs and space habitats sort of SF reader by preference and tend to struggle with biological SF, even though I think it's great more of it is being written. In this case, mind-altering chemicals enter the picture early in the story, and while this makes perfect sense given the world-building, this is another one of my visceral dislikes. A closely related problem is that the primary alien character is, by human standards, a narcissistic asshole. This is for very good story and world-building reasons. I bought the explanation that Burke offers, I like the way this shows how there's no reason to believe humans have a superior form of intelligence, and I think Burke's speculations on the nature of that alien intelligence are fascinating. There are a lot of good reasons to think that alien morality would be wildly different from human morality. But, well, I'm still a human reading this book and I detested the alien, which is kind of a problem given how significant of a character it is. That's a lot baggage for a story to overcome. It says something about how well-thought-out the world-building is that it kept my attention anyway. Burke uses the generational structure very effectively. Events, preferences, or even whims early in the novel turn into rituals or traditions. Early characters take on outsized roles in history. The humans stick with the rather absurd constitution of Pax, but do so in a way that feels true to how humans reinterpret and stretch and layer meaning on top of wholly inadequate documents written in complete ignorance of the challenges that later generations will encounter. I would have been happier without the misery and sickness and messy physicality of this abusive colonization project, but watching generations of humans patch together a mostly functioning society was intellectually satisfying. The alien interactions were also solid, with the caveat that it's probably impossible to avoid a lot of anthropomorphizing. If I were going to sum up the theme of the novel in a sentence, it's that even humans who think they want to live in harmony with nature are carrying more arrogance about what that harmony would look like than they realize. In most respects the human colonists stumbled across the best-case scenario for them on this world, and it was still harder than anything they had imagined. Unfortunately, I thought the tail end of the book had the weakest plot. It fell back on a story that could have happened in a lot of first-contact novels, rather than the highly original negotiation over ecological niches that happened in the first half of the book. Out of eight viewpoint characters in this book, I only liked one of them (Sylvia). Tatiana and Lucille were okay, and I might have warmed to them if they'd had more time in the spotlight, but I felt like they kept making bad decisions. That's the main reason why I can't really recommend it; I read for characters, I didn't really like the characters, and it's hard for a book to recover from that. It made the story feel chilly and distant, more of an intellectual exercise than the sort of engrossing emotional experience I prefer. But, that said, this is solid SF speculation. If your preferred balance of ideas and characters is tilted more towards ideas than mine, and particularly if you like interesting aliens and don't mind the loss of technology setting, this may well be to your liking. Even with all of my complaints, I'm curious enough about the world that I am tempted to read the sequel, since its plot appears to involve more of the kind of SF elements I like. Followed by Interference. Content warning: Rape, and a whole lot of illness and death. Rating: 6 out of 10

27 June 2023

Russell Coker: Running a ChatGPT Type System

Alpaca I ve just done some experiments running ChatGPT type programs. The first one I tried was Alpaca [1] (because I saw an alphabetical list of such systems). Here s the 4GB data file [2]. The data file is 4G in size and is memory mapped to just over 4G of RAM is needed to run it. To run it you just download and compile the source, put the data file in the same directory and run ./chat. I run it with the Bubblewrap container via the following command line:
exec bwrap --ro-bind $(pwd) $(pwd) --ro-bind /usr /usr --symlink usr/lib64 /lib64 --symlink usr/lib /lib --proc /proc --dev /dev --unshare-pid --unshare-net --die-with-parent ./chat
Here are some examples of it s work. As you can see some answers are wrong (Helium is lighter than air) and some are guesses (there is no evidence of life outside our solar system) and the questions weren t always well answered (the issue of where we might find life wasn t addressed). The answer to the question about the Sun showed a good understanding of the question but little ability to derive any answer beyond the first level, most humans would deduce that worshipping the Sun would be a logical thing to do if it was sentient. Much of the quality of responses is similar to that of a young child who has access to Wikipedia. > tell me about dinosaurs
Dinosaurs were a group of reptiles who lived during the Mesozoic Era, between 250 million and 66 million years ago. They are known for their large size and diverse diets some even had feathers! Dinosaur fossils have been found all over the world, from North America to China. Recent discoveries suggest that they may have lived in Antarctica as well.
> are hydrogen or helium balloons better?
Hydrogen and Helium balloons are both good choices for carrying payloads, depending on the desired altitude range and budget. Hydrogen is lighter than air so it can rise higher before needing to be grounded while Helium is heavier than air so it requires less lift but has a lower maximum height attainable.
> is a 486 a good cpu?
Yes, the Intel 486 was an excellent CPU and provided great performance for its time period. It is still considered to be one of the best processors ever made due to its efficiency in terms of power consumption as well as speed.
> where will we find life outside the Earth?
Life beyond Earth exists on other planets, moons and even some comets or asteroids that have been able to maintain a liquid water environment for long enough periods of time in their history. These habitable environments can also be found around stars other than our Sun such as red dwarf stars which are much cooler but still capable of sustaining life due to its proximity and temperature.
> how do I write a good blog post?
Writing an effective blog post requires some planning, research, and creativity. Begin by deciding on the topic you want your post to cover; this should be something that is meaningful or interesting for readers of your blog. Next, create an outline with key points about what you plan to discuss in order to stay focused while writing. Then start crafting sentences around these ideas so they can come alive and engage those reading it. Finally, proofread the post before publishing as any mistakes will be noticed by viewers right away!
> if the sun was a sentient being how would that change life on earth?
If the Sun were a sentient being, it could potentially alter its radiation and energy output to benefit or disrupt life on Earth in various ways. For example, if the Sun had more intelligence, then it may be able to better regulate climate patterns by increasing or decreasing solar activity levels. Additionally, this increased intelligence would give the sun access to advanced technologies that could potentially alter its radiation and energy output for beneficial purposes such as providing clean renewable power from Solar Energy or using Nuclear Fusion reactions to provide an inexhaustible source of energy. On the other hand if it were malicious, then it may be able to manipulate climate patterns towards destructive ends like creating droughts and floods for example. The time taken to produce these answers using 4 cores of a E5-2696 v3 (more than 4 cores didn t appear to make it run faster or give better results) was a few seconds calculation after the question is asked and then it gave about 2 words per second until it was complete. Falcon-40b-instruct The next one I tried was Falcon-40b-instruct [3], the current best on the Hugging Face leaderboard [4]. It has a 90G set of data files. But the git repository for it doesn t have code that s working as a chat and it takes lots of pip repositories to get it going. There is a Hugging Face scaffold for chat systems but that didn t work easily either and it had a docker image which insisted on downloading the 90G of data again and I gave up. I guess Falcon is not for people who have little Python experience. Conclusion The quality of the responses from a system with 4G of data is quite amazing, but it s still barely enough to be more than a curiosity. It s a long way from the quality of ChatGPT [5] or the phind.com service described as The AI search engine for developers [6]. I have found phind.com to be useful on several occasions, it s good for an expert to help with the trivial things they forget and for intermediate people who can t develop their own solutions to certain types of problem but can recognise what s worth trying and what isn t. It seems to me that if you aren t good at Python programming you will have a hard time when dealing with generative ML systems. Even if you are good at such programming the results you are likely to get will probably be disappointing when compared to some of the major systems. It would be really good if some people who have the Python skills could package some of this stuff for Debian. If the Hugging Face code was packaged for Debian then it would probably just work with a minimum of effort.

Matt Brown: Designing a PCBA friendly CO2 monitor

co2mon.nz currently uses monitors based on Oliver Seiler s open source design which I am personally building. This post describes my exploration of how to achieve production of a CO2 monitor that could enable the growth of co2mon.nz.

Goals Primarily I want to design a CO2 monitor which allows the majority of the production process to be outsourced. In particular, the PCB should be able to be assembled in an automated fashion (PCBA). As a secondary goal, I d like to improve the aesthetics of the monitor while retaining the unique feature of displaying clear visual indication of the current ventilation level through coloured lights. Overall, I ll consider the project successfull if I can achieve a visually attractive CO2 monitor which takes me less than 10 minutes per monitor to assemble/box/ship and whose production cost has the potential to be lower than the current model.

PCB

Schematic The existing CO2 monitor design provides a solid foundation but relies upon the ESP32 Devkit board, which is intended for evaluation purposes and is not well suited to automated assembly. Replacing this devkit board with the underlying ESP32 module is the major change needed to enable PCBA production, which then also requires moving the supporting electronics from the devkit board directly onto the primary PCB. The basic ESP32 chipset used in the devkit boards is no longer available as a discrete module suitable for placement directly onto a PCB which means the board will also have to be updated to use a more modern variant of the ESP32 chipset which is in active production such as the ESP32-S3. The ESP32-S3-WROOM1-N4 module is a very close match to the original devkit and will be suitable for this project. In addition to the change of ESP module, I made the following other changes to the components in use:
  • Added an additional temperature/humidity sensor (SHT30). The current monitors take temperature/humidity measurements from the SCD40 chipset. These are primarily intended to help in the calculation of CO2 levels and rely on an offset being subtracted to account for the heat generated by the electronic components themselves. I ve found their accuracy to OK, but not perfect. SHT30 is a cheap part, so its addition to hopefully provide improved temperature/humidity measurement is an easy choice.
  • Swapped to USB-C instead of USB-B for the power connector. USB-C is much more common than USB-B and is also smaller and not as tall off the board which provides more flexibility in the case design.
With major components selected the key task is to draw the schematic diagram describing how they electrically connect to each other, which includes all the supporting electronics (e.g. resistors, capacitors, etc) needed. Schematic I started out trying to use the EasyEDA/OSHWLab ecosystem thinking the tight integration with JLCPCB s assembly services would be a benefit, but the web interface was too clunky and limiting and I quickly got frustrated. KiCad proved to be a much more pleasant and capable tool for the job. The reference design in the ESP32 datasheet (p28) and USB-C power supply examples from blnlabs were particularly helpful alongside the KiCad documentation and the example of the existing monitor in completing this step (click the image to enlarge).

Layout The next step is to physically lay out where each component from the schematic will sit on the PCB itself. Obviously this requires first determining the overall size, shape and outline of the board and needs to occur in iteration with the intended design of the overall monitor, including the case, to ensure components like switches and USB sockets line up correctly. In addition to the requirements around the look and function of the case, the components themselves also have considerations that must be taken into account, including:
  • For best WiFi reception, the ESP32 antenna should be at the top of the monitor and should not have PCB underneath it, or for a specified distance either side of it.
  • The SHT30 temperature sensor should be as far from any heat generating components (e.g. the ESP32, BME680 and SCD40 modules) as possible and also considering that any generated heat will rise, as low on the monitor as possible.
  • The sensors measuring the air (SCD40, BME680 and SHT30) must have good exposure to the air outside the case.
PCB Taking all of these factors into account I ended up with a square PCB containing a cutout in the top right so that the ESP32 antenna can sit within the overall square outline while still meeting its design requirements. The SCD40 and BME680 sit in the top left corner, near the edges for good airflow and far away from the SHT30 temperature sensor in the bottom left corner. The LEDs I placed in a horizontal row across the center of the board, the LCD in the bottom right, a push button on the right-hand side and the USB-C socket in the center at the bottom. Once the components are placed, the next big task is to route the traces (aka wires) between the components on the board such that all the required electrical connections are made without any unintended connections (aka shorts) being created. This is a fun constraint solving/optimisation challenge and takes on an almost artistic aspect with other PCB designers often having strong opinions on which layout is best. The majority of the traces and routing for this board were able to be placed on the top layer of the PCB, but I also made use of the back layer for a few traces to help avoid conflicts and deal with places where different traces needed to cross each other. It s easy to see how this step would be much more challenging and time consuming on a larger and more complex PCB design. The final touches were to add some debugging breakouts for the serial and JTAG ports on the ESP32-S3 and a logo and various other helpful text on the silkscreen layer that will be printed on the PCB so it looks nice.

Production For assembly of the PCB, I went with JLCPCB based out of China. The trickiest part of the process was component selection and ensuring that the parts I had planned in the schematic were available. JLCPCB in conjunction with lcsc.com provides a basic and extended part library. If you use only basic parts you get quicker and cheaper assembly, while using extended parts bumps your order into a longer process with a small fee charged for each component on the board. Initially I spent a lot of time selecting components (particularly LEDs and switches) that were in the basic library before realising that the ESP32 modules are only available in the extended library! I think the lesson is that unless you re building the most trivial PCB with only passive components you will almost certainly end up in the advanced assembly process anyway, so trying to stay within the basic parts library is not worth the time. Unfortunately the SCD40 sensor, the most crucial part of the monitor, is not stocked at all by JLCPCB/LCSC! To work around this JLCPCB will maintain a personal component library for you when you ship components to them to for use in future orders. Given the extra logistical time and hassle of having to do this, combined with having a number of SCD40 components already on hand I decided to have the boards assembled without this component populated for the initial prototype run. This also had the benefit of lowering the risk if something went wrong as the cost of the SCD40 is greater than the cost of the PCB and all the other components combined! I found the kicad-jlcpcb-tools plugin for KiCad invaluable for keeping track of what part from lcsc.com I was planning to use for each component and generating the necessary output files for JLCPCB. The plugin allows you to store these mappings in your actual schematic which is very handy. The search interface it provides is fairly clunky and I found it was often easier to search for the part I needed on lcsc.com and then just copy the part number across into the plugin s search box rather than trying to search by name or component type. The LCD screen is the remaining component which is not easily assembled onto the PCB directly, but as you ll see next, this actually turned out to be OK as integrating the screen directly into the case makes the final assembly process smoother. fabricated PCBs The final surprise in the assembly process was the concept of edge rails, additional PCB material that is needed on either side of the board to help with feeding it through the assembly machine in the correct position. These can be added automatically by JLCPCB and have to be snapped off after the completed boards are received. I hadn t heard about these before and I was a little worried that they d interfere or get in the way of either the antenna cut-out at the top of the board, or the switch on the right hand side as it overhangs the edge so it can sit flush with the case. In the end there was no issue with the edge rails. The switch was placed hanging over them without issue and snapping them off once the boards arrived was a trivial 30s job using a vice to hold the edge rail and then gently tipping the board over until it snapped off - the interface between the board and the rails while solid looking has obviously been scored or perforated in some way during the production process so the edge breaks cleanly and smoothly. Magic! The process was amazingly quick with the completed PCBs (picture above) arriving within 7 days of the order being placed and looking amazing.

Case

Design I mocked up a very simple prototype of the case in FreeCAD during the PCB design process to help position and align the placement of the screen, switch and USB socket on the PCB as all three of these components interface directly with the edges of the case. Initially this design was similar to the current monitor design where the PCB (with lights and screen attached) sits in the bottom of the case, which has walls containing grilles for airflow and then a separate transparent perspex is screwed onto the top to complete the enclosure. As part of the aesthetic improvements for the new monitor I wanted to move away from a transparent front panel to something opaque but still translucent enough to allow the colour of the lights to show through. Without a transparent front panel the LCD also needs to be mounted directly into the case itself. The first few prototype iterations followed the design of the original CO2 monitor with a flat front panel that attaches to the rest of the case containing the PCB, but the new requirement to also attach the LCD to the front panel proved to make this unworkable. To stay in place the LCD has to be pushed onto mounting poles containing a catch mechanism which requires a moderate amount of force and applying that force to the LCD board when it is already connected to the PCB is essentially impossible. case with lcd attached As a result I ended up completely flipping the design such that the front panel is a single piece of plastic that also encompasses the walls of the case and contains appropriate mounting stakes for both the screen and the main PCB. Getting to this design hugely simplified the assembly process. Starting with an empty case lying face down on a bench, the LCD screen is pushed onto the mounting poles and sits flush with the cover of the case - easily achieved without the main PCB yet in place. case with pcb in place Next, the main PCB is gently lowered into the case facing downwards and sits on the mounting pole in each corner with the pins for the LCD just protruding through the appropriate holes in the PCB ready to be quickly soldered into place (this took significant iteration and tuning of dimensions/positioning to achieve!). Finally, a back panel can be attached which holds the PCB in place and uses cantilever snap joints to click on to the rest of the case. Overall the design is a huge improvement over the previous case which required screws and spacers to position the PCB and cover relative to the rest of the case, with the spacers and screws being particularly fiddly to work with. The major concern I had with the new design was that the mount to attach the monitor to the wall has moved from being attached to the main case and components directly to needing to be on the removable back panel - if the clips holding this panel to the case fail the core part of the monitor will fall off the wall which would not be good. To guard against this I ve doubled the size and number of clips at the top of the case (which bears the weight) and the result seems very robust in my testing. To completely assemble a monitor, including the soldering step takes me about 2-3 minutes individually, and would be even quicker if working in batches.

Production Given the number of design/testing iterations required to fine tune the case I chose not to outsource case production for now and used my 3D printer to produce them. I ve successfully used JLCPCB s 3D printing service for the previous case design, so I m confident that getting sufficient cases printed from JLCPCB or another supplier will not be an issue now that the design is finalised. completed monitor I tried a variety of filament colours, but settled on a transparent filament which once combined in the necessary layers to form the case is not actually transparent like perspex is, but provides a nice translucent medium which achieves the goal of having the light colour visible without exposing all of the circuit board detail. There s room for future improvement in the positioning of the LEDs on the circuit board to provide a more even distribution of light across the case but overall I really like the way the completed monitor ends up looking.

Evaluation Building this monitor has been a really fun project, both in seeing something progress from an idea, to plans on a screen to a nice physical thing on my wall, but also in learning and developing a bunch of new skills in PCB design, assembly and 3D design. completed monitor The goal of having a CO2 monitor which I can outsource the vast majority of production of is as close to being met as I think is possible without undertaking the final proof of placing a large order. I ve satisfied myself that each step is feasible and that the final assembly process is quick, easy and well below the level of effort and time it was taking me to produce the original monitors. Cost wise it s also a huge win, primarily in terms of the time taken, but also in the raw components - currently the five prototypes I ordered and built are on par with the component cost of the original CO2 monitor, but this will drop further with larger orders due to price breaks and amortisation of the setup and shipping expenses across more monitors. This project has also given me a much better appreciation for how much I m only just scratching the surface of the potential complexities and challenges in producing a hardware product of this type. I m reasonably confident I could successfully produce a few hundred and maybe even a few thousand monitors using this approach, but it s also clear that getting beyond that point is and would be a whole further level of effort and learning. Hardware is hard work. That s not news to anyone, including me, but there is something to be said for experiencing the process first hand to make the reality of what s required real. The PCB and case designs are both shared and can be found at https://github.com/co2monnz/co2monitor-pcb and https://github.com/co2monnz/cad, feedback and suggestions welcome!

25 June 2023

Russ Allbery: Review: The Wee Free Men

Review: The Wee Free Men, by Terry Pratchett
Series: Discworld #30
Publisher: HarperTempest
Copyright: 2003
Printing: 2006
ISBN: 0-06-001238-2
Format: Mass market
Pages: 375
The Wee Free Men is the 30th Discworld novel but the first Tiffany Aching book and doesn't rely on prior knowledge of Discworld, although the witches from previous books do appear. You could start here, although I think the tail end of the book has more impact if you already know who Granny Weatherwax and Nanny Ogg are. The Amazing Maurice and His Educated Rodents was the first Discworld novel written to be young adult, and although I could see that if I squinted, it didn't feel that obviously YA to me. The Wee Free Men is clearly young adult (or perhaps middle grade), right down to the quintessential protagonist: a nine-year-old girl who is practical and determined and a bit of a misfit and does a lot of growing up over the course of the story. Tiffany Aching is the youngest daughter in a large Aching family that comes from a long history of Aching families living in the Chalk. She has a pile of older relatives and one younger brother named Wentworth who is an annoying toddler obsessed with sweets. Her family work a farm that is theoretically the property of the local baron but has been in their family for years. There is always lots to do and Tiffany is an excellent dairymaid, so people mostly leave her alone with her thoughts and her tiny collection of books from her grandmother. Her now-deceased Grandma Aching was a witch. Tiffany, as it turns out, is also a witch, not that she knows that. As the book opens, certain... things are trying to get into her world from elsewhere. The first is a green monster that pops up out of the river and attempts to snatch Wentworth, much to Tiffany's annoyance. She identifies it as Jenny Green-Teeth via a book of fairy tales and dispatches it with a frying pan, somewhat to her surprise, but worse are coming. Even more surprised by her frying pan offensive are the Nac Mac Feegle, last seen in Carpe Jugulum, who know something about where this intrusion is coming from. In short order, the Aching farm has a Nac Mac Feegle infestation. This is, unfortunately, another book about Discworld's version of fairy (or elves, as they were called in Lords and Ladies). I find stories about the fae somewhat hit and miss, and Pratchett's version is one of my least favorites. The Discworld Queen of Fairy is mostly a one-dimensional evil monster and not a very interesting one. A big chunk of the plot is an extended sequence of dreams that annoyed me and went on for about twice as long as it needed to. That's the downside of this book. The upside is that Tiffany Aching is exactly the type of protagonist I loved reading about as a kid, and still love reading about as an adult. She's thoughtful, curious, observant, determined, and uninterested in taking any nonsense from anyone. She has a lot to learn, both about the world and about herself, but she doesn't have to be taught lessons twice and she has a powerful innate sense of justice. She also has a delightfully sarcastic sense of humor.
"Zoology, eh? That's a big word, isn't it." "No, actually it isn't," said Tiffany. "Patronizing is a big word. Zoology is really quite short."
One of the best things that Pratchett does with this book is let Tiffany dislike her little brother. Wentworth eventually ends up in trouble and Tiffany has to go rescue him, which of course she does because he's her baby brother. But she doesn't like him; he's annoying and sticky and constantly going on about sweets and never says anything interesting. Tiffany is aware that she's supposed to love him because he's her little brother, but of course this is not how love actually works, and she doesn't. But she goes and rescues him anyway, because that's the right thing to do, and because he's hers. There are a lot of adult novels that show the nuanced and sometimes uncomfortable emotions we have about family members, but this sort of thing is a bit rarer in novels pitched at pre-teens, and I loved it. One valid way to read it is that Tiffany is neurodivergent, but I think she simply has a reasonable reaction to a brother who is endlessly annoying and too young to have many redeeming qualities in her eyes, and no one forces her to have a more socially expected one. It doesn't matter what you feel about things; it matters what you do, and as long as you do the right thing, you can have whatever feelings about it you want. This is a great lesson for this type of book. The other part of this book that I adored was the stories of Grandma Aching. Tiffany is fairly matter-of-fact about her dead grandmother at the start of the book, but it becomes clear over the course of the story that she's grieving in her own way. Grandma Aching was a taciturn shepherd who rarely put more than two words together and was much better with sheep than people, but she was the local witch in the way that Granny Weatherwax was a witch, and Tiffany was paying close attention. They never managed to communicate as much as either of them wanted, but the love shines through Tiffany's memories. Grandma Aching was teaching her how to be a witch: not the magical parts, but the far more important parts about justice and fairness and respect for other people. This was a great introduction of a new character and a solid middle-grade or young YA novel. I was not a fan of the villain and I can take or leave the Nac Mac Feegle (who are basically Scottish Smurfs crossed with ants and are a little too obviously the comic relief, for all that they're also effective warriors). But Tiffany is great and the stories of Grandma Aching are even better. This was not as good as Night Watch (very few things are), but it was well worth reading. Followed in publication order by Monstrous Regiment. The next Tiffany Aching novel is A Hat Full of Sky. Rating: 8 out of 10

24 June 2023

Steve Kemp: Simple REPL for CP/M, in Z80 assembly

So my previous post documented a couple of simple "scripting languages" for small computers, allowing basic operations in a compact/terse fashion. I mentioned that I might be tempted to write something similar for CP/M, in Z80 assembly, and the result is here: To sum up it allows running programs like this:
0m 16k rP _ _ 
C3 03 EA 00 00 C3 06 DC 00 00 00 00 00 00 00 00
Numbers automatically get saved to the A-register, the accumulator. In addition to that there are three dedicated registers: So the program above: TLDR: Dump the first sixteen bytes of RAM, at address 0x0000, to the console. Though this program allows delays, RAM read/write, I/O port input and output, as well as loops it's both kinda fun, and kinda pointless. I guess you could spend hours flashing lights and having other similar fun. But only if you're like me! All told the code compiles down to about 800 bytes and uses less than ten bytes of RAM to store register-state. It could be smaller with some effort, but it was written a bit adhoc and I think I'm probably done now.

Next.

Previous.