Search Results: "ag"

5 June 2014

John Sullivan: GPG keysigning and government identification

Please stop recommending that checking government-issued ID is a good way to verify someone's identity before signing their GPG key. Have you been a US bartender before? Or held any other position where you've had to verify an ID? It's not an easy thing to do. People in those positions have books of valid IDs from different states. They have lights that show the security marks. They still get it wrong regularly. A very amateur fake ID, or borrowed real ID, will fool just about everyone in any informal context. What's even worse is that people have a habit of happily looking at passports from other countries than their own, and nodding knowingly. It's fun, but be honest, you have no idea what you're doing. How about just signing keys with people you would actually say you know well enough to trust? It's not the Web of Amateur ID Checking. ID checking is at best ineffective against the threats it's supposed to address, and is probably actually damaging to the Web of Trust because of the false sense of security. No idea what I'm talking about? Learn to encrypt your email by reading the FSF's new Email Self-Defense Guide, published in honor of today's Reset The Net effort.

Dirk Eddelbuettel: RcppArmadillo 0.4.300.8.0

A new minor / bug fix release 4.300.8 of Armadillo, the templated C++ library for linear algebra, was tagged by Conrad in his SVN repo a few days ago, following earlier snapshots in the 4.300.* series. We had prepared two earlier releases for GitHub but not CRAN in order to accomodate the CRAN maintainer's desire of "a release every one to two months" expressed in the CRAN Repo Policy. However, two actual bugs in the interaction between MinGW and C++11 were reported on the rcpp-devel mailing list, and this releases addresses these. Hence time for new release 0.4.300.8.0 of RcppArmadillo which is now on CRAN and in Debian. This release brings a few upstream changes detailed below such as nice new upstream changes such as more robust norm() (and related) functions, and fixes related to matrix and cube interactions. From our end, we added a better detection of Windows via both _WIN32 and WIN32 (as the former apparently gets undefined by MinGW in C++11 mode). We also added the ability to turn on C++11 support from R (possible since R 3.1.0) yet also turn it off for Armadillo. This is needed as the prescribed compiler on Windows is g++ 4.6.2 -- which offers a subset of C++11 which is good enough for a number of things from the C++11 standard, but not advanced enough for everything which Armadillo uses when C++11 support is turned on. As Armadillo continues to offer a choice of C++ standards, we can use the ability to deploy C++11 only outside of its internals. It is worth repeating that this issue should only affect Windows users wishing to use C++11; other platforms are fine as they generally have more modern compilers.
Changes in RcppArmadillo version 0.4.300.8.0 (2014-05-31)
  • Upgraded to Armadillo release Version 4.300.8 (Medieval Cornea Scraper)
    • More robust norm-related functions
    • Fixes between interactions between cube and vector types.
  • Adds a #define ARMA_DONT_USE_CXX11 to provide an option to turn C++11 off for Armadillo (but client packages may still use it)
  • More robust Windows detection by using _WIN32 as well as WIN32 as the latter gets diabled by MinGW with C++11
  • On Windows, C++11 can be turned off as the Armadillo code base uses more features of C++11 than g++ 4.6.2 version in Rtools implements
Changes in RcppArmadillo version 0.4.300.5.0 (2014-05-19)
  • Upgraded to Armadillo release Version 4.300.5 (Medieval Cornea Scraper)
    • Handle possible underflows and overflows in norm(), normalise(), norm_dot()
    • Fix for handling of null vectors by norm_dot()
Changes in RcppArmadillo version 0.4.300.2.0 (2014-05-13)
  • Upgraded to Armadillo release Version 4.300.2 (Medieval Cornea Scraper)
    • faster find()
Courtesy of CRANberries, there is also a diffstat report for the most recent release As always, more detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

4 June 2014

Daniel Pocock: Trialing the xTuple/PostBooks next generation web UI

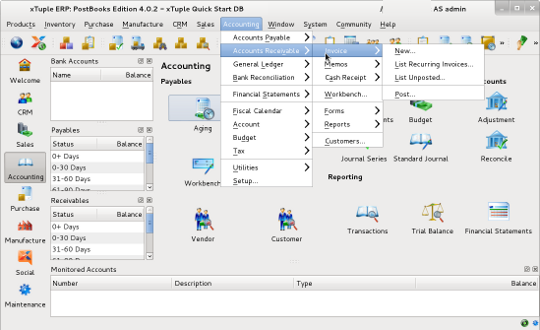
For some time I've been using PostBooks to keep track of finances. The traditional PostBooks system has a powerful Qt GUI. The xTuple team have been hard at work creating a shiny new web-based user interface. The traditional UI has no dedicated server - all users communicate directly with the PostgreSQL database where stored procedures and triggers ensure the correct logic is applied. The new model provides an xTuple application server that can handle requests from web users and potentially other third-party apps too. Who is it for? Some people may feel that the web UI is intended to appeal to mobile users. While it is useful for mobile and tablet devices, this is not strictly the aim, John has discussed this in a blog. One benefit of the web UI is that accountants and book-keepers do not need to have a copy of every exact PostBooks version that every client is using. Given that many people only need their accountant to look at their books for just a few hours at the end of each year, the ease of access with a web UI will make a big difference. Installing it quickly The xTuple Git repository provides a script to install the whole server quickly. Initially it just supported a single Ubuntu release, I just contributed some tweaks to generalize it for Debian wheezy and potentially other releases. It doesn't appear too difficult to generalize it further for Fedora or RHEL users. To get going, I recommend trying it in a fresh virtual machine, either in a server environment or desktop VirtualBox solution. The installation script will install various packages on the machine and mess about with the PostgreSQL setup so you will not want to run the automated setup script on any machine where you have existing databases. Once the virtual machine is setup, make sure sudo is installed and configured:
# apt-get install sudo
# visudo
and then run the install as your normal user:
git clone --recursive git://github.com/xtuple/xtuple.git
cd xtuple
git remote add XTUPLE git://github.com/xtuple/xtuple.git
git fetch XTUPLE
git checkout git describe --abbrev=0
chmod a+x scripts/install_xtuple.sh
scripts/install_xtuple.sh
If all goes well, 5-10 minutes later it is ready to run:
cd node-datasource
node main.js
The port numbers will appear on the screen and you can connect with a web browser. Trying it out Despite my comments above to the effect that this is not primarily aimed at mobile, the first and second device I tested with were both mobile devices, Samsung Galaxy S3 and a Samsung Galaxy Note 3. I feel the Note is far better for this type of application, primarily due to screen size and the fact that most of the forms in the application have fields that launch popup menus. It appears to work in both Chrome and Firefox on these devices. One handy feature is that the mobile device can dial numbers directly from the CRM address book, this is facilitated with the tel URI. My impression is that this is still a product that is in the final stages of development, although some people will be able to use it almost immediately. One significant thing to note is that the database schema is very stable due to the long history of the traditional xTuple/PostBooks products.

Junichi Uekawa: gnome-screensaver isn't installed.

gnome-screensaver isn't installed. gnome package doesn't seem to depend on that, and gnome-screensaver doesn't start up by default. If it's not running screensaver / lockscreen doesn't seem to appear. Hmm.. how is it supposed to work ?

Russell Coker: Android Device Service Life

In recent years Android devices have been the most expensive things I ve purchased apart from airline tickets and other travel/holiday expenses. As they are expensive I d like to use them for as long as possible to get the most value for money. Also as I give my devices to relatives when they no longer work for me I d like to avoid having relatives hassling me about their phone not working as desired. So I ve been thinking about the features that I need to make it possible to use a phone or tablet for a long time. RAM The way Android works is that when an application in the foreground requests more memory background applications may be closed to free some memory. Android doesn t use swap by default, there is some documentation on how to enable it (and it s not difficult to figure out for anyone who has used Linux before) but generally it s not done. If you run a larger application the chances of apps closing in the background (causing delays when you switch back to them and possibly a loss of context if the app is buggy and doesn t preserve all state) are increased. As a general trend apps tend to get bigger to provide more features and also because users who own newer bigger devices don t complain as much about memory use. Also to make things worse new versions of Android tend to use more RAM. So a phone that runs well can suddenly start performing badly when you upgrade to a new version of Android (which incidentally usually can t be reversed) and upgrade to new versions of apps (which can t be reversed through the Google Play Store). The Sony Ericsson Xperia X10 was a very nice phone when it was released, it ran Android 2.1 very quickly. When I upgraded the Xperia X10s that my wife and I used to Android 2.3 (which was necessary to have the phone run as a Wifi access point) performance dropped considerably. The Android upgrade combined with newer larger apps means that those phones are barely usable now. 384M of RAM was plenty in early 2011 when I first used the Xperia X10 but it s not nearly enough now. Recently 2G of RAM has been the minimum for a mid-range or high-end phone. It seems difficult to imagine a new Android feature as compelling as the addition of Wifi access point support in Android 2.3 that would drive an upgrade to a future memory hogging version of the OS. It also seems difficult to imagine Android apps needing enough memory to destroy the performance of a phone with 2G of RAM. But then I couldn t imagine the 384M in an Xperia X10 becoming inadequate or the 512M in a Samsung Galaxy S becoming barely usable either. Storage Until fairly recently storage in an Android device was divided into USB attached storage (a VFAT filesystem that could be directly mounted on a PC) and a Linux filesystem that was used for all internal operations of the phone. On such devices it typically wasn t possible to change partition sizes without a lot more skill than most users possess and most of the storage space was reserved for USB attachment. If you only had a few Android apps and lots of photos, movies, etc then this worked well. But if you wanted to install larger Android apps then you would have big problems. Even with Android 4.x devices (which all seem to have a single filesystem) you can easily run out of space. Modern games often take several hundred megs of storage. Games that take 500M+ for the Android package install (which also requires the same amount of temporary space for installation and upgrade) are common. Sometimes games download data files after they have been installed for a total size approaching 2G (such as The Sims Freeplay). When I bought a Nexus 4 for my wife I got the version with 8G of storage because paying an extra $50 for the 16G version seemed unreasonable. 8G was fine for my wife, but when she got a new phone I gave the Nexus 4 to a relative who wanted to play The Sims and other big games. That relative isn t so happy about having a limited number of games on their phone and I have to fix it when storage space runs out and things start aborting (when storage runs out the Google App Store program aborts and uses lots of space for temporary files). I recently bought a tablet with 32G of storage and filled 16G on the first day (tablets are good for watching
TV and TV shows are big). Fortunately the tablet in question has a SD socket so that when space becomes a problem in a year or two I can buy an SD card and keep using it. An unfortunate recent decision by Google was to prevent apps from being run from a SD card. So even if you have a device with a SD socket you still need to have enough internal storage for all apps and their private data. At 500M+ for a modern game that means a device with 8G of storage (which includes space for the OS) will be lucky to get 8 games installed. If you want to use a phone to it s full capacity (playing various media files, games, etc) then it seems that the minimum storage capacity would be 8G of internal storage and a SD socket. For a device without an SD socket (such as the Nexus 5 with 16G or 32G of storage) your future use will be limited. 32G is probably enough for a phone given that you can recode movies to use less space (the FullHD screen on the Nexus 5 is nice but 720p movies will probably look good enough). But the larger screens of tablets demand better video quality so the Nexus tablets are probably a bad choice due to lack of storage space. Screen Size and Resolution I have previously written about the sizes of devices and how they may be used by people of various ages [1]. That should be of use for anyone who plans to use their old phone as an educational device for their children (which appears to be very common). But apart from that I can t think of any reason why size would suddenly make an old phone obsolete. Only young children will have their hands change size in any significant way. Resolution also shouldn t be a huge problem, the 480*854 screen on the Xperia X10 is fairly good for a 4 screen. While a higher resolution makes text more readable at a small size for most users the availability of a higher resolution screen isn t going to make their old phone obsolete. CPU The only Android devices I owned that appeared to develop CPU speed issues late in life were the Xperia X10 phones, and that might be more due to RAM limits and the OS upgrade. All the other devices were either obviously slow at purchase time or are still performing well now. CPU speed may make it difficult or impossible to play new games, but shouldn t affect other uses of a phone or tablet. Conclusion It seems to me that if you want to use an Android device for more than 2 years then storage capacity should be a major factor in choosing which device to purchase. It seems that lack of storage space is in many cases the main factor that makes older devices annoying or impossible to use.

Dirk Eddelbuettel: Introducing RPushbullet

A new package of mine appeared on CRAN today: RPushbullet. A few days ago, I had tweeted about a first version available via its GitHub repo. The package is now on CRAN which will make it easier to install for many. You still need an API key (free, after registration at Pushbullet) and one or more target devices to message to: an modern smartphone (Android, iPhone, ...) or a Chrome browser provided you also installed the corresponding app. I also set up a short web page on my server with some more information and an example. So pushbullet away...

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 June 2014

Sune Vuorela: Bringing KDE forward

The almost-yearly large KDE-sprint in Randa, Switzerland is doing a fundraiser to get this year s event running. See http://www.kde.org/fundraisers/randameetings2014/ This year, it is besides the recurring multimedia topics, a lot about improving the new KDE Frameworks, the related documentation and the development experience with IDE s and such. It is also a good way to come full circle, since it was back in 2011 when I was at the Randa Meetings that the KDE Frameworks initiative was started. So once again: http://www.kde.org/fundraisers/randameetings2014/

Vasudev Kamath: Using WSME with Flask microframework

After reading Julien Danjou's I found out WSME (Web Service Made Easy) a Python framework which allows us to easily create Web Services in Python. For SILPA we needed a REST like interface and I thought of giving it try as WSME readily advertised the Flask integration, and this post was born when I read the documentation for Flask integration. First of all Flask is a nice framework which will right way allow development of REST api for simple purposes, but my requirement was bit complicated where I had to expose function in a separate python modules through SILPA. I think detailed requirement can be part of another post, so let me explain how to use WSME with Flask app. WSME integration with Flask is done via decorator function wsmeext.flask.signature which expects you to provide it with signature of function to expose. And here is its documentation, basically signature of signature function is
wsmeext.flask.signature(return_type, *arg_types, **options)
Yeah thats all docs have sadly. So basically exposing is the only thing WSME handles for us here, routing and other stuffs need to be done by Flask itself. So lets consider a example, simple function to add as shown below.
def add(a, b):
    return a + b
For providing REST like service, all you need below code.
from flask import Flask
from wsmeext.flask import signature
app = Flask(__name__)
@app.route('/add')
@signature(int, int, int)
def add(a, b):
    return a + b
if __name__ == '__main__':
       app.run()
So first argument to signature is return type of function and rest arguments are the argument to function to be exposed. Now you can access the newly exposed service by visiting http://localhost:5000/add but don't forget to pass the arguments either via query string or through post. You can restrict methods of access via Flask's route. So what's the big deal of not having docs right?.. Well fun part began when we use bit more complex return type like dictionaries or lists . Below is modified code I'm using to demonstrate problem I faced during using dict as return type.
from flask import Flask
from wsmeext.flask import signature
app = Flask(__name__)
@app.route('/add')
@signature(dict, int, int)
def add(a, b):
    return  "result": a + b 
if __name__ == '__main__':
    app.run()
Basically I'm returning a dictionary containing result now, for demonstration purpose. When I run the application boom python barked at me with following message.
Traceback (most recent call last):
File "wsme_dummy.py", line 7, in <module>
 @signature(dict, int, int)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsmeext\flask.py", line 48, in decorator
 funcdef.resolve_types(wsme.types.registry)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsme\api.py", line 109, in resolve_types
 self.return_type = registry.resolve_type(self.return_type)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsme\types.py", line 739, in resolve_type
 type_ = self.register(type_)
File "c:\Users\invakam2\.virtualenvs\wsmetest\lib\site-packages\wsme\types.py", line 668, in register
 class_._wsme_attributes = None
TypeError: can't set attributes of built-in/extension type 'dict'
After going through code from files involved in above traces this is what I found
  1. wsmeext.flask.signature inturn uses wsme.signature which is just alias of wsme.api.signature.
  2. Link in documentation in sentence See @signature for parameter documentation is broken and should actually link to wsme.signature in docs.
  3. wsme.signature actually calls resolve_type to check on types of return and arguments. This function checks if types are instance of dict or list in such cases it creates instances of wsme.type.DictType and wsme.type.ArrayType respectively with values from the argument.
  4. When I just passed built-in type dict the control went to else part which just passed the type to wsme.type.Register.registry function which tries to set the attribute _wsme_attribute which actually raises TypeError as we can't set attribute for built-in types.
So by inspecting code of wsme.type.Registry.resolve_type and wsme.type.Registry.register its clear that what signature expects when arguments or return type is dictionary/list is instance of dictionary/list with type of value in it. May be sentence is bit vague but I'm not sure how to put it more clearly, as an example in our case add function returns dictioanry with key as string and value as int, so return type argument for signature will be str: int . Similarly if you return array with int values it will be [int]. With above understanding our add function now looks like below.
@signature( str: int , int, int)
def add(a, b):
   return  'result': a + b 
and now code worked just fine!. What I couldn't figure out here is there is no way to have tuple as return value or argument, but I guess that is not big deal. So immidiate task for me after finding this is fix the link in documentation to point to wsme.signature and probably put some note some where in documentation about above finding.

Holger Levsen: 2014-06-03-systemd-mostly-harmless

so, systemd now and teh world still turns... So, two days ago I rebooted my wheezy system into systemd and what shall I say, it was+is like the last Debian stable updates: boring. It just works. Kudos for all those who made this happen! I've one lazyweb question: what reasons are there for me to try out systemd from wheezy-backports? Plus another observation from maintaining piuparts.d.o: currently all major desktops in jessie (with the exception of cinnamon (which may or may not deserve the label 'major'...) depend on 'systemd-sysv', IOW: it's not just GNOME, which needs a modern initsystem.

Daniel Pocock: Click to dial for mobile users of your web sites

If there was a trivial way to let mobile phone users call you from your web site, just by adding a single HTML element to the page, would you do it? In fact, there is. It doesn't even require a mobile WebRTC browser. It works for virtually any smartphone and a growing number of desktops too. Introducing the tel: URI The tel: URI is defined in RFC 3966. For most mobile phone users, if they click a link to a tel: URI, their browser will copy the link into their dialer for convenience. To protect users against calls to 0900 premium rate numbers, the user still has to make one more click to confirm they want to dial. Examples Here is a tel: URI:
tel:+44-20-7135-7070
Here is how to create a link with it: <a href="tel:+44-20-7135-7070">020 7135 7070 (from abroad: +44 20 7135 7070)</a> and here is how it looks on the page:
Call me on 020 7135 7070 (from abroad: +44 20 7135 7070)
(Note: some planet aggregation sites block the link in the example) and here is what appears on the mobile device after a user clicks the tel: URI link: For desktop users too Many desktop users can also benefit from tel: URIs. If they have a modern telephone system in their office, the system administrator may have already added a tel: URI handler to their desktop. Anyone with a software PBX or a SIP account can also potentially use the TBDialOut extension for Thunderbird to help convert address book phone numbers into tel: or sip: URIs or even URLs for some bespoke dialer. For those who want extra convenience, the Telify extension for Firefox will look for phone numbers in any HTML page and display them as tel: URIs so you can click them even if the web developer overlooked this.

2 June 2014

Rapha&#235;l Hertzog: My Free Software Activities since January 2014

If you follow my blog closely, you noticed that I skipped all my usual monthly summaries in 2014. It s not that I stopped doing free software work, instead I was just too busy to be able to report about what I did. As an excuse, let me tell you that we just moved into a new house which was in construction since may last year. The lack of visible activity on my blog resulted in a steady decrease of the amount of donations received (January: 70.72 , February: 71.75 , March: 51.25 , April: 39.9 , May: 40.33 ). Special thanks to all the people who kept supporting my work even though I stopped reporting about it. So let s fix this. This report will be a bit less detailed since it covers the whole period since the start of the year. Debian France Preparations related to general assemblies. The year started with lots of work related to Debian France. First I took care of setting up limesurvey with Alexandre Delano to handle the vote to pick our new logo:
The new logo of Debian France I also helped Sylvestre Ledru to finalize and close the accounting books for 2013 in preparation for the general assembly that was due later in the month. I wrote the moral report of the president to be presented to the assembly. And last step, I collected vote mandates to ensure that we were going to meet the quorum for the extraordinary assembly that was planned just after the usual yearly assembly. The assemblies took place during a two days mini-debconf in Paris (January 17-18) where I was obviously present even though I gave no talk besides announcing the logo contest winner and thanking people for their participation.
Assembl e g n rale 2014 de Debian France

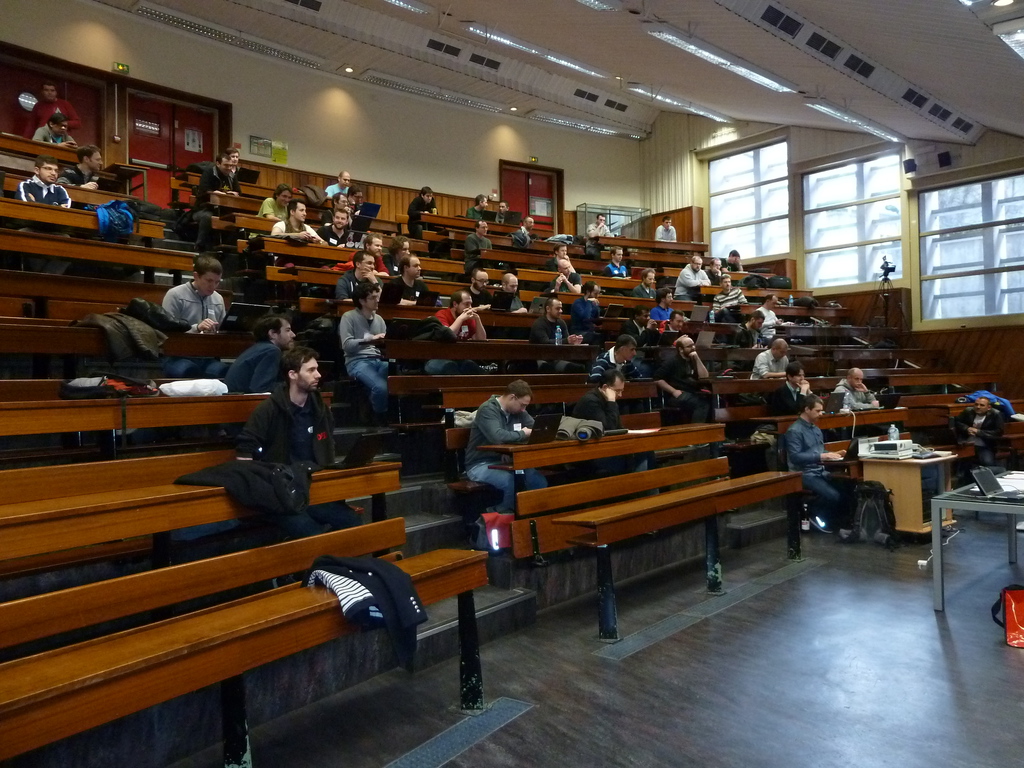
The Debian France members during the general assembly

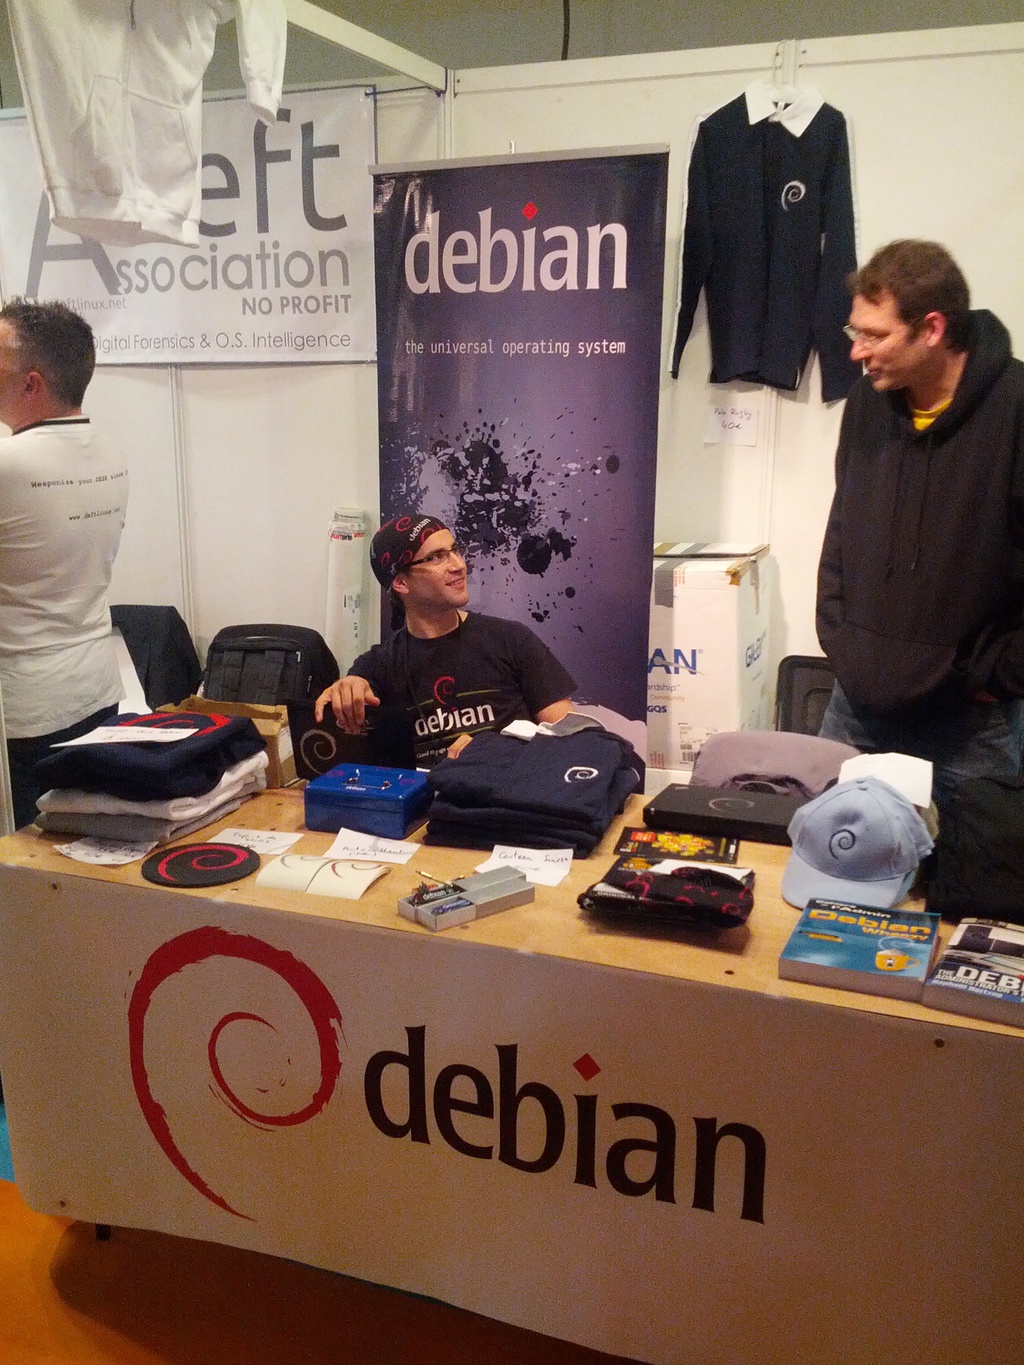
It s worth noting that the extraordinary assembly was meant primarily to enshrine in our bylaws the possibility to act as a trusted organization for Debian. This status should be officialized by the Debian project leader (Lucas Nussbaum) in the upcoming weeks since we answered satisfactorily to all questions. Our paypal donation form and the accounting tools behind it are ready. Galette packaging and members map. I managed to hand over the package maintenance of galette to Fran ois-R gis Vuillemin. I sponsored all his uploads and we packaged a new plugin that allows to create a map with all the members who accept to share their location. The idea was to let people meet each other when they don t live far away with the long term goal to have Debian France organized activities not only in Paris but everywhere in France. New contributor game. Last but not least, I organized a game to encourage people to do their first contribution to Debian by offering them a copy of my book if they managed to complete a small Debian project. We got many interesting projects but the result so far seem to be very mixed. Many people did not complete their project (yet) that said for the few that did substantial work, it was rather good and they seem to be interested to continue to contribute. Debian France booth at Solutions Linux in Paris. Like each year, I spent two days in Paris to help man the Debian France booth at Solutions Linux. We had lots of goodies on sale and we made more than 2000 EUR in earnings during the two days. I also used this opportunity to try to convince companies to support the new Debian LTS effort.
Debian France booth at Solutions Linux

Tanguy Ortolo and Fernando Lagrange behind the Debian France booth

The Debian Administrator s Handbook In the last days of 2013, we released the wheezy update of the book. Then I quickly organized everything needed so that the various translation teams can now focus their efforts on the latest release of the book. Later (in February) I announced the availability of the French and Spanish translations. Debian Squeeze LTS When the security team called for help to try to put in place long term support for Squeeze, I replied positively because I m convinced that it s very important if Debian wants to stay an acceptable choice in big deployments and because I knew that some of my customers would be interested Thus I followed all the discussions (on a semi-private list first and then on debian-lts@lists.debian.org) and contributed my own experience. I have also taken up the responsibility to coordinate with the Debian contributors who can be hired to work on Squeeze LTS so that we have a clear common offer for all the companies who have offered financial support towards Squeeze LTS. Expect further news on this front in the upcoming days/weeks. Tryton I have been a long time user of SQL-Ledger to manage the accounting of my company Freexian. But while the license is free software, the project is not. It s the work of a single developer who doesn t really accept help. I have thus been considering to move to something else for a long time but never did anything. This year, after some rough evaluation, I decided to switch to Tryton for my company. It s probably not a wise choice from a business perspective because that migration took me many hours of unpaid labor but from a free software perspective it s definitely better than everything else I saw. I contributed a lot of bug reports and a few patches already (#3596, #3631, #3633, #3665, #3667, #3694, #3695, #3696, #3697) mainly about problems found in the French chart of accounts but also about missing features for my use case. I also accepted to sponsor Matthias Berhle, who is maintaining the official Debian packages of Tryton. He s already a Debian maintainer so it s mainly a matter of reviewing new source packages and granting him the required rights. Misc Debian work Thanks See you next month for a new summary of my activities.

2 comments Liked this article? Click here. My blog is Flattr-enabled.

B lint R czey: I Can Hear Music again (thanks to forked-daapd/Debian)

When I started looking for a lightweight solution of serving a music library over LAN I did not expect so many complications. I expected it not to be a unique need to have something running on a SheevaPlug straight from the Debian repository. Apparently it kind of was. Debian used to have mt-daapd (popcon: 165), but now it is available from oldstable only and upstream is dead. There is tangerine (popcon: 98) with its Mono dependencies and GUI which seemed to me overkill and more like a demo of a networked application written in Mono than a music library server. The most promising candidate was forked-daapd (popcon: 220) but it was far from being a true winner. First, it had a series of dead upstreams. At the beginning it was forked from mt-daapd (hence the name) by Julien Blache who also served as the prior Debian maintainer. Then the code base was forked and converted to use Grand Central Dispatch. Then the GCD fork died off slowly as well a few years ago. When I found the package it had been unmaintained for a few years and was based on the GCD branch which prevented building it on many architectures and the server itself was crashing or quitting occasionally. Luckily there still existed a fork thanks to Espen J rgensen which was well maintained and could serve as a way out but examining it closely it turned out that it had switched to libevent from GCD but to a version (1.4) which is present only in oldstable! And some say Debian s software versions are ancient ;-). Moreover it was not simply libevent 1.4-based, but it included some heavily patched parts of it. Espen also liked the idea of packaging his version in Debian and we extracted the patches to libevent and slowly got them accepted to libevent s master. Forked-daapd s master works best with libevent 2.1.4-alpha, but thanks to Espen the development branch now also works with libevent 2.0.x giving up some performance and a little feature. This was a long journey, but finally Espen s forked-daapd became ready for being used as a new upstream of the Debian package thus please welcome 20.0+git20140530+gc740e6e-1, the first version of forked-daapd building on all architectures for a very long time and a prime candidate for being the music library server in Jessie (and wheezy-backports, soon)! Testing, bug reports are always welcome! From the package description:
 forked-daapd is an iTunes-compatible media server, originally intended
 as a rewrite of Firefly Media Server (also known as mt-daapd).
 It supports a wide range of audio formats, can stream video to iTunes,
 FrontRow and other compatible clients, has support for Apple's Remote
 iPhone/iPod application and can stream music to AirTunes devices like
 the AirPort Express.
 It also features RSP support for Roku's SoundBridge devices.
 Built-in, on-the-fly decoding support enables serving popular free music
 formats like FLAC, Ogg Vorbis or Musepack to those clients that do not
 otherwise support them.

Daniel Pocock: Fixing WebRTC dropouts

A few people have observed dropouts using WebRTC, including the new Debian community service at rtc.debian.org I've been going over some of these problems and made some improvements. If you tried it before and had trouble, please try again (rtc.debian.org is running with some of the fixes already). If anybody else has seen these problems or continues to experience them, please let the reSIProcate community know about it through the repro-users mailing list. WebSocket link disconnects immediately when call starts In this case, you may see the picture of the other person for a split second and then the websocket link disconnects and JSCommunicator re-initializes itself. People observing this problem had sometimes found that audio-only calls would work more frequently. I believe one reason for this problem has been some incorrect handling of the OpenSSL error queue. I posted my observations about this on the resiprocate developer's list and included a fix for it in the recent 1.9.7 release. Call starts, no remote picture appears, call stops after 20 seconds or so In this case, if you look closely in the JavaScript console, you may see that one of the endpoints has sent a SIP BYE message. A BYE message usually includes a reason such as this: Reason: SIP ;cause=200; text="RTP Timeout"
This particular reason (RTP Timeout) may indicate that the TURN server is faulty, not running at all or is not reachable due to one or both users being behind a firewall. If you experience this problem but some other reason code appears, please share your observations on the repro-users mailing list so it can be improved. For those people who have firewall problems, this will eventually be resolved when the browsers support TURN over a TLS connection through a HTTP proxy. We also hope to provide better feedback in the JavaScript UI of JSCommunicator to tell people their call was blocked by a firewall.

Francesca Ciceri: 100 bugs triaged: achievement unlocked

After two weeks working as OPW intern for Mozilla, it's time for a recap!
What exactly I've been doing in these two weeks? 100 bugs triaged: achievement unlocked! Yes, this is the thing I'm most proud of. I'm a bit cheating here, as strictly speaking, since the beginning of the internship I've triaged only 44 bugs.
But I've decided to count from the beginning of my activity on bugzilla, at the end of March, since I've started work on that as part of the small contribution required for applying to OPW.
Therefore, it's all OPW related :) Here's the grand total. Right now, I've decided to work on an average of 5 bugs a day: it's mostly triage and/or verification, which is quite fun.
It consists in trying to have a more complete and detailed bug report for the developers: asking the right questions to the reporter, ensuring that the bug is filed against the right product or component and all the information about platforms and version are correct. Or verifying that the bug isn't a duplicate, which involves doing some voodoo with Bugzilla quicksearch (I'm not so good with that yet, mostly because I'm not imaginative enough in the queries... but I'm getting better!) Sometimes triaging means reading lots of documentation (to be sure that something is a bug and not a feature) and checking meta-bugs and release notes to be able to pinpoint the time when something was introduced and the reasoning behind it.
That takes a lot of time, but it makes you discover some funny things, like the Mighty Bouncing Unicorn. And while I know it sounds a bit cruel, it's really good when you're verifying a fix and you find it's not totally ok, or that it triggered another bug.
I've been assured that feeling satisfied after that it's an essential part of the sadistic QA work. Writing FAQs for new triager This started as a personal project even before knowing I've been selected for OPW, and it's now part of my internship: I've been writing a first draft of FAQ for those who approach for the first time the Bug Triaging and Verifying work in Mozilla. It meant taking a whole lot of IRC logs and scan them for the most asked questions during bugdays, and you can find here my first draft. I'll send a RFC today about it on dev-quality mailing list and link it to the main Bugdays page. Lessons learned So, what I've learned in these two weeks? That I'm pretty good at figuring things alone, but I like to have feedback on what I'm working on.
That testing things is an art, and perfectionism is a big plus.
That there are such things as stupid questions, but you have to ask them nonetheless.
That people in the Mozilla community are quite friendly and not scary at all. Not even in video! :) Wishlist I've been thinking about this a lot, and I think I'd like to have They will probably become my next pet project.

Steve Kemp: Reflections on Lua-based email clients

Until recently I was very happy with my console mail client, Lumail, thinking I'd written it in a flexible manner, with lots of Lua-callable primitives. Now I'm beginning to suspect that I might have gone down the wrong path at some point. The user interface, at startup consists of a list of mailboxes. The intention being that you select a mailbox, and open it. That then takes you to a list of messages. (There is a cool and simple to use option to open the union of multiple mailboxes, which is something I use daily.) Now the list of mailboxes is sorted alphabetically, so the user interface looks something like this:
UI
Now the issue that triggered my rethink: Sure you think. It's just a list of strings. You could pass an array to a lua on_sort_maildirs function, and then use the returned array/table as teh display order. Simple. Simple until you realize the user might want to do more than operate solely on the list of strings. Perhaps they wish to put folders with unread messages at the top. At which point you need a "count_unread( maildir )" function. (Which does exist.) Anyway the realisation I had is that the CMaildir object, on the C++ side, isn't exposed to the Lua-side. So the (useful) member functions which should be exported/visible are not. Really what I'm trying to say is that I think I've implemented and exported useful Lua primitives, but actually many more parts of the implementation could be usefully exported - but are not, and that comes from the choice I made to expose "things" not "objects". If I'd exposed objects right from the start I'd have been in a better place. Oh well. I continued to toy with a basic GUI mail-client last week, but I've pretty much written that off as a useful way to spend my time. For the moment I'll leave email alone, I've done enough and despite niggles what I have is absolutely the best mail client for me. (It is a shame that Mutt is so heavyweight and hard to deal with, and that notmuch never really took off.)

Enrico Zini: when-i-said-iloveyou

When I said "I love you"
All people ever say is: thank you (a celebration of life) and please (an opportunity to make life more wonderful). Marshall Rosenberg
I have said "I love you" many times in my life, and many times I have failed to say it, because, for me, it is not an easy thing to say. It is not easy when I have no idea what the other person will make of it: will they be frightened? Will they feel awkward around me afterwards? Will they disappear from my life? But do I know what I myself mean when I say it? I have said "I love you" because I thought you somehow expected it of me. "please, consider me worth of you". I have said "I love you" to beg for affection. "please, love me back". I have said "I love you" because I was grateful to you for existing in my life. "thank you". I now understand why it has not been easy for me to say "I love you" when I was feeling, or imagining, that I had to say it. I now understand why I have sometimes made myself awkward, as I was begging. I now understand why, when I said "I love you" out of gratitude, when I said it to celebrate that you exist in my life, that's when I felt no trouble, no fear, and when I felt that my words really were fitting with what I was feeling and what I was wanting to say.

Russ Allbery: Review: Debt

Review: Debt, by David Graeber
Publisher: Melville House
Copyright: 2011, 2012
Printing: October 2012
ISBN: 1-61219-129-0
Format: Trade paperback
Pages: 453
You probably remember this story from introductory economics. Originally, people exchanged things through barter. I needed grain but had a cow. You had a farm but needed milk. I gave you milk for your grain. But this was tedious and awkward, and required finding the right combination of people who needed something the other person had on hand. Then, people invented money: small objects with an agreed-upon value that you could keep and use later when you needed something else. In other words, both a medium of exchange and a store of value. And that improved matters for a long time, although war-torn societies or societies that collapsed (the supposed "Dark Ages" often raises its head) would sometimes "revert to barter" for some period of time until things were stable enough for currency to reappear. Following that story was usually some story about the emergence of money based on credit: goldsmith shops that started a side business in storing other people's coins and giving them receipts, leading to the receipts trading like the coins since the shops were trustworthy, and from there into the Bank of England and eventually the fractional reserve banking system, fiat money, and all the modern machinery of finance. All of this was dated from the early Enlightenment and the development of modern finance in Europe. It's a very neat story, and it makes a great deal of intuitive sense. That barter system does feel like what you'd have to do without money, but one can immediately see how obnoxious and limiting it would be. These stories play into our intuitive sense of history: people started with emergent properties of the physical world (different people have different goods and different skills and want to exchange them) and then develop layers of abstraction on top of them, eventually leading to the sophistication of modern societies. However, David Graeber is not an economist. He's an anthropologist: the profession devoted to understanding how people actually do things rather than how we've reconstructed our history based on our modern perspective. And, as he points out, engagingly and comprehensively, in chapter two of Debt, there is no evidence that this story about economic history has anything whatsoever to do with reality. And quite a bit of evidence that it does not. As best as we've been able to determine, not only is there no society in the world that deals with routine, day-to-day needs like grain and milk through barter, there never has been such a society in human history. Instead, history and anthropology shows that credit is, in a sense, older than currency: the earliest recorded economic transactions were built on a rich system of credit, but in the form of purchases from shopkeepers on credit, or credit clearinghouses through the local government or temple. Those credit records were often denominated in some standardized commodity so many cattle or bushels of grain that could create the impression that the economy worked on barter. But the anthropological evidence indicates that this was more an accounting technique than a practical currency. People rarely brought the named commodity to the temple to pay off some debt. Rather, there was an agreed conversion from various other goods to that standardized commodity, and its primary purpose was consistent bookkeeping. Specie minted coins appear to come later, and wax and wane throughout history depending on local circumstance. For example, Europe did not "revert to barter" after the collapse of the Roman Empire, but the inhabitants did stop using specie and returned to a system of credit and record-keeping... records that continued to be denominated in Roman currency, even though few people still used the actual coins. That's one fascinating observation with which Graeber begins this book. The other is the question of why we have such a strong social and moral belief that people must pay their debts. This moral belief is ever-present in discussions about the 2008 financial collapse, and more broadly in discussions about the modern economy, but it's not as obvious of a belief as it might appear on the surface. After all, the banking and investment system is founded on the principle that not everyone will repay their debts, and therefore lenders receive a risk premium based on the likelihood that the debt won't be repaid. But, despite building the possibility of non-repayment into the system, debt forgiveness or intentional default is almost unthinkable and considered a huge moral problem. To this, Graeber brings the perspective of historical anthropology: human societies have struggled with the problems of debt and repayment from the beginning of recorded history, and have attempted a wide variety of solutions to those problems, including massive debt forgiveness. The jubilee described in the Bible was not novel; rather, it reflected a common practice to keep abuses of debt under control in ancient Sumer. The subtitle of Debt is The First 5,000 Years, and this book is a historical survey. But Graeber puts off the history to first lay an intellectual groundwork for our understanding of debt, and I found that preliminary discussion extremely valuable. Most memorable was the way Graeber divides human economic relationships into communism (in the old sense, not the political sense), exchange, and hierarchy. Capitalism has consumed our economic analysis to such a degree that exchange is the only economic basis that gets much discussion, but the other two are both obvious and pervasive once Graeber points them out. Human civilization could not exist without all three. And Graeber also points out one aspect of exchange-based economics that had not previously occurred to me: it's the economic relationship that one creates with strangers. Debt has the unique characteristic that it can be discharged, at which point the relationship ceases. This has far more complex and far-reaching moral and social implications than one might initially realize, and Graeber did a wonderful job opening my eyes to some of the subtleties. Debt is clearly a scholarly work, but Graeber's writing is clear and engaging. I found most of this book to be surprisingly easy reading. The hardest going was Graeber's discussion of societies that use a form of currency to arrange relationships between people (marriages, births, and deaths, primarily), but not day-to-day economic transactions. I suspect this area is closer to Graeber's areas of personal research and field work, which resulted in more technical detail. I'm still not sure I completely grasp the principles that Graeber was trying to communicate. But I was struck by the observation of alienation's role in turning a human being into a commodity, and how that links with debt's role as the economic transaction one has with strangers. Graeber covers slavery only glancingly, but makes some memorable points about the use of violence to rip someone out of their social context, and how that is necessary in human cultures before humans can be reduced to a commodity. There's a lot here, and I've only scratched the surface. I haven't mentioned, for example, the fascinatingly elegant theory that coining money and then requiring taxes be paid in the same money is a simple and highly effective way of funding armies, an explanation for specie that is largely unproven but that I find more compelling than the ones I've previously heard. Approaching debt from an anthropological instead of economic perspective is surprisingly enlightening. Debt is primarily a historical and cultural discussion rather than a set of proposed solutions, but Graeber does effectively show that debt as a moral obligation is not an unquestionable moral stance, but rather has a long history as one side of a two-sided political debate. I also came away from this book more conscious of the social implications and costs of debt-structured interactions, and wanting to push more of the language of debt out of my day-to-day dealings. Graeber is well known as one of the supporters of Occupy Wall Street, and Debt, while a well-defended academic work, certainly does advocate a position. But the academic analysis is more prominent than the advocacy, and I found his positions well-defended and well-argued. I do need to give the caveat that I don't have the anthropological background to distinguish the statements from Graeber that are well-established common knowledge in anthropology from the ones that are more controversial, and I would be a bit leery of taking this book as the final word on the topic. But it fully deserves its popularity and reputation as a thought-provoking and valuable contribution to the conversation. It's another book that I want to re-read someday to digest further, and the sort of book whose observations keep occurring to me in subsequent discussions or news stories. If you're at all interested in the way in which we construct the morality around economics and debt, I think this is a book that you should read. It's thoughtful, challenging, and surprising, and it passes my acid test for books of this sort with flying colors: after reading it, you realize that many things are more complicated, more historical, and less novel than you had originally thought. Highly recommended. Rating: 9 out of 10

1 June 2014

Paul Tagliamonte: Back from TCamp 2014

Great time, super well organized by this year s TCamp staff. Really outstanding. Lots of really amazing discussion, and I feel a lot of effort is finally jelling around Open Civic Data, which is an absolute thrill for me. Can t wait to see what the next few months bring!

Antonio Terceiro: An introduction to the Debian Continuous Integration project

Debian is a big system. At the time of writing, looking at my local package list caches tells me that the unstable suite contains 21306 source packages, and 42867 binary packages on amd64. Between these 42867 binary packages, there is an unthinkable number of inter-package dependencies. For example the dependency graph of the ruby packages contains other 20-something packages. A new version of any of these packages can potentially break some functionality in the ruby package. And that dependency graph is very small. Looking at the dependency graph for, say, the rails package will make your eyes bleed. I tried it here, and GraphViz needed a PNG image with 7653 10003 pixels to draw it. It ain t pretty. Installing rails on a clean Debian system will pull in another 109 packages as part of the dependency chain. Again, as new versions of those packages are uploaded the archive, there is a probability that a backwards-incompatible change, or even a bug fix which was being worked around, might make some funcionality in rails stop working. Even if that probability is low for each package in the dependency chain, with enough packages the probability of any of them causing problems for rails is quite high. And still the rails dependency chain is not that big. libreoffice will pull in another 264 packages. gnome will pull in 1311 dependencies, and kde-full 1320 (!). With a system this big, problems will arrive, and that s a fact of life. As developers, what we can do is try to spot these problems as early as possible, and fixing them in time to make a solid release with the high quality Debian is known for. While automated testing is not the proverbial Silver Bullet of Software Engineering, it is an effective way of finding regressions. Back in 2006, Ian Jackson started the development of autopkgtest as a tool to test Debian packages in their installed form (as opposed to testing packages using their source tree). In 2011, the autopkgtest test suite format was proposed as a standard for the Debian project, in what we now know as the DEP-8 specification. Since then, some maintainers such as myself started experimenting with DEP-8 tests in their packages. There was an expectation in the air that someday, someone would run those tests for the entire archive, and that would be a precious source of QA information. Durign the holiday break last year, I decided to give it a shot. I initially called the codebase dep8. Later I renamed it to debci, since it could potentially also run other other types of test suites in the future. Since early January, ci.debian.net run an instance of debci for the Debian Project. The Debian continuous Integration will trigger tests at most 4 times a day, 3 hours after each dinstall run. It will update a local APT cache and look for packages that declare a DEP-8 test suite. Each package with a test suite will then have its test suite executed if there was any change in its dependency chain since the last test run. Existing test results are published at ci.debian.net every hour, and at the end of each batch a global status is updated. Maintainers can subscribe to a per package Atom feed to keep up with their package test results. People interested in the overall status can subscribe to a global Atom feed of events. Since the introduction of Debian CI in mid-January 2014, we have seen an amazing increase in the number of packages with test suites. We had little less than 200 packages with test suites back then, against around 350 now (early June 2014). The ratio of packages passing passing their test suite has also improved a lot, going from less than 50% to more than 75%. There is documentation available, including a FAQ for package maintainers with further information about how the system works, how to declare test suites in their packages and how to reproduce test runs locally. Also available is development information about debci itself, to those inclined to help improve the system. This is just the beginning. debci is under a good rate of development, and you can expect to see a constant flux of improvements. In special, I would like to mention a few people who are giving amazing contributions to the project:

Andrew Cater: Not quite the last of the 32 bit machines ...

I've just got back my daughter's netbook. About 5 years old. Originally cost me 100 as part of a deal with my ISP.

1.6GHz Atom N270 processor, 2GB of memory, 120GB of Samsung hard disk.
It's a "Freedom" netbook - almost certainly made by Quanta. Atheros chipset for wifi. [A9285 for wifi, Realtek 8101E for Ethernet]

This is the sort of machine that is probably going into landfill round about now. It's been running XP and mostly used by my father, who has given up on it now it won't update.

I used the unofficial Debian 7.5 cd which includes firmware because I was going to be using wifi to install Debian and because I didn't know what wifi chipset was in there. I had previously tested and run a Debian live USB image but faced problems - the cursor wouldn't play although the KDE desktop appeared fine.

An expert install selecting KDE worked fine but produced immediate problems: cursor was erratic, the screen blacked out and I couldn't switch it off - I had to remove the mains power and battery to kill it.

A second install over the top of this, wiping out the first install but selecting LXDE worked perfectly and works well. It's possible that a full KDE desktop is stressing this litle 10 inch laptop's 2GB and display memory a bit too much.

I'm very pleased to have rescued this machine and got a Linux that "just works" albeit a bit more slowly than I'm used to. Even if it gets used just as a terminal for amateur radio / a spare emergency machine in a corner somewhere, it's better than being junked. Best of all, installing vrms shows that, although I enabled non-free in the initial install, this machine requires no non-free firmware so has saved me the cost of buying an FSF approved secondhand Thinkpad.


Next.

Previous.