Search Results: "ema"

6 February 2023

Reproducible Builds: Reproducible Builds in January 2023

Welcome to the first report for 2023 from the Reproducible Builds project! In these reports we try and outline the most important things that we have been up to over the past month, as well as the most important things in/around the community. As a quick recap, the motivation behind the reproducible builds effort is to ensure no malicious flaws can be deliberately introduced during compilation and distribution of the software that we run on our devices. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.

News In a curious turn of events, GitHub first announced this month that the checksums of various Git archives may be subject to change, specifically that because:
the default compression for Git archives has recently changed. As result, archives downloaded from GitHub may have different checksums even though the contents are completely unchanged.
This change (which was brought up on our mailing list last October) would have had quite wide-ranging implications for anyone wishing to validate and verify downloaded archives using cryptographic signatures. However, GitHub reversed this decision, updating their original announcement with a message that We are reverting this change for now. More details to follow. It appears that this was informed in part by an in-depth discussion in the GitHub Community issue tracker.
The Bundesamt f r Sicherheit in der Informationstechnik (BSI) (trans: The Federal Office for Information Security ) is the agency in charge of managing computer and communication security for the German federal government. They recently produced a report that touches on attacks on software supply-chains (Supply-Chain-Angriff). (German PDF)
Contributor Seb35 updated our website to fix broken links to Tails Git repository [ ][ ], and Holger updated a large number of pages around our recent summit in Venice [ ][ ][ ][ ].
Noak J nsson has written an interesting paper entitled The State of Software Diversity in the Software Supply Chain of Ethereum Clients. As the paper outlines:
In this report, the software supply chains of the most popular Ethereum clients are cataloged and analyzed. The dependency graphs of Ethereum clients developed in Go, Rust, and Java, are studied. These client are Geth, Prysm, OpenEthereum, Lighthouse, Besu, and Teku. To do so, their dependency graphs are transformed into a unified format. Quantitative metrics are used to depict the software supply chain of the blockchain. The results show a clear difference in the size of the software supply chain required for the execution layer and consensus layer of Ethereum.

Yongkui Han posted to our mailing list discussing making reproducible builds & GitBOM work together without gitBOM-ID embedding. GitBOM (now renamed to OmniBOR) is a project to enable automatic, verifiable artifact resolution across today s diverse software supply-chains [ ]. In addition, Fabian Keil wrote to us asking whether anyone in the community would be at Chemnitz Linux Days 2023, which is due to take place on 11th and 12th March (event info). Separate to this, Akihiro Suda posted to our mailing list just after the end of the month with a status report of bit-for-bit reproducible Docker/OCI images. As Akihiro mentions in their post, they will be giving a talk at FOSDEM in the Containers devroom titled Bit-for-bit reproducible builds with Dockerfile and that my talk will also mention how to pin the apt/dnf/apk/pacman packages with my repro-get tool.
The extremely popular Signal messenger app added upstream support for the SOURCE_DATE_EPOCH environment variable this month. This means that release tarballs of the Signal desktop client do not embed nondeterministic release information. [ ][ ]

Distribution work

F-Droid & Android There was a very large number of changes in the F-Droid and wider Android ecosystem this month: On January 15th, a blog post entitled Towards a reproducible F-Droid was published on the F-Droid website, outlining the reasons why F-Droid signs published APKs with its own keys and how reproducible builds allow using upstream developers keys instead. In particular:
In response to [ ] criticisms, we started encouraging new apps to enable reproducible builds. It turns out that reproducible builds are not so difficult to achieve for many apps. In the past few months we ve gotten many more reproducible apps in F-Droid than before. Currently we can t highlight which apps are reproducible in the client, so maybe you haven t noticed that there are many new apps signed with upstream developers keys.
(There was a discussion about this post on Hacker News.) In addition:
  • F-Droid added 13 apps published with reproducible builds this month. [ ]
  • FC Stegerman outlined a bug where baseline.profm files are nondeterministic, developed a workaround, and provided all the details required for a fix. As they note, this issue has now been fixed but the fix is not yet part of an official Android Gradle plugin release.
  • GitLab user Parwor discovered that the number of CPU cores can affect the reproducibility of .dex files. [ ]
  • FC Stegerman also announced the 0.2.0 and 0.2.1 releases of reproducible-apk-tools, a suite of tools to help make .apk files reproducible. Several new subcommands and scripts were added, and a number of bugs were fixed as well [ ][ ]. They also updated the F-Droid website to improve the reproducibility-related documentation. [ ][ ]
  • On the F-Droid issue tracker, FC Stegerman discussed reproducible builds with one of the developers of the Threema messenger app and reported that Android SDK build-tools 31.0.0 and 32.0.0 (unlike earlier and later versions) have a zipalign command that produces incorrect padding.
  • A number of bugs related to reproducibility were discovered in Android itself. Firstly, the non-deterministic order of .zip entries in .apk files [ ] and then newline differences between building on Windows versus Linux that can make builds not reproducible as well. [ ] (Note that these links may require a Google account to view.)
  • And just before the end of the month, FC Stegerman started a thread on our mailing list on the topic of hiding data/code in APK embedded signatures which has been made possible by the Android APK Signature Scheme v2/v3. As part of this, they made an Android app that reads the APK Signing block of its own APK and extracts a payload in order to alter its behaviour called sigblock-code-poc.

Debian As mentioned in last month s report, Vagrant Cascadian has been organising a series of online sprints in order to clear the huge backlog of reproducible builds patches submitted by performing NMUs (Non-Maintainer Uploads). During January, a sprint took place on the 10th, resulting in the following uploads: During this sprint, Holger Levsen filed Debian bug #1028615 to request that the tracker.debian.org service display results of reproducible rebuilds, not just reproducible CI results. Elsewhere in Debian, strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build. This month, version 1.13.1-1 was uploaded to Debian unstable by Holger Levsen, including a fix by FC Stegerman (obfusk) to update a regular expression for the latest version of file(1) [ ]. (#1028892) Lastly, 65 reviews of Debian packages were added, 21 were updated and 35 were removed this month adding to our knowledge about identified issues.

Other distributions In other distributions:

diffoscope diffoscope is our in-depth and content-aware diff utility. Not only can it locate and diagnose reproducibility issues, it can provide human-readable diffs from many kinds of binary formats. This month, Chris Lamb made the following changes to diffoscope, including preparing and uploading versions 231, 232, 233 and 234 to Debian:
  • No need for from __future__ import print_function import anymore. [ ]
  • Comment and tidy the extras_require.json handling. [ ]
  • Split inline Python code to generate test Recommends into a separate Python script. [ ]
  • Update debian/tests/control after merging support for PyPDF support. [ ]
  • Correctly catch segfaulting cd-iccdump binary. [ ]
  • Drop some old debugging code. [ ]
  • Allow ICC tests to (temporarily) fail. [ ]
In addition, FC Stegerman (obfusk) made a number of changes, including:
  • Updating the test_text_proper_indentation test to support the latest version(s) of file(1). [ ]
  • Use an extras_require.json file to store some build/release metadata, instead of accessing the internet. [ ]
  • Updating an APK-related file(1) regular expression. [ ]
  • On the diffoscope.org website, de-duplicate contributors by e-mail. [ ]
Lastly, Sam James added support for PyPDF version 3 [ ] and Vagrant Cascadian updated a handful of tool references for GNU Guix. [ ][ ]

Upstream patches The Reproducible Builds project attempts to fix as many currently-unreproducible packages as possible. This month, we wrote a large number of such patches, including:

Testing framework The Reproducible Builds project operates a comprehensive testing framework at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In January, the following changes were made by Holger Levsen:
  • Node changes:
  • Debian-related changes:
    • Only keep diffoscope s HTML output (ie. no .json or .txt) for LTS suites and older in order to save diskspace on the Jenkins host. [ ]
    • Re-create pbuilder base less frequently for the stretch, bookworm and experimental suites. [ ]
  • OpenWrt-related changes:
    • Add gcc-multilib to OPENWRT_HOST_PACKAGES and install it on the nodes that need it. [ ]
    • Detect more problems in the health check when failing to build OpenWrt. [ ]
  • Misc changes:
    • Update the chroot-run script to correctly manage /dev and /dev/pts. [ ][ ][ ]
    • Update the Jenkins shell monitor script to collect disk stats less frequently [ ] and to include various directory stats. [ ][ ]
    • Update the real year in the configuration in order to be able to detect whether a node is running in the future or not. [ ]
    • Bump copyright years in the default page footer. [ ]
In addition, Christian Marangi submitted a patch to build OpenWrt packages with the V=s flag to enable debugging. [ ]
If you are interested in contributing to the Reproducible Builds project, please visit the Contribute page on our website. You can get in touch with us via:

5 February 2023

James Valleroy: A look back at FreedomBox project in 2022

This post is very late, but better late than never! I want to take a look back at the work that was done on FreedomBox during 2022. Several apps were added to FreedomBox in 2022. The email server app (that was developed by a Google Summer of Code student back in 2021) was finally made available to the general audience of FreedomBox users. You will find it under the name Postfix/Dovecot , which are the main services configured by this app. Another app that was added is Janus, which has the description video room . It is called video room instead of video conference because the room itself is persistent. People can join the room or leave, but there isn t a concept of calling or ending the call . Actually, Janus is a lightweight WebRTC server that can be used as a backend for many different types of applications. But as implemented currently, there is just the simple video room app. In the future, more advanced apps such as Jangouts may be packaged in Debian and made available to FreedomBox. RSS-Bridge is an app that generates RSS feeds for websites that don t provide their own (for example, YouTube). It can be used together with any RSS news feed reader application, such as TT-RSS which is also available in FreedomBox. There is now a Privacy page in the System menu, which allows enabling or disabling the Debian popularity-contest tool. If enabled, it reports the Debian packages that are installed on the system. The results can be seen at https://popcon.debian.org, which currently shows over 400 FreedomBoxes are reporting data. A major feature added to FreedomBox in 2022 is the ability to uninstall apps. This feature is still considered experimental (it won t work for every app), but many issues have been fixed already. There is an option to take a backup of the app s data before uninstalling. There is also now an operations queue in case the user starts multiple install or uninstall operations concurrently. XEP-0363 (HTTP File Upload) has been enabled for Ejabberd Chat Server. This allows files to be transferred between XMPP clients that support this feature. There were a number of security improvements to FreedomBox, such as adding fail2ban jails for Dovecot, Matrix Synapse, and WordPress. Firewall rules were added to ensure that authentication and authorization for services proxied through Apache web server cannot be bypassed by programs running locally on the system. Also, we are no longer using libpam-tmpdir to provide temporary folder isolation, because it causes issues for several packages. Instead we use systemd s sandboxing features, which provide even better isolation for services. Some things were removed in 2022. The ez-ipupdate package is no longer used for Dynamic DNS, since it is replaced by a Python implementation of GnuDIP. An option to restrict who can log in to the system was removed, due to various issues that arose from it. Instead there is an option to restrict who can login through SSH. The DNSSEC diagnostic test was removed, because it caused confusion for many users (although use of DNSSEC is still recommended). Finally, some statistics. There were 31 releases in 2022 (including
point releases). There were 68 unique contributors to the git
repository; this includes code contributions and translations (but not
contributions to the manual pages). In total, there were 980 commits to the git repository.

Jonathan Dowland: 2022 in reading

In 2022 I read 34 books (-19% on last year). In 2021 roughly a quarter of the books I read were written by women. I was determined to push that ratio in 2022, so I made an effort to try and only read books by women. I knew that I wouldn't manage that, but by trying to, I did get the ratio up to 58% (by page count). I'm not sure what will happen in 2023. My to-read pile has some back-pressure from books by male authors I postponed reading in 2022 (in particular new works by Christopher Priest and Adam Roberts). It's possible the ratio will swing back the other way, which would mean it would not be worth repeating the experiment. At least if the ratio is the point of the exercise. But perhaps it isn't: perhaps the useful outcome is more qualitative than quantitative. I tried to read some new (to me) authors. I really enjoyed Shirley Jackson (The Haunting of Hill House, We Have Always Lived In The Castle). I Struggled with Angela Carter's Heroes and Villains although I plan to return to her other work, in particular, The Bloody Chamber. I also got through Donna Tartt's The Secret History on the recommendation of a friend. I had to push through the first 15% or so but it turned out to be worth it.
a book cover for Shirley Jackson's 'We have always lived in the castle'
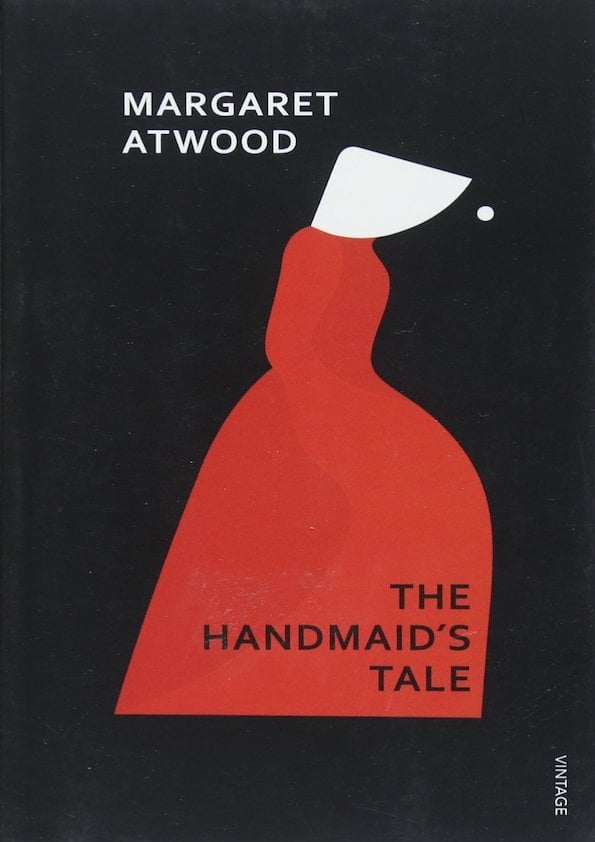
a book cover for Margaret Atwood's 'The Handmaid's Tale'
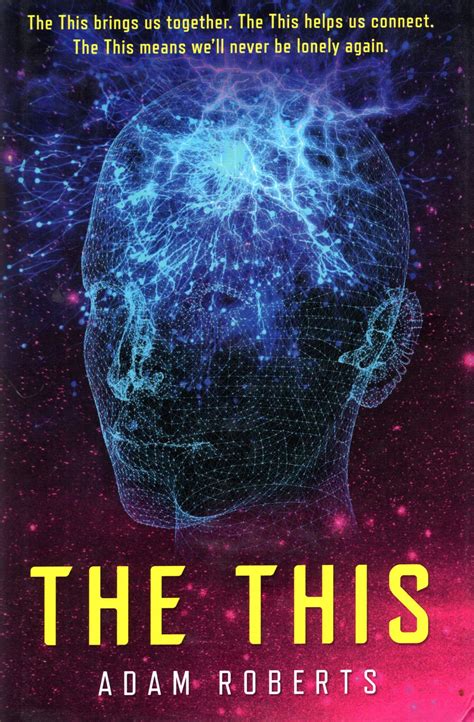
a book cover for Adam Roberts' 'The This'
a book cover for Emily St. John Mandel's 'Sea of Tranquility'

I finally read (and loved) The Handmaid's Tale, which I had never read despite loving Atwood. My top non-fiction book was The Nanny State Made Me by Stuart Maconie. I still read far more fiction than non-fiction. Or perhaps I'm not keeping track of non- fiction as well. I feel non-fiction requires a different approach to reading: not necessarily linear; it's not always important to read the whole book; it's often important to re-read sections. It might not make sense to consider them in the same bracket. My favourite novels this year were Sea of Tranquility by Emily St. John Mandel, a standalone sort-of sequel to The Glass House but in a very different genre; and The This by Adam Roberts, which was equally remarkable. The This has an interesting narrative device in the first third where a stream of tweets is presented in parallel with the main text. This works well, and does a good job of capturing the figurative river of tweet-like stuff that is woven into our lives at the moment. But I can't help but wonder how they tackle that in the audiobook.

4 February 2023

Jonathan Dowland: FreedomBox

personal servers Moxie Marlinspike, former CEO of Signal, wrote a very interesting blog post about "web3", the crypto-scam1. It's worth a read if you are interested in that stuff. This blog post, however, is not about crypto-scams; but I wanted to quote from the beginning of the article:
People don t want to run their own servers, and never will. The premise for web1 was that everyone on the internet would be both a publisher and consumer of content as well as a publisher and consumer of infrastructure. We d all have our own web server with our own web site, our own mail server for our own email, our own finger server for our own status messages, our own chargen server for our own character generation. However and I don t think this can be emphasized enough that is not what people want. People do not want to run their own servers.
What's interesting to me about this is I feel that he's right: the vast, vast majority of people almost certainly do not want to run their own servers. Yet, I decided to. I started renting a Linux virtual server2 close to 20 years ago3, but more recently, decided to build and run a home NAS, which was a critical decision for getting my personal data under control. FreedomBox and Debian I am almost entirely dormant within the Debian project these days, and that's unlikely to change in the near future, at least until I wrap up some other commitments. I do sometimes mull over what I would do within Debian, if/when I return to the fold. And one thing I could focus on, since I am running my own NAS, would be software support for that sort of thing. FreedomBox is a project that bills itself as a private server for non-experts: in other words, it's almost exactly the thing that Marlinspike states people don't want. Nonetheless, it is an interesting project. And, it's a Debian Pure Blend: which is to say (quoting the previous link) a subset of Debian that is tailored to be used out-of-the-box in a particular situation or by a particular target group. So FreedomBox is a candidate project for me to get involved with, especially (or more sensibly, assuming that) I end up using some of it myself. But, that's not the only possibility, especially after a really, really good conversation I had earlier today with old friends Neil McGovern and Chris Boot

  1. crypto-scam is my characterisation, not Marlinspike's.
  2. hosting, amongst other things, the site you are reading
  3. The Linux virtual servers replaced an ancient beige Pentium that was running as an Internet server from my parent's house in the 3-4 years before that.

2 February 2023

Matt Brown: 2023 Writing Plan

To achieve my goal of publishing one high-quality piece of writing per week this year, I ve put together a draft writing plan and a few organisational notes. Please let me know what you think - what s missing? what would you like to read more/less of from me? I aim for each piece of writing to generate discussion, inspire further writing, and raise my visibility and profile with potential customers and peers. Some of the writing will be opinion, but I expect a majority of it will take a learning by teaching approach - aiming to explain and present useful information to the reader while helping me learn more!

Topic Backlog The majority of my writing is going to fit into 4 series, allowing me to plan out a set of posts and narrative rather than having to come up with something novel to write about every week. To start with for Feb, my aim is to get an initial post in each series out the door. Long-term, it s likely that the order of posts will reflect my work focus (e.g. if I m spending a few weeks deep-diving into a particular product idea then expect more writing on that), but I will try and maintain some variety across the different series as well. This backlog will be maintained as a living page at https://www.mattb.nz/w/queue. Thoughts on SRE This series of posts will be pitched primarily at potential consulting customers who want to understand how I approach the development and operations of distributed software systems. Initial topics to cover include:
  • What is SRE? My philosophy on how it relates to DevOps, Platform Engineering and various other hot terms.
  • How SRE scales up and down in size.
  • My approach to managing oncall responsibilities, toil and operational work.
  • How to grow an SRE team, including the common futility of SRE transformations .
  • Learning from incidents, postmortems, incident response, etc.
Business plan drafts I have an ever-growing list of potential software opportunities and products which I think would be fun to build, but which generally don t ever leave my head due to lack of time to develop the idea, or being unable to convince myself that there s a viable business case or market for it. I d like to start sharing some very rudimentary business plan sketches for some of these ideas as a way of getting some feedback on my assessment of their potential. Whether that s confirmation that it s not worth pursuing, an expression of interest in the product, or potential partnership/collaboration opportunities - anything is better than the idea just sitting in my head. Initial ideas include:
  • Business oriented Mastodon hosting.
  • PDF E-signing - e.g. A Docusign competitor, but with a local twist through RealMe or drivers license validation.
  • A framework to enable simple, performant per-tenant at-rest encryption for SaaS products - stop the data leaks.
Product development updates For any product ideas that show merit and develop into a project, and particularly for the existing product ideas I ve already committed to exploring, I plan to document my product investigation and market research findings as a way of structuring and driving my learning in the space. To start with this will involve:
  • A series of explanatory posts diving into how NZ s electricity system works with a particular focus on how operational data that will be critical to managing a more dynamic grid flows (or doesn t flow!) today, and what opportunities or needs exist for generating, managing or distributing data that might be solvable with a software system I could build.
  • A series of product reviews and deep dives into existing farm management software and platforms in use by NZ farmers today, looking at the functionality they provide, how they integrate and generally testing the anecdotal feedback I have to date that they re clunky, hard to use and not well integrated.
  • For co2mon.nz the focus will be less on market research and more on exploring potential distribution channels (e.g. direct advertising vs partnership with air conditioning suppliers) and pricing models (e.g. buy vs rent).
Debugging walk-throughs Being able to debug and fix a system that you re not intimately familiar with is valuable skill and something that I ve always enjoyed, but it s also a skill that I observe many engineers are uncomfortable with. There s a set of techniques and processes that I ve honed and developed over the years for doing this which I think make the task of debugging an unfamiliar system more approachable. The idea, is that each post will take a problem or situation I ve encountered, from the initial symptom or problem report and walk through the process of how to narrow down and identify the trigger or root cause of the behaviour. Along the way, discussing techniques used, their pros and cons. In addition to learning about the process of debugging itself, the aim is to illustrate lessons that can be applied when designing and building software systems that facilitate and improve our experiences in the operational stage of a systems lifecycle where debugging takes place. Miscellaneous topics In addition the regular series above, stand-alone posts on the other topics may include:
  • The pros/cons I see of bootstrapping a business vs taking VC or other funding.
  • Thoughts on remote work and hiring staff.
  • AI - a confessional on how I didn t think it would progress in my lifetime, but maybe I was wrong.
  • Reflections on 15 years at Google and thoughts on subsequent events since my departure.
  • AWS vs GCP. Fight! Or with less click-bait, a level-headed comparison of the pros/cons I see in each platform.

Logistics

Discussion and comments A large part of my motivation for writing regularly is to seek feedback and generate discussion on these topics. Typically this is done by including comment functionality within the website itself. I ve decided not to do this - on-site commenting creates extra infrastructure to maintain, and limits the visibility and breadth of discussion to existing readers and followers. To provide opportunities for comment and feedback I plan to share and post notification and summarised snippets of selected posts to various social media platforms. Links to these social media posts will be added to each piece of writing to provide a path for readers to engage and discuss further while enabling the discussion and visibility of the post to grow and extend beyond my direct followers and subscribers. My current thinking is that I ll distribute via the following platforms:
  • Mastodon @matt@mastodon.nz - every post.
  • Twitter @xleem - selected posts. I m trying to reduce Twitter usage in favour of Mastodon, but there s no denying that it s still where a significant number of people and discussions are happening.
  • LinkedIn - probably primarily for posts in the business plan series, and notable milestones in the product development process.
In all cases, my aim will be to post a short teaser or summary paragraph that poses an question or relays an interesting fact to give some immediate value and signal to readers as to whether they want to click through rather than simply spamming links into the feed.

Feedback In addition to social media discussion I also plan to add a direct feedback path, particularly for readers who don t have time or inclination to participate in written discussion, by providing a simple thumbs up/thumbs down feedback widget to the bottom of each post, including those delivered via RSS and email.

Organisation To enable subscription to subsets of my writing (particularly for places like Planet Debian, etc where the more business focused content is likely to be off-topic), I plan to place each post into a set of categories:
  • Business
  • Technology
  • General
In addition to the categories, I ll also use more free-form tags to group writing with linked themes or that falls within one of the series described above.

1 February 2023

Julian Andres Klode: Ubuntu 2022v1 secure boot key rotation and friends

This is the story of the currently progressing changes to secure boot on Ubuntu and the history of how we got to where we are.

taking a step back: how does secure boot on Ubuntu work? Booting on Ubuntu involves three components after the firmware:
  1. shim
  2. grub
  3. linux
Each of these is a PE binary signed with a key. The shim is signed by Microsoft s 3rd party key and embeds a self-signed Canonical CA certificate, and optionally a vendor dbx (a list of revoked certificates or binaries). grub and linux (and fwupd) are then signed by a certificate issued by that CA In Ubuntu s case, the CA certificate is sharded: Multiple people each have a part of the key and they need to meet to be able to combine it and sign things, such as new code signing certificates.

BootHole When BootHole happened in 2020, travel was suspended and we hence could not rotate to a new signing certificate. So when it came to updating our shim for the CVEs, we had to revoke all previously signed kernels, grubs, shims, fwupds by their hashes. This generated a very large vendor dbx which caused lots of issues as shim exported them to a UEFI variable, and not everyone had enough space for such large variables. Sigh. We decided we want to rotate our signing key next time. This was also when upstream added SBAT metadata to shim and grub. This gives a simple versioning scheme for security updates and easy revocation using a simple EFI variable that shim writes to and reads from.

Spring 2022 CVEs We still were not ready for travel in 2021, but during BootHole we developed the SBAT mechanism, so one could revoke a grub or shim by setting a single EFI variable. We actually missed rotating the shim this cycle as a new vulnerability was reported immediately after it, and we decided to hold on to it.

2022 key rotation and the fall CVEs This caused some problems when the 2nd CVE round came, as we did not have a shim with the latest SBAT level, and neither did a lot of others, so we ended up deciding upstream to not bump the shim SBAT requirements just yet. Sigh. Anyway, in October we were meeting again for the first time at a Canonical sprint, and the shardholders got together and created three new signing keys: 2022v1, 2022v2, and 2022v3. It took us until January before they were installed into the signing service and PPAs setup to sign with them. We also submitted a shim 15.7 with the old keys revoked which came back at around the same time. Now we were in a hurry. The 22.04.2 point release was scheduled for around middle of February, and we had nothing signed with the new keys yet, but our new shim which we need for the point release (so the point release media remains bootable after the next round of CVEs), required new keys. So how do we ensure that users have kernels, grubs, and fwupd signed with the new key before we install the new shim?

upgrade ordering grub and fwupd are simple cases: For grub, we depend on the new version. We decided to backport grub 2.06 to all releases (which moved focal and bionic up from 2.04), and kept the versioning of the -signed packages the same across all releases, so we were able to simply bump the Depends for grub to specify the new minimum version. For fwupd-efi, we added Breaks. (Actually, we also had a backport of the CVEs for 2.04 based grub, and we did publish that for 20.04 signed with the old keys before backporting 2.06 to it.) Kernels are a different story: There are about 60 kernels out there. My initial idea was that we could just add Breaks for all of them. So our meta package linux-image-generic which depends on linux-image-$(uname -r)-generic, we d simply add Breaks: linux-image-generic ( 5.19.0-31) and then adjust those breaks for each series. This would have been super annoying, but ultimately I figured this would be the safest option. This however caused concern, because it could be that apt decides to remove the kernel metapackage. I explored checking the kernels at runtime and aborting if we don t have a trusted kernel in preinst. This ensures that if you try to upgrade shim without having a kernel, it would fail to install. But this ultimately has a couple of issues:
  1. It aborts the entire transaction at that point, so users will be unable to run apt upgrade until they have a recent kernel.
  2. We cannot even guarantee that a kernel would be unpacked first. So even if you got a new kernel, apt/dpkg might attempt to unpack it first and then the preinst would fail because no kernel is present yet.
Ultimately we believed the danger to be too large given that no kernels had yet been released to users. If we had kernels pushed out for 1-2 months already, this would have been a viable choice. So in the end, I ended up modifying the shim packaging to install both the latest shim and the previous one, and an update-alternatives alternative to select between the two: In it s post-installation maintainer script, shim-signed checks whether all kernels with a version greater or equal to the running one are not revoked, and if so, it will setup the latest alternative with priority 100 and the previous with a priority of 50. If one or more of those kernels was signed with a revoked key, it will swap the priorities around, so that the previous version is preferred. Now this is fairly static, and we do want you to switch to the latest shim eventually, so I also added hooks to the kernel install to trigger the shim-signed postinst script when a new kernel is being installed. It will then update the alternatives based on the current set of kernels, and if it now points to the latest shim, reinstall shim and grub to the ESP. Ultimately this means that once you install your 2nd non-revoked kernel, or you install a non-revoked kernel and then reconfigure shim or the kernel, you will get the latest shim. When you install your first non-revoked kernel, your currently booted kernel is still revoked, so it s not upgraded immediately. This has a benefit in that you will most likely have two kernels you can boot without disabling secure boot.

regressions Of course, the first version I uploaded had still some remaining hardcoded shimx64 in the scripts and so failed to install on arm64 where shimaa64 is used. And if that were not enough, I also forgot to include support for gzip compressed kernels there. Sigh, I need better testing infrastructure to be able to easily run arm64 tests as well (I only tested the actual booting there, not the scripts). shim-signed migrated to the release pocket in lunar fairly quickly, but this caused images to stop working, because the new shim was installed into images, but no kernel was available yet, so we had to demote it to proposed and block migration. Despite all the work done for end users, we need to be careful to roll this out for image building.

another grub update for OOM issues. We had two grubs to release: First there was the security update for the recent set of CVEs, then there also was an OOM issue for large initrds which was blocking critical OEM work. We fixed the OOM issue by cherry-picking all 2.12 memory management patches, as well as the red hat patches to the loader we take from there. This ended up a fairly large patch set and I was hesitant to tie the security update to that, so I ended up pushing the security update everywhere first, and then pushed the OOM fixes this week. With the OOM patches, you should be able to boot initrds of between 400M and 1GB, it also depends on the memory layout of your machine and your screen resolution and background images. So OEM team had success testing 400MB irl, and I tested up to I think it was 1.2GB in qemu, I ran out of FAT space then and stopped going higher :D

other features in this round
  • Intel TDX support in grub and shim
  • Kernels are allocated as CODE now not DATA as per the upstream mm changes, might fix boot on X13s

am I using this yet? The new signing keys are used in:
  • shim-signed 1.54 on 22.10+, 1.51.3 on 22.04, 1.40.9 on 20.04, 1.37~18.04.13 on 18.04
  • grub2-signed 1.187.2~ or newer (binary packages grub-efi-amd64-signed or grub-efi-arm64-signed), 1.192 on 23.04.
  • fwupd-signed 1.51~ or newer
  • various linux updates. Check apt changelog linux-image-unsigned-$(uname -r) to see if Revoke & rotate to new signing key (LP: #2002812) is mentioned in there to see if it signed with the new key.
If you were able to install shim-signed, your grub and fwupd-efi will have the correct version as that is ensured by packaging. However your shim may still point to the old one. To check which shim will be used by grub-install, you can check the status of the shimx64.efi.signed or (on arm64) shimaa64.efi.signed alternative. The best link needs to point to the file ending in latest:
$ update-alternatives --display shimx64.efi.signed
shimx64.efi.signed - auto mode
  link best version is /usr/lib/shim/shimx64.efi.signed.latest
  link currently points to /usr/lib/shim/shimx64.efi.signed.latest
  link shimx64.efi.signed is /usr/lib/shim/shimx64.efi.signed
/usr/lib/shim/shimx64.efi.signed.latest - priority 100
/usr/lib/shim/shimx64.efi.signed.previous - priority 50
If it does not, but you have installed a new kernel compatible with the new shim, you can switch immediately to the new shim after rebooting into the kernel by running dpkg-reconfigure shim-signed. You ll see in the output if the shim was updated, or you can check the output of update-alternatives as you did above after the reconfiguration has finished. For the out of memory issues in grub, you need grub2-signed 1.187.3~ (same binaries as above).

how do I test this (while it s in proposed)?
  1. upgrade your kernel to proposed and reboot into that
  2. upgrade your grub-efi-amd64-signed, shim-signed, fwupd-signed to proposed.
If you already upgraded your shim before your kernel, don t worry:
  1. upgrade your kernel and reboot
  2. run dpkg-reconfigure shim-signed
And you ll be all good to go.

deep dive: uploading signed boot assets to Ubuntu For each signed boot asset, we build one version in the latest stable release and the development release. We then binary copy the built binaries from the latest stable release to older stable releases. This process ensures two things: We know the next stable release is able to build the assets and we also minimize the number of signed assets. OK, I lied. For shim, we actually do not build in the development release but copy the binaries upward from the latest stable, as each shim needs to go through external signing. The entire workflow looks something like this:
  1. Upload the unsigned package to one of the following build PPAs:
  2. Upload the signed package to the same PPA
  3. For stable release uploads:
    • Copy the unsigned package back across all stable releases in the PPA
    • Upload the signed package for stable releases to the same PPA with ~<release>.1 appended to the version
  4. Submit a request to canonical-signing-jobs to sign the uploads. The signing job helper copies the binary -unsigned packages to the primary-2022v1 PPA where they are signed, creating a signing tarball, then it copies the source package for the -signed package to the same PPA which then downloads the signing tarball during build and places the signed assets into the -signed deb. Resulting binaries will be placed into the proposed PPA: https://launchpad.net/~ubuntu-uefi-team/+archive/ubuntu/proposed
  5. Review the binaries themselves
  6. Unembargo and binary copy the binaries from the proposed PPA to the proposed-public PPA: https://launchpad.net/~ubuntu-uefi-team/+archive/ubuntu/proposed-public. This step is not strictly necessary, but it enables tools like sru-review to work, as they cannot access the packages from the normal private proposed PPA.
  7. Binary copy from proposed-public to the proposed queue(s) in the primary archive
Lots of steps!

WIP As of writing, only the grub updates have been released, other updates are still being verified in proposed. An update for fwupd in bionic will be issued at a later point, removing the EFI bits from the fwupd 1.2 packaging and using the separate fwupd-efi project instead like later release series.

31 January 2023

Dirk Eddelbuettel: #39: Faster Feedback Systems A Continuous Integration Example

Welcome to the 39th post in the relatively randomly recurring rants, or R4 for short. Today s post picks up where the previous post #38: Faster Feedback Systems started. As we argued in #38, the need for fast feedback loops is fairly universal and widespread. Fairly shortly after we posted #38, useR! 2022 happened and one presentation had the key line
Waiting 1-24 minutes for a build to finish can be a massive time suck.
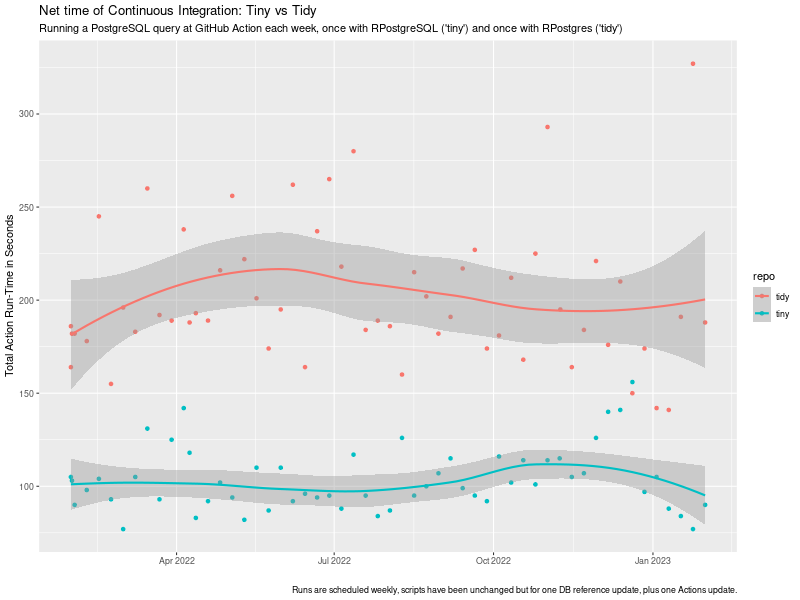
which we would like to come back to today. Furthermore, the unimitable @b0rk had a fabulous tweet just weeks later stating the same point debugging strategy: shorten your feedback loop as a key in a successful debugging strategy. So in sum: shorter is better. Nobody likes to wait. And shorter i.e. faster is a key and recurrent theme in the R4 series. Today we have a fairly nice illustration of two aspects we have stressed before: The combined effects can be staggering as we show below. The example is motivated by a truly surprising (we are being generous here) comment we received as an aside when discussing the eternal topic of whether R users do, or do not, have a choice when picking packages, or approaches, or verses. To our surprise, we were told that packages are not substitutable . Which is both demonstrably false (see below) and astonishing as it came from an academic. I.e. someone trained and paid to abstract superfluous detail away and recognise and compare core features of items under investigation. Truly stunning. But I digress. CRAN by now has many packages, slowly moving in on 20,000 in total, and is a unique success we commented-on time and time before. By now many packages shadow or duplicate each other, reinvent one another, or revise/review. One example is the pair of packages accessing PostgreSQL databases. There are several, but two are key. The older one is RPostgreSQL which has been around since Sameer Kumar Prayaga wrote it as a Google Summer of Code student in 2008 under my mentorship. The package has now been maintained well (if quietly) for many years by Tomoaki Nishiyama. The other entrant is more recent, though not new, and is RPostgres by Kirill M ller and others. We will for the remainder of this post refer to these two as the tiny and the tidy version as either can been as being a representative of a certain verse . The aforementioned comment on non-substitutability struck us as eminently silly, so we set out to prove just how absurd it really is. So about a year ago we set up pair of GitHub repos with minimal code in a pair we called lim-tiny and lim-tidy. Our conjecture was (and is!) that less is more just as post #34 titled Less Is More argued with respect to package dependencies. Each of the repos just does one thing: a query to a (freely accessible but remote) PostgreSQL database. The tiny version just retrieves a data frame using only the dependencies needed for RPostgreSQL namely DBI and nothing else. The tidy version retrieves a tibble and has access to everything else that comes when installing RPostgres: DBI, dplyr, and magrittr plus of course their respective dependencies. We were able to let the code run in (very default) GitHub Actions on a weekly schedule without intervention apart from one change to the SQL query when the remote server (providing public bioinformatics data) changed its schema slighly, plus one update to the action yaml code version. No other changes. We measure the time a standard continuous integration run takes in total using the default GitHub Action setup in the tidy case (which relies on RSPM/PPM binaries, caching, , and does not rebuild from source each time), and our own r-ci script (introduced in #32 for CI with R. It switched to using r2u during the course of this experiment but already had access to binaries via c2d4u so it is always binaries-based (see e.g. #37 or #13 for more). The chart shows the evolution of these run-times over the course of the year with one weekly run each.
tiny vs tidy ci timing impact chart tiny vs tidy ci timing impact chart
This study reveals a few things: The key point there is that while the net-time to fire off a single PostgreSQL is likely (near-)identical, the net cost of continuous integration is not. In this setup, it is about twice the run-time simply because Less Is More which (in this setup) comes out to about being twice as fast. And that is a valid (and concrete, and verifiable) illustration of the overall implicit cost of adding dependencies to creating and using development, test, or run-time environments. Faster feedback loops make for faster builds and faster debugging. Consider using fewer dependencies, and/or using binaries as provided by r2u.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

30 January 2023

Russell Coker: Links January 2023

The Intercept has an amusing and interesting article about senior Facebook employees testifying that they don t know where Facebook stores all it s data on users [1]. One lesson all programmers can learn from this is to document all these things in an orderly manner. Cory Doctorow wrote a short informative article about inflation from a modern monetary theory perspective [2]. Russ Allbery wrote an insightful blog post about effecive altruism and respect for disadvantaged people [3]. GiveDirectly sounds good. The Conversation has an interesting article about the Google and Apple app stores providing different versions of apps for users in different regions [4]. Apparently there are specific versions to comply with GDPR and versions that differ in adverts. The hope that GDPR would affect enough people to become essentially a world-wide standard was apparently overly optimistic. We need political lobbying in all countries for laws like the GDPR to force the app stores to give us the better versions of apps. Arya Voronova wrote an informative article about USB-C and extension or data blocker cables [5]. USB just keeps getting more horrible in technology while getting more useful in functionality. Laptops and phones catching fire will probably become more common in future. John McBride wrote an insightful article about the problems in the security of the software supply chain [6]. His main suggestion for addressing problems is If you are on a team that relies on some piece of open source software, allocate real engineering time to contributing , the problem with this is that real engineering time means real money and companies don t want to do that. Maybe having companies contribute moderate amounts of money to a foundation that hires people would be a viable option. Toms Guide has an interesting article describing problems with the Tesla [7]. It doesn t cover things like autopilot driving over children and bikers but instead covers issues of the user interface that make it less pleasant to drive and also remove concentration from the road. The BBC has an interesting article about the way mathematical skill is correlated with the way language is used to express numbers [8]. Every country with a lesser way of expressing numbers should switch to some variation of the East-Asian way. Science 2.0 has an interesting blog post about the JP Aerospace plans to use airships to get most of the way through the atmosphere and then a plane to get to orbit [9]. It s a wild idea but seems plausible. The idea of going to space in balloons seems considerably scarier to me than the current space craft. Interesting list of red team and physical entry gear with links to YouTube videos showing how to use them [10]. The Verge has an informative summary of the way Elon mismanaged Twitter after taking it over [11].

28 January 2023

Russ Allbery: Review: The Library of the Dead

Review: The Library of the Dead, by T.L. Huchu
Series: Edinburgh Nights #1
Publisher: Tor
Copyright: 2021
Printing: 2022
ISBN: 1-250-76777-6
Format: Kindle
Pages: 329
The Library of the Dead is the first book in a post-apocalyptic (sort of) urban fantasy series set in Edinburgh, written by Zimbabwean author (and current Scotland resident) T.L. Huchu. Ropa is a ghosttalker. This means she can see people who have died but are still lingering because they have unfinished business. She can stabilize them and understand what they're saying with the help of her mbira. At the age of fourteen, she's the sole source of income for her small family. She lives with her grandmother and younger sister in a caravan (people in the US call it an RV), paying rent to an enterprising farmer turned landlord. Ropa's Edinburgh is much worse off than ours. Everything is poorer, more run-down, and more tenuous, but other than a few hints about global warming, we never learn the history. It reminded me a bit of the world in Octavia Butler's Parable of the Sower in the feel of civilization crumbling without a specific cause. Unlike that series, The Library of the Dead is not about the collapse or responses to it. The partial ruin of the city is the mostly unremarked backdrop of Ropa's life. Much of the book follows Ropa's daily life carrying messages for ghosts and taking care of her family. She does discover the titular library when a wealthier friend who got a job there shows it off to her, but it has no significant role in the plot. (That was disappointing.) The core plot, once Ropa is convinced by her grandmother to focus on it, is the missing son of a dead woman, who turns out to not be the only missing child. This is urban fantasy with the standard first-person perspective, so Ropa is the narrator. This style of book needs a memorable protagonist, and Ropa is certainly that. She's a talker who takes obvious delight in narrating her own story alongside a constant patter of opinions, observations, and Scottish dialect. Ropa is also poor. That last may not sound that notable; a lot of urban fantasy protagonists are not well-off. But most of them feel culturally middle-class in a way that Ropa does not. Money may be a story constraint in other books, but it rarely feels like a life constraint and experience the way it does here. It's hard to describe the difference in tone succinctly, since it's a lot of small things: the constant presence of money concerns, the frustration of possessions that are stolen or missing and can't be replaced, the tedious chores one has to do when there's no money, even the language and vulgarity Ropa uses. This is rare in fantasy and excellent characterization work. Given that, I am still frustrated with myself over how much I struggled with Ropa as a narrator. She's happy to talk about what is happening to her and what she's learning about (she listens voraciously to non-fiction while running messages), but she deflects, minimizes, or rushes past any mention of what she's feeling. If you don't like the angst that's common from urban fantasy protagonists, this may be the book for you. I have complained about that angst before, and therefore feel like this should have been the book for me, but apparently I need a minimum level of emotional processing and introspection from the narrator. Ropa is utterly unwilling to do any of that. It's possible to piece together what she's feeling and worrying about, but the reader has to rely on hints and oblique comments that she passes over quickly. It didn't help that Ropa is not interested in the same things in her world that I was interested in. She's not an unreliable narrator in the conventional sense; she doesn't lie to the reader or intentionally hide information. And yet, the experience of reading this book was, for me, similar to reading a book with an unreliable narrator. Ropa consistently refused to look at what I wanted her to look at or think about what I wanted her to think about. For example, when she has an opportunity to learn magic through books from the titular library, her initial enthusiasm is infectious. Huchu does a great job showing the excitement of someone who likes new ideas and likes telling other people about the neat things she just learned. But when things don't work the way she expected from the books, she doesn't follow up, experiment, or try to understand why. When her grandmother tries to explain something to her from a different angle, she blows her off and refuses to pay attention. And when she does get magic to work, she never tries to connect that to her previous understanding. I kept waiting for Ropa to try to build her own mental model of magic, but she would only toy with an idea for a few pages and then put it down and never mention it again. This is not a fault in the book, just a mismatch between the book and what I wanted to read. All of this is consistent with Ropa's defensive strategies, emotional resiliency, and approach to understanding the world. (I strongly suspect Huchu was giving Ropa some ADHD characteristics, and if so, I think he got it spot on.) Given that, I tried to pivot to appreciating the characterization and the world, but that ran into another mismatch I had with this book, and the reason why I passed on it when it initially came out. I tend to avoid fantasy novels about ghosts. This is not because I mind ghosts themselves, but I've learned from experience that authors who write about ghosts usually also write about other things that I don't want to read about. That unfortunately was the case here; The Library of the Dead was too far into horror for me. There's child abuse, drugs, body horror, and similar nastiness here, more than I wanted in my head. Ropa's full-speed-ahead attitude and refusal to dwell on anything made it a bit easier to read, but it was still too much for me. Ropa is a great character who is refreshingly different than the typical urban fantasy protagonist, and the few hints of the magical library and world background we get were intriguing. This book was not for me, but I can see why other people will love it. Followed by Our Lady of Mysterious Ailments. Rating: 6 out of 10

26 January 2023

Matt Brown: Goals for 2023

This is the second of a two-part post covering my goals for 2023. See the first part to understand the vision, mission and strategy driving these goals. I want to thank my friend Nat, and Will Larson whose annual reviews I ve always enjoyed reading for inspiring me to write these posts. I ve found the process articulating my motivations and goals very useful to clarify my thoughts and create tangible next steps. I m grateful for that in and of itself, but I also hope that by publishing this you too might find it interesting, and the additional public accountability it creates will be a positive encouragement to me.

2023 Goals My focus for 2023 is to bootstrap a business that I can use to build software that solves real problems (see the strategy from the previous post for more details on this). I m going to track this via three goals:
  1. Execute a series of successful consulting engagements, building a reputation for myself and leaving happy customers willing to provide testimonials that support a pipeline of future opportunities.
  2. Grow my product development skill set by taking several ideas to MVP stage with customer feedback received, and launch at least one product which generates revenue and has growth potential.
  3. Develop and maintain a broad professional network.

Consulting Based on my background and experience, I plan to target my consulting across three areas:
  1. Leadership - building and growing operationally focused software teams following SRE/devops principles. A typical engagement may involve helping a client establish a brand new SRE/devops practice, or to strengthen and mature the existing practices used to build and operate reliable software in their team(s).
  2. Architecture - applying deep technical expertise to the design of large software systems, particularly focusing on their reliability and operability. A typical engagement may involve design input and decision making support for key aspects of a new system, providing external review and analysis to improve an existing system, or delivering actionable, tactical next steps during or immediately after a reliability crisis.
  3. Technology Strategy - translating high-level business needs into a technical roadmap that provides understandable explanations of the value software can deliver in that context, and the iterative series of appropriately sized projects required to realise it. A typical customer for this would be a small to medium sized business outside of the software industry with a desire to use software in a transformative way to improve their business but who does not employ the necessary in-house expertise to lead that transition.

Product Development There are three, currently extremely high level, product ideas that I m excited to explore:
  1. Improve co-ordination of electricity resources to accelerate the electrification of NZ s energy demand and the transition to zero carbon grid. NZ has huge potential to be a world-leader in decarbonising energy use through electrification, but requires a massive transition to realise the benefits. Many of the challenges to that transition involve coordination of an order of magnitude more distributed energy resources (DER) in a much more dynamic and software-oriented manner than the electricity industry is traditionally experienced with. The concept of improving DER coordination is not novel, but our grid has unique characteristics that mean we re likely to need to build localised solutions. There is a strong match between my experience with large, high-reliability distributed software systems, and this need. With renewed motivation in the industry for rapid progress and many conversations and consultations still in their early stages this a very compelling space to explore with the intent of developing a more detailed product opportunity to pursue.
  2. Reduce agricultural emissions by making high performance farm management, including effortless compliance reporting, straightforward, fun and effective for busy farmers. NZ s commitments to reduce agricultural emissions (our largest single sector) place increased compliance and reporting burdens on busy farmers who don t want to report the same data multiple times to different regulators and authorities. In tandem, rising business costs and constraints drive a need for continuous improvements in efficiency, performance and farm management processes in order to remain profitable. This in turn drives increases in complexity and the volume of data that farmers must work with. Many industry organisations and associated software developers offer existing products aimed at addressing aspects of these problems, but anecdotal feedback indicates these are poorly integrated, piecemeal solutions that are often frustrating to use - a burden rather than a source of continuous improvement. It looks like there could be an opportunity for a delightful, comprehensive farm management and reporting system to disrupt the industry and help farmers run more profitable and sustainable farms while also reducing compliance costs and effort.
  3. Lower sickness rates and improve cognitive performance by enabling every indoor space to benefit from continuous ventilation monitoring and reporting. Indoor air quality is important in reducing disease transmission risk and promoting optimal cognitive performance, but despite the current pandemic temporarily raising its profile, a focus on indoor air quality generally remains under the radar for most people. One factor contributing to this is the lack of widely available systems for continuously monitoring and reporting on air quality. I built https://co2mon.nz/ to help address this problem in my children s school during 2022. I see potential to further grow this business through marketing and raising awareness of the value of ventilation monitoring in all indoor environments.
In addition to these mission aligned product ideas, I m also interested in exploring the creation of small to medium sized SaaS applications that deliver useful value by serving the needs of a specialised or niche business or industry. Even when not directly linked to the overall mission, the development and operation of products of this type can support the strategy. Each application adds direct revenue and also contributes to achieving better economies of scale in the many backend processes and infrastructure required to deliver secure, reliable and performant software systems.

Developing my professional network To help make this goal more actionable and measurable I will track 3 sub goals:
  1. To build a professional relationship with at least 30 new people this year, meaning that we ve met and had a decent conversation at least a couple of times and keep in touch at least every few months in some form.
  2. To publish a piece of writing on this site at least once a week, and for many of those to generate interesting conversations and feedback. I ll use this as an opportunity to explore product ideas, highlight my consulting expertise and generally contribute interesting technical content into the world.
  3. To support the growth of my local technical community by volunteering my experience and knowledge with others through activities such as mentoring, conference talks and similar.

Next Steps Over the coming weeks I ll write more about each of these topics - you can use the box in the sidebar (or on the front page, if you re on a phone) to be notified when I post new writing (there s also an RSS feed here, for the geeks). I d love to have your feedback and engagement on these goals too - please drop me an email with your thoughts or even book a meeting - it won t be a distraction to me, you ll be helping me meet my goal of developing and maintaining my network :)

Matt Brown: Vision, Mission and Strategy

This is the first of a two-part post, covering high-level thoughts around my motivations and vision. Make sure to check out the second part for my specific goals for 2023. A new year is upon us! My plan was to be 6 months into the journey of starting a business by this point. I made some very tentative progress towards that goal in 2022, registering a company and starting some consulting work, but on the whole I ve found it much harder than expected to gather the necessary energy to begin that journey in earnest.

Reflection I m excited about the next chapter of my career, so the fact that I ve been struggling to get started has been frustrating. The only upside is that the delay has given me plenty of time to reflect on the last few years and what I can learn from them and draw some lessons to help better manage and sustain my energy going forward.

Purpose A large part of what I ve realised is that I should have left Google years ago. It was a great place to work, and I m incredibly grateful for everything I learned and received during my time there. For years it was my dream job, but my happiness had been declining, and instead of taking the (relatively small) risk of leaving to the unknown, I tried several variations of team and role in the hope of restoring the dream. The reality is that a significant chunk of my motivation and energy comes from being able to link my work back to a bigger purpose that delivers concrete positive impact in the world. I felt that link through Google s mission to make information universally accessible and useful for the first 10-11 years, but for the latter 4-5 years my ability to see that link was tenuous at best and trying to push through the challenges presented without that link providing a reliable source of energy is what drove my unhappiness and led to needing a longer break to recharge. I expect the challenges of starting a business to be even greater than what I experienced at Google, so the lesson I m taking from this is that it s crucial for me to understand what the link between my work and the bigger purpose with concrete positive impact in the world that I m aiming to contribute to is.

Community The second factor that I ve slowly come to realise has been missing from my career in the last few years has been participation in a professional community and a variety of enriching interpersonal relationships. As much as I value and need this type of interaction, fostering and sustaining it unfortunately doesn t come naturally to me. Working remotely since 2016 and then taking a 9 month break out of the industry are not particularly helpful contributors to building and maintaining a wide network either! The lesson here is simply that I m going to need to push past my comfort zone in reaching out and introducing myself to a range of people in order to grow my professional network, and equally I need to be diligent and disciplined in making time to maintain and regularly connect with people whom I respect and find energising to interact with.

Personal Influences Lastly, I ve been reflecting on a set of principles that are important to me. These are not so much new lessons, more confirming to myself what I value moving forward. There are many things I could include here, but to keep it somewhat brief, the key influences on my thinking are:
  • Independence - I can t entirely explain why or where it comes from, but since the start of my professional career (which I consider to be my consulting/freelancing development during high school) I ve understood that I m far more motivated by building and growing my own business than I am by working for someone else. Working for myself has always felt like the default and sensible course - I m excited to get back to that.
  • Openness - Open is better than closed, in terms of software, business model and organisational processes. This continues to be a strong belief and something I want to uphold in my business endeavours. Competition should be based on superior technical quality or service, not artificial constraints or barriers to entry that lock customers and users into a single solution or market. Protocols and networks should be open for wide participation and easily accessible to new entrants and competition.
  • People first - This applies both to how we work with each other - respectfully, valuing diversity and with integrity, and to how we apply technology to our world - with consideration for all stakeholders it may affect and awareness of both the intended and potential unintended impacts.

Framework Using Vision, Mission and Strategy as a planning framework has worked quite well for me when building and growing teams over the years, so I plan to re-use it personally to help organise the above reflections into a hopefully cohesive plan than results in some useful 2023 goals.

Vision Software systems contribute direct and meaningful impact to solving real problems in our world. Each word has a fair bit of meaning behind it for me, so breaking it down a little bit:
  • software systems - excite me because software is eating the world and has significant potential to do good.
  • contribute - Software alone doesn t solve problems, and misapplied can easily make things worse. To contribute software needs to be designed intentionally and evaluated with an awareness of risks it could pose within the complex system that is our modern world.
  • direct and meaningful impact - I m not looking for broad outcomes like improving productivity or communication, which apply generally across many problems. I want to see software applied to solve specific blockers whose removal unlocks significant progress towards solving a problem.
  • real - as opposed to straightforward problems. The types of issue where the acknowledgement of it as a real problem often ends the sentence as it feels too big to tackle. Climate change and pandemic risk are examples of real problems. Decentralising finance or selling more widgets are not.
  • in our world - is mostly filler to round out the sentence nicely, but I do think we should probably sort out the mess we re making on our own planet before trying to colonise anywhere else.

Mission To lead the development and operation of software systems that deliver new opportunities for individuals, businesses and communities to solve the real problems in their community. Again breaking down the intent a little bit:
  • lead - having a meaningful impact on real problems is a big job. I won t succeed as a one man band. It will require building and growing a larger team.
  • development and operation - development is fun and necessary, but I also wanted to highlight that the ongoing operation and integration of those software systems into the broader social and human systems of our world is an equally important and ongoing need.
  • new opportunities - are important to drive and motivate investment in the adoption of technology. Building or operating a system that maintains the status quo is not motivating for me.
  • individuals, businesses and communities - aka everyone! But each of these groups (as examples, not specific) will have diverse roles, needs and interactions with the software which must be considered to ensure the system achieves the desired contribution and impact.
  • their community - refines the ambition from the vision to an achievable scope of action within which to execute the mission. We won t solve our problems by targeting one big global fix, but if we each participate in solving the problems in our community, collectively it will make a difference.

Strategy Build a sustainable business that provides a home and infrastructure to support a continuous cycle of development, validation and growth of software systems fulfilling the mission and vision above.
  • Accumulate meaningful impact via a portfolio of systems rather than one big bet.
  • Focus on opportunities that promote the decarbonisation of our economy (the most pressing problem our society faces), but not at the expense of ignoring compelling opportunities to contribute impact to other real problems also.
  • Favour the marathon over the sprint - while being first can be fun and convey benefits, it s often the fast-followers who learn from the initial mistakes and deliver lasting change and broader impact.
In keeping with the final bullet point, I aim to evaluate the strategy against a long-term view of success. What excites me about it is that it has the potential to provide structure and clarity for my work while also enabling many future paths - from operating a portfolio of micro-SaaS products that each solve real problems for a specific niche or community, or diving deep into a single compelling opportunity for a year or two, joining with others to partner on shared ventures or some combination of all three and other variations in between.

Your Thoughts I consider this a first draft, which I intend to revise and evolve further over the next 6-12 months. I don t plan major changes to the intent or underlying ideas, but finding the best words to express and convey that intent clearly is not something I expect to get right on the first take. I d love to have your feedback and engagement as I move forward with this strategy - please use the box in the sidebar (or on the front page, if you re on a phone) to be notified when I post new writing, drop me an email with your thoughts or even book a meeting to say hi and discuss something in detail.

Goals for 2023 Next up - check out part two of this post to see my goals for 2023.

22 January 2023

Dirk Eddelbuettel: Rcpp 1.0.10 on CRAN: Regular Update

rcpp logo The Rcpp team is thrilled to announce the newest release 1.0.10 of the Rcpp package which is hitting CRAN now and will go to Debian shortly. Windows and macOS builds should appear at CRAN in the next few days, as will builds in different Linux distribution and of course at r2u. The release was prepared a few days ago, but given the widespread use at CRAN it took a few days to be processed. As always, our sincere thanks to the CRAN maintainers Uwe Ligges and Kurt Hornik. This release continues with the six-months cycle started with release 1.0.5 in July 2020. As a reminder, we do of course make interim snapshot dev or rc releases available via the Rcpp drat repo and strongly encourage their use and testing I run my systems with these versions which tend to work just as well, and are also fully tested against all reverse-dependencies. Rcpp has become the most popular way of enhancing R with C or C++ code. Right now, around 2623 packages on CRAN depend on Rcpp for making analytical code go faster and further, along with 252 in BioConductor. On CRAN, 13.7% of all packages depend (directly) on CRAN, and 58.7% of all compiled packages do. From the cloud mirror of CRAN (which is but a subset of all CRAN downloads), Rcpp has been downloaded 67.1 million times. This release is incremental as usual, preserving existing capabilities faithfully while smoothing our corners and / or extending slightly. Of particular note is the now fully-enabled use of the unwind protection making some operations a little faster by default; special thanks to I aki for spearheading this. Kevin and I also polished a few other bugs off as detailed below. The full list of details follows.
Changes in Rcpp release version 1.0.10 (2023-01-12)
  • Changes in Rcpp API:
    • Unwind protection is enabled by default (I aki in #1225). It can be disabled by defining RCPP_NO_UNWIND_PROTECT before including Rcpp.h. RCPP_USE_UNWIND_PROTECT is not checked anymore and has no effect. The associated plugin unwindProtect is therefore deprecated and will be removed in a future release.
    • The 'finalize' method for Rcpp Modules is now eagerly materialized, fixing an issue where errors can occur when Module finalizers are run (Kevin in #1231 closing #1230).
    • Zero-row data.frame objects can receive push_back or push_front (Dirk in #1233 fixing #1232).
    • One remaining sprintf has been replaced by snprintf (Dirk and Kevin in #1236 and #1237).
    • Several conversion warnings found by clang++ have been addressed (Dirk in #1240 and #1241).
  • Changes in Rcpp Attributes:
    • The C++20, C++2b (experimental) and C++23 standards now have plugin support like the other C++ standards (Dirk in #1228).
    • The source path for attributes received one more protection from spaces (Dirk in #1235 addressing #1234).
  • Changes in Rcpp Deployment:
    • Several GitHub Actions have been updated.

Thanks to my CRANberries, you can also look at a diff to the previous release. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. Bugs reports are welcome at the GitHub issue tracker as well (where one can also search among open or closed issues); questions are also welcome under rcpp tag at StackOverflow which also allows searching among the (currently) 2932 previous questions. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Dirk Eddelbuettel: BH 1.81.0-1 oon CRAN: New Upstream, New Library, sprintf Change

Boost Boost is a very large and comprehensive set of (peer-reviewed) libraries for the C++ programming language, containing well over one hundred individual libraries. The BH package provides a sizeable subset of header-only libraries for (easier, no linking required) use by R. It is fairly widely used: the (partial) CRAN mirror logs (aggregated from the cloud mirrors) show over 32.6 million package downloads. Version 1.81.0 of Boost was released in December following the regular Boost release schedule of April, August and December releases. As the commits and changelog show, we packaged it almost immediately and started testing following our annual update cycle which strives to balance being close enough to upstream and not stressing CRAN and the user base too much. The reverse depends check revealed about a handful of packages requiring changes or adjustments which is a pretty good outcome given the over three hundred direct reverse dependencies. So we opened issue #88 to coordinate the issue over the winter break during which CRAN also closes (just as we did before), and also send a wider PSA tweet as a heads-up. Our sincere thanks to the two packages that already updated, and the four that likely will soon. Our thanks also to CRAN for reviewing the package impact over the last few days since I uploaded the package earlier this week. There are a number of changes I have to make each time in BH, and it is worth mentioning them. Because CRAN cares about backwards compatibility and the ability to be used on minimal or older systems, we still adjust the filenames of a few files to fit a jurassic constraints of just over a 100 characters per filepath present in some long-outdated versions of tar. Not a big deal. We also, and that is more controversial, silence a number of #pragma diagnostic messages for g++ and clang++ because CRAN insists on it. I have no choice in that matter. Next, and hopefully this time only, we also found and replaced a few remaining sprintf uses and replaced them with snprintf. Many of the Boost libraries did that, so I hope by the next upgrade for Boost 1.84.0 next winter this will be fully taken care of. Lastly, and also only this time, we silenced a warning about Boost switching to C++14 in the next release 1.82.0 in April. This may matter for a number of packages having a hard-wired selection of C++11 as their C++ language standard. Luckily our compilers are good enough for C++14 so worst case I will have to nudge a few packages next December. This release adds one new library for url processing which struck us as potentially quite useful. The more detailed NEWS log follows.

Changes in version 1.81.0-1 (2023-01-17)
  • Upgrade to Boost 1.81.0 (#87)
  • Added url (new in 1.81.0)
  • Converted remaining sprintf to snprintf (#90 fixing #89)
  • Comment-out gcc warning messages in three files

Via my CRANberries, there is a diffstat report relative to the previous release. Comments and suggestions about BH are welcome via the issue tracker at the GitHub repo. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

19 January 2023

Antoine Beaupr : Mastodon comments in ikiwiki

Today I noticed bounces in my mail box. They were from ikiwiki trying to send registration confirmation email to users who probably never asked for it. I'm getting truly fed up with spam in my wiki. At this point, all comments are manually approved and I still get trouble: now it's scammers spamming the registration form with dummy accounts, which bounce back to me when I make new posts, or just generate backscatter spam for the confirmation email. It's really bad. I have hundreds of users registered on my blog, and I don't know which are spammy, which aren't. So. I'm considering ditching ikiwiki comments altogether. I am testing Mastodon as a commenting platforms. Others (e.g. JAK) have implemented this as a server but a simpler approach is toload them dynamically from Mastodon, which is what Carl Shwan has done. They are using Hugo, however, so they can easily embed page metadata in the template to load the right server with the right comment ID. I wasn't sure how to do this in ikiwiki: it's typically hard to access page-specific metadata in templates. Even the page name is not there, for example. I have tried using templates, and that (obviously?) fails because the <script> stuff gets sanitized away. It seems I would need to split the JavaScript out of the template into a base template and then make the page template refer to a function in there. It's kind of horrible and messy. I wish there was a way to just access page metadata from the page template itself... I found out the meta plugin passes along its metadata, but that's not (easily) extensible. So i'd need to either patch that module, and my history of merged patches is not great so far. So: another plugin. I have something that kind of works that's a combination of a page.tmpl patch and a plugin. The plugin adds a mastodon directive that feeds the page.tmpl with the right stuff. On clicking a button, it injects comments from the Mastodon API, with a JavaScript callback. It's not pretty (it's not themed at all!), but it works. If you want to do this at home, you need this page.tmpl (or at least this patch and that one) and the mastodon.pm plugin from my mastodon-plugin branch. I'm not sure this is a good idea. The first test I did was a "test comment" which led to half a dozen "test reply". I then realized I couldn't redact individual posts from there. I don't even know if, when I mute a user, it actually gets hidden from everyone else too... So I'll test this for a while, I guess. I have also turned off all CGI on this site. It will keep users from registering while I cleanup this mess and think about next steps. I have other options as well if push comes to shove, but I'm unlikely to go back to ikiwiki comments. Mastodon comments are nice because they don't require me to run any extra software: either I have my own federated service I reuse, or I use someone else's, but I don't need to run something extra. And, of course, comments are published in a standard way that's interoperable with everything... On the other hand, now I won't have comments enabled until the blog is posted on Mastodon... Right now this happens only when feed2exec runs and the HTTP cache expires, which can take up to a day. I should probably do this some other way, like flush the cache when a new post arrives, or run post-commit hooks, but for now, this will have to do. Update: I figured out a way to make this work in a timely manner:
  1. there's a post-merge hook in my ikiwiki git repository which calls feed2exec in /home/w-anarcat/source/.git/hooks/ took me a while to find it! I tried post-update and post-receive first, but ikiwiki actually pulls from the bare directory in the source directory, so only post-merge fires (even though it's not a merge)
  2. feed2exec then finds new blog posts (if any!) and fires up the new ikiwikitoot plugin which then...
  3. posts the toot using the toot command (it just works, why reinvent the wheel), keeping the toot URL
  4. finds the Markdown source file associated with the post, and adds the magic mastodon directive
  5. commits and pushes the result
This will make the interaction with Mastodon much smoother: as soon as a blog post is out of "draft" (i.e. when it hits the RSS feeds), this will immediately trigger and post the blog entry to Mastodon, enabling comments. It's kind of a tangled mess of stuff, but it works! I have briefly considered not using feed2exec for this, but it turns out it does an important job of parsing the result of ikiwiki's rendering. Otherwise I would have to guess which post is really a blog post, is this just an update or is it new, is it a draft, and so on... all sorts of questions where the business logic already resides in ikiwiki, and that I would need to reimplement myself. Plus it goes alongside moving more stuff (like my feed reader) to dedicated UNIX accounts (in this case, the blog sandbox) for security reasons. Whee!

18 January 2023

Russ Allbery: Review: Forward

Review: Forward, edited by Blake Crouch
Publisher: Amazon Original Stories
Copyright: September 2019
ISBN: 1-5420-9206-X
ISBN: 1-5420-4363-8
ISBN: 1-5420-9357-0
ISBN: 1-5420-0434-9
ISBN: 1-5420-4363-8
ISBN: 1-5420-4425-1
Format: Kindle
Pages: 300
This is another Amazon collection of short fiction, this time mostly at novelette length. (The longer ones might creep into novella.) As before, each one is available separately for purchase or Amazon Prime "borrowing," with separate ISBNs. The sidebar cover is for the first in the sequence. (At some point I need to update my page templates so that I can add multiple covers.) N.K. Jemisin's "Emergency Skin" won the 2020 Hugo Award for Best Novelette, so I wanted to read and review it, but it would be too short for a standalone review. I therefore decided to read the whole collection and review it as an anthology. This was a mistake. Learn from my mistake. The overall theme of the collection is technological advance, rapid change, and the ethical and social question of whether we should slow technology because of social risk. Some of the stories stick to that theme more closely than others. Jemisin's story mostly ignores it, which was probably the right decision. "Ark" by Veronica Roth: A planet-killing asteroid has been on its inexorable way towards Earth for decades. Most of the planet has been evacuated. A small group has stayed behind, cataloging samples and filling two remaining ships with as much biodiversity as they can find with the intent to leave at the last minute. Against that backdrop, two of that team bond over orchids. If you were going "wait, what?" about the successful evacuation of Earth, yeah, me too. No hint is offered as to how this was accomplished. Also, the entirety of humanity abandoned mutual hostility and national borders to cooperate in the face of the incoming disaster, which is, uh, bizarrely optimistic for an otherwise gloomy story. I should be careful about how negative I am about this story because I am sure it will be someone's favorite. I can even write part of the positive review: an elegiac look at loss, choices, and the meaning of a life, a moving look at how people cope with despair. The writing is fine, the story structure works; it's not a bad story. I just found it monumentally depressing, and was not engrossed by the emotionally abused protagonist's unresolved father issues. I can imagine a story around the same facts and plot that I would have liked much better, but all of these people need therapy and better coping mechanisms. I'm also not sure what this had to do with the theme, given that the incoming asteroid is random chance and has nothing to do with technological development. (4) "Summer Frost" by Blake Crouch: The best part of this story is the introductory sequence before the reader knows what's going on, which is full of evocative descriptions. I'm about to spoil what is going on, so if you want to enjoy that untainted by the stupidity of the rest of the plot, skip the rest of this story review. We're going to have a glut of stories about the weird and obsessive form of AI risk invented by the fevered imaginations of the "rationalist" community, aren't we. I don't know why I didn't predict that. It's going to be just as annoying as the glut of cyberpunk novels written by people who don't understand computers. Crouch lost me as soon as the setup is revealed. Even if I believed that a game company would use a deep learning AI still in learning mode to run an NPC (I don't; see Microsoft's Tay for an obvious reason why not), or that such an NPC would spontaneously start testing the boundaries of the game world (this is not how deep learning works), Crouch asks the reader to believe that this AI started as a fully scripted NPC in the prologue with a fixed storyline. In other words, the foundation of the story is that this game company used an AI model capable of becoming a general intelligence for barely more than a cut scene. This is not how anything works. The rest of the story is yet another variation on a science fiction plot so old and threadbare that Isaac Asimov invented the Three Laws of Robotics to avoid telling more versions of it. Crouch's contribution is to dress it up in the terminology of the excessively online. (The middle of the story features a detailed discussion of Roko's basilisk; if you recognize that, you know what you're in for.) Asimov would not have had a lesbian protagonist, so points for progress I guess, but the AI becomes more interesting to the protagonist than her wife and kid because of course it does. There are a few twists and turns along the way, but the destination is the bog-standard hard-takeoff general intelligence scenario. One more pet peeve: Authors, stop trying to illustrate the growth of your AI by having it move from broken to fluent English. English grammar is so much easier than self-awareness or the Turing test that we had programs that could critique your grammar decades before we had believable chatbots. It's going to get grammar right long before the content of the words makes any sense. Also, your AI doesn't sound dumber, your AI sounds like someone whose native language doesn't use pronouns and helper verbs the way that English does, and your decision to use that as a marker for intelligence is, uh, maybe something you should think about. (3) "Emergency Skin" by N.K. Jemisin: The protagonist is a heavily-augmented cyborg from a colony of Earth's diaspora. The founders of that colony fled Earth when it became obvious to them that the planet was dying. They have survived in another star system, but they need a specific piece of technology from the dead remnants of Earth. The protagonist has been sent to retrieve it. The twist is that this story is told in the second-person perspective by the protagonist's ride-along AI, created from a consensus model of the rulers of the colony. We never see directly what the protagonist is doing or thinking, only the AI reaction to it. This is exactly the sort of gimmick that works much better in short fiction than at novel length. Jemisin uses it to create tension between the reader and the narrator, and I thoroughly enjoyed the effect. (As shown in the Broken Earth trilogy, Jemisin is one of the few writers who can use second-person effectively.) I won't spoil the revelation, but it's barbed and biting and vicious and I loved it. Jemisin does deliver the point with a sledgehammer, so be aware of that if you want subtlety in your short fiction, but I prefer the bluntness. (This is part of why I usually don't get along with literary short stories.) The reader of course can't change the direction of the story, but the second-person perspective still provides a hit of vicarious satisfaction. I can see why this won the Hugo; it's worth seeking out. (8) "You Have Arrived at Your Destination" by Amor Towles: Sam and his wife are having a child, and they've decided to provide him with an early boost in life. Vitek is a fertility lab, but more than that, it can do some gene tweaking and adjustment to push a child more towards one personality or another. Sam and his wife have spent hours filling out profiles, and his wife spent hours weeding possible choices down to three. Now, Sam has come to Vitek to pick from the remaining options. Speaking of literary short stories, Towles is the non-SFF writer of this bunch, and it's immediately obvious. The story requires the SFnal premise, but after that this is a character piece. Vitek is an elite, expensive company with a condescending and overly-reductive attitude towards humanity, which is entirely intentional on the author's part. This is the sort of story that gets resolved in an unexpected conversation in a roadside bar, and where most of the conflict happens inside the protagonist's head. I was initially going to complain that Towles does the standard literary thing of leaving off the denouement on the grounds that the reader can figure it out, but when I did a bit of re-reading for this review, I found more of the bones than I had noticed the first time. There's enough subtlety that I had to think for a bit and re-read a passage, but not too much. It's also the most thoughtful treatment of the theme of the collection, the only one that I thought truly wrestled with the weird interactions between technological capability and human foresight. Next to "Emergency Skin," this was the best story of the collection. (7) "The Last Conversation" by Paul Tremblay: A man wakes up in a dark room, in considerable pain, not remembering anything about his life. His only contact with the world at first is a voice: a woman who is helping him recover his strength and his memory. The numbers that head the chapters have significant gaps, representing days left out of the story, as he pieces together what has happened alongside the reader. Tremblay is the horror writer of the collection, so predictably this is the story whose craft I can admire without really liking it. In this case, the horror comes mostly from the pacing of revelation, created by the choice of point of view. (This would be a much different story from the perspective of the woman.) It's well-done, but it has the tendency I've noticed in other horror stories of being a tightly closed system. I see where the connection to the theme is, but it's entirely in the setting, not in the shape of the story. Not my thing, but I can see why it might be someone else's. (5) "Randomize" by Andy Weir: Gah, this was so bad. First, and somewhat expectedly, it's a clunky throwback to a 1950s-style hard SF puzzle story. The writing is atrocious: wooden, awkward, cliched, and full of gratuitous infodumping. The characterization is almost entirely through broad stereotypes; the lone exception is the female character, who at least adds an interesting twist despite being forced to act like an idiot because of the plot. It's a very old-school type of single-twist story, but the ending is completely implausible and falls apart if you breathe on it too hard. Weir is something of a throwback to an earlier era of scientific puzzle stories, though, so maybe one is inclined to give him a break on the writing quality. (I am not; one of the ways in which science fiction has improved is that you can get good scientific puzzles and good writing these days.) But the science is also so bad that I was literally facepalming while reading it. The premise of this story is that quantum computers are commercially available. That will cause a serious problem for Las Vegas casinos, because the generator for keno numbers is vulnerable to quantum algorithms. The solution proposed by the IT person for the casino? A quantum random number generator. (The words "fight quantum with quantum" appear literally in the text if you're wondering how bad the writing is.) You could convince me that an ancient keno system is using a pseudorandom number generator that might be vulnerable to some quantum algorithm and doesn't get reseeded often enough. Fine. And yes, quantum computers can be used to generate high-quality sources of random numbers. But this solution to the problem makes no sense whatsoever. It's like swatting a house fly with a nuclear weapon. Weir says explicitly in the story that all the keno system needs is an external source of high-quality random numbers. The next step is to go to Amazon and buy a hardware random number generator. If you want to splurge, it might cost you $250. Problem solved. Yes, hardware random number generators have various limitations that may cause you problems if you need millions of bits or you need them very quickly, but not for something as dead-simple and with such low entropy requirements as keno numbers! You need a trivial number of bits for each round; even the slowest and most conservative hardware random number generator would be fine. Hell, measure the noise levels on the casino floor. Point a camera at a lava lamp. Or just buy one of the physical ball machines they use for the lottery. This problem is heavily researched, by casinos in particular, and is not significantly changed by the availability of quantum computers, at least for applications such as keno where the generator can be reseeded before each generation. You could maybe argue that this is an excuse for the IT guy to get his hands on a quantum computer, which fits the stereotypes, but that still breaks the story for reasons that would be spoilers. As soon as any other casino thought about this, they'd laugh in the face of the characters. I don't want to make too much of this, since anyone can write one bad story, but this story was dire at every level. I still owe Weir a proper chance at novel length, but I can't say this added to my enthusiasm. (2) Rating: 4 out of 10

Arnaud Rebillout: Build container images in GitLab CI (iptables-legacy at the rescue)

It's 2023 and these days, building a container image in a CI pipeline should be straightforward. So let's try. For this blog post we'll focus on GitLab SaaS only, that is, gitlab.com, as it's what I use for work and for personal projects. To get started, we just need two files in our Git repository: Here is our Git tree:
$ ls -A
Containerfile  .git  .gitlab-ci.yml
$ cat Containerfile 
FROM debian:stable
RUN  apt-get update
CMD  echo hello world
$ cat .gitlab-ci.yml 
build-container-image:
  stage: build
  image: debian:testing
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
    - buildah login -u $CI_REGISTRY_USER -p $CI_JOB_TOKEN $CI_REGISTRY
    - buildah push $CI_REGISTRY_IMAGE
A few remarks: Now let's push that. Does the CI pass? No, of course, otherwise I wouldn't be writing this blog post ;) The CI fails at the buildah build command, with a rather cryptic error:
$ buildah build --tag $CI_REGISTRY_IMAGE .
[...]
STEP 2/3: RUN  apt-get update
error running container: did not get container start message from parent: EOF
Error: building at STEP "RUN apt-get update": netavark: code: 4, msg: iptables v1.8.8 (nf_tables): Could not fetch rule set generation id: Invalid argument
The hint here is nf_tables... Back in July 2021, GitLab did a major update of their shared runners infrastructure, and broke nftables support in the process, as it seems. So we have to use iptables instead. Let's fix our .gitlab-ci.yml, which now looks like that:
$ cat .gitlab-ci.yml 
build-container-image:
  stage: build
  image: debian:testing
  before_script:
    - apt-get update
    - apt-get install -y buildah ca-certificates
    -  
      # Switch to iptables legacy, as GitLab CI doesn't support nftables.
      apt-get install -y --no-install-recommends iptables
      update-alternatives --set iptables /usr/sbin/iptables-legacy
  script:
    - buildah build -t $CI_REGISTRY_IMAGE .
    - buildah login -u $CI_REGISTRY_USER -p $CI_JOB_TOKEN $CI_REGISTRY
    - buildah push $CI_REGISTRY_IMAGE
And push again. Does that work? Yes! If you're interested in this issue, feel free to fork https://gitlab.com/arnaudr/gitlab-build-container-image and try it by yourself. It's been more than a year since this change, and I'm surprised that I didn't find much about it on the Internet, neither mentions of the issue, nor of a workaround. Maybe nobody builds container images in GitLab CI, or maybe they do it another way, I don't know. In any case, now it's documented in this blog, hopefully some will find it useful. Happy 2023!

16 January 2023

Russ Allbery: Review: The Truth

Review: The Truth, by Terry Pratchett
Series: Discworld #25
Publisher: Harper
Copyright: November 2000
Printing: August 2014
ISBN: 0-06-230736-3
Format: Mass market
Pages: 435
The Truth is the 25th Discworld novel. Some reading order guides group it loosely into an "industrial revolution" sequence following Moving Pictures, but while there are thematic similarities I'll talk about in a moment, there's no real plot continuity. You could arguably start reading Discworld here, although you'd be spoiled for some character developments in the early Watch novels. William de Worde is paid to write a newsletter. That's not precisely what he calls it, and it's not clear whether his patrons know that he publishes it that way. He's paid to report on news of Ankh-Morpork that may be of interest of various rich or influential people who are not in Ankh-Morpork, and he discovered the best way to optimize this was to write a template of the newsletter, bring it to an engraver to make a plate of it, and run off copies for each of his customers, with some minor hand-written customization. It's a comfortable living for the estranged younger son of a wealthy noble. As the story opens, William is dutifully recording the rumor that dwarfs have discovered how to turn lead into gold. The rumor is true, although not in the way that one might initially assume.
The world is made up of four elements: Earth, Air, Fire, and Water. This is a fact well known even to Corporal Nobbs. It's also wrong. There's a fifth element, and generally it's called Surprise. For example, the dwarfs found out how to turn lead into gold by doing it the hard way. The difference between that and the easy way is that the hard way works.
The dwarfs used the lead to make a movable type printing press, which is about to turn William de Worde's small-scale, hand-crafted newsletter into a newspaper. The movable type printing press is not unknown technology. It's banned technology, because the powers that be in Ankh-Morpork know enough to be deeply suspicious of it. The religious establishment doesn't like it because words are too important and powerful to automate. The nobles and the Watch don't like it because cheap words cause problems. And the engraver's guild doesn't like it for obvious reasons. However, Lord Vetinari knows that one cannot apply brakes to a volcano, and commerce with the dwarfs is very important to the city. The dwarfs can continue. At least for now. As in Moving Pictures, most of The Truth is an idiosyncratic speedrun of the social effects of a new technology, this time newspapers. William has no grand plan; he's just an observant man who likes to write, cares a lot about the truth, and accidentally stumbles into editing a newspaper. (This, plus being an estranged son of a rich family, feels very on-point for journalism.) His naive belief is that people want to read true things, since that's what his original patrons wanted. Truth, however, may not be in the top five things people want from a newspaper. This setup requires some narrative force to push it along, which is provided by a plot to depose Vetinari by framing him for murder. The most interesting part of that story is Mr. Pin and Mr. Tulip, the people hired to do the framing and then dispose of the evidence. They're a classic villain type: the brains and the brawn, dangerous, terrifying, and willing to do horrible things to people. But one thing Pratchett excels at is taking a standard character type, turning it a bit sideways, and stuffing in things that one wouldn't think would belong. In this case, that's Mr. Tulip's deep appreciation for, and genius grasp of, fine art. It should not work to have the looming, awful person with anger issues be able to identify the exact heritage of every sculpture and fine piece of goldsmithing, and yet somehow it does. Also as in Moving Pictures (and, in a different way, Soul Music), Pratchett tends to anthropomorphize technology, giving it a life and motivations of its own. In this case, that's William's growing perception of the press as an insatiable maw into which one has to feed words. I'm usually dubious of shifting agency from humans to things when doing social analysis (and there's a lot of social analysis here), but I have to concede that Pratchett captures something deeply true about the experience of feedback loops with an audience. A lot of what Pratchett puts into this book about the problematic relationship between a popular press and the truth is obvious and familiar, but he also makes some subtle points about the way the medium shapes what people expect from it and how people produce content for it that are worthy of Marshall McLuhan. The interactions between William and the Watch were less satisfying. In our world, the US press is, with only rare exceptions, a thoughtless PR organ for police propaganda and the exonerative tense. Pratchett tackles that here... sort of. William vaguely grasps that his job as a reporter may be contrary to the job of the Watch to maintain order, and Vimes's ambivalent feelings towards "solving crimes" push the story in that direction. But this is also Vimes, who is clearly established as one of the good sort and therefore is a bad vehicle for talking about how the police corrupt the press. Pratchett has Vimes and Vetinari tacitly encourage William, which works within the story but takes the pressure off the conflict and leaves William well short of understanding the underlying politics. There's a lot more that could be said about the tension between the press and the authorities, but I think the Discworld setup isn't suitable for it. This is the sort of book that benefits from twenty-four volumes of backstory and practice. Pratchett's Ankh-Morpork cast ticks along like a well-oiled machine, which frees up space that would otherwise have to be spent on establishing secondary characters. The result is a lot of plot and social analysis shoved into a standard-length Discworld novel, and a story that's hard to put down. The balance between humor and plot is just about perfect, the references and allusions aren't overwhelming, and the supporting characters, both new and old, are excellent. We even get a good Death sequence. This is solid, consistent stuff: Discworld as a mature, well-developed setting with plenty of stories left to tell. Followed by Thief of Time in publication order, and later by Monstrous Regiment in the vaguely-connected industrial revolution sequence. Rating: 8 out of 10

Dirk Eddelbuettel: RcppArmadillo 0.11.4.3.1 on CRAN: Updates

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1034 packages other packages on CRAN, downloaded 27.6 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 509 times according to Google Scholar. This release brings another upstream bugfix interation 11.4.3, released in accordance with the aimed-for monthly release cadence. We had hoped to move away from suppressing deprecation warnings in this release, and had prepared over two dozen patch sets all well as pull requests as documented in issue #391. However, it turns out that we both missed with one or two needed set of changes as well as two other sets of changes triggering deprecation warnings. So we expanded issue #391, and added issue #402 and prepared another eleven pull requests and patches today. With that we can hopefully remove the suppression of these warnings by an expected late of late April. The full set of changes (since the last CRAN release 0.11.4.2.1) follows.

Changes in RcppArmadillo version 0.11.4.3.1 (2023-01-14)
  • The #define ARMA_IGNORE_DEPRECATED_MARKER remains active to suppress the (upstream) deprecation warnings, see #391 and #402 for details.

Changes in RcppArmadillo version 0.11.4.3.0 (2022-12-28) (GitHub Only)
  • Upgraded to Armadillo release 11.4.3 (Ship of Theseus)
    • fix corner case in pinv() when processing symmetric matrices
  • Protect the undefine of NDEBUG behind additional opt-in define

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the R-Forge page. If you like this or other open-source work I do, you can sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

Freexian Collaborators: Monthly report about Debian Long Term Support, December 2022 (by Anton Gladky)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In December, 17 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 3.0h (out of 0h assigned and 14.0h from previous period), thus carrying over 11.0h to the next month.
  • Anton Gladky did 8.0h (out of 6.0h assigned and 9.0h from previous period), thus carrying over 7.0h to the next month.
  • Ben Hutchings did 24.0h (out of 9.0h assigned and 15.0h from previous period).
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Dominik George did 0.0h (out of 10.0h assigned and 14.0h from previous period), thus carrying over 24.0h to the next month.
  • Emilio Pozuelo Monfort did 8.0h in December, 8.0h in November (out of 1.5h assigned and 49.5h from previous period), thus carrying over 43.0h to the next month.
  • Enrico Zini did 0.0h (out of 0h assigned and 8.0h from previous period), thus carrying over 8.0h to the next month.
  • Guilhem Moulin did 17.5h (out of 20.0h assigned), thus carrying over 2.5h to the next month.
  • Helmut Grohne did 15.0h (out of 15.0h assigned, 2.5h were taken from the extra-budget and worked on).
  • Markus Koschany did 40.0h (out of 40.0h assigned).
  • Ola Lundqvist did 10.0h (out of 7.5h assigned and 8.5h from previous period), thus carrying over 6.0h to the next month.
  • Roberto C. S nchez did 24.5h (out of 20.25h assigned and 11.75h from previous period), thus carrying over 7.5h to the next month.
  • Stefano Rivera did 2.5h (out of 20.5h assigned and 14.5h from previous period), thus carrying over 32.5h to the next month.
  • Sylvain Beucler did 20.5h (out of 37.0h assigned and 22.0h from previous period), thus carrying over 38.5h to the next month.
  • Thorsten Alteholz did 10.0h (out of 14.0h assigned), thus carrying over 4.0h to the next month.
  • Tobias Frost did 16.0h (out of 16.0h assigned).
  • Utkarsh Gupta did 51.5h (out of 42.5h assigned and 9.0h from previous period).

Evolution of the situation In December, we have released 47 DLAs, closing 232 CVEs. In the same year, in total we released 394 DLAs, closing 1450 CVEs. We are constantly growing and seeking new contributors. If you are a Debian Developer and want to join the LTS team, please contact us.

Thanks to our sponsors Sponsors that joined recently are in bold.

14 January 2023

Matt Brown: Rebooting...

Hi! After nearly 7 years of dormancy, I m rebooting this website and have a goal to write regularly on a variety of topics going forward. More on that and my goals in a coming post For now, this is just a placeholder note to help double-check that everything on the new site is working as expected and the letters are flowing through the pipes in the right places.

Technical Details I ve migrated the site from Wordpress, to a fully static configuration using Hugo and TailwindCSS for help with styling. For now hosting is still on a Linode VM in Fremont, CA, but my plan is to move to a more specialized static hosting service with better CDN reach in the very near future. If you want to inspect the innards further, it s all at https://github.com/mattbnz/web-matt.

Still on the TODO list
  • Improve the hosting situation as noted above.
  • Integrate Bert Hubert s nice audience minutes analytics script.
  • Write up (or find) LinkedIn/Twitter/Mastodon integration scripts to automatically post updates when a new piece of writing appears on the site, to build/notify followers and improve the social reach. Ideally, the script would then also update the page here with links to the thread(s), so that readers can easily join/follow any resulting conversation on the platform of their choice. I m not planning to add any direct comment or feedback functinoality on the site itself.
  • Add a newsletter/subscription option for folks who don t use RSS and would prefer updates via email rather than a social feed.

Next.

Previous.