Search Results: "zed"

12 October 2017

Joachim Breitner: Isabelle functions: Always total, sometimes undefined

Often, when I mention how things work in the interactive theorem prover [Isabelle/HOL] (in the following just Isabelle 1) to people with a strong background in functional programming (whether that means Haskell or Coq or something else), I cause confusion, especially around the issue of what is a function, are function total and what is the business with undefined. In this blog post, I want to explain some these issues, aimed at functional programmers or type theoreticians. Note that this is not meant to be a tutorial; I will not explain how to do these things, and will focus on what they mean.

HOL is a logic of total functions If I have a Isabelle function f :: a b between two types a and b (the function arrow in Isabelle is , not ), then by definition of what it means to be a function in HOL whenever I have a value x :: a, then the expression f x (i.e. f applied to x) is a value of type b. Therefore, and without exception, every Isabelle function is total. In particular, it cannot be that f x does not exist for some x :: a. This is a first difference from Haskell, which does have partial functions like
spin :: Maybe Integer -> Bool
spin (Just n) = spin (Just (n+1))
Here, neither the expression spin Nothing nor the expression spin (Just 42) produce a value of type Bool: The former raises an exception ( incomplete pattern match ), the latter does not terminate. Confusingly, though, both expressions have type Bool. Because every function is total, this confusion cannot arise in Isabelle: If an expression e has type t, then it is a value of type t. This trait is shared with other total systems, including Coq. Did you notice the emphasis I put on the word is here, and how I deliberately did not write evaluates to or returns ? This is because of another big source for confusion:

Isabelle functions do not compute We (i.e., functional programmers) stole the word function from mathematics and repurposed it2. But the word function , in the context of Isabelle, refers to the mathematical concept of a function, and it helps to keep that in mind. What is the difference?
  • A function a b in functional programming is an algorithm that, given a value of type a, calculates (returns, evaluates to) a value of type b.
  • A function a b in math (or Isabelle) associates with each value of type a a value of type b.
For example, the following is a perfectly valid function definition in math (and HOL), but could not be a function in the programming sense:
definition foo :: "(nat   real)   real" where
  "foo seq = (if convergent seq then lim seq else 0)"
This assigns a real number to every sequence, but it does not compute it in any useful sense. From this it follows that

Isabelle functions are specified, not defined Consider this function definition:
fun plus :: "nat   nat   nat"  where
   "plus 0       m = m"
   "plus (Suc n) m = Suc (plus n m)"
To a functional programmer, this reads
plus is a function that analyses its first argument. If that is 0, then it returns the second argument. Otherwise, it calls itself with the predecessor of the first argument and increases the result by one.
which is clearly a description of a computation. But to Isabelle, the above reads
plus is a binary function on natural numbers, and it satisfies the following two equations:
And in fact, it is not so much Isabelle that reads it this way, but rather the fun command, which is external to the Isabelle logic. The fun command analyses the given equations, constructs a non-recursive definition of plus under the hood, passes that to Isabelle and then proves that the given equations hold for plus. One interesting consequence of this is that different specifications can lead to the same functions. In fact, if we would define plus' by recursing on the second argument, we d obtain the the same function (i.e. plus = plus' is a theorem, and there would be no way of telling the two apart).

Termination is a property of specifications, not functions Because a function does not evaluate, it does not make sense to ask if it terminates. The question of termination arises before the function is defined: The fun command can only construct plus in a way that the equations hold if it passes a termination check very much like Fixpoint in Coq. But while the termination check of Fixpoint in Coq is a deep part of the basic logic, in Isabelle it is simply something that this particular command requires for its internal machinery to go through. At no point does a termination proof of the function exist as a theorem inside the logic. And other commands may have other means of defining a function that do not even require such a termination argument! For example, a function specification that is tail-recursive can be turned in to a function, even without a termination proof: The following definition describes a higher-order function that iterates its first argument f on the second argument x until it finds a fixpoint. It is completely polymorphic (the single quote in 'a indicates that this is a type variable):
partial_function (tailrec)
  fixpoint :: "('a   'a)   'a   'a"
where
  "fixpoint f x = (if f x = x then x else fixpoint f (f x))"
We can work with this definition just fine. For example, if we instantiate f with ( x. x-1), we can prove that it will always return 0:
lemma "fixpoint (  n . n - 1) (n::nat) = 0"
  by (induction n) (auto simp add: fixpoint.simps)
Similarly, if we have a function that works within the option monad (i.e. Maybe in Haskell), its specification can always be turned into a function without an explicit termination proof here one that calculates the Collatz sequence:
partial_function (option) collatz :: "nat   nat list option"
 where "collatz n =
        (if n = 1 then Some [n]
         else if even n
           then do   ns <- collatz (n div 2);    Some (n # ns)  
           else do   ns <- collatz (3 * n + 1);  Some (n # ns) )"
Note that lists in Isabelle are finite (like in Coq, unlike in Haskell), so this function returns a list only if the collatz sequence eventually reaches 1. I expect these definitions to make a Coq user very uneasy. How can fixpoint be a total function? What is fixpoint ( n. n+1)? What if we run collatz n for a n where the Collatz sequence does not reach 1?3 We will come back to that question after a little detour

HOL is a logic of non-empty types Another big difference between Isabelle and Coq is that in Isabelle, every type is inhabited. Just like the totality of functions, this is a very fundamental fact about what HOL defines to be a type. Isabelle gets away with that design because in Isabelle, we do not use types for propositions (like we do in Coq), so we do not need empty types to denote false propositions. This design has an important consequence: It allows the existence of a polymorphic expression that inhabits any type, namely
undefined :: 'a
The naming of this term alone has caused a great deal of confusion for Isabelle beginners, or in communication with users of different systems, so I implore you to not read too much into the name. In fact, you will have a better time if you think of it as arbitrary or, even better, unknown. Since undefined can be instantiated at any type, we can instantiate it for example at bool, and we can observe an important fact: undefined is not an extra value besides the usual ones . It is simply some value of that type, which is demonstrated in the following lemma:
lemma "undefined = True   undefined = False" by auto
In fact, if the type has only one value (such as the unit type), then we know the value of undefined for sure:
lemma "undefined = ()" by auto
It is very handy to be able to produce an expression of any type, as we will see as follows

Partial functions are just underspecified functions For example, it allows us to translate incomplete function specifications. Consider this definition, Isabelle s equivalent of Haskell s partial fromJust function:
fun fromSome :: "'a option   'a" where
  "fromSome (Some x) = x"
This definition is accepted by fun (albeit with a warning), and the generated function fromSome behaves exactly as specified: when applied to Some x, it is x. The term fromSome None is also a value of type 'a, we just do not know which one it is, as the specification does not address that. So fromSome None behaves just like undefined above, i.e. we can prove
lemma "fromSome None = False   fromSome None = True" by auto
Here is a small exercise for you: Can you come up with an explanation for the following lemma:
fun constOrId :: "bool   bool" where
  "constOrId True = True"
lemma "constOrId = ( _.True)   constOrId = ( x. x)"
  by (metis (full_types) constOrId.simps)
Overall, this behavior makes sense if we remember that function definitions in Isabelle are not really definitions, but rather specifications. And a partial function definition is simply a underspecification. The resulting function is simply any function hat fulfills the specification, and the two lemmas above underline that observation.

Nonterminating functions are also just underspecified Let us return to the puzzle posed by fixpoint above. Clearly, the function seen as a functional program is not total: When passed the argument ( n. n + 1) or ( b. b) it will loop forever trying to find a fixed point. But Isabelle functions are not functional programs, and the definitions are just specifications. What does the specification say about the case when f has no fixed-point? It states that the equation fixpoint f x = fixpoint f (f x) holds. And this equation has a solution, for example fixpoint f _ = undefined. Or more concretely: The specification of the fixpoint function states that fixpoint ( b. b) True = fixpoint ( b. b) False has to hold, but it does not specify which particular value (True or False) it should denote any is fine.

Not all function specifications are ok At this point you might wonder: Can I just specify any equations for a function f and get a function out of that? But rest assured: That is not the case. For example, no Isabelle command allows you define a function bogus :: () nat with the equation bogus () = Suc (bogus ()), because this equation does not have a solution. We can actually prove that such a function cannot exist:
lemma no_bogus: "  bogus. bogus () = Suc (bogus ())" by simp
(Of course, not_bogus () = not_bogus () is just fine )

You cannot reason about partiality in Isabelle We have seen that there are many ways to define functions that one might consider partial . Given a function, can we prove that it is not partial in that sense? Unfortunately, but unavoidably, no: Since undefined is not a separate, recognizable value, but rather simply an unknown one, there is no way of stating that A function result is not specified . Here is an example that demonstrates this: Two partial functions (one with not all cases specified, the other one with a self-referential specification) are indistinguishable from the total variant:
fun partial1 :: "bool   unit" where
  "partial1 True = ()"
partial_function (tailrec) partial2 :: "bool   unit" where
  "partial2 b = partial2 b"
fun total :: "bool   unit" where
  "total True = ()"
  "total False = ()"
lemma "partial1 = total   partial2 = total" by auto
If you really do want to reason about partiality of functional programs in Isabelle, you should consider implementing them not as plain HOL functions, but rather use HOLCF, where you can give equational specifications of functional programs and obtain continuous functions between domains. In that setting, () and partial2 = total. We have done that to verify some of HLint s equations.

You can still compute with Isabelle functions I hope by this point, I have not scared away anyone who wants to use Isabelle for functional programming, and in fact, you can use it for that. If the equations that you pass to fun are a reasonable definition for a function (in the programming sense), then these equations, used as rewriting rules, will allow you to compute that function quite like you would in Coq or Haskell. Moreover, Isabelle supports code extraction: You can take the equations of your Isabelle functions and have them expored into Ocaml, Haskell, Scala or Standard ML. See Concon for a conference management system with confidentially verified in Isabelle. While these usually are the equations you defined the function with, they don't have to: You can declare other proved equations to be used for code extraction, e.g. to refine your elegant definitions to performant ones. Like with code extraction from Coq to, say, Haskell, the adequacy of the translations rests on a moral reasoning foundation. Unlike extraction from Coq, where you have an (unformalized) guarantee that the resulting Haskell code is terminating, you do not get that guarantee from Isabelle. Conversely, this allows you do reason about and extract non-terminating programs, like fixpoint, which is not possible in Coq. There is currently ongoing work about verified code generation, where the code equations are reflected into a deep embedding of HOL in Isabelle that would allow explicit termination proofs.

Conclusion We have seen how in Isabelle, every function is total. Function declarations have equations, but these do not define the function in an computational sense, but rather specify them. Because in HOL, there are no empty types, many specifications that appear partial (incomplete patterns, non-terminating recursion) have solutions in the space of total functions. Partiality in the specification is no longer visible in the final product.

PS: Axiom undefined in Coq This section is speculative, and an invitation for discussion. Coq already distinguishes between types used in programs (Set) and types used in proofs Prop. Could Coq ensure that every t : Set is non-empty? I imagine this would require additional checks in the Inductive command, similar to the checks that the Isabelle command datatype has to perform4, and it would disallow Empty_set. If so, then it would be sound to add the following axiom
Axiom undefined : forall (a : Set), a.
wouldn't it? This axiom does not have any computational meaning, but that seems to be ok for optional Coq axioms, like classical reasoning or function extensionality. With this in place, how much of what I describe above about function definitions in Isabelle could now be done soundly in Coq. Certainly pattern matches would not have to be complete and could sport an implicit case _ undefined. Would it help with non-obviously terminating functions? Would it allow a Coq command Tailrecursive that accepts any tailrecursive function without a termination check?

  1. Isabelle is a metalogical framework, and other logics, e.g. Isabelle/ZF, behave differently. For the purpose of this blog post, I always mean Isabelle/HOL.
  2. Isabelle is a metalogical framework, and other logics, e.g. Isabelle/ZF, behave differently. For the purpose of this blog post, I always mean Isabelle/HOL.
  3. Let me know if you find such an n. Besides n = 0.
  4. Like fun, the constructions by datatype are not part of the logic, but create a type definition from more primitive notions that is isomorphic to the specified data type.
10 October 2017

Carl Chenet: The Slack Threat

During a long era, electronic mail was the main communication tool for enterprises. Slack, which offer public or private group discussion boards and instant messaging between two people, challenge its position, especially in the IT industry. Not only Slack has features known and used since IRC launch in the late 80s, but Slack also offers file sending and sharing, code quoting, and it indexing for ulterior searches everything that goes through the application. Slack is also modular with numerous plug-in to easily add new features. Using the Software-As-A-Service (SAAS) model, Slack basic version is free, and users pay for options. Slack is now considered by the Github generation like the new main enterprise communication tool. As I did in my previous article on the Github threat, this one won t promote Slask s advantages, as many other articles have already covered all these points ad nauseam, but to show the other side and to warn the companies using this service about its inherent risks. So far, these risks have been ignored, sometimes voluntary in the name of the It works ideology. Neglecting all economic and safety consideration, neglecting all threat to privacy and individual freedom. We ll see about them below.

Github, a software forge as a SAAS, with all the advantage but also all the risk of its economic model

All your company communication since its creation When a start-up chooses Slack, all of its internal communication will be stored by Slack. When someone uses this service, the simple fact to chat through it means that the whole communication is archived. One may point that within the basic Slack offer, only the last 10.000 messages can be read and searched. Bad argument. Slack stored every message and every file shared as it pleases. We ll see below this application behavior is of capital importance in the Slack threat to enterprises. And the problem is the same for all other companies which choose Slack at one point or another. If they replace their traditional communication method with it, Slack will have access to capital data, not only in volume, but also because of their value for the company itself Or anyone interested in this company life. Search Your Entire Archive One of the main arguments to use Slack is its Search your entire archive feature. One can search almost anything one can think of. Why? Because everything is indexed. Your team chat archive or the more or less confidential documents exchanged with the accountant department; everything is in it in order to provide the most effective search tool.

The search bar, well-known by Slack users

We can t deny it s a very attractive feature for everyone inside the company. But it is also a very attractive feature for everyone outside of the company who would want to know more about its internal life. Even more if you re looking for a specific subject. If Slack is the main communication tool of your company, and if as I ve experienced in my professional life, some teams prefer to use it than to go to the office next door or even bug you to put the information on the dedicated channel, one can easily deduce that nothing in this type of company escape Slack. The automatic indexation and the search feature efficiency are excellent tools to get all the information needed, in quantity and in quality. As such, it s a great social engineering tool for everyone who has access to it, with a history as old as the use of Slack as a communication tool in the company. Across borders And Beyond! Slack is a Web service which uses mainly Amazon Web services and most specially Cloudfront, as stated by the available information on Slack infrastructure. Even without a complete study of said infrastructure, it s easy to state that all the data regarding many innovative global companies around the world (and some of them including for all their internal communication since their creation) are located in the United States, or at least in the hands of a US company, which must follow US laws, a country with a well-known history of large scale industrial espionage, as the whistleblower Edward Snowden demonstrated it in 2013 and where company data access has no restriction under the Patriot Act, as in the Microsoft case (2014) where data stored in Ireland by the Redmond software editor have been given to US authorities.

Edward Snowden, an individual and corporate freedom fighter

As such, Slack s automatic indexation and search tool are a boon for anyone spy agency or hacker which get authorized access to it. To trust a third party with all, or at least most of, your internal corporate communication is a certain risk for your company if the said third party doesn t follow the same regulations as yours or if it has different interests, from a data security point of view or more globally on its competitiveness. A badly timed data leak can be catastrophic. What s the point of secretly preparing a new product launch or an aggressive takeover if all your recent Slack conversations have leaked, including your secret plans? What if Slack is hacked? First let s remember that even if a cyber attack may appear as a rare or hypothetical scenario to a badly informed and hurried manager, it is far from being as rare as she or he believes it (or wants to believe it). Infrastructure hacking is quite common, as a regular visit to Hacker News will give you multiple evidence. And Slack itself has already been hacked. February 2015: Slack is the victim during four days of a cyber attack, which was made public by the company in March. Officially, the unauthorized access was limited to information on the users profiles. It is impossible to measure exactly what and who was impacted by this attack. In a recent announcement, Yahoo confessed that these 3 billion accounts (you ve read well: 3 billions) were compromised late 2014!

Yahoo, the company which suffered the largest recorded cyberattack regarding the compromised account numbers

Officially, Slack stated that No financial or payment information was accessed or compromised in this attack. Which is, and by far, the least interesting of all data stored within Slack! With company internal communication indexed sometimes from the very beginning of said company and searchable, Slack may be a potential target for cybercriminal not looking for its users financial credentials but more their internal data already in a usable format. One can imagine Slack must give information on a massive data leak, which can t be ignored. But what would happen if only one Slack user is the victim of said leak? The Free Alternative Solutions As we demonstrated above, companies need to find an alternative solution to Slack, one they can host themselves to reduce data leaks and industrial espionage and dependency on the Internet connection. Luckily, Slack success created its own copycats, some of them being also free software. Rocket.chat is one of them. Its comprehensive service offers chat rooms, direct messages and file sharing but also videoconferencing and screen sharing, and even most features. Check their dedicated page. You can also try an online demo. And even more, Rocket Chat has a very simple extension system and an API. Mattermost is another service which has the advantages of proximity and of compatibility with Slack. It offers numerous features including the main expected by this type of software. It also offers numerous apps and plug-ins to interact with online services, software forges, and continuous integration tools. It works In the introduction, we discussed the It works effect, usually invoked to dispel any arguments about data protection and exchange confidentiality we discussed in this article. True, one single developer can ask: why worry about it? All I want is to chat with my colleagues and send files! Because Slack service subscription in the long term put the company continuously at risk. Maybe it s not the employees place to worry about it, they just have to do their job the more efficiently possible. On the other side, the company management, usually non-technical, may not be aware of what risks will threaten their company with this technical choice. The technical management may pretend to be omniscient, nobody is fooled. Either someone from the direction will ask the right question (where are our data and who can access them?) or someone from the technical side alert them officially on these problems. This is this technical audience, even if not always heard by their direction, which is the target of this article. May they find in it the right arguments to be convincing. We hope that the several points we developed in this article will help you to make the right choice. About Me Carl Chenet, Free Software Indie Hacker, founder of the French-speaking Hacker News-like Journal du hacker. Follow me on social networks Translated from French by St phanie Chaptal. Original article written in October 2016.

Reproducible builds folks: Reproducible Builds: Weekly report #128

Here's what happened in the Reproducible Builds effort between Sunday October 1 and Saturday October 7 2017: Media coverage Documentation updates Packages reviewed and fixed, and bugs filed Reviews of unreproducible packages 32 package reviews have been added, 46 have been updated and 62 have been removed in this week, adding to our knowledge about identified issues. Weekly QA work During our reproducibility testing, FTBFS bugs have been detected and reported by: diffoscope development strip-nondeterminism development Rob Browning noticed that strip-nondeterminism was causing serious performance regressions in the Clojure programming language within Debian. After some discussion, Chris Lamb also posted a query to debian-devel in case there were any other programming languages that might be suffering from the same problem. reprotest development Versions 0.7.1 and 0.7.2 were uploaded to unstable by Ximin Luo: It included contributions already covered by posts of the previous weeks, as well as new ones from: tests.reproducible-builds.org Misc. This week's edition was written by Bernhard M. Wiedemann, Chris Lamb, Holger Levsen, Mattia Rizzolo & reviewed by a bunch of Reproducible Builds folks on IRC & the mailing lists.

4 October 2017

Norbert Preining: Einstein and Freud s letters on Why War? 85th anniversary

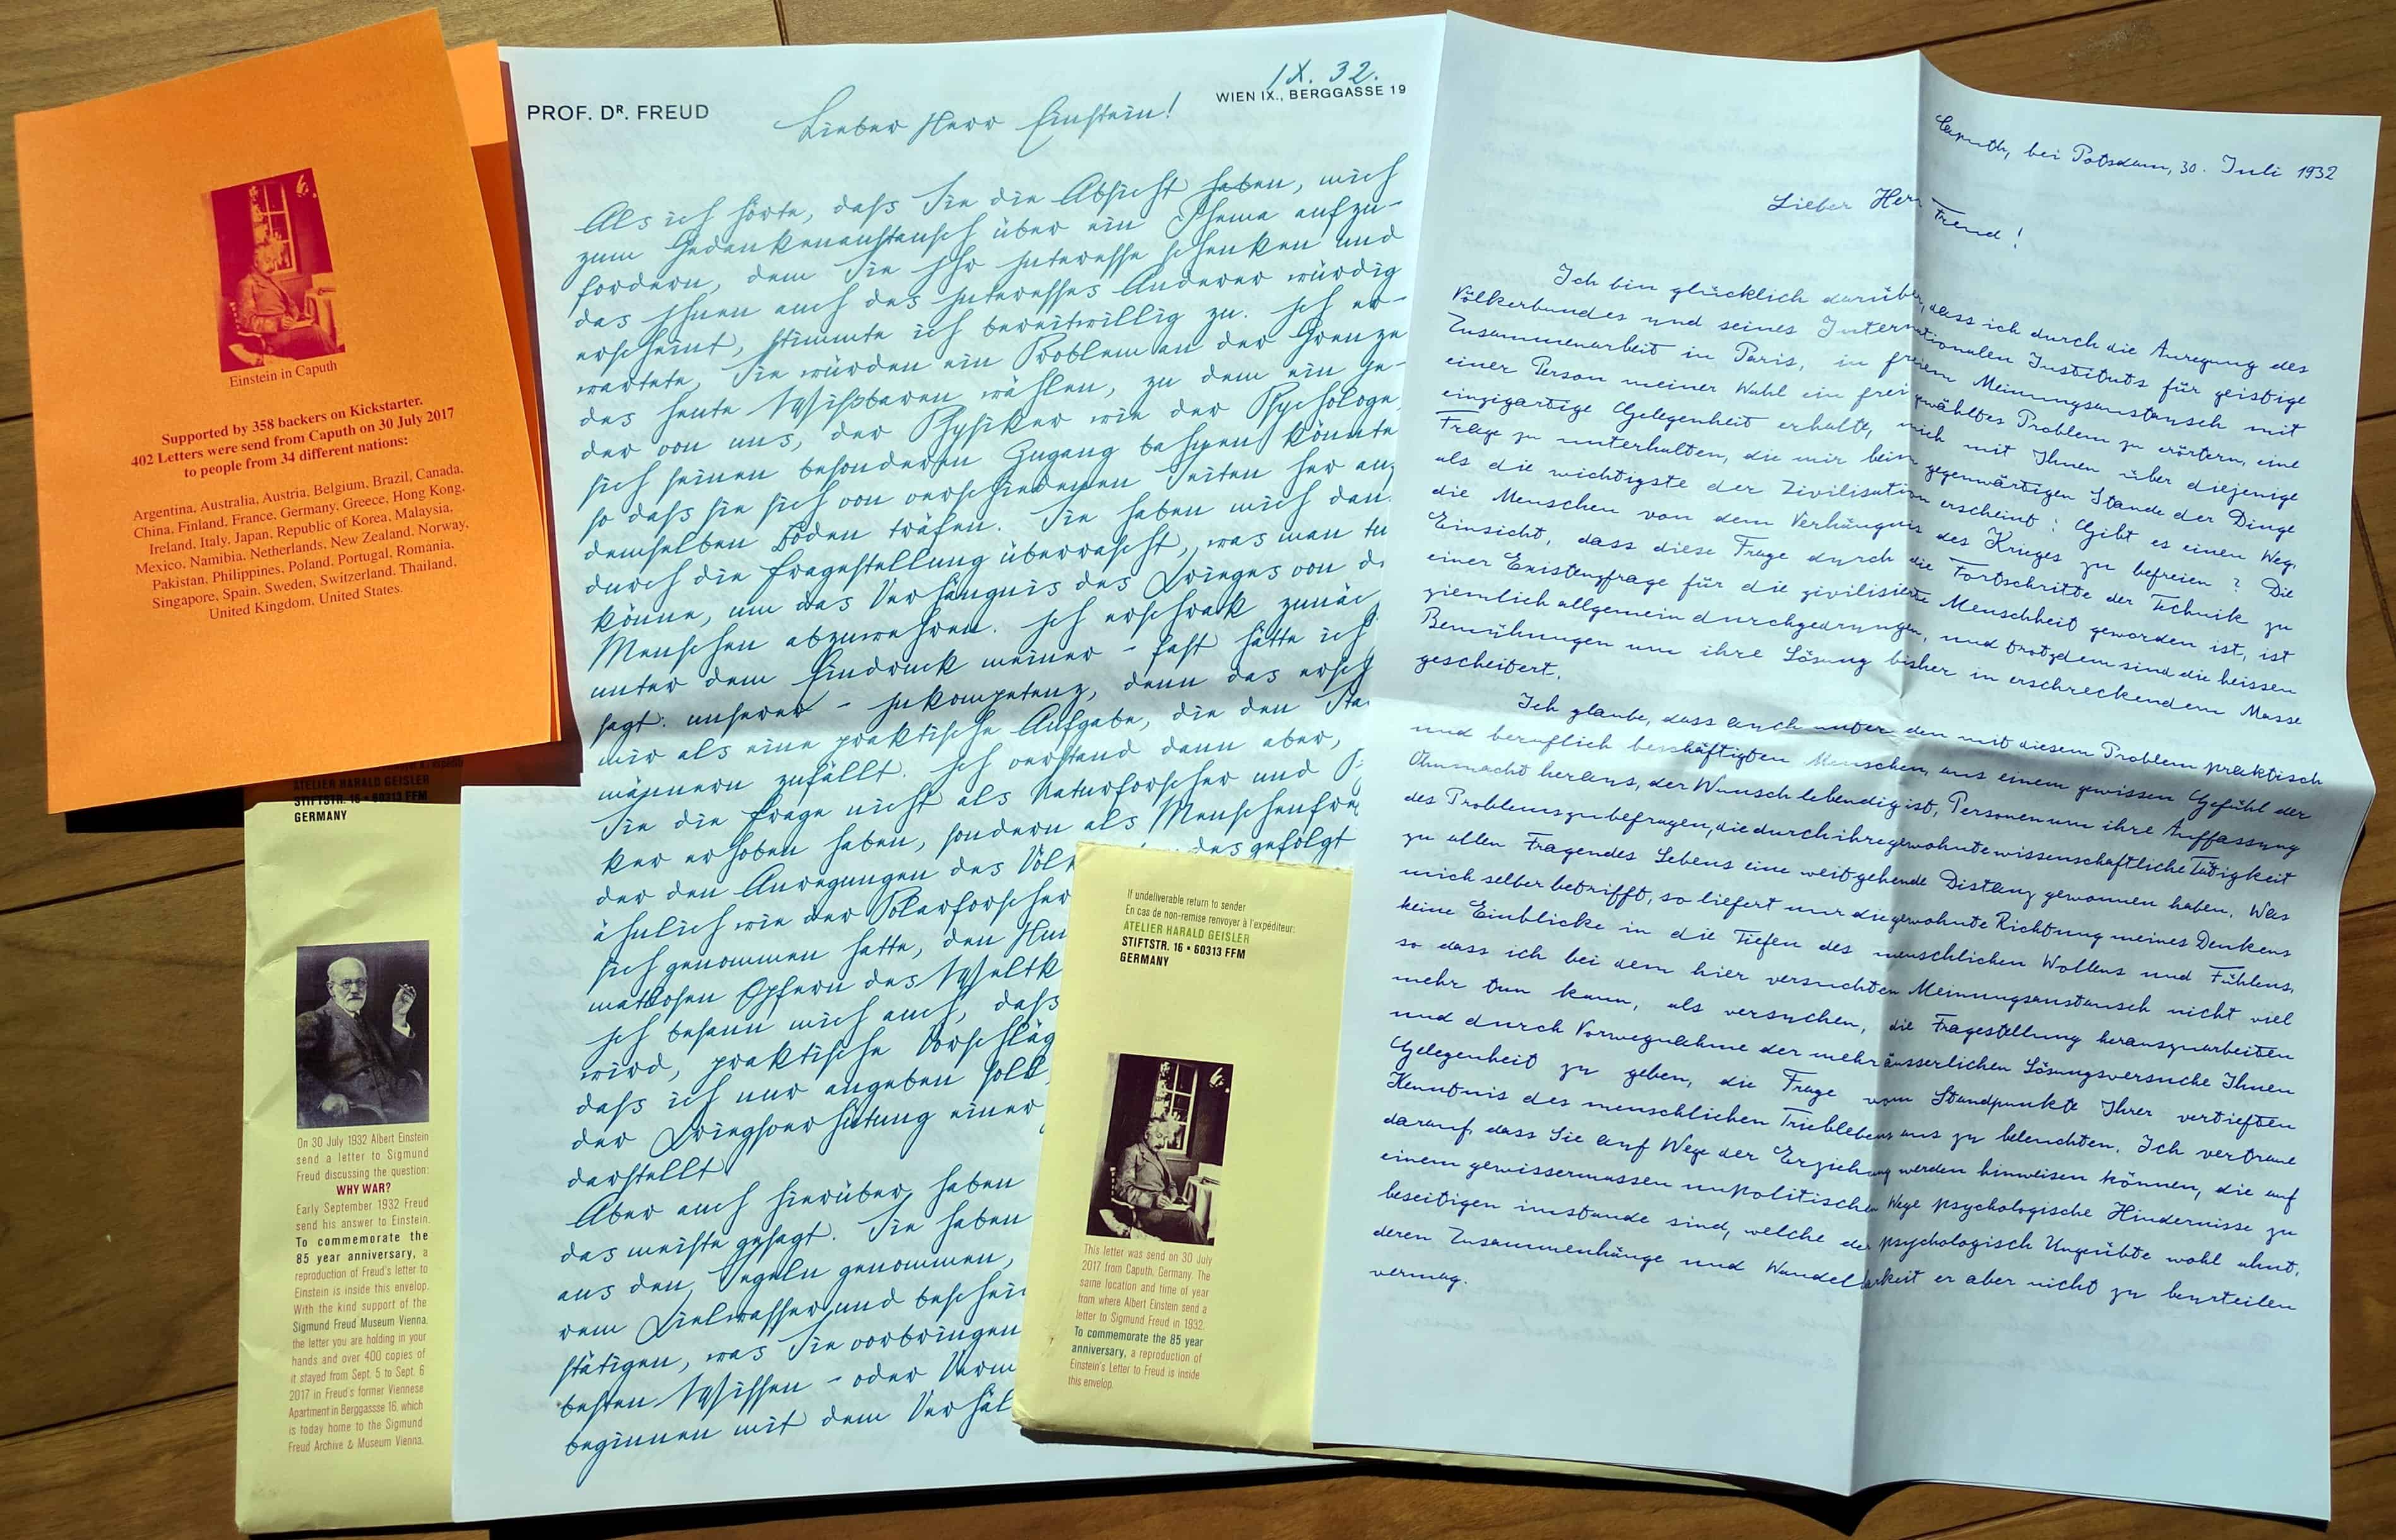
85 years ago, on 30 July 1932, Albert Einstein send a letter to Sigmund Freud discussing the question: Why War? Freud answered to this letter in early September 1932. To commemorate the 85 year anniversary, the German typographer Harald Geisler has started a project on Kickstarter to recreate the letters send back then. Over the last weeks the two letters have arrived at my place in Japan:
But not only were the letters reproduces, but typeset in the original digitized handwriting and sent from the original locations. Harald Geisler crafted fonts based on the hand-writing of Einstein and Freud, an layout out the pages of the letters according to the originals. Since the letters were originally written in German, an English translation also typeset in the hand-writing font was added.
In addition to the a bit archaic hand writing of Freud which even many German natives will not be able to read, the German text of his letter has been included in normal print style. Not only that, Harald Geisler even managed to convince the Sigmund Freud Museum to let rest the letters for one night in the very office where the original letter was written, so all the letters send out actually came from Freud s office.
This project was one of the first Kickstarter projects I supported, and I really liked the idea, and would like to thanks Harald Geisler for realizing it. These kind of activities, combining of typography, history, action, dedication, keep our culture and history alive. Thanks.
Harald Geisler also invites us all to continue the dialog on Why War?, which is getting more and more relevant again, with war-mongering becoming respected practice.

3 October 2017

Dimitri John Ledkov: An interesting bug - network-manager, glibc, dpkg-shlibdeps, systemd, and finally binutils

Not so long ago I went to effectively recompile NetworkManager and fix up minor bug in it. It built fine across all architectures, was considered to be installable etc. And I was expecting it to just migrate across. At the time, glibc was at 2.26 in artful-proposed and NetworkManager was built against it. However release pocket was at glibc 2.24. In Ubuntu we have a ProposedMigration process in place which ensures that newly built packages do not regress in the number of architectures built for; installable on; and do not regress themselves or any reverse dependencies at runtime.

Thus before my build of NetworkManager was considered for migration, it was tested in the release pocket against packages in the release pocket. Specifically, since package metadata only requires glibc 2.17 NetworkManager was tested against glibc currently in the release pocket, which should just work fine....
autopkgtest [21:47:38]: test nm: [-----------------------
test_auto_ip4 (__main__.ColdplugEthernet)
ethernet: auto-connection, IPv4 ... FAIL ----- NetworkManager.log -----
NetworkManager: /lib/x86_64-linux-gnu/libc.so.6: version GLIBC_2.25' not found (required by NetworkManager)
At first I only saw failing tests, which I thought is transient failure. Thus they were retried a few times. Then I looked at the autopkgtest log and saw above error messages. Perplexed, I have started a lxd container with ubuntu artful, enabled proposed and installed just network-manager from artful-proposed and indeed a simple NetworkManager --help failed with above error from linker.

I am too young to know what dependency-hell means, since ever since I used Linux (Ubuntu 7.04) all glibc symbols were versioned, and dpkg-shlibdeps would generate correct minimum dependencies for a package. Alas in this case readelf confirmed that indeed /usr/sbin/NetworkManager requires 2.25 and dpkg depends is >= 2.17.

Further reading readelf output I checked that all of the glibc symbols used are 2.17 or lower, and only the "Version needs section '.gnu.version_r'" referenced GLIBC_2.25 symbol. Inspecting dpkg-shlibdeps code I noticed that it does not parse that section and only searches through the dynamic symbols used to establish the minimum required version.

Things started to smell fishy. On one hand, I trust dpkg-shlibdeps to generate the right dependencies. On the other hand I also trust linker to not tell lies either. Hence I opened a Debian BTS bug report about this issue.

At this point, I really wanted to figure out where the reference to 2.25 comes from. Clearly it was not from any private symbols as then the reference would be on 2.26. Checking glibc abi lists I found there were only a handful of symbols marked as 2.25
$ grep 2.25 ./sysdeps/unix/sysv/linux/x86_64/64/libc.abilist
GLIBC_2.25 GLIBC_2.25 A
GLIBC_2.25 __explicit_bzero_chk F
GLIBC_2.25 explicit_bzero F
GLIBC_2.25 getentropy F
GLIBC_2.25 getrandom F
GLIBC_2.25 strfromd F
GLIBC_2.25 strfromf F
GLIBC_2.25 strfroml F
Blindly grepping for these in network-manager source tree I found following:
$ grep explicit_bzero -r configure.ac src/
configure.ac: explicit_bzero],
src/systemd/src/basic/string-util.h:void explicit_bzero(void *p, size_t l);
src/systemd/src/basic/string-util.c:void explicit_bzero(void *p, size_t l)
src/systemd/src/basic/string-util.c: explicit_bzero(x, strlen(x));
First of all it seems like network-manager includes a partial embedded copy of systemd. Secondly that code is compiled into a temporary library and has autconf detection logic to use explicit_bzero. It also has an embedded implementation of explicit_bzero when it is not available in libc, however it does not have FORTIFY_SOURCES implementation of said function (__explicit_bzero_chk) as was later pointed out to me. And whilst this function is compiled into an intermediary noinst library, no functions that use explicit_bzero are used in the end by NetworkManger binary. To proof this, I've dropped all code that uses explicit_bzero, rebuild the package against glibc 2.26, and voila it only had Version reference on glibc 2.17 as expected from the end-result usage of shared symbols.

At this point toolchain bug was a suspect. It seems like whilst explicit_bzero shared symbol got optimised out, the version reference on 2.25 persisted to the linked binaries. At this point in the archive a snapshot version of binutils was in use. And in fact forcefully downgrading bintuils resulted in correct compilation / versions table referencing only glibc 2.17.

Mathias then took over a tarball of object files and filed upstream bug report against bintuils: "[2.29 Regression] ld.bfd keeps a version reference in .gnu.version_r for symbols which are optimized out". The discussion in that bug report is a bit beyond me as to me binutils is black magic. All I understood there was "we moved sweep and pass to another place due to some bugs", doing that introduced this bug, thus do multiple sweep and passes to make sure we fix old bugs and don't regress this either. Or something like that. Comments / Better description of the bintuils fix are welcomed.

Binutils got fixed by upstream developers, cherry-picked into debian, and ubuntu, network-manager got rebuild and everything is wonderful now. However, it does look like unused / deadend code paths tripped up optimisations in the toolchain which managed to slip by distribution package dependency generation and needless require a higher up version of glibc. I guess the lesson here is do not embed/compile unused code. Also I'm not sure why network-manager uses networkd internals like this, and maybe systemd should expose more APIs or serialise more state into /run, as most other things query things over dbus, private socket, or by establishing watches on /run/systemd/netif. I'll look into that another day.

Thanks a lot to Guillem Jover, Matthias Klose, Alan Modra, H.J. Lu, and others for getting involved. I would not be able to raise, debug, or fix this issue all by myself.

2 October 2017

Antoine Beaupr : My free software activities, September 2017

Debian Long Term Support (LTS) This is my monthly Debian LTS report. I mostly worked on the git, git-annex and ruby packages this month but didn't have time to completely use my allocated hours because I started too late in the month.

Ruby I was hoping someone would pick up the Ruby work I submitted in August, but it seems no one wanted to touch that mess, understandably. Since then, new issues came up, and not only did I have to work on the rubygems and ruby1.9 package, but now the ruby1.8 package also had to get security updates. Yes: it's bad enough that the rubygems code is duplicated in one other package, but wheezy had the misfortune of having two Ruby versions supported. The Ruby 1.9 also failed to build from source because of test suite issues, which I haven't found a clean and easy fix for, so I ended up making test suite failures non-fatal in 1.9, which they were already in 1.8. I did keep a close eye on changes in the test suite output to make sure tests introduced in the security fixes would pass and that I wouldn't introduce new regressions as well. So I published the following advisories:
  • ruby 1.8: DLA-1113-1, fixing CVE-2017-0898 and CVE-2017-10784. 1.8 doesn't seem affected by CVE-2017-14033 as the provided test does not fail (but it does fail in 1.9.1). test suite was, before patch:
    2199 tests, 1672513 assertions, 18 failures, 51 errors
    
    and after patch:
    2200 tests, 1672514 assertions, 18 failures, 51 errors
    
  • rubygems: uploaded the package prepared in August as is in DLA-1112-1, fixing CVE-2017-0899, CVE-2017-0900, CVE-2017-0901. here the test suite passed normally.
  • ruby 1.9: here I used the used 2.2.8 release tarball to generate a patch that would cover all issues and published DLA-1114-1 that fixes the CVEs of the two packages above. the test suite was, before patches:
    10179 tests, 2232711 assertions, 26 failures, 23 errors, 51 skips
    
    and after patches:
    1.9 after patches (B): 10184 tests, 2232771 assertions, 26 failures, 23 errors, 53 skips
    

Git I also quickly issued an advisory (DLA-1120-1) for CVE-2017-14867, an odd issue affecting git in wheezy. The backport was tricky because it wouldn't apply cleanly and the git package had a custom patching system which made it tricky to work on.

Git-annex I did a quick stint on git-annex as well: I was able to reproduce the issue and confirm an approach to fixing the issue in wheezy, although I didn't have time to complete the work before the end of the month.

Other free software work

New project: feed2exec I should probably make a separate blog post about this, but ironically, I don't want to spend too much time writing those reports, so this will be quick. I wrote a new program, called feed2exec. It's basically a combination of feed2imap, rss2email and feed2tweet: it allows you to fetch RSS feeds and send them in a mailbox, but what's special about it, compared to the other programs above, is that it is more generic: you can basically make it do whatever you want on new feed items. I have, for example, replaced my feed2tweet instance with it, using this simple configuration:
[anarcat]
url = https://anarc.at/blog/index.rss
output = feed2exec.plugins.exec
args = tweet "%(title)0.70s %(link)0.70s"
The sample configuration file also has examples to talk with Mastodon, Pump.io and, why not, a torrent server to download torrent files available over RSS feeds. A trivial configuration can also make it work as a crude podcast client. My main motivation to work on this was that it was difficult to extend feed2imap to do what I needed (which was to talk to transmission to download torrent files) and rss2email didn't support my workflow (which is delivering to feed-specific mail folders). Because both projects also seemed abandoned, it seemed like a good idea at the time to start a new one, although the rss2email community has now restarted the project and may produce interesting results. As an experiment, I tracked my time working on this project. It turns out it took about 45 hours to write that software. Considering feed2exec is about 1400 SLOC, that's 30 lines of code per hour. I don't know if that's slow or fast, but it's an interesting metric for future projects. It sure seems slow to me, but we need to keep in mind those 30 lines of code don't include documentation and repeated head banging on the keyboard. For example, I found two issues with the upstream feedparser package which I use to parse feeds which also seems unmaintained, unfortunately. Feed2exec is beta software at this point, but it's working well enough for me and the design is much simpler than the other programs of the kind. The main issue people can expect from it at this point is formatting issues or parse errors on exotic feeds, and noisy error messages on network errors, all of which should be fairly easy to fix in the test suite. I hope it will be useful for the community and, as usual, I welcome contributions, help and suggestions on how to improve the software.

More Python templates As part of the work on feed2exec, I did cleanup a few things in the ecdysis project, mostly to hook tests up in the CI, improve on the advancedConfig logger and cleanup more stuff. While I was there, it turns out that I built a pretty decent basic CI configuration for Python on GitLab. Whereas the previous templates only had a non-working Django example, you should now be able to chose a Python template when you configure CI on GitLab 10 and above, which should hook you up with normal Python setup procedures like setup.py install and setup.py test.

Selfspy I mentioned working on a monitoring tool in my last post, because it was a feature from Workrave missing in SafeEyes. It turns out there is already such a tool called selfspy. I did an extensive review of the software to make sure it wouldn't leak out confidential information out before using it, and it looks, well... kind of okay. It crashed on me at least once so far, which is too bad because then it loses track of the precious activity. I have used it at least once to figure out what the heck I worked on during the day, so it's pretty useful. I particularly used it to backtrack my work on feed2exec as I didn't originally track my time on the project. Unfortunately, selfspy seems unmaintained. I have proposed a maintenance team and hopefully the project maintainer will respond and at least share access so we don't end up in a situation like linkchecker. I also sent a bunch of pull requests to fix some issues like being secure by default and fixing the build. Apart from the crash, the main issue I have found with the software is that it doesn't detect idle time which means certain apps are disproportionatly represented in statistics. There are also some weaknesses in the crypto that should be adressed for people that encrypt their database. Next step is to package selfspy in Debian which should hopefully be simple enough...

Restic documentation security As part of a documentation patch on the Restic backup software, I have improved on my previous Perl script to snoop on process commandline arguments. A common flaw in shell scripts and cron jobs is to pass secret material in the environment (usually safe) but often through commandline arguments (definitely not safe). The challenge, in this peculiar case, was the env binary, but the last time I encountered such an issue was with the Drush commandline tool, which was passing database credentials in clear to the mysql binary. Using my Perl sniffer, I could get to 60 checks per second (or 60Hz). After reimplementing it in Python, this number went up to 160Hz, which still wasn't enough to catch the elusive env command, which is much faster at hiding arguments than MySQL, in large part because it simply does an execve() once the environment is setup. Eventually, I just went crazy and rewrote the whole thing in C which was able to get 700-900Hz and did catch the env command about 10-20% of the time. I could probably have rewritten this by simply walking /proc myself (since this is what all those libraries do in the end) to get better result, but then my point was made. I was able to prove to the restic author the security issues that warranted the warning. It's too bad I need to repeat this again and again, but then my tools are getting better at proving that issue... I suspect it's not the last time I have to deal with this issue and I am happy to think that I can come up with an even more efficient proof of concept tool the next time around.

Ansible 101 After working on documentation last month, I ended up writing my first Ansible playbook this month, converting my tasksel list to a working Ansible configuration. This was a useful exercise: it allow me to find a bunch of packages which have been removed from Debian and provides much better usability than tasksel. For example, it provides a --diff argument that shows which packages are missing from a given setup. I am still unsure about Ansible. Manifests do seem really verbose and I still can't get used to the YAML DSL. I could probably have done the same thing with Puppet and just run puppet apply on the resulting config. But I must admit my bias towards Python is showing here: I can't help but think Puppet is going to be way less accessible with its rewrite in Clojure and C (!)... But then again, I really like Puppet's approach of having generic types like package or service rather than Ansible's clunky apt/yum/dnf/package/win_package types...

Pat and Ham radio After responding (too late) to a request for volunteers to help in Puerto Rico, I realized that my amateur radio skills were somewhat lacking in the "packet" (data transmission in ham jargon) domain, as I wasn't used to operate a Winlink node. Such a node can receive and transmit actual emails over the airwaves, for free, without direct access to the internet, which is very useful in disaster relief efforts. Through summary research, I stumbled upon the new and very promising Pat project which provides one of the first user-friendly Linux-compatible Winlink programs. I provided improvements on the documentation and some questions regarding compatibility issues which are still pending. But my pet issue is the establishment of pat as a normal internet citizen by using standard protocols for receiving and sending email. Not sure how that can be implemented, but we'll see. I am also hoping to upload an official Debian package and hopefully write more about this soon. Stay tuned!

Random stuff I ended up fixing my Kodi issue by starting it as a standalone systemd service, instead of gdm3, which is now completely disabled on the media box. I simply used the following /etc/systemd/service/kodi.service file:
[Unit]
Description=Kodi Media Center
After=systemd-user-sessions.service network.target sound.target
[Service]
User=xbmc
Group=video
Type=simple
TTYPath=/dev/tty7
StandardInput=tty
ExecStart=/usr/bin/xinit /usr/bin/dbus-launch --exit-with-session /usr/bin/kodi-standalone -- :1 -nolisten tcp vt7
Restart=on-abort
RestartSec=5
[Install]
WantedBy=multi-user.target
The downside of this is that it needs Xorg to run as root, whereas modern Xorg can now run rootless. Not sure how to fix this or where... But if I put needs_root_rights=no in Xwrapper.config, I get the following error in .local/share/xorg/Xorg.1.log:
[  2502.533] (EE) modeset(0): drmSetMaster failed: Permission denied
After fooling around with iPython, I ended up trying the xonsh shell, which is supposed to provide a bash-compatible Python shell environment. Unfortunately, I found it pretty unusable as a shell: it works fine to do Python stuff, but then all my environment and legacy bash configuration files were basically ignored so I couldn't get working quickly. This is too bad because the project looked very promising... Finally, one of my TLS hosts using a Let's Encrypt certificate wasn't renewing properly, and I figured out why. It turns out the ProxyPass command was passing everything to the backend, including the /.well-known requests, which obviously broke ACME verification. The solution was simple enough, disable the proxy for that directory:
ProxyPass /.well-known/ !

Antoine Beaupr : Strategies for offline PGP key storage

While the adoption of OpenPGP by the general population is marginal at best, it is a critical component for the security community and particularly for Linux distributions. For example, every package uploaded into Debian is verified by the central repository using the maintainer's OpenPGP keys and the repository itself is, in turn, signed using a separate key. If upstream packages also use such signatures, this creates a complete trust path from the original upstream developer to users. Beyond that, pull requests for the Linux kernel are verified using signatures as well. Therefore, the stakes are high: a compromise of the release key, or even of a single maintainer's key, could enable devastating attacks against many machines. That has led the Debian community to develop a good grasp of best practices for cryptographic signatures (which are typically handled using GNU Privacy Guard, also known as GnuPG or GPG). For example, weak (less than 2048 bits) and vulnerable PGPv3 keys were removed from the keyring in 2015, and there is a strong culture of cross-signing keys between Debian members at in-person meetings. Yet even Debian developers (DDs) do not seem to have established practices on how to actually store critical private key material, as we can see in this discussion on the debian-project mailing list. That email boiled down to a simple request: can I have a "key dongles for dummies" tutorial? Key dongles, or keycards as we'll call them here, are small devices that allow users to store keys on an offline device and provide one possible solution for protecting private key material. In this article, I hope to use my experience in this domain to clarify the issue of how to store those precious private keys that, if compromised, could enable arbitrary code execution on millions of machines all over the world.

Why store keys offline? Before we go into details about storing keys offline, it may be useful to do a small reminder of how the OpenPGP standard works. OpenPGP keys are made of a main public/private key pair, the certification key, used to sign user identifiers and subkeys. My public key, shown below, has the usual main certification/signature key (marked SC) but also an encryption subkey (marked E), a separate signature key (S), and two authentication keys (marked A) which I use as RSA keys to log into servers using SSH, thanks to the Monkeysphere project.
    pub   rsa4096/792152527B75921E 2009-05-29 [SC] [expires: 2018-04-19]
      8DC901CE64146C048AD50FBB792152527B75921E
    uid                 [ultimate] Antoine Beaupr  <anarcat@anarc.at>
    uid                 [ultimate] Antoine Beaupr  <anarcat@koumbit.org>
    uid                 [ultimate] Antoine Beaupr  <anarcat@orangeseeds.org>
    uid                 [ultimate] Antoine Beaupr  <anarcat@debian.org>
    sub   rsa2048/B7F648FED2DF2587 2012-07-18 [A]
    sub   rsa2048/604E4B3EEE02855A 2012-07-20 [A]
    sub   rsa4096/A51D5B109C5A5581 2009-05-29 [E]
    sub   rsa2048/3EA1DDDDB261D97B 2017-08-23 [S]
All the subkeys (sub) and identities (uid) are bound by the main certification key using cryptographic self-signatures. So while an attacker stealing a private subkey can spoof signatures in my name or authenticate to other servers, that key can always be revoked by the main certification key. But if the certification key gets stolen, all bets are off: the attacker can create or revoke identities or subkeys as they wish. In a catastrophic scenario, an attacker could even steal the key and remove your copies, taking complete control of the key, without any possibility of recovery. Incidentally, this is why it is so important to generate a revocation certificate and store it offline. So by moving the certification key offline, we reduce the attack surface on the OpenPGP trust chain: day-to-day keys (e.g. email encryption or signature) can stay online but if they get stolen, the certification key can revoke those keys without having to revoke the main certification key as well. Note that a stolen encryption key is a different problem: even if we revoke the encryption subkey, this will only affect future encrypted messages. Previous messages will be readable by the attacker with the stolen subkey even if that subkey gets revoked, so the benefits of revoking encryption certificates are more limited.

Common strategies for offline key storage Considering the security tradeoffs, some propose storing those critical keys offline to reduce those threats. But where exactly? In an attempt to answer that question, Jonathan McDowell, a member of the Debian keyring maintenance team, said that there are three options: use an external LUKS-encrypted volume, an air-gapped system, or a keycard. Full-disk encryption like LUKS adds an extra layer of security by hiding the content of the key from an attacker. Even though private keyrings are usually protected by a passphrase, they are easily identifiable as a keyring. But when a volume is fully encrypted, it's not immediately obvious to an attacker there is private key material on the device. According to Sean Whitton, another advantage of LUKS over plain GnuPG keyring encryption is that you can pass the --iter-time argument when creating a LUKS partition to increase key-derivation delay, which makes brute-forcing much harder. Indeed, GnuPG 2.x doesn't have a run-time option to configure the key-derivation algorithm, although a patch was introduced recently to make the delay configurable at compile time in gpg-agent, which is now responsible for all secret key operations. The downside of external volumes is complexity: GnuPG makes it difficult to extract secrets out of its keyring, which makes the first setup tricky and error-prone. This is easier in the 2.x series thanks to the new storage system and the associated keygrip files, but it still requires arcane knowledge of GPG internals. It is also inconvenient to use secret keys stored outside your main keyring when you actually do need to use them, as GPG doesn't know where to find those keys anymore. Another option is to set up a separate air-gapped system to perform certification operations. An example is the PGP clean room project, which is a live system based on Debian and designed by DD Daniel Pocock to operate an OpenPGP and X.509 certificate authority using commodity hardware. The basic principle is to store the secrets on a different machine that is never connected to the network and, therefore, not exposed to attacks, at least in theory. I have personally discarded that approach because I feel air-gapped systems provide a false sense of security: data eventually does need to come in and out of the system, somehow, even if only to propagate signatures out of the system, which exposes the system to attacks. System updates are similarly problematic: to keep the system secure, timely security updates need to be deployed to the air-gapped system. A common use pattern is to share data through USB keys, which introduce a vulnerability where attacks like BadUSB can infect the air-gapped system. From there, there is a multitude of exotic ways of exfiltrating the data using LEDs, infrared cameras, or the good old TEMPEST attack. I therefore concluded the complexity tradeoffs of an air-gapped system are not worth it. Furthermore, the workflow for air-gapped systems is complex: even though PGP clean room went a long way, it's still lacking even simple scripts that allow signing or transferring keys, which is a problem shared by the external LUKS storage approach.

Keycard advantages The approach I have chosen is to use a cryptographic keycard: an external device, usually connected through the USB port, that stores the private key material and performs critical cryptographic operations on the behalf of the host. For example, the FST-01 keycard can perform RSA and ECC public-key decryption without ever exposing the private key material to the host. In effect, a keycard is a miniature computer that performs restricted computations for another host. Keycards usually support multiple "slots" to store subkeys. The OpenPGP standard specifies there are three subkeys available by default: for signature, authentication, and encryption. Finally, keycards can have an actual physical keypad to enter passwords so a potential keylogger cannot capture them, although the keycards I have access to do not feature such a keypad. We could easily draw a parallel between keycards and an air-gapped system; in effect, a keycard is a miniaturized air-gapped computer and suffers from similar problems. An attacker can intercept data on the host system and attack the device in the same way, if not more easily, because a keycard is actually "online" (i.e. clearly not air-gapped) when connected. The advantage over a fully-fledged air-gapped computer, however, is that the keycard implements only a restricted set of operations. So it is easier to create an open hardware and software design that is audited and verified, which is much harder to accomplish for a general-purpose computer. Like air-gapped systems, keycards address the scenario where an attacker wants to get the private key material. While an attacker could fool the keycard into signing or decrypting some data, this is possible only while the key is physically connected, and the keycard software will prompt the user for a password before doing the operation, though the keycard can cache the password for some time. In effect, it thwarts offline attacks: to brute-force the key's password, the attacker needs to be on the target system and try to guess the keycard's password, which will lock itself after a limited number of tries. It also provides for a clean and standard interface to store keys offline: a single GnuPG command moves private key material to a keycard (the keytocard command in the --edit-key interface), whereas moving private key material to a LUKS-encrypted device or air-gapped computer is more complex. Keycards are also useful if you operate on multiple computers. A common problem when using GnuPG on multiple machines is how to safely copy and synchronize private key material among different devices, which introduces new security problems. Indeed, a "good rule of thumb in a forensics lab", according to Robert J. Hansen on the GnuPG mailing list, is to "store the minimum personal data possible on your systems". Keycards provide the best of both worlds here: you can use your private key on multiple computers without actually storing it in multiple places. In fact, Mike Gerwitz went as far as saying:
For users that need their GPG key on multiple boxes, I consider a smartcard to be essential. Otherwise, the user is just furthering her risk of compromise.

Keycard tradeoffs As Gerwitz hinted, there are multiple downsides to using a keycard, however. Another DD, Wouter Verhelst clearly expressed the tradeoffs:
Smartcards are useful. They ensure that the private half of your key is never on any hard disk or other general storage device, and therefore that it cannot possibly be stolen (because there's only one possible copy of it). Smartcards are a pain in the ass. They ensure that the private half of your key is never on any hard disk or other general storage device but instead sits in your wallet, so whenever you need to access it, you need to grab your wallet to be able to do so, which takes more effort than just firing up GnuPG. If your laptop doesn't have a builtin cardreader, you also need to fish the reader from your backpack or wherever, etc.
"Smartcards" here refer to older OpenPGP cards that relied on the IEC 7816 smartcard connectors and therefore needed a specially-built smartcard reader. Newer keycards simply use a standard USB connector. In any case, it's true that having an external device introduces new issues: attackers can steal your keycard, you can simply lose it, or wash it with your dirty laundry. A laptop or a computer can also be lost, of course, but it is much easier to lose a small USB keycard than a full laptop and I have yet to hear of someone shoving a full laptop into a washing machine. When you lose your keycard, unless a separate revocation certificate is available somewhere, you lose complete control of the key, which is catastrophic. But, even if you revoke the lost key, you need to create a new one, which involves rebuilding the web of trust for the key a rather expensive operation as it usually requires meeting other OpenPGP users in person to exchange fingerprints. You should therefore think about how to back up the certification key, which is a problem that already exists for online keys; of course, everyone has a revocation certificates and backups of their OpenPGP keys... right? In the keycard scenario, backups may be multiple keycards distributed geographically. Note that, contrary to an air-gapped system, a key generated on a keycard cannot be backed up, by design. For subkeys, this is not a problem as they do not need to be backed up (except encryption keys). But, for a certification key, this means users need to generate the key on the host and transfer it to the keycard, which means the host is expected to have enough entropy to generate cryptographic-strength random numbers, for example. Also consider the possibility of combining different approaches: you could, for example, use a keycard for day-to-day operation, but keep a backup of the certification key on a LUKS-encrypted offline volume. Keycards introduce a new element into the trust chain: you need to trust the keycard manufacturer to not have any hostile code in the key's firmware or hardware. In addition, you need to trust that the implementation is correct. Keycards are harder to update: the firmware may be deliberately inaccessible to the host for security reasons or may require special software to manipulate. Keycards may be slower than the CPU in performing certain operations because they are small embedded microcontrollers with limited computing power. Finally, keycards may encourage users to trust multiple machines with their secrets, which works against the "minimum personal data" principle. A completely different approach called the trusted physical console (TPC) does the opposite: instead of trying to get private key material onto all of those machines, just have them on a single machine that is used for everything. Unlike a keycard, the TPC is an actual computer, say a laptop, which has the advantage of needing no special procedure to manage keys. The downside is, of course, that you actually need to carry that laptop everywhere you go, which may be problematic, especially in some corporate environments that restrict bringing your own devices.

Quick keycard "howto" Getting keys onto a keycard is easy enough:
  1. Start with a temporary key to test the procedure:
        export GNUPGHOME=$(mktemp -d)
        gpg --generate-key
    
  2. Edit the key using its user ID (UID):
        gpg --edit-key UID
    
  3. Use the key command to select the first subkey, then copy it to the keycard (you can also use the addcardkey command to just generate a new subkey directly on the keycard):
        gpg> key 1
        gpg> keytocard
    
  4. If you want to move the subkey, use the save command, which will remove the local copy of the private key, so the keycard will be the only copy of the secret key. Otherwise use the quit command to save the key on the keycard, but keep the secret key in your normal keyring; answer "n" to "save changes?" and "y" to "quit without saving?" . This way the keycard is a backup of your secret key.
  5. Once you are satisfied with the results, repeat steps 1 through 4 with your normal keyring (unset $GNUPGHOME)
When a key is moved to a keycard, --list-secret-keys will show it as sec> (or ssb> for subkeys) instead of the usual sec keyword. If the key is completely missing (for example, if you moved it to a LUKS container), the # sign is used instead. If you need to use a key from a keycard backup, you simply do gpg --card-edit with the key plugged in, then type the fetch command at the prompt to fetch the public key that corresponds to the private key on the keycard (which stays on the keycard). This is the same procedure as the one to use the secret key on another computer.

Conclusion There are already informal OpenPGP best-practices guides out there and some recommend storing keys offline, but they rarely explain what exactly that means. Storing your primary secret key offline is important in dealing with possible compromises and we examined the main ways of doing so: either with an air-gapped system, LUKS-encrypted keyring, or by using keycards. Each approach has its own tradeoffs, but I recommend getting familiar with keycards if you use multiple computers and want a standardized interface with minimal configuration trouble. And of course, those approaches can be combined. This tutorial, for example, uses a keycard on an air-gapped computer, which neatly resolves the question of how to transmit signatures between the air-gapped system and the world. It is definitely not for the faint of heart, however. Once one has decided to use a keycard, the next order of business is to choose a specific device. That choice will be addressed in a followup article, where I will look at performance, physical design, and other considerations.
This article first appeared in the Linux Weekly News.

Uwe Kleine-K nig: IPv6 in my home network

I am lucky and get both IPv4 (without CGNAT) and IPv6 from my provider. Recently after upgrading my desk router (that is an Netgear WNDR3800 that serves the network on my desk) from OpenWRT to latest LEDE I looked into what can be improved in the IPv6 setup for both my home network (served by a FRITZ!Box) and my desk network. Unfortunately I was unable to improve the situation compared to what I already had before. Things that work Making IPv6 work in general was easy, just a few clicks in the configuration of the FRITZ!Box and it mostly worked. After that I have: Things that don't work There are a few things however that I'd like to have, that are not that easy it seems: ULA for both nets I let the two routers announce an ULA prefix each. Unfortunately I was unable to make the LEDE box announce its net on the wan interface for clients in the home net. So the hosts in the desk net know how to reach the hosts in the home net but not the other way round which makes it quite pointless. (It works fine as long as the FRITZ!Box announces a global net, but I'd like to have local communication work independent of the global connectivity.) To fix this I'd need something like radvd on my LEDE router, but that isn't provided by LEDE (or OpenWRT) any more as odhcpd is supposed to be used which AFAICT is unable to send RAs on the wan interface though. Ok, probably I could install bird, but that seems a bit oversized. I created an entry in the LEDE forum but without any reply up to now. Alternatively (but less pretty) I could setup an IPv6 route in the FRITZ!Box, but that only works with a newer firmware and as this router is owned by my provider I cannot update it. Firewalling The FRITZ!Box has a firewall that is not very configurable. I can punch a hole in it for hosts with a given interface-ID, but that only works for hosts in the home net, not the machines in the delegated subnet behind the LEDE router. In fact I think the FRITZ!Box should delegate firewalling for a delegated net also to the router of that subnet. So having a global address on the machines on my desk doesn't allow me to reach them from the internet. Update: according to the German changelog firmware 6.83 seems to include that feature. Cheers AVM. Now waiting for my provider to update ...

James McCoy: Monthly FLOSS activity - 2017/09 edition

Debian devscripts Before deciding to take an indefinite hiatus from devscripts, I prepared one more upload merging various contributed patches and a bit of last minute cleanup. I also setup integration with Travis CI to hopefully catch issues sooner than "while preparing an upload", as was typically the case before. Anyone with push access to the Debian/devscripts GitHub repo can take advantage of this to test out changes, or keep the development branches up to date. In the process, I was able to make some improvements to travis.debian.net, namely support for DEB_BUILD_PROFILES and using a separate, minimal docker image for running autopkgtests. unibilium neovim Oddly, the mips64el builds were in BD-Uninstallable state, even though luajit's buildd status showed it was built. Looking further, I noticed the libluajit-5.1 ,-dev binary packages didn't have the mips64el architecture enabled, so I asked for it to be enabled. msgpack-c There were a few packages left which would FTBFS if I uploaded msgpack-c 2.x to unstable. All of the bug reports had either trivial work arounds (i.e., forcing use of the v1 C++ API) or trivial patches. However, I didn't want to continue waiting for the packages to get fixed since I knew other people had expressed interest in the new msgpack-c. Trying to avoid making other packages insta-buggy, I NMUed autobahn-cpp with the v1 work around. That didn't go over well, partly because I didn't send a finalized "Hey, I'd like to get this done and here's my plan to NMU" email. Based on that feedback, I decided to bump the remaining bugs to "serious" instead of NMUing and upload msgpack-c. Thanks to Jonas Smedegaard for quickly integrating my proposed fix for libdata-messagepack-perl. Hopefully, upstream has some time to review the PR soon. vim subversion

neovim

1 October 2017

Paul Wise: FLOSS Activities September 2017

Changes

Issues

Review

Administration
  • icns: merged patches
  • Debian: help guest user with access, investigate/escalate broken network, restart broken stunnels, investigate static.d.o storage, investigate weird RAID mails, ask hoster to investigate power issue,
  • Debian mentors: lintian/security updates & reboot
  • Debian wiki: merged & deployed patch, redirect DDTSS translator, redirect user support requests, whitelist email addresses, update email for accounts with bouncing email,
  • Debian derivatives census: merged/deployed patches
  • Debian PTS: debugged cron mails, deployed changes, reran scripts, fixed configuration file
  • Openmoko: debug reboot issue, debug load issues

Communication

Sponsors The samba bug was sponsored by my employer. All other work was done on a volunteer basis.

30 September 2017

Chris Lamb: Free software activities in September 2017

Here is my monthly update covering what I have been doing in the free software world in September 2017 (previous month):
Reproducible builds

Whilst anyone can inspect the source code of free software for malicious flaws, most software is distributed pre-compiled to end users. The motivation behind the Reproducible Builds effort is to allow verification that no flaws have been introduced either maliciously or accidentally during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised. I have generously been awarded a grant from the Core Infrastructure Initiative to fund my work in this area. This month I:
  • Published a short blog post about how to determine which packages on your system are reproducible. [...]
  • Submitted a pull request for Numpy to make the generated config.py files reproducible. [...]
  • Provided a patch to GTK upstream to ensure the immodules.cache files are reproducible. [...]
  • Within Debian:
    • Updated isdebianreproducibleyet.com, moving it to HTTPS, adding cachebusting as well as keeping the number up-to-date.
    • Submitted the following patches to fix reproducibility-related toolchain issues:
      • gdk-pixbuf: Make the output of gdk-pixbuf-query-loaders reproducible. (#875704)
      • texlive-bin: Make PDF IDs reproducible. (#874102)
    • Submitted a patch to fix a reproducibility issue in doit.
  • Categorised a large number of packages and issues in the Reproducible Builds "notes" repository.
  • Chaired our monthly IRC meeting. [...]
  • Worked on publishing our weekly reports. (#123, #124, #125, #126 & #127)


I also made the following changes to our tooling:
reproducible-check

reproducible-check is our script to determine which packages actually installed on your system are reproducible or not.

  • Handle multi-architecture systems correctly. (#875887)
  • Use the "restricted" data file to mask transient issues. (#875861)
  • Expire the cache file after one day and base the local cache filename on the remote name. [...] [...]
I also blogged about this utility. [...]
diffoscope

diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues.

  • Filed an issue attempting to identify the causes behind an increased number of timeouts visible in our CI infrastructure, including running a number of benchmarks of recent versions. (#875324)
  • New features:
    • Add "binwalking" support to analyse concatenated CPIO archives such as initramfs images. (#820631).
    • Print a message if we are reading data from standard input. [...]
  • Bug fixes:
    • Loosen matching of file(1)'s output to ensure we correctly also match TTF files under file version 5.32. [...]
    • Correct references to path_apparent_size in comparators.utils.file and self.buf in diffoscope.diff. [...] [...]
  • Testing:
    • Make failing some critical flake8 tests result in a failed build. [...]
    • Check we identify all CPIO fixtures. [...]
  • Misc:
    • No need for try-assert-except block in setup.py. [...]
    • Compare types with identity not equality. [...] [...]
    • Use logging.py's lazy argument interpolation. [...]
    • Remove unused imports. [...]
    • Numerous PEP8, flake8, whitespace, other cosmetic tidy-ups.

strip-nondeterminism

strip-nondeterminism is our tool to remove specific non-deterministic results from a completed build.

  • Log which handler processed a file. (#876140). [...]

disorderfs

disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues.


Debian My activities as the current Debian Project Leader are covered in my monthly "Bits from the DPL" email to the debian-devel-announce mailing list.
Lintian I made a large number of changes to Lintian, the static analysis tool for Debian packages. It reports on various errors, omissions and general quality-assurance issues to maintainers: I also blogged specifically about the Lintian 2.5.54 release.

Patches contributed
  • debconf: Please add a context manager to debconf.py. (#877096)
  • nm.debian.org: Add pronouns to ALL_STATUS_DESC. (#875128)
  • user-setup: Please drop set_special_users hack added for "the convenience of heavy testers". (#875909)
  • postgresql-common: Please update README.Debian for PostgreSQL 10. (#876438)
  • django-sitetree: Should not mask test failures. (#877321)
  • charmtimetracker:
    • Missing binary dependency on libqt5sql5-sqlite. (#873918)
    • Please drop "Cross-Platform" from package description. (#873917)
I also submitted 5 patches for packages with incorrect calls to find(1) in debian/rules against hamster-applet, libkml, pyferret, python-gssapi & roundcube.

Debian LTS

This month I have been paid to work 15 hours on Debian Long Term Support (LTS). In that time I did the following:
  • "Frontdesk" duties, triaging CVEs, etc.
  • Documented an example usage of autopkgtests to test security changes.
  • Issued DLA 1084-1 and DLA 1085-1 for libidn and libidn2-0 to fix an integer overflow vulnerabilities in Punycode handling.
  • Issued DLA 1091-1 for unrar-free to prevent a directory traversal vulnerability from a specially-crafted .rar archive. This update introduces an regression test.
  • Issued DLA 1092-1 for libarchive to prevent malicious .xar archives causing a denial of service via a heap-based buffer over-read.
  • Issued DLA 1096-1 for wordpress-shibboleth, correcting an cross-site scripting vulnerability in the Shibboleth identity provider module.

Uploads
  • python-django:
    • 1.11.5-1 New upstream security release. (#874415)
    • 1.11.5-2 Apply upstream patch to fix QuerySet.defer() with "super" and "subclass" fields. (#876816)
    • 2.0~alpha1-2 New upstream alpha release of Django 2.0, dropping support for Python 2.x.
  • redis:
    • 4.0.2-1 New upstream release.
    • 4.0.2-2 Update 0004-redis-check-rdb autopkgtest test to ensure that the redis.rdb file exists before testing against it.
    • 4.0.2-2~bpo9+1 Upload to stretch-backports.
  • aptfs (0.11.0-1) New upstream release, moving away from using /var/lib/apt/lists internals. Thanks to Julian Andres Klode for a helpful bug report. (#874765)
  • lintian (2.5.53, 2.5.54) New upstream releases. (Documented in more detail above.)
  • bfs (1.1.2-1) New upstream release.
  • docbook-to-man (1:2.0.0-39) Tighten autopkgtests and enable testing via travis.debian.net.
  • python-daiquiri (1.3.0-1) New upstream release.

I also made the following non-maintainer uploads (NMUs):

Debian bugs filed
  • clipit: Please choose a sensible startup default in "live" mode. (#875903)
  • git-buildpackage: Please add a --reset option to gbp pull. (#875852)
  • bluez: Please default Device "friendly name" to hostname without domain. (#874094)
  • bugs.debian.org: Please explicitly link to packages,tracker .debian.org. (#876746)
  • Requests for packaging:
    • selfspy log everything you do on the computer. (#873955)
    • shoogle use the Google API from the shell. (#873916)

FTP Team

As a Debian FTP assistant I ACCEPTed 86 packages: bgw-replstatus, build-essential, caja-admin, caja-rename, calamares, cdiff, cockpit, colorized-logs, comptext, comptty, copyq, django-allauth, django-paintstore, django-q, django-test-without-migrations, docker-runc, emacs-db, emacs-uuid, esxml, fast5, flake8-docstrings, gcc-6-doc, gcc-7-doc, gcc-8, golang-github-go-logfmt-logfmt, golang-github-google-go-cmp, golang-github-nightlyone-lockfile, golang-github-oklog-ulid, golang-pault-go-macchanger, h2o, inhomog, ip4r, ldc, libayatana-appindicator, libbson-perl, libencoding-fixlatin-perl, libfile-monitor-lite-perl, libhtml-restrict-perl, libmojo-rabbitmq-client-perl, libmoosex-types-laxnum-perl, libparse-mime-perl, libplack-test-agent-perl, libpod-projectdocs-perl, libregexp-pattern-license-perl, libstring-trim-perl, libtext-simpletable-autowidth-perl, libvirt, linux, mac-fdisk, myspell-sq, node-coveralls, node-module-deps, nov-el, owncloud-client, pantomime-clojure, pg-dirtyread, pgfincore, pgpool2, pgsql-asn1oid, phpliteadmin, powerlevel9k, pyjokes, python-evdev, python-oslo.db, python-pygal, python-wsaccel, python3.7, r-cran-bindrcpp, r-cran-dotcall64, r-cran-glue, r-cran-gtable, r-cran-pkgconfig, r-cran-rlang, r-cran-spatstat.utils, resolvconf-admin, retro-gtk, ring-ssl-clojure, robot-detection, rpy2-2.8, ruby-hocon, sass-stylesheets-compass, selinux-dbus, selinux-python, statsmodels, webkit2-sharp & weston. I additionally filed 4 RC bugs against packages that had incomplete debian/copyright files against: comptext, comptext, ldc & python-oslo.concurrency.

29 September 2017

Sven Hoexter: Last rites to the lyx and elyxer packaging

After having been a heavy LyX user from 2005 to 2010 I've continued to maintain LyX more or less till now. Finally I'm starting to leave that stage and removed myself from the Uploaders list. The upload with some other last packaging changes is currently sitting in the git repo. Mainly because lintian on ftp-master currently rejects 'pakagename@packages.d.o' maintainer addresses (the alternative to the lists.alioth.d.o maintainer mailinglists). For elyxer I filled a request for removal. It hasn't seen any upstream activity for a while and the LyX build in HTML export support improved. My hope is that if I step away far enough someone else might actually pick it up. I had this strange moment when I lately realized that xchat got reintroduced to Debian after mapreri and myself spent some time last year to get it removed before the stretch release.

27 September 2017

Dirk Eddelbuettel: RcppAnnoy 0.0.10

A few short weeks after the more substantial 0.0.9 release of RcppAnnoy, we have a quick bug-fix update. RcppAnnoy is our Rcpp-based R integration of the nifty Annoy library by Erik. Annoy is a small and lightweight C++ template header library for very fast approximate nearest neighbours. Micha l Benesty noticed that our getItemsVector() function didn't, ahem, do much besides crashing. Simple bug, they happen--now fixed, and a unit test added. Changes in this version are summarized here:

Changes in version 0.0.10 (2017-09-25)
  • The getItemsVector() function no longer crashes (#24)

Courtesy of CRANberries, there is also a diffstat report for this release.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

26 September 2017

Enrico Zini: Systemd timer units

These are the notes of a training course on systemd I gave as part of my work with Truelite. .timer units Configure activation of other units (usually a .service unit) at some given time. The functionality is similar to cron, with more features and a finer time granularity. For example, in Debian Stretch apt has a timer for running apt update which runs at a random time to distribute load on servers:
# /lib/systemd/system/apt-daily.timer
[Unit]
Description=Daily apt download activities
After=network-online.target
Wants=network-online.target
[Timer]
OnCalendar=*-*-* 6,18:00
RandomizedDelaySec=12h
Persistent=true
[Install]
WantedBy=timers.target
The corresponding apt-daily.service file then only runs when the system is on mains power, to avoid unexpected batter drains for systems like laptops:
# /lib/systemd/system/apt-daily.service
[Unit]
Description=Daily apt download activities
Documentation=man:apt(8)
ConditionACPower=true
[Service]
Type=oneshot
ExecStart=/usr/lib/apt/apt.systemd.daily update
Note that if you want to schedule tasks with an accuracy under a minute (for example to play a beep every 5 seconds when running on battery), you need to also configure AccuracySec= for the timer to a delay shorter than the default 1 minute. This is how to make your computer beep when on battery:
# /etc/systemd/system/beep-on-battery.timer
[Unit]
Description=Beeps every 10 seconds
[Install]
WantedBy=timers.target
[Timer]
AccuracySec=1s
OnUnitActiveSec=10s
# /etc/systemd/system/beep-on-battery.service
[Unit]
Description=Beeps when on battery
ConditionACPower=false
[Service]
Type=oneshot
ExecStart=/usr/bin/aplay /tmp/beep.wav
See:

Russ Allbery: Review: Artemis Fowl

Review: Artemis Fowl, by Eoin Colfer
Series: Artemis Fowl #1
Publisher: Disney-Hyperion
Copyright: 2001
ISBN: 1-4231-2452-9
Format: Kindle
Pages: 281
Artemis Fowl is the heir to the Fowl criminal empire and a child prodigy. He's also one of the few humans to know of the existence of fairies, who are still present in the world, hiding from humans and living by their own rules. As the book opens, he's in search of those rules: a copy of the book that governs the lives of fairies. With that knowledge, he should be able to pull off a heist worthy of his family's legacy. Captain Holly Short is a leprechaun... or, more correctly, a LEPrecon. She's one of the fairy police officers that investigate threats to the fairies who are hiding in a vast underground civilization. The fairies have magic, but they also have advanced (and miniaturized) technology, maintained in large part by a grumpy and egotistical centaur (named Foaly, because it's that sort of book). She's also the fairy unlucky enough to be captured by Artemis's formidable personal bodyguard their first attempt to kidnap a hostage for their ransom demands. This is the first book of a long series of young adult novels that has also spawned graphic novels and a movie currently in production. It has that lean and clear feeling of the younger side of young adult writing: larger-than-life characters who are distinctive and easy to remember, a short introductory setup that dives directly into the main plot, and a story that neatly pulls together every element raised in the story. The world-building is its strongest point, particularly the mix of tongue-in-cheek technology ships that ride magma plumes, mechanical wings, and helmet-mounted lights to blind trolls and science-tinged magic that the fairies build their police and army on. Fairies are far beyond humans in capability, and can be deadly and ruthless, but they have to follow a tightly constrained set of rules that are often not convenient. Sadly, the characters don't live up to the world-building. I did enjoy a few of them, particularly Artemis's loyal bodyguards and the dwarf Mulch Diggums. But Holly, despite being likable, is a bit of a blank slate: the empathetic, overworked trooper who is mostly indistinguishable from other characters in similar stories. The gruff captain, the sarcastic technician Foaly, and the various other LEP agents all felt like they were taken straight from central casting. And then there's Artemis himself. Artemis is the protagonist of the story, in that he's the one who initiates all of the action and the one who has the most interesting motivations. The story is about him, as the third-person narrator in the introduction makes clear. He's trying very hard to be a criminal genius with the deductive abilities of Sherlock Holmes and the speaking style of a Bond villain, but he's also twelve, his father has disappeared, and his mother is going slowly insane. I picked this book up on the recommendation of another reader who found that contrast compelling. Unfortunately, I thought Artemis was just an abusive jerk. Yes, yes, family tragedy, yes, he's trapped in his conception of himself, but he's arrogant, utterly uncaring about how his actions affect other people, and dismissive and cruel even to his bodyguards (who are much better friends than he deserves). I think liking this book requires liking Artemis at least well enough to consider him an anti-hero, and I can squint and see that appeal if you have that reaction. But I just wanted him to lose. Not in the "you will be slowly redeemed over the course of a long series" way, but in the "you are a horrible person and I hope you get what's coming to you" way. The humor of the fairy parts of the book was undermined too much by the fact that many of them would like to kill Artemis for real, and I mostly wanted them to succeed. This may or may not have to do with my low tolerance for egotistical smart-asses who order other people to do things that they refuse to explain. Without some appreciation for Artemis, this is a story with some neat world-building, a fairly generic protagonist in Holly, and a plot in which the bad guys win. To make matters worse, I thought the supposedly bright note at the end of the story was just creepy, as was everything else involving Artemis's mother. The review I read was of the first three books, so it's entirely possible that this series gets better as it goes along, but there wasn't enough I enjoyed in the first book for me to keep reading. Followed by Artemis Fowl: The Arctic Incident. Rating: 5 out of 10

25 September 2017

Steve Kemp: Started work on an internet-of-things Radio

So recently I was in York at the Bytemark office, and I read a piece about building a radio in a Raspberry Pi magazine. It got me curious, so when I got home to sunny Helsinki I figured I'd have a stab at it. I don't have fixed goal in mind, but what I do have is: The initial goal is simple wire the receiver/decoder to the board, and listen to the radio. After that there are obvious extenstions, such as adding an LCD display to show the frequency (What's the frequency Kenneth), and later to show the station details, via RDS. Finally I could add some buttons/switches/tweaks for selecting next/previous stations, and adjusting the volume. Initially that'll be handled by pointing a browser at the IP-address of the device. The first attempt at using the RDA5807M chip was a failure, as the thing was too damn small and non-standardly sized. Adding header-pins to the chips was almost impossible, and when I did get them soldered on the thing just gave me static-hisses. However I later read the details of the chip more carefully and realized that it isn't powerfull enough to drive (even) headphones. It requires an amp of some kind. With that extra knowledge I was able to send the output to the powered-speakers I have sat beside my PC. My code is basic, it sets up the FM-receiver/decoder, and scans the spectrum. When it finds a station it outputs the name over the serial console, via RDS, and then just plays it. I've got an PAM8403-based amplifier board on-order, when that arrives I'll get back to the project, and hookup WiFi and a simple web-page to store stations, tuning, etc. My "token goal" at the moment is a radio that switches on at 7AM and switches off at 8AM. In addition to that it'll serve a web-page allowing interactive control, regardless of any buttons that are wired in. I also have another project in the wings. I've ordered a software-defined radio (USB-toy) which I'm planning to use to plot aircraft in real-time, as they arrive/depart/fly over Helsinki. No doubt I'll write that up too.

19 September 2017

Sylvain Beucler: dot-zed extractor

Following last week's .zed format reverse-engineered specification, Lo c Dachary contributed a POC extractor!
It's available at http://www.dachary.org/loic/zed/, it can list non-encrypted metadata without password, and extract files with password (or .pem file).
Leveraging on python-olefile and pycrypto, only 500 lines of code (test cases excluded) are enough to implement it :)

Next.

Previous.