Search Results: "ema"

27 February 2023

Billy Warren: My take on IRCs - let's rest from Slack and Discord for a while.

I want to interest those that haven t used IRCs for a while through this article. This article generally leans toward the Debian Community but I hope it gives you some perspectives into IRCs and also interests you in joining the Debian Community as well. Most Generation Z developers I know have at least used slack, discord, discourse and so many other communication tools but so few have used IRCs so heavily and this could be because they find it boring and limited to what kind of content they can share and what community they are participating in. I got interested in using IRCs when I joined Debian and was able to navigate my way through using some online resources. While IRC may not be as popular as other communication tools like Slack or Discord, it remains a valuable tool for communication and collaboration within the open-source community. Its open-source nature and lightweight protocol make it a flexible and customizable tool that can be used in various settings. Internet Relay Chat (IRC) is a communication protocol that has been around since the late 1980s. Despite its age, it is still a popular tool for communication and collaboration, especially within the open-source community. It is mostly known to be used by people that work on boring projects or maintain legacy code (I can t state how true this is though). Interesting facts about IRC include that it was created by a Finnish developer named Jarkko Oikarinen, who wanted to create a communication tool that would allow him to chat with his friends in real-time (the FaceBook of those days). The first IRC network was called EFnet, and it quickly grew in popularity as more and more people began to use the protocol for communication and collaboration. IRC allows users to connect to servers and join channels (chat rooms) where they can communicate in real time with other users who have also joined the same channel. Many open-source projects use IRC channels for communication and collaboration among developers. The Debian project has a number of IRC channels that are used for communication and collaboration among developers and users. I have at least interacted with three of them which include;- To start using IRC, you will need to choose an IRC client, which is software that allows you to connect to IRC networks. Some popular IRC clients for Debian users include HexChat, irssi, and WeeChat. These clients are free and open source, and can be downloaded from the Debian repositories.Once you have chosen an IRC client, you can connect to an IRC network and start joining channels. Many open-source projects have their own IRC channels, where developers can discuss the project and collaborate in real time. One of the benefits of using IRC that I found out was that it is a lightweight protocol, which means that it can be used on a wide variety of devices, including desktop computers and smartphones. This makes it an ideal communication tool for developers who may be working on different devices and need to communicate with each other quickly and easily. IRC is still a valuable tool for communication and collaboration within the open-source community even if it is not given the same popularity as other communication tools. Like some of the good old legacy designs whose function never goes old, IRC is one of them.

25 February 2023

Gregor Herrmann: demo video: dpt(1) in pkg-perl-tools

in the Debian Perl Group we are maintaining a lot of packages (around 4000 at the time of writing). this also means that we are spending some time on improving our tools which allow us to handle this amount of packages in a reasonable time. many of the tools are shipped in the pkg-perl-tools package since 2013, & lots of them are scripts which are called as subcommands of the dpt(1) wrapper script. in the last years I got the impression that not all team members are aware of all the useful tools, & that some more promotion might be called for. & last week I was in the mood for creating a short demo video to showcase how I use some dpt(1) subcommands when updating a package to a new upstream release. (even though I prefer text over videos myself :)) probably not a cinematographic masterpiece but as the feedback of a few viewers has been positive, I'm posting it here as well: (direct link as planets ignore iframes )

24 February 2023

Dirk Eddelbuettel: ttdo 0.0.9 on CRAN: Small Update

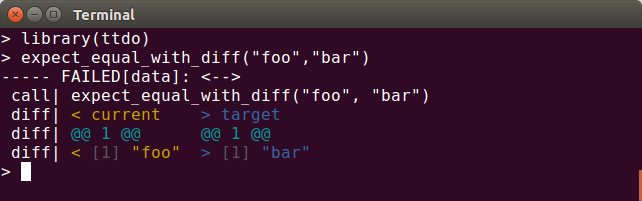
A new minor release of our ttdo package arrived on CRAN a few days ago. The ttdo package extends the excellent (and very minimal / zero depends) unit testing package tinytest by Mark van der Loo with the very clever and well-done diffobj package by Brodie Gaslam to give us test results with visual diffs (as shown in the screenshot below) which seemingly is so compelling an idea that it eventually got copied by another package which shall remain unnamed ttdo screenshot This release adds a versioned dependency on the just released tinytest version 1.4.1. As we extend tinytest (for use in the autograder we deploy within the lovely PrairieLearn framework) by consuming the tinytest code we have to update in sync. There were no other code changes in the package beside the usual maintenance of badges and continuous integration setup. As usual, the NEWS entry follows.

Changes in ttdo version 0.0.9 (2023-02-21)
  • Minor cleanup in README.md
  • Minor continuous integration update
  • Updated (versioned) depends on tinytest to 1.4.1

My CRANberries provides the usual summary of changes to the previous version. Please use the GitHub repo and its issues for any questions. If you like this or other open-source work I do, you can now sponsor me at GitHub.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

23 February 2023

Steve Kemp: A quick hack for Emacs

As I've mentioned in the past I keep a work-log, or work-diary, recording my activities every day. I have a bunch of standard things that I record, but one thing that often ends up happening is that I make references to external bug trackers, be they Jira, Bugzilla, or something else. Today I hacked up a simple emacs minor-mode for converting these references to hyperlinks, automatically, via the use of regular expressions. Given this configuration:
(setq linkifier-patterns '(
          ("\\\<XXX-[0-9]+\\\>" "https://jira.example.com/browse/%s")
          ("\\\<BUG-[0-9]+\\\>" "https://bugzilla.example.com/show?id=%s")))
When the minor-mode is active the any literal text that matches the pattern, for example "XXX-1234", will suddenly become a clickable button that will open Jira, and BUG-1234 will become a clickable button that opens the appropriate bug in Bugzilla. There's no rewriting of the content, this is just a bit of magic that changes the display of the text (i.e. I'm using a button/text-property). Since I mostly write in org-mode I could have written my text like so:
[[jira:XXX-1234][XXX-1234]]
But that feels like an ugly thing to do, and that style of links wouldn't work outside org-files anyway. That said it's a useful approach if you're only using org-mode, and the setup is simple:
(add-to-list 'org-link-abbrev-alist
    '("jira" . "http://jira.example.com/browse/%s"))
Anyway, cute hack. Useful too.

Paul Tagliamonte: Announcing hz.tools

Interested in future updates? Follow me on mastodon at @paul@soylent.green. Posts about hz.tools will be tagged #hztools.

If you're on the Fediverse, I'd very much appreciate boosts on my announcement toot!
Ever since 2019, I ve been learning about how radios work, and trying to learn about using them the hard way by writing as much of the stack as is practical (for some value of practical) myself. I wrote my first Hello World in 2018, which was a simple FM radio player, which used librtlsdr to read in an IQ stream, did some filtering, and played the real valued audio stream via pulseaudio. Over 4 years this has slowly grown through persistence, lots of questions to too many friends to thank (although I will try), and the eternal patience of my wife hearing about radios nonstop for years into a number of Go repos that can do quite a bit, and support a handful of radios. I ve resisted making the repos public not out of embarrassment or a desire to keep secrets, but rather, an attempt to keep myself free of any maintenance obligations to users so that I could freely break my own API, add and remove API surface as I saw fit. The worst case was to have this project feel like work, and I can t imagine that will happen if I feel frustrated by PRs that are getting ahead of me solving problems I didn t yet know about, or bugs I didn t understand the fix for. As my rate of changes to the most central dependencies has slowed, i ve begun to entertain the idea of publishing them. After a bit of back and forth, I ve decided it s time to make a number of them public, and to start working on them in the open, as I ve built up a bit of knowledge in the space, and I and feel confident that the repo doesn t contain overt lies. That s not to say it doesn t contain lies, but those lies are likely hidden and lurking in the dark. Beware. That being said, it shouldn t be a surprise to say I ve not published everything yet for the same reasons as above. I plan to open repos as the rate of changes slows and I understand the problems the library solves well enough or if the project dead ends and I ve stopped learning.

Intention behind hz.tools It s my sincere hope that my repos help to make Software Defined Radio (SDR) code a bit easier to understand, and serves as an understandable framework to learn with. It s a large codebase, but one that is possible to sit down and understand because, well, it was written by a single person. Frankly, I m also not productive enough in my free time in the middle of the night and on weekends and holidays to create a codebase that s too large to understand, I hope! I remain wary of this project turning into work, so my goal is to be very upfront about my boundaries, and the limits of what classes of contributions i m interested in seeing. Here s some goals of open sourcing these repos:
  • I do want this library to be used to learn with. Please go through it all and use it to learn about radios and how software can control them!
  • I am interested in bugs if there s a problem you discover. Such bugs are likely a great chance for me to fix something I ve misunderstood or typoed.
  • I am interested in PRs fixing bugs you find. I may need a bit of a back and forth to fully understand the problem if I do not understand the bug and fix yet. I hope you may have some grace if it s taking a long time.
Here s a list of some anti-goals of open sourcing these repos.
  • I do not want this library to become a critical dependency of an important project, since I do not have the time to deal with the maintenance burden. Putting me in that position is going to make me very uncomfortable.
  • I am not interested in feature requests, the features have grown as I ve hit problems, I m not interested in building or maintaining features for features sake. The API surface should be exposed enough to allow others to experiment with such things out-of-tree.
  • I m not interested in clever code replacing clear code without a very compelling reason.
  • I use GNU/Linux (specifically Debian ), and from time-to-time I ve made sure that my code runs on OpenBSD too. Platforms beyond that will likely not be supported at the expense of either of those two. I ll take fixes for bugs that fix a problem on another platform, but not damage the code to work around issues / lack of features on other platforms (like Windows).

I m not saying all this to be a jerk, I do it to make sure I can continue on my journey to learn about how radios work without my full time job becoming maintaining a radio framework single-handedly for other people to use even if it means I need to close PRs or bugs without merging it or fixing the issue. With all that out of the way, I m very happy to announce that the repos are now public under github.com/hztools.

Should you use this? Probably not. The intent here is not to provide a general purpose Go SDR framework for everyone to build on, although I am keenly aware it looks and feels like it, since that what it is to me. This is a learning project, so for any use beyond joining me in learning should use something like GNU Radio or a similar framework that has a community behind it. In fact, I suspect most contributors ought to be contributing to GNU Radio, and not this project. If I can encourage people to do so, contribute to GNU Radio! Nothing makes me happier than seeing GNU Radio continue to be the go-to, and well supported. Consider donating to GNU Radio!

hz.tools/rf - Frequency types The hz.tools/rf library contains the abstract concept of frequency, and some very basic helpers to interact with frequency ranges (such as helpers to deal with frequency ranges, or frequency range math) as well as frequencies and some very basic conversions (to meters, etc) and parsers (to parse values like 10MHz). This ensures that all the hz.tools libraries have a shared understanding of Frequencies, a standard way of representing ranges of Frequencies, and the ability to handle the IO boundary with things like CLI arguments, JSON or YAML. The git repo can be found at github.com/hztools/go-rf, and is importable as hz.tools/rf.
 // Parse a frequency using hz.tools/rf.ParseHz, and print it to stdout.
 freq := rf.MustParseHz("-10kHz")
fmt.Printf("Frequency: %s\n", freq+rf.MHz)
// Prints: 'Frequency: 990kHz'

// Return the Intersection between two RF ranges, and print
 // it to stdout.
 r1 := rf.Range rf.KHz, rf.MHz 
r2 := rf.Range rf.Hz(10), rf.KHz * 100 
fmt.Printf("Range: %s\n", r1.Intersection(r2))
// Prints: Range: 1000Hz->100kHz
These can be used to represent tons of things - ranges can be used for things like the tunable range of an SDR, the bandpass of a filter or the frequencies that correspond to a bin of an FFT, while frequencies can be used for things such as frequency offsets or the tuned center frequency.

hz.tools/sdr - SDR I/O and IQ Types This is the big one. This library represents the majority of the shared types and bindings, and is likely the most useful place to look at when learning about the IO boundary between a program and an SDR. The git repo can be found at github.com/hztools/go-sdr, and is importable as hz.tools/sdr. This library is designed to look (and in some cases, mirror) the Go io idioms so that this library feels as idiomatic as it can, so that Go builtins interact with IQ in a way that s possible to reason about, and to avoid reinventing the wheel by designing new API surface. While some of the API looks (and is even called) the same thing as a similar function in io, the implementation is usually a lot more naive, and may have unexpected sharp edges such as concurrency issues or performance problems. The following IQ types are implemented using the sdr.Samples interface. The hz.tools/sdr package contains helpers for conversion between types, and some basic manipulation of IQ streams.
IQ Format hz.tools Name Underlying Go Type
Interleaved uint8 (rtl-sdr) sdr.SamplesU8 [][2]uint8
Interleaved int8 (hackrf, uhd) sdr.SamplesI8 [][2]int8
Interleaved int16 (pluto, uhd) sdr.SamplesI16 [][2]int16
Interleaved float32 (airspy, uhd) sdr.SamplesC64 []complex64
The following SDRs have implemented drivers in-tree.
SDR Format RX/TX State
rtl u8 RX Good
HackRF i8 RX/TX Good
PlutoSDR i16 RX/TX Good
rtl kerberos u8 RX Old
uhd i16/c64/i8 RX/TX Good
airspyhf c64 RX Exp
The following major packages and subpackages exist at the time of writing:
Import What is it?
hz.tools/sdr Core IQ types, supporting types and implementations that interact with the byte boundary
hz.tools/sdr/rtl sdr.Receiver implementation using librtlsdr.
hz.tools/sdr/rtl/kerberos Helpers to enable coherent RX using the Kerberos SDR.
hz.tools/sdr/rtl/e4k Helpers to interact with the E4000 RTL-SDR dongle.
hz.tools/sdr/fft Interfaces for performing an FFT, which are implemented by other packages.
hz.tools/sdr/rtltcp sdr.Receiver implementation for rtl_tcp servers.
hz.tools/sdr/pluto sdr.Transceiver implementation for the PlutoSDR using libiio.
hz.tools/sdr/uhd sdr.Transceiver implementation for UHD radios, specifically the B210 and B200mini
hz.tools/sdr/hackrf sdr.Transceiver implementation for the HackRF using libhackrf.
hz.tools/sdr/mock Mock SDR for testing purposes.
hz.tools/sdr/airspyhf sdr.Receiver implementation for the AirspyHF+ Discovery with libairspyhf.
hz.tools/sdr/internal/simd SIMD helpers for IQ operations, written in Go ASM. This isn t the best to learn from, and it contains pure go implemtnations alongside.
hz.tools/sdr/stream Common Reader/Writer helpers that operate on IQ streams.

hz.tools/fftw - hz.tools/sdr/fft implementation The hz.tools/fftw package contains bindings to libfftw3 to implement the hz.tools/sdr/fft.Planner type to transform between the time and frequency domain. The git repo can be found at github.com/hztools/go-fftw, and is importable as hz.tools/fftw. This is the default throughout most of my codebase, although that default is only expressed at the leaf package libraries should not be hardcoding the use of this library in favor of taking an fft.Planner, unless it s used as part of testing. There are a bunch of ways to do an FFT out there, things like clFFT or a pure-go FFT implementation could be plugged in depending on what s being solved for.

hz.tools/ fm,am - analog audio demodulation and modulation The hz.tools/fm and hz.tools/am packages contain demodulators for AM analog radio, and FM analog radio. This code is a bit old, so it has a lot of room for cleanup, but it ll do a very basic demodulation of IQ to audio. The git repos can be found at github.com/hztools/go-fm and github.com/hztools/go-am, and are importable as hz.tools/fm and hz.tools/am. As a bonus, the hz.tools/fm package also contains a modulator, which has been tested on the air and with some of my handheld radios. This code is a bit old, since the hz.tools/fm code is effectively the first IQ processing code I d ever written, but it still runs and I run it from time to time.
 // Basic sketch for playing FM radio using a reader stream from
 // an SDR or other IQ stream.

bandwidth := 150*rf.KHz
reader, err = stream.ConvertReader(reader, sdr.SampleFormatC64)
if err != nil  
...
 
demod, err := fm.Demodulate(reader, fm.DemodulatorConfig 
Deviation: bandwidth / 2,
Downsample: 8, // some value here depending on sample rate
 Planner: fftw.Plan,
 )
if err != nil  
...
 
speaker, err := pulseaudio.NewWriter(pulseaudio.Config 
Format: pulseaudio.SampleFormatFloat32NE,
Rate: demod.SampleRate(),
AppName: "rf",
StreamName: "fm",
Channels: 1,
SinkName: "",
 )
if err != nil  
...
 
buf := make([]float32, 1024*64)
for  
i, err := demod.Read(buf)
if err != nil  
...
 
if i == 0  
panic("...")
 
if err := speaker.Write(buf[:i]); err != nil  
...


hz.tools/rfcap - byte serialization for IQ data The hz.tools/rfcap package is the reference implementation of the rfcap spec , and is how I store IQ captures locally, and how I send them across a byte boundary. The git repo can be found at github.com/hztools/go-rfcap, and is importable as hz.tools/rfcap. If you re interested in storing IQ in a way others can use, the better approach is to use SigMF rfcap exists for cases like using UNIX pipes to move IQ around, through APIs, or when I send IQ data through an OS socket, to ensure the sample format (and other metadata) is communicated with it. rfcap has a number of limitations, for instance, it can not express a change in frequency or sample rate during the capture, since the header is fixed at the beginning of the file.

21 February 2023

Freexian Collaborators: Monthly report about Debian Long Term Support, January 2023 (by Anton Gladky)

Like each month, have a look at the work funded by Freexian s Debian LTS offering. This is the first monthly report in 2023.

Debian LTS contributors In January, 17 contributors have been paid to work on Debian LTS. which is possibly the highest number of active contributors per month! Their reports are available:
  • Abhijith PA did 0.0h (out of 3.0h assigned and 11.0h from previous period), thus carrying over 14.0h to the next month.
  • Adrian Bunk did 26.25h (out of 26.25h assigned).
  • Anton Gladky did 11.5h (out of 8.0h assigned and 7.0h from previous period), thus carrying over 3.5h to the next month.
  • Ben Hutchings did 8.0h (out of 24.0h assigned), thus carrying over 16.0h to the next month.
  • Chris Lamb did 18.0h (out of 18.0h assigned).
  • Emilio Pozuelo Monfort did 8.0h (out of 0h assigned and 43.0h from previous period), thus carrying over 35.0h to the next month.
  • Guilhem Moulin did 20.0h (out of 17.5h assigned and 2.5h from previous period).
  • Helmut Grohne did 10.0h (out of 15.0h assigned), thus carrying over 5.0h to the next month.
  • Lee Garrett did 7.5h (out of 20.0h assigned), thus carrying over 12.5h to the next month.
  • Markus Koschany did 26.25h (out of 26.25h assigned).
  • Ola Lundqvist did 4.5h (out of 10.0h assigned and 6.0h from previous period), thus carrying over 11.5h to the next month.
  • Roberto C. S nchez did 3.75h (out of 18.75h assigned and 7.5h from previous period), thus carrying over 22.5h to the next month.
  • Stefano Rivera did 4.5h (out of 0h assigned and 32.5h from previous period), thus carrying over 28.0h to the next month.
  • Sylvain Beucler did 23.5h (out of 0h assigned and 38.5h from previous period), thus carrying over 15.0h to the next month.
  • Thorsten Alteholz did 14.0h (out of 10.0h assigned and 4.0h from previous period).
  • Tobias Frost did 19.0h (out of 19.0h assigned).
  • Utkarsh Gupta did 43.25h (out of 26.25h assigned and 17.0h from previous period).

Evolution of the situation Furthermore, we released 46 DLAs in January, which resolved 146 CVEs. We are working diligently to reduce the number of packages listed in dla-needed.txt, and currently, we have 55 packages listed. We are constantly growing and seeking new contributors. If you are a Debian Developer and want to join the LTS team, please contact us.

Thanks to our sponsors Sponsors that joined recently are in bold.

17 February 2023

Enrico Zini: Monitoring a heart rate monitor

I bought myself a cheap wearable Bluetooth LE heart rate monitor in order to play with it, and this is a simple Python script to monitor it and plot data. Bluetooth LE I was surprised that these things seem decently interoperable. You can use hcitool to scan for devices:
hcitool lescan
You can then use gatttool to connect to device and poke at them interactively from a command line. Bluetooth LE from Python There is a nice library called Bleak which is also packaged in Debian. It's modern Python with asyncio and works beautifully! Heart rate monitors Things I learnt: How about a proper fitness tracker? I found OpenTracks, also on F-Droid, which seems nice Why script it from a desktop computer? The question is: why not? A fitness tracker on a phone is useful, but there are lots of silly things one can do from one's computer that one can't do from a phone. A heart rate monitor is, after all, one more input device, and there are never enough input devices! There are so many extremely important use cases that seem entirely unexplored:

Jonathan McDowell: First impressions of the VisionFive 2

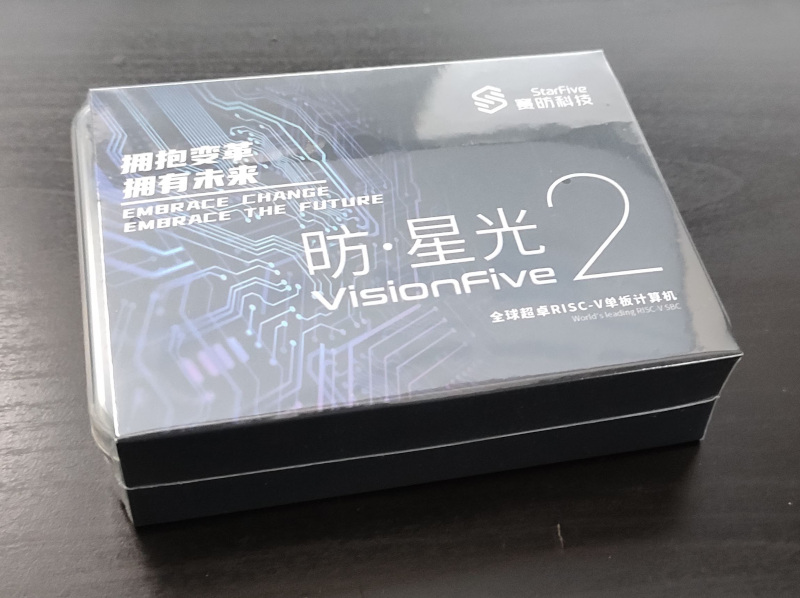
VisionFive 2 packaging Back in September last year I chose to back the StarFive VisionFive 2 on Kickstarter. I don t have a particular use in mind for it, but I felt it was one of the first RISC-V systems that were relatively capable (mentally I have it as somewhere between a Raspberry Pi 3 + a Pi 4). In particular it s a quad 1.5GHz 64-bit RISC-V core with 8G RAM, USB3, GigE ethernet and a single M.2 PCIe slot. More than ample as a personal machine for playing around with RISC-V and doing local builds. I ended up paying 67 for the Early Bird variant (dual GigE ethernet rather than 1 x 100Mb and 1 x GigE). A couple of weeks ago I got an email with a tracking number and last week it finally turned up. Being impatient the first thing I did was plug it into a monitor, connect up a keyboard, and power it on. Nothing except some flashing lights. Looking at the boot selector DIP switches suggested it was configured to boot from UART, so I flipped them to (what I thought was) the flash setting. It wasn t - turns out the ON marking on the switches represents logic 0 and it was correctly setup when I got it. I went to read the documentation which talked about writing an image to a MicroSD card, but also had details of the UART connection. Wanting to make sure the device was at least doing something before I actually tried an OS on it I hooked up a USB/serial dongle and powered the board up again. Success! U-Boot appeared and I could interact with it. I went to the VisionFive2 Debian page and proceeded to torrent the Image-69 image, writing it to a MicroSD card and inserting it in the slot on the bottom of the board. It booted fine. I can t even tell you what graphical environment it booted up because I don t remember; it worked fine though (at 1080p, I ve seen reports that 4K screens will make it croak). Poking around the image revealed that it s built off a snapshot.debian.org snapshot from 20220616T194833Z, which is a little dated at this point but I understand the rationale behind picking something that works and sticking with it. The kernel is of course a vendor special, based on 5.15.0. Further investigation revealed that the entire X/graphics stack is living in /usr/local, which isn t overly surprising; it s Imagination based. I was pleasantly surprised to discover there is work to upstream the Imagination support, but I m not planning to run the board with a monitor attached so it s not a high priority for me. Having discovered all that I decided to see how well a clean Debian unstable install from Debian Ports would go. I had a spare Intel Optane lying around (it s a stupid 22110 M.2 which is too long for any machine I own), so I put it in the slot on the bottom of the board. To my surprise it Just Worked and was detected ok:
# lspci
0000:00:00.0 PCI bridge: PLDA XpressRich-AXI Ref Design (rev 02)
0000:01:00.0 USB controller: VIA Technologies, Inc. VL805/806 xHCI USB 3.0 Controller (rev 01)
0001:00:00.0 PCI bridge: PLDA XpressRich-AXI Ref Design (rev 02)
0001:01:00.0 Non-Volatile memory controller: Intel Corporation NVMe Datacenter SSD [Optane]
I created a single partition with an ext4 filesystem (initially tried btrfs, but the StarFive kernel doesn t support it), and kicked off a debootstrap with:
# mkfs -t ext4 /dev/nvme0n1p1
# mount /dev/nvme0n1p1 /mnt
# debootstrap --keyring=/etc/apt/trusted.gpg.d/debian-ports-archive-2023.gpg \
	unstable /mnt https://deb.debian.org/debian-ports
The u-boot setup has a convoluted set of vendor scripts that eventually ends up reading a /boot/extlinux/extlinux.conf config from /dev/mmcblk1p2, so I added an additional entry there using the StarFive kernel but pointing to the NVMe device for /. Made sure to set a root password (not that I ve been bitten by that before, too many times), and rebooted. Success! Well. Sort of. I hit a bunch of problems with having a getty running on ttyS0 as well as one running on hvc0. The second turns out to be a console device from the RISC-V SBI. I did a systemctl mask serial-getty@hvc0.service which made things a bit happier, but I was still seeing odd behaviour and output. Turned out I needed to reboot the initramfs as well; the StarFive one was using Plymouth and doing some other stuff that seemed to be confusing matters. An update-initramfs -k 5.15.0-starfive -c built me a new one and everything was happy. Next problem; the StarFive kernel doesn t have IPv6 support. StarFive are good citizens and make their 5.15 kernel tree available, so I grabbed it, fed it the existing config, and tweaked some options (including adding IPV6 and SECCOMP, which chrony wanted). Slight hiccup when it turned out trying to do things like make sound modular caused it to fail to compile, and having to backport the fix that allowed the use of GCC 12 (as present in sid), but it got there. So I got cocky and tried to update it to the latest 5.15.94. A few manual merge fixups (which I may or may not have got right, but it compiles and boots for me), and success. Timings:
$ time make -j 4 bindeb-pkg
  [linux-image-5.15.94-00787-g1fbe8ac32aa8]
real	37m0.134s
user	117m27.392s
sys	6m49.804s
On the subject of kernels I am pleased to note that there are efforts to upstream the VisionFive 2 support, with what appears to be multiple members of StarFive engaging in multiple patch submission rounds. It s really great to see this and I look forward to being able to run an unmodified mainline kernel on my board. Niggles? I have a few. The provided u-boot doesn t have NVMe support enabled, so at present I need to keep a MicroSD card to boot off, even though root is on an SSD. I m also seeing some errors in dmesg from the SSD:
[155933.434038] nvme nvme0: I/O 436 QID 4 timeout, completion polled
[156173.351166] nvme nvme0: I/O 48 QID 3 timeout, completion polled
[156346.228993] nvme nvme0: I/O 108 QID 3 timeout, completion polled
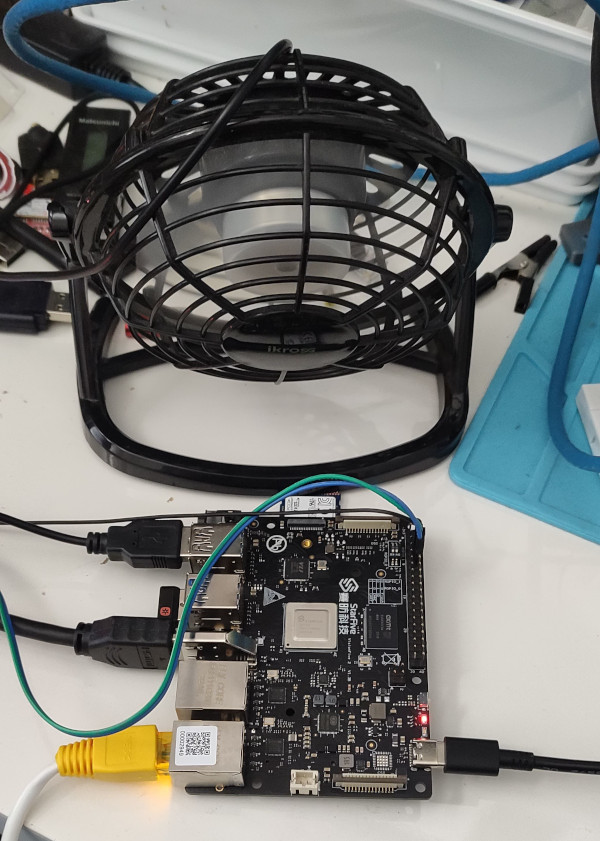
It doesn t seem to cause any actual issues, and it could be the SSD, the 5.15 kernel or an actual hardware thing - I ll keep an eye on it (I will probably end up with a different SSD that actually fits, so that ll provide another data point). More annoying is the temperature the CPU seems to run at. There s no heatsink or fan, just the metal heatspreader on top of the CPU, and in normal idle operation it sits at around 60 C. Compiling a kernel it hit 90 C before I stopped the job and sorted out some additional cooling in the form of a desk fan, which kept it as just over 30 C. Bare VisionFive 2 SBC board with a small desk fan pointed at it I haven t seen any actual stability problems, but I wouldn t want to run for any length of time like that. I ve ordered a heatsink and also realised that the board supports a Raspberry Pi style PoE Hat , so I ve got one of those that includes a fan ordered (I am a complete convert to PoE especially for small systems like this). With the desk fan setup I ve been able to run the board for extended periods under load (I did a full recompile of the Debian 6.1.12-1 kernel package and it took about 10 hours). The M.2 slot is unfortunately only a single PCIe v2 lane, and my testing topped out at about 180MB/s. IIRC that is about half what the slot should be capable of, and less than a 10th of what the SSD can do. Ethernet testing with iPerf3 sustained about 941Mb/s, so basically maxing out the port. The board as a whole isn t going to set any speed records, but it s perfectly usable, and pretty impressive for the price point. On the Debian side I ve not hit any surprises. There s work going on to move RISC-V to a proper release architecture, and I m hoping to be able to help out with that, but the version of unstable I installed from the ports infrastructure has looked just like any other Debian install. Which is what you want. And that pretty much sums up my overall experience of the VisionFive 2; it s not noticeably different than any other single board computer. That s a good thing, FWIW, and once the kernel support lands properly upstream (it ll be post 6.3 at least it seems) it ll be a boring mainline supported platform that just happens to be RISC-V.

15 February 2023

Valhalla's Things: My experience with a PinePhone

Posted on February 15, 2023
I ve had and used1 a PinePhone for quite some time now, and a shiny new blog sounds like a good time to do a review of my experience. TL;DL: I love it, but my use cases may not be very typical. While I ve had a mobile phone since an early time (my parents made me carry one for emergencies before it was usual for my peers) I ve never used a typical smartphone (android / iPhone / those other proprietary things) because I can t trust them not to be designed to work against me (data collection, ads, tricking users into micro payments, and other antipatterns of proprietary software design), and bringing them to sanity as most of the people I know do is too much effort for my tastes. Instead, as a phone I keep using an old nokia featurephone2 which is reliable, only requires charging once a week, and can easily survive falling from hand height to the ground, even if thrown 3. And then I ve been carrying a variety of other devices to do other computer-like tasks; earlier it was just a laptop, or a netbook, a Pandora (all of which used a dongle to connect to mobile network internet) then I tried a phone with FirefoxOS (it could have been better) and now the PinePhone has taken their place, at least when I m not carrying a laptop anyway. So, the tasks I use the PinePhone for are mostly:
  1. sending and receiving xmpp messages, with no need for notifications (when somebody needs to tell me something where urgency is required, they know to use the other phone, either with a call or an sms);
  2. tethering an internet connection to the laptop;
  3. reading djvu scans of old books while standing in a queue or something;
  4. checking something on the internet when I m not close to a real computer (i.e. one with a keyboard and a big screen);
  5. running a timer while heat-setting fabric paint with an iron (and reading a djvu book at the same time yes, this is a very specific task, but it has happened multiple times already :D );
  6. running a calculator with unit conversions;
  7. running the odd command line program;
  8. taking pictures, especially those that I want to send soon (I often also carry a DSLR camera, but I tend to wait a few days before I download them from the card);
  9. map related things.
3 and 5 work perfectly well, no issues there. 1, 2 and 4 usually work just fine, except for the fact that sometimes while the phone is suspended it forgets about being a phone, and needs to be restarted to turn the modem back on. It s not a big deal while using the phone, I just need to check before I try to use it after a few hours. For 1, I also had to take care to install dino-im from experimental, as up to now the features required to fit the interface in a mobile screen aren t available in the official release, but I believe that this has just been fixed. Somewhat related to 4, I ve also installed kiwix and the dumps of wiktionary and wikivoyage, but I haven t had a chance to travel much, so I m not really using it. For 6 I m quite happy with qalculate, the GUI version of qalc (which is what I use on my laptop), even if it has a few minor interface issues, and 7 of course works as well as it can, given the limitations of a small screen and virtual keyboard. 8 is, let us say, problematic. The camera on the PinePhone is peculiar, only works with a specific software, and even there the quality of the pictures is, well, low-fi, vintagey pictures are a look and that s a specific artistic choice, right? Thanks to the hard work of the megapixels maintainer the quality has improved a lot, and these days it is usable, but there are still limits (no webcam in the browser, no recording of videos). 9 is really bad. A few times I can remember getting a GPS fix. A few times in many months, and now and then I keep trying, to see if a miracle has happened, but usually I only get a vague position from wifi data (which isn t great, when walking through less densely populated areas). I ve seen another PinePhone running gpsd and getting data from an external GPS receiver via bluetooth, and if I really needed it I may seriously consider that solution. Also, the apps available in mobian aren t great either, even when compared to running tangogps on an OpenMoko with pre-downloaded maps (I mean! I don t think my expectations are too high!). I ve heard that PureMaps is quite good as a software, but a bit of a PITA to package for Debian, and I really hope that one day there will be a linux-first mobile device with good GPS hardware, so that people will be encouraged to fix the software side. Thankfully, I don t usually need GPS and navigation software; when I m driving into places I don t know I usually have a human navigator, and when walking into places I can do with just a static map (either printed on paper or on the PinePhone), maybe some pre-calculated route from the OSM website and looking at street names to find out where I am. Overall, for my use cases the PinePhone works just fine and is an useful addition to the things I always carry with me, and I don t feel the pressing need to get an android phone. I don t think it s ready as a daily driver for everybody, but I think that depending on one s needs it s worth asking around (I d recommend doing so on the fediverse with a #PinePhone and #mobian hashtag), as there is a non-zero chance that it may be a good fit for you.

  1. which, if I m not mistaken, is often not implied by the fact of owning it :D
  2. for very low values of feature: it doesn t have any kind of internet access, and there are only 3 games, one of which is snake.
  3. don t ask.

13 February 2023

Jonathan Dowland: A visit to Prusa Labs

.
.

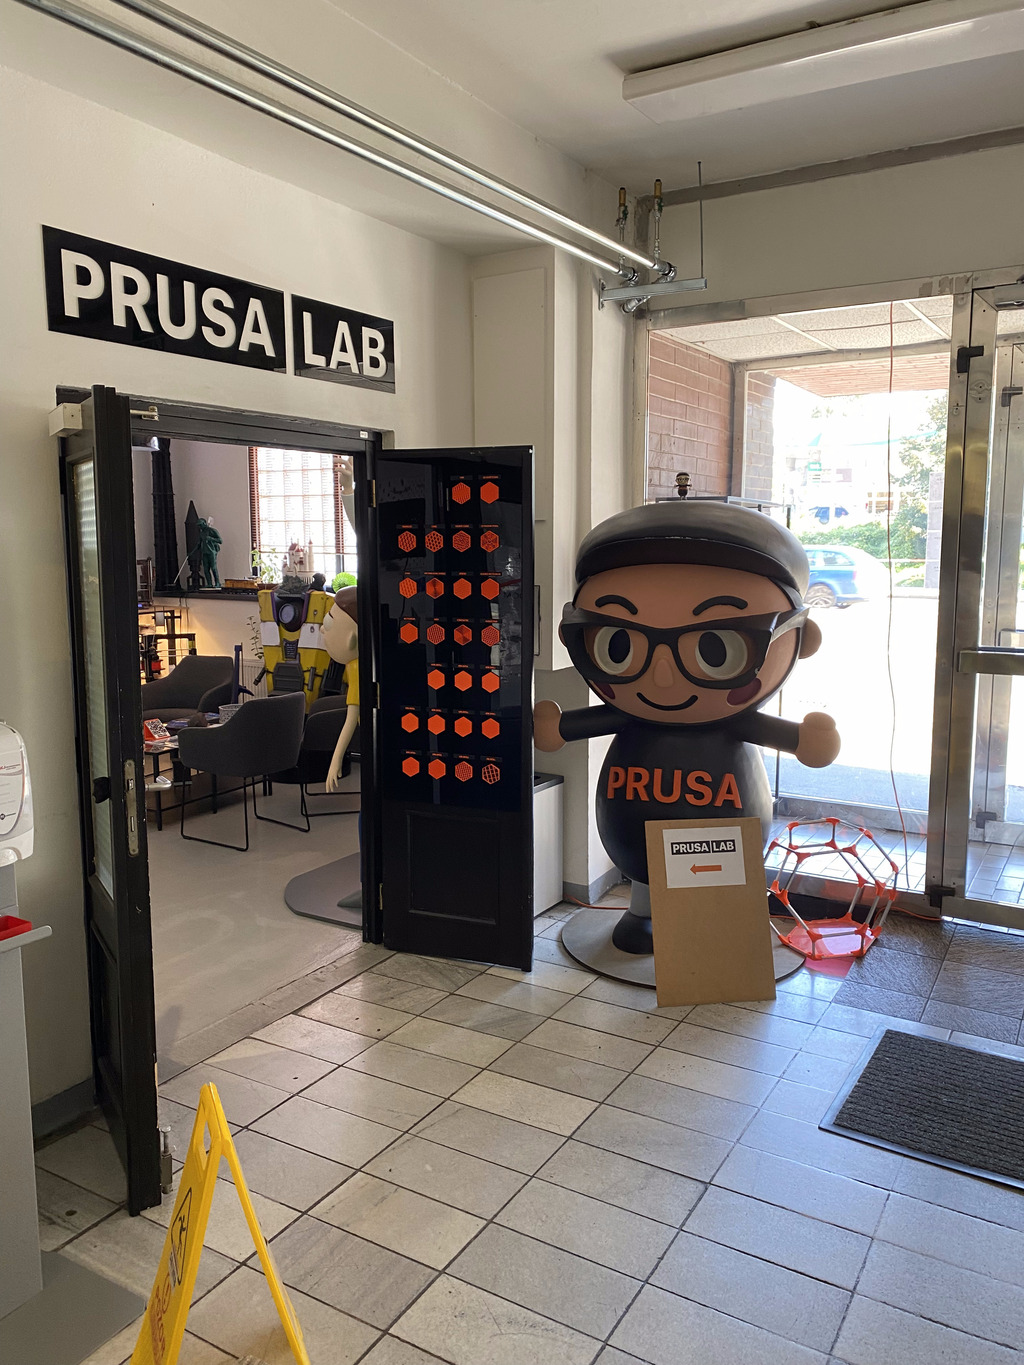
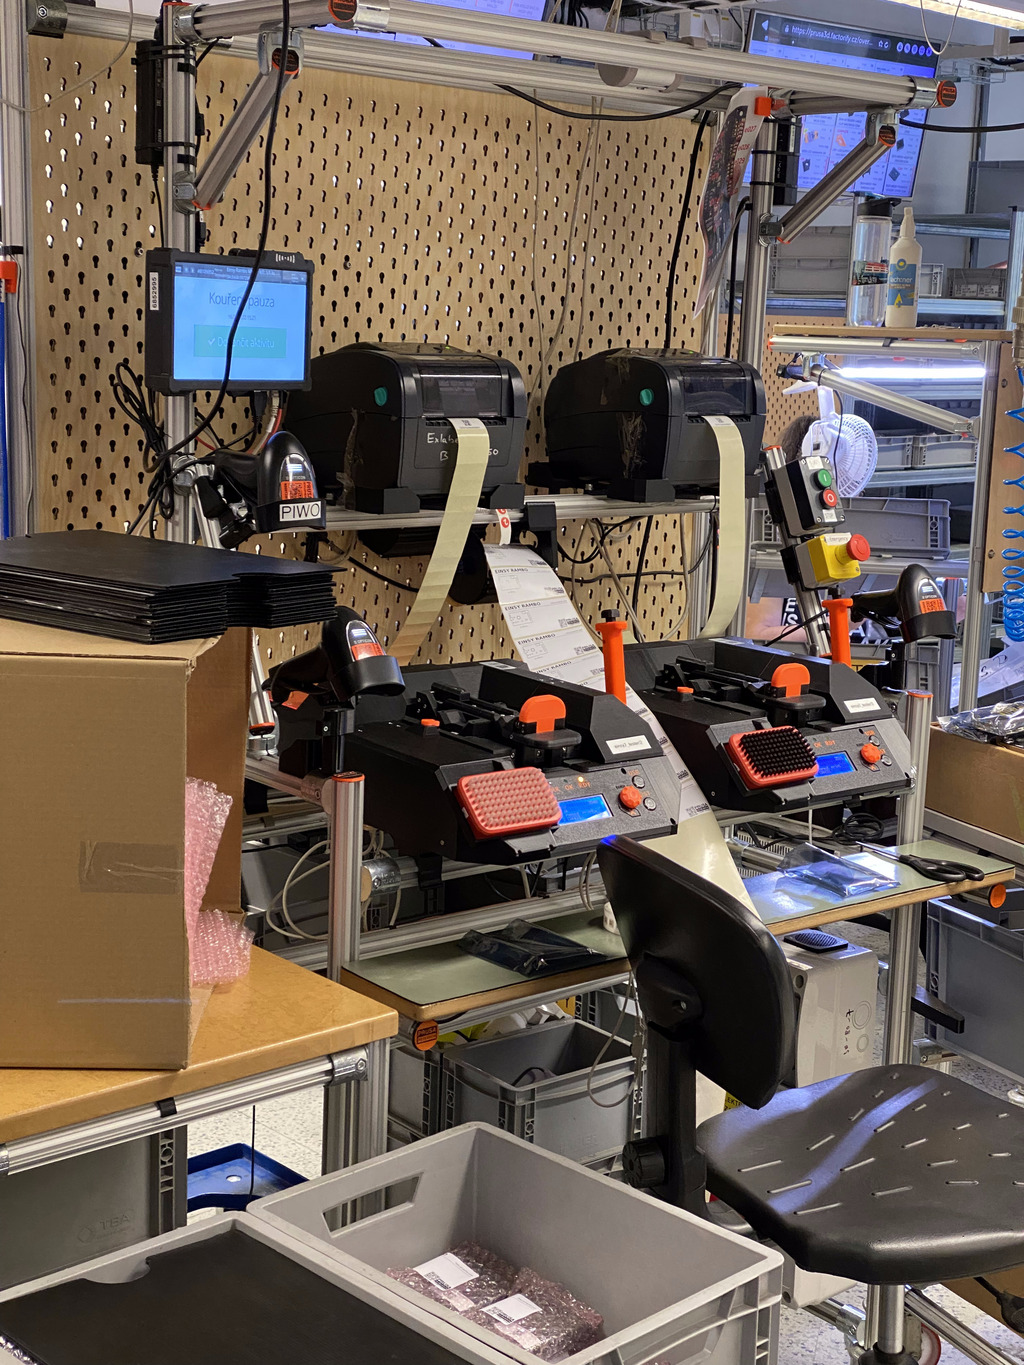
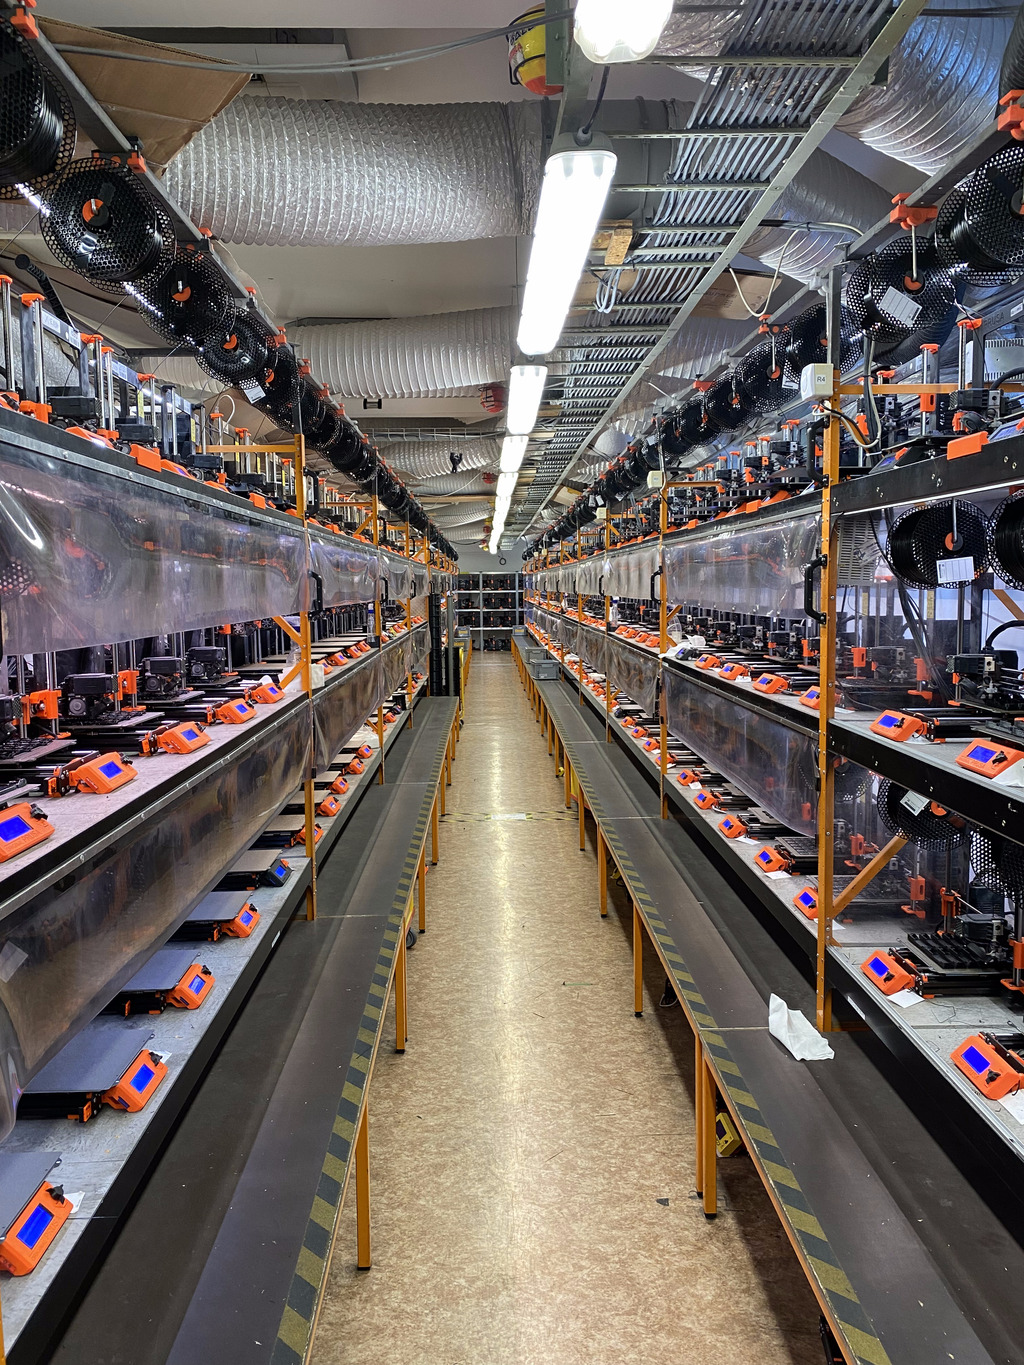
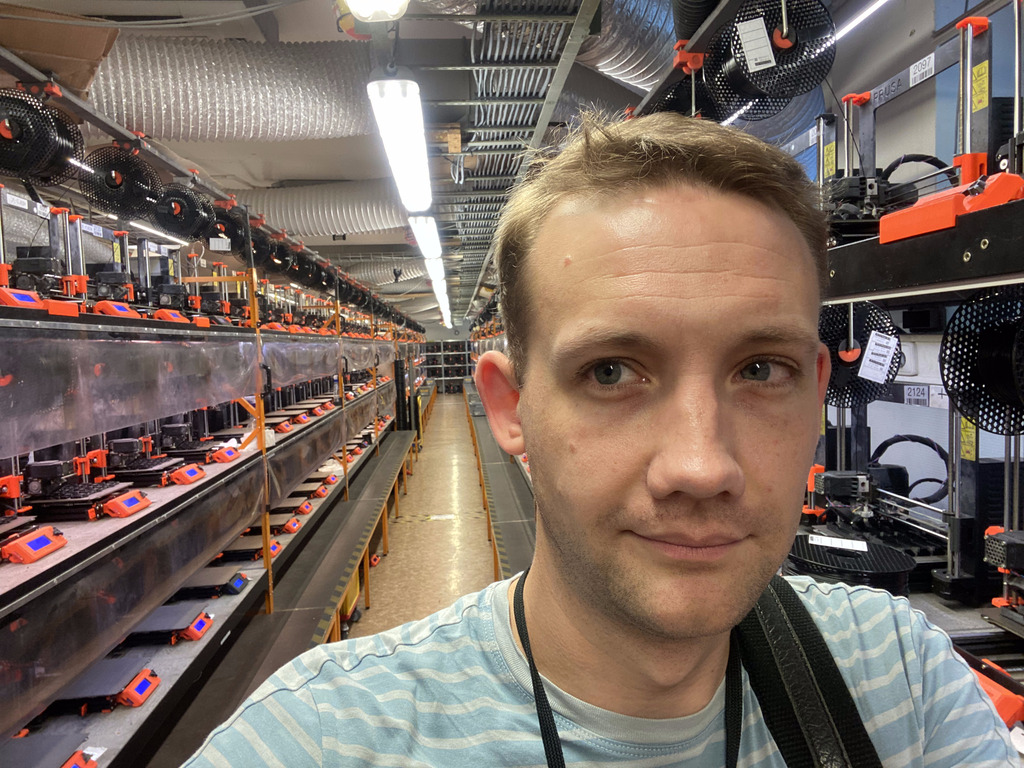
In September I was in Czechia for a Red Hat event. I ended up travelling via Prague, and had an unexpected extra day due to an airline strike causing my flight home to be cancelled. I took the opportunity to visit Prusa's offices/factory/Lab, and it was amazing! The Prusa team were all busy getting ready for the Prague Maker Faire that was happening the day afterwards.1 On arriving at the street which houses Prusa's Lab and Office buildings, the first thing that hit me was the smell. I find the melted-plastic smell of FDM printing (with PLA, at least) quite pleasant, and this was a super-condensed version of that, pumping out of their ground-floor windows. I started at the reception area on the ground floor. Outside reception there's a lovely sculpture representing the history of the development of the MK3S+.
The Reception The Reception
SLS Farm in the former Hack lab SLS Farm in the former Hack lab
History of the MK3S+ History of the MK3S+

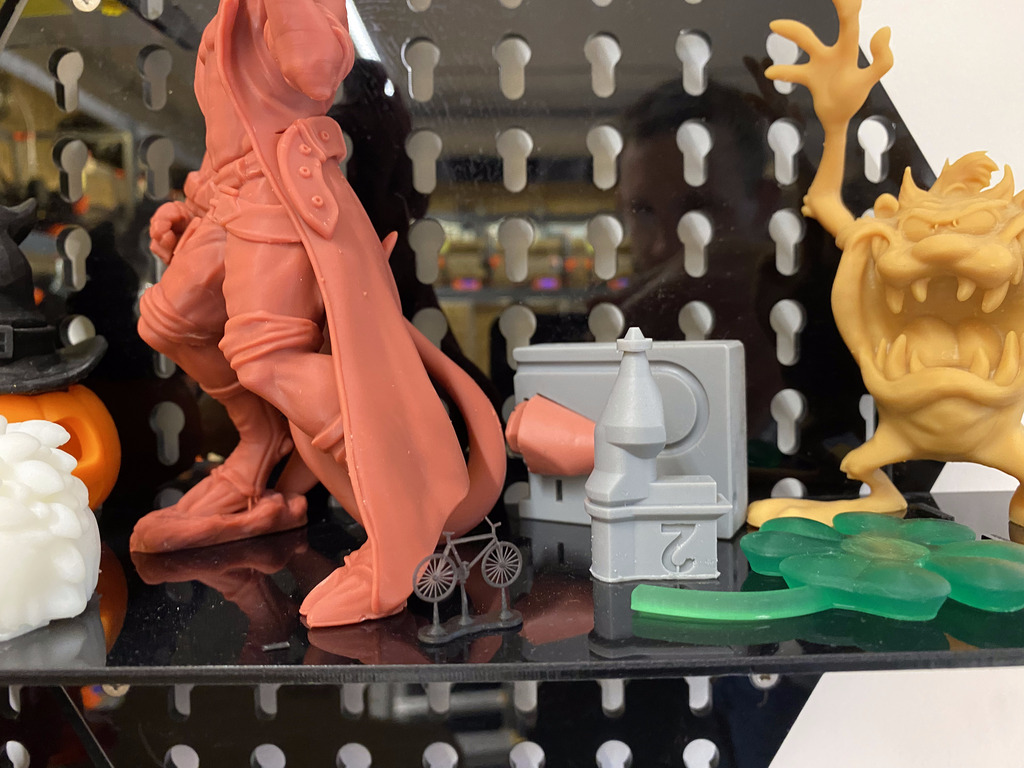
At the reception you have a small waiting area with shelves of demonstration prints and some spools of Prusament. From here, our kind guide first took us to a region on the ground floor that used to be (prior to COVID times) the public maker/hack lab. The lab contained two modest farms of printers: one of their flagship FDM printer, the MK3S+, and another of their SLS resin printers. A close up of some example resin models is pictured above. The bicycle was tiny: about the size of a thumbnail.
A Historic display A Historic display
Bespoke QE equipment Bespoke QE equipment
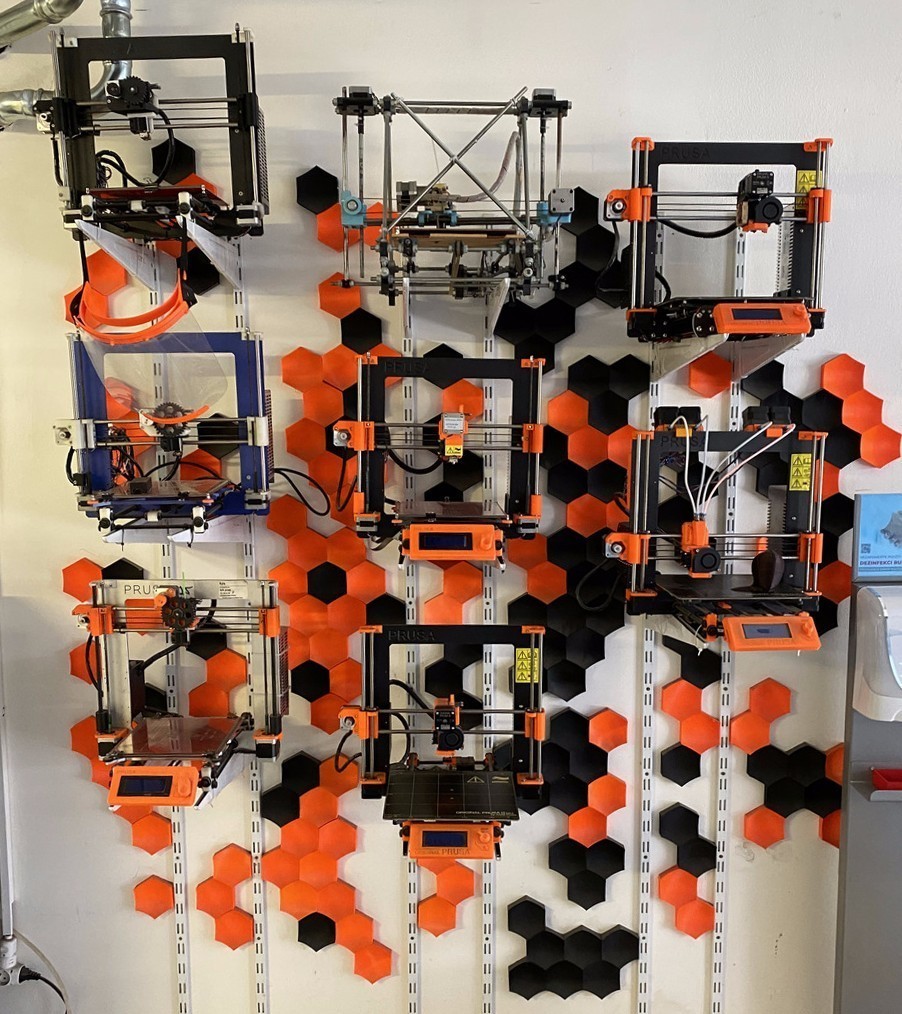
The MK3S+ Farm The MK3S+ Farm

. Moi in the Farm
2KG orange PLA spools for the Farm 2KG orange PLA spools for the Farm
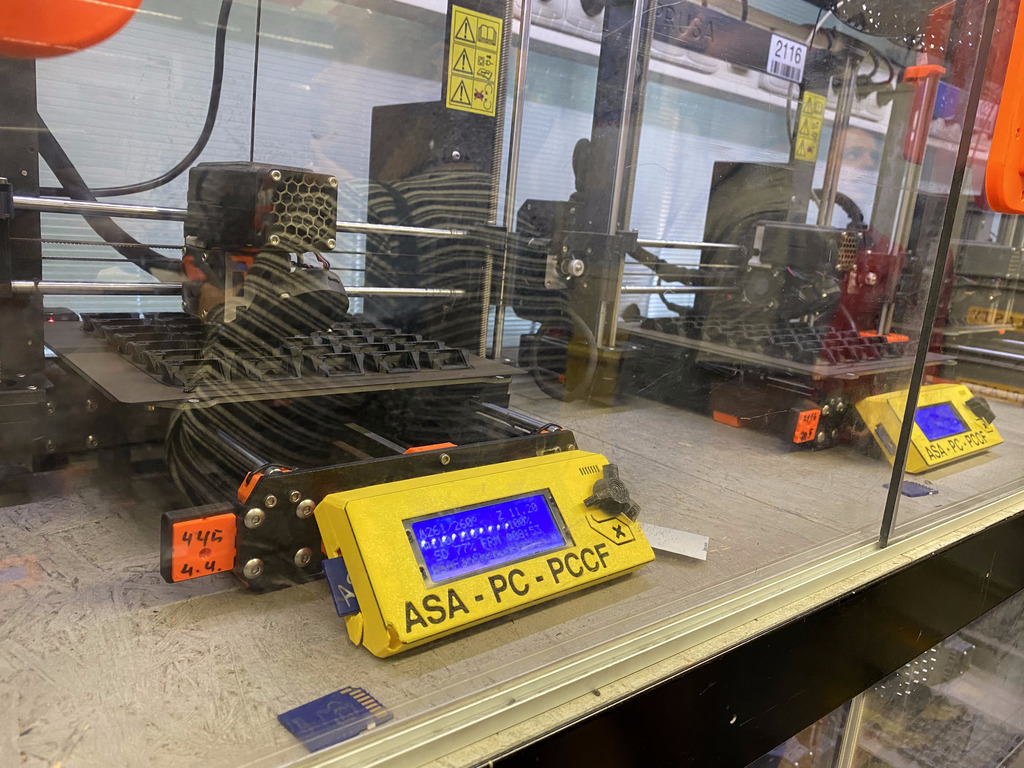
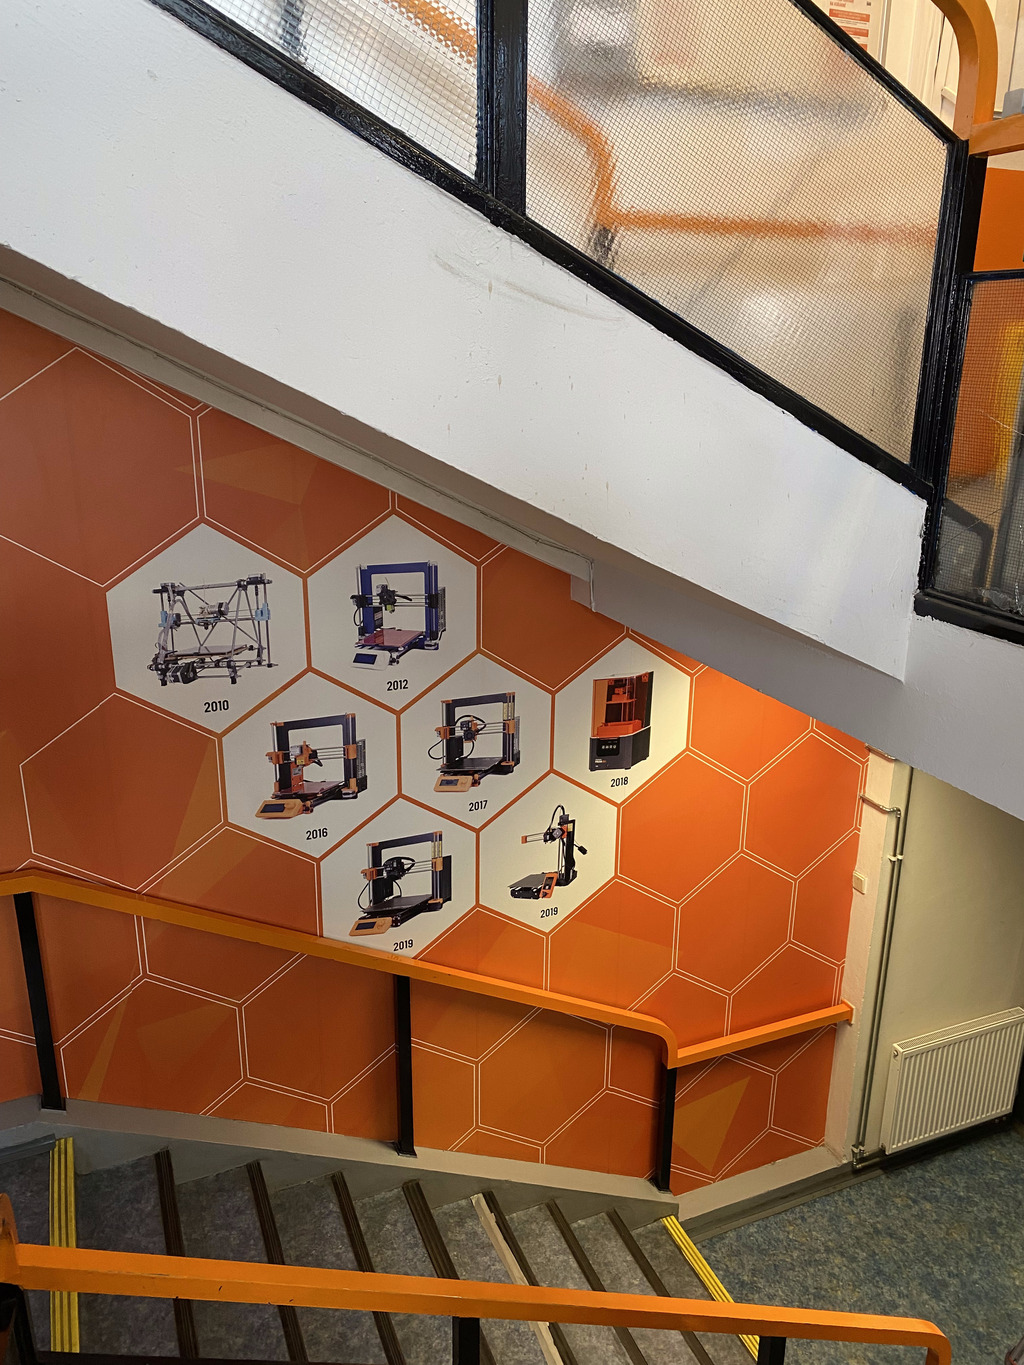
The rest of the ground floor area was full of heavy machinery and prototyping equipment. Onwards we went to the upstairs floors. Upstairs, past a nice graphic of Prusa's historic products, we visited the assembly and QE testing areas. They have a very organised system of parts buckets and some thorough QE processes, including some bespoke equipment that produces the "receipt" of tests and calibration that they provide for you in the box when you buy a 3D printer. After that, we visited the production Farm: a large room full of MK3S+ printers churning out parts for other printers. The noise was remarkable. The printers were running custom firmware to continually print the part they had been set for. Some of the printers were designated for printing with ASA: they were colour-coded (yellow controller surround) and within boxed regions to prevent the fumes causing problems. (picture at the top) Outside the room sat palettes of orange PETG plastic for the printer farm on 2KG spools (not a size they sell to the public just yet) The final part of the trip was outside, to the real farm: Prusa have a smallholding with Alpacas at the rear of their estate. Whilst we visited it, Josef Prusa himself turned up (in a snazzy looking custom colour Tesla) to feed the animals, say hello and pose for a picture. Overall, it was a fantastic visit. I'm very grateful to Air France for cancelling my flight home, and to Prusa Labs (in particular Luk ) for allowing me to come and say hello!

  1. I managed to squeeze that in too on my way to my rescheduled flight, although it was a rush visit and I don't have much to say or show from it. Suffice to say that it was lovely and bittersweet since the UK Maker Faire used to be hosted in my fair home city of Newcastle before they stopped.

Vincent Bernat: Building a SQL-like language to filter flows

Akvorado collects network flows using IPFIX or sFlow. It stores them in a ClickHouse database. A web console allows a user to query the data and plot some graphs. A nice aspect of this console is how we can filter flows with a SQL-like language:
Filter editor in Akvorado console
Often, web interfaces expose a query builder to build such filters. I think combining a SQL-like language with an editor supporting completion, syntax highlighting, and linting is a better approach.1 The language parser is built with pigeon (Go) from a parsing expression grammar or PEG. The editor component is CodeMirror (TypeScript).

Language parser PEG grammars are relatively recent2 and are an alternative to context-free grammars. They are easier to write and they can generate better error messages. Python switched from an LL(1)-based parser to a PEG-based parser in Python 3.9. pigeon generates a parser for Go. A grammar is a set of rules. Each rule is an identifier, with an optional user-friendly label for error messages, an expression, and an action in Go to be executed on match. You can find the complete grammar in parser.peg. Here is a simplified rule:
ConditionIPExpr "condition on IP"  
  column:("ExporterAddress"i   return "ExporterAddress", nil  
        / "SrcAddr"i   return "SrcAddr", nil  
        / "DstAddr"i   return "DstAddr", nil  ) _ 
  operator:("=" / "!=") _ 
  ip:IP  
    return fmt.Sprintf("%s %s IPv6StringToNum(%s)",
      toString(column), toString(operator), quote(ip)), nil
   
The rule identifier is ConditionIPExpr. It case-insensitively matches ExporterAddress, SrcAddr, or DstAddr. The action for each case returns the proper case for the column name. That s what is stored in the column variable. Then, it matches one of the possible operators. As there is no code block, it stores the matched string directly in the operator variable. Then, it tries to match the IP rule, which is defined elsewhere in the grammar. If it succeeds, it stores the result of the match in the ip variable and executes the final action. The action turns the column, operator, and IP into a proper expression for ClickHouse. For example, if we have ExporterAddress = 203.0.113.15, we get ExporterAddress = IPv6StringToNum('203.0.113.15'). The IP rule uses a rudimentary regular expression but checks if the matched address is correct in the action block, thanks to netip.ParseAddr():
IP "IP address"   [0-9A-Fa-f:.]+  
  ip, err := netip.ParseAddr(string(c.text))
  if err != nil  
    return "", errors.New("expecting an IP address")
   
  return ip.String(), nil
 
Our parser safely turns the filter into a WHERE clause accepted by ClickHouse:3
WHERE InIfBoundary = 'external' 
AND ExporterRegion = 'france' 
AND InIfConnectivity = 'transit' 
AND SrcAS = 15169 
AND DstAddr BETWEEN toIPv6('2a01:e0f:ffff::') 
                AND toIPv6('2a01:e0f:ffff:ffff:ffff:ffff:ffff:ffff')

Integration in CodeMirror CodeMirror is a versatile code editor that can be easily integrated into JavaScript projects. In Akvorado, the Vue.js component, InputFilter, uses CodeMirror as its foundation and leverages features such as syntax highlighting, linting, and completion. The source code for these capabilities can be found in the codemirror/lang-filter/ directory.

Syntax highlighting The PEG grammar for Go cannot be utilized directly4 and the requirements for parsers for editors are distinct: they should be error-tolerant and operate incrementally, as code is typically updated character by character. CodeMirror offers a solution through its own parser generator, Lezer. We don t need this additional parser to fully understand the filter language. Only the basic structure is needed: column names, comparison and logic operators, quoted and unquoted values. The grammar is therefore quite short and does not need to be updated often:
@top Filter  
  expression
 
expression  
 Not expression  
 "(" expression ")"  
 "(" expression ")" And expression  
 "(" expression ")" Or expression  
 comparisonExpression And expression  
 comparisonExpression Or expression  
 comparisonExpression
 
comparisonExpression  
 Column Operator Value
 
Value  
  String   Literal   ValueLParen ListOfValues ValueRParen
 
ListOfValues  
  ListOfValues ValueComma (String   Literal)  
  String   Literal
 
// [ ]
@tokens  
  // [ ]
  Column   std.asciiLetter (std.asciiLetter std.digit)*  
  Operator   $[a-zA-Z!=><]+  
  String  
    '"' (![\\\n"]   "\\" _)* '"'?  
    "'" (![\\\n']   "\\" _)* "'"?
   
  Literal   (std.digit   std.asciiLetter   $[.:/])+  
  // [ ]
 
The expression SrcAS = 12322 AND (DstAS = 1299 OR SrcAS = 29447) is parsed to:
Filter(Column, Operator, Value(Literal),
  And, Column, Operator, Value(Literal),
  Or, Column, Operator, Value(Literal))
The last step is to teach CodeMirror how to map each token to a highlighting tag:
export const FilterLanguage = LRLanguage.define( 
  parser: parser.configure( 
    props: [
      styleTags( 
        Column: t.propertyName,
        String: t.string,
        Literal: t.literal,
        LineComment: t.lineComment,
        BlockComment: t.blockComment,
        Or: t.logicOperator,
        And: t.logicOperator,
        Not: t.logicOperator,
        Operator: t.compareOperator,
        "( )": t.paren,
       ),
    ],
   ),
 );

Linting We offload linting to the original parser in Go. The /api/v0/console/filter/validate endpoint accepts a filter and returns a JSON structure with the errors that were found:
 
  "message": "at line 1, position 12: string literal not terminated",
  "errors": [ 
    "line":    1,
    "column":  12,
    "offset":  11,
    "message": "string literal not terminated",
   ]
 
The linter source for CodeMirror queries the API and turns each error into a diagnostic.

Completion The completion system takes a hybrid approach. It splits the work between the frontend and the backend to offer useful suggestions for completing filters. The frontend uses the parser built with Lezer to determine the context of the completion: do we complete a column name, an operator, or a value? It also extracts the column name if we are completing something else. It forwards the result to the backend through the /api/v0/console/filter/complete endpoint. Walking the syntax tree was not as easy as I thought, but unit tests helped a lot. The backend uses the parser generated by pigeon to complete a column name or a comparison operator. For values, the completions are either static or extracted from the ClickHouse database. A user can complete an AS number from an organization name thanks to the following snippet:
results := []struct  
  Label  string  ch:"label" 
  Detail string  ch:"detail" 
 
columnName := "DstAS"
sqlQuery := fmt.Sprintf( 
 SELECT concat('AS', toString(%s)) AS label, dictGet('asns', 'name', %s) AS detail
 FROM flows
 WHERE TimeReceived > date_sub(minute, 1, now())
 AND detail != ''
 AND positionCaseInsensitive(detail, $1) >= 1
 GROUP BY label, detail
 ORDER BY COUNT(*) DESC
 LIMIT 20
 , columnName, columnName)
if err := conn.Select(ctx, &results, sqlQuery, input.Prefix); err != nil  
  c.r.Err(err).Msg("unable to query database")
  break
 
for _, result := range results  
  completions = append(completions, filterCompletion 
    Label:  result.Label,
    Detail: result.Detail,
    Quoted: false,
   )
 
In my opinion, the completion system is a major factor in making the field editor an efficient way to select flows. While a query builder may have been more beginner-friendly, the completion system s ease of use and functionality make it more enjoyable to use once you become familiar.

  1. Moreover, building a query builder did not seem like a fun task for me.
  2. They were introduced in 2004 in Parsing Expression Grammars: A Recognition-Based Syntactic Foundation. LR parsers were introduced in 1965, LALR parsers in 1969, and LL parsers in the 1970s. Yacc, a popular parser generator, was written in 1975.
  3. The parser returns a string. It does not generate an intermediate AST. This makes it simpler and it currently fits our needs.
  4. It could be manually translated to JavaScript with PEG.js.

10 February 2023

Jonathan Dowland: HLedger, 1 year on

It's been a year since I started exploring HLedger, and I'm still going. The rollover to 2023 was an opportunity to revisit my approach. Some time ago I stumbled across Dmitry Astapov's HLedger notes (fully-fledged hledger, which I briefly mentioned in eventual consistency) and decided to adopt some of its ideas. new year, new journal First up, Astapov encourages starting a new journal file for a new calendar year. I do this for other, accounting-adjacent files as a matter of course, and I did it for my GNUCash files prior to adopting HLedger. But the reason for those is a general suspicion that a simple mistake with those softwares could irrevocably corrupt my data. I'm much more confident with HLedger, so rolling over at years end isn't necessary for that. But there are other advantages. A quick obvious one is you can get rid of old accounts (such as expense accounts tied to a particular project, now completed). one journal per import In the first year, I periodically imported account data via CSV exports of transactions and HLedger's (excellent) CSV import system. I imported all the transactions, once each, into a single, large journal file. Astapov instead advocates for creating a separate journal for each CSV that you wish to import, and keep around the CSV, leaving you with a 1:1 mapping of CSV:journal. Then use HLedger's "include" mechanism to pull them all into the main journal. With the former approach, where the CSV data was imported precisely, once, it was only exposed to your import rules once. The workflow ended up being: import transactions; notice some that you could have matched with import rules and auto-coded; write the rule for the next time. With Astapov's approach, you can re-generate the journal from the CSV at any point in the future with an updated set of import rules. tracking dependencies Now we get onto the job of driving the generation of all these derivative journal files. Astapov has built a sophisticated system using Haskell's "Shake", which I'm not yet familiar, but for my sins I'm quite adept at (GNU-flavoured) UNIX Make, so I started building with that. An example rule
import/jon/amex/%.journal: import/jon/amex/%.csv rules/amex.csv.rules
    rm -f $(@D)/.latest.$*.csv $@
    hledger import --rules-file rules/amex.csv.rules -f $@ $<
This captures the dependency between the journal and the underlying CSV but also to the relevant rules file; if I modify that, and this target is run in the future, all dependent journals should be re-generated.1 opening balances It's all fine and well starting over in a new year, and I might be generous to forgive debts, but I can't count on others to do the same. We need to carry over some balance information from one year to the next. Astapov has a more complex (or perhaps featureful) scheme for this involving a custom Haskell program, but I bodged something with a pair of make targets:
import/opening/2023.csv: 2022.journal
    mkdir -p import/opening
    hledger bal -f $< \
                $(list_of_accounts_I_want_to_carry_over) \
        -O csv -N > $@
import/opening/2023.journal: import/opening/2023.csv rules/opening.rules
    rm -f $(@D)/.latest.2023.csv $@
    hledger import --rules-file rules/opening.rules \
        -f $@ $<
I think this could be golfed into a year-generic rule with a little more work. The nice thing about this approach is the opening balances for a given year might change, if adjustments are made in prior years. They shouldn't, for real accounts, but very well could for more "virtual" liabilities. (including: deciding to write off debts.) run lots of reports Astapov advocates for running lots of reports, and automatically. There's a really obvious advantage of that to me: there's no chance anyone except me will actually interact with HLedger itself. For family finances, I need reports to be able to discuss anything with my wife. Extending my make rules to run reports is trivial. I've gone for HTML reports for the most part, as they're the easiest on the eye. Unfortunately the most useful report to discuss (at least at the moment) would be a list of transactions in a given expense category, and the register/aregister commands did not support HTML as an output format. I submitted my first HLedger patch to add HTML output support to aregister: https://github.com/simonmichael/hledger/pull/2000 addressing the virtual posting problem I wrote in my original hledger blog post that I had to resort to unbalanced virtual postings in order to record both a liability between my personal cash and family, as well as categorise the spend. I still haven't found a nice way around that. But I suspect having broken out the journal into lots of other journals paves the way to a better solution to the above. The form of a solution I am thinking of is: some scheme whereby the two destination accounts are combined together; perhaps, choose one as a primary and encode the other information in sub-accounts under that. For example, repeating the example from my hledger blog post:
2022-01-02 ZTL*RELISH
    family:liabilities:creditcard        -3.00
    family:dues:jon                       3.00
    (jon:expenses:snacks)                 3.00
This could become
2022-01-02 ZTL*RELISH
    family:liabilities:creditcard        -3.00
    family:liabilities:jon:snacks
(I note this is very similar to a solution proposed to me by someone responding on twitter). The next step is to recognise that sometimes when looking at the data I care about one aspect, and at other times the other, but rarely both. So for the case where I'm thinking about family finances, I could use account aliases to effectively flatten out the expense category portion and ignore it. On the other hand, when I'm concerned about how I've spent my personal cash and not about how much I owe the family account, I could use aliases to do the opposite: rewrite-away the family:liabilities:jon prefix and combine the transactions with the regular jon:expenses account heirarchy. (this is all speculative: I need to actually try this.) catching errors after an import When I import the transactions for a given real bank account, I check the final balance against another source: usually a bank statement, to make sure they agree. I wasn't using any of the myriad methods to make sure that this remains true later on, and so there was the risk that I make an edit to something and accidentally remove a transaction that contributed to that number, and not notice (until the next import). The CSV data my bank gives me for accounts (not for credit cards) also includes a 'resulting balance' field. It was therefore trivial to extend the CSV import rules to add balance assertions to the transactions that are generated. This catches the problem. There are a couple of warts with balance assertions on every such transaction: for example, dealing with the duplicate transaction for paying a credit card: one from the bank statement, one from the credit card. Removing one of the two is sufficient to correct the account balances but sometimes they don't agree on the transaction date, or the transactions within a given day are sorted slightly differently by HLedger than by the bank. The simple solution is to just manually delete one or two assertions: there remain plenty more for assurance. going forward I've only scratched the surface of the suggestions in Astapov's "full fledged HLedger" notes. I'm up to step 2 of 14. I'm expecting to return to it once the changes I've made have bedded in a little bit. I suppose I could anonymize and share the framework (Makefile etc) that I am using if anyone was interested. It would take some work, though, so I don't know when I'd get around to it.

  1. the rm latest bit is to clear up some state-tracking files that HLedger writes to avoid importing duplicate transactions. In this case, I know better than HLedger.

Antoine Beaupr : Picking a USB-C dock and charger

Dear lazy web, help me pick the right hardware to make my shiny new laptop work better. I want a new USB-C dock and travel power supply.

Background I need advice on hardware, because my current setup in the office doesn't work so well. My new Framework laptop has four (4!) USB-C ports which is great, but it only has those ports (there's a combo jack, but I don't use it because it's noisy). So right now I have the following setup:
  • HDMI: monitor one
  • HDMI: monitor two
  • USB-A: Yubikey
  • USB-C: USB-C hub, which has:
    • RJ-45 network
    • USB-A keyboard
    • USB-A mouse
    • USB-A headset
... and I'm missing a USB-C port for power! So I get into this annoying situation where I need to actually unplug the USB-A Yubikey, unplug the USB-A expansion card, plug in the power for a while so it can charge, and then do that in reverse when I need the Yubikey again (which is: often). Another option I have is to unplug the headset, but I often need both the headset and the Yubikey at once. I also have a pair of earbuds that work in the combo jack, but, again, they are noticeably noisy. So this doesn't work. I'm thinking I should get a USB-C Dock of some sort. The Framework forum has a long list of supported docks in a "megathread", but I figured people here might have their own experience with docks and laptop/dock setups. So what should USB-C Dock should I get? Should I consider changing to a big monitor with a built-in USB-C dock and power? Ideally, i'd like to just walk in the office, put the laptop down and insert a single USB-C cable and be done with it. Does that even work with Wayland? I have read reports of Displaylink not working in Sway specifically... does that apply to any multi-monitor over a single USB-C cable setup? Oh, and what about travel options? Do you have a fancy small form factor USB-C power charger that you really like?

Current ideas Here are the devices I'm considering right now...

USB chargers The spec here is at least 65W USB-C with international plugs. I particularly like the TOFU, but I am not sure it will deliver... I found that weird little thing through this Twitter post from Benedict Reuschling, from this blog post, from 2.5 admins episode 127 (phew!). Update: I ordered a TOFU power station today (2023-02-20). I'm a little concerned about the power output (45W instead of 65W for the Framework charger), but I suspect it will not actually be a problem while traveling, since the laptop will keep its charge during the day and will charge at night... The device shipped 3 days later, with an estimated delivery time of 12 to 15 days, so expect this thing to take its sweet time landing on your desk.

USB Docks Specification:
  • must have 2 or more USB-A ports (3 is ideal, otherwise i need a new headset adapter)
  • at least one USB-C port, preferably more
  • works in Linux
  • 2 display support (or one big monitor?), ideally 2x4k for future-proofing, HDMI or Display-Port, ideally also with double USB-C/Thunderbolt for future-proofing
  • all on one USB-C wire would be nice
  • power delivery over the USB-C cable
  • not too big, preferably
Note that I move from 4 USB-A ports down to 2 or 3 because I can change the USB-A cable on my keyboard for USB-C. But that means I need a slot for a USB-C port on the dock of course. I also could live with one less USB-A cable if I find a combo jack adapter, but that would mean a noisy experience. Options found so far:
  • ThinkPad universal dock/40ay0090us): 300$USD, 65-100W, combo jack, 3x USB3.1, 2x USB2.0, 1x USB-C, 2x Display Port, 1x HDMI Port, 1x Gigabit Ethernet
  • Caldigit docks are apparently good, and the USB-C HDMI Dock seems like a good candidate (not on sale in there Canada shop), but leaves me wondering whether I want to keep my old analog monitors around and instead get proper monitors with USB-C inputs, and use something like Thunderbolt Element hub (230$USD). Update: I wrote Caldigit and they don't seem to have any Dock that would work for me, they suggest the TS3 plus which only has a single DP connector (!?). The USB-C HDMI dock is actually discontinued and they mentioned that they do have trouble with Linux in general.
  • I was also recommended OWC docks as well. update: their website is a mess, and live chat has confirmed they do not actually have any device that fits the requirement of two HDMI/DP outputs.
  • Anker also has docks (e.g. the Anker 568 USB-C Docking Station 11-in-1 looks nice, but holy moly 300$USD... Also, Anker docks are not all equal, I've heard reports of some of them being bad. Update: I reached out to Anker to clarify whether or not their docks will work on Linux and to advise on which dock to use, and their response is that they "do not recommend you use our items with Linux system". So I guess that settles it with Anker.
  • Cable Matters are promising, and their "USB-C Docking Station with Dual 4K HDMI and 80W Charging for Windows Computers might just actually work. It was out of stock on their website and Amazon but after reaching out to their support by email, they pointed out a product page that works in Canada.
Also: this post from Big Mess Of Wires has me worried that anything might work at all. It's where I had the Cable Matters reference however... Update: I ordered a this dock from Cable Matters from Amazon (reluctantly). It promises Linux support and checked all the boxes for me (4x USB-A, audio, network, 2xHDMI). It kind of works? I tested the USB-A ports, charging, networking, and the HDMI ports, all worked the first time. But! When I disconnect and reconnect the hub, the HDMI ports stop working. It s quite infuriating especially since there s very little diagnostics available. It s unclear how the devices show up on my computer, I can t even tell what device provides the HDMI connectors in lsbusb. I ve also seen the USB keyboard drop keypresses, which is also ... not fun. I suspect foul play inside Sway. And yeah, those things are costly! This one goes for 300$ a pop, not great. Update 2: Cable Matters support responded by simply giving me this hack that solved it at least for now. Just reverse the USB-C cable, and poof, everything works. Magic.

Your turn! So what's your desktop setup like? Do you have docks? a laptop? a desktop? did you build it yourself? Did you solder a USB-C port in the back of your neck and interface directly with the matrix and there's no spoon? Do you have a 4k monitor? Two? A 8k monitor that curves around your head in a fully immersive display? Do you work on a Occulus rift and only interface the world through 3d virtual reality, including terminal emulators? Thanks in advance!

Reproducible Builds (diffoscope): diffoscope 235 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 235. This version includes the following changes:
[ Akihiro Suda ]
* Update .gitlab-ci.yml to push versioned tags to the container registry.
  (Closes: reproducible-builds/diffoscope!119)
[ Chris Lamb ]
* Fix compatibility with PyPDF2. (Closes: reproducible-builds/diffoscope#331)
* Fix compatibility with ImageMagick 7.1.
  (Closes: reproducible-builds/diffoscope#330)
[ Daniel Kahn Gillmor ]
* Update from PyPDF2 to pypdf. (Closes: #1029741, #1029742)
[ FC Stegerman ]
* Add support for Android resources.arsc files.
  (Closes: reproducible-builds/diffoscope!116)
* Add support for dexdump. (Closes: reproducible-builds/diffoscope#134)
* Improve DexFile's FILE_TYPE_RE and add FILE_TYPE_HEADER_PREFIX, and remove
  "Dalvik dex file" from ApkFile's FILE_TYPE_RE as well.
[ Efraim Flashner ]
* Update external tool for isoinfo on guix.
  (Closes: reproducible-builds/diffoscope!124)
You find out more by visiting the project homepage.

9 February 2023

Sam Hartman: Building Carthage with Carthage

This is the second in a series of blog posts introducing Carthage, an Infrastructure as Code framework I ve been working on the last four years. In this post we ll talk about how we use Carthage to build the Carthage container images. We absolutely could have just used a Containerfile to do this; in fact I recently removed a hybrid solution that produced an artifact and then used a Containerfile to turn it into an OCI image. The biggest reason we don t use a Containerfile is that we want to be able to reuse the same infrastructure (installed software and configuration) across multiple environments. For example CarthageServerRole, a reusable Carthage component that install Carthage itself is used in several places:
  1. on raw hardware when we re using Carthage to drive a hypervisor
  2. As part of image building pipelines to build AMIs for Amazon Web Services
  3. Installed onto AWS instances built from the Debian AMI where we cannot use custom AMIs
  4. Installed onto KVM VMs
  5. As part of building the Carthage container images
So the biggest thing Carthage gives us is uniformity in how we set up infrastructure. We ve found a number of disadvantages of Containerfiles as well:
  1. Containerfiles mix the disadvantages of imperative and declarative formats. Like a declarative format they have no explicit control logic. It seems like that would be good for introspecting and reasoning about Containers. But all you get is the base image and a set of commands to build a container. For reasoning about common things like whether a container has a particular vulnerability or can be distributed under a particular license, that s not very useful. So we don t get much valuable introspection out of the declarative aspects, and all too often we see Containerfiles generated by Makefiles or other multi-level build-systems to get more logic or control flow.
  2. Containerfiles have limited facility for doing things outside the container. The disadvantage of this is that you end up installing all the software you need to build the container into the container itself (or having a multi-level build system). But for example if I want to use Ansible to configure a container, the easiest way to do that is to actually install Ansible into the container itself, even though Ansible has a large dependency chain most of which we won t need in the container. Yes, Ansible does have a number of connection methods including one for Buildah, but by the point you re using that, you re already using a multi-level build system and aren t really just using a Containerfile.
Okay, so since we re not going to just use a Containerfile, what do we do instead? We produce a CarthageLayout. A CarthageLayout is an object in the Carthage modeling language. The modeling language looks a lot like Python in fact it s even implemented using Python metaclasses and uses the Python parser. However, there are some key semantic differences and it may help to think of the modeling language as its own thing. Carthage layouts are typically contained in Carthage plugins. For example, the oci_images plugin is our focus today. Most of the work in that plugin is in layout.py, and the layout begins here:
class layout(CarthageLayout):
    add_provider(ConfigLayout)
    add_provider(carthage.ansible.ansible_log, str(_dir/"ansible.log"))
The add_provider calls are special, and we ll discuss them in a future post. For now, think of them as assignments in a more complex namespace than simple identifiers. But the heart of this layout is the CarthageImage class:
    class CarthageImage(PodmanImageModel, carthage_base.CarthageServerRole):
        base_image = injector_access('from_scratch_debian')
        oci_image_tag = 'localhost/carthage:latest'
        oci_image_command = ['/bin/systemd']
Most of the work of our image is done by inheritance. We inherit from the CarthageServerRole from the carthage_base plugin collection. A role is a reusable set of infrastructure that can be attached directly to a MachineModel. By inheriting from this role, we request the installation of the Carthage software. The role also supports copying in various dependencies; for example when Carthage is used to manage a cluster of machines, the layout corresponding to the cluster can automatically be copied to all nodes in the cluster. We do not need this feature to build the container image. The CarthageImage class sets its base image. Currently we are using our own base Debian image that we build with debootstrap and then import as a container image. In the fairly near future, we ll change that to:
        base_image =  debian:bookworm 
That will simply use the Debian image from Dockerhub. We are building our own base image for historical reasons and need to confirm that everything works before switching over. By setting oci_image_tag we specify where in the local images the resulting image will be stored. We also specify that this image boots systemd. We actually do want to do a bit of work on top of CarthageServerRole specific to the container image. To do that we use a Carthage feature called a Customization. There are various types of customization. For example MachineCustomization runs a set of tasks on a Machine that is booted and on the network. When building images, the most common type of customization is a FilesystemCustomization. For these, we have access to the filesystem, and we have some way of running a command in the context of the filesystem. We don t boot the filesystem as a machine unless we need to. (We might if the filesystem is a kvm VM or AWS instance for example). Carthage collects all the customizations in a role or image model. In the case of container image classes like PodmanImageModel, each customization is applied as an individual layer in the resulting container image. Roles and customizations are both reusable infrastructure. Roles typically contain customizations. Roles operate at the modeling layer; you might introspect a machine s model or an image s model to see what functionality (roles) it provides. In contrast, customizations operate at the implementation layer. They do specific things like move files around, apply Ansible roles or similar. Let s take a look at the customization applied for the Carthage container image (full code):

        class customize_for_oci(FilesystemCustomization):

            @setup_task("Remove Software")
            async def remove_software(self):
                await self.run_command("apt", "-y", "purge",
                                       "exim4-base",
                                       )

            @setup_task("Install service")
            async def install_service(self):
               # installs and activates a systemd unit
Then to pull it all together, we simply run the layout:
sudo PYTHONPATH=$(pwd) python3 ./bin/carthage-runner ./oci_images build
In the next post, we will dig more into how to make infrastructure reusable.

comment count unavailable comments

8 February 2023

Chris Lamb: Most anticipated films of 2023

Very few highly-anticipated movies appear in January and February, as the bigger releases are timed so they can be considered for the Golden Globes in January and the Oscars in late February or early March, so film fans have the advantage of a few weeks after the New Year to collect their thoughts on the year ahead. In other words, I'm not actually late in outlining below the films I'm most looking forward to in 2023...

Barbie No, seriously! If anyone can make a good film about a doll franchise, it's probably Greta Gerwig. Not only was Little Women (2019) more than admirable, the same could be definitely said for Lady Bird (2017). More importantly, I can't help feel she was the real 'Driver' behind Frances Ha (2012), one of the better modern takes on Claudia Weill's revelatory Girlfriends (1978). Still, whenever I remember that Barbie will be a film about a billion-dollar toy and media franchise with a nettlesome history, I recall I rubbished the "Facebook film" that turned into The Social Network (2010). Anyway, the trailer for Barbie is worth watching, if only because it seems like a parody of itself.

Blitz It's difficult to overstate just how important the aerial bombing of London during World War II is crucial to understanding the British psyche, despite it being a constructed phenomenon from the outset. Without wishing to underplay the deaths of over 40,000 civilian deaths, Angus Calder pointed out in the 1990s that the modern mythology surrounding the event "did not evolve spontaneously; it was a propaganda construct directed as much at [then neutral] American opinion as at British." It will therefore be interesting to see how British Grenadian Trinidadian director Steve McQueen addresses a topic so essential to the British self-conception. (Remember the controversy in right-wing circles about the sole Indian soldier in Christopher Nolan's Dunkirk (2017)?) McQueen is perhaps best known for his 12 Years a Slave (2013), but he recently directed a six-part film anthology for the BBC which addressed the realities of post-Empire immigration to Britain, and this leads me to suspect he sees the Blitz and its surrounding mythology with a more critical perspective. But any attempt to complicate the story of World War II will be vigorously opposed in a way that will make the recent hullabaloo surrounding The Crown seem tame. All this is to say that the discourse surrounding this release may be as interesting as the film itself.

Dune, Part II Coming out of the cinema after the first part of Denis Vileneve's adaptation of Dune (2021), I was struck by the conception that it was less of a fresh adaptation of the 1965 novel by Frank Herbert than an attempt to rehabilitate David Lynch's 1984 version and in a broader sense, it was also an attempt to reestablish the primacy of cinema over streaming TV and the myriad of other distractions in our lives. I must admit I'm not a huge fan of the original novel, finding within it a certain prurience regarding hereditary military regimes and writing about them with a certain sense of glee that belies a secret admiration for them... not to mention an eyebrow-raising allegory for the Middle East. Still, Dune, Part II is going to be a fantastic spectacle.

Ferrari It'll be curious to see how this differs substantially from the recent Ford v Ferrari (2019), but given that Michael Mann's Heat (1995) so effectively re-energised the gangster/heist genre, I'm more than willing to kick the tires of this about the founder of the eponymous car manufacturer. I'm in the minority for preferring Mann's Thief (1981) over Heat, in part because the former deals in more abstract themes, so I'd have perhaps prefered to look forward to a more conceptual film from Mann over a story about one specific guy.

How Do You Live There are a few directors one can look forward to watching almost without qualification, and Hayao Miyazaki (My Neighbor Totoro, Kiki's Delivery Service, Princess Mononoke Howl's Moving Castle, etc.) is one of them. And this is especially so given that The Wind Rises (2013) was meant to be the last collaboration between Miyazaki and Studio Ghibli. Let's hope he is able to come out of retirement in another ten years.

Indiana Jones and the Dial of Destiny Given I had a strong dislike of Indiana Jones and the Kingdom of the Crystal Skull (2008), I seriously doubt I will enjoy anything this film has to show me, but with 1981's Raiders of the Lost Ark remaining one of my most treasured films (read my brief homage), I still feel a strong sense of obligation towards the Indiana Jones name, despite it feeling like the copper is being pulled out of the walls of this franchise today.

Kafka I only know Polish filmmaker Agnieszka Holland through her Spoor (2017), an adaptation of Olga Tokarczuk's 2009 eco-crime novel Drive Your Plow Over the Bones of the Dead. I wasn't an unqualified fan of Spoor (nor the book on which it is based), but I am interested in Holland's take on the life of Czech author Franz Kafka, an author enmeshed with twentieth-century art and philosophy, especially that of central Europe. Holland has mentioned she intends to tell the story "as a kind of collage," and I can hope that it is an adventurous take on the over-furrowed biopic genre. Or perhaps Gregor Samsa will awake from uneasy dreams to find himself transformed in his bed into a huge verminous biopic.

The Killer It'll be interesting to see what path David Fincher is taking today, especially after his puzzling and strangely cold Mank (2020) portraying the writing process behind Orson Welles' Citizen Kane (1941). The Killer is said to be a straight-to-Netflix thriller based on the graphic novel about a hired assassin, which makes me think of Fincher's Zodiac (2007), and, of course, Se7en (1995). I'm not as entranced by Fincher as I used to be, but any film with Michael Fassbender and Tilda Swinton (with a score by Trent Reznor) is always going to get my attention.

Killers of the Flower Moon In Killers of the Flower Moon, Martin Scorsese directs an adaptation of a book about the FBI's investigation into a conspiracy to murder Osage tribe members in the early years of the twentieth century in order to deprive them of their oil-rich land. (The only thing more quintessentially American than apple pie is a conspiracy combined with a genocide.) Separate from learning more about this disquieting chapter of American history, I'd love to discover what attracted Scorsese to this particular story: he's one of the few top-level directors who have the ability to lucidly articulate their intentions and motivations.

Napoleon It often strikes me that, despite all of his achievements and fame, it's somehow still possible to claim that Ridley Scott is relatively underrated compared to other directors working at the top level today. Besides that, though, I'm especially interested in this film, not least of all because I just read Tolstoy's War and Peace (read my recent review) and am working my way through the mind-boggling 431-minute Soviet TV adaptation, but also because several auteur filmmakers (including Stanley Kubrick) have tried to make a Napoleon epic and failed.

Oppenheimer In a way, a biopic about the scientist responsible for the atomic bomb and the Manhattan Project seems almost perfect material for Christopher Nolan. He can certainly rely on stars to queue up to be in his movies (Robert Downey Jr., Matt Damon, Kenneth Branagh, etc.), but whilst I'm certain it will be entertaining on many fronts, I fear it will fall into the well-established Nolan mould of yet another single man struggling with obsession, deception and guilt who is trying in vain to balance order and chaos in the world.

The Way of the Wind Marked by philosophical and spiritual overtones, all of Terrence Malick's films are perfumed with themes of transcendence, nature and the inevitable conflict between instinct and reason. My particular favourite is his stunning Days of Heaven (1978), but The Thin Red Line (1998) and A Hidden Life (2019) also touched me ways difficult to relate, and are one of the few films about the Second World War that don't touch off my sensitivity about them (see my remarks about Blitz above). It is therefore somewhat Malickian that his next film will be a biblical drama about the life of Jesus. Given Malick's filmography, I suspect this will be far more subdued than William Wyler's 1959 Ben-Hur and significantly more equivocal in its conviction compared to Paolo Pasolini's ardently progressive The Gospel According to St. Matthew (1964). However, little beyond that can be guessed, and the film may not even appear until 2024 or even 2025.

Zone of Interest I was mesmerised by Jonathan Glazer's Under the Skin (2013), and there is much to admire in his borderline 'revisionist gangster' film Sexy Beast (2000), so I will definitely be on the lookout for this one. The only thing making me hesitate is that Zone of Interest is based on a book by Martin Amis about a romance set inside the Auschwitz concentration camp. I haven't read the book, but Amis has something of a history in his grappling with the history of the twentieth century, and he seems to do it in a way that never sits right with me. But if Paul Verhoeven's Starship Troopers (1997) proves anything at all, it's all in the adaption.

Stephan Lachnit: Setting up fast Debian package builds using sbuild, mmdebstrap and apt-cacher-ng

In this post I will give a quick tutorial on how to set up fast Debian package builds using sbuild with mmdebstrap and apt-cacher-ng. The usual tool for building Debian packages is dpkg-buildpackage, or a user-friendly wrapper like debuild, and while these are geat tools, if you want to upload something to the Debian archive they lack the required separation from the system they are run on to ensure that your packaging also works on a different system. The usual candidate here is sbuild. But setting up a schroot is tedious and performance tuning can be annoying. There is an alternative backend for sbuild that promises to make everything simpler: unshare. In this tutorial I will show you how to set up sbuild with this backend. Additionally to the normal performance tweaking, caching downloaded packages can be a huge performance increase when rebuilding packages. I do rebuilds quite often, mostly when a new dependency got introduced I didn t specify in debian/control yet or lintian notices a something I can easily fix. So let s begin with setting up this caching.

Setting up apt-cacher-ng Install apt-cacher-ng:
sudo apt install apt-cacher-ng
A pop-up will appear, if you are unsure how to answer it select no, we don t need it for this use-case. To enable apt-cacher-ng on your system, create /etc/apt/apt.conf.d/02proxy and insert:
Acquire::http::proxy "http://127.0.0.1:3142";
Acquire::https::proxy "DIRECT";
In /etc/apt-cacher-ng/acng.conf you can increase the value of ExThreshold to hold packages for a shorter or longer duration. The length depends on your specific use case and resources. A longer threshold takes more disk space, a short threshold like one day effecitvely only reduces the build time for rebuilds. If you encounter weird issues on apt update at some point the future, you can try to clean the cache from apt-cacher-ng. You can use this script:

Setting up mmdebstrap Install mmdebstrap:
sudo apt install mmdebstrap
We will create a small helper script to ease creating a chroot. Open ~/.local/bin/mmupdate and insert:
#!/bin/sh
mmdebstrap \
  --variant=buildd \
  --aptopt='Acquire::http::proxy "http://127.0.0.1:3142";' \
  --arch=amd64 \
  --components=main,contrib,non-free \
  unstable \
  ~/.cache/sbuild/unstable-amd64.tar.xz \
  http://deb.debian.org/debian
Notes:
  • aptopt enables apt-cacher-ng inside the chroot.
  • --arch sets the CPU architecture (see Debian Wiki).
  • --components sets the archive components, if you don t want non-free pacakges you might want to remove some entries here.
  • unstable sets the Debian release, you can also set for example bookworm-backports here.
  • unstable-amd64.tar.xz is the output tarball containing the chroot, change accordingly to your pick of the CPU architecture and Debian release.
  • http://deb.debian.org/debian is the Debian mirror, you should set this to the same one you use in your /etc.apt/sources.list.
Make mmupdate executable and run it once:
chmod +x ~/.local/bin/mmupdate
mkdir -p ~/.cache/sbuild
~/.local/bin/mmupdate
If you execute mmupdate again you can see that the downloading stage is much faster thanks to apt-cacher-ng. For me the difference is from about 115s to about 95s. Your results may vary, this depends on the speed of your internet, Debian mirror and disk. If you have used the schroot backend and sbuild-update before, you probably notice that creating a new chroot with mmdebstrap is slower. It would be a bit annoying to do this manually before we start a new Debian packaging session, so let s create a systemd service that does this for us. First create a folder for user services:
mkdir -p ~/.config/systemd/user
Create ~/.config/systemd/user/mmupdate.service and add:
[Unit]
Description=Run mmupdate
Wants=network-online.target
[Service]
Type=oneshot
ExecStart=%h/.local/bin/mmupdate
Start the service and test that it works:
systemctl --user daemon-reload
systemctl --user start mmupdate
systemctl --user status mmupdate
Create ~/.config/systemd/user/mmupdate.timer:
[Unit]
Description=Run mmupdate daily
[Timer]
OnCalendar=daily
Persistent=true
[Install]
WantedBy=timers.target
Enable the timer:
systemctl --user enable mmupdate.timer
Now every day mmupdte will be run automatically. You can adjust the period if you think daily rebuilds are a bit excessive. A neat advantage of period rebuilds is that they the base files in your apt-cacher-ng cache warm every time they run.

Setting up sbuild: Install sbuild and (optionally) autopkgtest:
sudo apt install --no-install-recommends sbuild autopkgtest
Create ~/.sbuildrc and insert:
# backend for using mmdebstrap chroots
$chroot_mode = 'unshare';
# build in tmpfs
$unshare_tmpdir_template = '/dev/shm/tmp.sbuild.XXXXXXXX';
# upgrade before starting build
$apt_update = 1;
$apt_upgrade = 1;
# build everything including source for source-only uploads
$build_arch_all = 1;
$build_arch_any = 1;
$build_source = 1;
$source_only_changes = 1;
# go to shell on failure instead of exiting
$external_commands =   "build-failed-commands" => [ [ '%SBUILD_SHELL' ] ]  ;
# always clean build dir, even on failure
$purge_build_directory = "always";
# run lintian
$run_lintian = 1;
$lintian_opts = [ '-i', '-I', '-E', '--pedantic' ];
# do not run piuparts
$run_piuparts = 0;
# run autopkgtest
$run_autopkgtest = 1;
$autopkgtest_root_args = '';
$autopkgtest_opts = [ '--apt-upgrade', '--', 'unshare', '--release', '%r', '--arch', '%a', '--prefix=/dev/shm/tmp.autopkgtest.' ];
# set uploader for correct signing
$uploader_name = 'Stephan Lachnit <stephanlachnit@debian.org>';
You should adjust uploader_name. If you don t want to run autopkgtest or lintian by default you can also disable it here. Note that for packages that need a lot of space for building, you might want to comment the unshare_tmpdir_template line to prevent a OOM build failure. You can now build your Debian packages with the sbuild command :)

Finishing touches You can add these variables to your ~/.bashrc as bonus (with adjusted name / email):
export DEBFULLNAME="<your_name>"
export DEBEMAIL="<your_email>"
export DEB_BUILD_OPTIONS="parallel=<threads>"
In particular adjust the value of parallel to ensure parallel builds. If you are new to signing / uploading your package, first install the required tools:
sudo apt install devscripts dput-ng
Create ~/.devscripts and insert:
DEBSIGN_KEYID=<your_gpg_fingerpring>
USCAN_SYMLINK=rename
You can now sign the .changes file with:
debsign ../<pkgname_version_arch>.changes
And for source-only uploads with:
debsign -S ../<pkgname_version_arch>_source.changes
If you don t introduce a new binary package, you always want to go with source-only changes. You can now upload the package to Debian with
dput ../<filename>.changes

Update Feburary 22nd Jochen Sprickerhof, who originally advised me to use the unshare backend, commented that one can also use --include=auto-apt-proxy instead of the --aptopt option in mmdebstrap to detect apt proxies automatically. He also let me know that it is possible to use autopkgtest on tmpfs (config in the blog post is updated) and added an entry on the sbuild wiki page on how to setup sbuild+unshare with ccache if you often need to build a large package. Further, using --variant=apt and --include=build-essential will produce smaller build chroots if wished. On the contrary, one can of course also use the --include option to include debhelper and lintian (or any other packages you like) to further decrease the setup time. However, staying with buildd variant is a good choice for official uploads.

Resources for further reading https://wiki.debian.org/sbuild
https://www.unix-ag.uni-kl.de/~bloch/acng/html/index.html
https://wiki.ubuntu.com/SimpleSbuild
https://wiki.archlinux.org/title/Systemd/Timers
https://manpages.debian.org/unstable/autopkgtest/autopkgtest-virt-unshare.1.en.html
Thanks for reading!

Antoine Beaupr : Major outage with Oricom uplink

The server that normally serves this page, all my email, and many more services was unavailable for about 24 hours. This post explains how and why.

What happened? Starting February 2nd, I started seeing intermittent packet loss on the network. Every hour or so, the link would go down for one or two minutes, then come back up. At first, I didn't think much of it because I was away and could blame the crappy wifi or the uplink I using. But when I came in the office on Monday, the service was indeed seriously degraded. I could barely do videoconferencing calls as they would cut out after about half an hour. I opened a ticket with my uplink, Oricom. They replied that it was an issue they couldn't fix on their end and would need someone on site to fix. So, the next day (Tuesday, at around 10EST) I called Oricom again, and they made me do a full modem reset, which involves plugging a pin in a hole for 15 seconds on the Technicolor TC4400 cable modem. Then the link went down, and it didn't come back up at all. Boom. Oricom then escalated this to their upstream (Oricom is a reseller of Videotron, who has basically the monopoly on cable in Qu bec) which dispatched a tech. This tech, in turn, arrived some time after lunch and said the link worked fine and it was a hardware issue. At this point, Oricom put a new modem in the mail and I started mitigation.

Mitigation

Website The first thing I did, weirdly, was trying to rebuild this blog. I figured it should be pretty simple: install ikiwiki and hit rebuild. I knew I had some patches on ikiwiki to deploy, but surely those are not a deal breaker, right? Nope. Turns out I wrote many plugins and those still don't ship with ikiwiki, despite having been sent upstream a while back, some years ago. So I deployed the plugins inside the .ikiwiki directory of the site in the hope of making things a little more "standalone". Unfortunately, that didn't work either because the theme must be shipped in the system-wide location: I couldn't figure out how to put it to have it bundled with the main repository. At that point I mostly gave up because I had spent too much time on this and I had to do something about email otherwise it would start to bounce.

Email So I made a new VM at Linode (thanks 2.5admins for the credits) to build a new mail server. This wasn't the best idea, in retrospect, because it was really overkill: I started rebuilding the whole mail server from scratch. Ideally, this would be in Puppet and I would just deploy the right profile and the server would be rebuilt. Unfortunately, that part of my infrastructure is not Puppetized and even if it would, well the Puppet server was also down so I would have had to bring that up first. At first, I figured I would just make a secondary mail exchanger (MX), to spool mail for longer so that I wouldn't lose it. But I decided against that: I thought it was too hard to make a "proper" MX as it needs to also filter mail while avoiding backscatter. Might as well just build a whole new server! I had a copy of my full mail spool on my laptop, so I figured that was possible. I mostly got this right: added a DKIM key, installed Postfix, Dovecot, OpenDKIM, OpenDMARC, glue it all together, and voil , I had a mail server. Oh, and spampd. Oh, and I need the training data, oh, and this and... I wasn't done and it was time to sleep. The mail server went online this morning, and started accepting mail. I tried syncing my laptop mail spool against it, but that failed because Dovecot generated new UIDs for the emails, and isync correctly failed to sync. I tried to copy the UIDs from the server in the office (which I had still access to locally), but that somehow didn't work either. But at least the mail was getting delivered and stored properly. I even had the Sieve rules setup so it would get sorted properly too. Unfortunately, I didn't hook that up properly, so those didn't actually get sorted. Thankfully, Dovecot can re-filter emails with the sieve-filter command, so that was fixed later. At this point, I started looking for other things to fix.

Web, again I figured I was almost done with the website, might as well publish it. So I installed the Nginx Debian package, got a cert with certbot, and added the certs to the default configuration. I rsync'd my build in /var/www/html and boom, I had a website. The Goatcounter analytics were timing out, but that was easy to turn off.

Resolution Almost at that exact moment, a bang on the door told me mail was here and I had the modem. I plugged it in and a few minutes later, marcos was back online. So this was a lot (a lot!) of work for basically nothing. I could have just taken the day off and wait for the package to be delivered. It would definitely have been better to make a simpler mail exchanger to spool the mail to avoid losing it. And in fact, that's what I eventually ended up doing: I converted the linode server in a mail relay to continue accepting mail with DNS propagates, but without having to sort the mail out of there... Right now I have about 200 mails in a mailbox that I need to move back into marcos. Normally, this would just be a simple rsync, but because both servers have accepted mail simultaneously, it's going to be simpler to just move those exact mails on there. Because dovecot helpfully names delivered files with the hostname it's running on, it's easy to find those files and transfer them, basically:
rsync -v -n --files-from=<(ssh colette.anarc.at find Maildir -name '*colette*' ) colette.anarc.at: colette/
rsync -v -n --files-from=<(ssh colette.anarc.at find Maildir -name '*colette*' ) colette/ marcos.anarc.at:
Overall, the outage lasted about 24 hours, from 11:00EST (16:00UTC) on 2023-02-07 to the same time today.

Future work I'll probably keep a mail relay to make those situations more manageable in the future. At first I thought that mail filtering would be a problem, but that happens post queue anyways and I don't bounce mail based on Spamassassin, so back-scatter shouldn't be an issue. I basically need Postfix, OpenDMARC, and Postgrey. I'm not even sure I need OpenDKIM as the server won't process outgoing mail, so it doesn't need to sign anything, just check incoming signatures, which OpenDMARC can (probably?) do. Thanks to everyone who supported me through this ordeal, you know who you are (and I'm happy to give credit here if you want to be deanonymized)!

7 February 2023

Stephan Lachnit: Installing Debian on F2FS rootfs with deboostrap and systemd-boot

I recently got a new NVME drive. My plan was to create a fresh Debian install on an F2FS root partition with compression for maximum performance. As it turns out, this is not entirely trivil to accomplish. For one, the Debian installer does not support F2FS (here is my attempt to add it from 2021). And even if it did, grub does not support F2FS with the extra_attr flag that is required for compression support (at least as of grub 2.06). Luckily, we can install Debian anyway with all these these shiny new features when we go the manual road with debootstrap and using systemd-boot as bootloader. We can break down the process into several steps:
  1. Creating the partition table
  2. Creating and mounting the root partition
  3. Bootstrapping with debootstrap
  4. Chrooting into the system
  5. Configure the base system
  6. Define static file system information
  7. Installing the kernel and bootloader
  8. Finishing touches
Warning: Playing around with partitions can easily result in data if you mess up! Make sure to double check your commands and create a data backup if you don t feel confident about the process.

Creating the partition partble The first step is to create the GPT partition table on the new drive. There are several tools to do this, I recommend the ArchWiki page on this topic for details. For simplicity I just went with the GParted since it has an easy GUI, but feel free to use any other tool. The layout should look like this:
Type         Partition        Suggested size
 
EFI          /dev/nvme0n1p1           512MiB
Linux swap   /dev/nvme0n1p2             1GiB
Linux fs     /dev/nvme0n1p3        remainder
Notes:
  • The disk names are just an example and have to be adjusted for your system.
  • Don t set disk labels, they don t appear on the new install anyway and some UEFIs might not like it on your boot partition.
  • The size of the EFI partition can be smaller, in practive it s unlikely that you need more than 300 MiB. However some UEFIs might be buggy and if you ever want to install an additional kernel or something like memtest86+ you will be happy to have the extra space.
  • The swap partition can be omitted, it is not strictly needed. If you need more swap for some reason you can also add more using a swap file later (see ArchWiki page). If you know you want to use suspend-to-RAM, you want to increase the size to something more than the size of your memory.
  • If you used GParted, create the EFI partition as FAT32 and set the esp flag. For the root partition use ext4 or F2FS if available.

Creating and mounting the root partition To create the root partition, we need to install the f2fs-tools first:
sudo apt install f2fs-tools
Now we can create the file system with the correct flags:
mkfs.f2fs -O extra_attr,inode_checksum,sb_checksum,compression,encrypt /dev/nvme0n1p3
For details on the flags visit the ArchWiki page. Next, we need to mount the partition with the correct flags. First, create a working directory:
mkdir boostrap
cd boostrap
mkdir root
export DFS=$(pwd)/root
Then we can mount the partition:
sudo mount -o compress_algorithm=zstd:6,compress_chksum,atgc,gc_merge,lazytime /dev/nvme0n1p3 $DFS
Again, for details on the mount options visit the above mentioned ArchWiki page.

Bootstrapping with debootstrap First we need to install the debootstrap package:
sudo apt install debootstrap
Now we can do the bootstrapping:
debootstrap --arch=amd64 --components=main,contrib,non-free,non-free-firmware unstable $DFS http://deb.debian.org/debian
Notes:
  • --arch sets the CPU architecture (see Debian Wiki).
  • --components sets the archive components, if you don t want non-free pacakges you might want to remove some entries here.
  • unstable is the Debian release, you might want to change that to testing or bookworm.
  • $DFS points to the mounting point of the root partition.
  • http://deb.debian.org/debian is the Debian mirror, you might want to set that to http://ftp.de.debian.org/debian or similar if you have a fast mirror in you area.

Chrooting into the system Before we can chroot into the newly created system, we need to prepare and mount virtual kernel file systems. First create the directories:
sudo mkdir -p $DFS/dev $DFS/dev/pts $DFS/proc $DFS/sys $DFS/run $DFS/sys/firmware/efi/efivars $DFS/boot/efi
Then bind-mount the directories from your system to the mount point of the new system:
sudo mount -v -B /dev $DFS/dev
sudo mount -v -B /dev/pts $DFS/dev/pts
sudo mount -v -B /proc $DFS/proc
sudo mount -v -B /sys $DFS/sys
sudo mount -v -B /run $DFS/run
sudo mount -v -B /sys/firmware/efi/efivars $DFS/sys/firmware/efi/efivars
As a last step, we need to mount the EFI partition:
sudo mount -v -B /dev/nvme0n1p1 $DFS/boot/efi
Now we can chroot into new system:
sudo chroot $DFS /bin/bash

Configure the base system The first step in the chroot is setting the locales. We need this since we might leak the locales from our base system into the chroot and if this happens we get a lot of annoying warnings.
export LC_ALL=C.UTF-8 LANG=C.UTF-8
apt install locales console-setup
Set your locales:
dpkg-reconfigure locales
Set your keyboard layout:
dpkg-reconfigure keyboard-configuration
Set your timezone:
dpkg-reconfigure tzdata
Now you have a fully functional Debian chroot! However, it is not bootable yet, so let s fix that.

Define static file system information The first step is to make sure the system mounts all partitions on startup with the correct mount flags. This is done in /etc/fstab (see ArchWiki page). Open the file and change its content to:
# file system                               mount point   type   options                                                            dump   pass
# NVME efi partition
UUID=XXXX-XXXX                              /boot/efi     vfat   umask=0077                                                         0      0
# NVME swap
UUID=XXXXXXXX-XXXX-XXXX-XXXX-XXXXXXXXXXXX   none          swap   sw                                                                 0      0
# NVME main partition
UUID=XXXXXXXX-XXXX-XXXX-XXXX-XXXXXXXXXXXX   /             f2fs   compress_algorithm=zstd:6,compress_chksum,atgc,gc_merge,lazytime   0      1
You need to fill in the UUIDs for the partitions. You can use
ls -lAph /dev/disk/by-uuid/
to match the UUIDs to the more readable disk name under /dev.

Installing the kernel and bootloader First install the systemd-boot and efibootmgr packages:
apt install systemd-boot efibootmgr
Now we can install the bootloader:
bootctl install --path=/boot/efi
You can verify the procedure worked with
efibootmgr -v
The next step is to install the kernel, you can find a fitting image with:
apt search linux-image-*
In my case:
apt install linux-image-amd64
After the installation of the kernel, apt will add an entry for systemd-boot automatically. Neat! However, since we are in a chroot the current settings are not bootable. The first reason is the boot partition, which will likely be the one from your current system. To change that, navigate to /boot/efi/loader/entries, it should contain one config file. When you open this file, it should look something like this:
title      Debian GNU/Linux bookworm/sid
version    6.1.0-3-amd64
machine-id 2967cafb6420ce7a2b99030163e2ee6a
sort-key   debian
options    root=PARTUUID=f81d4fae-7dec-11d0-a765-00a0c91e6bf6 ro systemd.machine_id=2967cafb6420ce7a2b99030163e2ee6a
linux      /2967cafb6420ce7a2b99030163e2ee6a/6.1.0-3-amd64/linux
initrd     /2967cafb6420ce7a2b99030163e2ee6a/6.1.0-3-amd64/initrd.img-6.1.0-3-amd64
The PARTUUID needs to point to the partition equivalent to /dev/nvme0n1p3 on your system. You can use
ls -lAph /dev/disk/by-partuuid/
to match the PARTUUIDs to the more readable disk name under /dev. The second problem is the ro flag in options which tell the kernel to boot in read-only mode. The default is rw, so you can just remove the ro flag. Once this is fixed, the new system should be bootable. You can change the boot order with:
efibootmgr --bootorder
However, before we reboot we might add well add a user and install some basic software.

Finishing touches Add a user:
useradd -m -G sudo -s /usr/bin/bash -c 'Full Name' username
Debian provides a TUI to install Desktop Environment. To open it, run:
tasksel
Now you can finally reboot into your new system:
reboot

Resources for further reading https://ivanb.neocities.org/blogs/y2022/debootstrap
https://www.debian.org/releases/stable/amd64/apds03.en.html
https://www.addictivetips.com/ubuntu-linux-tips/set-up-systemd-boot-on-arch-linux/
https://p5r.uk/blog/2020/using-systemd-boot-on-debian-bullseye.html
https://www.linuxfromscratch.org/lfs/view/stable/chapter07/kernfs.html
Thanks for reading!

6 February 2023

Vincent Bernat: Fast and dynamic encoding of Protocol Buffers in Go

Protocol Buffers are a popular choice for serializing structured data due to their compact size, fast processing speed, language independence, and compatibility. There exist other alternatives, including Cap n Proto, CBOR, and Avro. Usually, data structures are described in a proto definition file (.proto). The protoc compiler and a language-specific plugin convert it into code:
$ head flow-4.proto
syntax = "proto3";
package decoder;
option go_package = "akvorado/inlet/flow/decoder";
message FlowMessagev4  
  uint64 TimeReceived = 2;
  uint32 SequenceNum = 3;
  uint64 SamplingRate = 4;
  uint32 FlowDirection = 5;
$ protoc -I=. --plugin=protoc-gen-go --go_out=module=akvorado:. flow-4.proto
$ head inlet/flow/decoder/flow-4.pb.go
// Code generated by protoc-gen-go. DO NOT EDIT.
// versions:
//      protoc-gen-go v1.28.0
//      protoc        v3.21.12
// source: inlet/flow/data/schemas/flow-4.proto
package decoder
import (
        protoreflect "google.golang.org/protobuf/reflect/protoreflect"
Akvorado collects network flows using IPFIX or sFlow, decodes them with GoFlow2, encodes them to Protocol Buffers, and sends them to Kafka to be stored in a ClickHouse database. Collecting a new field, such as source and destination MAC addresses, requires modifications in multiple places, including the proto definition file and the ClickHouse migration code. Moreover, the cost is paid by all users.1 It would be nice to have an application-wide schema and let users enable or disable the fields they need. While the main goal is flexibility, we do not want to sacrifice performance. On this front, this is quite a success: when upgrading from 1.6.4 to 1.7.1, the decoding and encoding performance almost doubled!
goos: linux
goarch: amd64
pkg: akvorado/inlet/flow
cpu: AMD Ryzen 5 5600X 6-Core Processor
                              initial.txt                 final.txt               
                                 sec/op        sec/op     vs base                 
Netflow/with_encoding-12      12.963    2%   7.836    1%  -39.55% (p=0.000 n=10)
Sflow/with_encoding-12         19.37    1%   10.15    2%  -47.63% (p=0.000 n=10)

Faster Protocol Buffers encoding I use the following code to benchmark both the decoding and encoding process. Initially, the Decode() method is a thin layer above GoFlow2 producer and stores the decoded data into the in-memory structure generated by protoc. Later, some of the data will be encoded directly during flow decoding. This is why we measure both the decoding and the encoding.2
func BenchmarkDecodeEncodeSflow(b *testing.B)  
    r := reporter.NewMock(b)
    sdecoder := sflow.New(r)
    data := helpers.ReadPcapPayload(b,
        filepath.Join("decoder", "sflow", "testdata", "data-1140.pcap"))
    for _, withEncoding := range []bool true, false   
        title := map[bool]string 
            true:  "with encoding",
            false: "without encoding",
         [withEncoding]
        var got []*decoder.FlowMessage
        b.Run(title, func(b *testing.B)  
            for i := 0; i < b.N; i++  
                got = sdecoder.Decode(decoder.RawFlow 
                    Payload: data,
                    Source: net.ParseIP("127.0.0.1"),
                 )
                if withEncoding  
                    for _, flow := range got  
                        buf := []byte 
                        buf = protowire.AppendVarint(buf, uint64(proto.Size(flow)))
                        proto.MarshalOptions .MarshalAppend(buf, flow)


         )
     
 
The canonical Go implementation for Protocol Buffers, google.golang.org/protobuf is not the most efficient one. For a long time, people were relying on gogoprotobuf. However, the project is now deprecated. A good replacement is vtprotobuf.3
goos: linux
goarch: amd64
pkg: akvorado/inlet/flow
cpu: AMD Ryzen 5 5600X 6-Core Processor
                              initial.txt               bench-2.txt              
                                sec/op        sec/op     vs base                 
Netflow/with_encoding-12      12.96    2%   10.28    2%  -20.67% (p=0.000 n=10)
Netflow/without_encoding-12   8.935    2%   8.975    2%        ~ (p=0.143 n=10)
Sflow/with_encoding-12        19.37    1%   16.67    2%  -13.93% (p=0.000 n=10)
Sflow/without_encoding-12     14.62    3%   14.87    1%   +1.66% (p=0.007 n=10)

Dynamic Protocol Buffers encoding We have our baseline. Let s see how to encode our Protocol Buffers without a .proto file. The wire format is simple and rely a lot on variable-width integers. Variable-width integers, or varints, are an efficient way of encoding unsigned integers using a variable number of bytes, from one to ten, with small values using fewer bytes. They work by splitting integers into 7-bit payloads and using the 8th bit as a continuation indicator, set to 1 for all payloads except the last.
Variable-width integers encoding in Protocol Buffers: conversion of 150 to a varint
Variable-width integers encoding in Protocol Buffers
For our usage, we only need two types: variable-width integers and byte sequences. A byte sequence is encoded by prefixing it by its length as a varint. When a message is encoded, each key-value pair is turned into a record consisting of a field number, a wire type, and a payload. The field number and the wire type are encoded as a single variable-width integer called a tag.
Message encoded with Protocol Buffers: three varints, two sequences of bytes
Message encoded with Protocol Buffers
We use the following low-level functions to build the output buffer: Our schema abstraction contains the appropriate information to encode a message (ProtobufIndex) and to generate a proto definition file (fields starting with Protobuf):
type Column struct  
    Key       ColumnKey
    Name      string
    Disabled  bool
    // [ ]
    // For protobuf.
    ProtobufIndex    protowire.Number
    ProtobufType     protoreflect.Kind // Uint64Kind, Uint32Kind,  
    ProtobufEnum     map[int]string
    ProtobufEnumName string
    ProtobufRepeated bool
 
We have a few helper methods around the protowire functions to directly encode the fields while decoding the flows. They skip disabled fields or non-repeated fields already encoded. Here is an excerpt of the sFlow decoder:
sch.ProtobufAppendVarint(bf, schema.ColumnBytes, uint64(recordData.Base.Length))
sch.ProtobufAppendVarint(bf, schema.ColumnProto, uint64(recordData.Base.Protocol))
sch.ProtobufAppendVarint(bf, schema.ColumnSrcPort, uint64(recordData.Base.SrcPort))
sch.ProtobufAppendVarint(bf, schema.ColumnDstPort, uint64(recordData.Base.DstPort))
sch.ProtobufAppendVarint(bf, schema.ColumnEType, helpers.ETypeIPv4)
For fields that are required later in the pipeline, like source and destination addresses, they are stored unencoded in a separate structure:
type FlowMessage struct  
    TimeReceived uint64
    SamplingRate uint32
    // For exporter classifier
    ExporterAddress netip.Addr
    // For interface classifier
    InIf  uint32
    OutIf uint32
    // For geolocation or BMP
    SrcAddr netip.Addr
    DstAddr netip.Addr
    NextHop netip.Addr
    // Core component may override them
    SrcAS     uint32
    DstAS     uint32
    GotASPath bool
    // protobuf is the protobuf representation for the information not contained above.
    protobuf      []byte
    protobufSet   bitset.BitSet
 
The protobuf slice holds encoded data. It is initialized with a capacity of 500 bytes to avoid resizing during encoding. There is also some reserved room at the beginning to be able to encode the total size as a variable-width integer. Upon finalizing encoding, the remaining fields are added and the message length is prefixed:
func (schema *Schema) ProtobufMarshal(bf *FlowMessage) []byte  
    schema.ProtobufAppendVarint(bf, ColumnTimeReceived, bf.TimeReceived)
    schema.ProtobufAppendVarint(bf, ColumnSamplingRate, uint64(bf.SamplingRate))
    schema.ProtobufAppendIP(bf, ColumnExporterAddress, bf.ExporterAddress)
    schema.ProtobufAppendVarint(bf, ColumnSrcAS, uint64(bf.SrcAS))
    schema.ProtobufAppendVarint(bf, ColumnDstAS, uint64(bf.DstAS))
    schema.ProtobufAppendIP(bf, ColumnSrcAddr, bf.SrcAddr)
    schema.ProtobufAppendIP(bf, ColumnDstAddr, bf.DstAddr)
    // Add length and move it as a prefix
    end := len(bf.protobuf)
    payloadLen := end - maxSizeVarint
    bf.protobuf = protowire.AppendVarint(bf.protobuf, uint64(payloadLen))
    sizeLen := len(bf.protobuf) - end
    result := bf.protobuf[maxSizeVarint-sizeLen : end]
    copy(result, bf.protobuf[end:end+sizeLen])
    return result
 
Minimizing allocations is critical for maintaining encoding performance. The benchmark tests should be run with the -benchmem flag to monitor allocation numbers. Each allocation incurs an additional cost to the garbage collector. The Go profiler is a valuable tool for identifying areas of code that can be optimized:
$ go test -run=__nothing__ -bench=Netflow/with_encoding \
>         -benchmem -cpuprofile profile.out \
>         akvorado/inlet/flow
goos: linux
goarch: amd64
pkg: akvorado/inlet/flow
cpu: AMD Ryzen 5 5600X 6-Core Processor
Netflow/with_encoding-12             143953              7955 ns/op            8256 B/op        134 allocs/op
PASS
ok      akvorado/inlet/flow     1.418s
$ go tool pprof profile.out
File: flow.test
Type: cpu
Time: Feb 4, 2023 at 8:12pm (CET)
Duration: 1.41s, Total samples = 2.08s (147.96%)
Entering interactive mode (type "help" for commands, "o" for options)
(pprof) web
After using the internal schema instead of code generated from the proto definition file, the performance improved. However, this comparison is not entirely fair as less information is being decoded and previously GoFlow2 was decoding to its own structure, which was then copied to our own version.
goos: linux
goarch: amd64
pkg: akvorado/inlet/flow
cpu: AMD Ryzen 5 5600X 6-Core Processor
                              bench-2.txt                bench-3.txt              
                                 sec/op        sec/op     vs base                 
Netflow/with_encoding-12      10.284    2%   7.758    3%  -24.56% (p=0.000 n=10)
Netflow/without_encoding-12    8.975    2%   7.304    2%  -18.61% (p=0.000 n=10)
Sflow/with_encoding-12         16.67    2%   14.26    1%  -14.50% (p=0.000 n=10)
Sflow/without_encoding-12      14.87    1%   13.56    2%   -8.80% (p=0.000 n=10)
As for testing, we use github.com/jhump/protoreflect: the protoparse package parses the proto definition file we generate and the dynamic package decodes the messages. Check the ProtobufDecode() method for more details.4 To get the final figures, I have also optimized the decoding in GoFlow2. It was relying heavily on binary.Read(). This function may use reflection in certain cases and each call allocates a byte array to read data. Replacing it with a more efficient version provides the following improvement:
goos: linux
goarch: amd64
pkg: akvorado/inlet/flow
cpu: AMD Ryzen 5 5600X 6-Core Processor
                              bench-3.txt                bench-4.txt              
                                 sec/op        sec/op     vs base                 
Netflow/with_encoding-12       7.758    3%   7.365    2%   -5.07% (p=0.000 n=10)
Netflow/without_encoding-12    7.304    2%   6.931    3%   -5.11% (p=0.000 n=10)
Sflow/with_encoding-12        14.256    1%   9.834    2%  -31.02% (p=0.000 n=10)
Sflow/without_encoding-12     13.559    2%   9.353    2%  -31.02% (p=0.000 n=10)
It is now easier to collect new data and the inlet component is faster!

Notice Some paragraphs were editorialized by ChatGPT, using editorialize and keep it short as a prompt. The result was proofread by a human for correctness. The main idea is that ChatGPT should be better at English than me.


  1. While empty fields are not serialized to Protocol Buffers, empty columns in ClickHouse take some space, even if they compress well. Moreover, unused fields are still decoded and they may clutter the interface.
  2. There is a similar function using NetFlow. NetFlow and IPFIX protocols are less complex to decode than sFlow as they are using a simpler TLV structure.
  3. vtprotobuf generates more optimized Go code by removing an abstraction layer. It directly generates the code encoding each field to bytes:
    if m.OutIfSpeed != 0  
        i = encodeVarint(dAtA, i, uint64(m.OutIfSpeed))
        i--
        dAtA[i] = 0x6
        i--
        dAtA[i] = 0xd8
     
    
  4. There is also a protoprint package to generate proto definition file. I did not use it.

Next.

Previous.