Search Results: "ag"

13 June 2025

Reproducible Builds (diffoscope): diffoscope 298 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 298. This version includes the following changes:
[ Chris Lamb ]
* Handle RPM's HEADERSIGNATURES and HEADERIMMUTABLE specially to avoid
  unncessarily large diffs. Based almost entirely on code by Daniel Duan.
  (Closes: reproducible-builds/diffoscope#410)
* Update copyright years.
You find out more by visiting the project homepage.

12 June 2025

Dirk Eddelbuettel: #50: Introducing almm: Activate-Linux (based) Market Monitor

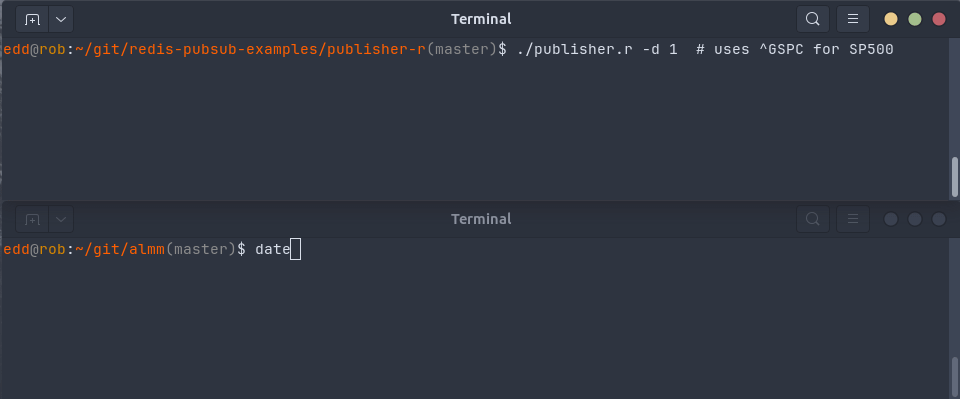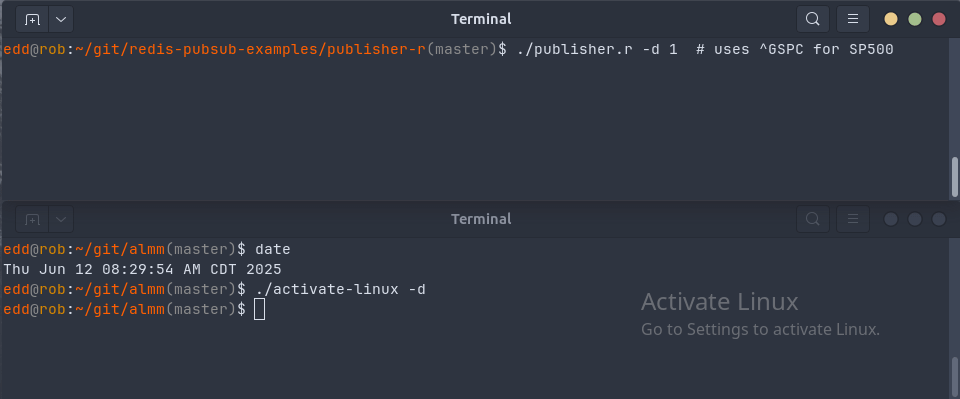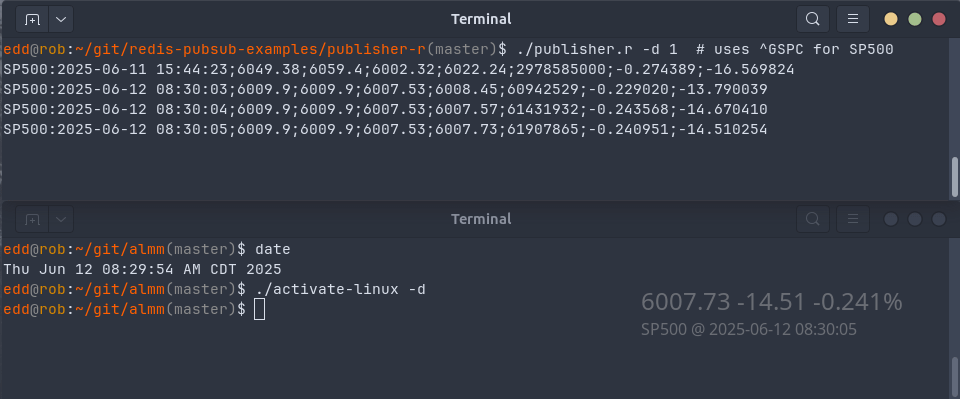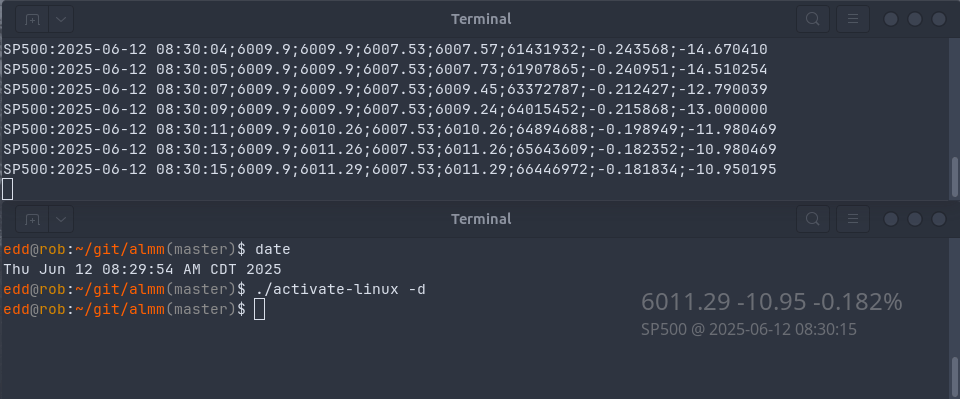
Welcome to post 50 in the R4 series. Today we reconnect to a previous post, namely #36 on pub/sub for live market monitoring with R and Redis. It introduced both Redis as well as the (then fairly recent) extensions to RcppRedis to support the publish-subscibe ( pub/sub ) model of Redis. In short, it manages both subscribing clients as well as producer for live, fast and lightweight data transmission. Using pub/sub is generally more efficient than the (conceptually simpler) poll-sleep loops as polling creates cpu and network load. Subscriptions are lighterweight as they get notified, they are also a little (but not much!) more involved as they require a callback function. We should mention that Redis has a recent fork in Valkey that arose when the former did one of these non-uncommon-among-db-companies licenuse suicides which, happy to say, they reversed more recently so that we now have both the original as well as this leading fork (among others). Both work, the latter is now included in several Linux distros, and the C library hiredis used to connect to either is still licensed permissibly as well. All this came about because Yahoo! Finance recently had another hickup in which they changed something leading to some data clients having hiccups. This includes GNOME applet Stocks Extension I had been running. There is a lively discussion on its issue #120 suggestions for example a curl wrapper (which then makes each access a new system call). Separating data acquisition and presentation becomes an attractive alternative, especially given how the standard Python and R accessors to the Yahoo! Finance service continued to work (and how per post #36 I already run data acquisition). Moreoever, and somewhat independently, it occurred to me that the cute (and both funny in its pun, and very pretty in its display) ActivateLinux program might offer an easy-enough way to display updates on the desktop. There were two aspects to address. First, the subscription side needed to be covered in either plain C or C++. That, it turns out, is very straightforward and there are existing documentation and prior examples (e.g. at StackOverflow) as well as the ability to have an LLM generate a quick stanza as I did with Claude. A modified variant is now in the example repo redis-pubsub-examples in file subscriber.c. It is deliberately minimal and the directory does not even have a Makefile: just compile and link against both libevent (for the event loop controlling this) and libhiredis (for the Redis or Valkey connection). This should work on any standard Linux (or macOS) machine with those two (very standard) libraries installed. The second aspect was trickier. While we can get Claude to modify the program to also display under x11, it still uses a single controlling event loop. It took a little bit of probing on my event to understand how to modify (the x11 use of) ActivateLinux, but as always it was reasonably straightforward in the end: instead of one single while loop awaiting events we now first check for pending events and deal with them if present but otherwise do not idle and wait but continue in another loop that also checks on the Redis or Valkey pub/sub events. So two thumbs up to vibe coding which clearly turned me into an x11-savvy programmer too The result is in a new (and currently fairly bare-bones) repo almm. It includes all files needed to build the application, borrowed with love from ActivateLinux (which is GPL-licensed, as is of course our minimal extension) and adds the minimal modifications we made, namely linking with libhiredis and some minimal changes to x11/x11.c. (Supporting wayland as well is on the TODO list, and I also need to release a new RcppRedis version to CRAN as one currently needs the GitHub version.) We also made a simple mp4 video with a sound overlay which describes the components briefly: Comments and questions welcome. I will probably add a little bit of command-line support to the almm. Selecting the symbol subscribed to is currently done in the most minimal way via environment variable SYMBOL (NB: not SYM as the video using the default value shows). I also worked out how to show the display only one of my multiple monitors so I may add an explicit screen id selector too. A little bit of discussion (including minimal Docker use around r2u) is also in issue #121 where I first floated the idea of having StocksExtension listen to Redis (or Valkey). Other suggestions are most welcome, please use issue tickets at the almm repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

11 June 2025

Iustin Pop: This blog finally goes git-annex!

A long, long time ago I have a few pictures on this blog, mostly in earlier years, because even with small pictures, the git repository became 80MiB soon this is not much in absolute terms, but the actual Markdown/Haskell/CSS/HTML total size is tiny compared to the picture, PDFs and fonts. I realised I need a better solution, probably about ten years ago, and that I should investigate git-annex. Then time passed, and I heard about git-lfs, so I thought that s the way forward. Now, I recently got interested again into doing something about this repository, and started researching.

Detour: git-lfs I was sure that git-lfs, being supported by large providers, would be the modern solution. But to my surprise, git-lfs is very server centric, which in hindsight makes sense, but for a home setup, it s not very good. Maybe I misunderstood, but git-lfs is more a protocol/method for a forge to store files, rather than an end-user solution. But then you need to backup those files separately (together with the rest of the forge), or implement another way of safeguarding them. Further details such as the fact that it keeps two copies of the files (one in the actual checked-out tree, one in internal storage) means it s not a good solution. Well, for my blog yes, but not in general. Then posts on Reddit about horror stories people being locked out of github due to quota, as an example, or this Stack Overflow post about git-lfs constraining how one uses git, convinced me that s not what I want. To each their own, but not for me I might want to push this blog s repo to github, but I definitely wouldn t want in that case to pay for github storage for my blog images (which are copies, not originals). And yes, even in 2025, those quotas are real GitHub limits and I agree with GitHub, storage and large bandwidth can t be free.

Back to the future: git-annex So back to git-annex. I thought it s going to be a simple thing, but oh boy, was I wrong. It took me half a week of continuous (well, in free time) reading and discussions with LLMs to understand a bit how it works. I think, honestly, it s a bit too complex, which is why the workflows page lists seven (!) levels of workflow complexity, from fully-managed, to fully-manual. IMHO, respect to the author for the awesome tool, but if you need a web app to help you manage git, it hints that the tool is too complex. I made the mistake of running git annex sync once, to realise it actually starts pushing to my upstream repo and creating new branches and whatnot, so after enough reading, I settled on workflow 6/7, since I don t want another tool to manage my git history. Maybe I m an outlier here, but everything automatic is a bit too much for me. Once you do managed yourself how git-annex works (on the surface, at least), it is a pretty cool thing. It uses a git-annex git branch to store metainformation, and that is relatively clean. If you do run git annex sync, it creates some extra branches, which I don t like, but meh.

Trick question: what is a remote? One of the most confusing things about git-annex was understanding its remote concept. I thought a remote is a place where you replicate your data. But not, that s a special remote. A normal remote is a git remote, but which is expected to be git/ssh/with command line access. So if you have a git+ssh remote, git-annex will not only try to push it s above-mentioned branch, but also copy the files. If such a remote is on a forge that doesn t support git-annex, then it will complain and get confused. Of course, if you read the extensive docs, you just do git config remote.<name>.annex-ignore true, and it will understand that it should not sync to it. But, aside, from this case, git-annex expects that all checkouts and clones of the repository are both metadata and data. And if you do any annex commands in them, all other clones will know about them! This can be unexpected, and you find people complaining about it, but nowadays there s a solution:
git clone   dir && cd dir
git config annex.private true
git annex init "temp copy"
This is important. Any leaf git clone must be followed by that annex.private true config, especially on CI/CD machines. Honestly, I don t understand why by default clones should be official data stores, but it is what it is. I settled on not making any of my checkouts stable , but only the actual storage places. Except those are not git repositories, but just git-annex storage things. I.e., special remotes. Is it confusing enough yet ?

Special remotes The special remotes, as said, is what I expected to be the normal git annex remotes, i.e. places where the data is stored. But well, they exist, and while I m only using a couple simple ones, there is a large number of them. Among the interesting ones: git-lfs, a remote that allows also storing the git repository itself (git-remote-annex), although I m bit confused about this one, and most of the common storage providers via the rclone remote. Plus, all of the special remotes support encryption, so this is a really neat way to store your files across a large number of things, and handle replication, number of copies, from which copy to retrieve, etc. as you with.

And many of other features git-annex has tons of other features, so to some extent, the sky s the limit. Automatic selection of what to add git it vs plain git, encryption handling, number of copies, clusters, computed files, etc. etc. etc. I still think it s cool but too complex, though!

Uses Aside from my blog post, of course. I ve seen blog posts/comments about people using git-annex to track/store their photo collection, and I could see very well how the remote encrypted repos any of the services supported by rclone could be an N+2 copy or so. For me, tracking photos would be a bit too tedious, but it could maybe work after more research. A more practical thing would probably be replicating my local movie collection (all legal, to be clear) better than just run rsync from time to time and tracking the large files in it via git-annex. That s an exercise for another day, though, once I get more mileage with it - my blog pictures are copies, so I don t care much if they get lost, but movies are primary online copies, and I don t want to re-dump the discs. Anyway, for later.

Migrating to git-annex Migrating here means ending in a state where all large files are in git-annex, and the plain git repo is small. Just moving the files to git annex at the current head doesn t remove them from history, so your git repository is still large; it won t grow in the future, but remains with old size (and contains the large files in its history). In my mind, a nice migration would be: run a custom command, and all the history is migrated to git-annex, so I can go back in time and the still use git-annex. I na vely expected this would be easy and already available, only to find comments on the git-annex site with unsure git-filter-branch calls and some web discussions. This is the discussion on the git annex website, but it didn t make me confident it would do the right thing. But that discussion is now 8 years old. Surely in 2025, with git-filter-repo, it s easier? And, maybe I m missing something, but it is not. Not from the point of view of plain git, that s easy, but because interacting with git-annex, which stores its data in git itself, so doing this properly across successive steps of a repo (when replaying the commits) is, I think, not well defined behaviour. So I was stuck here for a few days, until I got an epiphany: As I m going to rewrite the repository, of course I m keeping a copy of it from before git-annex. If so, I don t need the history, back in time, to be correct in the sense of being able to retrieve the binary files too. It just needs to be correct from the point of view of the actual Markdown and Haskell files that represent the meat of the blog. This simplified the problem a lot. At first, I wanted to just skip these files, but this could also drop commits (git-filter-repo, by default, drops the commits if they re empty), and removing the files loses information - when they were added, what were the paths, etc. So instead I came up with a rather clever idea, if I might say so: since git-annex replaces files with symlinks already, just replace the files with symlinks in the whole history, except symlinks that are dangling (to represent the fact that files are missing). One could also use empty files, but empty files are more valid in a sense than dangling symlinks, hence why I settled on those. Doing this with git-filter-repo is easy, in newer versions, with the new --file-info-callback. Here is the simple code I used:
import os
import os.path
import pathlib

SKIP_EXTENSIONS= 'jpg', 'jpeg', 'png', 'pdf', 'woff', 'woff2' 
FILE_MODES =  b"100644", b"100755" 
SYMLINK_MODE = b"120000"

fas_string = filename.decode()
path = pathlib.PurePosixPath(fas_string)
ext = path.suffix.removeprefix('.')

if ext not in SKIP_EXTENSIONS:
  return (filename, mode, blob_id)

if mode not in FILE_MODES:
  return (filename, mode, blob_id)

print(f"Replacing ' filename ' (extension '. ext ') in  os.getcwd() ")

symlink_target = '/none/binary-file-removed-from-git-history'.encode()
new_blob_id = value.insert_file_with_contents(symlink_target)
return (filename, SYMLINK_MODE, new_blob_id)
This goes and replaces files with a symlink to nowhere, but the symlink should explain why it s dangling. Then later renames or moving the files around work naturally , as the rename/mv doesn t care about file contents. Then, when the filtering is done via:
git-filter-repo --file-info-callback <(cat ~/filter-big.py ) --force
It is easy to onboard to git annex:
  • remove all dangling symlinks
  • copy the (binary) files from the original repository
  • since they re named the same, and in the same places, git sees a type change
  • then simply run git annex add on those files
For me it was easy as all such files were in a few directories, so just copying those directories back, a few git-annex add commands, and done. Of course, then adding a few rsync remotes, git annex copy --to, and the repository was ready. Well, I also found a bug in my own Hakyll setup: on a fresh clone, when the large files are just dangling symlinks, the builder doesn t complain, just ignores the images. Will have to fix.

Other resources This is a blog that I read at the beginning, and I found it very useful as an intro: https://switowski.com/blog/git-annex/. It didn t help me understand how it works under the covers, but it is well written. The author does use the sync command though, which is too magic for me, but also agrees about its complexity

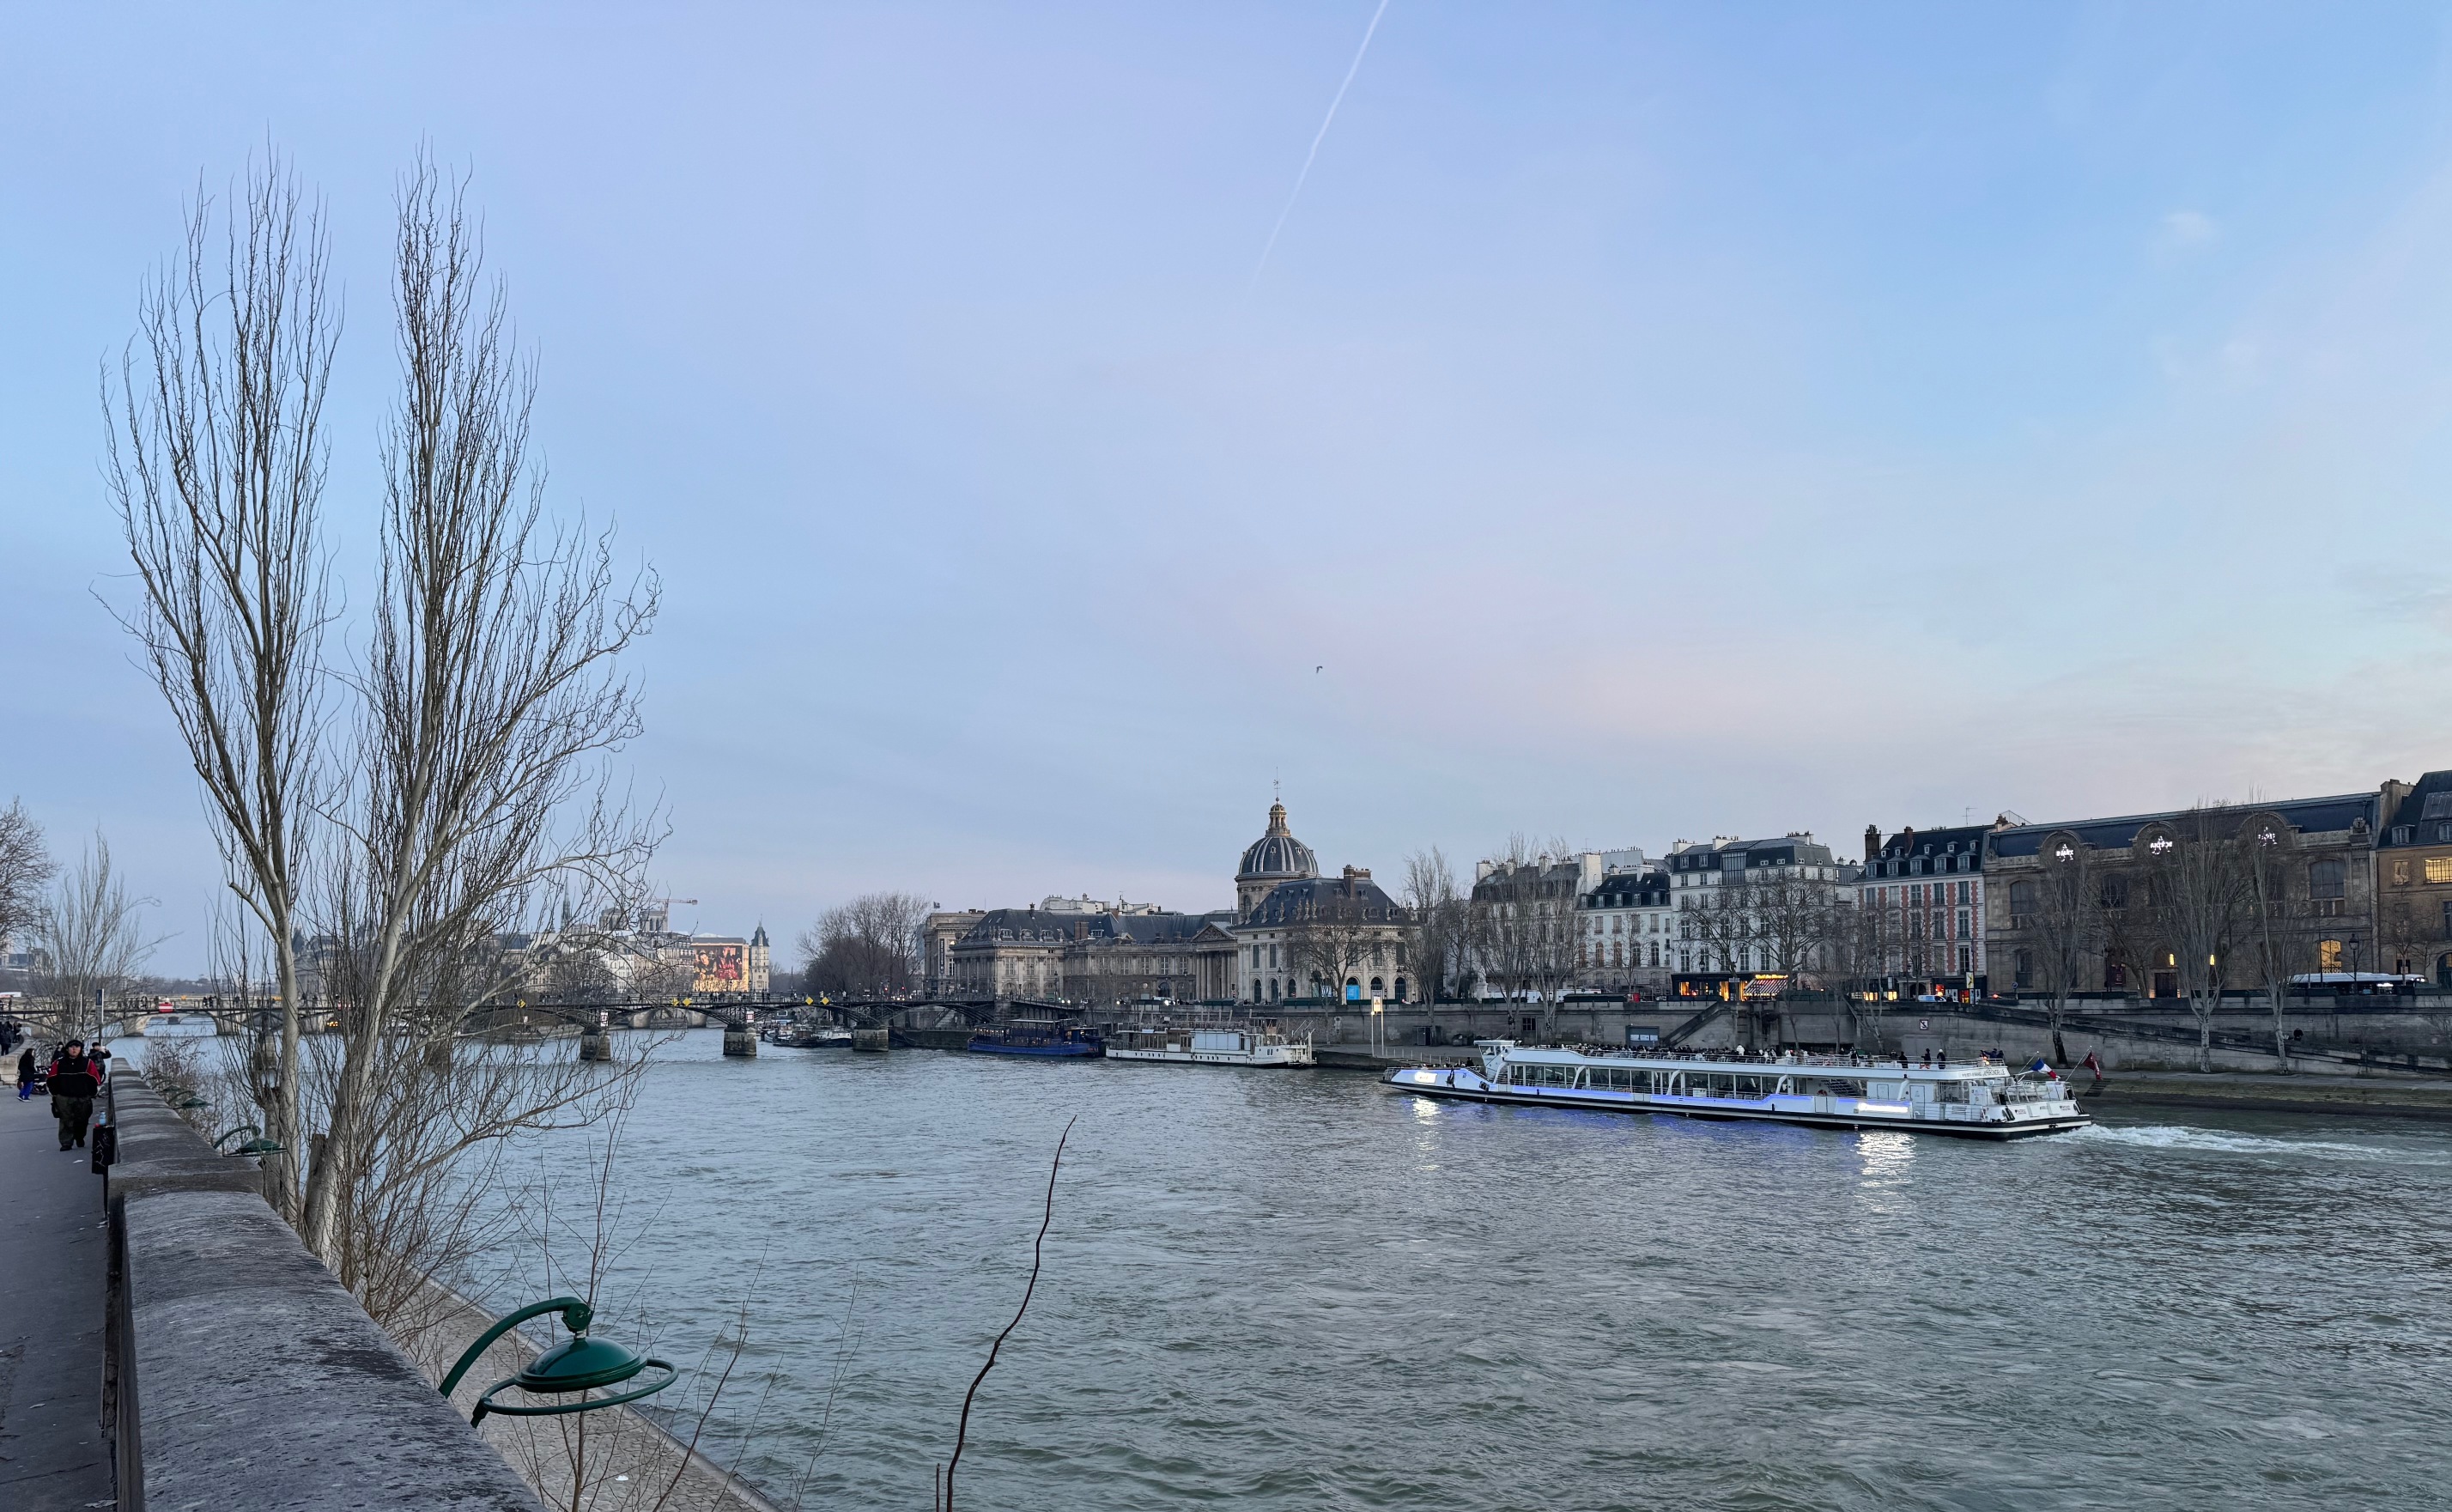
The proof is in the pudding And now, for the actual first image to be added that never lived in the old plain git repository. It s not full-res/full-size, it s cropped a bit on the bottom. Earlier in the year, I went to Paris for a very brief work trip, and I walked around a bit it was more beautiful than what I remembered from way way back. So a bit random selection of a picture, but here it is:
Un bateau sur la Seine Un bateau sur la Seine
Enjoy!

Gunnar Wolf: Understanding Misunderstandings - Evaluating LLMs on Networking Questions

This post is a review for Computing Reviews for Understanding Misunderstandings - Evaluating LLMs on Networking Questions , a article published in Association for Computing Machinery (ACM), SIGCOMM Computer Communication Review
Large language models (LLMs) have awed the world, emerging as the fastest-growing application of all time ChatGPT reached 100 million active users in January 2023, just two months after its launch. After an initial cycle, they have gradually been mostly accepted and incorporated into various workflows, and their basic mechanics are no longer beyond the understanding of people with moderate computer literacy. Now, given that the technology is better understood, we face the question of how convenient LLM chatbots are for different occupations. This paper embarks on the question of whether LLMs can be useful for networking applications. This paper systematizes querying three popular LLMs (GPT-3.5, GPT-4, and Claude 3) with questions taken from several network management online courses and certifications, and presents a taxonomy of six axes along which the incorrect responses were classified: The authors also measure four strategies toward improving answers: The authors observe that, while some of those strategies were marginally useful, they sometimes resulted in degraded performance. The authors queried the commercially available instances of Gemini and GPT, which achieved scores over 90 percent for basic subjects but fared notably worse in topics that require understanding and converting between different numeric notations, such as working with Internet protocol (IP) addresses, even if they are trivial (that is, presenting the subnet mask for a given network address expressed as the typical IPv4 dotted-quad representation). As a last item in the paper, the authors compare performance with three popular open-source models: Llama3.1, Gemma2, and Mistral with their default settings. Although those models are almost 20 times smaller than the GPT-3.5 commercial model used, they reached comparable performance levels. Sadly, the paper does not delve deeper into these models, which can be deployed locally and adapted to specific scenarios. The paper is easy to read and does not require deep mathematical or AI-related knowledge. It presents a clear comparison along the described axes for the 503 multiple-choice questions presented. This paper can be used as a guide for structuring similar studies over different fields.

Sven Hoexter: HaProxy: Two Ways of Activating PROXY Protocol

If you ever face the need to activate the PROXY Protocol in HaProxy (e.g. if you're as unlucky as I'm, and you have to use Google Cloud TCP proxy load balancer), be aware that there are two ways to do that. Both are part of the frontend configuration. accept-proxy This one is the big hammer and forces the usage of the PROXY protocol on all connections. Sample:
      frontend vogons
          bind *:2342 accept-proxy ssl crt /etc/haproxy/certs/vogons/tls.crt
tcp-request connection expect-proxy If you have to, e.g. during a phase of migrations, receive traffic directly, without the PROXY protocol header and from a proxy with the header there is also a more flexible option based on a tcp-request connection action. Sample:
      frontend vogons
          bind *:2342 ssl crt /etc/haproxy/certs/vogons/tls.crt
          tcp-request connection expect-proxy layer4 if   src 35.191.0.0/16 130.211.0.0/22  
Source addresses here are those of GCP global TCP proxy frontends. Replace with whatever suites your case. Since this is happening just after establishing a TCP connection, there is barely anything else available to match on beside of the source address. HaProxy Documentation

John Goerzen: I Learned We All Have Linux Seats, and I m Not Entirely Pleased

I recently wrote about How to Use SSH with FIDO2/U2F Security Keys, which I now use on almost all of my machines. The last one that needed this was my Raspberry Pi hooked up to my DEC vt510 terminal and IBM mechanical keyboard. Yes I do still use that setup! To my surprise, generating a key on it failed. I very quickly saw that /dev/hidraw0 had incorrect permissions, accessible only to root. On other machines, it looks like this:
crw-rw----+ 1 root root 243, 16 May 24 16:47 /dev/hidraw16
And, if I run getfacl on it, I see:
# file: dev/hidraw16
# owner: root
# group: root
user::rw-
user:jgoerzen:rw-
group::---
mask::rw-
other::---
Yes, something was setting an ACL on it. Thus began to saga to figure out what was doing that. Firing up inotifywatch, I saw it was systemd-udevd or its udev-worker. But cranking up logging on that to maximum only showed me that uaccess was somehow doing this. I started digging. uaccess turned out to be almost entirely undocumented. People say to use it, but there s no description of what it does or how. Its purpose appears to be to grant access to devices to those logged in to a machine by dynamically adding them to ACLs for devices. OK, that s a nice goal, but why was machine A doing this and not machine B? I dug some more. I came across a hint that uaccess may only do that for a seat . A seat? I ve not heard of that in Linux before. Turns out there s some information (older and newer) about this out there. Sure enough, on the machine with KDE, loginctl list-sessions shows me on seat0, but on the machine where I log in from ttyUSB0, it shows an empty seat. But how to make myself part of the seat? I tried various udev rules to add the seat or master-of-seat tags, but nothing made any difference. I finally gave up and did the old-fashioned rule to just make it work already:
TAG=="security-device",SUBSYSTEM=="hidraw",GROUP="mygroup"
I still don t know how to teach logind to add a seat for ttyUSB0, but oh well. At least I learned something. An annoying something, but hey. This all had a laudable goal, but when there are so many layers of indirection, poorly documented, with poor logging, it gets pretty annoying.

Scarlett Gately Moore: KDE Application snaps 25.04.2 released!

KDE MascotKDE Mascot
Release notes: https://kde.org/announcements/gear/25.04.2/ Now available in the snap store! Along with that, I have fixed some outstanding bugs: Ark: now can open/save files in removable media Kasts: Once again has sound WIP: Updating Qt6 to 6.9 and frameworks to 6.14 Enjoy everyone! Unlike our software, life is not free. Please consider a donation, thanks!

Freexian Collaborators: Debian Contributions: Updated Austin, DebConf 25 preparations continue and more! (by Anupa Ann Joseph)

Debian Contributions: 2025-05 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Updated Austin, by Colin Watson and Helmut Grohne Austin is a frame stack sampling profiler for Python. It allows profiling Python applications without instrumenting them while losing some accuracy in the process, and is the only one of its kind presently packaged for Debian. Unfortunately, it hadn t been uploaded in a while and hence the last Python version it worked with was 3.8. We updated it to a current version and also dealt with a number of architecture-specific problems (such as unintended sign promotion, 64bit time_t fallout and strictness due to -Wformat-security ) in cooperation with upstream. With luck, it will migrate in time for trixie.

Preparing for DebConf 25, by Stefano Rivera and Santiago Ruano Rinc n DebConf 25 is quickly approaching, and the organization work doesn t stop. In May, Stefano continued supporting the different teams. Just to give a couple of examples, Stefano made changes in DebConf 25 website to make BoF and sprints submissions public, so interested people can already know if a BoF or sprint for a given subject is planned, allowing coordination with the proposer; or to enhance how statistics are made public to help the work of the local team. Santiago has participated in different tasks, including the logistics of the conference, like preparing more information about the public transportation that will be available. Santiago has also taken part in activities related to fundraising and reviewing more event proposals.

Miscellaneous contributions
  • Lucas fixed security issues in Valkey in unstable.
  • Lucas tried to help with the update of Redis to version 8 in unstable. The package hadn t been updated for a while due to licensing issues, but now upstream maintainers fixed them.
  • Lucas uploaded around 20 ruby-* packages to unstable that weren t updated for some years to make them build reproducible. Thanks to reproducible builds folks to point out those issues. Also some unblock requests (and follow-ups) were needed to make them reach trixie in time for the release.
  • Lucas is organizing a Debian Outreach session for DebConf 25, reaching out to all interns of Google Summer of Code and Outreachy programs from the last year. The session will be presented by in-person interns and also video recordings from the interns interested in participating but did not manage to attend the conference.
  • Lucas continuously works on DebConf Content team tasks. Replying to speakers, sponsors, and communicating internally with the team.
  • Carles improved po-debconf-manager: fixed bugs reported by Catalan translator, added possibility to import packages out of salsa, added using non-default project branches on salsa, polish to get ready for DebCamp.
  • Carles tested new apt in trixie and reported bugs to apt , installation-report , libqt6widget6 .
  • Carles used po-debconf-manager and imported remaining 80 packages, reviewed 20 translations, submitted (MR or bugs) 54 translations.
  • Carles prepared some topics for translation BoF in DebConf (gathered feedback, first pass on topics).
  • Helmut gave an introductory talk about the mechanics of Linux namespaces at MiniDebConf Hamburg.
  • Helmut sent 25 patches for cross compilation failures.
  • Helmut reviewed, refined and applied a patch from Jochen Sprickerhof to make the Multi-Arch hinter emit more hints for pure Python modules.
  • Helmut sat down with Christoph Berg (not affiliated with Freexian) and extended unschroot to support directory-based chroots with overlayfs. This is a feature that was lost in transitioning from sbuild s schroot backend to its unshare backend. unschroot implements the schroot API just enough to be usable with sbuild and otherwise works a lot like the unshare backend. As a result, apt.postgresql.org now performs its builds contained in a user namespace.
  • Helmut looked into a fair number of rebootstrap failures most of which related to musl or gcc-15 and imported patches or workarounds to make those builds proceed.
  • Helmut updated dumat to use sqop fixing earlier PGP verification problems thanks to Justus Winter and Neal Walfield explaining a lot of sequoia at MiniDebConf Hamburg.
  • Helmut got the previous zutils update for /usr-move wrong again and had to send another update.
  • Helmut looked into why debvm s autopkgtests were flaky and with lots of help from Paul Gevers and Michael Tokarev tracked it down to a race condition in qemu. He updated debvm to trigger the problem less often and also fixed a wrong dependency using Luca Boccassi s patch.
  • Santiago continued the switch to sbuild for Salsa CI (that was stopped for some months), and has been mainly testing linux, since it s a complex project that heavily customizes the pipeline. Santiago is preparing the changes for linux to submit a MR soon.
  • In openssh, Colin tracked down some intermittent sshd crashes to a root cause, and issued bookworm and bullseye updates for CVE-2025-32728.
  • Colin spent some time fixing up fail2ban, mainly reverting a patch that caused its tests to fail and would have banned legitimate users in some common cases.
  • Colin backported upstream fixes for CVE-2025-48383 (django-select2) and CVE-2025-47287 (python-tornado) to unstable.
  • Stefano supported video streaming and recording for 2 miniDebConfs in May: Macei and Hamburg. These had overlapping streams for one day, which is a first for us.
  • Stefano packaged the new version of python-virtualenv that includes our patches for not including the wheel for wheel.
  • Stefano got all involved parties to agree (in principle) to meet at DebConf for a mediated discussion on a dispute that was brought to the technical committee.
  • Anupa coordinated the swag purchase for DebConf 25 with Juliana and Nattie.
  • Anupa joined the publicity team meeting for discussing the upcoming events and BoF at DebConf 25.
  • Anupa worked with the publicity team to publish Bits post to welcome GSoc 2025 Interns.

Freexian Collaborators: Monthly report about Debian Long Term Support, May 2025 (by Roberto C. S nchez)

Like each month, have a look at the work funded by Freexian s Debian LTS offering.

Debian LTS contributors In May, 22 contributors have been paid to work on Debian LTS, their reports are available:
  • Abhijith PA did 8.0h (out of 0.0h assigned and 8.0h from previous period).
  • Adrian Bunk did 26.0h (out of 26.0h assigned).
  • Andreas Henriksson did 1.0h (out of 15.0h assigned and 3.0h from previous period), thus carrying over 17.0h to the next month.
  • Andrej Shadura did 3.0h (out of 10.0h assigned), thus carrying over 7.0h to the next month.
  • Bastien Roucari s did 20.0h (out of 20.0h assigned).
  • Ben Hutchings did 8.0h (out of 20.0h assigned and 4.0h from previous period), thus carrying over 16.0h to the next month.
  • Carlos Henrique Lima Melara did 12.0h (out of 11.0h assigned and 1.0h from previous period).
  • Chris Lamb did 15.5h (out of 0.0h assigned and 15.5h from previous period).
  • Daniel Leidert did 25.0h (out of 26.0h assigned), thus carrying over 1.0h to the next month.
  • Emilio Pozuelo Monfort did 21.0h (out of 16.75h assigned and 11.0h from previous period), thus carrying over 6.75h to the next month.
  • Guilhem Moulin did 11.5h (out of 8.5h assigned and 6.5h from previous period), thus carrying over 3.5h to the next month.
  • Jochen Sprickerhof did 3.5h (out of 8.75h assigned and 17.5h from previous period), thus carrying over 22.75h to the next month.
  • Lee Garrett did 26.0h (out of 12.75h assigned and 13.25h from previous period).
  • Lucas Kanashiro did 20.0h (out of 18.0h assigned and 2.0h from previous period).
  • Markus Koschany did 20.0h (out of 26.25h assigned), thus carrying over 6.25h to the next month.
  • Roberto C. S nchez did 20.75h (out of 24.0h assigned), thus carrying over 3.25h to the next month.
  • Santiago Ruano Rinc n did 15.0h (out of 12.5h assigned and 2.5h from previous period).
  • Sean Whitton did 6.25h (out of 6.0h assigned and 2.0h from previous period), thus carrying over 1.75h to the next month.
  • Sylvain Beucler did 26.25h (out of 26.25h assigned).
  • Thorsten Alteholz did 15.0h (out of 15.0h assigned).
  • Tobias Frost did 12.0h (out of 12.0h assigned).
  • Utkarsh Gupta did 1.0h (out of 15.0h assigned), thus carrying over 14.0h to the next month.

Evolution of the situation In May, we released 54 DLAs. The LTS Team was particularly active in May, publishing a higher than normal number of advisories, as well as helping with a wide range of updates to packages in stable and unstable, plus some other interesting work. We are also pleased to welcome several updates from contributors outside the regular team.
  • Notable security updates:
    • containerd, prepared by Andreas Henriksson, fixes a vulnerability that could cause containers launched as non-root users to be run as root
    • libapache2-mod-auth-openidc, prepared by Moritz Schlarb, fixes a vulnerability which could allow an attacker to crash an Apache web server with libapache2-mod-auth-openidc installed
    • request-tracker4, prepared by Andrew Ruthven, fixes multiple vulnerabilities which could result in information disclosure, cross-site scripting and use of weak encryption for S/MIME emails
    • postgresql-13, prepared by Bastien Roucari s, fixes an application crash vulnerability that could affect the server or applications using libpq
    • dropbear, prepared by Guilhem Moulin, fixes a vulnerability which could potentially result in execution of arbitrary shell commands
    • openjdk-17, openjdk-11, prepared by Thorsten Glaser, fixes several vulnerabilities, which include denial of service, information disclosure or bypass of sandbox restrictions
    • glibc, prepared by Sean Whitton, fixes a privilege escalation vulnerability
  • Notable non-security updates:
    • wireless-regdb, prepared by Ben Hutchings, updates information reflecting changes to radio regulations in many countries
This month s contributions from outside the regular team include the libapache2-mod-auth-openidc update mentioned above, prepared by Moritz Schlarb (the maintainer of the package); the update of request-tracker4, prepared by Andrew Ruthven (the maintainer of the package); and the updates of openjdk-17 and openjdk-11, also noted above, prepared by Thorsten Glaser. Additionally, LTS Team members contributed stable updates of the following packages:
  • rubygems and yelp/yelp-xsl, prepared by Lucas Kanashiro
  • simplesamlphp, prepared by Tobias Frost
  • libbson-xs-perl, prepared by Roberto C. S nchez
  • fossil, prepared by Sylvain Beucler
  • setuptools and mydumper, prepared by Lee Garrett
  • redis and webpy, prepared by Adrian Bunk
  • xrdp, prepared by Abhijith PA
  • tcpdf, prepared by Santiago Ruano Rinc n
  • kmail-account-wizard, prepared by Thorsten Alteholz
Other contributions were also made by LTS Team members to packages in unstable:
  • proftpd-dfsg DEP-8 tests (autopkgtests) were provided to the maintainer, prepared by Lucas Kanashiro
  • a regular upload of libsoup2.4, prepared by Sean Whitton
  • a regular upload of setuptools, prepared by Lee Garrett
Freexian, the entity behind the management of the Debian LTS project, has been working for some time now on the development of an advanced CI platform for Debian-based distributions, called Debusine. Recently, Debusine has reached a level of feature implementation that makes it very usable. Some members of the LTS Team have been using Debusine informally, and during May LTS coordinator Santiago Ruano Rinc n has made a call for the team to help with testing of Debusine, and to help evaluate its suitability for the LTS Team to eventually begin using as the primary mechanism for uploading packages into Debian. Team members who have started using Debusine are providing valuable feedback to the Debusine development team, thus helping to improve the platform for all users. Actually, a number of updates, for both bullseye and bookworm, made during the month of May were handled using Debusine, e.g. rubygems s DLA-4163-1. By the way, if you are a Debian Developer, you can easily test Debusine following the instructions found at https://wiki.debian.org/DebusineDebianNet. DebConf, the annual Debian Conference, is coming up in July and, as is customary each year, the week preceding the conference will feature an event called DebCamp. The DebCamp week provides an opportunity for teams and other interested groups/individuals to meet together in person in the same venue as the conference itself, with the purpose of doing focused work, often called sprints . LTS coordinator Roberto C. S nchez has announced that the LTS Team is planning to hold a sprint primarily focused on the Debian security tracker and the associated tooling used by the LTS Team and the Debian Security Team.

Thanks to our sponsors Sponsors that joined recently are in bold.

9 June 2025

Sergio Cipriano: Why package X is installed in your Debian

Why package X is installed in your Debian When I was looking for alternatives to mount a USB flash drive without sudo, I came across udisks2. To my surprise, this package was already installed on my machine. I found these two methods to understand why:
$ apt rdepends udisks2 --installed
udisks2
Reverse Depends:
  Depends: gnome-disk-utility (>= 2.7.6)
  Depends: gvfs-daemons
  Recommends: fwupd
$ aptitude why udisks2
i   task-gnome-desktop Depends gnome-core                
i A gnome-core         Depends gnome-disk-utility (>= 46)
i A gnome-disk-utility Depends udisks2 (>= 2.7.6)
The i marker means installed packages. The A marker means the package was installed automatically.

8 June 2025

Thorsten Alteholz: My Debian Activities in May 2025

Debian LTS This was my hundred-thirty-first month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on: I also continued my to work on libxmltok and suricata. This month I also had to do some support on seger, for example to inject packages newly needed for builds. Debian ELTS This month was the eighty-second ELTS month. During my allocated time I uploaded or worked on: All packages I worked on have been on the list of longstanding packages. For example espeak-ng has been on this list for more than nine month. I now understood that there is a reason why packages are on this list. Some parts of the software have been almost completely reworked, so that the patches need a reverse rework. For some packages this is easy, but for others this rework needs quite some time. I also continued to work on libxmltok and suricata. Debian Printing Unfortunately I didn t found any time to work on this topic. Debian Astro This month I uploaded bugfix versions of: Debian Mobcom This month I uploaded bugfix versions of: misc This month I uploaded bugfix versions of: Thanks a lot to the Release Team who quickly handled all my unblock bugs! FTP master It is this time of the year when just a few packages arrive in NEW: it is Hard Freeze. So I enjoy this period and basically just take care of kernels or other important packages. As people seem to be more interested in discussions than in fixing RC bugs, my period of rest seems to continue for a while. So thanks for all this valuable discussions and really thanks to the few people who still take care of Trixie. This month I accepted 146 and rejected 10 packages. The overall number of packages that got accepted was 147.

Debian Outreach Team: GSoC 2024 Final Report: Project DebMobCom

GSoC 2024: Project DebMobCom

Introduction Hi, my name is Nathan Doris and this is my report on contributing to the Debian Mobile Communication project for GSoC 2024 under the guidance of my mentor, Thorsten Alteholz.

Project MobCom Debian s Mobile Communication team takes care of updating and creating packages for the open-source mobile communication software suite known as Osmocom. The ongoing development of this software stack requires constant updating and creation of packages to support this progress. The goal of GSoC 2024 DebMobCom is to update, recreate and add these Osmocom packages.

My Work Over the few months that I contributed to Debian I successfully updated/recreated more than a dozen packages for DebMobCom. A list of my accomplishments can be found here as well as on the Debian QA page.

What I Learned Before I began this journey I had very little experience with Debian packaging. By the end of GSoC not only had I learned about building packages but I also gained more knowledge regarding Linux, Debian, shell scripting, automake, C, GNU and gitlab/Salsa. As I reflect back on the past few months I am amazed at the amount and depth of information I have learned. Listed below are examples of items that I found especially important.
  • Debian Packaging Workflow
    • Every package to be built relies upon the information inside the /debian folder. This is where I learned the importance of every templated file such as the control, changelog, rules, watch, *.symbols, *.install and many others. As I worked on these files I witnessed the relationship between them and the finished .deb package. From this workflow I can appreciate the amount of imagination and work that was put into this process.
  • Debian Tooling
    • I learned many tools while building packages but sbuild accompanied by lintian is what I spent the most time with. Sbuild is an autobuilder that produces the final .deb packages. It also integrates with another tool, lintian, which checks each package and informs you of any errors such as policy violations, common mistakes and best practices. Thorsten s words, keep lintian happy still resonate with me after each package build.
    • Another tool I frequently require use of is quilt. Quilt is a wonderful tool that manages patches for packages. I became quite well versed in updating patches, removing and also creating my own.
  • Copyright
    • I hadn t realised how important licensing was until I started contributing to Debian. I predominantly used licensecheck to extract copyright information from source code. This was a tedious task but obviously extremely important in keeping Debian packages free.

Challenges What I found particularly challenging (and enjoyable) was the amount of troubleshooting required to complete tasks. Although I spent countless hours reading documentation such as the New Maintainers Guide, Policy Manual, Wiki and manual pages it was still extremely difficult. Complex packages are not quite covered in the docs so out-of-the-box thinking is required.

Conclusion First of all I d like to say a big thank you to my mentor Thorsten. His support was critical for my success. Contributing to Debian and the overall GSoC experience was such a positive event in my life. I enjoyed all aspects of the experience. The skills I have acquired will propel me forward into further open-source activities and communities. As I continue to contribute to this project my goal of becoming a Debian Maintainer is becoming a reality.

Colin Watson: Free software activity in May 2025

My Debian contributions this month were all sponsored by Freexian. Things were a bit quieter than usual, as for the most part I was sticking to things that seemed urgent for the upcoming trixie release. You can also support my work directly via Liberapay or GitHub Sponsors. OpenSSH After my appeal for help last month to debug intermittent sshd crashes, Michel Casabona helped me put together an environment where I could reproduce it, which allowed me to track it down to a root cause and fix it. (I also found a misuse of strlcpy affecting at least glibc-based systems in passing, though I think that was unrelated.) I worked with Daniel Kahn Gillmor to fix a regression in ssh-agent socket handling. I fixed a reproducibility bug depending on whether passwd is installed on the build system, which would have affected security updates during the lifetime of trixie. I backported openssh 1:10.0p1-5 to bookworm-backports. I issued bookworm and bullseye updates for CVE-2025-32728. groff I backported a fix for incorrect output when formatting multiple documents as PDF/PostScript at once. debmirror I added a simple autopkgtest. Python team I upgraded these packages to new upstream versions: In bookworm-backports, I updated these packages: I fixed problems building these packages reproducibly: I backported fixes for some security vulnerabilities to unstable (since we re in freeze now so it s not always appropriate to upgrade to new upstream versions): I fixed various other build/test failures: I added non-superficial autopkgtests to these packages: I packaged python-django-hashids and python-django-pgbulk, needed for new upstream versions of python-django-pgtrigger. I ported storm to Python 3.14. Science team I fixed a build failure in apertium-oci-fra.

7 June 2025

Evgeni Golov: show your desk - 2025 edition

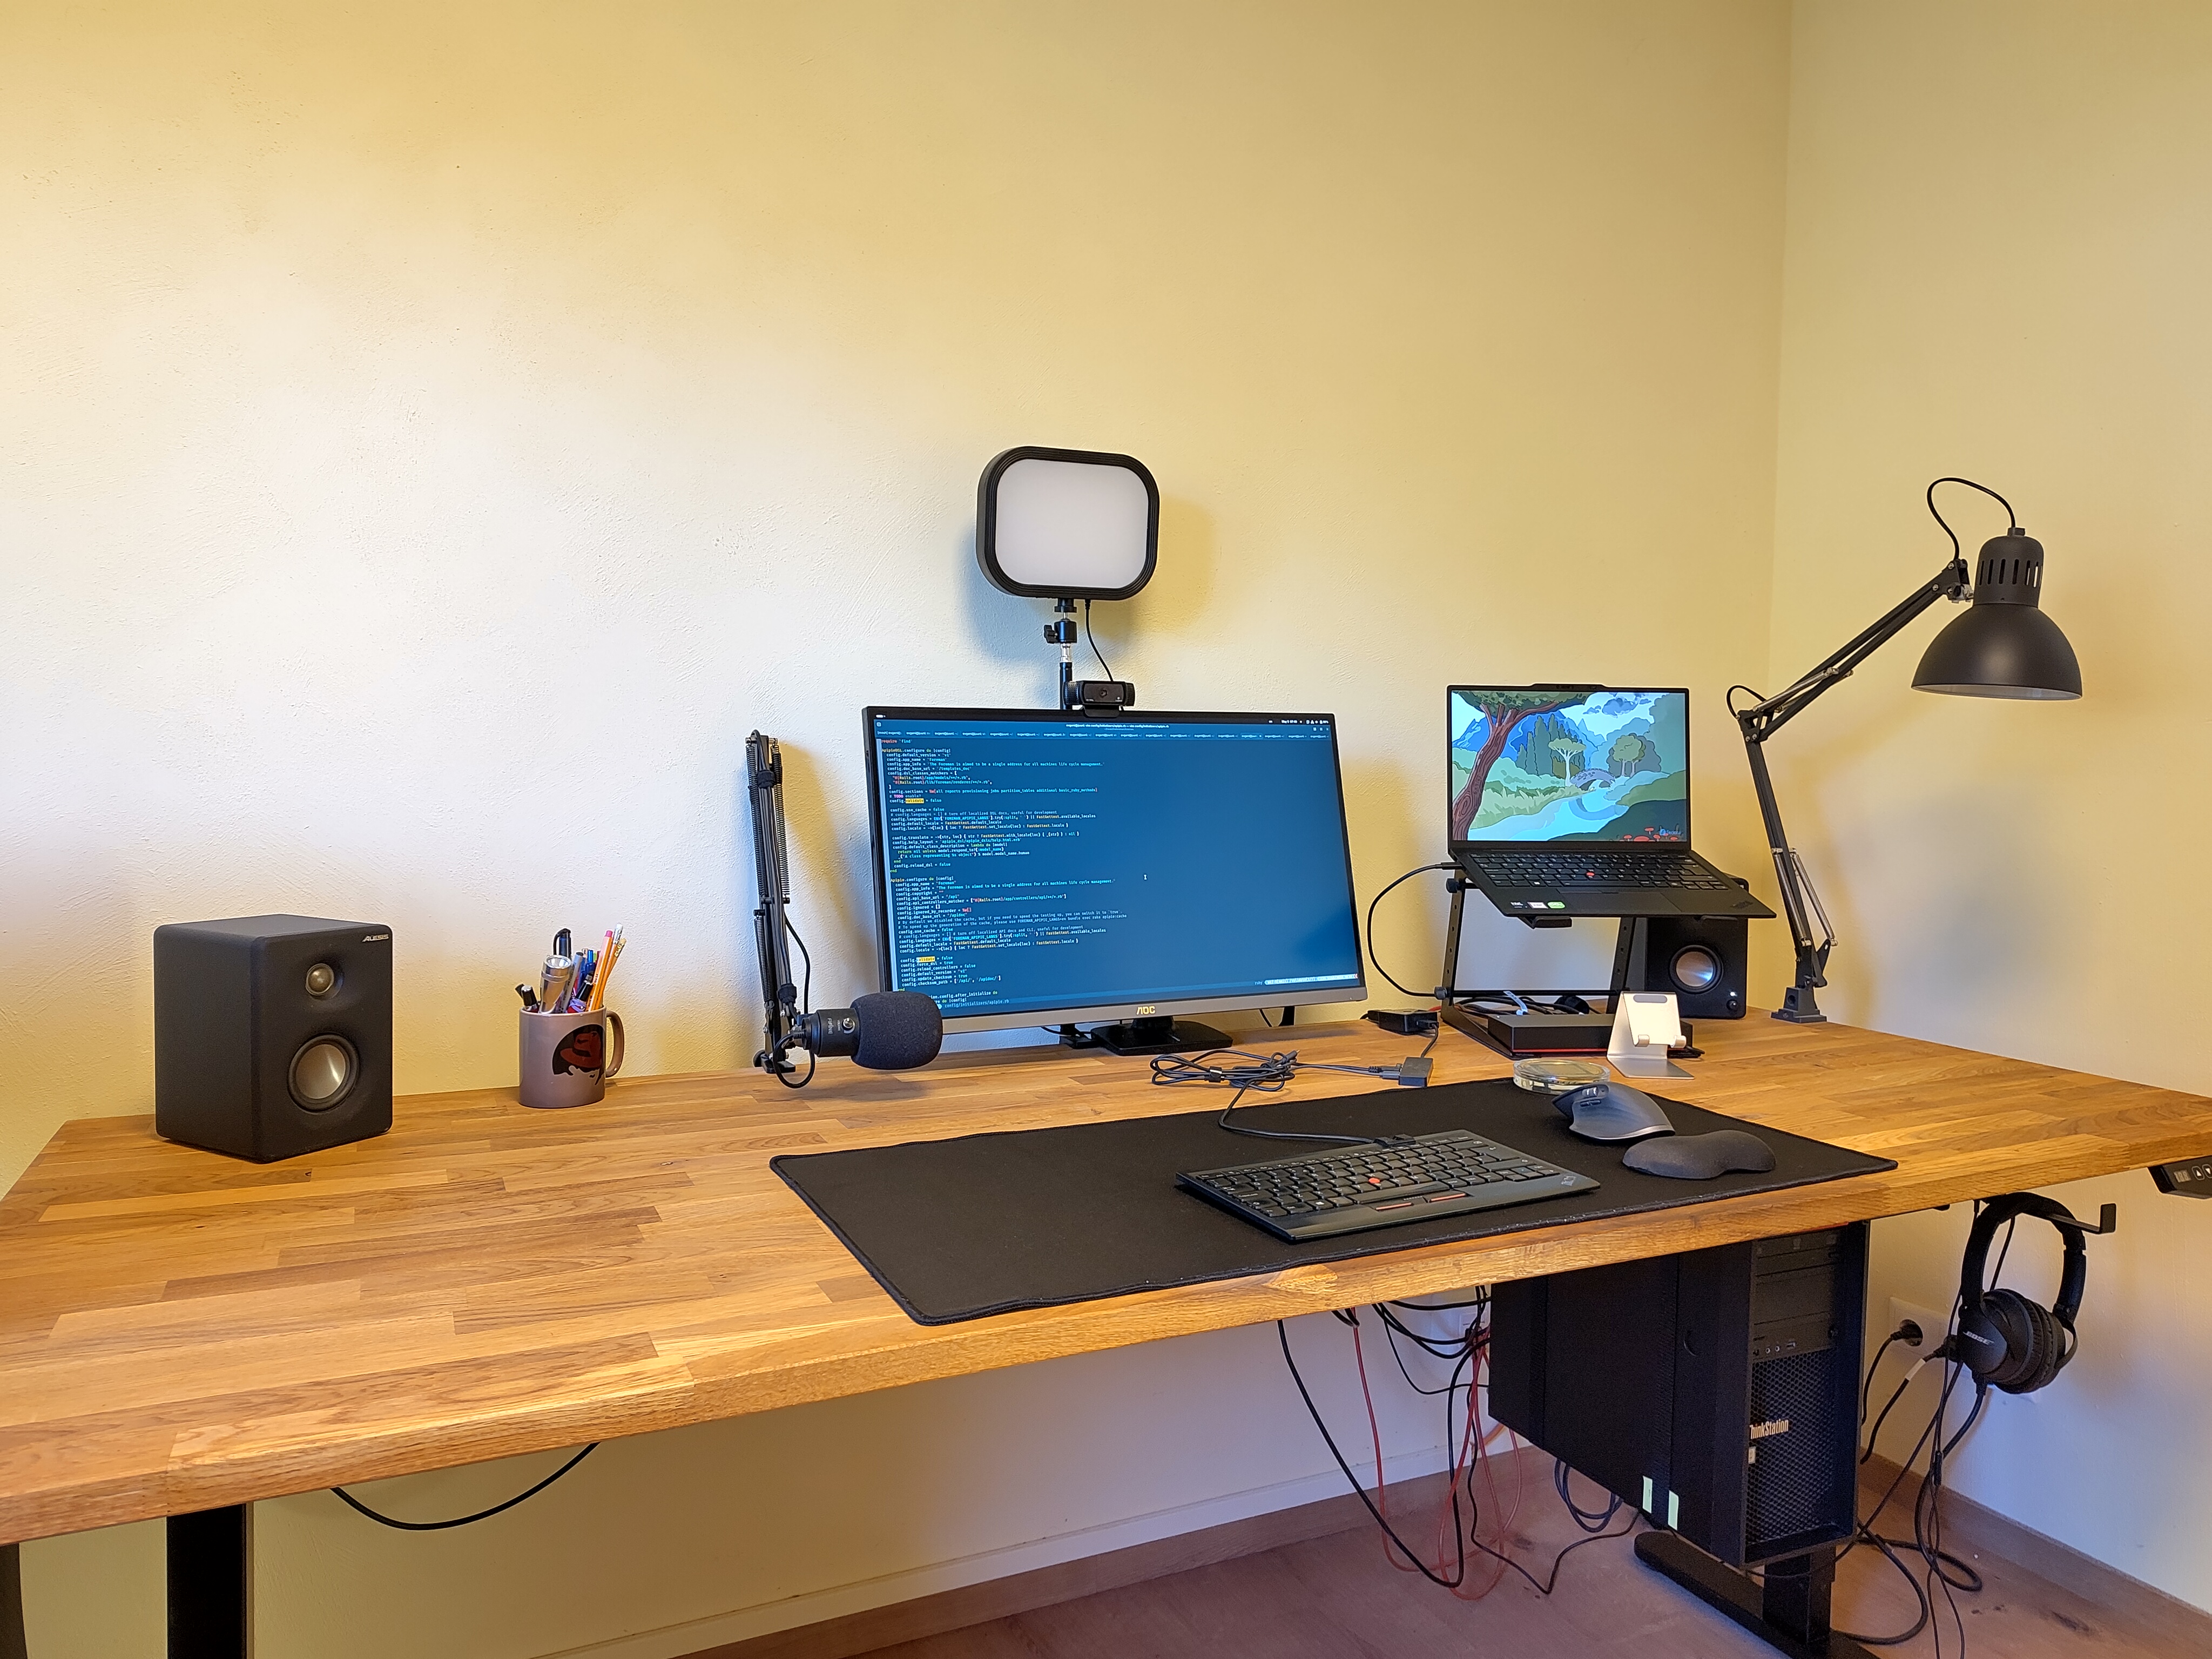
Back in 2020 I posted about my desk setup at home. Recently someone in our #remotees channel at work asked about WFH setups and given quite a few things changed in mine, I thought it's time to post an update. But first, a picture! standing desk with a monitor, laptop etc (Yes, it's cleaner than usual, how could you tell?!) desk It's still the same Flexispot E5B, no change here. After 7 years (I bought mine in 2018) it still works fine. If I'd have to buy a new one, I'd probably get a four-legged one for more stability (they got quite affordable now), but there is no immediate need for that. chair It's still the IKEA Volmar. Again, no complaints here. hardware Now here we finally have some updates! laptop A Lenovo ThinkPad X1 Carbon Gen 12, Intel Core Ultra 7 165U, 32GB RAM, running Fedora (42 at the moment). It's connected to a Lenovo ThinkPad Thunderbolt 4 Dock. It just works . workstation It's still the P410, but mostly unused these days. monitor An AOC U2790PQU 27" 4K. I'm running it at 150% scaling, which works quite decently these days (no comparison to when I got it). speakers As the new monitor didn't want to take the old Dell soundbar, I have upgraded to a pair of Alesis M1Active 330 USB. They sound good and were not too expensive. I had to fix the volume control after some time though. webcam It's still the Logitech C920 Pro. microphone The built in mic of the C920 is really fine, but to do conference-grade talks (and some podcasts ), I decided to get something better. I got a FIFINE K669B, with a nice arm. It's not a Shure, for sure, but does the job well and Christian was quite satisfied with the results when we recorded the Debian and Foreman specials of Focus on Linux. keyboard It's still the ThinkPad Compact USB Keyboard with TrackPoint. I had to print a few fixes and replacement parts for it, but otherwise it's doing great. Seems Lenovo stopped making those, so I really shouldn't break it any further. mouse Logitech MX Master 3S. The surface of the old MX Master 2 got very sticky at some point and it had to be replaced. other notepad I'm still terrible at remembering things, so I still write them down in an A5 notepad. whiteboard I've also added a (small) whiteboard on the wall right of the desk, mostly used for long term todo lists. coaster Turns out Xeon-based coasters are super stable, so it lives on! yubikey Yepp, still a thing. Still USB-A because... reasons. headphones Still the Bose QC25, by now on the third set of ear cushions, but otherwise working great and the odd 15 cushion replacement does not justify buying anything newer (which would have the same problem after some time, I guess). I did add a cheap (~10 ) Bluetooth-to-Headphonejack dongle, so I can use them with my phone too (shakes fist at modern phones). And I do use the headphones more in meetings, as the Alesis speakers fill the room more with sound and thus sometimes produce a bit of an echo. charger The Bose need AAA batteries, and so do some other gadgets in the house, so there is a technoline BC 700 charger for AA and AAA on my desk these days. light Yepp, I've added an IKEA Tertial and an ALDI "face" light. No, I don't use them much. KVM switch I've "built" a KVM switch out of an USB switch, but given I don't use the workstation that often these days, the switch is also mostly unused.

6 June 2025

Reproducible Builds: Reproducible Builds in May 2025

Welcome to our 5th report from the Reproducible Builds project in 2025! Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please do visit the Contribute page on our website. In this report:
  1. Security audit of Reproducible Builds tools published
  2. When good pseudorandom numbers go bad
  3. Academic articles
  4. Distribution work
  5. diffoscope and disorderfs
  6. Website updates
  7. Reproducibility testing framework
  8. Upstream patches

Security audit of Reproducible Builds tools published The Open Technology Fund s (OTF) security partner Security Research Labs recently an conducted audit of some specific parts of tools developed by Reproducible Builds. This form of security audit, sometimes called a whitebox audit, is a form testing in which auditors have complete knowledge of the item being tested. They auditors assessed the various codebases for resilience against hacking, with key areas including differential report formats in diffoscope, common client web attacks, command injection, privilege management, hidden modifications in the build process and attack vectors that might enable denials of service. The audit focused on three core Reproducible Builds tools: diffoscope, a Python application that unpacks archives of files and directories and transforms their binary formats into human-readable form in order to compare them; strip-nondeterminism, a Perl program that improves reproducibility by stripping out non-deterministic information such as timestamps or other elements introduced during packaging; and reprotest, a Python application that builds source code multiple times in various environments in order to to test reproducibility. OTF s announcement contains more of an overview of the audit, and the full 24-page report is available in PDF form as well.

When good pseudorandom numbers go bad Danielle Navarro published an interesting and amusing article on their blog on When good pseudorandom numbers go bad. Danielle sets the stage as follows:
[Colleagues] approached me to talk about a reproducibility issue they d been having with some R code. They d been running simulations that rely on generating samples from a multivariate normal distribution, and despite doing the prudent thing and using set.seed() to control the state of the random number generator (RNG), the results were not computationally reproducible. The same code, executed on different machines, would produce different random numbers. The numbers weren t just a little bit different in the way that we ve all wearily learned to expect when you try to force computers to do mathematics. They were painfully, brutally, catastrophically, irreproducible different. Somewhere, somehow, something broke.
Thanks to David Wheeler for posting about this article on our mailing list

Academic articles There were two scholarly articles published this month that related to reproducibility: Daniel Hugenroth and Alastair R. Beresford of the University of Cambridge in the United Kingdom and Mario Lins and Ren Mayrhofer of Johannes Kepler University in Linz, Austria published an article titled Attestable builds: compiling verifiable binaries on untrusted systems using trusted execution environments. In their paper, they:
present attestable builds, a new paradigm to provide strong source-to-binary correspondence in software artifacts. We tackle the challenge of opaque build pipelines that disconnect the trust between source code, which can be understood and audited, and the final binary artifact, which is difficult to inspect. Our system uses modern trusted execution environments (TEEs) and sandboxed build containers to provide strong guarantees that a given artifact was correctly built from a specific source code snapshot. As such it complements existing approaches like reproducible builds which typically require time-intensive modifications to existing build configurations and dependencies, and require independent parties to continuously build and verify artifacts.
The authors compare attestable builds with reproducible builds by noting an attestable build requires only minimal changes to an existing project, and offers nearly instantaneous verification of the correspondence between a given binary and the source code and build pipeline used to construct it , and proceed by determining that t he overhead (42 seconds start-up latency and 14% increase in build duration) is small in comparison to the overall build time.
Timo Pohl, Pavel Nov k, Marc Ohm and Michael Meier have published a paper called Towards Reproducibility for Software Packages in Scripting Language Ecosystems. The authors note that past research into Reproducible Builds has focused primarily on compiled languages and their ecosystems, with a further emphasis on Linux distribution packages:
However, the popular scripting language ecosystems potentially face unique issues given the systematic difference in distributed artifacts. This Systemization of Knowledge (SoK) [paper] provides an overview of existing research, aiming to highlight future directions, as well as chances to transfer existing knowledge from compiled language ecosystems. To that end, we work out key aspects in current research, systematize identified challenges for software reproducibility, and map them between the ecosystems.
Ultimately, the three authors find that the literature is sparse , focusing on few individual problems and ecosystems, and therefore identify space for more critical research.

Distribution work In Debian this month:
Hans-Christoph Steiner of the F-Droid catalogue of open source applications for the Android platform published a blog post on Making reproducible builds visible. Noting that Reproducible builds are essential in order to have trustworthy software , Hans also mentions that F-Droid has been delivering reproducible builds since 2015 . However:
There is now a Reproducibility Status link for each app on f-droid.org, listed on every app s page. Our verification server shows or based on its build results, where means our rebuilder reproduced the same APK file and means it did not. The IzzyOnDroid repository has developed a more elaborate system of badges which displays a for each rebuilder. Additionally, there is a sketch of a five-level graph to represent some aspects about which processes were run.
Hans compares the approach with projects such as Arch Linux and Debian that provide developer-facing tools to give feedback about reproducible builds, but do not display information about reproducible builds in the user-facing interfaces like the package management GUIs.
Arnout Engelen of the NixOS project has been working on reproducing the minimal installation ISO image. This month, Arnout has successfully reproduced the build of the minimal image for the 25.05 release without relying on the binary cache. Work on also reproducing the graphical installer image is ongoing.
In openSUSE news, Bernhard M. Wiedemann posted another monthly update for their work there.
Lastly in Fedora news, Jelle van der Waa opened issues tracking reproducible issues in Haskell documentation, Qt6 recording the host kernel and R packages recording the current date. The R packages can be made reproducible with packaging changes in Fedora.

diffoscope & disorderfs diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 295, 296 and 297 to Debian:
  • Don t rely on zipdetails --walk argument being available, and only add that argument on newer versions after we test for that. [ ]
  • Review and merge support for NuGet packages from Omair Majid. [ ]
  • Update copyright years. [ ]
  • Merge support for an lzma comparator from Will Hollywood. [ ][ ]
Chris also merged an impressive changeset from Siva Mahadevan to make disorderfs more portable, especially on FreeBSD. disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into directory system calls in order to flush out reproducibility issues [ ]. This was then uploaded to Debian as version 0.6.0-1. Lastly, Vagrant Cascadian updated diffoscope in GNU Guix to version 296 [ ][ ] and 297 [ ][ ], and disorderfs to version 0.6.0 [ ][ ].

Website updates Once again, there were a number of improvements made to our website this month including:

Reproducibility testing framework The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. However, Holger Levsen posted to our mailing list this month in order to bring a wider awareness to funding issues faced by the Oregon State University (OSU) Open Source Lab (OSL). As mentioned on OSL s public post, recent changes in university funding makes our current funding model no longer sustainable [and that] unless we secure $250,000 in committed funds, the OSL will shut down later this year . As Holger notes in his post to our mailing list, the Reproducible Builds project relies on hardware nodes hosted there. Nevertheless, Lance Albertson of OSL posted an update to the funding situation later in the month with broadly positive news.
Separate to this, there were various changes to the Jenkins setup this month, which is used as the backend driver of for both tests.reproducible-builds.org and reproduce.debian.net, including:
  • Migrating the central jenkins.debian.net server AMD Opteron to Intel Haswell CPUs. Thanks to IONOS for hosting this server since 2012.
  • After testing it for almost ten years, the i386 architecture has been dropped from tests.reproducible-builds.org. This is because that, with the upcoming release of Debian trixie, i386 is no longer supported as a regular architecture there will be no official kernel and no Debian installer for i386 systems. As a result, a large number of nodes hosted by Infomaniak have been retooled from i386 to amd64.
  • Another node, ionos17-amd64.debian.net, which is used for verifying packages for all.reproduce.debian.net (hosted by IONOS) has had its memory increased from 40 to 64GB, and the number of cores doubled to 32 as well. In addition, two nodes generously hosted by OSUOSL have had their memory doubled to 16GB.
  • Lastly, we have been granted access to more riscv64 architecture boards, so now we have seven such nodes, all with 16GB memory and 4 cores that are verifying packages for riscv64.reproduce.debian.net. Many thanks to PLCT Lab, ISCAS for providing those.

Outside of this, a number of smaller changes were also made by Holger Levsen:
  • reproduce.debian.net-related:
    • Only use two workers for the ppc64el architecture due to RAM size. [ ]
    • Monitor nginx_request and nginx_status with the Munin monitoring system. [ ][ ]
    • Detect various variants of network and memory errors. [ ][ ][ ][ ]
    • Add a prominent link to reproducible-builds.org. [ ]
    • Add a rebuilderd-cache-cleanup.service and run it daily via timer. [ ][ ][ ][ ][ ]
    • Be more verbose what sources are being downloaded. [ ]
    • Correctly deal with packages with an epoch in their version [ ] and deal with binNMUs versions with an epoch as well [ ][ ].
    • Document how to reschedule all other errors on all archs. [ ]
    • Misc documentation improvements. [ ][ ][ ][ ]
    • Include the $HOSTNAME variable in the rebuilderd logfiles. [ ]
    • Install the equivs package on all worker nodes. [ ][ ]
  • Jenkins nodes:
    • Permit the sudo tool to fix up permission issues. [ ][ ]
    • Document how to manage diskspace with OpenStack. [ ]
    • Ignore a number of spurious monitoring errors on riscv64, FreeBSD, etc.. [ ][ ][ ][ ]
    • Install ntpsec-ntpdate (instead of ntpdate) as the former is available on Debian trixie and bookworm. [ ][ ]
    • Use the same SSH ControlPath for all nodes. [ ]
    • Make sure the munin user uses the same SSH config as the jenkins user. [ ]
  • tests.reproducible-builds.org-related:
    • Disable testing of the i386 architecture. [ ][ ][ ][ ][ ]
    • Document the current disk usage. [ ][ ]
    • Address some image placement now that we only test three architectures. [ ]
    • Keep track of build performance. [ ]
  • Misc:
    • Fix a (harmless) typo in the multiarch_versionskew script. [ ]
In addition, Jochen Sprickerhof made a series of changes related to reproduce.debian.net:
  • Add out of memory detection to the statistics page. [ ]
  • Reverse the sorting order on the statistics page. [ ][ ][ ][ ]
  • Improve the spacing between statistics groups. [ ]
  • Update a (hard-coded) line number in error message detection pertaining to a debrebuild line number. [ ]
  • Support Debian unstable in the rebuilder-debian.sh script. [ ] ]
  • Rely on rebuildctl to sync only arch-specific packages. [ ][ ]

Upstream patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. This month, we wrote a large number of such patches, including:

Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Dirk Eddelbuettel: #49: The Two Cultures of Deploying Statistical Software

Welcome to post 49 in the R4 series. The Two Cultures is a term first used by C.P. Snow in a 1959 speech and monograph focused on the split between humanities and the sciences. Decades later, the term was (quite famously) re-used by Leo Breiman in a (somewhat prophetic) 2001 article about the split between data models and algorithmic models . In this note, we argue that statistical computing practice and deployment can also be described via this Two Cultures moniker. Referring to the term linking these foundational pieces is of course headline bait. Yet when preparing for the discussion of r2u in the invited talk in Mons (video, slides), it occurred to me that there is in fact a wide gulf between two alternative approaches of using R and, specifically, deploying packages. On the one hand we have the approach described by my friend Jeff as you go to the Apple store, buy the nicest machine you can afford, install what you need and then never ever touch it . A computer / workstation / laptop is seen as an immutable object where every attempt at change may lead to breakage, instability, and general chaos and is hence best avoided. If you know Jeff, you know he exaggerates. Maybe only slightly though. Similarly, an entire sub-culture of users striving for reproducibility (and sometimes also replicability ) does the same. This is for example evidenced by the popularity of package renv by Rcpp collaborator and pal Kevin. The expressed hope is that by nailing down a (sub)set of packages, outcomes are constrained to be unchanged. Hope springs eternal, clearly. (Personally, if need be, I do the same with Docker containers and their respective Dockerfile.) On the other hand, rolling is fundamentally different approach. One (well known) example is Google building everything at @HEAD . The entire (ginormous) code base is considered as a mono-repo which at any point in time is expected to be buildable as is. All changes made are pre-tested to be free of side effects to other parts. This sounds hard, and likely is more involved than an alternative of a whatever works approach of independent changes and just hoping for the best. Another example is a rolling (Linux) distribution as for example Debian. Changes are first committed to a staging place (Debian calls this the unstable distribution) and, if no side effects are seen, propagated after a fixed number of days to the rolling distribution (called testing ). With this mechanism, testing should always be installable too. And based on the rolling distribution, at certain times (for Debian roughly every two years) a release is made from testing into stable (following more elaborate testing). The released stable version is then immutable (apart from fixes for seriously grave bugs and of course security updates). So this provides the connection between frequent and rolling updates, and produces immutable fixed set: a release. This Debian approach has been influential for any other projects including CRAN as can be seen in aspects of its system providing a rolling set of curated packages. Instead of a staging area for all packages, extensive tests are made for candidate packages before adding an update. This aims to ensure quality and consistence and has worked remarkably well. We argue that it has clearly contributed to the success and renown of CRAN. Now, when accessing CRAN from R, we fundamentally have two accessor functions. But seemingly only one is widely known and used. In what we may call the Jeff model , everybody is happy to deploy install.packages() for initial installations. That sentiment is clearly expressed by this bsky post:
One of my #rstats coding rituals is that every time I load a @vincentab.bsky.social package I go check for a new version because invariably it s been updated with 18 new major features
And that is why we have two cultures. Because some of us, yours truly included, also use update.packages() at recurring (frequent !!) intervals: daily or near-daily for me. The goodness and, dare I say, gift of packages is not limited to those by my pal Vincent. CRAN updates all the time, and updates are (generally) full of (usually excellent) changes, fixes, or new features. So update frequently! Doing (many but small) updates (frequently) is less invasive than (large, infrequent) waterfall -style changes! But the fear of change, or disruption, is clearly pervasive. One can only speculate why. Is the experience of updating so painful on other operating systems? Is it maybe a lack of exposure / tutorials on best practices? These Two Cultures coexist. When I delivered the talk in Mons, I briefly asked for a show of hands among all the R users in the audience to see who in fact does use update.packages() regularly. And maybe a handful of hands went up: surprisingly few! Now back to the context of installing packages: Clearly only installing has its uses. For continuous integration checks we generally install into ephemeral temporary setups. Some debugging work may be with one-off container or virtual machine setups. But all other uses may well be under maintained setups. So consider calling update.packages() once in while. Or even weekly or daily. The rolling feature of CRAN is a real benefit, and it is there for the taking and enrichment of your statistical computing experience. So to sum up, the real power is to use For both tasks, relying on binary installations accelerates and eases the process. And where available, using binary installation with system-dependency support as r2u does makes it easier still, following the r2u slogan of Fast. Easy. Reliable. Pick All Three. Give it a try!

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

5 June 2025

Matthew Garrett: Twitter's new encrypted DMs aren't better than the old ones

(Edit: Twitter could improve this significantly with very few changes - I wrote about that here. It's unclear why they'd launch without doing that, since it entirely defeats the point of using HSMs)

When Twitter[1] launched encrypted DMs a couple
of years ago, it was the worst kind of end-to-end
encrypted - technically e2ee, but in a way that made it relatively easy for Twitter to inject new encryption keys and get everyone's messages anyway. It was also lacking a whole bunch of features such as "sending pictures", so the entire thing was largely a waste of time. But a couple of days ago, Elon announced the arrival of "XChat", a new encrypted message platform built on Rust with (Bitcoin style) encryption, whole new architecture. Maybe this time they've got it right?

tl;dr - no. Use Signal. Twitter can probably obtain your private keys, and admit that they can MITM you and have full access to your metadata.

The new approach is pretty similar to the old one in that it's based on pretty straightforward and well tested cryptographic primitives, but merely using good cryptography doesn't mean you end up with a good solution. This time they've pivoted away from using the underlying cryptographic primitives directly and into higher level abstractions, which is probably a good thing. They're using Libsodium's boxes for message encryption, which is, well, fine? It doesn't offer forward secrecy (if someone's private key is leaked then all existing messages can be decrypted) so it's a long way from the state of the art for a messaging client (Signal's had forward secrecy for over a decade!), but it's not inherently broken or anything. It is, however, written in C, not Rust[2].

That's about the extent of the good news. Twitter's old implementation involved clients generating keypairs and pushing the public key to Twitter. Each client (a physical device or a browser instance) had its own private key, and messages were simply encrypted to every public key associated with an account. This meant that new devices couldn't decrypt old messages, and also meant there was a maximum number of supported devices and terrible scaling issues and it was pretty bad. The new approach generates a keypair and then stores the private key using the Juicebox protocol. Other devices can then retrieve the private key.

Doesn't this mean Twitter has the private key? Well, no. There's a PIN involved, and the PIN is used to generate an encryption key. The stored copy of the private key is encrypted with that key, so if you don't know the PIN you can't decrypt the key. So we brute force the PIN, right? Juicebox actually protects against that - before the backend will hand over the encrypted key, you have to prove knowledge of the PIN to it (this is done in a clever way that doesn't directly reveal the PIN to the backend). If you ask for the key too many times while providing the wrong PIN, access is locked down.

But this is true only if the Juicebox backend is trustworthy. If the backend is controlled by someone untrustworthy[3] then they're going to be able to obtain the encrypted key material (even if it's in an HSM, they can simply watch what comes out of the HSM when the user authenticates if there's no validation of the HSM's keys). And now all they need is the PIN. Turning the PIN into an encryption key is done using the Argon2id key derivation function, using 32 iterations and a memory cost of 16MB (the Juicebox white paper says 16KB, but (a) that's laughably small and (b) the code says 16 * 1024 in an argument that takes kilobytes), which makes it computationally and moderately memory expensive to generate the encryption key used to decrypt the private key. How expensive? Well, on my (not very fast) laptop, that takes less than 0.2 seconds. How many attempts to I need to crack the PIN? Twitter's chosen to fix that to 4 digits, so a maximum of 10,000. You aren't going to need many machines running in parallel to bring this down to a very small amount of time, at which point private keys can, to a first approximation, be extracted at will.

Juicebox attempts to defend against this by supporting sharding your key over multiple backends, and only requiring a subset of those to recover the original. I can't find any evidence that Twitter's does seem to be making use of this,Twitter uses three backends and requires data from at least two, but all the backends used are under x.com so are presumably under Twitter's direct control. Trusting the keystore without needing to trust whoever's hosting it requires a trustworthy communications mechanism between the client and the keystore. If the device you're talking to can prove that it's an HSM that implements the attempt limiting protocol and has no other mechanism to export the data, this can be made to work. Signal makes use of something along these lines using Intel SGX for contact list and settings storage and recovery, and Google and Apple also have documentation about how they handle this in ways that make it difficult for them to obtain backed up key material. Twitter has no documentation of this, and as far as I can tell does nothing to prove that the backend is in any way trustworthy. (Edit to add: The Juicebox API does support authenticated communication between the client and the HSM, but that relies on you having some way to prove that the public key you're presented with corresponds to a private key that only exists in the HSM. Twitter gives you the public key whenever you communicate with them, so even if they've implemented this properly you can't prove they haven't made up a new key and MITMed you the next time you retrieve your key)

On the plus side, Juicebox is written in Rust, so Elon's not 100% wrong. Just mostly wrong.

But ok, at least you've got viable end-to-end encryption even if someone can put in some (not all that much, really) effort to obtain your private key and render it all pointless? Actually no, since you're still relying on the Twitter server to give you the public key of the other party and there's no out of band mechanism to do that or verify the authenticity of that public key at present. Twitter can simply give you a public key where they control the private key, decrypt the message, and then reencrypt it with the intended recipient's key and pass it on. The support page makes it clear that this is a known shortcoming and that it'll be fixed at some point, but they said that about the original encrypted DM support and it never was, so that's probably dependent on whether Elon gets distracted by something else again. And the server knows who and when you're messaging even if they haven't bothered to break your private key, so there's a lot of metadata leakage.

Signal doesn't have these shortcomings. Use Signal.

[1] I'll respect their name change once Elon respects his daughter

[2] There are implementations written in Rust, but Twitter's using the C one with these JNI bindings

[3] Or someone nominally trustworthy but who's been compelled to act against your interests - even if Elon were absolutely committed to protecting all his users, his overarching goals for Twitter require him to have legal presence in multiple jurisdictions that are not necessarily above placing employees in physical danger if there's a perception that they could obtain someone's encryption keys

comment count unavailable comments

4 June 2025

Gunnar Wolf: The subjective value of privacy Assessing individuals' calculus of costs and benefits in the context of state surveillance

This post is an unpublished review for The subjective value of privacy Assessing individuals' calculus of costs and benefits in the context of state surveillance
Internet users, software developers, academics, entrepreneurs basically everybody is now aware of the importance of considering privacy as a core part of our online experience. User demand, and various national or regional laws, have made privacy a continuously present subject. And privacy is such an all-encompassing, complex topic, the angles from which it can be studied seems never to finish; I recommend computer networking-oriented newcomers to the topic to refer to Brian Kernighan s excellent work [1]. However, how do regular people like ourselves, in our many capacities feel about privacy? Lukas Antoine presents a series of experiments aiming at better understanding how people throughout the world understands privacy, and when is privacy held as more or less important than security in different aspects, Particularly, privacy is often portrayed as a value set at tension against surveillance, and particularly state surveillance, in the name of security: conventional wisdom presents the idea of privacy calculus. This is, it is often assumed that individuals continuously evaluate the costs and benefits of divulging their personal data, sharing data when they expect a positive net outcome, and denying it otherwise. This framework has been accepted for decades, and the author wishes to challenge it. This book is clearly his doctoral thesis on political sciences, and its contents are as thorough as expected in this kind of product. The author presents three empirical studies based on cross-survey analysis. The first experiment explores the security justifications for surveillance and how they influence their support. The second one searches whether the stance on surveillance can be made dependent on personal convenience or financial cost. The third study explores whether privacy attitude is context-dependant or can be seen as a stable personality trait. The studies aim to address the shortcomings of published literature in the field, mainly, (a) the lack of comprehensive research on state surveillance, needed or better understanding privacy appreciation, (b) while several studies have tackled the subjective measure of privacy, there is a lack of cross-national studies to explain wide-ranging phenomena, (c) most studies in this regard are based on population-based surveys, which cannot establish causal relationships, (d) a seemingly blind acceptance of the privacy calculus mentioned above, with no strong evidence that it accurately measures people s motivations for disclosing or withholding their data. The specific take, including the framing of the tension between privacy and surveillance has long been studied, as can be seen in Steven Nock s 1993 book [2], but as Sannon s article in 2022 shows [3], social and technological realities require our undertanding to be continuously kept up to date. The book is full with theoretical references and does a very good job of explaining the path followed by the author. It is, though, a heavy read, and, for people not coming from the social sciences tradition, leads to the occasional feeling of being lost. The conceptual and theoretical frameworks and presented studies are thorough and clear. The author is honest in explaining when the data points at some of his hypotheses being disproven, while others are confirmed. The aim of the book is for people digging deep into this topic. Personally, I have authored several works on different aspects of privacy (such as a book [4] and a magazine number [5]), but this book did get me thinking on many issues I had not previously considered. Looking for comparable works, I find Friedewald et al. s 2017 book [6] chapter organization to follow a similar thought line. My only complaint would be that, for the publication as part of its highly prestigious publisher, little attention has been paid to editorial aspects: sub-subsection depth is often excessive and unclear. Also, when publishing monographs based on doctoral works, it is customary to no longer refer to the work as a thesis and to soften some of the formal requirements such a work often has, with the aim of producing a more gentle and readable book; this book seems just like the mass-production of an (otherwise very interesting and well made) thesis work. References:

Gunnar Wolf: Humanities and big data in Ibero-America Theory, methodology and practical applications

This post is an unpublished review for Humanities and big data in Ibero-America Theory, methodology and practical applications
Digital humanities is a young though established field. It deals with different expressions in which digital data manipulation techniques can be applied and used to analyze subjects that are identified as belonging to the humanities. Although most often used to analyze different aspects of literature or social network analysis, it can also be applied to other humanistic disciplines or artistic expressions. Digital humanities employs many tools, but those categorized as big data are among the most frequently employed. This book samples different takes on digital humanities, with the particularity that it focuses on Ibero-American uses. It is worth noting that this book is the second in a series of four volumes, published or set to be published between 2022 and 2026. Being the output of a field survey, I perceive this book to be targeted towards fellow Digital Humanists people interested in applying computational methods to further understand and research topics in the humanities. It is not a technical book in the sense Computer Science people would recognize as such, but several of the presented works do benefit from understanding some technical concepts. The 12 articles (plus an introduction) that make up this book are organized in three parts: (1) Theoretical Framework presents the ideas and techniques of data science (that make up the tools for handling big data), and explores how data science can contribute to literary analysis, all while noting that many such techniques are usually frowned upon in Latin America as data science smells neoliberal ; (2) Methodological Issues looks at specific issues through the lens of how they can be applied to big data, with specific attention given to works in Spanish; and (3) Practical Applications analyzes specific Spanish works and communities based on big data techniques. Several chapters treat a recurring theme: the simultaneous resistance and appropriation of big data by humanists. For example, at least three of the chapters describe the tensions between humanism ( aesthesis ) and cold, number-oriented data analysis ( mathesis ). The analyzed works of Parts 2 and 3 are interesting and relatively easy to follow. Some inescapable ideological gleans from several word uses from the book s and series name, which refers to the Spanish-speaking regions as Ibero-America , often seen as Eurocentric, in contrast with the Latin America term much more widely used throughout the region. I will end with some notes about the specific versions of the book I reviewed. I read both an EPUB version and a print copy. The EPUB did not include links for easy navigation to footnotes, that is, the typographical superindexes are not hyperlinked to the location of the notes, so it is very impractical to try to follow them. The print version (unlike the EPUB) did not have an index, that is, the six pages before the introduction are missing from the print copy I received. For a book such as this one, not having an index hampers the ease of reading and referencing.

Gunnar Wolf: Computational modelling of robot personhood and relationality

This post is an unpublished review for Computational modelling of robot personhood and relationality
If humans and robots were to be able to roam around the same spaces, mutually recognizing each other for what they are, how would interaction be? How can we model such interactions in a way that we can reason about and understand the implications of a given behavior? This book aims at answering this question. The book is split into two very different parts. Chapters 1 through 3 are mostly written with a philosophical angle. It starts by framing the possibility of having sentient androids exist in the same plane as humans, without them trying to pass as us or vice versa. The first chapters look at issues related to personhood, that is, how androids can be treated as valid interaction partners in a society with humans, and how interactions with them can be seen as meaningful. In doing so, several landmarks of the past 40 years in the AI field are reviewed. The issues of the Significant Concerns that make up a society and give it coherence and of Personhood and Relationality , describing how this permeates from a society into each of the individuals that make it up, the relations between them and the social objects that bring individuals closer together (or farther apart) are introduced and explained. The second part of the book is written from a very different angle, and the change in pace took me somewhat by surprise. Each subsequent chapter presents a different angle of the Affinity system, a model that follows some aspects of human behavior over time and in a given space. Chapter 4 introduces the Affinity environment: a 3D simulated environment with simulated physical laws and characteristics, where a number of agents (30-50 is mentioned as usual) interact. Agents have a series of attributes ( value memory ), can adhere to different programs ( narratives ), and gain or lose on some vectors ( economy ). They can sense the world around them with sensors, and can modify the world or signal other agents using effectors. The last two chapters round out the book, as expected: the first presents a set of results from analyzing a given set of value systems, and the second gives readers the conclusions reached by the author. However, I was expecting more either having at least a link to download the Affinity system and continue exploring it or modifying some of the aspects it models to get it to model a set of agents with different stories and narratives, or extend it to yet unforseen behaviors, or at least have the author present a more complete comparison of results than the evaluation of patterns resulting from a given run. The author is a well-known, prolific author in the field, and I was expecting bigger insights from this book. Nevertheless, the book is an interesting and fun read, with important insights in both the first and second parts. There is a certain lack of connection between their respective rhythms, and the second part indeed builds on the concepts introduced in the first one. Overall, I enjoyed reading the book despite expecting more.

Next.

Previous.