Search Results: "tar"

19 September 2010

Joerg Jaspert: FTPMaster meeting, II - NO baklava

Wanted to post this yesterday, but somehow didnt work out, so here we go now Another meeting day passed, another lot of commits into our repository, another day without entirely breaking the system. But wait, one more chance to break it today, maybe we finally manage. :) Yesterday we got volatile sorted out for Squeeze (Lenny stays like it is, seperate). Its now a suite on ftp-master, and we have all the neccessary information and workflow around it defined. At least so far that we can operate the suite, we don t define what gets into it, we just take that from the volatile team (or, I think, in future, from the SRMs) in a kind of textfile similar to how testing works. Besides having Alex unbreak our bts categorize script, Mark fixing up our BYHAND processing and implementing the volatile stuff I mentioned above, we also merged a patchset from Luca that allows us to provide the packages.debian.org service with a tree containing changelogs, copyright files, NEWS.Debian and README.Debian. Metadata basically. Which they extracted in the past, and that was taking up quite a lot of resources. Much easier if we provide it and they just use it. This is now done for both, the main archive as well as the backports archive. As soon as I upgrade the security archive it will also be done there, which should additionally enable packages.debian.org to display those files for all archives (run by FTPMaster). This update is scheduled for the upcoming week, DSA already gave me the needed bits and pieces on a host so I can do it without breaking security during the process. We currently export this metadata set only to the packages.debian.org host. We do want to provide it to more, but I am waiting for a reply from DSA as to which machine I should use for the open access to those files. When I have that reply it should be available for you all. As a sidenote from that: If you need to compute any data that has to do with the Debian archive (information out of source/binary packages or something around it) and if you do that with your own scripts - you are most likely doing it wrong. Talk to us. We might be able to help you extracting the data you need and keep it updated. Recent examples for that are the above changelogs, but also things like the package-file-mapping snapshot uses to easily determine which file belongs to which source/version, but also information like the Maintainers index, the Uploaders index and whatnot. The simple way is - ask us. We are processing a shitload of data, it might not be too complicated to let your set fall out somewhere at the side, but if you never ask you will never find out Today we start working on some internals of dak and will have some more discussion on agenda points like data.debian.org and the git source format. We already had some words on other points, but those are ones which will take a long time more to fix, like generally reworking the internals of our database to enable us having multiple archives with pretty different access levels inside one machine. (Think of security archive on ftpmaster host. You want to ensure embargoed security issues actually stay embargoed until they are released. Means a good set of neccessary changes inside the database to handle this. We have ideas, but getting them implemented will take a bit).
And of course we had been out for food too, helps to stay alive. Turkish restaurant. All nice and well - until they told us they have NO BAKLAVA. Args. Suckers. They ruined this year! WAAAAAAAAAAAAAAAAH. I wish them a windows OS for their live! If not worse! (Can it be worse than windows?) ;-)

Asheesh Laroia: When "free software" got a new name

On January 30, 1998, Wired.com gushed about the ethical underpinnings of the free software movement. The movement was growing:
Netscape's bold move last week [was] to free the source code of its browser is a prime-time endorsement for no-cost, build-it-yourself software.
The free software movement was in its second decade. In the first decade, corporations learned to tolerate it. In the late '90s, a transition was underway. Red Hat was one of the first companies ostensibly founded on free software principles. But as free software grew, some were concerned that its name was holding it back. The article explains with a link to a page within gnu.org:
But "free software" is an ambiguous term - there is a difference in meaning between the cultures of PC-based proprietary systems and the Net-centric UNIX worlds.
Michael Stutz, the author of the piece, surveyed the writing of Eric S. Raymond and interviewed luminaries like Bob Young, Russell Nelson, and Marc Andreessen. The article is about the creation of a new term for the freely-reusable code produced by the free software movement.
As proponents of free software often point out, while this software can be free-of-cost - that is, gratis - the real issue is about freedom, or human liberty. So it is really freed software.
Yes, that's right -- freed software. The emphasis is in the original. Most of us know the names Eric S. Raymond and Russ Nelson as people involved early-on in the Open Source Initiative. I guess January 1998 is before they decided on the "open source" name. Today, the community is divided into people who think it's important to say "free software" and the rest who call it "open source." We'd all agree with the following statement from the article:
"Freed software is a big win for society in general," said Russell Nelson.
And that's today's random page from the history books.

18 September 2010

Robert Collins: Maintainable pyunit test suites fixtures

So a while back I blogged about maintainable test suites. One of the things I ve been doing since is fiddling with the heart of the fixtures concept. To refresh your memory, I m defining fixture as some basic state you want to reach as part of doing a test. For instance, when you ve mocked out 2 system calls in preparation for some test code that represent a state you want to reach. When you ve loaded sample data into a database before running the actual code you want to make assertions about that also represents a state you want to reach. So does simply combining three or four objects so you can run some code. Now, there are existing frameworks in python for this sort of thing. testresources and testscenarios both go some way towards this (and I and to blame for them :) ), so does the zope testrunner with layers, and the testfixtures project has some lovely stuff as well. And this is without even mentioning py.test! There are a few things that you need from the point of view of running a test and establishing this state: Large test suites or test suites dealing with various sorts of external facilities will also often want to optimise this process and put the same state into place for many tests. The (and I m not exaggerating) terrible setUpClass and setUpModule and other similar helpers are often abused for this. Why are they terrible? They are terrible because they are fragile; there is no (defined in the contract) way to check that the state is valid for the next test, and its common to see false passes and false failures in tests using setUpClass and similar. So we also need some way to reuse such expensive things while still having a way to check that test isolation hasn t been compromised. Having looked around, I ve come to the conclusion we ll all benefit if there is a single core protocol for doing these things, something that can be used and built on in many different ways for many different purposes. There was nothing (that I found) that actually met all these requires and was also tasteful enough that folk might really like using it. I give you fixtures . Or on Launchpad. This small API is intended to be a common contract that all sorts of different higher level test libraries can build on. As such it has little to no policy or syntatic sugar. It does have a nice core, integration with pyunit.TestCase, and I m going to add a library of useful generic fixtures (like temporary directories, environment isolators and so on) to it. I d be delighted to add more committers to the project, and intend to have it be both Python 2.x and 3.x compatible (if its not already my CI machine isn t back online after the move yet, I m short of round tuits). Now, if you re writing some code like:
class MyTest(TestCase):
    def setUp(self):
        foo = Foo()
        bar = Bar()
        self.quux = Quux(Foo(), Bar())
        self.addCleanup(self.quux.done)
You can make it reusable across your code base simply by moving it into a fixture like this:
class QuuxFixture(fixtures.Fixture):
    def setUp(self):
        foo = Foo()
        bar = Bar()
        self.quux = Quux(Foo(), Bar())
        self.addCleanup(self.quux.done)
class MyTest(TestCase, fixtures.TestWithFixtures):
    def setUp(self):
        self.useFixture(QuuxFixture)
I do hope that the major frameworks (nose, py.test, unittest2, twisted) will include the useFixture glue themselves shortly; I will offer it as a patch to the code after giving it some time to settle. Further possibilities include declared fixtures for tests, and we should be able to make setUpClass better by letting fixtures installed during it get reset between tests.

17 September 2010

Jo Shields: Mono mythbusting, September 2010 edition

There are corners of the Internest where foolish people congregate, and invent stories. These foolish stories are then read as gospel by trusting people, and reposted, until the original made-up source is concealed from view. As an attempt to stem this flow of disinformation, here are some commonly held but incorrect beliefs about the Mono framework, and an explanation of the reality of the situation, as far as I understand it. The next Mono version is co-developed with Microsoft There is a grain of truth behind this one, but it s a gross mischaracterisation. Mono 2.8, when it ships, will bundle, for convenience, a number of Free Software libraries, which are released by Microsoft under a license considered Free Software by the Free Software Foundation, the Ms-PL. These are: So, to summarise, there are five Free Software libraries written by Microsoft under the Ms-PL included in Mono 2.8 but only two of those five are new, and none of them were co-developed in any meaningful sense. Mono development is dead There have been reports that Mono development has ended, on the basis that no commits have been made to Novell s Subversion server for a few weeks. However, these reports miss one minor detail Mono has moved to Github.com. There were 35 commits from 9 different people to the main mono.git repository (of dozens of repositories under the main Mono project) in the last 2 days, at time of writing far from dead. Mono lacks features found in Microsoft.NET Mono lacks libraries found in Microsoft.NET, such as the Windows Presentation Framework GUI toolkit. In terms of features, i.e. things implemented at a compiler or runtime level, Mono is typically more advanced. This is helped in no small part by Mono s Free Software development model, allowing experimentation and what if changes to the core runtime which a sluggish corporate behemoth like Microsoft cannot accommodate. To give three real-world examples, Mono allows embedding of its compiler as a service, and provides a REPL shell this is a planned feature for .NET 5.0, but has been available for years in Mono; Mono.Simd provides a number of data structures which will run on any version of Mono or Microsoft.NET, but will use optimized CPU extensions like SSE when run on a sufficiently new version of Mono, on an appropriate architecture as far as I m aware, there is nothing like this available or planned for Microsoft.NET. Mono is able to produce fully compiled, static executables which do not need to JIT anything at runtime this is used for iPhone compilation, for example, where JITters are not permitted. There is no comparable feature in Microsoft.NET. Clearly, Microsoft.NET can only be thought of as more featureful if one defines features in terms of does it have lots of libraries? in terms of functionality, Mono is ahead. Mono can sneak onto your system without your knowledge If you don t have the mono-runtime package installed, you can t run Mono apps. It is possible to install some Mono apps alongside the awful-yet-popular mononono equivs package, since the popular equivs script fails to place Conflicts on the correct packages (F-Spot will be blocked, Tomboy will not). No package in Debian or Ubuntu embeds its own copy of the Mono runtime, and we have no plans to make any changes to packaging which would allow execution of any C# application without mono-runtime installed. If one is using a different OS, then things may be different e.g. The Sims 3 for Mac & PC uses embedded Mono, which you wouldn t know about without looking. Canonical are pursuing a pro-Mono agenda, and are responsible for it being pushed in Debian Mono development has been happening in Debian for longer than Canonical has existed the first upload was made in April 2002. Ubuntu is made primarily from software already available in Debian deemed of sufficient quality, and when F-Spot and Tomboy became parts of the default Ubuntu desktop system in 2006, both pieces of software were already available in Debian and deemed of sufficient quality. Nobody working on Mono in Debian is paid by Canonical actually, that s not entirely true, three packages related to accessibility are officially maintained by someone who was hired by Canonical after doing the initial packaging work when he worked for Novell. But the Mono runtime itself, Canonical have no influence over its direction in Debian. As for a pro-Mono agenda , they ve always taken an extremely pragmatic approach to language choice, never showing any real preference for one language or another when it comes to app selection. They don t exhibit any overt anti-Mono policies, which is not the same thing. The names of people contributing to Mono in Debian are not secret check the pkg-mono team page on Alioth. The System.Windows.Forms namespace is protected by Microsoft patents The truth is, nobody knows for sure if SWF, or any other part of Mono, or any other framework such as Vala or Python, is covered by Microsoft patents. The way the US patent system is contrived, it is actively dangerous to check whether something contains any patents when you write it, as you are liable for triple damages should it later emerge that there WAS a patent, even if your searching missed the fact. You cannot patent an API or namespace only a specific implementation of a software concept, in those countries where software patents are permitted. There has never been any evidence shown that Mono s implementation of SWF, or indeed any part of Mono, infringes any Microsoft-held patents, because if that were the case, then the code would be rewritten to avoid the issue much like the approach taken by Linux kernel developers when a patent becomes apparent. The belief within the Mono community is that the core parts of Mono as defined in ECMA334/335 are safe (they are covered by the Microsoft Community Promise patent grant); any of the Ms-PL libraries mentioned above is definitely safe (Ms-PL includes an explicit patent grant); and the rest of the package is likely safe too (on the basis that it is a named component of the Open Innovation Network s list of protected software and on the basis that there s unlikely to be anything patentable in one of many implementations of basic ideas like database connectors). Nobody knows for sure, because that s how the system works. But, again, nobody knows for sure that Microsoft patents don t apply to other frameworks such as Python there is simply a belief and an assumption that they do not. MonoDevelop contributors removed GPL code from MonoDevelop, in an attack on the GPL This is somewhat disingenuous, given MonoDevelop is LGPL. The MonoDevelop team excised the remaining GPL code (and there wasn t much of it) in order to grant greater Freedom to developers. Previously, the entire MonoDevelop IDE was a GPL combination, meaning any add-ins for the IDE also needed to be GPL, regardless of developer choice. Now, any developer can write an add-in for MonoDevelop, using the license of their choice, whether another Free license like the Mozilla Public License, or a proprietary closed-source add-in. They are still welcome to produce GPL add-ins, if they want to, as well. Mono won t run random Microsoft.NET apps anyway, so isn t really cross-platform Actually, this one is often true. When developers write apps for Windows primarily, they rarely take the time to think is this the correct way to do it? and will often plough on with an assumption about the Windows way of doing things. It might be simple things like filesystem assumptions (assuming a case-insensitive filesystem, or assuming a backslash is used to separate directories, not a forward slash). It might be more involved, such as using P/Invokes into Windows-specific C libraries, when a more cross-platform alternative is possible. So, often, random applications for Microsoft.NET won t run on Mono. The reverse is also true F-Spot or GNOME Do are fairly heavily tied to Linux (or to UNIX-like OSes with X11, at any rate), through the libraries they invoke being fairly platform-specific. You can write platform-specific Java, with one quick piece of JNI, too. It should be noted, however, that Mono makes the chance of .NET applications being ported to Linux (and/or Mac) much more likely, since even in the worst case scenario, a company only needs to fix a portion of their source to make it cross-platform. The Mono team have a tool called MoMA, which will scan an application and its libraries, and give you detailed reports on the app s portability. This info is used at both ends by app vendors who want to become more portable, and by the Mono team who want to fill in the most frequently encountered blanks. And, it should be stressed, writing cross-platform apps is entirely possible if one desires it e.g. the IRC client Smuxi is pure cross-platform C#, and the executables compiled on Mono on Linux will run fine on Microsoft.NET on Windows. Portability in this direction is important too consider how many people have been introduced to Free Software thanks to availability of Free apps on Windows like OpenOffice.org, Firefox, Pidgin or GIMP. You can download Tomboy for Windows, and work is ongoing on fixing Banshee portability issues (which are mostly caused by gStreamer). Mono on Android is a terrible idea which will be super slow There are two efforts to enable developers to write Android applications with Mono a paid proprietary product from Novell called MonoDroid, and an untitled porting effort by big-name Android hacker Koushik Dutta. I have no insight into MonoDroid since it hasn t been released yet, but Koush did some benchmarks of his work which exhibited some remarkable figures compared to Dalvik (and even compared to Sun Java for ARM). Those numbers haven t been updated to reflect the Froyo Dalvik JITter, but Mono on Android is still very exciting from a performance perspective. Mono isn t really Free Software The source code is all available under Free Software licenses. So, um, yes it is. We don t need Mono because we have $LANG By the same logic, we don t need $LANG because we have Mono. By all means, use the language of your choice other developers will use the language of their choice too. If you want to use Vala or Python or Java, then by all means, go ahead. It doesn t mean there s no room for more languages, better suited to other usage patterns. Haskell is great for some types of development, so is Fortran, and so is C#. You might not need Mono because of $LANG, but there are others in the world with different needs. Mono apps are all slow, and crash your computer, and stuff No userland app can crash your Linux system, unless there s a bug in the kernel, or you have some severe problems with your hardware. If you ve ever observed a crash as a result of running a Mono app, then it s really coincidence that Mono is tickling whichever part of your system is busted. As for slow startup time may well be slower than for apps written in C or Vala. There s a delay due to the JITter needing to compile all the libraries used by the application (we may AOT the most common libraries in a future Mono package version, at upstream s recommendation). Once an app is running, it should be fast compared to a Python app, and memory-light compared to a Java app. The new garbage collector in Mono 2.8 should also offer significant improvements to performance, especially under heavy workloads. Ubuntu s default GTK+ themes require Mono This is my favourite recent nonsense to emerge from the Internest. There are reports mostly restricted to IRC and blog comments, that (paraphrasing here) removing Mono removes the Ubuntu themes . Here s the reality: in Ubuntu 10.04, a new visual style was implemented throughout the distro. As part of this, small icons (e.g. notification area icons) were set to be black-and-white by default, and colourised when attention is needed (e.g. the power-off icon turns red when a reboot is needed, the messaging indicator turns green when there s a new message). All of these new monochrome icons are in a package named ubuntu-mono . Removing the ubuntu-mono icon package will also remove the new Ubuntu GTK+ themes, in the light-themes package. So there s your explanation: the themes have a dependence on some monochrome icons, not on the Mono framework.

Joerg Jaspert: FTPMaster meeting, I

I announced it some while ago on debian-project, we have a FTPMaster meeting this weekend. It started out with a little workout session View image before we started discussing some things from our agenda. In the middle of the discussion we took a little sidestep, looking for a victim to promote to ftpmaster. So we selected someone not attending, he can t run away screaming. And for that: Send your condolences over to Torsten Werner. Or maybe congratulations, your call :) Right now Mark is fixing up our byhand processing and Alex is doing some other Debian work, while I m merging patches from Luca. Thats it for now, sometime soon we are going to eat, after which we put some more discussions on our agenda. Still two more days to go :)

Raphaël Hertzog: How to create Debian packages with alternative compression methods

While gzip is the standard Unix tool when it comes to compression, there are other tools available and some of them are performing better than gzip in terms of compression ratio. This article will explain where you can make use of them in your Debian packaging work. In the source package A source package is composed of multiple files. The .dsc file is always uncompressed and it s fine since it s a small textual file. The upstream tarballs can be compressed with gzip (orig.tar.gz), bzip2 (orig.tar.bz2), lzma (orig.tar.lzma) or xz (orig.tar.xz), so choose the one that you want if upstream provides the tarball compressed with multiple tools. Put it at the right place and dpkg-source will automatically use it. Note however that packages using source format 1.0 are restricted to gzip, and the main Debian archive currently only allows gzip and bzip2 (xz might be allowed later) even if the source format 3.0 (quilt) supports all of them. The debian packaging files are provided either in a .diff.gz file for source format 1.0 (again only gzip is supported) or in a .debian.tar file for source format 3.0 (quilt) . The latter tarball can be compressed with the tool of your choice, you just have to tell dpkg-source which one to use (see below, note that gzip is the default). In a native package, dpkg-source must generate the main tarball and you can instruct it to use another tool than gzip with the --compression option. That option is usually put in debian/source/options:
# Use bzip2 instead of gzip
compression = "bzip2"
compression-level = 9
For 3.0 (quilt) source packages, this option is not very useful as the debian tarball that gets compressed is usually not very large. But some maintainers like to use the same compression tool for the upstream tarball and the debian tarball, so you can use this option to harmonize both. In native packages, it s much more interesting: for instance the size of dpkg s source package has been reduced of 30% by switching to bzip2, saving 2Mb of disk. In the binary packages .deb files also contain compressed tar archives and by default they use gzip as well:
$ ar t dpkg_1.15.9_i386.deb
debian-binary
control.tar.gz
data.tar.gz
data.tar.gz is the archive that contains all the files to be installed and it s the one that you can compress with another tool if you want. Again this is mostly interesting for (very) large packages where the size difference clearly justifies deviating from the default compression tool. Try it out and see how many megabytes you can shove. Another aspect that you must keep in mind is that those alternative tools might use important amount of memory to do their job, both for compression and decompression. So if your package is meant to be installed on embedded platforms, or if you want to build your package on low-end hardware with few memory, you might want to stick with gzip. Now how do you change the compression tool? Easy, dpkg-deb supports a -Z option, so you just have to pass -Zbzip2 for example. You can also pass -z6 for example to change the compression level to 6 (it s interesting because a lower compression level might require less memory depending on the tool used). The dpkg-deb invocation is typically hidden behind the call to dh_builddeb in your debian/rules so you have to replace that invocation with dh_builddeb -- -Zbzip2 . If you are using a debhelper 7 tiny rules files, you have to add an override like in this example:
%:
	dh $@
override_dh_builddeb:
	dh_builddeb -- -Zbzip2
If you are using CDBS, you have to set the variable DEB_DH_BUILDDEB_ARGS:
include /usr/share/cdbs/1/rules/debhelper.mk
[...]
DEB_DH_BUILDDEB_ARGS = -- -Zbzip2
I hope you found this article helpful. Follow me on identi.ca or on twitter.
Flattr this Share/Bookmark One comment Support my work

Russell Coker: Preferring Low Quality and Microsoft Software

Is Low Quality in Italian Academia related to the choice of Low Quality Software? Diego Gambetta and Gloria Origgi wrote an interesting paper titled L-worlds: The curious preference for low quality and its norms [1]. The paper describes how in Italian universities (and large portions of Italian life) there are covert agreements that both parties in a transaction (the employee and the employer or the buyer and the seller) will deliver less than agreed while pretending that they are offering the agreed exchange. People who offer high quality in exchanges are discriminated against because they make people who offer low quality in exchange feel guilty. Nathan suggests that this is the explanation for people choosing to pay for inferior software from Microsoft instead of getting superior software for free [2]. Now it does seem quite plausible that someone who is offering low quality goods in the manner of Italian academia would refuse to consider software from any company other than Microsoft, after all the easiest way of selecting software is to phone a MS representative and be told exactly what to buy. But I don t think that this explains even a significant fraction of the people who refuse free software. There is no direct analogy between bilateral agreements to produce low quality and the choice of MS Software because MS Software is quite expensive (they demand what would be considered a high quality trade in the jargon of the paper). If someone was to buy one of the cheaper laptops in Australia (around $650 new) and upgrade to the full version of Windows 7 along with purchasing the home version of MS Office then the cost of software would be almost as much as the cost of hardware. If they wanted one other MS product then the cost of MS software would probably be greater than the cost of hardware. Hardware costs are steadily falling and MS prices are only increasing, for people who use MS software we should expect that soon the MS tax will be the majority of the costs of running a typical PC. Good Reasons for Choosing MS One thing we have to consider is that there are people who have good reasons for using MS software. One example is the companies that depend on proprietary applications which are central to their business. When the entire company s data is stored in an undocumented proprietary database it s really not easy to change to a different application even when everyone in the company knows the software to be of amazingly low quality. If the vendor of the proprietary application in question decides to only support MS Windows then it s customers (victims?) have no choice about which OS to use. One interesting thing to note about such companies that are locked in to proprietary software is that the amount that they spend per year on license and support fees is usually greater than the cost of hiring one good programmer. If a few such companies formed a consortium to develop free software to manage their business where each company paid the salary of one programmer then after a couple of years of development they could move to the free software and reduce their operating expenses. Another category of users who have a good reason to choose MS is the people who play games seriously. If you want to play games then MS Windows does offer some real advantages. The price of games will usually be a fraction of the hardware cost (the serious gamers spend a lot more on hardware than most people) and MS Windows is apparently the best PC OS for commercial games. Personally I ve found that there are more than enough free games on Linux to waste my time, Warzone 2100 [3] is one that I currently play, and I ve tried Battle for Wesnoth [4] in the past and found it too time consuming and addictive. How a Preference for Low Quality could lead to Microsoft I think that everyone who has any significant experience in the computer industry has encountered companies that have large areas of low quality. This generally tends to be in large corporations as small companies can t afford the waste. In some large corporations Linux on the desktop is never considered, even when people are hired as Linux sysadmins and there are obvious productivity benefits to having the same OS on the desktop as on the servers (even if two desktop PCs are required so that proprietary software can be run on MS-Windows). Major wrote a good satire of the corporate IT non-working culture with a comparison to medical work [5], it illustrates the principle of a coalition to ensure low quality. He later documented how he was sacked by the low quality coalition at a company that uses a lot of Microsoft software [6]. So it does seem that when customers don t care at all about the quality of the result it does help drive some sales for Microsoft. But that doesn t explain the market share that they have. It takes a lot of work to get Market Share without Quality Microsoft has spared no effort in gaining market share. Every possible effort including buying out small competitors, aggressively FUDing competition, using all manner of legal attacks (including the threat of patent suits), and deliberately breaking standards has been used. I think it s reasonable to assume that the MS senior management are not entirely stupid, they do so many things that are unethical and possibly illegal because they know that they need to do so to maintain their market share. The result is that the market capitalisation of MS is almost as high as that of Apple and Apple makes vastly superior products. Given the amount of effort that MS uses to keep market share it seems apparent that they aren t just relying on customers not caring about quality. Should users have to Understand Computers? My observation is that most users don t want to know much about how their computers work. The desire to understand computers seems to be about as common as the desire to understand cars, people just want to buy one that looks good and have it work. The difference is that cars are very compatible while computers aren t. Cars have the same controls in the same places and large parts of the design are specified by law so that they can t differ between models. Proprietary software is usually intentionally incompatible with other software (both open and proprietary) to try and gain a competitive advantage. Hardware is often incompatible due to the rapid developments in technology and the requirements for new interfaces to take advantage of new features. In concept it seems reasonable for someone who is about to spend $30,000 on a car and $1000 on a computer (for hardware and software) to spend 30 times longer considering which brand of car to buy. One could argue that more than 30 times as much consideration should be given to the car as most people can t afford to discard a car that they don t like. As people spend a few minutes considering which brand of car to buy they can be excused for spending a few seconds considering which type of computer to buy. But once a choice has been made about which software to use it s very difficult to change to something else, while in comparison it s easy to drive a car that was manufactured by a different company. So a poorly informed choice made at an early stage can have costly long-term affects when buying software. If we had mandated open standards for file formats and data interchange then users would be able to make choices that don t result in their data being locked in to some proprietary format. Such standards could be set through government tender processes, if every government agency was to only buy software that complies with open standards then the proprietary software vendors would scramble to make their products less incompatible. The result would be that bad choices in purchasing software could become learning experiences that result in better purchases in future instead of being a lock on users that forces them to keep using the same software that doesn t satisfy their needs. Conclusion I think that the best thing about the paper by Diego Gambetta and Gloria Origgi is that it highlights the issue of low quality. No-one wants to be considered a loser, so maybe this can encourage people to strive for high quality (or at least try to make their work suck a little less). Regardless of the conclusion they eventually reach, it s probably good for people to occasionally wonder do I suck? .

Erich Schubert: Random background python script

I use the following python script to choose a random background on login:
#!/usr/bin/python
import os, os.path, random, gconf
startdir="PUT YOUR FOLDER HERE"
gkey="/desktop/gnome/background/picture_filename"imgs=[]
for root, dirs, files in os.walk(startdir):
  for file in files:
    base, ext = os.path.splitext(file)
    if ext.lower() in [".jpg", ".png", ".svg"]:
      imgs.append(os.path.join(root, file))img = random.choice(imgs)gconf.client_get_default().set_string(gkey, img)
It's fairly simple, but shows the power of the python libraries. It "walks" the directory tree, collects all files of the given extensions, chooses one at random, then updates the gconf key for the Gnome background image.P.S. Yes, I know a couple of ways to do that in a shell script, too. However, then one I used failed with whitespace in file names, so I decided to rewrite it in a much more sane language ... the random involved was also a hack.

16 September 2010

Michal Čihař: Cleaning up phpMyAdmin's feature requests

The phpMyAdmin's feature tracker is kind of special thing, which grows all the time. From time to time I try to go through all of them and properly mark those who are fixed meanwhile or do not make sense anymore. Today I started with 277 (49 of them already marked as fixed in upcoming releases). After random accessing the list and about one hour I'm down to 266 (53 out of them fixed in git). Well 15 less is not that much better, but at least I managed to kill some long waiting zombies, which turned out to be bugs instead of feature requests.

Vincent Sanders: The turmoil of an entropy key release.

Last week we released 1.1.3 of the Entropy Key software. Poor Daniel struggled for days to get this out the door but finally he managed to build all the various debs, rpms and tars for the supported platforms and Rob got it all uploaded and announced.

The release is kinda strange in that it was the first in which the main changes were for performance. OK there is an improvement to resilience in the face of failed re-keying which some users were seeing in high load situations, but that high load was (in some cases) being caused by the daemon itself.

The process was mainly driven by one of our users, Nix, who was experiencing ekeyd using "too much" CPU on his system.

Of course on our servers during testing ekeyd it had used around a percent of CPU, certainly nothing that flagged as a problem in our own use (yes we eat our own dogfood ;-) Alas for this user on a 500MHz geode it was guzzling down 10% of his CPU which was clearly unacceptable.

This user however instead of guessing what the problem might be or simply leaving it up to us did something about it. He instrumented ekeyd, located the garbage collector tuning parameters as being incorrectly set and supplied a patch. Did he stop there? no! he then went on to profile the code further and clean up the hotspots. This resulted in ekeyd falling to less than 1% of the runtime of his system.

By reducing the CPU usage of ekeyd to this level it became more apparent where a previously reported bug was coming from, which enabled me to address it.

I know sometimes I complain about Open Source software but at times like this it makes me happy that we released the ekeyd software freely. This is how its supposed to be! Everyone working to make better software and benefiting together.

It has not just been on this occasion either, throughout the last year since our very first 1.0 release there has been helpful and useful feedback, patches from several users and even the odd thankyou mail. This project then has been a positive Open Source experience and I look forward to another constructive year maintaining this software.


Dirk Eddelbuettel: BLAS, BLASter, BLAStest: Some benchmark results, and a benchmarking framework

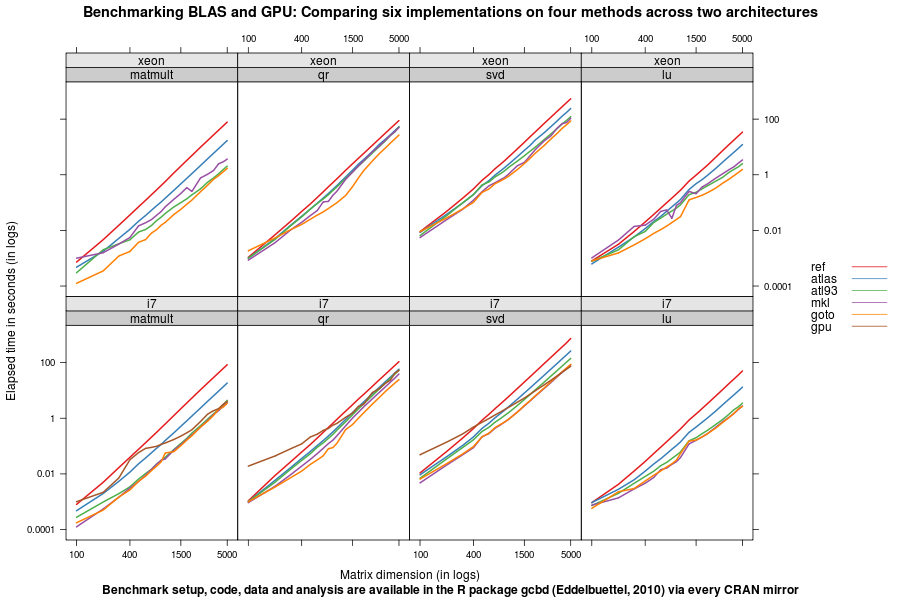
Usage of accelerated BLAS libraries seems to shrouded in some mystery, judging from somewhat regularly recurring requests for help on lists such as r-sig-hpc (gmane version), the R list dedicated to High-Performance Computing. Yet it doesn't have to be; installation can be really simple (on appropriate systems). Another issue that I felt needed addressing was a comparison between the different alternatives available, quite possibly including GPU computing. So a few weeks ago I sat down and wrote a small package to run, collect, analyse and visualize some benchmarks. That package, called gcbd (more about the name below) is now on CRAN as of this morning. The package both facilitates the data collection for the paper it also contains (in the vignette form common among R packages) and provides code to analyse the data---which is also included as a SQLite database. All this is done in the Debian and Ubuntu context by transparently installing and removing suitable packages providing BLAS implementations: that we can fully automate data collection over several competing implementations via a single script (which is also included). Contributions of benchmark results is encouraged---that is the idea of the package. The paper itself describes the background and technical details before presenting the results. The benchmark compares the basic reference BLAS, Atlas (both single- and multithreaded), Goto, Intel MKL and a GPU-based approach. This blog post is not the place to recap all results, so please do see the paper for more details. But one summary chart regrouping the main results fits well here: GPU/CPU Benchmark Results This chart, in a log/log form, shows how reference BLAS lags everything, how multithreaded newer Atlas improves over the standard Atlas package currently still the default in both distros, how the Intel MKL (available via Ubuntu) is fairly good but how Goto wins almost everything. GPU computing is compelling for really large sizes (at double precision) and too costly at small ones. It also illustrates variability and different computational cost across the methods tested: svd is more expensive than level-3 matrix multiplication, and the different implementations are less spread apart. More details are in the paper; code, data etc are in the package gcbd. The larger context is to do something like this benchmarking exercise, but across distributions, operating systems and possibly also GPU cards. Mark and I started to talk about this during and after R/Finance earlier this year and have some ideas. Time permitting, that work should be happening in the GPU/CPU Benchmarks (gdb) project, and that's why this got called gcbd as a simpler GPU/CPU Benchmarks on Debian Systems study.
15 September 2010

Gunnar Wolf: On enjoying history, opposed to what happens around me

Portadas de los discos de Diana Uribe I have always liked learning and understanding history. Since I discovered him, for a couple of years already I always try to catch Javier Garciadiego's program Conversaciones sobre historia, Saturday 9AM in the Horizonte 108 radio station (can be listened to online). This program started by going over the events just before the beginning of the 1910 revolution in Mexico - and along slightly over five years, one hour per week and following different threads, the program has reached the end of the Cristiada, in the early 1930s. Garciadiego has a very nice, followable, amenable way of telling history, and I have recommended his program to many friends. This last June, I spent some days in Guatemala City, for DrupalCamp Centroam rica. I stayed with my good Colombian friend, Dilson, and at his house he had framed a poster of the History of the Civilizations. Of course, I got my nose close to it, guessing as many faces as possible in the lot. And he showed me his last Christmas present: Two books, each of them with 6 CDs. One is Historia de las Civilizaciones, the second one is Historia de las independencias. They are made by Colombia's very well known and well regarded historian Diana Uribe. I copied the CDs in order to listen to them later And wow, was I impressed! Diana Uribe makes a great narrative about topics that to some people would seem boring and dry. As I said, I have always found passion in understanding the human processes that have shaped civilization and brought us all the way to where we stand now. Well, Diana Uribe manages to bring more "normal" people to this passion. While looking for information on her to share in this blog post, I found so many places offering download of her disks, with apparently young people talking about how she has got them all so excited and interested in history... That's, I think, the best "thank you" any academician can get: having non-specialists say how her work has opened up the passion of one of the world's least sexy professions to them. And yes there are so many "thank you" and "I want" commentaries, so much of what I would call "fan mail", that it took me a bit to find an online library carrying both works. And yes, at ~US$50 each, I do intend to buy them. Now, why am I writing this today? Well, yes, because I finished listening to the series today, but besides During this year, most of Latin American countries conmemorate their 200 years of existence. Most of the independentist struggles in the continent started in 1809-1810. And today is the "partying" day in Mexico Says the legend that in the night between September 15 and 16, 1810, a priest who is always painted as old and charismatic called on his small town urging the people to rise and fight for independence, and as a result of that, only 11 years later Mexico was a fully independent country, spanning from Costa Rica to California, and... well, a nice and very idealized myth. A century later, in 1910, after a very long stability and growth period (attained mostly through repression, the same abstract thing named as "the people" rose against the dictator Porfirio D az, who had been Mexico's president for 30 years. The revolution deeply changed the social face of the country, but politically... After ~15 years of fighting, the result was that a 30 year long dictatorship was replaced by a 70 year long one... And our political system still has not evolved beyond that model. Now, comparing what has not improved nor even stayed the same but went backwards... A century ago, the festivities of the hundred years of independence were a time for showing pride, for showing to the guests from more "civilized" countries how ours was by then a modern, thriving country worth believing in, worth investing in: Besides the important, majestic and well built monuments that were erected and still stand today (i.e. the Column of the Independence or Hemiciclo a Ju rez, many institutions that would socially shape the next century even after D az's death, even after he had been declared not the role model we wanted after all were born: The National University (nowadays the most important university in Latin America), the National School for Professors, the Railroad Technical School and many others (see Javier Aranda's note for some more details)... The celebration was well-thought and planned. Of course, it didn't go into some darker corners, the country was as uneven and unfair as it can be for the poorer indigenous population (which back then was a majority), and what not. But this year? Well, we are expecting an impressive show tonight (which I won't see, even though I'd like to, as I no longer have a TV and even if I had wanted to go downtown for the celebration, different government branches are insisting we should just sit and watch it by TV at home as it can be too crowded... so not even that was well thought out Of course not every Mexican can go to the same square and see the same de-facto president do the ritual, but some more redundancy could be thought, spreading acts through all of the city instead of concentrating the festivities all along Reforma. But anyway Leaving aside our current de-facto ruler's inabilities to do anything worthy, which are already well known and documented... I took this opportunity to listen to a great work, and am most happy to do it, and to be able to share it with you.

Iustin Pop: Virtual hardware failures

Note: The title is intentionally unclear; it can be read both as virtual failures and failures of virtual hardware , and I'm not sure which one is the better for the cases below. One of the funny things about virtualization is how virtual hardware fails. It often happens that my NFS-stored virtual machine images suffer an NFS glitch or something, at which point one can see in the kernel logs:
kernel: mptscsih: ioc0: attempting task abort! (sc=ffff880018320100)
kernel: sd 0:0:0:0: [sda] CDB: Read(10): 28 00 00 00 00 38 00 00 08 00
kernel: mptscsih: ioc0: task abort: FAILED (sc=ffff880018320100)
kernel: mptscsih: ioc0: attempting target reset! (sc=ffff880018320100)
kernel: sd 0:0:0:0: [sda] CDB: Read(10): 28 00 00 00 00 38 00 00 08 00
kernel: mptscsih: ioc0: target reset: SUCCESS (sc=ffff880018320100)
kernel: mptscsih: ioc0: attempting task abort! (sc=ffff880018320100)
kernel: sd 0:0:0:0: [sda] CDB: Read(10): 28 00 00 00 00 38 00 00 08 00
kernel: mptscsih: ioc0: task abort: FAILED (sc=ffff880018320100)
kernel: mptscsih: ioc0: attempting task abort! (sc=ffff88001eefcc00)
kernel: sd 0:0:0:0: [sda] CDB: Read(10): 28 00 00 98 01 a7 00 00 08 00
kernel: mptscsih: ioc0: task abort: FAILED (sc=ffff88001eefcc00)
kernel: mptscsih: ioc0: attempting target reset! (sc=ffff880018320100)
kernel: sd 0:0:0:0: [sda] CDB: Read(10): 28 00 00 00 00 38 00 00 08 00
kernel: mptscsih: ioc0: target reset: SUCCESS (sc=ffff880018320100)
While the NFS transient issues are probably a real bug, I have this image of a state machine inside the driver trying over and over the same error paths, in a futile attempt at fixing the hardware , and not locking onto/matching the real hardware behaviour. Or, this most recent case during boot and resource probing:
kernel:  e1000: 0000:00:08.0: e1000_probe: The EEPROM Checksum Is Not Valid
kernel:  /*********************/
kernel:  Current EEPROM Checksum : 0x031a
kernel:  Calculated              : 0x031a
kernel:  Offset    Values
kernel:  ========  ======
kernel:  00000000: 08 00 27 f6 f3 9b 00 00 ff ff 00 00 00 00 00 00
kernel:  00000010: 00 00 00 00 08 44 1e 00 86 80 0e 10 86 80 40 30
kernel:  00000020: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
kernel:  00000030: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
kernel:  00000040: 00 00 61 70 0c 28 c8 00 c8 00 00 00 00 00 00 00
kernel:  00000050: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 02 06
kernel:  00000060: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00 00
kernel:  00000070: 00 00 00 00 00 00 00 00 00 00 00 00 00 00 1a 03
kernel:  Include this output when contacting your support provider.
kernel:  This is not a software error! Something bad happened to your hardware or
kernel:  EEPROM image. Ignoring this problem could result in further problems,
kernel:  possibly loss of data, corruption or system hangs!
kernel:  The MAC Address will be reset to 00:00:00:00:00:00, which is invalid
kernel:  and requires you to set the proper MAC address manually before continuing
kernel:  to enable this network device.
kernel:  Please inspect the EEPROM dump and report the issue to your hardware vendor
kernel:  or Intel Customer Support.
kernel:  /*********************/
kernel:  e1000: 0000:00:08.0: e1000_probe: Invalid MAC Address
kernel:  e1000: 0000:00:08.0: e1000_probe: (PCI:33MHz:32-bit) 00:00:00:00:00:00
kernel:  e1000: eth0: e1000_probe: Intel(R) PRO/1000 Network Connection
This is an emulated Intel NIC under VirtualBox. I have never seen it before, and it went away after a reboot. The most funny thing is the This is not a software error! message well, it definitely is :), but the driver has no way to know that. I think that these software-driven failures probably trigger some obscure error handling paths; I assume that the usual failures for real versus virtual hardware are quite different in nature, and that recovery is again different. This leads to using the wrong strategy for recovery, but fortunately nothing is really broken, just in the wrong state Since I'm not familiar with low-level driver details, I might be wrong of course; I'm just speculating on what I think goes on inside the driver. I'm not even mentioning virtual clock issues, as those are no longer funny

14 September 2010

Russell Coker: How to Start Learning Linux

I was asked for advice on how to start learning Linux. Rather than replying via email I m writing a blog post for future people who ask such questions and also to get comments from other people which may provide information I missed. Join a LUG The best thing to do is to start by joining your local Linux Users Group (LUG). Linux International maintains a list of LUGs that is reasonably comprehensive [1]. Even if there isn t a LUG near enough for you to attend meetings you can learn a lot from a mailing list of a LUG that s close to your region. There is usually no great reason not to join the mailing list of a LUG in a different region or country, but a local LUG is that the advice will often be tailored to issues such as the local prices of hardware and the practices of your government. Also note that Linux International doesn t list all LUGs, the MLUG group in Melbourne [2] and the BLUG group in Ballarat [3] aren t listed. Anyone who joins LUG (the group based in Melbourne, Victoria that I m a member of) will be advised of the smaller groups in the region if they ask on the list. As an aside it would probably make sense for the main LUV web page [4] to have links to local LUGs and to the LI page of users groups and for other LUGs to do the same. It s pretty common for a Google search to turn up the web site of a LUG that s near the ideal location but not quite right. Also it would be good if LUV could have a link to the Victorian Linux Users Group in Canada this should reduce the confusion a bit and they have a link to us [5]. Play with Linux Get a spare PC (with no important data) and try installing different distributions of Linux on it. Make sure that it never has anything particularly important so you can freely try things out without worrying about the risk of losing data. Part of the learning process usually involves breaking a system so badly that it needs to be reinstalled. Linux can run on really old hardware, an old system with 64M of RAM will do for learning (but 128M will really be preferred and 256M will be even better). Learn with other Beginners LUV has a very active beginners group, with a beginners mailing list and special beginners meetings. A group that has such things will be more helpful as you can easily learn from other people who are at a similar level to you. Also you can spend time learning Linux with friends, just spend a weekend with some friends who want to learn Linux and play with things you can often learn more by trying things than by reading books etc. Do some Programming One of the advantages of Linux (and other Free Software OSs) is that it comes with a full range of programming languages for free. You can get a much greater understanding of an OS by writing programs for it and a typical Linux distribution gives you all the tools you need. Any other Ideas? Does anyone have any other suggestions? Please leave a comment.

Mohammed Sameer: Twitter OAuth Proxy

I'm using Twitter plugin for Contacts and Conversations to twitter on my N900.

Twitter recently moved to OAuth. Problem is the Maemo package is outdated and seems to be unmaintained.

I did some research and came across a blog entry about exploring OAuth-protected APIs and some code. Nice idea but not usable for me.

I ended up sitting down and writing a small python script that will re-route your HTTP requests to api.twitter.com after adding all the OAuth bills and whistles, read the reply from twitter and send it back. Neat ? :-)

There's also supertweet.net which I've discovered after I finished writing my script but seems they don't support all of the twitter API call while my script does that.

The script is simple without much error checking but it's been working for me for a few days already.

Last thing, I'm not interested in running a service like supertweet. I'll not be implementing the full OAuth protocol. Need to use it ? Register your own application.

Get the code while hot!

git clone git@gitorious.org:twitter-proxy/twitter-proxy.git

Next step: Thinking of maintaining the twitter plugin for Maemo. I already compiled the latest code and it sort of works fine :-) read more

Kees Cook: my part in the ecosystem

I was asked to write about what I do at Canonical and what I do in the Free Software community at large. There is obviously a great deal of overlap, but I ll start with the things I m involved with when I m wearing my Ubuntu hat. My primary job at Canonical is keeping Ubuntu secure. This means that I, along with the rest of the Ubuntu Security Team, coordinate with other Free Software distributions and upstream projects to publish fixes together so that everyone in the community has the smallest possible window of vulnerability, no matter if they re running Ubuntu, Debian, RedHat/Fedora, SUSE/openSUSE, Gentoo, etc. Between vendor-sec, oss-security, and the steady stream of new CVEs, there is plenty going on. In addition to updates, the Security Team works on pro-active security protections. I work on userspace security hardening via patches to gcc and the kernel, and via build-wrapper script packages. Much of this work has been related trying to coordinate these changes with Debian, and to clean up unfinished pieces that were left unsolved by RedHat, who had originally developed many of the hardening features. Things like proper /proc/$pid/maps permissions, real AT_RANDOM implementation, upstreaming executable stack fixing patches, upstreaming kernel NX-emu, etc. Most of the kernel work I ve done has gotten upstream, but lately some of the more aggressive protections have been hitting frustrating upstream roadblocks. Besides the hardening work, I also improve and support the AppArmor Mandatory Access Control system, as well as write and improve confinement profiles for processes on Ubuntu. This work ends up improving everyone s experience with AppArmor, especially now that it has gotten accepted upstream in the Linux kernel. I audit code from time to time, both on the clock with Canonical and in my free time. I m no Tavis Ormandy, but I try. ;) I ve found various security issues in Xorg, Koffice, smb4k, libgd2, Inkscape, curl+GnuTLS, hplip, wpa_supplicant, Flickr Drupal module, poppler/xpdf, LimeSurvey, tunapie, and the Linux kernel. With my Canonical hat off, I do all kinds of random things around the Free Software ecosystem. I m a sysadmin for kernel.org. In Debian, I maintain a few packages, continue to try to push for security hardening, and contribute to the CVE triage efforts of the Debian Security Team. I ve written or maintain several weird projects, including MythTVFS for browsing MythTV recordings, GOPchop for doing non-encoding editing of MPEG2-PS streams, Perl s Device::SerialPort module, and the TAP paging server Sendpage. For a selection of things I ve contributed to other project, I ve implemented TPM RNG access in rng-tools, made contributions to Inkscape s build and print systems, implemented CryptProtect for Wine, wrote a PayPal IPN agent in PHP that actually checks SSL certificates unlike every other implementation I could find, added additional protocol-specific STARTTLS negotiations to OpenSSL, implemented the initial DVD navigation support in MPlayer, updated serial port logic in Scantool for communicating with vehicle CAN interfaces, tried to add support for new types of timeouts in Snort and Ettercap, fixed bugs in mutt, and added HPUX audio support to the Apple ][ emulator XGS. As you can see, I like making weird/ancient protocols, unfriendly file formats, and security features more accessible to people using Free Software. I ve done this through patches, convincing people to take those patches, auditing code, testing fixes and features, and doing packaging work. When I go to conferences, I attend UDS, DefCon, OSCon, and LinuxCon. I ve presented in the past at OSCon on various topics including security, testing, and video formats, and presented at the Linux Security Summit (miniconf before LinuxCon this year) on the need to upstream various out-of-tree security features available to the Linux kernel. I love our ecosystem, and I love being part of it. :)

Raphaël Hertzog: How to customize dpkg-source s behaviour in your Debian source package

dpkg-source is the program that generates the Debian source package when a new package version is built. It offers many interesting command-line options but they are often not used because people don t know how to ensure that they are used every time the package is built. Let s fill that gap! It is possible to forward some options to dpkg-source by typing them on the dpkg-buildpackage command line but you d have to remember to type them every time. You could create a shell alias to avoid typing them but then you can t have different options for different packages. Not very practical. The proper solution has been implemented last year (in dpkg 1.15.5). It is now possible to put options in debian/source/options. Any long option (those starting with -- ) can be put in that file, one option per line with the leading -- stripped. Here s an example:
# Bzip2 compression for debian.tar
compression = "bzip2"
compression-level = 7
# Do not generate diff for changes in config.(sub guess)
extend-diff-ignore = "(^ /)config.(sub guess)$"
Notice that spaces around the equal sign are possible contrary on the command line. You can use quotes around the value but it s not required. The debian/source/options file is part of the source package so if someone else grabs the resulting source package and rebuilds everything, they will use the options that you defined in that file. You can also use debian/source/local-options but this time the file will not be included in the resulting source package. This is interesting for options that you want to use when you build from the VCS (Version Control Repository, aka git/svn/bzr/etc.) but that people downloading the resulting source package should not have. Some options (like --unapply-patches) are only allowed in that file to ensure a consistent experience for users of source packages. You can learn more about the existing options in the dpkg-source manual page. Read it, I m sure you ll learn something. Did you know that you can tell dpkg-source to abort if you have upstream changes not managed by an existing patch in debian/patches? It s --abort-on-uptream-changes and it s only allowed in debian/source/local-options. Be sure to subscribe to the RSS feed or to the email newsletter to not miss useful documentation for Debian contributors! Flattr this Share/Bookmark 3 comments Support my work

Dominique Dumont: Creating a DEP-5 parser with Config::Model

Hello Following a discussion on #debian-perl IRC channel, I ve proposed to provide a script to parse DEP-5 files. The goal is to be able to parse *and* validate DEP-5 files. DEP-5 is a
proposal to make debian/copyright machine-interpretable. This proposal is driven by Lars Wirzenius. With Config::Model, any evolution of DEP-5 specification will
be easy to include in the DEP-5 model read by Config::Model. What DEP-5 model ? To keep a long story short, let s say that DEP-5 model is a description of DEP-5 syntax and semantic that can be used by Config::Model to perform validation. For more detail on how to create a model, please read this doc. In other word, DEP-5 model is DEP-5 document translated into a special format. First step was to directly edit the doc and munge it into a YAML document describing the structure of DEP-5. Here s a small extract of this YAML file (slightly edited to remove most long descriptions) :
 
---
class:
  Debian::Dep5:
    class_description: >
       Machine-readable debian/copyright
    accept:
      name_match: X-.*
      type: leaf
      value_type: string
    element:
      Format-Specification:
        mandatory: 1
        type: leaf
        value_type: uniline
        description: >-
          URI of the format specification, such as ...
      Name:
        type: leaf
        value_type: uniline
      Files:
        type: hash
        index_type: string
        ordered: 1
        cargo:
          type: node
          config_class_name: Debian::Dep5::Content

During this YAML file creation step, the problem raised by the License keyword became obvious because of License properties: Long story short, I had to add to Config::Model the possibility to specify a Parse::RecDescent grammar to validate a value. More on this later. Of course, the first draft of a model in YAML was far from being perfect. So the second step was to load it with config-edit-model. I had to fix a number of YAML errors and then some errors in the model description. Then, I had to write a parser to load the DEP-5 data into Config::Model tree. I first used Rapha l Hertzog s Dpkg::Control::Hash module. But this one is not able to cope with repeated fields without clobbering them. So I had to provide my own parser. The parser is divided in 2 parts:
- the parse function to load DEP-5 data in a simple data structure
- the read function to load the simple data structure into Config::Model s configuration tree You can view the code on Config::Model repository. Then the model is divided in 3 configuration classes: And the full model of Dep-5 can be also read on Config::Model repository: (The models are biggish because they include help text taken from DEP-5 documentation) Now some explanation is required on how is performed the License validation. The trick is that each License used must be listed in Dep5 s license parameter which is specified this way (in YAML syntax):
 
License:
  type: hash
  index_type: string
  allow_keys_matching: '^(?i:Apache Artistic BSD etc... other)[\d\.\-]*\+?$'
  cargo:
     type: leaf
     value_type: string
So this License element contains the list of licenses with their full text and only Licenses whose name matches the regular expression are accepted. Now, let s explain how the files are tied to the declaredlicenses. The Debian::Dep5::Content class had a License element that represent the relation between the files and the License(s). This bond is represented by Debian::Dep5::License configuration class. The abbrev and full_license elements are fairly obvious. The abbrev element is another matter. Here s its declaration (minus the description and help):
 abbrev:
 type: leaf
 value_type: uniline
 default: other
So far, so good. Now the meaty part: the validation requirement based on Parse::RecDescent
grammar: "license (oper license)(s?)
          oper: 'and'   'or'
          license: /[\\w\\-\\.\\+]+/i\n
               # PRD action to check if the license text is provided
               $return = $arg[0]->grab('! License')->defined($item[0]);
               "
This grammar specifies: This way, an abbreviation cannot be used without a proper License statement. This code is the first stab. Some more work is to be done soon: Anyway, I ll soon release Config::Model with this first version of DEP-5 parser. As always feedback are more than welcome. All the best update: added missing Parse::RecDescent link

13 September 2010

Iustin Pop: 3ware raid resize via pivot_root

How pivot_root won against a stupid RAID controller This post is brought to you by a very stupid 3ware 9650SE RAID controller, which doesn't understand the concept of growing a RAID array after all disks have been replaced by bigger ones. Or, well, it can, but the procedure, involving sending array dumps to the technical support, then receiving a program to run under DOS (!), doesn't inspire me with confidence. Furthermore, this stupid RAID card doesn't allow easy reordering (if it's possible, and I just missed it, please let me know) of the RAID arrays at runtime, only from the BIOS screen, and I didn't have access to that (only poor man's serial console under Linux). So, after buying new harddrives, and replacing the original ones in the RAID1 array with double the capacity, I realised I have to do a manual conversion. Basically, go into single-user mode, remount all read-only, split the RAID1 array into its (identical) components, change root directory to the second disk, re-partition the first disk, copy the data from the 2nd to the 1st disk, then re-add the 2nd disk to the 1st one (repartitioned) to re-establish the RAID1. All this, on a headless (no keyboard, no VGA) machine, just with a serial console. Of course, if this is just your local machine, you can easily reboot from an external media, and do all this easily from a full user-space. In any case, I'm writing this down, as there seem to be no easily findable guides on how to do the resize on a 3ware with its restrictions. Procedure Disclaimer: you might lose data via this, there are no guarantees. Have up-to-date backups. First, make sure you have power control (you can power-cycle the box if needed) and the serial console works. Also, make absolutely sure that the RAID array is fully consistent, and that you don't have any bad sectors on the drives, as you will lose redundancy during the operation. If /usr is not on your root file-system, then you need to copy /usr/sbin/chroot to somewhere on it. Also, if you have tools for the array that are not on your root file-system, you should copy them there now. In my case, that was tw_cli. First reboot Reboot into init=/bin/sh. Note: I've tried to simply go into single-user mode, or to reboot with emergency, but this doesn't work, because in both modes, beside the init process with PID 1 and your shell, there's another init process (the parent of the shell), and I didn't know how to tell it to re-execute itself. To the main init process it's easy, you just run telinit u, but that child keeps the old root directory mounted. If it's possible to re-exec that child too, then this step can be skipped please let me know how! Changing the root mount Make sure everything is mounted read-only (should be), then split the raid array into its component drives, using whatever tool the card needs. For me, it was:
# tw_cli /c0/u0 migrate type=single
The second drive now should be visible e.g. as /dev/sdc, so mount it somewhere, and pivot_root to it:
# mount -o ro /dev/sdcX /mnt
# cd /mnt/
# pivot_root . mnt/
# exec chroot .
At this point, the new root (on some partition on /dev/sdc) is mount at the root, and the exec call replaced the current shell with another one that has the right root directory. So nothing should keep the old root directory (at /dev/sdaX) in use, and umount /mnt (or umount /dev/sdaX) should succeed now. Recreate the first raid array Now, since it's no longer in use, you can delete and recreate the first raid array. Once it's available, you have two choices: I did the latter, since I wanted to use the new alignment standards (the initial installation was still using sector 63 for the boot partition, etc.) as a future preparation for either SSD or 4K-sector drives. So I used: In any case, either copy the entire disk, or each partition in turn, or possibly pvmove from the old to the new disk, etc. Switch back the root mount At this point, /dev/sdc is no longer used, and you can again change the root directory. This is similar to the first pivot_root, but now using /dev/sda as a target. All the instructions are the same. Convert back to RAID1 Now, since (in our example) /dev/sdc is no longer in-use, you can delete that drive and rejoin it to the first drive, recreating the RAID1 array. In my case:
# tw_cli
/> /c0/u2 delete
blah blah [y/n] y
/> /c0/u0 migrate type=raid1 disk=X
At this point, the machine is again redundant (or will be once the resync finishes), but it still needs one more step or it won't boot correctly. Reinstall the boot-loader Now, for reinstall the boot loader, you'll probably need to mount /boot (and mount it read-write), and do whatever you need. In my case, I re-ran lilo, but grub-install /dev/sda should also work. Final reboot And now, you only need to reboot into the normal, resized system. Since you can't easily use shutdown when booted with /bin/sh as init, just use /proc/sysrq-trigger to sync/unmount/reboot. Thoughts While I use a hardware RAID controller for the battery backup it offers, I have never thought it cannot do such a simple operation (compare with mdadm --grow /dev/mdX --size=max). Second, I knew about pivot_root but have not used it before. It's a very very nice thing, and the only downside is that you can't really use it with more than a few processes, since it's hard/impossible to change a random process' root directory. But anyway, it works, and it's damn handy for doing things to the root file-system or in general to the root drive (e.g. just repartitioning it) when you can't boot from another media (e.g. remote machine).

Alastair McKinstry: So what should we call these things ?

The Exoclimes conference ended on an interesting perennial problem: what should we call these things we work on? The climate folks pointed out what the astronomers have grown used to: the telephone numbers we use as planet names. The two most studied Hot Jupiters, for example, are HD209458b and HD189733b. Come on, we could do better than that. In fact the naming worries started earlier when Frank Selsis asked people to avoid calling the planets he works on "super-Earths" (or should that be Super-Earths?). Dimitar Sasselov had accidentally kicked up a kerfuffle in the media a few weeks back by calling them "Earth-like" planets, when he meant "Earth-sized" planets. Selsis pointed out non-scientists will interpret "super-Earth" to mean "like Earth, only Better!", when we mean its just a bigger ball of rock and ice than Earth. But what to call them? Well, at least one planet already has a name, sort of: HD 209458b is frequently called 'Osiris'. And there is a published list of possible planet names. But Osiris the Egyptian god is more famous than Osiris the planet, confusing google. And people are going to assume things based on the planet names: are we really going to name a planet Vulcan? One suggestion was that if we found a system with seven planets we could call them after the Seven Dwarfs, but this was ruled out: don't mention the war (but dwarfs could also mean brown dwarfs!) At the end of the conference, there was show of hands: who agreed with naming planets? of about 100 present, all in favour, none against. The delegate to the IAU commision on the matter, which had voted against, duly noted. Perhaps we will name them then. Tags , ,

Next.

Previous.
