Search Results: "ron"

29 June 2007

Joey Hess: google notebook

There's a photo of me going around the interwebs with a strange caption that misses what was going on. The real story is, after my notebook's power supply died, I tried out this other weird notebook that Google had obtained, apparently from some alternate universe, and was giving away at the conference. It was very nice and small, and had impressive touch-screen data-entry technology (though I kept losing the stylus), and amazing battery power. Seems the data I put it in might stick around for a good hundred years, without any recharging. I was happy to not have to hook a clunky British power adapter up to it. It was also impressively easy to enter arbitrary unicode character such as BOPOMOFO LETTER EH, RUNIC TVIMADUR SYMBOL, and THING I SCRIBBLED DURING BORING PRESENTATION WITH CEDILLA BELOW. Downsides: No wifi or other network (didn't check GSM), very limited storage space (only a few dozen Kibobytes I think), an atrocious text editor that made moving text around way too hard, and had a really bad font, difficulty deleting things (the obvious way to delete something often accidentially removed nearby files as well -- and didn't actually regain any storage space), and very limited encryption (best I could get out it was rot-13). On the network front, there is apparently some "Postal Mail" app that can be used to send mail, but it can take like, weeks, and charges per message. And yeah, no solitare at all, though there was this hangman app. All in all, I was happy to get my Fujitsu back, though I might hold onto this Google notebook thing for emergencies. Won't be porting d-i to it anytime soon though.

28 June 2007

Steve McIntyre: Slowly recovering...

Debconf's over for another year - people have gone their separate ways, taking their newly-shared sense of purpose (and germs!) back home with them. Speaking for the organising team, I think we can justifiably be proud of ourselves - we seem to have pulled off a Debconf! Not everything worked perfectly or quite as we expected/wanted, but in the end I don't think we had any major issues. Fundamentally, it seems that all the attendees enjoyed themselves immensely and lots of productive work and socialising happened. That's the important bit! Thanks to all of you that turned up and helped us to make the conference a success this year, especially the volunteers who dived in to fetch, carry, man the front desk, run the cameras, organise the day trip, etc. And also (of course) to the sponsors who paid for the event - we love you all! The orga team still have some small bits to finish up before we declare things completely finished, though. We've still got some bits and pieces left in Edinburgh yet, waiting to be returned to their respective owners. And we're going to make a start on the post-conference report shortly. That's a place where conference attendees can help us again - we're looking for short write-ups of your experiences at the conference and a good selection of photos to give an impression of how things went. If you're able/willing to help, please mail the debconf-team list. Thank you and goodnight.

Biella Coleman: Minimizing Lingusitic Drift for the Sake of Political Clarity and Integrity

I am finally catching up with the remarkably thick goulash of email and blogs entries that comes from traveling for well over a month and today I read one in particular When is Open Source not Open Source? that captivated my interest for it compellingly addresses the dangers that follow from diluting, or one might say hijacking, the term open source. When people learn that I study “free software” one of the most common questions I get asked is: why did I chose free software over open source? The answer is quite simple: given that the bread and butter of my research covers ethics, freedom, and liberalism, free software is the obvious path to follow, yet I also feel like a lot of my work is still relevant to the open source camp because of the affinities between the two. I have long maintained that the ideological gulf between open source and free software is not so great nor impassable, but more modest. As most know, both share a certain strong commitment to access and in a strict technical sense they refer to the same set of licenses. Philosophically there is agreement that openness and, especially, non-discrimination are essential for the quality of software and often by close extension, the vibrancy of community responsible for the software. Of course, when pontificating the ramifications and implications of openness, they do part company and enter into different territories. Free software tends to flag rights and freedoms, while open source meanders into a discussion of markets, business, and competition and in this regard they do craft different visions of the social world and human behavior, etc. But the case that Karl Fogel writes about, where OSI is strongly opposing the use of the term open source for licenses that don’t adhere to the definition demonstrates where the two positions join. As Michael Tiemann from the OSI succinctly put it:
The FSF may have got the orthodoxy wrong, and the OSI may have got the interpretation wrong, but we both agree that prohibition of commercial use without special permission is antithetical to both positions.
There is a unmistakable kernel of agreement and it is great to see the OSI taking such a strong stance in this regard. Now, David Richard’s response, who seeks, I think, to essentially dilute the term open source, is as (or perhaps even more) fascinating for in a nut shell, and using a lot of florid religious imagery, it accuses the OSI of being too rigid! In his own words:
I believe the OSI has a wonderful opportunity to continue being relevant and helping to lead the movement forward. If, however, y’all choose to define your denomination of this religion in a way that we don’t fit in, that’s fine. No hard feelings. It’s your choice. You’ll ultimately be excluding a large congregation and we for one will continue trying to build a church made up of others like ourselves.
In response, I would say that the goal of F/OSS is not to be inclusive of anyone who wants to release bits of source code, but to create the conditions under which software, as it has been defined by the community, can be created. Join the church if you would like to make free/open source software as defined and you can go elsewhere (i.e., create a different term) if you are creating something different, even if it is only slightly different. Integrity matters. And again inclusiveness, if it comes at the expense of the main goal, is not a boon but a danger to F/OSS. The OSI will remain relevant by halting the dilution of the term OSI, not by expanding the definition so that it is left with no substance. And in contradistinction to what David Richard maintains, however, there is a great degree of flexibility within this domain but it does not lie in the strict definition of F/OSS but in the realm of interpretation. You are also free, as Mako and I have argued elsewhere to interpret the significance of F/OSS in multiple ways. And I think this is where the political strength of free software lies. There is interplay between a well-defined goal (in this case for creating free software) and a more flexible realm of interpreting the significance of these technical practice. And we wold lose and I might add, a lot if we became flexible about the strict definition of F/OSS and inflexible about its political significance. I get irked with folks like David Richards who would like to bend open source rules to meet their (often commercial) interests and I find it pretty na ve when folks say the political significance of F/OSS is just x (or worse should be x) for in reality its political significance lies in the fact that it has spawned multiple types of political and economic projects. And there is something almost playfully ironic, (or at least it makes me smile) in this fact. Though there is strict definition contained withing F/OSS, this strictness has, at least to some extent, encouraged by an extreme and very healthy form of political proliferation and promiscuity. More than anyone else I know, Mako has most passionately and thoughtfully argued for the importance of what I would call political clarity and integrity. That is, the importance of having a well articulated definition for social movements, for they act, as he says a rallying point to realize a social movement. Urging the Creative Commons to learn from F/OSS and dare to simultaneously narrow and more clearly define their goals, he states it quite nicely in the following terms:
Free software advocates have been able to use the free software definition as the rallying point for a powerful social movement. Free software, like the concept of freedom in any freedom movement, is something that one can demand, something that one can protest for, and something that one can work toward. Working toward these goals, free and open source software movements have created the GNU/Linux operating system and billions of lines of freely available computer code.
In essence, a definition that people can abide by, respect, and perhaps eventually cherish is the condition of possibility to make working political code. And given how hard it is to make social change happen (at least in comparison to build computer code), we should learn from what F/OSS has to offer. And at the same time there is another lesson embedded in F/OSS. The Free Software Definition is well defined; but it must be emphasized, narrowly so. It does not try to do everything and have everyone pledge allegiance to an inordinately complex set of commitments. Clarity, narrowness, and well-defined goals –> these three attributes have powered it far and wide and I hope it remains so. Now, since the term open source is not trademarked, we are left with the problem of how to challenge the current hijacking of the term. For the solution, I will leave you with Karl Fogel, who I think proposes a good solution:
Note that the OSI s objection is not to the Zimbra license per se. The objection is just to Zimbra s calling that license open source . They can use any license they want, but they shouldn t call it open source unless it actually is. Freedom is freedom, and no amount of spin will change that. So what should we do about this? The term open source isn t trademarked. Years ago, the OSI tried to register it, but it was apparently too generic. …But there is public opinion. What Danese and Michael are proposing doing is organizing a lot of open source developers (and I mean open source according to the traditional definition, the one the OSI and I and most other open source developers I know adhere to) to stand up and, basically, say All of us agree on what the definition of open source is, and we reject as non-open source any license that does not comply with the letter and spirit of the Open Source Definition.

MJ Ray: BBC Two's Money Programme Tonight

I wrote this yesterday:
"Dear BBC Money Programme, I'm really surprised that BBC Two's Money Programme "How Green is Your High Street?" correctly mentions that the recent greenwashing of public listed companies is motivated by shareholder returns rather than ethics, yet doesn't mention that cooperative businesses are motivated by ethics. [pic of agm lunch] Nor does it mention that the UK's largest cooperative retailer, the Cooperative Group, has been at the forefront of moving its stores to renewable energy and developing friendlier food packaging across its whole range, from biodegradable onion nets to thin-but-tough whisky bottles. I think it's also the first high street retailer to commit to only selling A-rated electrical appliances in its stores. It does this because it is motivated by ethics as well as dividends. As a result, the Co-operative Group food stores are outperforming competitors in the IGD reports and winning awards such as the Queens Award for Enterprise in Sustainable Development. Why do you ignore this success of green and ethical principles in your report?"
and this morning Sam notes he's seen the Daily Mirror report that the co-operative food came top in the original research so will there be a nice present on the end of the TV show?

Antti-Juhani Kaijanaho: The Dying Philosophers Problem

Reading a masters thesis draft that mentions the dining philosophers problem – a parable about the difficulties of process synchronization very well known in computer science – it occurred to me that it must not be a very good idea to eat just spaghetti (or just rice). I asked a nutritionist about it, and here is her answer. Even if they manage to avoid deadlock or livelock, dying of malnutrition is not going to be their first problem, go read the full story! [Typos and thinkos corrected after initial publication]

Cameron Dale: Making DebTorrent Work With APT

It's been a while since I've given a status update for my Google Summer of Code project to create a BitTorrent proxy for downloading packages using APT, so here it is. I've been working hard on integrating support for APT into the DebTorrent program. I've almost got it working perfectly, now it's just a matter of testing to make sure all is well. The functionality works like this: There are two things I really like about this. One of the best is the backup HTTP downloader. It insures that if you're an early adopter and there are no peers, or if the package you're requesting is rare and can't be found in any connected peers, the download will still occur in a reasonable amount of time (taking no more, or less, mirror bandwidth than if you had just been using APT directly). The other thing I like is that you get the BitTorrent-style peer-to-peer downloading, with simple HTTP proxying thrown in for free. You can run DebTorrent on a single computer on your network, and have the others connect to it to initiate downloads and request packages. I haven't done any serious time testing, but I estimate it currently only takes twice as long to use as a regular APT update and download from a mirror. Most of that slowdown is because it currently only processes a single request at a time from APT, which is not very efficient for BitTorrent systems where downloading from multiple peers is how the highest download speeds are achieved. I have been talking to the APT maintainer, Michael Vogt, about a better way to do this, probably by adding a new APT transport method for DebTorrent (i.e. debtorrent:// instead of http://). This will not only speed up the downloads, but also hopefully provide better feedback to the APT user, as currently it will seem nothing is happening until the download comes in all at once at the end. My work has unfortunately been slowed by other commitments, and bugs. I have two papers to submit to a conference by Monday, but after that I should be back full time on DebTorrent. I also spent a long time tracking down and fixing a bug in the underlying BitTornado code (which lead to much rejoicing at 3am), only to find it was fixed in upstream's CVS. (Doh!)

27 June 2007

Neil Williams: UK politics

I usually don't foray into this topic but I'm unsure whether this is something that others simply haven't noticed or whether everyone else is just being nice to the new UK PM and the new deputy leader of the governing political party.

Gordon Brown: GB
Harriet Harmann: HH

Is it just me or doesn't that just lend itself to being shortened to: GBH ?
(Grevious Bodily Harm in UK court speak) - the repetition of harm in Harmann almost qualifies as a recursive acronym!

Rob Taylor: the taste of sweet crack

I’ve been gradually pushing on in my free time on gobject-introspection, so I can make the dbus-glib bindings decent. A couple of months ago back I started hacking up a code scanner to generate the introspection xml,using code from gtk-doc, but using perl regexps to parse C just made me feel dirty… Johan Dahlin pointed me at Sparse, a front-end parser for c developed by some of the kernel guys. The only problem is that it doesn’t have language bindings (or even, seemingly, a stable abi). So I’ve just submitted a patch to sparse that adds an executable ‘c2xml‘. c2xml will dump the parse tree of the input file as a simple xml structure, suitable for manipulation by some python or suchlike. That could then be used to, say, generate c api descriptions, documentation and language bindings or make code navigation or refactoring tools. I like it!

Martin F. Krafft: Contact forms and idiot corporations

Every now and then I must get in touch with a company whose client I am. With that I mean that the company has my record in their customer database and that I can log in to their webpages with the associated account. Since companies generally don't consider their clients' comfort, they'll usually make you click about a dozen times through mazes of silly questions until you reach a HTML form you can use to send your message on the way. If you take a wrong turn anywhere in the maze, you'll be dropped into a list of frequently asked questions and have to start from scratch your quest for the contact form. I understand the motivation, which is to shield the understaffed customer support department from just those frequently asked questions. However, never has my issue been adequatly answered in those shielding documents. For instance, with Lufthansa, I've had to request ticket changes because they had screwed up (and not my travel agent), or request replacement member cards. And in the Case of Cablecom, I've been trying for months to hear their statement on why my 3500/350 kbps cable connection only ever delivers around 1500/250 (as established in a long-term trial over almost seven weeks), and to get them to stop sending several pages of advertisements about the same products with each and every invoice I get. In none of these cases could I find any useful information online, so I had to embark on the painful journey to the contact form, formulate my request into a tiny text box that would often not even be able to show start and end of a single sentence without scrolling (this is German after all), nor respect line breaks, and then hit the "send" key with a drop of sweat on my forehead because you never know what kind of crack the CGI on the other hand had smoked just a minute ago. What pisses me off most of all is, however, that in the two cases of Lufthansa and Cablecom (this list is not exhaustive, I'm sure, Sunrise is another offender), you have to login to your customer account in order to be able to fill out the contact form, where they ask you for all your contact details again. I don't understand why they want gender, birthdate, postal address, phone number, email address and whatever else for a simple support request one means of contact so they can get their answer to you should be enough. But what I surely don't understand is why they can't just use your login cookie to retrieve all those data from their data store. It sure seems like they're not really in control of their own infrastructure. And this list is not exhaustive. NP: Dredg: Live at the Fillmore

MJ Ray: Never a frown with Gordon Brown?

Finally, Gordon Brown has eventually become the eleventh Prime Minister of Queen Elizabeth II, as expected for most of his ten years as finance minister. The opening of his first speech was drowned out on the BBC by helicopters, but it continued with
"This will be a new government with new priorities. [...] meeting the concerns and aspirations of our whole country. [...] I want the best of chances for everyone. That is my mission. If we can fulfil the potential and realise the talents of all our people then I am absolutely sure that Britain can be the great global success story of this century. [...] I will try to do my utmost" (full text from ePolitix)
but there are lots of questions left open about what his utmost will be. From whether we'll see more co-operative ministers, through environmental and free-software-related policies, to just how the "clunking fist" will deal with the "trojan tory" David Cameron leader of the opposition, it's all unknown just now. I think he's the first PM who could use a Stranglers track as his theme.

Russell Coker: Strange SATA Disk Performance

Below is a GNUPlot graph of ZCAV output from a 250G SATA disk. The disk has something wrong with it (other disks of the same brand in machines of the same configuration give more regular graphs). The expected graph will start high on the Y scale (MB/s) and steadily drop as the reads go to shorter tracks near the spindle. The ZCAV results page has some examples of the expected results. If you have any ideas as to what might cause this performance result then please make a comment on this blog post. strange-sata

26 June 2007

Russell Coker: Advertising Free Software Projects

Today I just noticed the following advert on one of my web pages:
MINIX3 is a new reliable
free operating system. Smaller
than Linux. Try it It’s free!
www.minix3.org This made me think about some of the potential ways of advertising free software projects. It seems that in some ways Google Adwords is not the only way that can be used for advertising free software, and in some ways isn’t the most effective. I believe that the most effective method would be to ask people to advertise the project. I am generally positive towards the aims of the Minix project and am happy to give them some free advertising if asked (I’ve just given them a free advert above without being asked). While Google adlinks and equivalent things in blog posts are easy to set up, effective advertising may require something more. A series of pictures (in different sizes and color schemes) for the link would help, and the project would ideally have a specific landing site for people who see the advert. Someone who sees an advert targeted to newbies will have different requirements from the web site to someone who already knows about it and typed the URL in from memory! For a big campaign you would probably want to have multiple landing sites for different adverts targetted at different people. One example of how this can be used is my Bonnie++ page which gets about 6000 hits a month - many of which are from users of proprietary Unix. Linux users often have Bonnie++ as part of their distribution and don’t have much of a need to visit my web site so I expect that even though the vast majority of Bonnie++ users run Linux the proportion of site visitors might not be so strongly in favour of Linux. I would be happy to place an advert on that page to encourage proprietary Unix users to use the most free distribution of Linux if someone was to prepare the advert and give me some HTML code I can easily add to my site. To some extent the web site for every free software project could be used to advertise some related projects (or projects that are liked by the people who run the site). If you are a contributor to a free software project that you think I would like then feel free to prepare an advert and send it to me. If it fits with what I’m doing then I’ll give you some free advertising! Blogs are also a good mechanism for advertising free software projects, but it seems that this is already being used a lot - having said that… As a gratuitous plug: my favourite distribution of Linux is Debian (here are my Debian blog entries) and I run NSA Security Enhanced Linux (SE Linux) on all my machines (here are my SE Linux blog entries).

Evan Prodromou: 6 Messidor CCXV

We had a great weekend this last weekend here in Montreal. Yesterday, June 24, was Saint-Jean-Baptiste Day here in Quebec -- the national holiday of this cool and fun nation. St. Jean Baptiste is important to me in a lot of ways. Of course, it's cool that it's the national holiday of our adopted new home. But John the Baptist, the patron saint of Quebec, is also our family's name saint. ''Prodromos'' means "forerunner" in Greek, and it's one of the titles of St. John. Most of all, it's the day that Maj and I moved to Montreal. We came in on St. Jean Baptiste Day, 2003, and we've been here ever since. We drove my beautiful 1972 Citro n DS from San Francisco, where my niece Elena had just been born, all the way out here. We arrives on June 24th and wandered around the McGill Ghetto looking for our sight-unseen sublet. It's hard to believe it's only been 4 years -- it seems like so much longer. We had a good day yesterday. The three of us went to Piknic in the afternoon and hung out with our friends Jeremy and Lina and their two great kids Clea and Sylvie. We had a lot of hummus and pasta salad and bread and cheese and generally had a great time. Meg and Catherine came and hung out for a while, and also our friend Kristen, who's 7 months pregnant and has a 10-month-old. Good luck on that one. Most of all a pretty day enjoying the outdoors in our new home town, as well as fun dancing to house under a big Calder statue. How great is that? tags:

72 hours from Flickr I forgot to mention that we had a really nice time on Friday evening going to the 24 Hours of Flickr party at the SAT. Heather Champ, community leader at Flickr and welcomer to partiers, put it well: "We have three requirements for Flickr parties: the food must be good, the drinks must be copious, and the schwag must be ample." And that's exactly what happened. All the usual Montreal suspects were out in force: YULblog types, Web entrepreneurs, Web pranksters. It was great seeing m-c and c-c, who wore their awesome Flickr Socks -- although they each had a matching pair. I also talked to Allen Morris, which was really fun. He's a developer living now in Saranac Lake, one of the towns in the Adirondacks I find strangely compelling. We exchanged GPG key signatures and talked a lot about the Bay Area (California), where we both once lived. Probably my best talk was with Heather Champ and Derek Powazek. We talked about their joys of creation of JPG Magazine, the despair of leaving it, and looking forward to the future. We also chatted a lot about print on demand technologies, which we're evaluating for Wikitravel. Heather took the photo of my friend Ben Cerveny at Burning Man that's become his avatar icon on about every social software platform I know of. It must be good to capture someone in the way they want to think of themselves. I took my own self-concept picture by putting the camera on the dashboard of my Citroen. Heh. All in all a good party. One thing I was interested to find out was that there's a Yahoo! Quebec, which launched last month and I guess just slipped by me. Sadly, if you click on the "English" button, it takes you to... Yahoo! Canada. Hey, Yahoo! There are actually a lot of anglophones here! Just in case you were wondering. tags:

Montreal Web Development Book Club Montreal Web scene stalwart Heri Rakotomalala -- the man with the magic name, originally from Madagascar, along with Montevideo and Marfa, one of the M-places on my travel wishlist -- recently started a Montreal Web Development Book Club. It's a meeting for people interested in the practical side of the Web to talk about the books they read and let that drift into talk about the work we do and ideas we have. I think the book club is an awesome idea. Book clubs are a great grass-roots intellectual meetup that we don't often celebrate in the post-flash mob BarCamp-ized world. The great thing about a book club, for Web people, is that it filters out the bullshitters and dilettantes. If you're going to a book club, you're going to have to know what you're talking about, and you're going to have to care about the subject. The book gives focus that keeps the conversation from drifting to tangential topics. Flakes and hangers-on just don't have the stamina for it. Also, we met at La ka, so it was nice to have some beers in a good place on a hot night. Why not? We managed to talk about a lot of good books, too. Jean-Fran ois <something> (I didn't get his last name) talked about In Search of Stupidity, a look at the last 25 years of marketing and business blunders in the high-tech realm. Our industry is subject to a lot of decisions that seem absolutely self-defeating in hindsight, and the book goes in-depth on 15 case studies -- like Wordstar, Ashton-Tate and Borland. It sounds like a great cautionary tale for Web 2.0 startup mavens. Heri talked about the book Information Architecture for the World Wide Web -- the infamous "Polar Bear Book". It sounds like a really good book for doing initial planning for a Web site, but I'm really interested in tools for profiling an IA effort. We get about 2 million unique visitors a month at Wikitravel, for example, which is a huge amount of usability data I could be mining. But I don't really have the tools for it, so I don't do it much. I'd love to know, for example, about people who land on a Wikitravel page from a search engine and then leave. What were they looking for? Why couldn't they find it? Also, users who browse through our pages clicking on links, then resort to a full-text search. What did they think they were clicking on, and what were they looking for instead? Did they find it? How can we put that in front of them in the first place? Most of all, I want to know how and why people start editing Wikitravel pages, and why they stop. Of people who click the "edit" button, only 1 in 17 click "save". (That is one bit of clickpath analysis I've done.) Why? I've often been tempted to put a survey up when someone navigates away from our edit page. "Why didn't you save? Tell us so we can fix it for other people." I talked about the book I just finished reading a few weeks ago, Everything is Miscellaneous. It's the latest book by Dave Weinberger about how we impose order on information to make it easy to understand and retrieve. It's an awesome book -- really fun -- especially for someone married to a knowledge management expert. I don't think I gave a good enough description of the book to ignite the club's interest, but I hope they check it out, because it's really readable and good. At the end of the meeting Heri took a poll and decided that we'll continue doing the book club on the last Monday of the month. I've already picked out my book for next month: RESTful Web Services. I've heard good things about this book (admittedly mostly from the co-author Leonard Richardson) and I want to give it a look-see. So book-club fodder it is. ''Update: Heri has his own book club report here.'' tags:

25 June 2007

MJ Ray: Blogging from debconf7: 5. How many rainstorms does it take to kill one audio player?

Partly because of a lack of funding for debconf, partly because of bad organisation (long story, may be told later) and partly to get back to work (got a new contract on Thursday, so it was worth it), I left debconf on Wednesday, the day of the day trip. Those of you who were there may have noticed it rained pretty damn hard. After I checked out, I sat in the lobby and lined all my luggage with plastic, to make really sure it was waterproof. I left a few things which didn't matter, like bottles, in the side pockets, outside the plastic. I headed out with the intention of visiting Teviot one last time, to pick up things from the Front Desk which arrived after I did, but as I waded uphill, I changed my plan and headed straight for Waverley station. There I sat, snacking and drip-drying until my train left. I watched the day trippers leave, but I don't think they looked up to the bridge where I sat. There was a very strange sign fragment on the ground on the far side of the train tracks at Waverley platform 7: it said
"How many assassins does it take to kill one man?"
How debconf-coincidence is that? I tried to get a picture, but my camera wasn't happy about the light levels. Anyone else see it? Is it still there? I met some very nice people on the train to Manchester. Sat at the same table as me were a young web designer and someone who was stationed in London (during World War 2, IIRC). Both had interesting stories and both had connections to France. A fourth person got on in Lancashire and just sat quietly, reading the University of Lancaster Travel Plan 2004. Manchester city centre was fascinating. I travelled through it quite a few times more than 10 years ago, but it has poshed up since then. Most buildings seem relentlessly gothic, like someone took London St Pancras as the inspiration for an entire city, but there's the occasional classical and modernist building punctuating things. I'll put the photos up soon. After a quick walk around, I felt it was about to rain again and I didn't fancy a second soaking in one day, so I headed into a pretty good cafe called "Java" by Oxford Road station and waited for my train. The rest of the journey back was pretty uneventful, as far as I can recall. Unfortunately, once I got home, I discovered that some of my hardware was outside the plastic lining and was soaked by the first rainstorm... these posts have been delayed while I got some of it working again, but it seems that the infernal Samsung YP-U2 audio player is totally dead.

Adeodato Sim : Reminiscence

During the landing of my flight back to Alicante, I had my powered off laptop lying on my legs. A stewardess approached me and asked me to place it on the bag in the seat in front of me. I looked at her, and said: “Does not fit.”

24 June 2007

Christine Spang: DebConf7

Going: Best. Choice. Ever. (Ironically?,) I spent way less time on my computer than I do when I’m at home.

Jose Carlos Garcia Sogo: iPhone and the corporate environment

Enrique Dans writes about the "The Coming Battle: Apple's iPhone vs. Corporate IT Departments". He makes an interesting point on how this new gadget can be a point of friction between managers of IT departments and their employees using this kind of gadgets, usually corporate executives. Syncing the database with RIM devices, or redirecting email accounts (iPhone is not capable of using corporate Blackberry or MS Exchange servers), can be a problem in corporate world. If you read those articles, they blame iPhone for not supporting all these enterprise-class software.
Incompatible technology has become an increasing problem for businesses as hand-held email and phone devices are evolving into minicomputers that can do such things as download music, take pictures and surf the Web. In the past, businesses have been unwilling to support certain devices, like those with cameras, for instance, because of concerns employees could use them to document company secrets. ... A business email system can use a popular email standard known as IMAP to sync with an iPhone. While many large companies have the ability to activate IMAP, they have chosen not to because they are worried about exposing their mail servers to the public.
Basically, IT departments are blaming iPhone for not supporting their competition systems, and they are not requiring all them (and themselves) to be using standards, which were just designed to avoid this kind of problems. They are afraid. No more comments.

Jose Carlos Garcia Sogo: iPhone and the corporate environment

Enrique Dans writes about the "The Coming Battle: Apple's iPhone vs. Corporate IT Departments". He makes an interesting point on how this new gadget can be a point of friction between managers of IT departments and their employees using this kind of gadgets, usually corporate executives. Syncing the database with RIM devices, or redirecting email accounts (iPhone is not capable of using corporate Blackberry or MS Exchange servers), can be a problem in corporate world. If you read those articles, they blame iPhone for not supporting all these enterprise-class software.
Incompatible technology has become an increasing problem for businesses as hand-held email and phone devices are evolving into minicomputers that can do such things as download music, take pictures and surf the Web. In the past, businesses have been unwilling to support certain devices, like those with cameras, for instance, because of concerns employees could use them to document company secrets. ... A business email system can use a popular email standard known as IMAP to sync with an iPhone. While many large companies have the ability to activate IMAP, they have chosen not to because they are worried about exposing their mail servers to the public.
Basically, IT departments are blaming iPhone for not supporting their competition systems, and they are not requiring all them (and themselves) to be using standards, which were just designed to avoid this kind of problems. They are afraid. No more comments.

Steve Kemp: Unknown, even to its own employees, its massive profits are generated by military technology, genetic experimentation and viral weaponry

The scanning of the Debian source archive for security bugs has begun. I've wrote about this previously and there was some interest in how it worked, so I've put up a simple webpage describing the process. There are a lot of results to go through, but so far I've managed to find one local root exploit and many many many trivial problems. Sample bugs: Unfortunately my usertags seem to be broken. This was working a day or two ago. Not sure if I fucked up or if the BTS is broken ..?

Mike Hommey: Playing more with LVM, LUKS and the device mapper

Following my previous entry about playing around with LVM, LUKS and the device mapper, I documented myself about internals involved in pvmove, which is more of a challenge, considering there is no such documentation. I could find no useful documentation for either the device mapper or LVM. A bit of good old UTSL later, I could elaborate how to do what I wanted, and realized it was even possible to do in shell script. So here you are : a shell script to transform an LVM physical volume to a LVM over LUKS physical volume,. I’ll detail in between how it works. As the previous script, use at your own risk, it comes with no warranty.
Note you theorically can still access the filesystems underneath without problems. It’s an in-place and live conversion. Also note this is more a proof of concept than a proper, risk-less and well-written solution.

set -e
dev=$1
luks=$(mktemp)
cryptdev=$(basename $dev)_crypt
pvsize=$(pvs -o pe_start,pv_size --units s --noheadings --nosuffix "$dev" awk ' print $1 + $2 ')
devsize=$(blockdev --getsz "$dev")
mchunk=8
The script takes the physical volume device to convert as an argument. Note there is no check for the validity of its value.

dd of="$luks" seek=$devsize count=0 bs=512 2> /dev/null
luksdev=$(losetup -f)
losetup "$luksdev" "$luks"
trap "losetup -d \"$luksdev\"; rm -f \"$luks\"" EXIT
Next, we create a sparse luks file the same size as the device (in case luksFormat would use the size somehow, but I believe it doesn’t), and a loopback device on this file. The trap is here to avoid leaving the loopback device and the file when an error occurs later (though during the conversion itself, it will be pointless).

cryptsetup luksFormat -q "$luksdev"
cryptsetup luksOpen "$luksdev" $ cryptdev _real
read start length crypt format key IVoff cdev offset <<EOF
$(dmsetup table $ cryptdev _real)
EOF
We create a LUKS device, so that we can get the encryption key ($key), and the size of the LUKS header ($offset). Note you need to add –showkey to the dmsetup table command on sid.

if [ $(expr $devsize - $pvsize) -lt $offset ]; then
  echo Not enough free space after LVM physical volume
  cryptsetup luksClose $ cryptdev _real
  exit
fi
Check we have enough space after the LVM physical volume to offset everything by the size of the LUKS header. If not, you can still try again after you reduce the size of the LVM physical volume by an extent.

if [ $(expr $devsize % $offset % $mchunk) -gt 0 ]; then
  echo Last
  cryptsetup luksClose $ cryptdev _real
  exit
fi
This is another check to avoid surprises at the end, when dealing with the last chunk. As the script is written for the moment, it doesn’t support cases where this last chunk is not a multiple of $mchunk. So we need to abort in these.

read major minor <<EOF
$(stat -t "$dev" awk ' print $10,$11 ')
EOF
maps=$(dmsetup deps awk -F: "/\($major, $minor\)/ print \$1 ")
dmsetup create $cryptdev <<EOF
0 $length linear $dev 0
EOF
dmsetup reload $ cryptdev _real <<EOF
$start $length crypt $format $key $IVoff $dev $offset
EOF
dmsetup resume $ cryptdev _real
for map in $ maps ; do
  dmsetup table "$map" sed s,$major:$minor,/dev/mapper/$cryptdev, dmsetup reload "$map"
  dmsetup resume "$map"
done
Here, we create the dev_crypt device mapper that is our fake LUKS device, which starts as a simple linear mapper and will end as a complete crypt mapper. This fake LUKS device is inserted as an intermediate mapper between the LVM device mapper and the real device. So, the LVM device mapper will have this fake LUKS device as backend, and, at the beginning, the fake LUKS device maps linearly to the real device. Note we look for all device mappers using the real device as backend before creating the fake LUKS device to avoid finding the fake LUKS device in the list. Also note dmsetup reload only loads a new table in the INACTIVE slot, and dmsetup resume makes this inactive table LIVE.

cursor=$length
chunk=$offset
while [ $cursor -gt 0 ]; do
  cursor=$(expr $cursor - $chunk)
  if [ $cursor -lt 0 ]; then
    chunk=$(expr $chunk + $cursor)
    cursor=0
  fi
  (
  [ $cursor -ne 0 ] && echo 0 $cursor linear $dev 0
  echo $cursor $chunk mirror core 1 $mchunk 2 $dev $cursor /dev/mapper/$ cryptdev _real $cursor
  [ $cursor -lt $(expr $length - $chunk) ] && echo $(expr $cursor + $chunk) $(expr $length - $cursor - $chunk) crypt $format $key $(expr $IVoff + $cursor + $chunk) $dev $(expr $offset + $cursor + $chunk)
  ) dmsetup reload "$cryptdev"
  dmsetup resume "$cryptdev"
  chunks=$(expr $chunk / $mchunk)
  while ! dmsetup status "$cryptdev" grep "$chunks/$chunks"; do
    true
  done
done
This is where the main work is done : moving the data around. We actually just let the device mapper deal with the data duplication, $offset blocks by $offset blocks ($offset being the LUKS header size), using a mirror target for the chunk being moved. So our disk looks like the following:
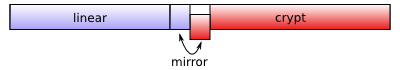
We use the extra dev_crypt_real device (the previously remapped LUKS device) as the encryption backend for the mirror.
I haven’t figured a better way to wait for the end of the mirroring than to do a loop checking with dmsetup status, dmsetup wait doesn’t seem to be very helpful here.
Anyways, this is the part of the script where you don’t want a crash to occur. Because if it does, all you can do is start on a rescue system, and try to find where the encrypted part of the disk start to setup a device mapper by hand.
And you’d better have the luks temporary file in a directory that is neither in RAM (think tmpfs) nor in the LVM you are converting (/tmp in a default etch install is, for instance ; note the script works nevertheless fine in this case). Also note the trap will remove the luks temporary file if the script exits…

dmsetup reload "$cryptdev" <<EOF
$start $length crypt $format $key $IVoff $dev $offset
EOF
dmsetup resume "$cryptdev"
dmsetup remove "$ cryptdev _real"
dd if="$luks" of=$dev count=$offset bs=512 2> /dev/null
Final steps of the conversion : our dev_crypt device becomes a full LUKS volume, so we can remove dev_crypt_real and add the LUKS headers at the top of the device we converted. At this moment, the LUKS volume is setup just as if it had been setup by cryptsetup. For LVM to recognize the change properly, you need to run pvscan. Once you ran it, you can do whatever you want with LVM. Now, you may want to add the following to your /etc/crypttab file:

$cryptdev $dev none luks
i.e. hda5_crypt /dev/hda5 none luks if the device was /dev/hda5. And if the LVM volume you converted contains your root filesystem, you should run (for Debian systems):

update-initramfs -u
I tested this successfully under qemu and will give it a shot on my laptop some time soon. Now, because I had a hard time not finding much about the mirror target of the device mapper, here is what I could gather about it. The target syntax is as follows:

<logical_start_sector> <num_sectors> mirror [ core disk ] <num_params> <param> ... <num_mirrors> [ <destination > <start_sector> ] ...
logical_start_sector, num_sectors, destination and start_sector have the same meaning as in other targets.
core and disk are two different log types (to track differences between mirrors), respectively in memory and on disk.
num_params and params depend on the log type: num_mirrors is the number of mirrors and for each mirror, we have a pair destination and start_sector. [ Update: after a quick look at the device mapper source code in Linus’s git tree, updated the mirror target description ]

Next.

Previous.