Search Results: "ed"

13 May 2015

Jonathan Dowland: Amiga floppy recovery project

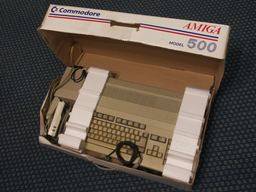
I've still got it! I've still got it!
Recovered floppy disks Recovered floppy disks

My first computer was an Amiga A500, and my brother and I spent a fair chunk of our childhoods creating things with it. These things are locked away on 3.5" floppy disks, but they were also lost a long time ago. A few weeks ago my dad found them in a box in his loft, so a disk-reading project is now on the horizon! Step one is to catalogue what we've got, which I've done here. Step two is to check which, if any, of these are not already in circulation amongst archivists. Thanks to Matthew Garrett for pointing me at the Software Preservation Society, which is a good first place to check. When we get to the reading step, there are quite a few approaches I could take. Which one to use depends to some extent on which disks we need to read, and whether they employ any custom sector layout or other copy protection schemes. I think the easiest method using equipment I already have is probably Amiga Explorer and a null-modem cable, as this approach will work on an A500 with Workbench 1.3. There are a variety of hardware tools and projects for reading Amiga floppies on a PC, but the most interesting one to me is DiscFerret, which is open hardware and software.

Ritesh Raj Sarraf: Gitolite and Gitweb

This article is for self, so that I don't again forget the specifics. The last time I did the same setup, it wasn't very important in terms of security. gitolite(3) + gitweb can give an impressive git tool with very simple user acls. After you setup gitolite, ensure that the umask value in gitolite is approriate, i.e. the gitolite group has r-x privilege. This is needed for the web view. Add your apache user to the gitolite group. With the umask changes, and the group association, apache's user will now be able to read gitolite repos. Now, imagine a repo setting like the following:
repo virtualbox
    RW+     =   admin
    R   =   gitweb
This allows 'R'ead for gitweb. But by Unix ACLs, now even www-data will have 'RX' on all (the ones created after the UMASK) the repositories.
rrs@chutzpah:~$ sudo ls -l /var/lib/gitolite3/repositories/
[sudo] password for rrs:
total 20
drwxr-x--- 7 gitolite3 gitolite3 4096 May 12 17:13 foo.git
drwx------ 8 gitolite3 gitolite3 4096 May 13 12:06 gitolite-admin.git
drwxr-x--- 7 gitolite3 gitolite3 4096 May 13 12:06 linux.git
drwx------ 7 gitolite3 gitolite3 4096 May 12 16:38 testing.git
drwxr-x--- 7 gitolite3 gitolite3 4096 May 12 17:20 virtualbox.git
13:10          
But just www-data. No other users. Because for 'O', there is no 'rwx'. And below shows gitolite's ACL in picture...
test@chutzpah:~$ git clone gitolite3@chutzpah:virtualbox
Cloning into 'virtualbox'...
Enter passphrase for key '/home/test/.ssh/id_rsa':
FATAL: R any virtualbox test DENIED by fallthru
(or you mis-spelled the reponame)
fatal: Could not read from remote repository.
Please make sure you have the correct access rights
and the repository exists.

Categories:

Keywords:

Lucas Nussbaum: systemd: Type=simple and avoiding forking considered harmful?

(This came up in a discussion on debian-user-french@l.d.o) When converting from sysvinit scripts to systemd init files, the default practice seems to be to start services without forking, and to use Type=simple in the service description. What Type=simple does is, well, simple. from systemd.service(5):

If set to simple (the default value if neither Type= nor BusName= are specified), it is expected that the process configured with ExecStart= is the main process of the service. In this mode, if the process offers functionality to other processes on the system, its communication channels should be installed before the daemon is started up (e.g. sockets set up by systemd, via socket activation), as systemd will immediately proceed starting follow-up units. In other words, systemd just runs the command described in ExecStart=, and it s done: it considers the service is started. Unfortunately, this causes a regression compared to the sysvinit behaviour, as described in #778913: if there s a configuration error, the process will start and exit almost immediately. But from systemd s point-of-view, the service will have been started successfully, and the error only shows in the logs:

root@debian:~# systemctl start ssh
root@debian:~# echo $?
0
root@debian:~# systemctl status ssh
  ssh.service - OpenBSD Secure Shell server
 Loaded: loaded (/lib/systemd/system/ssh.service; enabled)
 Active: failed (Result: start-limit) since mer. 2015-05-13 09:32:16 CEST; 7s ago
 Process: 2522 ExecStart=/usr/sbin/sshd -D $SSHD_OPTS (code=exited, status=255)
 Main PID: 2522 (code=exited, status=255)
mai 13 09:32:16 debian systemd[1]: ssh.service: main process exited, code=exited, status=255/n/a
mai 13 09:32:16 debian systemd[1]: Unit ssh.service entered failed state.
mai 13 09:32:16 debian systemd[1]: ssh.service start request repeated too quickly, refusing to start.
mai 13 09:32:16 debian systemd[1]: Failed to start OpenBSD Secure Shell server.
mai 13 09:32:16 debian systemd[1]: Unit ssh.service entered failed state.
With sysvinit, this error is detected before the fork(), so it shows during startup:
root@debian:~# service ssh start
 [....] Starting OpenBSD Secure Shell server: sshd/etc/ssh/sshd_config: line 4: Bad configuration option: blah
 /etc/ssh/sshd_config: terminating, 1 bad configuration options
 failed!
 root@debian:~#
It s not trivial to fix that. The implicit behaviour of sysvinit is that fork() sort-of signals the end of service initialization. The systemd way to do that would be to use Type=notify, and have the service signals that it s ready using systemd-notify(1) or sd_notify(3) (or to use socket activation, but that s another story). However that requires changes to the service. Returning to the sysvinit behaviour by using Type=forking would help, but is not really a solution: but what if some of the initialization happens *after* the fork? This is actually the case for sshd, where the socket is bound after the fork (see strace -f -e trace=process,network /usr/sbin/sshd), so if another process is listening on port 22 and preventing sshd to successfully start, it would not be detected. I wonder if systemd shouldn t do more to detect problems during services initialization, as the transition to proper notification using sd_notify will likely take some time. A possibility would be to wait 100 or 200ms after the start to ensure that the service doesn t exit almost immediately. But that s not really a solution for several obvious reasons. A more hackish, but still less dirty solution could be to poll the state of processes inside the cgroup, and assume that the service is started only when all processes are sleeping. Still, that wouldn t be entirely satisfying

NOKUBI Takatsugu: Jessie installer with kvm/serial console

I tried to install Jessie on a brand-new virtual machine (kvm), but it has a problem about serial console login. At least, wheezy installer worked fine because it adds getty entry on /etc/inittab. Jessie uses systemd but no care about getty service for serial console. The probrem is reported as #769406. My solution is invoke systemctl enable serial-getty@ttyS0.service via ssh.

Zlatan Todori : How to answer as a master

I have spent some fair amount of time during the life to explore making great responses to generic question (technical one included) and I can say without doubt that it is a pretty simple thing one could learn. First of all, answering question via email or in personal, it is very important that people feel that the person answering is there and is really "getting" their question. So a personal notice at beginning or at the end is not necessary but is a big plus. Particular part of answer should have 3 phases: straight yes or no answer, brief explaining why yes or no, and then explaining the opposite solution. Very important to keep it precise and simple as possible while explaining all what is needed for the person which asked question. For example Joe asks:
Can I install library libfoo1.2 without breaking software foo1.1
And Jane would answer:
Hi Joe, very good question as people often do try things like that and could end up in complicated situation. So the answer is NO. Pulling the libfoo1.2 would break foo1.1 because there were numerous changes from libfoo1.1 that break backward compatibility and there was also rewriting and porting to a newer version of language. Now having that out of way, you can safely pull also foo1.2 and install it with libfoo1.2 which is tested and should work for you without any problems. Best regards, Jane
And that's it. Lean, clean, cyborg.

12 May 2015

Simon Josefsson: Certificates for XMPP/Jabber

I am revamping my XMPP server and I ve written down notes on how to set up certificates to enable TLS. I will run Debian Jessie with JabberD 2.x, using the recent jabberd2 jessie-backport. The choice of server software is not significant for the rest of this post. Running XMPP over TLS is a good idea. So I need a X.509 PKI for this purpose. I don t want to use a third-party Certificate Authority, since that gives them the ability to man-in-the-middle my XMPP connection. Therefor I want to create my own CA. I prefer tightly scoped (per-purpose or per-application) CAs, so I will set up a CA purely to issue certificates for my XMPP server. The current XMPP specification, RFC 6120, includes a long section 13.7 that discuss requirements on Certificates. One complication is the requirement to include an AIA for OCSP/CRLs fortunately, it is not a strict MUST requirement but a weaker SHOULD . I note that checking revocation using OCSP and CRL is a MUST requirement for certificate validation some specification language impedence mismatch at work there. The specification demand that the CA certificate MUST have a keyUsage extension with the digitalSignature bit set. This feels odd to me, and I m wondering if keyCertSign was intended instead. Nothing in the XMPP document, nor in any PKIX document as far as I am aware of, will verify that the digitalSignature bit is asserted in a CA certificate. Below I will assert both bits, since a CA needs the keyCertSign bit and the digitalSignature bit seems unnecessary but mostly harmless. My XMPP/Jabber server will be chat.sjd.se and my JID will be simon@josefsson.org . This means the server certificate need to include references to both these domains. The relevant DNS records for the josefsson.org zone is as follows, see section 3.2.1 of RFC 6120 for more background.
_xmpp-client._tcp.josefsson.org.	IN	SRV 5 0 5222 chat.sjd.se.
_xmpp-server._tcp.josefsson.org.	IN	SRV 5 0 5269 chat.sjd.se.
The DNS records or the sjd.se zone is as follows:
chat.sjd.se.	IN	A	...
chat.sjd.se.	IN	AAAA	...
The following commands will generate the private key and certificate for the CA. In a production environment, you would keep the CA private key in a protected offline environment. I m asserting a expiration date ~30 years in the future. While I dislike arbitrary limits, I believe this will be many times longer than the anticipated lifelength of this setup.
openssl genrsa -out josefsson-org-xmpp-ca-key.pem 3744
cat > josefsson-org-xmpp-ca-crt.conf << EOF
[ req ]
x509_extensions = v3_ca
distinguished_name = req_distinguished_name
prompt = no
[ req_distinguished_name ]
CN=XMPP CA for josefsson.org
[ v3_ca ]
subjectKeyIdentifier=hash
basicConstraints = CA:true
keyUsage=critical, digitalSignature, keyCertSign
EOF
openssl req -x509 -set_serial 1 -new -days 11147 -sha256 -config josefsson-org-xmpp-ca-crt.conf -key josefsson-org-xmpp-ca-key.pem -out josefsson-org-xmpp-ca-crt.pem
Let s generate the private key and server certificate for the XMPP server. The wiki page on XMPP certificates is outdated wrt PKIX extensions. I will embed a SRV-ID field, as discussed in RFC 6120 section 13.7.1.2.1 and RFC 4985. I chose to skip the XmppAddr identifier type, even though the specification is somewhat unclear about it: section 13.7.1.2.1 says that it is no longer encouraged in certificates issued by certification authorities while section 13.7.1.4 says Use of the id-on-xmppAddr format is RECOMMENDED in the generation of certificates . The latter quote should probably have been qualified to say client certificates rather than certificates , since the latter can refer to both client and server certificates. Note the use of a default expiration time of one month: I believe in frequent renewal of entity certificates, rather than use of revocation mechanisms.
openssl genrsa -out josefsson-org-xmpp-server-key.pem 3744
cat > josefsson-org-xmpp-server-csr.conf << EOF
[ req ]
distinguished_name = req_distinguished_name
prompt = no
[ req_distinguished_name ]
CN=XMPP server for josefsson.org
EOF
openssl req -sha256 -new -config josefsson-org-xmpp-server-csr.conf -key josefsson-org-xmpp-server-key.pem -nodes -out josefsson-org-xmpp-server-csr.pem
cat > josefsson-org-xmpp-server-crt.conf << EOF
subjectAltName=@san
[san]
DNS=chat.sjd.se
otherName.0=1.3.6.1.5.5.7.8.7;UTF8:_xmpp-server.josefsson.org
otherName.1=1.3.6.1.5.5.7.8.7;UTF8:_xmpp-client.josefsson.org
EOF
openssl x509 -sha256 -CA josefsson-org-xmpp-ca-crt.pem -CAkey josefsson-org-xmpp-ca-key.pem -set_serial 2 -req -in josefsson-org-xmpp-server-csr.pem -out josefsson-org-xmpp-server-crt.pem -extfile josefsson-org-xmpp-server-crt.conf
With this setup, my XMPP server can be tested by the XMPP IM Observatory. You can see the c2s test results and the s2s test results. Of course, there are warnings regarding the trust anchor issue. It complains about a self-signed certificate in the chain. This is permitted but not recommended however when the trust anchor is not widely known, I find it useful to include it. This allows people to have a mechanism of fetching the trust anchor certificate should they want to. Some weaker cipher suites trigger warnings, which is more of a jabberd2 configuration issue and/or a concern with jabberd2 defaults. My jabberd2 configuration is simple in c2s.xml I add a <id> entity with the require-starttls , cachain , and pemfile fields. In s2s.xml, I have the <pemfile>, <resolve-ipv6>, and <require-tls> entities. Some final words are in order. While this setup will result in use of TLS for XMPP connections (c2s and s2s), other servers are unlikely to find my CA trust anchor, let alone be able to trust it for verifying my server certificate. I m happy to read about Peter Saint-Andre s recent SSL/TLS work, and in particular I will follow the POSH effort.

Michal &#268;iha&#345;: python-gammu 2.2

After recent porting python-gammu to Python 3, it was quite obvious to me that new release will have some problems. Fortunately they have proven to be rather cosmetic and no big bugs were found so far. Anyway it's time to push the minor fixes to the users, so here comes python-gammu 2.2. As you can see, the changes are pretty small, but given that I don't expect much development in the future, it's good to release them early.

Filed under: English Gammu python-gammu SUSE Wammu 0 comments

11 May 2015

Bits from Debian: Debian Ruby team sprint 2015

The Debian Ruby Ruby team had a first sprint in 2014. The experience was very positive, and it was decided to do it again in 2015. Last April, the team once more met at the IRILL offices, in Paris, France. The participants worked to improve the quality Ruby packages in Debian, including fixing release critical and security bugs, improving metadata and packaging code, and triaging test failures on the Debian Continuous Integration service. The sprint also served to prepare the team infrastructure for the future Debian 9 release: Group photo of sprint participants. Left to right: Christian Hofstaedtler, Tomasz Nitecki, Sebastien Badia and Antonio Terceiro Left to right: Christian Hofstaedtler, Tomasz Nitecki, Sebastien Badia and Antonio Terceiro. A full report with technical details has been posted to the relevant Debian mailing lists.

Simon Josefsson: Laptop decision fatigue

I admit defeat. I have made some effort into researching recent laptop models (see first and second post). Last week I asked myself what the biggest problem with my current 4+ year old X201 is. I couldn t articulate any significant concern. So I have bought another second-hand X201 for semi-permanent use at my second office. At ~225 USD/EUR, including another docking station, it is an amazing value. I considered the X220-X240 but they have a different docking station, and were roughly twice the price the latter allowed for a Samsung 850 PRO SSD purchase. Thanks everyone for your advice, anyway!

Julien Danjou: My interview about software tests and Python

I've recently been contacted by Johannes Hubertz, who is writing a new book about Python in German called "Softwaretests mit Python" which will be published by Open Source Press, Munich this summer. His book will feature some interviews, and he was kind enough to let me write a bit about software testing. This is the interview that I gave for his book. Johannes translated to German and it will be included in Johannes' book, and I decided to publish it on my blog today. Following is the original version. How did you come to Python?
I don't recall exactly, but around ten years ago, I saw more and more people using it and decided to take a look. Back then, I was more used to Perl. I didn't really like Perl and was not getting a good grip on its object system. As soon as I found an idea to work on if I remember correctly that was rebuildd I started to code in Python, learning the language at the same time. I liked how Python worked, and how fast I was to able to develop and learn it, so I decided to keep using it for my next projects. I ended up diving into Python core for some reasons, even doing things like briefly hacking on projects like Cython at some point, and finally ended up working on OpenStack. OpenStack is a cloud computing platform entirely written in Python. So I've been writing Python every day since working on it. That's what pushed me to write The Hacker's Guide to Python in 2013 and then self-publish it a year later in 2014, a book where I talk about doing smart and efficient Python. It had a great success, has even been translated in Chinese and Korean, so I'm currently working on a second edition of the book. It has been an amazing adventure! Zen of Python: Which line is the most important for you and why?
I like the "There should be one and preferably only one obvious way to do it". The opposite is probably something that scared me in languages like Perl. But having one obvious way to do it is and something I tend to like in functional languages like Lisp, which are in my humble opinion, even better at that. For a python newbie, what are the most difficult subjects in Python?
I haven't been a newbie since a while, so it's hard for me to say. I don't think the language is hard to learn. There are some subtlety in the language itself when you deeply dive into the internals, but for beginners most of the concept are pretty straight-forward. If I had to pick, in the language basics, the most difficult thing would be around the generator objects (yield). Nowadays I think the most difficult subject for new comers is what version of Python to use, which libraries to rely on, and how to package and distribute projects. Though things get better, fortunately. When did you start using Test Driven Development and why?
I learned unit testing and TDD at school where teachers forced me to learn Java, and I hated it. The frameworks looked complicated, and I had the impression I was losing my time. Which I actually was, since I was writing disposable programs that's the only thing you do at school. Years later, when I started to write real and bigger programs (e.g. rebuildd), I quickly ended up fixing bugs I already fixed. That recalled me about unit tests and that it may be a good idea to start using them to stop fixing the same things over and over again. For a few years, I wrote less Python and more C code and Lua (for the awesome window manager), and I didn't use any testing. I probably lost hundreds of hours testing manually and fixing regressions that was a good lesson. Though I had good excuses at that time it is/was way harder to do testing in C/Lua than in Python. Since that period, I have never stopped writing "tests". When I started to hack on OpenStack, the project was adopting a "no test? no merge!" policy due to the high number of regressions it had during the first releases. I honestly don't think I could work on any project that does not have at least a minimal test coverage. It's impossible to hack efficiently on a code base that you're not able to test in just a simple command. It's also a real problem for new comers in the open source world. When there are no test, you can hack something and send a patch, and get a "you broke this" in response. Nowadays, this kind of response sounds unacceptable to me: if there is no test, then I didn't break anything! In the end, it's just too much frustration to work on non tested projects as I demonstrated in my study of whisper source code. What do you think to be the most often seen pitfalls of TDD and how to avoid them best?
The biggest problems are when and at what rate writing tests. On one hand, some people starts to write too precise tests way too soon. Doing that slows you down, especially when you are prototyping some idea or concept you just had. That does not mean that you should not do test at all, but you should probably start with a light coverage, until you are pretty sure that you're not going to rip every thing and start over. On the other hand, some people postpone writing tests for ever, and end up with no test all or a too thin layer of test. Which makes the project with a pretty low coverage. Basically, your test coverage should reflect the state of your project. If it's just starting, you should build a thin layer of test so you can hack it on it easily and remodel it if needed. The more your project grow, the more you should make it sold and lay more tests. Having too detailed tests is painful to make the project evolve at the start. Having not enough in a big project makes it painful to maintain it. Do you think, TDD fits and scales well for the big projects like OpenStack?
Not only I think it fits and scales well, but I also think it's just impossible to not use TDD in such big projects. When unit and functional tests coverage was weak in OpenStack at its beginning it was just impossible to fix a bug or write a new feature without breaking a lot of things without even noticing. We would release version N, and a ton of old bugs present in N-2 but fixed in N-1 were reopened. For big projects, with a lot of different use cases, configuration options, etc, you need belt and braces. You cannot throw code in a repository thinking it's going to work ever, and you can't afford to test everything manually at each commit. That's just insane.

Craig Small: procps using GitLab CI

procps-ciThe procps project for a few years has been hosted at Gitorious. With the announcement that Gitorious has been acquired by GitLab and that all repositories need to move there, procps moved along to GitLab. At first I thought it would just be a like for like thing, but then I noticed that GitLab has this GitLab CI feature and had to try it out. CI here stands for Continuous Integration and is a way of automatically testing your program builds using a bunch of test scripts. procps already has a set of tests, with some a level of coverage that has room for improvement, so it was a good candidate to use for CI. The way GitLab works is they have a central control point that is linked to the git repo and you create runners, which are the systems that actually compile the programs and run the tests. The runners then feed back their results and GitLab CI shows it all in pretty red or green. The first problem was building this runner. Most of the documentation assumes you are building testing for Ruby. procps is built using C with the test scripts in TCL, so there was going to be some need to make some adjustments. I chose to use docker containers so that there was at least some isolation between the runners and the base system. I soon found the docker container I used (ruby:2.6 as suggested by GitLab) didn t have autopoint which mean autogen.sh failed so I had no configure script so no joy there. Now my second problem was I had never used docker before and beyond that it was some sort of container thing so like virtual machines lite, I didn t know much about it. The docker docs are very good and soon I had built my own custom docker image that had all the programs I need to compile and test procps. It s basically a cut-down Debian image with a few things like gettext-bin and dejagnu added in. Docker is not a full system With that all behind me and a few oh I need that too (don t forget you need git) moments we had a working CI runner. This was a Good Thing. You then find that your assumptions for your test cases may not always be correct. This is especially noticeable when testing something like procps which needs to work of the proc filesystem. A good example is, what uses session ID 1? Generally its init or systemd, but in Docker this is what everything runs as. A test case which assumes things about SID=1 will fail, as it did. This probably won t be a problem for testing a lot of normal programs that don t need to dig a deep into the host system as procps does, but it is something to remember. The docker environment looks a lot like a real system from the inside, but there are differences, so the lesson here is to write better tests (or fix the ones that failed, like I did). The runner and polling Now, there needs to be communication between the CI website and the runner, so the runner knows there is something for it to do. The gitlab runner has this setup rather well, except the runner is rather aggressive about its polling, hitting the website every 3 seconds. For someone on some crummy Australian Internet with low speeds and download quotas, this can get expensive in network resources. As there is on average an update once a week or so these seems rather excessive. My fix is pretty manual, actually its totally manual. I stop the daemon, then if I notice there are pending jobs I start the daemon, let it do its thing, then shut it down again. This is certainly not an optimal solution but works for now. I will look into doing something more clever later, possibly with webhooks.

Zlatan Todori : Reboot to roots

I am working in software development field for more then 5 years. During that period I came across of other developers which vast majority can be described as terrible people. That is what sets probably difference between hacker mind and average software engineer. People tend to think if they have position of software developer they are god-like and should be treated like that. Hackers know who they are and tend to be Socrates-wise "I know that I know nothing". As student of mechanical engineering (majoring in mechatronics) I didn't have much of programming so naturally I had some personal difficulties to grasp software field but once I got in I stopped almost totally doing my student duties as it didn't cross path with my love towards hacking. And now after that many years in software field, in which I mostly worked as freelancer for other people and companies (where it wasn't unusual that I got hired personally by a guy who couldn't or didn't know how to finish his work, I hand the code which he would present as his own work, but I don't mind as I needed the money to get on) and my work ended as proprietary - I am just fed up with all this nonsense. Someone would think what is problem there - well for me it is, as being part of Debian and wider Free software ecosystem I know proprietary software is not fostering better society in all together so it made me a bit unhappy about it. The thing that actually is really annoying me are asshole so-called software engineers and the most - bad behavior towards users. Users should be treated as supporters of your software and if proprietary company treats their users as shit then it's obvious that they don't care for the users but rather for the money and only money. Proprietary isn't here the only bad thing, open source community has it share of terrible responses - which comes naturally if you take the sheer amount of people in open source. I for instance was called on Debian IRC a peasant and even I sheep in my early days - but Debian as all communities has its bad seeds and sometimes even non-Debianities trolls hop on our channels. I didn't let myself put down because I personally got the chance to meet many of them and they change the flow of my life at that point. I am unhappy at the current state of things worldwide and personally but I have now made a decision that I am shifting towards being technical customer support engineer or for me better named as Happiness Hero. Why, one would ask because as software engineer you would make more? Well, firstly I don't care that much about money (or to be even more precise, as capitalism has made a sick money-grabbing society, you can never pay me enough as I am more worth then entire capitalistic system so in the end I don't care that much how I am paid) and secondly happiness hero can earn more then software engineer which latest #talkpay hashtag on Twitter showed. I have made IMHO many good pieces of code that will never be contributed as mine, but I achieved no happiness and rather achieved few months ago a rather bad burnout. My shift towards happiness hero should look like this - I am pretty well prepared technically for that position, I have experience with helping users and in general with people and I tend to be pretty good at that (but that we would need to ask them) and with part that I enjoy helping people to debug their technical problem so they can spend more time on others things (read family, creativity, hobbies) is something I believe will put me well into position to achieve happiness so I can create for myself time to finish damn faculty (where TBH professors showed that they can be one of the worst enemies of their students - and I am highly doubting in this generic way of schooling for centuries) and if I get some decent paycheck with this capitalistic system I will have a chance to sponsor a poor family that has child talented in artistic field - or to say SHARE something material for cultural and emotional gain. Take that capitalism! And the best part, I will start to believe more in myself so I have already few offers for that kind of position but am waiting for few more and I am screening companies to find one that fits me best - shares values with mine and has a great interaction with their users. One of the companies that makes me want to screen more companies is Buffer. When you read this and this you will see their way of life and perks are really something every company should do - then you will understand why I want to give my self a chance which I believe I finally deserved. And, no, I didn't apply for Buffer as I don't use their service nor did have time to read the two books needed for applying (which I think is really a great thing to foster people into getting more knowledge). I can only wish them best luck in future. I am currently doing one small software development thing (freelance) for next two weeks and after that I am hoping to get enough good offer to start with happiness job and retreat from software development for some good amount of time. That doesn't mean I will cease my Free software activities - on contrary I think I will have more time and even more will to work on Free software development in my spare time. So if anyone or any company that works with open source community has a position for happiness hero, get in touch with me and we will have a good talk. End point - I want to grow and become who am I, and not who I should be according to others.

10 May 2015

Eduard Sanou: Reproducible builds on Debian for GSoC 2015

This is the first blog post of a series I will be writing about my experiences contributing to Debian for Google Summer of Code 2015.

A bit about myself I m a Spanish student doing a master s in Computer Science in Barcelona. I graduated on Electrical Engineering (we call it Telecommunications here). I ve always been interested in computing and programming and I have worked on several projects on my own using C, python and go. My main interests in the field are programming languages, security, cryptography, distributed and decentralized systems and embedded systems. I m an advocate of free software, I try to use it as much as I m able to in my devices and also try to convince my friends and family of its benefits. I have been using GNU/Linux for nearly ten years as my main operating system and I have tried several *BSD s recently. One of my latest personal projects is a gameboy emulator written in C (still work in progress) which already plays many games (without sound though) . You can find other minor projects in my github page (I try to publish all the code I write online, under free software licence) After so many years of using free software and benefiting from it, I thought it was about time to contribute back! That s why I gave GSoC a try and applied to work on the Reproducible Builds project for Debian :) And I got accepted!

Reproducible Builds The idea behind this project is that currently many packages aren t built in a reproducible manner; that is, they contain timestamps, building machine name, unique IDs, and results from other processes that happen differently between machines, like file ordering in compressed files. The project aims to patch all the Debian packages / the building scripts in order to generate the same binary (bit by bit) independently of the machine, timezone, etc where it is built. This way, a cryptographic hash of the built package can be distributed and many people can rebuild the package to verify that the binary in the repositories indeed corresponds to the right source code by means of comparing the hash.

Motivation One of the main advantages of the free software is that source code is available for peer review. This makes it easier for users to trust their software, as they can check the source to verify that the program is not doing anything bad. Even if the user doesn t do that, they can trust the wider community with that task. But many distributions serve packages in binary form, so how do we know that the binary comes from the publicly available source code? The current solution is that the developers who build the packages sign them cryptographically; but this lands all the trust to the developer and the machines used for building. I became interested in this topic with a very nice talk given at 31c3 by Mike Perry from Tor and Seth Schoen from the EFF. They focused on reproducible builds applied to the tor browser bundle, showing a small demo of how a building machine could be compromised to add hidden functionalities when compiling code (so that the developer could be signing a compromised package without their knowledge).

Benefits There are two main groups who benefit with reproducible builds:

For users The user can be more secure when installing packages in binary form since they don t need to trust a specific developer or building machine. Even if they don t rebuild the package by themselves to verify it, there would be others doing so, who will easily alert the community when the binary doesn t match the source code.

For developers The developer no longer has the responsibility of using his identity to sign the package for wide distribution, nor is that much responsible of the damage to users if their machine is compromised to alter the building process, since the community will easily detect it and alert them. This later point is specially useful with secure and privacy aware software. The reason is that there are many powerful organizations around the world with interest on having backdoors in widely used software, be it to spy on users or to target specific groups of people. Considering the amount of money these organizations have for such purposes, it s not hard to imagine that they could try to blackmail developers into adding such backdoors on the built packages. Or they could try to compromise the building machine. With reproducible builds the developer is safer, as such attack is no longer useful.

Reproducible Builds in Debian The project kicked-off at Debian at mid 2013 , leaded by Lunar and soon followed by many other developers (h01ger, deki, mapreri, ). Right now about 80% of the packages in the unstable branch of Debian can be built reproducibly. The project is very active, with many developers sending patches every week. A machine running Jenkins (which was set up at the end of 2012 for other purposes) is being used since late 2014 to continuously build packages in different settings to check if they are built reproducibly or not. In order to analyze why packages fail to build reproducibly, a tool called debbindiff has been developed, which is able to output in text or html form a smart diff of two builds. Another tool called strip-nondeterminism has been developed to remove non-determinism from files during the building process. For this GSoC I plan on helping improving these tools (mainly debbindiff), write many patches to achieve reproducibility in more packages and write documentation about it. Some of the packages fail to build reproducibly due to specifics of their building processes, whereas others fail due to the usage of toolchains that add non-determinism. I ll focus more on the later ones in order to improve the state more packages. akira will also be working on this project for this GSoC. Finally, I just want to add that I m looking forward to contribute to Debian, meet the community and learn more about the internals of this awesome distribution!

Petter Reinholdtsen: Norwegian citizens now required by law to give their fingerprint to the police

5 days ago, the Norwegian Parliament decided, unanimously, that all citizens of Norway, no matter if they are suspected of something criminal or not, are required to give fingerprints to the police (vote details from Holder de ord). The law make it sound like it will be optional, but in a few years there will be no option any more. The ID will be required to vote, to get a bank account, a bank card, to change address on the post office, to receive an electronic ID or to get a drivers license and many other tasks required to function in Norway. The banks plan to stop providing their own ID on the bank cards when this new national ID is introduced, and the national road authorities plan to change the drivers license to no longer be usable as identity cards. In effect, to function as a citizen in Norway a national ID card will be required, and to get it one need to provide the fingerprints to the police. In addition to handing the fingerprint to the police (which promised to not make a copy of the fingerprint image at that point in time, but say nothing about doing it later), a picture of the fingerprint will be stored on the RFID chip, along with a picture of the face and other information about the person. Some of the information will be encrypted, but the encryption will be the same system as currently used in the passports. The codes to decrypt will be available to a lot of government offices and their suppliers around the globe, but for those that do not know anyone in those circles it is good to know that the encryption is already broken. And they can be read from 70 meters away. This can be mitigated a bit by keeping it in a Faraday cage (metal box or metal wire container), but one will be required to take it out of there often enough to expose ones private and personal information to a lot of people that have no business getting access to that information. The new Norwegian national IDs are a vehicle for identity theft, and I feel sorry for us all having politicians accepting such invasion of privacy without any objections. So are the Norwegian passports, but it has been possible to function in Norway without those so far. That option is going away with the passing of the new law. In this, I envy the Germans, because for them it is optional how much biometric information is stored in their national ID. And if forced collection of fingerprints was not bad enough, the information collected in the national ID card register can be handed over to foreign intelligence services and police authorities, "when extradition is not considered disproportionate". Update 2015-05-12: For those unable to believe that the Parliament really could make such decision, I wrote a summary of the sources I have for concluding the way I do (Norwegian Only, as the sources are all in Norwegian).

Ian Campbell: Qcontrol Homepage Moved to www.hellion.org.uk/qcontrol

Since gitorious has now shutdown I've (finally!) moved the qcontrol homepage to: http://www.hellion.org.uk/qcontrol. Source can now be found at http://git.hellion.org.uk/qcontrol.git.

9 May 2015

Daniel Silverstone: Kimchi Trial 1 - Part 1

I have spent today making my first ever batch of Kimchi. I have been documenting it in photos as I go, but thought I'd write up what I did so that if anyone else fancies having a go too, we can compare results. For a start, this recipe is nowhere near "traditional" because I don't have access to certain ingredients such as glutinous rice flour. I'm sure if I searched in many of the asian supermarkets around the city centre I could find it, but I'm lazy so I didn't even try. I am not writing this up as a traditional recipe because I'm kinda making it up as I go along, with hints from various sources including the great and wonderful Maangchi whose YouTube channel I follow. Observant readers or followers of Maangchi will recognise the recipe as being close to her Easy Kimchi recipe, however since I'm useless, it won't be exact. If this batch turns out okay then I'll write it up as a proper recipe for you to follow. I started off with three Chinese Leaf cabbages which seemed to be about 1.5kg or so once I'd stripped the less nice outer leaves, cored and chopped them. Chopped up cabbage I then soaked and drained the cabbage in cold water... Soaking cabbage ...before sprinkling a total of one third of a cup of salt over the cabbage and mixing it to distribute the salt. Salted Cabbage Then I returned to the cabbage every 30 minutes to re-mix it a total of three times. After the cabbage had been salted for perhaps 1h45m or so, I rinsed it out. Maangchi recommends washing the cabbage three times so that's what I did before setting it out to drain in a colander. Drained salted cabbage 1h45m later Maangchi then calls for the creation of a porridge made from sweet rice flour which it turns out is very glutinous. Since I lack the ability to get that flour easily I substituted cornflour which I hope will be okay and then continued as before. One cup of water, one third of a cup of cornflour was heated until it started to bubble and then one sixth of a cup of sugar was added. Stirred throughout, once it went translucent I turned the heat off and proceeded. Porridge thingy One half of a red onion, a good thumb (once peeled) of ginger, half a bulb of garlic and one third of a cup of fish sauce went into a mini-zizzer. I then diagonal-chopped about five spring onions, and one leek, before cutting a fair sized carrot into inch long pieces before halving and then thinly slicing it. Maangchi calls for julienned carrots but I am not that patient. Veggybits Into the cooled porridge I put two thirds of a cup of korean hot pepper flakes (I have the coarse, but a mix of coarse and fine would possibly be better), the zizzed onion/garlic/ginger/fish mix and the vegetables... All in the pan ...before mixing that thoroughly with a spatula. Mixed vegetables Next came the messy bit (I put latex gloves on, and thoroughly washed my gloved hands for this). Into my largest mixing bowl I put a handful of the drained cabbage into the bowl and a handful of the pepper mix. Thoroughly mixing this before adding another handful of cabbage and pepper mix I repeated until all the cabbage and hot pepper mixed vegetables are well combined. I really got your arms into it, squishing it around, separating the leek somewhat, etc. Bowl of kimchi As a final task, I scooped the kimchi into a clicklok type box, pressing it down firmly to try and remove all the air bubbles, before sealing it in for a jolly good fermenting effort. I will have to remove a little tonight for our dinner (beef strips marinated in onion, ginger and garlic, with kimchi on rice) but the rest will then sit to ferment for a bit. Expect a part-2 with the report from tonight's dinner and a part-3 with the results after fermentation. Box of kimchi
As an aside, I got my hot pepper flakes from Sous Chef who, it turns out, also stock glutinous rice flour -- I may have to get some more from them in the future. (#notsponsored)

Daniel Silverstone: Kimchi Trial 1 - Part 2

Last night we tried the small amount of 'fresh kimchi' from my epic kimchi making trial. I marinaded some beef strips in a blended paste of onion, garlic, ginger, and sesame oil for a few hours before frying that up, and serving on rice with stir-fried carrots, leek and spring onion. A little fresh kimchi on the side for flavour. Delicious dinner I think the Kimchi was a success. Dearest Rob said that it tasted of Kimchi. The flavours were not very well combined and quite clearly underdeveloped, and the pepper flakes were still a little hard. I expect this to resolve over the next few days as it begins to ferment. All in all, experiment going well, expect part 3 when I know how it tastes after fermentation begins.

Daniel Silverstone: Kimchi Trial 1 - Part 3 - Kimchiguk

Earlier this week I allowed some of my colleagues at work to try the Kimchi and one of them (James) liked it enough to ask for a tub of it just for himself. Being a lovely person I obliged. My darling Rob decided that what he really wanted was Kimchiguk or Kimchijijae. Being both wonderful and lacking in ingredients, I set to do achieving something. I read a few recipes, worked out that I lacked critical ingredients and so set about simulating Kimchiguk. I grabbed two and a bit cupfuls of kimchi from the box in the fridge, chopped it up more finely, popped it into a pot along with about a pound of cubed pork belly, two teaspoons of hot pepper flakes, two teaspoons of sugar, and two teaspoons of cornflour. I then topped that off with five cups of water, mixed it up, brought it to the boil and simmered it for 30 minutes. Then I cubed some tofu, popped that in and simmered it for another 10 minutes while some rice cooked. Served in a bowl over rice, my approximation of Kimchiguk turned out pretty well. (Note it fed both of us and there was a serving left over.) Kimchiguk - Kimchi soup With a do-over, I'd try harder to get pork shoulder (belly is quite fatty) and given the option I'd wait until I had hot pepper paste because the malty fermented sweetness of hot pepper paste is pretty much impossible to emulate otherwise.

Yves-Alexis Perez: Xfce 4.12 in Debian sid

So, following the Jessie release, and after a quick approval by the release team for the 4.12 transition, we've uploaded Xfce 4.12 to sid and have asked the RT to schedule the relevant binNMUs for the libxfce4util and xfce4-panel reverse dependencies. It went apparently well (besides some hickups here and there, lilke some lag on sparc, and some build-failulres on hurd). So Xfce 4.12 is now in sid, and should migrate to Stretch in the following weeks, provided nothing release critical is found.

Hideki Yamane: Now we don't have do-release-upgrade/fedup

We've noted some instructions to release note, but probably next step is providing upgrade tool like do-release-upgrade (ubuntu) and fedup (fedora). I hope such cool tool would be provided before Stretch release.

Or if someone would start it already, tell me about it.

Next.

Previous.