Search Results: "rul"

30 April 2016

Daniel Stender: My work for Debian in April

This month I've worked on the these things for Debian: To begin with that, I've set up a Debhelper sequencer script for dh-buildinfo1, this add-on now can be used with dh $@ --with buildinfo in deb/rules instead of having to explicitly call it somewhere in an override. Debops I've set up initial Debian packages of Debops2, a collection of fine crafted Ansible roles and playbooks especially for Debian servers (servers which run on Debian), which are shipped with a couple of helper and wrapper scripts in Python3. There are two binary packages, one for the toolset (debops), and the other for the playbooks and roles of the project (debops-playbooks). The application is easy to use, just initialize a new project with debops-init foo and add your server(s) to foo/ansible/inventory/hosts belonging to groups representing services and things you want to employ on them. For example, the group [debops_gitlab] automatically installs a complete running Gitlab setup on one or a multitude of servers in the same run with the debops command4. Other groups like [debops_mariadb_server] could be used accordingly in the same host inventory. Ansible works without agent, so you don't have to prepare freshly setup servers with nothing special to use that tool randomly (like on localhost). The list of things you could deploy with Debops is quite amazing and dozens of services are at hand. The new Debian packages are currently in experimental because they need some more fine tuning, e.g. there are a couple of minor error messages which recently occur using it, but it works well. The (early staged) documentation unfortunately couldn't be packaged because of the scattered resp. collective nature of the project (all parts have their own Github repositories)5, and also how to generate the upstream tarball remains a bit of a challenge (currently, it's the outcome of debops-init)6. I'll have this package in unstable soon. More info on Debops is coming up, then. HashiCorp's Packer I'm very glad to announce that Packer7 is ready being available in unstable, and the RFP bug could be finally closed after I've taken it over8. It's another great and much convenient devops tool which does a lot of different things in an automated fashion using only a single "one-argument" CLI tool in combination with a couple of lines in a configuration script (thanks to Yaroslav Halchenko for the tip). Packer helps creating machine images for different platforms. This is like when you use e.g. Debian installations in a Qemu box for testing or development purposes. Instead of setting up a new virtual machine manually the same way as installing Debian on another computer this process can be completely automated with Packer, like I've written about in this blog entry here9. You just need a template which contains instructions for the included Qemu builder and a preseeding script for the Debian installer, and there you go drinking your coffee while Packer does all the work: download the ISO image for installation, create the new virtual harddrive, boot the emulator, run the whole installation process automatically like with answering questions, selecting things, reboot without ISO image to complete the installation etc. A couple of minutes and you have a new pre-baked virtual machine image like from a vendoring machine, another fresh one could be created anytime. Packer10 supports a number of builders for different target platforms (desktop virtualization solutions as much as public cloud providers and private cloud software), can build in parallel, and also the full range of common provisioners can be employed in the process to equip the newly installed OSs with services and programs. Vagrant boxes could be generated by one of the included postprocessors. I'll write more on Packer here on this blog, soon. There were more then two dozens of packages missing to complete Packer11, which is the achievement of combined forces within the pkg-go group. Much thanks esp. to Alexandre Viau who have worked on the most of the needed new packages. Thanks also to the FTP masters which were always very quick in reviewing the Go packages, so that it could be proceeded to build and package the sub dependent new ones always consecutively. Squirrel3 I've didn't had the major work of that and just sponsored this for Fabian Wolff, but want to highlight here that there's a new package of Squirrel12 now available in Debian13. Squirrel is a lightweight scripting language, somewhat comparable to Lua. It's fully object-oriented and highly embeddable, it's used in a lot of commerical computer games under the hood for implementing intelligence for bots next to other things14, but also for the Internet of Things (it's embedded in hardware from Electric Imp). Squirrel functions could be called from C++15. I've filed an ITP bug for Squirrel already in 2011 (#651195), but always something else had a higher priority, and it ended up being an RFP. I'm really glad that it got picked up and completed quickly afterwards. misc There were a couple of uploads on updated upstream tarballs and for fixing bugs, namely afl/2.10b-1 and 2.11b-1, python-afl/0.5.3-1, pyutilib/5.3.2-1, pyomo/4.3.11327-1, libvigraimpex/1.10.0+git20160211.167be93dfsg-2 (fix of #820429, thanks to Tobias Frost), and gamera/3.4.2+svn1454-1. For the pkg-go group, I've set up a new package of github-mitchellh-ioprogress (which is needed by the official DigitalOcean CLI tool doctl, now RFP #807956 instead of ITP due to the lack of time, again a lot of missing packages are missing for that), and provided a little patch for dh-make-golang updating some standards16. For Packer I've also updated azure-go-autorest and azure-sdk as team upload (#821938, #821832), but it came out that the project which is currently under heavy development towards a new official release broke a lot in the past weeks (no Git branching have been used), so that Packer as a matter of fact needed a vendored snapshot, although there have been only a couple of commits in between. Docker-registry has the same problem with the new package of azure-sdk/2.1.1~beta1, so that it needed to be fixed, too (#822146). By the way, the tool ratt17 comes very handy for automatically test building down all reverse dependencies, not only for Go packages (thanks to Tianon Gravi for the tip). Finally, I've posted the needed reverse depencies as RFP bugs for Terraform18 (again quite a lot), Vuls19, and cve-dictionary20, which is needed for Vuls. I'll let them rest a while waiting to get picked up before working anything down.

26 April 2016

Jonathan McDowell: Notes on Kodi + IR remotes

This post is largely to remind myself of the details next time I hit something similar; I found bits of relevant information all over the place, but not in one single location. I love Kodi. These days the Debian packages give me a nice out of the box experience that is easy to use. The problem comes in dealing with remote controls and making best use of the available buttons. In particular I want to upgrade the VDR setup my parents have to a more modern machine that s capable of running Kodi. In this instance an AMD E350 nettop, which isn t recent but does have sufficient hardware acceleration of video decoding to do the job. Plus it has a built in fintek CIR setup. First step was finding a decent remote. The fintek is a proper IR receiver supported by the in-kernel decoding options, so I had a lot of flexibility. As it happened I ended up with a surplus to requirements Virgin V Box HD remote (URC174000-04R01). This has the advantage of looking exactly like a STB remote, because it is one. Pointed it at the box, saw that the fintek_cir module was already installed and fired up irrecord. Failed to get it to actually record properly. Googled lots. Found ir-keytable. Fired up ir-keytable -t and managed to get sensible output with the RC-5 decoder. Used irrecord -l to get a list of valid button names and proceed to construct a vboxhd file which I dropped in /etc/rc_keymaps/. I then added a
fintek-cir * vboxhd
line to /etc/rc_maps.cfg to force my new keymap to be loaded on boot. That got my remote working, but then came the issue of dealing with the fact that some keys worked fine in Kodi and others didn t. This seems to be an issue with scancodes above 0xff. I could have remapped the remote not to use any of these, but instead I went down the inputlirc approach (which is already in use on the existing VDR box). For this I needed a stable device file to point it at; the /dev/input/eventN file wasn t stable and as a platform device it didn t end up with a useful entry in /dev/input/by-id. A quick
udevadm info -a -p $(udevadm info -q path -n /dev/input/eventN)
provided me with the PNP id (FIT0002) allowing me to create /etc/udev/rules.d/70-remote-control.rules containing
KERNEL=="event*",ATTRS id =="FIT0002",SYMLINK="input/remote"
Bingo, a /dev/input/remote symlink. /etc/defaults/inputlirc ended up containing:
EVENTS="/dev/input/remote"
OPTIONS="-g -m 0"
The options tell it to grab the device for its own exclusive use, and to take all scancodes rather than letting the keyboard ones through to the normal keyboard layer. I didn t want anything other than things specifically configured to use the remote to get the key presses. At this point Kodi refused to actually do anything with the key presses. Looking at ~kodi/.kodi/temp/kodi.log I could see them getting seen, but not understood. Further searching led me to construct an Lircmap.xml - in particular the piece I needed was the <remote device="/dev/input/remote"> bit. The existing /usr/share/kodi/system/Lircmap.xml provided a good starting point for what I wanted and I dropped my generated file in ~kodi/.kodi/userdata/. (Sadly it turns out I got lucky with the remote; it seems to be using the RC-5x variant which was broken in 3.17; works fine with the 3.16 kernel in Debian 8 (jessie) but nothing later. I ve narrowed down the offending commit and raised #117221.) Helpful pages included:

Pau Garcia i Quiles: Is KDE the right place for Thunderbird?

For years, Mozilla has been saying they are no longer focused on Thunderbird and its place is outside of Mozilla. Now it seems they are going to act on what they said: Mozilla seeks new home for e-mail client Thunderbird. The candidates they are exploring are the Software Freedom Conservancy, The Document Foundation, and I expect at least the Apache Software Foundation to be a serious candidate, and Gnome to propose. Some voices in KDE say we should also propose the KDE eV as a candidate hosting organization. What follows is my opinion, not the official opinion of the eV or the board s, or the KDE Community s opinion. Take it with a grain (or more) of salt. I am not so sure. I am trying to think what the KDE eV can offer to Mozilla to be appealing to them and if my analysis is correct, we are too far and Thunderbird would pose many risks to the other projects in KDE. (I am blurring the lines between KDE eV , KDE community , KDE Frameworks , etc as it has no relevance for the discussion) Thunderbird is an open source project/product with a lot of commercial users and has (still has?) many paid contributors. IMHO what Mozilla is looking for is an organization with a well-oiled funding machine, able to campaign for money (even if in a tight circle, something like ours Patron program), and accept and process funds in a way that directly benefits Thunderbird. I e. hiring developers to implement X or Y, or work on some area full-time, or at least, half-time. KDE does not work like that. KDE has few commercial users (other than distros, if you want to count them as commercial users). Other than Blue Systems, I don t think we have any developer working for KDE. Also, the eV is not exactly a well-oiled funding machine. We have been talking about that for years. And we do not hire developers directly to work on X or Y (at most, we pay for part of the expenses of sprints). All of that makes me think we are not the right host for Thunderbird. But it does not stop there! Let s say Thunderbird comes to KDE and suddenly we are offered USD 1 M from several organizations who want to be Patrons of Thunderbird , or influence Thunderbird, or whatever. First problem: do we allow funds to go to a specific project rather than the eV deciding how to distribute them? AFAIK we do not allow that and at least one KDE sub-project has had trouble with that in the past. Then there is the thing about Patrons of Thunderbird : no such thing. Either you are a Patron of KDE, including Plasma Mobile, OwnCloud, and whatnot, or you are nothing. You cannot be a Patron of Partial KDE, namely Thunderbird . Influencing, did I say? The eV is by its own rules not an influencer on KDE s direction, just an entity to provide legal and economic support. Quite the opposite from what Mozilla does today for Thunderbird. Even if funders would not mind all that, there is the huge risk this poses for all the other projects. With as little as USD 200K donated towards Thunderbird (and USD 200K is not much for a product with so many commercial users, which means a healthy ecosystem of companies making money on support, development, etc, and thus donating to somehow influence or be perceived as important players), Thunderbird becomes the most important project in KDE. How would we manage this? In any sensible organization, Thunderbird would become the main focus and all the other KDE projects would be relegated. Even if we decide not to, external PR would make that look like it happened. For all those reasons, I think KDE is not the right place for Thunderbird at the moment. It would require a big change in what the eV can do and how it operates. And that change may be for good but it s not there now and it will not be by the time Mozilla has to decide if KDE is the right place. All that, and I have not even talked about technology and what any sensible Thunderbird customer would think today: what is the medium and long-term roadmap? Migrate Thunderbird users to Kontact/KDE PIM? Port Thunderbird to Qt + KF5, maybe including moving to QtWebEngine? Will Windows support be deteriorated by that change? Or maybe the plan is to cancel KMail and Akregator? Those are second-thoughts, unimportant right now. Update If you want to contribute to the discussion, please join the KDE-Community mailing list.

25 April 2016

Norbert Preining: G del and Daemons an excursion into literature

Explaining G del s theorems to students is a pain. Period. How can those poor creatures crank their mind around a Completeness and an Incompleteness Proof I understand that. But then, there are brave souls using G del s theorems to explain the world of demons to writers, in particular to answer the question:
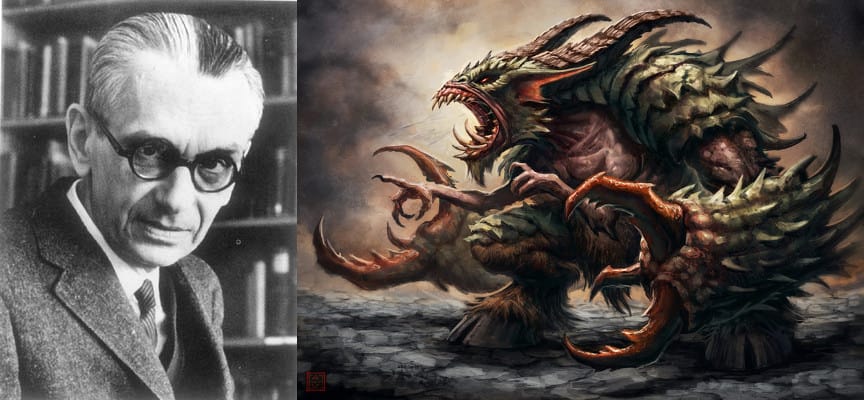
You can control a Demon by knowing its True Name, but why?
goedel-glabrezu Very impressive. Found at worldbuilding.stackexchange.com, pointed to me by a good friend. I dare to full quote author Cort Ammon (nothing more is known), to preserve this masterpiece. Thanks!!!!
Use of their name forces them to be aware of the one truth they can never know. Tl/Dr: If demons seek permanent power but trust no one, they put themselves in a strange position where mathematical truisms paint them into a corner which leaves their soul small and frail holding all the strings. Use of their name suggests you might know how to tug at those strings and unravel them wholesale, from the inside out! Being a demon is tough work. If you think facing down a 4000lb Glabrezu without their name is difficult, try keeping that much muscle in shape in the gym! Never mind how many manicurists you go through keeping the claws in shape! I don t know how creative such demons truly are, but the easy route towards the perfect French tip that can withstand the rigors of going to the gym and benching ten thousand pounds is magic. Such a demon might learn a manicure spell from the nearby resident succubi. However, such spells are often temporary. No demon worth their salt is going to admit in front of a hero that they need a moment to refresh their mani before they can fight. The hero would just laugh at them. No, if a demon is going to do something, they re going to do it right, and permanently. Not just nice french tips with a clear lacquer over the top, but razor sharp claws that resharpen themselves if they are blunted and can extend or retract at will! In fact, come to think of it, why even go to the gym to maintain one s physique? Why not just cast a magic spell which permanently makes you into the glorious Hanz (or Franz) that the trainer keeps telling you is inside you, just waiting to break free. Just get the spell right once, and think of the savings you could have on gym memberships. Demons that wish to become more powerful, permanently, must be careful. If fairy tales have anything to teach is, it s that one of the most dangerous things you can do is wish for something forever, and have it granted. Forever is a very long time, and every spell has its price. The demon is going to have to make sure the price is not greater than the perks. It would be a real waste to have a manicure spell create the perfect claws, only to find that they come with a peculiar perchance to curve towards one s own heart in an attempt to free themselves from the demon that cast them. So we need proofs. We need proofs that each spell is a good idea, before we cast it. Then, once we cast it, we need proof that the spell actually worked intended. Otherwise, who knows if the next spell will layer on top perfectly or not. Mathematics to the rescue! The world of First Order Logic (FOL, or herefter simply logic ) is designed to offer these guarantees. With a few strokes of a pen, pencil, or even brush, it can write down a set of symbols which prove, without a shadow of a doubt, that not only will the spell work as intended, but that the side effects are manageable. How? So long as the demon can prove that they can cast a negation spell to undo their previous spell, the permanency can be reverted by the demon. With a few more fancy symbols, the demon can also prove that nobody else outside of the demon can undo their permanency. It s a simple thing for mathematics really. Mathematics has an amazing spell called reductio ad infinitum which does unbelievable things. However, there is a catch. There is always a catch with magic, even when that magic is being done through mathematics. In 1931, Kurt G del published his Incompleteness Theorems. These are 3 fascinating works of mathematical art which invoke the true names of First Order Logic and Set Theory. G del was able to prove that any system which is powerful enough to prove out all of algebra (1 + 1 = 2, 2 + 1 = 3, 3 * 5 = 15, etc.), could not prove its own validity. The self referential nature of proving itself crossed a line that First Order Logic simply could not return from. He proved that any system which tries must pick up one of these five traits: If the demon wants itself to be able to cancel the spell, his proof is going to have to include his own abilities, creating just the kind of self referential effects needed to invoke G del s incompleteness theorems. After a few thousand years, the demon may realize that this is folly. A fascinating solution the demon might choose is to explore the incomplete solution to G del s challenge. What if the demon permits the spell to change itself slightly, but in an unpredictable way. If the demon was a harddrive, perhaps he lets a single byte get changed by the spell in a way he cannot expect. This is actually enough to sidestep G del s work, by introducing incompleteness. However, now we have to deal with pesky laws of physic and magics. We can t just create something out of nothing, so if we re going to let the spell change a single byte of us, there must be a single byte of information, its dual, that is unleashed into the world. Trying to break such conservation laws opens up a whole can of worms. Better to let that little bit go free into the world. Well, almost. If you repeat this process a whole bunch of times, layering spells like a Matryoska doll, you re eventually left with a soul that is nothing but the leftover bits of your spells that you simply don t know enough about to use. If someone were collecting those bits and pieces, they might have the undoing of your entire self. You can t prove it, of course, but its possible that those pieces that you sent out into the world have the keys to undo your many layers of armor, and then you know they are the bits that can nullify your soul if they get there. So what do you do? You hide them. You cast your spells only on the darkest of nights, deep in a cave where no one can see you. If you need assistants, you make sure to ritualistically slaughter them all, lest one of them know your secret and whisper it to a bundle of reeds, The king has horns, if you are familiar with the old fairy tale. Make it as hard as possible for the secret to escape, and hope that it withers away to nothingness before someone discovers it, leaving you invincible. Now we come back to the name. The demon is going to have a name it uses to describe its whole self, including all of the layers of spellcraft it has acquired. This will be a great name like Abraxis, the Unbegotten Father or Satan, lord of the underworld. However, they also need to keep track of their smaller self, their soul. Failure to keep track of this might leave them open to an attack if they had missed a detail when casting their spells, and someone uncovered something to destroy them. This would be their true name, potentially something less pompous, like Gaylord Focker or Slartybartfarst. They would never use this name in company. Why draw attention to the only part of them that has the potential to be weak. So when the hero calls out for Slartybartfarst, the demon truly must pay attention. If they know the name the demon has given over the remains of their tattered soul, might they know how to undo the demon entirely? Fear would grip their inner self, like a child, having to once again consider that they might be mortal. Surely they would wish to destroy the hero that spoke the name, but any attempt runs the risk of falling into a trap and exposing a weakness (surely their mind is racing, trying to enumerate all possible weaknesses they have). It is surely better for them to play along with you, once you use their true name, until they understand you well enough to confidently destroy you without destroying themselves. So you ask for answers which are plausible. This one needs no magic at all. None of the rules are invalid in our world today. Granted finding a spell of perfect manicures might be difficult (believe me, some women have spent their whole life searching), but the rules are simply those of math. We can see this math in non-demonic parts of society as well. Consider encryption. An AES-256 key is so hard to brute force that it is currently believed it is impossible to break it without consuming 3/4 of the energy in the Milky Way Galaxy (no joke!). However, know the key, and decryption is easy. Worse, early implementations of AES took shortcuts. They actually left the signature of the path they took through the encryption in their accesses to memory. The caches on the CPU were like the reeds from the old fable. Merely observing how long it took to read data was sufficient to gather those reeds, make a flute, and play a song that unveils the encryption key (which is clearly either The king has horns or 1-2-3-4-5 depending on how secure you think your luggage combination is). Observing the true inner self of the AES encryption implementations was enough to completely dismantle them. Of course, not every implementation fell victim to this. You had to know the name of the implementation to determine which vulnerabilities it had, and how to strike at them. Or, more literally, consider the work of Alfred Whitehead, Principia Mathematica. Principia Mathematica was to be a proof that you could prove all of the truths in arithmetic using purely procedural means. In Principia Mathematica, there was no manipulation based on semantics, everything he did was based on syntax manipulating the actual symbols on the paper. G del s Incompleteness Theorem caught Principia Mathematica by the tail, proving that its own rules were sufficient to demonstrate that it could never accomplish its goals. Principia Mathematica went down as the greatest Tower of Babel of modern mathematical history. Whitehead is no longer remembered for his mathematical work. He actually left the field of mathematics shortly afterwards, and became a philosopher and peace advocate, making a new name for himself there. (by Cort Ammon)

24 April 2016

Dominique Dumont: Automount usb devices with systemd

Hello Ever since udisk-glue was obsoleted with udisk (the first generation), I ve been struggling to find a solution to automatically mount a usb drive when such a device is connected to a kodi based home cinema PC. I wanted to avoid writing dedicated scripts or udev rules. Systemd is quite powerful and I thought that a simple solution should be possible using systemd configuration. Actually, auto-mount notion covers 2 scenario :
  1. A device is mounted after being plugged in
  2. An already available device is mounted when a process accesses its mount point
The first case is the one that is needed with Kodi. The second may be usefull so is also documented in this post. For the first case, add a line like the following in /etc/fstab:
/dev/sr0 /mnt/br auto defaults,noatime,auto,nofail 0 2
and reload systemd configuration:
sudo systemctl daemon-reload
The important parameters are auto and nofail : with auto , systemd mounts the filesystem as soon as the device is available. This behavior is different from sysvinit where auto is taken into account only when mount -a is run by init scripts. nofail ensures that boot does not fail when the device is not available. The second case is handled by a line like the following one (even if the line is split here to improve readability):
/dev/sr0 /mnt/br auto defaults,x-systemd.automount,\
   x-systemd.device-timeout=5,noatime,noauto 0 2
With the line above in /etc/fstab, the file system is mounted when user does (for instance) ls /mnt/br (actually, the first ls fails and triggers the mount. A second ls gives the expected result. There s probably a way to improve this behavior, but I ve not found it ) x-systemd.* parameters are documented in systemd.mount(5). Last but not least, using a plain device file (like /dev/sr0) works fine to automount optical devices. But it is difficult to predict the name of a device file created for a usb drive, so a LABEL or a UUID should be used in /etc/fstab instead of a plain device file. I.e. something like:
LABEL=my_usb_drive /mnt/my-drive auto defaults,auto,nofail 0 2
All the best
Tagged: kodi, systemd

21 April 2016

John Goerzen: Count me as a systemd convert

Back in 2014, I wrote about some negative first impressions of systemd. I also had a plea to debian-project to end all the flaming, pointing out that jessie will still boot , noting that my preference was for sysvinit but things are what they are and it wasn t that big of a deal. Although I still have serious misgivings about the systemd upstream s attitude, I ve got to say I find the system rather refreshing and useful in practice. Here s an example. I was debugging the boot on a server recently. It mounts a bunch of NFS filesystems and runs a third-party daemon that is started from an old-style /etc/init.d script. We had a situation where the NFS filesystems the daemon required didn t mount on boot. The daemon then was started, and unfortunately it basically does a mkdir -p on startup. So it started running and processing requests with negative results. So there were two questions: why did the NFS filesystems fail to start, and how could we make sure the daemon wouldn t start without them mounted? For the first, journalctl -xb was immensely helpful. It logged the status of each individual mount, and it turned out that it looked like a modprobe or kernel race condition when a bunch of NFS mounts were kicked off in parallel and all tried to load the nfsv4 module at the same time. That was easy enough to work around by adding nfsv4 to /etc/modules. Now for the other question: refusing to start the daemon if the filesystems weren t there. With systemd, this was actually trivial. I created /etc/systemd/system/mydaemon.service.requires (I ll call the service mydaemon here), and in it I created a symlink to /lib/systemd/system/remote-fs.target. Then systemctl daemon-reload, and boom, done. systemctl list-dependencies mydaemon will even show the the dependency tree, color-coded status of each item on it, and will actually show every single filesystem that remote-fs requires and the status of it in one command. Super handy. In a non-systemd environment, I d probably be modifying the init script and doing a bunch of manual scripting to check the filesystems. Here, one symlink and one command did it, and I get tools to inspect the status of the mydaemon prerequisites for free. I ve got to say, as someone that has occasionally had to troubleshoot boot ordering and update-rc.d symlink hell, troubleshooting this stuff in systemd is considerably easier and the toolset is more powerful. Yes, it has its set of poorly-documented complexity, but then so did sysvinit. I never thought the world is falling folks were right, but by now I can be counted among those that feels like systemd has matured to the point where it truly is superior to sysvinit. Yes, in 2014 it had some bugs, but by here in 2016 it looks pretty darn good and I feel like Debian s decision has been validated through my actual experience with it.

Mario Lang: Scraping the web with Python and XQuery

During a JAWS for Windows training, I was introduced to the Research It feature of that screen reader. Research It is a quick way to utilize web scraping to make working with complex web pages easier. It is about extracting specific information from a website that does not offer an API. For instance, look up a word in an online dictionary, or quickly check the status of a delivery. Strictly speaking, this feature does not belong in a screen reader, but it is a very helpful tool to have at your fingertips. Research It uses XQuery (actually, XQilla) to do all the heavy lifting. This also means that the Research It Rulesets are theoretically also useable on other platforms. I was immediately hooked, because I always had a love for XPath. Looking at XQuery code is totally self-explanatory for me. I just like the syntax and semantics. So I immediately checked out XQilla on Debian, and found #821329 and #821330, which were promptly fixed by Tommi Vainikainen, thanks to him for the really quick response! Unfortunately, making xqilla:parse-html available and upgrading to the latest upstream version is not enough to use XQilla on Linux with the typical webpages out there. Xerces-C++, which is what XQilla uses to fetch web resources, does not support HTTPS URLs at the moment. I filed #821380 to ask for HTTPS support in Xerces-C to be enabled by default. And even with HTTPS support enabled in Xerces-C, the xqilla:parse-html function (which is based on HTML Tidy) fails for a lot of real-world webpages I tried. Manually upgrading the six year old version of HTML Tidy in Debian to the latest from GitHub (tidy-html5, #810951) did not help a lot either.
Python to the rescue XQuery is still a very nice language for extracting information from markup documents. XQilla just has a bit of a hard time dealing with the typical HTML documents out there. After all, it was designed to deal with well-formed XML documents. So I decided to build myself a little wrapper around XQilla which fetches the web resources with the Python Requests package, and cleans the HTML document with BeautifulSoup (which uses lxml to do HTML parsing). The output of BeautifulSoup can apparently be passed to XQilla as the context document. This is a fairly crazy hack, but it works quite reliably so far. Here is how one of my web scraping rules looks like:
from click import argument, group
@group()
def xq():
  """Web scraping for command-line users."""
  pass
@xq.group('github.com')
def github():
  """Quick access to github.com."""
  pass
@github.command('code_search')
@argument('language')
@argument('query')
def github_code_search(language, query):
  """Search for source code."""
  scrape(get='https://github.com/search',
         params= 'l': language, 'q': query, 'type': 'code' )
The function scrape automatically determines the XQuery filename according to the callers function name. Here is how github_code_search.xq looks like:
declare function local:source-lines($table as node()*) as xs:string*
 
  for $tr in $table/tr return normalize-space(data($tr))
 ;
let $results := html//div[@id="code_search_results"]/div[@class="code-list"]
for $div in $results/div
let $repo := data($div/p/a[1])
let $file := data($div/p/a[2])
let $link := resolve-uri(data($div/p/a[2]/@href))
return (concat($repo, ": ", $file), $link, local:source-lines($div//table),
        "---------------------------------------------------------------")
That is all I need to implement a custom web scraping rule. A few lines of Python to specify how and where to fetch the website from. And a XQuery file that specifies how to mangle the document content. And thanks to the Python click package, the various entry points of my web scraping script can easily be called from the command-line. Here is a sample invokation:
fx:~/xq% ./xq.py github.com
Usage: xq.py github.com [OPTIONS] COMMAND [ARGS]...
  Quick access to github.com.
Options:
  --help  Show this message and exit.
Commands:
  code_search  Search for source code.
fx:~/xq% ./xq.py github.com code_search Pascal '"debian/rules"'
prof7bit/LazPackager: frmlazpackageroptionsdeb.pas
https://github.com/prof7bit/LazPackager/blob/cc3e35e9bae0c5a582b0b301dcbb38047fba2ad9/frmlazpackageroptionsdeb.pas
230 procedure TFDebianOptions.BtnPreviewRulesClick(Sender: TObject);
231 begin
232 ShowPreview('debian/rules', EdRules.Text);
233 end;
234
235 procedure TFDebianOptions.BtnPreviewChangelogClick(Sender: TObject);
---------------------------------------------------------------
prof7bit/LazPackager: lazpackagerdebian.pas
https://github.com/prof7bit/LazPackager/blob/cc3e35e9bae0c5a582b0b301dcbb38047fba2ad9/lazpackagerdebian.pas
205 + 'mv ../rules debian/' + LF
206 + 'chmod +x debian/rules' + LF
207 + 'mv ../changelog debian/' + LF
208 + 'mv ../copyright debian/' + LF
---------------------------------------------------------------
For the impatient, here is the implementation of scrape:
from bs4 import BeautifulSoup
from bs4.element import Doctype, ResultSet
from inspect import currentframe
from itertools import chain
from os import path
from os.path import abspath, dirname
from subprocess import PIPE, run
from tempfile import NamedTemporaryFile
import requests
def scrape(get=None, post=None, find_all=None,
           xquery_name=None, xquery_vars= , **kwargs):
  """Execute a XQuery file.
  When either get or post is specified, fetch the resource and run it through
  BeautifulSoup, passing it as context to the XQuery.
  If find_all is given, wrap the result of executing find_all on
  the BeautifulSoup in an artificial HTML body.
  If xquery_name is not specified, the callers function name is used.
  xquery_name combined with extension ".xq" is searched in the directory
  where this Python script resides and executed with XQilla.
  kwargs are passed to get or post calls.  Typical extra keywords would be:
  params -- To pass extra parameters to the URL.
  data -- For HTTP POST.
  """
  response = None
  url = None
  context = None
  if get is not None:
    response = requests.get(get, **kwargs)
  elif post is not None:
    response = requests.post(post, **kwargs)
  if response is not None:
    response.raise_for_status()
    context = BeautifulSoup(response.text, 'lxml')
    dtd = next(context.descendants)
    if type(dtd) is Doctype:
      dtd.extract()
    if find_all is not None:
      context = context.find_all(find_all)
    url = response.url
  if xquery_name is None:
    xquery_name = currentframe().f_back.f_code.co_name
  cmd = ['xqilla']
  if context is not None:
    if type(context) is BeautifulSoup:
      soup = context
      context = NamedTemporaryFile(mode='w')
      print(soup, file=context)
      cmd.extend(['-i', context.name])
    elif isinstance(context, list) or isinstance(context, ResultSet):
      tags = context
      context = NamedTemporaryFile(mode='w')
      print('<html><body>', file=context)
      for item in tags: print(item, file=context)
      print('</body></html>', file=context)
      context.flush()
      cmd.extend(['-i', context.name])
  cmd.extend(chain.from_iterable(['-v', k, v] for k, v in xquery_vars.items()))
  if url is not None:
    cmd.extend(['-b', url])
  cmd.append(abspath(path.join(dirname(__file__), xquery_name + ".xq")))
  output = run(cmd, stdout=PIPE).stdout.decode('utf-8')
  if type(context) is NamedTemporaryFile: context.close()
  print(output, end='')
The full source for xq can be found on GitHub. The project is just two days old, so I have only implemented three scraping rules as of now. However, adding new rules has been made deliberately easy, so that I can just write up a few lines of code whenever I find something on the web which I'd like to scrape on the command-line. If you find this "framework" useful, make sure to share your insights with me. And if you impelement your own scraping rules for a public service, consider sharing that as well. If you have an comments or questions, send me mail. Oh, and by the way, I am now also on Twitter as @blindbird23.

20 April 2016

Jonathan Dowland: mount-on-demand backups

Last week, someone posted a request for help on the popular Server Fault Q&A site: they had apparently accidentally deleted their entire web hosting business, and all their backups. The post (now itself deleted) was a reasonably obvious fake, but mainstream media reported on it anyway, and then life imitated art and 123-reg went and did actually delete all their hosted VMs, and their backups. I was chatting to some friends from $job-2 and we had a brief smug moment that we had never done anything this bad, before moving on to incredulity that we had never done anything this bad in the 5 years or so we were running the University web servers. Some time later I realised that my personal backups were at risk from something like this because I have a permanently mounted /backup partition on my home NAS. I decided to fix it. I already use Systemd to manage mounting the /backup partition (via a backup.mount file) and its dependencies. I'll skip the finer details of that for now. I planned to define some new Systemd units for each backup job which was previously scheduled via Cron in order that I could mark them as depending on the /backup mount. I needed to adjust that mount definition by adding StopWhenUnneeded=true. This ensures that /backup will be unmounted when it is not in use by another job, and not at risk of a stray rm -rf. The backup jobs are all simple shell scripts that convert quite easily into services. An example: backup-home.service:
[Unit]
Requires=backup.mount
After=backup.mount
[Service]
User=backupuser
Group=backupuser
ExecStart=/home/backupuser/bin/phobos-backup-home
To schedule this, I also need to create a timer: backup-home.timer:
[Timer]
OnCalendar=*-*-* 04:01:00
[Install]
WantedBy=timers.target
To enable the timer, you have to both enable and start it:
systemctl enable backup-home.timer
systemctl start backup-home.timer
I created service and timer units for each of my cron jobs. The other big difference to driving these from Cron is that by default I won't get any emails if the jobs generate output - in particular, if they fail. I definitely do want mail if things fail. The Arch Wiki has an interesting proposed solution to this which I took a look at. It's a bit clunky, and my initial experiments with a derivation from this (using mail(1) not sendmail(1)) have not yet generated any mail. Pros and Cons The Systemd timespec is more intuitive than Cron's. It's a shame you need a minimum of three more lines of boilerplate for the simplest of timers. I think WantedBy=timers.target should probably be an implicit default for all .timer type units. Here I think clarity suffers in the name of consistency. With timers, start doesn't kick-off the job, it really means "enable" in the context of timers, which is clumsy considering the existing enable verb, which seems almost superfluous, but is necessary for consistency, since Systemd units need to be enabled before they can be started As Simon points out in the comments, this is not true. Rather, "enable" is needed for the timer to be active upon subsequent boots, but won't enable it in the current boot. "Start" will enable it for the current boot, but not for subsequent ones. Since I need a .service and a .unit file for each active line in my crontab, that's a lot of small files (twice as many as the number of jobs being defined) and they're all stored in system-wide folder because of the dependency on the necessarily system-level units defining the mount. It's easy to forget the After= line for the backup services. On the one hand, it's a shame that After= doesn't imply Require=, so you don't need both; or alternatively there was a convenience option that did both. On the other hand, there are already too many Systemd options and adding more conjoined ones would just make it even more complicated. It's a shame I couldn't use user-level units to achieve this, but they could not depend on the system-level ones, nor activate /backup. This is a sensible default, since you don't want any user to be able to start any service on-demand, but some way of enabling it for these situations would be good. I ruled out systemd.automount because a stray rm -rf would trigger the mount which defeats the whole exercise. Apparently this might be something you solve with Polkit, as the Arch Wiki explains, which looks like it has XML disease. I need to get mail-on-error working reliably.

18 April 2016

Dirk Eddelbuettel: RcppCCTZ 0.0.4

A few days ago a new upstream version "2.0" of CCTZ was released. See here for the corresponding post on the Google OpenSource Blog. CCTZ is a C++ library for translating between absolute and civil times using the rules of a time zone. It requires only a proper C++11 compiler and the standard IANA time zone data base which standard Unix, Linux, OS X, ... computers tend to have in /usr/share/zoneinfo. RcppCCTZ connects this library to R by relying on Rcpp. This new version adds more support to the notion of civil time representation -- i.e. independent of timezones -- which can then be mapped to different time zone representations. Changes in this version are summarized here:
Changes in version 0.0.4 (2016-04-17)
  • Synchronized with CCTZ v2 upstream.
  • Updated examples.cpp accordingly
A quick example is provided here where we look at the time when Neil Armstrong first stepped on the moon as an absolute ("civil") time and two local representations:
// from examples/hello.cc
// 
// [[Rcpp::export]]
int helloMoon()  
    cctz::time_zone syd;
    if (!cctz::load_time_zone("Australia/Sydney", &syd)) return -1;
    // Neil Armstrong first walks on the moon
    const auto tp1 = cctz::convert(cctz::civil_second(1969, 7, 21, 12, 56, 0), syd);
    const std::string s = cctz::format("%F %T %z", tp1, syd);
    Rcpp::Rcout << s << "\n";
    cctz::time_zone nyc;
    cctz::load_time_zone("America/New_York", &nyc);
    const auto tp2 = cctz::convert(cctz::civil_second(1969, 7, 20, 22, 56, 0), nyc);
    return tp2 == tp1 ? 0 : 1;
 
We can call this from R, and get the expected result (of equivalence between the dates):
R> library(RcppCCTZ)
R> helloMoon()
1969-07-21 12:56:00 +1000
[1] 0
R>
We also have a diff to the previous version thanks to CRANberries. More details, issue tickets etc at the GitHub repository.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

16 April 2016

Scott Kitterman: Future of secure systems in the US

As a rule, I avoid writing publicly on political topics, but I m making an exception. In case you haven t been following it, the senior Republican and the senior Democrat on the Senate Intelligence Committee recently announced a legislative proposal misleadingly called the Compliance with Court Orders Act of 2016. The full text of the draft can be found here. It would effectively ban devices and software in the United States that the manufacturer cannot retrieve data from. Here is a good analysis of the breadth of the proposal and a good analysis of the bill itself. While complying with court orders might sound great in theory, in practice this means these devices and software will be insecure by design. While that s probably reasonably obvious to most normal readers here, don t just take my word for it, take Bruce Schneier s. In my opinion, policy makers (and it s not just in the United States) are suffering from a perception gap about security and how technically hard it is to get right. It seems to me that they are convinced that technologists could just do security right while still allowing some level of extraordinary access for law enforcement if they only wanted to. We ve tried this before and the story never seems to end well. This isn t a complaint from wide eyed radicals that such extraordinary access is morally wrong or inappropriate. It s hard core technologists saying it can t be done. I don t know how to get the message across. Here s President Obama, in my opinion, completely missing the point when he equates a desire for security with fetishizing our phones above every other value. Here are some very smart people trying very hard to be reasonable about some mythical middle ground. As Riana Pfefferkorn s analysis that I linked in the first paragraph discusses, this middle ground doesn t exist and all the arm waving in the world by policy makers won t create it. Coincidentally, this same week, the White House announced a new Commission on Enhancing National Cybersecurity . Cybersecurity is certainly something we could use more of, unfortunately Congress seems to be heading off in the opposite direction and no one from the executive branch has spoken out against it. Security and privacy are important to many people. Given the personal and financial importance of data stored in computers (traditional or mobile), users don t want criminals to get a hold of it. Companies know this, which is why both Apple IOS and Google Android both encrypt their local file systems by default now. If a bill anything like what s been proposed becomes law, users that care about security are going to go elsewhere. That may end up being non-US companies products or US companies may shift operations to localities more friendly to secure design. Either way, the US tech sector loses. A more accurate title would have been Technology Jobs Off-Shoring Act of 2016. EDIT: Fixed a typo.

13 April 2016

Petter Reinholdtsen: I.F. Stone - an inspiration for us all

I first got to know I.F. Stone when I came across an article by Jon Schwarz on The Intercept about his extraordinary contribution to investigative journalism in USA. The article is about a new documentary in two parts (part one is 12 minutes and part two is 30 minutes), and I found both truly fascinating. It is amazing what he was able to find by digging up public sources and government papers. He documented lots of government abuse and cover ups, and I find his weekly news letters inspiring to read even today.
All governments are run by liars and nothing they say should be believed.
- I. F. Stone
His starting point was that reporters should not assume governments and corporations are telling the truth, but verify all their claims as much as possible. I wonder how many Norwegian reporters can be said to follow the principles of I. F. Stone. They are definitely in short supply. If you, like me half a year ago, have never heard of him, check him out.

Mehdi Dogguy: 2016 DPL election

It is time of the year where Debian project members should elect a new project leader. This year, only one candidate has stepped up, yours truly. As a reminder, my platform is published here. The campaign has been quite calm, comparing to past editions, which is not surprising given the number of candidates. There have been some interesting questions though as detailed below:
There are not many questions. It will take little time to read, if you haven't already.

Last but not least, please do vote! You have until 2016-04-16 23:59:59 UTC to vote (as announced here). It is very important to share your opinion and take part in the reflection around the future of the project. That every project member takes part in the evolutions that should be implemented to stay relevant and innovative in what we do.

26 March 2016

Jonathan McDowell: Dr Stoll: Or how I learned to stop worrying and love the GPL

[I wrote this as part of BelFOSS but I think it s worth posting here.] My Free Software journey starts with The Cuckoo s Egg. Back in the early 90s a family friend suggested I might enjoy reading it. He was right; I was fascinated by the world of interconnected machines it introduced me to. That helped start my involvement in FidoNet, but it also got me interested in Unix. So when I saw a Linux book at the Queen s University bookshop (sadly no longer with us) with a Slackware CD in the back I had to have it. The motivation at this point was to have a low cost version of Unix I could run on the PC hardware I already owned. I had no knowledge of the GNU Project before this point, and as I wasn t a C programmer I had no interest in looking at the source code. I spent some time futzing around with it and that partition (I was dual booting with DOS 6.22) fell into disuse. It wasn t until I d learnt some C and turned up to university, which provided me with an internet connection and others who were either already using Linux or interested in doing so, that I started running a Linux box full time. Once I was doing that I became a lot more interested in the Open Source side of the equation. Rather than running a closed operating system that even the API for wasn t properly specified (or I wouldn t have needed my copy of Undocumented DOS) I had the complete source to both the underlying OS and all the utilities that it was using. For someone doing a computer science degree this was invaluable. Minix may have been the OS discussed in the OS Design module I studied, but Linux was a much more feature complete option that I was running on my desktop and could also peer under the hood of. In my professional career I ve always welcomed the opportunities to work with Open Source. A long time ago I experienced a particularly annoying issue when writing a device driver under QNX. The documentation didn t seem to match the observed behaviour of the subsystem I was interfacing with. However due to licensing issues only a small number of people in the organisation were able to actually look at the QNX source. So I ended up wasting a much more senior engineer s time with queries like I think it s actually doing x, y and z instead of a, b and c; can you confirm? . Instances where I can look directly at the source code myself make me much more productive. Commercial development also started to make me more understanding of the Free Software nature of the code I was running. It wasn t just the ability to look at the code which was useful, but also the fact there was no need to reinvent the wheel. Need a base OS to build an appliance on? Debian ensures that the main component is Free for all usage. No need to worry about rolling your own compilers, base libraries etc. From a commercial perspective that allows you to concentrate on the actual product. And when you hit problems, the source is available and you can potentially fix it yourself or at least more easily find out if there s been a fix for that issue released (being able to see code development in version control systems rather than getting a new upstream release with a whole heap on unrelated fixes in it really helps with that). I had thus progressed from using FLOSS because it was free-as-in-beer, to appreciating the benefits of Open Source in my own learning and employment experiences, to a deeper understanding of the free-as-in-speech benefits that could be gained. However at this point I was still thinking very much from a developer mindset. Even my thoughts about how users can benefit from Free Software were in the context of businesses being able to easily switch suppliers or continue to maintain legacy software because they had the source to their systems available. One of the major factors that has helped me to see beyond this is the expansion of the Internet of Things (IoT). With desktop or server software there is by and large a choice about what to use. This is not the case with appliances. While manufacturers will often produce a few revisions of software for their devices, usually eventually there is a newer and shiny model and the old one is abandoned. This is problematic for many reasons. For example, historically TVs have been long lived devices (I had one I bought second hand that happily lasted me 7+ years). However the smart capabilities of the TV I purchased in 2012 are already of limited usefulness, and LG have moved on to their current models. I have no intention of replacing the device any time soon, so have had to accept it is largely acting as a dumb display. More serious is the lack of security updates. For a TV that doesn t require a network connection to function this is not as important, but the IoT is a trickier proposition. For example Matthew Garrett had an awful experience with some intelligent light bulbs, which effectively circumvented any home network security you might have set up. The manufacturer s defence? No longer manufactured or supported. It s cases like these that have slowly led me to a more complete understanding of the freedom that Free Software truly offers to users. It s not just about cost free/low cost software. It s not just about being able to learn from looking at the source to the programs you are running. It s not even about the freedom to be able to modify the programs that we use. It s about giving users true Freedom to use and modify their devices as they see fit. From this viewpoint it is much easier to understand the protections against Tivoization that were introduced with GPLv3, and better appreciate the argument sometimes made that the GPL offers more freedom than BSD style licenses.

23 March 2016

Petter Reinholdtsen: Full battery stats collector is now available in Debian

Since this morning, the battery-stats package in Debian include an extended collector that will collect the complete battery history for later processing and graphing. The original collector store the battery level as percentage of last full level, while the new collector also record battery vendor, model, serial number, design full level, last full level and current battery level. This make it possible to predict the lifetime of the battery as well as visualise the energy flow when the battery is charging or discharging. The new tools are available in /usr/share/battery-stats/ in the version 0.5.1 package in unstable. Get the new battery level graph and lifetime prediction by running:
/usr/share/battery-stats/battery-stats-graph /var/log/battery-stats.csv
Or select the 'Battery Level Graph' from your application menu. The flow in/out of the battery can be seen by running (no menu entry yet):
/usr/share/battery-stats/battery-stats-graph-flow
I'm not quite happy with the way the data is visualised, at least when there are few data points. The graphs look a bit better with a few years of data. A while back one important feature I use in the battery stats collector broke in Debian. The scripts in /usr/lib/pm-utils/power.d/ were no longer executed. I suspect it happened when Jessie started using systemd, but I do not know. The issue is reported as bug #818649 against pm-utils. I managed to work around it by adding an udev rule to call the collector script every time the power connector is connected and disconnected. With this fix in place it was finally time to make a new release of the package, and get it into Debian. If you are interested in how your laptop battery is doing, please check out the battery-stats in Debian unstable, or rebuild it on Jessie to get it working on Debian stable. :) The upstream source is available from github. As always, patches are very welcome.

Ingo Juergensmann: Xen randomly crashing server

It's a long story... an oddessey of almost two years... But to start from the beginning: Back then I rented a server at Hetzner until they decided to bill for every IP address you got from them. I got a /26 in the past and so I would have to pay for every IP address of that subnet in addition to the server rent of 79.- EUR/month. That would have meant nearly doubling the monthly costs. So I moved with my server from Hetzner to rrbone Net, which offered me a /26 on a rented Cisco C200 M2 server for a competitve price. After migrating the VMs from Hetzner to rrbone with the same setup that was running just fine at Hetzner I experienced spontaneous reboots of the server, sometimes several times per day and in short time frame. The hosting provider was very, very helpful in debugging this like exchanging the memory, setting up a remote logging service for the CIMC and such. But in the end we found no root cause for this. The CIMC logs showed that the OS was rebooting the machine. Anyway, I then bought my own server and exchanged the Cisco C200 by my own hardware, but the reboots still happen as before. Sometimes the servers runs for weeks, sometimes the server crashes 4-6 times a day, but usually it's like a pattern: when it crashes and reboots, it will do that again within a few hours and after the second reboot the chances are high that the server will run for several days without a reboot - or even weeks. The strange thing is, that there are absolutely no hints in the logs, neither syslog or in the Xen logs, so I assume that's something quite deep in the kernel that causes the reboot. Another hint is, that the reboots fairly often happened, when I used my Squid proxy on one of the VMs to access the net. I'm connecting for example by SSH with portforwarding to one VM, whereas the proxy runs on another VM, which led to network traffic between the VMs. Sometimes the server crashed on the very firsts proxy requests. So, I exchanged Squid by tinyproxy or other proxies, moved the proxy from one VM to that VM I connect to using SSH, because I thought that the inter-VM traffic may cause the machine to reboot. Moving the proxy to another virtual server I rented at another hosting provider to host my secondary nameserver did help a little bit, but with no real hard proof and statistics, just an impression of mine. I moved from xm toolstack to xl toolstack as well, but didn't help either. The reboots are still happening and in the last few days very frequent. Even with the new server I exchanged the memory, used memory mirroring as well, because I thought that it might be a faulty memory module or something, but still rebooting out of the blue. During the last weekend I configured grub to include "noreboot" command line and then got my first proof that somehow the Xen network stack is causing the reboots: This is a screenshot of the IPMI console, so it's not showing the full information of that kernel oops, but as you can see, there are most likely such parts involved like bridge, netif, xenvif and the physical igb NIC. Here's another screenshot of a crash from this night: Slightly different information, but still somehow network involved as you can see in the first line (net_rx_action). So the big question is: is this a bug Xen or with my setup? I'm using xl toolstack, the xl.conf is basically the default, I think:
## Global XL config file ##

# automatically balloon down dom0 when xen doesn't have enough free
# memory to create a domain
autoballoon=0

# full path of the lockfile used by xl during domain creation
#lockfile="/var/lock/xl"

# default vif script
#vif.default.script="vif-bridge"
With this the default network scripts of the distribution (i.e. Debian stable) should be used. The network setup consists of two brdiges:
auto xenbr0
iface xenbr0 inet static
address 31.172.31.193
netmask 255.255.255.192
gateway 31.172.31.254
bridge_ports eth0
pre-up brctl addbr xenbr0 auto xenbr1
iface xenbr1 inet static
address 192.168.254.254
netmask 255.255.255.0
pre-up brctl addbr xenbr1
There are some more lines to that config like setting up some iptables rules with up commands and such. But as you can see my eth0 NIC is part of the "main" xen bridge with all the IP addresses that are reachable from the outside. The second bridge is used for internal networking like database connections and such. I would rather like to use a netconsole to capture the full debug output in case of a new crash, but unfortunately this only works until the bridge is brought up and in place:
[ 0.000000] Command line: placeholder root=UUID=c3....22 ro debug ignore_loglevel loglevel=7 netconsole=port@31.172.31.193/eth0,514@5.45.x.y/e0:ac:f1:4c:y:x
[ 32.565624] netpoll: netconsole: local port $port
[ 32.565683] netpoll: netconsole: local IPv4 address 31.172.31.193
[ 32.565742] netpoll: netconsole: interface 'eth0'
[ 32.565799] netpoll: netconsole: remote port 514
[ 32.565855] netpoll: netconsole: remote IPv4 address 5.45.x.y
[ 32.565914] netpoll: netconsole: remote ethernet address e0:ac:f1:4c:y:x
[ 32.565982] netpoll: netconsole: device eth0 not up yet, forcing it
[ 36.126294] netconsole: network logging started
[ 49.802600] netconsole: network logging stopped on interface eth0 as it is joining a master device
So, the first question is: how to use netconsole with an interface that is used on a bridge? The second question is: is the setup with two bridges with Xen ok? I've been using this setup for years now and it worked fairly well on the Hetzner server as well, although I used there xm toolstack with a mix of bridge and routed setup, because Hetzner didn't like to see the MAC addresses of the other VMs on the switch and shut the port down if that happens.
Kategorie:

13 March 2016

Ingo Juergensmann: Letsencrypt: challenging challenges solved

A few weeks ago I was wondering in Letsencrypt: challenging challenges about how to setup Letsencrypt when a domain is spread across several virtual machines (VM). One of the possible solutions would be to consolidate everything on one single VM, which is nothing I would like to do. The second option would need to generate the Letsencrypt certs on the webserver and copy over the certs to the appropriate VM on a regular basis or event driven. The third option is to use a network share - and this is what I'm using right now. So, my setup is as following after I solved the GlusterFS issue with rpcbind binding to all interfaces, although it has been configured to only listen to certain interfaces (solution was: simply remove all NFS related stuff): On Dom0 (or the host machine) I run GlusterFS as a server on a small 1 GB LVM as part of a replicate with the VM that will do the actual Letsencrypt work:
Volume Name: le
Type: Replicate
Status: Started
Number of Bricks: 1 x 2 = 2
Transport-type: tcp
Bricks:
Brick1: 192.168.x.254:/srv/gfs/le
Brick2: 192.168.x.1:/srv/gfs/le
This is to ensure that on reboot of the machine every other VM using Letsencrypt certs can mount the GlusterFS share, because the host machine will be there for sure whereas the other VM generating the certs with the letsencrypt.sh script might still be booting. And when the GlusterFS share is missing services will not start on the other VMs because of the missing certs, of course. So, the replica on the virtualization host (Dom0) is only acting as some kind of always-being-available network share, because, well, the other VM will not always be there... for example during a kernel update when a reboot is required. The same setup is on my mailserver, acting as the second GlusterFS brick of that replica drive. The mailserver hosts the bind9 nameserver as well and I might do something that new domains with Letsencrypt certs get added to my DNSSEC setup as well. Of course, when the letsencrypt.sh script creates or updates the certs, it needs the certs being mounted in that configured location, so I needed to add a line to /etc/fstab:
192.168.x.254:/le /etc/letsencrypt.sh/certs glusterfs noexec,nodev,_netdev 0 0
Basically the same needs to be done on the other VMs where you want to use the certs as well, but you may want to mount the share as read-only there. The next step was a little more tricky. When letsencrypt.sh generates new certs, Letsencrypt will contact the webserver for that domain to respond to the ACME challenge. This requires that on each VM you want to use letsencrypt you have to run a webserver. Well, actually at least that there is somewhere a webserver that can answer these requests for that specific domain... Now, the setup of the webserver (Apache in my case) is like this: I'm using the Apache macro module to make it more easy, so I generated two small configs in /etc/apache/conf-available and enabled them bei a2enconf: letsencrypt-proxy.conf to do some setup for proxying the ACME challenges to a common website called acme.example.org. And then letsencrypt-sslredir.conf to setup SSL redirection when everything is in place and the domain can be switched over to HTTPS-only. letsencrypt-proxy.conf:
<Macro le_proxy>
ProxyRequests Off
<Proxy *>
Order deny,allow
Allow from all
</Proxy>
ProxyPass /.well-known/acme-challenge/ http://acme.windfluechter.net/
ProxyPassReverse / http://% HTTP_HOST /.well-known/acme-challenge/
</Macro>
letsencrypt-sslredir.conf:
<Macro le_sslredir>
RewriteEngine on
RewriteCond % HTTPS !=on
RewriteRule . https://% HTTP_HOST % REQUEST_URI [L]
</Macro>
So, after all the setup of a virtual host for Apache looks like this:
<Macro example.org>
(lots of setup stuff)
</Macro>
<VirtualHost 31.172.31.x:443 [2a01:a700:4629:x::1]:443>
Header always set Strict-Transport-Security "max-age=31556926; includeSubDomains"
SSLEngine on
# letsencrypt certs:
SSLCertificateFile /etc/letsencrypt.sh/certs/example.org/fullchain.pem
SSLCertificateKeyFile /etc/letsencrypt.sh/certs/example.org/privkey.pem
SSLHonorCipherOrder On
Use example.org
Use le_proxy
</VirtualHost>
<VirtualHost 31.172.31.x:80 [2a01:a700:4629:x::1]:80>
Use example.org
Use le_proxy
Use le_sslredir
</VirtualHost>
le_sslredir is only needed when you are sure that you want all traffic being redirected to HTTPS. For example when your blog is listed on planet.debian.org or other Planets you might want to omit this from your HTTP config because bug #813313 is not yet solved. In the end, when creating a new Letsencrypt cert, you need to add the le_proxy macro to your website, add the domain to letsencrypt.sh config in /etc/letsencrypt.sh/domains.txt and then the scripts will request a new cert from Letsencrypt, handling the ACME challenge stuff via the URL redirection in le_proxy being redirected to your acme.exmaple.org site and finally writes your new cert to the GlusterFS share. From that share you can then use the new cert on all needed VMs, be it your mailserver, webserver or XMPP/SIP server VMs. At least this works for me.
Kategorie:

11 March 2016

Steinar H. Gunderson: Agon and the Candidates tournament

The situation where Agon (the designated organizer of the Chess World Championship, and also the Candidates tournament, the prequalifier to said WC) is trying to claim exclusive rights of the broadcasting of the moves (not just the video) is turning bizarre. First of all, they have readily acknowledged they have no basis in copyright to do so; chess moves, once played, are facts and cannot be limited. They try to jump through some hoops with a New York-specific doctrine (even though the Candidates, unlike the World Championship, is played in Moscow) about hot news , but their main weapon seems to be that they simply will throw out anyone from the hall who tries to report on the moves, and then try to give them only to those that promise not to give them on. This leads to the previously unheard-of situation where you need to register and accept their terms just to get to watch the games in your browser. You have to wonder what they will be doing about the World Championship, which is broadcast unencrypted on Norwegian television (previous editions also with no geoblock). Needless to say, this wasn't practically possible to hold together. All the big sites (like Chessdom, ChessBomb and Chess24) had coverage as if nothing had happened. Move sourcing is a bit of a murky business where nobody really wants to say where they get the moves from (although it's pretty clear that for many tournaments, the tournament organizers will simply come to one or more of the big players with an URL they can poll at will, containing the games in the standard PGN format), and this was no exception ChessBomb went to the unusual move of asking their viewers to download Tor and crowdsource the moves, while Chessdom and Chess24 appeared to do no such thing. In fact, unlike Chessdom and ChessBomb, Chess24 didn't seem to say a thing about the controversy, possibly because they now found themselves on the other side of the fence from Norway Chess 2015, where they themselves had exclusive rights to the PGN in a similar controversy although it would seem from a tweet that they were perfectly okay with people just re-broadcasting from their site if they paid for a (quite expensive) premium membership, and didn't come up with any similar legal acrobatics to try to scare other sites. However, their ToS were less clear on the issue, and they didn't respond to requests for clarification at the time, so I guess all of this just continues to be on some sort of gentleman's agreement among the bigger players. (ChessBomb also provides PGNs for premium members for the tournaments they serve, but they expressly prohibit rebroadcast. They claim that for the tournaments they host, which is a small minority, they provide free PGNs for all.) Agon, predictably, sent out angry letters where they threatened to sue the sites in question, although it's not clear at all to me what exactly they would sue for. Nobody seemed to care, except one entity TWIC, which normally has live PGNs from most tournaments, announced they would not be broadcasting from the Candidats tournament. This isn't that unexpected, as TWIC (which is pretty much a one-man project anyway) mainly is about archival, where they publish weekly dumps of all top-level games played that week. This didn't affect a lot of sites, though, as TWIC's live PGNs are often not what you'd want to base a top-caliber site on (they usually lack clock information, and moves are often delayed by half a minute or so). I run a hobby chess relay/analysis site myself (mainly focusing on the games of Magnus Carlsen), though, so I've used TWIC a fair bit in the past, and if I were to cover the Candidates tournament (I don't plan to do so, given Agon's behavior, although I plan to cover the World Championship itself), I might have been hit by this. So, that was the background. The strange part started when worldchess.com, Agon's broadcasting site, promptly went down during the first round of the Candidates tournament today Agon blamed DDoS, which I'm sure is true, but it's unclear exactly how strong the DDoS was, and if they did anything at all to deal with it other than to simply wait it out. But this lead to the crazy situation where the self-declared monopolist was the only big player not broadcasting the tournament in some form. And now, in the trully bizarre move, World Chess is publishing a detailed rebuttal of Agon's arguments, explaining how it is bad for chess, not juridically sound, and also morally wrong. Yes, you read that right; Agon's broadcast site is carrying an op-ed saying Agon is wrong. You at least have to give them credit for not trying to censor their columinst when he says something they don't agree with. Oh, and if you want those PGNs? I will, at least for the time being, be pushing them out live on http://pgn.sesse.net/. I have not gone into any agreement with Agon, and they're hosted in Norway, far from any New York-specific doctrines. So feel free to relay from them, although I would of course be happy to know if you do.

Dirk Eddelbuettel: Rcpp now used by 600 CRAN packages

600 Rcpp packages Earlier this morning, Rcpp reached another milestone: 600 packages on CRAN now depend on it (as measured by Depends, Imports and LinkingTo declarations). The graph is on the left depicts the growth of Rcpp usage over time. Rcpp cleared 300 packages in November 2014. It passed 400 packages in June of last year (when I only tweeted about it) and then 500 packages in late October. The chart now extends to the very beginning as I manually compiled some more data from the CRANberries checked with crandb. Then next part uses manually saved entries, and the final and largest part of the data set was generated semi-automatically via a short script appending updates to a small file-based backend. A list of user package is kept on this page. Also displayed in the graph is the relative proportion of CRAN packages using Rcpp. The four per-cent hurdle was cleared just before useR! 2014 where I showed a similar graph (as two distinct graphs) in my invited talk. We passed five percent in December of 2014, six percent last July, seven percent just before Christmas and now stands at 7.31 percent, or a little less than one in thirteen R packages. 600 user packages is truly humbling, a staggering number and a big responsibility. We continue to try our best try to keep Rcpp as performant and reliable as it has been so that the next set of packages can rely on it---just like these 600 do. So with that a very big Thank You! to all users and contributors of Rcpp for help, suggestions, bug reports, documentation or, of course, code.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. Please report excessive re-aggregation in third-party for-profit settings.

3 March 2016

Simon Richter: Why sysvinit?

As most distributions have switched to systemd as default "init", some people have asked why we actually keep sysvinit around, as it's old and crusty, and systemd can do so much more. My answer is: systemd and sysvinit solve entirely different problems, and neither can ever replace the other fully. The big argument in favour of systemd is integration: when you keep everything in one process, it is easy to make sure that components talk to each other. That is nice, but kind of misses the point: integration could be done via IPC as well, and systemd uses a lot of it to separate privileges anyway. The tighter integration comes from something else: the configuration format. Where sysvinit uses a lot of shell scripts ("imperative" format), systemd uses explicit keywords ("descriptive" format), and this is the important design decision here: descriptive formats cannot do anything unanticipated, neither good nor bad. This is important for UI programmers: if there is a button that says "if I close the lid switch, suspend the laptop", then this needs to be connected to functionality that behaves this way, and this connection needs to work in both directions, so the user will find the active setting there when opening the dialog. So, we need to limit ourselves to a closed set of choices, so the UI people can prepare translations. This is the design tradeoff systemd makes: better integration in exchange for less flexibility. Of course, it is simple to allow "custom" actions everywhere, but that starts to break the "well-integrated" behaviour. There is an old blog post from Joey Hess about how to implement a simple alarm clock, using systemd, and this shows both how powerful and how limited the system is. On one hand, the single line WakeSystem=true takes care of the entire dependency chain attached to making sure the system is actually on -- when the system is going to suspend mode, some program needs to determine that there are scheduled jobs that should wake up the system, determined which of these is the next one, program the wakeup time into the hardware and only then allow the suspend to continue. On the other hand, the descriptive framework already breaks down in this simple example, because the default behaviour of the system is to go to sleep if the lid switch is closed, and the easiest way to fix this is to tell systemd to ignore the lid switch while the program is running. The IPC permissions disallow scheduled user jobs from setting this, so a "custom" action is taken that sets up the "ignore the lid switch" policy, changes to an unprivileged user, and runs the actual job. So, it is possible to get back flexibility, but this is traded for integration: while the job is running, any functionality that the "suspend laptop when the lid is closed" button had, is broken. For something simple as a switch on a personal laptop that breaks if the user configures something that is non-standard, that is acceptable. However, the keywords in the service unit files, the timer files, etc. are also part of a descriptive framework, and the services using them expect that the things they promise are kept by the framework, so there is a limit to how many exceptions you can grant. SystemV init really comes from the other direction here. Nothing is promised to init scripts but a vague notion that they will be run with sufficient privileges. There is no dependency tracking that ensures that certain services will always start before others, just priorities. You can add a dependency system like insserv if you like and make sure that all the requirements for it to work (i.e. services declaring their dependencies) are given, and there is a safe fallback of not parallelizing so we can always play it safe. Because there is so little promised to scripts, writing them becomes a bit tedious -- all of them have a large case statement where they parse the command line, all of them need to reimplement dropping privileges and finding the PID of a running process. There are lots of helpers for the more common things, like the LSB standard functions for colorful and matching console output, and Debian's start-stop-daemon for privilege and PID file handling, but in the end it remains each script's responsibility. Systemd will never be able to provide the same flexibility to admins while at the same time keeping the promises made in the descriptive language, and sysvinit will never reach the same amount of easy integration. I think it is fairly safe to predict both of these things, and I'd even go a step further: if any one of them tried, I'd ask the project managers what they were thinking. The only way to keep systems as complex as these running is to limit the scope of the project. With systemd, the complexity is kept in the internals, and it is important for manageability that all possible interactions are well-defined. That is a huge issue when writing adventure games, where you need to define interaction rules for each player action in combination with each object, and each pair of objects that can be combined with the "Use" action. Where adventure games would default to "This doesn't seem to work." or "I cannot use this.", this would not be a helpful error message when we're trying to boot, so we really need to cut down on actions and object types here. Sysvinit, on the other hand, is both more extreme in limiting the scope to very few actions (restart, wait, once) and only one object type (process that can be started and may occasionally terminate) in the main program, and a lot more open in what scripts outside the main program are allowed to do. The prime example for this is that the majority of configuration takes place outside the inittab even -- a script is responsible for the interface that services are registered by dropping init scripts into specific directories, and scripts can also create additional interfaces, but none of this is intrinsic to the init system itself. Which system is the right choice for your system is just that: your choice. You would choose a starting point, and customize what is necessary for your computer to do what you want it to do. Here's the thing: most users will be entirely happy with fully uncustomized systemd. It will suspend your laptop if you close the lid, and even give your download manager veto power. I fully support Debian's decision to use systemd as the default init for new installs, because it makes sense to use the default that is good for the vast majority of users. However, my opening statement still stands: systemd can never support all use cases, because it is constrained by its design. Trying to change that would turn it into an unmaintainable mess, and the authors are right in rejecting this. There are use cases that define the project, and use cases that are out of scope. This is what we need sysvinit for: the bits that the systemd project managers rightfully reject, but that are someone's use case. Telling these users to get lost would be extremely bad style for the "universal operating system." For example, if someone needs a service that asks a database server for a list of virtual machines to start, runs each in its private network namespace that is named after replacing part of the virtual machine name with the last two octets of the host machine's IP address, then binds a virtual Ethernet device into the network namespace and sets up a NAT rule that allows devices to talk to the public Internet and a firewall rule to stop VMs from talking to each other. Such a beast would live outside of systemd's world view. You can easily start it, but systemd would not know how to monitor it (as long as there is some process still running, is that a good sign), not know how to shut down one instance, not know how to map processes to instances and so on. SystemV init has the advantage here that none of these things are defined by the system, and as long as my init script has some code to handle "status", I can easily check up on my processes with the same interface I'd use for everything else. This requires me to have more knowledge of how the init system works, that is true, however I'd also venture that the learning curve for sysvinit is shallower. If you know shell scripting, you can understand what init scripts do, without memorizing special rules that govern how certain keywords interact, and keeping track of changes to these rules as the feature set is expanded. That said, I'm looking at becoming the new maintainer of the sysvinit package so we can continue to ship it and give our users a choice, but I'd definitely need help, as I only have a few systems left that won't run properly with systemd because of its nasty habit to keep lots of code in memory where sysvinit would unload it after use (by letting the shell process end), and these don't make good test systems. The overall plan is to set up a CI system that Ideally, I'd like to reach a state where we can actually ensure that the default configuration is somewhat similar regardless of which init system we use, and that it is possible to install with either (this is a nasty regression in jessie: bootstrapping a foreign-architecture system broke). This will take time, and step one is probably looking at bugs first -- I'm grateful for any help I can get here, primarily I'd like to hear about regressions via bug reports. tl;dr: as a distribution, we need both systemd and sysvinit. If you suggest that systemd can replace sysvinit, I will probably understand that you think that the systemd maintainers don't know project management. I'm reluctantly looking at becoming the official maintainer because I think it is important to keep around.
Arturo Borrero Gonz lez: Current status of iptables & nftables in Debian


I would like to give an overview of what is the current status of iptables & nftables in Debian.
Some information contained in this article is not new, this post is about what happened to iptables & nftables in the last 3 months, focusing on the integration with Debian.
versionsBy the time of this article, upstream versions are:
Debian testing (stretch) contains updated versions of all of them:
  • iptables 1.6.0-2
  • nftables 0.5+snapshot20151106-1
  • libnftnl 1.0.5+snapshot20151106-1
The snapshot versioning thing in nftables and libnftnl is the result of packaging a few commits ahead of last upstream release to workaround some nasty bugs.
the iptables-compat stuff
The iptables 1.6.0 release contains a new set of tools called 'compat'. These tools uses the same syntax of iptables,ip6tables,arptables,ebtables but internally read/write data to the nf_tables kernel subsystem.
You can find these compat tools in a binary pacakge: 'iptables-nftables-compat'.

That is one of the approaches available to help admins migrate from iptables to nftables.

Other approach is textual translations. In this case, the admin calls the translation utility using iptables syntax to get the same rule written in native nft syntax.
However, this approach is a work in progress and Debian lacks of this functionality right now . I hope next upstream release of iptables will include some of this.
iptables maintenance
In Debian bug #805018, I contacted former maintainer Laurence J. Lane about the 1.6.0 upstream release and the need to pay attention to such a big release.
Unfortunately, it seems Laurence got his key expired, and he can no longer maintain any package until a new key is in place. Hope we can see him back soon.

So, I took over the maintenance of iptables, with the help of Ana Guerrero, which has been reviewing my work and sponsoring the uploads. Thanks Ana!

As part of this new maintenance, I cleaned up a bit the iptables bug tracker. I closed some very old bugs (see for example #295567 and #118187) which are no longer useful.
ready for stable?
With the stretch freeze coming by the end of 2016, I want to be sure that the main Netfilter packages are in shape for a Debian stable release.
I won't let packages migrate to stable if there is no extensive testing. It should be clear that packages are ready for Debian stable for me to let them go stable.

My concerns regarding nftables & iptables in stable are different actually:
  • iptables: piece of software too widespread. I don't want to break any system with the 1.6.0 migration.
  • nftables: the 0.5 release is old already with regards to the upstream development.
So please, let me know any feedback you may have :-)

Next.

Previous.
