Activity summary
During the month of May, 21 contributors have been
paid to work on Debian LTS (links to individual
contributor reports are located below).
The team released 56 DLAs fixing 877 CVEs.
May was a much busier month than usual, especially due to the disclosed
vulnerabilities on linux regarding Local Privilege Escalation (LPE), that
included public proof-of-concept (PoC) exploits. These reports of course
impacted Debian as a whole, and the situation warrants a special mention to the
Kernel Team, especially Ben Hutching and Salvatore Bonaccorso, who faced the
pace and released linux packages on a weekly basis. On the LTS side, the Front
Desk team also
triaged a significant flow of high severity CVEs.
It is also important to note that
Debian 12 ( bookworm ) will be
handed over to
the LTS Team on June 11th. If you benefit from Debian, especially during the
full 5-year lifecycle, please consider subscribing as a sponsor of Debian LTS:
https://www.freexian.com/lts/debian/.
Moreover, Debian 11 ( bullseye ) will reach the end of the Debian LTS period on
August 31st. After that, Freexian will continue the security support under the
Extended LTS offer.
The team published several notable updates:
As mentioned above, several exploitable LPE vulnerabilities in linux were published during May. Ben released the following DLAs for the Debian LTS versions:
exim update
(DLA-4580-1),
prepared by Thorsten, to address a vulnerability that may result in remote code
execution.
gnutls28 update
(DLA-4595-1) by
Guilhem Moulin, fixes several vulnerabilities that may result in execution of
arbitrary code, information leak, authentication bypass, among other impacts.
krb5 updates released as
DLA-4603-1, fixing
two vulnerabilities that may yield to a denial of service. Updated prepared by
Emmanuel Arias
lemonldap-ng
(DLA-4602-1),
released by Abhijith PA, fixing multiple vulnerabilities
Two imagemagick updates
(DLA-4559-1 and
DLA-4609-1), prepared
by Bastien Roucari s, fixing several vulnerabilities
openjdk-11 and openjdk-17 updates
(DLA-4566-1 and
DLA-4565-1), both
prepared by Emilio, to fix seven vulnerabilities.
php7.4 update
(DLA-4586-1) to fix
six vulnerabilities that could result in remote code execution, information
disclosure or denial of service. Update prepared by Guilhem Moulin.
python3.9 update (DLA-4583-1), prepared
by Arnaud Rebillout, addressing multiple vulnerabilities.
Contributions from outside the LTS Team:
We are greatly thankful for the contributions from people outside the LTS Team:
Colin Watson prepared an OpenSSH update, that was released by Santiago as
DLA-4584-1.
Thomas Goirand handled a keystone update, whose advisory was done by Santiago
and released as
DLA-4611-1.
Christopher Obbard kindly prepared a sentry-python update, released as
DLA-4612-1.
Christoph Goehre made two thunderbird updates
(DLA-4562-1 and
DLA-4582-1). As is
customary, Emilio released the advisories.
The LTS Team has also contributed with updates to the latest Debian releases:
Andreas proposed a firewalld update
for bookworm to fix a local issue that may result in bypass control rules.
Andreas proposed atril updates
for trixie and bookworm.
Thorsten completed the uploads of zvbi, taglib and libuev to bookworm and did
an upload of libcoap3 for
wtrixie.
Tobi prepared libpng1.6 updates for trixie and bookworm, released as
DSA-6263-1.
Moreover, thanks to our partnership with Catalyst, it has been possible to extend the support for Samba 4.17, the version shipped with Debian 12. In May, several vulnerabilities were disclosed, and their patches were prepared by Catalyst. For Debian 12, the update was prepared by the Samba maintainer and released as DSA-6297-1.
There has been a video blog post recently published with a review of Ubuntu Touch as an option to opt out of the Android world: https://www.youtube.com/watch?v=wTK6TS3pXgc
Thanks to @SwitchandClick for spending time on this and publishing that video. Much appreciated.
Many Issues amended in upcoming 24.04-2.0 Release
When I watched that video referenced above, I continuously thought: ah... this is fixed in the next major release of Ubuntu Touch, or: ah... this is a known issue that we have on the roadmap..., or: ah... this is done in this ways by design (so it's a feature or basic functionality)...
Let me just state, that most of the criticized aspects will be resolved in upcoming Ubuntu Touch release 24.04-2.0 (the tests in that video blog post have been run on Ubuntu Touch 24.04-1.x):
Camera notch and rounding corners get honoured now by the UI
Ubuntu Touch's default webbrowser (Morph Browser) has been bumped from Chromium engine v87 (Qt5 based) to v134 (Qt6 based), installing another browser should not be necessary anymore (note that the privacy level in Morph Browser is pretty high, so using other browsers could mean a loss of privacy).
Bluetooth pairing agent got added to the bluetooth indicator
Ubuntu Touch now supports Snaps on CLI level and in the OpenStore app
Libertine has received fixes, but no substantial improvements. It mainly targets users who want to use their Ubuntu Touch device as desktop daily driver. Libertine-provided desktop apps UI-wise are often not usable on a phone-like device.
The full feature preview of the 24.04-2.0 release can be found here: https://ubports.com/blog/ubports-news-1/ubuntu-touch-24-04-2-0-beta-is-n...
Ubuntu Touch App Ecosystem
The app ecosystem of Ubuntu Touch is quite specific, because many apps in Ubuntu Touch have been explicitly developed for Ubuntu Touch using a widget toolkit called Lomiri.Components. However, in Ubuntu Touch we also encourage developers to provide apps written with other convergent-capable toolkits, such as QQC2-based apps or Kirigami-based apps.
One reason for the very different app ecosystem in Ubuntu Touch is that many service providers don't have Ubuntu Touch on their radar when investing in app development for their services. Some Ubuntu Touch App Developers work around this by either implementing unofficial client apps for web services (e.g. the Flow app for Deezer by Sander Klootwijk), others provide the web service via implementing a web app (will not work when offline, but at least will show up as an app in the launcher).
The overall solution for making Open-Store.io more familiar to users who migrate from Android is that commercial service providers start honouring digital sovereignty and start providing apps for Linux. Not just for the Linux desktop, but also for mobile Linux platforms. This dual use case can easily achieved with an app development that bears convergence in mind.
App Ecosystems are also a Matter of Perspective
And one more minor note: whenever I open an Android appstore or can peak over someone's shoulder using an iOS device: I always wonder: what are all these apps about??? Never heard about them.
So, familiarity really depends on perspective. And perspective depends on what you are used to. Change what you do and your perspective will follow.
Ubuntu Touch's root filesystem (rootfs) is Immutable
Only thing from that video blog post that we haven't fixed and won't do so in the midterm future is apt-get not working on the command line.
The reason for this is: the Ubuntu Touch root file system is an immutable file system and thus shall not be changed via apt-get & friends by ordinary users.
There are various discussions ongoing such as dpkg-divert'ing apt-get to a wrapper shell script that spits out an error message if rootfs is mounted read-only and someone tries to install packages the Debian/Ubuntu way. Other approaches are to mount some RAM disk over the rootfs, so apt-get can be used at runtime but changes to the system get reset at reboot.
However, it is possible to mount the root filesystem read-write and test newer package versions (as UT core developers do regularly, in fact). If you tinker with this, it is recommended to reflash your device (don't wipe user data, when you reflash!) from time to time, because adding packages or package upgrades to your rootfs may over time corrupt the integrity of the rootfs.
One reason for apt-get breaking the rootfs and thus your Ubuntu Touch development device is that the upgrade process of the rootfs image is incremental, so update tarballs sometimes contain only those parts that got changed between this and your previous upgrade (sometimes, upgrades contain a complete rootf image, depending on the interval between upgrades). If files from an incremental update tarball mix into a rootfs that got tinkered with via apt-get, you really end up on your own. Re-flashing will grab the complete rootfs tarball and wipe the whole rootfs and reinstall a fresh version of the newest rootfs image. Developers also do this in regular intervals to ensure their test device is clean again before running more/other tests.
Go default compatibility, by Helmut Grohne
At the MiniDebConf Hamburg, Andrew Lee
had prepared a talk on how Debian accidentally chooses Go compatibility.
Helmut joined Tobias Quathammer and Andrew Lee in looking into the problem.
Go has a compatibility system where modules declare a desired Go version to be
compatible with. This influences various features such as whether RSA keys
smaller than 1024 bits are accepted. Unfortunately, Debian s way of building Go
packages is unique in setting GO111MODULE=off, which practically implies a
very old compatibility version that enables a number of insecure settings. Most
Linux distributions use the default GO111MODULE=on and therefore consult a
go.mod file that often declares a sensible version. While doing so is the way
for Debian longer term, getting there involves major changes so we also sought
a more short term workaround. We developed a
patch to the Go compiler
that would enable it to pick up a compatibility version from the environment.
Tobias uploaded it to unstable. The next step is
communicating the declared compatibility version
from go.mod to the compiler via the new variable. Then, rebuilding the archive
resolves the immediate symptoms. This does not save us from having to perform
the larger transition to GO111MODULE=on, but this shortcut can be backported
to trixie.
Trimming build-essential, by Helmut Grohne
One of the harder problems of the architecture cross bootstrap is correctly
expressing the Build-Depends of glib during the toolchain bootstrap. It
implicitly depends on build-essential, which happens to depend on libc6-dev.
This poses a cycle. It applies even for cross building, because it is
interpreted for the host architecture and that there is no way of satisfying
this dependency during the toolchain bootstrap.
Given discussions at MiniDebConf Hamburg
with Jochen Sprickerhof and others, a seemingly stupid idea evolved: Let s
delete build-essential. What looks insane on the surface might deserve a
second look. Given how we moved away from C, C++ and autotools, what is in
build-essential no longer is required by much of the archive. With the rise of
debputy, debian/rules no longer has to be a makefile. While the task would
be huge, those packages relevant to architecture bootstrap could explicitly
support building without the implied dependency making their dependencies
explicit. In a number of cases, this amounts to issuing a dependency on
g++-for-host. This dependency requires the use of architecture-prefixed tools.
Therefore, Helmut wrote a debhelper change
that makes it always pass build tools to various build systems. This also
enables more packages to honour environment variables such as CC and CXX.
Python upstream engagement, by Stefano Rivera
Stefano attended PyCon US (at personal expense)
to improve upstream relations and ensure Debian s voice is heard where it needs
to be. On Friday there was a packaging summit
(notes) with good
discussion on the future of the wheel format, and some discussion of the new
abi3t shared library format for free-threaded python.
In preparation for the event, Stefano did a complete review of the current patch
stack.
Stefano s primary goal was to get some of Debian s patches merged during the
sprints, and results were mixed. Some trivial patches
(e.g. GH-150098, made progress
and merged, but the most consequential patch Debian is carrying
is still blocked. Stefano will
continue to try to drive progress on this.
Miscellaneous contributions
Carles worked on po-debconf-manager:
Reviewed Catalan translations for 6 packages, submitted 10 packages to
maintainers, and removed 3 packages from po-debconf-manager.
Carles worked on check-relations:
Continued improving the backend, including importing source package build
dependencies to better support analysis of Debian blends. Added support for
ignoring packages using regular expressions and source package names in response
to user feedback. Used the tool to report 5 new bugs and followed up on
previously reported issues.
Helmut sent a cross build patch on behalf of a customer.
Helmut uploaded debvm and guess_concurrency both featuring improved
reproducibility and documentation.
Helmut continued maintaining rebootstrap and made it correctly handle binNMUs
of gcc-defaults. Additionally, he poked at existing gcc patches giving answers,
rebasing or closing them.
Helmut supported the video team in Hamburg mixing audio.
Helmut continued to report undeclared file conflicts of various kinds and
corresponded with maintainers about them.
Antonio attended a debate during the Brazil Internet Forum
about the impacts of the child protection regulation (ECA Digital) on free
software operating systems.
Antonio worked on Debian CI to improve the system transparency for users. This
included listing any pending jobs explicitly in the job lists for each
package/architecture/suite page, as well as adding a
queue status page that users can check
for an estimate of test latency.
Antonio worked on several Debian CI maintenance tasks, including but not
limited to some monitoring improvements, replacing usage of fonts-font-awesome
with fonts-fork-awesome, and adding the ability in debci to configure a global
notice (which is being used in Debian CI to point to the system status pages).
Antonio started doing some tests related to the change of default Debian CI
backend from lxc to incus-lxc. This helped identify an omission in the creation
of incus-lxc images. It was missing dpkg-dev, which caused a few packages that
assumed its presence to fail. In the end, the incus-lxc backend will be fixed to
include dpkg-dev by default in the image, but that uncovered an undeclared
dependency in gem2deb (Ruby packaging helper) and in ruby-byebug, both
already fixed in unstable.
May included the discovery of several high-severity Linux kernel root
exploits. Stefano updated kernels and rebooted debian.social infrastructure
several times.
Stefano supported the Hamburg miniDebConf s
wafer website during the event, and set up an instance
for the 2027 edition too.
Stefano supported the bursary team issuing bursaries for
DebConf 26.
Stefano uploaded routine updates of python-pip, pystemmer, snowball-data,
snowball (making up a mini, uncoordinated snowball transition),
python-authlib, python-discovery, python-installer, python-mitogen,
python-pipx, python-cachecontrol, platformdirs, and python-virtualenv.
Stefano fixed a small number of bugs in dh-python, culminating in the
7.20260524 upload.
Thorsten finally managed to upload a new upstream version of hplip. He also
uploaded a new upstream version of epson-inkjet-printer-escpr. Last but not
least with the help of other contributors he could fix bugs in lprng.
Lucas and Santiago contributed significantly to the DebConf 26 Content team;
helping to organize the team, review and rate talk proposals.
Lucas also supported a packaging sprint held in India by rebuilding and
publishing the latest results of the Ruby 3.4 transition effort.
Santiago continued contributing to the efforts to organize DebConf 26,
especially supporting the local team with different tasks.
In collaboration with Emmanuel Arias, Santiago is mentoring Aryan Karamtoth,
a GSoC participant that is working to introduce linux live-patching support in
Debian. The GSoC project started in May, with community bonding and coding.
Santiago reviewed a merge request
to prepare the clang-extract package for debian. clang-extract is one of the
building blocks that will help to extract specific functions from large C code,
so only relevant code can be patched, without recompiling the whole original
basecode.
Anupa assisted Jean-Pierre Giraud with the point release announcements for
Debian 13.5 and Debian 12.14.
Colin backported various security fixes from OpenSSH 10.3 to all supported
releases (including LTS and ELTS).
Colin backported IP quality-of-service fixes to OpenSSH in trixie. The
situation there had been unsatisfactory for some time, and upstream reworked
their QoS support in OpenSSH 10.1 in a way that typically produces much better
results.
Colin imported new upstream versions of 26 Python packages, and fixed around
25 RC bugs for the Python team.
AI slop is invading the web. A recent story about disallowing LLM-generated
submissions on Lobsters triggered a lot of debate. My personal worst
offenders are LinkedIn articles with AI-generated images and uninspired
articles filled with emojis from people trying to masquerade as experts on a
subject they don t care enough to write themselves. While I am unhappy about
this situation, I rely on LLMs for grammar, copyediting, and
translation. I don t see this as a contradiction.
I am a native French speaker, but I blog in both English and French. When I
started writing this blog in 2011, I was composing in French and translating
to English, but I found it was better to work in the reverse order to
avoid unnatural and non-idiomatic constructions. One of my goals is to write
good English but I never felt it was my strong point.1 For example, verb
tenses are often an issue, even if I mostly stick with the present tense. I
learn the rules and forget them right away. I also don t feel like hiring an
editor for something I see as a hobby.
As an example, I have kept the history of the successive iterations when writing
Scaling Akvorado BMP RIB with sharding :
the first draft, authored with the help of a thesaurus,2
I know that LLMs may alter the author s voice when editing, but the
corrections in the second step are minor. The prompt asks to apply light
stylistic edits, with some guidance around avoiding passive voice, long
sentences, bland verbs, and filler words. It also defines the target audience:
technical with a B2 level in English.
In the following excerpt, I used long time instead of long-standing. The
former is missing a hyphen and applies to people a long-time friend, while
the later relates to a situation a long-standing agreement. I had a hard
time understanding the reason of the second change: the LLM prefers a
defining relative clause to provide the definition of RIB sharding.
As the Internet routing table contains more than 1 million routes, Akvorado
needs to scale to tens of millions of routes. This has been a long
time long-standing challenge, but I expect this issue is now
fixed by using RIB sharding, a method to split that
splits the routing database into several parts to enable concurrent
updates.
In the next modification, the LLM puts device instead of equipment. This is
correct as equipment is an uncountable noun. I know that, but I still fall
into this trap.
When Akvorado does not find a route from a specific device, it falls back to a
route sent by another equipment device.
I ask the LLM to use descriptive verbs and it complies by replacing a
multi-word predicate with a lexically rich verb:
The benchmarks demonstrate it has better performance than
outperforms other packages, both packages for
lookups, insertions, and memory usage.
It also fixes grammar errors. In the next excerpt, a list of routes is a
singular expression. Moreover, stored is a state and I should not use into
as it expresses a change.
The list of routes for each prefix are is not stored
directly into in the prefix tree.
As a last example, consider the following snippet. The require verb
accepts a noun or an object followed by a to-infinitive. I can t use it with
just a to-infinitive.
An alternative would be to have one prefix tree for each peer but it would
require to configure configuring all routers to export
their routes.
As someone who didn t grow up speaking English, I struggle with these grammar
rules despite reading a lot of English material.3 French is more
complex to get started but more systematic. English is full of irregularities.
On each page, I disclose in the footer whether an AI modified the content. There
are three levels:
: no AI or almost no AI (e.g., grammar corrections)
: enhanced (e.g., copyediting)
: generated (e.g., translated from another language, even if human-edited)
Hover or tap the icon to reveal the AI s name and its role in the document.
Example of AI usage disclosure: Claude Sonnet 4.5 edited this article.
The graph below shows which tool altered each post, year by year. Recently, I
applied the grammar skill to past articles. Since 2018,
French articles have been translated with the help of DeepL first, then of
an LLM. Since 2024, English articles are copyedited.
🖼 Graph showing the AI usage over the years. Each level get its own
color.
AI usage over the years. Hover or tap a band for the details.
If you are strongly against any usage of LLMs specifically for writing, I hope
you accept my more nuanced position on the usage of these tools as a trade-off
to provide clearer and more engaging articles. Years of literature on improving
English told us it is important to choose the right word to keep the reader
engaged.
[ ] Good writing consists of mastering the fundamentals (vocabulary,
grammar, the elements of style) and then filling the third level of your
toolbox with the right instruments.
Stephen King, On Writing
Note
Unlike other recent articles, I did not use an LLM to edit this post:
an unnamed person kindly accepted to proofread it. I translated it to French
without using an LLM either.
I am quite happy with the writing tools provided by Kagi. Both the
translate tool and the dictionary are a valuable help to find
different wordings. I also lean on Kagi s research assistant when
researching a topic.
When I was ten, I played Monkey Island 2 in English without having
taken any classes. I used a dictionary to translate word by word and I found
the irregular verbs confusing and not in the dictionary.
Official announcement
European Voxit community strengthens digital sovereignty: shared codebase completed.
Read the official announcement at: https://www.voxit.org/european-voxit-community-strengthens-digital-sover...
The Voxit community and platform development
The Voxit participation platform is originally based on the open source Polis platform developed by The Computational Democracy Project in the United States, but since its establishment in autumn 2025, the European Voxit community has been developing an independent solution, adapted to European needs.
The aim is to create an open source, interoperable and scalable participation infrastructure suited to Europe s regulatory environment and aligned with democratic values. Through this development work, Voxit is becoming a clearly distinct fork of the original Polis platform allowing Europe to develop participatory infrastructure at its own pace and according to its own governance needs, while the original Polis project continues to break new ground. This enables Europe to build its own open and trustworthy digital democracy tools, rooted in public governance and European democratic traditions.
Voxit 1.0 source code is now available
The source code for version 1.0 of the European community edition of the Voxit platform has now been published and is openly maintained on GitLab.com at: https://gitlab.com/voxit/voxit#
The RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices.
SpacemiT is a Chinese RISC-V CPU manufacturer that launched on May 11th, 2026, their long-anticipated next-gen RISC-V AI chip K3. It is among the earliest RISC-V CPUs that adhere to the RVA23 standard and performance-wise it is quite capable, providing 130 KDMIPS general computing power, 60 TOPS on INT4 which translates to about 15 tokens per second when running a 30 billion parameter large language model.
The aspect that really makes it stand out is:
Comparing the resellers
SpacemiT does not sell anything directly to consumers. Instead you need to buy a board that includes the K3 chip from an integrator. Currently the main resellers are:
All of the above are Chinese companies that ship to customers both inside and outside China. DeepComputing stands out as the only one that actually has done real integration and ships the K3 on a custom board, while the others simply resell the SpacemiT-produced K3 pico-ITX and K3 CoM260 Kit.
Milk-V
Milk-V is a RISC-V specialized integrator, as the name already implies. They sell the K3 under the name Jupiter2. Of all the K3 pico-ITX reseller product pages, the Jupiter2 presentation is the nicest and most detailed. Unfortunately their order page at arace.tech only states that it is a pre-order with no information about shipping schedule, taxes, or other details like what SSD is included (if any). Based on the pictures it does ship with a Milk-V branded case. The 32 GB RAM lists at 504 EUR, which is a very reasonable price. The @MilkV_Official account on X recently promoted the K3.
Documentation and support
As of this writing, the Milk-V Jupiter2 documentation site is just a stub and has no actual content, and only two links to the SpacemiT K3 documentation site. For support there is a web forum with a dedicated Jupiter2 section. There is also a Matrix space, but unlike their other products, there is no dedicated Jupiter (neither v1 nor v2) channel.
Community size and open source involvement
At least one prior Milk-V product was certified by Canonical, which indicates there is some collaboration in progress. Canonical also lists the Milk-V Titan on its official Ubuntu for RISC-V partner-built hardware page.
Sipeed
The Sipeed K3 announcement is well written (in English) with all the relevant details and links to additional PDF manuals. However, their main page at sipeed.com says nothing about the K3, so one must know the subpage URL to access it. They offer both the K3 CoM260 kit compatible with Jetson Orin Nano carrier boards, and the stand-alone K3 pico-ITX-sized motherboard. The CoM260 kit is only 10 USD cheaper than the full pico-ITX motherboard, so choosing the latter is a no-brainer if starting from scratch. The pico-ITX model with 32 GB DDR5 RAM sells for 639 USD. The product page does not mention anything about hard disk size, so you don t really know exactly what you will be getting if placing an order. There is no indication about case, Wi-Fi antennas or power supply either, so most likely they are not included.
Their store.sipeed.com website does not work at all, and their Taobao and AliExpress stores are not public and only accessible to registered users. The order page also says nothing about shipping time, delivery time, or taxes. The X account @SipeedIO is active and recently posted pictures of shipments in progress.
Documentation and support
The main documentation wiki does not yet have any K3 content at the time of writing. There is a Discord channel for general RISC-V discussion, and their MaixHub also has a discussion board, but I didn t find anything K3-specific.
Community size and open source involvement
Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community.
Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.
Banana Pi
Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version.
Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.
Documentation and support
I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.
Community size and open source involvement
Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.
Firefly
Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally.
Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.
Documentation and support
The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet.
For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.
Community size and open source involvement
Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.
DeepComputing
Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it.
The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case.
After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.
Documentation and support
DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.
Community size and open source involvement
DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products.
Conclusion
After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence.
The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon.
What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence.
Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details.
I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.
Debian LTS/ELTS
This was my hundred-forty-third month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian.
During my allocated time I uploaded or worked on:
[DLA 4580-1] exim4 security update to fix one CVE related to remote code execution.
[DLA 4591-1] rsync security update to fix five CVEs related to local root privilege escalation.
[#1134340] trixie-pu bug for libcoap3 to fix two CVEs in Trixie; the debdiff was confirmed and the upload was accepted to the proposed update queue.
This was a rather strange month. The details about the embargoed exim4 issue arrived only after I already went to bed and the embargo lift was 18 hours later. Luckily Stretch was not really affected and the uploads for Bullseye and Buster went out on time.
Something similar happened with the embargoed issue of rsync. The info arrived at 8:00 in the morning and the embargo lift was on 2:00 next morning. From an Europeans point of view, the Australians do have strange time zones. But there is more to this than that. Upstream sent more than 50(!) patches for these five CVEs that needed a backport to Bullseye. As things turned out, there is a regression in the upload to Unstable and investigations are ongoing whether this regression is also available in the backported patches for Trixie, Bookworm and Bullseye. So rsync-updates for Buster and Stretch is in the works, but I am afraid they need some more time.
All good things come by threes. Two critical CVEs of hplip appeared and a new upstream version was released by HP. HP is no longer interested in working with distributions and over time more than 80 patches have been accumulated that need a rebase for a new upstream version. For that reason I avoid this package as much as I can, but two critical CVEs did apply some kind of pressure on the maintainer. So I finally managed to do this update and the latest version of hplip is now in Debian. Nevertheless, this feels good :-). Anyway, it is not over yet. HP does not have a public repository nor do they publish patches for these CVEs. So I am still searching for the correct fixes to backport them to Bullseye, Buster and Stretch. The other distributions have the same problem and a silver lining appears on the horizon.
I also prepared an update of gimp for Buster and Stretch, but due to an accident I only managed to release the corresponing ELA in June. The accident was also the reason for only half a week of FD. Thanks to Daniel who took over.
Debian Printing
This month I uploaded a new upstream versions:
This work is generously funded by Freexian!
Debian Lomiri
This month I continued to work on unifying packaging on Debian and Ubuntu. This makes it easier to work on those packages independent of the used platform.
This work is generously funded by Fre(i)e Software GmbH!
Debian Astro
This month I uploaded a new upstream version or a bugfix version of:
Introduction
I have just bought a HP Z4 G4 with W-2125 CPU for $320 and I decided it was a good time to do some benchmarks on Debian package building to see which system I should use for that.
The W-2125 CPU scores only 9,954 on the passmark multithread test but scores 2,546 on single thread [1]. Passmark seems to have some limitations as the only DDR3 system that s important to me at the moment (the HP Z420 workstation my parents use which cost me $750 in 2021) with a E5-2620 CPU scoring 5,325 for multithread and 1,113 for single thread [2]. From the passmark results one would expect that the system is slightly more than twice as fast as the Z420 for operations that involve less than 4 CPU cores.
For the initial tests of the Z4 G4 I ran them with hyper-threading enabled as 4 cores isn t much by today s standards and also the machine in question is going to be less exposed to hostile data and contain less secret data than most of my systems so the security risks of hyper-threading are less of a concern.
I did some tests with a couple of tasks that are very important to me, building SE Linux policy packages (something I may do a dozen times in a day) and building Warzone 2100 (which I do less often but is the most intensive build process I regularly run). At the bottom of this post there are tables with the results from building these packages on my Z640 workstation with a E5-2696 v4 CPU [3], the Z420, and the new machine.
For the Warzone 2100 package I tested building on my Z840 dual CPU system [4]. I didn t test building the SE Linux policy on the Z840 this time because that package can t take advantage of even 22 cores. When I initially got the Z840 running it built the policy packages faster because the Z640 had an older CPU that was slower for single core operations than the CPUs in the Z840.
BTRFS Compression
For some time I have noticed significant differences in compile time on my workstation, a factor of more than 2. I did more tests and noticed that top showed something like the following, those kernel threads are all BTRFS related, except for gfx which is probably something graphical caused by running Chrome with about 300 tabs open.
I had been running BTRFS with the mount option compress=zstd:15 which caused much of the performance problems when building. It was also a random performance issue which I think happened due to the BTRFS 30 second write-back sometimes taking more than 30 seconds during the build process which then caused a second write-back.
I did tests on ZSTD compression levels 5, 8, 10, and 15. 15 was never good and often really bad. 10 was not unbearable but consistently slower. 8 was sometimes as fast as 5 and sometimes quite a bit slower. I didn t test levels below 5 because I need to have some compression and it seemed that the benefits of reducing compression were dropping off below 8.
I found that the BTRFS compression delay is not counted in system time for the process. I think it s the fsync() system calls in the semodule and dpkg-deb programs that cause the delays related to BTRFS compression waiting for kernel threads.
BOINC
I have all my systems other than laptops running BOINC in the background so that CPU power is used for scientific research when I don t have any personal use for it [5]. I believe that it s immoral to waste CPU power when it could be used for research.
In the below table which has test results from building the package with and without BOINC, and with different ZSTD compression levels in BTRFS all the worst entries were from when BOINC was running apart from one where ZSTD level 15 compression was used. The really poor performance with ZSTD level 15 was an outlier, but it wasn t an uncommon outlier so I left it in.
Running BOINC in the background configured to use all CPU cores caused a significant increase in user CPU time (the time a CPU core spent actually running the program). My initial thought was that it s partly related to turbo boost .
The Intel ARK page for the CPU in the Z420 shows that it s main clock speed is 2.0GHz with a 2.5GHz turbo boost [6]. The turbo boost is apparently largely based on temperature and apparently limited to one core, so if the other CPU cores are all being used then the CPU will probably be too hot to have the turbo boost and if it happens it might not happen for my compile processes.
The ARK page for the E5-2699 v4 (which is a similar CPU to the E5-2696 v4 that I m using but is officially documented by Intel) [7] shows that it has a base clock speed of 2.2GHz and a turbo boost speed of 3.6 GHz. 322 vs 244 seconds of user CPU time means running 32% slower which can plausibly be explained by the lack of a 64% turbo boost with a bit of help from the 55MB L3 cache being thrashed.
Turbo boost would only be a noticeable issue for building packages like the SE Linux policy packages which doesn t take much advantage of multi-core CPUs. For a build process to average at best 362% CPU use there has to be large parts of the process that are limited to one or two cores which can potentially give a benefit from turbo-boost.
When building the Warzone 2100 packages most of the build time is running basis-universal which is a multi-threaded program to compress GPU texture data. This usually causes a load average of 300+ on the Z640 or 600+ on the Z840. But the build time is still increased by more than 50% on both the Z640 and the Z840 when BOINC is running in the background, which seems to be an indication that it s not related to turbo boost. I verified that BOINC is running at IDLE schedule priority with the following command:
# chrt -p $(pidof -s einstein_O4MD_2.01_x86_64-pc-linux-gnu)
pid 2974874's current scheduling policy: SCHED_IDLE
pid 2974874's current scheduling priority: 0
In theory this means that BOINC won t affect foreground processes.
Hyper Threading on the W-2125
The best claims I ve seen about HT are 15% to 30% performance boost. The best I ve actually seen in the past is about 18%. Seeing a 10% benefit for building Warzone 2100 is at the low end of the range I expected. 8 virtual cores is not many for a build process that causes a load average of 600+ when running on a system with 44 real cores.
I was surprised to see a 6% performance benefit in hyper-threading for building the SE Linux policy as I didn t think there was enough use of threading or multiple processes to allow that.
Many build scripts use a number of processes that match the number of apparent CPU cores. While make -j 88 might give a theoretical performance benefit on a 44 core system it will also take a lot of RAM and any paging will outweigh the benefits of hyper-threading. On a system with only 4 real cores there s less potential for using too much RAM and as security isn t so important on that system I will leave it on.
Comparing the CPUs
The best results of the Z640 and Z4G4 are only 50% faster than the best results of the Z420.
The Z420 has a E5-2620 CPU which is far from the fastest CPU available for that system the E5-2687W has 8 cores and rates 10,021/1,669 on passmark [8] which is far better than the 5,331/1,114 the E5-2620. The E5-2687W is the fastest CPU that HP lists as supported by the Z420 and it supports DDR3-1666 RAM as opposed to the DDR3-1333 that is the fastest that the E5-2620 supports. With suitable hardware upgrades the Z420 would probably only take about 20% longer to do builds of the SE Linux policy and other packages that can t take advantage of more than 8 CPU cores.
The Z4G4 system has 4 RAM channels which means that you should get some performance benefits from having 4 DIMMs, my system currently has 2 and I haven t yet managed to get more DDR4-2666 DIMMs. But I d still expected a W-2125 CPU with 2*DDR4-2666 DIMMs outperform any E5-26xx CPU with 4*DDR4-DDR-2400 DIMMs for tasks that average less than 4 CPU cores.
In retrospect I would have been better off getting a HP Z820 (two socket server with DDR3 RAM) than the first DDR4 systems I got. It seems that for reasonable size builds a two socket system comes close to twice the speed of a single socket system. I did briefly own a HP ML350 two CPU system with DDR3 RAM but it was too noisy for my intended use as a deskside workstation so I sold it.
Things to Investigate
I plan to do more investigation on BTRFS compression, how to get the best compression without excessive delays and how to recognise when delays are happening. I have some SSDs that have sustained write speeds as low as 15MB/s (Crucial P1 series) so for those I could probably have very high compression levels without slowing the system down.
The fact that BIONC slows things down so much seems to be a bug. When processes are running with the IDLE scheduling class there shouldn t be such significant delays. Is it due to cache thrashing? How can I best get BOINC suitably throttled when I m sitting at my workstation, I don t want BOINC connecting to the local X server (which it repeatedly tries to do). Do I need to tune my kernel for better handling of IDLE scheduling?
When I get more DIMMs in the Z4G4 I need to do more tests to see if it gives an overall performance boost.
Also the Z4G4 system has a BIOS option for sub NUMA which basically means treating the different RAM channels on a single CPU as NUMA zones, I enabled that option which does nothing presumably because I only have 2 DIMMs, the results when I have 4 DIMMs will be interesting. I will also do some NUMA tests on the Z840 to see what benefits it gives.
I have a selection of RAM speeds that will work in the Z4G4, if I have enough spare time I ll test what difference that makes for CPU bound tasks that matter to me.
For package building fsync() is not helpful, if the system crashes before it s done then I will just do the build again. For a build cluster it is probably a good feature and probably doesn t affect aggregate performance when multiple packages are built at the same time, but for the single user case probably not. I will investigate libeatmydata for package building [9].
Conclusion
The progress in CPUs seems to have slowed down a lot recently. The main benefits seem to be in more CPU cores and for newer sockets with more RAM channels.
The CPUs that do have improvements in single core performance are the i9 series (which mostly doesn t come with motherboards supporting ECC) and AMD CPUs (which is rare in enterprise class hardware). Maybe I should get a server with an i9 or AMD CPU for tasks that need a fast turn around with a small number of cores. That would probably outperform any CPU designed for large core counts for things like building the policy and setting up test VMs (which depends on package installation speed that is single core bottlenecked).
The W-21xx CPUs seem to offer little benefit over the E5-26xxv4 CPUs and not a lot of benefit over E5-26xx CPUs (with DDR3). Even the W-22xx CPUs look like they aren t going to offer a lot as they are only an incremental improvement over the W-21xx series. I had considered making the Z4G4 my main desktop workstation after the high end W CPUs become affordable, but it looks like that won t be worth it until such CPUs drop from the current ebay price of $900 to $100.
I think I ll keep waiting for a decent socket LGA3647 or DDR5 based server [10] for my next significant upgrade.
Tables
Building SE Linux Refpolicy
Uploaded labwc 0.9.7-1 to unstable;
labwc 0.20 was released upstream since then, but it requires wlroots 0.20.1
which has not landed in Debian yet
Uploaded usbguard 1.1.4+ds-3 & 1.1.4+ds-4: cleaned up the packaging and
fixed some long standing issues with the configuration; the legacy permission
system isn t the default anymore
Uploaded foot 1.27.0-1 to unstable
Uploaded scdoc 1.11.4-2 to unstable
Uploaded cage 0.3.0-2 to unstable
Uploaded sway 1.12~rc3-2 to unstable; on the same day sway 1.12 was released
and I uploaded 1.12-1 to unstable
Uploaded swayimg 5.2-1 to unstable
Uploaded git-quick-stats 2.11.0-1 to unstable
Uploaded grim 1.5.0+ds-1 to unstable
DH Related Work
A big chunk of my DH related work went into designing & implementing a search
app for the APIS framework. Our
goal is to have a way of searching over various types of Django models. The app
introduces a search model that indexes all registered models. We use a
combination of PostgreSQLs full text
search and
Trigram Similarity to find the search results. Using a
SearchVectorField
and GinIndices for the trigram indexed fields we can reach a somewhat
acceptable performance.
We released versions 0.63 and 0.64 of the APIS framework. The 0.63 release
introduced the new entities app, which will soon hopefully replace the legacy
apis_entities & apis_metainfo modules. Version 0.64 moved some logic from
the legacy modules the entities module.
We made some progress in defining the endpoints for the
PFP
API.
Welcome to the May 2026 report from the Reproducible Builds project.
These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
In this month s report, we cover:
Debian to ship reproducible packages in forky and beyond
In a huge change in Debian s reproducibility policy, the Debian Release Team announced that:
we ve decided it s time to say that Debian must ship reproducible packages. Since yesterday, we have enabled our migration software to block migration of new packages that can t be reproduced [on reproduce.debian.net] or existing packages in testing that regress in reproducibility.
That is to say, if newly-uploaded packages are not reproducible, they won t be considered candidates for inclusion in the next stable release of Debian codenamed forky. (Some exceptions may be granted.)
This news generated a number of articles and comments in various news outlets:
Holger Levsen on reproducing official Debian packages
Reproducible Builds developer Holger Levsen gave a talk at the 2026 Hamburg MiniDebconf this year on the topic of reproduce.debian.net - reproducing what is distributed from ftp.d.o.
Holger s talk announced that Debian intends to ship only reproducible packages in forky and beyond (see above), but also talked more broadly about reproducible builds, our testing framework and the Debian archive. That is to say, moving away from testing whether a package is reproducible in a theoretical sense (eg. whether we can build it twice in different environments and achieve the same result in our test system), and attempting to reproduce the same .deb files in the official Debian archive itself. This small-sounding distinction is actually essential, as this is the only means through which the reproducible builds technique can determine whether build systems are compromised are not.
A video (32m37s) of the talk is available, as are Holger s slides.
Reproducible Builds 2026 summit to be held in Gothenburg, Sweden
As initially announced in March 2026, we will be having our yearly Reproducible Builds summit 2026 in Gothenburg Sweden, from September 22 until 24, followed by two days of hacking!
Further information will be provided on our website and on the rb-general mailing list very soon.
Kettle: Attested Builds for Verifiable Software
Andr Arko and Amean Asad published a paper this month on Kettle, a build system that produces cryptographically verifiable provenance for software built inside Trusted Execution Environments :
A Kettle build records the source commit, dependency set, toolchain, build
environment and output artifact digests in a provenance document produced
inside a measured confidential VM. The SHA-256 digest of that document is
committed to the TEE platform s attestation report-data field, so the
hardware-signed attestation report is itself the signature on the provenance,
with the signing identity chaining to the TEE manufacturer s root of trust
rather than to the build infrastructure operator. Because the CVM image is
itself reproducible, its launch measurement is public and stable, which lets
a build requester pre-attest the CVM before submitting any input and
optionally deliver source over a TLS channel terminated inside it, so the
build runs end-to-end confidentially without the host ever seeing source code
in plaintext.
New rebuilderd version announced
rebuilderd, our server designed for monitoring the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net.
A new version, 0.27.0, was released this month, with the following headline changes:
The new rebuilderd package is currently available in the extra-testing repository. Note the Arch Linux package is upgraded from v0.25.0 from v0.27.0; please be patient with the database migrations on first restart, and make
yourself familiar with the breaking changes in v0.26.0 too.
Reproducible open source messengers
GitHub developer BarbossHack is maintaining an repository/page on GitHub to track reproducibility status of open source messengers .
Perhaps rebuilderd needs a feature where GOOD packages are also periodically rebuilt in exponential back-off style and compared against current upstream build and also our last GOOD build. This would confirm whether a package is reproducible if built in a short time window but also help uncover longer time window issues that are currently hidden.
Patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
This was a particularly busy month for me in terms of Debian
contributions.
It started with a week in Hamburg for the MiniDebConf. I talked to
many colleagues face-to-face and worked on various bugs and
maintenance tasks. I m pleased to have finally found the time to
reproduce and fix the boot-time crashes in the parallel port
subsystem that have been reported
many times recently.
A series of easily exploited kernel LPE (local privilege execution)
issues were published this month, mostly with very little coordination
with distributions. Salvatore and I had to upload fixes for these at
roughly weekly intervals. All of these fixes needed to be applied to
4 different upstream branches (currently 5.10, 6.1, 6.12, and 7.0) and
7 Debian branches (including backports).
In September 2025, I attended the annual LibreOffice conference in Budapest, Hungary. This gave me an opportunity to explore the city, which I will cover in this post.
Let s start with the currency. Although Hungary is a part of the European Union (EU), it doesn t use the euro as its currency. Instead, it uses Hungarian forints (denoted by Ft ). During my time in Hungary, 1 Indian rupee was equal to 4 Hungarian forints.
After reaching the Budapest airport, I bought a 15-day public transport pass. The public transport counter is after you pass customs and immigration. The pass allows unlimited use of public transport in the city. I had to show my passport and pay 5950 Ft to get the pass. The pass had my passport number mentioned on it. The public transport passes can also be bought at any of the tram stations as well.
This is the counter from where I bought my public transport pass.
My unlimited public transport pass for Budapest. I have redacted my passport number from it.
An automatic ticket machine at a tram station in Budapest.
Budapest is a union of two cities Buda and Pest lying on opposite sides of the Danube River. My hotel Corvin Hotel was on the Pest side.
Budapest had good public transport. The buses, metros, and trams complemented each other. For example, the airport didn t have metro or tram connectivity, but it was served by the bus. Most of the metro was on the Pest side, with only a couple of stations falling in Buda. However, both sides had an extensive network of trams.
Furthermore, the information about the public transport was easily accessible. For instance, the map of tram stops inside the trams also included the bus routes one could get after alighting at those stops.
From the airport, I took a bus followed by taking a metro on the M3 line to reach within walking distance of my hotel.
An M3 line metro in Budapest.
During the conference I would take the tram to the conference venue. The trams were modern and fast. They also had a smiley face at the front, which gave them a friendly look. It seemed like the trams were happily doing their job. The city also had a good pedestrian infrastructure along with separate cycling tracks.
A tram in Budapest having a smiley face at the front.
Budapest s tap water is officially safe to drink, which was mentioned on a sticker posted on the wall of the bathroom of my hotel room. So, I did not need to buy any water bottles while I was there.
On the 6th of September, I went on a sightseeing tour of Budapest with my Dione. Our friend Attila, who was a local (from Hungary), joined us. We went to the central market from our hotel by metro.
If you read my post on Vienna, I mentioned that the metro stations don t have AFC gates but ticket validators instead. Budapest s metro also has the same system. If you buy individual tickets, you need to validate them using the validators on the station before boarding the metro. If you are using a public transport pass like I was, then you do not need to validate, and you can board the metro directly.
A ticket validator at a metro station in Budapest.
In 10-15 minutes, we reached the central market. Attila showed us around. I bought a fridge magnet and paprika powder as souvenirs. Paprika powder is a signature spice of Hungary. It is mainly available in two forms one is sweet and the other being spicy. I wanted the spicy one, but I didn t get that in that market. Therefore, I had to contend with buying the sweet version. The sweet version isn t sweet though, it is just not spicy. After bringing that paprika powder home, it is mainly used for food coloring. I like it though and use it frequently in my omelets and other dishes.
Central market.
The building right behind the tram is the central market building.
At some point, Atilla had to join the The Document Foundation (TDF) sightseeing group, so we parted ways at the central market. Dione and I continued our sightseeing and decided to start with visiting the Hungarian parliament, which is a tourist attraction. It was because we were on the Pest side and the parliament was also on the same side, while other tourist attractions were on the Buda side.
So, Dione and I hopped on a tram and went to the parliament. We got off at a tram station just outside the parliament. The parliament is the icon of Budapest. The building has a gothic architecture and colored brown and white. One can buy tickets and take an inside tour. However, we didn t have a lot of time, so we stayed outside the building.
Hungarian Parliament building.
After spending some time outside the parliament building, we took a tram to the Chain Bridge. As I mentioned earlier, Budapest has two parts Buda and Pest separated by the Danube River. To go from one of the sides to the other requires crossing a bridge. Although Budapest has many bridges linking the two sides, the main one is the Chain Bridge.
We walked on the chain bridge to get to the other side. The bridge gave a good view of the Danube River. It also had a statue of a lion. The Buda Castle (another major landmark of Budapest) was visible from the bridge.
A shot of Chain Bridge.
The lion statue on the Chain Bridge.
After reaching the other side of the bridge (the Buda side), we sat on a bench for some time and then planned on where to go next. We decided to go to Fisherman s Bastion, which is another tourist attraction.
We used the OSMAnd~ app to figure out which bus to take and hopped on one. Soon we reached Fisherman s Bastion, where we found a flight of stairs that led upwards. Upon climbing the stairs, we got a panoramic view of the city. It also gave us a good view of the Hungarian parliament across the river. Going further upstairs, we found a statue of Stephen I of Hungary. He was the first king of Hungary, getting the crown in the year 1900.
A view of Hungarian parliament from Fisherman s bastion.
I found Fisherman s Bastion to be the best tourist attraction in the city. As mentioned earlier, it offers a panoramic view of the city, which I liked. I liked the arhitecture and open space there. If you find yourself in Budapest, I would highly recommend that you visit Fisherman s Bastion.
Fisherman s Bastion.
Statue of Stephen I of Hungary at Fisherman s Bastion.
Next, we went downstairs and returned to where the bus dropped us. From here on, we walked in random streets to see the residential and non-touristy side of Budapest. It was not so random as we walked towards Batthy ny t r metro station. Upon reaching the metro station, we found a caf where we stopped for a while for some coffee. After injecting some caffeine into our blood, we proceeded to find a place to have lunch.
Batthy ny t r metro station.
For lunch, we decided to go to R k czi t r metro station after reading on the internet about the food options there. Upon exiting the metro station, we found a market inside a building that had a lot of shops, but most of them were closed.
After roaming around inside a bit, we found an Italian place open and decided to eat there. The name of this place was Matteos. We ordered an eggplant parmigiana, a lasagna artichoke, and a classic tiramisu. It wasn t very tasty but filled us up for the day.
A picture of Matteos, where we had our lunch.
Budapest has four metro lines, and we had been to three of them, so we decided to try the remaining line, which was the M1 line. It is the oldest line in the city and has a different vibe than the modern lines. This line was opened in 1896, one of the oldest subway systems in the world.
The coaches were much smaller than the other metro lines, and the seating arrangement was something you would expect from a bus than a typical metro train. We rode all the way to the last stop, Mexik i t. Upon going outside, we found out there wasn t much to do here.
At this point, I checked the map and realized that Heroes Square is just a couple of metro stations away. Heroes Square is a tourist attraction in Budapest. It is located in Zugl a and is a historically significant place in Budapest. It has a monument which features the Seven chieftains of the Magyars.
M1 line station and tracks. It is the oldest metro transit of Budapest and one of the oldest in the world. It started operations in 1896.
Here, our unlimited public transport pass was handy because if it was paid per trip, we would think of the stop as a wasted one because we would have to buy a ticket again, but in this case we could just hop on again without any regrets.
An M1 line metro train entering the station.
So we took the M1 line again and deboarded at H s k tere station, followed by walking to the square. After roaming around for a while, we saw a trolleybus and decided to ride on that.
Heroes Square.
This is the trolleybus we took in Budapest.
A trolleybus is an electric bus that is powered by overhead electric cables. It is like a tram but runs on roads instead of tracks. We got down at D zsa Gy rgy t metro station. Then we took a metro to our hotel.
Before going to the hotel, we went to a place to eat something. We had coffee and l ngos. L ngos is a deep-fried Hungarian dish, which looks exactly like the Indian flatbread bhatura. I found it tasty, but since it was deep-fried, that was almost a given.
L ngos a dish which looks like the Indian flatbread bhatura.
The next day we went to Vienna the capital of Austria which I have already posted about. Check it out here.
I had a good time in Budapest, and it is a beautiful city with good public transport and some amazing sites to visit.
That s it for now, and see you next time!
Credits: Thanks Dione and Badri for proofreading.
In January 2025,
as a pre-requisite for something else, I published a minimal neovim
plugin called nvim- wiki. It's essentially just the features from
vimwiki that I regularly use, which is a small fraction them.
I forgot to blog about it. I recently dusted it off and cleaned it up.
You can find it here, along with a longer list of its features and
how to configure it: https://github.com/jmtd/nvim-microwiki
I had a couple of design goals. I didn't want to define a new filetype,
so this is designed to work with the existing markdown one. I'm
using neovim, so I wanted to leverage some of its features: this plugin
is written in Lua, rather than vimscript. I use the parse trees
provided by TreeSitter to navigate the structure of a document.
I also decided to "plug into" the existing tag stack navigation, rather
than define another dimension of navigation (along with buffers, etc.)
to track: Following a wiki-link pushes onto the tag stack, just as if
you followed a tag.
This was my first serious bit of Lua programming, as well as my first
dive into neovim (or even vim) internals.
Lua is quite reasonable. Most
of the vim and neovim architecture is reasonable. The emerging conventions
about structuring neovim plugins are mostly reasonable. TreeSitter is, well,
interesting, but the devil is very much in the details. Somehow all
together the experience for me was largely just frustrating, and I didn't
really enjoy writing it.
ffs provides a minor mode for simple plain text presentations in
Emacs, where the slides are separated using the page-delimiter, by
default the form feed character (^L).
I wrote ffs in early 2022 for my LibrePlanet 2022 presentation the
Net beyond the Web, and earlier this year decided to polish it towards
being a proper package and submit it to GNU ELPA. The manual still
needs some more work, but the overall package is in pretty good shape
so I submitted for inclusion in GNU ELPA.
ffs and I owe a debt of gratitude to Protesilaos for rounds of
code review and feedback for improving and polishing the package in
preparation for submission to GNU ELPA. You can watch videos of these
sessions posted earlier on my website:
Further, inspiration for parts of ffs's implementation was
gratefully drawn from Protesilaos's Logos package for Emacs.
Dedicated to the loving memory of Farangis Yousefinia.
Below are the release notes.
Version 0.2.2 on 2026-05-21
First release of ffs on GNU ELPA.
The attempted build of ffs 0.2.1 within GNU ELPA build sandbox failed
with an Error: void-function (org-texinfo-kbd-macro) due to use of
#+macro: kbd (eval (org-texinfo-kbd-macro $1)) in ffs.org for better
formatting of key sequences in the exported Texinfo copy. This seems
to have happened for the specific case of generating a plain text
README using ox-ascii where ELPA didn't load ox-texinfo. To try
and mitigate this, a README.md has been added for use as the package
README instead of ffs.org. If not sufficient, a Texinfo copy of the
ffs manual will be shipped instead of the Org one in the next release.
ffs 0.2.2 also includes small fixes and improvements throughout
ffs.el from Stefan Monnier, and additional feedback to be addressed
in future releases.
Version 0.2.1 on 2026-05-20
The attempted build of ffs 0.2.0 within GNU ELPA build sandbox failed
with a "Cannot include file" error on the "#+include: fdl.org" in the
manual. So, as a workaround, we switch to using the official Texinfo
copy of the GNU FDL license rather than an Org copy.
Version 0.2.0 on 2026-05-19
First release of ffs intended for GNU ELPA.
After a few years of inactivity, in early 2026 I decided to dust off
ffs.el, polish and document it, and offer for inclusion in GNU ELPA
as a proper package.
Default value of ffs-default-face-height changed to nil
To minimize unexpected and/or unnecessary changes out-of-the-box, the
default value of ffs-default-face-height has been changed to nil.
ffs-edit-buffer-name demoted from user option to variable
This is not an important user-facing setting, so to help avoid
overwhelming users with many options, this has been demoted from a
user option to a variable.
Several new user options for customizing ffs's behaviour
As part of the effort to bring ffs more in line with the conventions
of other existing Emacs packages, the mechanisms for toggling various
parts of Emacs's interface to minimize visual clutter were changed
from being minor modes to being customizable user options. These are
the replacement new user options, with a default value of nil:
ffs-hide-cursor
ffs-hide-mode-line
ffs-hide-header-line
Their value is buffer-local, and may be set globally using
setq-default. See the sample configuration in the manual for an
example of how to customize them.
The new ffs-page-delimiter user option defines the page delimiter
inserted by ffs-edit-done when inserting a new slide. Emacs's
page-delimiter regexp should be able to match ffs-page-delimiter's
value, so if you use a custom page-delimiter be sure to customize
ffs-page-delimiter accordingly.
The new ffs-echo-progress user option controls whether to display in
echo area the progress through the slides. When non-nil, changing
slides will also display the progress through the slides in the echo
area. The format of the displayed progress can be customized using
the new ffs-echo-progress-format user option.
The new ffs-edit-display-buffer-alist user option may be used to
control the Window configuration for the ffs-edit buffer. By
default, it will display the ffs-edit buffer in the same window.
The new ffs-edit-done-hook user option may be used to define hooks
to be run at the end of ffs-edit-done after returning to the main
ffs presentation buffer.
Lastly, a new ffs-find-speaker-notes-function variable was added to
allow customizing the find function used for opening the speaker's
notes file, defaulting to find-file-other-frame.
Version 0.1.0 on 2022-05-19
Initial publication of ffs.el as part of my personal configurations
for GNU Emacs.
My first attempt at this concept was a now-archived ffsanim.el,
a major mode implementation that used Emacs's animate library to
animate slide texts onto the screen. Shortly after realizing the
shortcomings of that approach, I abandoned it in favour a minor mode
implementation and published version 0.1.0 of what is now ffs in
my personal configs repository.
I used this implementation for presenting my LibrePlanet 2022 talk,
The Net beyond the Web.
I picked "ffs" as the package name, the acronym for form feed slides.
I have been helping co-maintain the Debian curl package for a few
years now, and even though Samuel and Charles do most of the work, I'm
happy to jump in and help when needed. This is one of those cases.
Nowadays the package is maintained by 3 people (with help from others
occasionally), but it hasn't always been like this. Samuel adopted
the package back in 2021, and since then it has received a lot of love
and care to make sure it lives up to Debian's standards. Again, kudos
to both him and Charles who have been doing great work on this front.
But a little more than 20 years ago, the situation in Debian (and
curl!) was "a bit" different.
Once upon a time...
According to d/changelog, the Debian curl maintainer in 2005
introduced changes to the packaging that allowed it to generate a
version of libcurl for each TLS backend available: OpenSSL and
GnuTLS. This meant that curl would have two binary library packages:
libcurl3-openssl and its respective -dev variant, for libcurl
linked against OpenSSL; and
libcurl3-gnutls and its respective -dev variant, for libcurl
linked against GnuTLS.
But then, around 2006/2007 or so, upstream curl decided to bump the
SONAME version of libcurl from 3 to 4. At the time, they apparently
did not version their library symbols like they do now, which
was... less than ideal. I don't judge them: curl and a lot of other
important projects have come a long way when we consider best
practices to write shared libraries.
Meanwhile, on Debian land, the release team was having trouble with
other transitions going on at the time. For those who are not versed
in Debian's vocabulary, a transition happens when a shared library
gets its SONAME version bumped: when this happens, we have to make
sure that all reverse dependencies of that library still build with
the new version, and fix things that fail. The more reverse
dependencies the library has, the harder this work gets.
When upstream curl bumping the SONAME version of libcurl, the Debian
curl maintainer at the time correctly renamed the binary packages from
libcurl3- openssl,gnutls (and their -dev variants) to
libcurl4- openssl,gnutls (and their -dev variants), which
obviously triggered a transition. And a big one, because libcurl is
used by several projects.
Long story short, the Debian release team found themselves between a
rock and a hard place. According to the late Steve Langasek at the
time:
We talked a while back about the curl transition, and about how upstream's
change from libcurl.so.3 to libcurl.so.4 is gratuitously painful for us in
light of the large number of reverse dependencies.
The libcurl transition has at this point gotten tangled with soname
transitions in jasper, exiv2, kexiv2, and God only knows what else. So I'd
like to revisit this question, because tracking this transition is costing
the release team a lot of time that would be better spent elsewhere, and
removing the need for a libcurl transition promises to reduce the complexity
of the other components by an order of magnitude.
On looking at the curl package, I've come to understand that the
symbol versioning in place in this library is the result of a
Debian-local patch. That's great news, because it suggests a solution
to this quandary that doesn't require an unreasonable amount of
developer time.
Yeah, it wasn't pretty. Here's what was proposed:
I am proposing the following:
Keep the library soname the same as it currently is upstream. Because
upstream uses unversioned symbols, our package will be binary-compatible
with applications built against the upstream libcurl regardless of what we
do with symbol versioning, so leaving the soname alone minimizes the
amount of patching to be done against upstream code here.
Revert the Debian symbol versioning to the libcurl3 version, and make
libcurl.so.3 a symlink to libcurl.so.4. We have already established that
libcurl.so.4 is still API-compatible with libcurl.so.3, in spite of the
soname change upstream; reverting the symbol versioning will make it fully
ABI-compatible with libcurl.so.3, and adding the symlink lets
previously-built binaries find it.
Revert the Debian package names to the curl 7.15.5 versions. Because
compatibility has been restored with libcurl3 and libcurl3-gnutls,
restoring the package names provides the best upgrade path from etch to
lenny; and because the symbol versions have been reverted, the libraries
are not binary-compatible with the Debian packages currently named
libcurl4/libcurl4-gnutls/libcurl4-openssl (in spite of being
binary-compatible with upstream), so it would be wrong to keep the current
names regardless.
Drop the SSL-less variant of the library, which was not present in curl
7.15.5; AFAICS, there is no use case where a user of curl needs to not
have SSL support, so this split seems to be unnecessary overhead. Please
correct me if I'm mistaken.
Leave the -dev package names alone otherwise, to simplify binNMUing of the
reverse-dependencies (some packages have already added versioned
build-deps on libcurl4.*-dev -- I have no idea why -- so reverting the
names would mean more work to chase down those packages). Drop
libcurl4-dev as a binary package, though, in favor of being Provided by
libcurl4-gnutls-dev. Many of the packages currently build-depending on
libcurl4-dev -- including some that wrongly used libcurl3-dev before --
are GPL, and these are apparently all packages where having SSL support
missing in libcurl4 wasn't hurting them, so libcurl4-gnutls-dev seems to
be the reasonable "default" here.
Schedule binNMUs for all reverse-dependencies.
Again, no judgement here: this was what needed to be done at the time,
and I believe it was a good solution given the circumstances.
In the end, the binary library packages got renamed again: from
libcurl4- openssl,gnutls back to libcurl3- openssl,gnutls (but
not their -dev variants!), but they continued shipping
libcurl libraries whose SONAME version was 4. This solved the
immediate problem of untangling the transitions mentioned by Steve,
but introduced a technical debt that would stick with the package
literally for decades.
The situation at the end of 2007 was:
libcurl3-openssl with libcurl4-openssl-dev; and
libcurl3-gnutls with libcurl4-gnutls-dev.
More discrepancy is added
Eventually the libcurl3-openssl package got renamed to libcurl3,
but aside from that the situation with mismatched library names
vs. SONAME versions stayed relatively unchanged until around 2018,
when the Debian curl maintainer at the time (a different person)
renamed libcurl3 to libcurl4 to fix a bug. This was the right
thing to do for libcurl3, and at the time upstream curl was already
properly versioning their symbols, but for some reason
libcurl3-gnutls got left behind. So now we had:
libcurl4 with libcurl4-dev; and
libcurl3-gnutls with libcurl4-gnutls-dev.
In other words, we now have a discrepancy between the OpenSSL and
GnuTLS variants' names. Yeah, confusing. And this is the situation
right now, on May 2026, while I write this post.
To make matters worse, the Debian curl package has been carrying a
patch to facilitate the split of OpenSSL and GnuTLS flavours for
decades now, and, for some reason I didn't bother to investigate, the
patch pins the SONAME version of libcurl3-gnutls to CURL_GNUTLS_3,
effectively overriding upstream's decision to version the symbols as
CURL_GNUTLS_4.
A call to make things right
Back in 2022, Simon McVittie filed a Debian bug to try and call our
attention to the fact that we were shipping this messy set of curl
packages. I had just started to get involved in the package
maintenance and Samuel asked me to take a look at the bug. I noticed
it was going to take more time than I had available, so I decided to
put it in my TODO list (TM).
Simon was generous enough to lay out a possible plan to tackle the
problem, but I had a feeling that this was going to be harder than it
looked. I kept postponing working on the bug, but also kept thinking
about it now and then because it's an interesting thing to solve.
Then, a month or so ago the Debian Brasil community got together for
MiniDebConf Campinas 2026 and we decided to do a bug squashing party
there. I started working on a few FTBFS bugs with GCC 16, but then
got remembered about the curl bug and thought that that was the
perfect time and place to start working on it, for a few reasons:
Samuel and Charles were also attending the conference, so I could
talk to them about my plans and show them a PoC.
The initial plan
The plan I had in mind was a variant of Simon's proposed plan:
I would have to adjust our GnuTLS-specific patch so that it did not
override the SONAME version for libcurl-gnutls. Then,
For each symbol from libcurl3-gnutls I would have to:
Explicitly version it as curl_symbol_name@@CURL_GNUTLS_4.
Create an alias for the symbol (let's call it __curl_compat_symbol_name).
Explicitly version this alias as __curl_compat_symbol_name@CURL_GNUTLS_3.
Have a separate version of curl's linker script to make it
possible to create a hierarchy between CURL_GNUTLS_3 and
CURL_GNUTLS_4 symbols.
Note that this whole dance is needed because it is a hard requirement
that programs linked against libcurl3-gnutls keep working when we
ship libcurl4-gnutls, without needing to recompile them. Due to the
fact that we will not really bump the SONAME of libcurl-gnutls (but
instead fix the symbol versions shipped by it), we cannot expect
programs to break given that they are actually using the exact same
ABI as before.
Unfortunately (as it is common with low level tools) the documentation
for ld's versioning syntax is quite incomplete and hard to find.
One of the best sources I found was this blog post. For this reason,
let me quickly explain the different notations for symbol versioning
used above.
curl_symbol_name@@CURL_GNUTLS_4
When we use curl_symbol_name@@CURL_GNUTLS_4 (note the @@) we are
telling the linker that this should be considered the default
version of curl_symbol_name. In other words, when a binary that
links against libcurl-gnutls calls curl_symbol_name, the linker
should use curl_symbol_name@@CURL_GNUTLS_4 to resolve the symbol.
There are a few ways to specify a symbol version in C/C++:
__curl_compat_symbol_name@CURL_GNUTLS_3
Finally, when we use __curl_compat_symbol_name@CURL_GNUTL_3 (note
the single @) we are telling the linker that this symbol exists, but
it should not be used as the default symbol. In fact, this
notation will basically hide the symbol and make it only available for
those programs that have already been linked against it. It's a way
of saying "don't offer this symbol when linking, but it's here in case
a program needs it to run" (it's a bit more complicated than that, but
you get the point).
The reason I had to create an alias to the function before
versioning the symbol with @CURL_GNUTLS_3 is because, once I've
versioned the main symbol as @@CURL_GNUTLS_4, I can't create another
version of it. It's also important to mention that to be able to
create a version for the alias I also had to change its visibility to
default. In the end, the alias ended up being defined as:
First attempt and lessons learned
For my PoC I decided to tackle a small subset of the problem. The
symbols file for libcurl3-gnutls contains around 100 symbols that
need to be fixed, so I chose two of them and started trying to write a
patch to see if I could make things work. And after some time
struggling with GCC's syntax and inspecting nm -D's output I finally
got something that looked like it was going to work. The two symbols
I had chosen to work with got correctly versioned (both as
@@CURL_GNUTLS_4 and @CURL_GNUTLS_3), and a quick-and-dirty C
program that used those symbols correctly compiled and ran with the
expected symbols. I showed the results to Samuel and Charles, we got
excited about what we saw, and then the conference ended.
Second attempt and some adjustments
After getting back home I resumed the work on my branch and wrote an
Emacs function that semi-automatically adjusted all 100+ symbols
listed in the symbols file so that they all looked like:
The patch was big but mostly repetitive, and I was happy to have come
up with a solution that looked clean. Until I tried to build the
package, that is.
I started seeing some strange errors that happened when ld was
trying to link the final libcurl4-gnutls object (yes, at that point
I had already renamed the binary package). This is one of the errors
I was getting from ld (I got variants of this error as I was trying
to fix the approach):
/usr/bin/x86_64-linux-gnu-ld.bfd: .libs/libcurl_gnutls_la-easy.o: in function dupeasy_meta_freeentry':./debian/build-gnutls/lib/./debian/build-gnutls/lib/easy.c:1024: multiple definition of curl_easy_cleanup'; .libs/libcurl_gnutls_la-easy.o:./debian/build-gnutls/lib/./debian/build-gnutls/lib/easy.c:908: first defined here/usr/bin/x86_64-linux-gnu-ld.bfd: .libs/libcurl-gnutls.so.4.8.0: version node not found for symbol curl_easy_duphandle@CURL_GNUTLS3/usr/bin/x86_64-linux-gnu-ld.bfd: failed to set dynamic section sizes: bad value
This was strange. I did some tests with very simple versions of a
shared library using the versioning mechanism I had implemented and it
all worked. I could not reproduce the problem, and that's not a great
feeling to have.
Then, after reading a lot of documentation and blog posts throughout
the internet I found something interesting. Apparently ld has a
limitation when it comes to dealing with symbols versioned with @@.
If there is a single symbol versioned like that in a source file (the
actual term is TU, which means Translation Unit, but let's
simplify), then ld is happy and generates the expected version
without issues. But when we're dealing with multiple definitions of
@@ symbols in a source file (which is exactly what happens in curl),
then ld can get confused and start giving errors during the link
stage.
To solve that limitation, we have to resort to yet another symbol
versioning notation: @@@. Yes, three at signs. For example:
Note that we have to use __asm__ because GCC's __attribute__
doesn't support the triple-at notation.
What this does is tell the linker to create a versioned symbol for
curl_symbol_name, set it as the default symbol when linking, but
also remove the unversioned curl_symbol_name symbol. This makes
ld happy and allows it to successfully link libcurl-gnutls. As
usual, you won't find any mention of the @@@ notation inside ld's
documentation.
With libcurl-gnutls compiling again, I had to adjust libcurl's
linker script to create a hierarchy between CURL_GNUTLS_3 and
CURL_GNUTLS_4 symbols. Here's the final version of the file:
CURL_GNUTLS_3 global: curl_easy_cleanup; /* lots of other symbols here */ local: *; ;CURL_GNUTLS_4 global: curl_*; local: *; CURL_GNUTLS_3;
Debian package adjustments
After getting the hard part out of the way, the rest was easy. It was
time to finally rename libcurl3-gnutls to libcurl4-gnutls.
Initially I was thinking that I'd need to ask the release team for a
transition to happen, but as it turns out that won't be necessary.
Because we are effectively shipping the same exact library/ABI and the
only difference is the inclusion of the extra CURL_GNUTLS_4
versioned symbols, and given that we will be shipping CURL_GNUTLS_3
versioned symbols to guarantee backwards compatibility, packages won't
need to get rebuild just to pick up the new dependency. Instead, we
can safely turn libcurl3-gnutls into a transitional package that
depends on libcurl4-gnutls.
Merge request and next steps
This is the merge request where I am working on the fix. As of this
writing it is in a draft state, but I expect to merge in the next
couple of days. Once the fixed curl package is uploaded, we should
keep an eye on the archive to make sure no unexpected bugs happen.
I would like to carry this patch downstream at least until forky is
released. It doesn't make sense to propose it upstream because this
problem is Debian-specific and should be fixed there. We will need to
make sure that all reverse dependencies of libcurl3-gnutls are
recompiled before we can get rid of the transitional package, too.
This was a fun bug to investigate and fix, and I am happy that we will
finally have sensible names (and symbol versions!) for both of our
libcurl variants. Stay tuned for the next challenge!
I have been battling Large Language Models (LLM1) for the past
couple of weeks and have struggled to think about what it means and
how to deal with its fallout.
Because the fight has come from many fronts, I've come to articulate
this in terms of the Four Horsemen of the Apocalypse.
War: bot armies
Let's start with War. We've been battling bot armies for control of
our GitLab server for a while. Bots crawl virtually infinite
endpoints on our Git repositories (as opposed to downloading an
archive or shallow clone), including our fork of Firefox, Tor Browser,
a massive repository.
At first, we've tried various methods: robots.txt, blocking user
agents, and finally blocking entire networks. I wrote
asncounter. It worked for a while.
But now, blocking entire networks doesn't work: they come back some
other way, typically through shady proxy networks, which is kind
of ironic considering we're essentially running the largest proxy
network of the world.
Out of desperation, we've forced users to use cookies when
visiting our site. We haven't deployed Anubis yet, as we worry
that bots have broken Anubis anyways and that it does not really
defend against a well-funded attacker, something which Pretix
warned against in 2025 already.
(We have a whole discussion regarding those tools here.)
But even that, predictably, has failed. I suspect what we consider
bots are now really agents. They run full web browsers, JavaScript
included, so a feeble cookie is no match for the massive bot armies.
Side note on LLM "order of battle"
We often underestimate the size of that army. The cloud was huge even
before LLMs, serving about two thirds of the web. Even larger swaths of
clients like government and corporate databases have all moved to the
cloud, in shared, but private infrastructure with massive spare
capacity that is readily available to anyone who pays.
LLMs have made the problem worse by dramatically expanding the
capacity of the "cloud". We now have data centers that defy
imagination with millions of cores, petabytes of memory, exabytes
of storage.
I thought that 25 gigabit residential internet in Switzerland
could bring balance, but this is nothing compared to the scale of
those data centers.
Those companies can launch thousands, if not millions of fully
functional web browsers at our servers. Computing power or bandwidth
are not a limitation for them, our primitive infrastructure is. No one
but hyperscalers can deal with this kind of load, and I suspect that
they are also struggling, as even Google is deploying extreme
mechanisms in reCAPTCHA.
This is the largest attack on the internet since the Morris
worm but while Robert Tappan Morris went to jail on a felony,
LLM companies are celebrated as innovators and will soon be too big to
fail.2
Which brings us to the second horsemen, famine.
Famine: shortages
All that computing power doesn't come out of thin air: it needs
massive amounts of hardware, power, and cooling.
Earlier this year, I've heard from a colleague that their Dell
supplier refused to even provide a quote before August. Dell!
In February, Western Digital's hard drive production for 2026 was
already sold out. Hard drives essentially doubled in price within
a year, and some have now tripled. A server quote we had in
November has now quadrupled, going from 10 thousand to FORTY
thousand dollars for a single server.
But regular folks are facing real-life shortages as well, as
city-size data centers are being built at neck-breaking speed,
stealing fresh water and energy from human beings to feed the war
machine.
We've been scared of losing our jobs, but it seems that Apocalypse has
yet to fully materialize. Regardless for engineers, the market feels
tighter than it was a couple years ago, and everyone feels on edge
that they will just have to learn to operate LLMs to keep their jobs.
Update: it turns out I was clearly too optimistic. Cisco is laying
off 4,000 or 5% of its staff in a jolly announcement celebrating
a record $15.8 billion revenue, and Meta will lay off 8,000 or
10% of its workforce, in horrifying conditions. See also the
jobloss.ai tracker which counts 125,000 jobs lost since January
2025, as of May 2026.
Which brings us, of course, to Death.
Death: security and copyright
Our third horseman is one I did not expect a couple of months
ago. Back at FOSDEM, curl's maintainer Daniel Stenberg famously
complained about the poor quality of LLM-generated reports but
then, a few months later, everyone is scrambling to deal with floods
of good reports.
In the past two weeks, this culminated in a significant number of
critical security issues across multiple projects. Chained
together, remote code execution vulnerabilities in Nginx and
Apache and two local privilege escalations in the Linux kernel
(dirtyfrag and fragnesia) essentially gave anyone root access to any unpatched server to the web.
As I write this, another vulnerability dropped, which gives read
access to any file to a local user, compromising TLS and SSH private
keys.
All those vulnerabilities were released without any significant
coordination while people scrambled to mitigate.
Many people including Linus Torvalds are now considering issues
discovered through LLMs to be essentially public. This puts some
debates about disclosure processes in perspective, to say the
least.
But this is not merely the death of the traditional coordinated disclosure
process, the C programming language, or the Linux kernel: remember
that those bots are trained on a large corpus of copyrighted
material. Facebook has trained their models on pirated books and
Nvidia has done deals with Anna's Archive to secure access to
large swaths of copyrighted material. The US Congress seems to think
LLM outputs are not copyrightable, like any other machine outputs.
With many people now vibe coding their way out of learning or
remembering how computers work, is this the Death of Copyright?
And that, of course, brings us to the final horseman: Pestilence.
Pestilence: slop
There is a growing meme that programming is essentially over as we
know it. That you can simply vibe-code applications from scratch and
it's pretty good.
Maybe that's true.
So far, most of my attempts at resolving any complex problem with a
LLM have often failed with bizarre failures. Some worked surprisingly
well. Maybe, of course, I am holding it wrong.
I personally don't believe LLMs will ever be good enough to produce
and maintain software at scale. They're surprisingly good at finding
security flaws right now. But what I see is also a lot of
Bullshit, with a capital B. It's not lying: it does not "know"
anything, so it can't lie. It's misleadingly cohesive and
deliberate, but it lacks meaning, intent, will.
I have not been confronted with much slop, apart from the lobster
Jesus or the yellow man atrocities, and particularly not in my
work. But I see what it is doing to my profession: beyond
vibe-coding, people are now token-maxxing, and
land-grabbing their colleagues.
I don't like what LLMs do to our communities, or the fabric of
software we live with.
Software does not evolve in a void. It is a team effort, be it free
software or a corporate product. Generations of humans have carefully
built the scaffolding of technology required for modern networks and
software to operate, in a convoluted contraption that no single human
fully understands anymore.
The idea of simply giving up on that understanding entirely and
delegating it to an unproven model is not only chilling, it feels just
plain stupid. Not stupid as in Skynet, stupid as in "I can't get
inside the data center because the authentication system is
down". Except we're in a "the power plant doesn't reboot" or "their
LLM found an 0day in our slop" kind of stupid.
The fifth horsemen
Researching for this article, I looked up the four horsemen and found
out they original seems to have been:
Famine
War
Death
Conquest (??)
I was surprised. I grew up thinking about the horsemen being Famine,
War, Pestilence, and Death. So I went back to my original source
which actually claims the horsemen are:
Time has taken its toll on you, the lines that crack your face.
Famine, your body, it has torn through, withered in every place.
Pestilence for what you've had to endure, and what you have put others through
Death, deliverance for you, for sure, now there's nothing you can do
So I guess that makes no sense either, which, fair enough, I shouldn't
rely on Metallica for theological references. Especially since that
song was originally called Mechanix and was "about having sex at
a gas station".
Anyways.
The point is, there are actually five horsemen, and the fifth one is,
in my opinion, Conquest.
Those companies (and not "AI", mind you) are taking over the
world. I sense a strong connection with the "post-truth" world imposed
on us by fascists like Trump and Putin. It's not an accident, it's a
power grab part of the Californian Ideology3. Just like Airbnb
broke housing, Uber destroyed the transportation and Amazon is taking
over retail and server hosting, LLM companies are essentially trying
to take over if not everything, at least Cognition as a whole.
But the capitalization of those companies (OpenAI and Nvidia in particular)
are so far beyond reason that their inevitable collapse will likely
lead to a global financial collapse of biblical proportions.
Because they will inevitably fail like previous bubbles they are built
on. And when they fail, I hope it zips all the way back through the
blockchain scam, the ad surveillance system, and the dot com then git
me back my internet.
The Tower of Babel
While I'm off in the woods hallucinating (ha!) on biblical allegories,
I feel there's another sign that the apocalypse is coming.
The Tower of Babel myth says that humans tried to create a big
tower up to heaven and become god. God confounds their speech and
scatters the human race. End of utopia.
This is what is happening to our human translators now. LLMs being,
after all, Language Models, they are excellent at translation work. So
much that the only translators not replaced by LLMs right now are
interpreters, who translate vocally in real time. But
interpreters are worried about their jobs as well.
This concretely means we will lose the human capacity, as a
civilization, to translate between each other. It is still an open
question whether the remaining revision work will be enough for
translators to avoid deskilling, but other research has shown that LLM
use leads to cognitive decline, impacts critical thinking,
and generally, that deskilling is a common outcome.
Ultimately, I think this is where LLMs bring us. Towards collapse.
So this is a call to arms. Fight back!
Poison bots. Build local real-world communities.
Go low tech. Moore's law is dead, make use of it.
Patch your shit. Go weird.
Refuse slop. Train your brain. Refuse distillation.
The horsemen will collapse, but let's not go down with them.
Butlerian Jihad!
This article was written without the use of a large language model
and should not be used to train one.
Updates
A paragraph was added about the job apocalypse, which was of course
under-estimate.
Why Timnit Gebru was fired is extremely important and
interesting. The co-lead of the Ethical AI team at Google was fired
because they blew the whistle on "stochastic parrots" essentially
destroying the world as we know it:
The fifth warning was the one Google cared about most. [...]
The internet would become a place where the dominant voice was a
statistical average of dominant voices, presented as a neutral
assistant.
The warnings from the paper are eerily similar to my horsemen:
predicted the hallucination (pestilence)
bias amplification (war?)
environmental cost (famine)
un-auditable training corpus (death?)
"centralize linguistic and cultural power in the hands of the
small number of companies" (conquest)
I prefer "LLM" to Artificial Intelligence, as I don't consider
models to have "Intelligence" which goes far beyond the analytical
traits we train models for. Intelligence requires embodiment
and social interaction; machines lack the innate human skills of
empathy, feeling and care, which explains a lot of the evils
behind the current trends.
It should be noted that Morris also happened to be one of the
founder of Y Combinator where he is in good company with
other techno-fascists like Peter Thiel, Sam Altman, and so
on. Crime, after all, pays.
In the recent weeks I've been engaging Prot as an Emacs coach to help
with doing review passes over my upcoming ffs package as I work on
polishing and documenting it in preparation for offering it for
inclusion in GNU ELPA.
UPDATE 2026-05-15 08:50:10 -0400: Prot also published an article
about our session on his website:
https://protesilaos.com/codelog/2026-05-15-emacs-amin-bandali-ffs-display-buffer-org-capture/
Today we had our third session where we started by reviewing and
talking about my recent changes to ffs, then ventured to other
Emacs-related topics with the overarching theme of the flexibility
and extensibility of GNU Emacs, including display-buffer-alist,
keyboard macros, defining a custom ox-bhtml Org export backend
derived from Org's ox-html for ultimate flexibility when exporting
my site's pages from Org to HTML, Org capture, plain text files and
Emacs's diary and how it compares to org-agenda, and keeping a
journal with the help of Emacs.
Here is the video recording of our session, which I share with Prot's
permission:
You can view or download the full-resolution video from the Internet
Archive.
Lastly, here is the snippet Prot shared for having Isearch treat space
as a wildcard, helpful for more easily matching multiple parts of a
line:

 The Debian LTS Team, funded by Freexian s Debian LTS offering, is
pleased to report its activities for May.
 There has been a video blog post recently published with a review of Ubuntu Touch as an option to opt out of the Android world:

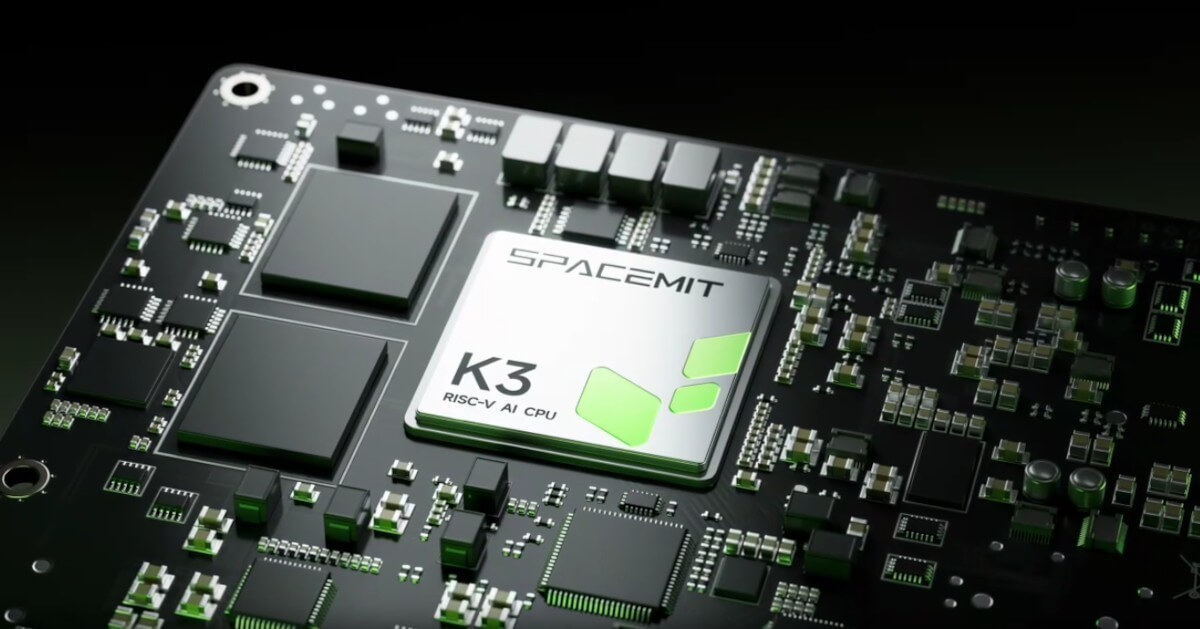 The RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices.
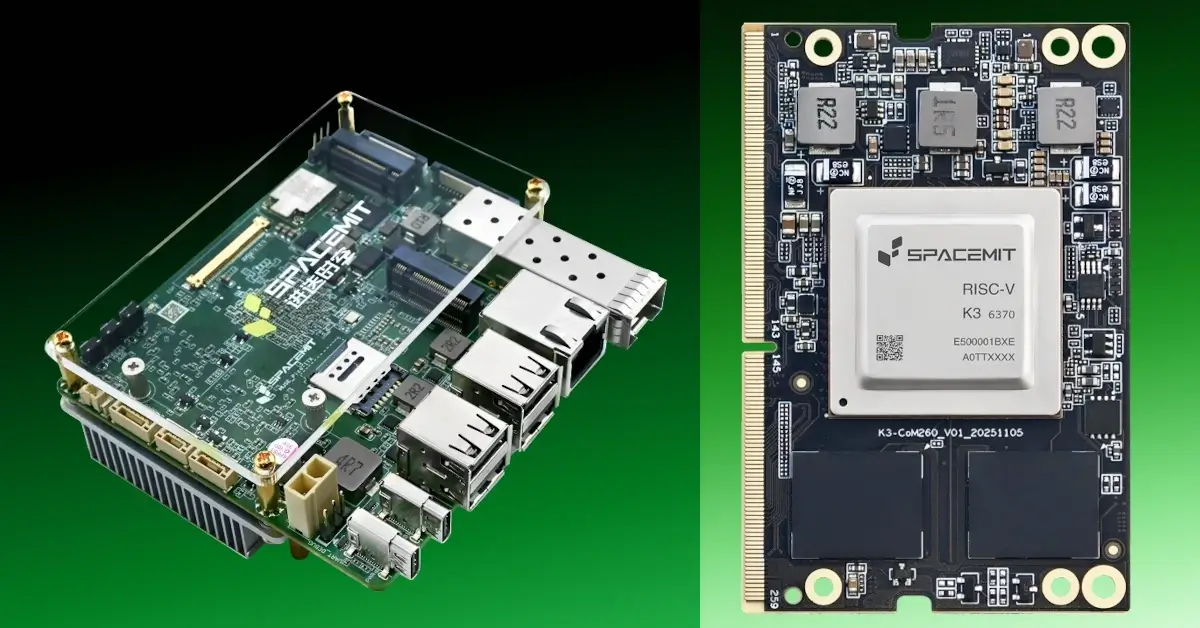
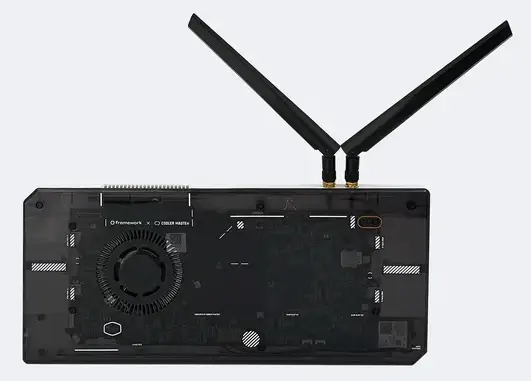
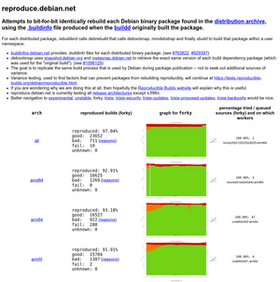
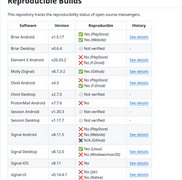


 This was a particularly busy month for me in terms of Debian
contributions.
It started with a week in Hamburg for the MiniDebConf. I talked to
many colleagues face-to-face and worked on various bugs and
maintenance tasks. I m pleased to have finally found the time to
reproduce and fix the
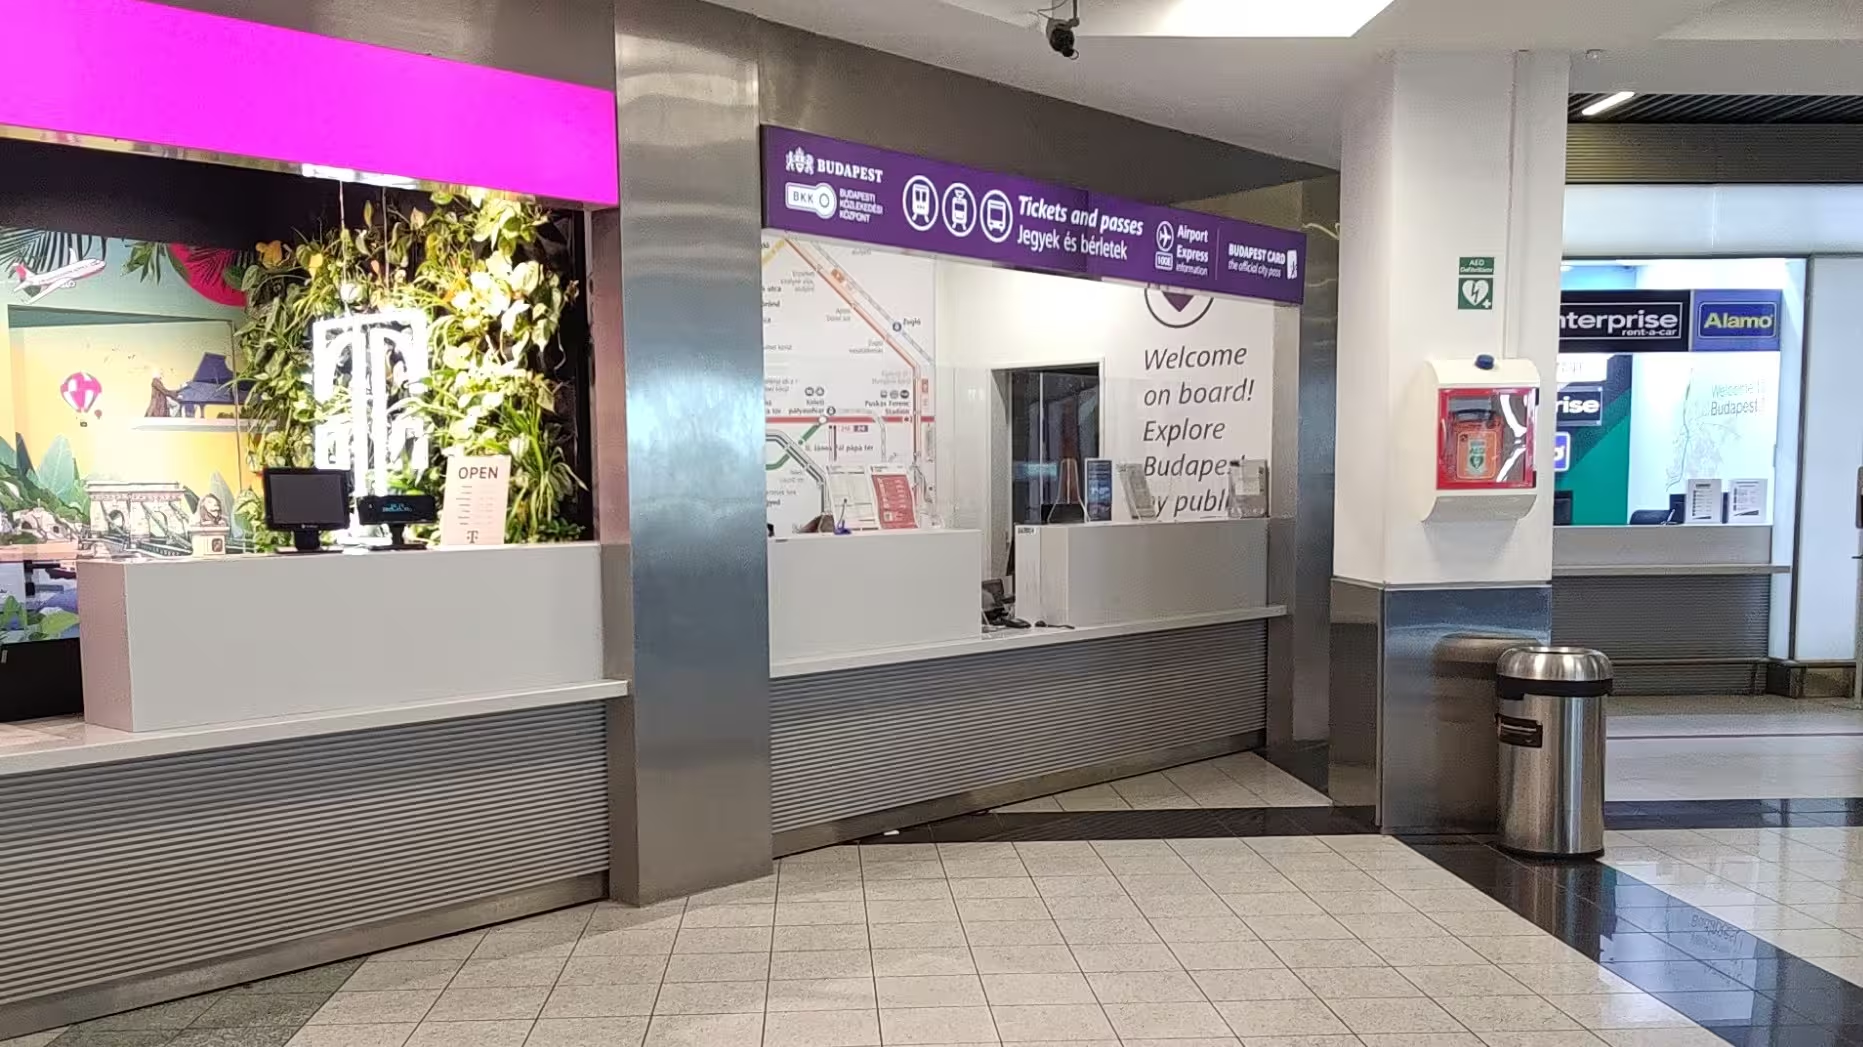 This is the counter from where I bought my public transport pass.
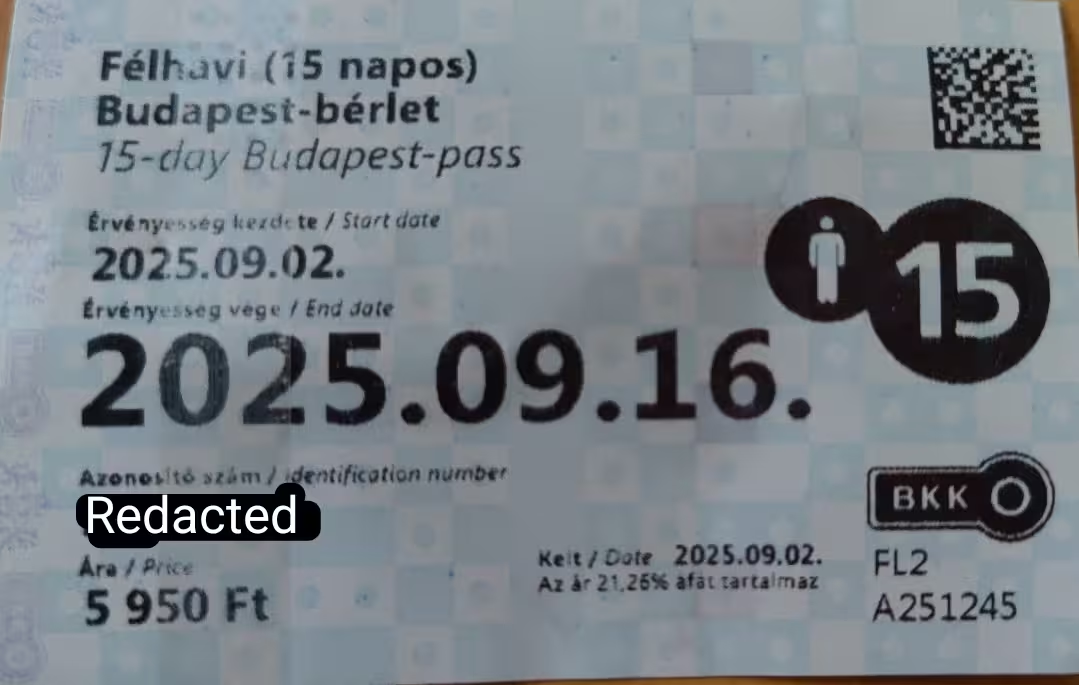 My unlimited public transport pass for Budapest. I have redacted my passport number from it.
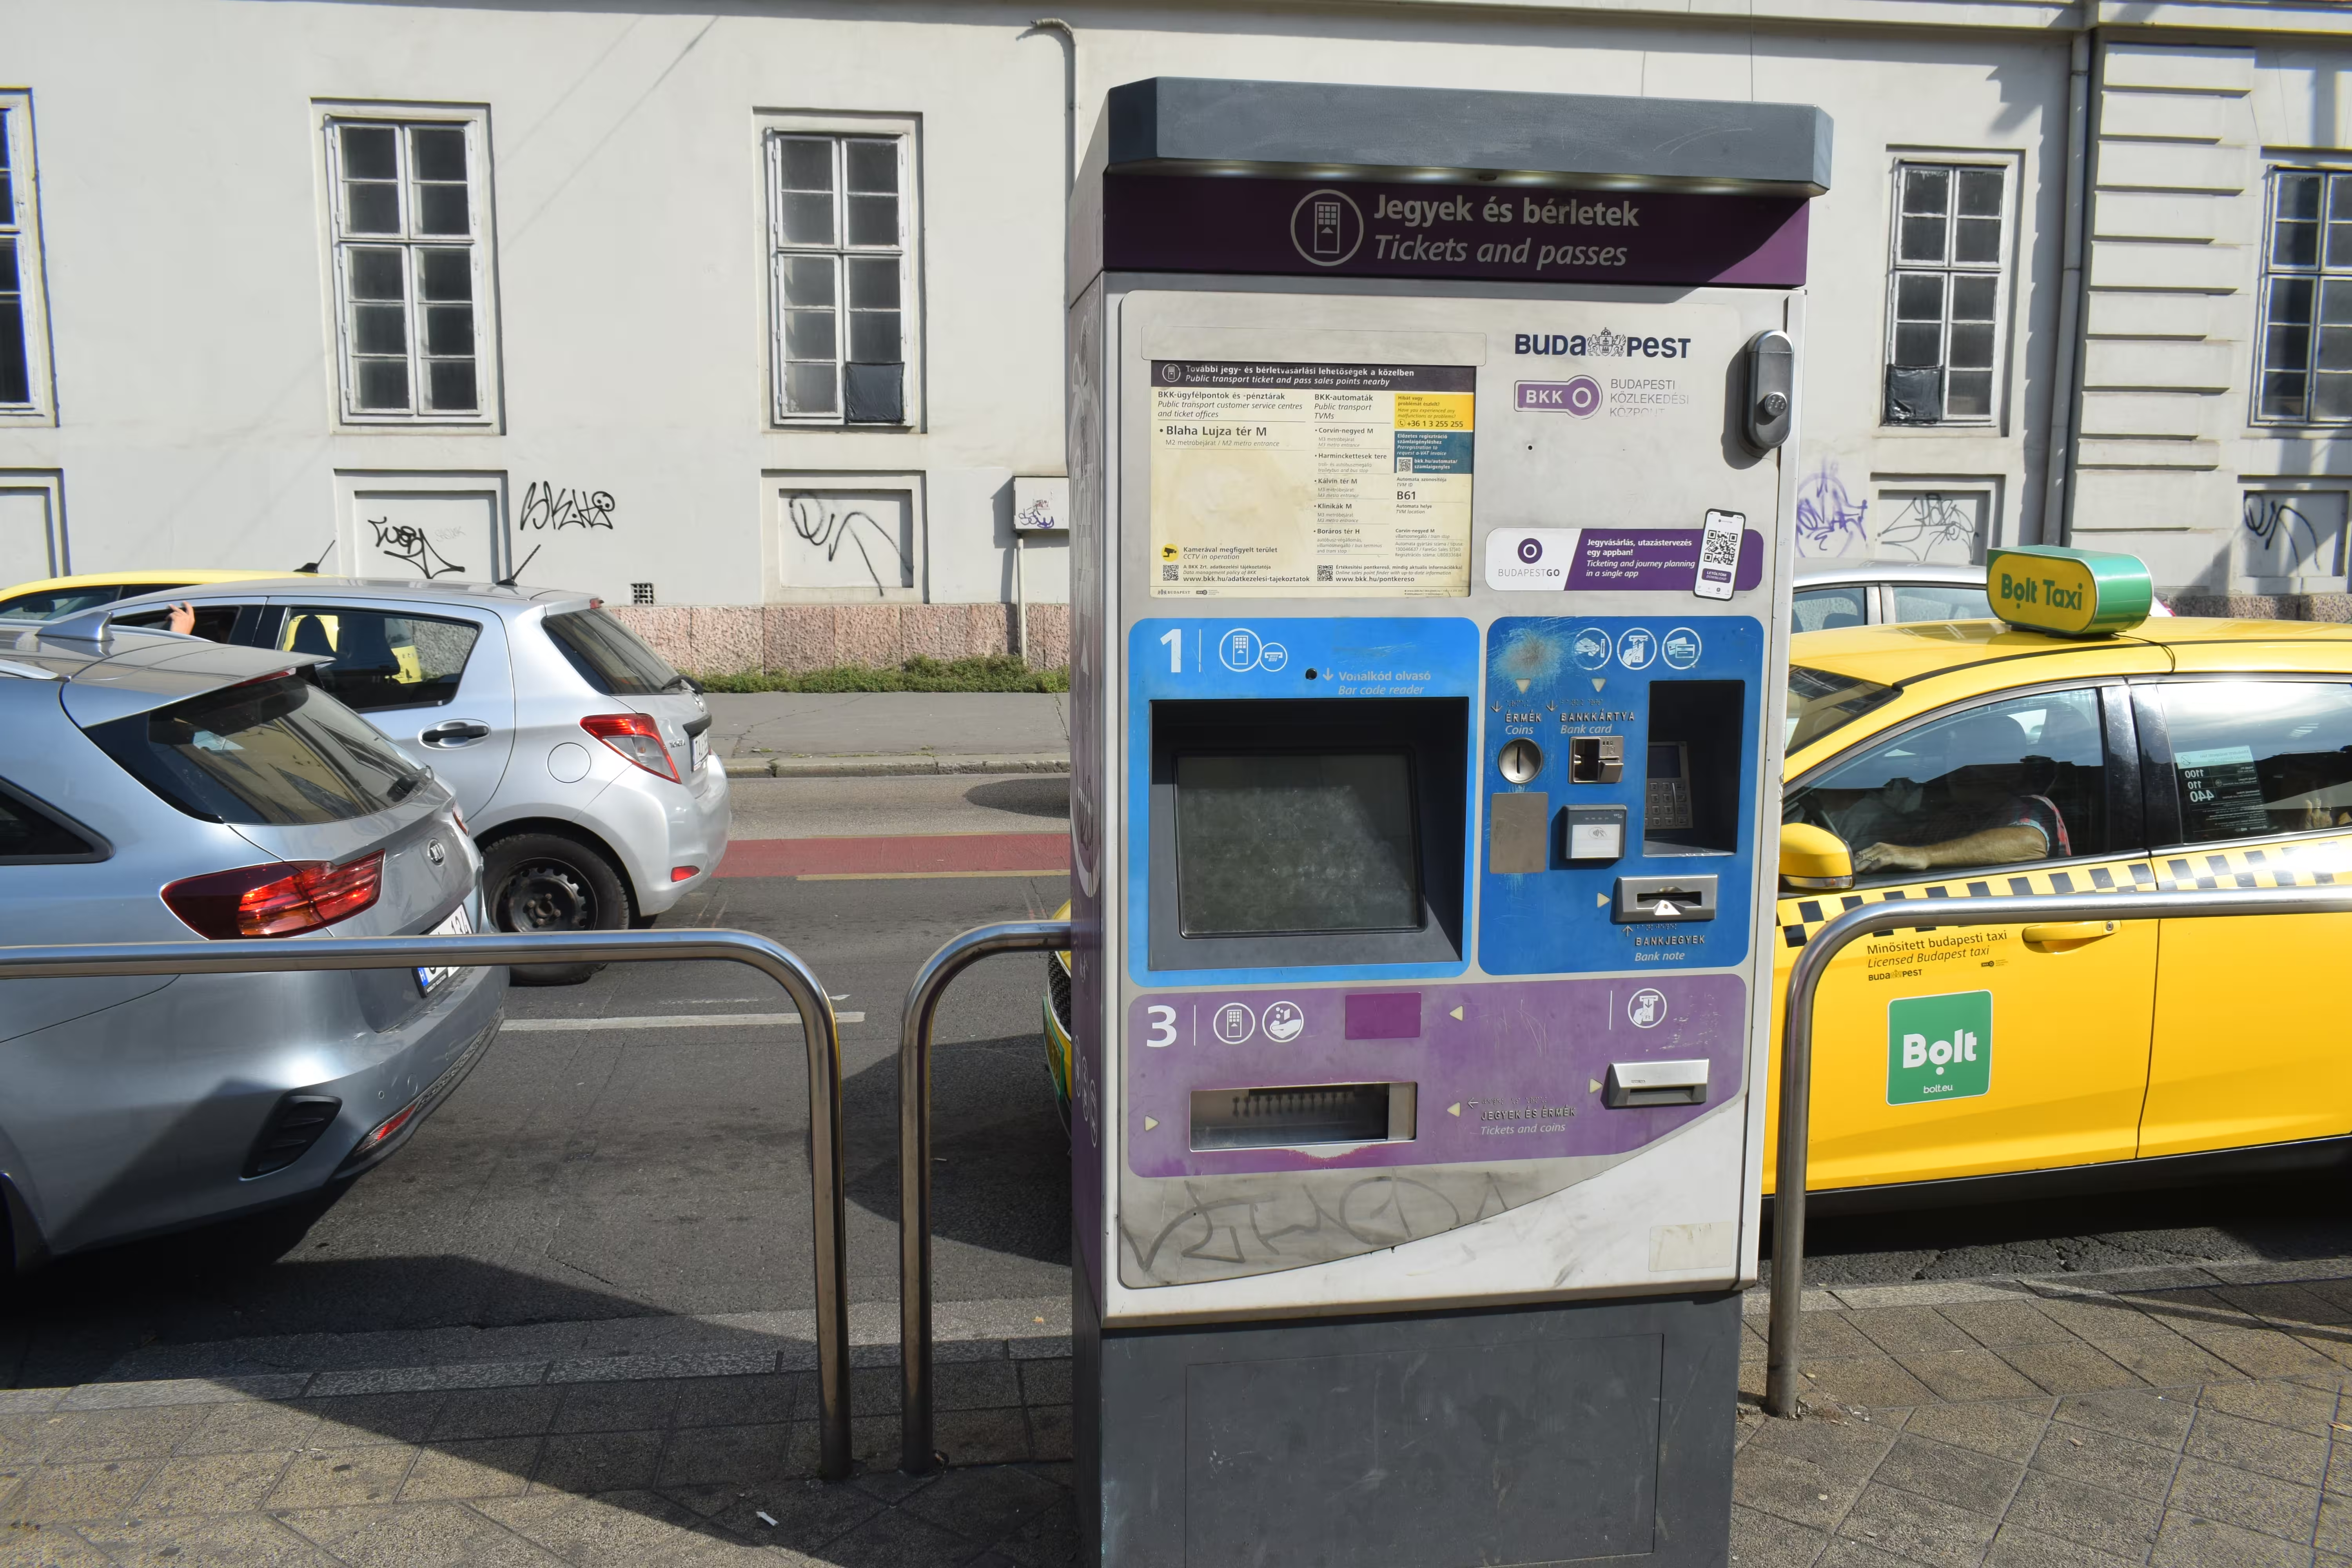 An automatic ticket machine at a tram station in Budapest.
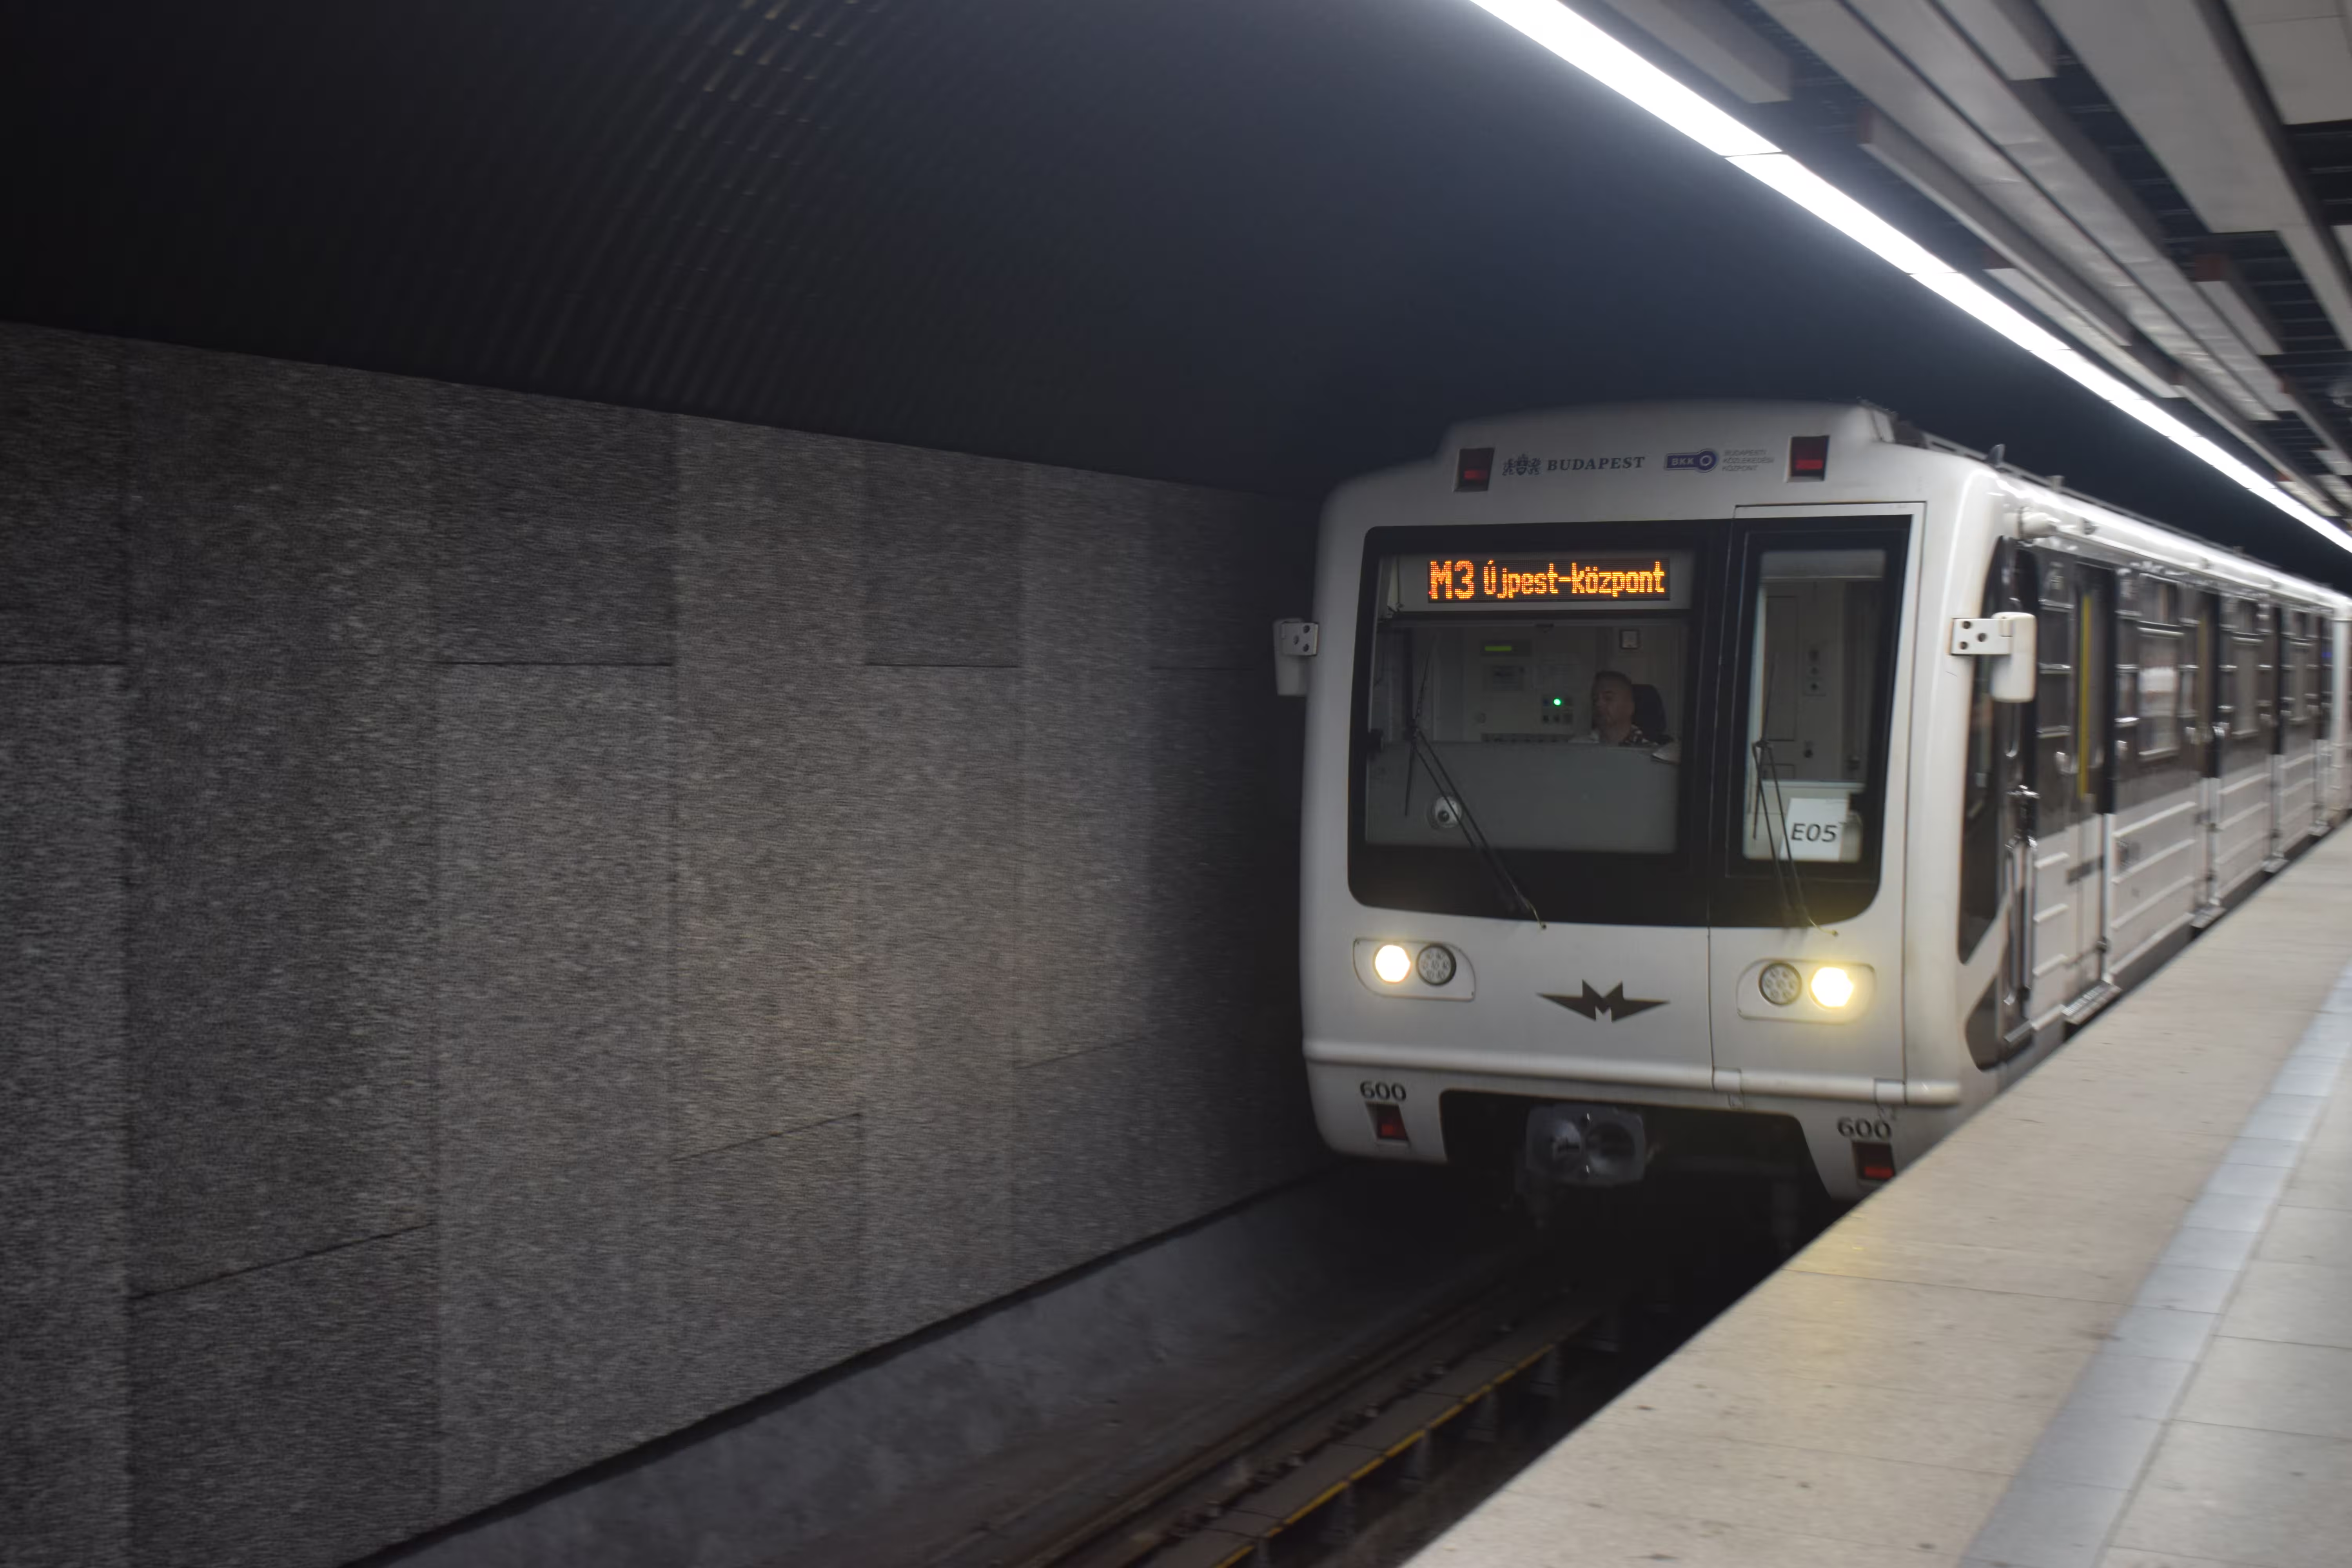 An M3 line metro in Budapest.
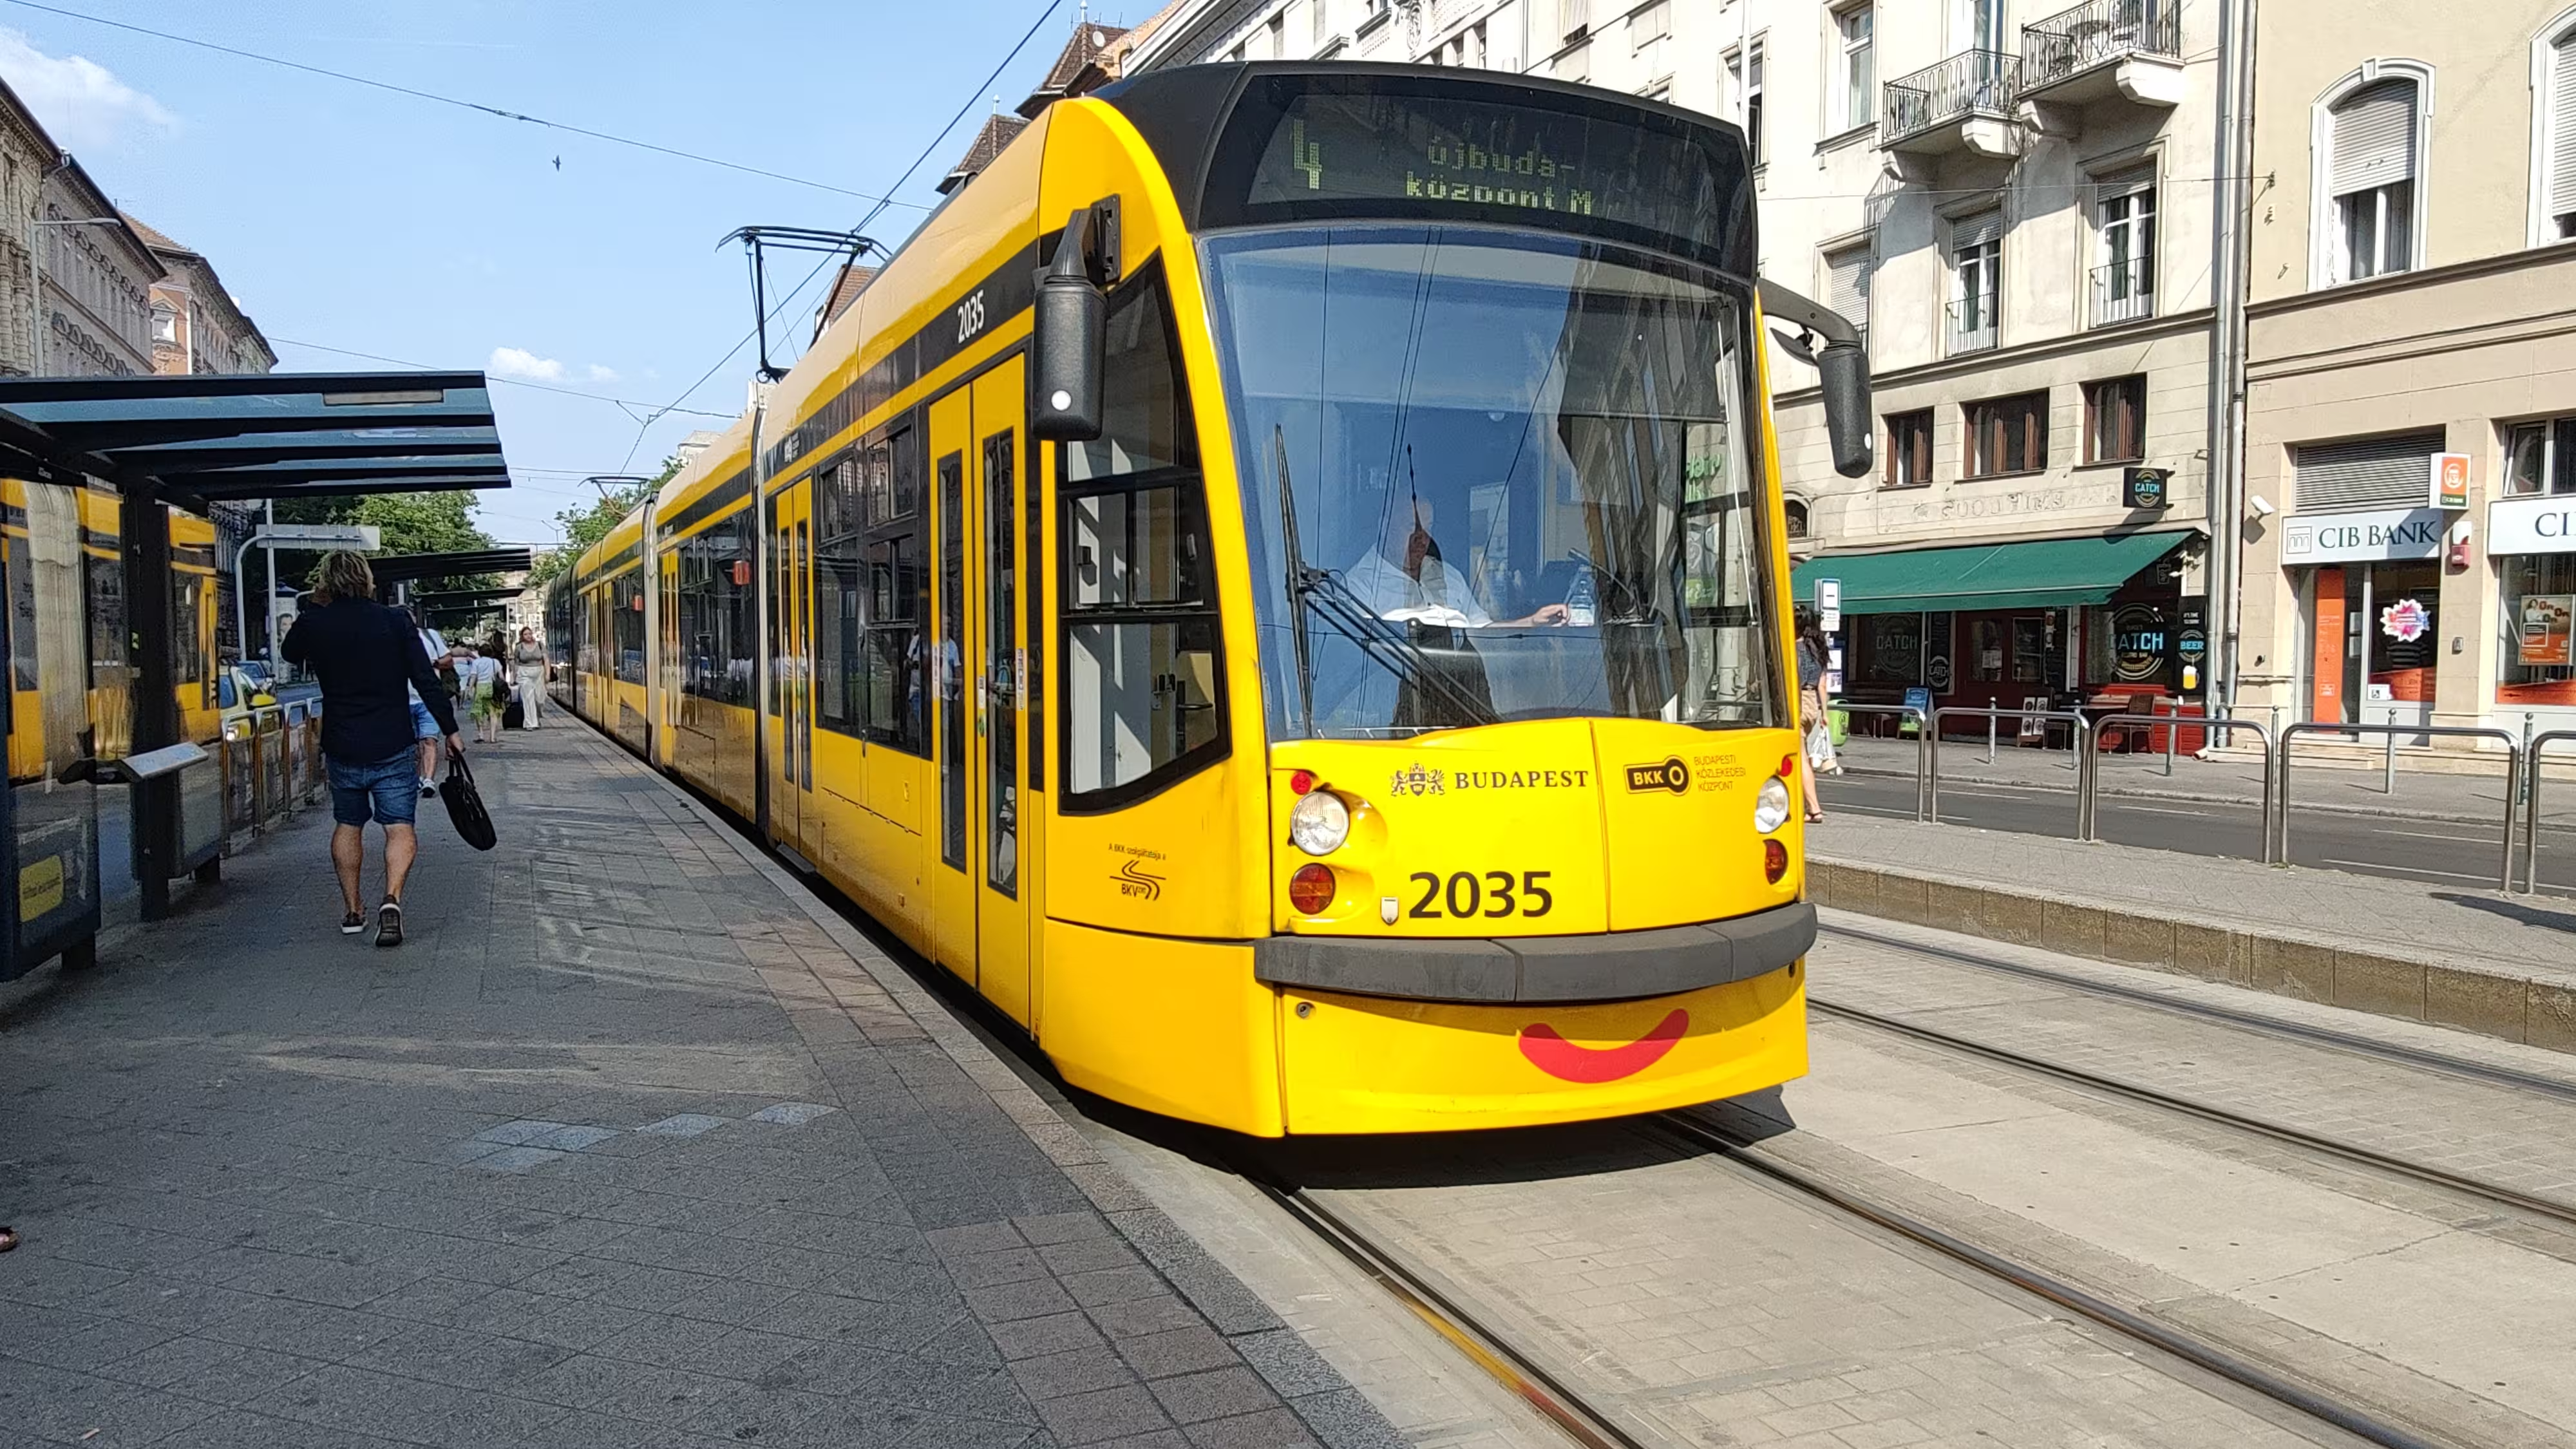 A tram in Budapest having a smiley face at the front.
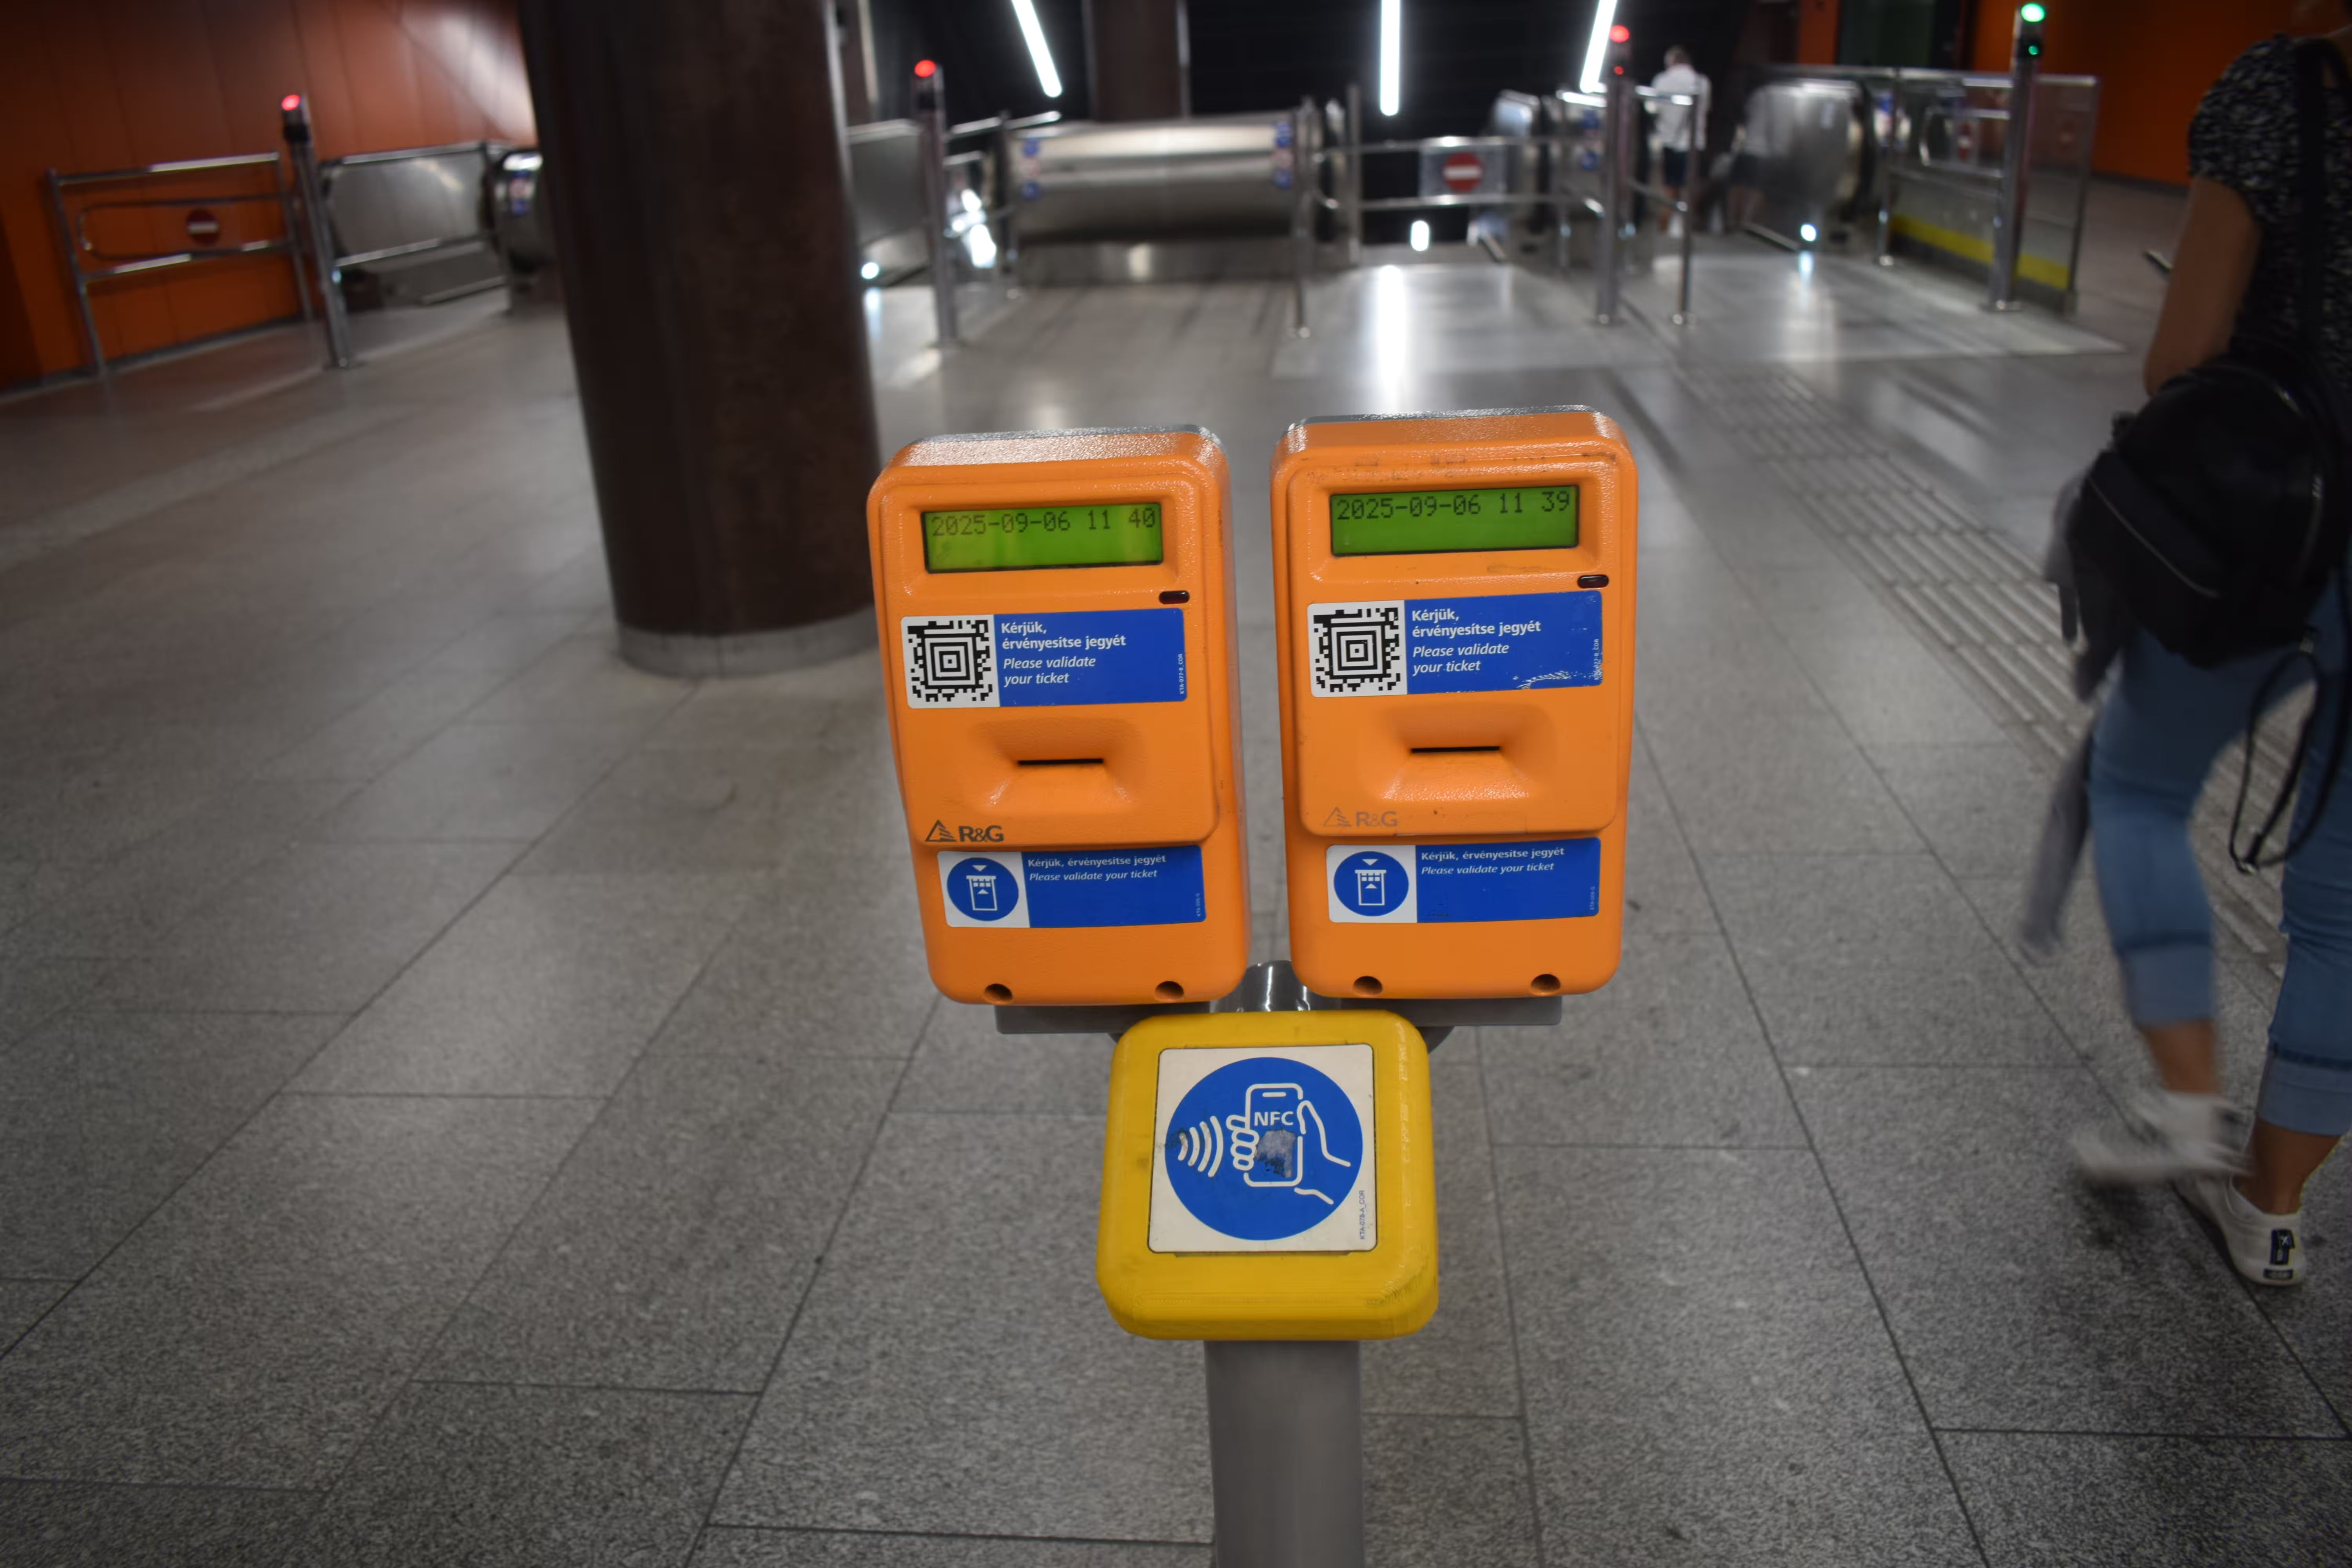 A ticket validator at a metro station in Budapest.
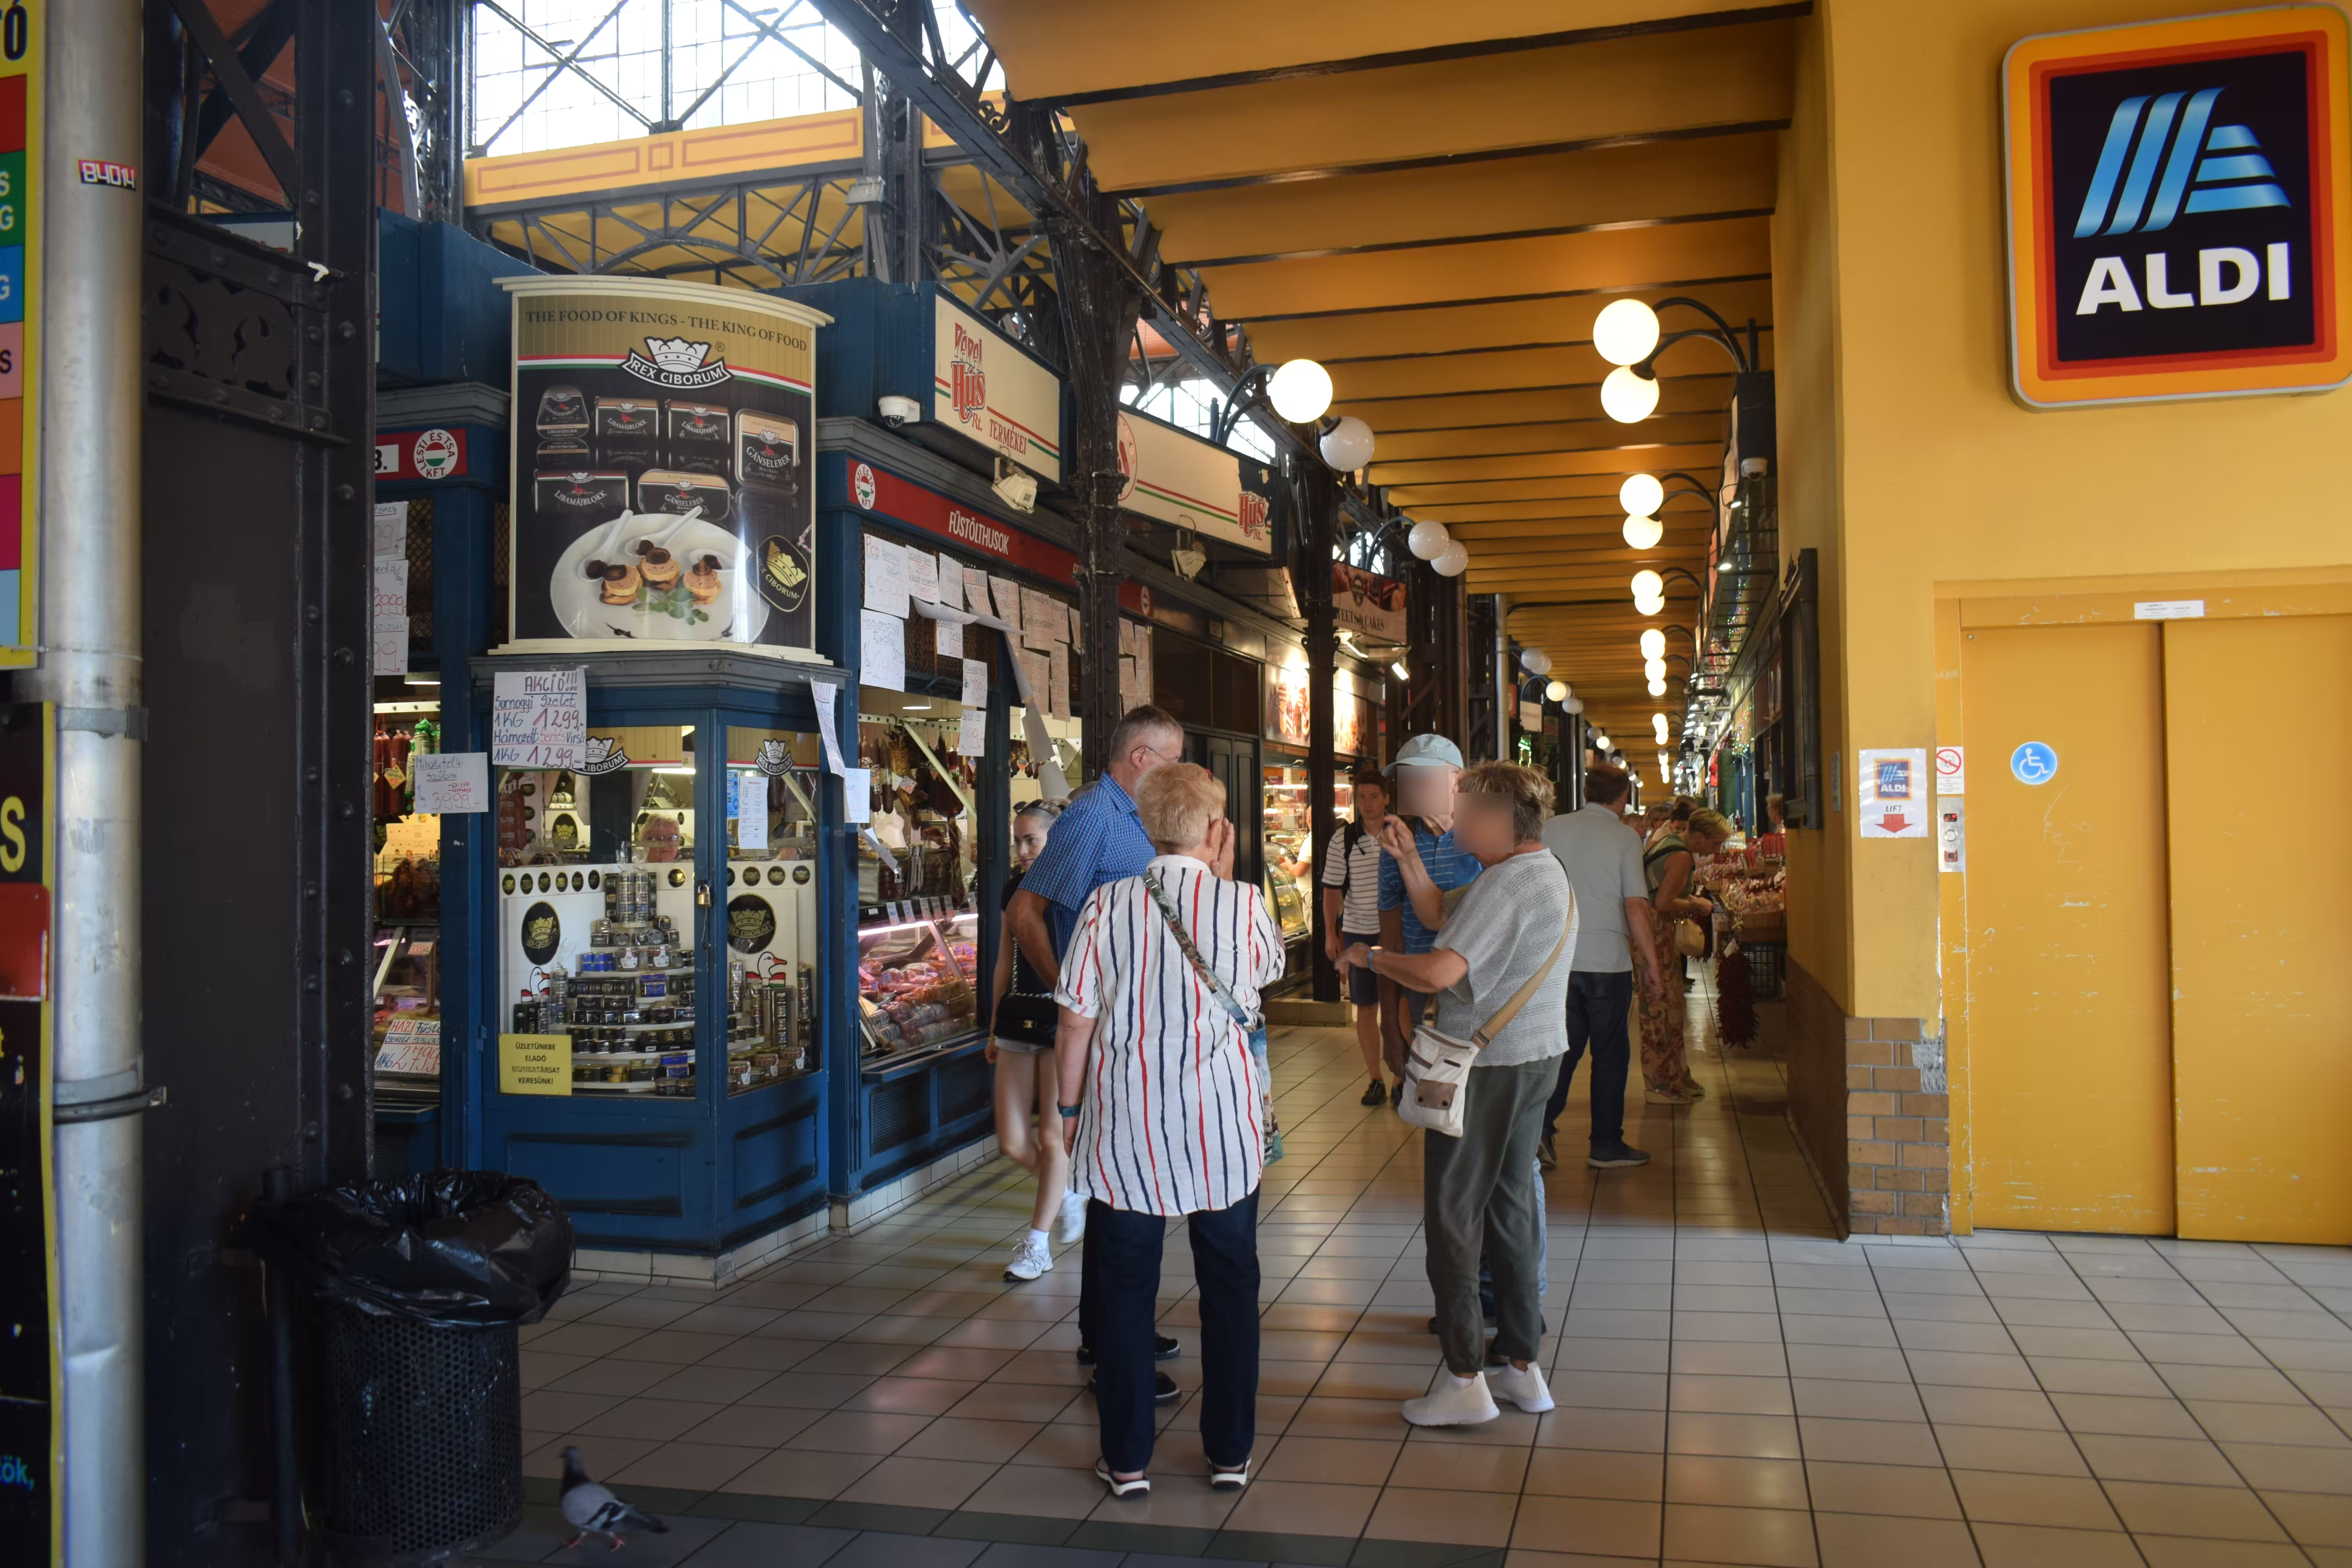 Central market.
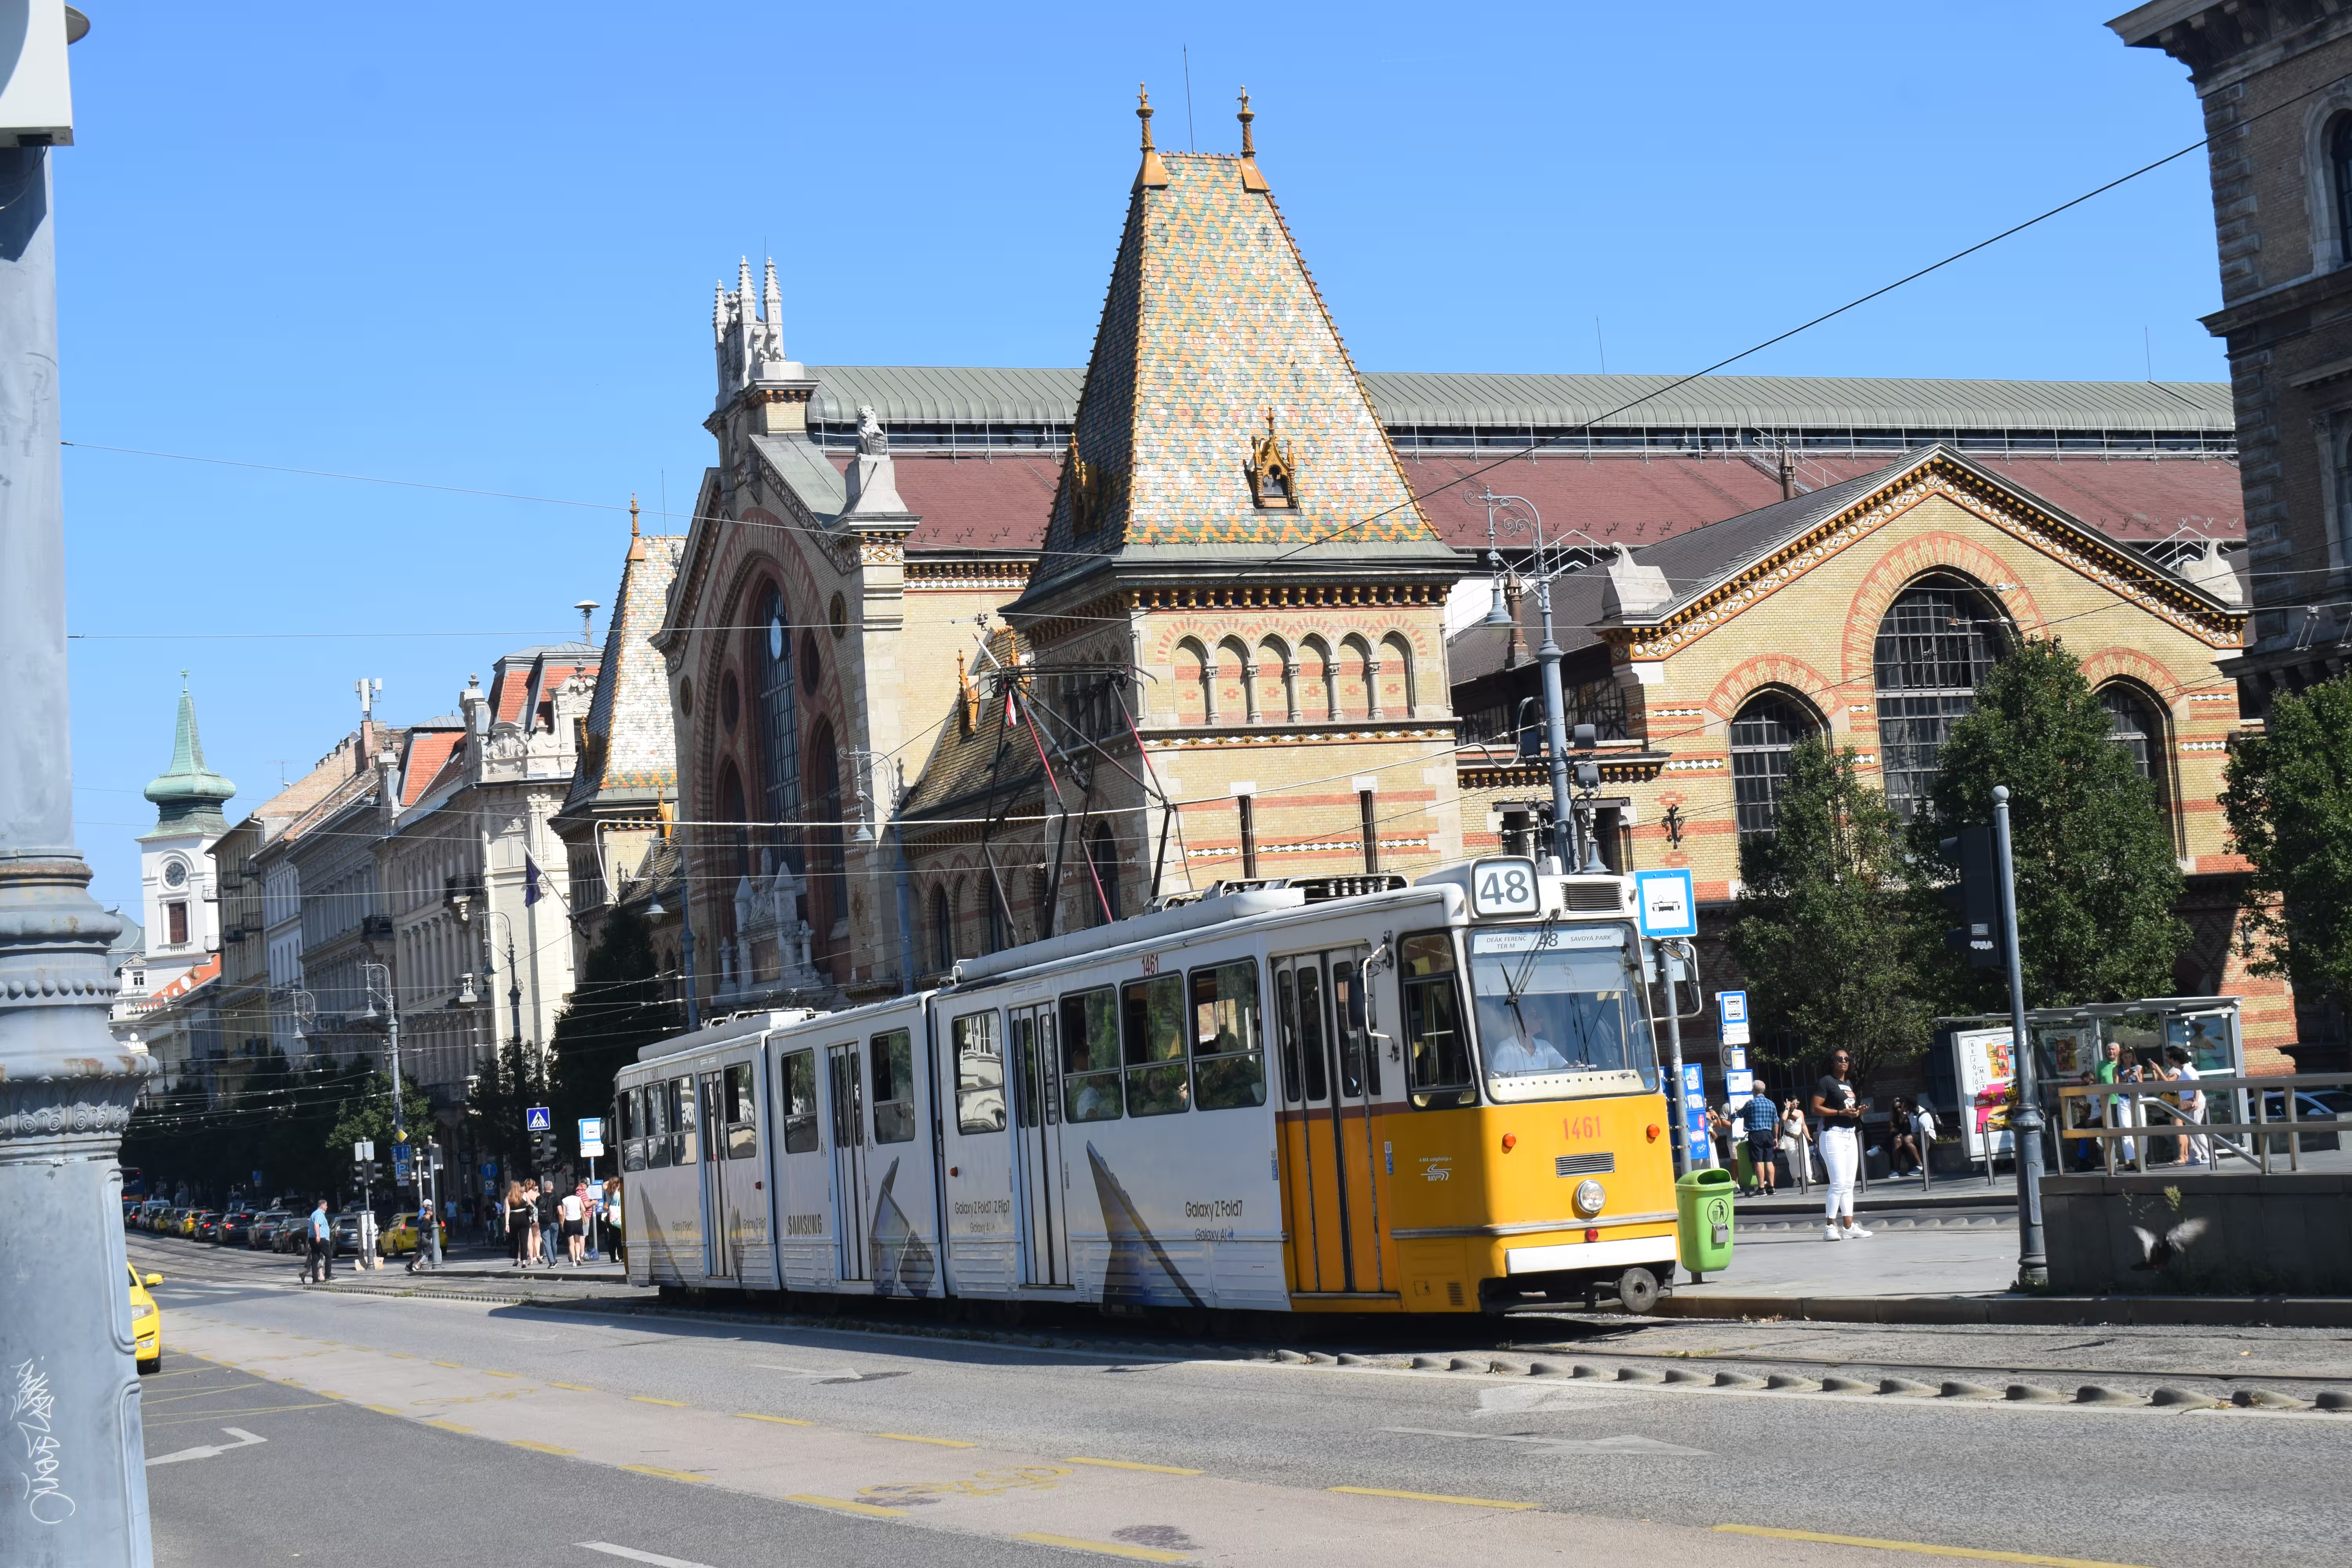 The building right behind the tram is the central market building.
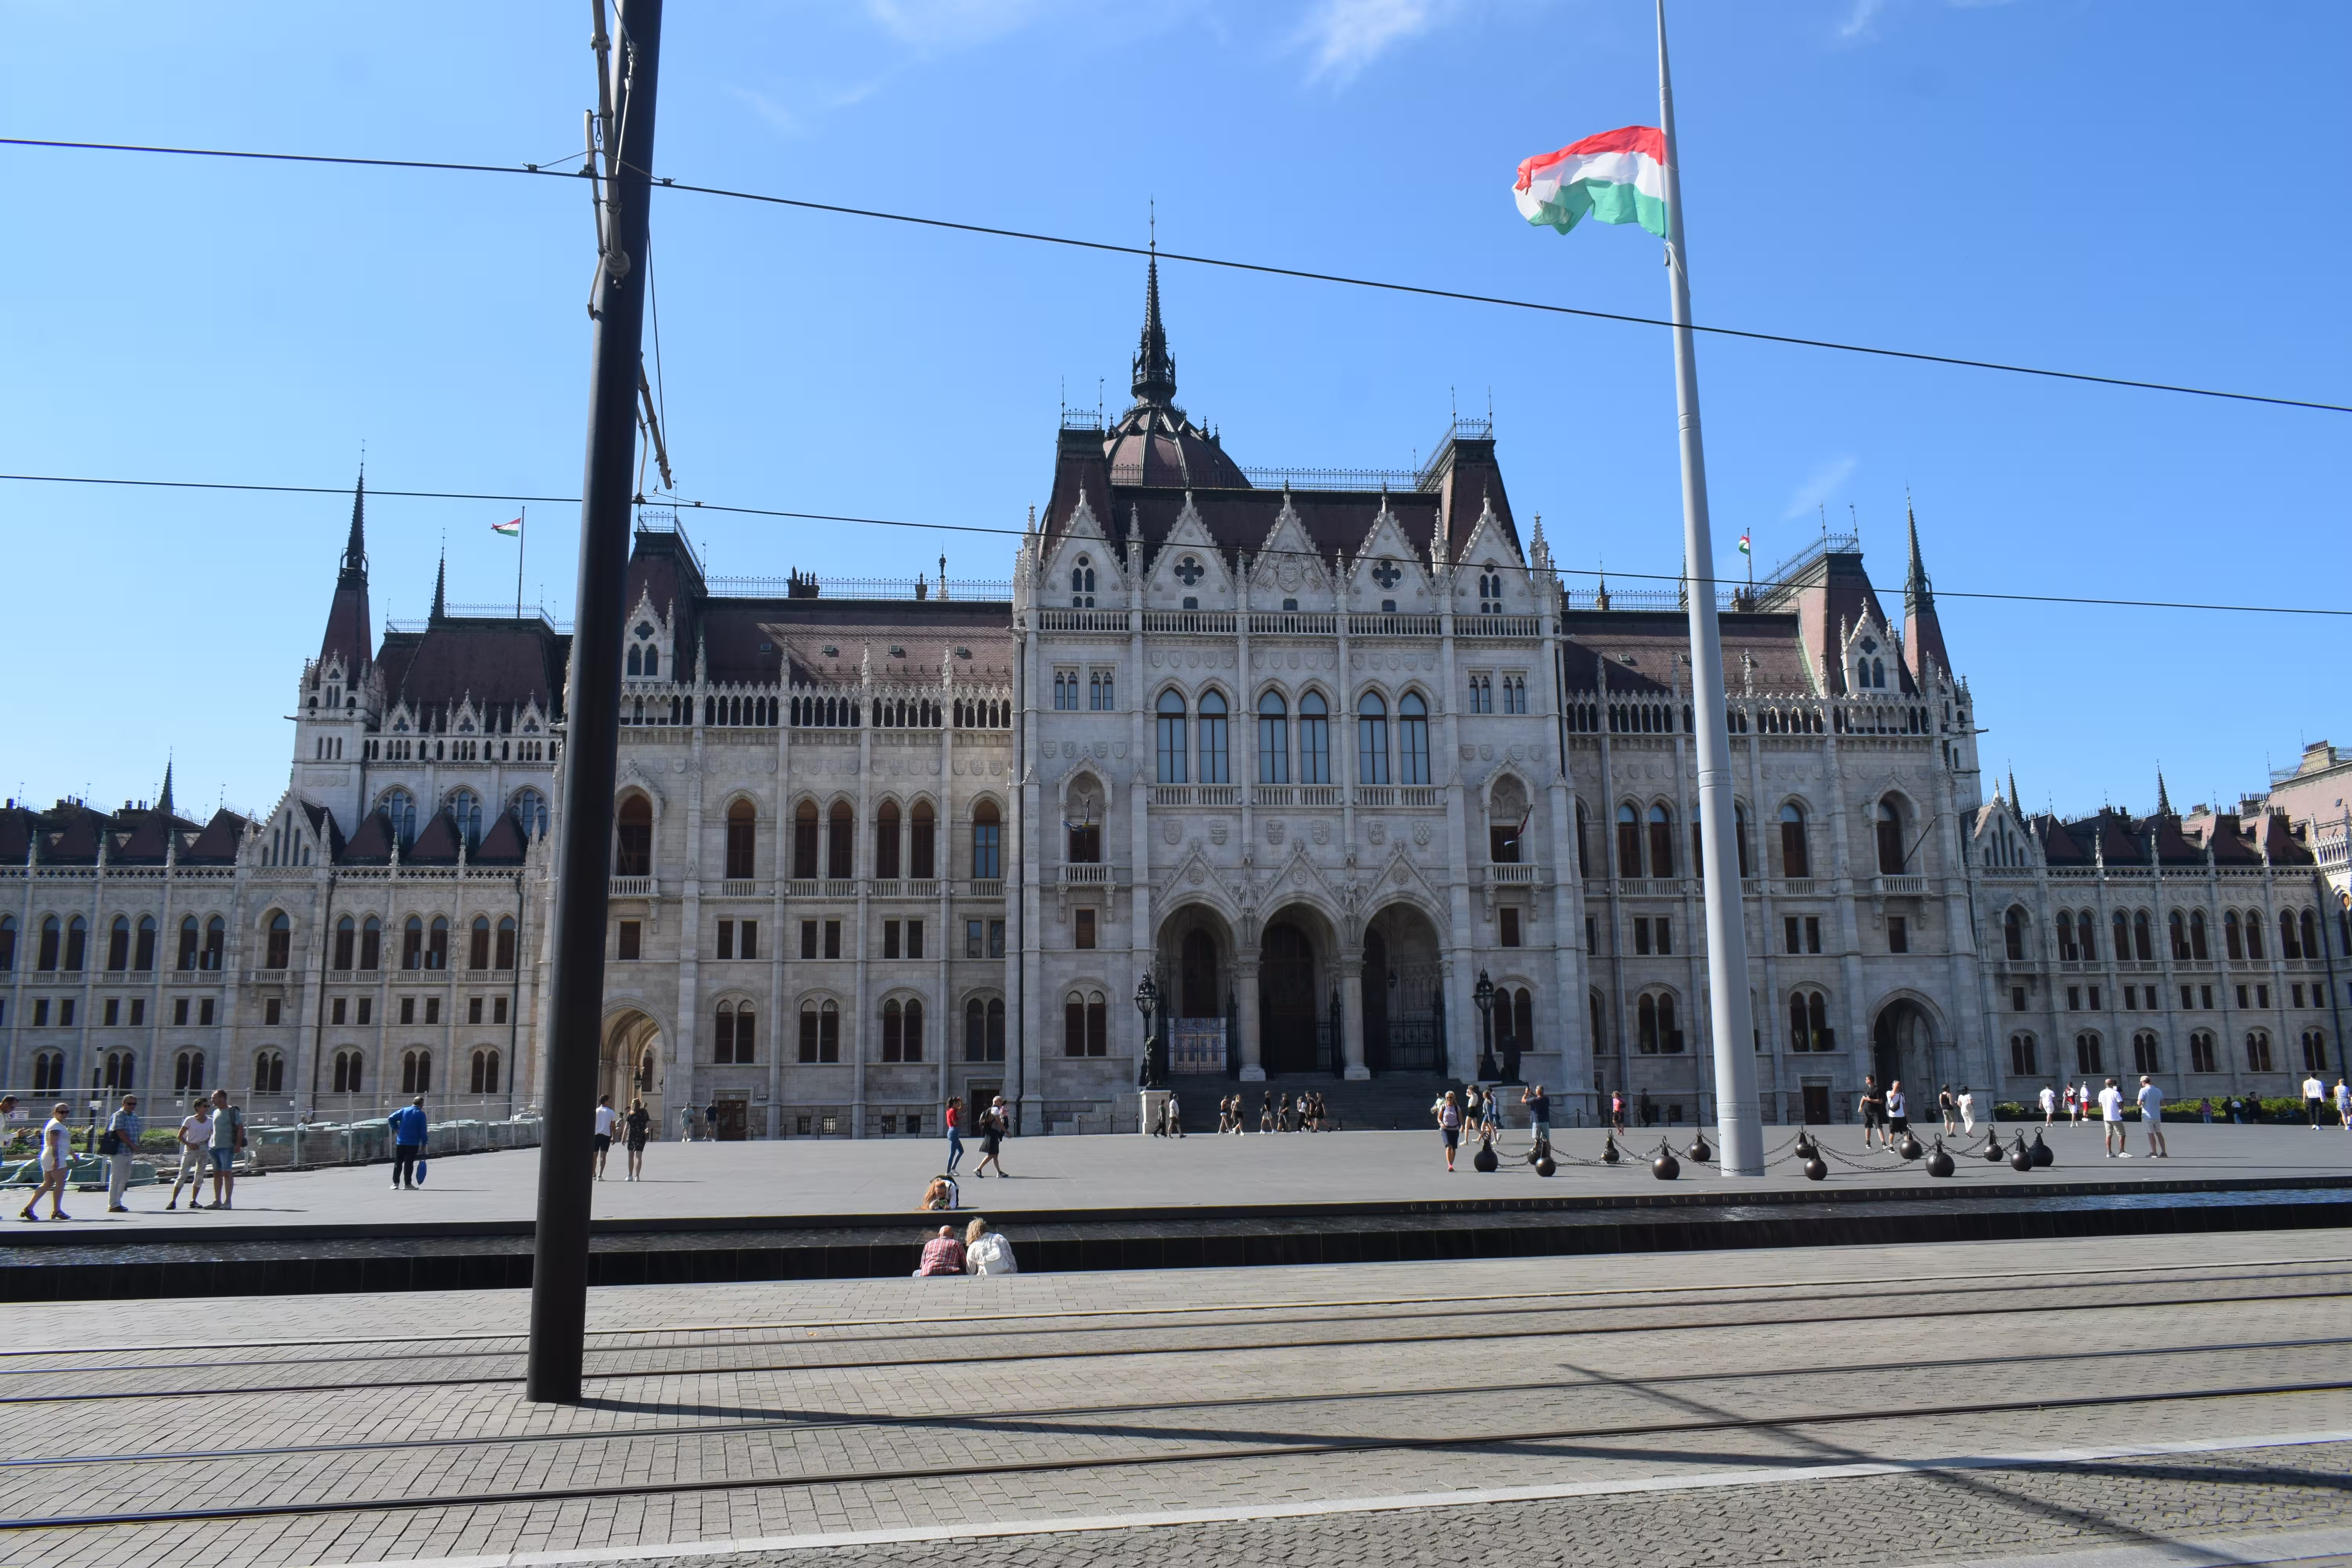 Hungarian Parliament building.
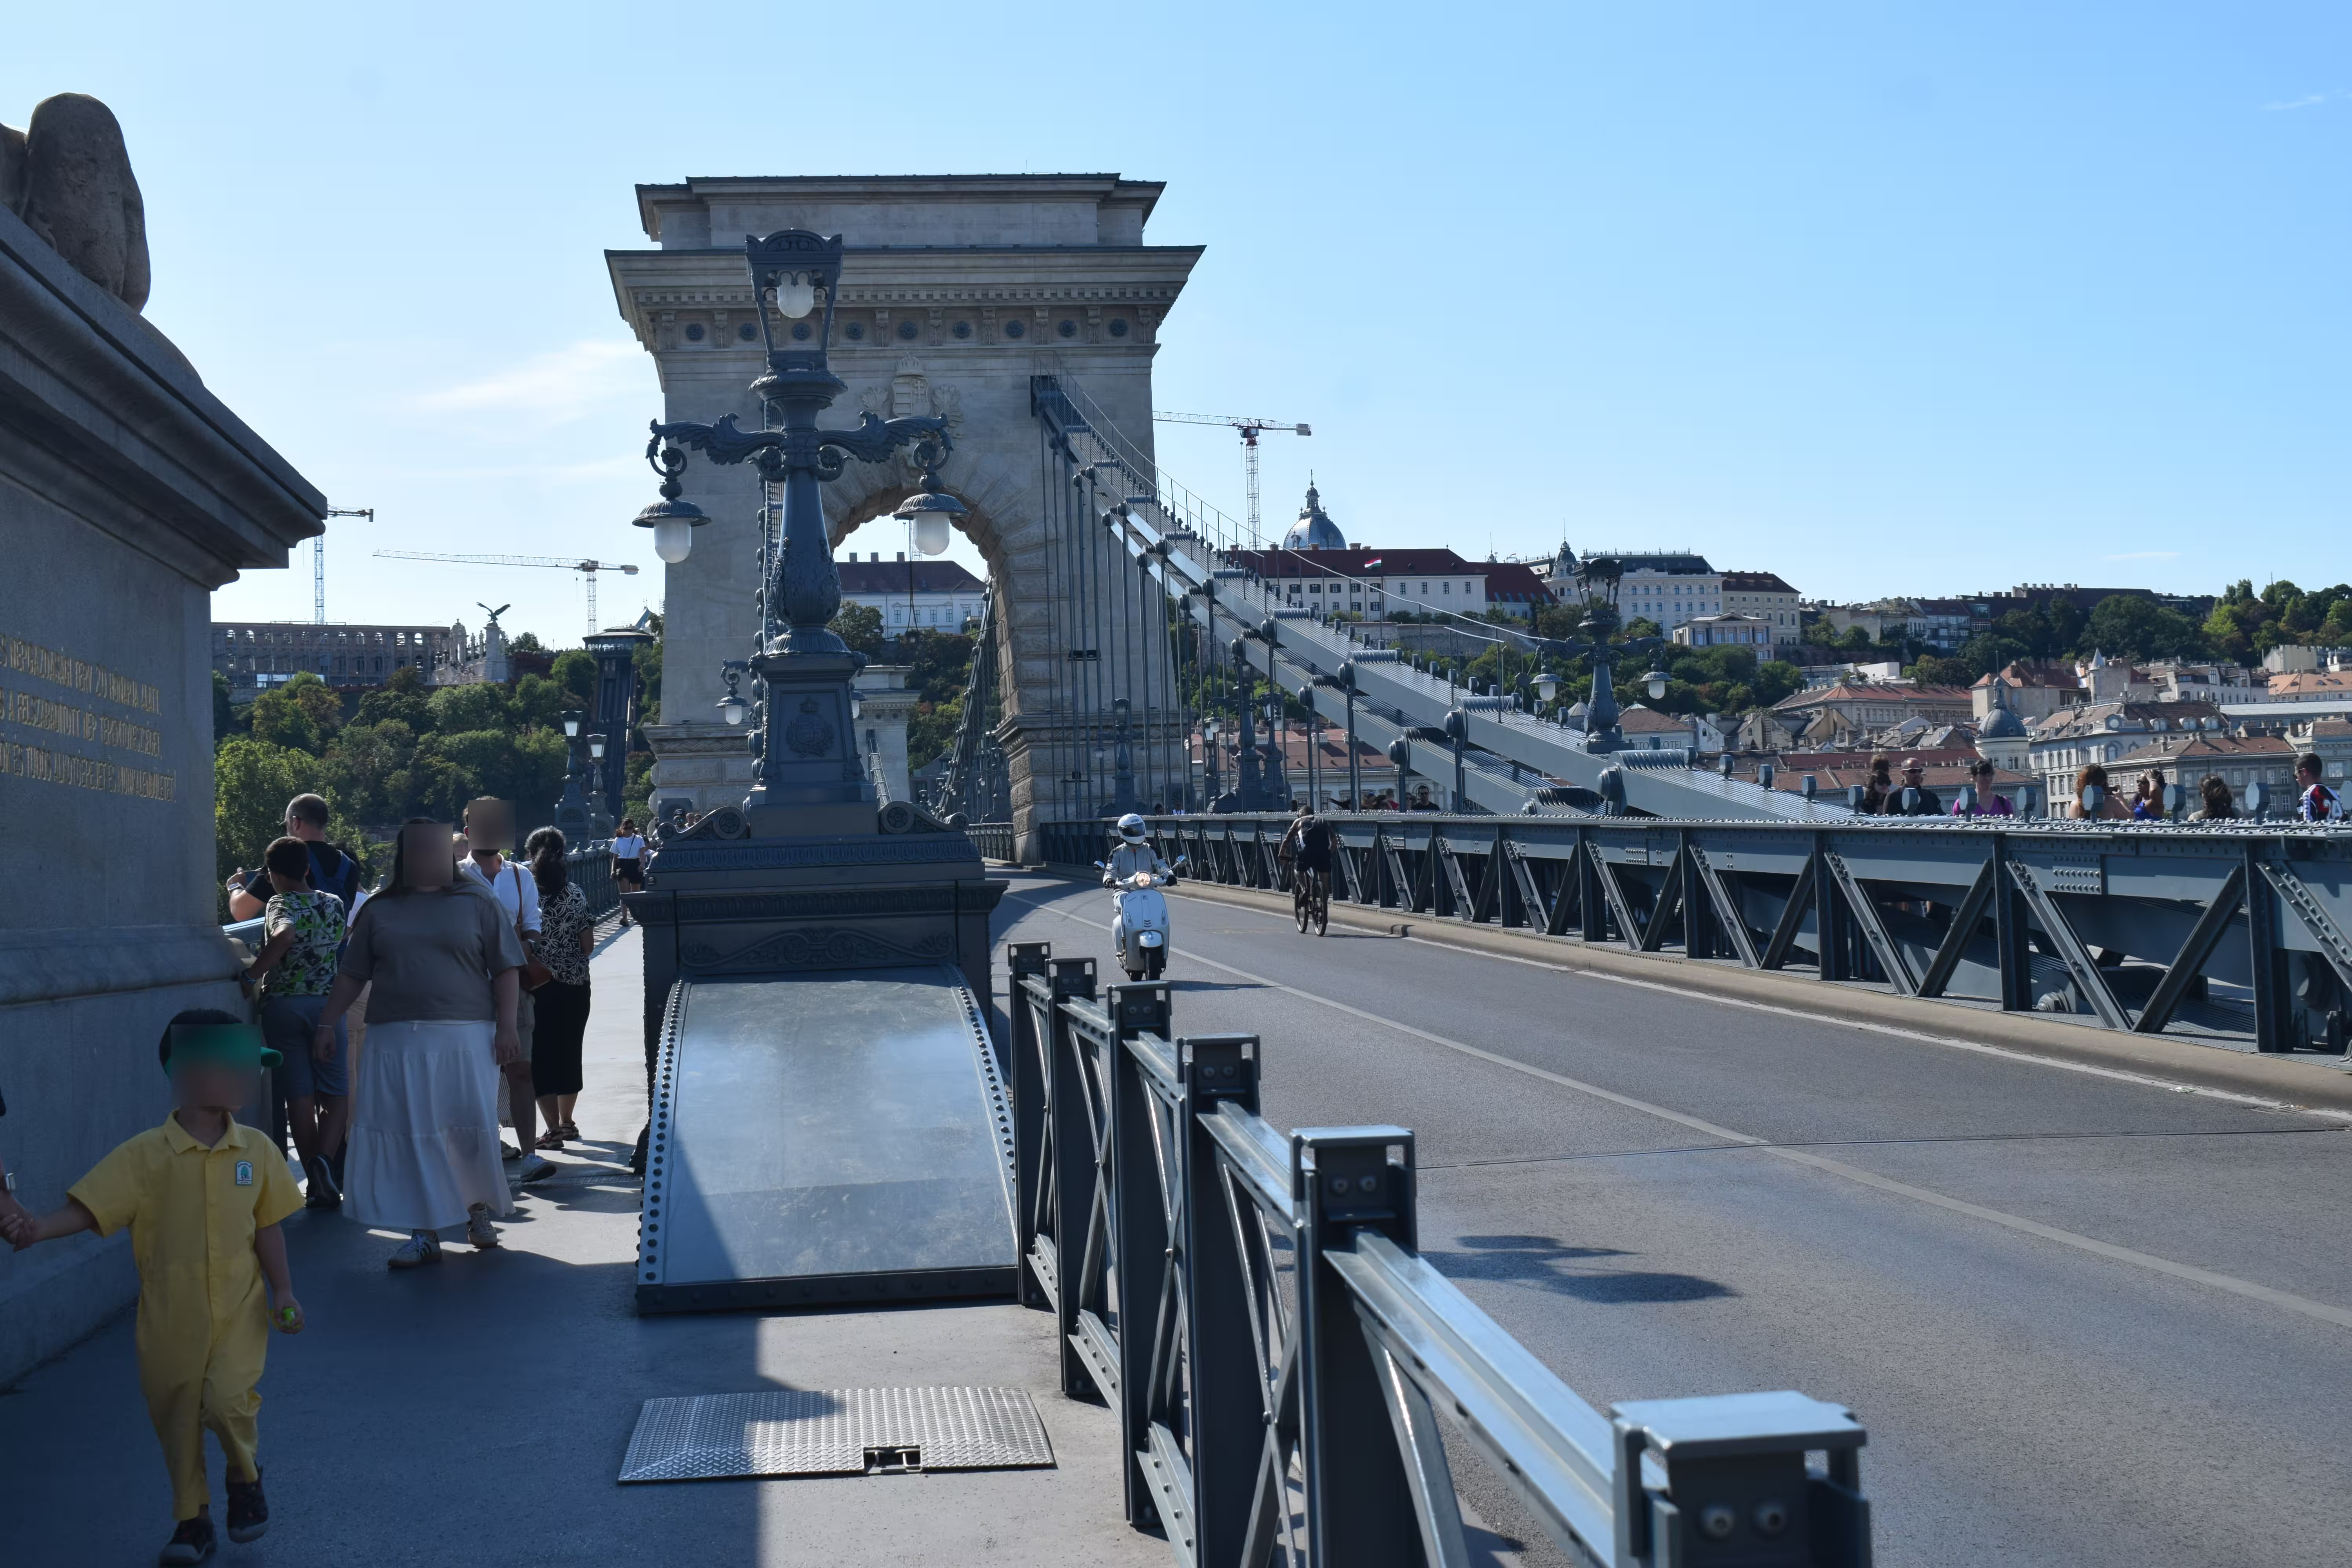 A shot of Chain Bridge.
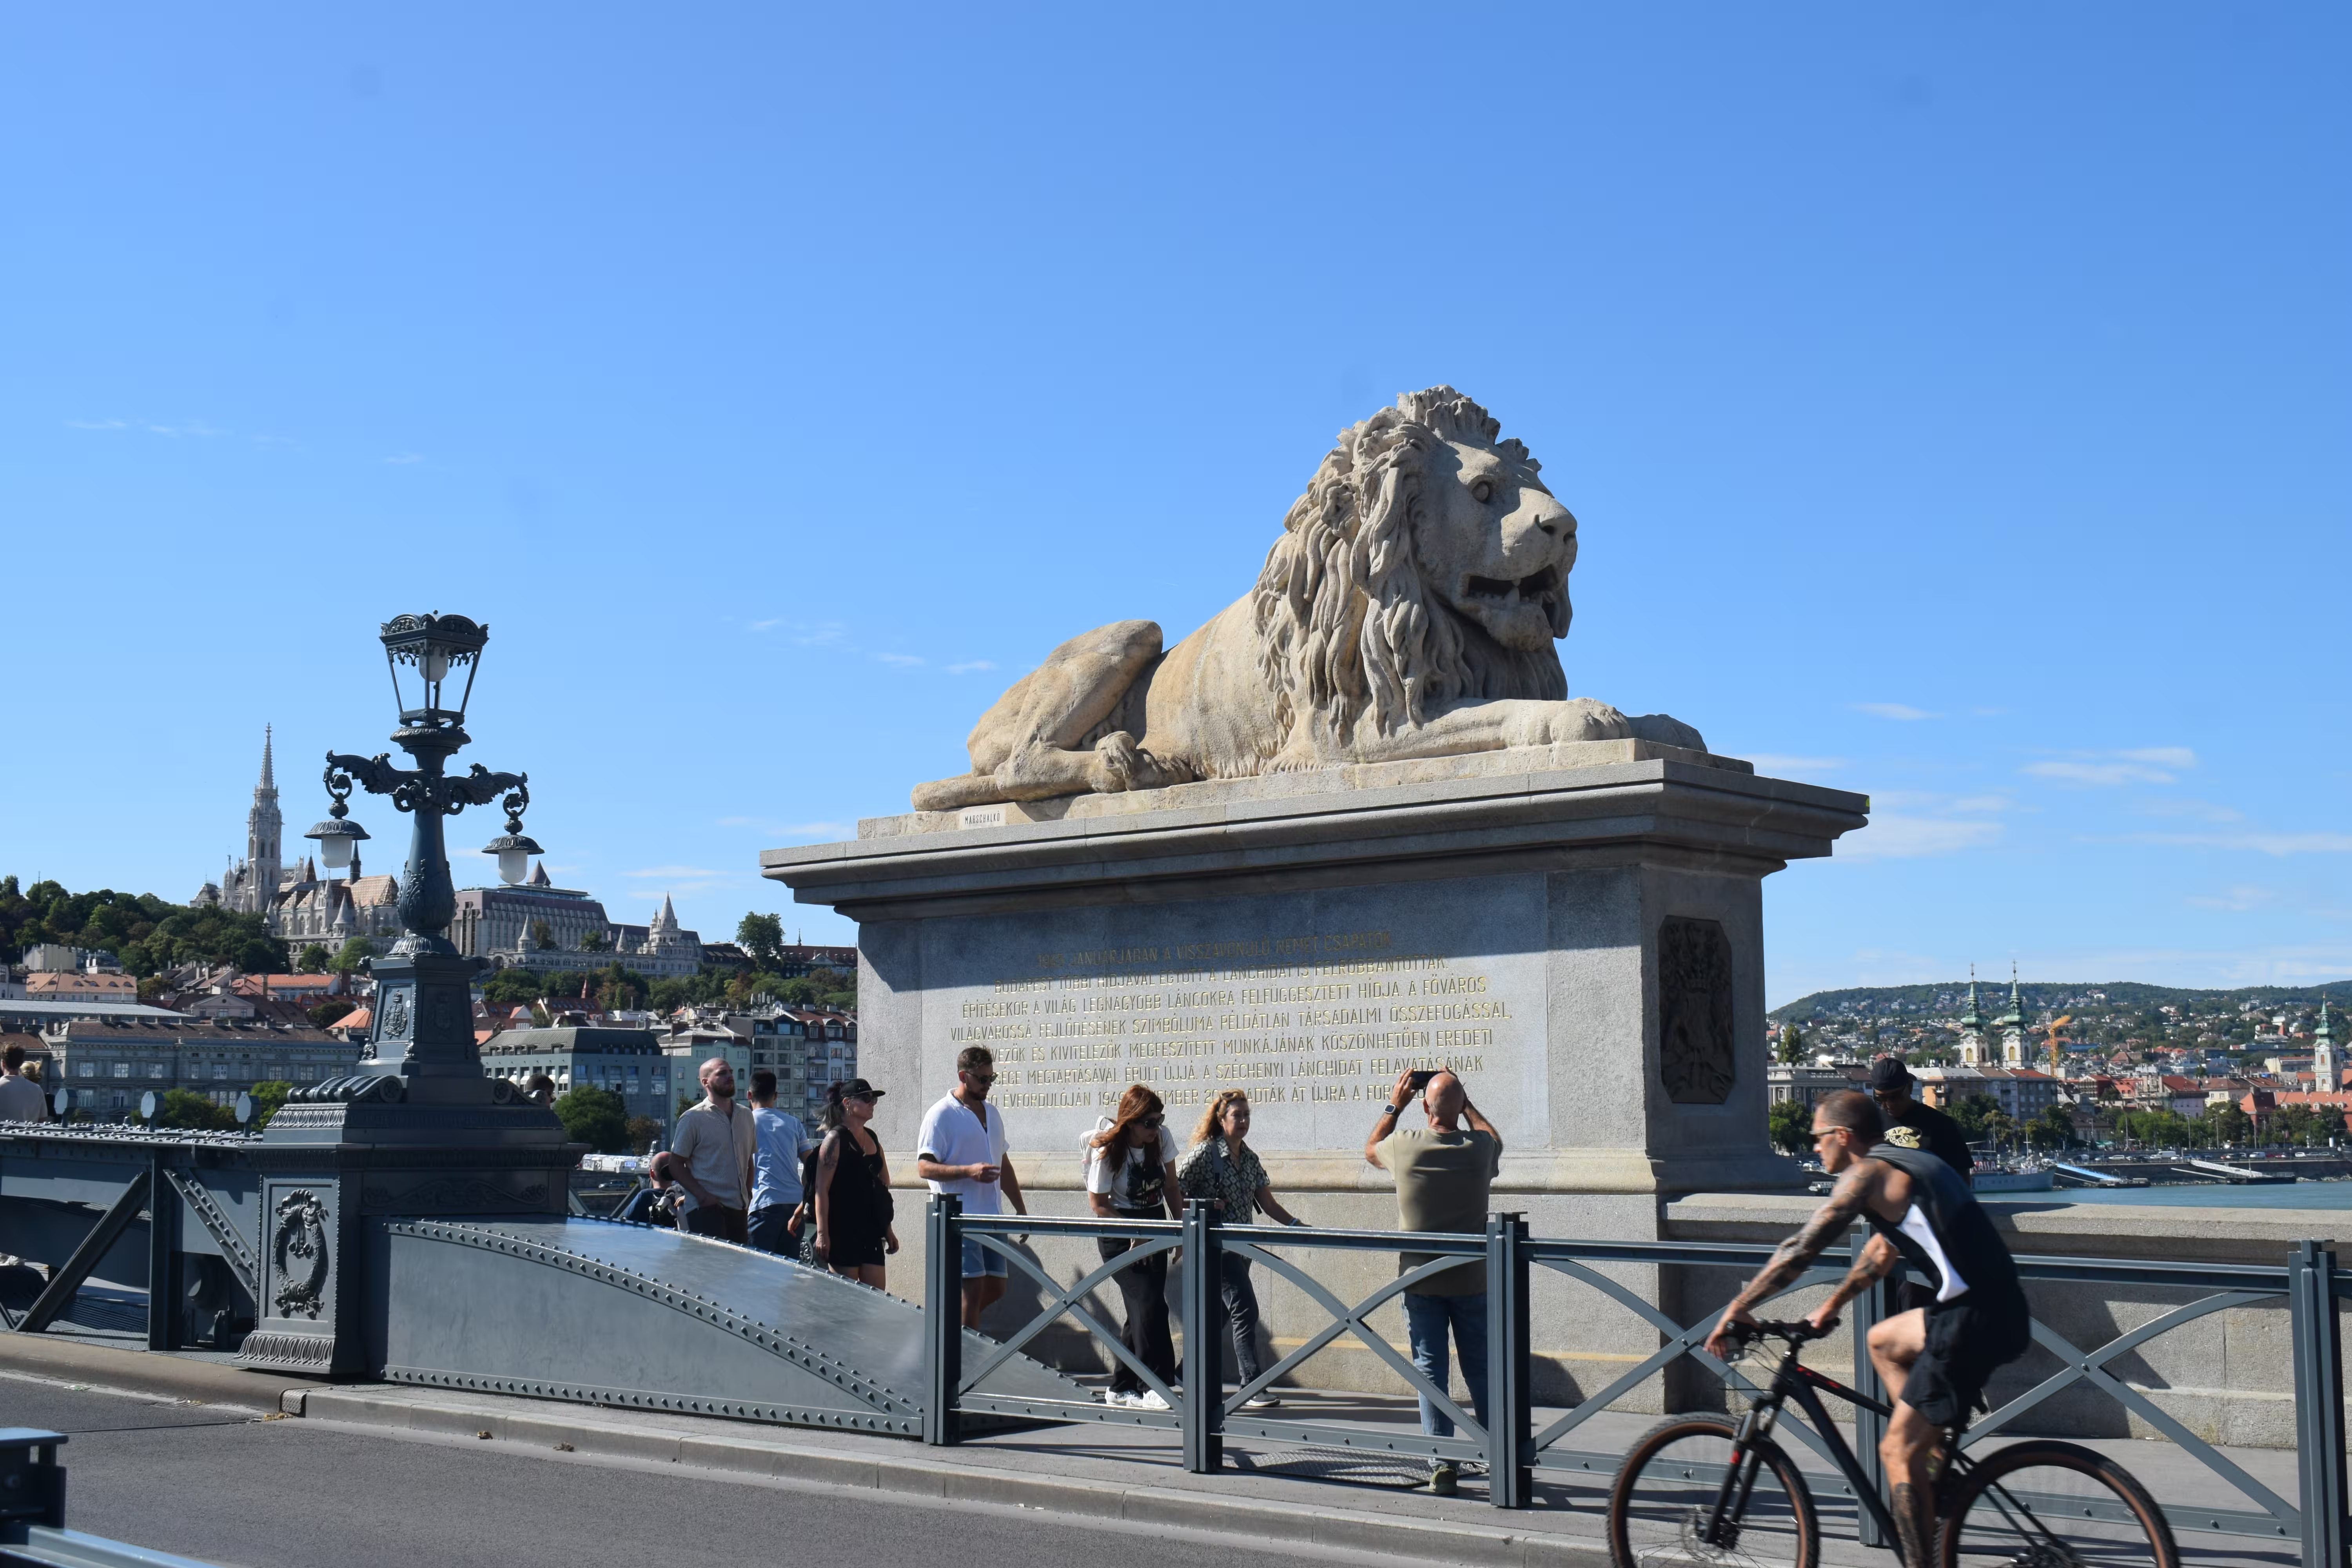 The lion statue on the Chain Bridge.
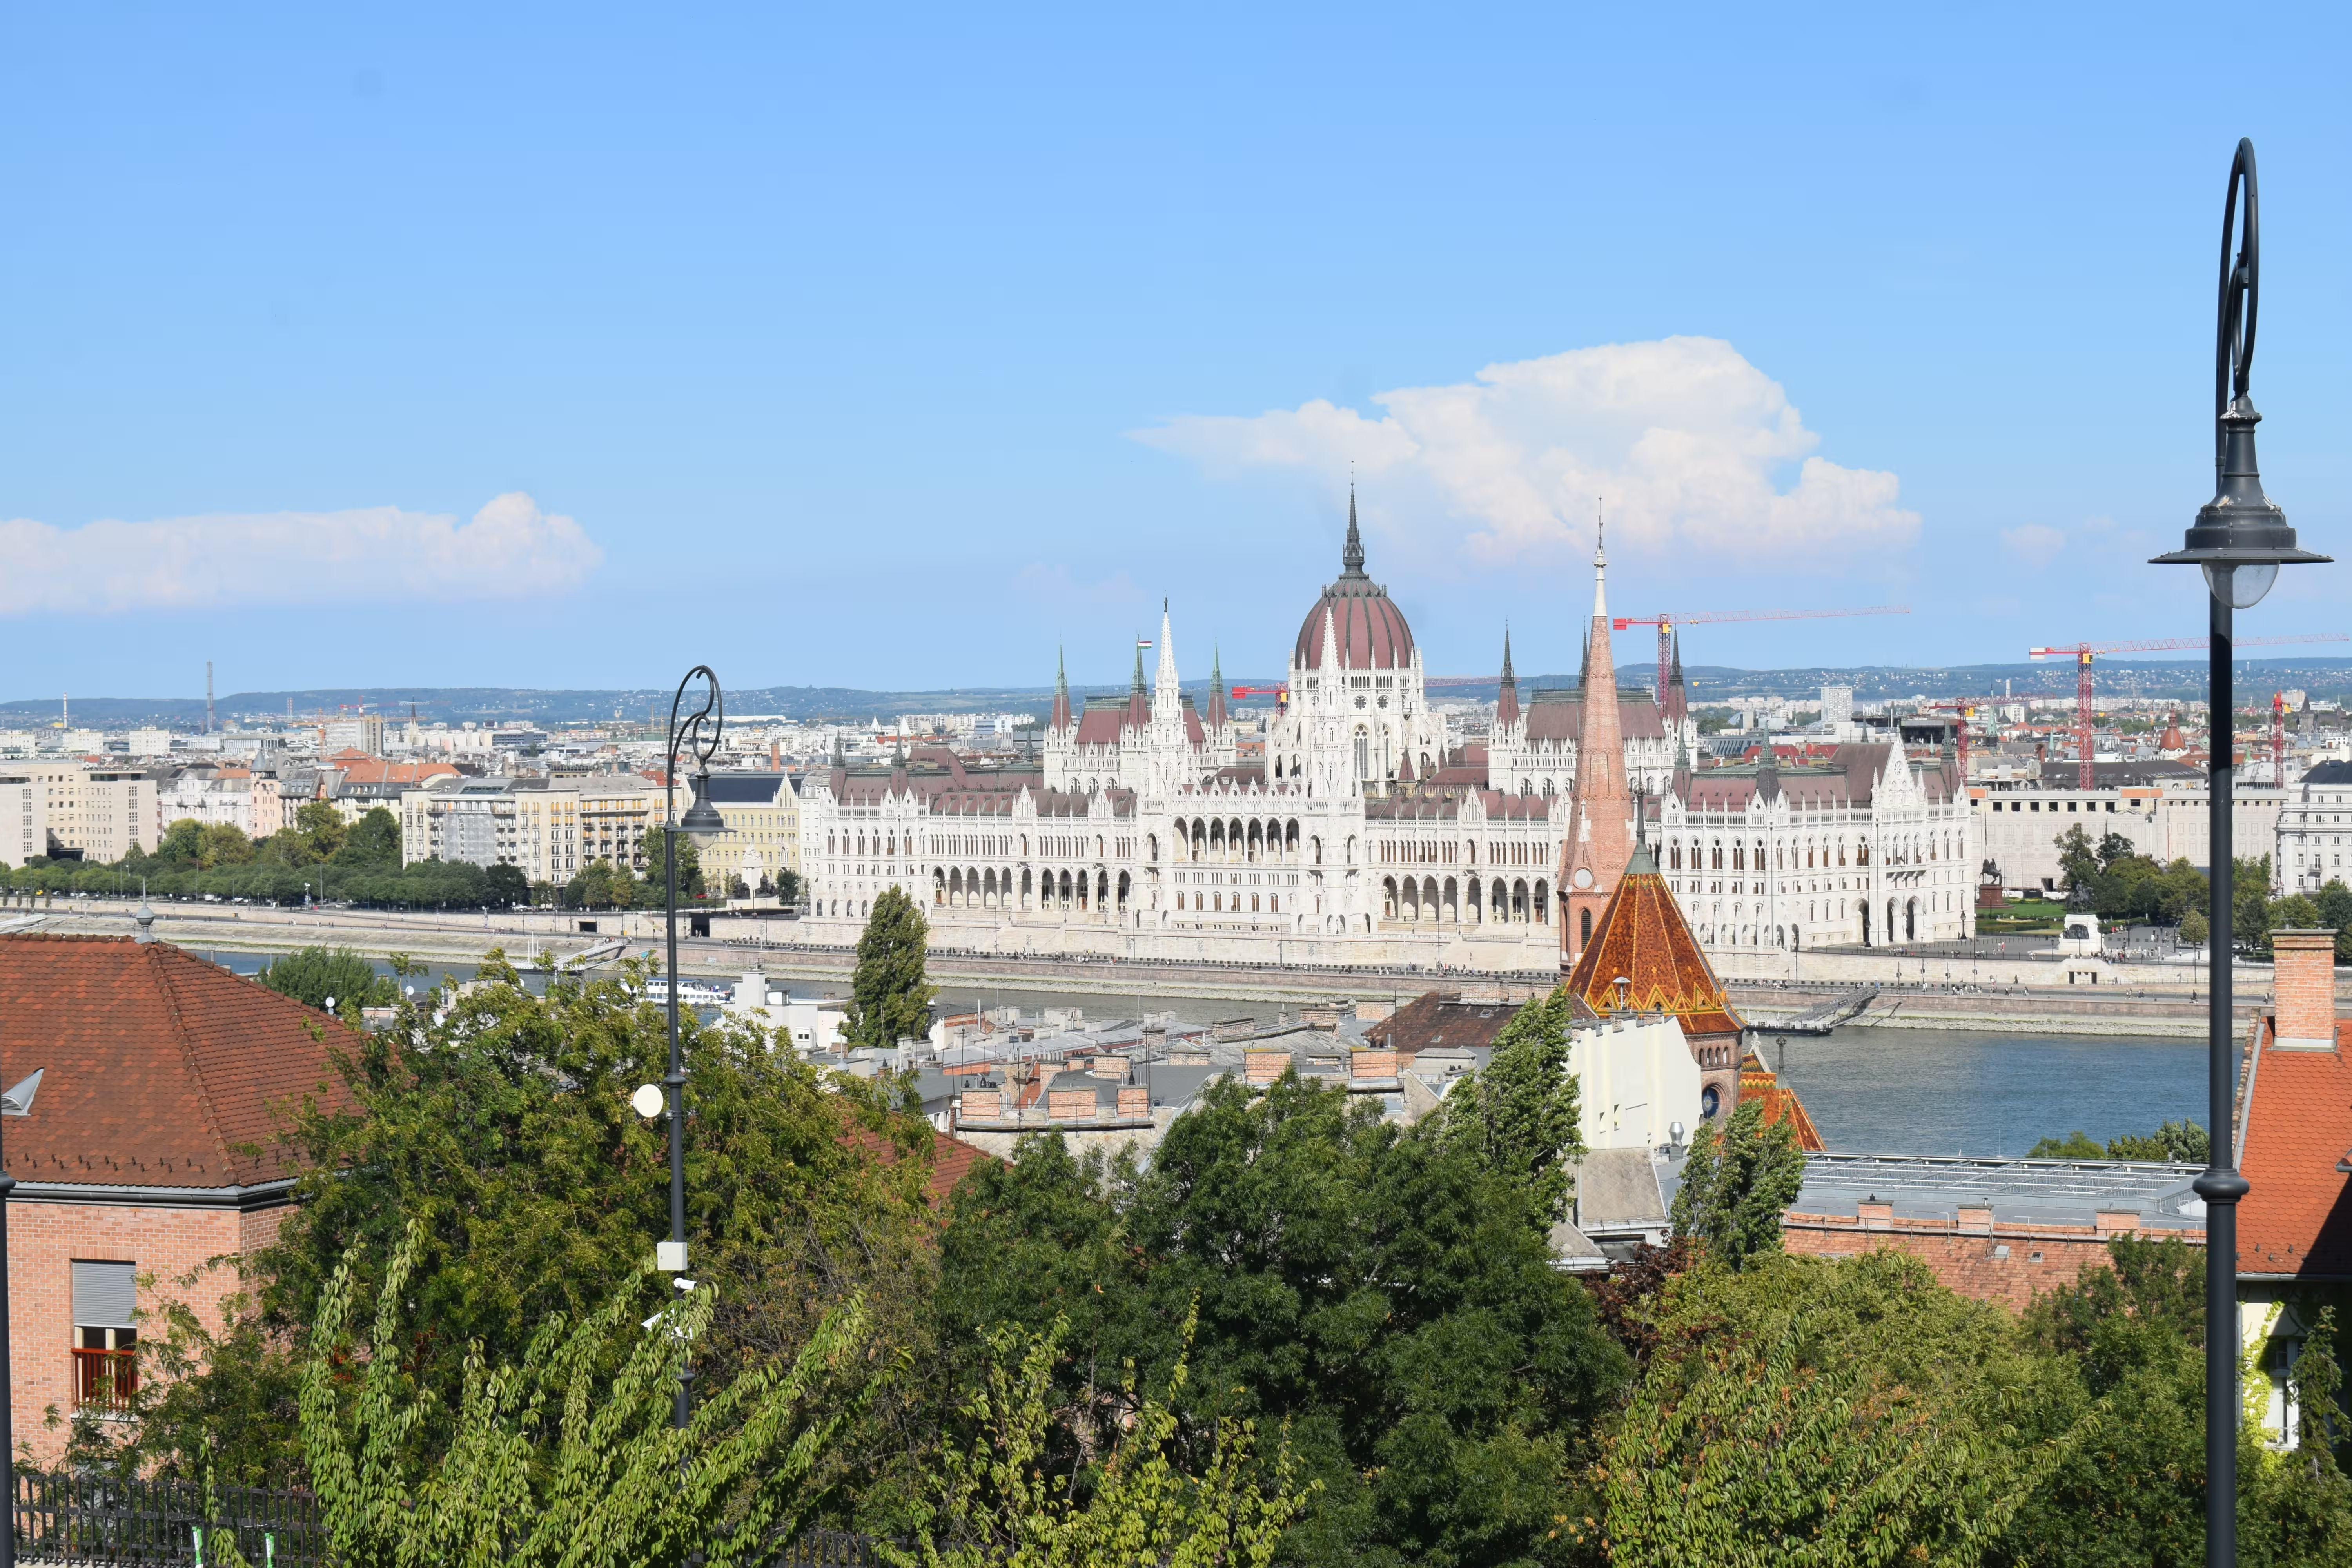 A view of Hungarian parliament from Fisherman s bastion.
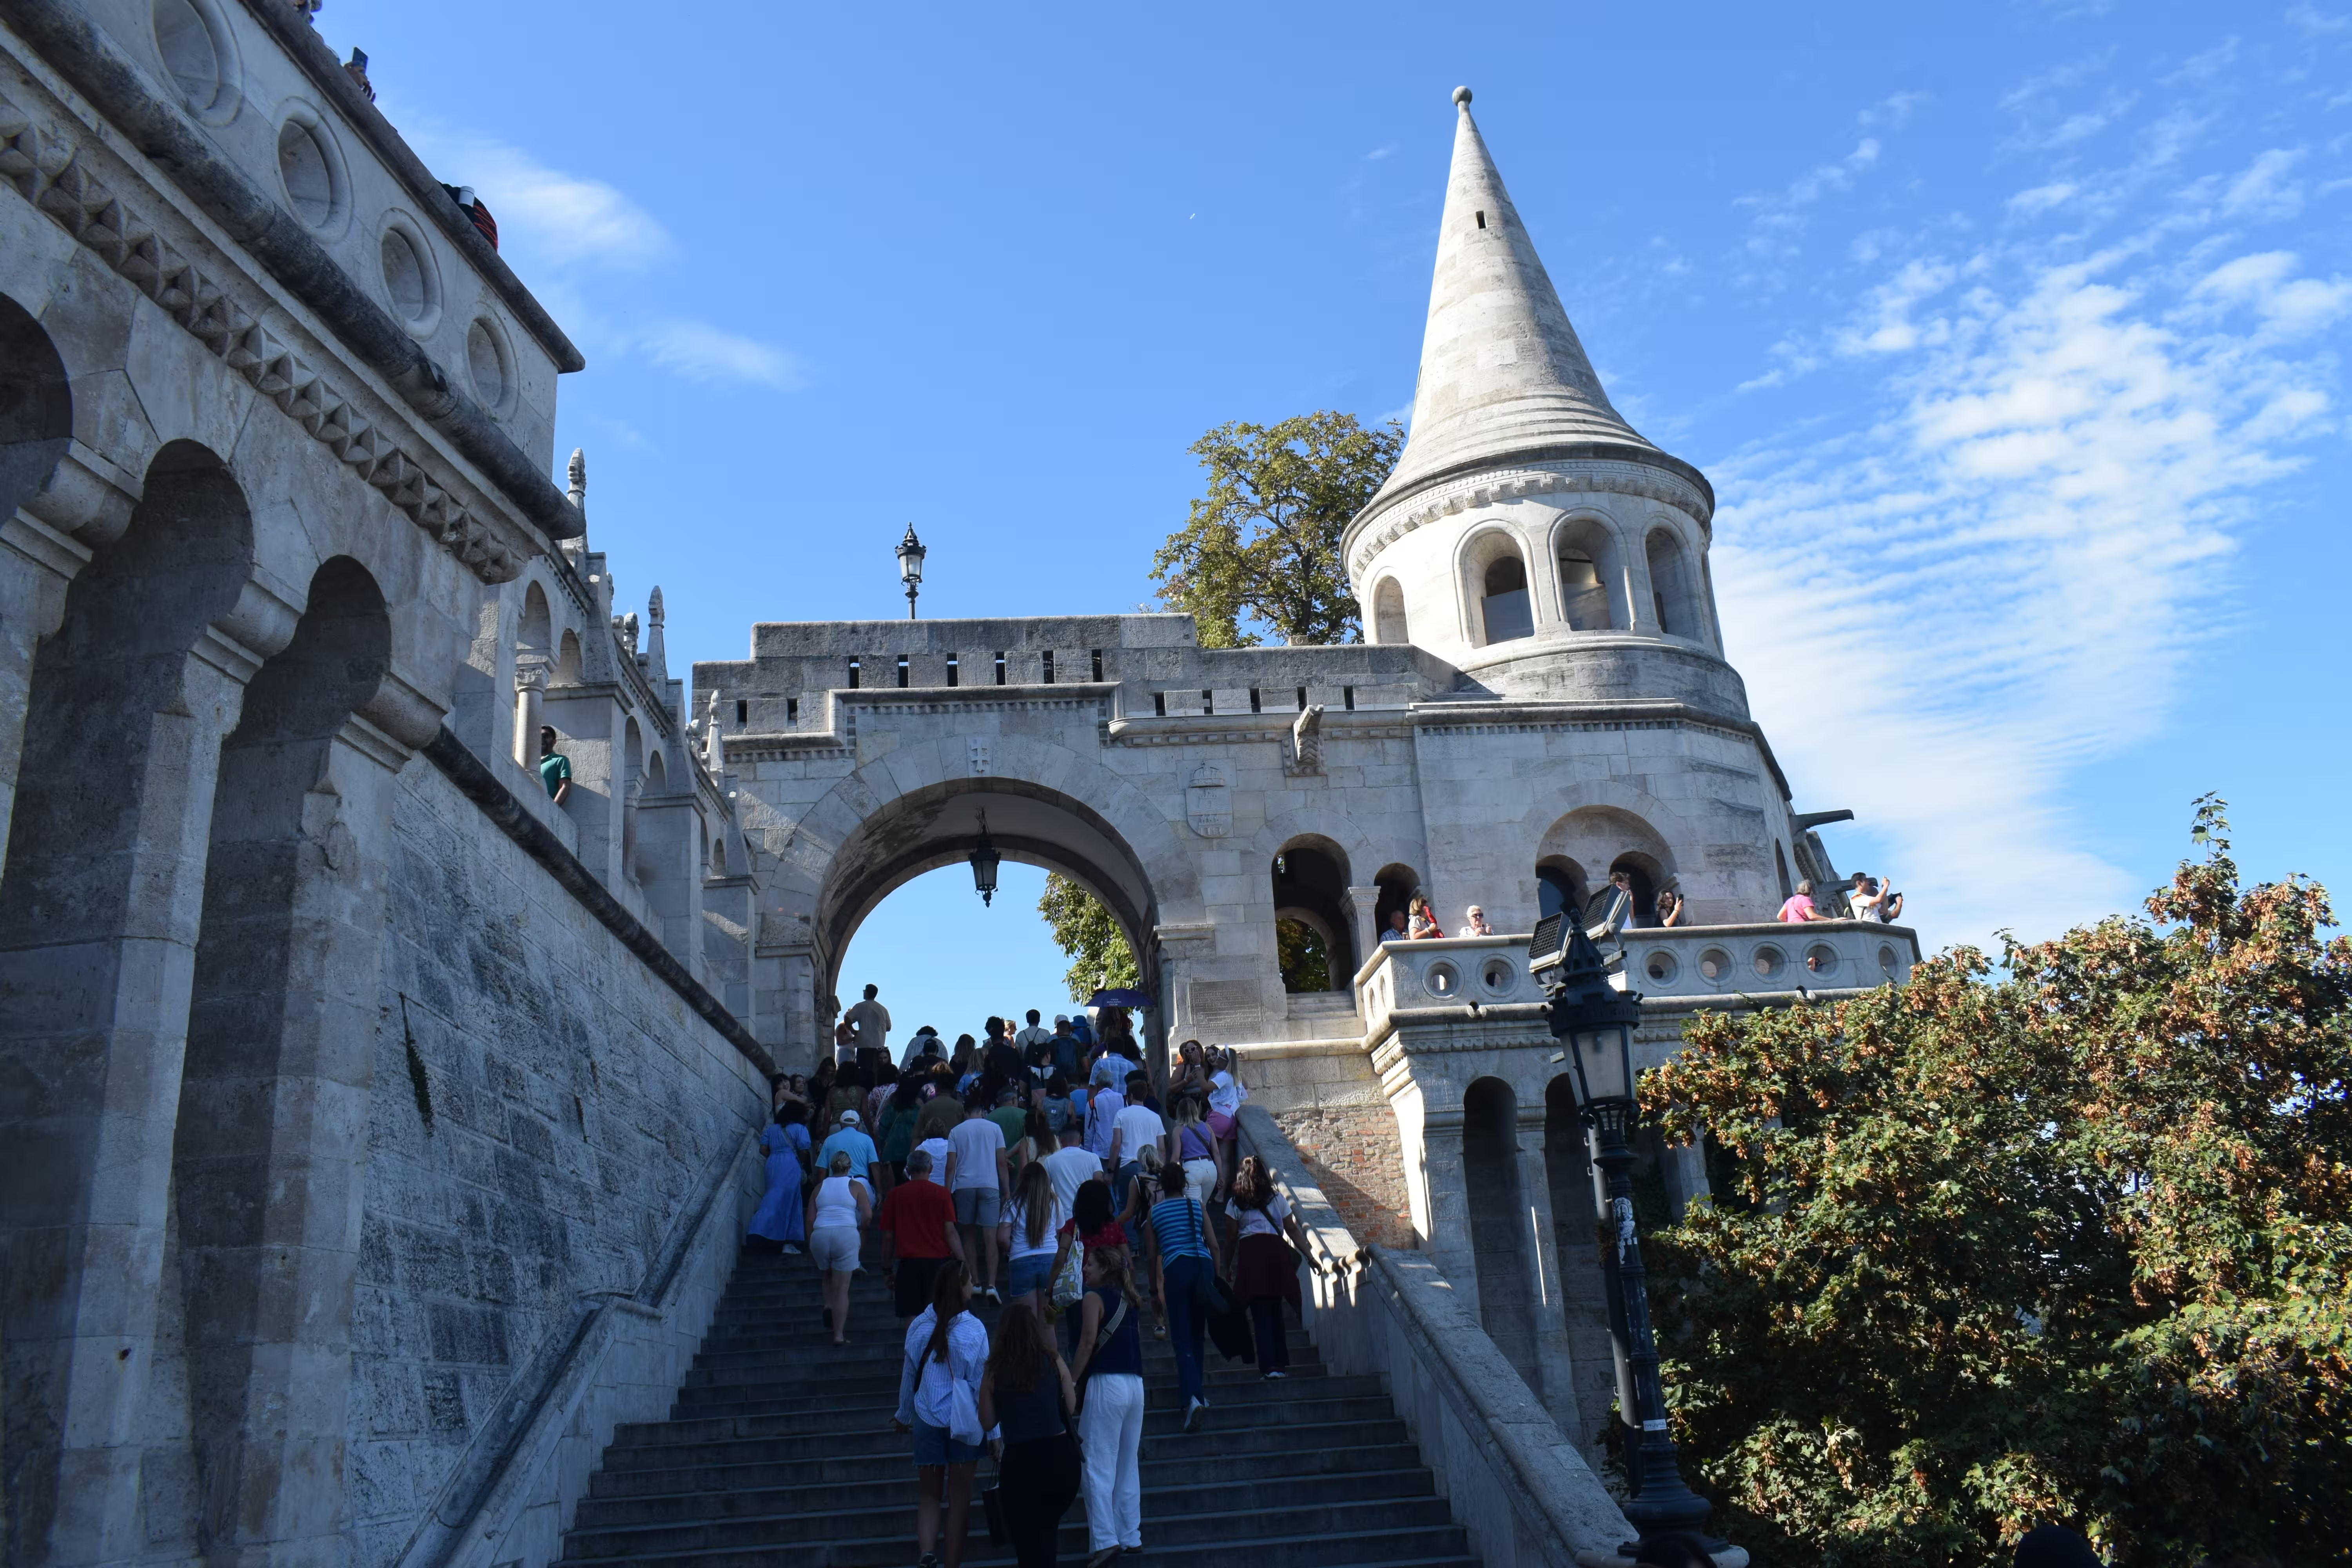 Fisherman s Bastion.
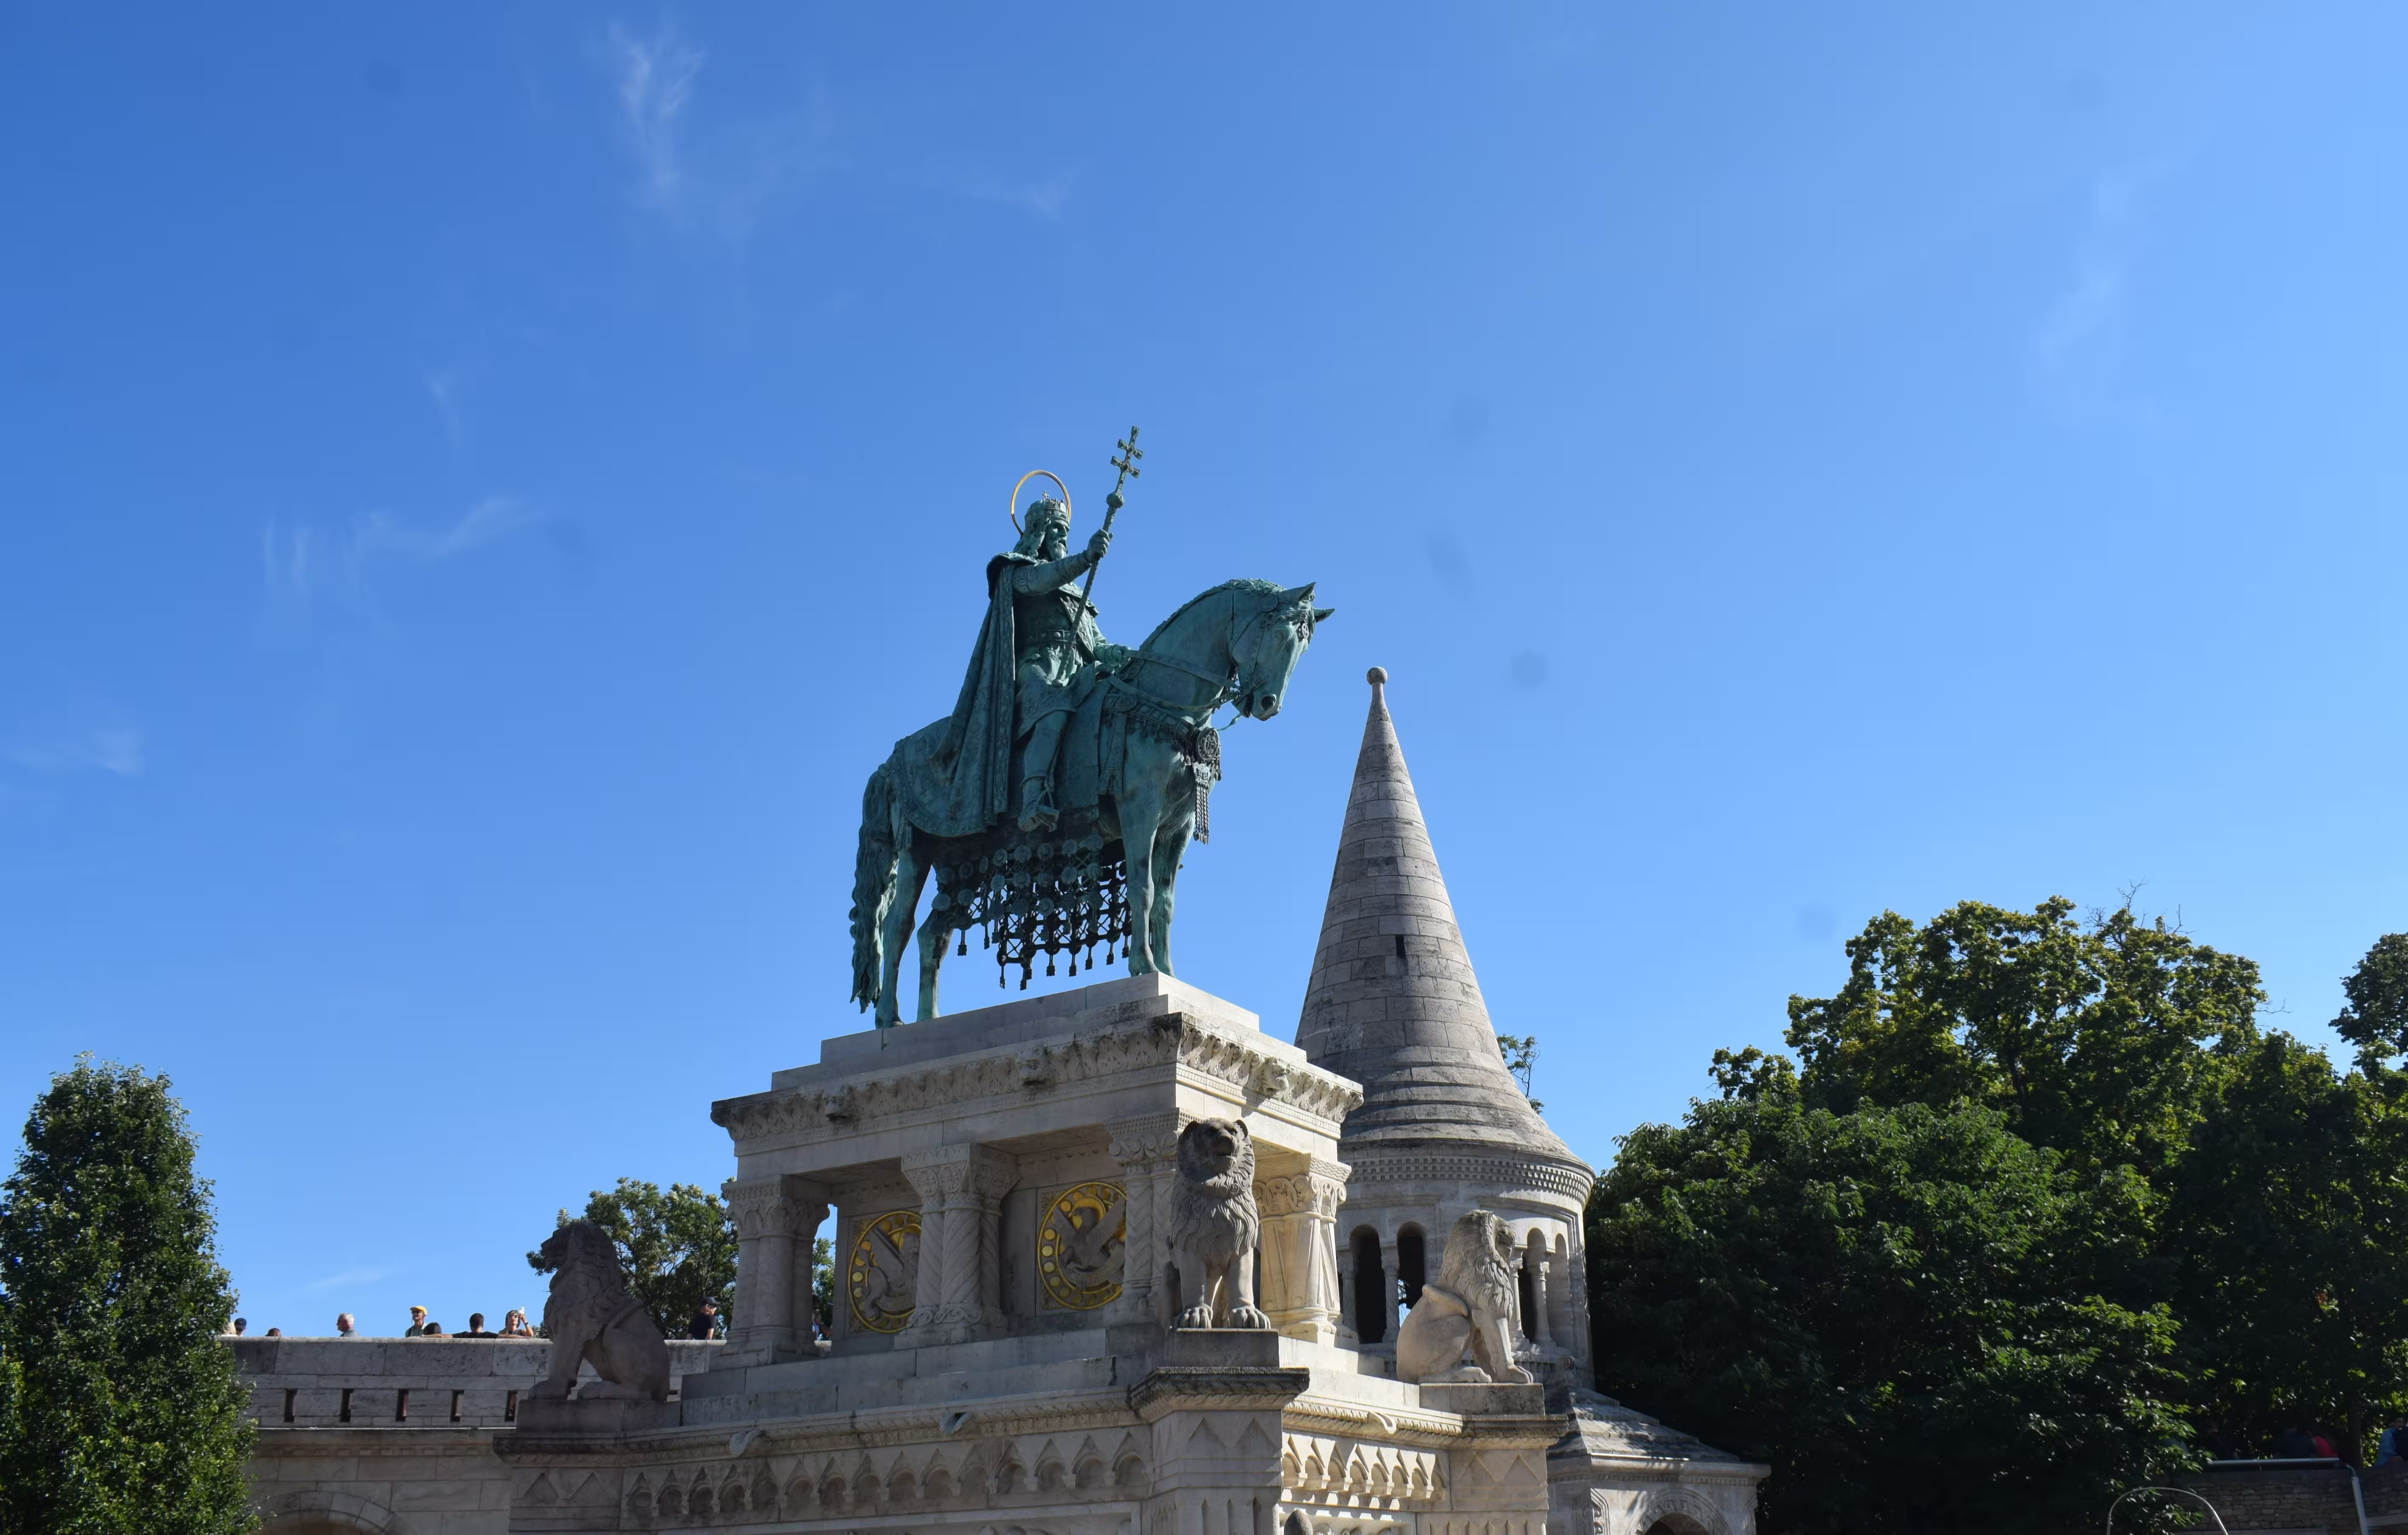 Statue of Stephen I of Hungary at Fisherman s Bastion.
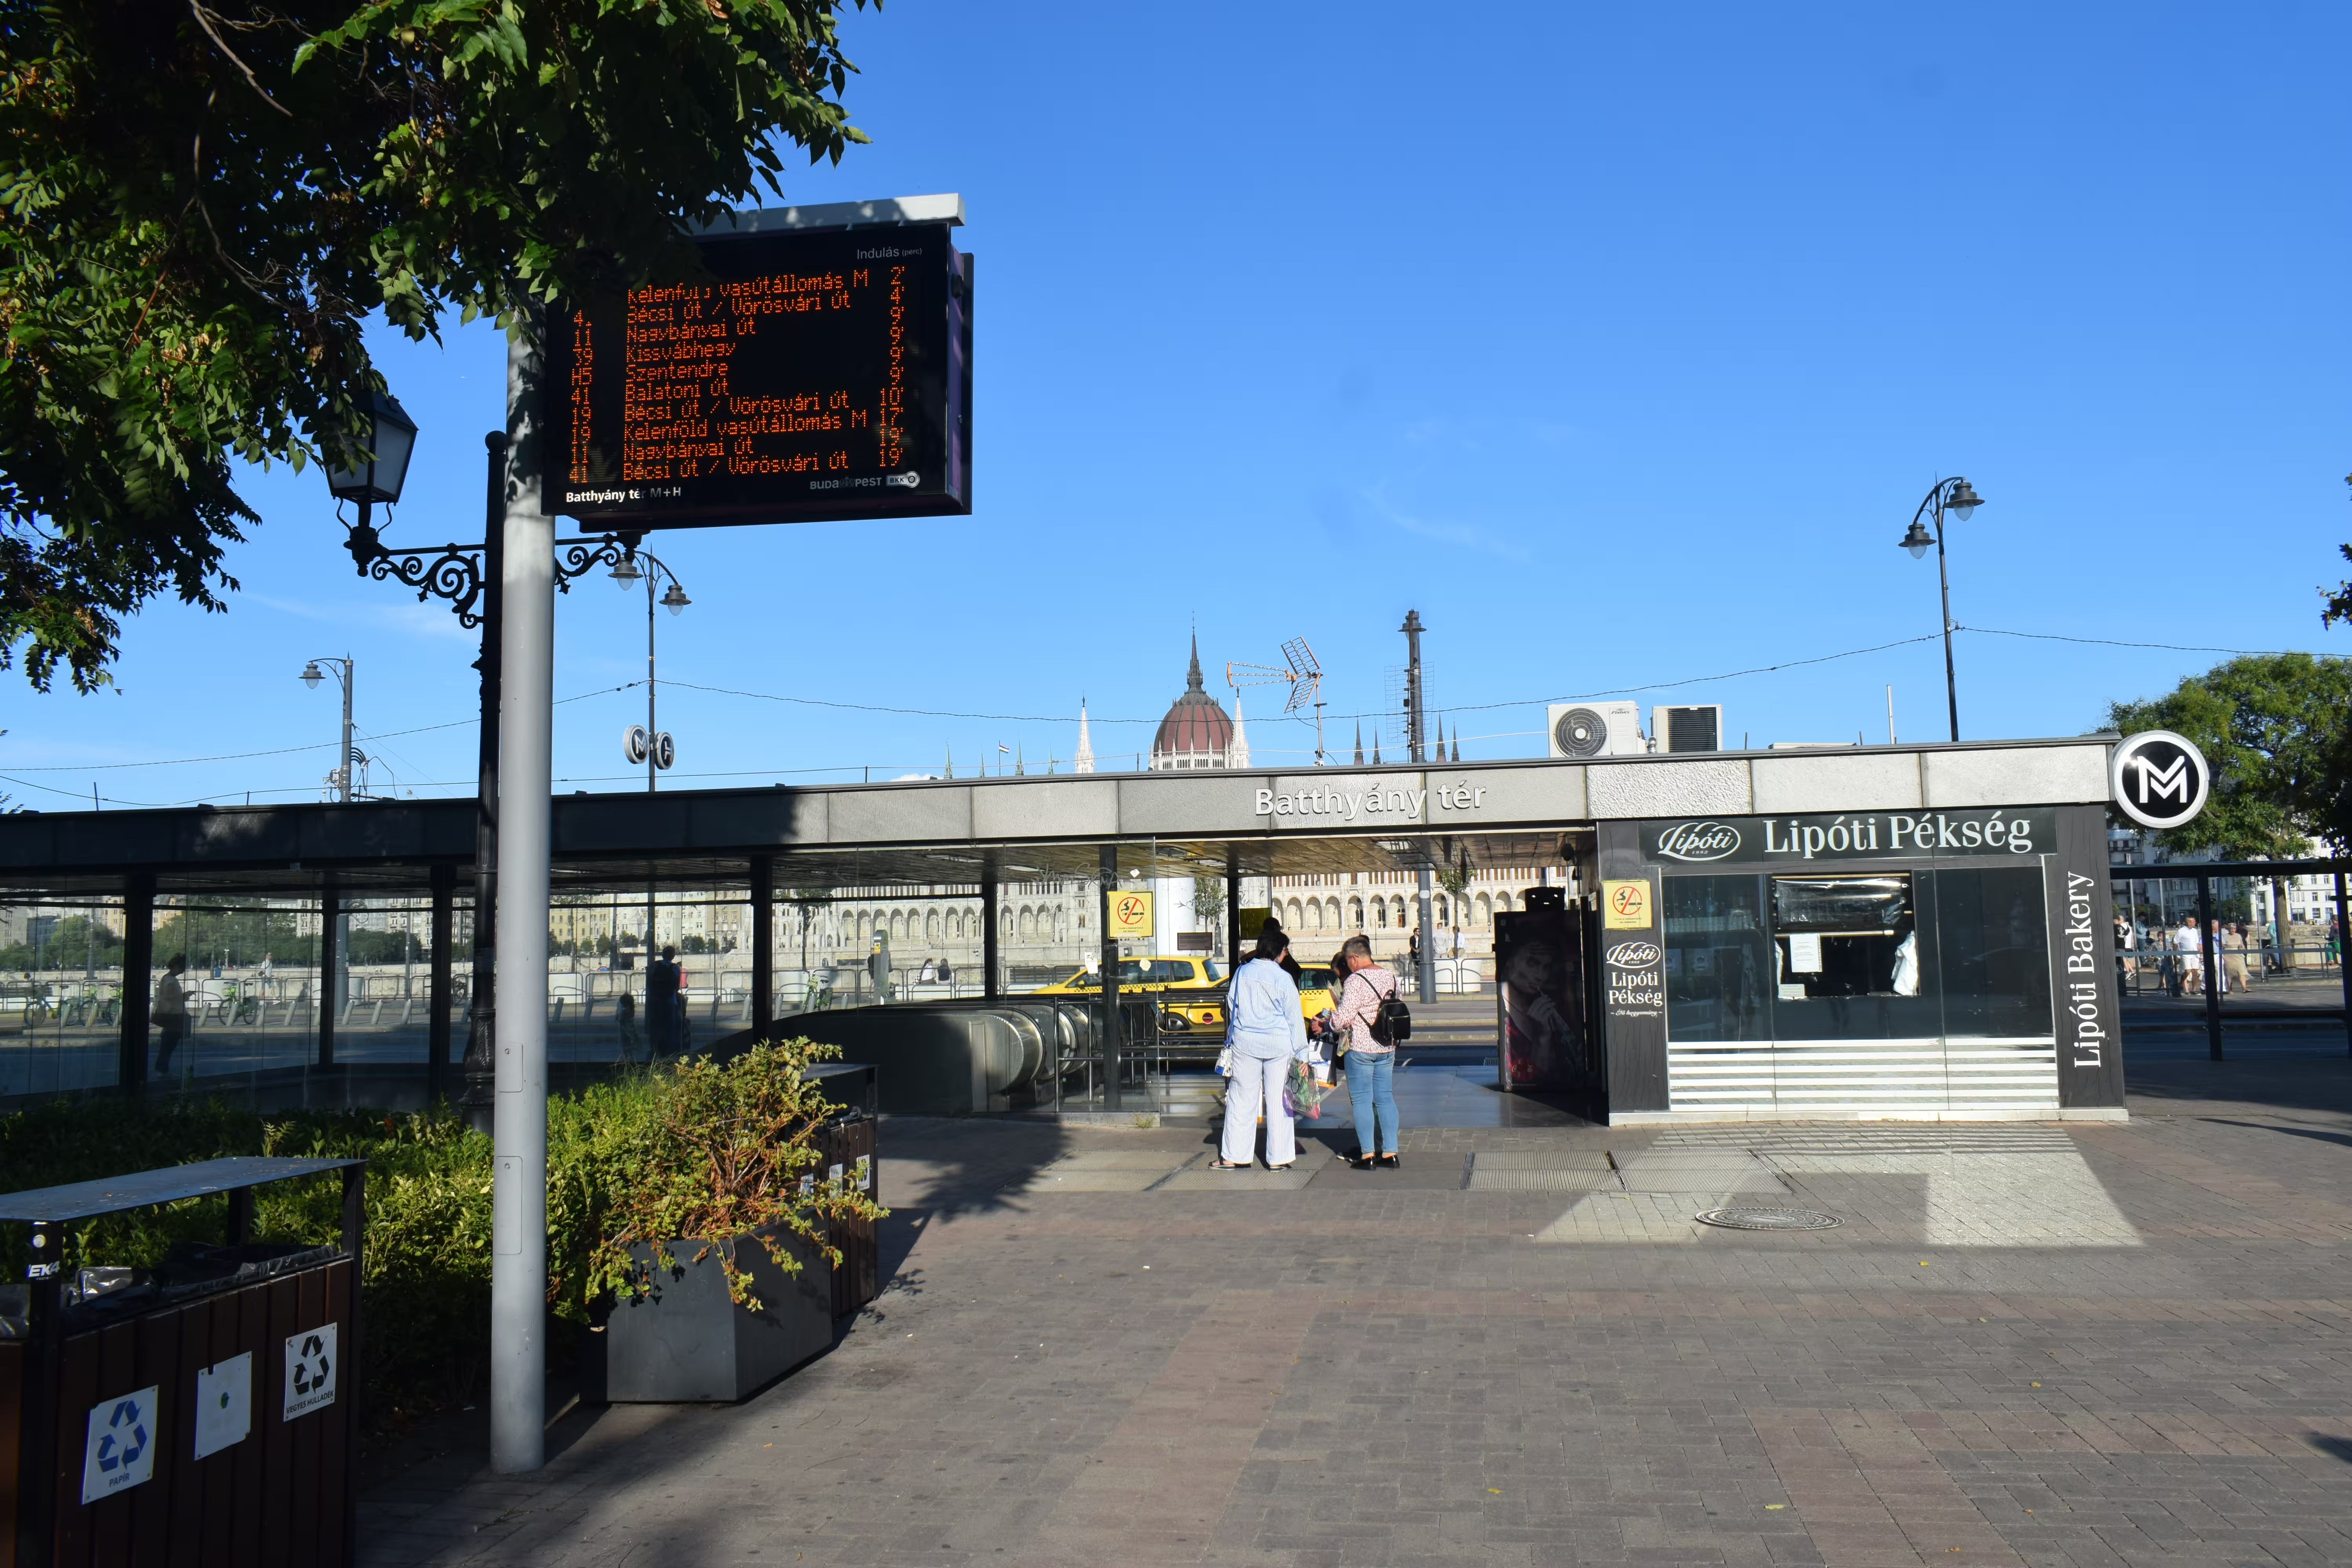 Batthy ny t r metro station.
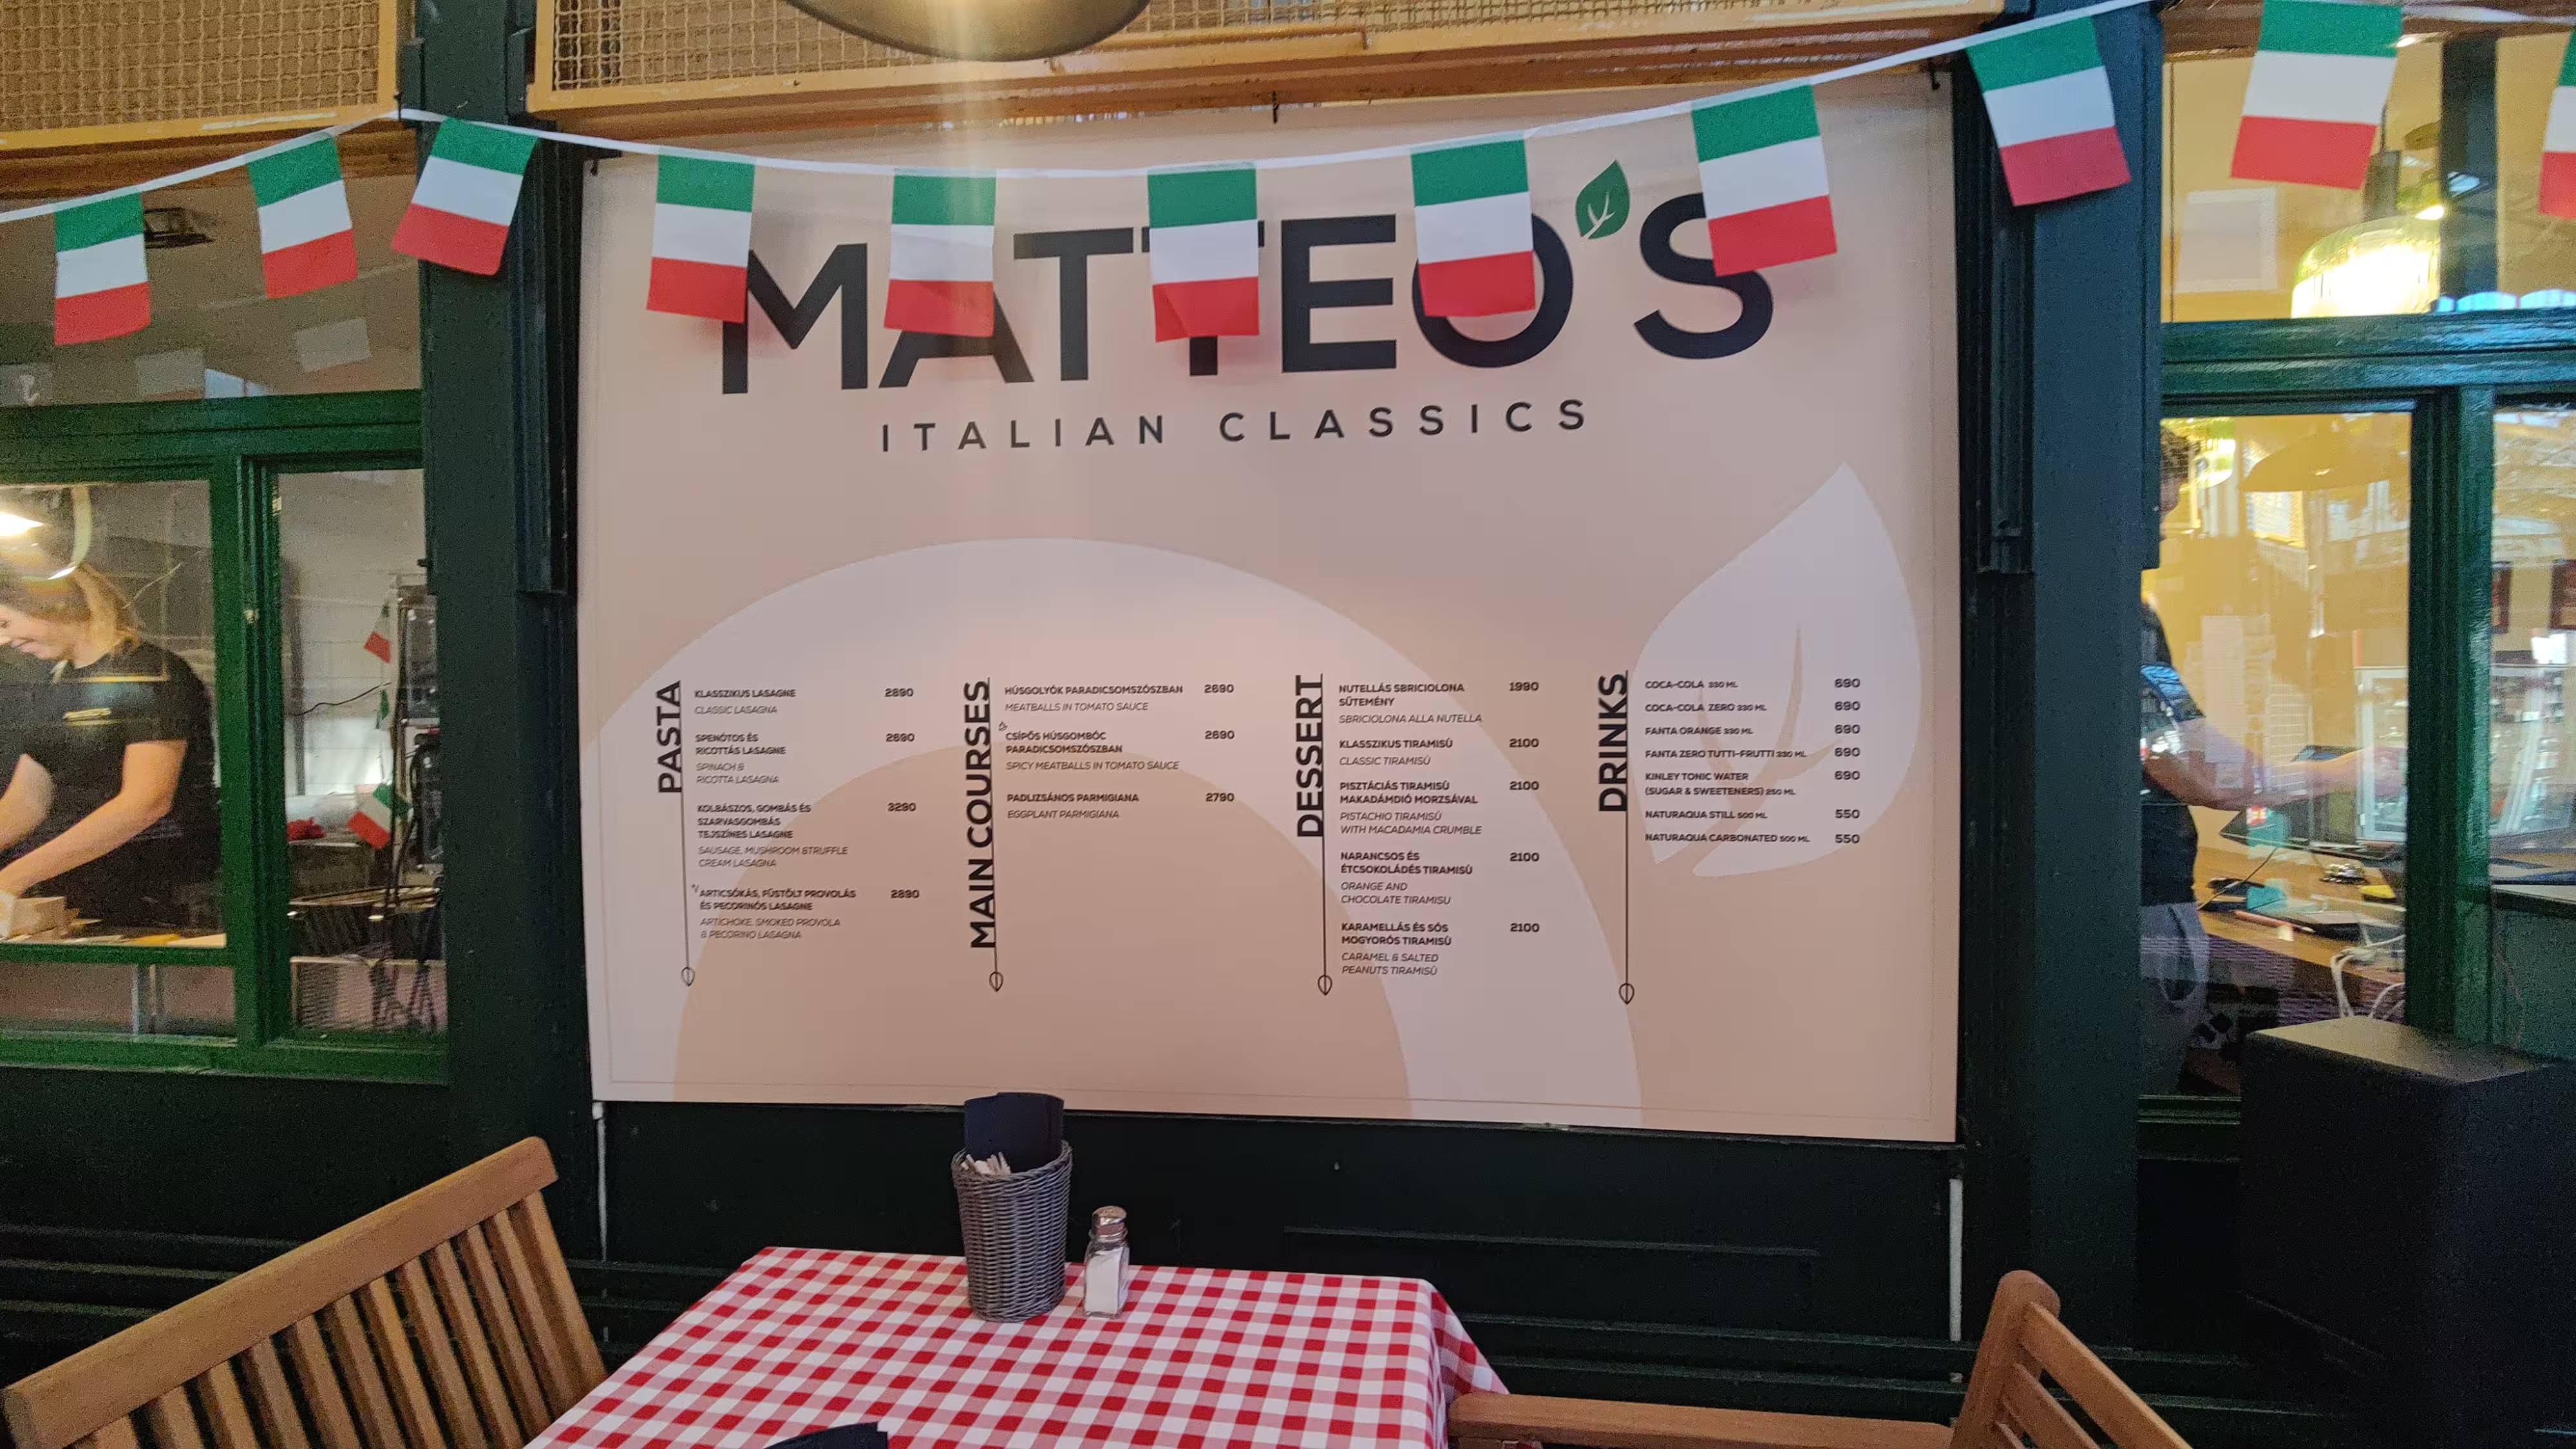 A picture of Matteos, where we had our lunch.
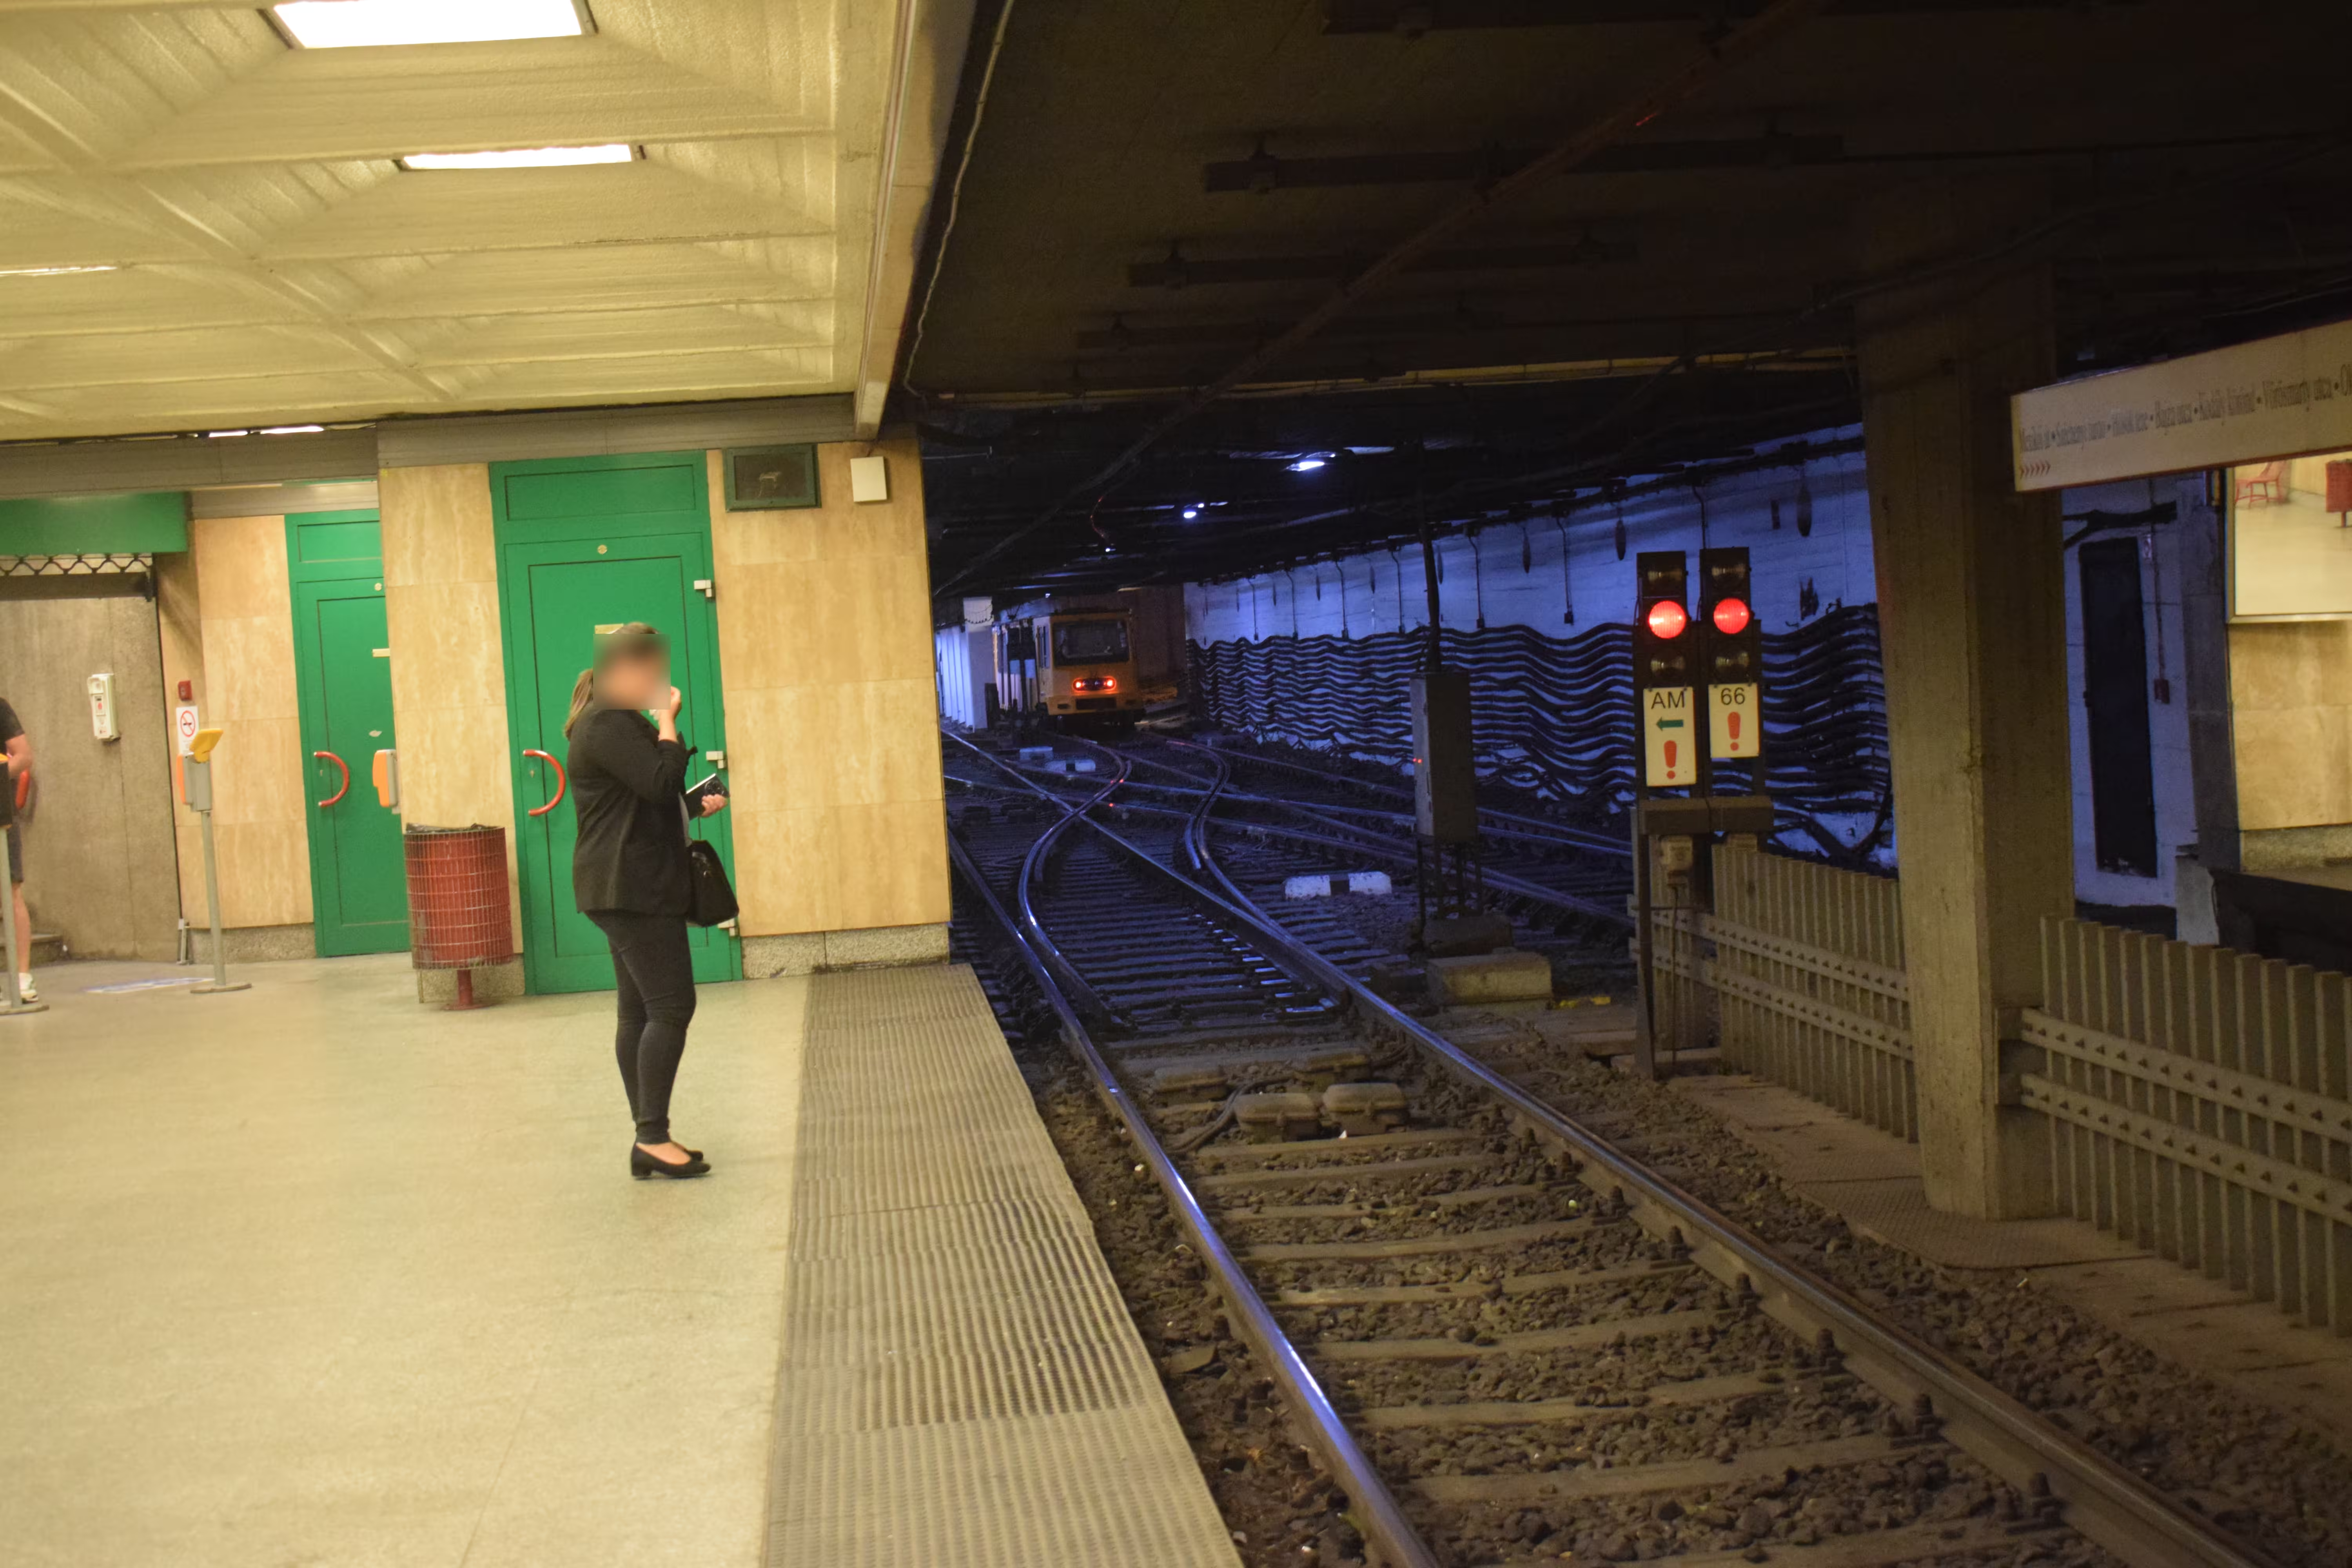 M1 line station and tracks. It is the oldest metro transit of Budapest and one of the oldest in the world. It started operations in 1896.
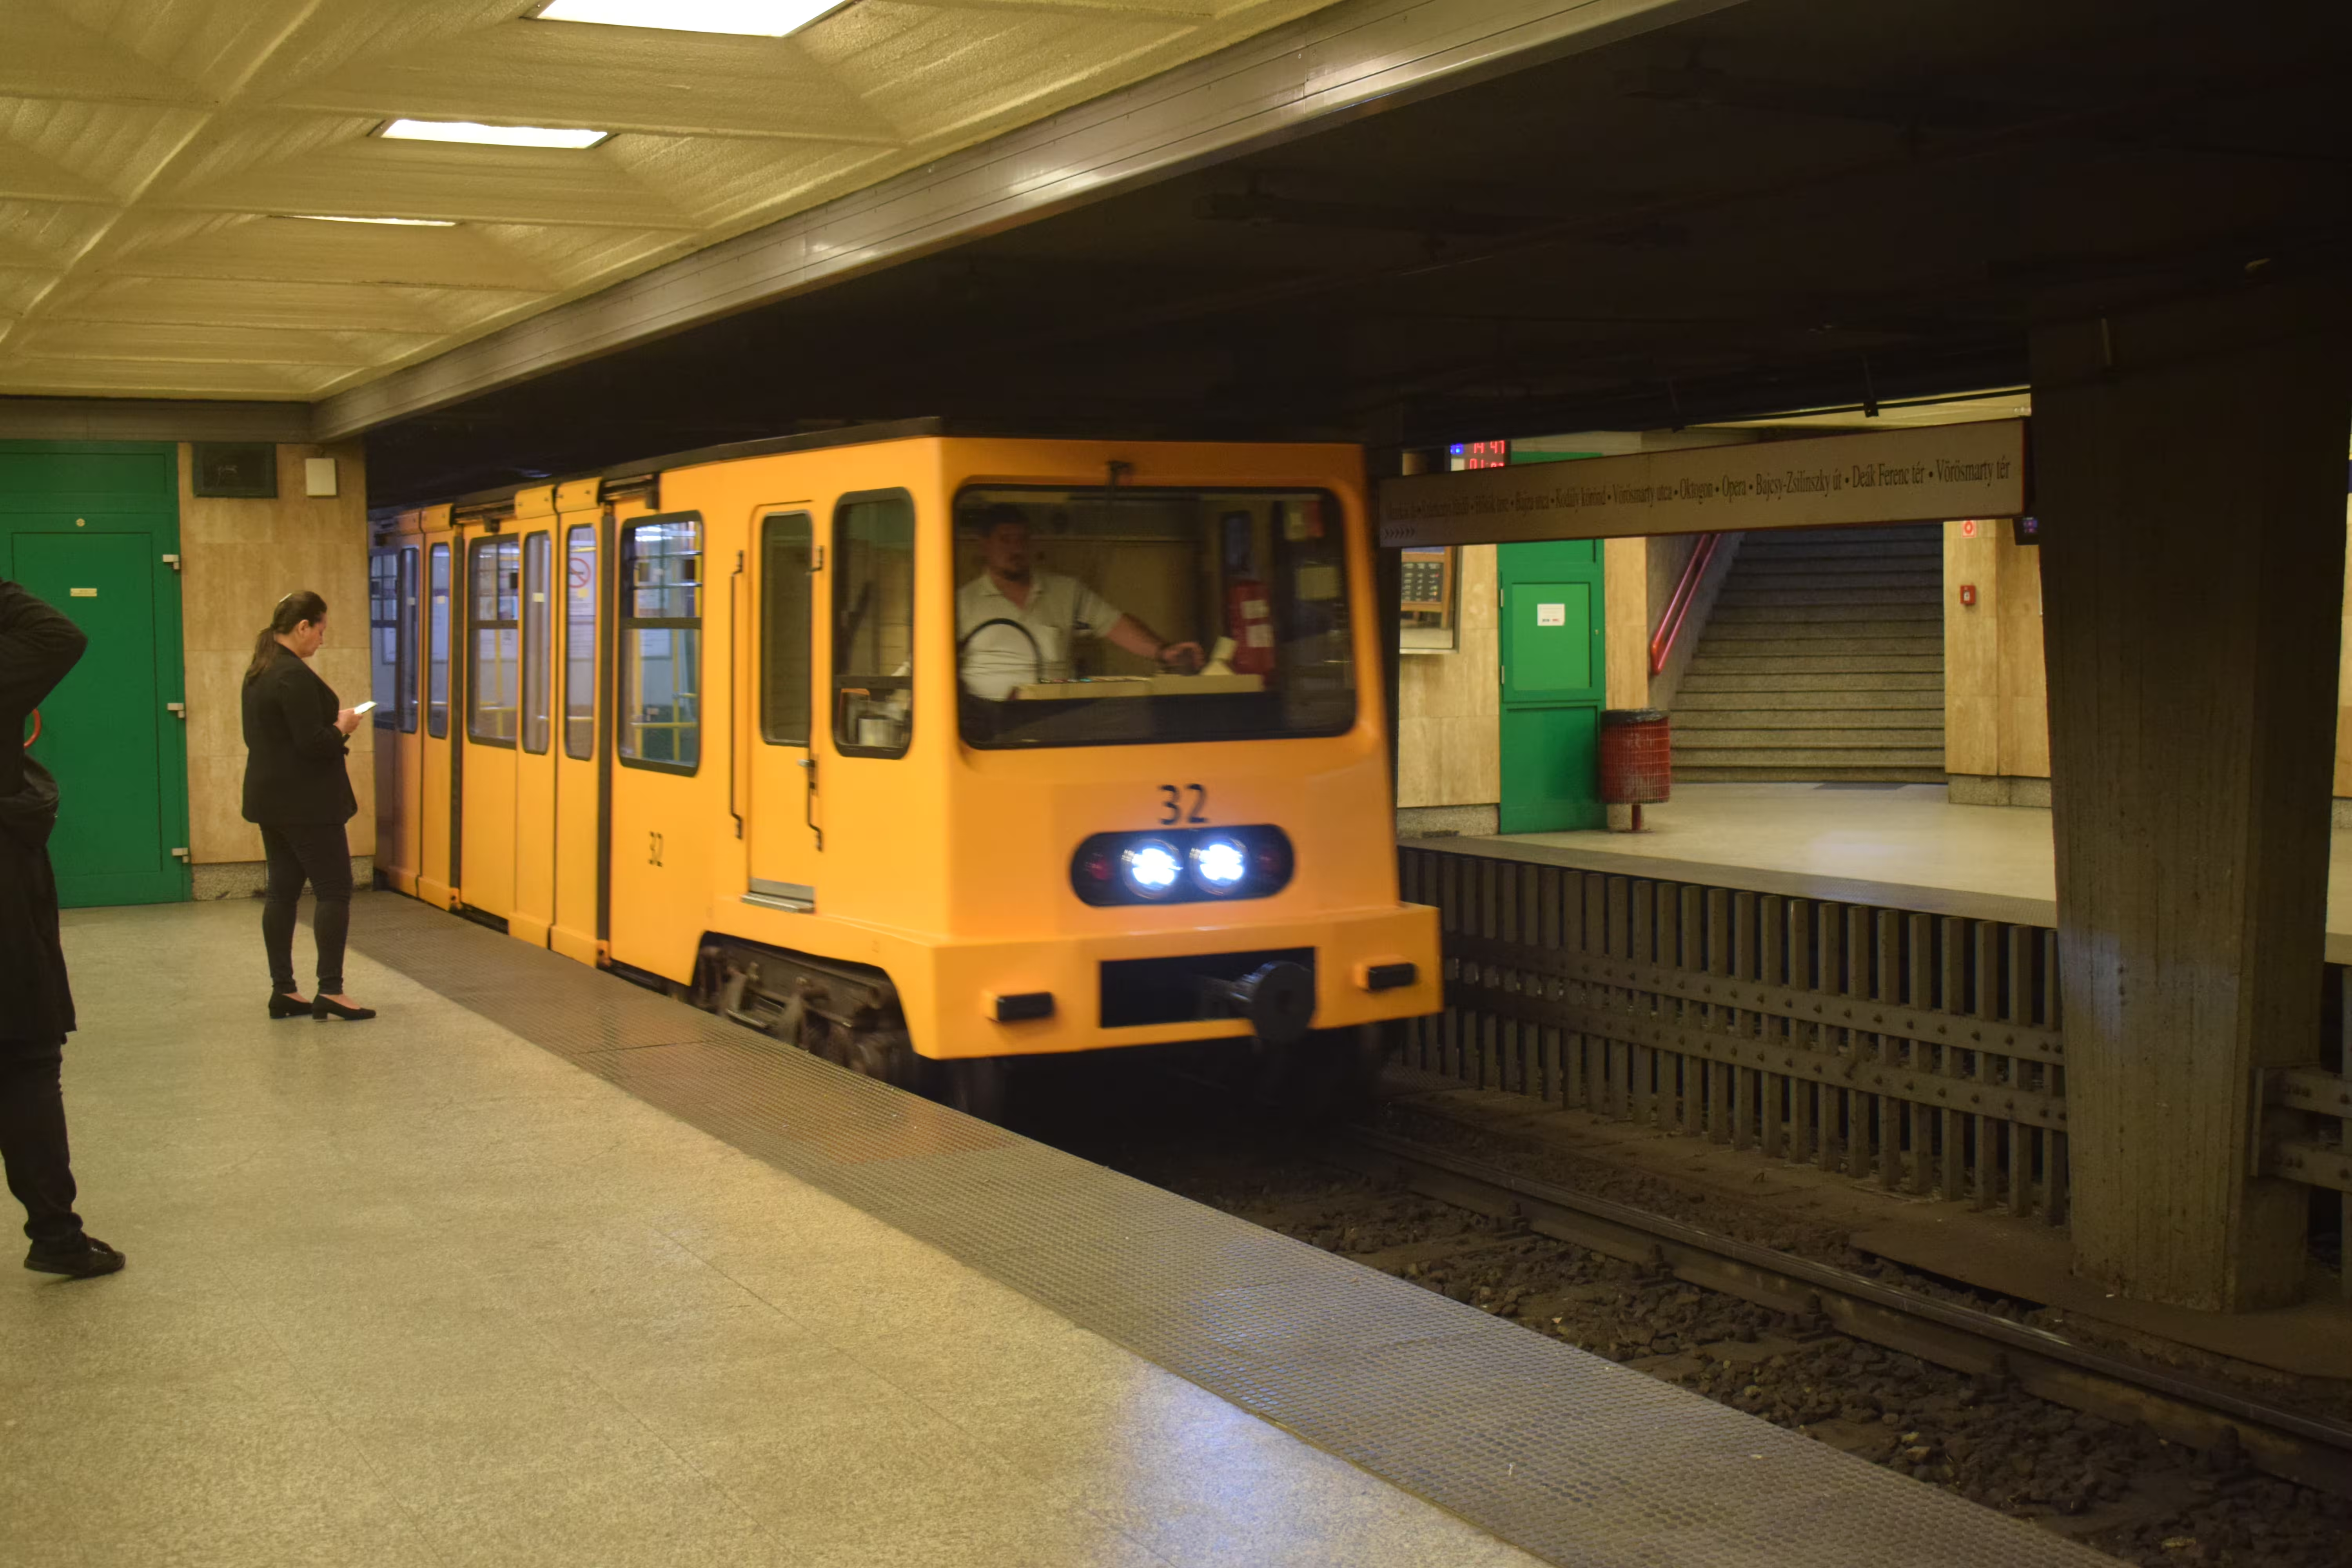 An M1 line metro train entering the station.
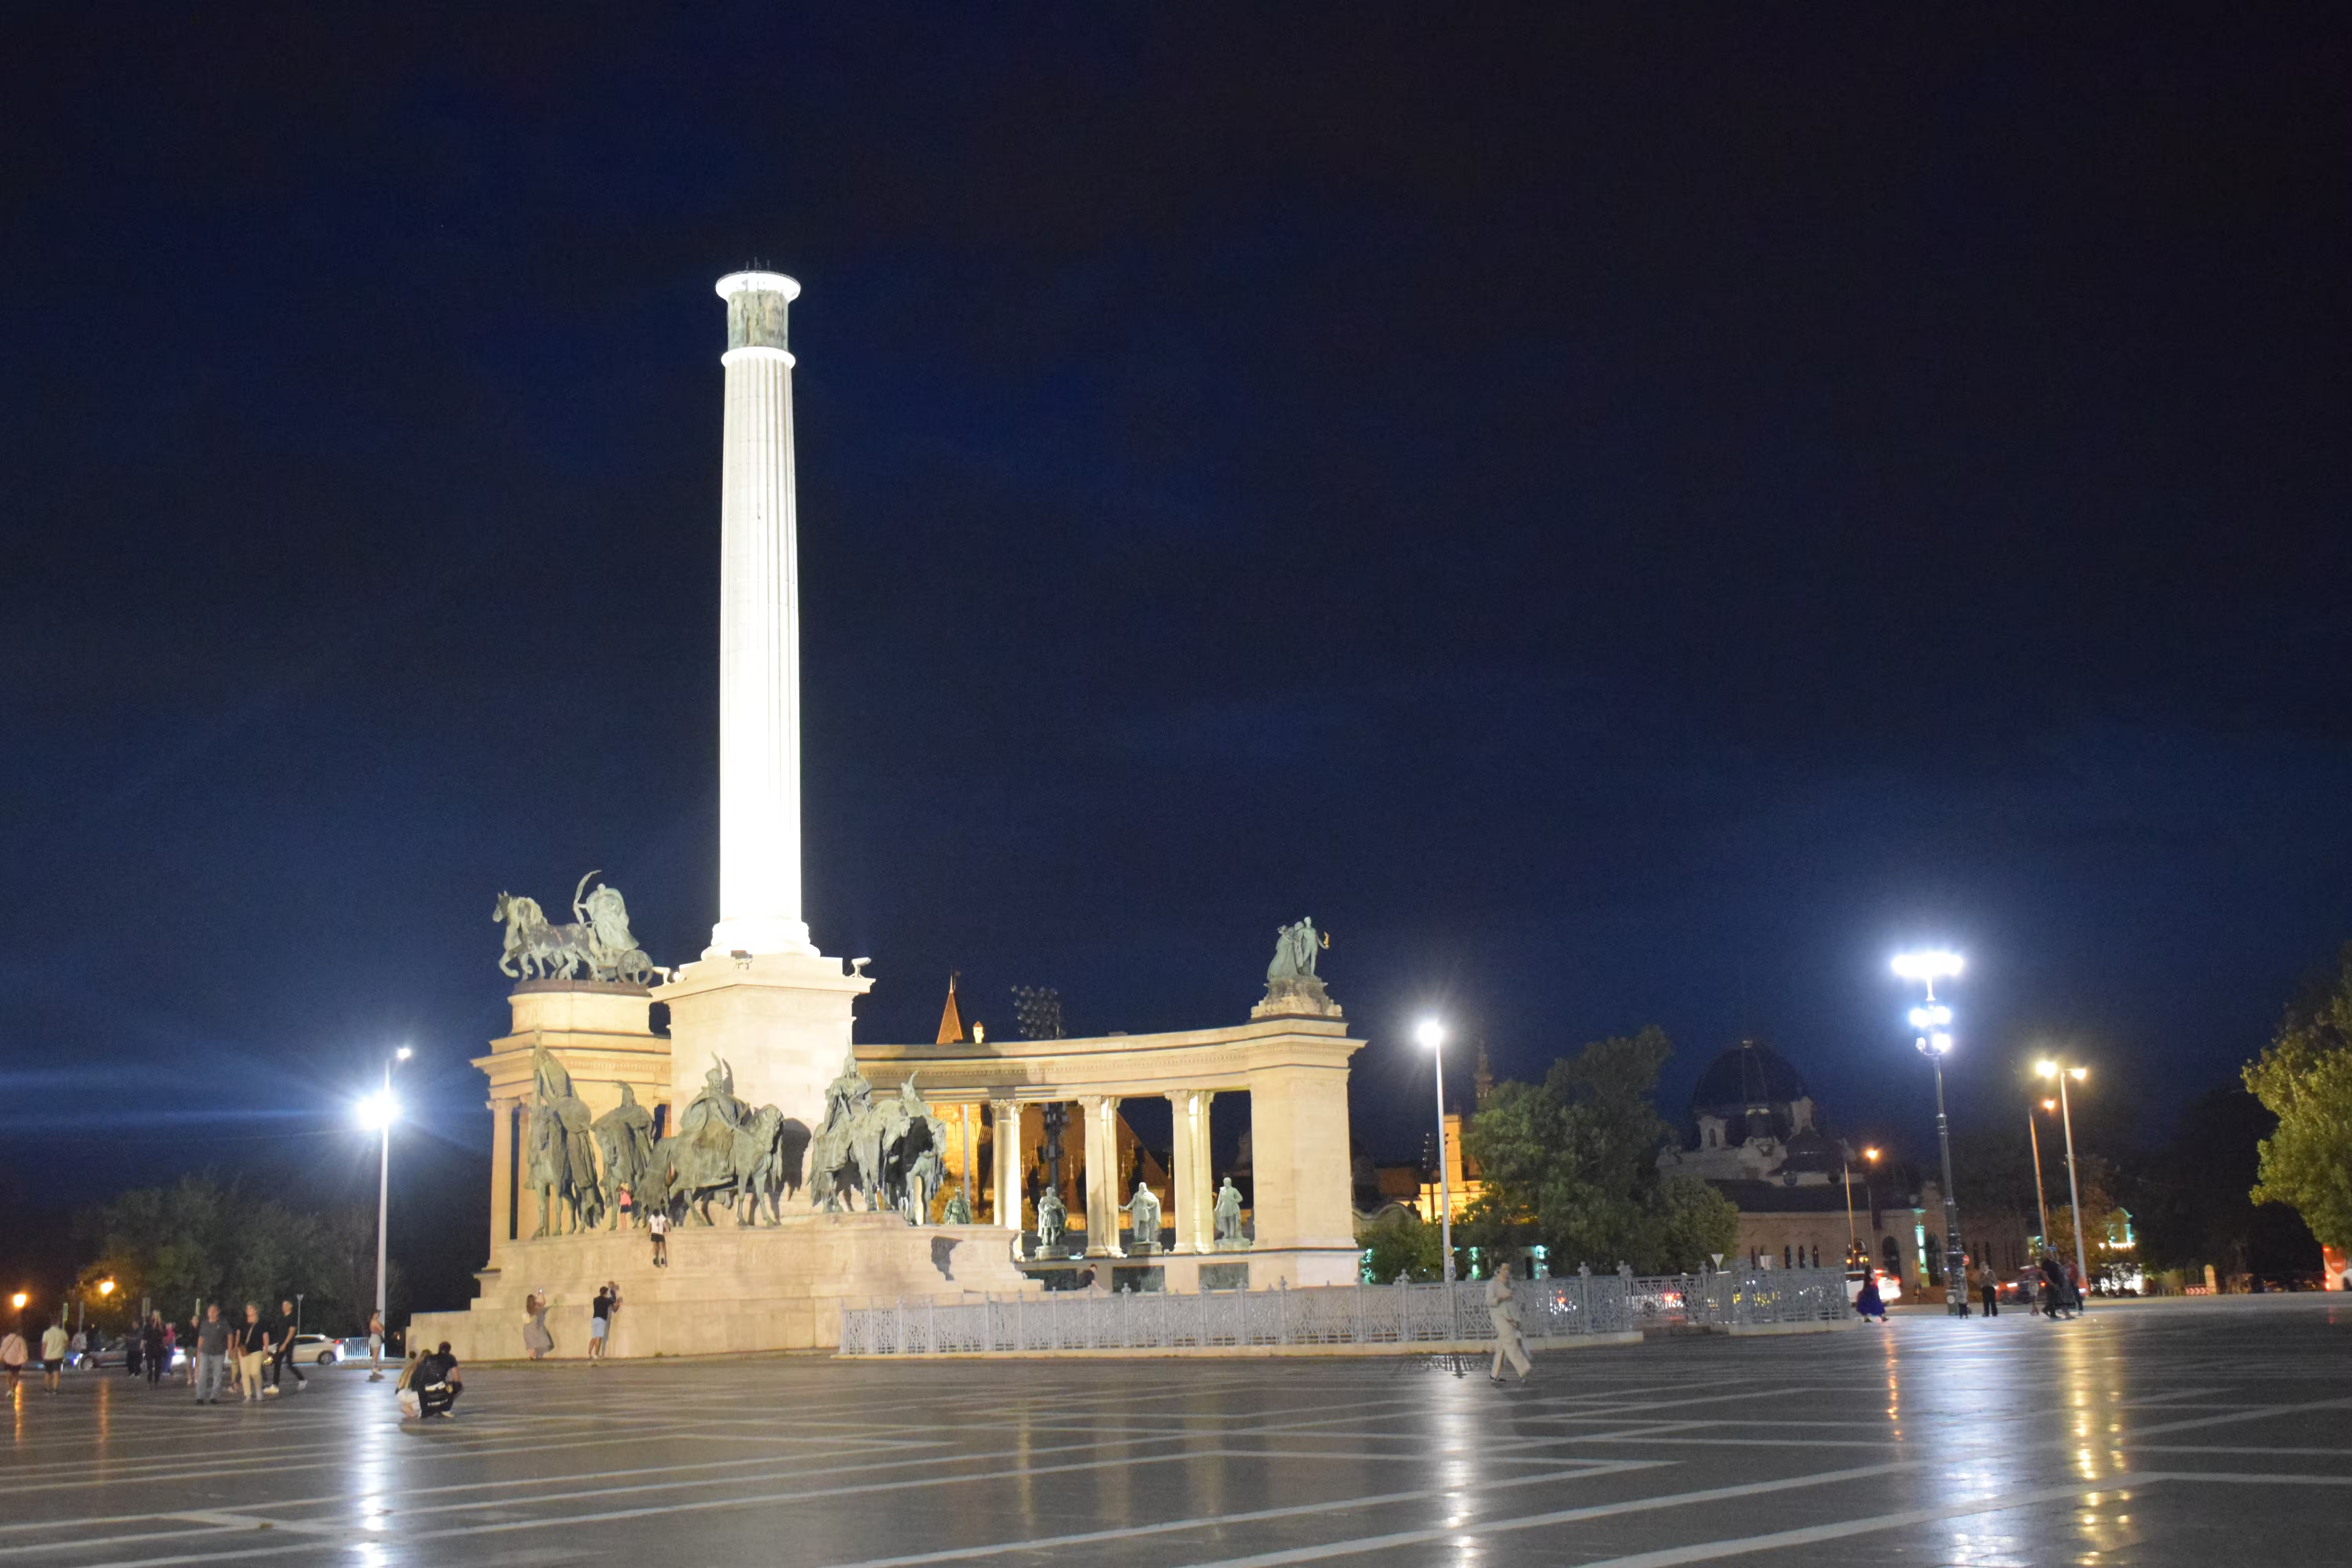 Heroes Square.
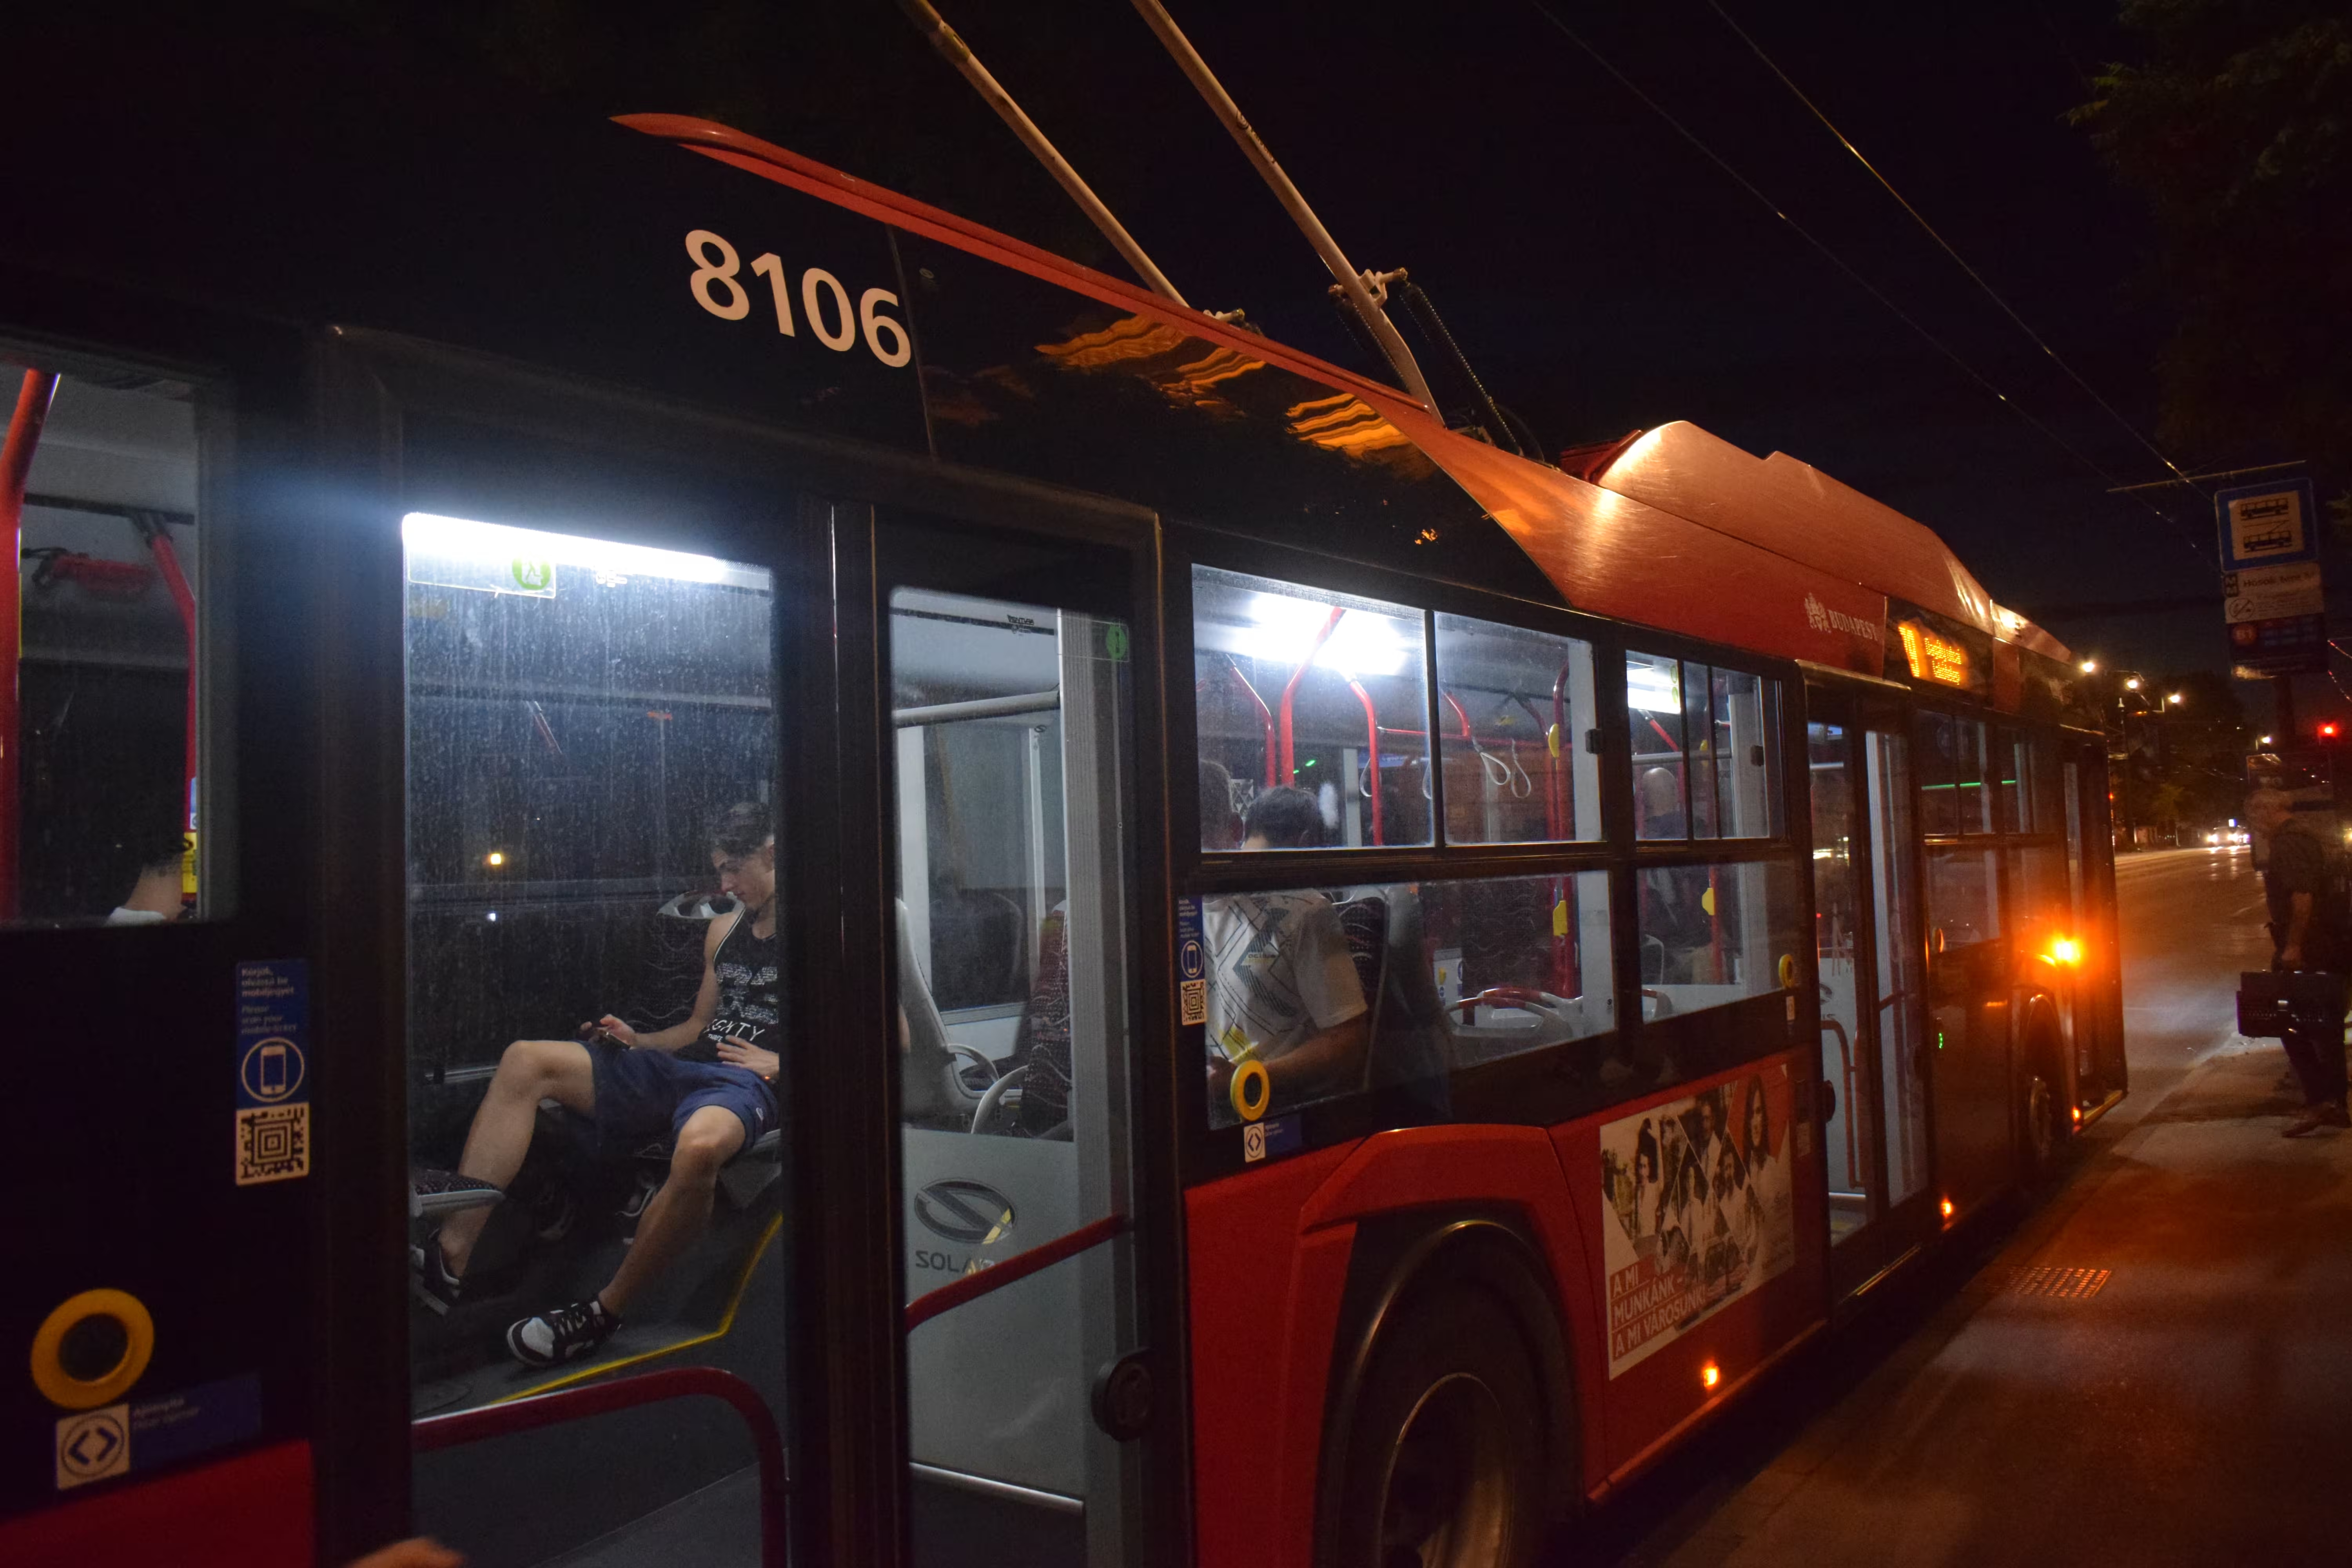 This is the trolleybus we took in Budapest.
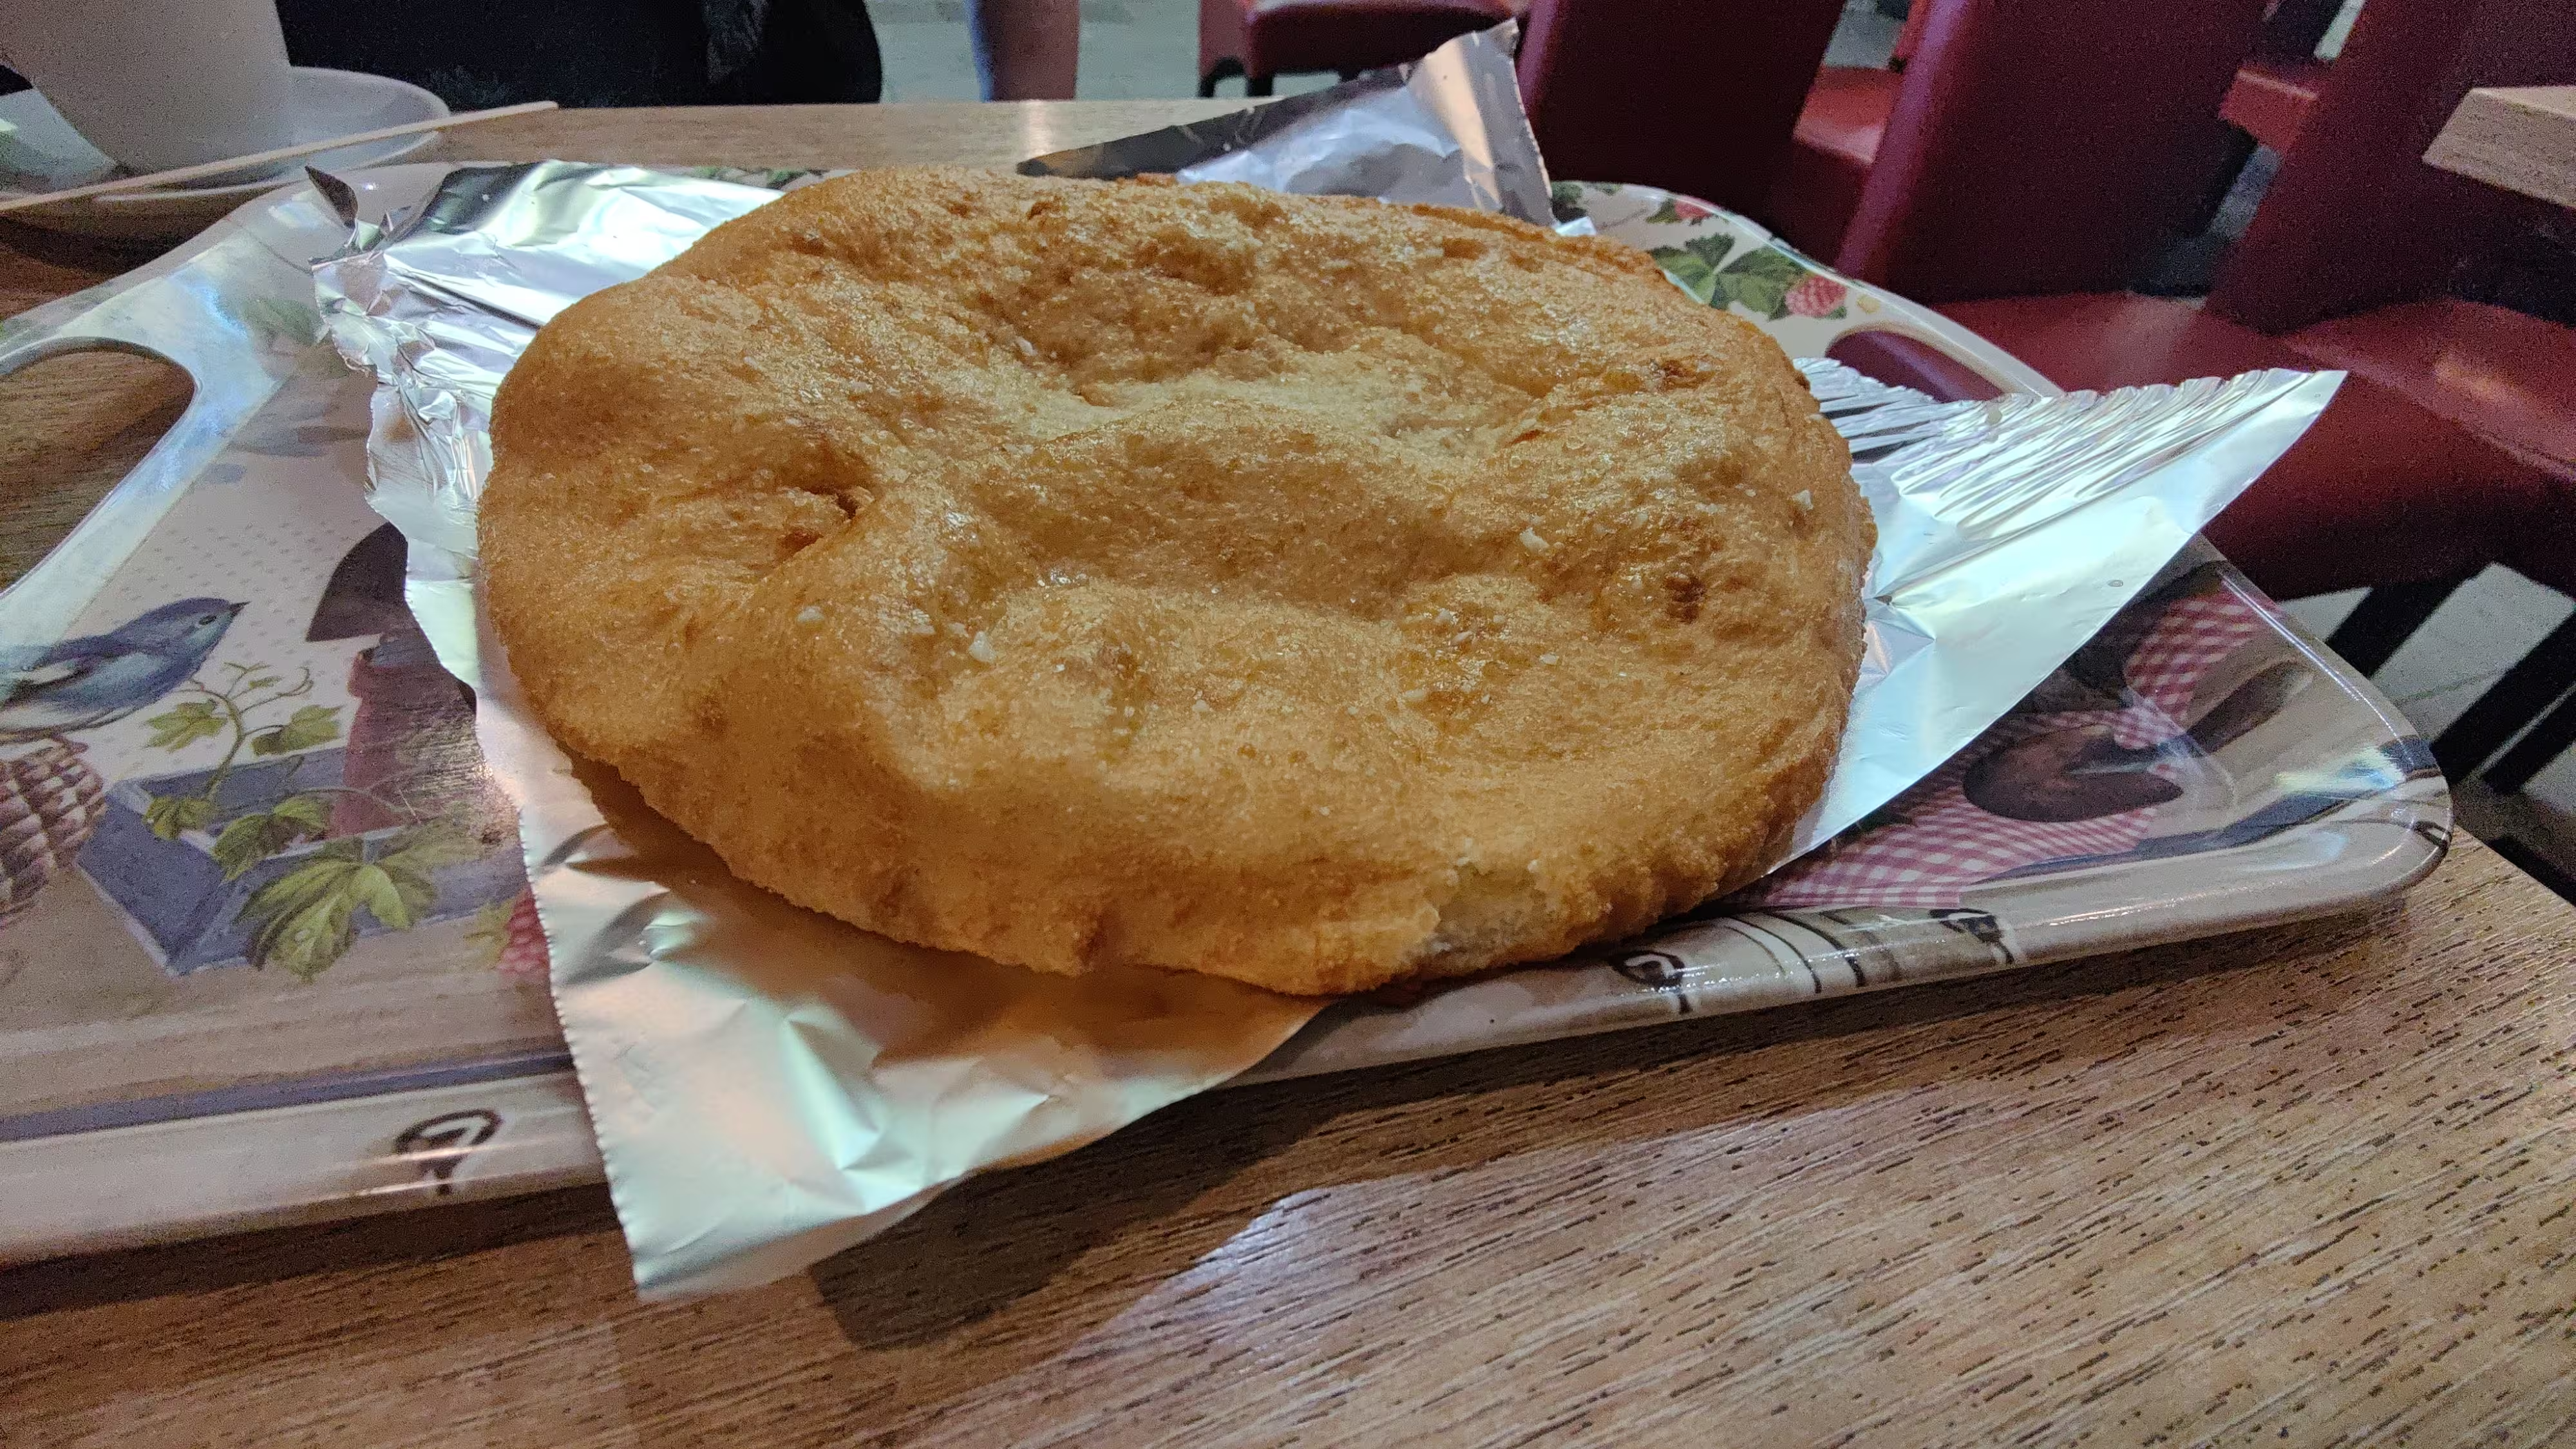 L ngos a dish which looks like the Indian flatbread bhatura.
 In January 2025,
as a pre-requisite for something else, I published a minimal