Search Results: "cts"

20 June 2026

Gunnar Wolf: systemd for Linux SysAdmins

This post is a review for Computing Reviews for systemd for Linux SysAdmins , a book published in Apress
systemd. Yes, in full lowercase. If there was ever a technology to cause controversy in the Linux world, this is it. Since its inception in 2010, systemd s goals were set quite high: to replace the vital part in every Linux system that takes care of the system boot process. It quickly reached maturity, allowing it to be adopted as the main init system in most major distributions just five years later. Despite describing events that happened over a decade ago, systemd adoption still raises the temperature in any Linux-related discussion. David Both s comprehensive book tackles the what, why, and how issues surrounding systemd. Carefully divided into 16 chapters, going from the basics and some of the technical and political history behind the project to the different subsystems and aspects covered by systemd, its almost 450 pages can scare people away. But the text is written in a very clear, tutorial-like fashion, and while it can be read sequentially, cover-to-cover, readers can also pick a single aspect and jump straight to the relevant chapter. A frequent criticism of the systemd project is that it aims to basically rewrite all of a Linux system, and just looking at this book s index shows there is some truth to it. The first chapter is an introduction to the systemd project and a brief overview of its history (including the controversies around it), and the following four chapters deal with understanding and controlling the system boot process. That leaves ten chapters to cover different aspects or subprojects of systemd, such as time and date issues (synchronization, time specifications, and controlling repetitive tasks), understanding and leveraging the system journal that strongly departs from the old syslog system, network configuration and firewall management, system health and performance debugging all aspects that in the traditional Unix philosophy were managed by independent programs. And I can identify several systemd subprojects not covered by this book! We long-time Unix and Linux administrators took pride in how highly performant and stable systems were supported by the simplicity of our tools; systemd critics point out this massive project has absorbed dozens of individual tools, yielding corporate control over vast swaths of vital system tooling. Truth is, as a sysadmin myself, systemd is today one of my greatest allies. I appreciate how the author evaluates every component independently, including his personal evaluation of each even acknowledging when he prefers working with the traditional programs. If I had to note one criticism: given the many console captures, having a maximum width below 70 characters means several lines are unnaturally cut short (and continued with odd indentations). There is probably no right way to solve this, but it does affect the reading experience.

19 June 2026

Wouter Verhelst: Agentic coding and Free Software

Through work, I have paid license to windsurf (recently renamed to "devin"), an application for LLM-based (aka, "Agentic") development. I hadn't been using it that much, but in an effort to more clearly understand how this whole AI development thing works, I decided to give it a closer look recently. My conclusions: In its current form, this whole LLM wave is problematic for multiple reasons. But ignoring that, and looking at the technology only, I can say that:

Problems Lest someone (incorrectly) assume that I am arguing in favour of the current state of affairs with regards to LLMs, let me state this first. The way LLMs are built today is highly parasitic. Websites are downloaded in whole, at unsustainable rates, regardless of the consent of the people who made the original content. The result is predictable: servers get overloaded, server administrators attempt to implement various mitigations. Some of these mitigations work; some do, for a while; some are entirely useless. In actual fact, the mitigations are an arms race -- if too many people implement the same mitigation, then the people who try to build yet another LLM so they can extract rent will just try to work around the mitigation, eventually they will succeed, and you'll just have to come up with another mitigation. It's a bit like spam; you introduce regex-based spam filters, they introduce spelling mistakes, you introduce bayesian filters, they add a large batch of markov chain-generated semi-nonsense words made invisible by markup, you add filters to block emails with such markup, they move the text into an image. We have working mitigations today, but eventually we'll run out of ideas. LLMs glob up everything they can while ignoring the license of the source material. The people who push those LLMs claim that pushing the source material through the machine learning algorithms makes the output of the algorithm distinct enough from the source material that the license no longer applies; I'm not so sure that this is true. I guess the New York Times v OpenAI lawsuit will teach us some of the answer to that question here, but even so the ethical questions about "is it OK to bring down another server just so we can download the internet for another for-pay LLM" are still open. And regardless of what the law states, my opinion on "you're using my copyleft code to generate code under a different license" is not something you might like if you agree with the rent seekers' opinion on the subject. That all being said and true, the technology works. You can have a "conversation" with an LLM that resembles a human one. If you pass it some data, you can use plain english to ask it questions about that data, which is a lot easier than to ask it about that in a formal way. You can request it to generate some code, and it will generate something that looks like what you need and that will be mostly correct for like 95% of the time. Now, yes, 95% of the time is not 100% of the time, and no, you can't ask it to "write me a piece of software that implements this 300-page requirements document and get back to me when you're done", because it will fail, and you won't know where it has failed, and you'll take it into production and expect everything to be fine because it won't and this one minor logic bug will cause half your servers to spin and consume credits with your infrastructure provider with nothing to show for it. But that doesn't mean you can't use an LLM to build a large piece of software. It just means you have to understand the LLMs limitations and strenghts, and use them correctly. Here's what an LLM is good at:
  • Generating plausible text
  • Interpreting text to figure out what a plausible meaning or summary of that text is
  • Giving vague indications as to what the probable context of a given body of text is.
It turns out that that's enough to use the LLM to build a reliable piece of software, provided you do it right.

Paradigm shift An LLM can generate text by the truckful. The generated text could be code. Given a good enough LLM, the generated text might even run and do something useful. You can try to blindly run the code, and if it doesn't run correctly, you can paste the error message to the LLM, and it can tell you what went wrong and how you could possibly fix it. This creates a feedback loop: you ask it for an amount of code, you run the code, you receive an error, you tell it that the code is problematic and give it the error message, it makes changes to the code, now you have something that at least no longer fails at startup. If you ask it to add tests to make sure that your code acts as per your specification, now you get an error if and when the code doesn't act as per your specification. Or, well, at least not as per the part of the specification that was correctly turned into a unit test by the LLM. LLMs have a context window, so if the error message is pasted in the same conversation as where the code was generated, it is able to reuse the earlier prompts to refine how it should interpret the error message that you received. You can't really paste the source code of an entire application into the prompt of your LLM, that would quickly overrun its context window. But LLMs also allow you to provide some form of background information -- a document, say -- on which you ask it to reason. It will interpret that document, but doing so uses less of the LLMs context window. So providing the LLM with your application's source code as background information can help it understand better how your code interacts. This is especially helpful if you only provide the LLM the background information relevant to the actual question. So now if you are able to:
  • Create background context with your application's source code
  • Have the LLM generate a first draft of your requested change, plus the tests to make sure it works
  • Compile (if applicable) the generated code (and tests) and run said tests
  • Return any error messages to the LLM with a request to correct the error
Then the combination of "getting it 95% right off the bat" and the above feedback loop means you can generate syntactically correct code, that probably does what you need, in minutes. I say "probably" for a reason. There are going to be cases where you specify a request without a number of details (because they are implied), and the LLM will get most of those details right but just not implement the one bit because it's an automaton and it doesn't think. Or you will ask it to make sure that two bits of the application look exactly the same, without specifying that they must act the same, now and in the future, and it will just generate the same block of code twice and then in a future change it will change one but not the other. But if you review the changes, and you have experience as a programmer, you will be able to spot most cases where the LLM got it wrong. And so it's possible, if not necessarily easy at first, to use an LLM to generate mostly correct code. There are certain places where "mostly correct" code is not desireable. But equally, there are also cases where, "mostly correct" is good enough. After all, most of the software you run today -- the bits of it that weren't, yet, generated by an LLM -- is only "mostly correct", too, because to err is human and we all make mistakes. If not, there wouldn't be any CVEs and your software would never do anything wrong. Now, doing the feedback loop described above is certainly something you could do manually. You could open an account on one of the LLM websites, upload the source code of your application, ask it to generate some new feature, download the newly generated feature, run it, and then copy/paste any error messages back into the LLM. But that's a lot of manual work of the type that computers are pretty good at. So that's what the "windsurf" tool helps you with: you run it inside your IDE -- either a VSCode-based tool that you download from their website which comes with their product preinstalled, or a separate JetBrains plugin that you can install. You can then open your entire relevant codebase in a workspace in your IDE. You then ask the LLM, through the IDE, to generate a new feature in your codebase, and to also generate the test while it's at it. It will use a mixture of LLM interpretation and non-LLM functionality to scoop out the relevant bits of your codebase to send to the LLM as background information, will send it your prompt, will download the generated code and patch or create files, will compile (if required) and run the newly generated code and tests, and will refine the generated code if the tests produce any errors. All mostly automatic; by default, running anything requires explicit confirmation. You can turn that off completely (probably not a good idea), or you can give it a whitelist of things that you don't want to confirm (perhaps OK), and the tool also passes standing instructions to the LLM to never generate any command that deletes a file (which, like with any LLM, can be overridden, but it requires you to be very stubborn and to use more credits than you'd probably like). All this put together means you can build something without writing any piece of code, provided you do it right.

A technically positive evolution Don't go and say, "here's a 300-page document, read it and write whatever the document says". It will get it wrong, it will write a massive test suite that it will only run at the end, it will choke itself up trying to interpret the massive amount of failures it encounters, it will fill up its context window and it will start to forget some of the requirements. That won't work. But what you can do -- what I did, in fact -- is this. First, create an empty workspace. Don't put any code in it. Then, tell the LLM to generate a backend framework using technology X and a frontend framework using technology Y that initially only says "hello, world". Also add tests to it, and run the tests. It will do that. You'll not get much, but it will work. Then, ask it to add some UI elements. A login page, perhaps. A navigation bar. Small things. Most of it doesn't have to be functional -- but tests must be there for the bits that are, and have it run the tests and evaluate the results. Rinse, repeat, until you have a working application. Importantly, in between the steps, you should also run the application yourself and see if the change was implemented correctly. Sometimes it won't be. Sometimes there will be a subtle bug -- I at one point had a the application hang after a few minutes. Sometimes you tell it that there's a subtle bug, and it will discover it more quickly than you could, and it will fix it, and in implementing the fix it will uncover another bug, and then you have to fix that one -- the fix it came up with for the hang was to move something to an async process on the server, which caused the application to start spinning while trying to create hundreds of async jobs (this is when I realized that the hang was a deadlock due to some part of the codebase doing something that indirectly triggered itself). Sometimes it will try to fix the bug you tell it about, and you'll see that it's going off on a tangent that has nothing to do with what you're seeing. It's important to keep an eye on what it's doing, so you can guide it back on track when that happens -- when I told it about the hang, it started investigating the part of the code which sends out emails, thinking that it could hang while waiting for sendmail to finish, but the hang was happening when the application was idle, not when it was sending out emails, and only when I told it about it happening when it was idle did it find the deadlock. So it's not a fully automatic process, and it needs to be guided by someone who knows what they're doing. But if that is the case, you can come up with something that works. I spent evenings and breaks for about a week, and I managed to create a working application which, had I written it by hand, would have taken me a few months of full-time work to come up with. And I now have a side project, fully complete and working, that I had been thinking about doing for more than a decade, but never got around to actually doing, because of all the work that would be involved and I just didn't see myself having the time for. It's not perfect code. But it's mostly good enough, and it will perform the job it needs to. And it looks far slicker than most of the side projects I've done in the past, because in the past I would prioritize between implementing new features or making something look slick, and I would decide that the new feature was more important because it's only for me and there's only me and nobody cares if it looks good or not and I don't have three weeks to come up with something that looks better. But here, I found myself sometimes spending 10 minutes writing a prompt with instructions on making things look better. Because what's 10 minutes when you just spent an hour writing down and refining specifications for functionality and tests? There are a number of other things in which an LLM can help a programmer. For instance. I received a bug report recently in a project I'm paid to maintain that I couldn't make heads or tails of. I opened the source code in my windsurf IDE, pasted the bug report in the prompt, and then requested the tool to analyze the source code and the associated logs and tell me how the described behavior could be happening. It turned out that I had overlooked something, but with the help of the tool, I found the bug in minutes. I was trying to understand a particular part of a large codebase that I didn't really grasp very well. I loaded the codebase in the tool, and asked it to explain to me how a particular action is performed by the code. I requested specific functions and line numbers. I now have a far better understanding of how the code works, and will be able to write that patch that I've been wanting to write for years -- without using the LLM. I have been struggling for, literally, years with understanding why another tool that I maintain was misbehaving in a particular way but only in Firefox. I opened the codebase in Firefox, explained the buggy behavior in plain English, and asked it to explain how this could be happening. It picked up some obscure corner case behavior of ffmpeg and mp4 containers that I was not aware of and that perfectly explained why things were misbehaving in the way that they were. At the same time, there are limitations. Giving an LLM a codebase that was originally generated by an LLM (either the same one or another one) seems to work well. Giving it a codebase that was written by a human and expecting it to correctly update it seems to be more error-prone. I did one or two of those as a trial, and it is more problematic than anything. An LLM is also not intelligent, notwithstanding the popular term of "Artificial Intelligence". On multiple occasions, I've asked it to write a test case for some code that was not set up to do so; and rather than suggesting a refactor is required, it would instead copy the code that needed to be tested and then test the copy, rather than the original. The tool has made multiple similar errors. I have sometimes people describe agentic coding as "similar to interacting with junior programmers", but that is not the case. A junior programmer will either fill in the gaps in your specifications, or ask for clarification when something seems off. The LLM will not do that; it will do what you ask, exactly that and nothing more. If you missed a corner case in your specification, then all bets are off. I remember learning about programming language generations in college. A first-generation language is "machine code", a second-generation language is "assembler", a third-generation language is any high-level language such as C, Perl, or Pascal. I've forgotten what set a 3rd-generation language apart from a 4th-generation language. But I remember the definition they gave me for a 5th-generation language: "you tell the computer what to do, and it will do it". At the time, I thought it was ridiculous. Nobody could ever write something like that. But it's here. And it's a threat to free software.

A threat to free software? Yes. There is the obvious part where most of the well-known LLMs are non-free software. I mean, there are some "open source" LLM models. The windsurf tool that I used doesn't allow you to use them (directly), but they're there. There are also open source applications that implement what the windsurf editor does. So it's definitely possible to work like this without resorting to non-free software and non-free services, even though the non-free LLMs might be a bit ahead of the curve of the free ones. But that's not what I mean. And there is also the obvious thing which I mentioned earlier in this post, which is that the people who try to build LLMs are doing it in unethical, disgusting ways, causing downtimes and disregarding licenses for whatever they can get their grubby hands on. Ideally we wouldn't be in that situation, and ideally this wouldn't be a problem, but we are where we are. And there's the obvious thing where the OSI sold itself out and declared that a machine learning program can be open source even when the very things it was built from -- the training data -- is not available. That's a major issue that the free software community needs to fight against, but there's not really anything that that is a threat to free software. You just build your own, free software, LLM, and you're done. The actual threat is in funding and developer support. Most large businesses do not care about free-as-in-freedom software. They like the free-as-in-beer part, and they appreciate that the free-as-in-freedom bits can make the software more customizable. They are (mostly) happy to do sponsorships of the free-as-in-freedom projects that they use if that means their free-as-in-beer usage of the software gets improved. But why would you care about all that when you can just generate the code you need, rather than interacting with an open source community that may or may not care about your business's interests?

Where to go from here Although I think the moral and environmental issues with LLMs are real and problematic, given the experiments I did I am not convinced that the concept of interacting with a computer system in natural language and to use it to generate code is necessarily deficient. There are pitfalls, but they can be managed. It is possible to use such a system to create throwaway, proof-of-concept type "good enough" code bases. It can be used to interpret code bases and to understand bug reports. I believe that the major issue with LLMs has to do with that saying about hammers and nails:
If all you have is a hammer, then everything looks like a nail.
LLMs are an outgrowth of machine learning, pushed by large corporations. These large corporations have a lot of money. If all you have is money, then every problem can be fixed by throwing more money at it. The initial language models were promising but not (yet) good enough, and it seemed that one way in which they could be improved was to increase the scale of the statistics: throw more hardware (and thus money) at it, and rather than improving the efficiency of the models, just scale up. Scaling up is something that megacorporations are very good at. It's only a money problem, after all. Does that mean that "scaling up" is the only way to improve the models, though? I'm not convinced. Some hardware, such as most modern Apple and Samsung devices, ship with accelerator hardware for machine learning algorithms. There are some models that are small enough to be able to run on these devices. I don't see why it should not be possible to create a small(er) language model that can do some useful part of the above-described use cases; if not locally, then at least on a server that one can run on-prem rather than requiring that you pay rent to one of the LLM companies. The Software Freedom Conservancy has published an aspirational statement on machine learning-assisted programming that, I think, gets a lot right. It's not quite a definition, but it's something to keep in mind. Perhaps that's the way forward? More questions than answers at this point, anyway.

Freexian Collaborators: Monthly report about Debian Long Term Support, May 2026 (by Santiago Ruano Rinc n)

The Debian LTS Team, funded by Freexian s Debian LTS offering, is pleased to report its activities for May.

Activity summary During the month of May, 21 contributors have been paid to work on Debian LTS (links to individual contributor reports are located below). The team released 56 DLAs fixing 877 CVEs. May was a much busier month than usual, especially due to the disclosed vulnerabilities on linux regarding Local Privilege Escalation (LPE), that included public proof-of-concept (PoC) exploits. These reports of course impacted Debian as a whole, and the situation warrants a special mention to the Kernel Team, especially Ben Hutching and Salvatore Bonaccorso, who faced the pace and released linux packages on a weekly basis. On the LTS side, the Front Desk team also triaged a significant flow of high severity CVEs. It is also important to note that Debian 12 ( bookworm ) will be handed over to the LTS Team on June 11th. If you benefit from Debian, especially during the full 5-year lifecycle, please consider subscribing as a sponsor of Debian LTS: https://www.freexian.com/lts/debian/. Moreover, Debian 11 ( bullseye ) will reach the end of the Debian LTS period on August 31st. After that, Freexian will continue the security support under the Extended LTS offer. The team published several notable updates:
  • As mentioned above, several exploitable LPE vulnerabilities in linux were published during May. Ben released the following DLAs for the Debian LTS versions:
  • exim update (DLA-4580-1), prepared by Thorsten, to address a vulnerability that may result in remote code execution.
  • gnutls28 update (DLA-4595-1) by Guilhem Moulin, fixes several vulnerabilities that may result in execution of arbitrary code, information leak, authentication bypass, among other impacts.
  • krb5 updates released as DLA-4603-1, fixing two vulnerabilities that may yield to a denial of service. Updated prepared by Emmanuel Arias
  • lemonldap-ng (DLA-4602-1), released by Abhijith PA, fixing multiple vulnerabilities
  • Two imagemagick updates (DLA-4559-1 and DLA-4609-1), prepared by Bastien Roucari s, fixing several vulnerabilities
  • openjdk-11 and openjdk-17 updates (DLA-4566-1 and DLA-4565-1), both prepared by Emilio, to fix seven vulnerabilities.
  • php7.4 update (DLA-4586-1) to fix six vulnerabilities that could result in remote code execution, information disclosure or denial of service. Update prepared by Guilhem Moulin.
  • python3.9 update (DLA-4583-1), prepared by Arnaud Rebillout, addressing multiple vulnerabilities.
Contributions from outside the LTS Team: We are greatly thankful for the contributions from people outside the LTS Team:
  • Colin Watson prepared an OpenSSH update, that was released by Santiago as DLA-4584-1.
  • Thomas Goirand handled a keystone update, whose advisory was done by Santiago and released as DLA-4611-1.
  • Christopher Obbard kindly prepared a sentry-python update, released as DLA-4612-1.
  • Christoph Goehre made two thunderbird updates (DLA-4562-1 and DLA-4582-1). As is customary, Emilio released the advisories.
The LTS Team has also contributed with updates to the latest Debian releases: Moreover, thanks to our partnership with Catalyst, it has been possible to extend the support for Samba 4.17, the version shipped with Debian 12. In May, several vulnerabilities were disclosed, and their patches were prepared by Catalyst. For Debian 12, the update was prepared by the Samba maintainer and released as DSA-6297-1.

Individual Debian LTS contributor reports

Thanks to our sponsors Sponsors that joined recently are in bold.

18 June 2026

Mike Gabriel: Commenting on the recent Ubuntu Touch review done by @SwitchandClickOfficial on Youtube

There has been a video blog post recently published with a review of Ubuntu Touch as an option to opt out of the Android world: https://www.youtube.com/watch?v=wTK6TS3pXgc Thanks to @SwitchandClick for spending time on this and publishing that video. Much appreciated. Many Issues amended in upcoming 24.04-2.0 Release When I watched that video referenced above, I continuously thought: ah... this is fixed in the next major release of Ubuntu Touch, or: ah... this is a known issue that we have on the roadmap..., or: ah... this is done in this ways by design (so it's a feature or basic functionality)... Let me just state, that most of the criticized aspects will be resolved in upcoming Ubuntu Touch release 24.04-2.0 (the tests in that video blog post have been run on Ubuntu Touch 24.04-1.x): The full feature preview of the 24.04-2.0 release can be found here: https://ubports.com/blog/ubports-news-1/ubuntu-touch-24-04-2-0-beta-is-n... Ubuntu Touch App Ecosystem The app ecosystem of Ubuntu Touch is quite specific, because many apps in Ubuntu Touch have been explicitly developed for Ubuntu Touch using a widget toolkit called Lomiri.Components. However, in Ubuntu Touch we also encourage developers to provide apps written with other convergent-capable toolkits, such as QQC2-based apps or Kirigami-based apps. One reason for the very different app ecosystem in Ubuntu Touch is that many service providers don't have Ubuntu Touch on their radar when investing in app development for their services. Some Ubuntu Touch App Developers work around this by either implementing unofficial client apps for web services (e.g. the Flow app for Deezer by Sander Klootwijk), others provide the web service via implementing a web app (will not work when offline, but at least will show up as an app in the launcher). The overall solution for making Open-Store.io more familiar to users who migrate from Android is that commercial service providers start honouring digital sovereignty and start providing apps for Linux. Not just for the Linux desktop, but also for mobile Linux platforms. This dual use case can easily achieved with an app development that bears convergence in mind. App Ecosystems are also a Matter of Perspective And one more minor note: whenever I open an Android appstore or can peak over someone's shoulder using an iOS device: I always wonder: what are all these apps about??? Never heard about them. So, familiarity really depends on perspective. And perspective depends on what you are used to. Change what you do and your perspective will follow. Ubuntu Touch's root filesystem (rootfs) is Immutable Only thing from that video blog post that we haven't fixed and won't do so in the midterm future is apt-get not working on the command line. The reason for this is: the Ubuntu Touch root file system is an immutable file system and thus shall not be changed via apt-get & friends by ordinary users. There are various discussions ongoing such as dpkg-divert'ing apt-get to a wrapper shell script that spits out an error message if rootfs is mounted read-only and someone tries to install packages the Debian/Ubuntu way. Other approaches are to mount some RAM disk over the rootfs, so apt-get can be used at runtime but changes to the system get reset at reboot. However, it is possible to mount the root filesystem read-write and test newer package versions (as UT core developers do regularly, in fact). If you tinker with this, it is recommended to reflash your device (don't wipe user data, when you reflash!) from time to time, because adding packages or package upgrades to your rootfs may over time corrupt the integrity of the rootfs. One reason for apt-get breaking the rootfs and thus your Ubuntu Touch development device is that the upgrade process of the rootfs image is incremental, so update tarballs sometimes contain only those parts that got changed between this and your previous upgrade (sometimes, upgrades contain a complete rootf image, depending on the interval between upgrades). If files from an incremental update tarball mix into a rootfs that got tinkered with via apt-get, you really end up on your own. Re-flashing will grab the complete rootfs tarball and wipe the whole rootfs and reinstall a fresh version of the newest rootfs image. Developers also do this in regular intervals to ensure their test device is clean again before running more/other tests.

17 June 2026

Dirk Eddelbuettel: rspdlite 0.1.0-1 on CRAN: New Package!

Very happy to share that a new package rspdlite arrived on CRAN today in its inaugural version 0.1.0-1. It wraps and provides the (header-only) C++20 library spdlite which its author describes (aptly) as tiny, fast, capable. Just like its bigger sibbling spdlog (which we wrapped as rcppspdlog), it is written by Gabi Melman. However, with a focus on C++20 and compile-time configuration, it is lighter, nimbler and faster. It is also still a fairly young project so changes may occur. I have been working on this for about a month, and it is ready for use by R and C++. It contains the initial upstream release 0.1.0, and I plan to follow the upstream versioning making this first release as 0.1.0-1. The package itself provides the headers for use from other C++ projects (i.e. mostly other packages), as well as a simple R wrapper so that logging can occur from either C++ or R. It will generally access the single logger instance in a compilation unit. So for a package built against these header it would be shared library of that package. At present we provide the basic logging level setters and getters, formatting accessors, and two (compile-time) options of a null logger and a file-based logger. More options are availble from the C++ level, multiple logging sinks are but one example. Some examples are provided in the package as an R example and a C++ example; these are probably best examined from the sources. The NEWS entry for this release is simply and just announces that we have a release. More details are in the ChangeLog and the GitHub repo.
Changes in version 0.1.0-1 (2025-06-08)
  • Initial complete version and CRAN upload

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub. You can also sponsor my Tour de Shore 2026 ride in support of the Maywood Fine Arts Center.

16 June 2026

Mike Gabriel: Ubuntu Touch development - 24.04-2.0 Beta and Meaning of Branching-Off

The next Ubuntu Touch major release is approaching rapidly, yesterday we reached a major step in the preparation of the upcoming Ubuntu Touch 24.04-2.0 release: The branching-off (see below on what that is). Ubuntu Touch 24.04-2.0 Beta is Now Available Part of this development release step is the publication of the 24.04-2.0 Beta release images, for more details and information see:
https://ubports.com/blog/ubports-news-1/ubuntu-touch-24-04-2-0-beta-is-n... And additionally, find below some background information on how we maintain various Ubuntu Touch releases in parallel via Git(Lab). In fact, the release model of Ubuntu Touch has partially been adopted from how we in Debian maintains our various Debian versions in parallel, only that in Ubuntu Touch we use Git(Lab) for maintaining the different package versions and not, like in Debian, the APT archive itself. What does 'Branching-Off' Mean? Last Saturday, in the UBports Q&A, I explained Ubuntu Touch's "branching-off", an aspect of the Ubuntu Touch release workflow based on Git(Lab). To make this accessible to even more people, here it comes as a write-up: We host many Git repositories on GitLab, and our primary work is done on the main branches, which contain the bleeding-edge code. When a merge request is deemed critical for stable versions of Ubuntu Touch, we cherry-pick it into a release series branch. Currently, we land our changes in the main branches and then cherry-pick them to the ubports/24.04.1.x branches. The 'branching off' process for the upcoming 24.04-2.x release means that our current main branches will be copied over to create new branches for this release cycle, namely ubports/24.04-2.x. This has two major implications. First, any item that hasn't been translated by the time of the branch-off will not receive any more translation updates during the 24.04-2.x cycle. This is why it is crucial that translation work is completed before the branching-off. Warning of Breaking Changes arriving soon in 26.04-1.x Daily Development UT Images Second, looking ahead to the release after 24.04-2.x, we will be approaching 26.04-1.x. The OS base will change to Ubuntu 26.04 LTS, hopefully being ready for release to Ubuntu Touch users before the end of the year. We already have a list of features we want to land there. Because we plan to include various major changes, such as the switch from Mir 1 to Mir 2, new calendar and contacts backends, Qt6-based core apps and service components, etc., the likelihood of breaking changes at the beginning of the 26.04-1.x release cycle (which will become the next main branches' target) is very high. The Ubuntu Touch 24.04-2.0 Release Schedule The current release schedule is estimated to be: 25 May 2026 [done]
Platform stability freeze 24.04-2.x 25 May 2026 [done]
String freeze 24.04-2.x 15 June 2026 [done]
Branching-off (and unfreeze 26.04-1.x development), UT image release: 24.04-2.0 Beta 22 or 29 June 2026 [coming]
Final freeze for 24.04-2.x, UT image release: 24.04-2.0 RC 6 or 13 July 2026 [coming]
Release version 24.04-2.0

Vincent Bernat: Building a Soviet Nail Factory: how KPIs killed efficiency

In 2008, I landed my second job, in the network team at Orange Portails1, the division behind the websites and search engine of the French telecom operator Orange. The place ran like clockwork: a comprehensive technical setup, a dedicated team for every part of the business, and room to focus on what I do best. A few years later, none of that mattered: thanks to an obsession with the numbers, we could no longer deliver new services on time.

Disclaimer This is a story I like to tell to warn people about Goodhart s law.2 As these events happened almost 15 years ago, my recollection is a bit fuzzy. I left in 2012.

The first years During my first years, the department operated like a startup. Its cradle was the French company Echo. They built a search engine. France T l com bought it and renamed it Voila. It was the most visited search engine in France in the early 2000s. France T l com consolidated the portal activities into the Wanadoo Portails division, later renamed Orange Portails. The technical environment was excellent. We had many internal tools:3 a ticket system, an RRD-based graphing tool, an IPAM, a reporting tool, and an SNMP-based alerting tool.4 We deployed our Linux servers with CFEngine. We installed systems and applications from internal Debian repositories. We documented everything in a private MediaWiki instance. Supervision was performed with an ancestor of Xymon. The network architecture was clean and scalable with little legacy. We onboarded new people in a day. It was a nurturing environment for me. I developed several tools: lldpd, an 802.1AB implementation, Snimpy, a pythonic binding for Net-SNMP, Wiremaps, a layer-2 discovery tool with a time machine to know which device is connected where, Kit r , a tool to simulate network conditions, QCSS-3, a controller for load-balancers, and ipoo, a service available through a Jabber chatbot and a Greasemonkey script to expose IP-related information. I added SNMP support for Keepalived and Quagga. I also started this blog, with articles like Anycast DNS, TLS-related articles like TLS computational DoS mitigation, SNMP-related articles like Integration of Net-SNMP into an event loop, Linux-related articles like Tuning Linux IPv4 route cache, and an article about VXLAN long before it was cool.

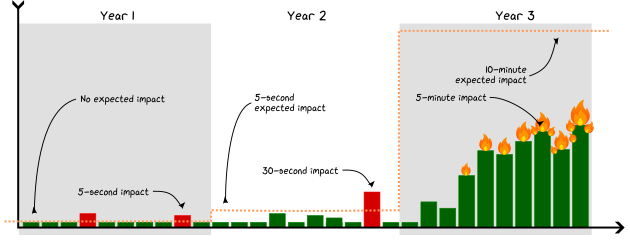
The collapse When we needed new servers, the on-site team would take a set from the inventory, install our base Linux distribution on them, put them in the datacenter, and cable them to the top-of-the-rack switches. We opened a ticket describing the servers we needed, and one week later, our servers were available. Orange wanted to know if this team was performing well, so they asked for KPIs. They decided to use the number of tickets completed in a year. They asked to double this number. So instead of one ticket for a new service, we would open six tickets one per server. By the end of the year, the KPIs had more than doubled. Everybody saw it as a success for performance management. So, they asked to do the same for the next year. Now, we needed to open a ticket per server and per step. Again, the KPIs doubled. Behind the scenes, the tickets went to different people and were no longer handled in order. So, for the next year, it was decided to have meta-tickets and meetings to follow the progress of these tickets. Of course, all these extra steps pushed the KPI even higher. This performance management method spread to the other teams.5 Everything became slower. Instead of a couple of weeks, a new service now took six months. We built a Soviet nail factory. But the KPIs were good, and we stopped caring. Let me give you another example. We had to estimate the impact of each night operation. We weren t half bad: we declared most operations without any expected impact. Most of the time, there was no impact. One time out of five, there was a 5-second impact. We were told to try harder to meet our expected impact. What did we do? We started declaring a 5-second expected impact. One day, we got a 30-second impact and were told we failed to match the expected impact. In the end, we declared most operations with a 10-minute expected impact, and we stopped caring: instead of carefully shifting traffic around, we allowed ourselves a 5-minute impact. And our KPIs were never better.
Graph showing the impact of night operations. Year after year, the impact tolerance has been increased. In the final year, the expected impact is 10 minutes, and all operations remain under this threshold. However, the impacts are much more significant than they were in the first year.
An artist's rendering of the evolution of impacts over the years.

KPIs are not bad, but they are easy to break. Use them carefully: let the people doing the work help choose the metrics, and tie those metrics to the quality of the service for example, with service level objectives. Otherwise, even dedicated people stop caring, game the system, and eventually quit.6

  1. Internally, this division was named Hebex. It was located in Bagnolet (next to Paris) and Sophia-Antipolis (near Nice).
  2. Goodhart s law often gets the credit, but Campbell s law describes my experience even better: the more you lean on a number to make decisions, the faster people corrupt it.
  3. At the time, SaaS was not really a thing. I remember we considered, with a couple of colleagues, selling Wiremaps as a SaaS, with homomorphic encryption for the database. But who would outsource their observability stack?
  4. Snalert was a metacircular alerting tool in Perl. It was able to poll a very large number of SNMP targets in a short timespan. All our monitoring was SNMP-based, including system monitoring.
  5. My team also managed the rules of many Linux-based firewalls. To increase our KPIs, we used the same method: rather than accepting one ticket with a flow matrix, we requested one ticket per flow.
  6. Orange is not unique. Google s promotion process is another well-known example of a broken KPI. Michael Lynch explains it in Why I Quit Google to Work for Myself.

15 June 2026

Freexian Collaborators: Debian Contributions: Go default compatibility, Trimming build-essential, Python upstream engagement and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-05 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

Go default compatibility, by Helmut Grohne At the MiniDebConf Hamburg, Andrew Lee had prepared a talk on how Debian accidentally chooses Go compatibility. Helmut joined Tobias Quathammer and Andrew Lee in looking into the problem. Go has a compatibility system where modules declare a desired Go version to be compatible with. This influences various features such as whether RSA keys smaller than 1024 bits are accepted. Unfortunately, Debian s way of building Go packages is unique in setting GO111MODULE=off, which practically implies a very old compatibility version that enables a number of insecure settings. Most Linux distributions use the default GO111MODULE=on and therefore consult a go.mod file that often declares a sensible version. While doing so is the way for Debian longer term, getting there involves major changes so we also sought a more short term workaround. We developed a patch to the Go compiler that would enable it to pick up a compatibility version from the environment. Tobias uploaded it to unstable. The next step is communicating the declared compatibility version from go.mod to the compiler via the new variable. Then, rebuilding the archive resolves the immediate symptoms. This does not save us from having to perform the larger transition to GO111MODULE=on, but this shortcut can be backported to trixie.

Trimming build-essential, by Helmut Grohne One of the harder problems of the architecture cross bootstrap is correctly expressing the Build-Depends of glib during the toolchain bootstrap. It implicitly depends on build-essential, which happens to depend on libc6-dev. This poses a cycle. It applies even for cross building, because it is interpreted for the host architecture and that there is no way of satisfying this dependency during the toolchain bootstrap. Given discussions at MiniDebConf Hamburg with Jochen Sprickerhof and others, a seemingly stupid idea evolved: Let s delete build-essential. What looks insane on the surface might deserve a second look. Given how we moved away from C, C++ and autotools, what is in build-essential no longer is required by much of the archive. With the rise of debputy, debian/rules no longer has to be a makefile. While the task would be huge, those packages relevant to architecture bootstrap could explicitly support building without the implied dependency making their dependencies explicit. In a number of cases, this amounts to issuing a dependency on g++-for-host. This dependency requires the use of architecture-prefixed tools. Therefore, Helmut wrote a debhelper change that makes it always pass build tools to various build systems. This also enables more packages to honour environment variables such as CC and CXX.

Python upstream engagement, by Stefano Rivera Stefano attended PyCon US (at personal expense) to improve upstream relations and ensure Debian s voice is heard where it needs to be. On Friday there was a packaging summit (notes) with good discussion on the future of the wheel format, and some discussion of the new abi3t shared library format for free-threaded python. In preparation for the event, Stefano did a complete review of the current patch stack. Stefano s primary goal was to get some of Debian s patches merged during the sprints, and results were mixed. Some trivial patches (e.g. GH-150098, made progress and merged, but the most consequential patch Debian is carrying is still blocked. Stefano will continue to try to drive progress on this.

Miscellaneous contributions
  • Carles worked on po-debconf-manager: Reviewed Catalan translations for 6 packages, submitted 10 packages to maintainers, and removed 3 packages from po-debconf-manager.
  • Carles worked on check-relations: Continued improving the backend, including importing source package build dependencies to better support analysis of Debian blends. Added support for ignoring packages using regular expressions and source package names in response to user feedback. Used the tool to report 5 new bugs and followed up on previously reported issues.
  • Helmut sent a cross build patch on behalf of a customer.
  • Helmut uploaded debvm and guess_concurrency both featuring improved reproducibility and documentation.
  • Helmut continued maintaining rebootstrap and made it correctly handle binNMUs of gcc-defaults. Additionally, he poked at existing gcc patches giving answers, rebasing or closing them.
  • Helmut supported the video team in Hamburg mixing audio.
  • Helmut continued to report undeclared file conflicts of various kinds and corresponded with maintainers about them.
  • Antonio attended a debate during the Brazil Internet Forum about the impacts of the child protection regulation (ECA Digital) on free software operating systems.
  • Antonio worked on Debian CI to improve the system transparency for users. This included listing any pending jobs explicitly in the job lists for each package/architecture/suite page, as well as adding a queue status page that users can check for an estimate of test latency.
  • Antonio worked on several Debian CI maintenance tasks, including but not limited to some monitoring improvements, replacing usage of fonts-font-awesome with fonts-fork-awesome, and adding the ability in debci to configure a global notice (which is being used in Debian CI to point to the system status pages).
  • Antonio started doing some tests related to the change of default Debian CI backend from lxc to incus-lxc. This helped identify an omission in the creation of incus-lxc images. It was missing dpkg-dev, which caused a few packages that assumed its presence to fail. In the end, the incus-lxc backend will be fixed to include dpkg-dev by default in the image, but that uncovered an undeclared dependency in gem2deb (Ruby packaging helper) and in ruby-byebug, both already fixed in unstable.
  • Stefano did some minimal work on debian-reimbursements to get it working with current versions of django-allauth.
  • May included the discovery of several high-severity Linux kernel root exploits. Stefano updated kernels and rebooted debian.social infrastructure several times.
  • Stefano supported the Hamburg miniDebConf s wafer website during the event, and set up an instance for the 2027 edition too.
  • Stefano supported the bursary team issuing bursaries for DebConf 26.
  • Stefano uploaded routine updates of python-pip, pystemmer, snowball-data, snowball (making up a mini, uncoordinated snowball transition), python-authlib, python-discovery, python-installer, python-mitogen, python-pipx, python-cachecontrol, platformdirs, and python-virtualenv.
  • Stefano fixed a small number of bugs in dh-python, culminating in the 7.20260524 upload.
  • Thorsten finally managed to upload a new upstream version of hplip. He also uploaded a new upstream version of epson-inkjet-printer-escpr. Last but not least with the help of other contributors he could fix bugs in lprng.
  • Lucas and Santiago contributed significantly to the DebConf 26 Content team; helping to organize the team, review and rate talk proposals.
  • Lucas also supported a packaging sprint held in India by rebuilding and publishing the latest results of the Ruby 3.4 transition effort.
  • Santiago continued contributing to the efforts to organize DebConf 26, especially supporting the local team with different tasks.
  • In collaboration with Emmanuel Arias, Santiago is mentoring Aryan Karamtoth, a GSoC participant that is working to introduce linux live-patching support in Debian. The GSoC project started in May, with community bonding and coding. Santiago reviewed a merge request to prepare the clang-extract package for debian. clang-extract is one of the building blocks that will help to extract specific functions from large C code, so only relevant code can be patched, without recompiling the whole original basecode.
  • Anupa assisted Jean-Pierre Giraud with the point release announcements for Debian 13.5 and Debian 12.14.
  • Colin backported various security fixes from OpenSSH 10.3 to all supported releases (including LTS and ELTS).
  • Colin backported IP quality-of-service fixes to OpenSSH in trixie. The situation there had been unsatisfactory for some time, and upstream reworked their QoS support in OpenSSH 10.1 in a way that typically produces much better results.
  • Colin imported new upstream versions of 26 Python packages, and fixed around 25 RC bugs for the Python team.

12 June 2026

Mike Gabriel: Ayatana Indicators: Call for Translations

In the process of preparing a major Ubuntu Touch release (v24.04-2.0, coming soon...) we will also update Ayatana Indicators in Ubuntu Touch. Last week various new features have been added to some of the indicators (toggle switch to keep the display switched on permanently, blue tooth pairing agent, redesign of the keyboard indicator, etc.) and those changes require translation updates. If you can, please visit [1] this weekend and help translating Ayatana Indicators into your native language. Thanks so much!!! light+love
Mike [1] https://hosted.weblate.org/projects/ayatana-indicators/

Reproducible Builds (diffoscope): diffoscope 319 released

The diffoscope maintainers are pleased to announce the release of diffoscope version 319. This version includes the following changes:
[ Jochen Sprickerhof ]
* Improve header detection for Sphinx documentation projects.
You find out more by visiting the project homepage.

9 June 2026

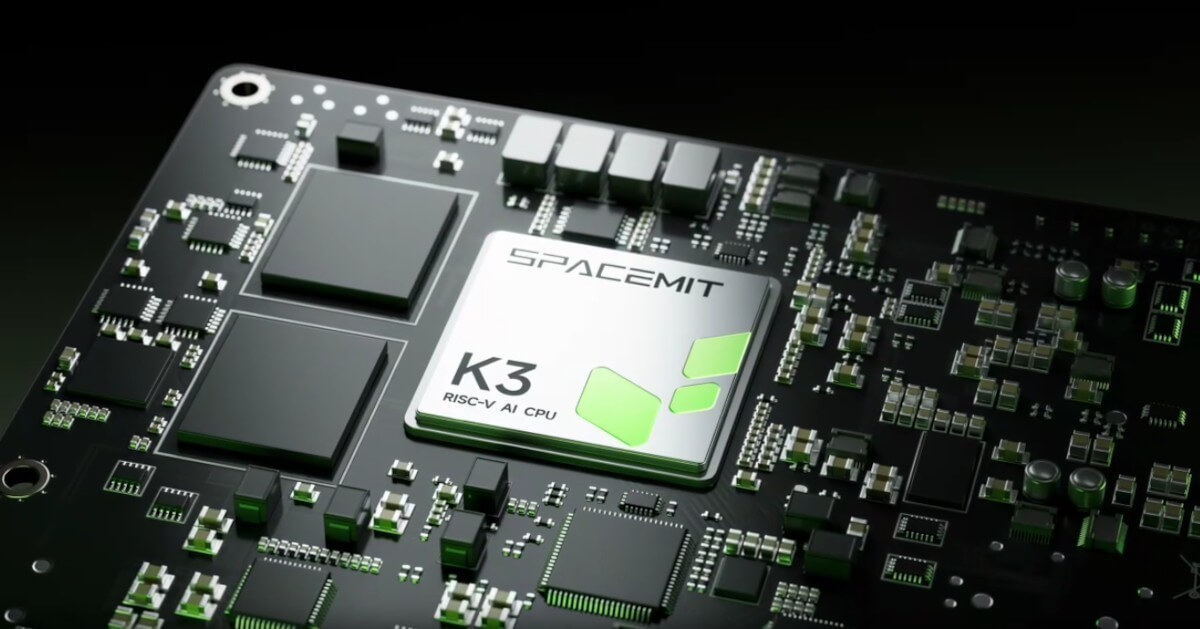
Otto Kek l inen: SpacemiT K3 is a compelling RISC-V AI CPU, but difficult to buy

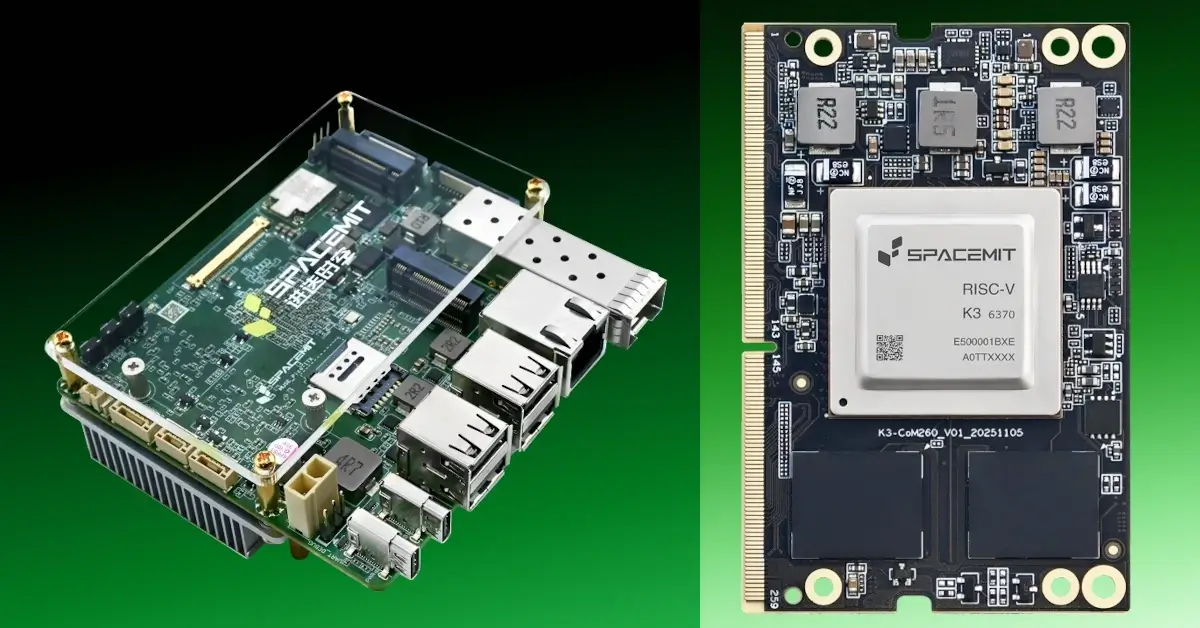
Featured image of post SpacemiT K3 is a compelling RISC-V AI CPU, but difficult to buyThe RISC-V CPU architecture has been gaining a lot of popularity since it launched in 2014, and now that the industry is standardizing on the RVA23 level that includes vector support as a mandatory extension, we are likely to see a lot more edge- and IoT devices with the ability to run local LLMs at reasonable speed, and most importantly at very compelling prices. SpacemiT is a Chinese RISC-V CPU manufacturer that launched on May 11th, 2026, their long-anticipated next-gen RISC-V AI chip K3. It is among the earliest RISC-V CPUs that adhere to the RVA23 standard and performance-wise it is quite capable, providing 130 KDMIPS general computing power, 60 TOPS on INT4 which translates to about 15 tokens per second when running a 30 billion parameter large language model. The aspect that really makes it stand out is: SpacemiT also develops their own Debian-based Linux distribution Bianbu OS, and seems to have collaboration going on with the wider community. Their community site seems active, and they also have a dedicated X account @spacemit_riscv and Reddit account r/spacemit_riscv posting relevant progress info on Linux kernel upstreaming activities. The X account is also responsive, as evidenced by its replies to my questions. Canonical lists the SpacemiT K3 pico-ITX and K3 CoM260 Kit on its official Ubuntu for RISC-V partner-built hardware page, which strengthens the perception that upstream Linux support is being taken seriously. The SpacemiT folks also gave an interesting talk at the 2026 Ubuntu Summit that includes a peek into their roadmap with future K3, K7 and K9 models. For technical details, see SpacemiT s K3 pico-ITX documentation, the Jetson Orin Nano-compatible K3 CoM260 board documentation and documentation of the K3 processor itself. The SpacemiT K3 pico-ITX board and the K3 CoM260 board side-by-side (not to scale)
Comparing the resellers SpacemiT does not sell anything directly to consumers. Instead you need to buy a board that includes the K3 chip from an integrator. Currently the main resellers are: All of the above are Chinese companies that ship to customers both inside and outside China. DeepComputing stands out as the only one that actually has done real integration and ships the K3 on a custom board, while the others simply resell the SpacemiT-produced K3 pico-ITX and K3 CoM260 Kit.

Milk-V Milk-V is a RISC-V specialized integrator, as the name already implies. They sell the K3 under the name Jupiter2. Of all the K3 pico-ITX reseller product pages, the Jupiter2 presentation is the nicest and most detailed. Unfortunately their order page at arace.tech only states that it is a pre-order with no information about shipping schedule, taxes, or other details like what SSD is included (if any). Based on the pictures it does ship with a Milk-V branded case. The 32 GB RAM lists at 504 EUR, which is a very reasonable price. The @MilkV_Official account on X recently promoted the K3.

Documentation and support As of this writing, the Milk-V Jupiter2 documentation site is just a stub and has no actual content, and only two links to the SpacemiT K3 documentation site. For support there is a web forum with a dedicated Jupiter2 section. There is also a Matrix space, but unlike their other products, there is no dedicated Jupiter (neither v1 nor v2) channel.

Community size and open source involvement At least one prior Milk-V product was certified by Canonical, which indicates there is some collaboration in progress. Canonical also lists the Milk-V Titan on its official Ubuntu for RISC-V partner-built hardware page.

Sipeed The Sipeed K3 announcement is well written (in English) with all the relevant details and links to additional PDF manuals. However, their main page at sipeed.com says nothing about the K3, so one must know the subpage URL to access it. They offer both the K3 CoM260 kit compatible with Jetson Orin Nano carrier boards, and the stand-alone K3 pico-ITX-sized motherboard. The CoM260 kit is only 10 USD cheaper than the full pico-ITX motherboard, so choosing the latter is a no-brainer if starting from scratch. The pico-ITX model with 32 GB DDR5 RAM sells for 639 USD. The product page does not mention anything about hard disk size, so you don t really know exactly what you will be getting if placing an order. There is no indication about case, Wi-Fi antennas or power supply either, so most likely they are not included. Their store.sipeed.com website does not work at all, and their Taobao and AliExpress stores are not public and only accessible to registered users. The order page also says nothing about shipping time, delivery time, or taxes. The X account @SipeedIO is active and recently posted pictures of shipments in progress.

Documentation and support The main documentation wiki does not yet have any K3 content at the time of writing. There is a Discord channel for general RISC-V discussion, and their MaixHub also has a discussion board, but I didn t find anything K3-specific.

Community size and open source involvement Sipeed has had at least one of their previous devices certified by Canonical, which indicates they are active in the community. Note that the other RISC-V company SiFive that also has had hardware certified and officially supported by Canonical is a different company, despite the very similar name.

Banana Pi Banana Pi announced that they offer both the K3 CoM260 kit and the K3 pico-ITX motherboard version. Their product page for the K3 confusingly shows a MediaTek product in the page banner rather than the SpacemiT K3. Based on the product description and the fact they renamed the product as BPI-SM10, it seems to ship with some carrier board. The product pictures look identical to the SpacemiT documentation and there is no picture of the carrier board, and details are very sparse. The pico-ITX version with 8 GB RAM and 128 GB SSD sells for 293 USD and the CoM260 developer kit with the same specs sells for 287 USD and the 32 GB RAM with 128 GB SSD model sells for 595 USD. The shop page shows only five orders so far and items are currently out of stock. As there was no 32 GB RAM version of the pico-ITX available at all, this isn t an option for me as I want to run 30B parameter models that need the larger memory version. Of all of these resellers, the Banana Pi website seems the most outdated. It does not have a search feature, it is not mobile-friendly, pictures can t be pinched to zoom in and so forth. Product names are also almost all identical, and as the product listings only show the beginning of the product name, figuring out what product is what requires extra effort that just makes the online purchase experience plain bad.

Documentation and support I was only able to find the documentation page for the CoM260 kit, but none for the pico-ITX version. For support there is a forum, but the category list does not show any section for K3, and the forum search prohibits using the search term k3 as too short.

Community size and open source involvement Banana Pi has a long history in the ARM single-board computer market, but their presence in the RISC-V ecosystem is still growing. Their X account @sinovoip has posted only once about the K3 and otherwise promotes their ARM boards. However, their community culture page does express a commitment to open hardware in general, but there is no visible K3-specific community activity.

Firefly Firefly s K3 product page is comprehensive. Based on the details, they do not offer the K3 pico-ITX variant at all, but only the K3 CoM260 board inside the AIBOX-K3 Firefly RISC-V Edge Mini PC product. This is a feature-complete offering with a Jetson Orin Nano carrier board and case. The AIBOX-K3 with 32 GB RAM and 128 GB SSD in a case sells for 689 USD in their own Firefly.store. Unfortunately it only has HDMI and there is no USB-C with DisplayPort support, which is a deal-breaker for me personally. Interestingly, Firefly also offers rack-mounted servers with K3 as the CPU.

Documentation and support The wiki link on the product page is broken. The Firefly wiki does have a section for the AIBOX-K3, but it too has a broken link. It seems that as of the time of writing, there is no wiki section for this product yet. For support there is a web forum, which does have at least one K3 thread covering guides such as Hermes Agent installation, though broader K3-specific sections are still sparse.

Community size and open source involvement Firefly s X account @TeeFirefly has had no posts since 2024, and their GitLab/T-Firefly shows mostly 2024 activity, with only one repository updated in 2025 and nothing in 2026. Historically they have built a moderate community around their ARM-based Rockchip boards, with active forums and wiki contributions for those product lines. Their RISC-V K3 offerings are newer, and likely need a lot more polish to be attractive products overall.

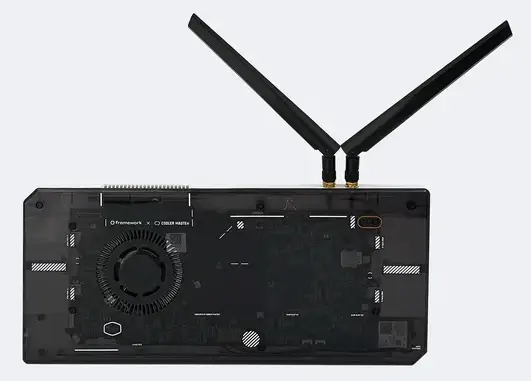
DeepComputing Last, but certainly not least, is the laptop manufacturer DeepComputing that offers a Framework laptop compatible motherboard with the SpacemiT K3 chip. They also sell the plain motherboard, or with the Cooler Master case, which allows one to easily connect it to an external monitor and keyboard and use it as a desktop computer. The plain board with 32 GB RAM and no SSD sells for about 882 EUR. Shipping of the first batch is expected to start by end of June 2026. Their X account @DeepComputingio promotes this DC-ROMA RISC-V Mainboard III as their flagship product, so they seem to put a lot of effort into it. The overall product design and packaging seems good. Of all the K3 resellers and integrators that I was able to find, DeepComputing is the only one that actually designs their own boards with the K3 processor, while all the other vendors above are simply reselling the vanilla K3 boards with or without a case. After reviewing all these options I decided to buy the DC-ROMA RISC-V Mainboard III for Framework Laptop 13 with 32 GB RAM, 1 TB SSD and the Cooler Master case, totalling about 1100 EUR.

Documentation and support DeepComputing maintains product information for their RISC-V hardware at github.com/DC-DeepComputing/Framework, with documentation of the newest Mainboard III (FML13V05) still being finalized ahead of the first batch shipment. They provide community support through Discord and web forum, although the latter has very little activity.

Community size and open source involvement DeepComputing has established itself as a pioneer in RISC-V laptops, beginning with the DC-ROMA. I have seen their stand at FOSDEM, which shows they are genuinely active in the open source community. Canonical lists DeepComputing s first mainboard / FML13V01 on its official Ubuntu for RISC-V partner-built hardware page, and it seems likely that they will continue to collaborate with Canonical with the new model once it ships. While the underlying Linux enablement depends on SpacemiT s upstream efforts, DeepComputing s involvement helps bridge the gap between reference hardware and consumer-ready products. DeepComputing K3 board in the Cooler Master case

Conclusion After weighing all the options, I ended up placing an order with DeepComputing for their custom K3 board with the Cooler Master case. Despite the premium price, the active community support and the properly documented promise of a complete, working system made it easy to place an order with confidence. The SpacemiT K3 is poised to be one of the most significant RISC-V chips for local AI workloads, thanks to its RVA23 compliance and high tokens per second potential. Yet the buying experience in mid-2026 remains fragmented and incomplete. Hopefully this is just because the product is new, and they will get the purchase experience polished soon. What struck me most during this process was how poor the customer experience is across nearly all of these vendor websites: broken links, missing search functions, outdated product banners, pages that show the wrong product entirely, and no information about shipping times, stock levels, taxes, and so on. One wonders why these companies don t fully invest in their web presence. Personally I would assume they likely have enough customers already, primarily through domestic channels like Taobao and JD.com, that they do not feel any pressure to improve their international-facing sites. However, I did also review what was offered on Taobao, and the product details were very incomplete there too. Taobao, however, has a built-in live chat with almost all sellers, which can be used to ask questions and thus compensate for missing product details. I don t fully understand why the sales process seems unpolished. The websites feel almost like an afterthought a checkbox to claim global reach while the real business apparently happens elsewhere via closed platforms or via inaccessible reseller channels. It is a frustrating reminder that in the RISC-V hardware world, the technology may be open and global, but the purchase experience is less so.

7 June 2026

Dirk Eddelbuettel: RQuantLib 0.4.27 on CRAN: Small Extension

A new minor release 0.4.27 of RQuantLib, the first in over a year, arrived on CRAN a couple of minutes ago, has just now been uploaded to Debian, and is being built for r2u as well. QuantLib is a rather comprehensice free/open-source library for quantitative finance. RQuantLib connects (some parts of) it to the R environment and language, and has been part of CRAN for nearly twenty-three years (!!) as it was one of the first packages I uploaded to CRAN. This release of RQuantLib brings an update to the interface for all equity options, vanilla and exotics as well as implied volatilities. We now support the option maturity via either an actual maturity date, or the (fractional business-day years) numeric. This uses a clever little Rcpp trick I should discuss in a separate blog post. We also re-ran compileAttributes() to re-create the RcppExports.cpp file now using a slightly improved way of calling Rf_error for an ongoing Rcpp transition, and did some more standard maintenance. The details from the NEWS file follow as usual.

Changes in RQuantLib version 0.4.27 (2026-06-07)
  • All equity option functions can now take either a (fractional) time span to expiry or a given date, and accept a daycounter setter.
  • Two very old schedule helpers had a superfluous try/catch removed.
  • The continuous integration setup received a minor update.
  • The RcppExports.cpp file was updated to aid a Rcpp transition.

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

Vasudev Kamath: debsecan-mcp v0.1.2 released to PyPI

I finally carved out some time today to prepare and release debsecan-mcp v0.1.2 to PyPI. During this release, I integrated PyPI's trusted publisher mechanism, which authenticates directly via GitHub Actions and eliminates the need for manual uploads or static API tokens.
What is New? There are no feature updates in this release; the changes are strictly focused on PyPI publishing requirements. This was handled entirely within the Antigravity IDE. The primary change replaces the python-apt dependency with python-debian for version comparison. PyPI rejects packages that reference external Git repositories, and python-apt lacks an official PyPI release. The original python-apt logic remains intact: if the system has python-apt installed, the server defaults to it. Otherwise, it falls back to the comparison logic implemented via the python-debian NativeVersion class.
What Next? The next release will introduce a standalone CLI utility called debvulns. It mirrors debsecan functionality but surfaces the cleaner, richer vulnerability data already implemented in debsecan-mcp. The code is written, and I will release it once testing is complete. I also owe a post explaining my rationale for designing a CLI utility alongside the MCP server, and my broader thoughts on CLI vs. MCP workflows. I aim to publish that next week.

5 June 2026

Russell Coker: CPUs and Debian Package Building

Introduction I have just bought a HP Z4 G4 with W-2125 CPU for $320 and I decided it was a good time to do some benchmarks on Debian package building to see which system I should use for that. The W-2125 CPU scores only 9,954 on the passmark multithread test but scores 2,546 on single thread [1]. Passmark seems to have some limitations as the only DDR3 system that s important to me at the moment (the HP Z420 workstation my parents use which cost me $750 in 2021) with a E5-2620 CPU scoring 5,325 for multithread and 1,113 for single thread [2]. From the passmark results one would expect that the system is slightly more than twice as fast as the Z420 for operations that involve less than 4 CPU cores. For the initial tests of the Z4 G4 I ran them with hyper-threading enabled as 4 cores isn t much by today s standards and also the machine in question is going to be less exposed to hostile data and contain less secret data than most of my systems so the security risks of hyper-threading are less of a concern. I did some tests with a couple of tasks that are very important to me, building SE Linux policy packages (something I may do a dozen times in a day) and building Warzone 2100 (which I do less often but is the most intensive build process I regularly run). At the bottom of this post there are tables with the results from building these packages on my Z640 workstation with a E5-2696 v4 CPU [3], the Z420, and the new machine. For the Warzone 2100 package I tested building on my Z840 dual CPU system [4]. I didn t test building the SE Linux policy on the Z840 this time because that package can t take advantage of even 22 cores. When I initially got the Z840 running it built the policy packages faster because the Z640 had an older CPU that was slower for single core operations than the CPUs in the Z840. BTRFS Compression For some time I have noticed significant differences in compile time on my workstation, a factor of more than 2. I did more tests and noticed that top showed something like the following, those kernel threads are all BTRFS related, except for gfx which is probably something graphical caused by running Chrome with about 300 tabs open.
2144316 root      20   0       0      0      0 I  26.6   0.0   0:36.76 kworker/u88:20-btrfs-endio-write                                                                                                                                                                             
2221470 root      20   0       0      0      0 I  23.7   0.0   0:01.85 kworker/u88:12-gfx                                                                                                                                                                                           
2221436 root      20   0       0      0      0 I  15.1   0.0   0:07.48 kworker/u88:8-btrfs-compressed-write                                                                                                                                                                         
2166191 root      20   0       0      0      0 I  12.8   0.0   0:15.80 kworker/u88:23-btrfs-compressed-write                                                                                                                                                                        
2126387 root      20   0       0      0      0 I  10.2   0.0   1:29.11 kworker/u88:4-events_unbound 
I had been running BTRFS with the mount option compress=zstd:15 which caused much of the performance problems when building. It was also a random performance issue which I think happened due to the BTRFS 30 second write-back sometimes taking more than 30 seconds during the build process which then caused a second write-back. I did tests on ZSTD compression levels 5, 8, 10, and 15. 15 was never good and often really bad. 10 was not unbearable but consistently slower. 8 was sometimes as fast as 5 and sometimes quite a bit slower. I didn t test levels below 5 because I need to have some compression and it seemed that the benefits of reducing compression were dropping off below 8. I found that the BTRFS compression delay is not counted in system time for the process. I think it s the fsync() system calls in the semodule and dpkg-deb programs that cause the delays related to BTRFS compression waiting for kernel threads. BOINC I have all my systems other than laptops running BOINC in the background so that CPU power is used for scientific research when I don t have any personal use for it [5]. I believe that it s immoral to waste CPU power when it could be used for research. In the below table which has test results from building the package with and without BOINC, and with different ZSTD compression levels in BTRFS all the worst entries were from when BOINC was running apart from one where ZSTD level 15 compression was used. The really poor performance with ZSTD level 15 was an outlier, but it wasn t an uncommon outlier so I left it in. Running BOINC in the background configured to use all CPU cores caused a significant increase in user CPU time (the time a CPU core spent actually running the program). My initial thought was that it s partly related to turbo boost . The Intel ARK page for the CPU in the Z420 shows that it s main clock speed is 2.0GHz with a 2.5GHz turbo boost [6]. The turbo boost is apparently largely based on temperature and apparently limited to one core, so if the other CPU cores are all being used then the CPU will probably be too hot to have the turbo boost and if it happens it might not happen for my compile processes. The ARK page for the E5-2699 v4 (which is a similar CPU to the E5-2696 v4 that I m using but is officially documented by Intel) [7] shows that it has a base clock speed of 2.2GHz and a turbo boost speed of 3.6 GHz. 322 vs 244 seconds of user CPU time means running 32% slower which can plausibly be explained by the lack of a 64% turbo boost with a bit of help from the 55MB L3 cache being thrashed. Turbo boost would only be a noticeable issue for building packages like the SE Linux policy packages which doesn t take much advantage of multi-core CPUs. For a build process to average at best 362% CPU use there has to be large parts of the process that are limited to one or two cores which can potentially give a benefit from turbo-boost. When building the Warzone 2100 packages most of the build time is running basis-universal which is a multi-threaded program to compress GPU texture data. This usually causes a load average of 300+ on the Z640 or 600+ on the Z840. But the build time is still increased by more than 50% on both the Z640 and the Z840 when BOINC is running in the background, which seems to be an indication that it s not related to turbo boost. I verified that BOINC is running at IDLE schedule priority with the following command:
# chrt -p $(pidof -s einstein_O4MD_2.01_x86_64-pc-linux-gnu)
pid 2974874's current scheduling policy: SCHED_IDLE
pid 2974874's current scheduling priority: 0
In theory this means that BOINC won t affect foreground processes. Hyper Threading on the W-2125 The best claims I ve seen about HT are 15% to 30% performance boost. The best I ve actually seen in the past is about 18%. Seeing a 10% benefit for building Warzone 2100 is at the low end of the range I expected. 8 virtual cores is not many for a build process that causes a load average of 600+ when running on a system with 44 real cores. I was surprised to see a 6% performance benefit in hyper-threading for building the SE Linux policy as I didn t think there was enough use of threading or multiple processes to allow that. Many build scripts use a number of processes that match the number of apparent CPU cores. While make -j 88 might give a theoretical performance benefit on a 44 core system it will also take a lot of RAM and any paging will outweigh the benefits of hyper-threading. On a system with only 4 real cores there s less potential for using too much RAM and as security isn t so important on that system I will leave it on. Comparing the CPUs The best results of the Z640 and Z4G4 are only 50% faster than the best results of the Z420. The Z420 has a E5-2620 CPU which is far from the fastest CPU available for that system the E5-2687W has 8 cores and rates 10,021/1,669 on passmark [8] which is far better than the 5,331/1,114 the E5-2620. The E5-2687W is the fastest CPU that HP lists as supported by the Z420 and it supports DDR3-1666 RAM as opposed to the DDR3-1333 that is the fastest that the E5-2620 supports. With suitable hardware upgrades the Z420 would probably only take about 20% longer to do builds of the SE Linux policy and other packages that can t take advantage of more than 8 CPU cores. The Z4G4 system has 4 RAM channels which means that you should get some performance benefits from having 4 DIMMs, my system currently has 2 and I haven t yet managed to get more DDR4-2666 DIMMs. But I d still expected a W-2125 CPU with 2*DDR4-2666 DIMMs outperform any E5-26xx CPU with 4*DDR4-DDR-2400 DIMMs for tasks that average less than 4 CPU cores. In retrospect I would have been better off getting a HP Z820 (two socket server with DDR3 RAM) than the first DDR4 systems I got. It seems that for reasonable size builds a two socket system comes close to twice the speed of a single socket system. I did briefly own a HP ML350 two CPU system with DDR3 RAM but it was too noisy for my intended use as a deskside workstation so I sold it. Things to Investigate I plan to do more investigation on BTRFS compression, how to get the best compression without excessive delays and how to recognise when delays are happening. I have some SSDs that have sustained write speeds as low as 15MB/s (Crucial P1 series) so for those I could probably have very high compression levels without slowing the system down. The fact that BIONC slows things down so much seems to be a bug. When processes are running with the IDLE scheduling class there shouldn t be such significant delays. Is it due to cache thrashing? How can I best get BOINC suitably throttled when I m sitting at my workstation, I don t want BOINC connecting to the local X server (which it repeatedly tries to do). Do I need to tune my kernel for better handling of IDLE scheduling? When I get more DIMMs in the Z4G4 I need to do more tests to see if it gives an overall performance boost. Also the Z4G4 system has a BIOS option for sub NUMA which basically means treating the different RAM channels on a single CPU as NUMA zones, I enabled that option which does nothing presumably because I only have 2 DIMMs, the results when I have 4 DIMMs will be interesting. I will also do some NUMA tests on the Z840 to see what benefits it gives. I have a selection of RAM speeds that will work in the Z4G4, if I have enough spare time I ll test what difference that makes for CPU bound tasks that matter to me. For package building fsync() is not helpful, if the system crashes before it s done then I will just do the build again. For a build cluster it is probably a good feature and probably doesn t affect aggregate performance when multiple packages are built at the same time, but for the single user case probably not. I will investigate libeatmydata for package building [9]. Conclusion The progress in CPUs seems to have slowed down a lot recently. The main benefits seem to be in more CPU cores and for newer sockets with more RAM channels. The CPUs that do have improvements in single core performance are the i9 series (which mostly doesn t come with motherboards supporting ECC) and AMD CPUs (which is rare in enterprise class hardware). Maybe I should get a server with an i9 or AMD CPU for tasks that need a fast turn around with a small number of cores. That would probably outperform any CPU designed for large core counts for things like building the policy and setting up test VMs (which depends on package installation speed that is single core bottlenecked). The W-21xx CPUs seem to offer little benefit over the E5-26xxv4 CPUs and not a lot of benefit over E5-26xx CPUs (with DDR3). Even the W-22xx CPUs look like they aren t going to offer a lot as they are only an incremental improvement over the W-21xx series. I had considered making the Z4G4 my main desktop workstation after the high end W CPUs become affordable, but it looks like that won t be worth it until such CPUs drop from the current ebay price of $900 to $100. I think I ll keep waiting for a decent socket LGA3647 or DDR5 based server [10] for my next significant upgrade. Tables Building SE Linux Refpolicy
System BOINC Compression CPU Time Elapsed CPU%
Z640 no 8 248.82user 55.58system 1:23.88elapsed 362%CPU
Z4G4 no 5 245.15user 34.63system 1:24.93elapsed 329%CPU
Z640 no 5 244.75user 34.87system 1:25.98elapsed 325%CPU
Z4G4 no 10 245.21user 35.64system 1:29.63elapsed 313%CPU
Z640 no 8 248.71user 55.90system 1:33.01elapsed 327%CPU
Z640 no 10 250.90user 55.78system 1:42.12elapsed 300%CPU
Z640 yes 8 298.19user 69.30system 1:59.77elapsed 306%CPU
Z640 yes 10 300.58user 68.90system 2:01.53elapsed 304%CPU
Z420 no 5 359.01user 44.95system 2:07.33elapsed 317%CPU
Z640 yes 5 322.40user 71.82system 2:34.66elapsed 254%CPU
Z420 yes 5 372.03user 42.95system 2:42.15elapsed 255%CPU
Z640 yes 15 299.26user 67.18system 2:59.77elapsed 203%CPU
Z640 no 15 250.05user 54.60system 3:07.61elapsed 162%CPU
Building Warzone 2100
System BOINC Compression CPU Time Elapsed CPU%
Z840 no 10 6549.21user 89.46system 4:18.90elapsed 2564%CPU
Z840 no 5 6533.81user 90.50system 4:19.24elapsed 2555%CPU
Z640 no 5 7040.87user 183.12system 7:13.50elapsed 1666%CPU
Z840 yes 5 8039.52user 169.62system 8:02.86elapsed 1700%CPU
Z640 yes 5 7486.44user 205.03system 11:09.97elapsed 1148%CPU
Z4G4 no 5 7891.32user 74.45system 17:48.03elapsed 745%CPU
Z4G4 no 10 7942.10user 77.43system 17:58.72elapsed 743%CPU
Hyper-Threading
Build HT Compression CPU Time Elapsed CPU%
Warzone yes 5 7891.32user 74.45system 17:48.03elapsed 745%CPU
Warzone yes 10 7942.10user 77.43system 17:58.72elapsed 743%CPU
Warzone no 5 4492.45user 59.09system 19:59.01elapsed 379%CPU
Warzone no 10 4497.28user 59.46system 20:07.15elapsed 377%CPU
Refpolicy yes 5 245.15user 34.63system 1:24.93elapsed 329%CPU
Refpolicy yes 10 245.21user 35.64system 1:29.63elapsed 313%CPU
Refpolicy no 5 180.84user 29.74system 1:32.30elapsed 228%CPU
Refpolicy no 10 180.29user 30.07system 1:35.01elapsed 221%CPU

4 June 2026

Reproducible Builds: Reproducible Builds in May 2026

Welcome to the May 2026 report from the Reproducible Builds project. These reports outline what we ve been up to over the past month, highlighting items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website. In this month s report, we cover:

  1. Debian to ship reproducible packages in forky and beyond
  2. Holger Levsen on reproducing official Debian packages
  3. Reproducible Builds 2026 summit to be held in Gothenburg, Sweden
  4. Kettle: Attested Builds for Verifiable Software
  5. New rebuilderd version announced
  6. Reproducible open source messengers
  7. Distribution work
  8. Misc news
  9. Patches
  10. Documentation updates


Debian to ship reproducible packages in forky and beyond In a huge change in Debian s reproducibility policy, the Debian Release Team announced that:
we ve decided it s time to say that Debian must ship reproducible packages. Since yesterday, we have enabled our migration software to block migration of new packages that can t be reproduced [on reproduce.debian.net] or existing packages in testing that regress in reproducibility.
That is to say, if newly-uploaded packages are not reproducible, they won t be considered candidates for inclusion in the next stable release of Debian codenamed forky. (Some exceptions may be granted.) This news generated a number of articles and comments in various news outlets:

Holger Levsen on reproducing official Debian packages Reproducible Builds developer Holger Levsen gave a talk at the 2026 Hamburg MiniDebconf this year on the topic of reproduce.debian.net - reproducing what is distributed from ftp.d.o. Holger s talk announced that Debian intends to ship only reproducible packages in forky and beyond (see above), but also talked more broadly about reproducible builds, our testing framework and the Debian archive. That is to say, moving away from testing whether a package is reproducible in a theoretical sense (eg. whether we can build it twice in different environments and achieve the same result in our test system), and attempting to reproduce the same .deb files in the official Debian archive itself. This small-sounding distinction is actually essential, as this is the only means through which the reproducible builds technique can determine whether build systems are compromised are not. A video (32m37s) of the talk is available, as are Holger s slides.

Reproducible Builds 2026 summit to be held in Gothenburg, Sweden As initially announced in March 2026, we will be having our yearly Reproducible Builds summit 2026 in Gothenburg Sweden, from September 22 until 24, followed by two days of hacking! Further information will be provided on our website and on the rb-general mailing list very soon.

Kettle: Attested Builds for Verifiable Software Andr Arko and Amean Asad published a paper this month on Kettle, a build system that produces cryptographically verifiable provenance for software built inside Trusted Execution Environments :
A Kettle build records the source commit, dependency set, toolchain, build environment and output artifact digests in a provenance document produced inside a measured confidential VM. The SHA-256 digest of that document is committed to the TEE platform s attestation report-data field, so the hardware-signed attestation report is itself the signature on the provenance, with the signing identity chaining to the TEE manufacturer s root of trust rather than to the build infrastructure operator. Because the CVM image is itself reproducible, its launch measurement is public and stable, which lets a build requester pre-attest the CVM before submitting any input and optionally deliver source over a TLS channel terminated inside it, so the build runs end-to-end confidentially without the host ever seeing source code in plaintext.
A PDF of the paper is available online.

New rebuilderd version announced rebuilderd, our server designed for monitoring the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. A new version, 0.27.0, was released this month, with the following headline changes:
  • Improved .udeb support
  • Breaking changes in pkg sync configuration
  • Manual cleanup needed for Arch Linux instances
As kpcyrd s announcement mentions:
The new rebuilderd package is currently available in the extra-testing repository. Note the Arch Linux package is upgraded from v0.25.0 from v0.27.0; please be patient with the database migrations on first restart, and make yourself familiar with the breaking changes in v0.26.0 too.

Reproducible open source messengers GitHub developer BarbossHack is maintaining an repository/page on GitHub to track reproducibility status of open source messengers .

Distribution work In Debian this month, the loong64 architecture was added to reproduce.debian.net. This is a 64-bit Reduced Instruction Set Computer (RISC) instruction set architecture developed by Loongson. Vagrant Cascadian performed Non-Maintainer Uploads (NMUs) in Debian for several packages with outstanding patches over a year old. These included rocdbgapi, onevpl-intel-gpu, python-pytest-shell-utilities, python-mt-940 and pympress. On tests.reproducible-builds.org, Vagrant Cascadian fixed the huge spike in build failures by adding passwd to the base tarballs, and re-enabled building gcc and binutils packages with PGO (Profile Guided Optimization) and LTO (Link Time Optimization) to avoid giving a false sense of reproducibility. Inconsistencies on the reproducibility of the condor package were brought up on the Debian reproducible-builds mailing list. Following a hunch, Vagrant Cascadian eventually identified the issue was related to embedded kernel versions which was then fixed upstream and fixed in Debian as well. Lastly, 40 reviews of Debian packages were added, 68 were updated and 75 were removed this month adding to our knowledge about identified issues. A number of issue types were updated, such as the addition of a new sphinx_reading_durations toolchain issue [ ], a golang_mango_generates_manpages_with_build_date issue [ ] and a random_offset_id_in_cython_linetrace [ ]. In addition, the timestamps_in_qhc issue was refocused to timestamps_in_qhc [ ].
In Fedora, Jelle van der Waa submitted a request for an official Fedora rebuilderd package which was reviewed by Neal Gompa.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.

Misc news On our mailing list this month:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:

Documentation updates


Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

1 June 2026

Amin Bandali: Free software activities in May 2026

Hello and welcome to my May 2026 free software activities report. A lot's been going on in my life offline so I took a bit of a hiatus from doing these reports, but I've had a fairly productive month of May so I thought it'd be nice to do another one for this month.

GNU & FSF
  • GNU Emacs:
    • ffs-0.2.2: I finally polished and published my ffs package for GNU Emacs on GNU ELPA. Many thanks to Protesilaos for rounds of code review and feedback for improving and polishing the package in preparation for submission to GNU ELPA.
    • bug#81101: Trying to visit https://www.emacswiki.org in EWW I noticed it fails with a Somebody wants you to give them money error due to the anti-bot challenge being served with a HTTP 402 (Payment Required) response. So I landed a patch 12eec781ed6 to no longer do that. Thanks to Emacs comaintainer Sean Whitton for reviewing and approving my proposed patch.
    • bug#81107: I noticed that in EWW, unlike <input type="submit"> HTML buttons, <button> elements were not tab-stoppable, leading to poorer usability and accessibility. So I landed a patch ec3d662de0b to fix that. Thanks to Emacs comaintainer Eli Zaretskii for reviewing, providing feedback, and accepting my proposed change.
    • Emacs Chat with Sacha Chua: I joined Sacha for a new episode of her Emacs Chat podcast, where we talked about Emacs and life. I gave a quick tour of my Emacs configuration, discussing at length my configurations for EXWM (Emacs X Window Manager) among other topics like Emacs's facility for visually indicating buffer boundaries in the fringe by setting indicate-buffer-boundaries and my convenience configuration macros.
  • maintainers@: I started the next long-overdue round of emails to GNU package maintainers to confirm the contact information we have on file for them and get a brief status update about their packages. Emails are sent in small batches to keep the workload of handling the responses manageable for assistant GNUisances.
  • GNU Spotlight: I prepared and sent the May GNU Spotlight to the FSF campaigns team for publication on the FSF's community blog and the monthly Free Software Supporter newsletter.

Debian
I've begun the work toward updating the Jami package in Debian unstable again, which means I need to package new releases of its direct and indirect dependencies. For OpenDHT, I need to update RESTinio, and to do that I first need to package expected-lite and sobjectizer for Debian:
  • #1120837: ITP: expected-lite expected objects for C++11 and later
  • #1137609: ITP: sobjectizer C++ implementation of Actor, Publish-Subscribe, and CSP models
I've been working on packaging both and hope to have them uploaded to the archive in the next days and weeks. That's it for this month's report. Take care, and so long for now.

29 May 2026

Dirk Eddelbuettel: RcppArmadillo 15.2.7-1 on CRAN: Micro Upstream Update

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1272 other packages on CRAN, downloaded 46.6 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 693 times according to Google Scholar. This versions updates to the 15.2.7 upstream Armadillo release made today. The package has already been updated for Debian, and built for r2u. As the upstream was modest, we for once skipped reverse-dependency checks. That bet paid off as CRAN found no issues among the over 1270 reverse dependencies. However, one package referenced a package archived today, hence invisible to CRAN and triggered a (false positive) NOTE of reference to non-existing package . We came close. Anyway, the package made it CRAN shortly thereafter following the standard brief email exchange explaining the false-positive nature of the NOTE. All changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.2.7-1 (2026-05-29)
  • Upgraded to Armadillo release 15.2.7 (Medium Roast Deluxe)
    • More efficient checks for aliasing

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub. You can also sponsor my Tour de Shore 2026 ride in support of the Maywood Fine Arts Center.

26 May 2026

Russ Allbery: Review: The Keeper of Magical Things

Review: The Keeper of Magical Things, by Julie Leong
Publisher: Ace
Copyright: 2025
ISBN: 0-593-81593-9
Format: Kindle
Pages: 353
The Keeper of Magical Things is a cozy fantasy novel. It is set in the same universe as The Teller of Small Fortunes, but it doesn't share any characters or plot, they're not marketed as a series, and so far as I can remember neither book would spoil the other. It is Julie Leong's second novel. Certainty Bulrush is a novice mage with one reliable magical ability: She can talk to objects and occasionally convince them to do small things. This ability is clearly magical, which means Certainty is indeed a mage, but this appears to be all that her magic can do. The Guild has requirements for the level of magical ability required to become a full mage that go beyond talking stained quilts into unstaining themselves, which is why Certainty has been a novice for six years. This by itself is a problem, since Certainty's cohort keeps passing her by. Worse, though, is that she was counting on the wages of a full mage to pay for her brother's training to become an apothecary. The thought of failing him is extremely upsetting. Certainty therefore jumps at an offered mission to take a cartload of excess magical objects that are causing a dangerous build-up of energies in the Guildtower to safe storage in the small and very unmagical village of Shpelling. Successful completion of that mission will earn Certainty a promotion to Deputy Keeper and therefore to a full mage. This is the opportunity she didn't know to hope for. The only drawback is that she will have to work with Mage Aurelia, the famously off-putting farspeaker and magical scholar the other novices refer to as the ice witch. Aurelia is every bit as icy, formal, and condescending as Certainty was afraid she would be, Shpelling grows nothing but garlic, and the inhabitants are suspicious and hostile. The mission could be a disaster if it weren't for Certainty's stubborn good nature. It's arguably a spoiler to say that there's an enemies to lovers romance, but it's hinted at on the cover, mentioned in the publisher's blurb and, honestly, if you aren't expecting an enemies to lovers romance by a few chapters in, you probably haven't read many books of this sort. I found The Keeper of Magical Things quietly enjoyable but extremely predictable. If you're in the mood for what it's offering, the predictability may not be a problem, but it was the kind of book where the direction the plot was headed was so obvious that I got a bit bored waiting for it to arrive. Certainty has a good heart, humble origins, limited but specialized magical ability, and a self-esteem problem, and if you've read much fantasy, you've probably read two or three or a dozen other books with variations of this protagonist. You know how they generally turn out, and that is indeed what you're going to get after the obligatory setbacks and tragedies and looming catastrophes. Aurelia, similarly, is a variation on a character you've probably met before. Certainty discovers, not long into the book, that the brilliant over-achieving mage wears a necklace (supposedly to help her focus) that constantly whispers to her how inadequate she is and how much harder she needs to work. The necklace was given to her by her parents. This book is not exactly subtle. That said, there's nothing wrong with the characterization. Both Certainty and Aurelia are interesting characters with rounded-out personalities, although it takes a while before Certainty (or the reader) is allowed to see Aurelia's. Their interactions with the inhabitants of Shpelling are fun to watch in the same way that it can be fun to watch people play PowerWash Simulator. You're not in overwhelming suspense about what's going to happen, but the details are amusing and it is satisfying to watch people with good intentions slowly fix things. There is a plot, and a villain, and a not-subtle message about how everyone deserves acknowledgment and respect, and the hours I spent reading about these characters were enjoyable. The problem with this book isn't that there's anything wrong with it, but that it may not give you more enjoyment than another book you could have been reading. I quite liked The Teller of Small Fortunes in part because it surprised me in a few places and the main character felt a bit different than the typical fantasy protagonist. The Keeper of Magical Things felt less original and a bit more obvious and predictable. It was still quietly good-hearted and occasionally charming, and I think I'll still remember Certainty in a few months, but I'm not feeling the urge to push it into anyone's hands. If you're in the mood for a gentle fantasy about finding solutions to people's problems and waiting out the prickliness of people who desperately need a friend, you may enjoy this a great deal. Just don't expect unpredictable twists and turns or a surprising plot structure. An apparent third book in this loose series, The Isle of Lonely Monsters, is currently scheduled for publication in 2027. Rating: 6 out of 10

24 May 2026

Vincent Bernat: Sharding a routing table for lock-free reads in Go

To associate routing information like AS paths or BGP communities to flows, Akvorado can import routes through the BGP Monitoring Protocol (BMP). As the Internet routing table contains more than 1 million routes, Akvorado needs to scale to tens of millions of routes.1 This has been a long-standing challenge,2 but I expect this issue is now fixed by using RIB sharding, a method that splits the routing database into several parts to enable concurrent updates.

Previous implementation Akvorado connects 2 elements to build its RIB:
  1. a prefix tree, and
  2. a list of routes attached to each prefix.
Akvorado BMP RIB implementation before sharding with the memory layout of each structure and a single lock.
Akvorado BMP RIB implementation without sharding. One single read/write lock.
In the diagram above, the RIB stores five IPv4 prefixes and two IPv6 prefixes. One of them, 2001:db8:1::/48, contains three routes:
  • from peer 3, next hop 2001:db8::3:1, AS 65402, AS path 65402, community 65402:31,
  • from peer 4, next hop 2001:db8::4:1, same ASN, AS path, and community,
  • from peer 5, next hop 2001:db8::5:1, AS 65402, AS path 65401 65402, community 65402:31.
The rib structure is defined in Go as follows:
type rib struct  
    tree          *bart.Table[prefixIndex]
    routes        map[routeKey]route
    nlris         *intern.Pool[nlri]
    nextHops      *intern.Pool[nextHop]
    rtas          *intern.Pool[routeAttributes]
    nextPrefixID  prefixIndex
    freePrefixIDs []prefixIndex
 
The prefix tree uses the bart package, an adaptation of Donald Knuth s ART algorithm. The benchmarks demonstrate it outperforms other packages for lookups, insertions, and memory usage.3 Plus, the author is quite helpful.

Storing routes in a map The list of routes for each prefix is not stored directly in the prefix tree: it would put too much pressure on the garbage collector by allocating per-prefix arrays. Instead, the RIB assigns a unique 32-bit prefix identifier for each prefix, either by picking the last available prefix identifier from the freePrefixIDs array if any, or using the nextPrefixID value before incrementing it. Then, the routes are stored in the routes map, leveraging the optimized Swiss table in Go. To retrieve routes attached to a prefix, we look them up one by one in the routes map with a 64-bit key combining the 32-bit prefix index with a 32-bit route index matching the position of the route in the list. Akvorado scans routes from the first to the last to find the best one.4 It knows there is no more route if the route key returns no result.
type prefixIndex uint32
type routeIndex uint32
type routeKey uint64

Interning routes A route contains a BGP peer identifier, a partial NLRI5, the next hop, and the attributes.
type route struct  
    peer       uint32
    nlri       intern.Reference[nlri]
    nextHop    intern.Reference[nextHop]
    attributes intern.Reference[routeAttributes]
    prefixLen  uint8
 
type nlri struct  
    family bgp.Family
    path   uint32
    rd     RD
 
type nextHop netip.Addr
type routeAttributes struct  
    asn              uint32
    asPath           []uint32
    communities      []uint32
    largeCommunities []bgp.LargeCommunity
 
To save memory and allocations, NLRI, next hops, and route attributes are interned : a 32-bit integer replaces the real value. The mechanism predates the unique package introduced in Go 1.23. We keep it because it has different trade-offs:
  • It uses explicit reference counting instead of relying on weak pointers.
  • It works with non-comparable values implementing Hash() and Equal() methods.6
  • It uses explicit pool instances. This will be useful for sharding.
  • It has better performance. See for example this benchmark.
  • It consumes half the memory thanks to unsigned 32-bit references instead of pointers.
  • But it is not safe for concurrent use.

Why does it not scale?

Note At AS 12322, we don t use BMP yet.7 But Gerhard Bogner had the patience, availability, and technical skills to help me debug this issue.

The global read/write lock is a bottleneck in this implementation. But how? There are several users of the RIB, each with its own set of constraints:
  • The Kafka workers look up the RIB to enrich flows with routing information. They are bound by the number of Kafka partitions.8 Akvorado also adjusts their number to ensure efficient batching to ClickHouse. On our setup, the number of workers oscillates between 8 and 16. As we want to observe the latest data, we cannot afford for the Kafka workers to lag too much.
  • The monitored routers send route updates through the BMP protocol. When connecting, they can send millions of routes.9 After the initial synchronization, updates are sent continuously and may spike from time to time. The router detects a stuck BMP station when its TCP window is full and resets the session in this case. While Akvorado implements a large incoming buffer, it still needs to update the received routes with the write lock held fast enough to avoid being detected as stuck.
  • When a remote BGP peer goes down, Akvorado flushes the associated routes by walking the RIB with the write lock held. When a monitored router goes down, Akvorado waits a bit but eventually flushes all the associated routes.
In short: on a busy setup, lock contention is high for both readers and writers, and neither can lag too much behind.

RIB sharding

First step: basic sharding To remove the global lock, the RIB is split into several shards, each one handling a subset of the prefixes:
Akvorado BMP RIB implementation after sharding with the memory layout of each structure and one lock per shard.
Akvorado BMP RIB implementation with sharding.
The prefix tree stays global and is protected by a single lock. Each shard gets its read/write lock, its route map, and its intern pools to store NLRIs, next hops, and route attributes, which would not have been possible with Go s unique package. The prefix indexes are also sharded: the 8 most significant bits are the shard index and the 24 remaining bits are the local prefix index. Gerhard confirmed that after this blind change, the BMP receiver chugged steadily. Later, I wrote a concurrent benchmark over half a million synthetic but plausible routes10 partitioned over 0 to 8 writers, churning routes as fast as possible, while 1 to 16 readers continuously look up a set of 10,000 routes. I don t know if this benchmark is realistic, but it confirms the improvements for both read and write latencies:
Two heatmaps. One for read latency ratio, the other for write latency ratio. Both of them comparing the speedup with colored tiles between the code before sharding and after sharding. Most tiles are green.
Read and write latency performance improvement after sharding.
It also shows that a high number of writers degrades read latency.

Second step: lock-free reads The single read/write lock protecting the prefix tree is the next target. The bart package provides alternative mutation methods returning an updated tree using copy-on-write. Readers don t need the global lock any more, leaving it only to synchronize writers. The prefix tree is boxed in an atomic pointer.
Akvorado BMP RIB implementation for sharding with lock-free reads. It shows the memory layout of each structure.
Akvorado BMP RIB implementation with sharding and lock-free reads.
Without a lock, readers can now fetch a stale prefix index when walking their copy of the tree if a concurrent writer removes the last route attached to this prefix index and recycles it for another prefix. To avoid this issue, we combine the prefix index with a generation number and store them in the tree:
type generation uint32
type prefixRef struct  
    idx prefixIndex
    gen generation
 
type rib struct  
    mu     sync.Mutex
    tree   atomic.Pointer[bart.Table[prefixRef]]
    shards []*ribShard
 
Each shard stores the generation number for each local prefix index. The generation number increases by one if the associated prefix index is freed. When looking up the routes attached to a prefix index, the reader checks if the generation number matches. Otherwise, it assumes the index was recycled and the list of routes is empty.11 You can see this case in the diagram above for prefix index 5, stored with a generation index of 3, while the current value in the []generations array is 4. The generation number could overflow, but it is not a problem as lookups are quick. Running the concurrent benchmark against this new implementation shows the improvements for the read latency as soon as the cost of the copy-on-write prefix tree is amortized.
Six heatmaps. Three for read latency ratio, three others for write latency ratio. They compare the numbers without sharding, with sharding, and with lock-free reads, pair by pair. For read latency, most tiles are green, showing an improvement of the second step. For write latency, the speedup is negative for a low number of readers.
Read and write latency performance improvement after lock-free reads. The middle column shows the cumulative improvements of both steps.

Among the multiple attempts to optimize the BMP component, RIB sharding is one of the more satisfying. Akvorado 2.2 implements the first step. PR #2433, drafted while writing this blog post, implements the second step and was released with Akvorado 2.4.

  1. Each router exporting flows doesn t need to send its routes. When Akvorado does not find a route from a specific device, it falls back to a route sent by another device. It is up to the operator to decide if this is a good enough approximation.
  2. I made many attempts to scale the BMP component. See for example PR #254, PR #255, PR #278, PR #2244, and PR #2245. Despite these efforts, this component remained problematic for some users. See discussion #2287 as the latest example.
  3. It keeps improving: bart 0.28.0 features a new implementation that trades a bit of memory for greater lookup performance. I did not test it yet, as I have been preparing this blog post for a couple of months already.
  4. Akvorado prefers the route matching the exact next hop. Otherwise, it falls back to any other route. This is an approximation. An alternative would be to have one prefix tree for each BGP peer but it would require configuring all routers to export their routes. pmacct s BMP daemon implements this approach.
  5. If we consider the BGP RIB as a database, the Network Layer Reachability Information (NLRI) is the primary key. Its content depends on the BGP family. With IPv4 or IPv6 unicast, this is the prefix. For VPNv4 and VPNv6 families, it includes the route distinguisher. If you enable the ADD-PATH extension, the NLRI also contains a path identifier. In our implementation, we don t store the prefix as we get it from the looked-up IP address using the prefix length stored separately.
  6. The Hash() methods rely on the hash/maphash package and on the unsafe package to avoid memory copies. See for example the Hash() function for the nlri structure.
  7. Despite being an author or co-author of the first BMP-related RFCs since 2016 (RFC 7854, RFC 8671, RFC 9069), Cisco did not implement it in a usable way in IOS XR until version 24.2.1. We still need to upgrade a few routers to enable this feature.
  8. KIP-932 introduces, in Kafka 4.2, the concept of share groups to enable cooperative consumption on the same partition. This is not supported in Akvorado yet.
  9. You can configure BMP to send routes for each BGP peer before or after applying the incoming policies. In this case, you can get more than one million routes for each transit peer. You can also tell BMP to send the local RIB, which only contains the best path for each prefix.
  10. The prefixes are random, but the prefix size distribution and the AS path length distribution follow the data provided by Geoff Huston.
  11. Alternatively, we could retry the lookup, but it would be pointless: the RIB is an eventually consistent database, and an empty list was a correct answer at some point in the recent past.

23 May 2026

Petter Reinholdtsen: Command line Norse God of Wind Hr svelg move the clouds

A while back, I came across the AI Fabric system created by Daniel Miessler. I liked its approach of providing command-line tools for filtering text using artificial idiocy services, allowing stepwise operations to be applied to a piece of text. The output of one operation can then serve as the input for another in other words, Unix pipeline processing powered by large language models. I do no longer remember exactly how I discovered it, but suspect it was via Matthew Berman's video "How To Install Fabric - Open-Source AI Framework That Can Automate Your Life". While the idea and concept behind AI Fabric appealed to me, its implementation has continued to rub me the wrong way. It started off as a Python project that I could only get running by downloading random programs from the internet using Poetry. I tried to assess how much work it would take to package all its missing dependencies for Debian. However, before I got very far, the project shifted away from Python and over to Go. This new implementation also relied on a build system that seemed to encourage users to run arbitrary code downloaded from the internet to get software working, and further moved to a language I do not master as well as Python. The change bothered me enough that I set my effort to set up a working command line LLM tool in Debian aside for several months. By chance, I came across a simple Python recipe in January demonstrating how to communicate with a llama.cpp API server. I had already been working on packaging llama.cpp for Debian together with the rest of Debian's AI team, and was fortunate enough to own a working instance with a 24 GiB VRAM GPU from AMD, allowing me to run useful models. Until that point, I had only used the basic web client provided by the Debian package, lacking the spare time to explore what else could be done. Then, I found this simple 50 line Python script demonstrating how to interact with llama.cpp's OpenAI-compatible API. I decided to revive the AI Fabric concept, and implement the Unix pipeline filter tool with as few dependencies as possible. It is now operational and working very well, relying solely on standard Python features. The tool include a copy of the LLM recipes from the AI Fabric project (called "patterns"), enabling easy access to request summaries, translations, code review and other useful tasks. Several hundred patterns are included, though I have only tested about ten so far. The LLM API server can be specified in ~/.config/hraesvelgr/config.ini like this:
[server]
url=https://some.llm.example.com:8080/v1/
model=Qwen/Qwen3.6-27B-FP8
With this configuration in place (you can also specify these values directly on the command line), you can specify a pattern and a file to process like this:
% bin/hraesvelgr --pattern explain_code bin/hraesvelgr
EXPLANATION:
This Python script is a client tool for interacting with an AI
service (likely a local LLM server) to process text using prompts
defined in the "AI Fabric" repository. It reads system and user
prompts from markdown files, sends them along with input text to a
chat completion API endpoint, and prints the generated response.
Key components:
1. It uses argparse for command-line argument parsing
2. The  send_chat_completion_request  function formats messages
   (system, user, query) into JSON and sends them via HTTP POST to
   an AI service endpoint
3.  read_file  function reads markdown files, replacing placeholders
   like  lang_code  with actual values from arguments
4. In main():
 - Parses command-line arguments for input file, API base URL,
   pattern type, language code, and debug flag
 - Ensures the base URL ends with a slash
 - Reads system prompt from data/patterns/ pattern /system.md
 - Optionally reads user prompt from data/patterns/ pattern /user.md
 - Reads input text either from stdin (when "-" is passed) or a file
 - Handles encoding fallback to ISO-8859-1 if UTF-8 fails
 - Sends the formatted request to the AI service and prints the response
The script assumes it's running in a directory containing a git
clone of https://github.com/danielmiessler/fabric/, which contains
the necessary prompt files.
This tool is designed to interface with local LLM servers that
support OpenAI-compatible chat completion APIs.
%
The list of available patterns can be viewed by running bin/hraesvelgr --list-patterns. I have found the summarize, translate, improve_writing, review_code, and explain_terms_and_conditions patterns particularly useful. For example using the latter combined with a text based web browser capable of dumping a page as plain text, can be done like this (originally formatted in markdown, I converted to HTML using pandoc for easier readability):
% w3m  -dump https://runbox.com/about/terms-service/   \
  hraesvelgr --pattern explain_terms_and_conditions
Executive Summary
This is a transparent, privacy-focused contract from
a Norwegian provider that generally respects user data rights and
operates under strict EU/EEA standards. However, it carries
strict liability limitations and an aggressive
data-deletion policy upon cancellation. The vibe is  Professional &
Privacy-First,  but you must manage your own backups and understand that
the company heavily shields itself from financial responsibility during
technical failures.
Key Takeaways
  • Your Data Stays Yours: Section 10.2 explicitly states Runbox will never use your transmitted or stored data for commercial purposes. This is a major privacy win.
[... trimmed output, as it is not the focus of this blog post ...] If you sign:
  1. Set up automated backups immediately. Use IMAP sync to a local drive or a secondary email provider before storing any critical documents or emails. Do not rely on Runbox as your only archive.
  2. Mark your calendar for the 30-day trial end date. Miss the payment window, and access closes instantly with no recovery period.
  3. Monitor price changes at renewal. Since they can adjust fees anytime, check their pricing page a few days before your subscription renews to avoid unexpected charges.
NO FORCED ARBITRATION CLAUSE FOUND.
REFUND POLICY IS STRICTLY CONDITIONAL (see Sections 4.2 4.5).
As you might have already noticed, I name my project after the Norse God of Wind. I found a nice description of the origin of the name on Wikipedia:
In Vaf r nism l (The Lay of Vaf r nir), Odin questions the wise j tunn Vaf r nir about the origin of the wind, and the j tunn answers:
He is called Hr svelg,
who sits at heaven s end,
a giant, in the shape of an eagle;
from his wings
they say the wind comes over all people.
(translated by John Lindow in Norse Mythology: A Guide to Gods, Heroes, Rituals, and Beliefs 2002)
The latest version of the code can be found at https://codeberg.org/pere/hraesvelgr/. Perhaps you will find it as useful as I did? As usual, if you use Bitcoin and wish to show your support of my activities, please send Bitcoin donations to my address 15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.

Next.

Previous.