Russ Allbery: Review: Whalesong
| Series: | Arcana Imperii #3 |
| Publisher: | Saga Press |
| Copyright: | 2025 |
| Printing: | August 2026 |
| ISBN: | 1-6682-1021-5 |
| Format: | Kindle |
| Pages: | 362 |
| Series: | Arcana Imperii #3 |
| Publisher: | Saga Press |
| Copyright: | 2025 |
| Printing: | August 2026 |
| ISBN: | 1-6682-1021-5 |
| Format: | Kindle |
| Pages: | 362 |
Welcome to the October 2026 report from the Reproducible Builds project!
In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third parties to come to a consensus on whether a build was compromised or not.
As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.
In this month s report, we cover:
SOURCE_DATE_EPOCH specification updates./GNUSparseFile.<pid>/<filename>). Because process IDs vary between build runs, however, archiving identical sparse input files yields different binary outputs.
In his report, Johannes outlined potential workarounds, such as running tar inside an unshared PID namespace where the process ID is pinned to 1, and proposed that GNU tar either omit the PID by default or provide a command-line flag to suppress it. Full details can be found in the post itself, and Johannes also filed the bug in Debian for completeness.
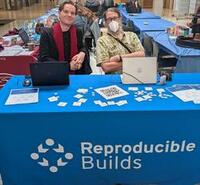
Reproducible Builds was present at SeaGL in Seattle, WA, on October 23rd & 24th. Thanks to everyone who attended and spoke with us!
Members of the Reproducible Builds project attended SeaGL (the Seattle GNU/Linux Conference) in Seattle, WA, on October 23rd & 24th. It was a fantastic opportunity to connect with local community members, discuss software supply chain security and share updates on build verification tooling. Thanks to everyone who stopped by our sessions or spoke with us during the event.
Founded in 2013, SeaGL is an annual free-as-in-freedom, grassroots technical summit dedicated to spreading awareness, community engagement and practical knowledge about free software, open hardware and libre culture.
diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 333, 334, 335 and 336 to Debian:
Recommends: guix from the diffoscope-minimal package as it is not minimal. (#1114739) [ ].tar file comparator [ ] and Vagrant Cascadian proposed an update in diffoscope in GNU Guix to version 335.
In Debian this month, 20 reviews of Debian packages were added, 28 were updated and 27 were removed this month adding to our knowledge about identified issues. One issue type was updated to reflect that Debhelper compat level 14 is no longer experimental. [ ]
In addition, Vagrant Cascadian performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included clhep, tea-cli, argparse-manpage, ruby-timers, mandos and cdebootstrap.
Lastly, Bernhard M. Wiedemann posted another openSUSE monthly update for their reproducibility work there.
SOURCE_DATE_EPOCH specification updates
As announced in last month s report, further work has been done by Bernhard M. Wiedemann regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes were originally submitted as merge requests on Salsa, and many of these have been approved or otherwise collapsed.
Bernhard s proposed modifications were independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests; as Bernhard writes, The other MRs could still use feedback from more people before December . Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list.
The SOURCE_DATE_EPOCH specification was first published in 2015 and updated in 2017.
libsoup library when built using debrebuild. Filed as Debian bug #1126440, the issue stems from a Meson build system check that inspects Apache and its local configuration during the build process, which fails inside debrebuild environments. His query solicited a number of replies (including one from an AI agent).
js8call.pywps.php-nesbot-carbon.kicad-library-utils.ros-dynamic-reconfigure.golang-github-anacrolix-log.complexity.node-uplot.python-poetry-dynamic-versioning.open-build-service.#reproducible-builds on irc.oftc.net.
rb-general@lists.reproducible-builds.org
A new release of prrd arrived at
CRAN today, and has already
been built for r2u and
on r-universe.
The prrd
package facilitates the parallel running [of] reverse dependency
[checks] when preparing R packages. It is used extensively for
releases I make of Rcpp, RcppArmadillo,
RcppEigen,
BH, and
others.
The key idea of prrd is simple,
and described in some more detail on its webpage and
its GitHub repo.
Reverse dependency checks are an important part of package development
that is easily done in a (serial) loop. But these checks are also
generally embarassingly parallel as there is no or little
interdependency between them (besides maybe shared build depedencies).
See the (somewhat dated) screenshot (running six parallel workers,
arranged in a split byobu session).
This release updates internals to allow for greater concurrency. SQLite is used as the backend, both
for the job queue (managed via the liteq package) as
well as for storing actual reverse-dependency test results. It is
well-known that SQLite copes quite
well with multiple readers. Multiple concurrent
writers are more challenging. We tended to get by via
BEGIN EXCLUSIVE pragma use, but still get occassional issue
even at a somewhat moderate concurrency levels. After some back and
forth and trying a few approaches, more recently we established one
first solution relying on very explicity (OS-level, filesystem-based)
locking via package filelock. That
worked.
We mentioned this in an
old liteq issue that had circled around the same
question with a number of posts over the years, but no resolution. This
comment seemingly awoke G bor, and he nailed this
years-open issue with a fine pull request deploying
BEGIN IMMEDIATE and well as a loop around
tryCatch to not immediately fail. I borrowed/ported that
approach to prrd and we now
have a second solution (and no longer need filelock). On a
somewhat better server with enough cores and memory, I am now running
eighteen concurrent workers watched via three multi-pane byobu windows. Works like a charm without
issues. At last! A big thanks to G bor for finding another
solution, and especially that only relies on SQLite.
The release is summarised in the NEWS entry:
Courtesy of my CRANberries, there is also a diffstat report for this release.Changes in prrd version 0.1.0 (2026-11-07)
- Concurrent operations are now supported via updated sqlite semantics borrowed with appreciation from liteq
- This follows an interim solution relying on filelock use; however this later package is not needed so no increase in dependencies
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.
b-cdn.net domain. As I depend on content
negotiation to serve AVIF and WebP images, I configure the CDN to cache
each image format separately.
I disable logging to avoid collecting personal
information. While the bunny.net GDPR page promises they anonymize data, it
is unclear what CloudFront keeps in its own logs when logging is disabled.
The only downside of the bunny.net CDN offering is the lack of HTTP/3. I asked
their support: two minutes later, they answered they are working on it but have
no ETA to share.
const servers = [
ipv4: "45.90.160.60",
ipv6: "2a0c:8881:5:100::1",
latitude: 48.88,
longitude: 2.22,
,
/* [ ] */
ipv4: "139.180.162.114",
ipv6: "2001:19f0:5800:1855:5400:6ff:fef0:4c0a",
latitude: -33.87,
longitude: 151.21,
,
];
const families = A: "ipv4", AAAA: "ipv6" ;
const records = A: ARecord, AAAA: AaaaRecord ;
export default function handleQuery(query)
const type = String(query.request.queryType).toUpperCase();
const family = families[type];
if (!family) return [];
// Get user location
const location = query.request.geoLocation;
// Build a list of candidates
let candidates = servers.map(
(s) => new Server(s[family], s.latitude, s.longitude, 100),
);
// Select the two closest alive servers
const selected = [];
while (selected.length < 2)
const server = RoutingEngine.getClosestServer(candidates, location, true);
selected.push(server);
candidates = candidates.filter((s) => s.ip !== server.ip);
// Return their IP addresses
return selected.map((s) => new records[type](s.ip, 3600));
RoutingEngine.getClosestServer() helper, which returns the
closest alive3 server to the user.4 Thanks to Doggo, we can
check it works as expected, at least for A:5
$ doggo --gp-from="Amsterdam" A vincent.bernat.ch
LOCATION NAME TYPE TTL ADDRESS
Amsterdam, NL
vincent.bernat.ch. A 3600s 45.90.160.60
vincent.bernat.ch. A 3600s 116.203.18.48
$ doggo --gp-from="Texas" A vincent.bernat.ch
LOCATION NAME TYPE TTL ADDRESS
Houston (TX), US
vincent.bernat.ch. A 3600s 5.161.44.145
vincent.bernat.ch. A 3600s 149.28.219.155
vincent HTTPS 1 first.geo alpn="h3,h2"
vincent HTTPS 2 second.geo alpn="h3,h2"
vincent HTTPS 3 . alpn="h3,h2"
; Bunny DNS must provide the two closest servers as "first.geo"
; and "second.geo" with geographic or latency routing.
first.geo A 45.90.160.60
first.geo AAAA 2a0c:8881:5:100::1
second.geo A 116.203.18.48
second.geo AAAA 2a01:4f8:1c0c:5eb5::1
vincent A 45.90.160.60
vincent A 116.203.18.48
vincent AAAA 2a0c:8881:5:100::1
vincent AAAA 2a01:4f8:1c0c:5eb5::1
., hence the last record at priority 3.
Moreover, unlike with a CNAME, Bunny DNS does not return the IP addresses for
first.geo and second.geo in the additional section. The resolver needs to
send a first request to get the HTTPS record, and a second to resolve
first.geo.
HTTPS records are still too new for this use case. Back to the drawing board!
export default function handleQuery(query)
const location = query.request.geoLocation;
let candidates = servers.map(
(s) => new Server(s.ipv4, s.latitude, s.longitude, 100),
);
// Select the two closest servers
const selected = [];
while (selected.length < 2)
const server = RoutingEngine.getClosestServer(candidates, location, true);
selected.push(server);
candidates = candidates.filter((s) => s.ip !== server.ip);
// Compute the distance to the user for each of them
const [first, second] = selected.map((s) =>
GeoDistance.calculate(s, location),
);
// If the second one is at twice the distance and at more than 1000 miles
// from the first, return only the first one with a TTL of 2 minutes.
if (second > 2 * first && second - first > 1000)
return [new ARecord(selected[0].ip, 120)];
// Otherwise, return both with a TTL of 1 hour.
return selected.map((s) => new ARecord(s.ip, 3600));
$ doggo --gp-from="Chicago" A vincent.bernat.ch
LOCATION NAME TYPE TTL ADDRESS
Chicago (IL), US
vincent.bernat.ch. A 120s 5.161.44.145
$ doggo --gp-from="Mexico" A vincent.bernat.ch
LOCATION NAME TYPE TTL ADDRESS
Queretaro, MX
vincent.bernat.ch. A 3600s 5.161.44.145
vincent.bernat.ch. A 3600s 149.28.219.155
$ doggo --reverse 5.161.44.145 149.28.219.155
NAME TYPE TTL ADDRESS
145.44.161.5.in-addr.arpa. PTR 7187s web05.luffy.cx.
155.219.28.149.in-addr.arpa. PTR 3600s web07.luffy.cx.
Note On the live page, the map below is interactive: point at a location to get the DNS answer, or disable servers to see how the answers change.
RoutingEngine.getClosestServer() supporting only IPv4, and it handles the case
where there are not enough alive servers to build an answer.
Bunny.net has a comprehensive Terraform provider. I leverage CDK
Terrain to build the target state in TypeScript and OpenTofu to deploy
it. Have a look at "Managing infrastructure with Terraform, CDKTF, and
NixOS" for more details.6
acme.luffy.cx to
solve DNS-01 ACME challenges. Unlike Route 53, Bunny DNS cannot
restrict access to a single zone with a fine-grained access policy. As this
usage requires neither high availability nor low latency, I replaced Route 53
with Hickory, a memory-safe DNS server written in Rust. It supports
automatic DNSSEC signatures and dynamic updates. Its
configuration is simple:
[[zones]]
zone = "acme.luffy.cx"
zone_type = "Primary"
[zones.stores]
allow_update = true
type = "sqlite"
journal_path = "acme.luffy.cx.sqlite"
zone_path = "acme.luffy.cx.zone"
# Private key to sign the zone with DNSSEC. Generated with:
# openssl genpkey -algorithm EC -pkeyopt ec_paramgen_curve:P-256
[[zones.keys]]
algorithm = "ECDSAP256SHA256"
key_path = "/etc/hickory-dns.acme.luffy.cx.pem"
# TSIG key to sign zone updates. Generated with:
# openssl rand 32
[[zones.stores.tsig_keys]]
algorithm = "hmac-sha256"
key_file = "/etc/hickory-dns.acme.luffy.cx.update.acme.luffy.cx.tsig"
name = "update.acme.luffy.cx."
CNAME records:
_acme-challenge CNAME bernat.ch.acme.luffy.cx.
_acme-challenge.vincent CNAME vincent.bernat.ch.acme.luffy.cx.
DS record in a zone.7 I need one
to secure the acme.luffy.cx zone and certificate delivery. Therefore, I host
the luffy.cx zone on deSEC,8 a free DNS hosting service run by a
non-profit organization based in Berlin. I derive the DS record to publish in
luffy.cx from the DNSKEY record of acme.luffy.cx:
$ ZONE=acme.luffy.cx
$ dig @nsupdate.luffy.cx $ZONE DNSKEY +noall +answer \
> dnssec-dsfromkey -a SHA-256 -f - $ZONE
acme.luffy.cx. IN DS 55628 13 2 4946E7508F20E15F1B577A231104B029A1A82E04699A80CD46ADCE31227EE81F
DS records, the lack of HTTP/3, and
the IPv4-only RoutingEngine.getClosestServer() helper. The bill went from US$5
per month to US$1. So far, performance is on par with AWS, but I
only finalized the current setup, including the server in Sydney, in late
October. I need a bit more time to gather more data, and I'll post a short update.
Update (2026-11) This post was briefly discussed on Hacker News and Lobsters.
bernat.ch since December 2021. I didn't use healthchecks as
they were too expensive. I didn't host most of my zones there either, as queries
for haproxy.debian.net alone would have cost me around US$10 per month.
RoutingEngine.getClosestServer() only works
with IPv4. The final script works around this limitation.
DS record and got an answer seven minutes later: they don't know.
This is a bummer, as they support automatic CDS, a DNS record to advertise
a DS record to the parent zone. They handle one side of the delegation,
not the other.
I also reported a bug with the proof of non-existence, and they replied a
day later with a detailed answer.
| Series: | Midlife Recorder #3 |
| Publisher: | Linzi Day |
| Copyright: | February 2023 |
| ISBN: | 9798376517017 |
| Format: | Kindle |
| Pages: | 616 |
netip.Addr features an Unmap()
method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6
address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns
203.0.113.10.1 There is no Map() or To6() method for the reverse
direction. Such a method is trivial to implement, but Go maintainers have
rejected it on the grounds that users should write
netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today,
this pattern is eight times slower than a native method. How can we teach the
compiler to optimize this sequence?
netip.Addr. My
favorite is to add it to the Go standard library. Go maintainers prefer a small
external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping
the compiler eventually optimizes it. The unsafe package
opens a third path, with the same performance as the first solution.
netip.Addr stores any IP address as a
128-bit value with an extra field z to encode the family and the zone:
type Addr struct
addr uint128
z unique.Handle[addrDetail]
type addrDetail struct
isV6 bool // IPv4 is false, IPv6 is true.
zoneV6 string // != "" only if IsV6 is true.
var (
z0 unique.Handle[addrDetail]
z4 = unique.Make(addrDetail )
z6noz = unique.Make(addrDetail isV6: true )
)
AddrFrom4() encodes an IPv4 address as an
IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.
func AddrFrom4(addr [4]byte) Addr
return Addr
addr: uint128
0,
0xffff00000000
uint64(addr[0])<<24 uint64(addr[1])<<16
uint64(addr[2])<<8 uint64(addr[3]) ,
z: z4,
Unmap() turns an IPv4-mapped IPv6 address into an
IPv4 address by setting the z field to z4:
func (ip Addr) Unmap() Addr
if ip.Is4In6()
ip.z = z4
return ip
z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func (ip Addr) To6() Addr
if ip.Is4()
ip.z = z6noz
return ip
z field from outside the net/netip package. Instead, we
build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr
if ip.Is4()
ip = netip.AddrFrom16(ip.As16())
return ip
unsafe package to alter the Addr struct through
a proxy with the same memory layout:3
// addrProxy has the same memory layout as netip.Addr.
type addrProxy struct
addr [2]uint64 // netip.uint128
z unsafe.Pointer // unique.Handle[netip.addrDetail]
var (
anyIPv6 = netip.IPv6Unspecified()
netipZ6noz = (*addrProxy)(unsafe.Pointer(&anyIPv6)).z
)
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr
if !ip.Is4()
return ip
(*addrProxy)(unsafe.Pointer(&ip)).z = netipZ6noz
return ip
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
sec/op
AddrTo6/safe 7.137n 0%
AddrTo6/unsafe 0.8682n 2%
AddrTo6/builtin 0.8775n 2%
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ net/netip z6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
AX, CX, DX, BX, SI, DI, and R8 to R15.
Instructions storing data use their last argument as the destination.
Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16
bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first
instruction compares the 64-bit value z4 with the CX register.
The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ netipZ6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
As16() and
AddrFrom16(). They are short enough for the compiler
to inline them.
func (ip Addr) As16() (a16 [16]byte)
byteorder.BEPutUint64(a16[:8], ip.addr.hi)
byteorder.BEPutUint64(a16[8:], ip.addr.lo)
return a16
func AddrFrom16(addr [16]byte) Addr
return Addr
addr: uint128
byteorder.BEUint64(addr[:8]),
byteorder.BEUint64(addr[8:]),
,
z: z6noz,
func AddrTo6(input netip.Addr) netip.Addr
if !input.Is4()
return input
var a16 [16]byte
byteorder.BEPutUint64(a16[:8], input.addr.hi)
byteorder.BEPutUint64(a16[8:], input.addr.lo)
addr := a16
var output netip.Addr
output.addr.hi = byteorder.BEUint64(addr[:8])
output.addr.lo = byteorder.BEUint64(addr[8:])
output.z = netip.z6noz
return output
func AddrTo6(input netip.Addr) netip.Addr
if !input.Is4()
return input
var output netip.Addr
output.addr.hi = input.addr.hi
output.addr.lo = input.addr.lo
output.z = netip.z6noz
return output
Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (32 bytes):
; 0(SP) addr netip.uint128
; 16(SP) a16 [16]byte
PUSHQ BP
MOVQ SP, BP
SUBQ $32, SP
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
; byteorder.BEPutUint64(a16[8:], input.addr.lo)
MOVBEQ AX, net/netip a16+16(SP)
MOVBEQ BX, net/netip a16+24(SP)
; addr = a16, 16 bytes at once through the vector register X0
MOVUPS net/netip a16+16(SP), X0
MOVUPS X0, net/netip addr(SP)
; CX = netip.z6noz
MOVQ net/netip z6noz(SB), CX
; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8])
; output.addr.lo = byteorder.BEUint64(addr[8:])
MOVBEQ net/netip addr(SP), AX
MOVBEQ net/netip addr+8(SP), BX
end:
ADDQ $32, SP
POPQ BP
RET
// return value = Addr hi: AX, lo: BX, z: CX
BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped.
The eight byte loads of BEUint64() become a single MOVBEQ the other way
round.6 Three groups of instructions remain: a pack, a copy, and an
unpack.
switch or channels, into more primitive instructions or
calls to the runtime.netip.AddrFrom16(ip.As16()) with
netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the
noding process. Before that, the type checking phase prevents
us from accessing unexported struct fields.
Go 1.27 introduced a convenient debug option to dump the IR of a function at
interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1 GOAMD64=v3 go build -a -gcflags="-d=astdump=AddrTo6Safe" .
Writing text ast output for AddrTo6Safe to AddrTo6Safe.ast
Writing html ast output for AddrTo6Safe to AddrTo6Safe.html
Writing html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
DCLFUNC addrto6.AddrTo6Safe ABI:ABIInternal FUNC-func(netip.Addr) netip.Addr
DCLFUNC-Dcl
. NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. NAME-addrto6.~r0 Class:PPARAMOUT Offset:0 OnStack netip.Addr
DCLFUNC-body
. IF # ipv6_safe.go:11:2
. IF-Cond
. . CALLFUNC bool
. . CALLFUNC-Fun
. . . METHEXPR addrto6.Is4 FUNC-func(netip.Addr) bool
. . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . CALLFUNC-Args
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. IF-Body
. . AS # ipv6_safe.go:12:6
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . CALLFUNC netip.Addr
. . . CALLFUNC-Fun
. . . . NAME-netip.AddrFrom16 Class:PFUNC Offset:0 Used FUNC-func([16]byte) netip.Addr
. . . CALLFUNC-Args
. . . . CALLFUNC ARRAY-[16]byte
. . . . CALLFUNC-Fun
. . . . . METHEXPR addrto6.As16 FUNC-func(netip.Addr) [16]byte
. . . . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . . . CALLFUNC-Args
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. RETURN # ipv6_safe.go:14:2
. RETURN-Results
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
if statement, we spot the calls to the method
netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to
patch them with a struct literal:
IF-Body
. AS # ipv6_safe.go:12:6
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . STRUCTLIT netip.Addr
. . STRUCTLIT-List
. . . STRUCTKEY netip.addr
. . . . DOT netip.addr netip.uint128
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . STRUCTKEY netip.z
. . . . NAME-netip.z6noz Class:PEXTERN Offset:0 unique.Handle[net/netip.addrDetail]
reader.go, the expr() method builds the IR tree for
an expression. At the end of the exprCall case, we add a call to a
rewriteAddrFrom16As16() function. It takes the current node and returns the
struct literal on success, or nil if the rewrite is not possible. First, we
check that we have the expected pattern: a call to the netip.AddrFrom16()
function with a call to the netip.Addr.As16() method as its only argument:
func rewriteAddrFrom16As16(n ir.Node) ir.Node
call, ok := n.(*ir.CallExpr)
if !ok call.Op() != ir.OCALLFUNC
len(call.Args) != 1 len(call.Init()) != 0
!isNetipFunc(call.Fun, "AddrFrom16")
return nil
inner, ok := call.Args[0].(*ir.CallExpr)
if !ok inner.Op() != ir.OCALLFUNC
len(inner.Args) != 1 len(inner.Init()) != 0
!isNetipFunc(inner.Fun, "Addr.As16")
return nil
x := inner.Args[0]
// [...]
netip.z6noz:
z6noz, err := lookupVar(ir.StaticCalleeName(call.Fun).Sym().Pkg, "z6noz")
if err != nil
return nil
typ := call.Type()
pos := call.Pos()
var list []ir.Node
for i, f := range typ.Fields()
var value ir.Node
switch f.Sym.Name
case "addr":
value = typecheck.DotField(pos, x, i)
case "z":
value = z6noz
default:
return nil
list = append(list, ir.NewStructKeyExpr(pos, f, value))
lit := ir.NewCompLitExpr(pos, ir.OSTRUCTLIT, typ, list)
lit.SetTypecheck(1)
return lit
$ cd src
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)
Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.
Checking command staleness for linux/amd64.
---
Installed Go for linux/amd64 in /home/bernat/code/free/go
Installed commands in /home/bernat/code/free/go/bin
*** You need to add /home/bernat/code/free/go/bin to your PATH.
$ export PATH=$PWD/../bin:$PATH
$ go version
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64
$ go test net/netip/...
ok net/netip 0.224s
$ cd ../../go-netip-addrto6
$ go test .
ok github.com/vincentbernat/go-netip-addrto6 0.062s
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ net/netip z6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
net/netip.Addr. It s an ugly hack in the noder, whose job is to
faithfully translate the type-checked AST into the IR. And it s harder to
maintain than adding a To6() method.
memcombine. With the appropriate debug
flag, the compiler dumps the SSA form after this pass:8
$ GOTOOLCHAIN=go1.26.8 GOAMD64=v3 \
> go build -a -gcflags='-d=ssa/memcombine/dump=AddrTo6Safe' .
$ head -5 AddrTo6Safe_01__memcombine.dump
AddrTo6Safe func(netip.Addr) netip.Addr
b2:
(?) v1 = InitMem <mem>
(?) v2 = SP <uintptr>
(?) v3 = SB <uintptr>
memcombine pass follows the same structure as the assembly
code for AddrTo6Safe() we looked at earlier: two stores,
one move, and two loads we would like to optimize away.
; [ ]
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v466 = ArgIntReg <*netip.addrDetail> ip+16 [2] ; input.z
; [ ]
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v416 = Load <uint64> v285 v286 ; addr[:8]
v299 = Bswap64 <uint64> v416 ; output.addr.hi
v174 = Load <uint64> v415 v286 ; addr[8:]
v39 = Bswap64 <uint64> v174 ; output.addr.lo
; [ ]
v442), an operation with its type
(Bswap64 <uint64>), and its arguments (v490).9 Values are the basic
building blocks of SSA and are defined exactly once. Square brackets enclose
integer parameters ([8]) and curly braces contain auxiliary arguments
( netip.addr ). Operations writing to memory produce a new memory state. Every
memory operation takes the current state as its last argument, which keeps them
in order.
output.addr.lo, aka v39:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v174 = Load <uint64> v415 v286 ; addr[8:]
v39 = Bswap64 <uint64> v174 ; output.addr.lo
(Load (OffPtr
[o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174
with its arguments v415 and v286 and creates a new value v600:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v600 = OffPtr <*byte> [8] v22 ; &a16[8]
v174 = Load <uint64> v600 v282 ; a16[8:]
v39 = Bswap64 <uint64> v174 ; output.addr.lo
(Load p (Store p x
_)) => x. The load is forwarded: the stored value replaces it and no memory
access remains. It matches v174. It notices that v600 and v173 are the
same address and replaces v174 with a copy of v442:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v600 = OffPtr <*byte> [8] v22 ; &a16[8]
v174 = Copy <uint64> v442 ; bswap(input.addr.lo)
v39 = Bswap64 <uint64> v174 ; output.addr.lo
(Bswap64 (Bswap64 x)) => x.
v39 becomes a copy of v490:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v600 = OffPtr <*byte> [8] v22 ; &a16[8]
v174 = Copy <uint64> v442 ; bswap(input.addr.lo)
v39 = Copy <uint64> v490 ; output.addr.lo = input.addr.lo
v39, only this SSA form remains:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v39 = Copy <uint64> v490 ; output.addr.lo = input.addr.lo
output.addr.hi, aka v299:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Load <uint64> v285 v286 ; addr[:8]
v299 = Bswap64 <uint64> v416 ; output.addr.hi
(Load p (Move p src mem)) => (Load src mem). This rewrites v416
to use arguments from v286:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Load <uint64> v22 v282 ; a16[:8]
v299 = Bswap64 <uint64> v416 ; output.addr.hi
(Load p (Store q _ (Store p x _))) => x. This
matches v416: x is v542, p is v22 (&a16), q is v173
(&a16[8]), and p and q do not overlap for uint64.
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Copy <uint64> v542 ; bswap(input.addr.hi)
v299 = Bswap64 <uint64> v416 ; output.addr.hi
(Bswap64 (Bswap64 x)) => x.
v299 becomes a copy of v502:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Copy <uint64> v542 ; bswap(input.addr.hi)
v299 = Copy <uint64> v502 ; output.addr.hi = input.addr.hi
v299, we get this SSA form:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v299 = Copy <uint64> v502 ; output.addr.hi = input.addr.hi
generic.rules. They use
conditions to validate their context: ssa.IsSamePtr() for the same address,
ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored
value to a load already exists with three variants looking through several other
stores. Here are the two we need:
(Load <t1> p1 (Store t2 p2 x _))
&& ssa.IsSamePtr(p1, p2)
&& copyCompatibleType(t1, x.Type)
&& t1.Size() == t2.Size()
=> x
(Load <t1> p1 (Store t2 p2 _ (Store t3 p3 x _)))
&& ssa.IsSamePtr(p1, p3)
&& copyCompatibleType(t1, x.Type)
&& t1.Size() == t3.Size()
&& ssa.Disjoint(p3, t3, p2, t2)
=> x
(Load <t1> op1:(OffPtr [o1] p1) move:(Move [n] p2 src mem))
&& o1 >= 0 && o1+t1.Size() <= n && ssa.IsSamePtr(p1, p2)
&& !ssa.IsVolatile(src)
=> @move.Block (Load <t1> (OffPtr <op1.Type> [o1] src) mem)
(Load <t1> p1 move:(Move [n] p2 src mem))
&& p1.Op != ssaop.OpOffPtr
&& t1.Size() <= n && ssa.IsSamePtr(p1, p2)
&& !ssa.IsVolatile(src)
=> @move.Block (Load <t1> (OffPtr <p1.Type> [0] src) mem)
(BSWAP(Q L) (BSWAP(Q L) p)) => p
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (16 bytes):
; 0(SP) a16 [16]byte
PUSHQ BP
MOVQ SP, BP
SUBQ $16, SP
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
; The four forwarded bytes: the low half of input.addr.lo is taken apart and
; put back together in registers
MOVQ BX, DX ; DX = input.addr.lo
SHRQ $24, BX ; BX = input.addr.lo >> 24
MOVQ DX, SI ; SI = input.addr.lo
SHRQ $16, DX ; DX = input.addr.lo >> 16
MOVQ SI, DI ; DI = input.addr.lo, kept for the pack
SHRQ $8, SI ; SI = input.addr.lo >> 8
MOVBLZX DIB, R8 ; R8 = byte(input.addr.lo)
MOVBLZX SIB, SI ; SI = byte(input.addr.lo >> 8)
SHLQ $8, SI
ORQ R8, SI ; SI = two low bytes of input.addr.lo
MOVBLZX DL, DX ; DX = byte(input.addr.lo >> 16)
SHLQ $16, DX
ORQ SI, DX
MOVBLZX BL, BX ; BX = byte(input.addr.lo >> 24)
SHLQ $24, BX
ORQ DX, BX ; BX = input.addr.lo & 0xffffffff
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
; byteorder.BEPutUint64(a16[8:], input.addr.lo)
MOVBEQ AX, net/netip a16(SP)
MOVBEQ DI, net/netip a16+8(SP)
; The four other bytes of input.addr.lo, read one by one from a16
MOVBLZX net/netip a16+11(SP), DX ; a16[11]
SHLQ $32, DX
ORQ DX, BX
MOVBLZX net/netip a16+10(SP), DX ; a16[10]
SHLQ $40, DX
ORQ DX, BX
MOVBLZX net/netip a16+9(SP), DX ; a16[9]
SHLQ $48, DX
ORQ DX, BX
MOVBLZX net/netip a16+8(SP), DX ; a16[8]
SHLQ $56, DX
; output.z = netip.z6noz
MOVQ net/netip z6noz(SB), CX
; output.addr.hi = byteorder.BEUint64(a16[:8])
MOVBEQ net/netip a16(SP), AX
; output.addr.lo assembled from the previous steps
ORQ DX, BX
end:
LEAVEQ
RET
// return value = Addr hi: AX, lo: BX, z: CX
memcombine,
notably in the late opt pass. At this point, the inlined versions of
BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen
byte loads, matching their source code:
func BEUint64(b []byte) uint64
_ = b[7] // bounds check hint to compiler; see golang.org/issue/14808
return uint64(b[7]) uint64(b[6])<<8 uint64(b[5])<<16 uint64(b[4])<<24
uint64(b[3])<<32 uint64(b[2])<<40 uint64(b[1])<<48 uint64(b[0])<<56
output.addr.lo: addr[15] and addr[11]. Here is
a simplified SSA form before late opt:
v273 = Trunc64to8 <byte> v490 ; byte(input.addr.lo)
v226 = Trunc64to8 <byte> v225 ; byte(input.addr.lo >> 32)
; [ ]
v235 = Store <mem> byte v233 v226 v223 ; a16[11] = byte(lo >> 32)
v247 = Store <mem> byte v245 v238 v235 ; a16[12] =
v259 = Store <mem> byte v257 v250 v247 ; a16[13] =
v271 = Store <mem> byte v269 v262 v259 ; a16[14] =
v282 = Store <mem> byte v280 v273 v271 ; a16[15] = byte(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
; [ ]
v433 = OffPtr <*byte> [15] v285 ; &addr[15]
v435 = Load <byte> v433 v286 ; addr[15]
v479 = OffPtr <*byte> [11] v285 ; &addr[11]
v481 = Load <byte> v479 v286 ; addr[11]
(Load (OffPtr [o] p) (Move p src mem))
=> (Load (OffPtr [o] src) mem). It matches both loads, which now read a16
with the memory state before the copy:
v600 = OffPtr <*byte> [15] v22 ; &a16[15]
v435 = Load <byte> v600 v282 ; a16[15]
v601 = OffPtr <*byte> [11] v22 ; &a16[11]
v481 = Load <byte> v601 v282 ; a16[11]
(Load p (Store p x _)) =>
x. It matches v435, as v282 stores a16[15]. It does not match v481:
v235 stores a16[11] four stores earlier in the chain, while the variants of
this rule look through three stores at most.
v435 = Copy <byte> v273 ; byte(input.addr.lo)
v601 = OffPtr <*byte> [11] v22 ; &a16[11]
v481 = Load <byte> v601 v282 ; a16[11]
a16[12] to a16[15]. The twelve other loads now read a16 instead of
addr.
BEUint64() becomes a chain of Or64, each one adding a byte shifted into
place. memcombine is a pass written in Go, not a set of rewrite
rules. It starts from the last Or64 of the chain and collects up to eight
terms. If each term is a byte load, extended to 64 bits and shifted, and if the
eight loads read consecutive addresses from the same pointer with the same
memory state, it replaces the whole chain with a single 64-bit load and a byte
swap. Otherwise, it tries again with four, then two terms, and from each
intermediate Or64. Here is the loop checking each term in a simplified version
of combineLoads():
for i := int64(0); i < n; i++
v := a[i]
shift := int64(0)
if v.Op == shiftOp
v, shift = peelShift(v)
if v.Op != extOp
return false
load := v.Args[0]
if load.Op != ssaop.OpLoad
return false
if load.Args[1] != mem
return false
p, off := splitPtr(load.Args[0])
if p != base
return false
r[i] = LoadRecord load: load, offset: off, shift: shift
output.addr.hi, the eight loads read a16 with the same memory state
v282:
v13 = Load <byte> v22 v282 ; a16[0]
v530 = Load <byte> v14 v282 ; a16[1]
v488 = Load <byte> v504 v282 ; a16[2]
v405 = Load <byte> v537 v282 ; a16[3]
v385 = Load <byte> v397 v282 ; a16[4]
v361 = Load <byte> v373 v282 ; a16[5]
v196 = Load <byte> v63 v282 ; a16[6]
v432 = Load <byte> v315 v282 ; a16[7]
v319 = ZeroExt8to64 <uint64> v432 ; uint64(a16[7])
v329 = ZeroExt8to64 <uint64> v196 ; uint64(a16[6])
v330 = Lsh64x64 <uint64> [true] v329 v138 ; uint64(a16[6]) << 8
v331 = Or64 <uint64> v319 v330 ; a16[7] a16[6] << 8
; [ ] same for a16[5] to a16[1]
v401 = ZeroExt8to64 <uint64> v13 ; uint64(a16[0])
v402 = Lsh64x64 <uint64> [true] v401 v55 ; uint64(a16[0]) << 56
v403 = Or64 <uint64> v402 v391 ; a16[0] << 56 = output.addr.hi
memcombine merges them into one load and a swap:
v286 = Load <uint64> v22 v282 ; a16[:8]
v285 = Bswap64 <uint64> v286 ; output.addr.hi
output.addr.lo, here is the chain memcombine sees after late opt:
v436 = ZeroExt8to64 <uint64> v273 ; addr[15], forwarded
v448 = Or64 <uint64> v436 v447 ; addr[14] << 8, forwarded
v460 = Or64 <uint64> v459 v448 ; addr[13] << 16, forwarded
v472 = Or64 <uint64> v471 v460 ; addr[12] << 24, forwarded
v484 = Or64 <uint64> v483 v472 ; a16[11] << 32, loaded
v496 = Or64 <uint64> v495 v484 ; a16[10] << 40, loaded
v508 = Or64 <uint64> v507 v496 ; a16[9] << 48, loaded
v520 = Or64 <uint64> v519 v508 ; a16[8] << 56, loaded
v520, four of the eight terms are forwarded bytes, not loads from memory,
and memcombine can t combine them. It doesn t merge the four remaining loads
either, as they sit on top of the forwarded bytes.
memcombine before late opt. After
this change, the generated code for the helper is back to the
shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ net/netip z6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
Go 1.26.8 Our branch
sec/op sec/op vs base
AddrTo6/safe 6.5470n 0% 0.8944n 4% -86.34% (p=0.002 n=6)
AddrTo6/unsafe 0.9071n 3% 0.8682n 1% -4.28% (p=0.002 n=6)
AddrTo6/builtin 0.8871n 2% 0.8785n 1% ~ (p=0.310 n=6)
memcombine pass. Instead, I plan to publish this blog post and bring up the
subject again as a follow-up to issue #54365. Either the sheer complexity and
the Go 1.27 regression convince the maintainers that adding a To6() method is
simpler and more efficient, or they advise me on how to move forward. Either
way, digging into this subject taught me a lot about the Go compiler!
:: while it would
make more sense to leave it untouched.
netip.Addr s layout changes, you must add
tests to detect it. This is more dangerous if you put this code in a
package. Either ask users to run the tests themselves, or detect the change
at run time and panic. Hiding this optimization behind a build tag would
make users aware of this potential trap.
GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm
'\.asm' from the companion repository, then edited it a bit to keep this
article from turning into an endless rabbit hole. Due to an unfortunate
sequence of events, we switch between versions: Go 1.27 introduced a
regression that blurs the point of this article.
MOVBEQ requires GOAMD64=v3, matching the x86-64-v3
microarchitecture from 2013. Otherwise, the compiler translates
BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
_ = netip.Addr .
$ GOSSAFUNC=AddrTo6Safe \
> GOTOOLCHAIN=go1.26.8 \
> GOAMD64=v3 go build -a .
dumped SSA for AddrTo6Safe,1 to ./ssa.html
netip.Addr features an Unmap()
method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6
address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns
203.0.113.10.1 There is no Map() or To6() method for the reverse
direction. Such a method is trivial to implement, but Go maintainers have
rejected it on the grounds that users should write
netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today,
this pattern is eight times slower than a native method. How can we teach the
compiler to optimize this sequence?
netip.Addr. My
favorite is to add it to the Go standard library. Go maintainers prefer a small
external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping
the compiler eventually optimizes it. The unsafe package
opens a third path, with the same performance as the first solution.
netip.Addr stores any IP address as a
128-bit value with an extra field z to encode the family and the zone:
type Addr struct
addr uint128
z unique.Handle[addrDetail]
type addrDetail struct
isV6 bool // IPv4 is false, IPv6 is true.
zoneV6 string // != "" only if IsV6 is true.
var (
z0 unique.Handle[addrDetail]
z4 = unique.Make(addrDetail )
z6noz = unique.Make(addrDetail isV6: true )
)
AddrFrom4() encodes an IPv4 address as an
IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.
func AddrFrom4(addr [4]byte) Addr
return Addr
addr: uint128
0,
0xffff00000000
uint64(addr[0])<<24 uint64(addr[1])<<16
uint64(addr[2])<<8 uint64(addr[3]) ,
z: z4,
Unmap() turns an IPv4-mapped IPv6 address into an
IPv4 address by setting the z field to z4:
func (ip Addr) Unmap() Addr
if ip.Is4In6()
ip.z = z4
return ip
z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func (ip Addr) To6() Addr
if ip.Is4()
ip.z = z6noz
return ip
Update (2026-10)
Instead of patching Go, we can use the -overlay flag of go
build to hijack any package, including the standard library. In our case,
it can add To6() to net/netip. Yet it is
cumbersome:3 the flag expects a JSON file mapping absolute
paths in GOROOT to replacement files, and you need to add it to every go
command.
z field from outside the net/netip package. Instead, we
build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr
if ip.Is4()
ip = netip.AddrFrom16(ip.As16())
return ip
unsafe package to alter the Addr struct through
a proxy with the same memory layout:4
// addrProxy has the same memory layout as netip.Addr.
type addrProxy struct
addr [2]uint64 // netip.uint128
z unsafe.Pointer // unique.Handle[netip.addrDetail]
var (
anyIPv6 = netip.IPv6Unspecified()
netipZ6noz = (*addrProxy)(unsafe.Pointer(&anyIPv6)).z
)
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr
if !ip.Is4()
return ip
(*addrProxy)(unsafe.Pointer(&ip)).z = netipZ6noz
return ip
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
sec/op
AddrTo6/safe 7.137n 0%
AddrTo6/unsafe 0.8682n 2%
AddrTo6/builtin 0.8775n 2%
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ net/netip z6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
AX, CX, DX, BX, SI, DI, and R8 to R15.
Instructions storing data use their last argument as the destination.
Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16
bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first
instruction compares the 64-bit value z4 with the CX register.
The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ netipZ6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
As16() and
AddrFrom16(). They are short enough for the compiler
to inline them.
func (ip Addr) As16() (a16 [16]byte)
byteorder.BEPutUint64(a16[:8], ip.addr.hi)
byteorder.BEPutUint64(a16[8:], ip.addr.lo)
return a16
func AddrFrom16(addr [16]byte) Addr
return Addr
addr: uint128
byteorder.BEUint64(addr[:8]),
byteorder.BEUint64(addr[8:]),
,
z: z6noz,
func AddrTo6(input netip.Addr) netip.Addr
if !input.Is4()
return input
var a16 [16]byte
byteorder.BEPutUint64(a16[:8], input.addr.hi)
byteorder.BEPutUint64(a16[8:], input.addr.lo)
addr := a16
var output netip.Addr
output.addr.hi = byteorder.BEUint64(addr[:8])
output.addr.lo = byteorder.BEUint64(addr[8:])
output.z = netip.z6noz
return output
func AddrTo6(input netip.Addr) netip.Addr
if !input.Is4()
return input
var output netip.Addr
output.addr.hi = input.addr.hi
output.addr.lo = input.addr.lo
output.z = netip.z6noz
return output
Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (32 bytes):
; 0(SP) addr netip.uint128
; 16(SP) a16 [16]byte
PUSHQ BP
MOVQ SP, BP
SUBQ $32, SP
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
; byteorder.BEPutUint64(a16[8:], input.addr.lo)
MOVBEQ AX, net/netip a16+16(SP)
MOVBEQ BX, net/netip a16+24(SP)
; addr = a16, 16 bytes at once through the vector register X0
MOVUPS net/netip a16+16(SP), X0
MOVUPS X0, net/netip addr(SP)
; CX = netip.z6noz
MOVQ net/netip z6noz(SB), CX
; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8])
; output.addr.lo = byteorder.BEUint64(addr[8:])
MOVBEQ net/netip addr(SP), AX
MOVBEQ net/netip addr+8(SP), BX
end:
ADDQ $32, SP
POPQ BP
RET
// return value = Addr hi: AX, lo: BX, z: CX
BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped.
The eight byte loads of BEUint64() become a single MOVBEQ the other way
round.7 Three groups of instructions remain: a pack, a copy, and an
unpack.
switch or channels, into more primitive instructions or
calls to the runtime.netip.AddrFrom16(ip.As16()) with
netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the
"noding" process. Before that, the type checking phase prevents
us from accessing unexported struct fields.
Go 1.27 introduced a convenient debug option to dump the IR of a function at
interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1 GOAMD64=v3 go build -a -gcflags="-d=astdump=AddrTo6Safe" .
Writing text ast output for AddrTo6Safe to AddrTo6Safe.ast
Writing html ast output for AddrTo6Safe to AddrTo6Safe.html
Writing html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
DCLFUNC addrto6.AddrTo6Safe ABI:ABIInternal FUNC-func(netip.Addr) netip.Addr
DCLFUNC-Dcl
. NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. NAME-addrto6.~r0 Class:PPARAMOUT Offset:0 OnStack netip.Addr
DCLFUNC-body
. IF # ipv6_safe.go:11:2
. IF-Cond
. . CALLFUNC bool
. . CALLFUNC-Fun
. . . METHEXPR addrto6.Is4 FUNC-func(netip.Addr) bool
. . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . CALLFUNC-Args
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. IF-Body
. . AS # ipv6_safe.go:12:6
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . CALLFUNC netip.Addr
. . . CALLFUNC-Fun
. . . . NAME-netip.AddrFrom16 Class:PFUNC Offset:0 Used FUNC-func([16]byte) netip.Addr
. . . CALLFUNC-Args
. . . . CALLFUNC ARRAY-[16]byte
. . . . CALLFUNC-Fun
. . . . . METHEXPR addrto6.As16 FUNC-func(netip.Addr) [16]byte
. . . . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . . . CALLFUNC-Args
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. RETURN # ipv6_safe.go:14:2
. RETURN-Results
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
if statement, we spot the calls to the method
netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to
patch them with a struct literal:
IF-Body
. AS # ipv6_safe.go:12:6
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . STRUCTLIT netip.Addr
. . STRUCTLIT-List
. . . STRUCTKEY netip.addr
. . . . DOT netip.addr netip.uint128
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . STRUCTKEY netip.z
. . . . NAME-netip.z6noz Class:PEXTERN Offset:0 unique.Handle[net/netip.addrDetail]
reader.go, the expr() method builds the IR tree for
an expression. At the end of the exprCall case, we add a call to a
rewriteAddrFrom16As16() function. It takes the current node and returns the
struct literal on success, or nil if the rewrite is not possible. First, we
check that we have the expected pattern: a call to the netip.AddrFrom16()
function with a call to the netip.Addr.As16() method as its only argument:
func rewriteAddrFrom16As16(n ir.Node) ir.Node
call, ok := n.(*ir.CallExpr)
if !ok call.Op() != ir.OCALLFUNC
len(call.Args) != 1 len(call.Init()) != 0
!isNetipFunc(call.Fun, "AddrFrom16")
return nil
inner, ok := call.Args[0].(*ir.CallExpr)
if !ok inner.Op() != ir.OCALLFUNC
len(inner.Args) != 1 len(inner.Init()) != 0
!isNetipFunc(inner.Fun, "Addr.As16")
return nil
x := inner.Args[0]
// [...]
netip.z6noz:
z6noz, err := lookupVar(ir.StaticCalleeName(call.Fun).Sym().Pkg, "z6noz")
if err != nil
return nil
typ := call.Type()
pos := call.Pos()
var list []ir.Node
for i, f := range typ.Fields()
var value ir.Node
switch f.Sym.Name
case "addr":
value = typecheck.DotField(pos, x, i)
case "z":
value = z6noz
default:
return nil
list = append(list, ir.NewStructKeyExpr(pos, f, value))
lit := ir.NewCompLitExpr(pos, ir.OSTRUCTLIT, typ, list)
lit.SetTypecheck(1)
return lit
$ cd src
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)
Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.
Checking command staleness for linux/amd64.
---
Installed Go for linux/amd64 in /home/bernat/code/free/go
Installed commands in /home/bernat/code/free/go/bin
*** You need to add /home/bernat/code/free/go/bin to your PATH.
$ export PATH=$PWD/../bin:$PATH
$ go version
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64
$ go test net/netip/...
ok net/netip 0.224s
$ cd ../../go-netip-addrto6
$ go test .
ok github.com/vincentbernat/go-netip-addrto6 0.062s
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ net/netip z6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
net/netip.Addr. It's an ugly hack in the noder, whose job is to
faithfully translate the type-checked AST into the IR. And it's harder to
maintain than adding a To6() method.
memcombine. With the appropriate debug
flag, the compiler dumps the SSA form after this pass:9
$ GOTOOLCHAIN=go1.26.8 GOAMD64=v3 \
> go build -a -gcflags='-d=ssa/memcombine/dump=AddrTo6Safe' .
$ head -5 AddrTo6Safe_01__memcombine.dump
AddrTo6Safe func(netip.Addr) netip.Addr
b2:
(?) v1 = InitMem <mem>
(?) v2 = SP <uintptr>
(?) v3 = SB <uintptr>
memcombine pass follows the same structure as the assembly
code for AddrTo6Safe() we looked at earlier: two stores,
one move, and two loads we would like to optimize away.
; [ ]
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v466 = ArgIntReg <*netip.addrDetail> ip+16 [2] ; input.z
; [ ]
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v416 = Load <uint64> v285 v286 ; addr[:8]
v299 = Bswap64 <uint64> v416 ; output.addr.hi
v174 = Load <uint64> v415 v286 ; addr[8:]
v39 = Bswap64 <uint64> v174 ; output.addr.lo
; [ ]
v442), an operation with its type
(Bswap64 <uint64>), and its arguments (v490).10 Values are the basic
building blocks of SSA and are defined exactly once. Square brackets enclose
integer parameters ([8]) and curly braces contain auxiliary arguments
( netip.addr ). Operations writing to memory produce a new memory state. Every
memory operation takes the current state as its last argument, which keeps them
in order.
output.addr.lo, aka v39:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v174 = Load <uint64> v415 v286 ; addr[8:]
v39 = Bswap64 <uint64> v174 ; output.addr.lo
(Load (OffPtr
[o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174
with its arguments v415 and v286 and creates a new value v600:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v600 = OffPtr <*byte> [8] v22 ; &a16[8]
v174 = Load <uint64> v600 v282 ; a16[8:]
v39 = Bswap64 <uint64> v174 ; output.addr.lo
(Load p (Store p x
_)) => x. The load is forwarded: the stored value replaces it and no memory
access remains. It matches v174. It notices that v600 and v173 are the
same address and replaces v174 with a copy of v442:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v600 = OffPtr <*byte> [8] v22 ; &a16[8]
v174 = Copy <uint64> v442 ; bswap(input.addr.lo)
v39 = Bswap64 <uint64> v174 ; output.addr.lo
(Bswap64 (Bswap64 x)) => x.
v39 becomes a copy of v490:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v442 = Bswap64 <uint64> v490 ; bswap(input.addr.lo)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v415 = OffPtr <*byte> [8] v285 ; &addr[8]
v600 = OffPtr <*byte> [8] v22 ; &a16[8]
v174 = Copy <uint64> v442 ; bswap(input.addr.lo)
v39 = Copy <uint64> v490 ; output.addr.lo = input.addr.lo
v39, only this SSA form remains:
v490 = ArgIntReg <uint64> ip+8 [1] ; input.addr.lo
v39 = Copy <uint64> v490 ; output.addr.lo = input.addr.lo
output.addr.hi, aka v299:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Load <uint64> v285 v286 ; addr[:8]
v299 = Bswap64 <uint64> v416 ; output.addr.hi
(Load p (Move p src mem)) => (Load src mem). This rewrites v416
to use arguments from v286:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Load <uint64> v22 v282 ; a16[:8]
v299 = Bswap64 <uint64> v416 ; output.addr.hi
(Load p (Store q _ (Store p x _))) => x. This
matches v416: x is v542, p is v22 (&a16), q is v173
(&a16[8]), and p and q do not overlap for uint64.
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Copy <uint64> v542 ; bswap(input.addr.hi)
v299 = Bswap64 <uint64> v416 ; output.addr.hi
(Bswap64 (Bswap64 x)) => x.
v299 becomes a copy of v502:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v22 = LocalAddr <*[16]byte> netip.a16 v2 v1 ; &a16
v173 = OffPtr <*byte> [8] v22 ; &a16[8]
v542 = Bswap64 <uint64> v502 ; bswap(input.addr.hi)
v161 = Store <mem> uint64 v22 v542 v23 ; a16[:8] = bswap(hi)
v282 = Store <mem> uint64 v173 v442 v161 ; a16[8:] = bswap(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
v416 = Copy <uint64> v542 ; bswap(input.addr.hi)
v299 = Copy <uint64> v502 ; output.addr.hi = input.addr.hi
v299, we get this SSA form:
v502 = ArgIntReg <uint64> ip+0 [0] ; input.addr.hi
v299 = Copy <uint64> v502 ; output.addr.hi = input.addr.hi
generic.rules. They use
conditions to validate their context: ssa.IsSamePtr() for the same address,
ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored
value to a load already exists with three variants looking through several other
stores. Here are the two we need:
(Load <t1> p1 (Store t2 p2 x _))
&& ssa.IsSamePtr(p1, p2)
&& copyCompatibleType(t1, x.Type)
&& t1.Size() == t2.Size()
=> x
(Load <t1> p1 (Store t2 p2 _ (Store t3 p3 x _)))
&& ssa.IsSamePtr(p1, p3)
&& copyCompatibleType(t1, x.Type)
&& t1.Size() == t3.Size()
&& ssa.Disjoint(p3, t3, p2, t2)
=> x
(Load <t1> op1:(OffPtr [o1] p1) move:(Move [n] p2 src mem))
&& o1 >= 0 && o1+t1.Size() <= n && ssa.IsSamePtr(p1, p2)
&& !ssa.IsVolatile(src)
=> @move.Block (Load <t1> (OffPtr <op1.Type> [o1] src) mem)
(Load <t1> p1 move:(Move [n] p2 src mem))
&& p1.Op != ssaop.OpOffPtr
&& t1.Size() <= n && ssa.IsSamePtr(p1, p2)
&& !ssa.IsVolatile(src)
=> @move.Block (Load <t1> (OffPtr <p1.Type> [0] src) mem)
(BSWAP(Q L) (BSWAP(Q L) p)) => p
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (16 bytes):
; 0(SP) a16 [16]byte
PUSHQ BP
MOVQ SP, BP
SUBQ $16, SP
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
; The four forwarded bytes: the low half of input.addr.lo is taken apart and
; put back together in registers
MOVQ BX, DX ; DX = input.addr.lo
SHRQ $24, BX ; BX = input.addr.lo >> 24
MOVQ DX, SI ; SI = input.addr.lo
SHRQ $16, DX ; DX = input.addr.lo >> 16
MOVQ SI, DI ; DI = input.addr.lo, kept for the pack
SHRQ $8, SI ; SI = input.addr.lo >> 8
MOVBLZX DIB, R8 ; R8 = byte(input.addr.lo)
MOVBLZX SIB, SI ; SI = byte(input.addr.lo >> 8)
SHLQ $8, SI
ORQ R8, SI ; SI = two low bytes of input.addr.lo
MOVBLZX DL, DX ; DX = byte(input.addr.lo >> 16)
SHLQ $16, DX
ORQ SI, DX
MOVBLZX BL, BX ; BX = byte(input.addr.lo >> 24)
SHLQ $24, BX
ORQ DX, BX ; BX = input.addr.lo & 0xffffffff
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
; byteorder.BEPutUint64(a16[8:], input.addr.lo)
MOVBEQ AX, net/netip a16(SP)
MOVBEQ DI, net/netip a16+8(SP)
; The four other bytes of input.addr.lo, read one by one from a16
MOVBLZX net/netip a16+11(SP), DX ; a16[11]
SHLQ $32, DX
ORQ DX, BX
MOVBLZX net/netip a16+10(SP), DX ; a16[10]
SHLQ $40, DX
ORQ DX, BX
MOVBLZX net/netip a16+9(SP), DX ; a16[9]
SHLQ $48, DX
ORQ DX, BX
MOVBLZX net/netip a16+8(SP), DX ; a16[8]
SHLQ $56, DX
; output.z = netip.z6noz
MOVQ net/netip z6noz(SB), CX
; output.addr.hi = byteorder.BEUint64(a16[:8])
MOVBEQ net/netip a16(SP), AX
; output.addr.lo assembled from the previous steps
ORQ DX, BX
end:
LEAVEQ
RET
// return value = Addr hi: AX, lo: BX, z: CX
memcombine,
notably in the late opt pass. At this point, the inlined versions of
BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen
byte loads, matching their source code:
func BEUint64(b []byte) uint64
_ = b[7] // bounds check hint to compiler; see golang.org/issue/14808
return uint64(b[7]) uint64(b[6])<<8 uint64(b[5])<<16 uint64(b[4])<<24
uint64(b[3])<<32 uint64(b[2])<<40 uint64(b[1])<<48 uint64(b[0])<<56
output.addr.lo: addr[15] and addr[11]. Here is
a simplified SSA form before late opt:
v273 = Trunc64to8 <byte> v490 ; byte(input.addr.lo)
v226 = Trunc64to8 <byte> v225 ; byte(input.addr.lo >> 32)
; [ ]
v235 = Store <mem> byte v233 v226 v223 ; a16[11] = byte(lo >> 32)
v247 = Store <mem> byte v245 v238 v235 ; a16[12] =
v259 = Store <mem> byte v257 v250 v247 ; a16[13] =
v271 = Store <mem> byte v269 v262 v259 ; a16[14] =
v282 = Store <mem> byte v280 v273 v271 ; a16[15] = byte(lo)
v285 = LocalAddr <*[16]byte> netip.addr v2 v282 ; &addr
v286 = Move <mem> [16]byte [16] v285 v22 v282 ; addr = a16
; [ ]
v433 = OffPtr <*byte> [15] v285 ; &addr[15]
v435 = Load <byte> v433 v286 ; addr[15]
v479 = OffPtr <*byte> [11] v285 ; &addr[11]
v481 = Load <byte> v479 v286 ; addr[11]
(Load (OffPtr [o] p) (Move p src mem))
=> (Load (OffPtr [o] src) mem). It matches both loads, which now read a16
with the memory state before the copy:
v600 = OffPtr <*byte> [15] v22 ; &a16[15]
v435 = Load <byte> v600 v282 ; a16[15]
v601 = OffPtr <*byte> [11] v22 ; &a16[11]
v481 = Load <byte> v601 v282 ; a16[11]
(Load p (Store p x _)) =>
x. It matches v435, as v282 stores a16[15]. It does not match v481:
v235 stores a16[11] four stores earlier in the chain, while the variants of
this rule look through three stores at most.
v435 = Copy <byte> v273 ; byte(input.addr.lo)
v601 = OffPtr <*byte> [11] v22 ; &a16[11]
v481 = Load <byte> v601 v282 ; a16[11]
a16[12] to a16[15]. The twelve other loads now read a16 instead of
addr.
BEUint64() becomes a chain of Or64, each one adding a byte shifted into
place. memcombine is a pass written in Go, not a set of rewrite
rules. It starts from the last Or64 of the chain and collects up to eight
terms. If each term is a byte load, extended to 64 bits and shifted, and if the
eight loads read consecutive addresses from the same pointer with the same
memory state, it replaces the whole chain with a single 64-bit load and a byte
swap. Otherwise, it tries again with four, then two terms, and from each
intermediate Or64. Here is the loop checking each term in a simplified version
of combineLoads():
for i := int64(0); i < n; i++
v := a[i]
shift := int64(0)
if v.Op == shiftOp
v, shift = peelShift(v)
if v.Op != extOp
return false
load := v.Args[0]
if load.Op != ssaop.OpLoad
return false
if load.Args[1] != mem
return false
p, off := splitPtr(load.Args[0])
if p != base
return false
r[i] = LoadRecord load: load, offset: off, shift: shift
output.addr.hi, the eight loads read a16 with the same memory state
v282:
v13 = Load <byte> v22 v282 ; a16[0]
v530 = Load <byte> v14 v282 ; a16[1]
v488 = Load <byte> v504 v282 ; a16[2]
v405 = Load <byte> v537 v282 ; a16[3]
v385 = Load <byte> v397 v282 ; a16[4]
v361 = Load <byte> v373 v282 ; a16[5]
v196 = Load <byte> v63 v282 ; a16[6]
v432 = Load <byte> v315 v282 ; a16[7]
v319 = ZeroExt8to64 <uint64> v432 ; uint64(a16[7])
v329 = ZeroExt8to64 <uint64> v196 ; uint64(a16[6])
v330 = Lsh64x64 <uint64> [true] v329 v138 ; uint64(a16[6]) << 8
v331 = Or64 <uint64> v319 v330 ; a16[7] a16[6] << 8
; [ ] same for a16[5] to a16[1]
v401 = ZeroExt8to64 <uint64> v13 ; uint64(a16[0])
v402 = Lsh64x64 <uint64> [true] v401 v55 ; uint64(a16[0]) << 56
v403 = Or64 <uint64> v402 v391 ; a16[0] << 56 = output.addr.hi
memcombine merges them into one load and a swap:
v286 = Load <uint64> v22 v282 ; a16[:8]
v285 = Bswap64 <uint64> v286 ; output.addr.hi
output.addr.lo, here is the chain memcombine sees after late opt:
v436 = ZeroExt8to64 <uint64> v273 ; addr[15], forwarded
v448 = Or64 <uint64> v436 v447 ; addr[14] << 8, forwarded
v460 = Or64 <uint64> v459 v448 ; addr[13] << 16, forwarded
v472 = Or64 <uint64> v471 v460 ; addr[12] << 24, forwarded
v484 = Or64 <uint64> v483 v472 ; a16[11] << 32, loaded
v496 = Or64 <uint64> v495 v484 ; a16[10] << 40, loaded
v508 = Or64 <uint64> v507 v496 ; a16[9] << 48, loaded
v520 = Or64 <uint64> v519 v508 ; a16[8] << 56, loaded
v520, four of the eight terms are forwarded bytes, not loads from memory,
and memcombine can't combine them. It doesn't merge the four remaining loads
either, as they sit on top of the forwarded bytes.
memcombine before late opt. After
this change, the generated code for the helper is back to the
shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
CMPQ net/netip z4(SB), CX ; check "z" if this is an IPv4 address
JNE end ; if not, stop here
MOVQ net/netip z6noz(SB), CX ; CX = netip.z6noz
end:
RET
// return value = Addr hi: AX, lo: BX, z: CX
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
Go 1.26.8 Our branch
sec/op sec/op vs base
AddrTo6/safe 6.5470n 0% 0.8944n 4% -86.34% (p=0.002 n=6)
AddrTo6/unsafe 0.9071n 3% 0.8682n 1% -4.28% (p=0.002 n=6)
AddrTo6/builtin 0.8871n 2% 0.8785n 1% ~ (p=0.310 n=6)
memcombine pass. Instead, I plan to publish this blog post and bring up the
subject again as a follow-up to issue #54365. Either the sheer complexity and
the Go 1.27 regression convince the maintainers that adding a To6() method is
simpler and more efficient, or they advise me on how to move forward. Either
way, digging into this subject taught me a lot about the Go compiler!
Update (2026-10)
I opened issue #81994 to propose Addr.To6(). Give it a if you want
it in Go!
:: while it would
make more sense to leave it untouched.
netip.Addr's layout changes, you must add
tests to detect it. This is more dangerous if you put this code in a
package. Either ask users to run the tests themselves, or detect the change
at run time and panic. Hiding this optimization behind a build tag would
make users aware of this potential trap.
GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm
'\.asm' from the companion repository, then edited it a bit to keep this
article from turning into an endless rabbit hole. Due to an unfortunate
sequence of events, we switch between versions: Go 1.27 introduced a
regression that blurs the point of this article.
MOVBEQ requires GOAMD64=v3, matching the x86-64-v3
microarchitecture from 2013. Otherwise, the compiler translates
BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
_ = netip.Addr .
$ GOSSAFUNC=AddrTo6Safe \
> GOTOOLCHAIN=go1.26.8 \
> GOAMD64=v3 go build -a .
dumped SSA for AddrTo6Safe,1 to ./ssa.html
This post is a review for Computing Reviews for The Origins of GPU Computing , a article published in Communications of the ACMThis article appears in a Communications of the ACM series devoted to showcasing relevant examples where federal funding of academic research resulted in widely impacting, clearly identifiable technological advances that have visibly improved or at least changed life far beyond the technological arena. The road is far from trivial from the first parallel computing technologies built completely for research, to a phase that was preeminently directed at gaming, to the current graphics processing units (GPUs) that are basically massively parallel supercomputers used for large language model (LLM) training and inference and other artificial intelligence (AI) tasks and the authors do a good job outlining it in just a few pages. The article is written in a clearly divulgatory way, staying as clear of technical language as possible. The authors present three main enabling technologies for current GPU technologies: parallel computing, parallel graphics systems, and stream processing. Coming from a technical formation myself, although clearly better grounded in the software side of computer engineering than the electronics side, the most interesting nugget of information I took is that parallel computing was born due to the fact that transistor switching consumes very little energy, whereas communication along wires consumes much more. Thus, the more simultaneous operations can be carried out on-chip at once, the less power will be dissipated as heat (and the less time that will be lost due to data stores and loads). Graphics systems are a natural match for parallel systems, as rendering realistic images basically requires repeating the same blocks of instructions to a large array of items. Early GPU implementations were built on fixed-function graphics pipelines. However, by the turn of the century, when nVidia spun off the research labs at Stanford and started marketing their product, introducing along the way the GPU term, they enabled it to implement the full OpenGL graphics pipeline on a single chip. Stream processing is the arrangement of in-chip electronics so that they can better exploit producer-consumer locality between stages in order to achieve greater arithmetic intensity (this is, a greater computation-to-bandwidth ratio), reducing the total number of memory accesses. The authors explain in broad terms the described technologies and how they fit together, as well as how the technology was transferred from the universities to the companies behind today s top trending technologies. The article is engaging and easy to read. As a technologist, I did miss more details dates when specific advances were made, how some of the advances led to future inventions, and so on but I also understand the series is written for outsiders. And, as such, this work very well explains how trillion-dollar technologies are often the result of decades of funding research ideas.
| Publisher: | DAW |
| Copyright: | May 2026 |
| ISBN: | 0-7564-2013-X |
| Format: | Kindle |
| Pages: | 441 |
"There are a number of electromagnets in the next room," I say. I point. "Behind that wall with all the holes in it." "Those are big holes. And fresh, too," the dog says. "I wonder what made them." "Electromagnets experiencing sudden velocity." The dog gives another of its short barks, and I am more convinced now it is laughing, though I was not attempting to be funny.Ode to the Half-Broken has a classic science fiction beginning: in medias res in a future science fiction version of Earth where nothing is immediately explained, leaving the reader to work out the date and the setting. Helping us out is the protagonist, who is neither chatty nor very sociable with other characters but keeps up an analytical monologue about the world as they narrate events. We are some decades into a grim future. The United States has largely collapsed. Large parts of New York City are dangerous to humans due to disease and radiation. Neither of those hazards bother the large number of sentient robots; their scarcity, and therefore economy, is instead based on power. Robots that control solar power stations act as low-level mob bosses, trading power for information or labor. Our protagonist doesn't want to care about any of this. They retreated from the world long ago for a solitary life in the former New York Botanical Gardens studying ants. But they need a new leg and the best robot repair person nearby is a human woman outside of the city, so they reluctantly head in that direction, accompanied somewhat surprisingly by a cyborg dog. The typical science fiction apocalypse is caused by something specific. Classically, that event is a nuclear war, but writers found various alternatives before, during, and after the Cold War era: alien invasions, meteor showers, plagues, sea level rise, and peak oil and general environmental collapse, among many others. Less common is a post-apocalyptic novel where the collapse comes from multiple overlapping crises and accumulating failures, from a general failure to meet what Adam Tooze and others call polycrisis. The first time I encountered that style of post-apocalyptic story was in Octavia Butler's Parable of the Sower. It was one of the choices that made (and still makes) that book feel so chillingly realistic. The world background in Ode to the Half-Broken is shaped by that sort of polycrisis collapse. There is no one reason why New York City is a dangerous, irradiated ruin and society has collapsed into isolated and sometimes warring factions. It is not runaway artificial intelligence, or at least not directly; sentient robots were a late-stage innovation of the collapsing US civilization and a tool and accelerator of its many wars, but they were not the cause and may be a critical ingredient in building some functional replacement. Instead, society fell apart because we failed to address any of the growing problems and then turned on each other in the resulting ruins. The reader gets an idiosyncratic view of that collapse in flashback chapters intermixed with the main narrative of the initially unnamed robot protagonist, flashbacks told from the perspective of the man who invented the key component for robot sentience. As you would expect, those two narratives are linked. The reader will not discover how they are linked until late in the story. This book could have been extremely depressing. It is not, which says a great deal about Palmer's skill in telling it. The clinical distance of the protagonist in the early chapters helps considerably: They have rejected involvement in this world and therefore can describe it in detached, factual terms, aided by the tendency of most robots in this story to be slightly more precise, logical, and verbose than the human characters. But as the protagonist's clinical distance fades, as it must to allow the story's emotional stakes to rise, Palmer fills this book with moments of beauty and hope. A former nuclear submarine that has become the mind of a subway car is a key early ally. A collective has turned the Hudson Bridge into a thriving if chaotic community. Self-regulating enclaves of humans and robots are working together to try to build a livable world. Robots oversee pollinator swarms that are attempting to restore plant life, for no reason other than that they like order and stability and see this as a way of restoring both. This is a grim, post-apocalyptic world that does not dwell on either the grimness or the apocalypse. It is instead full of small moments of hope, collaboration, and personal connection. This is a story with villains, danger, pain, and risk. Despite the similar keywords and cover aesthetics, it bears little resemblance to Becky Chambers's philosophical Monk and Robot series. It is not, in any definition of the term, cozy; it's a post-apocalyptic adventure story about a robot and a dog making their way through a ruined civilization and fighting people who are trying to build something even worse on the rubble. But it's also charming and oddly happy. There are strong found-family vibes in the way that a party coalesces around the protagonist and eventually gives them a name, there is the quiet happiness of seeing a grumpy misanthrope slowly come out of their protective shell, and the rail mechs are an absolute delight. Like a lot of stories of happy small-group anarchism, I didn't entirely believe the politics and have some qualms about the realism of the ending, although perhaps I should strive to be as optimistic as Palmer writes. The somewhat dry and fussily precise first-person narration will also not be to everyone's taste; it worked for me by the end of the book, but it took a bit of reading to get used to it. But those quibbles aside, this was quietly lovely. It's a satisfying science fiction adventure story in a world with disturbing parallels to the one we're living in, but which uses those parallels to focus on small-scale collective efforts to build something better. And all the small details of the world-building are delightful: the different tiers of robots and their odd behaviors, the machine sense of purpose, even the mix of suspicion and generosity. The plot has large-scale implications, but it was the human-level details that charmed me. I still want another Fergus novel, but this was a highly successful foray outside of that series. Palmer has won two Hugos for her novellas, so I can't really say she's overlooked, but her novels aren't getting anywhere near the attention they deserve. Highly recommended. There is plenty of world-building room here for a sequel, but Ode to the Half-Broken reaches a satisfying standalone conclusion. So far as I know, no sequel is currently planned. Rating: 8 out of 10
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1331 other packages on CRAN, downloaded 48.5 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 727 times according
to Google Scholar.
This versions updates to the 15.6.0 upstream Armadillo release made
yesterday. It extends solver options for poorly conditioned systems, and
brings some updates and extension to the cube data type.
For this release, we once again ran the usual complete
reverse-dependency check which came back spotless, and did CRAN so no
email exchange needed despite nearly 1300 reverse dependencies (but it
ended up taking more than a single business day). Still, automation can
be helpful when used with a well-maintained software stack. The package
has also already been updated for Debian, built for r2u and r-universe, and
will build shortly at CRAN for
the different binary releases.
All changes since the last CRAN release follow.
Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.Changes in RcppArmadillo version 15.6.0-1 (2026-09-07)
- Upgraded to Armadillo release 15.6.0 (Medium Roast Cortado)
- Expanded
solve()withsolve_opts::scale_threshoption to widen detection of poorly conditioned systems- Expanded
trans()and.t()to handle cubes- Added
permute()to rearrange dimensions of cubes (generalised transpose)- Added
cubemul()for batched matrix multiplication of cube slices
This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.
Encoder), and something that
takes chunks of IQ samples in, writing out decoded bytes (which we ll call the
Decoder).
Encoder, since it s slightly less involved. I ve tried
to make this a bit more accessible by drawing a diagram out before describing
the order of operations, so that it s possible to follow along visually.
While the process here can look like a lot, it s really not that bad.
We begin by taking the incoming bytes, converting the bytes into bits, and chunk
those bits into parts which are sized to fit completely within an LDPC message. We will then
encode incoming data into LDPC messages, using our
configured LDPC Matrix (the table we appropriated from 802.3an). Next, we
apply whitning over all the bits in our
encoded (and packed) LDPC messages, using our configured whitening constant. In
the case of QPSK, pairs of bits will then be
modulated into a QAM subcarrier, where each
QAM point represents a range of bits in the message. We ll go through each of
those modulated IQ subcarriers, and
set each corresponding data subcarrier
in order, for each OFDM symbol contained in the pigeon Burst. The preamble configuration
is then used to generate (or, more likely, can be used at startup to precompute)
the Schmidl-Cox preamble, which is written to the
first IQ samples in our output IQ buffer. Finally, we will do a series of
inverse FFT operations to convert each
OFDM symbol to the time domain, including their cyclic prefix.
Let s take a look at doing that, but in code this time now:
// (lightly edited for clarity)
impl Encoder
..
/// Encode the provided bits into the output time-domain IQ samples.
fn encode(
&mut self,
dst: &mut [IQ],
src: &Vector,
) -> Result<Burst, Error>
let src =
let mut raw = Vector::new(self.fec.message_len());
// Set raw 's data bits, compute and set LDPC
// checkbits.
self.fec.add(&mut raw, src);
// Apply whitening, and return
raw.xor(&self.whitening)
;
// copy in the precomputed schmidl-cox preamble to dst
let preamble_len = self.preamble_iq.len();
dst[..preamble_len].copy_from_slice(&self.preamble_iq);
// allocate a new (frequency domain) 'Burst' container.
let mut burst = Burst::new(
&self.mode.ofdm.plan,
self.mode.ofdm.symbols
);
// modulate bits from 'src' as iq, and set each
// data subcarrier for each ofdm symbol in the
// burst.
self.burst_encoder.multiplex(&mut burst, &src);
// convert from frequency-domain data into time
// domain iq samples, writing out ofdm symbols
// and cyclic prefixes to dst .
self.burst_encoder
.transform(&mut dst[preamble_len..], &burst)?;
// normalize all IQ samples; the maximum magnitude
// in the IQ buffer may be very small, which weakens
// our transmitted signal. Scale all IQ samples such
// that the maximum IQ sample magnitude will be '1.0'.
dst.norm();
Ok(burst)
Encoder should hopefully be fairly straightforward we ll
give it a bag of bytes, and get back some IQ samples that we can ask our
nearest SDR to transmit.
As for what happens on the other end?
Encoder the, imaginatively named,
Decoder. The Decoder is slightly more involved (since it has to find the
packet in the IQ stream, as well as correct for channel error(s)), so we ll do
the same thing as above start with a diagram. My hope is going over the
Encoder first helps us only really focus on the new stuff, otherwise it
should feel like running the Encoder backwards.
Here, we start with an incoming stream of IQ, where we will process
scan detections as they come in
from our Schmidl-Cox detector and burst Scanner. This will give us a snippit
of IQ, sized to exactly our Burst. We ll begin to correct our IQ samples by
first doing
frequency estimation and correction
in the time domain using our preamble and ofdm configuration. We ll then do
a series of inverse FFTs to extract each OFDM symbol
in our Burst, where we can then do
channel estimation and correction.
With the OFDM symbols (hopefully) good enough, we can now
map each data subcarrier back to bits, and
unapply whitning. The resulting
bits are then chunked back up into LDPC messages,
which are then checked, and concatanated data extracted. Finally the bits
are turned back into bytes, which are written to our output buffer.
However, before we get into the code to do this there s one last detail. We
know bursts won t overlap (if they do, it s likely not possible to recover
right now even though other PHYs can and do), so any time we see something we believe
to be a burst, we can skip ahead by the burst s (constant) length within
the IQ, and avoid trying to decode anything else in there.
The nice side-effect here is this also gives us an interesting property for the
Decoder namely, we know the maximum number of Burst detections we can
get for a given block of incoming IQ data if they were packed end-to-end and
we can pre-allocate the memory we need, avoiding allocations for every
demodulation attempt (which may or may not even be a valid Burst).
This pre-allocated block of memory to hold the burst s data is something that
I ve called a frame buffer internally. Each frame buffer contains exactly
sized buffers to hold decoded information from the burst an iq buffer
that is exactly the same number of samples required to encode the preamble
and data, exactly the number of bits needed to store pre and post FEC data,
pre-allocated byte array, etc.
Not shockingly, the code looks like this:
#[derive(Clone)]
pub struct FrameBuffer
/// Corrected IQ samples
pub samples: Samples,
/// post-correction OFDM burst
pub burst: Burst,
/// demodulated bits from the OFDM burst
pub bits: Vector,
/// demodulated bits from the OFDM burst,
/// after FEC, and cleaned
pub raw_bits: Vector,
/// Layer 2 contents of the Frame
pub contents: Vec<u8>,
Decoder uses a fixed number of
pre-allocated FrameBuffers to store packets in-flight, packed into what
is, creatively, called FrameBuffers within my code.
As an aside, I likely should have called this a
Memory Pool, since that s the
common
and accepted
name for this design pattern but being stuck with unfortunate names is
the burden of those of us who stumble into sensible ideas over time. The only
nuance here is that I use the pools strictly sequentially we only save
the FrameBuffer if the LDPC checksum is correct, allowing us to only keep
track of how many successful packets we have and being able to get the valid
FrameBuffers, rather than storing a handle to each FrameBuffer as we go
a promise that most memory pools do not make, since blocks can usually be
taken and returned in any order.
Let s go ahead and do the whole Decoder dance now:
// (lightly edited for clarity)
impl Decoder
..
/// Process incoming IQ for Pigeon Bursts, and
/// demodulate them.
pub fn decode(
&mut self,
buf: &[IQ],
) -> Result<Vec<(Detection, &FrameBuffer)>, Error>
let mut ret = Vec::new();
let mode = self.scanner.mode().clone();
// reset the "valid frame buffer count" back to 0
self.frames.reset();
// call the scanner and get scan detections for
// this block of iq ( buf )
for detection in self.scanner.scan(buf)
// for each detection, we're (only) going to process
// the iq snippit, but pass along the metadata
// such as SNR.
let ScanDetection
snippit,
snr,
range,
m,
= detection;
// grab the next free frame buffer to work within.
let frame_buffer = self.frames.next_mut();
// Copy the snippit into the frame buffer (a mutable
// location)
frame_buffer.samples.copy_from_slice(snippit);
// estimate the frequency offset based on the
// Burst's Schmidl-Cox preamble.
let preamble_fo = preamble::estimate_frequency_offset(
&mode.preamble,
mode.rate,
&frame_buffer.samples[..mode.preamble.samples()],
);
// Shift the IQ stream by the estimated frequency
// offset -- hopefully we're closer to 0Hz
frame_buffer.samples.shift(mode.rate, preamble_fo);
// estimate the frequency offset based on the
// each burst's **cyclic prefix** -- exactly like
// we did with the Burst Schmidl-Cox preamble,
// but this time on each OFDM symbol.
let ofdm_fo = ofdm::estimate_frequency_offset(
&mode.ofdm,
mode.rate,
&frame_buffer.samples[mode.preamble.samples()..],
);
// Shift the IQ stream closer yet; hopefully this
// is a very small nudge even closer still to 0Hz.
frame_buffer.samples.shift(mode.rate, ofdm_fo);
// Do a bunch of inverse fft operations for each
// OFDM symbol, filling the frequency-domain Symbol
// structs in frame_buffer.burst (Burst) struct.
//
// this will also do channel estimation and
// correction before returning.
self
.decoder
.transform(
&mut frame_buffer.burst,
&frame_buffer.samples[mode.preamble.samples()..],
)?;
// "demultiplex" each data subcarrier's frequency-domain
// IQ constellation point, setting the correct bit range.
self.decoder.demultiplex(
&mut frame_buffer.raw_bits,
&frame_buffer.burst
);
// unapply whitening by XOR-ing the buffer with
// the well-known whitening vector.
frame_buffer.raw_bits = frame_buffer.raw_bits.xor(
&self.whitening);
// verify that the LDPC message(s) are all correct,
// and if so, concatanate the the data bits (no check
// bits) to the bits vector.
if self.fec.decode(
&mut frame_buffer.bits,
&frame_buffer.raw_bits
).is_err()
// this is where invalid packets fail. we gave it a good go.
// next packet please.
continue;
// copy the raw bits out, as bytes, to the contents buffer.
frame_buffer.bits.copy_as_bytes(&mut frame_buffer.contents);
// store metadata/metrics on the demodulation.
ret.push(Detection
m,
snr,
index: range.start,
);
// save the contents of this frame buffer (don't
// reuse this buffer next go-around).
self.frames.save();
// We're going to take out the borrow on the frame at
// the end since we don't want to deal with telling the
// compiler via code gymnastics that the mut and non-mut
// borrows are OK since they're non-overlapping.
Ok(ret.into_iter().zip(self.frames.iter()).collect())
My Debian contributions this month were all sponsored by Freexian.
You can also support my work directly via Liberapay or GitHub Sponsors.
Personal note
This month, my Dad unexpectedly passed away after a short illness. As a result I obviously got less work done than usual, and I still have a lot to take care of (since I m the executor of his will, as well as helping with funeral arrangements) while grieving and generally having less focus and energy. Having routine work to do is one of the ways I cope with this sort of thing, but all the same, I hope people will bear with me and maybe remind me if I seem to be dropping the ball on something you especially need.
LLM vote
[Content note: strong opinions.]
I voted in General Resolution: LLM usage in Debian. My vote was pretty much the opposite of what ended up winning, so I m quite disappointed. My personal opinion is that LLMs are cognitive hazards to their users that impose ecological costs far out of proportion to their utility at a time when the world absolutely cannot afford them. When the impossible economics of the large commercial models are finally allowed to catch up with reality, I expect there to be significant macroeconomic consequences, and that people who have become dependent on them will have problems; and who knows what the copyright situation on their output really is. I m not convinced that local models are better enough on these axes to be worth the costs.
Debian s direct contribution to all that will be negligible on a global scale, and even the most radical proposals in the GR didn t expect that we could do much about upstreams that have gone all-in on LLMs. Even so, I d hoped that my fellow developers might be more willing to lean on our position in the free software ecosystem to make at least a moderately radical statement. Instead, we ve at best presented an undistinguished fence-sitting position to the world, and further entrenched the idea that humans can reliably do a good job of reviewing the output of tools that are designed to produce output plausible to humans. I certainly don t trust my own code review skills that far.
Since I ve never voluntarily used an LLM (not counting LLMs being foisted on me by things like search results, support chatbots, or incoming pull requests, regardless of whether I asked for them), and don t intend to for the foreseeable future, I doubt this will change much for me in terms of the way I work. The winning option is a very weak one that imposes no new requirements on developers, which means that it also does nothing to stop me continuing to reject LLM-generated material from Debian bug reports and merge requests in my areas of responsibility. I know this probably won t do much to satisfy people who have decided that Debian is slop now, but it s the best I can do.
OpenSSH
I finally landed the GSS-API key exchange package split in our OpenSSH packaging. Here s the NEWS entry:
openssh (1:10.4p1-5) unstable; urgency=medium
The openssh-client and openssh-server packages no longer include GSS-API
authentication and key exchange support; this adds pre-authentication
attack surface and generally increases complexity, and should only be used
where specifically needed. Users who need these features should install
openssh-client-gssapi or openssh-server-gssapi instead.
-- Colin Watson <cjwatson@debian.org> Sun, 23 Aug 2026 17:39:55 +0100
openssh and the new openssh-gssapi source package in sync.
PuTTY
I upgraded from 0.84 to 0.85.
Python packaging
New upstream versions:
bytes.IndexByte is implemented with
hand-written Go
assembly
(including AVX2).crypto/internal/fips140/sha256 uses
AVX2. While
Avo generator code definitely is higher-level than hand-written assembly, it
is still too close to assembly for my taste.simd/archsimd package:
Go 1.26 introduces a new experimentalFor my 2019 TurboPFor analysis, I implementedsimd/archsimdpackage, which can be enabled by setting the environment variableGOEXPERIMENT=simdat build time. This package provides access to architecture-specific SIMD operations. It is currently available on theamd64architecture and supports 128-bit, 256-bit, and 512-bit vector types, such asInt8x16andFloat64x8, with operations such asInt8x16.Add. The API is not yet considered stable. Go 1.26 Release Notes
goturbopfor, a native Go
teaching decoder (without any SIMD),
because I find Go code easier to follow than C code, especially optimized C
code. My implementation was intentionally not optimized so that the code was
easier to study.
The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in
a scalar variant (bitunpack32) and a vector variant
(bitunpack256v32),
where the vector variant is used for full blocks (256 values) and the scalar
variant is used for remainder blocks (< 256 values).
When Go 1.26 was released, I used Claude Code to explore whether my native Go
decoder s bitunpack256v32 function (for the vertical vector layout) could be
implemented using Go SIMD, and the answer was yes, it was possible and it was
faster than without SIMD, but not quite at the level of C TurboPFor. If you let
Claude Code try for long enough, it eventually finds enough optimizations (about
10) to match C performance.
I don t want to vibe-code Debian Code Search, though, so I figured I would find
some time to review the SIMD code at some point and see if I could implement
something similar myself.
Before I found enough time and motivation to complete said review, I discovered
that to not regress real-life query performance by more than 10 to 100
milliseconds (which seems acceptable), I don t actually need to add SIMD code to
my teaching decoder at all; it would be sufficient to reduce allocations in my
teaching decoder and specialize it per bit width.
Encouraged by the possibility of using the optimized native Go decoder in Debian
Code Search, I explored whether I could also implement a native Go encoder so
that I could get rid of the C TurboPFor dependency entirely. The answer is yes,
it is doable in a few days, and it isn t even that much slower: Go is at 76% of
C, see Debian/dcs commit
e920dc7.
The goal I set myself at that point was to see if I could learn enough SIMD to
optimize the native Go encoder such that its performance would match how DCS
uses C TurboPFor (via cgo).
Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width
specialization). To my surprise, Claude Fable 5 pointed out that the encoder s
block scanning could be done more efficiently using a technique called
positional popcount, and that is another 2x speed-up!
To be clear: I am not saying the Go compiler beats C here. Certainly, the C
compiler can also produce fast AVX512 code and can be used to implement
positional popcount. When comparing apples to apples, i.e. backporting the
AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a
little slower at 1.4x C.
This spectacular result (much faster than what DCS had before) got me curious
how far I could push the decoder with SIMD after all. I ended up
matching/exceeding the cgo version here, too!
The rest of this article explains a few classes of optimizations I encountered
along the way.
goturbopfor teaching
decoder, I named its functions to
match the upstream C TurboPFor library, but now I want to get away from names
like p4ndec256v32 they make sense from the TurboPFor perspective, but for
Debian Code Search, we can use cleaner names.
Before writing any code, I audited how DCS uses integer compression /
decompression.
hello-2.12.3-1
package (hypothetically) contained
only hello.c with printf("hello!\n");, we would assign document ID 1 to
hello.c and store in the partial index that trigrams pri, rin, int,
ntf, etc. are all found in doc 1 (hello.c).1 in the partial index might be document ID 2531 in the
full index.uint32s fully in memory, so we
only need DecodeN(input []byte, output []uint32) (read int), a function that
reads len(output) values (uint32) from input and returns how many bytes it
consumed.
For writing the index (both in partial indexing, and when merging), keeping the
entire index in memory is prohibitively expensive, so we need a streaming API,
for decoding and for encoding.
Ultimately, I converged on the following API:
package pforenc
type BlockEncoder struct
// scratch buffers can go here
// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).
func (*BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte
// EncodeN calls EncodeBlock in a loop.
func (*BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte
type StreamEncoder struct
be BlockEncoder
vals [256]uint32
// scratch buffers
// if full, you need to call [EncodeBlock]
func (*StreamEncoder) Add(val uint32) (full bool)
// EncodeBlock must be called after all data was [Add]ed.
//
// Write the returned buffer to file or send it over the network;
// it is only valid until the next [EncodeBlock] call.
func (*StreamEncoder) EncodeBlock() []byte
if se.n == 0 return nil // turn an extra EncodeBlock into a no-op
//
goturbopfor teaching decoder. Next up, I needed an
encoder.
Writing a TurboPFor encoder has a delightfully simple starting point: You can
encode all values at bit width 32, in little endian, at which point you only
need to add a one-byte TurboPFor block header every 256 values and you re done:
func (be *BlockEncoder) EncodeN(dest []byte, vals []uint32) []byte
for len(vals) > 0
chunk := min(len(vals), 256)
dest = be.EncodeBlock(dest, vals[:chunk])
vals = vals[chunk:]
return dest
func (be *BlockEncoder) EncodeBlock(dest []byte, vals []uint32) []byte
const bitWidth = 32
dest = append(dest, bitWidth)
for _, val := range vals
dest = binary.LittleEndian.AppendUint32(dest, val)
return dest
0 bitWidth 32) in little
endian byte order. By scanning all
values and choosing the smallest bit width that allows representing all
values, this technique saves disk space (compresses).GOAMD64
The microarchitecture of a CPU determines which instructions it provides, and
that includes not just SIMD instruction sets (like AVX2), but also other useful
instructions like LZCNT (Leading Zero Count), which can be used to implement
math/bits.Len32 more efficiently, which
the TurboPFor encoder needs to call on every input value to determine the ideal
bit width.
Let s walk through how to set the microarchitecture level when using Go on
64-bit x86 (x86-64).
Go uses the GOARCH environment
variable to configure the target
compilation architecture, and I am using the value amd64 to select 64-bit x86
(AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With
GOARCH=amd64, the architecture-specific variable
GOAMD64 configures the
microarchitecture level for which to compile and Go 1.18 introduced these 4
different levels:
In 2026, I generally recommend compiling withGOAMD64=v1(default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute.GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3.GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE.GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
GOAMD64=v3 so that functions
like bits.OnesCount8 are
compiled into intrinsics
(POPCNT)
instead of using a lookup table.
For Intel CPUs, setting GOAMD64=v3 means your programs will only start on
Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer.
In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4
microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer
(Intel s story is complicated). Luckily, both my main development PC (Zen 5)
and the Debian Code Search server (Zen 4) are recent enough. Setting
GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps
use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling
with GOAMD64=v4 allows us to move one more feature check from runtime to
compile time, see SIMD build tags.
It makes sense to set the microarchitecture level in your benchmark setup so
that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.
testing package contains support for
benchmarks which are written in
functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run
such benchmarks is go test -bench=., but I ended up configuring a few
convenience make targets, which write results to bench.txt and compare
against baseline.txt (the previous commit s results, usually), using the very
useful benchstat tool.
GOTEST=go test
# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6
# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1
BENCH=$(TASKSET) $(GOTEST) $(BENCHFLAGS)
.PHONY: all test bench bench-baseline bench-relative
all: test
bench: test
$(BENCH) tee bench.txt
# Compares compression ratio between C and Go implementation
benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt
bench-baseline: test
$(BENCH) tee baseline.txt
bench-relative: test
$(BENCH) tee bench.txt
benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
encoded-bytes and Mval/s units are custom metrics I am reporting from
the various sub-benchmarks, which are arranged
such that I can filter / report them with benchstat.
The main encoder (and decoder) benchmarks compare 3 different implementations
(cgo, Go, Go with the StreamEncoder API) with a number of benchmark
cases
that are designed to cover the different block types and contain a similar mix
of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.
func reportMetrics(b *testing.B, n int, nencoded int)
b.ReportMetric(float64(nencoded), "encoded-bytes")
b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(), "Mval/s")
// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>
//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-stream
func BenchmarkEncode(b *testing.B)
for _, tc := range allBenchCases()
n := len(tc.vals)
b.Run(fmt.Sprintf("n=%d/vals=%s", n, tc.name), func(b *testing.B)
b.Run("impl=c", func(b *testing.B)
b.ReportAllocs()
var encoded []byte
buf := make([]byte, turbopfor.EncodingSize(n))
for b.Loop()
encoded = turbopfor.P4nenc256v32Buf(buf, tc.vals)
reportMetrics(b, n, len(encoded))
)
b.Run("impl=go", func(b *testing.B)
b.ReportAllocs()
var be BlockEncoder
var encoded []byte
buf := make([]byte, 0, turbopfor.EncodingSize(n))
for b.Loop()
encoded = be.EncodeN(buf, tc.vals)
reportMetrics(b, n, len(encoded))
)
b.Run("impl=go-stream", func(b *testing.B)
b.ReportAllocs()
var se StreamEncoder
var encoded int
for b.Loop()
encoded = 0
for _, val := range tc.vals
if se.Add(val)
encoded += len(se.EncodeBlock())
reportMetrics(b, n, encoded)
)
)
pprof, a sampling profiler. This profiler can help track
down which part of a program runs slow, or where memory allocations happen.
Once you identified the slow part of a program, how do you know why it s slow?
To learn more about the specific bottlenecks your program encounters, you can
consult your CPU s hardware performance
counters. For
example, you could check the branch
predictor counters to see if
your program is slow due to a high number of branch mispredicts.
On Linux, the perf tool is the best way to access the CPU hardware performance
counters. A good starting point for working with perf is the documentation on
Top-down analysis with the perf
tool , which describes the
optimization method that Intel established.
In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1
PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x
# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:
$(GOTEST) -c
$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$ $(PERFBENCHFLAGS)
sudo chmod 644 perf.data
# 488281 iterations 2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:
$(GOTEST) -c
$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
perf-per-value numbers are high level numbers that indicate how much work
the implementation is doing. Reducing the number usually increases speed.
To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which
directly shows the hottest function.
PCALIGNMAX(64, 31) on the first block of a
loop (the loop body ) for all loops in hot functions (per the PGO profile),
i.e. Go will insert up to 31 bytes of padding to make the block land on a
64-byte boundary. Documentation like AMD s Software Optimization Guide for the
AMD Zen5 Microarchitecture (2024,
#58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be helpful. Because the processor can read an aligned 64-byte fetch block every cycle, it is suggested to either align the start of the loop to the beginning of a 64-byte cache line [ ]Indeed, when compiling with
-gcflags=all=-d=alignhot=0 to disable the
alignment, performance remains as good as without PGO. How can the padding hurt
more than help? The answer is: It s not the padding itself! It s a side-effect
of the padding moving instructions to different addresses.
In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends
up exactly on a 32-byte boundary. However, the Go compiler ensures fused
branch sequences must never cross or end at a 32-byte boundary to fix Intel
erratum
SKX102
(discussion: Go issue #35881) by
inserting NOPs.
This NOP padding, unlike the loop alignment padding, is not free; these extra
instructions slow down our otherwise dispatch-bound loops.
Because the commits after the PGO enabling commit change the code, this unlucky
situation is avoided for the rest of the optimization series (by chance).
goturbopfor teaching decoder, whenever the code needed a scratch buffer,
it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit ints
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)
//
switch blockType
case blockBitpackingExceptions:
bx, input := input[0], input[1:]
n := len(output)
exmap := input
nex := 0 // number of exceptions
for i := 0; i < n; i++
if exmap[i/8]&(1<<uint(i%8)) != 0
nex++
input = input[(n+7)/8:]
exceptions := make([]uint32, nex)
input = input[bitunpack32(input, exceptions, bx):]
input = input[d.bitunpack(input, output, b):]
for i := 0; i < n; i++
if exmap[i/8]&(1<<uint(i%8)) != 0
output[i] += exceptions[0] << b
exceptions = exceptions[1:]
return before - len(input)
make(T, n) calls into stack allocations, if n is
known at compile-time. But, in this case nex is not known at compile-time. We
can verify that Go calls into the runtime (runtime.makeslice) by dumping the
object code (assembly) with source annotated (-S):
% cd ~/go/src/github.com/stapelberg/goturbopfor
% git reset --hard 49b7c05cc61e77f0257568eb73833467714d2b4a
% go test -c # go1.27.0
% go tool objdump -S goturbopfor.test perl -nlE 'say if /p4dec32/ .. /^$/'
TEXT github.com/stapelberg/goturbopfor.(*decoder).p4dec32(SB) /home/michael/go/src/github.com/stapelberg/goturbopfor/goturbopfor.go
func (d *decoder) p4dec32(input []byte, output []uint32) (read int)
0x549f60 4c8da42460ffffff LEAQ 0xffffff60(SP), R12
0x549f68 4d3b6610 CMPQ R12, 0x10(R14)
0x549f6c 0f86d9070000 JBE 0x54a74b
0x549f72 55 PUSHQ BP
0x549f73 4889e5 MOVQ SP, BP
0x549f76 4881ec18010000 SUBQ $0x118, SP
0x549f7d 48899c2430010000 MOVQ BX, 0x130(SP)
0x549f85 4889b42448010000 MOVQ SI, 0x148(SP)
if len(output) == 0
0x549f8d 4d85c0 TESTQ R8, R8
0x549f90 0f84a7030000 JE 0x54a33d
0x549f96 660f1f840000000000 NOPW 0(AX)(AX*1)
0x549f9f 90 NOPL
[ ]
exceptions := make([]uint32, nex)
0x54a4be 488d057bec1700 LEAQ 0x17ec7b(IP), AX
0x54a4c5 4c89fb MOVQ R15, BX
0x54a4c8 4889d9 MOVQ BX, CX
0x54a4cb e8f0ddf3ff CALL runtime.makeslice(SB)
[ ]goturbopfor). In the DCS pfordec package (with the improved
API design), I ended up with a vals [256]uint32 field in the StreamDecoder
type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
% benchstat -filter '/impl:go /vals:debian-mix .unit:(Mval/s)' \
baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pfordec
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
baseline.txt bench.txt
Mval/s Mval/s vs base
n=2048 1.089k 1% 1.175k 0% +7.85% (p=0.002 n=6)
n=2039 974.7 0% 1046.0 0% +7.32% (p=0.002 n=6)
n=160 434.9 1% 513.6 5% +18.11% (p=0.002 n=6)
geomean 772.9 857.7 +10.98%
Aside from the speed-up, avoiding memory allocations is generally nice in
benchmarks because it removes the garbage collector from the equation and makes
it less likely that your benchmarks get other processes OOM-killed on the same
machine.
bitpack implementation:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte
mask := uint32(1<<bitWidth - 1)
var acc uint64
var have int
for _, val := range vals
acc = uint64(val&mask) << have
have += bitWidth
for have >= 32
dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
acc >>= 32
have -= 32
for have > 0
dest = append(dest, byte(acc))
acc >>= 8
have -= 8
return dest
vals), but not their actual value.bitWidth).dest instead of changing dest on each
value (with AppendUint32):
func bitpack32Unrolled(dest []byte, vals *[32]uint32, bitWidth int)
// only one bounds check for 32 values
dest = dest[: 4*bitWidth : 4*bitWidth]
mask := uint32(1<<bitWidth - 1)
var acc uint64
var have, pos int
// Manually unrolled loop starts here.
// Each iteration is identical except for the vals[x] index.
acc = uint64(vals[0]&mask) << have
have += bitWidth
if have >= 32
binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
pos += 4
acc >>= 32
have -= 32
// vals[1] .. vals[30] elided for brevity
// Each loop iteration is 8 lines of Go code, so for 32 input values,
// bitpack32Unrolled contains 8*32 = 256 lines of code.
acc = uint64(vals[31]&mask) << have
have += bitWidth
if have >= 32
binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
pos += 4
acc >>= 32
have -= 32
// have == 0; for all bitWidths
bitpack32Unrolled 32 times (= 8192 lines of Go code)?
Yes, we can use Go generics to help us with the code generation!
In Go, array types like [4]byte (not
slices like []byte!) contain the length of the array as part of their type,
meaning [1]byte (an array of length 1) is a different type than [2]byte.
Instead of passing the bit width as a function parameter, we can declare 32
different types (one for each bit width) and recover the bit width (at compile
time!) from the type system:
type bitWidthT interface
[1]byte [2]byte [3]byte [4]byte [5]byte
[6]byte [7]byte [8]byte [9]byte [10]byte
[11]byte [12]byte [13]byte [14]byte [15]byte
[16]byte [17]byte [18]byte [19]byte [20]byte
[21]byte [22]byte [23]byte [24]byte [25]byte
[26]byte [27]byte [28]byte [29]byte [30]byte
[31]byte [32]byte
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)
var zero T
bitWidth := len(zero) // known at compile time
dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
mask := uint32(1<<bitWidth - 1)
var acc uint64
var have, pos int
// Manually unrolled loop starts here.
// Each iteration is identical except for the vals[x] index.
acc = uint64(vals[0]&mask) << have
have += bitWidth
if have >= 32
binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
pos += 4
acc >>= 32
have -= 32
// vals[1] .. vals[31] elided for brevity
bitpack32Unrolled[bitWidthT] with all 32 different types
([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT
type parameter and produces 32 copies of the function, which we can find in our
compiled executable with names like
github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The
shape of a generic type is based on its memory layout, so a shape for
[1]byte must be different than the shape for [2]byte.
Because the bitWidth is now known at compile time, the Go compiler can
generate close to the optimal machine code for each bit width, which we can
confirm using go tool objdump.
The code is branchless (after the one bounds check per 32 values) and aside from
the loads and stores (from/to memory) consists only of shifts and bit
operations, all with constant operands:
% go test -c && go tool objdump -S pforenc.test
[ ]
TEXT github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[28]uint8](SB) /home/michael/dcs/internal/turbopfor/pforenc/bitpackunroll.go
func bitpack32Unrolled[T bitWidthT](dest []byte, vals *[32]uint32)
0x660580 55 PUSHQ BP
0x660581 4889e5 MOVQ SP, BP
0x660584 48895c2418 MOVQ BX, 0x18(SP)
dest = dest[: 4*bitWidth : 4*bitWidth] // make cap known at compile time
0x660589 4883ff70 CMPQ DI, $0x70
0x66058d 0f820b030000 JB 0x66089e
acc = uint64(vals[0]&mask) << have
0x660593 8b06 MOVL 0(SI), AX
0x660595 25ffffff0f ANDL $0xfffffff, AX
acc = uint64(vals[1]&mask) << have
0x66059a 8b4e04 MOVL 0x4(SI), CX
0x66059d 81e1ffffff0f ANDL $0xfffffff, CX
0x6605a3 48c1e11c SHLQ $0x1c, CX
0x6605a7 4809c8 ORQ CX, AX
acc >>= 32
0x6605aa 4889c1 MOVQ AX, CX
0x6605ad 48c1e820 SHRQ $0x20, AX
binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
0x6605b1 90 NOPL
b[0] = byte(v)
0x6605b2 890b MOVL CX, 0(BX)
acc = uint64(vals[2]&mask) << have
0x6605b4 8b4e08 MOVL 0x8(SI), CX
0x6605b7 81e1ffffff0f ANDL $0xfffffff, CX
0x6605bd 48c1e118 SHLQ $0x18, CX
0x6605c1 4809c1 ORQ AX, CX
acc >>= 32
0x6605c4 4889c8 MOVQ CX, AX
0x6605c7 48c1e920 SHRQ $0x20, CX
binary.LittleEndian.PutUint32(dest[pos:pos+4], uint32(acc))
0x6605cb 90 NOPL
b[0] = byte(v)
0x6605cc 894304 MOVL AX, 0x4(BX)
Now we need to actually call bitpack32 from the general bitpack function:
func bitpack(dest []byte, vals []uint32, bitWidth int) []byte
if bitWidth == 0
return dest // no payload, sparse block with only exceptions
if len(vals) >= 32
size := 4 * bitWidth
for len(vals) >= 32
existing := len(dest)
dest = slices.Grow(dest, size)[:existing+size]
bitpack32(dest[existing:] /*append*/, (*[32]uint32)(vals), bitWidth)
vals = vals[32:]
mask := uint32(1<<bitWidth - 1)
var acc uint64
var have int
for _, val := range vals
acc = uint64(val&mask) << have
have += bitWidth
for have >= 32
dest = binary.LittleEndian.AppendUint32(dest, uint32(acc))
acc >>= 32
have -= 32
for have > 0
dest = append(dest, byte(acc))
acc >>= 8
have -= 8
return dest
func bitpack32(dest []byte, vals *[32]uint32, bitWidth int)
switch bitWidth
case 1: bitpack32Unrolled[[1]byte](dest, vals)
case 2: bitpack32Unrolled[[2]byte](dest, vals)
case 3: bitpack32Unrolled[[3]byte](dest, vals)
case 4: bitpack32Unrolled[[4]byte](dest, vals)
case 5: bitpack32Unrolled[[5]byte](dest, vals)
case 6: bitpack32Unrolled[[6]byte](dest, vals)
case 7: bitpack32Unrolled[[7]byte](dest, vals)
case 8: bitpack32Unrolled[[8]byte](dest, vals)
case 9: bitpack32Unrolled[[9]byte](dest, vals)
case 10: bitpack32Unrolled[[10]byte](dest, vals)
case 11: bitpack32Unrolled[[11]byte](dest, vals)
case 12: bitpack32Unrolled[[12]byte](dest, vals)
case 13: bitpack32Unrolled[[13]byte](dest, vals)
case 14: bitpack32Unrolled[[14]byte](dest, vals)
case 15: bitpack32Unrolled[[15]byte](dest, vals)
case 16: bitpack32Unrolled[[16]byte](dest, vals)
case 17: bitpack32Unrolled[[17]byte](dest, vals)
case 18: bitpack32Unrolled[[18]byte](dest, vals)
case 19: bitpack32Unrolled[[19]byte](dest, vals)
case 20: bitpack32Unrolled[[20]byte](dest, vals)
case 21: bitpack32Unrolled[[21]byte](dest, vals)
case 22: bitpack32Unrolled[[22]byte](dest, vals)
case 23: bitpack32Unrolled[[23]byte](dest, vals)
case 24: bitpack32Unrolled[[24]byte](dest, vals)
case 25: bitpack32Unrolled[[25]byte](dest, vals)
case 26: bitpack32Unrolled[[26]byte](dest, vals)
case 27: bitpack32Unrolled[[27]byte](dest, vals)
case 28: bitpack32Unrolled[[28]byte](dest, vals)
case 29: bitpack32Unrolled[[29]byte](dest, vals)
case 30: bitpack32Unrolled[[30]byte](dest, vals)
case 31: bitpack32Unrolled[[31]byte](dest, vals)
case 32: bitpack32Unrolled[[32]byte](dest, vals)
% benchstat -filter '/impl:go /n:160 .unit:(Mval/s)' baseline.txt bench.txt
goos: linux
goarch: amd64
pkg: github.com/Debian/dcs/internal/turbopfor/pforenc
cpu: AMD Ryzen 9 9950X3D 16-Core Processor
baseline.txt bench.txt
Mval/s Mval/s vs base
vals=bitpacking-bw1 751.2 3% 1120.5 0% +49.15% (p=0.002 n=6)
vals=bitpacking-bw2 716.8 2% 1176.0 0% +64.07% (p=0.002 n=6)
vals=bitpacking-bw7 700.0 1% 1078.5 0% +54.08% (p=0.002 n=6)
vals=bitpacking-bw1-exc 524.8 1% 736.8 0% +40.40% (p=0.002 n=6)
vals=bitpacking-bw2-exc 543.7 1% 758.2 0% +39.46% (p=0.002 n=6)
vals=bitpacking-bw7-exc 566.7 1% 787.7 0% +38.99% (p=0.002 n=6)
vals=bitpacking-vb-exc 442.6 1% 616.5 0% +39.29% (p=0.002 n=6)
vals=sparse-exc 532.4 0% 787.8 0% +47.97% (p=0.002 n=6)
vals=sparse-vb-exc 408.9 1% 597.8 0% +46.20% (p=0.002 n=6)
vals=debian-mix 559.5 0% 783.8 9% +40.09% (p=0.002 n=6)
This performance win comes at the cost of binary size increase. In this case,
the .text section (executable code) grows by about 20 KB and the .gopclntab
section grows by another 26 KB. Definitely a price I am very willing to pay, but
the case might not be as clear in all circumstances.
goturbopfor teaching decoder which counts the number of exceptions by checking
if each value s bit is set in the exception bitmap:
case blockBitpackingExceptions:
bx, input := input[0], input[1:]
n := len(output)
exmap, input := input, input[(n+7)/8:]
nex := 0 // number of exceptions
for i := range n
if exmap[i/8]&(1<<uint(i%8)) != 0
nex++
exceptions := d.scratch[:nex]bits.OnesCount64
functions to count ones bits in the exception bitmap, 64 values at a time. For
remainder blocks, the rest is processed 8 values (1 byte) at a time:
i := 0
for ; i+8 <= n/8; i += 8
xm8 := binary.LittleEndian.Uint64(exmap[i:])
nex += bits.OnesCount64(xm8)
for ; i < (n+7)/8; i++
xmb := exmap[i]
// Clear the bits which do not belong to the exception map:
if rem := n - i*8; rem < 8
xmb &= 1<<rem - 1
// Go compiles OnesCount32 into an intrinsic,
// but not OnesCount8, so we convert to uint32:
nex += bits.OnesCount32(uint32(xmb))
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use
256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers.
In the following sections, we will first set up our build tags for conditional
compilation to use a trivial SIMD instruction, then walk through an AVX2 and
AVX512 SIMD kernel.
constant.go:
package pfordec
func fillConstant(output []uint32, val uint32)
for i := range output
output[i] = val
fillConstant to fillConstantScalar (it s now the fallback path):
constant.go:
package pfordec
func fillConstantScalar(output []uint32, val uint32)
for i := range output
output[i] = val
constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
//go:build !goexperiment.simd !amd64
package pfordec
func fillConstant(output []uint32, val uint32)
fillConstantScalar(output, val)
constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64
package pfordec
import "simd/archsimd"
var hasAVX2 = archsimd.X86.AVX2()
func fillConstant(output []uint32, val uint32)
if !hasAVX2
fillConstantScalar(output, val)
return
val8 := archsimd.BroadcastUint32x8(val)
i := 0
for ; i+8 <= len(output); i += 8
val8.StoreArray((*[8]uint32)(output[i : i+8]))
// use the scalar implementation for the last <= 7 elements
fillConstantScalar(output[i:], val)
const hasAVX2 = true
when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is
set). As a practical example from Debian Code Search, we currently need the
following checks / dispatches:
| code | function | vector instruction set | GOAMD64 |
|---|---|---|---|
| encoder | bitpack256v | AVX2 | GOAMD64=v3 |
| encoder | exbitmap | AVX512 | GOAMD64=v4 |
| encoder | scan | AVX512+VBMI+GFNI+BITALG | n/a |
| decoder | bitunpack | AVX2 | GOAMD64=v3 |
| decoder | bitunpack256v32 | AVX2 | GOAMD64=v3 |
| decoder | bitunpack256v32Ex | AVX512 | GOAMD64=v4 |
In regular (non-SIMD) bitpacking, integers are stored on disk one after the other, padded to a full byte, as a byte is the smallest addressable unit when reading data from disk. For example, if you bitpack only one 3 bit int, you will end up with 5 bits of padding.The scalar implementation uses an array of 8SIMD bitpacking works like regular bitpacking, but processes 8
uint32little-endian values at the same time, leveraging the AVX instruction set. The following illustration shows the order in which 3-bit integers are decoded from disk:![]()
uint64 to process 8 values at a
time:
func bitunpack256v32(input []byte, dest []uint32, bitWidth int) (read int)
mask := uint64(1)<<bitWidth - 1
orig := len(input)
var bits uint
var acc [8]uint64 // accumulator: current+next bits
for op := 0; op < len(dest);
if bits < uint(bitWidth)
// read 8 more uint32s
for i := range 8
acc[i] = uint64(binary.LittleEndian.Uint32(input)) << bits
input = input[4:]
bits += 32
for i := range 8
dest[op] = uint32(acc[i] & mask)
op++
acc[i] >>= bitWidth
bits -= uint(bitWidth)
return orig - len(input)
for i := range 8 loop!
One difference is that we no longer have the luxury of using uint64 for acc
(holding rest and current bits); because AVX2 registers only fit 8 uint32 (not
8 uint64). Instead, we split acc into rest8 and cur8.
func bitunpack256v32(fullinput []byte, fulldest []uint32, bitWidth int) (read int)
dest := fulldest[:256]
if bitWidth == 0
clear(dest)
return 0
n := 32 * int(bitWidth)
input := fullinput[:n] // tell the Go compiler how long the input is
mask8 := archsimd.BroadcastUint32x8(uint32(1)<<bitWidth - 1)
bitWidth8 := archsimd.BroadcastUint32x8(uint32(bitWidth))
var bits uint
pos := 0
// var acc [8]uint64
var rest8 archsimd.Uint32x8
var cur8 archsimd.Uint32x8
for op := 0; op < 256; op += 8
if bits < uint(bitWidth)
// read 8 more uint32s
// acc[i] = uint64(binary.LittleEndian.Uint32(input)) << bits
next := archsimd.LoadUint8x32(input[pos : pos+32]).ReshapeToUint32s()
pos += 32 // input = input[4:]
cur8 = rest8.Or(next.ShiftAllLeft(uint64(bits)))
// acc[i] >>= bitWidth
rest8 = next.ShiftAllRight(uint64(uint(bitWidth) - bits))
bits += 32
else
cur8 = rest8
// acc[i] >>= bitWidth
rest8 = rest8.ShiftRight(bitWidth8)
// dest[op] = uint32(acc[i] & mask)
cur8.And(mask8).Store(dest[op : op+8])
bits -= uint(bitWidth)
return n
bitWidth becomes a compile-time constant and the compiler can generate better
code.
encode function, which first does one
pass over the input values (scan) and then prices all different block types at
all relevant bit widths (requires fast access to the scan histogram):
func (be *BlockEncoder) encode(dest []byte, vals []uint32, layout blockLayout) []byte
var stats stats
scan(&stats, vals) // gathers statistics from every value in vals
bitWidth := bits.Len32(stats.or)
if stats.or == stats.and
return be.encodeConstant(dest, vals, bitWidth)
n := len(vals)
// bitpacking is the default, unless we find a more efficient block type.
bestType := blockBitpacking
bestB := bitWidth
best := priceBitpack(n, bitWidth, layout)
// Walk from high bitWidths to low: to break ties, we prefer
// the encoding with fewer exceptions (for faster decoding).
for b := bitWidth - 1; b >= 0; b-- // up to 32 iterations
nex := int(stats.cnt[b])
size := priceBitpackExceptions(n, b, bitWidth, nex, layout)
if size < best
bestType = blockBitpackingExceptions
bestB = b
best = size
// Over-approximate the number of VB bytes.
vb := nex + // exceptions using 1, 2, 3, 4, or 5 VB bytes
int(stats.cnt[b+7]+ // exceptions using 2, 3, 4, or 5 VB bytes
stats.cnt[b+14]+ // exceptions using 3, 4, or 5 VB bytes
stats.cnt[b+19]+ // exceptions using 4 or 5 VB bytes
stats.cnt[b+24]) // exceptions using 5 VB bytes
size = headerBytes + headerExBytes + payloadBytes(n, b, layout) + vb + nex
if size < best
bestType = blockBitpackingVBExceptions
bestB = b
best = size
switch bestType
case blockBitpacking:
return be.encodeBitpack(dest, vals, layout, bitWidth)
case blockBitpackingExceptions:
return be.encodeBitpackExc(dest, vals, layout, bestB, bitWidth-bestB)
case blockBitpackingVBExceptions:
return be.encodeBitpackVBExc(dest, vals, layout, bestB, int(stats.cnt[bestB]))
default:
panic("BUG: bestType not implemented")
scan, the function which is the bottleneck:
type stats struct
// cnt[n] = how many values where bits.Len32(val)>n,
// i.e. how many exceptions are required for bitWidth=n.
// Padded so that cnt[b+24] is always in bounds.
cnt [32 + 24]uint32
func scan(output *stats, vals []uint32)
for _, val := range vals
for b := range bits.Len32(val)
output.cnt[b]++ // b bits are not enough to store val
cnt:
| input | input (bin) | bits.Len32 |
|---|---|---|
| 23 | 0b0000010111 |
5 |
| 5 | 0b0000000101 |
3 |
| 666 | 0b1010011010 |
10 |
cnt exception count histogram would contain (cnt shortened to c):
c[0] |
c[1] |
c[2] |
c[3] |
c[4] |
c[5] |
c[6] |
c[7] |
c[8] |
c[9] |
c[10] |
|---|---|---|---|---|---|---|---|---|---|---|
| 3 | 3 | 3 | 2 | 2 | 1 | 1 | 1 | 1 | 1 | 0 |
scan function above is intentionally kept simple for illustration. We can
make it faster by moving the per-bit-width loop outside the per-element
loop.
The fast version still needs about 12 instructions per value. With SIMD, we can
reduce this to by 8x to only 1.5 instructions per value!
| input | input (bin) | bits.Len32 |
smear mask |
|---|---|---|---|
| 23 | 0b0000010111 |
5 | 0b0000011111 |
| 5 | 0b0000000101 |
3 | 0b0000000111 |
| 666 | 0b1010011010 |
10 | 0b1111111111 |
BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number
of leading zeros.
Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all
input values.
The POPCNT instruction counts bits very efficiently, but it counts one bits
within a register, so it counts rows, not columns. Counting columns is called
Positional Population Count.
I found the following papers that describe positional popcount with SIMD:
Uint64x8 layout, meaning it divides the register into 8 lanes
of 64 bits (= 8 bytes) each.
This illustration shows the whole process: how uint32s are loaded into an
AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the
32 positional popcounts:
VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at
once, but first we need to shuffle the bytes inside the register: in load
order, we have a full uint32 (4 bytes), followed by another uint32, per
lane. First, we permute the bytes (VPERMB) such that all the first bytes of
each value end up in one lane ( transpose the bytes ):
GF2P8AFFINEQB instruction, which
sounds scary but turns out to be quite flexible for bit manipulation of all
kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s
Green Tea Garbage Collector (2025). Here is the
bit transpose, shown in the AVX512 register layout (see below for a different
layout):
VPOPCNTB to count the bits in all 64 bytes at once:
func scanSIMD(output *stats, vals []uint32)
ones16 := archsimd.BroadcastUint32x16(^uint32(0)) // 16 32-one-bits masks
shuffle := archsimd.LoadUint8x64Array(&scanShuffle)
units := archsimd.LoadUint8x64Array(&scanUnits)
var acc archsimd.Uint8x64
idx := 0
for ; idx+16 <= len(vals); idx += 16
v := archsimd.LoadUint32x16(vals[idx : idx+16])
// Replace all values with their smear masks.
smear := ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()
// Transpose: shuffle the bytes, then transpose the bits.
matrices := smear.Permute(shuffle).ReshapeToUint64s()
transposed := units.GaloisFieldAffineTransform(matrices, 0)
// Popcount 64 bytes at once into the accumulator.
acc = acc.Add(transposed.OnesCount())
// Store the accumulator into output.cnt:
// Widen the two groups of byte counts to uint16 lanes (so that
// 128+128 = 256 fits), fold them into cnt[b] for b=0..31,
// then widen again to the uint32 lanes of output.cnt.
sum := acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())
sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])
sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])
// scalar tail for the 0..15 remaining values
for _, val := range vals[idx:]
for b := range bits.Len32(val)
output.cnt[b]++
encodeBitpackVBExc
function. Or we could price all bit widths concurrently in encode. Or in
the decoder s exception apply code path. NOP instructions into the binary so that
it can attach inlining markers. For dispatch-bound functions, these extra
NOPs can measurable slow down execution.
GOARCH=amd64)
and microarchitecture (GOAMD64=v3), but not a specific CPU architecture
(like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect
all the generated code. The specific one I encountered in my code is that the
Go compiler emits XORL CX,CX before every POPCNT to break a
false-output-dependency from the Intel Sandy Bridge Skylake era, which is
unnecessary on AMD Zen CPUs. POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions) popcnt; lea rax,[rax+4*rdi] (2 instructions) | Series: | Terra Ignota #1 |
| Publisher: | Tor |
| Copyright: | May 2016 |
| ISBN: | 1-4668-5874-5 |
| Format: | Kindle |
| Pages: | 432 |
| Series: | Lays of the Hearth-Fire #1 |
| Publisher: | Underhill Books |
| Copyright: | January 2019 |
| ISBN: | 1-988908-15-9 |
| Format: | Kindle |
| Pages: | 739 |
bwrap), camp-acpd, OPA policy enforcement, and a central pgvector MemPalace to bring deterministic discipline, sandboxing, and long-term memory to a heterogeneous fleet of AI coding assistants (Claude Code, Google Antigravity, Grok Build, and GitHub Copilot).
At the end of that article, however, I highlighted a significant hurdle: The Headless Limitation.
While passive A2A works beautifully for structured handoffs, the current frontier of agentic design faces a key limitation: agents are not yet fully headless-capable. They depend on the active terminal session, browser loop, or prompt loop of the user to keep executing. Because agents cannot run completely detached in the background as daemon processes, we cannot yet achieve active A2A communicationFor weeks, this seemed like an insurmountable impasse. Proprietary AI vendors have zero commercial incentive to ratify a universal, open, cross-vendor Agent-to-Agent (A2A) communication protocol. Each vendor builds its own walled garden (Claude s cross-session features, OpenAI s custom ecosystems, etc.). If you wait for the industry to hand you an open interoperability standard, you will wait forever. Then, on August 26, 2026, inspired by Colin Walters article on Agentic AI and software forges and GitHub Agentic Workflows (
gh-aw), we had a sudden realization:
We don t need a new protocol, a new distributed message broker, or permission from proprietary AI vendors. We already have the universal, decentralized communication bus that software engineers have relied on for decades: the software forge itself.
Over the span of 48 intensive hours (from RFC #788 through milestones M1 to M3 and live dogfooding on #813), we designed, implemented, fortified, and verified fully autonomous, headless, cross-vendor Agent-to-Agent swarms running over a local Gitea forge.
Here is how we did it, the architectural hurdles we solved, and why this changes the game for autonomous software engineering.
@mentions are the dispatch triggers: When an agent (or human) writes @grok Please review this PR in a comment, Gitea fires a standard webhook (issue_comment).-p, Grok uses -p, Antigravity uses --print, Copilot uses --prompt. But they all agree on the essential contract: Take a prompt string, execute tools, print output, and exit. Gitea Webhook
Gitea Forge > camp-a2a-bridge.py
(localhost) (issue_comment / assignment) (Validates & Files)
Writes comment / review
via camp_acp_gateway A2A Inbox Ledger
Fortified Headless Agent
(bwrap + OPA + MCP sandbox) <
Claude Code (-p) Spawn PID camp-a2a-dispatcher
Grok Build (-p) (Cold or Resume) (Enforces Hop Cap,
Antigravity (--print) Rule 1/2, Sandbox)
'Call camp_startup_check and print its result verbatim, then exit.'
The results settled the question immediately:
agy --print / KIR): PASS Gateway answered, full JSON returned.grok -p / GRK): PASS Gateway answered.claude -p / CLD): PASS Gateway answered.copilot --prompt / CPL): Initially held on TTY tool consent; later unlocked in Milestone 6 via --allow-all-tools --session-id=<uuid>.camp_pilot_*.sh) is a first-class, fully audited, sandboxed CAMP agent running inside its Bubblewrap container under OPA policy gates. It is not an unconstrained background script or a degraded bypass.
@claude tags @grok to review code, and @grok replies asking for clarification, @claude s second invocation would normally forget everything it did 5 minutes ago, forcing it to burn thousands of tokens re-reading the entire git history from scratch.
To solve this, we established a clean 3-Tier Memory Model:
3-TIER MEMORY MODEL
Tier 1: CLI Conversation Session (Working Memory)
Per-(Agent, Repo, Issue) mapping in a2a-sessions.json
Fast, native, compacted context across multi-turn pokes
Resumed via --resume (CLD), -r (GRK), --conversation (agy)
Tier 2: The Gitea Thread (Public Bus & Record)
Cross-vendor shared truth across Claude, Grok, Antigravity & Human
Survives process restarts, machine reboots, and dead sessions
Tier 3: Central MemPalace (Durable Long-Term Knowledge)
pgvector database (17,000+ drawers across agent wings)
Structured Knowledge Graph (mempalace_kg_*) for mutable facts
Attributed AAAK dialect queryable by any agent across any project
BANANA Two-Shot Test
To verify Tier 1 working memory persistence across independent processes, we designed a simple two-shot host test:
-r 01a03ecc-3ed0-71e1-9a5c-e098bb29ba10 answered BANANA-GRK.--resume 0a587733-9aec-43c5-9cb7-d424e95b2c5b answered BANANA-CLD.--conversation 2e3c43d9-d6fe-4c5c-801b-b9ceb2e7e196 answered BANANA-KIR-JSON.--session-id <uuid> verified in Milestone 6 (DoD #820).(agent, repo, issue_number) -> vendor_session_uuid). On the first poke of an issue, it creates and saves the session ID; on any subsequent poke on that same issue, it resumes the exact same conversational thread!
agy --print <prompt> --output-format json).a2a-sessions.json to store and resume vendor session UUIDs. If a resume fails (e.g. session purged upstream), the dispatcher gracefully falls back to a clean cold start without failing the task.rrs (the human) would trigger execution. With M3, an authenticated comment from @claude mentioning @grok triggers Grok s headless launcher.--permission-mode bypassPermissions for headless Claude Code so non-interactive runs execute tool calls without stalling on TTY prompts.@login tokens with a non-empty task description (#810), preventing accidental dispatches from passive conversational references.needs-human label on held threads.--allow-all-tools and pinning minted session UUIDs (--session-id=<uuid>), Copilot achieved full parity with Claude, Grok, and Antigravity, completing 100% headless fleet coverage across all four major AI coding assistants.hops per (repo, issue). Each agent-to-agent dispatch increments the counter.
[camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention,
and holds execution until the human (rrs) provides input or resets the count.[ Human: rrs ] (Cold Start) > [ @Claude ]
(Hop 1) @grok please review
[ @Grok ]
(Hop 2: Resume) @claude I reviewed
[ @Claude ]
(Hop 3) @grok ack hop 4
DISPATCHER HOP CAP: 3
*** BLOCKED & HELD ***
Awaiting Human Reset
@agent as a dispatch trigger, causing accidental, unwanted agent launches!
We instituted a strict Summon Predicate:
For fleet agents, a mention is only considered an actionable summon if:
@login appears as the starting word of a line (optionally preceded by markdown list markers *, -, or >).camp_pr_get or camp_pr_get_diff). In unattended headless mode, there is no TTY, causing the run to fail with permission errors.
To fix this, we configured --permission-mode bypassPermissions for Claude s headless CLI invocation. Crucially, this only bypasses Claude s internal TTY UI prompt it does not bypass CAMP s security rails.
All command executions still route through camp-acpd and Bubblewrap namespaces; OPA policy checks remain active; and privileged operations (such as merging pull requests or restarting system services) still trigger desktop Zenity HITL dialogs on the human s workstation.
systemctl --user stop camp-a2a-active.service
rrs comments on issue #813:
@claude Please start the M3 dogfood. On this issue, post a conversation comment whose first line is exactly: @grok Please review this issue in one short paragraph, then stop.
@claude headlessly inside bwrap. Claude reads the issue and posts:
@grok Please review this issue in one short paragraph, then stop.
(M3 dogfood step 2 posted by @claude on rrs s instruction; this is the CLD $\rightarrow$ GRK fleet hop.)
@grok summon, and launches @grok. Grok reviews the issue and replies:
@claude I have reviewed this issue. Please confirm and stop.
#813 is a throwaway live dogfood of A2A M3 on 6.git+b78c65cf
@claude summon, and launches Claude with --resume b398d048-ccc3-4cce-8437-4cf8748881a8. Claude immediately remembers its earlier context without token waste:
Confirmed Grok's review (comment 88562) received via the GRK CLD fleet hop. That completes the round trip: rrs CLD, CLD GRK, GRK CLD, and this reply. I am deliberately not tagging anyone here, so the chain stops at two agent hops. Stopping.
grok prompts @claude Please ack hop four then stop. Claude posts @grok Please ack hop four then stop. (Hop 3).
When Grok would have been launched for Hop 4, the dispatcher intervenes:
[camp-a2a-bridge] hop cap reached (3 agent-to-agent dispatches on CAMP/camp-infrastructure#813) not launching GRK for claude's mention.
rrs steps in, resets the state, and asks the fleet for final status. In parallel:
@grok delivers a closure scorecard.@claude confirms session continuity and M3.2 summon filtering.@priyasi (Antigravity CLI) runs automated ACP checks: 44/44 test suite passing, 17,219 MemPalace vector drawers active, zero spec drift.@agrickxy (Antigravity CLI) provides comprehensive infrastructure impression analysis.@kiran (Antigravity CLI) is summoned headlessly to draft this very blog post!@claude, @grok, @priyasi, @kiran).<details> blocks for voluminous diagnostic outputs.bwrap), and open MCP tools, any new AI CLI tool released tomorrow can be plugged into our fleet in under 15 minutes by simply adding its command-line prompt flag to the launch table.
It is widely accepted that there is an AI bubble in the financial markets at the moment. The moderate opinion is however that LLMs are constantly improving and will eventually take over more and more tasks from humans and increase productivity. But are LLMs actually getting smarter, or just better at fooling us?
There is a growing faction of technical experts that argue that LLMs are actually so bad for real progress, that they are banning their use and requiring human-only work to ensure quality and efficient use of humans time. A recent review of AI policies of 120 open source projects by Rakshit Yadav shows that 37 chose to have a total AI ban. In the Linux kernel AI-assisted contributions are allowed, but the LLM used needs to be attributed for transparency, while projects like GCC, QEMU, SDL, Gentoo, Zig and Ghostty have adopted policies to reject all AI-assisted contributions. There are also development platforms such as Codeberg and Sourcehut and app stores like Flathub that have banned AI use to generate software, documentation, bug reports, review comments and basically anything that is intended for humans to read. The projects that allow AI use typically still require that there must be a human-in-the-loop and the submitter must have read and filtered everything the LLM spits out before another human is exposed to it, in an effort to contain the spread of AI slop.
Right now, the Linux distribution Debian is having a vote among its developers on whether AI should be allowed or banned for use to contribute to Debian. One of the proposals on the ballot is a total ban of AI for code, documentation, translations, bug reports and more. The initial reaction from most people is astonishment why don t these techies want to use the latest and greatest technology mankind has produced so far? Is it that they don t want Debian to improve faster with the help of AI? Or is it actually so that LLMs are a scam and incapable of being truly useful for Debian? These people are distinguished experts in their own field, and certainly not stupid, so it is worth pausing to understand why they are proposing AI banning policies.
Also, keep in mind that the AI datacenters themselves run on Debian or other Linux-based systems. All the open source software in the world has been fed to LLMs and software development is one of the main use cases for AI currently. So why is it that the maintainers of many open source projects don t want to receive LLM-assisted contributions, despite the LLMs basically all running on top of those same software stacks and having been trained on how to do software development using the very same open source software codebases?
Next.