It is widely accepted that there is an AI bubble in the financial markets at the moment. The moderate opinion is however that LLMs are constantly improving and will eventually take over more and more tasks from humans and increase productivity. But are LLMs actually getting smarter, or just better at fooling us?
There is a growing faction of technical experts that argue that LLMs are actually so bad for real progress, that they are banning their use and requiring human-only work to ensure quality and efficient use of humans time. A recent review of AI policies of 120 open source projects by Rakshit Yadav shows that 37 chose to have a total AI ban. In the Linux kernel AI-assisted contributions are allowed, but the LLM used needs to be attributed for transparency, while projects like GCC, QEMU, SDL, Gentoo, Zig and Ghostty have adopted policies to reject all AI-assisted contributions. There are also development platforms such as Codeberg and Sourcehut and app stores like Flathub that have banned AI use to generate software, documentation, bug reports, review comments and basically anything that is intended for humans to read. The projects that allow AI use typically still require that there must be a human-in-the-loop and the submitter must have read and filtered everything the LLM spits out before another human is exposed to it, in an effort to contain the spread of AI slop.
Right now, the Linux distribution Debian is having a vote among its developers on whether AI should be allowed or banned for use to contribute to Debian. One of the proposals on the ballot is a total ban of AI for code, documentation, translations, bug reports and more. The initial reaction from most people is astonishment why don t these techies want to use the latest and greatest technology mankind has produced so far? Is it that they don t want Debian to improve faster with the help of AI? Or is it actually so that LLMs are a scam and incapable of being truly useful for Debian? These people are distinguished experts in their own field, and certainly not stupid, so it is worth pausing to understand why they are proposing AI banning policies.
Also, keep in mind that the AI datacenters themselves run on Debian or other Linux-based systems. All the open source software in the world has been fed to LLMs and software development is one of the main use cases for AI currently. So why is it that the maintainers of many open source projects don t want to receive LLM-assisted contributions, despite the LLMs basically all running on top of those same software stacks and having been trained on how to do software development using the very same open source software codebases?
Why LLMs are so deceptive
The output of an LLM often looks very compelling, professional and correct. Humans have evolved to trust or distrust new information based on easy to detect secondary factors like what authority the speaker holds, or how confidently and eloquently the message is conveyed. Humans are however very bad at fact-checking and cross-referencing new information, as it requires a lot of effort, and humans like saving energy and being as lazy as possible.
Information asymmetry
The less you know about something, the easier it is to fool you on that topic. Nobel prizes in economics have been given in for research on how information asymmetry distorts markets and leads to suboptimal outcomes. In the field of software engineering we have now witnessed a flood of aspiring software developers using AI to create software that looks like it might work, but that is actually full of flaws. These people are well-intended, but they simply lack the expertise to understand what they are actually doing, and don t possess the necessary judgement to decide when an LLM spits out something truly useful and when it is creating mostly garbage. This asymmetry in expertise I think explains the majority of the conflict currently witnessed in open source projects the senior developers are flooded with requests to review code that is bad and a waste of time for everyone involved, while availability of AI grows the pool of people who could contribute and create more code slop at an ever-increasing speed.
The information asymmetry could to some degree be evened out if seniors teach juniors to do software engineering well, but it is of course not feasible to quickly mass educate everyone. Also, it seems that many don t want to learn but instead expect to have all understanding outsourced to LLMs. Many seniors have noticed this and have stopped teaching juniors as the seniors don t like the feeling of having their time wasted by teaching people who don t want to learn. Juniors probably all understand that it would be better to learn to design and write software yourself, but using LLMs just feels too easy. I can fully relate to why people choose to take the path of least resistance. Unfortunately, that path often leads to a dead end.
Humans fall too easily for anthropomorphism
The human brain is wired to think that inanimate objects are alive and have feelings. Small children talk to their stuffed animals as if they were real, and lots of adults experience feelings of things happening in their surroundings due to some acts of gods or elves being angry or whatever. When we see a machine writing just like a human, or even more convincingly hear it talk and respond to our talk like a living thing, our brain automatically starts assuming it is a living thing with intelligence and feelings.
The fact that these creatures live in the abstract cloud and only appear through a portal we hold in our palm and behave in a way that was designed for maximum engagement makes the illusion even stronger. I recommend people try out running LLMs locally on their laptop to see the raw thing spitting out tokens and have some of the illusion shattered.
Also stop saying please to an LLM. It does not have any feelings.
Understanding temperature
In my experience understanding the concept of temperature in LLMs helps see why an LLM might confidently generate a plausible-looking but totally wrong code change. The large language models are statistical machines that, based on the input (previous tokens) to the neural network, try to predict what to output (next token). When running an LLM, if the temperature is configured to be zero, the output is very predictable and always follows the paths of the strongest connections (a.k.a. weights) between nodes and layers of the neural network. Unlike in living creatures where the brain learns and changes all the time, the weights of an LLM can only change during training. When an LLM is in normal use (during inference, generating next tokens) the weights are fixed, and if temperature is zero, the answer to a specific question will always be exactly the same. This is of course a bit boring and too machine-like, so typically LLMs have a bit of temperature set, which introduces random variation in what connections the neural network traverses.
Again, I recommend people try running small LLMs locally where temperature and other settings are fully exposed and configurable to see this themselves. It is a good antidote to falling for the illusion that LLMs would actually be intelligent.
Why benchmarks don t tell the whole story
If LLMs continue to produce so much garbage, why are benchmarks showing that they are constantly improving? AI models are indeed improving all the time. For example the CAIS AI dashboard visualizes how frontier models have evolved in the past few years. However, the best models still have a pass rate of only about 50% on the Humanity s Last Exam. On SWE-bench the best model today resolves just under 77%. That means there is a significant number of times when the AI is wrong. This matches my personal experiences, and the renowned Greg Kroah-Hartman recently wrote on the Linux developers mailing list that even with the best of the current and next generation tools, at least 1/3 of the results they generate are flat out wrong or harmful .
When generating cat videos the error rate does not matter, but in engineering, things absolutely must be correct. Sure, humans also make mistakes, but well educated and properly incentivized humans are so much more capable than LLMs in many regards. We can achieve complex things that work reliably, such as operating worldwide commercial air traffic without planes falling down every day.
There are currently a lot of humans who are incentivized to maintain the narrative that general artificial intelligence is coming soon and will take over everything. In fact, the whole financial system is currently skewed towards such a vision because the promise of falling labour costs and increased profits and monopolistic control of everything attracts capital like nothing before.
In this environment we need to remember that machines and economic systems are ultimately servants of humans, and not the other way around.
It s just a tool
LLMs are not a scam, but a useful tool and technology that has its uses. But the idea that AI has or will surpass humans any time soon in either capabilities or efficiency is simply not true, and we should listen to the people who created humanity s so far most complex systems (computers and software), who are saying that LLMs are in many cases so bad, that it might be better to ban them in certain places completely for the time being than to waste far more valuable human time on reading the text and code they generate.
The time asymmetry is not a new phenomenon as there has been various script kiddies for a long time. As an example, a person running a memory leak scanner without understanding the results and spending 10 minutes to file a bug report could force an open soruce maintainer to spend an hour on proving and explaining that the finding is false. What is new is how much the AI users blindly trust the outputs they get, and open source is uniquely vulnerable as there are no managers protecting developers use of time.
What I do, recommend, and expect to see in the next stages
I am using AI tools daily, and constantly experimenting with new models and new ways to use them. Sometimes they work, and often they don t. Sometimes looping AI on itself can make it fix its own errors, but sometimes it just gets derailed and will never arrive at the correct solution. When an LLM fails to make a calendar entry for the right time based on reading my email it is easy for me to spot that it is wrong. I try to avoid using LLMs for anything where I can t exercise judgement myself on whether the result was correct or not.
I also really hope that other people would not send me anything where their own effort was less than the effort I have to make reading and understanding it. This principle is not new many have heard the requirement that reading code must require less effort than what it took to write it.
I have always kept a high bar on software code and asked fellow developers to make sure their code is well structured, easy to follow and documented. LLMs unfortunately make it easier for people to cheat in this regard, but if cheating is easier, maybe the punishment and deterrence needs to be higher now too. Now with many open source projects adopting policies that put guardrails on AI use, I expect we will soon start witnessing cases where the policies are enforced and it will be interesting to see how violations are judged.
As a society we might also need to develop new social standards and rules in what is acceptable treatment of other humans in human-to-machine interactions, and perhaps also new standards in showing what humans are responsible for what machine as the machines start acting more and more independently. I encourage people to take part in these discussions, and in case of doubt, err on the side that favors real human interactions. Contrary to what many business people seem to think, and even though I am in general a techno-optimist myself, I don t feel there is any need to rush with AI adoption.
This event is happening soon see below for registration instructions!
We are extremely pleased to announce the upcoming Reproducible Builds summit, which will take place from September 22nd 24th 2026 in the city of Gothenburg, Sweden.
This year, we are thrilled to host the tenth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Vienna (2025), Hamburg (2023 2024), Venice (2022), Marrakesh (2019), Paris (2018), Berlin (2017), Berlin (2016) and Athens (2015).
If you re excited about joining us this year, please make sure to read the event page which has more details about the event and location. As in previous years, we will be sending invitations to all those who attended our previous summit events or expressed interest to do so. However, even if you do not receive a personal invitation, please do email the organizers and we will find a way to accommodate you.
About the event
The Reproducible Builds Summit is a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.
Schedule
Although the exact content of the meeting will be shaped by the participants, the main goals will include:
Update & exchange about the status of reproducible builds in various projects.
Improve collaboration both between and inside projects.
Expand the scope and reach of reproducible builds to more projects.
Work together and hack on solutions.
Establish space for more strategic and long-term thinking than is possible in virtual channels.
Brainstorm designs on tools enabling users to get the most benefits from reproducible builds.
Discuss how reproducible builds will be usable and meaningful to users and developers alike.
Logs and minutes will be published after the meeting.
Registration instructions
Please reach out if you d like to participate in hopefully interesting, inspiring and intense technical sessions about reproducible builds and beyond!
We look forward to what we anticipate to be yet another extraordinary event!
Welcome to the July 2026 report from the Reproducible Builds project!
In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not.
If you are interested in contributing to the project, please visit the Contribute page on our website.
In this month s report, we cover:
Tool development
diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 324, 325 and 326 to Debian:
Fix tests to work with zipdetails 4.0008. (#1141359)
Bump debhelper compatibility level to 13. []
Update copyright years. []
In addition, Paul Spooren made changes to allow trailing garbage in Gzip files [] and Vagrant Cascadian added an external tool reference for the pedump binary to use the mono package under GNU Guix. []
disorderfs is our FUSE-based filesystem that deliberately introduces non-determinism into system calls to reliably flush out reproducibility issues. This month, Christelle Gloor added the option to sort by ctime as returned by the lstat(2)syscall. [], which Chris Lamb uploaded whilst bumping the Standards-Version to version 4.7.4 []. Bernhard Wiedemann also updated disorderfs to version 0.7.0 in openSUSE.
Yet again, there were a number of improvements made to our website this month as well. For example, Chris Lamb, by request of Digital Ocean, changed the target of a referral link so that they can manage incoming referrers [] and pushed a number of changes to the Tools page [].
Distribution work
In Debian this month, 32 reviews of Debian packages were added, 26 were updated and a total of 21 were removed this month, adding to our extensive knowledge about identified issues.
A number of issue types were added by Chris Lamb, including:
We present VCAligner, a content-based alignment methodology that constructs inverted indexes over VCS histories to precisely map released artifacts to their originating commits, independent of fragile version tags. We evaluated VCAligner on a dataset of 2,984 verifiable PyPI packages derived from the 4,000 most-downloaded projects linked to public GitHub upstreams. Our results reveal a critical weakness in conventional tag-based heuristics: while they appear effective on 85% of the dataset, the residual 15% failure rate generates a catastrophic downstream audit workload of over 10.3 million commits. In contrast, VCAligner reduces this burden by two orders of magnitude ( 158 ), bounding the total workload to under 65,000 commits. Furthermore, we provide the large-scale characterization of Packaging Noise, classifying artifact divergence into structural additions (Path Phantoms) and content mutations (Blob Phantoms), thereby isolating the distinct attack surfaces of malicious injection and code tampering.
Python has become the default language for interacting with AI, with packages being distributed through registries like the Python Package Index (PyPI). This creates a need to analyse supply chains comprising such packages. One such analysis is to rebuild packages in order to identify compromised builds injecting malware. Independent rebuilds in hardened environments have the added advantage that they can generate and record provenance in order to increase the trustworthiness of packages. Two tools that are designed to automate such rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent. Although only 15.4% of macaron rebuilds and 19.1% of oss-rebuild rebuilds are byte-for-byte identical to the published PyPI wheels, daleq4py establishes wheel equivalence for 60.2% and 78.9% of source-equivalent rebuilds, respectively.
The security of open source applications benefits considerably from the possibility of rebuilding their source and verifying the output. F-Droid, a prominent distribution for open source Android applications, systematically rebuilds them from source and tests their bitwise reproducibility at app publishing time. However, F-Droid offers no guarantee that app reproducibility will continue to hold in the future. As software ecosystems evolve, reproducibility may degrade, with potential negative consequences for software preservation and security. We present the first empirical study of build reproducibility in the F-Droid app ecosystem. Analyzing historical reproducibility logs, we find that the overall bitwise reproducibility rate has been steadily increasing over time (as new versions of apps are published). We then evaluate how reproducibility holds in time for fixed app versions, by attempting to rebuild 18 904 app versions that F-Droid had previously confirmed bitwise reproducible, published between September 2018 and February 2026, achieving an 83% rebuild success rate, and identify missing dependencies as the dominant cause of failure, accounting for 76% of non-rebuildable cases. Among successfully rebuilt apps, 94% are also bitwise reproducible-i.e., they still yield bitwise identical artifacts upon rebuild. Together, these results show that while bitwise reproducibility largely holds for apps that can be rebuilt, rebuildability itself is highly sensitive to temporal decay.
Patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
Reproducible builds remove trust in the builder: anyone re-derives the same artifact from the same source, byte for byte. The same shape applies one layer over, to a retained record. Most record-keeping regimes (the EU AI Act s Article 12 logging is the current example) require that events be recorded and logs retained, but not that a retained log be verifiable, by a party who was not present, as unaltered and existing when claimed. That leaves an integrity obligation resting on trusting the party being audited.
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
After seeing a video a few months ago demonstrating how a
proprietary CAM solution uses machine learning and large language
models to automatically generate CNC instructions, and successfully
testing it on a real CNC, I began wondering if the same could be
achieved with free software. I still do not know the answer, but I may
be getting closer to finding out. Two weeks ago, I came across the
video "I Connected
Claude AI to FreeCAD (And It Models Parts Like an Engineer)" by
Make Form, which introduced me to the
FreeCAD MCP
project. Even though the video creator apparently believes it is
acceptable to download and run random binaries from the Internet on a
local machine (his setup uses UCX), I do not. I would probably have
left the project alone entirely if I had not noticed that all of its
dependencies are already available in Debian. This significantly
boosted my motivation, so I set out to test it using packages built
from source on Debian rather than relying on untrusted binaries.
The first hurdle was that
the MCP SDK for
Python was not present on my Debian Forky test machine. I
initially believed it was missing from Debian altogether, but it has
been available in Debian Unstable for about a month and is only absent
from Forky because some automated tests fail on architectures like
riscv64 and s390. Fortunately, backporting it was straightforward
using apt-get source -b python3-mcp . The next hurdle involved an
outdated version of the
Validators Python
library. Since I am a member of Debian's Python team, which
maintains this package, updating it to a sufficient version for
FreeCAD MCP was relatively easy. I could not upgrade to the latest
upstream release due to a new dependency on an Ethereum-related
library, so I settled on a 2024 version.
With those dependencies in place, I proceeded to create a Debian
package for FreeCAD MCP. I had previously submitted a
request for packaging of
FreeCAD MCP to gauge interest while deciding whether to prioritize
maintaining it myself. Because salsa.debian.org blocks access from
Tor users like myself, I published my draft packaging scripts in a Git
repository on Codeberg as the
Debian FreeCAD
MCP project and got it working with the FreeCAD 1.1 version in
Forky. I initially struggled with the button controls for the MCP
feature, which led me to submit a pull request titled
"Fixed
startup sync of checkable toolbar buttons" proposing a fix. Once
this confusion was resolved and the MCP setup was enabled via the GUI,
I was able to run FreeCAD completely headless using xvfb-run on a
machine without an X server to generate models. I am using a private
LLM service running the
Debian package of llama.cpp with the Qwen 3.6 model downloaded
from Hugging Face, configured with a maximum context window of 105k
tokens. I also tested the Bonsai model on my test laptop; initially,
its context window was too small (8k and 16k could not accommodate the
FreeCAD MCP instructions), but even after increasing it to 32k, it
proved useless for generating FreeCAD models so far. I've used Claw
Code, Aider and Open Code with my server so far, and for this test I
ended up with OpenCode because it was easy to set up to use an
MCP. Because none of my LLM services are set up to be multimodal
(capable of processing both text and images in this case), I
configured the MCP to return only textual feedback from FreeCAD. I am
unsure if this is a major limitation, though I suspect it might
be.
My testing experience remains limited, with no clear successes
yet. Part of the issue likely stems from my ability to provide
effective instructions for modeling 3D objects (I am relatively new to
FreeCAD, English is not my first language, and I lack a precise
vocabulary for describing construction features to an
LLM). Nevertheless, the LLM has demonstrated the capacity to create 3D
models in FreeCAD. In one of my first tests, I asked it to generate a
cube and then produce CAM/G-code instructions for a CNC machine. It
did output G-code (which remains untested), but I was surprised to
find that it bypassed FreeCAD's built-in CAM module entirely and
instead generated an external Python script to produce the code. This
was not quite what I intended, though my instructions were probably
unclear. The Qwen model with OpenCode seems to strongly prefer
programming directly; it frequently executes Python snippets inside
FreeCAD to achieve its goals rather than using the standard
sketch-and-extrude workflow I am accustomed to. In another test, I
asked the LLM to create a parameterized pipe assembly to see which of
FreeCAD's parametric tools it would choose, but found no evidence of
traditional parametric features in the output. When prompted, the LLM
explained that the parameters were embedded directly in the Python
script used to generate the model, rather than in native FreeCAD
features. With more explicit instructions, it eventually created a
FreeCAD spreadsheet to manage the parameters. The resulting model
looked much closer to my expectations and could have been useful with
further refinement. My so far last experiment was less successful: I
asked it to design a pipe clamp, but the LLM repeatedly failed to
position the clamping screws in a way that would actually secure the
brackets around the pipe. It is unclear whether this limitation lies
with the model, my prompt, or other factors.
Based on my testing so far, I am uncertain whether FreeCAD MCP is
merely a fun toy or a genuinely useful tool. I will only commit time
to maintaining it in Debian if it proves to be practically valuable. I
would welcome feedback from anyone who has experience with the
project, preferably via the original request-for-packaging mailing
list thread. Alternatively, I am available in the FreeCAD and Debian
AI IRC channels for further discussion.
As usual, if you use Bitcoin and wish to support my activities,
please send donations to
15oWEoG9dUPovwmUL9KWAnYRtNJEkP1u1b.
Radiant Star is a science fiction novel set in the Imperial Radch
universe without being a direct sequel to the other books in that
universe. It will badly spoil the end of Ancillary Mercy, and I recommend reading that trilogy first, but
it's independent of the other books in the same universe.
In the 3,008th year after the manifestation of the Radiant Star (the
1,024th since the founding of the Consorority itself), Zaved, a newly
minted consoror, disappeared a mere two days after the ceremony that
elevated her to womanhood. She left a note that read, Bored.
Back whenever. This was not normal or even remotely acceptable
behavior in a consoror, particularly one who held as much promise as
Zaved had, but what could the consorors do?
Zaved, faced with the unpleasant prospect of running out of money during
her galactic tour, plied a rich benefactor with tales of how talented,
polite, and obedient the boys of the Consorority are. Her plan worked
brilliantly. After funding further non-boring adventures, she arrived home
in Ooioiaa with a chest full of money and a pregnancy. Great for Zaved and
the Consorority; kind of a shame for her son Jonr, who is to be delivered
to her benefactor after proper training. Oh well, telling Jonr about that
is a problem for future Zaved.
After a strained childhood in which he convinces himself he is a misfit
with few redeeming qualities, Jonr ends up in a suspension pod. Before
shipping can be arranged, however, external events intervene, leaving Jonr
sitting unnoticed in a warehouse.
The planet of Aaa is in a highly inconvenient location, drifting as it
does through interstellar space unattached to any star. It would be as
irrelevant and overlooked as any other random interstellar object except
for two critical properties. The first is that Aaa and its sole city of
Ooioiaa are sacred to a religion of obscure origin. Its primary population
are members of a religious cult who believe the Radiant Star manifested in
the Temporal Location on Ooioiaa and will eventually return to bring light
to the galaxy. The second interesting property of Aaa is that it is
drifting ever so slowly towards a strategic system of military importance.
The first property brings pilgrims and their accompanying bounty of money,
food, and other resources necessary to dig a small city out of rock, make
it habitable, and supplement the sparse and strange native edible life.
The second property brings the Radchaai, who easily conquer the city of
Ooioiaa and are now faced with the unpleasant task of running it.
Some decades after the Radchaai conquest, having never left Aaa, Jonr is
woken up. He will not be sent off into the broader galaxy as a slave to
pay off a vacation debt. Instead, he will be one of the many protagonists
in this novel about the perils of living through supply chain disruptions
on a planet full of status-obsessed religious fanatics who would drown in
a rain shower.
The other books set in this universe make abundantly clear that the Radch
is a voracious colonial power that enslaves native populations and
enforces their own cultural preferences at the point of a gun. A reader
familiar with this series is predisposed to take whatever side is not the
Radch.
Radiant Star adds a complication, however. Charak Svo, the Radchaai
governor, is impatient with native inhabitants and strongly dislikes their
religion, but she is reasonably competent. The religious factions that ran
Ooioiaa before the arrival of the Radchaai, on the other hand, are
dogmatic authoritarians with the collective wisdom of a sack of turnips.
Charak does not get everything right and is arguably responsible for at
least one catastrophe. By the end of the book, though, I was firmly
convinced that had the original religious government still been in charge,
everyone would have died.
I found the structure of this book a little odd. The omniscient narrator
tells the story in the form of a history. The target audience appears to
be future inhabitants of Ooioiaa and adherents to the Radiant Star
religion, and the narrator is often maddeningly uninterested in topics
that a reader of the rest of the Imperial Radch books is intensely curious
about. This same property carries through to the plot: I was interested in
how all of the tensions in this obviously absurd society could be resolved
or, preferably, overturned entirely. The narrator, on the other hand, is
far more interested in Serque Tais's intent to become the last saint in
the Temporal Location, and in the details of the subsequent political,
economic, and religious fallout.
Leckie has written three novels set in the Imperial Radch after the
original trilogy: Provenance,
Translation State, and now Radiant
Star. I am sure that I'm not the only person who wants a direct
continuation of the original trilogy, but I'm drawing the conclusion that
Leckie doesn't want to write that. Instead, she's writing around the edges
of the subsequent events, in effect showing readers the shape of them and
their broader implications without showing the details.
Now that I can see what she's doing, I kind of like it. Given what we now
know from the books written around the edges, the ensuing events in the
center of galactic politics are chaotic in a way that could easily devolve
into tedious accounts of messy conflicts. Seeing the effects from afar
lets the reader fill in some of the blanks and speculate, and it makes the
moments where we get a concrete update (such as at the end of this book)
all the more rewarding. I still find it odd, though, to read a book where
the narrator's interests so sharply diverge from mine.
I wish I could say that Radiant Star sucked me in as the story
developed, but it never did. Part of the problem is that I think this book
is intended as a very dry farce, and farce often doesn't work with my
reading style. I prefer to attach myself to a protagonist and hope they do
competent things, and this book is full of characters who are being
themselves far too aggressively and loudly to have time to be competent at
anything. My favorite moments were therefore the small pockets of people
with sense: The governor, Jonr, his charge, and the delightfully strange
Justice of Albis. I enjoyed all of them, but I had trouble caring
about the overall plot and kept putting this book down for days between
chapters.
I think this is mostly personal taste, though. Like all of Leckie's novels
since the original Imperial Radch trilogy, Radiant Star is
competently executed and a little strange. When that strangeness aligns
with your tastes, it's a great deal of fun and rather unlike other science
fiction novels. In this case, it didn't quite work for me, but I suspect
it will for others.
I still want another Leckie novel with a ship as a protagonist, though.
Content notes: Rather disturbing (although bloodless) religious practices,
mass death.
Rating: 6 out of 10
Royals are my favourite ships in No Man's Sky. The HMS Blueberry is not my
first Exotic/Royal ship (that was the Gravity Hirakao XVI, and a story for
another time).
After years of on-off playing, I recently found my first Royal
multitool: Blue, with gold detailing. I have a Royal-style jetpack (I don't
remember where I got that). I thought I'd try and colour-match my multitool,
ship, jetpack and outfit. Since I only had one multitool, I matched the others to it.
And the HMS Blueberry (credit for the name goes to Beatrice) was the Exotic
in my collection which matched.
The HMS Blueberry is in viewable in my showroom, Honest Jon's Lightly-Used
Starships.
Paladin's Faith is the fourth book in T. Kingfisher's loosely
connected series of fantasy novels about the berserker former paladins of
the Saint of Steel. You could read this as a standalone, but there are
numerous (spoilery) references to the previous books in the series.
Marguerite, who was central to the plot of the first book in the series,
Paladin's Grace, is a spy with a
problem. An internal power struggle in the Red Sail, the organization that
she's been working for, has left her a target. She has a plan for how to
break their power sufficiently that they will hopefully leave her alone,
but to pull it off she's going to need help. As the story opens, she is
working to acquire that help in a very Marguerite sort of way: breaking
into the office of Bishop Beartongue of the Temple of the White Rat.
The Red Sail, the powerful merchant organization Marguerite worked for,
makes their money in the salt trade. Marguerite has learned that someone
invented a cheap and reproducible way to extract salt from sea water, thus
making the salt trade irrelevant. The Red Sail wants to ensure that
invention never sees the light of day, and has forced the artificer into
hiding. Marguerite doesn't know where they are, but she knows where she
can find out: the Court of Smoke, where the artificer has a patron.
Having grown up in Anuket City, Marguerite was familiar with many
clockwork creations, not to mention all the ways that they could go
horribly wrong. (Ninety-nine times out of a hundred, it was an
explosion. The hundredth time, it ran amok and stabbed innocent
bystanders, and the artificer would be left standing there saying,
"But I had to put blades on it, or how would it rake the leaves?"
while the gutters filled up with blood.)
All Marguerite needs to put her plan into motion is some bodyguards so
that she's not constantly distracted and anxious about being assassinated.
Readers of this series will be unsurprised to learn that the bodyguards
she asks Beartongue for are paladins, including a large broody male one
with serious self-esteem problems.
This is, like the other books in this series, a slow-burn romance with
infuriating communication problems and a male protagonist who would do
well to seek out a sack of hammers as a mentor. However, it has two things
going for it that most books in this series do not: a long and complex
plot to which the romance takes a back seat, and Marguerite, who is not
particularly interested in playing along with the expected romance
developments. There are also two main paladins in this story, not just
one, and the other is one of the two female paladins of the Saint of Steel
and rather more entertaining than Shane.
I generally like court intrigue stories, which is what fills most of this
book. Marguerite is an experienced operative, so the reader gets some
solid competence porn, and the paladins are fish out of water but are also
unexpectedly dangerous, which adds both comedy and satisfying
table-turning. I thoroughly enjoyed the maneuvering and the culture
clashes. Marguerite is very good at what she does, knows it, and is
entirely uninterested in other people's opinions about that, which
short-circuits a lot of Shane's most annoying behavior and keeps the story
from devolving into mopey angst like some of the books in this series have
done.
The end of this book takes the plot in a different direction that adds
significantly to the world-building, but also has a (thankfully short)
depths of despair segment that I endured rather than enjoyed. I am not
really in the mood for bleak hopelessness in my fiction at the moment,
even if the reader is fairly sure it will be temporary. But apart from
that, I thoroughly enjoyed this book from beginning to end. When we
finally meet the artificer, they are an absolute delight in that way that
Kingfisher is so good at. The whole story is infused with the sense of
determined and competent people refusing to stop trying to fix problems.
As usual, the romance was not for me and I think the book would have been
better without it, but it's less central to the plot and therefore annoyed
me less than any of the books in this series so far.
My one major complaint is the lack of gnoles, but we get some new and
intriguing world-building to make up for it, along with a setup for a
fifth book that I am now extremely curious about.
By this point in the series, you probably know if you like the general
formula. Compared to the previous book, Paladin's Hope, I thought Paladin's Faith was much
stronger and more interesting, but it's clearly of the same type. If, like
me, you like the plots but not the romance, the plot here is more
substantial. You will have to decide if that makes up for a romance in the
typical T. Kingfisher configuration.
Personally, I enjoyed this quite a bit, except for the short bleak part,
and I'm back to eagerly awaiting the next book in the series.
Rating: 8 out of 10
In my last post, Badri and I reached Kuala Lumpur - the capital of Malaysia - on the 7th of December 2024. We stayed in Bukit Bintang, the entertainment district of the city. Our accommodation was pre-booked at Manor by Mingle , a hostel where I had stayed for a couple of nights in a dormitory room earlier in February 2024.
We paid 4937 rupees (the payment was online, so we paid in Indian rupees) for 3 nights for a private room. From the Terminal Bersepadu Selatan (TBS) bus station, we took the metro to the Plaza Rakyat LRT station, which was around 500 meters from the hostel. Upon arriving at the hostel, we presented our passports at their request, followed by a 20 ringgit (400 rupee) deposit which would be refunded once we returned the room keys at checkout.
Manor by Mingle - the hostel where we stayed at during our KL transit. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
Our room was upstairs and it had a bunk bed. I had seen bunk beds in dormitories before, but this was my first time seeing a bunk bed in a private room. The room did not have any toilets, so we had to use shared toilets.
Unusually, the hostel was equipped with a pool. It also had a washing machine with dryers - this was one of the reasons we chose this hostel, because we were traveling light and hadn t packed too many clothes. The machine and dryer cost 10 ringgits (200 rupees) per use, and we only used it once. The hostel provided complimentary breakfast, which included coffee. Outside of breakfast hours, there was also a paid coffee machine.
During our stay, we visited a gurdwara - a place of worship for Sikhs - which was within walking distance from our hostel. The name of the gurdwara was Gurdwara Sahib Mainduab. However, it wasn t as lively as I had thought. The gurdwara was locked from the inside, and we had to knock on the gate and call for someone to open it. A man opened the gate and invited us in.
The gurdwara was small, and there was only one other visitor - a man worshipping upstairs. We went upstairs briefly, then settled down on the first floor.
We had some conversations with the person downstairs who kindly made chai for us. They mentioned that the langar (community meal) is organized on every Friday, which was unlike the gurdwaras I have been to where the langar is served every day. We were there for an hour before we left.
We also went to Adyar Ananda Bhavan (a restaurant chain) near our hostel to try the chain in Malaysia. The chain is famous in Southern India and also known by its short name A2B. We ordered
an onion dosa for 10 ringgits (200 rupees),
1 masala tea for 6 ringgits (120 rupees),
2 pooris for 8 ringgits (160 rupees) and
1 plate potato bajji for 7 ringgits (140 rupees).
Dosa served at Adyar Ananda Bhavan. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
All this came down to around 33 ringgits (including taxes), i.e. around 660 rupees. We also purchased some snacks such as murukku from there for our trip.
We had planned a day trip to Malacca, but had to cancel it due to rain. We didn t do a lot in Kuala Lumpur, and it ended up acting as a transit point for us to other destinations: flights from Kuala Lumpur were cheaper than Singapore, and in one case a flight via Kuala Lumpur was even cheaper than a direct flight!
We paid 15,000 rupees in total for the following three flights:
Kuala Lumpur to Brunei,
Brunei to Kuala Lumpur, and
Kuala Lumpur to Ho Chi Minh City (Vietnam).
These were all AirAsia flights. The cheap tickets, however, did not include any checked-in luggage, and the cabin luggage weight limit was 7 kg. We also bought quite some stuff in Kuala Lumpur and Singapore, leading to an increase in the weight of our luggage.
We estimated that it would be cheaper for us to take only essential items such as clothes, cameras, and laptops, and to leave behind souvenirs and other non-essentials in lockers at the TBS bus stand in Kuala Lumpur, than to pay more for check-in luggage. It would take 140 ringgits for us to add a checked-in bag from Kuala Lumpur to Bandar Seri Begawan and back, while the cost for lockers was 55 ringgits at the rate of 5 ringgits every six hours.
We had seen these lockers when we alighted at the bus stand while coming from Johor Bahru. There might have been lockers in the airport itself as well, which would have been more convenient as we were planning to fly back in soon, but we weren t sure about finding lockers at the airport and we didn t want to waste time looking.
We had an early morning flight for Brunei on the 10th of December. We checked out from our hostel on the night of the 9th of December, and left for TBS to take a bus to the airport. We took a metro from the nearest metro station to TBS. Upon reaching there, we put our luggage in the lockers. The lockers were automated and there was no staff there to guide us.
Lockers at TBS bus station. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
We bought a ticket for the airport bus from a counter at TBS for 26 ringgits for both of us. In order to give us tickets, the person at the counter asked for our passports, and we handed it over to them promptly. Since paying in cash did not provide any extra anonymity, I would advise others to book these buses online.
In Malaysia, you also need a boarding pass for buses. The bus terminal had kiosks for getting these printed, but they were broken and we had to go to a counter to obtain them. The boarding pass mentioned our gate number and other details such as our names and departure time of the bus. The company was Jet Bus.
My boarding pass for the bus to the airport in Kuala Lumpur. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
To go to our boarding gate, we had to scan our boarding pass to let the AFC gates open. Then we went downstairs, leading into the waiting area. It had departure boards listing the bus timings and their respective gates. We boarded our bus around 10 minutes before the departure time - 00:00 hours. It departed at its scheduled time and took 45 minutes to reach KL Airport Terminal 2, where we alighted.
We reached 6 hours before our flight s departure time of 06:30. We stopped at a convenience store at the airport to have some snacks. Then we weighed our bags at a weighing machine to check whether we were within the weight limit. It turned out that we were.
We went to an AirAsia counter to get our boarding passes. The lady at our counter checked our Brunei visas carefully and looked for any Brunei stamps on the passports to verify whether we had used that visa in the past. However, she didn t weigh our bags to check whether they were within the limit, and gave us our boarding passes.
We had more than 4 hours to go before our flight. This was the downside of booking an early morning flight - we weren t able to get a full night s sleep.
A couple of hours before our flight time, we were hanging around our boarding gate. The place was crowded, so there were no seats available. There were no charging points. There was a Burger King outlet there which had some seating space and charging points. As we were hungry, we ordered two cups of cappuccino coffee (15.9 ringgits) and one large french fries (8.9 ringgits) from Burger King. The total amount was 24 ringgits.
When it was time to board the flight, we went to the waiting area for our boarding gates. Soon, we boarded the plane. It took 2.5 hours to reach the Brunei International Airport in the capital city of Bandar Seri Begawan.
View of Kuala Lumpur from the aeroplane. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
Stay tuned for our experiences in Brunei!
Credits: Thanks to Badri, Benson and Contrapunctus for reviewing the draft.
DebConf25 was held at IMT Atlantique Brest Campus in France from 14th to 19th July 2025. As usual, it was preceded by DebCamp from 7th to 13th July.
I was less motivated to write this time. So this year, more pictures, less text. Hopefully, (eventually) I may come back to fill this up.
Conference
IMT Atlantique
Main conference area
RAK restaurant, the good food place near the venue
Bits from DPL (can't really miss the tradition of a Bits picture)
During the conference, Subin had this crazy idea of shooting Parody of a popular clip from the American-Malayalee television series Akkarakazhchakal advertising Debian. He explained the whole story in the BTS video. The results turned out great, TBF:
I managed to complete The Little Prince (Le Petit Prince) during my travel from Paris to Brest
Paris
Basilica of the Sacred Heart of Montmartre
View of Paris from the Basilica of the Sacred Heart of Montmartre
Paris streets
Cats rule the world, even on Paris streetlights
Eiffel Tower. It's massive.
View from Eiffel Tower Credits - Nilesh Patra, licensed under CC BY SA 4.0.
As for the next DebConf work, it has already started. It seems like it never ends. We close one and in one or two months start working on the next one. DebConf is going to Argentina this time and we have a nice little logo too now.
DebConf26 logo Credits - Romina Molina, licensed under CC BY SA 4.0.
Overall, DebConf25 Brest was a nice conference. Many thanks to local team, PEB and everyone involved for everything. Let s see about next year. Bye!
Welcome to the October 2025 report from the Reproducible Builds project!
Welcome to the very latest report from the Reproducible Builds project. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
In this report:
Farewell from the Reproducible Builds Summit 2025
Thank you to everyone who joined us at the Reproducible Builds Summit in Vienna, Austria!
We were thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. During this event, participants had the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim was to create an inclusive space that fosters collaboration, innovation and problem-solving.
The agenda of the three main days is available online however, some working sessions may still lack notes at time of publication.
One tangible outcome of the summit is that Johannes Starosta finished their rebuilderd tutorial, which is now available online and Johannes is actively seeking feedback.
Google s Play Store breaks reproducible builds for Signal
On the issue tracker for the popular Signal messenger app, developer Greyson Parrelli reports that updates to the Google Play store have, in effect, broken reproducible builds:
The most recent issues have to do with changes to the APKs that are made by the Play Store. Specifically, they add some attributes to some .xml files around languages are resources, which is not unexpected because of how the whole bundle system works. This is trickier to resolve, because unlike current expected differences (like signing information), we can t just exclude a whole file from the comparison. We have to take a more nuanced look at the diff. I ve been hesitant to do that because it ll complicate our currently-very-readable comparison script, but I don t think there s any other reasonable option here.
kpcyrd forwarded a fascinating tidbit regarding so-called ninja and samurai build ordering, that uses data structures in which the pointer values returned from malloc are used to determine some order of execution.
Arnout Engelen, Justin Cappos, Ludovic Court s and kpcyrd continued a conversation started in September regarding the Minimum Elements for a Software Bill of Materials . (Full thread)
Felix Moessbauer of Siemens posted to the list reporting that he had recently stumbled upon a couple of Debian source packages on the snapshot mirrors that are listed multiple times (same name and version), but each time with a different checksum . The thread, which Felix titled, Debian: what precisely identifies a source package is about precisely that what can be axiomatically relied upon by consumers of the Debian archives, as well as indicating an issue where we can t exactly say which packages were used during build time (even when having the .buildinfo files).
Luca DiMaio posted to the list announcing the release of xfsprogs 6.17.0 which specifically includes a commit that implements the functionality to populate a newly created XFS filesystem directly from an existing directory structure which makes it easier to create populated filesystems
without having to mount them [and thus is] particularly useful for reproducible builds . Luca asked the list how they might contribute to the docs of the System images page.
Reproducible Builds at the Transparency.dev summit
Holger Levsen gave a talk at this year s Transparency.dev summit in Gothenburg, Sweden, outlining the achievements of the Reproducible Builds project in the last 12 years, covering both upstream developments as well as some distribution-specific details. As mentioned on the talk s page, Holger s presentation concluded with an outlook into the future and an invitation to collaborate to bring transparency logs into Reproducible Builds projects .
The slides of the talk are available, although a video has yet to be released. Nevertheless, as a result of the discussions at Transparency.dev there is a new page on the Debian wiki with the aim of describing a potential transparency log setup for Debian.
Supply Chain Security for Go
Andrew Ayer has setup a new service at sourcespotter.com that aims to monitor the supply chain security for Go releases. It consists of four separate trackers:
A tool to verify that the Go Module Mirror and Checksum Database is behaving honestly and has not presented inconsistent information to clients.
A module monitor that records every module version served by the Go Module Mirror and Checksum Database, allowing you to monitor for unexpected versions of your modules.
A tool to verifies that the Go toolchains published in the Go Module Mirror can be reproduced from source code, making it difficult to hide backdoors in the binaries downloaded by the go command.
A telemetry config tracker that tracks the names of telemetry counters uploaded by the Go toolchain, to ensure that Go telemetry is not violating users privacy.
As the homepage of the service mentions, the trackers are free software and do not rely on Google infrastructure.
In March 2024, a sophisticated backdoor was discovered in xz, a core compression library in Linux distributions, covertly inserted over three years by a malicious maintainer, Jia Tan. The attack, which enabled remote code execution via ssh, was only uncovered by chance when Andres Freund investigated a minor performance issue. This incident highlights the vulnerability of the open-source supply chain and the effort attackers are willing to invest in gaining trust and access. In this article, I analyze the backdoor s mechanics and explore how bitwise build reproducibility could have helped detect it.
Although quantum computing is a rapidly evolving field of research, it can already benefit from adopting reproducible builds. This paper aims to bridge the gap between the quantum computing and reproducible builds communities. We propose a generalization of the definition of reproducible builds in the quantum setting, motivated by two threat models: one targeting the confidentiality of end users data during circuit preparation and submission to a quantum computer, and another compromising the integrity of quantum computation results. This work presents three examples that show how classical information can be hidden in transpiled quantum circuits, and two cases illustrating how even minimal modifications to these circuits can lead to incorrect quantum computation results.
The thesis focuses on providing a reproducible build process for two open-source E2EE messaging applications: Signal and Wire. The motivation to ensure reproducibility and thereby the integrity of E2EE messaging applications stems from their central role as essential tools for modern digital privacy. These applications provide confidentiality for private and sensitive communications, and their compromise could undermine encryption mechanisms, potentially leaking sensitive data to third parties.
Currently, there are numerous solutions and techniques available in the market to tackle supply chain security, and all claim to be the best solution. This thesis delves deeper by implementing those solutions and evaluates them for better understanding. Some of the tools that this thesis implemented are Syft, Trivy, Grype, FOSSA, dependency-check, and Gemnasium. Software dependencies are generated in a Software Bill of Materials (SBOM) format by using these open-source tools, and the corresponding results have been analyzed. Among these tools, Syft and Trivy outperform others as they provide relevant and accurate information on software dependencies.
In the wake of growing supply chain attacks, the FreeBSD developers are relying on a transparent build concept in the form of Zero-Trust Builds. The approach builds on the established Reproducible Builds, where binary files can be rebuilt bit-for-bit from the published source code. While reproducible builds primarily ensure verifiability, the zero-trust model goes a step further and removes trust from the build process itself. No single server, maintainer, or compiler can be considered more than potentially trustworthy.
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Bernhard Wiedemann and Zbigniew J drzejewski-Szmek extended ismypackagereproducibleyet.org with initial support for Fedora [].
In addition, a number of contributors added a series of notes from our recent summit to the website, including Alexander Couzens [], Robin Candau [][][][][][][][][] and kpcyrd [].
Tool development
diffoscope version 307 was uploaded to Debian unstable by Chris Lamb, who made a number of changes including fixing compatibility with LLVM version 21 [], an attempt to automatically attempt to deploy to PyPI by liaising with the PyPI developers/maintainers (with this experimental feature). [] In addition, Vagrant Cascadian updated diffoscope in GNU Guix to version 307.
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
At the beginning of the month I uploaded a new version of the sway
package to Debian. This contains two
backported patches, one to fix reported WM capabilities and one to revert the
default behavior for
drag_lock
to disabled.
I also uploaded new releases of cage (a
kiosk for Wayland), labwc, the
window-stacking Wayland compositor that is inspired by Openbox, and
wf-recorder, a tool for creating
screen recordings of wlroots-based Wayland compositors.
If I don t forget I try to update the watch file of the packages I touch to the
new version 5
format.
Simon Ser announcedvali, a C library for
Varlink. The blog post also mentions that this will be
a dependency of the next version of the kanshi Wayland output management
daemon and the PR to do so is now already merged. So I created ITP: vali A
Varlink C implementation and code
generator, packaged
the library and it is now waiting in NEW. In addition to libscfg this is now
the second dependency of kanshi that is in NEW.
On the Rust side of things I fixed a
bug in
carl. The fix introduces new date
properties which can be use to highlight a calendar date. I also updated
all the dependencies and plan to create a new release soon.
Later I dug up a Rust project that I started a couple of years ago, where I try
to use wasm-bindgen to
implement interactive web components. There is a lot I have to refactor in this
code base, but I will work on that and try to publish something in the next few
months.
Miscellaneous
Two weeks ago I wrote A plea for <dialog>,
which made the case for using standardized HTML elements instead of resorting
to JavaScript libraries.
I finally managed to update my shell Server to Debian 13.
I created an issue for the nextcloud-news android
client because I moved
to a new phone and my starred articles did not show up in the news app, which
is a bit annoying.
I got my ticket for 39C3.
In my dayjob I continued to work on the refactoring of the import logic of our
apis-core-rdf app. I released version 0.56 which also introduced the
#snackbar as the container for the toast message, as described in the
<dialog> block post. At the end of the month I released version 0.57
of apis-core-rdf, which got rid of the remaining leftovers of the old
import logic.
A couple of interesting articles I stumbled upon (or finally had the time to read):
Welcome to the September 2025 report from the Reproducible Builds project!
Welcome to the very latest report from the Reproducible Builds project. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. As ever, if you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
In this report:
Reproducible Builds Summit 2025
Please join us at the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria!
We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort.
During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.
If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!
Once the proper measurement points are known, we want to constrain the system such that what it does is simple enough to understand and easy to repeat. It is quite telling that the push for software that enables reproducible builds only really took off after an embarrassing widespread security issue ended up affecting the entire Internet. That there had already been 50 years of software development before anyone thought that introducing a few constraints might be a good idea is, well, let s just say it generates many emotions, none of them happy, fuzzy ones. []
Tool development
diffoscope version 306 was uploaded to Debian unstable by Chris Lamb. It included contributions already covered in previous months as well as some changes by Zbigniew J drzejewski-Szmek to address issues with the fdtump support [] and to move away from the deprecated codes.open method. [][]
strip-nondeterminism version 1.15.0-1 was uploaded to Debian unstable by Chris Lamb. It included a contribution by Matwey Kornilov to add support for inline archive files for Erlang s escript [].
kpcyrd has released a new version of rebuilderd. As a quick recap, rebuilderd is an automatic build scheduler that tracks binary packages available in a Linux distribution and attempts to compile the official binary packages from their (purported) source code and dependencies. The code for in-toto attestations has been reworked, and the instances now feature a new endpoint that can be queried to fetch the list of public-keys an instance currently identifies itself by. []
Lastly, Holger Levsen bumped the Standards-Version field of disorderfs, with no changes needed. [][]
Reproducibility testing framework
The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In August, however, a number of changes were made by Holger Levsen, including:
Setting up six new rebuilderd workers with 16 cores and 16 GB RAM each.
Move Debian live builds and some other Debian builds to the ionos10 node. []
Cleanup some legacy support from releases before Debian trixie. []
In addition, Jochen Sprickerhof made the following changes relating to reproduce.debian.net:
Do not expose pending jobs on the main site. []
Switch the frontpage to reference Debian forky [], but do not attempt to build Debian forky on the armel architecture [].
Use consistent and up to date rebuilder-debian.sh script. []
Fix supported worker architectures. []
Add a basic excuses page. []
Move to the pull184 branch. [][][][]
Fix a typo in the JavaScript. []
Update front page for the new v1 API. [][]
Lastly, Roland Clobus did some maintenance relating to the reproducibility testing of the Debian Live images. [][][][]
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
My trip to pgday.at started Wednesday at the airport in D sseldorf. I was there on time, and the plane started with an estimated flight time of about 90 minutes. About half an hour into the flight, the captain announced that we would be landing in 30 minutes - in D sseldorf, because of some unspecified technical problems. Three hours after the original departure time, the plane made another attempt, and we made it to Vienna.
On the plane I had already met Dirk Krautschick who had the great honor of bringing Slonik (in the form of a big extra bag) to the conference, and we took a taxi to the hotel. On the taxi, the next surprise happened: Hans-J rgen Sch nig unfortunately couldn't make it to the conference, and his talks had to be replaced. I had submitted a talk to the conference, but it was not accepted, and neither queued on the reserve list. But two speakers on the reserve list had cancelled, and another was already giving a talk in parallel to the slot that had to be filled, so Pavlo messaged me if I could hold the talk - well of course I could. Before, I didn't have any specific plans for the evening yet, but suddenly I was a speaker, so I joined the folks going to the speakers dinner at the Wiener Grill Haus two corners from the hotel. It was a very nice evening, chatting with a lot of folks from the PostgreSQL community that I had not seen for a while.
Thursday was the conference day. The hotel was a short walk from the venue, the Apothekertrakt in Vienna's Schloss Sch nbrunn. The courtyard was already filled with visitors registering for the conference. Since I originally didn't have a talk scheduled, I had signed up to volunteer for a shift as room host. We got our badge and swag bag, and I changed into the "crew" T-shirt.
The opening and sponsor keynotes took place in the main room, the Orangerie. We were over 100 people in the room, but apparently still not enough to really fill it, so the acoustics with some echo made it a bit difficult to understand everything. I hope that part can be improved for next time (which is planned to happen!).
I was host for the Maximilian room, where the sponsor sessions were scheduled in the morning. The first talk was by our Peter Hofer, also replacing the absent Hans. He had only joined the company at the beginning of the same week, and was already tasked to give Hans' talk on PostgreSQL as Open Source. Of course he did well.
Next was Tanmay Sinha from Readyset. They are building a system that caches expensive SQL queries and selectively invalidates the cache whenever any data used by these queries changes. Whenever actually fixing the application isn't feasible, that system looks like an interesting alternative to manually maintaining materialized views, or perhaps using pg_ivm.
After lunch, I went to Federico Campoli's Mastering Index Performance, but really spent the time polishing the slides for my talk. I had given the original version at pgconf.de in Berlin in May, and the slides were still in German, so I had to do some translating. Luckily, most slides are just git commit messages, so the effort was manageable.
The next slot was mine, talking about Modern VACUUM. I started with a recap of MVCC, vacuum and freezing in PostgreSQL, and then showed how over the past years, the system was updated to be more focused (the PostgreSQL 8.4 visibility map tells vacuum which pages to visit), faster (12 made autovacuum run 10 times faster by default), less scary (14 has an emergency mode where freezing switches to maximum speed if it runs out of time; 16 makes freezing create much less WAL) and more performant (17 makes vacuum use much less memory). In summary, there is still room for the DBA to tune some knobs (for example, the default autovacuum_max_workers=3 isn't much), but the vacuum default settings are pretty much okay these days for average workloads. Specific workloads still have a whopping 31 postgresql.conf settings at their disposal just for vacuum.
Right after my talk, there was another vacuum talk: When Autovacuum Met FinOps by Mayuresh Bagayatkar. He added practical advice on tuning the performance in cloud environments. Luckily, our contents did not overlap.
After the coffee break, I was again room host, now for Floor Drees and Contributing to Postgres beyond code. She presented the various ways in which PostgreSQL is more than just the code in the Git repository: translators, web site, system administration, conference organizers, speakers, bloggers, advocates. As a member of the PostgreSQL Contributors Committee, I could only approve and we should closer cooperate in the future to make people's contributions to PostgreSQL more visible and give them the recognition they deserve.
That was already the end of the main talks and everyone rushed to the Orangerie for the lightning talks. My highlight was the Sheldrick Wildlife Trust. Tickets for the conference had included the option to donate for the elephants in Kenya, and the talk presented the trust's work in the elephant orphanage there.
After the conference had officially closed, there was a bonus track: the Celebrity DB Deathmatch, aptly presented by Boriss Mejias. PostgreSQL, MongoDB, CloudDB and Oracle were competing for the grace of a developer. MongoDB couldn't stand the JSON workload, CloudDB was dismissed for handing out new invoices all the time, and Oracle had even brought a lawyer to the stage, but then lost control over a literally 10 meter long contract with too much fine print. In the end, PostgreSQL (played by Floor) won the love of the developer (played by our Svitlana Lytvynenko).
The day closed with a gathering at the Brandauer Schlossbr u - just at the other end of the castle ground, but still a 15min walk away. We enjoyed good beer and Kaiserschmarrn. I went back to the hotel a bit before midnight, but some extended that time quite some bit more.
On Friday, my flight back was only in the afternoon, so I spent some time in morning in the Technikmuseum just next to the hotel, enjoying some old steam engines and a live demonstration of Tesla coils. This time, the flight actually went to the destination, and I was back in D sseldorf in the late afternoon.
In summary, pgday.at was a very nice event in a classy location. Thanks to the organizers for putting in all the work - and next year, Hans will hopefully be present in person!
The post A Trip To Vienna With Surprises appeared first on CYBERTEC PostgreSQL Services & Support.
Welcome to the August 2025 report from the Reproducible Builds project!
Welcome to the latest report from the Reproducible Builds project for August 2025. These monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
In this report:
Reproducible Builds Summit 2025
Please join us at the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria!**
We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort.
During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.
If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!
Reproducible Builds and live-bootstrap at WHY2025
WHY2025 (What Hackers Yearn) is a nonprofit outdoors hacker camp that takes place in Geestmerambacht in the Netherlands (approximately 40km north of Amsterdam). The event is organised for and by volunteers from the worldwide hacker community, and knowledge sharing, technological advancement, experimentation, connecting with your hacker peers, forging friendships and hacking are at the core of this event .
At this year s event, Frans Faase gave a talk on live-bootstrap, an attempt to provide a reproducible, automatic, complete end-to-end bootstrap from a minimal number of binary seeds to a supported fully functioning operating system .
Frans talk is available to watch on video and his slides are available as well.
DALEQ Explainable Equivalence for Java Bytecode
Jens Dietrich of the Victoria University of Wellington, New Zealand and Behnaz Hassanshahi of Oracle Labs, Australia published an article this month entitled DALEQ Explainable Equivalence for Java Bytecode which explores the options and difficulties when Java binaries are not identical despite being from the same sources, and what avenues are available for proving equivalence despite the lack of bitwise correlation:
[Java] binaries are often not bitwise identical; however, in most cases, the differences can be attributed to variations in the build environment, and the binaries can still be considered equivalent. Establishing such equivalence, however, is a labor-intensive and error-prone process.
Jens and Behnaz therefore propose a tool called DALEQ, which:
disassembles Java byte code into a relational database, and can normalise this database by applying Datalog rules. Those databases can then be used to infer equivalence between two classes. Notably, equivalence statements are accompanied with Datalog proofs recording the normalisation process. We demonstrate the impact of DALEQ in an industrial context through a large-scale evaluation involving 2,714 pairs of jars, comprising 265,690 class pairs. In this evaluation, DALEQ is compared to two existing bytecode transformation tools. Our findings reveal a significant reduction in the manual effort required to assess non-bitwise equivalent artifacts, which would otherwise demand intensive human inspection. Furthermore, the results show that DALEQ outperforms existing tools by identifying more artifacts rebuilt from the same code as equivalent, even when no behavioral differences are present.
Reproducibility regression identifies issue with AppArmor security policies
Tails developer intrigeri has tracked and followed a reproducibility regression in the generation of AppArmor policy caches, and has identified an issue with the 4.1.0 version of AppArmor.
Although initially tracked on the Tails issue tracker, intrigeri filed an issue on the upstream bug tracker. AppArmor developer John Johansen replied, confirming that they can reproduce the issue and went to work on a draft patch. Through this, John revealed that it was caused by an actual underlying security bug in AppArmor that is to say, it resulted in permissions not (always) matching what the policy intends and, crucially, not merely a cache reproducibility issue.
Work on the fix is ongoing at time of writing.
Rust toolchain fixes
Rust Clippy is a linting tool for the Rust programming language. It provides a collection of lints (rules) designed to identify common mistakes, stylistic issues, potential performance problems and unidiomatic code patterns in Rust projects. This month, however, Sosth ne Gu don filed a new issue in the GitHub requesting a new check that would lint against non deterministic operations in proc-macros, such as iterating over a HashMap .
Dropping support for the armhf architecture. From July 2015, Vagrant Cascadian has been hosting a zoo of approximately 35 armhf systems which were used for building Debian packages for that architecture.
Holger Levsen also uploaded strip-nondeterminism, our program that improves reproducibility by stripping out non-deterministic information such as timestamps or other elements introduced during packaging. This new version, 1.14.2-1, adds some metadata to aid the deputy tool. ( #1111947)
Lastly, Bernhard M. Wiedemann posted another openSUSEmonthly update for their work there.
diffoscopediffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions, 303, 304 and 305 to Debian:
Improvements:
Use sed(1) backreferences when generating debian/tests/control to avoid duplicating ourselves. []
Move from a mono-utils dependency to versioned mono-devel mono-utils dependency, taking care to maintain the [!riscv64] architecture restriction. []
Use sed over awk to avoid mangling dependency lines containing = (equals) symbols such as version restrictions. []
Bug fixes:
Fix a test after the upload of systemd-ukify version 258~rc3. []
Ensure that Java class files are named .class on the filesystem before passing them to javap(1). []
Do not run jsondiff on files over 100KiB as the algorithm runs in O(n^2) time. []
Don t check for PyPDF version 3 specifically; check for >= 3. []
Misc:
Update copyright years. [][]
In addition, Martin Joerg fixed an issue with the HTML presenter to avoid crash when page limit is None [] and Zbigniew J drzejewski-Szmek fixed compatibility with RPM 6 []. Lastly, John Sirois fixed a missing requests dependency in the trydiffoscope tool. []
Website updates
Once again, there were a number of improvements made to our website this month including:
Chris Lamb:
Write and publish a news entry for the upcoming summit. []
Add some assets used at FOSSY, such as the badges and the paper handouts. []
Reproducibility testing framework
The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In August, however, a number of changes were made by Holger Levsen, including:
Ignore that the megacli RAID controller requires packages from Debian bookworm. []
In addition,
James Addison migrated away from deprecated toplevel deb822 Python module in favour of debian.deb822 in the bin/reproducible_scheduler.py script [] and removed a note on reproduce.debian.net note after the release of Debian trixie [].
Jochen Sprickerhof made a huge number of improvements to the reproduce.debian.net statistics calculation [][][][][][] as well as to the reproduce.debian.net service more generally [][][][][][][][].
Mattia Rizzolo performed a lot of work migrating scripts to SQLAlchemy version 2.0 [][][][][][] in addition to making some changes to the way openSUSE reproducibility tests are handled internally. []
Lastly, Roland Clobus updated the Debian Live packages after the release of Debian trixie. [][]
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
We are extremely pleased to announce the upcoming Reproducible Builds summit, which will take place from October 28th 30th 2025 in the historic city of Vienna, Austria.
This year, we are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Hamburg (2023 2024), Venice (2022), Marrakesh (2019), Paris (2018), Berlin (2017), Berlin (2016) and Athens (2015).
If you re excited about joining us this year, please make sure to read the event page which has more details about the event and location. As in previous years, we will be sending invitations to all those who attended our previous summit events or expressed interest to do so. However, even if you do not receive a personal invitation, please do email the organizers and we will find a way to accommodate you.
About the event
The Reproducible Builds Summit is a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort. During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.
With your help, we will bring this (and several other areas) into life:
The main seminar room.
Schedule
Although the exact content of the meeting will be shaped by the participants, the main goals will include:
Update & exchange about the status of reproducible builds in various projects.
Improve collaboration both between and inside projects.
Expand the scope and reach of reproducible builds to more projects.
Work together and hack on solutions.
Establish space for more strategic and long-term thinking than is possible in virtual channels.
Brainstorm designs on tools enabling users to get the most benefits from reproducible builds.
Discuss how reproducible builds will be usable and meaningful to users and developers alike.
Logs and minutes will be published after the meeting.
Registration instructions
Please reach out if you d like to participate in hopefully interesting, inspiring and intense technical sessions about reproducible builds and beyond!
We look forward to what we anticipate to be yet another extraordinary event!
Welcome to the seventh report from the Reproducible Builds project in 2025. Our monthly reports outline what we ve been up to over the past month, and highlight items of news from elsewhere in the increasingly-important area of software supply-chain security. If you are interested in contributing to the Reproducible Builds project, please see the Contribute page on our website.
In this report:
Reproducible Builds Summit 2025
We are extremely pleased to announce the upcoming Reproducible Builds Summit, set to take place from October 28th 30th 2025 in Vienna, Austria!
We are thrilled to host the eighth edition of this exciting event, following the success of previous summits in various iconic locations around the world, including Venice, Marrakesh, Paris, Berlin, Hamburg and Athens. Our summits are a unique gathering that brings together attendees from diverse projects, united by a shared vision of advancing the Reproducible Builds effort.
During this enriching event, participants will have the opportunity to engage in discussions, establish connections and exchange ideas to drive progress in this vital field. Our aim is to create an inclusive space that fosters collaboration, innovation and problem-solving.
If you re interesting in joining us this year, please make sure to read the event page which has more details about the event and location. Registration is open until 20th September 2025, and we are very much looking forward to seeing many readers of these reports there!
[Everything] changed earlier this year when reproducible-builds for SLES-16 became an official goal for the product. More people are talking about digital sovereignty and supply-chain security now. [ ] Today, only 9 of 3319 (source) packages have significant problems left (plus 7 with pending fixes), so 99.5% of packages have reproducible builds.
There are numerous policy compliance and regulatory processes being developed that target software development but do they solve actual problems? Does it improve the quality of software? Do Software Bill of Materials (SBOMs) actually give you the information necessary to verify how a given software artifact was built? What is the goal of all these compliance checklists anyways or more importantly, what should the goals be? If a software object is signed, who should be trusted to sign it, and can they be trusted forever?
Hosted by the Software Freedom Conservancy and taking place in Portland, Oregon, USA, FOSSY aims to be a community-focused event: Whether you are a long time contributing member of a free software project, a recent graduate of a coding bootcamp or university, or just have an interest in the possibilities that free and open source software bring, FOSSY will have something for you . More information on the event is available on the FOSSY 2025 website, including the full programme schedule.
Vagrant and Chris also staffed a table, where they will be available to answer any questions about Reproducible Builds and discuss collaborations with other projects.
Automation to derive declarative build definitions for existing PyPI (Python), npm (JS/TS), and Crates.io (Rust) packages.
SLSA Provenance for thousands of packages across our supported ecosystems, meeting SLSA Build Level 3 requirements with no publisher intervention.
Build observability and verification tools that security teams can integrate into their existing vulnerability management workflows.
Infrastructure definitions to allow organizations to easily run their own instances of OSS Rebuild to rebuild, generate, sign, and distribute provenance.
One difference with most projects that aim for bit-for-bit reproducibility, OSS Rebuild aims for a kind of semantic reproducibility:
Through automation and heuristics, we determine a prospective build definition for a target package and rebuild it. We semantically compare the result with the existing upstream artifact, normalizing each one to remove instabilities that cause bit-for-bit comparisons to fail (e.g. archive compression).
The extensive post includes examples about how to access OSS Rebuild attestations using the Go-based command-line interface.
New extension of Python setuptools to support reproducible builds
Wim Jeantine-Glenn has written a PEP 517 Build backend in order to enable reproducible builds when building Python projects that use setuptools.
Called setuptools-reproducible, the project s README file contains the following:
Setuptools can create reproducible wheel archives (.whl) by setting SOURCE_DATE_EPOCH at build time, but setting the env var is insufficient for creating reproducible sdists (.tar.gz). setuptools-reproducible [therefore] wraps the hooks build_sdistbuild_wheel with some modifications to make reproducible builds by default.
diffoscopediffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made the following changes, including preparing and uploading versions 301, 302 and 303 to Debian:
Improvements:
Use Difference.from_operation in an attempt to pipeline the output of the extract-vmlinux script, potentially avoiding it all in memory. []
Memoize a number of calls to --version, saving a very large number of external subprocess calls.
Bug fixes:
Don t check for PyPDF version 3 specifically, check for versions greater than 3. []
Ensure that Java class files are named .class on the filesystem before passing them to javap(1). []
Mask stderr from extract-vmlinux script. [][]
Avoid spurious differences in h5dump output caused by exposure of absolute internal extraction paths. (#1108690)
Misc:
Use our_check_output in the ODT comparator. []
Update copyright years. []
In addition:
Siva Mahadevan made a change to use the --print-armap long option when calling nm(1) for wider compatibility. []
Lastly, Chris Lamb added a tmpfs to try.diffoscope.org so that diffoscope has a non-trivial temporary area to unpack archives, etc. []
Elsewhere in our tooling, however, reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.30 was uploaded to Debian unstable by Holger Levsen, chiefly including a change by Rebecca N. Palmer to not call sudo with the -h flag in order to fix Debian bug #1108550. []
New library to patch system functions for reproducibility
Nicolas Graves has written and published libfate, a simple collection of tiny libraries to patch system functions deterministically using LD_PRELOAD. According to the project s README:
libfate provides deterministic replacements for common non-deterministic system functions that can break reproducible builds. Instead of relying on complex build systems or apps or extensive patching, libfate uses the LD_PRELOAD trick to intercept system calls and return fixed, predictable values.
Describing why he wrote it, Nicolas writes:
I originally used the OpenSUSE dettrace approach to make Emacs reproducible in Guix. But when Guix switch to GCC@14, dettrace stopped working as expected. dettrace is a complex piece of software, my need was much less heavy: I don t need to systematically patch all sources of nondetermism, just the ones that make a process/binary unreproducible in a container/chroot.
One desirable property is that someone else should be able to reproduce the same git bundle, and not only that a single individual is able to reproduce things on one machine. It surprised me to see that when I ran the same set of commands on a different machine (started from a fresh git clone), I got a different checksum. The different checksums occurred even when nothing had been committed on the server side between the two runs.
Website updates
Once again, there were a number of improvements made to our website this month including:
Bernhard M. Wiedemann added an entry related to R-B-OS on the History page. []
Chris Lamb:
Replaced rbtlog run by Fay by rbtlog run by Benl on the Who is involved page. []
Debian contributors have made significant progress toward ensuring package builds produce byte-for-byte reproducible results. You can check the status for packages installed on your system using the new package debian-repro-status, or visit reproduce.debian.net for Debian s overall statistics for trixie and later. You can contribute to these efforts by joining #debian-reproducible on IRC to discuss fixes, or verify the statistics by installing the new rebuilderd package and setting up your own instance.
Reproducibility testing framework
The Reproducible Builds project operates a comprehensive testing framework running primarily at tests.reproducible-builds.org in order to check packages and other artifacts for reproducibility. In July, however, a number of changes were made by Holger Levsen, including:
Make the dsa-check-packages output more useful. []
Setup the ppc64el architecture again, has it has returned this time with a 2.7 GiB database instead of 72 GiB. []
In addition, Jochen Sprickerhof improved the reproducibility statistics generation:
Enable caching of statistics. [][][]
Add some common non-reproducible patterns. []
Change output to directory. []
Add a page sorted by diffoscope size. [][]
Switch to Python s argparse module and separate output(). []
Holger also submitted a number of Debian bugs against rebuilderd and rebuilderd-worker:
Config files and scripts for a simple one machine setup. [][]
Create a rebuilderd user. []
Create rebuilderd-worker user with sbuild. []
Lastly, Mattia Rizzolo added a scheduled job to renew some SSL certificates [] and Vagrant Cascadian performed some node maintenance [][].
Upstream patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where appropriate. This month, we wrote a large number of such patches, including:
Finally, if you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
When companies design products a major concern seems to be what the reviewers will have to say about it. For any product of significant value the users are unable to perform any reasonable test before buying, for a casual user some problems may only be apparent after weeks of use so professional reviews are important to many people. The market apparently doesn t want reviews of the form here s a list of products that are quite similar and all do the job well, you can buy any of them, it s no big deal which would be the most technically accurate way of doing it.
So the reviewers compare the products on the criteria that are easiest to measure, this lead to phones being compared by how light and thin they are. I think it s often the case that users would be better served by thicker heavier phones that have larger batteries but instead they are being sold phones that have good battery life in a fresh installation but which don t last a day with a full load of apps installed.
The latest issue with bad reviews driving poor product design is electric cars. For a while the advocates of old fashioned cars have touted the range of petrol cars which has become an issue for comparing EVs. I have been driving cars for 35 years and so far I have never driven anywhere that s out of range of the current electric charging network, even with the range of the LEAF (which is smaller than many other EVs). If I ever felt the need to drive across the Nullarbor Plain then I could rent a car to do that and the costs of such car rental would be small compared to the money I m saving by driving an EV and also small when compared to the premium I would have to pay for an EV with a larger range.
Some of the recent articles I ve seen about EVs have covered vehicles with a battery range over 700Km which is greater than the legal distance a commercial driver can drive without a break. I ve also seen articles about plans to have a small petrol or Diesel motor in an EV to recharge the battery without directly driving the wheels. A 9KW Diesel motor could provide enough electricity on average to keep the charge maintained in a LEAF battery and according to the specs of Diesel generators would take about 55Kg of fuel to provide the charge a LEAF needs to drive 1000Km. The idea of a mostly electric hybrid car that can do 1000Km on one tank of fuel is interesting as a thought experiment but doesn t seem to have much actual use. Apparently a Chinese company is planning to release a car that can do 1400Km one one tank of fuel using such technology which is impressive but not particularly useful.
The next issue of unreasonable competition is in charge speed. Charging a car at 2KW from a regular power socket is a real limit to what you can do with a car. It s a limit that hasn t bothered me so far because the most driving I typically do in a week is less than one full charge, so at most I have to charge overnight twice in a week. But if I was going to drive to another city without hiring a car that has better range I d need a fast charger. Most current models of the Nissan LEAF support charging speeds up to 50KW which means fully charging the battery in under an hour (or slightly over an hour for the long range version). If I was to drive from Melbourne to Canberra in my LEAF I d have to charge twice which would be an annoyance at those speeds. There are a variety of EVs that can charge at 100KW and some as high as 350KW. 350KW is enough to fully charge the largest EV batteries in half an hour which seems to be as much as anyone would need. But there are apparently plans for 1MW car chargers which would theoretically be able to charge a Hummer (the EV with the largest battery) in 12 minutes. One obvious part of the solution to EV charging times is to not drive a Hummer! Another thing to note is that batteries can t be charged at a high rate for all charge levels, this is why advertising for fast chargers makes claims like 80% charge in half an hour which definitely doesn t mean 100% charge in 37.5 minutes !
There are significant engineering issues with high power applications. A 1MW cable is not just a bigger version of a regular power cable, there are additional safety issues, user training is required and cooling of the connector is probably required. That s a lot to just get a better number in the table at the end of a review. There is research in progress on the Megawatt Charging System which is designed to charge heavy vehicles (presumably trucks and buses) at up to 3.75MW. Charging a truck at that rate is reasonable as the process of obtaining and maintaining a heavy vehicle license requires a significant amount of effort and some extra training in 3.75MW charging probably doesn t make much difference.
A final issue with fast charging is the capacity of the grid. A few years ago I attended a lecture by an electrical engineer who works for the Victorian railway system which was very interesting. The Vic rail power setup involved about 100MW of grid connectivity with special contracts with the grid operators due to the fact that 1MW trains suddenly starting and stopping causes engineering problems that aren t trivial to solve. They were also working on battery packs and super capacitors to deal with regenerative braking and to avoid brownouts in long sections of track. For a medium size petrol station 14 bays for fuelling cars is common. If 6 such petrol stations were replaced with fast charging stations that can charge cars at 1MW each that would draw the same power as the train network for the entire state! There is a need for significant engineering work to allow most cars to be electric no matter how it s done, but we don t need to make that worse just for benchmarks.
Another short status update of what happened on my side last
month. Larger blocks besides the Phosh 0.47 release are on screen
keyboard and cell broadcast improvements, work on separate volume
streams, the switch of phoc to wlroots 0.19.0 and effort to make
Phosh work on Debian's upcoming stable release (Trixie) out of the
box. Trixie will ship with Phosh 0.46, if you want to try out 0.47
you can fetch it from Debian's experimental suite.
See below for details on the above and more:
phosh
Track volume control based on media role priority (MR)
Standardize audio stream roles (MR). Otherwise we'll have a hard time
with e.g. WirePlumbers role based policy linking as apps might use all kinds of types.
Reviews
This is not code by me but reviews on other peoples code. The list is
(as usual) slightly incomplete. Thanks for the contributions!

 It is widely accepted that there is an AI bubble in the financial markets at the moment. The moderate opinion is however that LLMs are constantly improving and will eventually take over more and more tasks from humans and increase productivity. But are LLMs actually getting smarter, or just better at fooling us?
There is a growing faction of technical experts that argue that LLMs are actually so bad for real progress, that they are banning their use and requiring human-only work to ensure quality and efficient use of humans time. A recent review of AI policies of 120 open source projects by Rakshit Yadav shows that 37 chose to have a total AI ban. In the Linux kernel AI-assisted contributions are allowed, but the LLM used needs to be attributed for transparency, while projects like GCC, QEMU, SDL, Gentoo, Zig and Ghostty have adopted policies to reject all AI-assisted contributions. There are also development platforms such as Codeberg and Sourcehut and app stores like Flathub that have banned AI use to generate software, documentation, bug reports, review comments and basically anything that is intended for humans to read. The projects that allow AI use typically still require that there must be a human-in-the-loop and the submitter must have read and filtered everything the LLM spits out before another human is exposed to it, in an effort to contain the spread of AI slop.
Right now, the Linux distribution Debian is having a vote among its developers on whether AI should be allowed or banned for use to contribute to Debian. One of the proposals on the ballot is a total ban of AI for code, documentation, translations, bug reports and more. The initial reaction from most people is astonishment why don t these techies want to use the latest and greatest technology mankind has produced so far? Is it that they don t want Debian to improve faster with the help of AI? Or is it actually so that LLMs are a scam and incapable of being truly useful for Debian? These people are distinguished experts in their own field, and certainly not stupid, so it is worth pausing to understand why they are proposing AI banning policies.
Also, keep in mind that the AI datacenters themselves run on Debian or other Linux-based systems. All the open source software in the world has been fed to LLMs and software development is one of the main use cases for AI currently. So why is it that the maintainers of many open source projects don t want to receive LLM-assisted contributions, despite the LLMs basically all running on top of those same software stacks and having been trained on how to do software development using the very same open source software codebases?


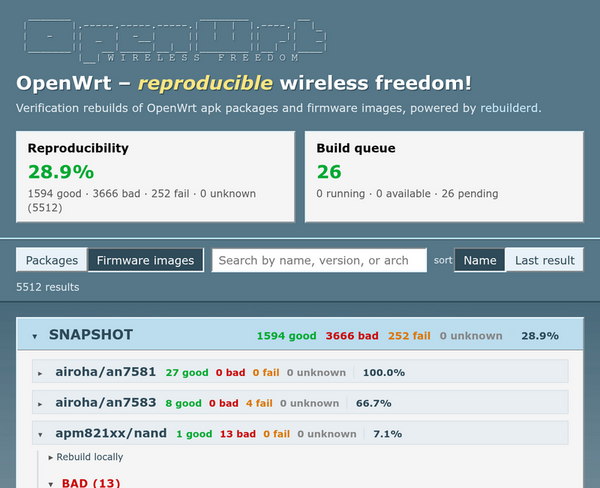

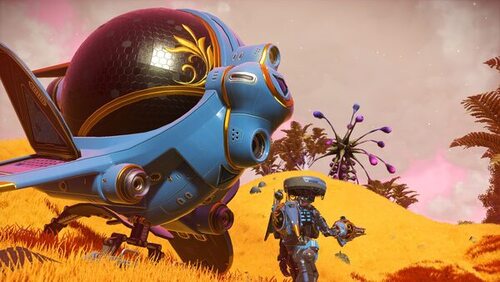
 Manor by Mingle - the hostel where we stayed at during our KL transit. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
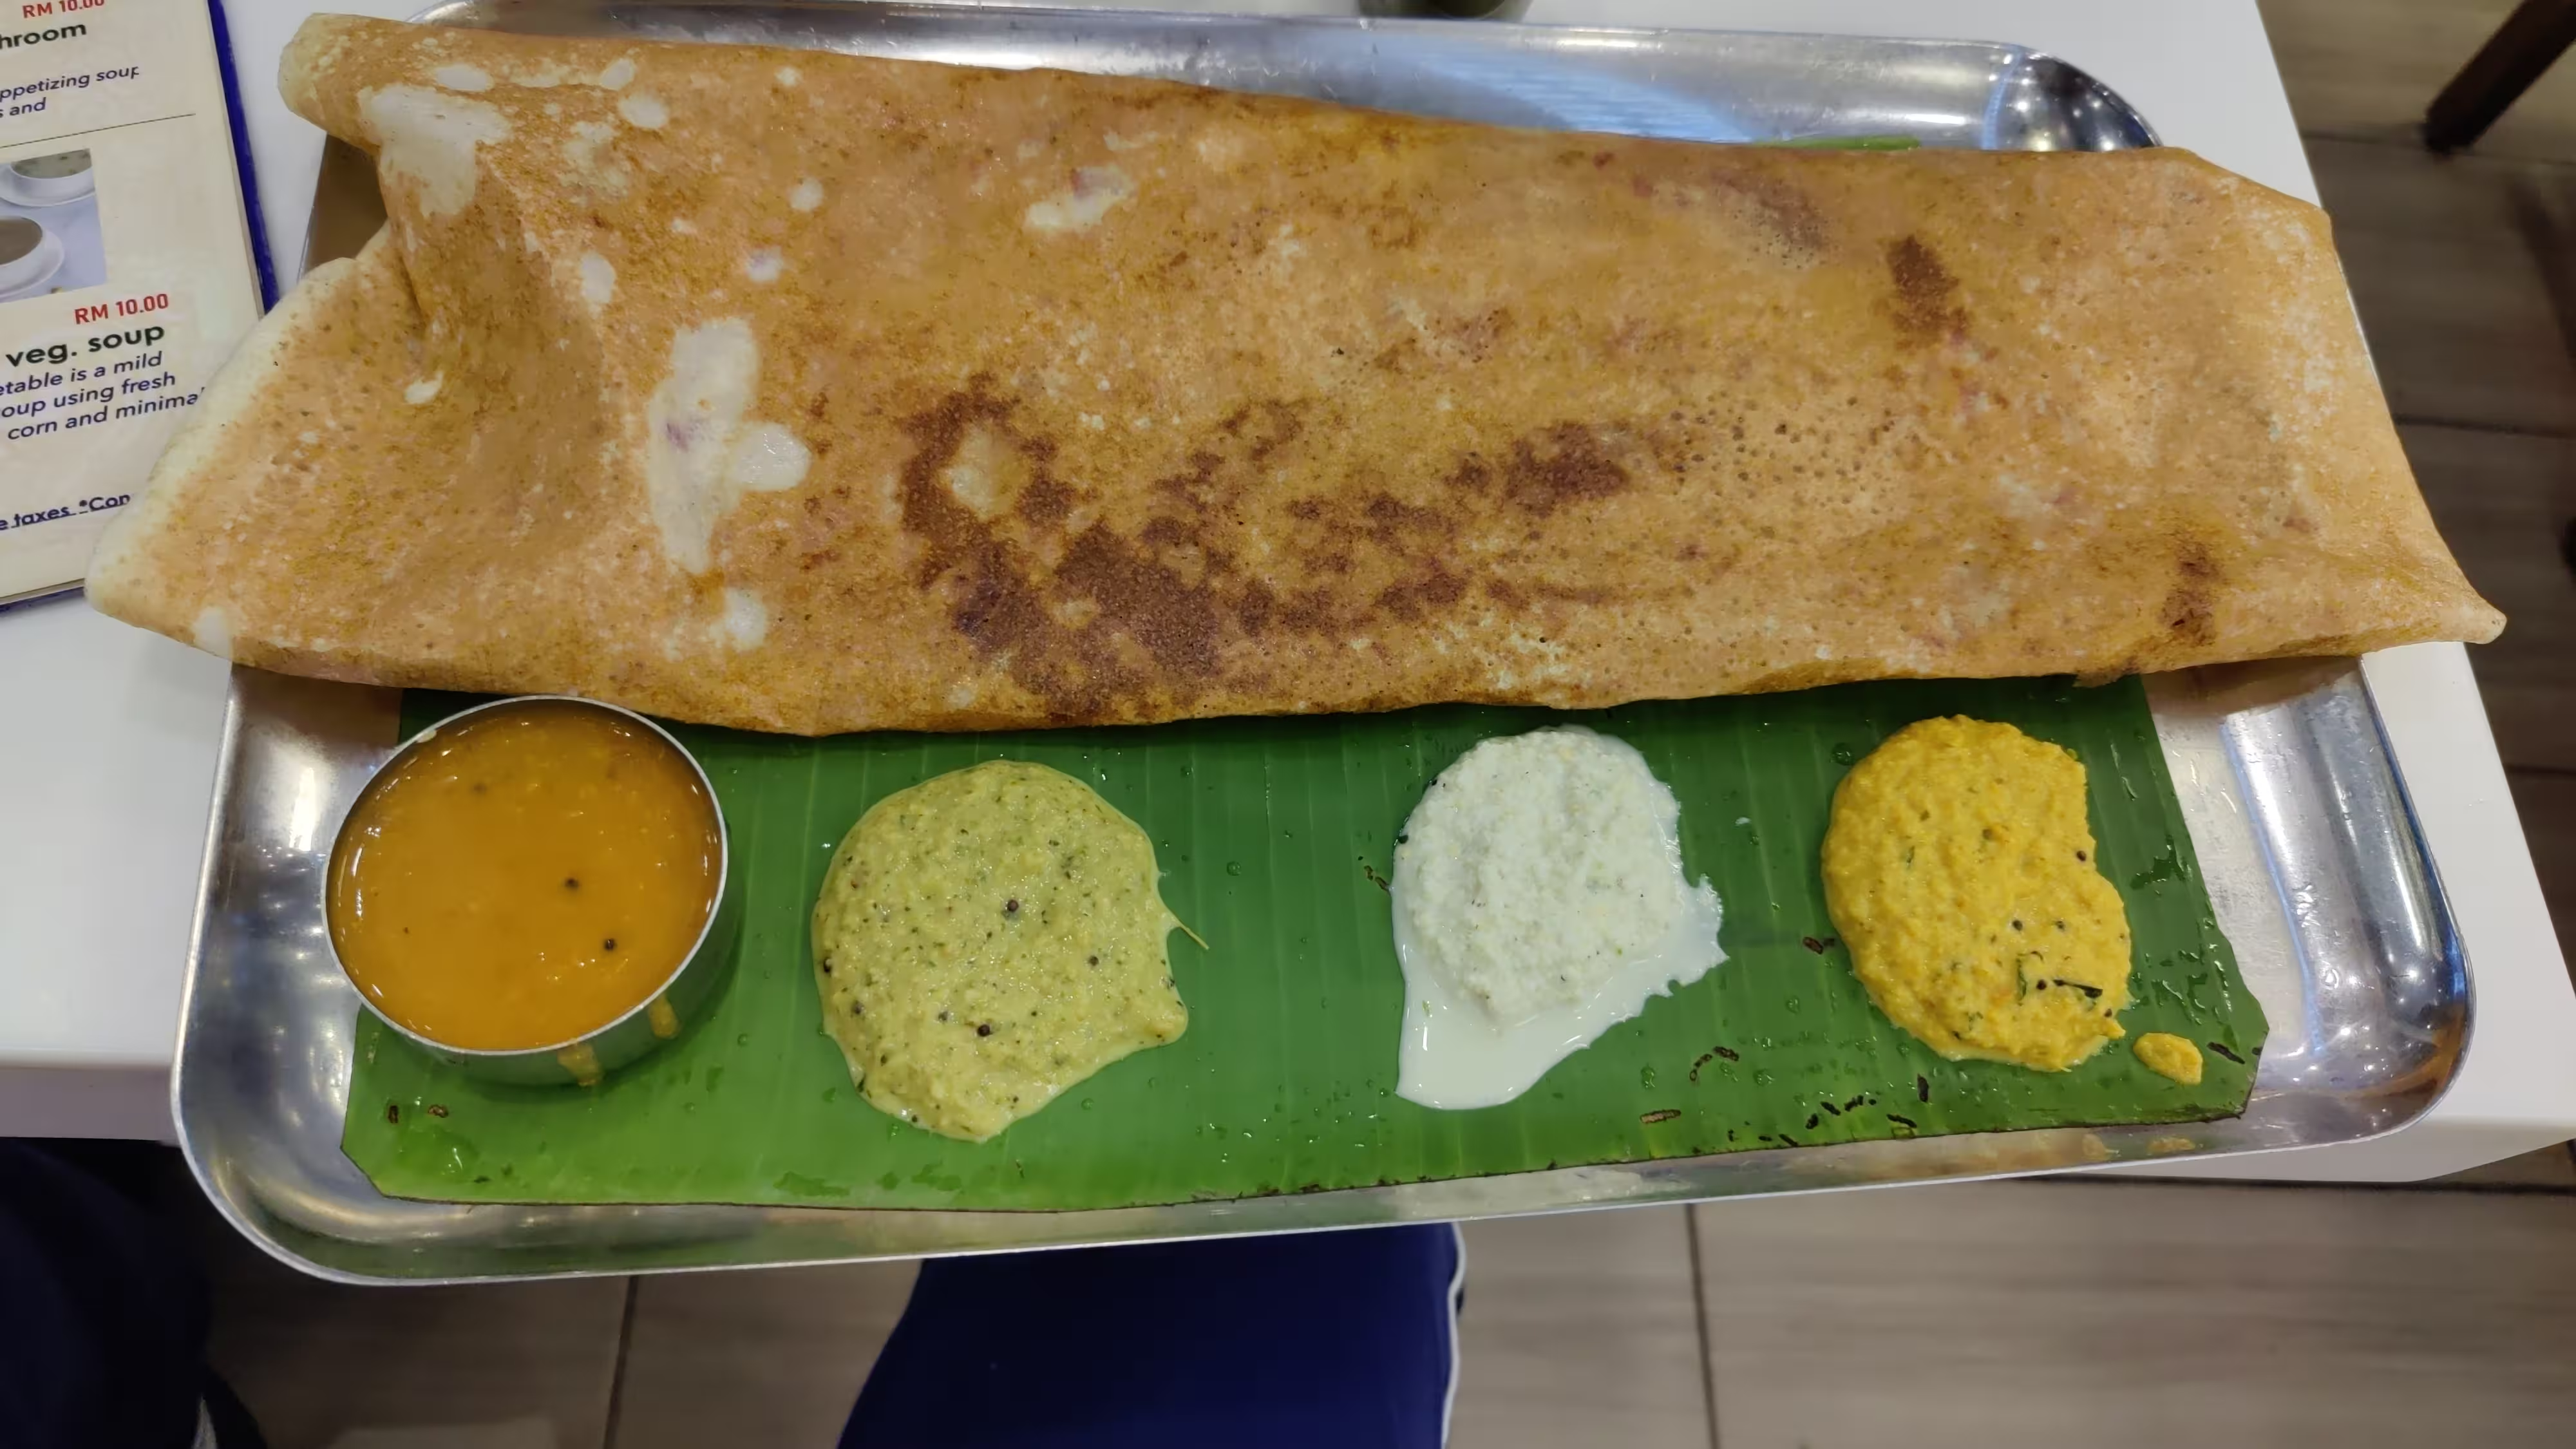 Dosa served at Adyar Ananda Bhavan. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
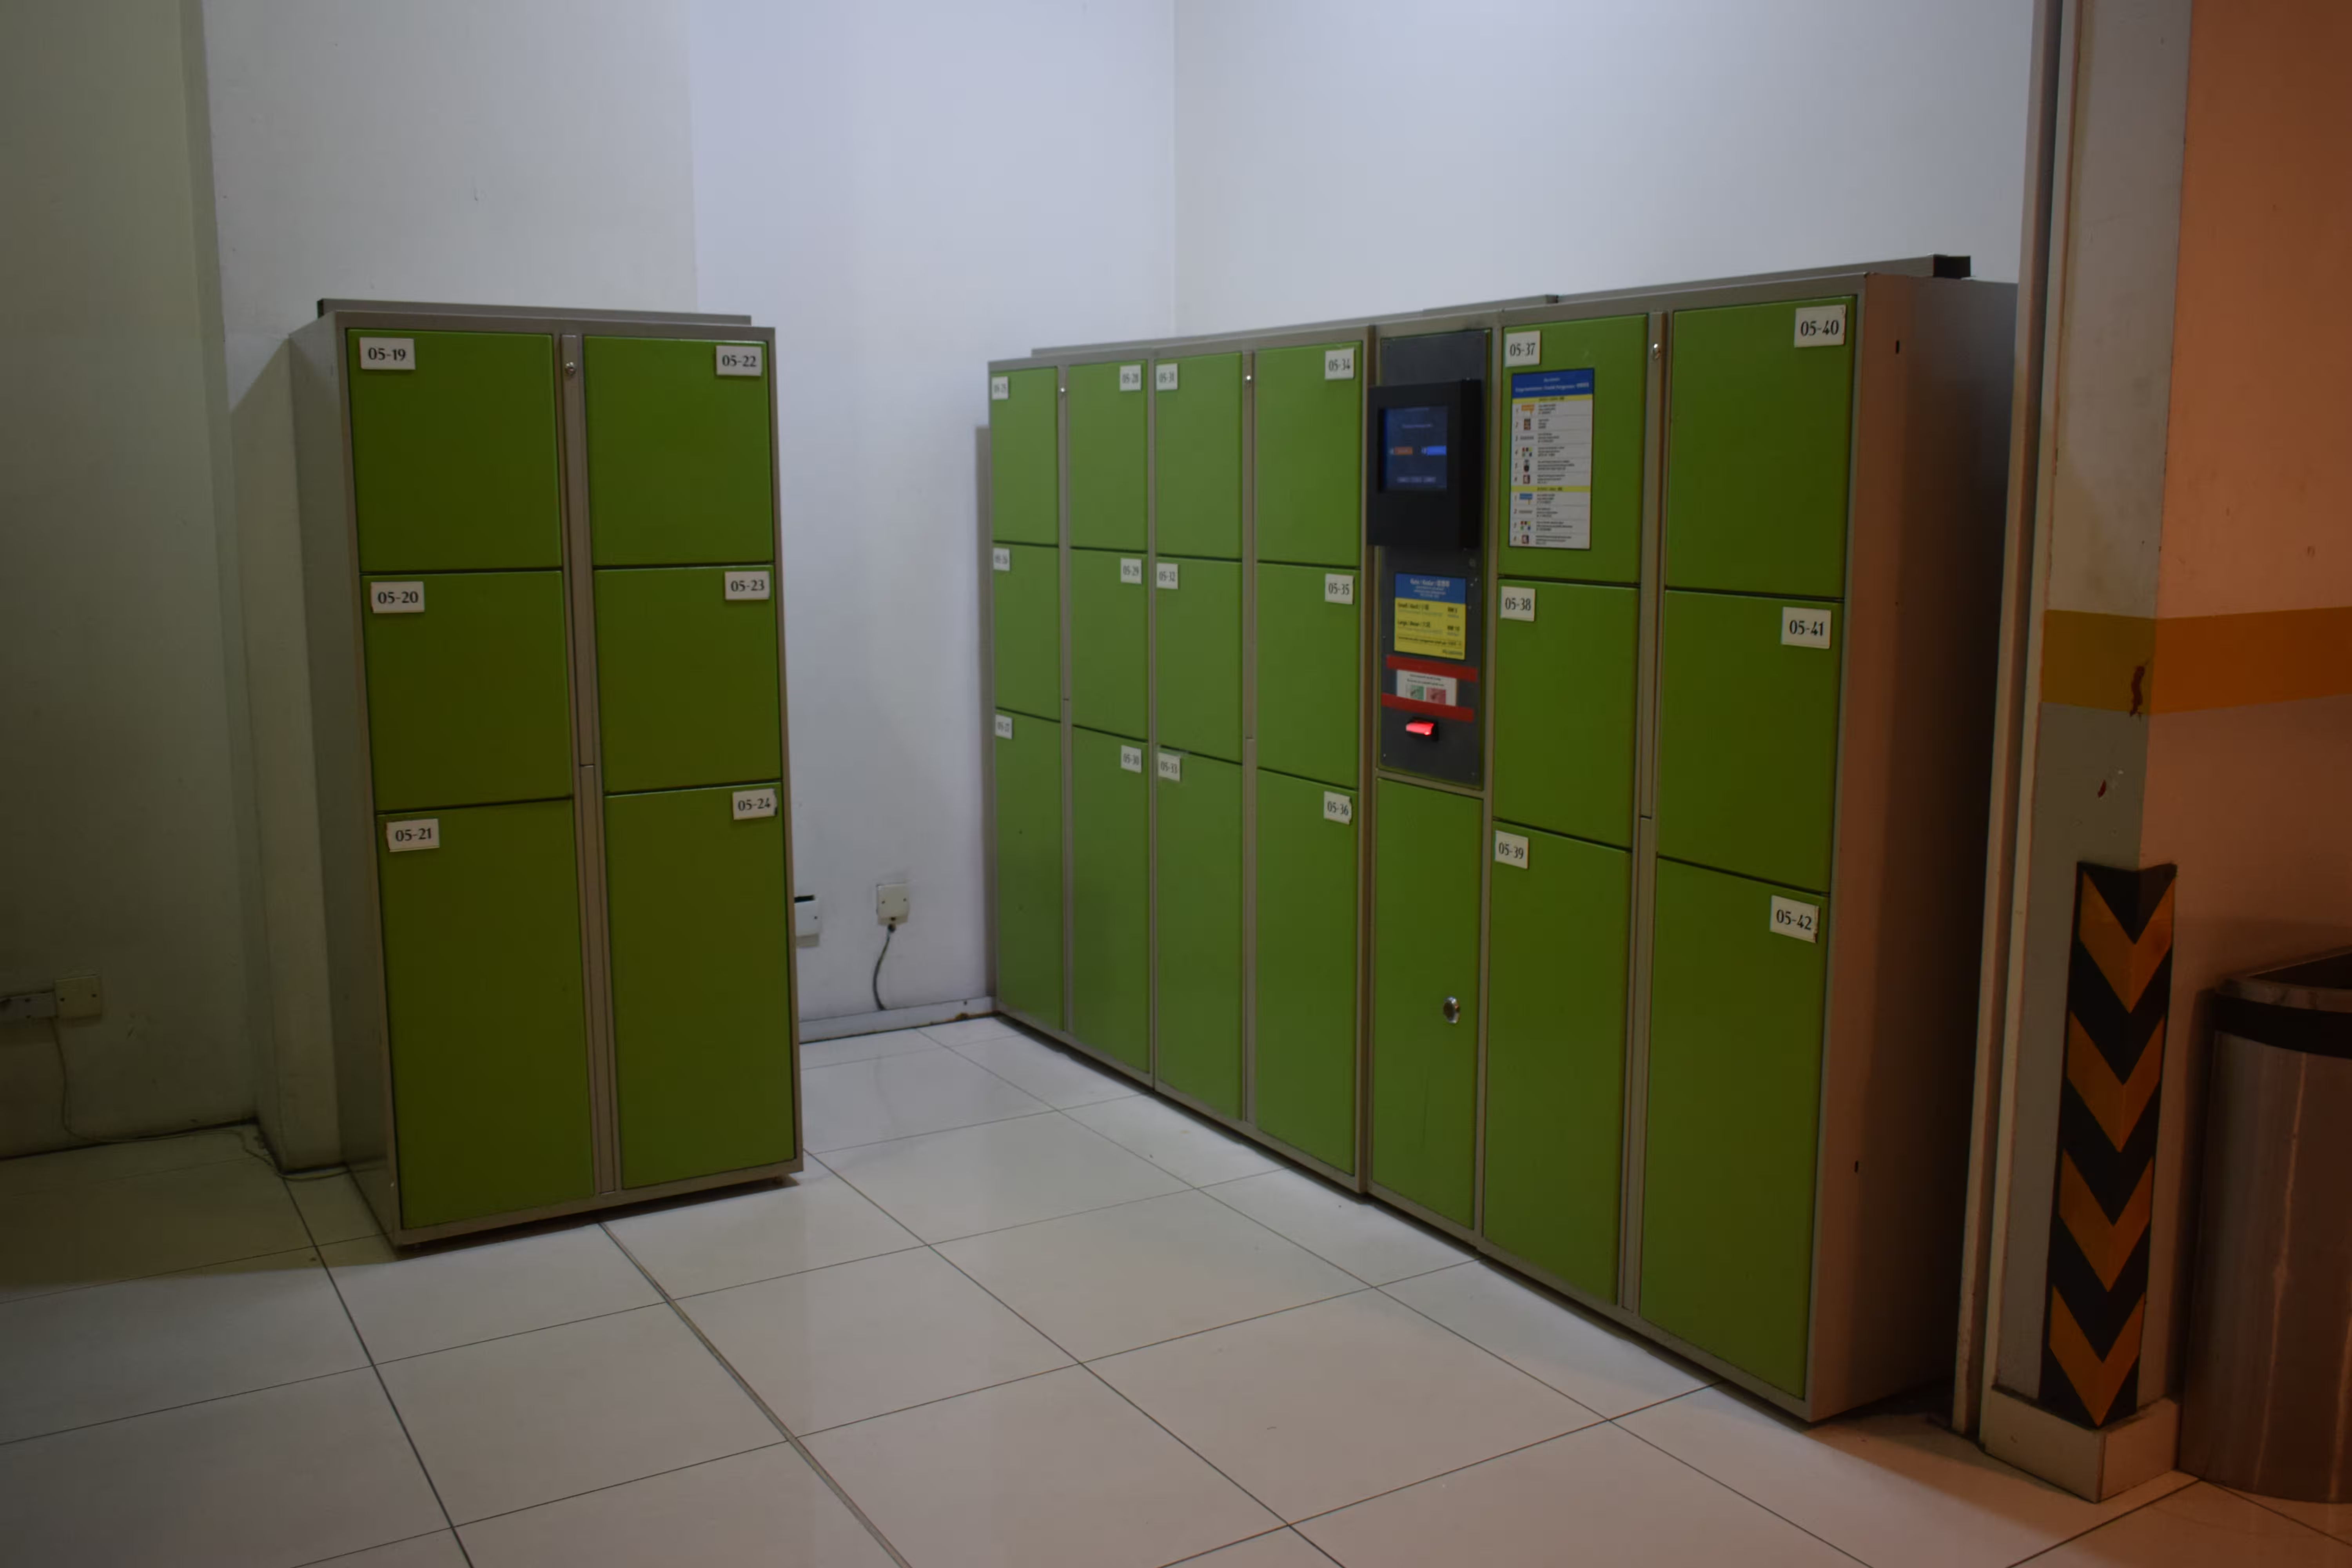 Lockers at TBS bus station. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
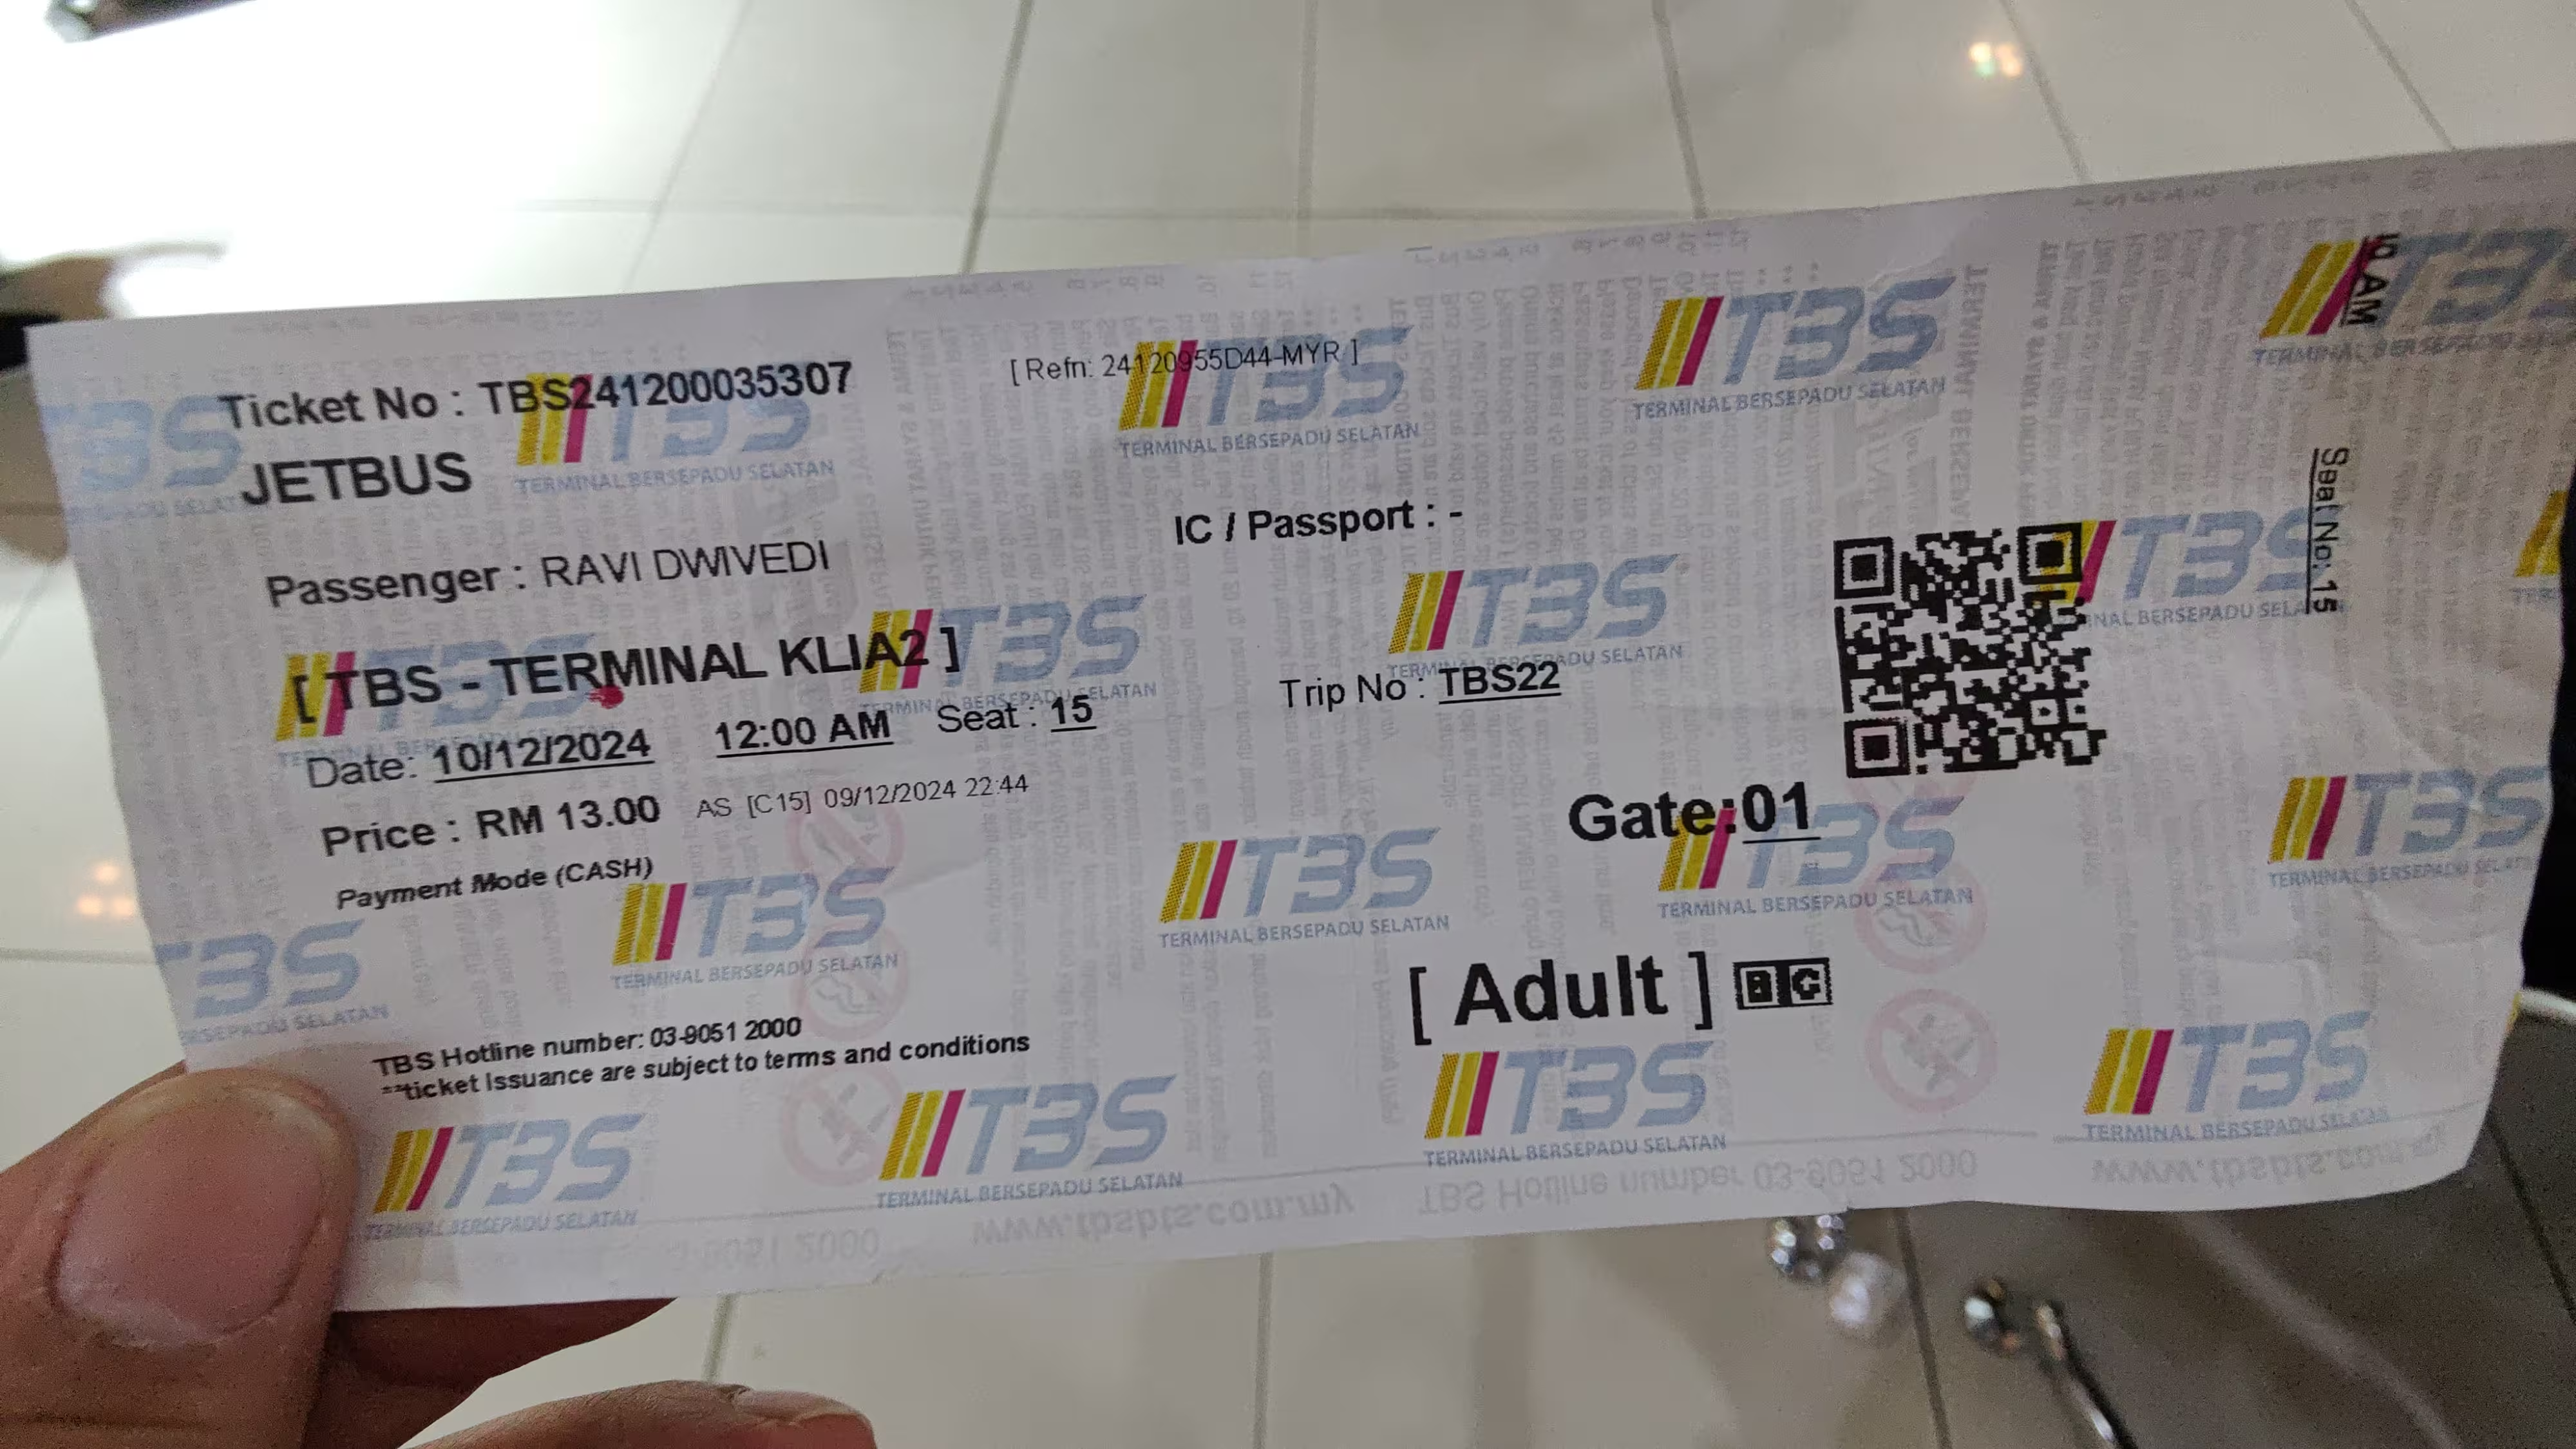 My boarding pass for the bus to the airport in Kuala Lumpur. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
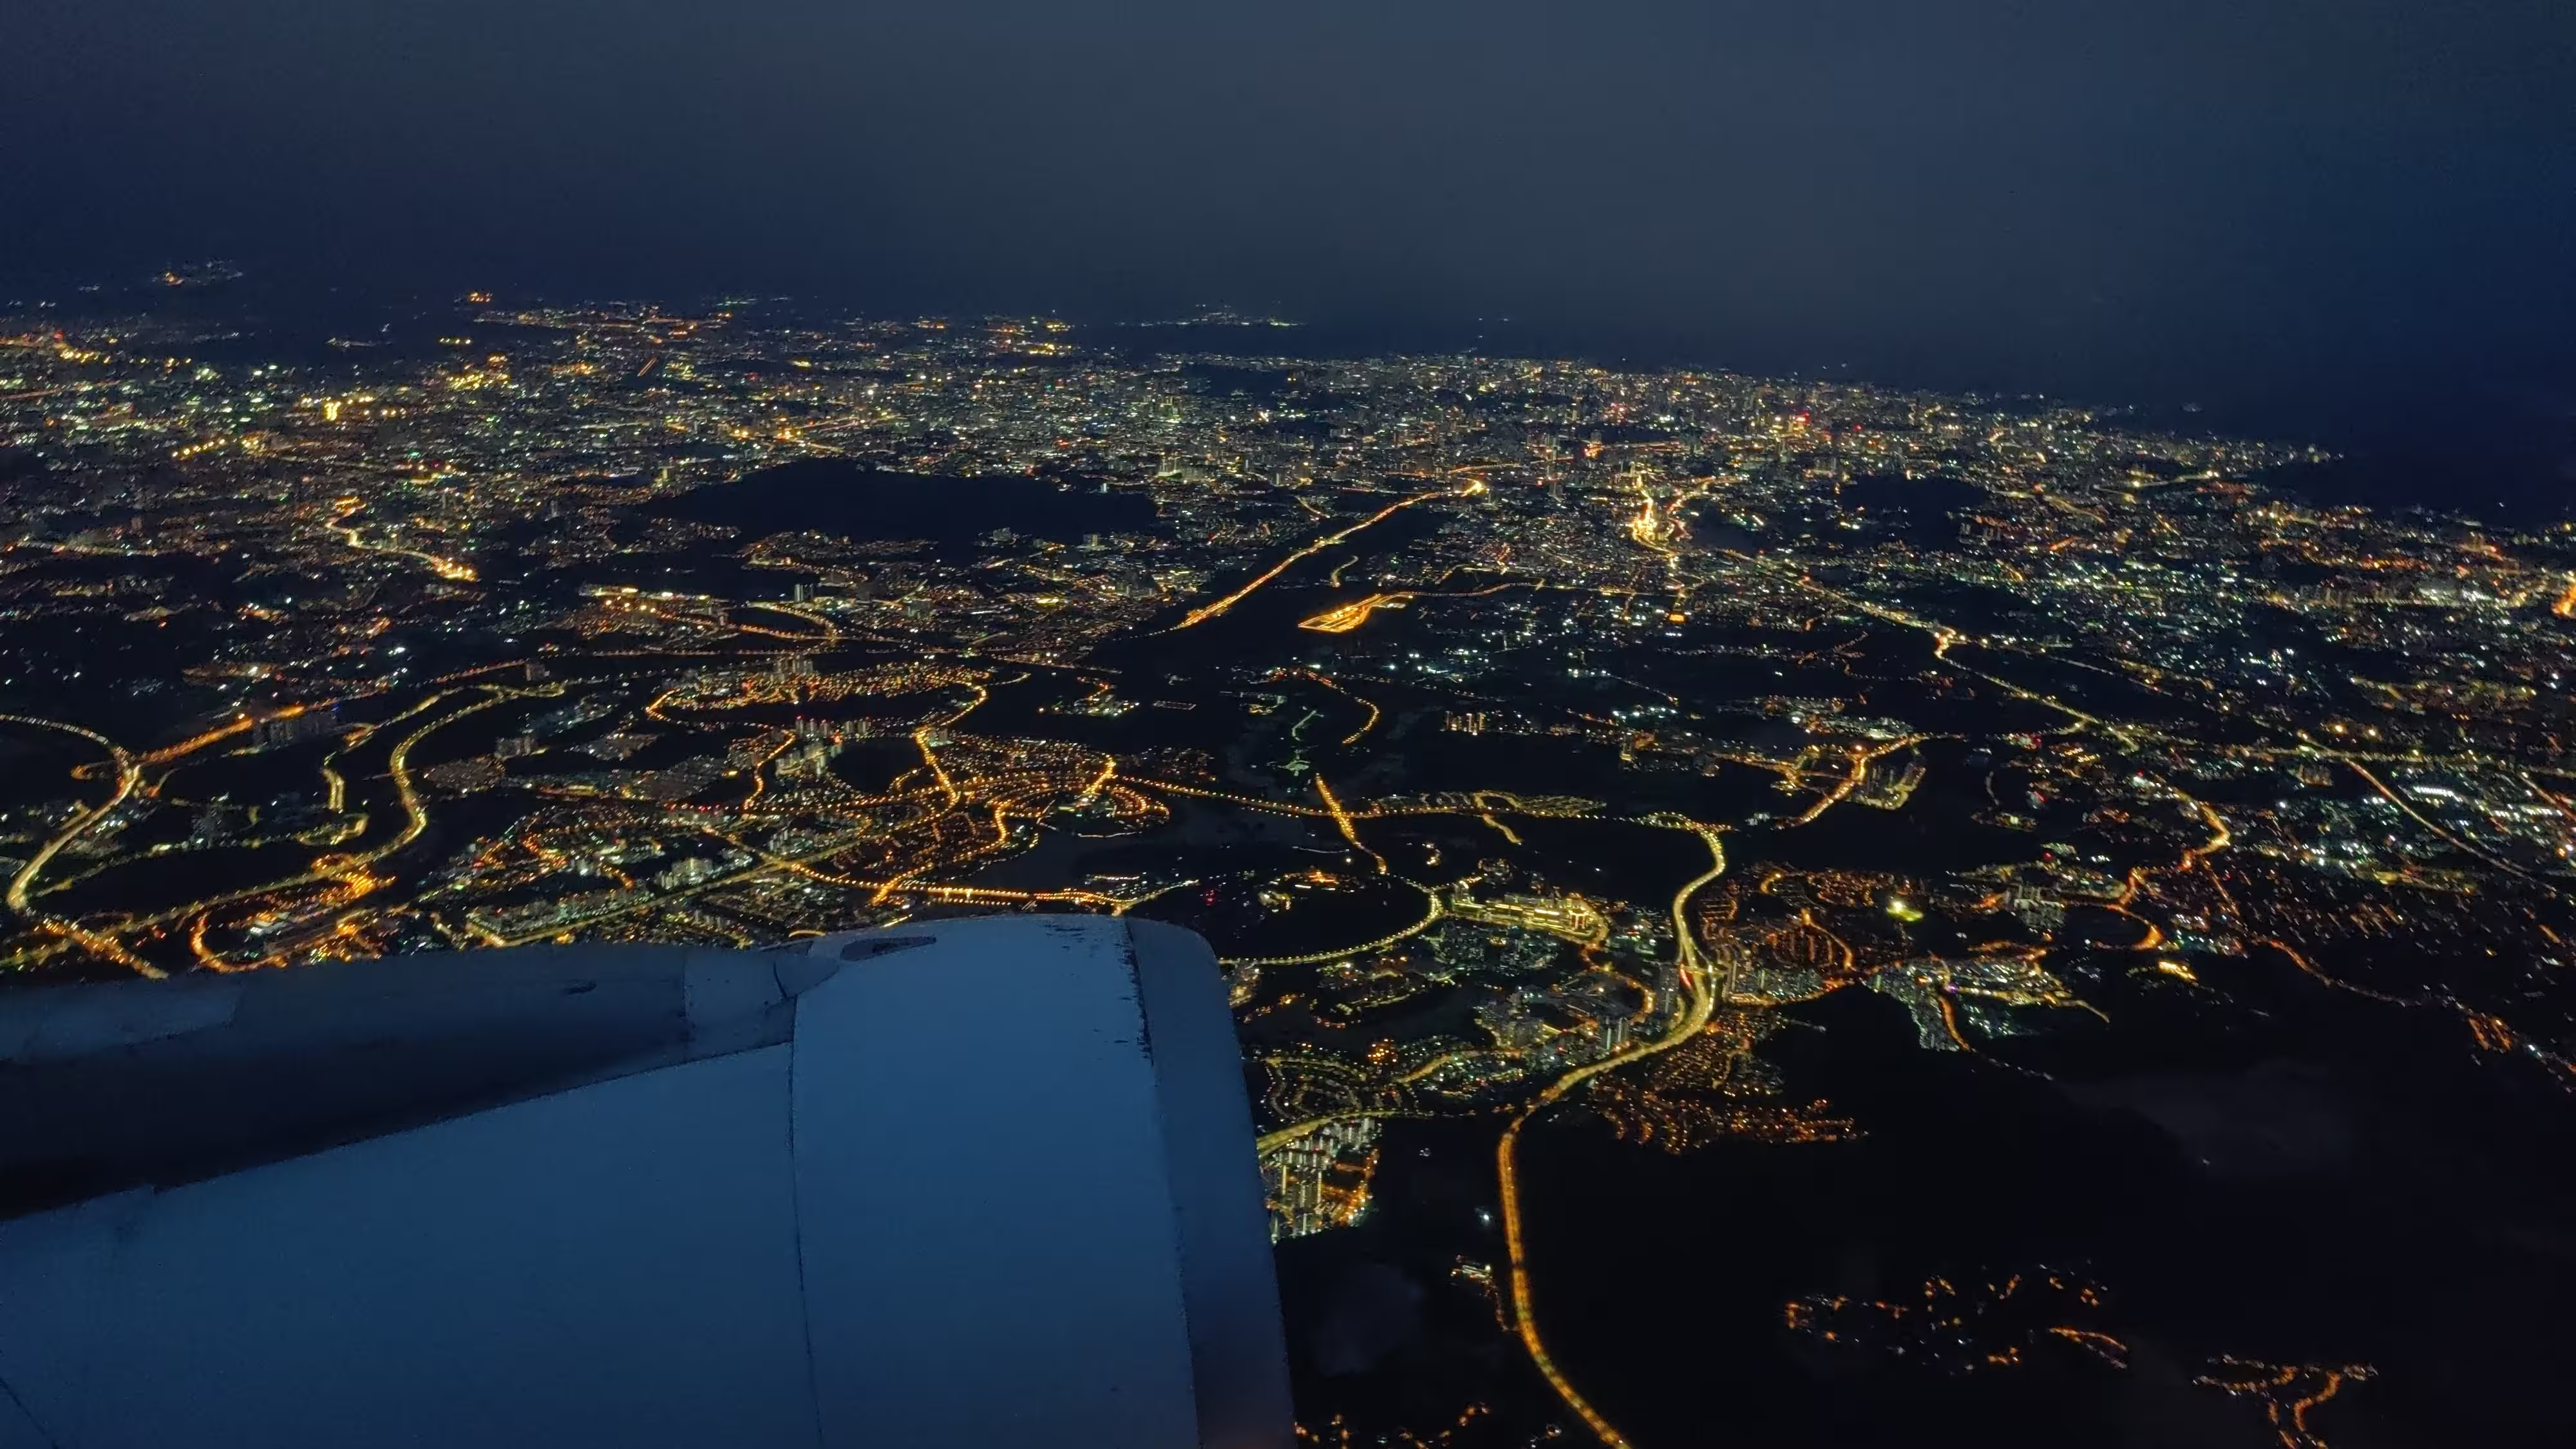 View of Kuala Lumpur from the aeroplane. Photo by Ravi Dwivedi. Released under the CC-BY-SA 4.0.
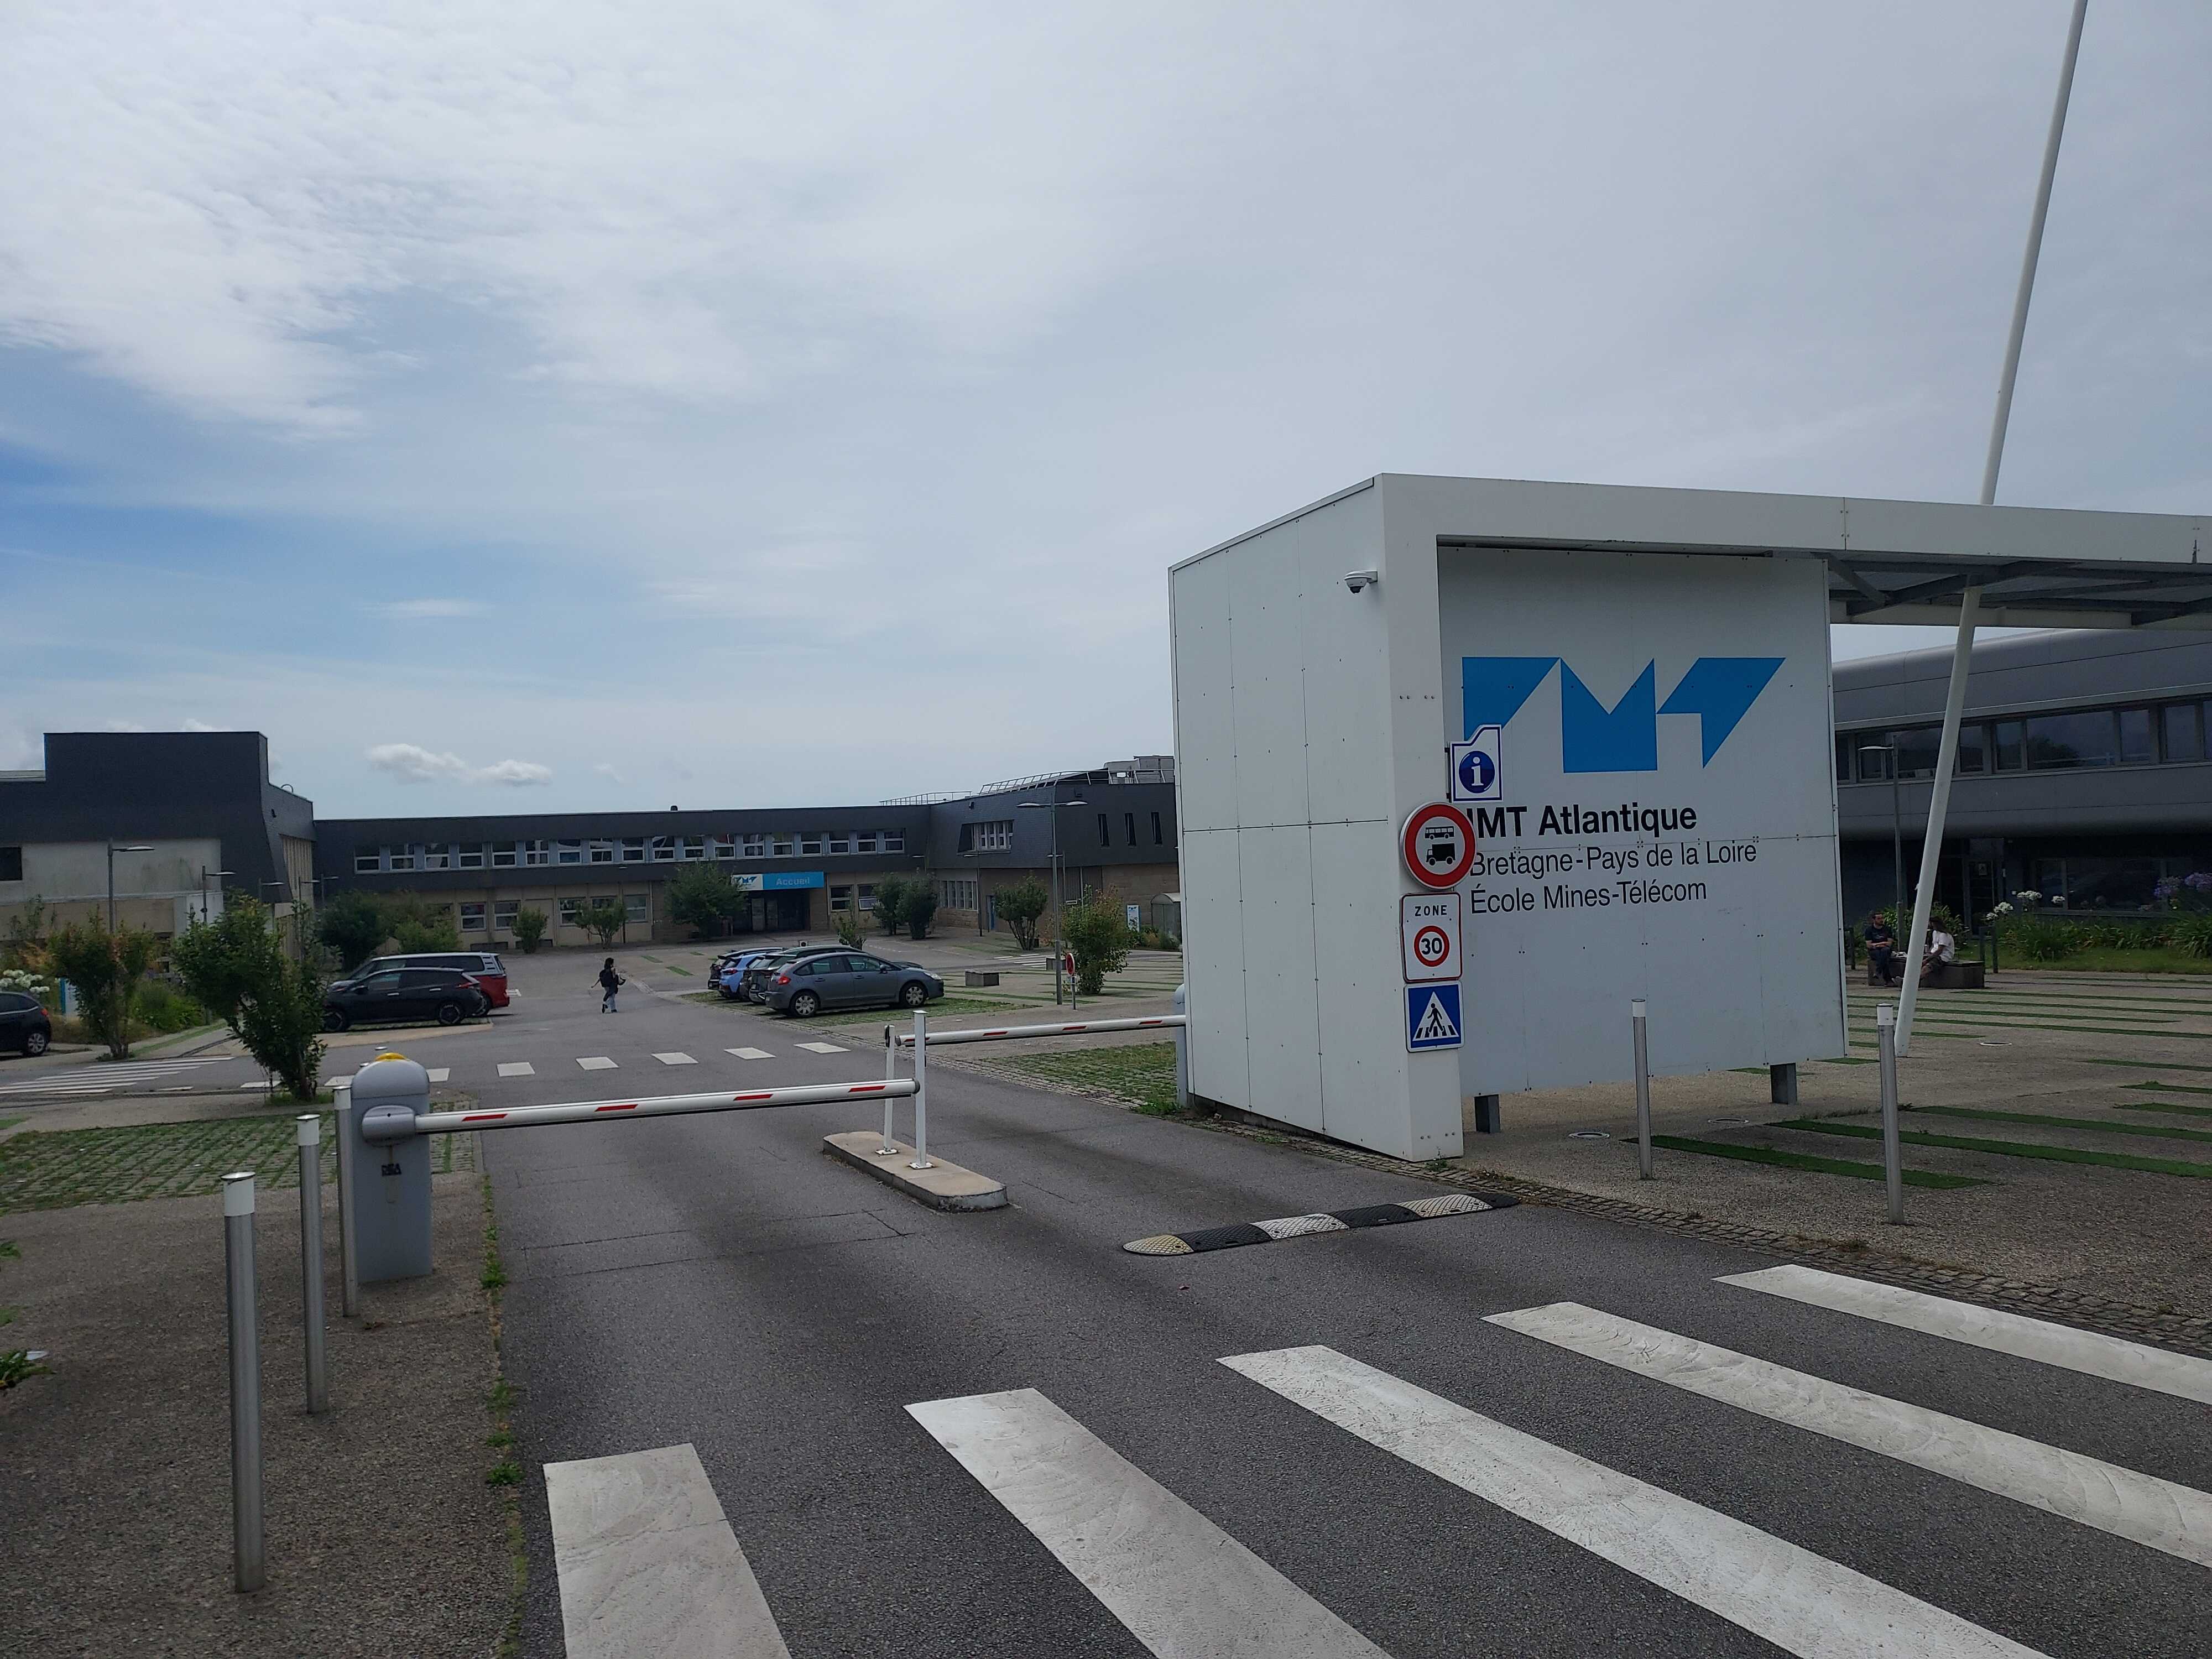
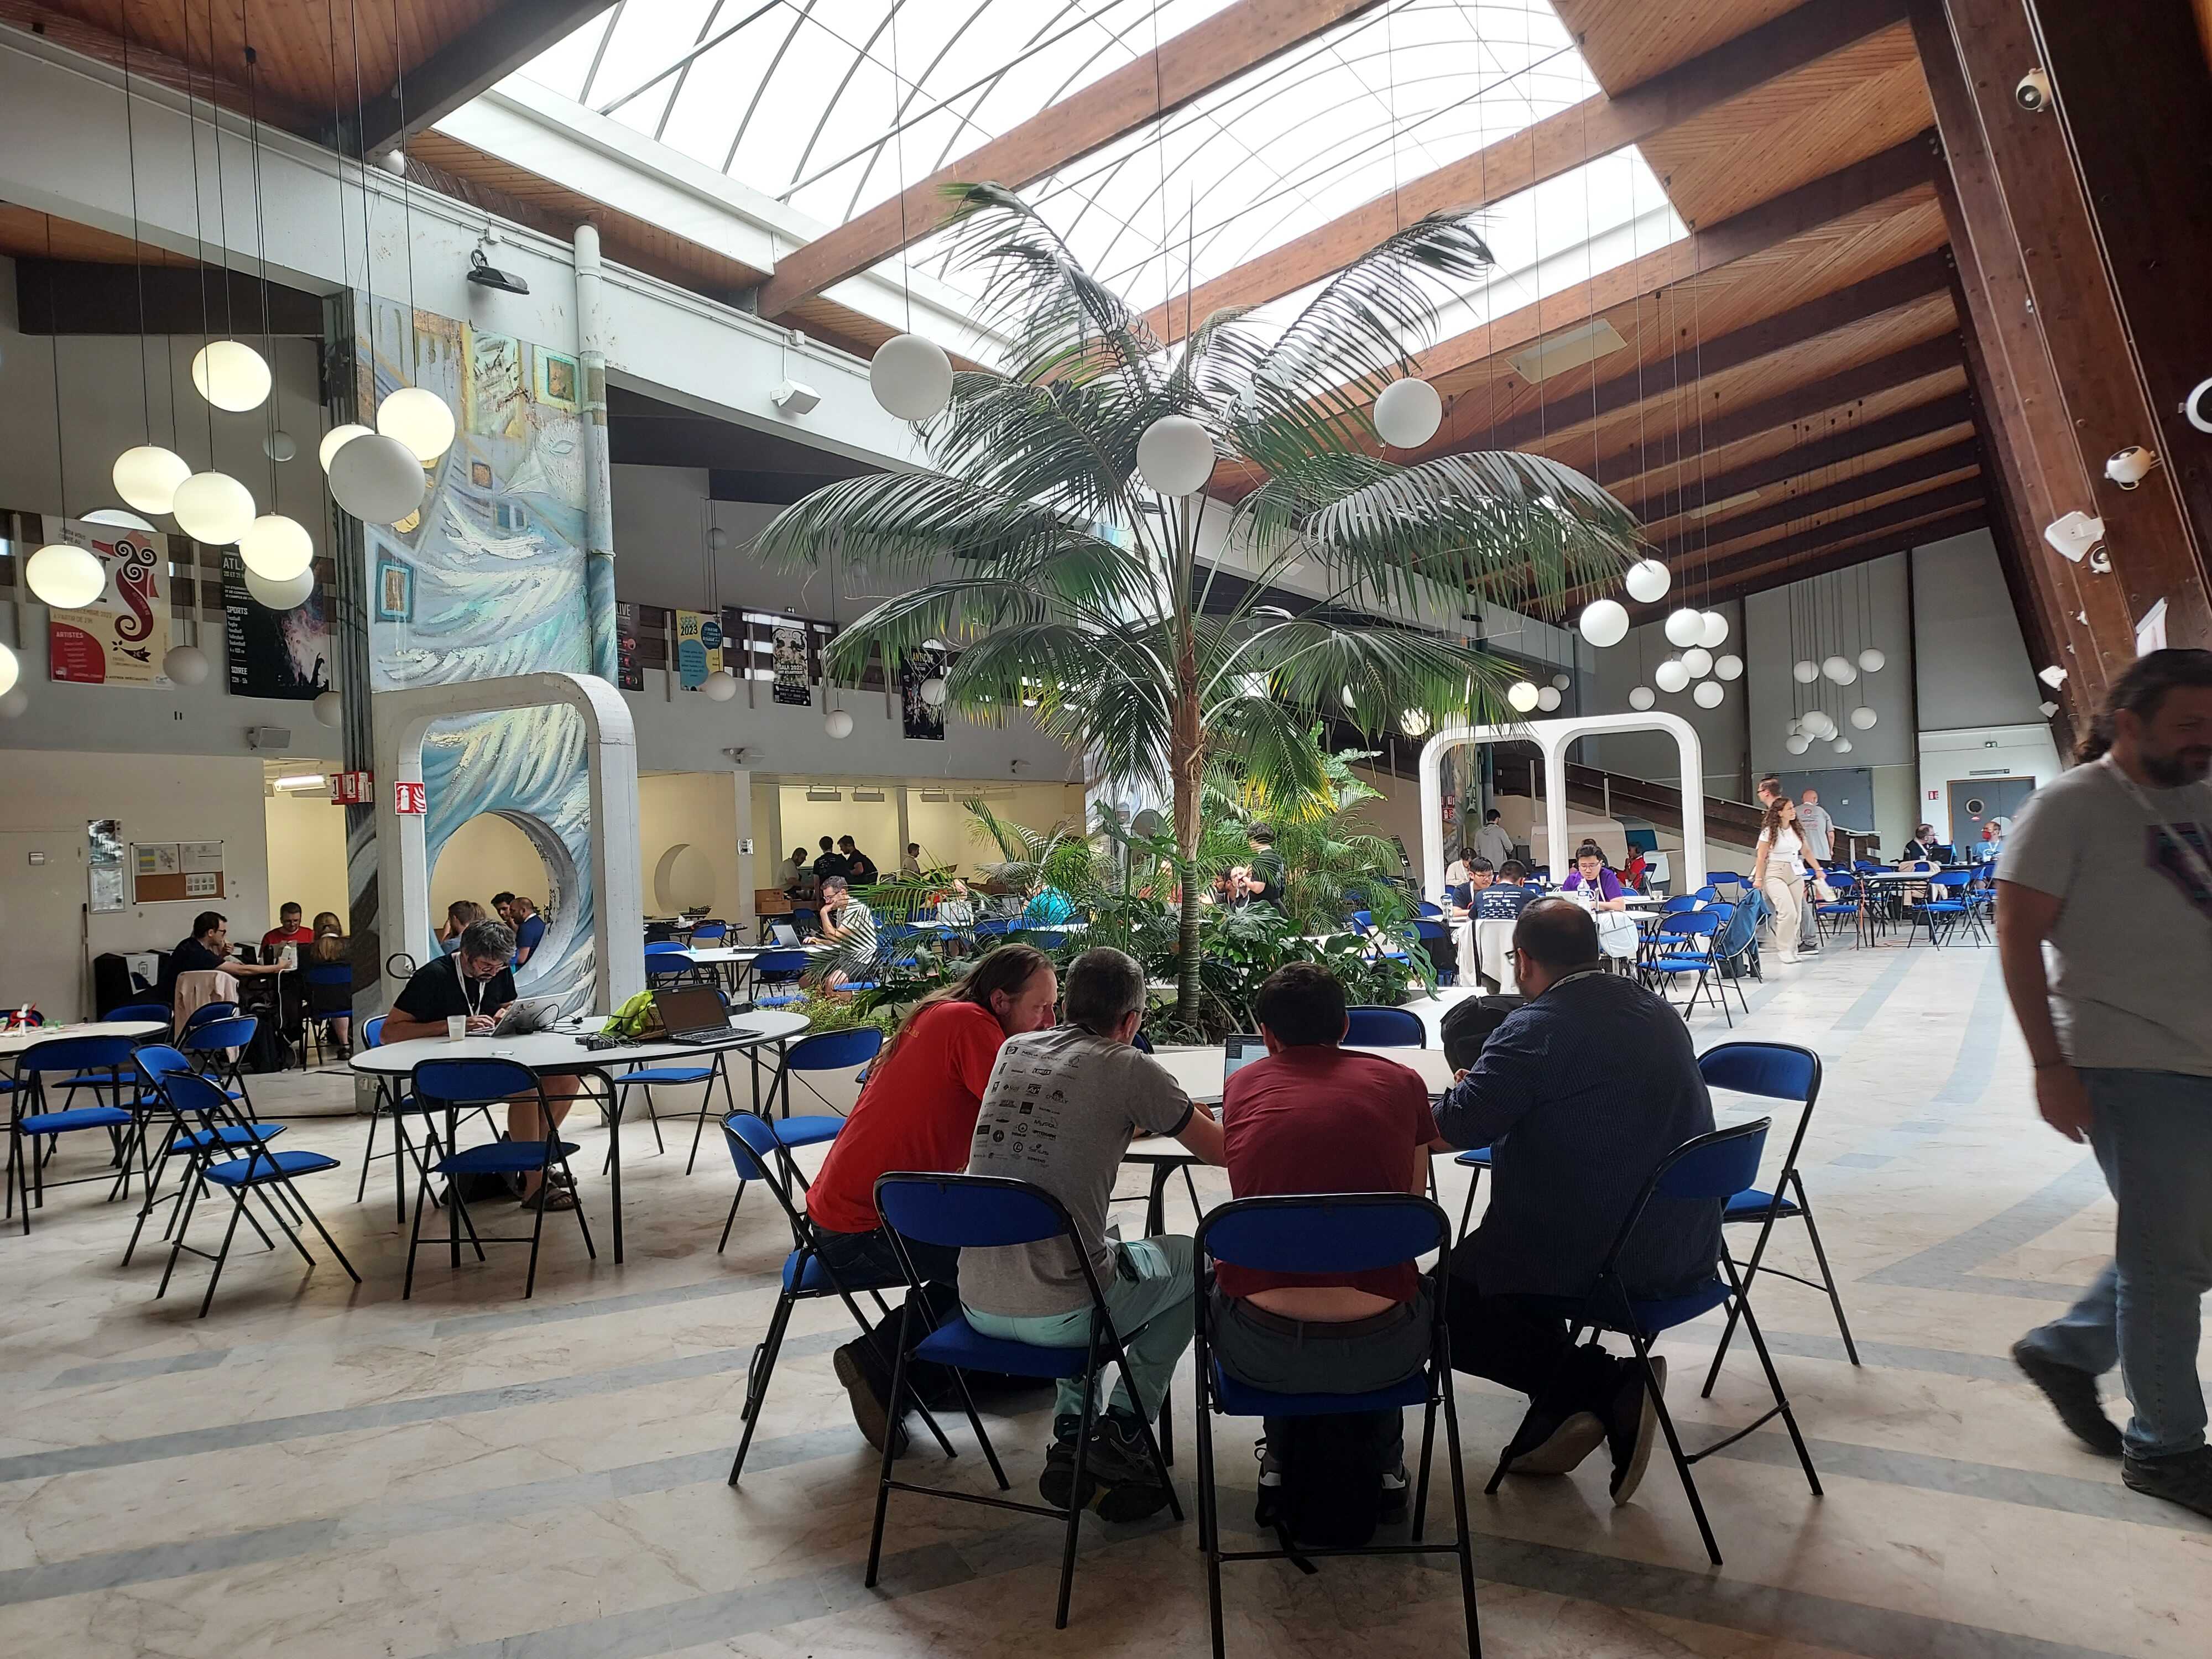

 DC25 network usage graphs.
 Flow diagrams.
 Streaming bandwidth graph.
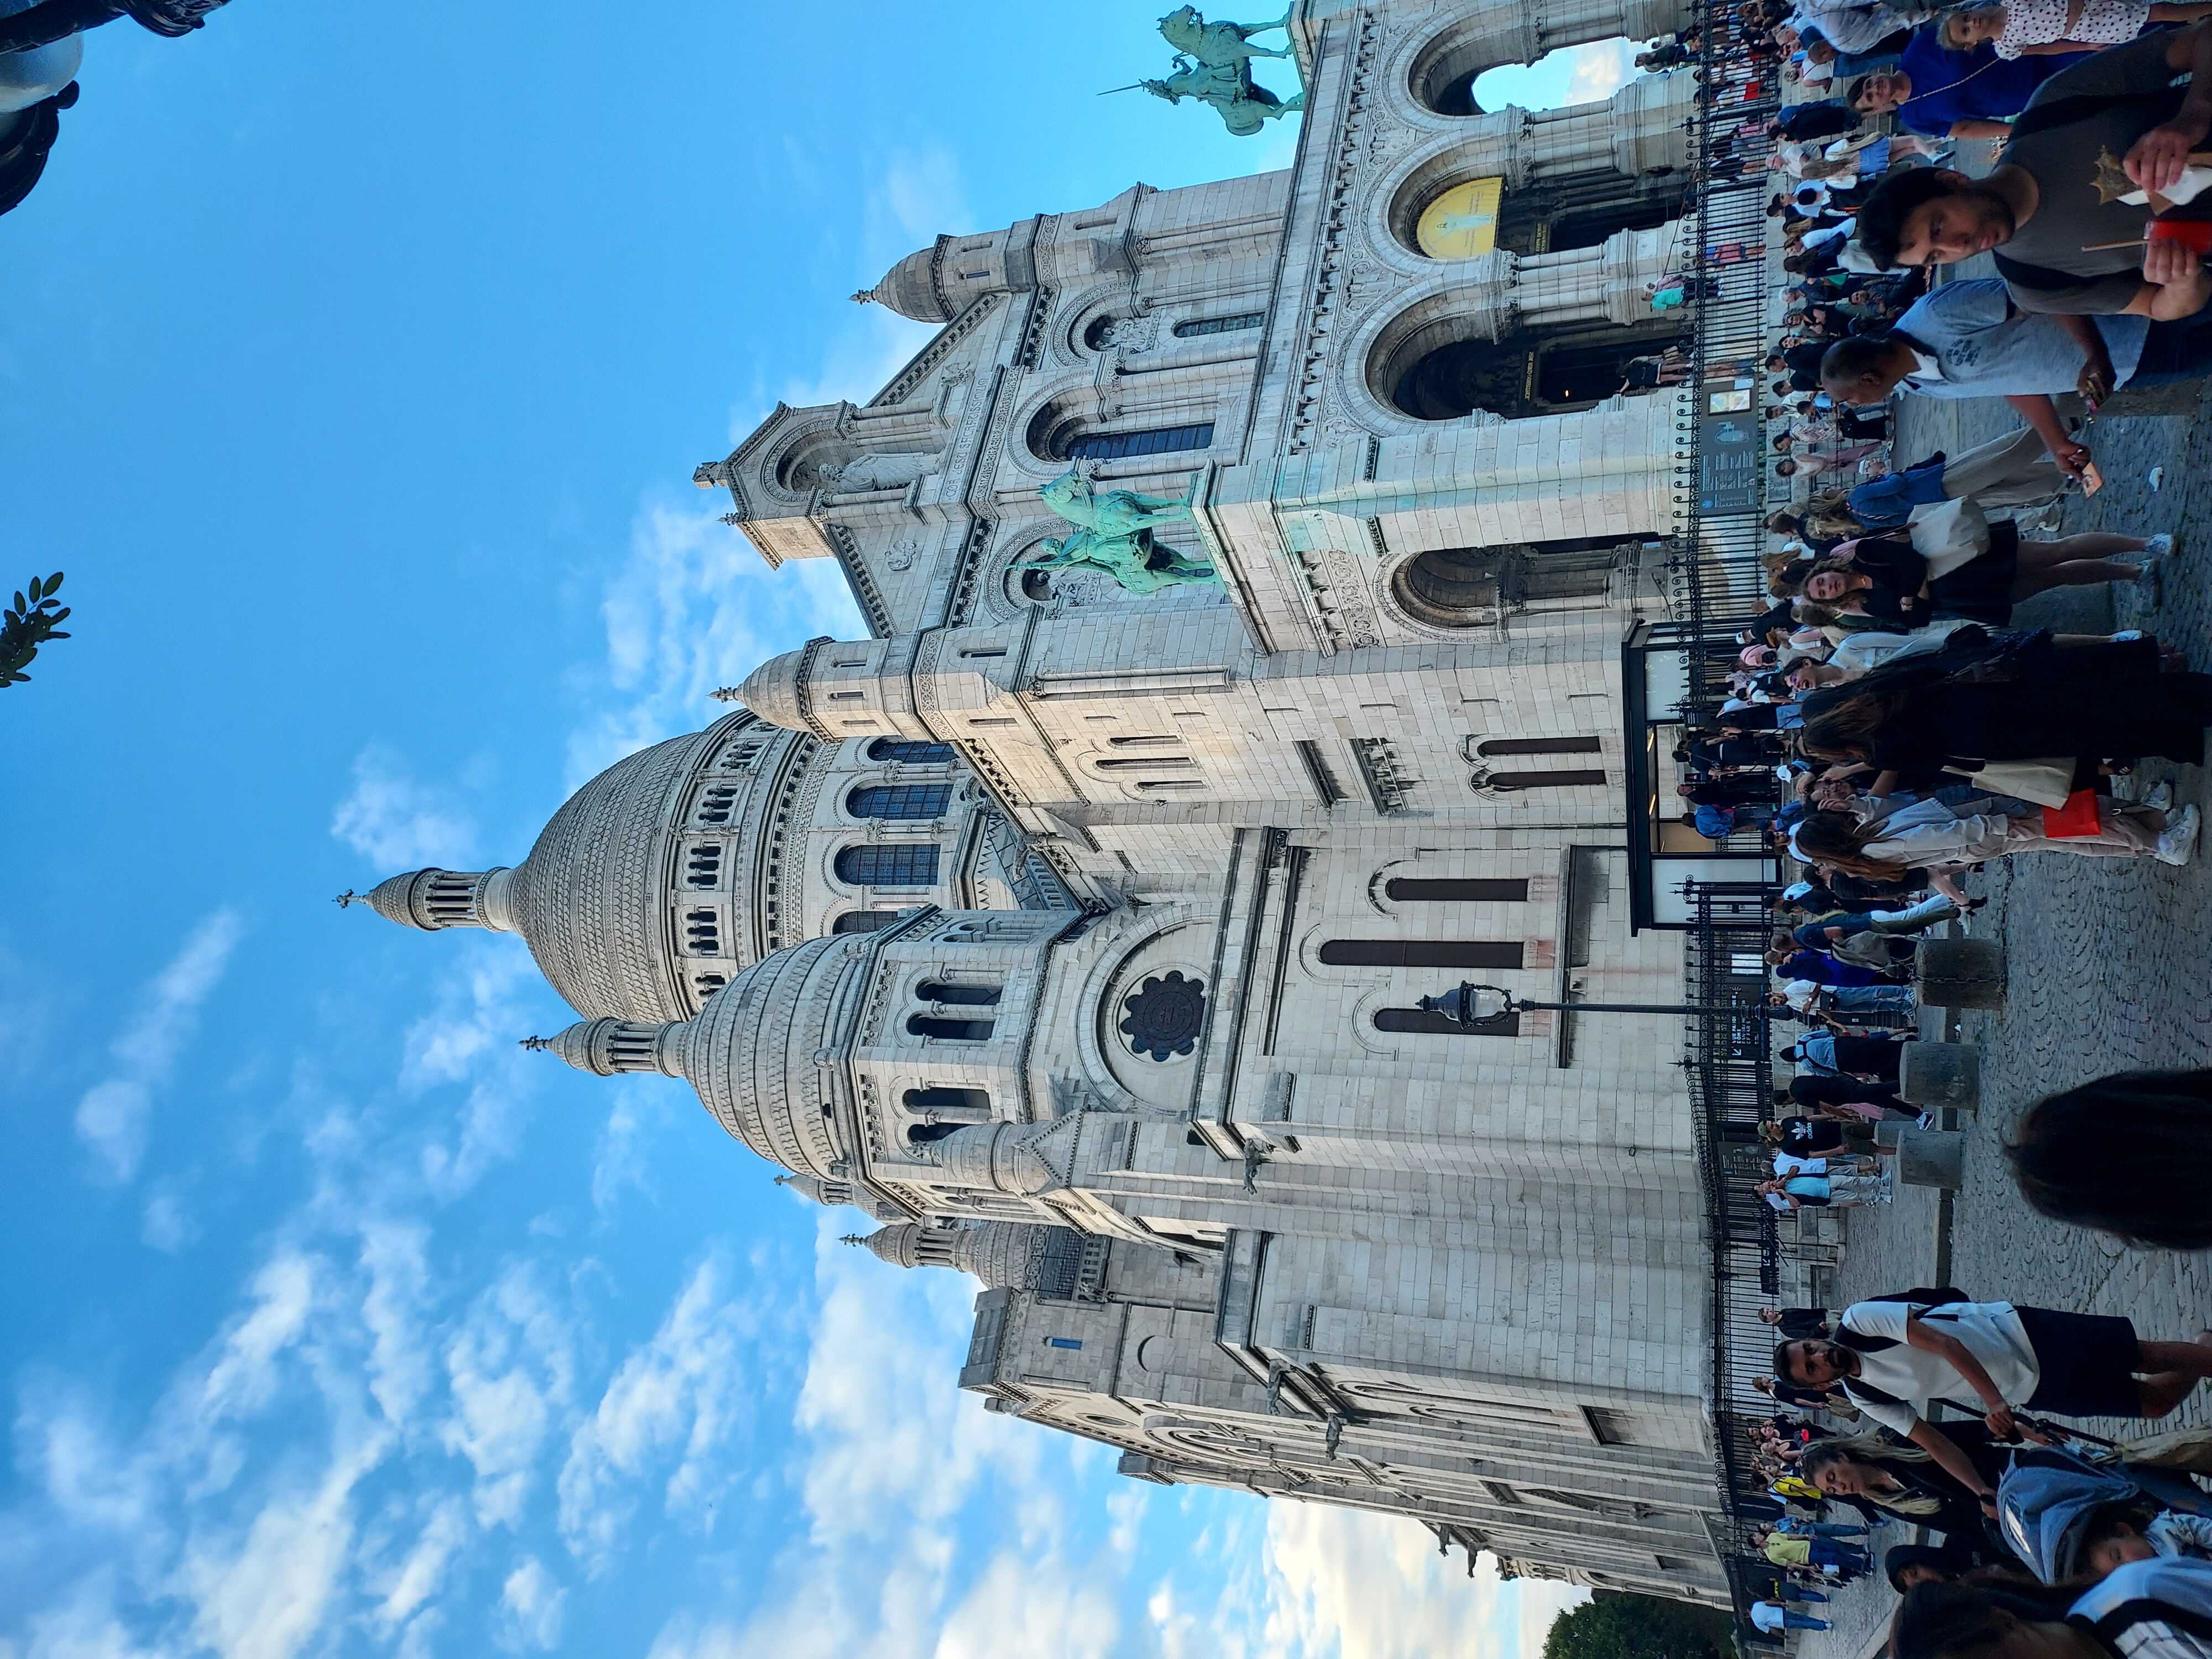
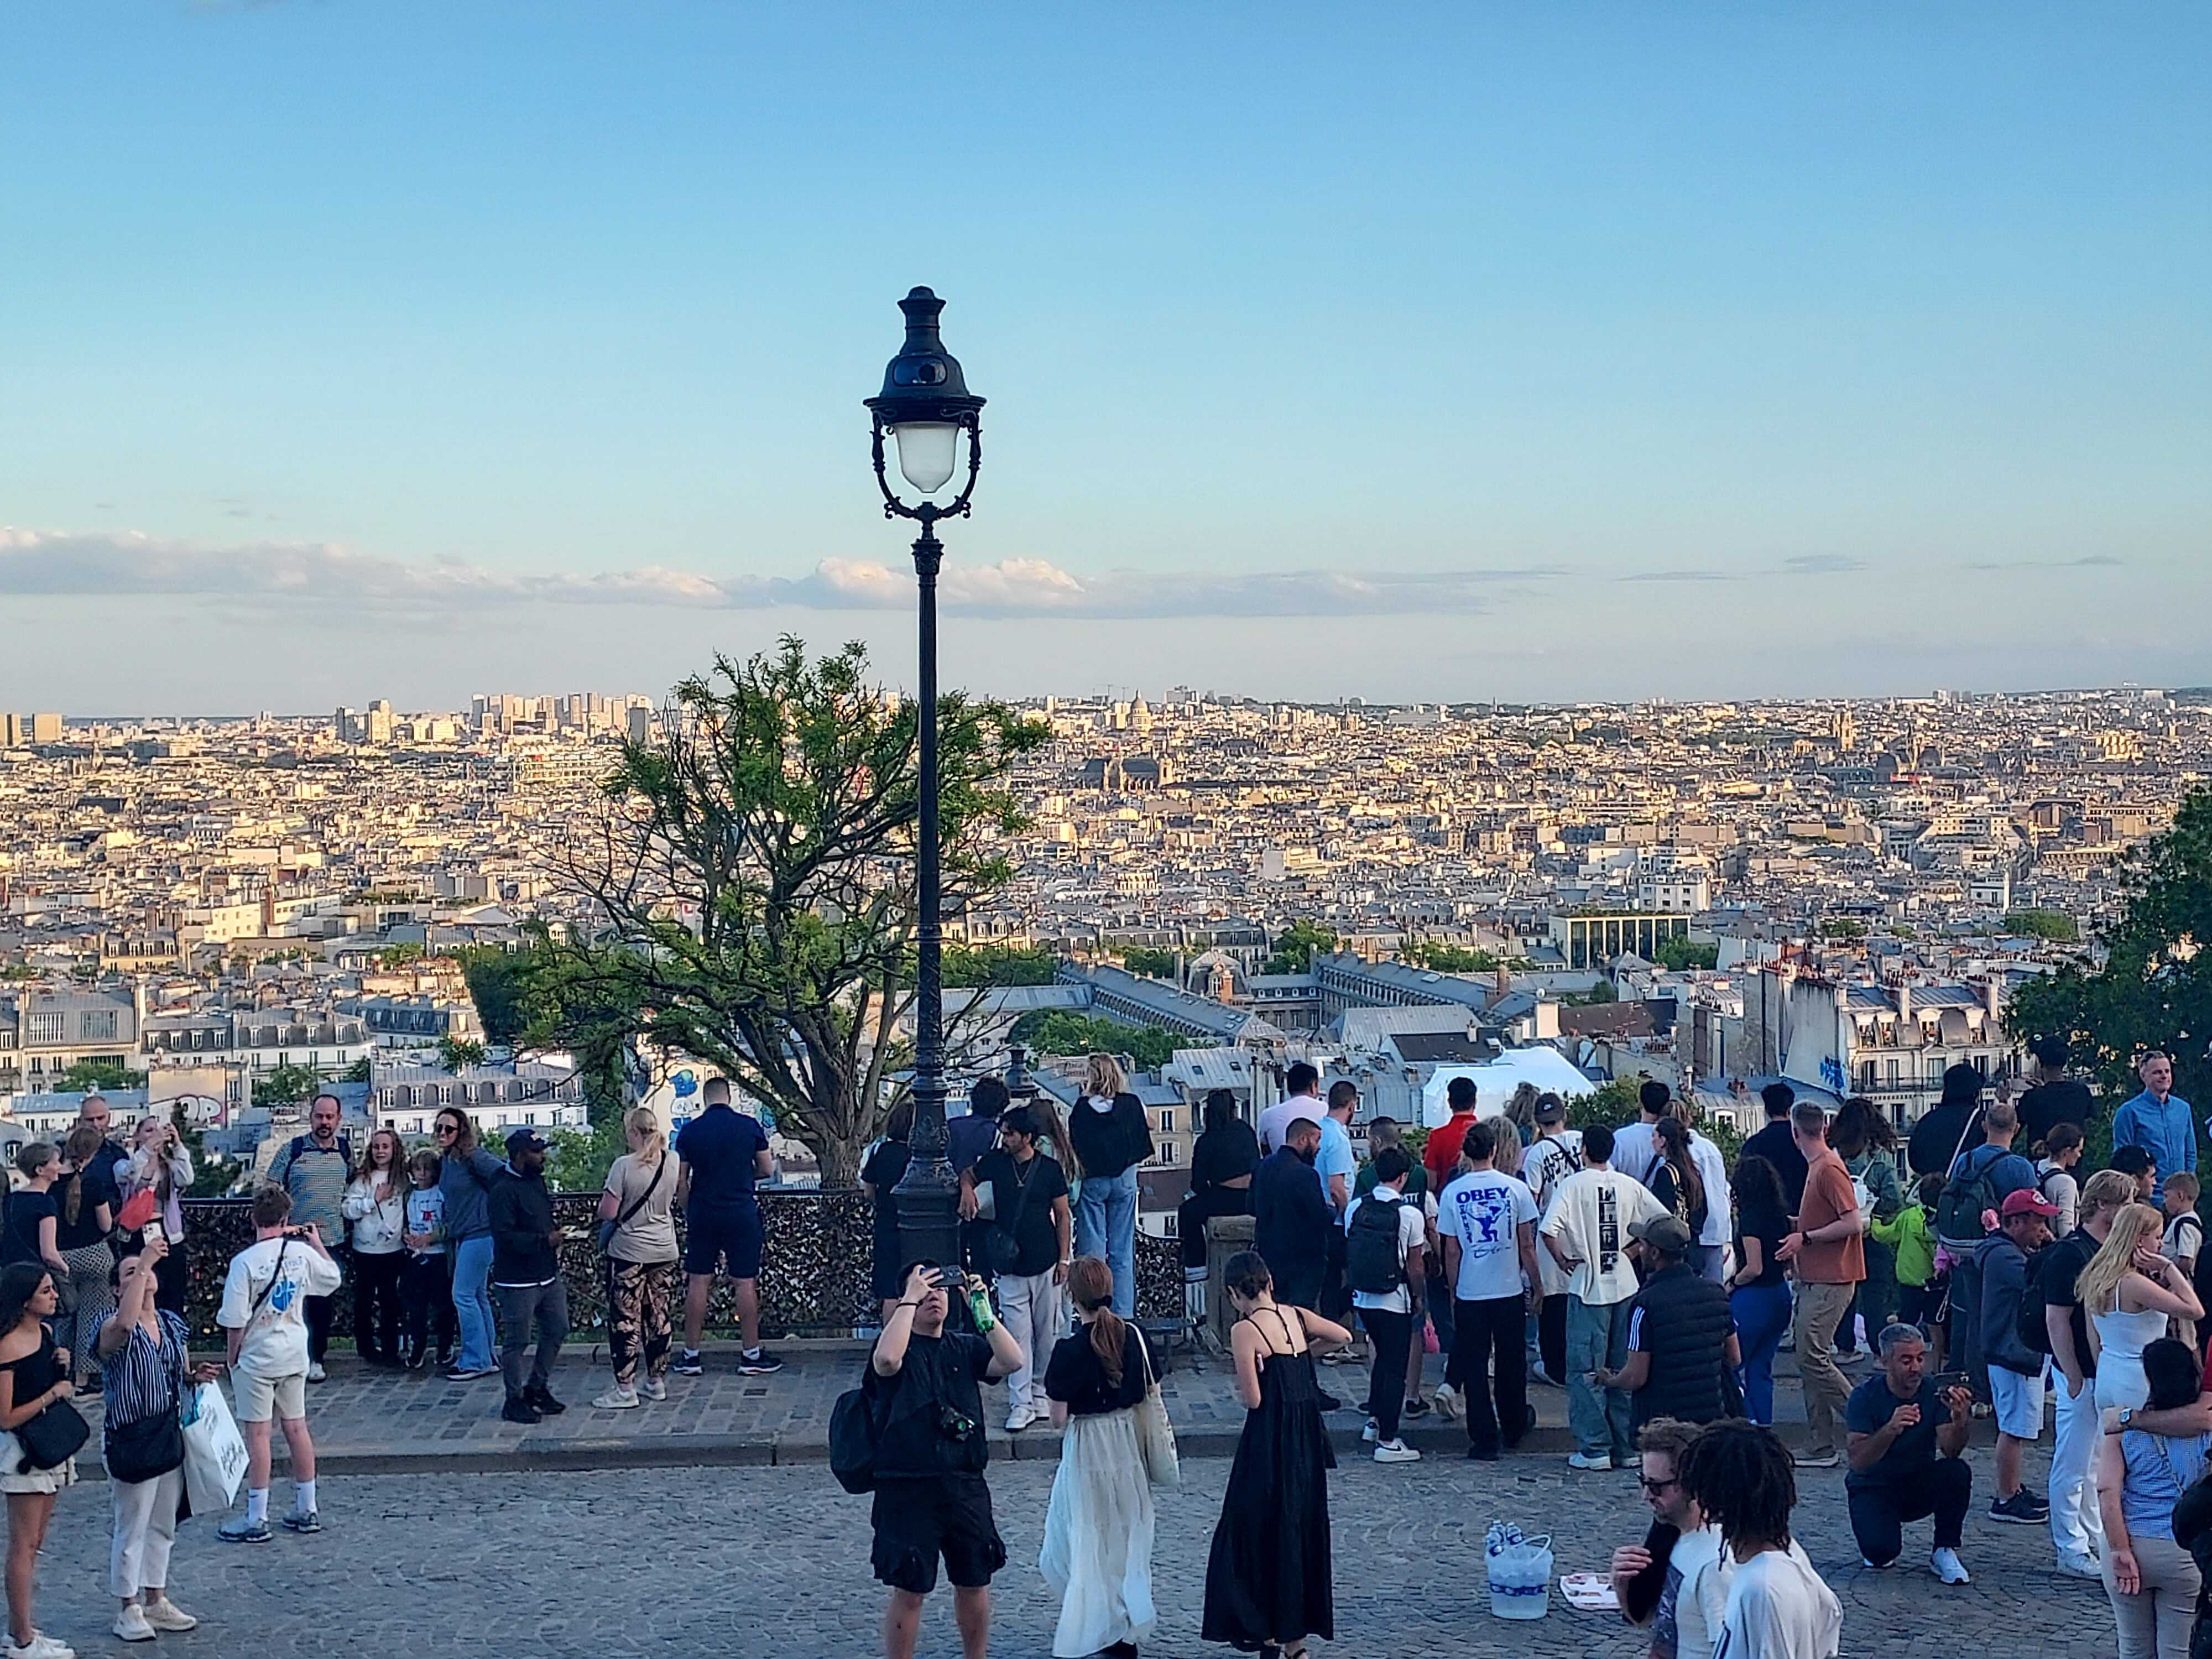
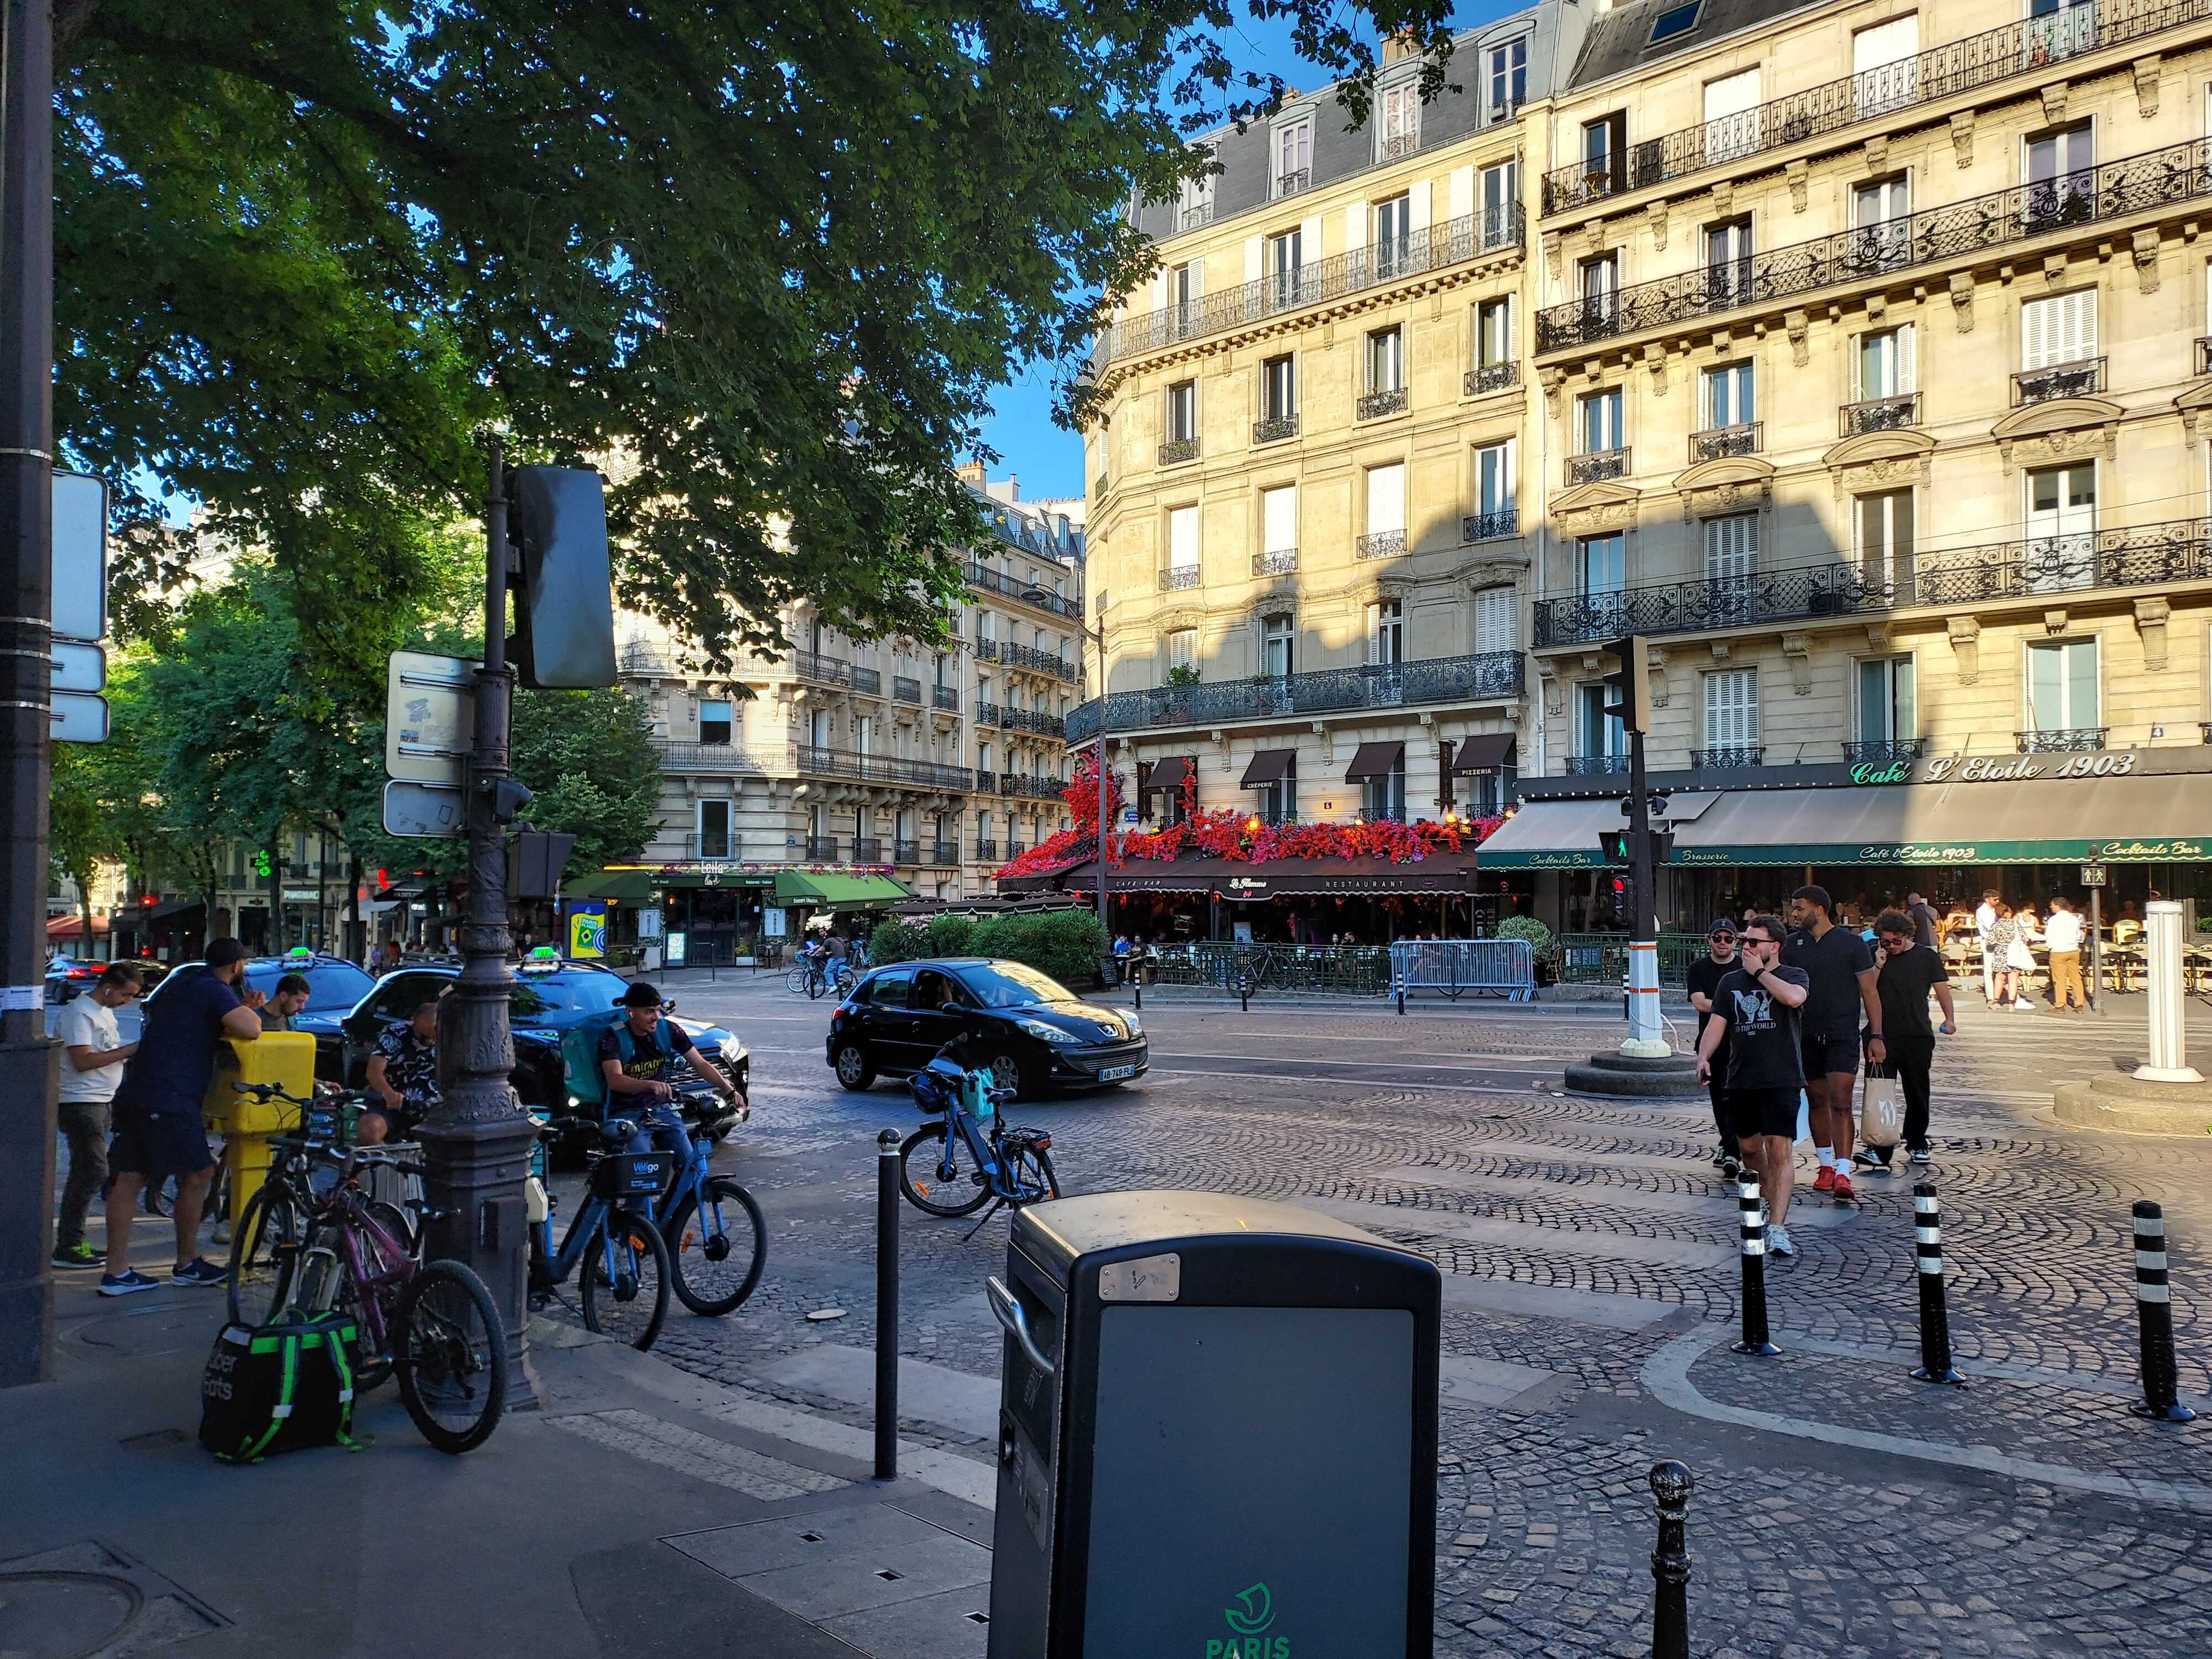
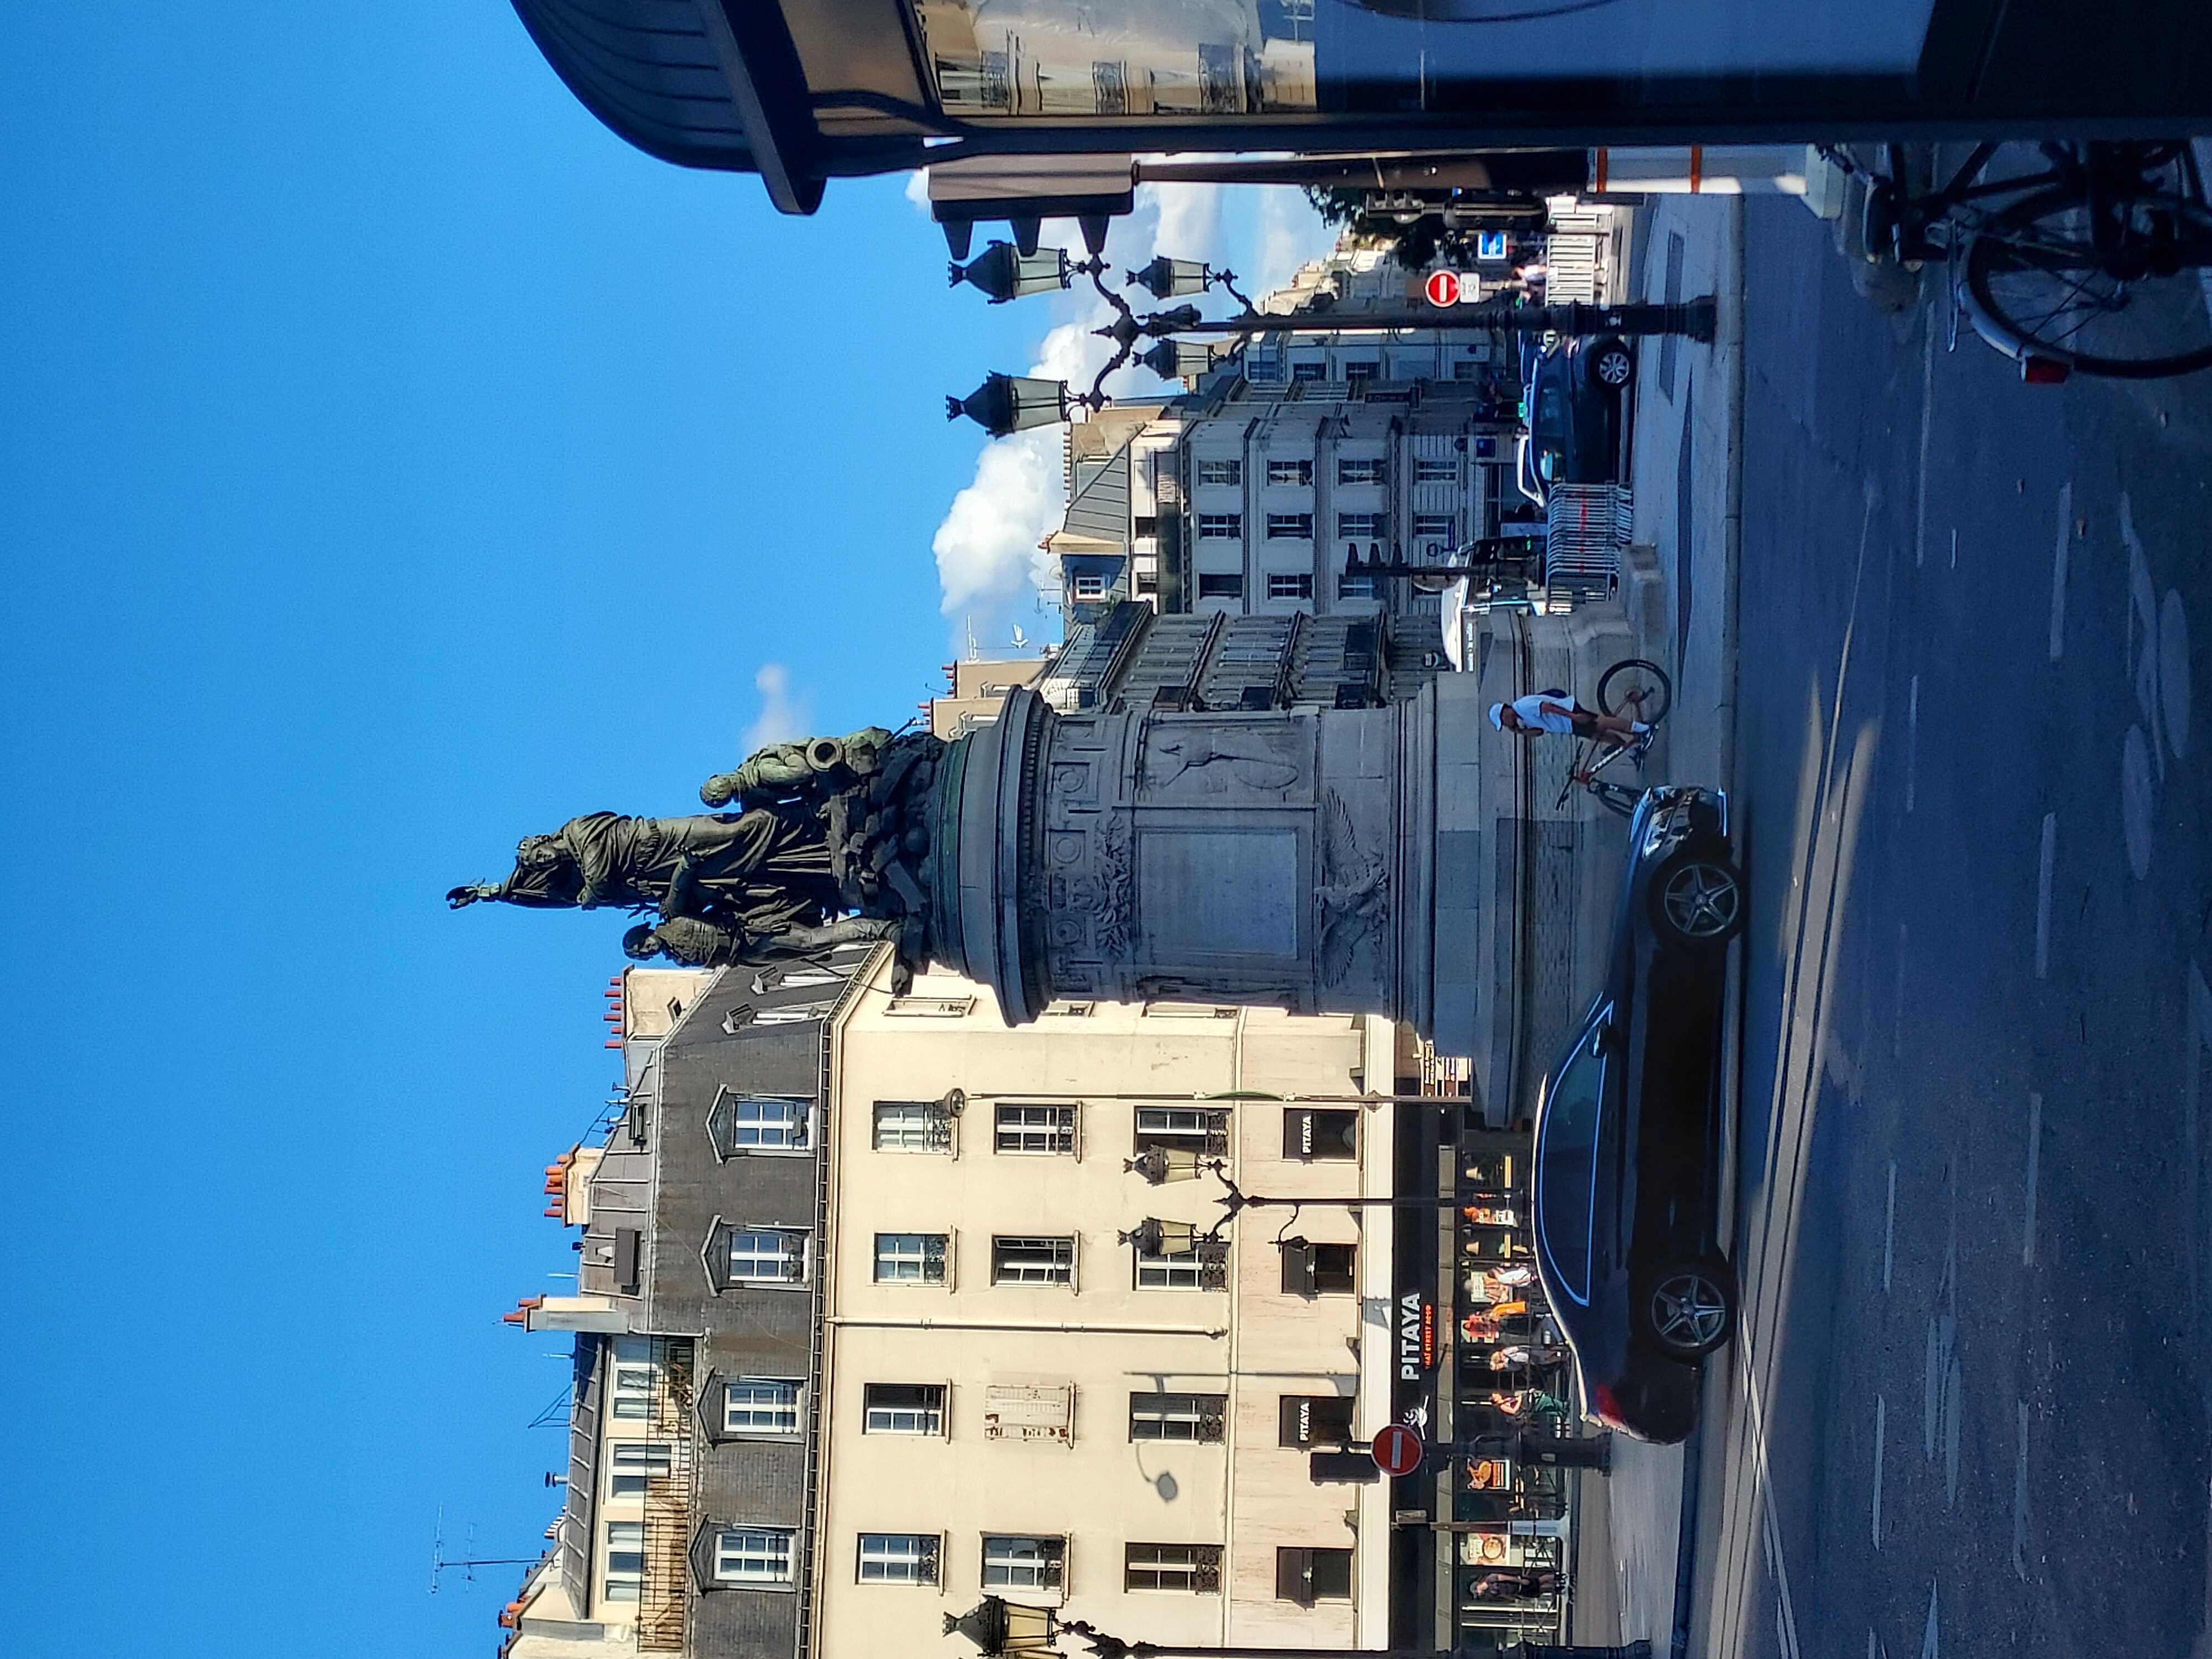
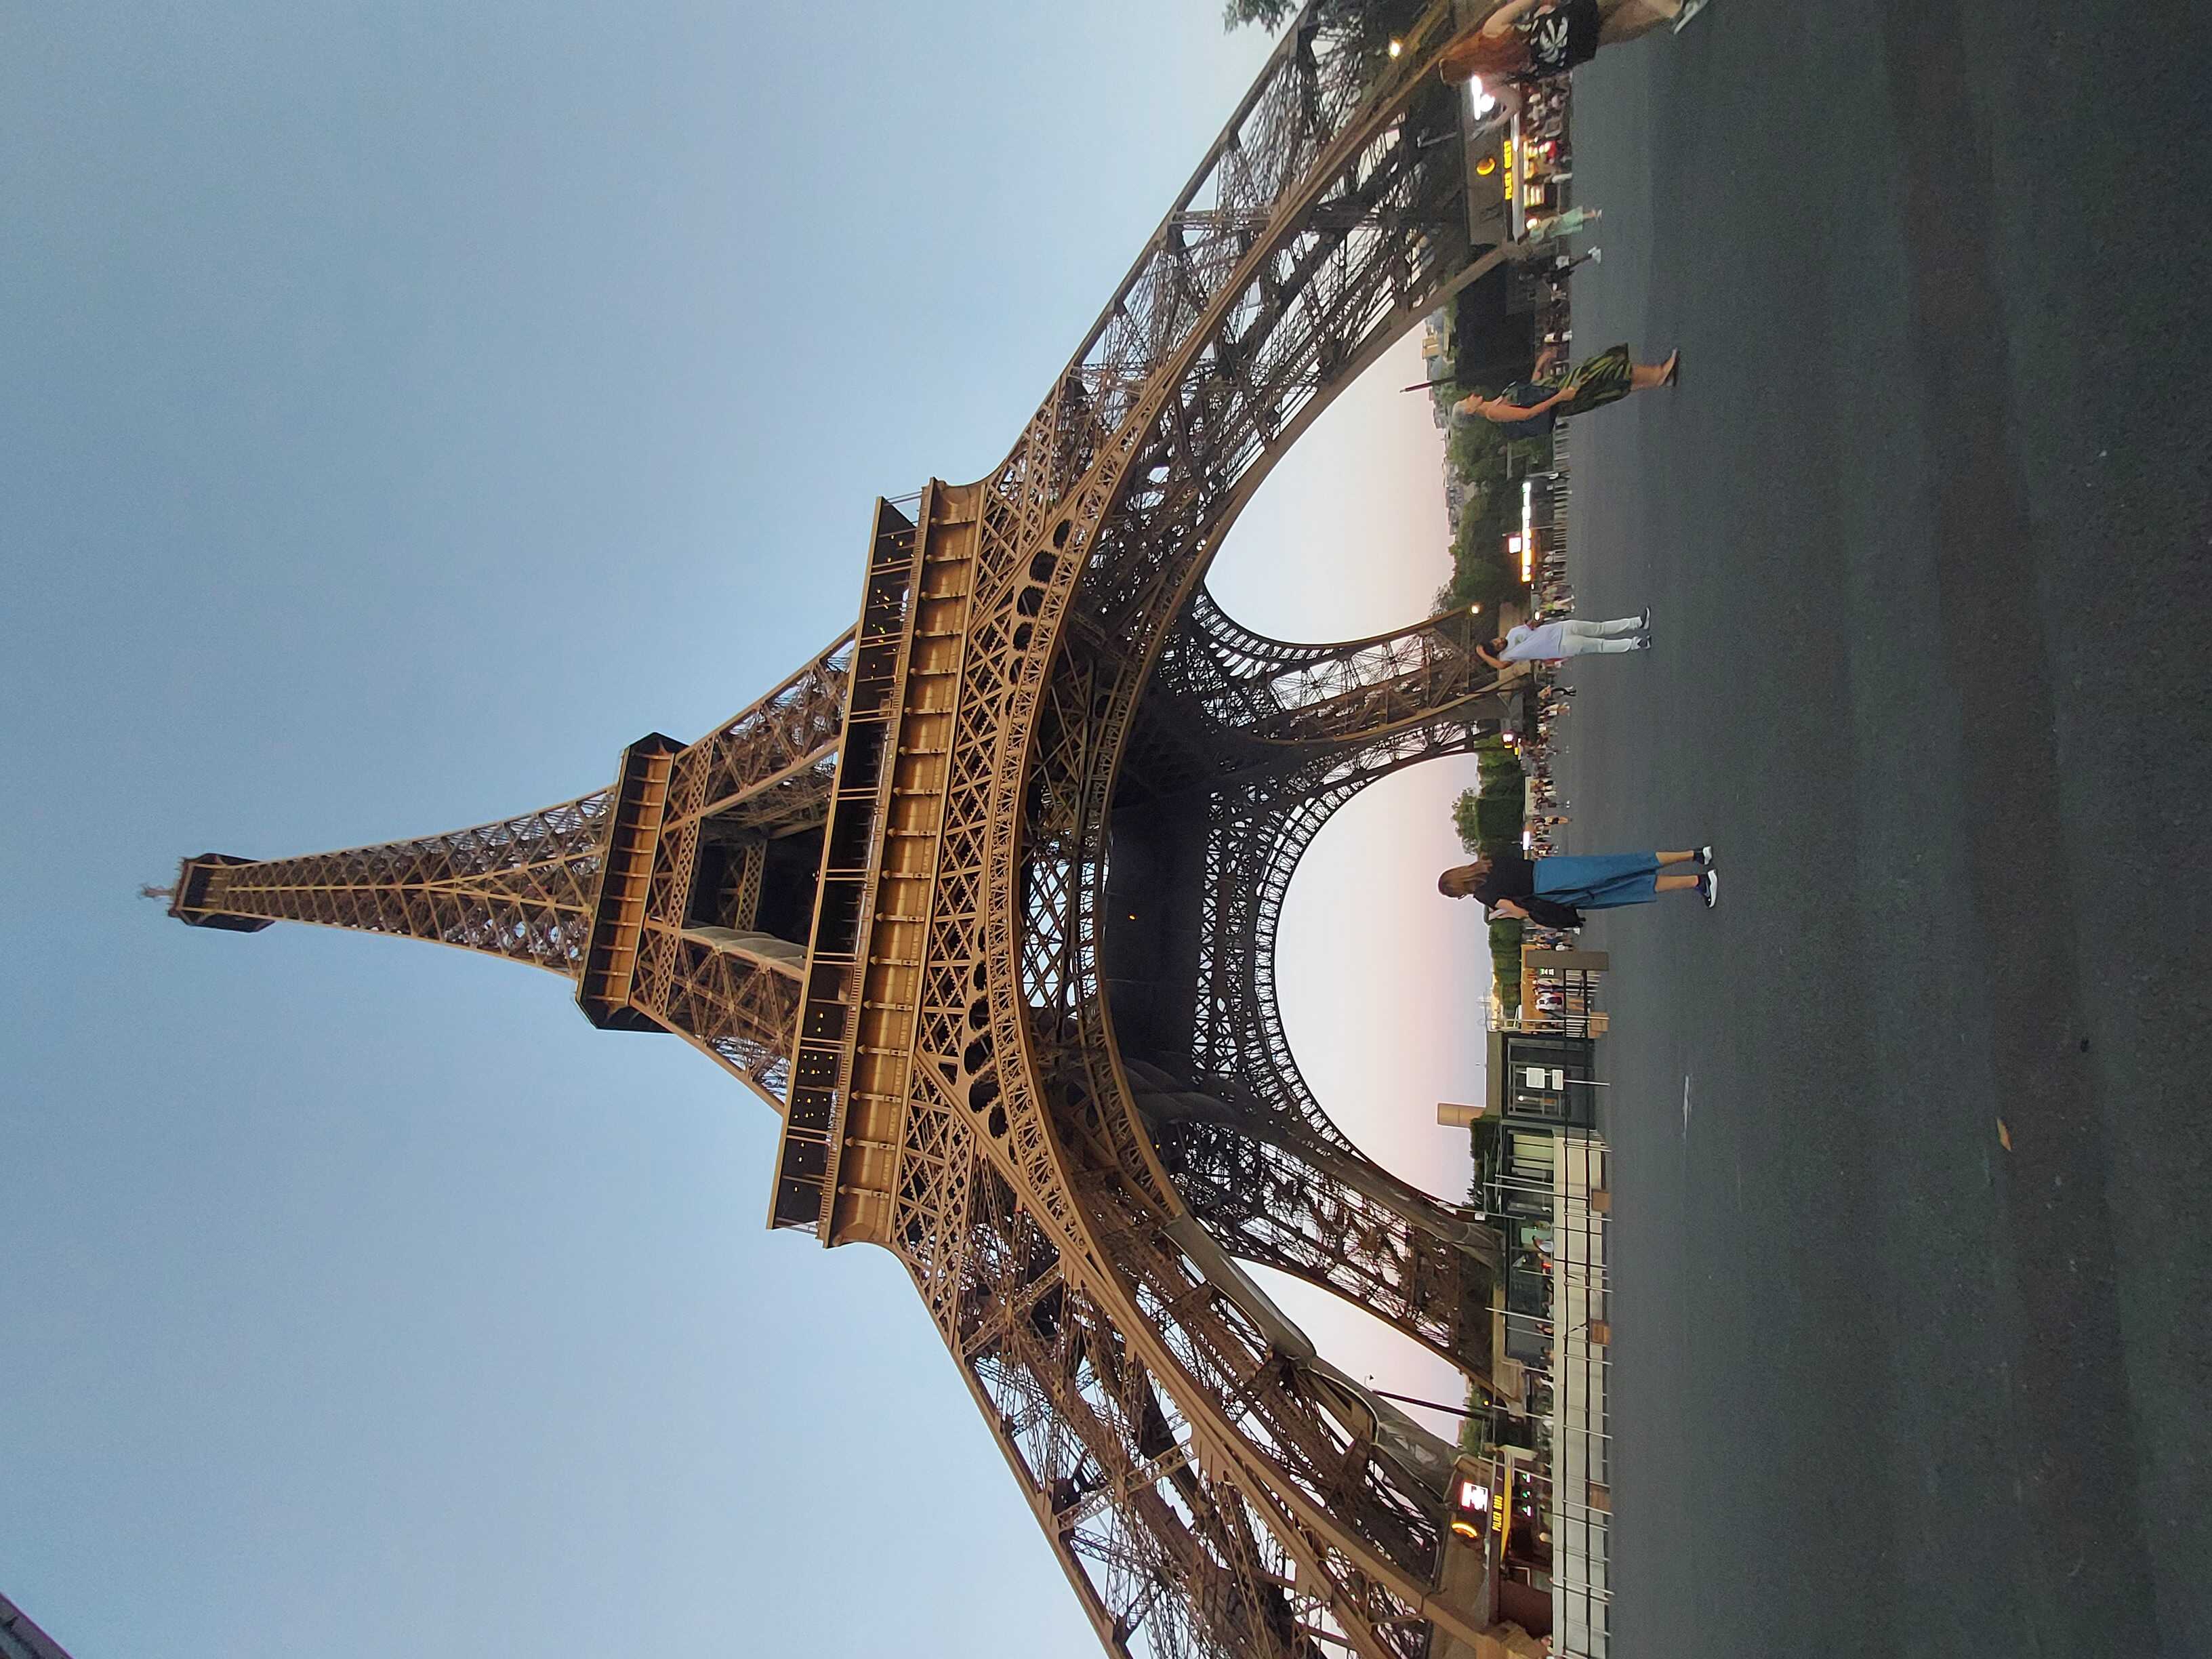
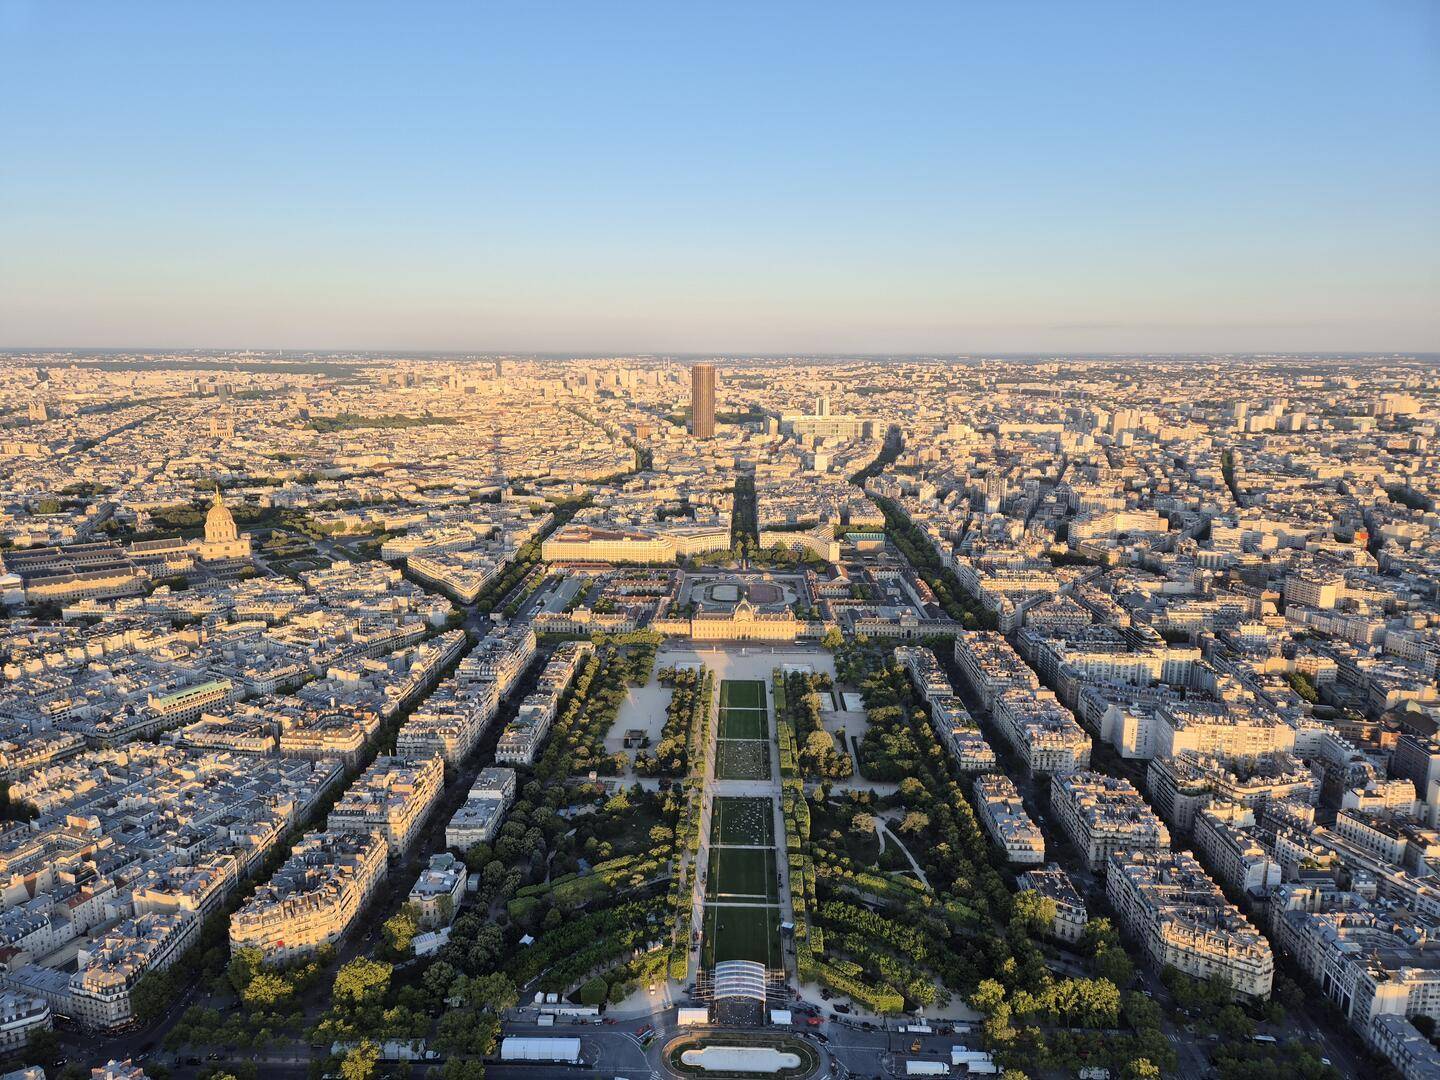



 My trip to pgday.at started Wednesday at the airport in D sseldorf. I was there on time, and the plane started with an estimated flight time of about 90 minutes. About half an hour into the flight, the captain announced that we would be landing in 30 minutes - in D sseldorf, because of some unspecified technical problems. Three hours after the original departure time, the plane made another attempt, and we made it to Vienna.
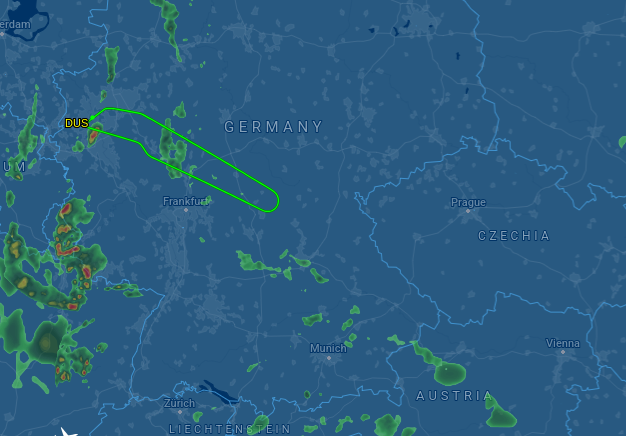
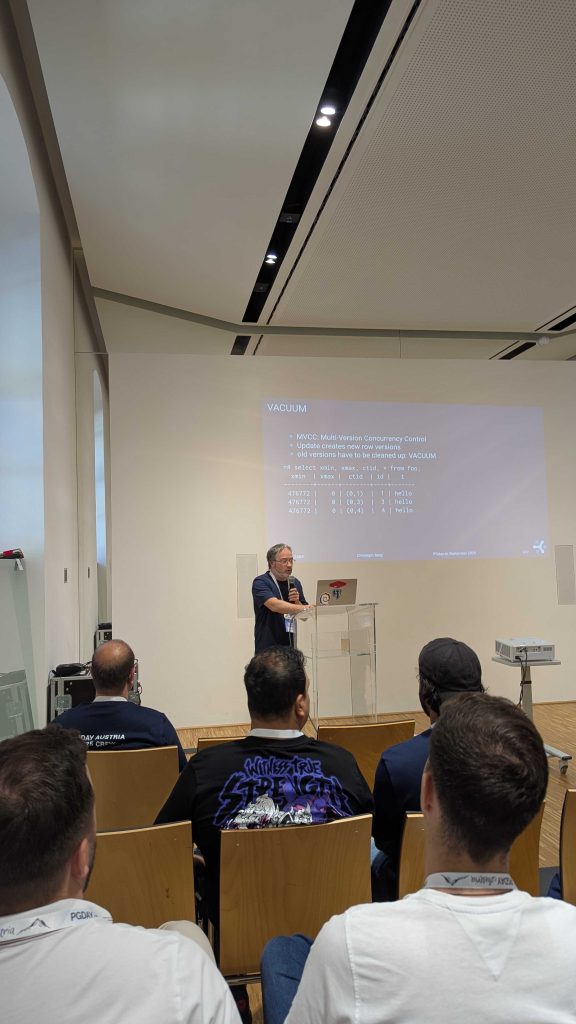
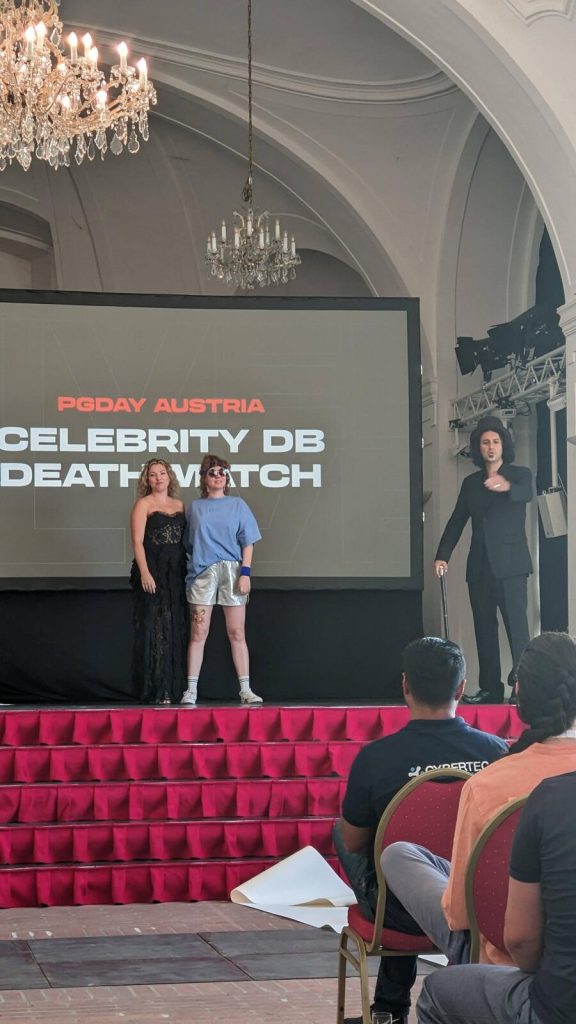
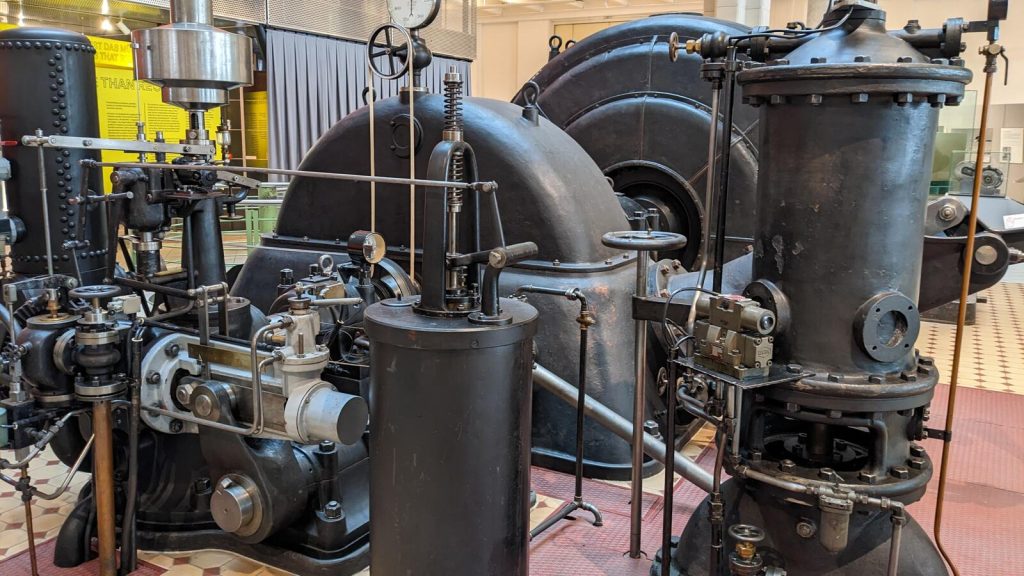






 Another short status update of what happened on my side last
month. Larger blocks besides the Phosh 0.47 release are on screen
keyboard and cell broadcast improvements, work on separate volume
streams, the switch of phoc to wlroots 0.19.0 and effort to make
Phosh work on Debian's upcoming stable release (Trixie) out of the
box. Trixie will ship with Phosh 0.46, if you want to try out 0.47
you can fetch it from Debian's experimental suite.
See below for details on the above and more: