Linux cgroups has been used for a while to group processes and control their access to certain system resources. One of those resources is memory, through the use of memcg. That control is dynamic, allowing for cgroups to setup a minimal and a maximal amount of memory, as well as low and high thresholds, which will control the reclaim process.
But what about device memory that is not available as system RAM? Memory that is not available to the Linux page allocator? One of those device memories is GPU VRAM.
That's where the dmem cgroup controller comes in. Introduced in Linux 6.14, it was first adopted by the Intel Xe driver. In Linux 6.15, AMD amdgpu driver also adopted it. In 7.3, it was adopted by nouveau.
Such a cgroup controller allows the system to be configured such that a workload, be it a browser, a game, or another GPU rendering process can have some minimal VRAM available. Or it can prevent one of these processes from using all VRAM, preventing your compositor from using it, for example.
Let's go through the system knobs that are available to control this and what's new in Linux 7.3.
dmem regions and dmem.capacity
Since a given system might have multiple GPUs, there might be multiple device memory regions. So, on dmem, each such region is described by a name. Every dmem cgroup setting file will contain one line per region. One of those files shows the capacity of each region in bytes and is present only in the root cgroup.
After enabling the dmem cgroup with the following command:
That shows that the GPU at PCI address 0000:03:00.0 has a 8176MiB VRAM dmem region.
dmem settings
When introduced at 6.14, the following settings were available.
dmem.current
In every dmem cgroup, including the root cgroup, the dmem.current is a read-only file that shows the current usage of each region by the given cgroup.
Here, we can check that total system usage is above 311 MB.
dmem.max
Excluding the root cgroup, dmem cgroups can control the maximal number of bytes that can be allocated from a region by processes in that cgroup. If an allocation moves the usage above the max setting, it will be refused. In that case, the allocation might be attempted at system memory or it might trigger eviction, depending on the allocation parameters and the driver.
Here, the max value has special meaning, which is unrestricted usage.
dmem.min
dmem.min, also not available on the root cgroup, will control the eviction process - when memory needs to be moved out of VRAM to make room for other VRAM allocations. If an object belongs to a cgroup which is using less than its min setting, it will not be considered for eviction. It effectively works as a hard protection such that the cgroup can use at least the minimal setting.
Given multiple cgroups may set a minimal value that exceeds the device memory capacity, it computes an effective minimal depending on the hierarchy.
dmem.low
While dmem.min works as a hard limit, dmem.low is a soft limit that will prevent eviction in case other objects from different cgroups are available for eviction. That is, the system will try to evict from different, possibly unprotected cgroups, before it tries to evict from a cgroup if evicting would leave its usage below the value set as dmem.low.
Recent developments in Linux 7.3
Some new changes have been recently introduced in the dmem cgroup controller and its integration with GPUs.
One of those is a new read-only file, dmem.peak, which was introduced to allow the peak usage of a region in a cgroup to be inspected.
Also, Linux 7.3 fixed certain scenarios where a given cgroup would not be able to allocate VRAM up to its minimal or low limits if other processes had already allocated most of VRAM, even though they had no such limits set.
Changing multiple regions' settings in a single write was possible before 7.3, but it was prone to failures which would not be reported to userspace and might have left the values partially updated. Starting with 7.3, only one region may be updated per write.
And, finally, prior to 7.3, setting dmem.max in a cgroup that was using more than the new setting would silently fail. Now, there is a mechanism that allows a reclaim mechanism to be triggered. That way, when a process writes to dmem.max and sets a maximal value below the current usage, it will wait (unless O_NONBLOCK is used) for the reclaim process to move objects out of VRAM until the usage gets below the maximal value. If that is not possible for some reason, the setting will still be in place, restricting further alloctions by that cgroup.
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1370 other packages on CRAN, downloaded 49.4 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 735 times according
to Google Scholar.
This versions updates to the 15.6.2 upstream Armadillo release made
yesterday. It, along with 15.6.1 release we incorporated earlier,
addresses only minor issues and should not present any user-facing
changes. As usual, we did run full reverse-depdency checks against the
over 1300 ackages, and did not find anything. As usual, we aim to
accommodate the desired CRAN
cadences for uploads and try not to exceed six in six months so we did
not ship 15.6.1-1 there. The package has also already been updated for
Debian, built for r2u and r-universe, and
will build shortly at CRAN for
the different binary releases.
All changes since the last CRAN release follow.
Changes in
RcppArmadillo version 15.6.2-1 (2026-10-16)
Upgraded to Armadillo release 15.6.2 (Medium Roast Cortado)
Faster inplace addition of eye() expressions
Changes
in RcppArmadillo version 15.6.1-1 [github-only] (2026-10-02)
Upgraded to Armadillo release 15.6.1 (Medium Roast Cortado)
Fix for failures in pinv() when using the (non-default)
"std" method
Epic just announced the upcoming version 2 of their Linux implementation of Easy Anti-Cheat. It s based on using the Linux eBPF security module to monitor what s happening, and then a bunch of extra infrastructure to make sure this can t be bypassed. The core part of this is requiring secure boot be enabled (ensuring that modified kernels can t be used), using measured boot to verify that secure boot is enabled and which keys are used (to prevent you from just signing your own modified kernel), and then doing remote attestation, a mechanism where the TPM generates a signed copy of the boot measurements and passes that off to a server which verifies it came from a real TPM, verifies that you have secure boot enabled and are using the right keys, and presumably then allows you into the game.
This is all fine as long as you can prove that the measurements provided are real, and that s actually a lot harder than you might think. First, we can simply make up our own quote signed with our own key and say that it came from a TPM. This is avoided by every TPM having an Endorsement Key (or EK) and an associated certificate, with that certificate being signed by the TPM vendor. If you have a list of all the legitimate TPM vendors and their CA keys, you can verify that the measurements came from a real TPM. Easy enough. So we need to get the measurements from a real TPM, and the one on our motherboard contains the measurements that were generated by the firmware and bootloader, and we can t reset those at runtime without resetting the TPM, which oh huh there s actually nothing stopping us from doing that at runtime, as long as we have access to the hardware. Many desktop boards have the TPM on a small plugin module with a standard pinout that includes a reset pin. Simply short that to ground briefly and the TPM is back in its initial state, and userland can write whatever measurements it wants to it. Boot a modified kernel which lies to the eBPF code? As long as you replay the expected log values from a boot with secure boot on and a trusted kernel, the TPM will still happily provide a legitimate set of measurements that ll satisfy the checker.
What if the TPM is less accessible, either because it s mounted directly to the motherboard or it s inside the CPU or chipset? That s going to be trickier. But here s the thing. The quote needs to come from a TPM, but not necessarily the TPM on your motherboard. TPMs these days are usually connected via the Serial Peripheral Interface, usually referred to as SPI. Microchip make a USB to SPI bridge, and there s a Linux driver. Wire one of those up with an appropriate header and you can plug in an easily available TPM module intended for plugging into a motherboard, and now we tell the kernel to ignore the motherboard TPM and make /dev/tpmrm0 point at the USB one and program it with a set of trusted measurements and once again everything is going to look just fine (yes obviously the eBPF code can look for this, but we re running a modified kernel so we can just lie to the eBPF code).
Remote attestation on PCs just doesn t work that well in environments where you can t associate a specific TPM with a specific system, which is basically everywhere except enterprises. But maybe that doesn t matter and cheaters wouldn t be willing to spend the $20 or so it d take to produce one of these things? That would seem somewhat surprising, but it s not impossible. And obviously any server-side cheat detection that triggers could then block that specific TPM, meaning they d need to go and get another TPM, and maybe that ends up being enough to discourage people from bothering. From a practical level, this may be sufficient. But at a technical level? It s not great.
Welcome to the September 2026 report from the Reproducible Builds project!
In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not.
As ever, if you are interested in contributing to the project, please visit our Contribute page on our website.
In this month s report, we cover:
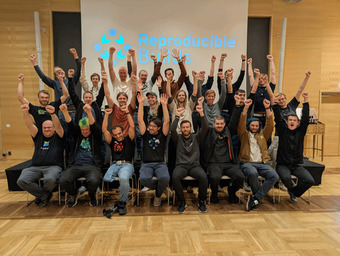
Reproducible Builds Summit 2026 held in Gothenburg, Sweden
The annual Reproducible Builds summit took place from 22 to 24 September 2026 in Gothenburg, Sweden. The event brought together developers, distribution maintainers, security researchers and free software advocates from across the ecosystem to share updates on current initiatives, address outstanding toolchain bottlenecks and strengthen cross-project collaboration.
Participants engaged in a series of working sessions and technical roundtables focused on expanding the practical scope of reproducibility. Discussions covered ongoing work within major Linux distributions, language-specific package ecosystems and the various parts of the binary verification infrastructure.
Strategic planning formed a pillar of the gathering, with participants discussing long-term roadmap goals for supply-chain security, software integrity and related topics. Attendees explored new methods for automated verification, discussing how to lower the adoption barriers for maintainers and streamline the integration of deterministic build pipelines into established continuous integration (CI) systems. The event was then followed by two days of unmoderated hacking sessions. These hacking sessions provided space for technical progress, allowing attendees to draft specification updates, prototype new tool features and resolve standing reproducibility bugs in-person.
Dettrace expanding architecture support for PGO & Lisp dumps
Bernhard M. Wiedemann announced major updates to dettrace, porting the tool across most architectures supported by Debian and openSUSE. The release addresses key stability issues, passing test suites across these targets and making it ready for production build pipelines.
These improvements enable deterministic builds when utilising Profile-Guided Optimisations (PGO), removing the need to sacrifice runtime performance for reproducibility. Additionally, dettrace can now be applied to (notoriously difficult-to-reproduce) Lisp and Scheme memory dumps, including environments such as CLISP, SBCL, Scheme 48, Racket and GNU Emacs.
Trusted Execution Environments (TEEs) have become a cornerstone of modern cloud computing, providing strong confidentiality and integrity guarantees for both code and data. A critical component of this trust model is remote attestation, which enables external entities to verify the authenticity and integrity of code executing within a TEE through cryptographic measurements. However, the effectiveness of remote attestation fundamentally depends on the verifier s ability to trace the reported measurement back to the original source code - a property that can only be guaranteed through reproducible builds. []
SOURCE_DATE_EPOCH specification updates
Bernhard M. Wiedemann shared a number of proposals regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes have been submitted as merge requests on Salsa.
Bernhard s proposed modifications are independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests by 1 December 2026. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list.
The specification was first published in 2015 and updated in 2017.
Reproducible Builds at SeaGL 2026
Reproducible Builds will be present at SeaGL in Seattle, WA, on October 23rd & 24th. Come chat with us in person!
Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture.
New Code of Conduct (CoC) for the Reproducible Builds project
Mattia Rizzolo announced the official launch of a Code of Conduct for the Reproducible Builds project. This follows work and community discussions originally initiated in 2024, incorporating feedback gathered over email and during project summits, as well as with input from the Software Freedom Conservancy.
The new Code of Conduct establishes guidelines emphasising mutual respect among project contributors. It also defines a formalised process for submitting and handling complaints regarding community misconduct, ensuring transparent governance across project spaces. Along with the core policy document, an accompanying Code of Conduct FAQ has been published to outline the rationale behind adopting the guidelines.
Supporter Spotlight: Jochen Sprickerhof
As a reminder, another supporter spotlight interview was published featuring long-time Debian and Reproducible Builds contributor Jochen Sprickerhof, highlighting his work on package verification and project infrastructure.
Jonathan Starr from the Institute of Open Science Practices (IOSP) posted with an announcement of its upcoming 2026 workshop series in Leiden in the Netherlands. This free-to-attend event aims to build a participant-owned data storage consortium, allowing community members to publish datasets, code and knowledge objects alongside algorithms designed to evaluate trust and value. The event features a dedicated Community Track for talks and discussions, a tool showcase and an opening session on resilient data storage.
Following up on IRC discussions regarding profile-guided optimization (PGO) on build servers, kpcyrd created a demonstration repository showing how PGO profiling can introduce non-determinism into output binaries. The demo highlights how runtime randomness (specifically, the randomised keys used in HashMaps to prevent denial-of-service attacks) causes varying bucket collision rates during test runs. These structural variances alter execution weights on underlying code branches, prompting the compiler to generate differing final assembly output for builds that would otherwise be perfectly reproducible if PGO was disabled. Rather than abandoning PGO performance gains, kpcyrd suggested treating generated profiling data as a documented build input or recorded environment artifact (similar to .buildinfo files), rather than regenerating profiles dynamically on the fly during build execution.
Tool and documentation development
diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 330, 331 and 332 to Debian. In particular, Chris committed support for radare2 versions greater than 5.9.0 [] based on input from Guillaume Girol [], and committed support for .nar files via Guix. [][].
Chris later modified diffoscope to not Build-Depend on the Debian package of GNU Guix, as its status in the Debian bug tracking system would transitively render diffoscope as being overly buggy for the next stable release []. Similarly, he adjusted the Build-Depends on the apksigcopier package as it has been removed from Debian testing [] and, finally, he updated a number of copyright years [][].
Vagrant Cascadian updated diffoscope in GNU Guix to version 332.
reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.33 was uploaded to Debian by Holger Levsen with the following changes:
Sergei Tachenov fixed the fileordering test on all filesystems, including the likes of ZFS, which could return a different order across two builds due to build being done in a different directory [].
Holger Levsen bumped the Standards-Version to 4.7.4, reflected that Priority: optional is the default now [], fixed the old Free Software Foundation address [] and bumped the debhelper compat level to 14 after confirming there are only desired changes [].
rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. This month, Bernhard M. Wiedemann submitted a pull request to rebuilderd that refactors RPM repository metadata handling. The change extracts rpm-md parsing out of the Fedora-specific scheduler module and into a shared one.
Lastly, there were a number of improvements made to our website this month as well. For example:
Chris Lamb:
Added a note re. TZ=UTC vs. TZ=UTC0 to the Timezones page. [][][]
Patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
Vagrant Cascadian also performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included molttemplate, buddy, xfonts-nexus, fte and lifelines.
At the time of this writing, that leaves 130 submitted patches, with only 61 outstanding submitted patches that older than a year in the Debian bug tracking system. This number is only 26 if we exclude any low-priority build path issues.
If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:
Review: Ties That Bond in Gretna Green, by Linzi Day
Series:
Midlife Recorder #3
Publisher:
Linzi Day
Copyright:
February 2023
ISBN:
9798376517017
Format:
Kindle
Pages:
616
Ties That Bond in Gretna Green is a self-published fantasy novel
and the third book in the Midlife Recorder series. As with the previous
book, it picks up almost immediately after Painting the Blues in Gretna Green. Day calls the genre
paranormal women's fantasy, and that sounds about right to me.
There is an intervening short story that you can get by
joining Day's mailing list (along
with an epilogue to the first book and to this book). I don't think it's
that important, but there are frequent references to it at the start of
this novel that become somewhat annoying if you haven't read it.
Valentine's Day is fast approaching. This the busiest day of the year for
the part of the Recorder's job that Niki already knew how to do: marrying
people. She performed marriage ceremonies in her previous job before her
inheritance, and she loved that work despite her awful boss. Performing
marriages in the Gateway sounds even more rewarding, but the sheer number
of couples and the political complications from the first two books create
logistical problems she has to solve first.
Also, the remaining member of her staff held over from her grandmother's
time has returned from vacation to discover that Niki has upended most of
what she thought she knew about the job. Time for Niki to apply what she
learned from the change management training her old boss forced her to
attend and then ignored! (If you just groaned, rest assured that Day
somehow makes this work, although she clearly has a higher opinion of
corporate training than I do.)
This plot was more to my taste than Painting the Blues, mostly
because Niki seemed on top of the problems and didn't postpone looking at
them for half the book. There is more of the management competence porn
that readers have come to expect of the series, a few more revelations
about Niki's magic, more mysterious manifestations and the first mention
of a prophecy, and a few political developments. As always, the pacing is
exceptional. These books grab me and pull me along, page after page, often
robbing me of sleep because I find them nearly impossible to put down.
Ties that Bond (and to some extent the last book) looked like it
was going to introduce a romantic subplot, and I was preparing to be
annoyed by it because I did not like the man in the subplot at all. I
won't spoil how it works out in this book, but I will say that Niki
surprised me and showed more sense than I thought the author was
telegraphing. This is not the first time that Day has surprised me with
what I thought was foreshadowing that did not turn out how I expected,
usually for the better. If she can keep that up, it's a nice effect (if a
bit unbalancing) and adds to my desire to read just one more chapter.
The way the world-building of these books is structured continues to
intrigue me. Day gets away with some problems that I think would be more
noticeable in other books thanks to the excellent pacing (no time to ponder
the world-building, we're on to the next crisis!) and the tight
third-person perspective. Niki is not a detail person, to say the least,
but she does keep returning to bits of world-building and poking at them a
bit harder, which gives Day repeated opportunities to shore up ideas that
felt shaky and dubious at first glance. Still, this is not a book that
prizes deep logical consistency or full exploration of the ramifications
of a bit of magic. You have to be willing to go along with the ride and
not think too hard.
For example, Niki can see bonds between couples and judge their strength.
This is apparently a long-standing power of the Recorder's line (she was
able to do that before she became the Recorder), and part of her
responsibility in these weddings is to check the bonds of the couples.
This leads to some well-handled scenes where she diagnoses a problem or
resolves a conflict because she can magically see the true relationship
structure.
Everyone in the book just takes this power in stride. This is wild to me!
This ability would completely upend half of society if you fully worked
out its ramifications and could find people other than Niki with the same
ability. Even if one assumes that a bond only forms over time and can't be
sensed in the early stages of a relationship (something the book never
establishes), can you imagine the implications of having an infallible
oracle that says at a glance whether a marriage will work (permanently,
the book strongly implies)? The implications for how to structure
marriage, for family planning, for psychology and psychiatry, for how to
structure dating, even for living arrangements and housing markets? This
is not a small world-building detail, and yet it's treated more like part
of Niki's characterization than like a foundation of society.
I think some of this all-vibes world-building may come from the general
new-age feel to how magic works. Day makes a grab-bag of random magic
canonical in this world: psychic lie detecting abilities, auras, chakras,
premonitions, and other bits of the sort of spiritualism that tends to be
heavily marketed to middle-class women. I have that niggling feeling that
one sometimes gets in SF that a lot of this is in the world-building
because the author believes it's partly real (see, for instance, psychic
powers and the Dean drive in 1960s science fiction). If one believes that
psychic powers and various bits of mysticism are true in our world, one
has already developed the rationalization mechanisms to explain away their
almost total lack of influence or impact on how the world is structured.
If one then introduces them into a true fantasy world, one may not notice
how many implications that should have for how society is structured,
since one is used to believing magic exists but has no significant
implications.
I could be entirely wrong about this analysis, and maybe it's a bit unfair
to Day. I should also be clear that this is not a complaint, just a point
of fascination to me when I think back over one of these books after I
finished it. There is a glut of fantasy out there that's constructed like
an engineering problem or that goes deep into politics or social theory,
usually written by people with strong opinions but not a lot of training
in real sociology. One of the joys of self-published books is that you
occasionally get something that assembles genre conventions in a way that
feels odd and delightfully strange. What if, in addition to dimensional
gates and overwhelming protean power invested in a true heir, all the
magic sold by the local Tarot and crystal store was also true? Sure, why
not! If the pacing is good and the story is grabby, it works for me.
It does seem worth attaching a warning for the folks who need scientific
reproducibility and explored implications in their world-building, though.
If you're the sort of reader who is bothered by political boundaries and
economic systems that match our world despite the existence of magic, this
series may cause you problems.
This continues to be a grabby, highly entertaining story of a woman who
finally gets to run her own small business the way that she always thought
the business should be run after years of working for an awful manager,
except that her business is total magical power over an interchange point
between dimensions, she's the chosen one, and the setting is a high
fantasy world with prophecies and gods. If that sounds appealing, don't
start here, but I highly recommend giving Midlife in Gretna Green a try. The series seems to be holding up.
Followed by a short story epilogue available by joining Day's mailing
list, an optional novella (maybe novelette) published in Spilling
the Tea in Gretna Green, and then Seeing Red in Gretna Green.
Rating: 7 out of 10
DebConf site visit, by Stefano Rivera
In preparation for DebConf 27, Stefano Rivera,
Nattie Mayer-Hutchings, and Jongmin Kim from the DebConf Committee visited
Asahikawa Japan. A contingent of the local team gathered to tour the venues
with us, discuss plans, and meet the local organizations assisting the event.
We held a press conference at the city hall that got
some coverage.
A few potential day-trip options were explored.
Photos from the site visit.
autopkgtest-virt-pconr, by Helmut Grohne
Following the creation of the pconr
module that provides a basis for
unschroot
and a more secure containment for mmdebstrap,
an experimental autopkgtest backend autopkgtest-virt-pconr
is now available. It fits a spot between autopkgtest-virt-unshare and more fully
fledged containers as it does not require much infrastructure like setting up
incus or lxc but still provides a containment running an initsystem. Due to the
use of erofs as base image format,
it boots and reverts quickly. This development also required fixing concurrency
issues in asyncvarlink and even shed
light on a matching bug in systemd
that was promptly fixed upstream.
Miscellaneous contributions
Carles reviewed and submitted six Catalan po-debconf translations using
po-debconf-manager.
Improved po-debconf-manager s workflow for updating translations.
Carles reviewed, translated or updated webwml
Catalan translations for security and CD pages. He also fixed issues that
prevented building webwml, deleted orphaned translation pages, etc. and
experimented with a more global HTML tidying up experiment.
Carles refactored check-relations
adding capacity to ignore concrete from_package -> to_package specific relations
and more flexibility around ignores. Detects unused ignore rules as well.
Carles improved some Wiki pages (LibreOffice,
Framework amongst some
other ones)
Thorsten did an hplip upload to replace an expired certificate of HP. This
certificate is used to sign new upstream releases and modules that can be
downloaded later. Afterwards work on a new upstream version started.
Thorsten also struggles with autopkgtest problems of the new upstream version
of cups. Work is still ongoing.
Antonio worked on several topics around Debian CI maintenance, reliability and
performance.
Stefano updated the autopkgtests for cPython packages in Debian to support
setuptools 80.
Stefano uploaded pypy 8.
Stefano helped to get DebConf 26 reimbursement claims processed, and worked on
some of the resulting issues in debian-reimbursements.
Emilio managed various transitions.
Emilio worked on the rustc-web/trixie bootstrap for armel, using the rustc
1.95 version from trixie-backports. This will be needed by the upcoming clamav
security updates.
Helmut sent patches for 11 cross build failures.
Helmut introduced a new build profile to libcap-ng to keep architecture cross
bootstrap working.
Helmut uploaded debvm_0.5.5
introducing support for Hurd thanks to a lot of work by Johannes Schauer Marin
Rodrigues.
Colin upgraded to new security releases of groff and parted.
Colin upgraded 50 Python packages to new upstream versions, and fixed over 40
RC bugs in the Python team.
Santiago continued mentoring Aryan Karamtoth with the GSoC project about
introducing livepatching support for linux. This mentoring is done in
collaboration with Emmanuel Arias. In particular, Santiago explored different
requirements for providing binary modules for the same kernel packages used by
Debian, that require a matching version number.
Anupa joined Jean-Pierre Giraud to prepare the files for point release
announcement for Debian 13.7.
(This is an updated version of an older post - the introduction remains the same, the technical details are different)
Linux draws a distinction between code running in kernel (kernel space) and applications running in userland (user space). This is enforced at the hardware level - in x86-speak1, kernel space code runs in ring 0 and user space code runs in ring 32. If you re running in ring 3 and you attempt to touch memory that s only accessible in ring 0, the hardware will raise a fault. No matter how privileged your ring 3 code, you don t get to touch ring 0.
Kind of. In theory. Traditionally this wasn t well enforced. At the most basic level, since root can load kernel modules, you could just build a kernel module that performed any kernel modifications you wanted and then have root load it. Technically user space code wasn t modifying kernel space code, but the difference was pretty semantic rather than useful. But it got worse - root could also map memory ranges belonging to PCI devices3, and if the device could perform DMA you could just ask the device to overwrite bits of the kernel4. Or root could modify special CPU registers ( Model Specific Registers , or MSRs) that alter CPU behaviour via the /dev/msr interface, and compromise the kernel boundary that way.
It turns out that there were a number of ways root was effectively equivalent to ring 0, and the boundary was more about reliability (ie, a process running as root that ends up misbehaving should still only be able to crash itself rather than taking down the kernel with it) than security. After all, if you were root you could just replace the on-disk kernel with a backdoored one and reboot. Going deeper, you could replace the bootloader with one that automatically injected backdoors into a legitimate kernel image. We didn t have any way to prevent this sort of thing, so attempting to harden the root/kernel boundary wasn t especially interesting.
In 2012 Microsoft started requiring vendors ship systems with UEFI Secure Boot, a firmware feature that allowed5 systems to refuse to boot anything without an appropriate signature. This not only enabled the creation of a system that drew a strong boundary between root and kernel, it arguably required one - what s the point of restricting what the firmware will stick in ring 0 if root can just throw more code in there afterwards? What ended up as the Lockdown Linux Security Module provides the tooling for this, blocking userspace interfaces that can be used to modify the kernel and enforcing that any modules have a trusted signature.
But that comes at something of a cost. Most of the features that Lockdown blocks are fairly niche, so the direct impact of having it enabled is small. Except that it also blocks hibernation6, and it turns out some people were using that. The obvious question is what does hibernation have to do with keeping root out of kernel space , and the answer is a little convoluted and is tied into how Linux implements hibernation. Basically, Linux saves system state into the swap partition and modifies the header to indicate that there s a hibernation image there instead of swap. On the next boot, the kernel sees the header indicating that it s a hibernation image, copies the contents of the swap partition back into RAM, and then jumps back into the old kernel code. What ensures that the hibernation image was actually written out by the kernel? Absolutely nothing, which means a motivated attacker with root access could turn off swap, write a hibernation image to the swap partition themselves, and then reboot. The kernel would happily resume into the attacker s image, giving the attacker control over what gets copied back into kernel space.
This is annoying, because normally when we think about attacks on swap we mitigate it by requiring an encrypted swap partition. But in this case, our attacker is root, and so already has access to the plaintext version of the swap partition. Disk encryption doesn t save us here. We need some way to verify that the hibernation image was written out by the kernel, not by root. And thankfully we have some tools for that.
Trusted Platform Modules (TPMs) are cryptographic coprocessors7 capable of doing things like generating encryption keys and then encrypting things with them. You can ask a TPM to encrypt something with a key that s tied to that specific TPM - the OS has no access to the decryption key, and nor does any other TPM. So we can have the kernel generate an encryption key, encrypt part of the hibernation image with it, and then have the TPM encrypt it. We store the encrypted copy of the key in the hibernation image as well. On resume, the kernel reads the encrypted copy of the key, passes it to the TPM, gets the decrypted copy back and is able to verify the hibernation image.
That s great! Except root can do exactly the same thing. This tells us the hibernation image was generated on this machine, but doesn t tell us that it was done by the kernel. We need some way to be able to differentiate between keys that were generated in kernel and ones that were generated in userland. TPMs have the concept of localities (effectively privilege levels) that would be perfect for this. Userland is only able to access locality 0, so the kernel could simply use locality 1 to encrypt the key. Unfortunately, localities are typically only available on systems that implement a Dynamic Root of Trust Measurement like Intel s TXT, and most consumer systems have no support for this. So, we need another approach.
TPMs have a set of Platform Configuration Registers (PCRs), intended for keeping a record of system state. The OS isn t able to modify the PCRs directly. Instead, the OS provides a cryptographic hash of some material to the TPM. The TPM takes the existing PCR value, appends the new hash to that, and then stores the hash of the combination in the PCR - a process called extension . This means that the new value of the TPM depends not only on the value of the new data, it depends on the previous value of the PCR - and, in turn, that previous value depended on its previous value, and so on. The only way to get to a specific PCR value is to either (a) break the hash algorithm, or (b) perform exactly the same sequence of writes. On system reset the PCRs go back to a known value, and the entire process starts again.
Some PCRs are different. PCR 23, for example, can be reset back to its original value without resetting the system. We can make use of that. The first thing we need to do is to prevent userland from being able to reset or extend PCR 23 itself. All TPM accesses go through the kernel, so this is a simple matter of parsing the write before it s sent to the TPM and returning an error if it s a sensitive command that would touch PCR 23. We now know that any change in PCR 23 s state will be restricted to the kernel.
When we encrypt material with the TPM, we can ask it to record the PCR state. This is given back to us as metadata accompanying the encrypted secret. Along with the metadata is an additional signature created by the TPM, which can be used to prove that the metadata is both legitimate and associated with this specific encrypted data. In our case, that means we know what the value of PCR 23 was when we encrypted the key. That means that if we simply extend PCR 23 with a known value in-kernel before encrypting our key, we can look at the value of PCR 23 in the metadata. If it matches, the key was encrypted by the kernel - userland can create its own key, but it has no way to extend PCR 23 to the appropriate value first. We now know that the key was generated by the kernel.
Unfortunately it turns out that some people actually make use of PCR 23, and
restricting it to the kernel makes them sad. There are other resettable PCRs, but only in non-0 localities, so (a) we can t reset them on most systems and (b) we ll just find someone who uses them anyway and run into the same problem. We need a different approach.
Thankfully TPMs have a small chunk of non-volatile RAM that can be used for storing things, and by storing I mean they can be used in a range of different ways. One of these is effectively as additional PCRs. These values can be configured such that they work the same way as PCRs, with the only way to modify them being to append a new hash to their existing value and update the new value to the hash of that merged value. We can allocate one of these for in-kernel use and reject any access from userspace, and also there are officially allocated ranges (so people shouldn t be using random values) and the namespace is large enough anyway that w eshouldn t collide with anyone, so we can carve one of those out and use it for this purpose.
Unfortunately, though, these NV indexes aren t included in the creation data we get when we create a key, so we need another approach. TPMs have the concept of sessions, a series of commands executed in sequence. A flag allows these sessions to be audited , with the TPM keeping a running track of the hash of the commands executed and the results returned. At the end of the session you can ask for a signed copy of this hash, and if you ve kept a log of all the commands then you can verify that they match that signed hash and know that this log represents a real communication with the TPM. If we read the NV index and generate the key inside the same session, we can verify that the key we re looking at was created while the NV index had a specific value, and if only the kernel can set that value then we know that the key was generated by the kernel.
Or, well, can we? Only new kernels would impose the restriction on modifying that NV index. An attacker could boot an old kernel, generate a key there in userland, sign a hibernation image with it, and then reboot into a new kernel. The new kernel would see a valid signature with a valid NV index associated with it and have no way to know it was generated from userland rather than the kernel. We need to be able to tell the difference between kernels that implement this feature and ones that don t, and we need to do that without being able to go back in time to change old kernel behaviour. We can extend a PCR to indicate we implement the new functionality, but so can an attacker running an old kernel.
The normal approach to determining whether an event occurred in a specific phase of the boot process is to cap the PCRs - extend them with a known value that indicates a transition between stages of the boot process. Any events that occur before the cap event must have occurred in the previous stage of boot, and since the final PCR value depends on the order of measurements and not just the contents of those measurements, if a PCR is capped before userland runs, userland can t fake the same PCR value afterwards. If Linux capped the PCRs before userland started running, we d be able to place a measurement there before the cap occurred and then prove that that extension occurred before userland had the opportunity to interfere. We could simply place a statement that the kernel supported the NV index restrictions there, and we d be fine.
Unfortunately Linux doesn t currently do this, and adding support for doing so doesn t fix the problem - if an attacker boots a kernel that doesn t cap a PCR, they can just cap it themselves from userland. So, we re faced with the same problem: booting an older kernel allows the system to be placed in an identical state to the current kernel, and a fake hibernation image can be written out. Solving this requires a PCR that was being modified after kernel code was running, but before userland was started, even with existing kernels.
Thankfully, there is one! PCR 5 is defined as containing measurements related to boot management configuration and data. One of the measurements it contains is the result of the UEFI ExitBootServices() call. ExitBootServices() is called at the transition from the UEFI boot environment to the running OS, and the kernel contains code that executes before it. So, if we measure an assertion regarding whether or not we support restricted access to NV indexes into PCR 5 before we call ExitBootServices(), this will prevent userspace from spoofing us (because userspace will only be able to extend PCR 5 after the firmware extended PCR 5 in response to ExitBootServices() being called). Obviously this depends on the firmware actually performing the PCR 5 extension when ExitBootServices() is called, but if firmware s out of spec then I don t think there s any real expectation of it being secure enough for any of this to buy you anything anyway.
That s what this patchset does. Review feedback so far seems positive, although James Bottomley suggested a design improvement. My approach of using an NV index as a PCR and generating a signing key made sense as a consequence of my original approach involving PCR 23, which had been to use the key creation data and not use audit sessions at all. But the goal isn t to use a key - it s to prove that hibernation occurred in-kernel, and while signing is one way of doing that, there are others. His suggestion is to simply record the hash of the hibernation image into the NV index and then read that back as part of the audit session. On resume we verify the audit session log is legitimate, read the hibernation image, and compare the hash of the hibernation image against the hash in the log. If it matches, and if the PCR 5 value matches, we know the audit session happened in kernel and that the hibernation image hasn t been modified.
It still seems like we re missing something, though. If we re not storing a key anywhere, how do we verify the audit session? To explain this we re going to need to go into some details about how TPM keys work in the first place. TPMs can produce a special kind of key called an Attestation Key, or AK. Attestation keys are used to sign attestation statements from the TPM, such as PCR quotes or audit logs. We need a separate key type for this in order to prove that the signature was generated as part of an attestation - normal TPM signing keys are fundamentally designed to sign arbitrary material, and so can be used by userland to sign something that looks identical to an attestation record. By being able to distinguish the types of key the TPM uses, we can prove that a signature was generated using an AK, and so know that it s a real TPM attestation (because nothing other than the TPM can sign stuff with an AK).
But even beyond this distinction, TPMs have different key types. Ordinary keys are generated using an RNG and will be unique. Primary keys are generated using a seed that is used as an input into a key derivation function. For a given TPM, using the same seed to generate the same type of primary key will always generate the same primary key8. We can have the kernel deterministically generate an AK during suspend in order to sign the audit log, and then generate the same key again on resume to validate it. This means we don t need any other form of trusted storage for the AK - the TPM already provides that functionality.
This is all rather complicated but I ve been thinking about this for some time now and I haven t come up with a cleaner solution. The only real open issue is the degree to which machines actually perform the PCR 5 extension. If it turns out there s a bunch that don t we ll need to come up with some alternative approach to identifying whether the kernel supports this functionality, but the design is such that that should be invisible to userspace so adding alternatives later shouldn t be an issue. Filtering accesses to the NV index is also not super clean, and depends on there not being alternative mechanisms to get at the TPM by sending raw commands. Again, this is intended to be opaque to userland and can be improved if we come up with something better later on (such as a secure way to pass a secret to the kernel on boot that can be used as an auth value for acess to the NV index).
Anyway. Time to go and fix the next thing.
Other architectures use different terminology here, such as supervisor and user mode, but it s broadly equivalent
In theory rings 1 and 2 would allow you to run drivers with privileges somewhere between full kernel access and userland applications, but in reality we just don t talk about them in polite company
This is how graphics worked in Linux before kernel modesetting turned up. XFree86 would just map your GPU s registers into userland and poke them directly. This was not a huge win for stability
IOMMUs can help you here, by restricting the memory PCI devices can DMA to or from. The kernel then gets to allocate ranges for device buffers and configure the IOMMU such that the device can t DMA to anything else. Except that region of memory may still contain sensitive material such as function pointers, and attacks like this can still cause you problems as a result.
This describes why I m using allowed rather than required here
Saving the system state to disk and powering down the platform entirely - significantly slower than suspending the system while keeping state in RAM, but also resilient against the system losing power.
With some handwaving around coprocessor . TPMs can t be part of the OS or the system firmware, but they don t technically need to be an independent component. Intel have a TPM implementation that runs on the Management Engine, a separate processor built into the motherboard chipset. AMD have one that runs on the Platform Security Processor, a small ARM core built into their CPU. Various ARM implementations run a TPM in Trustzone, a special CPU mode that (in theory) is able to access resources that are entirely blocked off from anything running in the OS, kernel or otherwise.
Unless the TPM is cleared, in which case it ll generate a new internal seed and now the keys will be different to before the clear
The Problem
I want to use a FOSS phone running Debian as my daily driver and not use a non-free OS on my phone. GrapheneOS [1] is a FOSS rebuild of Android, it s a great project and I commend them for what they are doing. But I want a system where I have access to all the bits and where I can ssh in to it and manage it in the same way as all other Linux systems. Android is free software but it s a closed design and the phones are expected to be appliances not full peers on the network. The Android native terminal emulator (AKA Linux development environment) is a nice feature, a VM with a default of 1GB of RAM but it s still separate from the main OS.
KDE Connect [2] is a system for KDE talking to phones, it is a great project and allows convenient interaction between a Linux PC and a phone. But in addition to that I d like the option to ssh to my phone to send an SMS or have one sent from a cron job. I blogged about using the basic functions of Kdeconnect from the command-line [3].
I have had ongoing issues with the battery not lasting long enough on the PinePhonePro (PPP) and the Librem 5 (L5) which makes them unusable for my purposes. For a phone running Droidian I can have an open ssh session (with keep-alive packets) running overnight on Wifi without any problems while for the PPP or L5 an hour of reading an ebook (the least demanding use of a phone) will use most of the battery.
I sent my FuriPhone back for warranty repair and it s been almost a month with no follow up, so I need to have another option.
The Aim
The aim of this post is to develop a rough design for a battery case for either a L5 or a PPP, I have both phones and they are both capable of doing what I want apart from battery life. Also designing a case that basically works for both phones and has two variations of the CAD file for 3D printing is good to allow collaboration with people who use either phone. Protecting the phone from damage when dropped is also a core feature.
I investigated commercial options. There are some reports of cases for other phones working, someone reported a PPP working well with a battery case for a Samsung S20 Ultra. The OtterBox uniVERSE Case for Samsung Galaxy XCover Pro is reported to fit the PPP so probably battery cases for the XCover Pro will also work. There are also universal power cases which have spring clips to fit a wide range of phone sizes, but they are much larger than other options and probably increase the risk of damage if the phone is dropped.
At this stage I m planning out the rough specs of a case that can be 3D printed to protect a phone while being easy to change the cells. The process of changing cells should be quick, easy, and not risk breaking anything. The hardware required should be affordable ($100AU plus some 3D printing seems reasonable) and should not require significant skills to assemble. After recent experiments with Thinkpad repair I ve determined that I am not good at electronics by today s standards so I plan to avoid anything difficult in that regard.
Battery Options
There are phone cases with batteries built in for the more common phones. A quick search on AliExpress turned up options for recent Pixel phones. They aren t as common as they used to be as Android phones and iPhones generally have good battery life nowadays. Of course there aren t such options for less common phones like the L5 and PPP.
It is cheap and easy to buy a portable battery for charging phones, but that s a separate bulky device and unless the connector is inside a protective case it leaves the phone vulnerable to catastrophic damage if dropped.
So can a suitable battery case be designed and 3D printed?
Cheap Batteries
According to Wikipedia the 18650 LiIon cell is the most commonly used LiIon battery, that is 18mm in diameter and 65mm in length. For a phone case thinner batteries would be more convenient but economies of scale make the 18650 cheap to buy new and commonly available on the second hand market. The current prices on AliExpress (in Australian dollars) are about $8 per cell when buying 10 at a time. Most of the cells on AliExpress don t have wires attached so they can be swapped in a carrier the way AA batteries are used, but the cells are symmetrical (no bump for positive) so the user has to take care of polarity. Chargers are around $22 for a 4 cell charger or $52 for a 12 cell charger.
I ve seen prices as low as $1 per cell on the second hand market, I haven t investigated the amount of usable capacity in such cells. Probably the prices for chargers I ve found aren t the best available but they are good enough to start the design. 10 cells and a 4 cell charger is about $100. That s about 130Wh while a 74Wh USB-C battery pack costs about $50. So the price per Wh is OK.
I have read about an attempt to do this for the L5 with two of the batteries designed for the L5 in a case attached to it, so you have 3*L5 batteries. It s an interesting approach but those batteries have poor value for money when compared to 18650 ($29US for 4500mAh compared to $8 for 3500mAh) and they also don t ship them outside the US at this time. The 18650 batteries are available everywhere cheaply and have multiple uses.
How They Fit
According to my measurements the PPP is 76mm wide and the L5 is 73mm wide. That s wide enough for 3*18mm or 4*18mm cells side by side arranged parallel to the long side of the phone or one 65mm long cell going across the phone with the necessary spring and wires.
The L5 is about 151mm long and the PPP is about 5mm longer. So that means that for just the cells we could have 2 cells in a row in parallel to the long side of the phone giving a 2*3 or 2*4 array or we could have a row of 8 cells parallel to the short side of the phone.
A quick search for controllers for a battery of LiIon cells that outputs USB-PD turned up one of the smaller ones as 40*28mm, here is the AliExpress page [4]. So that means we could have a maximum of about 4 cells and the controller while leaving space for the camera. Looking at other similar items it seems that most of them take a large portion of the 73mm width available and take a bit less than 30mm height. The price range for DC-DC voltage converters ranges from about $3 to $20, the one I linked to is currently $8.
The mass of 18650 cells is around 45g so 4 of them would be about 180g before counting the weight of the case and electronics. A L5 weighs 262g and a PPP weighs 220g so 180g of battery will make a significant difference, not an impossible difference but holding a PPP while reading an ebook is already annoying. Maybe the case could be designed to be easier to hold, a loop of wool attached to the top could be used to suspend the phone from one finger while the rest of the hand just keeps it steady.
In a default configuration the L5 has a 4500mAh 3.8V battery and the PPP has a 3000mAh 3.8V battery. The 18650 cells have up to 4000mAh with 3500mAh being common. So 4 such cells could multiply the battery life of a PPP by a factor of 5 or a L5 by 4. That would not be enough to last for a whole day without charging so they need to be easy to swap.
A 3 cell battery seems like a good option, 135g of batteries so the project overall wouldn t even double the weight of the phone with battery case. As it doesn t seem possible to put in enough cells to last a day of reasonable use (running a web browser, checking email, reading wikipedia, and having some IM systems checking for notifications) there doesn t seem to be a benefit in trying to stuff the maximum number of cells in. Going to 4 or 5 cells doesn t provide much benefit over 3 while increasing the weight and making the design more difficult. The modules for DC Voltage conversion often have configuration for the number of cells to be used so it wouldn t be difficult to print a new case and reconfigure the Voltage converter.
Design
A case needs to provide protection as well as hold the batteries. The lack of cases for the L5 and PPP is a problem even without the extra weight of a battery pack increasing the kinetic energy of falling phone. Ideally a drop from 1M on to concrete would not cause any damage to the phone, destruction of the case is OK as it would be 3D printed and can be rebuilt easily.
I think that a case where the phone slides in from the top would be best. To change cells one would slide the phone out and the cells would be immediately accessible with no divider between the phone and the cells. Sliding the phone in would hold the cells against the back of the case and as there is a gap of about 3mm on each side of the PPP between the display area and the edge of the phone there s plenty of space for the case to wrap around it at the sides and bottom. At the top there would have to be some sort of plastic clip. The PPP only has buttons on the top right so the case can be snug on all sides apart from the top right. The L5 has switches at the top left and buttons at the top right so whatever clips on to the top would really need some strength to cover the fall flat on face case.
The USB C plug would need to be held in place well enough to allow the phone to easily slide on to it but also be weak enough that it would move if a drop forced the phone out of the case.
Thingiverse has a design for a L5 case [5] (with several derivatives) and a design for a PPP case [6]. Those cases could be used as starting points and then changed to store batteries and the voltage change circuit board. I have just learned that it s possible to use rubberised material in a 3D printer which is apparently what those designs are for. If a case was printed with rubberised material the top could just stick in place after being pushed in.
Potential for Excessive Excitement
Having an exploding device in your pocket would be the exciting in a bad way. My initial idea was to have multiple 18650 cells in series. The problem is that if the cells have different capacity levels then one can run out before the rest and get to a deep discharge state which at a minimum causes damage to the cell.
One way of minimising risk is to have only a single cell in use at one time, here is a converter for a single cell to 5V [7]. It is possible to run multiple cells in parallel by simply wiring them together, but it s recommended to make sure that the voltage difference between cells is less than 0.2V to avoid high current when connecting.
The arrangement of cells is often referred to as nS or nP to refer to n cells in series or parallel. Aliexpress has a range of 1S to 6S devices. Some of the 2S devices have a connector for the mid point which permits separate voltage monitoring for both cells but there doesn t seem to be anything equivalent for 3S or more. They also don t appear to have anything to specifically manage 2P or 3P arrangements at the moment (they had a 3P board on sale when I looked into this last year).
Conclusion
This is a bigger project than I expected when I first started investigating it. I ve played with FreeCAD which seems OK but will take a lot of learning and practice. Then I need to do more investigation into the DC-DC converters to find one that works well and is unlikely to start a fire.
I will look into other phone options as well and keep chasing Furilabs people about my phone replacement.
netip.Addr features an Unmap()
method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6
address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns
203.0.113.10.1 There is no Map() or To6() method for the reverse
direction. Such a method is trivial to implement, but Go maintainers have
rejected it on the grounds that users should write
netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today,
this pattern is eight times slower than a native method. How can we teach the
compiler to optimize this sequence?
The alternatives
Let s explore three ways to implement the map semantics for netip.Addr. My
favorite is to add it to the Go standard library. Go maintainers prefer a small
external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping
the compiler eventually optimizes it. The unsafe package
opens a third path, with the same performance as the first solution.
Modifying the Go standard library
Internally, netip.Addr stores any IP address as a
128-bit value with an extra field z to encode the family and the zone:
typeAddrstructaddruint128zunique.Handle[addrDetail]typeaddrDetailstructisV6bool// IPv4 is false, IPv6 is true.zoneV6string// != "" only if IsV6 is true.var(z0unique.Handle[addrDetail]z4=unique.Make(addrDetail )z6noz=unique.Make(addrDetailisV6:true ))
AddrFrom4() encodes an IPv4 address as an
IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.funcAddrFrom4(addr[4]byte)AddrreturnAddraddr:uint1280,0xffff00000000uint64(addr[0])<<24uint64(addr[1])<<16uint64(addr[2])<<8uint64(addr[3]) ,z:z4,
Unmap() turns an IPv4-mapped IPv6 address into an
IPv4 address by setting the z field to z4:
Implementing the reverse direction inside the Go standard library is trivial: we
set the z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an// IPv6 address unmodified.func(ipAddr)To6()Addrifip.Is4()ip.z=z6nozreturnip
Update (2026-10)
Instead of patching Go, we can use the -overlay
flag of go build to hijack any package, including the standard
library. In our case, it can add To6() to net/netip. Yet
it is cumbersome:3 the flag expects a JSON file mapping absolute
paths in GOROOT to replacement files, and you need to add it to every go
command.
As a helper
We can t access the z field from outside the net/netip package. Instead, we
build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an// IPv6 address unmodified.funcAddrTo6(ipnetip.Addr)netip.Addrifip.Is4()ip=netip.AddrFrom16(ip.As16())returnip
As an unsafe function
Another solution uses the unsafe package to alter the Addr struct through
a proxy with the same memory layout:4
// addrProxy has the same memory layout as netip.Addr.typeaddrProxystructaddr[2]uint64// netip.uint128zunsafe.Pointer// unique.Handle[netip.addrDetail]var(anyIPv6=netip.IPv6Unspecified()netipZ6noz=(*addrProxy)(unsafe.Pointer(&anyIPv6)).z)// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an// IPv6 address unmodified.funcAddrTo6(ipnetip.Addr)netip.Addrif!ip.Is4()returnip(*addrProxy)(unsafe.Pointer(&ip)).z=netipZ6nozreturnip
Benchmarks
On my computer, with Go 1.27.1, the standard library solution costs 0.88 ns per
operation, while the solution favored by Go maintainers costs 7.14 ns. The
unsafe solution matches the performance of the first one.
Assembly code
Let s check the assembly code the compiler generates for each solution.5
The one built into the standard library looks like this:6
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnet/netip z6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
Go s assembly language is not a direct representation of the underlying
machine language: it operates on a semi-abstract instruction set derived from
Plan 9 s assembler. It has four pseudo-registers: FP (frame pointer
for function arguments), PC (program counter), SB (static base pointer for
global symbols), and SP (stack pointer). It also has architecture-specific
registers like AX, CX, DX, BX, SI, DI, and R8 to R15.
Instructions storing data use their last argument as the destination.
Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16
bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first
instruction compares the 64-bit value z4 with the CX register.
The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnetipZ6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
The helper solution has far more instructions. To understand why, let s look at
the code for As16() and
AddrFrom16(). They are short enough for the compiler
to inline them.
We can already guess the pattern to optimize: the code packs the IP address into
an array, copies it, then unpacks it. If we inline the Go code by hand, we get:
Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z; Push the stack (32 bytes):; 0(SP) addr netip.uint128; 16(SP) a16 [16]bytePUSHQBPMOVQSP,BPSUBQ$32,SPCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop here; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi); byteorder.BEPutUint64(a16[8:], input.addr.lo)MOVBEQAX,net/netip a16+16(SP)MOVBEQBX,net/netip a16+24(SP); addr = a16, 16 bytes at once through the vector register X0MOVUPSnet/netip a16+16(SP),X0MOVUPSX0,net/netip addr(SP); CX = netip.z6nozMOVQnet/netip z6noz(SB),CX; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8]); output.addr.lo = byteorder.BEUint64(addr[8:])MOVBEQnet/netip addr(SP),AXMOVBEQnet/netip addr+8(SP),BXend:ADDQ$32,SPPOPQBPRET// return value = Addr hi: AX, lo: BX, z: CX
The compiler does a decent job on the byte shuffling: the eight byte stores of
BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped.
The eight byte loads of BEUint64() become a single MOVBEQ the other way
round.7 Three groups of instructions remain: a pack, a copy, and an
unpack.
Hacking the Go compiler
The Go compiler has several phases:
The compiler converts the syntax tree and its types into its own intermediate
representation (IR). This process, called noding, goes through
a serialization format named unified IR.
This phase runs two steps: order of evaluation decomposes complex
statements into simpler ones, and desugaring transforms higher-level Go
constructs, like switch or channels, into more primitive instructions or
calls to the runtime.
The compiler rewrites the SSA form into machine-specific variants,
allocates registers, and applies more optimization passes. At the end, the
assembler turns the generated instructions into machine code.
The hammer
My first idea is to replace occurrences of netip.AddrFrom16(ip.As16()) with
netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the
noding process. Before that, the type checking phase prevents
us from accessing unexported struct fields.
Go 1.27 introduced a convenient debug option to dump the IR of a function at
interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1GOAMD64=v3gobuild-a-gcflags="-d=astdump=AddrTo6Safe".
Writing text ast output for AddrTo6Safe to AddrTo6Safe.astWriting html ast output for AddrTo6Safe to AddrTo6Safe.htmlWriting html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
In the HTML file, the first column shows the IR as it comes out of noding:
In the body of the if statement, we spot the calls to the method
netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to
patch them with a struct literal:
In noder s reader.go, the expr() method builds the IR tree for
an expression. At the end of the exprCall case, we add a call to a
rewriteAddrFrom16As16() function. It takes the current node and returns the
struct literal on success, or nil if the rewrite is not possible. First, we
check that we have the expected pattern: a call to the netip.AddrFrom16()
function with a call to the netip.Addr.As16() method as its only argument:
Have a look at the complete patch.8 We can test it
with the following commands:
$ cdsrc
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.Building Go toolchain2 using go_bootstrap and Go toolchain1.Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.Checking command staleness for linux/amd64.---Installed Go for linux/amd64 in /home/bernat/code/free/goInstalled commands in /home/bernat/code/free/go/bin*** You need to add /home/bernat/code/free/go/bin to your PATH.$ exportPATH=$PWD/../bin:$PATH$ goversion
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64$ gotestnet/netip/...
ok net/netip 0.224s$ cd../../go-netip-addrto6
$ gotest.
ok github.com/vincentbernat/go-netip-addrto6 0.062s
The generated code for the helper is now the shortest possible version!
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnet/netip z6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
Go maintainers are unlikely to accept this change. It relies on the internal
structure of net/netip.Addr. It s an ugly hack in the noder, whose job is to
faithfully translate the type-checked AST into the IR. And it s harder to
maintain than adding a To6() method.
The screwdriver
The right place for such an optimization is the generic SSA phase. One of
the last machine-independent passes is memcombine. With the appropriate debug
flag, the compiler dumps the SSA form after this pass:9
The result of the memcombine pass follows the same structure as the assembly
code for AddrTo6Safe()we looked at earlier: two stores,
one move, and two loads we would like to optimize away.
Each line features a value identifier (v442), an operation with its type
(Bswap64 <uint64>), and its arguments (v490).10 Values are the basic
building blocks of SSA and are defined exactly once. Square brackets enclose
integer parameters ([8]) and curly braces contain auxiliary arguments
( netip.addr ). Operations writing to memory produce a new memory state. Every
memory operation takes the current state as its last argument, which keeps them
in order.
To simplify this code, we could apply three rewriting rules:
The first one adds a shortcut when loading through a move: (Load (OffPtr
[o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174
with its arguments v415 and v286 and creates a new value v600:
The second one simplifies a load following a store: (Load p (Store p x
_)) => x. The load is forwarded: the stored value replaces it and no memory
access remains. It matches v174. It notices that v600 and v173 are the
same address and replaces v174 with a copy of v442:
To optimize it away, we also apply three rewriting rules:
The first one also adds a shortcut when loading through a move, but
without an offset: (Load p (Move p src mem)) => (Load src mem). This rewrites v416
to use arguments from v286:
The second rule forwards a value stored one step earlier, skipping over a
store to another address: (Load p (Store q _ (Store p x _))) => x. This
matches v416: x is v542, p is v22 (&a16), q is v173
(&a16[8]), and p and q do not overlap for uint64.
In practice
Most of these rules already exist in generic.rules. They use
conditions to validate their context: ssa.IsSamePtr() for the same address,
ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored
value to a load already exists with three variants looking through several other
stores. Here are the two we need:
There is no generic rule to cancel two byte swaps, but the AMD64 lowering
pass includes this rule:
(BSWAP(Q L)(BSWAP(Q L)p))=>p
After switching to Go s development branch and adding the missing
rule, the generated assembly code is worse than with Go 1.26.8,
even though our additional rule slightly improves the situation at the end:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z; Push the stack (16 bytes):; 0(SP) a16 [16]bytePUSHQBPMOVQSP,BPSUBQ$16,SPCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop here; The four forwarded bytes: the low half of input.addr.lo is taken apart and; put back together in registersMOVQBX,DX; DX = input.addr.loSHRQ$24,BX; BX = input.addr.lo >> 24MOVQDX,SI; SI = input.addr.loSHRQ$16,DX; DX = input.addr.lo >> 16MOVQSI,DI; DI = input.addr.lo, kept for the packSHRQ$8,SI; SI = input.addr.lo >> 8MOVBLZXDIB,R8; R8 = byte(input.addr.lo)MOVBLZXSIB,SI; SI = byte(input.addr.lo >> 8)SHLQ$8,SIORQR8,SI; SI = two low bytes of input.addr.loMOVBLZXDL,DX; DX = byte(input.addr.lo >> 16)SHLQ$16,DXORQSI,DXMOVBLZXBL,BX; BX = byte(input.addr.lo >> 24)SHLQ$24,BXORQDX,BX; BX = input.addr.lo & 0xffffffff; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi); byteorder.BEPutUint64(a16[8:], input.addr.lo)MOVBEQAX,net/netip a16(SP)MOVBEQDI,net/netip a16+8(SP); The four other bytes of input.addr.lo, read one by one from a16MOVBLZXnet/netip a16+11(SP),DX; a16[11]SHLQ$32,DXORQDX,BXMOVBLZXnet/netip a16+10(SP),DX; a16[10]SHLQ$40,DXORQDX,BXMOVBLZXnet/netip a16+9(SP),DX; a16[9]SHLQ$48,DXORQDX,BXMOVBLZXnet/netip a16+8(SP),DX; a16[8]SHLQ$56,DX; output.z = netip.z6nozMOVQnet/netip z6noz(SB),CX; output.addr.hi = byteorder.BEUint64(a16[:8])MOVBEQnet/netip a16(SP),AX; output.addr.lo assembled from the previous stepsORQDX,BXend:LEAVEQRET// return value = Addr hi: AX, lo: BX, z: CX
The rule loading through a move, added in Go 1.27, introduced this regression.
Out of order
Let s not give up now! In reality, the rewriting rules run before memcombine,
notably in the late opt pass. At this point, the inlined versions of
BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen
byte loads, matching their source code:
funcBEUint64(b[]byte)uint64_=b[7]// bounds check hint to compiler; see golang.org/issue/14808returnuint64(b[7])uint64(b[6])<<8uint64(b[5])<<16uint64(b[4])<<24uint64(b[3])<<32uint64(b[2])<<40uint64(b[1])<<48uint64(b[0])<<56
Let s follow two bytes of output.addr.lo: addr[15] and addr[11]. Here is
a simplified SSA form before late opt:
The first rule loads through the move: (Load (OffPtr [o] p) (Move p src mem))
=> (Load (OffPtr [o] src) mem). It matches both loads, which now read a16
with the memory state before the copy:
The second rule shortcuts a load following a store: (Load p (Store p x _)) =>
x. It matches v435, as v282 stores a16[15]. It does not match v481:
v235 stores a16[11] four stores earlier in the chain, while the variants of
this rule look through three stores at most.
The same happens to the other bytes: the rule forwards the four bytes stored
last, a16[12] to a16[15]. The twelve other loads now read a16 instead of
addr.
BEUint64() becomes a chain of Or64, each one adding a byte shifted into
place. memcombine is a pass written in Go, not a set of rewrite
rules. It starts from the last Or64 of the chain and collects up to eight
terms. If each term is a byte load, extended to 64 bits and shifted, and if the
eight loads read consecutive addresses from the same pointer with the same
memory state, it replaces the whole chain with a single 64-bit load and a byte
swap. Otherwise, it tries again with four, then two terms, and from each
intermediate Or64. Here is the loop checking each term in a simplified version
of combineLoads():
From v520, four of the eight terms are forwarded bytes, not loads from memory,
and memcombine can t combine them. It doesn t merge the four remaining loads
either, as they sit on top of the forwarded bytes.
Back in order
In summary, the rewriting rules run too early to be effective. A quick
workaround exists: run an earlier round of memcombine before late opt. After
this change, the generated code for the helper is back to the
shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnet/netip z6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
Next steps
I think Go maintainers would reject this change because of the additional
memcombine pass. Instead, I plan to publish this blog post and bring up the
subject again as a follow-up to issue #54365. Either the sheer complexity and
the Go 1.27 regression convince the maintainers that adding a To6() method is
simpler and more efficient, or they advise me on how to move forward. Either
way, digging into this subject taught me a lot about the Go compiler!
Update (2026-10)
I opened issue #81994 to propose Addr.To6(). Give it a if you want it in Go!
IPv4-mapped IPv6 addresses let you handle only IPv6 addresses in your code
and keep conversions at a few well-defined boundaries. I use them in
Akvorado.
This is not strictly equivalent. The zero value becomes :: while it would
make more sense to leave it untouched.
I suppose Go maintainers keep it inconvenient on purpose: they don t want
random packages to patch the standard library or other packages.
To avoid catastrophic bugs when netip.Addr s layout changes, you must add
tests to detect it. This is more dangerous if you put this code in a
package. Either ask users to run the tests themselves, or detect the change
at run time and panic. Hiding this optimization behind a build tag would
make users aware of this potential trap.
I produced the assembly code with GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm
'\.asm' from the companion repository, then edited it a bit to keep this
article from turning into an endless rabbit hole. Due to an unfortunate
sequence of events, we switch between versions: Go 1.27 introduced a
regression that blurs the point of this article.
The function is short enough for the compiler to inline it, so the assembly
code may vary depending on the surrounding code.
MOVBEQ requires GOAMD64=v3, matching the x86-64-v3
microarchitecture from 2013. Otherwise, the compiler translates
BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
When the call is used as a statement, a struct literal alone is invalid. The
patch then turns it into _ = netip.Addr .
The compiler can also write an HTML file with the result of each pass:
$ GOSSAFUNC=AddrTo6Safe\> GOTOOLCHAIN=go1.26.8\> GOAMD64=v3gobuild-a.
dumped SSA for AddrTo6Safe,1 to ./ssa.html
Source line numbers in parentheses follow value identifiers, but I removed
them from the examples. The SSA form also features branches, but we don t
need them to understand our optimizations.
netip.Addr features an Unmap()
method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6
address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns
203.0.113.10.1 There is no Map() or To6() method for the reverse
direction. Such a method is trivial to implement, but Go maintainers have
rejected it on the grounds that users should write
netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today,
this pattern is eight times slower than a native method. How can we teach the
compiler to optimize this sequence?
The alternatives
Let s explore three ways to implement the map semantics for netip.Addr. My
favorite is to add it to the Go standard library. Go maintainers prefer a small
external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping
the compiler eventually optimizes it. The unsafe package
opens a third path, with the same performance as the first solution.
Modifying the Go standard library
Internally, netip.Addr stores any IP address as a
128-bit value with an extra field z to encode the family and the zone:
typeAddrstructaddruint128zunique.Handle[addrDetail]typeaddrDetailstructisV6bool// IPv4 is false, IPv6 is true.zoneV6string// != "" only if IsV6 is true.var(z0unique.Handle[addrDetail]z4=unique.Make(addrDetail )z6noz=unique.Make(addrDetailisV6:true ))
AddrFrom4() encodes an IPv4 address as an
IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.funcAddrFrom4(addr[4]byte)AddrreturnAddraddr:uint1280,0xffff00000000uint64(addr[0])<<24uint64(addr[1])<<16uint64(addr[2])<<8uint64(addr[3]) ,z:z4,
Unmap() turns an IPv4-mapped IPv6 address into an
IPv4 address by setting the z field to z4:
Implementing the reverse direction inside the Go standard library is trivial: we
set the z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an// IPv6 address unmodified.func(ipAddr)To6()Addrifip.Is4()ip.z=z6nozreturnip
As a helper
We can t access the z field from outside the net/netip package. Instead, we
build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an// IPv6 address unmodified.funcAddrTo6(ipnetip.Addr)netip.Addrifip.Is4()ip=netip.AddrFrom16(ip.As16())returnip
As an unsafe function
Another solution uses the unsafe package to alter the Addr struct through
a proxy with the same memory layout:3
// addrProxy has the same memory layout as netip.Addr.typeaddrProxystructaddr[2]uint64// netip.uint128zunsafe.Pointer// unique.Handle[netip.addrDetail]var(anyIPv6=netip.IPv6Unspecified()netipZ6noz=(*addrProxy)(unsafe.Pointer(&anyIPv6)).z)// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an// IPv6 address unmodified.funcAddrTo6(ipnetip.Addr)netip.Addrif!ip.Is4()returnip(*addrProxy)(unsafe.Pointer(&ip)).z=netipZ6nozreturnip
Benchmarks
On my computer, with Go 1.27.1, the standard library solution costs 0.88 ns per
operation, while the solution favored by Go maintainers costs 7.14 ns. The
unsafe solution matches the performance of the first one.
Assembly code
Let s check the assembly code the compiler generates for each solution.4
The one built into the standard library looks like this:5
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnet/netip z6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
Go s assembly language is not a direct representation of the underlying
machine language: it operates on a semi-abstract instruction set derived from
Plan 9 s assembler. It has four pseudo-registers: FP (frame pointer
for function arguments), PC (program counter), SB (static base pointer for
global symbols), and SP (stack pointer). It also has architecture-specific
registers like AX, CX, DX, BX, SI, DI, and R8 to R15.
Instructions storing data use their last argument as the destination.
Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16
bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first
instruction compares the 64-bit value z4 with the CX register.
The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnetipZ6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
The helper solution has far more instructions. To understand why, let s look at
the code for As16() and
AddrFrom16(). They are short enough for the compiler
to inline them.
We can already guess the pattern to optimize: the code packs the IP address into
an array, copies it, then unpacks it. If we inline the Go code by hand, we get:
Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z; Push the stack (32 bytes):; 0(SP) addr netip.uint128; 16(SP) a16 [16]bytePUSHQBPMOVQSP,BPSUBQ$32,SPCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop here; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi); byteorder.BEPutUint64(a16[8:], input.addr.lo)MOVBEQAX,net/netip a16+16(SP)MOVBEQBX,net/netip a16+24(SP); addr = a16, 16 bytes at once through the vector register X0MOVUPSnet/netip a16+16(SP),X0MOVUPSX0,net/netip addr(SP); CX = netip.z6nozMOVQnet/netip z6noz(SB),CX; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8]); output.addr.lo = byteorder.BEUint64(addr[8:])MOVBEQnet/netip addr(SP),AXMOVBEQnet/netip addr+8(SP),BXend:ADDQ$32,SPPOPQBPRET// return value = Addr hi: AX, lo: BX, z: CX
The compiler does a decent job on the byte shuffling: the eight byte stores of
BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped.
The eight byte loads of BEUint64() become a single MOVBEQ the other way
round.6 Three groups of instructions remain: a pack, a copy, and an
unpack.
Hacking the Go compiler
The Go compiler has several phases:
The compiler converts the syntax tree and its types into its own intermediate
representation (IR). This process, called noding, goes through
a serialization format named unified IR.
This phase runs two steps: order of evaluation decomposes complex
statements into simpler ones, and desugaring transforms higher-level Go
constructs, like switch or channels, into more primitive instructions or
calls to the runtime.
The compiler rewrites the SSA form into machine-specific variants,
allocates registers, and applies more optimization passes. At the end, the
assembler turns the generated instructions into machine code.
The hammer
My first idea is to replace occurrences of netip.AddrFrom16(ip.As16()) with
netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the
noding process. Before that, the type checking phase prevents
us from accessing unexported struct fields.
Go 1.27 introduced a convenient debug option to dump the IR of a function at
interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1GOAMD64=v3gobuild-a-gcflags="-d=astdump=AddrTo6Safe".
Writing text ast output for AddrTo6Safe to AddrTo6Safe.astWriting html ast output for AddrTo6Safe to AddrTo6Safe.htmlWriting html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
In the HTML file, the first column shows the IR as it comes out of noding:
In the body of the if statement, we spot the calls to the method
netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to
patch them with a struct literal:
In noder s reader.go, the expr() method builds the IR tree for
an expression. At the end of the exprCall case, we add a call to a
rewriteAddrFrom16As16() function. It takes the current node and returns the
struct literal on success, or nil if the rewrite is not possible. First, we
check that we have the expected pattern: a call to the netip.AddrFrom16()
function with a call to the netip.Addr.As16() method as its only argument:
Have a look at the complete patch.7 We can test it
with the following commands:
$ cdsrc
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.Building Go toolchain2 using go_bootstrap and Go toolchain1.Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.Checking command staleness for linux/amd64.---Installed Go for linux/amd64 in /home/bernat/code/free/goInstalled commands in /home/bernat/code/free/go/bin*** You need to add /home/bernat/code/free/go/bin to your PATH.$ exportPATH=$PWD/../bin:$PATH$ goversion
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64$ gotestnet/netip/...
ok net/netip 0.224s$ cd../../go-netip-addrto6
$ gotest.
ok github.com/vincentbernat/go-netip-addrto6 0.062s
The generated code for the helper is now the shortest possible version!
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnet/netip z6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
Go maintainers are unlikely to accept this change. It relies on the internal
structure of net/netip.Addr. It s an ugly hack in the noder, whose job is to
faithfully translate the type-checked AST into the IR. And it s harder to
maintain than adding a To6() method.
The screwdriver
The right place for such an optimization is the generic SSA phase. One of
the last machine-independent passes is memcombine. With the appropriate debug
flag, the compiler dumps the SSA form after this pass:8
The result of the memcombine pass follows the same structure as the assembly
code for AddrTo6Safe()we looked at earlier: two stores,
one move, and two loads we would like to optimize away.
Each line features a value identifier (v442), an operation with its type
(Bswap64 <uint64>), and its arguments (v490).9 Values are the basic
building blocks of SSA and are defined exactly once. Square brackets enclose
integer parameters ([8]) and curly braces contain auxiliary arguments
( netip.addr ). Operations writing to memory produce a new memory state. Every
memory operation takes the current state as its last argument, which keeps them
in order.
To simplify this code, we could apply three rewriting rules:
The first one adds a shortcut when loading through a move: (Load (OffPtr
[o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174
with its arguments v415 and v286 and creates a new value v600:
The second one simplifies a load following a store: (Load p (Store p x
_)) => x. The load is forwarded: the stored value replaces it and no memory
access remains. It matches v174. It notices that v600 and v173 are the
same address and replaces v174 with a copy of v442:
To optimize it away, we also apply three rewriting rules:
The first one also adds a shortcut when loading through a move, but
without an offset: (Load p (Move p src mem)) => (Load src mem). This rewrites v416
to use arguments from v286:
The second rule forwards a value stored one step earlier, skipping over a
store to another address: (Load p (Store q _ (Store p x _))) => x. This
matches v416: x is v542, p is v22 (&a16), q is v173
(&a16[8]), and p and q do not overlap for uint64.
In practice
Most of these rules already exist in generic.rules. They use
conditions to validate their context: ssa.IsSamePtr() for the same address,
ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored
value to a load already exists with three variants looking through several other
stores. Here are the two we need:
There is no generic rule to cancel two byte swaps, but the AMD64 lowering
pass includes this rule:
(BSWAP(Q L)(BSWAP(Q L)p))=>p
After switching to Go s development branch and adding the missing
rule, the generated assembly code is worse than with Go 1.26.8,
even though our additional rule slightly improves the situation at the end:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z; Push the stack (16 bytes):; 0(SP) a16 [16]bytePUSHQBPMOVQSP,BPSUBQ$16,SPCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop here; The four forwarded bytes: the low half of input.addr.lo is taken apart and; put back together in registersMOVQBX,DX; DX = input.addr.loSHRQ$24,BX; BX = input.addr.lo >> 24MOVQDX,SI; SI = input.addr.loSHRQ$16,DX; DX = input.addr.lo >> 16MOVQSI,DI; DI = input.addr.lo, kept for the packSHRQ$8,SI; SI = input.addr.lo >> 8MOVBLZXDIB,R8; R8 = byte(input.addr.lo)MOVBLZXSIB,SI; SI = byte(input.addr.lo >> 8)SHLQ$8,SIORQR8,SI; SI = two low bytes of input.addr.loMOVBLZXDL,DX; DX = byte(input.addr.lo >> 16)SHLQ$16,DXORQSI,DXMOVBLZXBL,BX; BX = byte(input.addr.lo >> 24)SHLQ$24,BXORQDX,BX; BX = input.addr.lo & 0xffffffff; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi); byteorder.BEPutUint64(a16[8:], input.addr.lo)MOVBEQAX,net/netip a16(SP)MOVBEQDI,net/netip a16+8(SP); The four other bytes of input.addr.lo, read one by one from a16MOVBLZXnet/netip a16+11(SP),DX; a16[11]SHLQ$32,DXORQDX,BXMOVBLZXnet/netip a16+10(SP),DX; a16[10]SHLQ$40,DXORQDX,BXMOVBLZXnet/netip a16+9(SP),DX; a16[9]SHLQ$48,DXORQDX,BXMOVBLZXnet/netip a16+8(SP),DX; a16[8]SHLQ$56,DX; output.z = netip.z6nozMOVQnet/netip z6noz(SB),CX; output.addr.hi = byteorder.BEUint64(a16[:8])MOVBEQnet/netip a16(SP),AX; output.addr.lo assembled from the previous stepsORQDX,BXend:LEAVEQRET// return value = Addr hi: AX, lo: BX, z: CX
The rule loading through a move, added in Go 1.27, introduced this regression.
Out of order
Let s not give up now! In reality, the rewriting rules run before memcombine,
notably in the late opt pass. At this point, the inlined versions of
BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen
byte loads, matching their source code:
funcBEUint64(b[]byte)uint64_=b[7]// bounds check hint to compiler; see golang.org/issue/14808returnuint64(b[7])uint64(b[6])<<8uint64(b[5])<<16uint64(b[4])<<24uint64(b[3])<<32uint64(b[2])<<40uint64(b[1])<<48uint64(b[0])<<56
Let s follow two bytes of output.addr.lo: addr[15] and addr[11]. Here is
a simplified SSA form before late opt:
The first rule loads through the move: (Load (OffPtr [o] p) (Move p src mem))
=> (Load (OffPtr [o] src) mem). It matches both loads, which now read a16
with the memory state before the copy:
The second rule shortcuts a load following a store: (Load p (Store p x _)) =>
x. It matches v435, as v282 stores a16[15]. It does not match v481:
v235 stores a16[11] four stores earlier in the chain, while the variants of
this rule look through three stores at most.
The same happens to the other bytes: the rule forwards the four bytes stored
last, a16[12] to a16[15]. The twelve other loads now read a16 instead of
addr.
BEUint64() becomes a chain of Or64, each one adding a byte shifted into
place. memcombine is a pass written in Go, not a set of rewrite
rules. It starts from the last Or64 of the chain and collects up to eight
terms. If each term is a byte load, extended to 64 bits and shifted, and if the
eight loads read consecutive addresses from the same pointer with the same
memory state, it replaces the whole chain with a single 64-bit load and a byte
swap. Otherwise, it tries again with four, then two terms, and from each
intermediate Or64. Here is the loop checking each term in a simplified version
of combineLoads():
From v520, four of the eight terms are forwarded bytes, not loads from memory,
and memcombine can t combine them. It doesn t merge the four remaining loads
either, as they sit on top of the forwarded bytes.
Back in order
In summary, the rewriting rules run too early to be effective. A quick
workaround exists: run an earlier round of memcombine before late opt. After
this change, the generated code for the helper is back to the
shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.zCMPQnet/netip z4(SB),CX; check "z" if this is an IPv4 addressJNEend; if not, stop hereMOVQnet/netip z6noz(SB),CX; CX = netip.z6nozend:RET// return value = Addr hi: AX, lo: BX, z: CX
Next steps
I think Go maintainers would reject this change because of the additional
memcombine pass. Instead, I plan to publish this blog post and bring up the
subject again as a follow-up to issue #54365. Either the sheer complexity and
the Go 1.27 regression convince the maintainers that adding a To6() method is
simpler and more efficient, or they advise me on how to move forward. Either
way, digging into this subject taught me a lot about the Go compiler!
IPv4-mapped IPv6 addresses let you handle only IPv6 addresses in your code
and keep conversions at a few well-defined boundaries. I use them in
Akvorado.
This is not strictly equivalent. The zero value becomes :: while it would
make more sense to leave it untouched.
To avoid catastrophic bugs when netip.Addr s layout changes, you must add
tests to detect it. This is more dangerous if you put this code in a
package. Either ask users to run the tests themselves, or detect the change
at run time and panic. Hiding this optimization behind a build tag would
make users aware of this potential trap.
I produced the assembly code with GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm
'\.asm' from the companion repository, then edited it a bit to keep this
article from turning into an endless rabbit hole. Due to an unfortunate
sequence of events, we switch between versions: Go 1.27 introduced a
regression that blurs the point of this article.
The function is short enough for the compiler to inline it, so the assembly
code may vary depending on the surrounding code.
MOVBEQ requires GOAMD64=v3, matching the x86-64-v3
microarchitecture from 2013. Otherwise, the compiler translates
BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
When the call is used as a statement, a struct literal alone is invalid. The
patch then turns it into _ = netip.Addr .
The compiler can also write an HTML file with the result of each pass:
$ GOSSAFUNC=AddrTo6Safe\> GOTOOLCHAIN=go1.26.8\> GOAMD64=v3gobuild-a.
dumped SSA for AddrTo6Safe,1 to ./ssa.html
Source line numbers in parentheses follow value identifiers, but I removed
them from the examples. The SSA form also features branches, but we don t
need them to understand our optimizations.
One of the primary design principles for Linus Torvalds when creating Git is that it should be a distributed system, capable of working with multiple remotes. However, most people seem to use Git with just one remote, typically having GitHub or GitLab as the only origin.

Version control systems before Git relied on a centralized model. For example in Subversion or CVS you could only sync with one single remote server, which was considered the primary host of the source code. Git however is not just a VCS, but a DVCS, for distributed version control system. If you currently use Git with just one single remote as if it was a centralized version control system, now is the time to change that and learn how to add multiple remotes, and configure more flexible git pull and git push rules.
The first concept to grasp is that Git can have multiple remotes. For example, after running a basic clone command such as git clone https://github.com/ottok/debcraft.git you would end up with a single remote origin pointing to GitHub:
You can push and pull from these individually, or from all at once:
$ git pull --all
Fetching github
Fetching gitlab
Already up to date.
$ git pull --all
Fetching github
Fetching gitlab
Already up to date.
When you review the git history, note the labels gitlab/main and github/main which tell which commit the branch main points to on various remotes. In this case they are all in sync and point to the same 5d1815c:
$ git log --oneline
5d1815c (HEAD -> main, gitlab/main, github/main) Bump Debhelper version from 13 to 14
ca518a7 Temporarily disable automatic copyright year bumping due to frequent bugs
d6e201e Exclude .pm from codespell to decrease false positives (Closes: #1140488)
708ee35 Exclude debian/copyright from codespell due to frequent false positives
When pushing, you can choose what remote to push to. For example, if I am working on branch dev and I only want to push it to GitLab to trigger a CI run there, I can run git push gitlab dev. You can also configure a default remote by running once git push --set-upstream gitlab dev and thereafter simply run git push and it will automatically push the branch dev only to that remote.
A related setting is remote.pushDefault, which tells git which remote to push to when a branch does not define one of its own, and it applies to every branch that lacks a [branch] section in .git/config. Setting it once is what lets a repository have a per-branch pull remote, like the debcraft example below, and still have a single, predictable git push target. To see which remote git will use for each of your branches, run git branch -vv, and to refresh the remote-tracking branches of all remotes at once, run git fetch --all --prune.
If you want to have multiple remotes, but automatically push and pull to all of them at once, you configure one single remote to have multiple URLs with git remote set-url --add. Since git prints one line per push URL, git remote -v then shows the same remote several times, once for each URL it pushes to.
As an illustration, in my actual local Debcraft development project I have all these configured:
$ git remote -v
github-pull-requests git@github.com:ottok/debcraft.git (fetch)
github-pull-requests git@github.com:ottok/debcraft.git (push)
gitlab-merge-requests git@gitlab.com:ottok/debcraft.git (fetch)
gitlab-merge-requests git@gitlab.com:ottok/debcraft.git (push)
origin git@salsa.debian.org:debian/debcraft.git (fetch)
origin git@salsa.debian.org:debian/debcraft.git (push)
origin git@gitlab.com:ottok/debcraft.git (push)
origin git@github.com:ottok/debcraft.git (push)
otto git@salsa.debian.org:otto/debcraft.git (fetch)
otto git@salsa.debian.org:otto/debcraft.git (push)
otto git@gitlab.com:ottok/debcraft.git (push)
otto git@github.com:ottok/debcraft.git (push)
otto git@git.sr.ht:~ottok/debcraft (push)
otto ssh://git@codeberg.org/ottok/Debcraft.git (push)
salsa-merge-requests git@salsa.debian.org:debian/debcraft.git (fetch)
salsa-merge-requests git@salsa.debian.org:debian/debcraft.git (push)
The settings can also be viewed directly in the config file:
Use cases for distributed version control
The most obvious use case for any distributed system is improved availability. In this example, the salsa.debian.org is often overloaded/unavailable, so pushing to GitLab and GitHub as well allows collaborators to use them to fetch git commits if the primary code hosting site is unresponsive. Once it comes back online again, the next git push/pull will automatically bring it up to the same content as what backup hosts had.
The second main benefit is that having the code live on multiple code forges allows collaborators to use their own favorite host. Debcraft itself is a great example of this, as collaborators who don t have a Salsa account can - and have - submitted Merge Requests on GitLab.com and Pull Requests on GitHub.com.
A third use case is code hosting migrations. If you for example want to gradually phase out GitHub.com and replace it with something else, you could configure git to pull from the old location and push to both, ensuring that other collaborators can start using the new code hosting location without disruptions to those who have not yet updated their remotes or done a fresh git clone from the new location.
Automating setting up a project on multiple code forges
While I don t push all projects I work on to all Salsa/GitLab/GitHub, I do set up multiple remotes for enough git projects that I have this script to automate configuring a git repository that is cloned from Salsa to also push to GitLab and GitHub. It accepts the repository whether it was cloned over SSH or HTTPS, and it adds the push URLs and then pushes the current branch, all branches, and tags for you:
#!/bin/bash
# Add GitLab and GitHub push URLs to an existing git remote, so that a plain
# "git push" writes the same commits to all three code forges.
#
# Usage: ./git-multipush-salsa.sh
#
# Environment:
# SALSA_REMOTE remote to turn into a mirror, default origin
# SALSA_USER your Salsa user, only used to detect that the source
# remote is somebody else's project
# GITLAB_USER your GitLab user, default ottok
# GITHUB_USER your GitHub user, default ottok
# PROTOCOL ssh (default) or https, for the push URLs
set -euo pipefail
SCRIPT=$(basename "$0")
SALSA_REMOTE=$ SALSA_REMOTE:-origin
SALSA_USER=$ SALSA_USER:-otto
GITLAB_USER=$ GITLAB_USER:-ottok
GITHUB_USER=$ GITHUB_USER:-ottok
PROTOCOL=$ PROTOCOL:-ssh
die() echo "$SCRIPT: $*" >&2; exit 1;
# A failing command leaves the push URLs half configured behind, so say how
# to get back to where we started
fail()
echo "$SCRIPT: '$*' failed, the push URLs may already have been added" >&2
echo " git config --unset-all remote.$ SALSA_REMOTE .pushurl" >&2
echo " git remote set-url --add --push $ SALSA_REMOTE $ SALSA_URL " >&2
exit 1
git rev-parse --git-dir > /dev/null 2>&1 die "not inside a git repository"
git remote grep -qx "$SALSA_REMOTE" die "no remote named '$SALSA_REMOTE'"
# Example: git@salsa.debian.org:otto/salsa-ci-pipeline.git
SALSA_URL=$(git remote get-url "$SALSA_REMOTE")
# The source remote may use any of the URL forms salsa.debian.org accepts,
# for example git@salsa.debian.org:otto/salsa-ci-pipeline.git or
# https://salsa.debian.org/otto/salsa-ci-pipeline.git
case "$SALSA_URL" in
git@salsa.debian.org:*) SALSA_PATH=$ SALSA_URL#git@salsa.debian.org: ;;
ssh://git@salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#ssh://git@salsa.debian.org/ ;;
https://salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#https://salsa.debian.org/ ;;
http://salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#http://salsa.debian.org/ ;;
*) die "unexpected source URL '$SALSA_URL', expected a salsa.debian.org URL" ;;
esac
SALSA_PATH=$ SALSA_PATH%/
SALSA_PATH=$ SALSA_PATH%.git
SOURCE_USER=$ SALSA_PATH%%/*
PROJECT=$ SALSA_PATH##*/
# Write the push URLs in one and the same protocol, no matter how the
# repository happens to have been cloned
if [ "$PROTOCOL" = "https" ]
then
SALSA_URL="https://salsa.debian.org/$ SALSA_PATH .git"
GITLAB_URL="https://gitlab.com/$ GITLAB_USER /$ PROJECT .git"
GITHUB_URL="https://github.com/$ GITHUB_USER /$ PROJECT .git"
else
SALSA_URL="git@salsa.debian.org:$ SALSA_PATH .git"
GITLAB_URL="git@gitlab.com:$ GITLAB_USER /$ PROJECT .git"
GITHUB_URL="git@github.com:$ GITHUB_USER /$ PROJECT .git"
fi
# Mirroring somebody else's project is fine, but it is usually not what you
# want: you most likely want to mirror your own fork instead
if [ "$SOURCE_USER" != "$SALSA_USER" ]
then
echo "Note: $SALSA_REMOTE points to $SOURCE_USER's project, not your own."
echo "To mirror your own fork, run this with SALSA_REMOTE set to its name."
echo
fi
# Bail out instead of adding the same push URLs twice
EXISTING=$(git remote get-url --push --all "$SALSA_REMOTE")
if [ "$(printf '%s\n' "$EXISTING" wc -l)" -gt 1 ]
then
die "remote '$SALSA_REMOTE' already has multiple push URLs:
$EXISTING"
fi
echo "Mirroring $SALSA_URL to $GITLAB_URL and $GITHUB_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$SALSA_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$GITLAB_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$GITHUB_URL"
# Push the branch you have checked out first, and never with --force: the
# first branch a GitLab or GitHub project receives becomes its default branch,
# the one you then protect
DEFAULT_BRANCH=$(git symbolic-ref --short HEAD) die "not on a branch, check out a branch first"
git push -u "$SALSA_REMOTE" "$DEFAULT_BRANCH"
git push "$SALSA_REMOTE" --all
git push "$SALSA_REMOTE" --tags
# The push above creates the GitLab and GitHub projects, but GitLab projects
# are private by default, so make the new mirror public with glab if installed.
if command -v glab > /dev/null
then
echo "Make the GitLab project public and describe it as a mirror:"
glab api -X PUT "projects/$ GITLAB_USER %2F$ PROJECT " \
-f visibility=public \
-f description="Mirror of $ SALSA_URL " \
-f notification_email=disabled
else
echo "Install glab to do the same automatically, or visit"
echo "https://gitlab.com/$ GITLAB_USER /$ PROJECT /edit to make the project public"
fi
echo "To undo, drop all push URLs and add back only the original one:"
echo " git config --unset-all remote.$ SALSA_REMOTE .pushurl"
echo " git remote set-url --add --push $ SALSA_REMOTE $ SALSA_URL "
If you prefer not to install glab, the last part simply reduces to visiting the GitLab project settings once and ticking the project public, and it is also worth setting a description like Mirror of https://salsa.debian.org/debian/debcraft and disabling notification email there, as nobody wants a mirror sending out a flood of emails every time you push.
There are a few caveats worth knowing about before mirroring everything everywhere. Every push to a remote with multiple push URLs writes to all of them, so a project with continuous integration configured on three forges will run its CI three times and cost you roughly three times as much. If one of the push URLs fails, say because the host is momentarily unreachable, git prints the error and stops there, leaving the remotes listed after the failing one without the new commits. Simply re-run the push once the host is reachable again; the remotes that did get the commits will just respond with Everything up-to-date. And you should never force-push to only one of the remotes, as that leaves the mirrors permanently out of sync with your local repository.
Avoid pulling too much
Related to multiple remotes, you should also be aware that git allows one to configure which branches to pull. By default a git clone will track all branches from the remote and pull everything, which in a typical open source project will bring in a lot of temporary development branches in vain.
Thus it is better to run git clone with the --single-branch and --branch parameters to fetch only the branch that matters, which in most cases is the main branch. That can be accomplished with:
git clone --single-branch --branch main https://github.com/ottok/debcraft.git
If a repository was already cloned, it can be configured to track only one branch with:
For additional details about any of the tips in this post I recommend reading the git man pages.
Now go and spread your code around
Distributing your code over multiple code forges costs you almost nothing in configuration, and in return you get availability, a choice of host for your collaborators, and freedom to migrate without a big bang. Add the push URLs to the remotes you already have, push once, and you are done.
The rest of the git fundamentals are covered in my other posts. If your commits are not yet polished, start with what makes a good git commit message and git commit messages by example. If you work on Debian packaging, Git-based collaboration in Debian explains why the Salsa merge request workflow is built the way it is, and Salsa merge request best practices covers the review process itself.
Lots of posts in the debian-user mailing list complaining about updates with Debian 11.11 suddenly failing.
See Debian 11 Long Term Support reaches end-of-lifeAugust 31st, 2026
The Debian Long Term Support (LTS) Team hereby announces that Debian 11
bullseye support has reached its end-of-life today, 31 August 2026,
five years after its initial release on 14 August 2021.
Starting in September, Debian will not provide further security updates for
Debian 11. A subset of bullseye packages will be supported by external
parties. Detailed information can be found at
Extended LTS.
The Debian LTS Team is currently providing security support for Debian 12
bookworm, the current oldstable release. Thanks to the combined efforts
of different teams including the Security Team, the Release Team, and the LTS
Team, the Debian 12 life cycle encompasses five years.
Debian 12 will receive Long Term Support until 30 June 2028. The supported
architectures in Debian 12 LTS are amd64, i386, arm64, armhf and ppc64el.
For further information about using bookworm LTS and upgrading from
bullseye LTS, please refer to
LTS/Using.
Debian and its LTS Team would like to thank all contributing users, developers,
sponsors and other Debian teams who are making it possible to extend the life
of previous stable releases, and who have made Bullseye LTS a success.
If you rely on Debian LTS, please consider
joining the team,
providing patches, testing or
funding the efforts.
Activity summary
During the month of August, 19 contributors have been
paid to work on Debian LTS (links to individual
contributor reports are located below).
The team released 58 DLAs fixing 1885 CVEs.
Debian 11 ( bullseye ), which
has reached the end of its Long Term Support on 31 August 2026, will
now get security support from Freexian under the
Extended LTS offer.
The team published several notable updates:
chromium
(DLA 4710-1),
uploaded by Emilio, to fix 375 security flaws in bookworm, including
issues that could lead to arbitrary code execution.
Further DLA 4728-1,
uploaded by Emilio as well, fixed additional 41 security issues in bookworm and
DLA 4739-1
fixed 5 issues.
Last but not least,
DLA 4749-1
fixed another 15 issues and
DLA 4758-1
fixed another 7 issues.
ruby2.7
(DLA 4716-1),
uploaded by Abhijith, to fix four security flaws in bookworm, including
issues that could lead to arbitrary code execution.
several DLAs
(DLA 4717-1,
DLA 4720-1,
DLA 4723-1,
DLA 4724-1,
DLA 4745-1)
have been uploaded by Ben and Emilio to fix myriad security flaws in
different versions of the linux kernel
(5.10.262-1, 6.1.180-1, 6.12.100-1~deb12u1, 6.12.101-1~deb12u1)
in bullseye and bookworm.
7zip
(DLA 4718-1)
and p7zip
(DLA 4719-1),
uploaded by Sylvain, to fix multiple security flaws in bookworm and
bullseye, including issues that could yield to remote code execution.
ca-certificates
(DLA 4726-1),
uploaded by Bastien to add some new trusted certificates to bookworm and bullseye,
but also remove some untrusted ones.
thunderbird
(DLA 4727-1
and DLA 4754-1),
uploaded by Emilio to fix 35 and 31 issues in bookworm and bullseye.
nss
(DLA 4729-1),
uploaded by Jochen to fix a vulnerability in bookworm and bullseye that could
yield to arbitrary code execution.
libgd2
(DLA 4731-1),
uploaded by Guilhem to fix a vulnerability in bookworm and bullseye that could
yield to arbitrary code execution if a malformed GIF file is processed.
xorg-server
(DLA 4737-1
and DLA 4738-1),
uploaded by Arnaud to fix several vulnerabilities in bookworm and bullseye.
postgresql-15
(DLA 4740-1),
uploaded by Carlos Henrique Lima Melara to fix 26 vulnerabilities
in bookworm.
unzip
(DLA 4741-1),
uploaded by Andrej to fix a vulnerability in bookworm and bullseye
that could yield to arbitrary code execution.
firefox-esr
(DLA 4750-1),
uploaded by Emilio to fix 31 vulnerabilities in bookworm and bullseye
that could potentially result in arbitrary code execution, privilege escalation
or information disclosure.
nvidia-graphics-drivers
(DLA 4752-1 and
DLA 4753-1),
uploaded by Tobias to fix lots of vulnerabilities in bookworm and bullseye.
roundcube
(DLA 4760-1),
uploaded by Guilhem to fix ten vulnerabilities in bookworm and bullseye
that could potentially result in remote code execution or information disclosure.
Contributions from outside the LTS Team:
We are greatly thankful for the contributions from people outside the LTS Team:
Salvatore Bonaccorso released a libyaml-syck-perl security update
(DLA 4730-1),
to fix a denial of service and potentially arbitrary code execution.
Thomas Goirand released a neutron security update
(DLA 4735-1).
Thomas Goirand released an ironic security update
(DLA 4743-1).
Thomas Goirand released a designate security update
(DLA 4751-1),
to fix a denial of service or DNS hijacking.
The LTS Team has also contributed with updates to the latest Debian releases:
xrdp
(DSA 6469-1),
prepared by Abhijith to address privilege escalation and arbitrary
code execution related flaws.
Other contributions:
Besides the work on security updates, different documentation and tooling
changes were needed. This work was mainly done by Sylvain.
I ve long been interested in hardware key material storage devices. I ve been
a fan of yubikeys (I still remember
when my fancy new NEO-N showed up), PIV
(and its associated
smattering of
additionalfields),
SaaS HSMs,
the kernel keyring, some tooling
I ve fairly satisfied with the design of at prior companies, and of course,
our dear friend, the TPM. All that is not even to mention the scores of exotic
hardware security modules one generally comes across from time to time when
you re keeping a sharp eye out that you wind up playing with.
The concept of storing private key material on a disk, or even having it in
RAM has always skeeved me out, so I have a natural inclination to hardware
modules, and how shifting keying material around can change your risks
and threat model(s) in interesting ways.
I don t remember when I first came across the
MIFARE DESFire EV3, but a few weeks ago
I did a deep-dive into the state of the art of authentication schemes using
ID cards. My complete overview of what tradeoffs exist is pretty extensive
(and likely not interesting to the vast majority of the world), but the tl;dr
wound up being one of use PIV or use MIFARE DESFire EV3 . I wound up
picking DESFire for a recent project, and figured it s worth talking
a bit about what I learned, share some thoughts, and some code. That code is
published on crates.io/desox, and docs,
as is our custom, may be found at
docs.rs/desox
DESFire supports DES (I m sure most readers saw that one coming), 3DES (I
didn t bother playing with 3DES at all) or AES-128 (AFAICT always use this?)
keying material. It s worth noting that the DESFire only supports symmetric
keys and is not designed for public key cryptography, and operates exclusively
using shared symmetric key material. The DESFire EV series use those keys and
related authentication schemes to interact with files stored on the on-chip
EEPROM (2k, 4k, 8k, and 16k versions exist), or applications (groups of files
and authentication keys).
Talking to a DESFire EV3
Interactions with the card are done over NFC (ISO/IEC 14443 Type A), and
commands to/from the card may be in the usual ISO/IEC 7816-4 APDU format, or
unencapsulated bytes sent to/from the card are sent using a fixed instruction
set and return code structure saving a few bytes per message. I ve opted to
use their undocumented and proprietary format I found it easier to work
with and with a maximum message of 60 bytes, the savings matter a lot.
While powered via NFC, the card maintains a small amount of state about the
connection between the reader and the card in its RAM, including if the
session is authenticated or unauthenticated. I ll dig into how authentication
happens later, but it s worth knowing that sessions can become authenticated
using one of the symmetric keys shared by the card and the reader. The vast
majority of the
DESFire commands
I know about tend to work while either authenticated or unauthenticated,
with a few exceptions (GetUid, ChangeKey, and ChangeKeySettings
for example).
In general, I found working with this card particularly pleasant. There is a
fair amount of backwards-compatible behavior and multiple methods of
communication that confuse things a bit, but overall, it was better than
average to integrate with. Kudos to the NXP team. If the docs on this chip
were public, things would be orders of magnitude easier it s not entirely
clear to my why they re keeping so much of the interface documentation under
NDA, but it s the largest knock against the chip, by far.
Authentication
I found a lot of really great resources outlining how the handshake and
protocol works for a DESFire EV3, especially from
Ridrix,
some public datasheetsThrRealRevK
and posts from AndroidCrypto.
The gist here is that, because the DESFire only does symmetric key operations,
the key exchange (a type of SKA Symmetric Key Agreement) uses symmetric keys
to establish a unique session key which is used to sign or encrypt data
exchanged between the reader and the card. I m not going to get too in-depth
here, since there s a ton of other resources out there to dig into but I
will do a quick high-level description to keep this post mostly self-contained.
The authentication protocol serves two main functions to verify that both
parties know the same shared secret, as well as to act as a SKA to construct a
new session shared secret key. Here s a quick overview of how a shared session
key is derived between the reader and the card using our symmetric keys
(AES-128 in the case below).
the reader requests to start authentication with the card (something like
AA 00 to start an AES Authentication handshake with keyslot 0x00).
The card will then reply with AF (a status code that indicates more data
is to follow), followed by 16 bytes (in the case of AES-128) of encrypted
(using CBC) data.
The hosts then decrypts this block with the symmetric key from keyslot 0,
returning the card s session nonce.
The host generates 16 bytes (usually random) for its session
nonce.
The host sends an instruction of AF (indicating a continuation of
the previous command), followed by 32 bytes of encrypted data. When decrypted,
the first 16 bytes are our nonce generated in step #4, followed by the 16 bytes
provided by the card, decrypted in step #3, except where every byte is shifted
to the left by one place (the 0th byte is copied to the end).
The card will reply with 00 indicating a successful operation, followed
by 16 bytes, which when decrypted, is our session nonce from step #4, shifted
to the left by one byte in the same way that we did in step #5 with the card s
nonce.
At this point, both the reader and card have confirmed the other party has
the same symmetric secret key. The session is now authenticated and a
session key is derived using the two nonce blocks. Two hashing keys (K1
and K2) are derived from this key, which is used to maintain an ongoing
CMAC hash of the messages
coming and going to/from the card.
From here on out, the session is authenticated , and responses from the card
which were previously plain will now contain a 8-byte CMAC signature,
which can be used to ensure that the replies in question come from the
active session.
In my implementation of the handshake
I opted to encode the handshake state into rust types, just so I wouldn t make
any mistakes. The Handshake type contains the session internals (session
nonce values, keying state, to include IV, etc). This means the authentication
flow (from within my code) uses the Handshake struct to generate the commands
to send to the card in order:
/// Create a new Handshake , and return the
/// start auth command (something like AA 00 )
fnHandshake::<Initial>::begin(
output: &mut [u8],
key: [u8; 16],
key_id: u8,
) -> (Self, &[u8]);
After we get a reply back from the card (the encrypted version of the card s
session nonce, sometimes called Rnd_B in code I ve seen), we transition
states from Initial into HalfOpen.
/// Given the card's encrypted response, generate
/// our session nonce and generate a reply
/// (something that starts with AF followed by
/// 32 bytes of encrypted data).
fnHandshake::<Initial>::rnd_b(
self,
output: &mut [u8],
input: &[u8]
) -> (Handshake::<HalfOpen>, &[u8]);
Now that we re HalfOpen , we re waiting to hear back from the card to ensure
that it, too, can byte-shift our provided nonce. Once we have the card s reply,
we can check it using our complete helper, transitioning from HalfOpen to
Successful.
/// Check to ensure that the card replied with
/// our nonce byte-shifted by one place, indicating
/// that they know the symmetric secret in
/// this key slot.
fnHandshake::<HalfOpen>::complete(
self,
input: &[u8]
) -> Handshake::<Successful>;
Once the Handshake is successful, the only thing left to do is consume
the Handshake struct and turn it into the shared session key by running
it through the key derivation function.
/// Consume the Handshake struct and return the
/// new shared session secret key.
fnHandshake::<Successful>::into_key(self) -> [u8; 16];
From here on out we can use this session key for the remainder of our
interactions with the card signing messages from (and sometimes to!) the
card, or encrypted messages to and from the card. This key is used in CBC block
mode, where the session IV is updated with the last block of the encrypted
data.
Unit Testing
A nice proprietary of the SKA scheme we re using as part of DESFire is that the
derived session key is actually deterministic if you control your nonce RNG
(ok, actually, pretty true for most key agreements, but anyway), which means it
is possible to capture traffic over the NFC interface, and replay the NFC I/O
with cooked RNGs and ensure byte-identical messages and keys are generated.
Within desox-rs this is called replay (I m creative), and I ve got a few
replay sessions checked into VCS, which exercise a signficant amount fo the API
surface. All were derived from an actual session with a real DESFire card, and
can be updated with a live card and a --cfg flag.
Each replay file is a set of lines (request-response transactions), each
containing two space-delimited hex encoded NFC messages. For instance,
here s an authentication handshake in replay format:
The code that generated that exchange came from the test stored adjacent
to that file a handshake with the default DES key (all zeros), and
an RndA value hardcoded to 32c28fdafd3960de.
Since the card s RndB is similarly unchanging (I m replaying this file every
time), this will always derive the same session key, which means messages
(including encrypted ones or CMAC signed responses) will be identical, as well.
If you re playing with the DESFire yourself, feel free to grab my replay
files if you need a
known good baseline.
By default this will run using the
MockBackend,
replaying each file expecting a byte-identical request, and responding with
the harcoded customary reply. If the code (or test!) needs to change, updating
the tests is done by swapping the MockBackend out for a real one. Since I
had to do this a bunch during development, running cargo test
with RUSTFLAGS="--cfg desox_replay_rw" will, on run, overwrite the replay
file(s) for the executed test(s), ensuring all line-protocol changes are
explicitly caught and reviewed.
Observations
Most commands, even ones which require authentication, are transmitted without
CMAC signature(s) or encryption. CMAC signatures from the reader to the card
are not really used (except for writes to a file which specifies communication
must be CMAC signed), ditto for encryption (although that one is used for key
change operations, in addition to file writes on files that specify encrypted
communication must be used). The vast majority of commands take a plain
request from the reader, and return a CMAC signed response.
By my eye, this means that a malicious reader, or something otherwise capable
of holding the card online after communication with an authentic reader is
complete are able to execute privilaged commands (since one can simply ignore
the CMAC signatures on responses), so long as the command doesn t require the
reader to provide CMAC signatures (or encryption), or allow the card to power
down.
Fun with DESFire
I ve played around a bit with ways to use the DESFire cards in interesting
configurations, given what they re capable of. Here s some half-baked thoughts
I had while mucking around with the cards these are all poorly thought out
sketches of some things we can do given the specific tradeoffs I see with the
DESFire card. It s also worth noting that I don t have any of the actual
documentation, and am not a cryptographic grown-up, so take these sketches with
a massive grain of salt.
The first thing that came to mind when implementing this is how the
authentication scheme can shift the boundary of what is and is not trusted
(assuming good secure keying, and provided the key slots and card/application
permissions are configured correctly). Rather than push the key material out to
the machine connected to the NFC reader ( reader machine ), I instead tried
turning the NFC reader and computer into something psuedo-untrusted by merely
having it pass messages from the card to a trusted remote system ( remote
machine ). This means that the reader machine is exchanging NFC data with the
card, but that data is being decrypted, encrypted and processed by the trusted
remote machine the reader is unable to derive the session key.
For each of these, I wind up needing to authenticate so there s still a few
latent risks, but these can mostly be mitigated by asking for a readbacks of
any changed file(s), setting key permissions carefully, and requesting the
card s UID via the encrypted channel all of which would require the
symmetric secrets (which undermine the whole security model if comprimised).
This general construction is also subject to a hostile takeover of the
untrusted reader machine , since most commands (including destructive ones!)
are sent in PLAIN mode the reader machine can wait until authentication
is complete and then inject commands into the card and simply ignore the CMAC
signatures on responses, severing ties with the remote machine. As such, we
also need to take steps to ensure that the key being used is not one that
allows any access beyond what is allowed. Here were some ideas I sketched out
off the back of this theory.
The second-factor
Given some established (and authenticated) connection, part of the initial
authentication flow may use the DESFire card to prove physical control over it
as part of a handshake. This can serve as a second factor during some
authentication flow, requiring physical card presence at a reader to fully
initialize a connection. This does have one glaring downside, however it s
phishable. To use this for real , we d need to take some steps to prevent
obvious MITM flows (XOR the NFC messages with the URI as seen by the client?),
but maybe there s something interesting there.
This also has a second interesting attribute when used as part of a physical
system authentication flow, this becomes a logical place to inject access
control, being able to determine if some person is permitted to operate some
device at that particular time (Is Joe current on his Laser Cutter
certifications?) I think of the ideas I landed on, while conceptually
interesting (using an employee id card as a 2FA token, it s very fast), this
one is the least likely to turn into something real.
The encrypted-cookie
This construction, when paired with an encrypted DESFire file, allows the
remote machine to read/write an encrypted cookie to the card storing
small amount of encrypted data that the remote machine can read/write, but
not the reader machine , since this uses an encrypted and authenticated
channel from the remote machine directly to the DESFire card, without any
intermediate hosts needing to be fully trusted. I keep calling this the
encrypted cookie in my head because it feels conceptually similar to how Ruby
on Rails and Laravel handles cookies.
We d need to take a few extra steps here (for instance, ensure that you read
the cookie back over the encrypted channel after writing to prevent a malicious
reader from dropping writes) to secure the system, but it feels like the
structure of this is definitely decent.
The takeover
This time, let s say the computer attached to the NFC reader ( reader machine )
is semi-trusted. For this scheme, our trusted remote machine and the
reader machine pass messages over the network to handle authentication to the
card (as above), where the handshake data is being decrypted, encrypted and
processed by the trusted remote machine as usual. However, once the
authentication handshake is complete and a session key has been derived, the
remote system return the session key to the reader machine , giving it a
one-time-use key and authenticated session to the card.
We need to be careful about global/application permissions and key access
control to files but in this construction, we can allow the reader machine
to take over privileged actions using a scope-limited DESFire key without
handing over the card s true keying material (preventing cloning of the card).
This can be helpful to ensure messages to/from the card are truely from the
card (verifying CMAC signatures), enables the reader machine to directly
read/write to/from encrypted file(s), but allows the symmetric key material to
remain in as few places as possible which is critical given compromising
that secret will undermine the security of the entire system.
Welcome to the August 2026 report from the Reproducible Builds project!
In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not.
In this month s report, we cover:
New updated SBOM specification from CISA.gov
CISA, the Cybersecurity and Infrastructure Security Agency of the U.S. government published some the joint guidance entitled Minimum Elements for a Software Bill of Materials (SBOM), which updates and supersedes the baseline 2021 version covered in previous editions of these reports.
Whilst the PDF is worth skimming, the interesting changes include that the specification now mandates standard cryptographic hashes: unlike earlier standards that allowed hash omission or manifest-only parsing, hashes must be computed from the output. This is is important for reproducible builds, as it ensures the recording of the metadata required to demonstrate the shipped software matches the build output precisely where applicable. In addition, where the top-level only dependency limitation that was present in the 2021 version has been removed in favour of complete coverage with no minimum depth. That is, SBOMs are expected to reflect all linked libraries, vendored dependencies and other build-time inclusions.
The basic idea behind bootstrappable builds is to create a system that can be built without relying on pre-built artifacts. Can we go from zero to the modern day without having to just assume the existence of these already-built-for-us artifacts? The classic recipe for yogurt requires some yogurt to start the process, which is like how we normally build a C compiler today we start with an existing C compiler binary. You might think about making sourdough bread with your grandmother s starter brought over from the old country; we re basically making C compilers with Dennis Ritchie s starter carried over from Bell Labs .
The reason I like the idea of making reproducible builds work is that I think it can be done in such a way as to not require any work on the part of the producer of a distribution (which is a technical term for sdists or wheels, i.e., the people who upload stuff to PyPI), and thus make reproducible builds very low-friction for people to opt into supporting. []
Brett goes on to outline What s missing from the specs and how reproducibility might be visible on PyPI to consumers:
Assuming all of this comes to pass and we record the where the source code is that went into a distribution and the software used to make the distribution, how do we make it useful to people? Does every person who cares about having a secure supply chain have to rebuild everything they use themselves? Is there some way for even people who don t care about this stuff to benefit? []
Distribution work
In Debian this month, 23 reviews of Debian packages were added, 28 were updated and 27 were removed this month adding to our knowledge about identified issues. A number of issue types have been updated as well, such as the addition of a new toolchain issue related to python-traitlets [], and the note for an existing issue related to texi2html was updated as well [].
Lastly, Bernhard M. Wiedemann posted another openSUSEmonthly update for their reproducibility work there.
Unreproducible builds under EROFS filesystem fixed
Martin Pitt reported on Fosstodon that they had identified an issue where the mkfs ( make filesystem ) command for the EROFS (Enhanced Read-Only File System) subsystem of the Linux kernel did not have sorted extended file attributes, leading to reproducible builds.
Thankfully, Martin also reported that they had fixed this in a commit to the kernel which order[s] each inode s xattrs by name so that images stay reproducible . []
Tool and documentation development
diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 327, 328 and 329 to Debian. In particular, he ensured that diffoscope did not require python3-guestfs in the autopkgtests on 32-bit architectures in order to fix Debian bug (#1144372) []. Colin Watson made an additional change, handling a potentially missing openssh-client package when running the autopkgtests [], and Jochen Sprickerhof made a similar change to cope with missing cpio and qemu-img functionality [] whilst also updating the XML comparator to be considered when comparing SVG images [].
Yet again, there were a number of improvements made to our website this month as well. For example:
Chris Lamb added draft for a Gothenburg summit-related news article. [][]
Lastly, a large number of commits were pushed comprising an interview with Reproducible Builds developer Jochen Sprickerhof to be published within the next week. [][][][][][][]
Six new scholarly papers
Jens Dietrich, Spencer Sun, Tim W. White and Behnaz Hassanshahi (the result of a collaboration between Victoria University of Wellington and Oracle Australia published a paper this month entitled No Snake Oil: Verifying Python Package Builds. Drawing on the metaphor of snake oil , that is, a fake or ineffective medicine or solution sold with exaggerated claims of curing or fixing everything, the authors write that
Two tools that are designed to automate [PyPI] rebuilds and run them at scale are macaron and oss-rebuild. We study 12,180 popular releases from PyPI and find that the byte-for-byte equivalence rate is generally low. We analyse the reasons why they produce different wheels, and find that equivalence between the original and rebuilt wheels can often still be established, preserving most of the guarantees users expect from rebuildable releases. We present and evaluate daleq4py, a tool to establish the equivalence of Python wheels through the kernel of a normalisation function that is based on provenance-preserving datalog rules. Experimental results show that daleq4py substantially expands the set of rebuilds that can be accepted as equivalent.
pose a persistent threat to opensource software. Known attempts to inject such backdoors into widely used projects through malicious commits, tampered release packages, or compromised third-party dependencies, were stopped only by luck and manual review. Existing Continuous Integration (CI) pipelines cannot detect these attacks, and downstream binary analysis tools require substantial manual effort. In this work, we present Lily, an automated approach that strengthens open-source development and release processes against backdoor injection. Lily integrates a backdoor detection mechanism into (1) CI pipelines to block malicious commits, and (2) release vetting workflows to prevent tampered releases or compromised dependencies from entering large ecosystems, such as Linux distributions.
The full PDF can be read online.
Ranindya Paramitha and Laurie Williams of North Carolina State University along with Christian K stner of Carnegie Mellon University published a paper this month with the title of The Software Supply Chain as a Market for Lemons: A Multivocal Review of Trust Signal Collapse. (A lemon in American English, is a vehicle that turns out to have several manufacturing defects .) Their abstract is as follows:
Practitioners evaluating open-source dependencies rely on cheap trust signals, e.g., stars, download counts, and contributor activity, as substitutes for direct code inspection, assuming those signals reflect genuine trustworthiness. Prior work has documented individual signal gaming, but the landscape of collapses across all dependency-adoption signals, as well as the ecosystem s response, remains unexplored. The goal of this study is to aid software practitioners in understanding the reliability of dependency adoption trust signals, such as download counts and contributor activity, by conducting a multivocal review of 252 Google Search sources and 870 Reddit threads.
Worryingly, after their review, the authors conclude that cheap trust signals collapse under three simultaneous forces: adversarial manipulation, gaming techniques indistinguishable from legitimate behavior, and non-adversarial AI-driven inflation.
The full PDF of the paper is available online.
Julien Malka, Aman Sharma, Martin Monperrus, Stefano Zacchiroli and Th o Zimmermann published a paper this month on Trusting-Trust Attack against an Entire Linux Distribution through Binary Manipulation:
Ken Thompson s trusting-trust attack, in which a compromised compiler backdoors the programs it builds and reproduces the backdoor in subsequent rebuilds of itself, is widely regarded as a threat specific to compilers. We show that it is not. We construct a complete trusting-trust attack around GNU strip, an ordinary build utility that neither inspects nor generates source code, using only manipulations of finished ELF files.
Scarily, in the authors example, a single tampered strip in the binary seed implants a payload that propagates from one generation of strip to the next and survives into the final standard environment after the seed leaves the dependency closure [ ] without failures and backdoors .
A full PDF of the paper is available for download online.
Mehdi Keshanimm, Amirhossein Rahmati, Mohammad Hossein Aref and Abbas Heydarnoori published a paper that is currently under review at Emperical Software Engineering titled AROMA+: A Study of Factors Affecting Reproducible Builds in the Maven Ecosystem. (Maven is a/the build automation tool used for Java projects.) In their paper, the authors note that
[ ] reusing external software in a project presents a security risk when the source of the component is unknown or the consistency of a component cannot be verified. The SolarWinds attack serves as a popular example in which the injection of malicious code into a library affected thousands of customers and caused a loss of billions of dollars. [ ] Our research aims to support [reproducibility] efforts in the Maven ecosystem through automation. We investigate the feasibility of automatically finding the source code of a library from its Maven release and recovering information about the original release environment. Our tool, AROMA+, can obtain this critical information from the artifact and the source repository through several heuristics and we use the results for reproduction attempts of packages on Maven Central.
[A]rtifact verification requires more than deterministic builds: a verifier must also recover the source state, build environment, dependencies, and build instructions that produced the artifact. Decentralized-build ecosystems make this difficult because artifacts are produced through heterogeneous tools, maintainer-controlled workflows, and fragmented metadata. As a result, it remains unclear how often artifacts in these ecosystems can be independently verified. This paper studies artifact verifiability across four popular decentralized-build package ecosystems. We define an independent verifier model that relies only on registry-derivable metadata and an artifact comparison model with tiered equivalence levels. We implement these models in an Artifact Verification Pipeline and use it to measure artifact verifiability across the target ecosystems.
The authors conclude that beyond build determinism, verifiability is limited by missing source and build metadata, implicit release transformations, and unconventional build practices .
A PDF of their paper can be reviewed online.
Patches
The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including:
Two weeks ago, I released AppStream 1.2.0. This release contains a lot of great changes, but one of the most important ones concerns how media are being handled, and AppStream s default image export format.
AppStream is a Freedesktop metadata standard to describe software components. That can be anything from system services over fonts to console and graphical applications. AppStream metadata is supposed to give users enough information to decide whether they want to install a piece of software, to represent that piece of software, and to give the operating system enough information to decide whether a software component should be installed automatically and (to some extent) what capabilities and relations it has, to provide the user with sensible options.
Especially for the first two goals, and especially for GUI applications, AppStream supports icons and screenshots, which are used to showcase applications. Today, AppStream is used by all kinds of services, from Linux distributions over firmware updates to Flatpak and desktops directly. AppStream s original design however comes from the perspective of Linux distributions in 2011, where you may want to browse the software catalog offline, without delay, and without pinging an external server (which could be a privacy concern).
Therefore, a common way to deploy an AppStream-enabled software repository is to ship all icons of all applications in the repository to the user as part of the repository metadata download. AppStream does support remote icon downloads nowadays, and for a while I thought that this would become the default eventually. However, especially in today s world, having a bandwidth-saving, instantly responsive, privacy-protecting application browsing experience seems more important that ever.
PNG images are great!
The only format that AppStream supports for icons and screenshots (which are downloaded on-demand from your distributor s CDN) has always been exclusively PNG. PNG images are perfect for icons, because they compress well (especially for common icon shapes), are fast and simple to load, and can be loaded anywhere, by any toolkit or webbrowser. They also ensure we deliver faithful screenshot images, even though we may have scaled or re-rendered them. Still though, PNG images are less great for screenshots, as they are not very efficient, which puts strain on any CDN that has to deliver them, as well as on people s internet connections when browsing screenshots. Having smaller thumbnails alleviates that problem a little, but does not fully solve it.
But even for icons, PNG could be improved upon: In many cases, icons are re-downloaded with the repository metadata again and again, so having a large icon tarball adds up to the data transferred during metadata refreshes. AppStream also now supports large 128x128px icons, which nobody in 2012 expected we would need, adding even more data that will be re-downloaded. Saving some space here translates directly to lower bandwidth costs as well as faster downloads for users.
To improve PNG file sizes, the AppStream Compose library, which handles all image processing and metadata catalog composition, was running optipng on all generated PNG images. That does create smaller PNG images, but they were still relatively large compared to other image formats.
For a long time though, there was no alternative to PNG images for icons: There was no lossless image compression format that could give us the same quality as PNG images and that was also widely supported.
JPEG-XL vs PNG in AppStream
Since 2021 we have JPEG-XL (JXL), which offers a true lossless mode with often better compression than PNG. The issue was that JPEG-XL wasn t widely supported. Then, in 2025, the PDF Association selected JPEG-XL as the preferred image format for HDR images in PDFs, and now we are finally getting browser support and more ubiquitous availability of the format (you can try it right now in Firefox!).
For screenshots, using JXL s lossy mode, it has obvious and extreme size advantages over PNG, so supporting JXL or WebP for screenshot images was an obvious choice. If JXL would support the lossless case very well as well though, we could serve many use cases with the same exported image format, which is very attractive to me.
So, the obvious next question was whether it was worth the pain of switching the icon format, so I did some measurements on real icons. For that I used the AppStream component icon pool that Debian Unstable ships, which is almost 5000 application icons of various sizes, and converted them to PNG:
Icon size
Icons
PNG total
JXL total
Pool saved
PNG avg
JXL avg
Median saved
Mean saved
Worst
Best
Larger as JXL
48 48
1544
3.7 MiB
3.0 MiB
17.8%
2.4 KiB
2.0 KiB
17.9%
16.7%
-118.7%
60.0%
206
64 64
2018
7.0 MiB
5.8 MiB
17.8%
3.6 KiB
2.9 KiB
18.0%
15.8%
-112.7%
70.0%
279
128 128
1411
11.2 MiB
8.7 MiB
22.0%
8.1 KiB
6.3 KiB
20.1%
17.5%
-89.7%
61.0%
209
TOTAL
4973
21.9 MiB
17.5 MiB
19.9%
4.5 KiB
3.6 KiB
18.6%
16.6%
-118.7%
70.0%
694
PNG images saved with libpng at effort=4, compression=9, then optimized using optipng -o2, JXL images encoded using vips jxlsave lossless=1 effort=7 strip=1 via VIPS/libjxl.
As the table shows, using lossless JXL images over size-optimized PNG images (using optipng s default settings) provides a roughly 20% gain. This does not look like much, until you consider how often these files are downloaded: A 20% file size reduction may only save 1-2 MiB of disk space, but if they are downloaded over and over again by many clients, it will save a lot of bandwidth.
Interesting JXL encoding findings
As a sidequest, I was curious why some images were larger than their PNG counterparts when encoded with JXL, and what the ones that were significantly smaller were.
In short, the biggest size reductions for JXL existed on images that were already small as PNG, and contained large, flat color surfaces with hard edges and simple shapes. They were not very interesting, and much of JXL s wins come from accumulating smaller gains across all files, which compound the bigger icons get (especially at 128x128px, where JXL truly shines).
The events were JXL loses to PNG are more interesting: For example, it does quite poorly with pixel-art images that have a lot of repeating patterns. Those are encoded well by PNG, but less efficiently by JXL. Take for example Vonsh:
Icon of Vonsh, an SDL-based snake game, which PNG compresses better than JXL
My guess is that while PNG can exploit the repeating pixel patterns for compression, JXL s predicts surrounding pixels from its neighbours, which fails too often and makes it pay almost full entropy per pixel. In this single rare case, the PNG is at 5.4 KiB, while the JXL is almost 8 KiB in size.
Other cases I looked at were arguably buggy input data, where color channels were hidden under the alpha channel of the input image. PNG could probably again exploit repeats, while we were forcing JXL to encode pixels that were invisible in the final image. This is arguably a problem with the original input data. Currently, AppStream does not make any changes to icons at all, but in future we might add a filter that removes invisible colors from images to solve this pathological case (it was only two icons out of 5000 though, so it is not a high priority).
The third case I found where JXL loses to PNG were icons with checkerboard-like patterns:
Icon of x3270, an IBM 3270 Terminal Emulator
For those, PNG can likely again exploit the repeating patterns, while a checkerboard layout is pretty bad for left/top predictors like JXL s. However, in this case the size difference (and loss for JXL) is only 450 bytes, so even though JXL loses to PNG, it does so not by much.
JXL in AppStream
Given these findings, JPEG-XL is the default image format starting with AppStream 1.2.0. AppStream Compose will encode all images losslessly as JXL, while screenshots are encoded in lossy mode at Q=90 effort=7. Since the optipng step does not happen for JXL images, this comes at no speed penalty and is even a bit faster on modern x86_64 CPUs (where libjxl can use SIMD). PNG is still available, and Compose can be told to switch between the two formats.
Upsides of JXL in AppStream right now
If you use JXL in Compose or the recent release of appstream-generator, you will get much smaller images and, for screenshots, will benefit from other JPEG-XL features such as progressive decoding, providing a far nicer user experience. libAppStream has supported JXL icons since version 1.1.3, so your clients will need that version or a newer one, and all software centers will have to support loading JXL images (which all of them do, provided the right plugins are installed).
Downsides of switching to JXL too quickly
JXL is a very new format, so web browsers might not yet display it if you are serving webpages. Your clients may also have bugs in processing JXL images, as the format is still new . For example, switching on JXL in Debian sent KDE Discover into an infinite loop on startup while trying to load the icons (an issue which has been fixed, but clients will need that patch first before JXL is switched on).
This currently makes JXL enablement only possible when you know that your clients can support it. This is the case for me in Debian Unstable and Debian 14, which are using JXL images for a few weeks now, but not for any older releases. Platforms like Flatpak have it even harder, because they do know even less about their clients. So, even though it has big advantages, you may want to hold off on using JXL right away, and force PNG by setting the ImageFormat key to png in appstream-generator s configuration, or passing --image-format=png to appstreamcli compose.
It is also worth mentioning that JPEG-XL is much, much slower on systems that do not have SIMD instructions or for which the libjxl/jxl-rs library does not have them (such as apparently riscv64 right now). If this is a concern, you might not want to switch to JXL right away.
Media pipeline improvements
Besides the JXL default change, AppStream 1.2.0 also comes with a complete overhaul of its media processing pipeline. While libappstream, AppStream s main library, does not do any media processing and comes with very minimal dependencies to be embedded in client applications and used on servers, the same can not be said about libappstream-compose, AppStream s library to build metadata generating applications (the server-side part, usually).
The compose library has to render fonts into font specimen cards, inspect translation files, render SVG images, decode all kinds of raster images, inspect video files, etc. Especially the fonts, and the fact that fonts can appear in SVG images, has caused issues in the past, as libappstream-compose is a heavily threaded library and most font libraries can only work from a single thread. This forced the library to essentially go into single-thread mode anytime anything that could touch a font was being processed.
AppStream also originally was created for a safe world where applications were vetted by the distributors before their metadata was processed. This is increasingly not the case, so it made sense to put at least a few guardrails on the most complex part of the pipeline: The media processing. As part of the change, media processing was split out into a separate worker process. This solved two problems at once: Font handling was isolated in a single-threaded binary if we wanted to handle fonts in parallel, we could simply spawn more workers. And, being in a separate process, the media processing could now be sandboxed.
As part of the multiprocess changes, Compose also switched from using GdkPixbuf to VIPS for image processing. The latter allows for much more fine-grained control over the image output and encoding, and comes with a lot of well-maintained filters and operations, which made it possible to eliminate a fair chunk of AppStream s hand-rolled image processing operations. As part of this transition, we unfortunately lost the ability to read XPM images, which dropped about 20-30 applications from the pool at Debian. But in the name of security, this is a sensible choice, especially since most XPM icons were very small and low-resolution, and applications using them could benefit from adding a high-quality PNG icon anyway. With VIPS, we also now restrict the amount of image formats we can load to a sensible set, so extremely niche or unexpected formats will be outright rejected (this includes sane-but-unusual formats for screenshots and icons, such as TIFF images).
The Compose library, with all of these changes, will now just request high-level operations (e.g. render a font card for this font to a JXL image ) from the worker, and provide it with input data in sealed memfds and output locations as FDs as well. On Linux systems, the worker will use Landlock if available, to block all write access to the filesystem, deny device access and deny TCP and UDP as well. The sandbox can certainly be tightened a fair bit in future, but this was a good and safe start to gain some experience with it without having things break too easily, given the many places Compose is used in (also, Landlock s API is surprisingly nice to use, so it was easier than I thought to add in this early version).
With all of these changes, the libappstream-compose library is now also officially marked API-stable, so you should be able to rely on it in future to build new things (its API has barely changed in the past, and now with the new media API and defaults change in place, it was time to declare it stable).
I want to see / try this!
Currently, the easiest way to have a look at the new data is to check out Debian Unstable. If you have a JXL-enabled browser, you can also see the icons in AppStream Generator s HTML pages for Debian Sid. If you are using appstream-generator for your distribution, you will also get much more pleasant statistics and HTML pages, as well as fully deterministic media output and a whole bunch of security updates, so, update to its recent 1.0 release.
Please keep in mind that if you switch to JXL, the client tools receiving the image data have to support it. Support varies depending on the Linux distribution, so, test it first and switch the default back to PNG in case you encounter any issues.
What s next?
With so many features and changes landed, the next changes in AppStream will focus on improving what already exists and fixing any issues (there will be more blogposts about the other features 1.2.x delivers!). Testing with the entire Debian archive as data source makes me fairly confident though that there will not be many problems. In the longer term, tightening the media processing sandbox will also be something we might want to do, e.g. by hiding parts of the filesystem tree or filtering syscalls.
For JPEG-XL, one obvious question is Will you add support for it to the Freedesktop icon-theme specification as supported format alongside PNG, SVG(Z), and XPM? . For on-disk icon repositories, JXL s space-savings are less compelling, and it being HDR-capable is also not necessarily a killer feature (PNG can go a long way!). However, JPEG-XL s ability to immediately decode larger images at reduced resolution without resampling could legitimately be very powerful here, as applications could ship a single large image and quickly decode it at 1/2, 1/4 or 1/8 the size for different purposes in their UI. JPEG-XL also supports spot-color extra channels, which applications could use as masks to recolor raster icons at render time. This could be incredibly nice to color symbolic icons on-the-fly without any SVG and CSS. JXL also provides richer metadata, which might be neat for (license/author) documentation. So, the answer here is: Maybe it makes sense to allow another format, but this will have to be discussed first, as it would force JXL into every toolkit and desktop, which is a much bigger ask than supporting it only in AppStream.
As always, let me know what you think and please report any issues or bugs directly against AppStream or AppStream Generator if you encounter problems that are with the tools, and not with a project s metadata.
Armadillo is a powerful
and expressive C++ template library for linear algebra and scientific
computing. It aims towards a good balance between speed and ease of use,
has a syntax deliberately close to Matlab, and is useful for algorithm
development directly in C++, or quick conversion of research code into
production environments. RcppArmadillo
integrates this library with the R environment and language and is
widely used by (currently) 1331 other packages on CRAN, downloaded 48.5 million
times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint
/ vignette) by Conrad and myself has been cited 727 times according
to Google Scholar.
This versions updates to the 15.6.0 upstream Armadillo release made
yesterday. It extends solver options for poorly conditioned systems, and
brings some updates and extension to the cube data type.
For this release, we once again ran the usual complete
reverse-dependency check which came back spotless, and did CRAN so no
email exchange needed despite nearly 1300 reverse dependencies (but it
ended up taking more than a single business day). Still, automation can
be helpful when used with a well-maintained software stack. The package
has also already been updated for Debian, built for r2u and r-universe, and
will build shortly at CRAN for
the different binary releases.
All changes since the last CRAN release follow.
Changes in
RcppArmadillo version 15.6.0-1 (2026-09-07)
Upgraded to Armadillo release 15.6.0 (Medium Roast Cortado)
Expanded solve() with
solve_opts::scale_thresh option to widen detection of
poorly conditioned systems
Expanded trans() and .t() to handle
cubes
Added permute() to rearrange dimensions of cubes
(generalised transpose)
Added cubemul() for batched matrix multiplication of
cube slices
About the project and me
Your program crashes. You open gdb and get ?? instead of a stack trace. So
you go find the right -dbgsym package, for the right version, for the right
architecture, install it, and start again.
Debuginfod removes that
entire detour: gdb asks a server for symbols by the build-ID baked into the
binary. Debusine already built packages, already produced -dbgsym files, and
already hosted the archives; it just couldn t answer the question.
This summer I made it answer. My project was to add debuginfod server
functionality to Debusine so that it not only hosts -dbgsym packages, but
also serves their debug symbols over the
debuginfod(8)
protocol. Debian developers can then debug binaries by setting a single URL
that gdb uses to fetch the matching debug symbols. This project took me
through design, backend work, an extraction pipeline on the worker, HTTP
serving, documentation, and testing from the first blueprint all the way to
a live demo on debusine.debian.net.
Initial planning and design changes
A design first, in
!3030.
The proposal submitted for GSoC 2026 was just an overview of how things will
work, but in reality there were a lot of design questions which needed to be
answered before starting with contribution. Debusine keeps development
blueprints in its docs tree, reviewed like code, it s basically a blueprint
of what feature or new changes are we going to make. I was assigned the work
item
#957,
which was basically about how the idea of implementing a debuginfod server
functionality inside Debusine was initially proposed by a fellow member
which later became a project idea under GSoC 2026. My developer blueprint
pinned down the four decisions everything else depends on: extraction
happens on the worker after the build, symbols are stored as artifacts keyed
by build-ID, they re published into suites alongside their binaries, and
they re served from the archive root rather than per-suite. Settling that up
front meant the design discussions happened in a document instead of across
three merged branches.
One of those arguments became its own fix. My wording implied symbols were
unpacked inside the isolated sbuild environment (the consequence was I was
handed a
bug to
be solved in the first week of contribution period), when they re actually
extracted afterwards on the worker, where the build output already sits, a
distinction that matters, because doing work inside the unshare environment
means extra tooling in the chroot and more ways to affect the build.
!3119
corrected it before the wrong model spread into the code.
A new artifact type
Artifacts
are a major concept in Debusine overall, so as per the developer blueprint
we introduced a new artifact which was
debian:debug-symbols.
It holds every .debug file from one -dbgsym package. Its data is a validated
list of lowercase 40-character build-IDs, and each file is stored under its
build-ID as the path, so answering what are the symbols for this ID? is a
direct lookup, with no path translation in the request handler. One artifact
per package rather than per file: a util-linux build would otherwise spray
hundreds of artifacts, collection items and relations across the database
for no benefit. For implementing debian:debug-symbols artifact, I changed
the main
models.py
file, along with that since it s a norm to write unit tests, all mentioned
under
!3088.
Publishing workflow and solving a bug
Extracting symbols is only useful if they reach the archive people actually
install from, so
!3180
taught package_publish to follow the relates-to relation: copying binaries
into a suite now brings their debug symbols along automatically, with
nothing extra for the publisher to configure. Each build-ID becomes its own
collection item, for example debugsym:hello_2.10-5_amd64_fcc9064 each
carrying the package name, version and architecture copied from the binary,
so the item is meaningful on its own without dereferencing anything.
Uniqueness is enforced at both the suite and archive level, because the
serving URLs are archive-wide and two suites must never disagree about what
a build-ID means: republishing an identical file is accepted quietly, while
two different files claiming the same ID is an error worth failing on. A
partial index on the build-ID keeps the eventual HTTP lookup fast.
That looked finished until symbols started arriving in target suites
disconnected from their binaries published, but unfindable, because copying
items between collections silently dropped their artifact relations, and
that relation is the only thing tying the two together. The fix sat one
level above my feature, in the generic CopyCollectionItems task that does
the copying, and since it was reusable infrastructure rather than anything
debuginfod-specific, Colin implemented it himself in
!3228.
My project needed it to work at all; every other Debusine feature that
copies items now gets it for free.
Endpoint and CI tests
With symbols in the archive,
!3212
added the part users actually touch: GET / scope / workspace /buildid/<build-id>/debuginfo looks the ID up across
every suite in that workspace s archive, streams the file, and sets the
X-DEBUGINFOD-FILE and X-DEBUGINFOD-SIZE headers the protocol expects. It
also handles the two things gdb actually does: a HEAD probe before
committing to a download, and ranged requests to pull individual ELF
sections instead of the whole file. Scoping it to the archive rather than
the suite is what lets one URL cover a whole workspace, so the developer
never has to know which suite their binary came from.
Every merge request above landed with unit tests, but those only tell you
that the pieces behave correctly. What Colin and I wanted was a real gdb
fetching real symbols from a real instance, so
!3261
adds an autopkgtest that builds a package, publishes it, checks the HTTP
headers, then sets DEBUGINFOD_URLS and makes gdb go and get the symbols,
wired into the CI integration tests so it runs on every change. It took me a
day to learn that skipping the signing worker doesn t simplify that test, it
just hangs until the 30-minute timeout, because update_suites needs signing
to produce a usable repository.
The last piece,
!3301
covers the new artifact, the suite and archive changes, the new archive URL,
and a how-to for using it. My first how-to draft explained how everything
worked and offered four ways to set DEBUGINFOD_URLS; the version that
shipped gives one recommended setup and gets out of the way. The same pass
trimmed the blueprint down to only what s still unimplemented, since a
design document describing merged code is just an obstacle for the next
reader.
What s left
Only one item on my original plan didn t land: an archive-level
build_debug_symbols switch, modelled on Launchpad s equivalent, letting an
archive skip building -dbgsym packages entirely by passing
DEB_BUILD_OPTIONS=noautodbgsym to sbuild. It was always the stretch goal
rather than core scope, landing the extract-publish-serve path solidly
mattered more than landing it broadly. The design is written up in the
blueprint, and I intend to implement it myself.
The other gaps were deliberately out of scope from the start, and the
blueprint says so. DWZ supplement files aren t ingested, so packages using
compressed debug info may render without the alternate strings table;
debugging still works, it s just less complete. Source-file serving runs
into the same Debian packaging limits that constrain debuginfod.debian.net
today, making it a design question rather than a coding one. Executable
serving, the metrics and metadata endpoints, and federation to upstream
debuginfod servers were excluded for similar reasons, none of them are
needed for Debusine s core use case, and each would have crowded out the
parts that are.
One open bug is left too. On the last day of the coding period, Stefano
Rivera found that publishing ledger and linux was failing, because I had
told the database that a build-ID identifies one exact debug file which
isn t true in Debian, since dh_dwz runs once per binary package, so when one
object ships in two binary packages their .debug files differ while
describing identical code. How to fix it is still an open discussion
#1582,
though it may not land before the formal end of the project.
None of that is a handoff. GSoC s timeline is ending, my involvement isn t,
I m carrying on with Debusine until both the build_debug_symbols switch and
DWZ supplement support are merged, and I expect to keep contributing beyond
that. This project got me familiar with a codebase I enjoy working in, and
the remaining pieces are mine to finish.
Thanks!
The biggest thanks go to my mentor, Colin Watson, whose reviews consistently
found the thing I hadn t thought about. He also gave me room to get things
wrong first and understand why, which taught me more than being handed the
answer would have.
Thanks as well to Rapha l Hertzog, Enrico Zini, Stefano Rivera, Carles Pina
i Estany and Helmut Grohne and everyone else around Debusine and Freexian
for reviews, comments and patience with my questions.
Special thanks to Freexian for developing Debusine in the open and for
giving me access to test on
debusine.debian.net.
Finally, thanks to the wider Debian community, whose build-ID and -dbgsym
conventions did most of the hard work before I arrived and to Google Summer
of Code for providing a platform and the time to do this properly.
This August, I accomplished what I wanted for many years: I deleted the last cgo
dependency in Debian Code Search! This was made possible by Go s recently
introduced SIMD support, because now we can implement the TurboPFor integer
compression format as efficiently more efficiently, in fact, by using the
newer AVX512 instruction set! as the reference implementation.
Background: Why does DCS need a fast Integer Codec?
Debian Code Search (DCS) is a search engine that allows searching all the Open
Source source code within Debian, with either literal search expressions or
regular expression search queries.
A search engine uses an inverted index: a map from term to documents containing
the term. Each document is typically represented most efficiently by using an
id, so the index consists of many lists of document ids.
When searching, it is important to quickly decode these lists to answer the
search query. However, there is a point of diminishing returns where the
decoding speed, even though it can still be measurably improved quite a bit, no
longer influences the overall query duration.
From 2012 (its inception) to 2019, Debian Code Search used to use a small index
format, and queries were fast because the index was kept entirely in RAM. In
2019, I implemented the new index
format, which adds an
on-disk positional index. For literal queries (78.2% of DCS queries), querying
the positional index on disk is faster than querying the non-positional index in
RAM.
The efficient encoding of the TurboPFor format makes it possible to fit such an
index on a mid-sized Hetzner server, which I rent with two 1 TB SSD disks. The
optimized decoder of the C TurboPFor library is what made decoding fast at query
time.
If you want to dive deeper into the algorithm, see this blog post from February
2019:
Use a C library via cgo so gcc or clang compiles
SIMD code. Debian Code Search used to use the
powturbo/TurboPFor
C library via cgo for the last 7 years.
The C TurboPFor library has served us well, but Debian Code Search was always
intended to be a project using Go, so I would prefer it if I did not have any C
code in the project.
Go 1.26 (released in February 2026) introduced the simd/archsimd package:
Go 1.26 introduces a new experimental simd/archsimd
package, which can be enabled by setting
the environment variable GOEXPERIMENT=simd at build time. This package
provides access to architecture-specific SIMD operations. It is currently
available on the amd64 architecture and supports 128-bit, 256-bit, and
512-bit vector types, such as Int8x16 and Float64x8, with operations such
as Int8x16.Add. The API is not yet considered stable.
Go 1.26 Release Notes
For my 2019 TurboPFor analysis, I implemented goturbopfor, a native Go
teaching decoder (without any SIMD),
because I find Go code easier to follow than C code, especially optimized C
code. My implementation was intentionally not optimized so that the code was
easier to study.
The TurboPFor format/algorithm has a vector-optimized part: bitpacking comes in
a scalar variant (bitunpack32) and a vector variant
(bitunpack256v32),
where the vector variant is used for full blocks (256 values) and the scalar
variant is used for remainder blocks (< 256 values).
When Go 1.26 was released, I used Claude Code to explore whether my native Go
decoder s bitunpack256v32 function (for the vertical vector layout) could be
implemented using Go SIMD, and the answer was yes, it was possible and it was
faster than without SIMD, but not quite at the level of C TurboPFor. If you let
Claude Code try for long enough, it eventually finds enough optimizations (about
10) to match C performance.
I don t want to vibe-code Debian Code Search, though, so I figured I would find
some time to review the SIMD code at some point and see if I could implement
something similar myself.
Before I found enough time and motivation to complete said review, I discovered
that to not regress real-life query performance by more than 10 to 100
milliseconds (which seems acceptable), I don t actually need to add SIMD code to
my teaching decoder at all; it would be sufficient to reduce allocations in my
teaching decoder and specialize it per bit width.
Encouraged by the possibility of using the optimized native Go decoder in Debian
Code Search, I explored whether I could also implement a native Go encoder so
that I could get rid of the C TurboPFor dependency entirely. The answer is yes,
it is doable in a few days, and it isn t even that much slower: Go is at 76% of
C, see Debian/dcs commit
e920dc7.
The goal I set myself at that point was to see if I could learn enough SIMD to
optimize the native Go encoder such that its performance would match how DCS
uses C TurboPFor (via cgo).
Beating C TurboPFor was possible in 2-3 commits (SIMD and bit width
specialization). To my surprise, Claude Fable 5 pointed out that the encoder s
block scanning could be done more efficiently using a technique called
positional popcount, and that is another 2x speed-up!
To be clear: I am not saying the Go compiler beats C here. Certainly, the C
compiler can also produce fast AVX512 code and can be used to implement
positional popcount. When comparing apples to apples, i.e. backporting the
AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a
little slower at 1.4x C.
This spectacular result (much faster than what DCS had before) got me curious
how far I could push the decoder with SIMD after all. I ended up
matching/exceeding the cgo version here, too!
The rest of this article explains a few classes of optimizations I encountered
along the way.
Starting Point
When I wrote my goturbopfor teaching
decoder, I named its functions to
match the upstream C TurboPFor library, but now I want to get away from names
like p4ndec256v32 they make sense from the TurboPFor perspective, but for
Debian Code Search, we can use cleaner names.
Before writing any code, I audited how DCS uses integer compression /
decompression.
API design: BlockEncoder, BlockDecoder and streaming
In Debian Code Search, we have the following usage patterns:
Partial Indexing: When a new package (or package version) enters Debian,
all of its (text) files are indexed. If the hello-2.12.3-1
package (hypothetically) contained
only hello.c with printf("hello!\n");, we would assign document ID 1 to
hello.c and store in the partial index that trigrams pri, rin, int,
ntf, etc. are all found in doc 1 (hello.c).
Full Index Merging: The many thousands of partial index files (for each
Debian package) are combined into a small handful of large index files: When
searching, it would be expensive to consult thousands of indexes. To merge
multiple partial index files into one larger index (which can then be
efficiently queried), we need to re-encode the partial index files: what used
to be document ID 1 in the partial index might be document ID 2531 in the
full index.
Querying (searching): When users enter search queries, these queries need
to be answered as quickly as possible. The relevant entries in the full
indexes are decoded (in parallel).
For reading the index, we do keep the decoded uint32s fully in memory, so we
only need DecodeN(input []byte, output []uint32) (read int), a function that
reads len(output) values (uint32) from input and returns how many bytes it
consumed.
For writing the index (both in partial indexing, and when merging), keeping the
entire index in memory is prohibitively expensive, so we need a streaming API,
for decoding and for encoding.
Ultimately, I converged on the following API:
packagepforenctypeBlockEncoderstruct// scratch buffers can go here// EncodeBlock encodes len(vals)<=256 uint32s into dest (one TurboPFor block).func(*BlockEncoder)EncodeBlock(dest[]byte,vals[]uint32)[]byte// EncodeN calls EncodeBlock in a loop.func(*BlockEncoder)EncodeN(dest[]byte,vals[]uint32)[]bytetypeStreamEncoderstructbeBlockEncodervals[256]uint32// scratch buffers// if full, you need to call [EncodeBlock]func(*StreamEncoder)Add(valuint32)(fullbool)// EncodeBlock must be called after all data was [Add]ed.//
// Write the returned buffer to file or send it over the network;// it is only valid until the next [EncodeBlock] call.func(*StreamEncoder)EncodeBlock()[]byteifse.n==0returnnil// turn an extra EncodeBlock into a no-op//
This API (the decoder works similarly) allows us to process data in TurboPFor
format without any memory allocations. The types are not safe for concurrent use
by multiple goroutines. The zero value is ready to be used. For the streaming
API, the result only stays valid until the next call.
Initial Implementation
Before we can optimize anything, we need a working decoder and encoder. The
decoder already exists: my goturbopfor teaching decoder. Next up, I needed an
encoder.
Writing a TurboPFor encoder has a delightfully simple starting point: You can
encode all values at bit width 32, in little endian, at which point you only
need to add a one-byte TurboPFor block header every 256 values and you re done:
Of course, this is a terribly inefficient compressor, so after the first commit,
the real work starts: implement each block type until the compression matches
the original C TurboPFor implementation (same output file size), or in other
words: do the reverse of the decoder.
The TurboPFor bitpacking block type (bitpacking implementation
commit)
encodes a bit stream of variable bit width (where the bit width is in range
0 bitWidth 32) in little
endian byte order. By scanning all
values and choosing the smallest bit width that allows representing all
values, this technique saves disk space (compresses).
The bitpacking with exceptions block type (bitpacking with exceptions
implementation
commit)
determines two bit widths: one for values, the other bit width for encoding
exceptions. This allows choosing a lower bit width (that does not cover all
values) compared to the bitpacking block type. A bitmap encodes whether a
value has an exception or not.
The bitpacking with VB exceptions block type (bitpacking with VB
exceptions implementation
commit)
is a variant which does not use an exception bitmap and encodes exceptions
using a variable byte integer encoding. This is more efficient when there are
few exceptions (less than 20) or the exceptions are very different in bit
width compared to the other values.
Lastly, the constant block type (constant implementation
commit)
stores just one value on disk. This is useful for all-zero or all-one blocks,
for example.
I found it interesting to realize that the main work of the encoder is to scan
the input values and choose the optimal block type, whereas the actual encoding
itself is cheap in comparison.
At this point, we can look at
performance
and see that the Go encoder is at 76% of the C encoder.
In all honesty, I could have probably stopped here, but now that the milestone
of a viable replacement was reached, I got curious to see how far it would be
possible to push the encoder (how much work to reach C speeds?) and afterwards,
the decoder, too.
Setup
The microarchitecture level: set GOAMD64
The microarchitecture of a CPU determines which instructions it provides, and
that includes not just SIMD instruction sets (like AVX2), but also other useful
instructions like LZCNT (Leading Zero Count), which can be used to implement
math/bits.Len32 more efficiently, which
the TurboPFor encoder needs to call on every input value to determine the ideal
bit width.
Let s walk through how to set the microarchitecture level when using Go on
64-bit x86 (x86-64).
Go uses the GOARCH environment
variable to configure the target
compilation architecture, and I am using the value amd64 to select 64-bit x86
(AVX2 and AVX512 are instruction sets found on x86-64 CPUs). With
GOARCH=amd64, the architecture-specific variable
GOAMD64 configures the
microarchitecture level for which to compile and Go 1.18 introduced these 4
different levels:
GOAMD64=v1 (default): The baseline.
Exclusively generates instructions that all 64-bit x86 processors can execute.
GOAMD64=v2: all v1 instructions,
plus CMPXCHG16B, LAHF, SAHF, POPCNT, SSE3, SSE4.1, SSE4.2, SSSE3.
GOAMD64=v3: all v2 instructions,
plus AVX, AVX2, BMI1, BMI2, F16C, FMA, LZCNT, MOVBE, OSXSAVE.
GOAMD64=v4: all v3 instructions,
plus AVX512F, AVX512BW, AVX512CD, AVX512DQ, AVX512VL.
In 2026, I generally recommend compiling with GOAMD64=v3 so that functions
like bits.OnesCount8 are
compiled into intrinsics
(POPCNT)
instead of using a lookup table.
For Intel CPUs, setting GOAMD64=v3 means your programs will only start on
Haswell CPUs (2013) or newer; for AMD CPUs that means Zen 1 (2017) or newer.
In this specific case (DCS), I am even compiling with GOAMD64=v4. The v4
microarchitecture level requires AVX512, which means AMD Zen 4, Zen 5 or newer
(Intel s story is complicated). Luckily, both my main development PC (Zen 5)
and the Debian Code Search server (Zen 4) are recent enough. Setting
GOAMD64=v4 has little effect on Go 1.27 itself: the only change is that maps
use one less instruction (VPBROADCASTB instead of PSHUFB). But compiling
with GOAMD64=v4 allows us to move one more feature check from runtime to
compile time, see SIMD build tags.
It makes sense to set the microarchitecture level in your benchmark setup so
that you don t measure the slow fallback implementations. I use export GOAMD64=v4 in my Makefile.
Benchmarking setup
Go s built-in testing package contains support for
benchmarks which are written in
functions of the form func BenchmarkXxx(b *testing.B). The simplest way to run
such benchmarks is go test -bench=., but I ended up configuring a few
convenience make targets, which write results to bench.txt and compare
against baseline.txt (the previous commit s results, usually), using the very
useful benchstat tool.
GOTEST=go test# -count=6 gives p 0.002 in benchstat:
# https://pkg.go.dev/golang.org/x/perf/cmd/benchstat
BENCHFLAGS=-run=^$$ -bench=. -benchtime=200000x -count=6# use taskset -c1 to always pin to the same single core,
# avoiding accidental scheduling on different cores on
# mixed-core CPUs like the Ryzen 9 9950X3D.
TASKSET=taskset -c 1BENCH=$(TASKSET)$(GOTEST)$(BENCHFLAGS).PHONY: all test bench bench-baseline bench-relative
all: test
bench: test
$(BENCH) tee bench.txt
# Compares compression ratio between C and Go implementation
benchstat -col /impl -row '/n /vals' -filter '-/impl:go-stream .unit:(encoded-bytes)' bench.txt
# Compares performance between C (cgo) and Go implementation
benchstat -col /impl -row '/n /vals' -filter '.unit:(Mval/s)' bench.txt
bench-baseline: test
$(BENCH) tee baseline.txt
bench-relative: test
$(BENCH) tee bench.txt
benchstat -filter '-/impl:go-stream .unit:(encoded-bytes)' baseline.txt bench.txt
benchstat -filter '/impl:go .unit:(Mval/s)' baseline.txt bench.txt
The encoded-bytes and Mval/s units are custom metrics I am reporting from
the various sub-benchmarks, which are arranged
such that I can filter / report them with benchstat.
The main encoder (and decoder) benchmarks compare 3 different implementations
(cgo, Go, Go with the StreamEncoder API) with a number of benchmark
cases
that are designed to cover the different block types and contain a similar mix
of values as what we see in Debian Code Search:
// reportMetrics adds Mval/s and encoded-bytes metrics to all benchmarks.funcreportMetrics(b*testing.B,nint,nencodedint)b.ReportMetric(float64(nencoded),"encoded-bytes")b.ReportMetric(float64(b.N*n)/1e6/b.Elapsed().Seconds(),"Mval/s")// BenchmarkEncode/n=<N>/vals=<testcase>/impl=<c go go-stream>//
// e.g. BenchmarkEncode/n=2048/vals=one-constant/impl=go-streamfuncBenchmarkEncode(b*testing.B)for_,tc:=rangeallBenchCases()n:=len(tc.vals)b.Run(fmt.Sprintf("n=%d/vals=%s",n,tc.name),func(b*testing.B)b.Run("impl=c",func(b*testing.B)b.ReportAllocs()varencoded[]bytebuf:=make([]byte,turbopfor.EncodingSize(n))forb.Loop()encoded=turbopfor.P4nenc256v32Buf(buf,tc.vals)reportMetrics(b,n,len(encoded)) )b.Run("impl=go",func(b*testing.B)b.ReportAllocs()varbeBlockEncodervarencoded[]bytebuf:=make([]byte,0,turbopfor.EncodingSize(n))forb.Loop()encoded=be.EncodeN(buf,tc.vals)reportMetrics(b,n,len(encoded)) )b.Run("impl=go-stream",func(b*testing.B)b.ReportAllocs()varseStreamEncodervarencodedintforb.Loop()encoded=0for_,val:=rangetc.valsifse.Add(val)encoded+=len(se.EncodeBlock())encoded+=len(se.EncodeBlock())reportMetrics(b,n,encoded) ) )
CPU counters: perf
Go has included excellent performance tooling for many years, see the
Profiling Go Programs blog post (2011) for an
example of how to use pprof, a sampling profiler. This profiler can help track
down which part of a program runs slow, or where memory allocations happen.
Once you identified the slow part of a program, how do you know why it s slow?
To learn more about the specific bottlenecks your program encounters, you can
consult your CPU s hardware performance
counters. For
example, you could check the branch
predictor counters to see if
your program is slow due to a high number of branch mispredicts.
On Linux, the perf tool is the best way to access the CPU hardware performance
counters. A good starting point for working with perf is the documentation on
Top-down analysis with the perf
tool , which describes the
optimization method that Intel established.
In my Makefile, I set up two perf targets:
# GOTEST and TASKSET like shown in the earlier benchmarking setup section:
GOTEST=go test -pgo=encode.cpuprof
TASKSET=taskset -c 1PERFBENCHFLAGS=-test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=200000x
# Use perf(1) to capture AMD IBS (the equivalent to Intel PEBS)
# PipelineL1 is roughly equivalent to Intel TopdownL1
perf:$(GOTEST) -c
$(TASKSET) perf stat -M PipelineL1 ./pforenc.test -test.run=^$$$(PERFBENCHFLAGS) sudo perf record -F 4999 -e ibs_op// --call-graph fp ./pforenc.test -test.run=^$$$(PERFBENCHFLAGS) sudo chmod 644 perf.data
# 488281 iterations 2048 values = 1.000e9 values, so counter/1e9 = per value.
perf-per-value:$(GOTEST) -c
$(TASKSET) perf stat -x, -e cycles:u,instructions:u,branches:u,branch-misses:u ./pforenc.test -test.run=^$$ -test.bench='Encode/n=2048/vals=debian-mix/impl=go$$' -test.benchtime=488281x 2>&1 >/dev/null awk -F, ' printf "%-16s %6.2f /val\n", $$3, $$1/1e9 '
The perf-per-value numbers are high level numbers that indicate how much work
the implementation is doing. Reducing the number usually increases speed.
To see the counters for each instruction (and source code lines), I use make perf, followed by perf report. A quick shortcut is perf annotate, which
directly shows the hottest function.
Optimizations (scalar)
Let s first see how far we can get without reaching for SIMD instructions.
(The examples are not necessarily in commit order, but cherry-picked for clarity.)
Profile-Guided Optimization (PGO)
PGO stands for Profile-Guided Optimization and is a feature that Go introduced
as a preview in Go 1.20 (released in February 2023) and shipped as ready for
general production use in Go 1.21 (released in August
2023).
The idea is to capture a CPU profile that records where your program spends most
of its CPU time, which you then provide to the Go compiler to give it more data
to make better decisions.
Most importantly, this way the Go compiler can inline functions much more
aggressively than its usual heuristics allow,
which does have a measurably positive effect in my series of optimization
commits. Another optimization that a PGO profile allows the compiler to do is
conditional devirtualization but
our TurboPFor code does not use any interfaces.
My strategy is to enable PGO before doing any other optimizations, so that we
have the full inlining budget available that PGO gives us, and can measure the
effect of other commits clearly.
Surprisingly, turning on PGO actually decreases our
performance
(-13% geomean), but a closer investigation reveals that we just got unlucky. Let
me explain.
Aside from inlining and conditional devirtualization, PGO also influences
alignment: The Go compiler sets PCALIGNMAX(64, 31) on the first block of a
loop (the loop body ) for all loops in hot functions (per the PGO profile),
i.e. Go will insert up to 31 bytes of padding to make the block land on a
64-byte boundary. Documentation like AMD s Software Optimization Guide for the
AMD Zen5 Microarchitecture (2024,
#58455) explicitly recommends aligning hot loops that way:
[ ] for hot loops, some further knowledge of trade-offs can be
helpful. Because the processor can read an aligned 64-byte fetch block every
cycle, it is suggested to either align the start of the loop to the beginning
of a 64-byte cache line [ ]
Indeed, when compiling with -gcflags=all=-d=alignhot=0 to disable the
alignment, performance remains as good as without PGO. How can the padding hurt
more than help? The answer is: It s not the padding itself! It s a side-effect
of the padding moving instructions to different addresses.
In the unlucky arrangement, a macro-fused CMPQ+JGE instruction pair now ends
up exactly on a 32-byte boundary. However, the Go compiler ensures fused
branch sequences must never cross or end at a 32-byte boundary to fix Intel
erratum
SKX102
(discussion: Go issue #35881) by
inserting NOPs.
This NOP padding, unlike the loop alignment padding, is not free; these extra
instructions slow down our otherwise dispatch-bound loops.
Because the commits after the PGO enabling commit change the code, this unlucky
situation is avoided for the rest of the optimization series (by chance).
Reducing memory allocations
Memory allocations are quite expensive, at least in comparison to
encoding/decoding integers, so I followed my usual strategy of first reducing
memory allocations as much as possible.
In my goturbopfor teaching decoder, whenever the code needed a scratch buffer,
it would allocate it right then and there with make():
// p4dec32 decodes one block of TurboPFor-encoded 32 bit intsfunc(d*decoder)p4dec32(input[]byte,output[]uint32)(readint)// switchblockTypecaseblockBitpackingExceptions:bx,input:=input[0],input[1:]n:=len(output)exmap:=inputnex:=0// number of exceptionsfori:=0;i<n;i++ifexmap[i/8]&(1<<uint(i%8))!=0nex++input=input[(n+7)/8:]exceptions:=make([]uint32,nex)input=input[bitunpack32(input,exceptions,bx):]input=input[d.bitunpack(input,output,b):]fori:=0;i<n;i++ifexmap[i/8]&(1<<uint(i%8))!=0output[i]+=exceptions[0]<<bexceptions=exceptions[1:]returnbefore-len(input)
The Go compiler can turn make(T, n) calls into stack allocations, if n is
known at compile-time. But, in this case nex is not known at compile-time. We
can verify that Go calls into the runtime (runtime.makeslice) by dumping the
object code (assembly) with source annotated (-S):
An easy speed-up was to avoid allocations through
reuse
(in goturbopfor). In the DCS pfordec package (with the improved
API design), I ended up with a vals [256]uint32 field in the StreamDecoder
type, which brings us from 773 Mval/s to 858 Mval/s on the debian-mix:
Aside from the speed-up, avoiding memory allocations is generally nice in
benchmarks because it removes the garbage collector from the equation and makes
it less likely that your benchmarks get other processes OOM-killed on the same
machine.
Generics for bit width specialization
In general, we want to make it easy for the compiler to understand as much as
possible about our algorithm. Consider this bitpack implementation:
Let s think through what determines the iterations and control flow this
function uses:
The number of input values (vals), but not their actual value.
The bit width to pack into (bitWidth).
With a bit of careful rearrangement, we can provide the compiler with both, a
fixed number of input values (say, 32), and a bit width, both known at compile
time. Why is this worthwhile? Because we can manually unroll the loop, let the
compiler eliminate much of the repetition and get much faster compiled code as a
result!
Let s first fix the number of input values to 32 and rewrite the loop to
calculate the position offsets within dest instead of changing dest on each
value (with AppendUint32):
funcbitpack32Unrolled(dest[]byte,vals*[32]uint32,bitWidthint)// only one bounds check for 32 valuesdest=dest[:4*bitWidth:4*bitWidth]mask:=uint32(1<<bitWidth-1)varaccuint64varhave,posint// Manually unrolled loop starts here.// Each iteration is identical except for the vals[x] index.acc =uint64(vals[0]&mask)<<havehave+=bitWidthifhave>=32binary.LittleEndian.PutUint32(dest[pos:pos+4],uint32(acc))pos+=4acc>>=32have-=32// vals[1] .. vals[30] elided for brevity// Each loop iteration is 8 lines of Go code, so for 32 input values,// bitpack32Unrolled contains 8*32 = 256 lines of code.acc =uint64(vals[31]&mask)<<havehave+=bitWidthifhave>=32binary.LittleEndian.PutUint32(dest[pos:pos+4],uint32(acc))pos+=4acc>>=32have-=32// have == 0; for all bitWidths
Next, we want to specialize not just for 32 input values, but also for each of
the 32 bit widths.
Can we do better than hand-copying bitpack32Unrolled 32 times (= 8192 lines of Go code)?
Yes, we can use Go generics to help us with the code generation!
In Go, array types like [4]byte (not
slices like []byte!) contain the length of the array as part of their type,
meaning [1]byte (an array of length 1) is a different type than [2]byte.
Instead of passing the bit width as a function parameter, we can declare 32
different types (one for each bit width) and recover the bit width (at compile
time!) from the type system:
typebitWidthTinterface[1]byte[2]byte[3]byte[4]byte[5]byte[6]byte[7]byte[8]byte[9]byte[10]byte[11]byte[12]byte[13]byte[14]byte[15]byte[16]byte[17]byte[18]byte[19]byte[20]byte[21]byte[22]byte[23]byte[24]byte[25]byte[26]byte[27]byte[28]byte[29]byte[30]byte[31]byte[32]bytefuncbitpack32Unrolled[TbitWidthT](dest[]byte,vals*[32]uint32)varzeroTbitWidth:=len(zero)// known at compile timedest=dest[:4*bitWidth:4*bitWidth]// make cap known at compile timemask:=uint32(1<<bitWidth-1)varaccuint64varhave,posint// Manually unrolled loop starts here.// Each iteration is identical except for the vals[x] index.acc =uint64(vals[0]&mask)<<havehave+=bitWidthifhave>=32binary.LittleEndian.PutUint32(dest[pos:pos+4],uint32(acc))pos+=4acc>>=32have-=32// vals[1] .. vals[31] elided for brevity
When we instantiate bitpack32Unrolled[bitWidthT] with all 32 different types
([1]byte, [2]byte, , [32]byte), the compiler substitutes the bitWidthT
type parameter and produces 32 copies of the function, which we can find in our
compiled executable with names like
github.com/Debian/dcs/internal/turbopfor/pforenc.bitpack32Unrolled[go.shape.[12]uint8]. The
shape of a generic type is based on its memory layout, so a shape for
[1]byte must be different than the shape for [2]byte.
Because the bitWidth is now known at compile time, the Go compiler can
generate close to the optimal machine code for each bit width, which we can
confirm using go tool objdump.
The code is branchless (after the one bounds check per 32 values) and aside from
the loads and stores (from/to memory) consists only of shifts and bit
operations, all with constant operands:
Now we need to actually call bitpack32 from the general bitpack function:
funcbitpack(dest[]byte,vals[]uint32,bitWidthint)[]byteifbitWidth==0returndest// no payload, sparse block with only exceptionsiflen(vals)>=32size:=4*bitWidthforlen(vals)>=32existing:=len(dest)dest=slices.Grow(dest,size)[:existing+size]bitpack32(dest[existing:]/*append*/,(*[32]uint32)(vals),bitWidth)vals=vals[32:]mask:=uint32(1<<bitWidth-1)varaccuint64varhaveintfor_,val:=rangevalsacc =uint64(val&mask)<<havehave+=bitWidthforhave>=32dest=binary.LittleEndian.AppendUint32(dest,uint32(acc))acc>>=32have-=32forhave>0dest=append(dest,byte(acc))acc>>=8have-=8returndestfuncbitpack32(dest[]byte,vals*[32]uint32,bitWidthint)switchbitWidthcase1:bitpack32Unrolled[[1]byte](dest,vals)case2:bitpack32Unrolled[[2]byte](dest,vals)case3:bitpack32Unrolled[[3]byte](dest,vals)case4:bitpack32Unrolled[[4]byte](dest,vals)case5:bitpack32Unrolled[[5]byte](dest,vals)case6:bitpack32Unrolled[[6]byte](dest,vals)case7:bitpack32Unrolled[[7]byte](dest,vals)case8:bitpack32Unrolled[[8]byte](dest,vals)case9:bitpack32Unrolled[[9]byte](dest,vals)case10:bitpack32Unrolled[[10]byte](dest,vals)case11:bitpack32Unrolled[[11]byte](dest,vals)case12:bitpack32Unrolled[[12]byte](dest,vals)case13:bitpack32Unrolled[[13]byte](dest,vals)case14:bitpack32Unrolled[[14]byte](dest,vals)case15:bitpack32Unrolled[[15]byte](dest,vals)case16:bitpack32Unrolled[[16]byte](dest,vals)case17:bitpack32Unrolled[[17]byte](dest,vals)case18:bitpack32Unrolled[[18]byte](dest,vals)case19:bitpack32Unrolled[[19]byte](dest,vals)case20:bitpack32Unrolled[[20]byte](dest,vals)case21:bitpack32Unrolled[[21]byte](dest,vals)case22:bitpack32Unrolled[[22]byte](dest,vals)case23:bitpack32Unrolled[[23]byte](dest,vals)case24:bitpack32Unrolled[[24]byte](dest,vals)case25:bitpack32Unrolled[[25]byte](dest,vals)case26:bitpack32Unrolled[[26]byte](dest,vals)case27:bitpack32Unrolled[[27]byte](dest,vals)case28:bitpack32Unrolled[[28]byte](dest,vals)case29:bitpack32Unrolled[[29]byte](dest,vals)case30:bitpack32Unrolled[[30]byte](dest,vals)case31:bitpack32Unrolled[[31]byte](dest,vals)case32:bitpack32Unrolled[[32]byte](dest,vals)
Encoding remainder blocks is quite a bit faster (full blocks use the vertical
layout anyway):
This performance win comes at the cost of binary size increase. In this case,
the .text section (executable code) grows by about 20 KB and the .gopclntab
section grows by another 26 KB. Definitely a price I am very willing to pay, but
the case might not be as clear in all circumstances.
Optimization: Bigger strides with SIMD
Even without reaching for SIMD instructions, a TurboPFor implementation can be
made faster by making it work bigger strides. Take this code from the
goturbopfor teaching decoder which counts the number of exceptions by checking
if each value s bit is set in the exception bitmap:
caseblockBitpackingExceptions:bx,input:=input[0],input[1:]n:=len(output)exmap,input:=input,input[(n+7)/8:]nex:=0// number of exceptionsfori:=rangenifexmap[i/8]&(1<<uint(i%8))!=0nex++exceptions:=d.scratch[:nex]
We can use the bits.OnesCount64
functions to count ones bits in the exception bitmap, 64 values at a time. For
remainder blocks, the rest is processed 8 values (1 byte) at a time:
i:=0for;i+8<=n/8;i+=8xm8:=binary.LittleEndian.Uint64(exmap[i:])nex+=bits.OnesCount64(xm8)for;i<(n+7)/8;i++xmb:=exmap[i]// Clear the bits which do not belong to the exception map:ifrem:=n-i*8;rem<8xmb&=1<<rem-1// Go compiles OnesCount32 into an intrinsic,// but not OnesCount8, so we convert to uint32:nex+=bits.OnesCount32(uint32(xmb))
OnesCount64 uses a 64-bit register. For comparison, AVX2 SIMD instructions use
256-bit registers (= 8 uint32) and AVX512 SIMD instructions use 512-bit registers.
In the following sections, we will first set up our build tags for conditional
compilation to use a trivial SIMD instruction, then walk through an AVX2 and
AVX512 SIMD kernel.
SIMD build tags
Let s assume we have the following scalar code:
constant.go:
To increase throughput, we can use AVX2 instructions if they are available on the CPU on which the program runs, i.e. using runtime dispatch. We ll first rename fillConstant to fillConstantScalar (it s now the fallback path):
constant.go:
Next, we ll supply two different implementations (constant_nosimd.go and constant_amd64.go), the latter of which is selected when compiling for GOARCH=amd64 with GOEXPERIMENT=simd (the latter will hopefully be dropped in a later version of Go). The nosimd variant just dispatches to the fillConstantScalar, which will likely be inlined:
The constant_amd64.go variant assigns the hasAVX2 global variable by doing a CPUID check and then jumps to the scalar fallback if !hasAVX2, i.e. the CPU is too old:
//go:build goexperiment.simd && amd64packagepfordecimport"simd/archsimd"varhasAVX2=archsimd.X86.AVX2()funcfillConstant(output[]uint32,valuint32)if!hasAVX2fillConstantScalar(output,val)returnval8:=archsimd.BroadcastUint32x8(val)i:=0for;i+8<=len(output);i+=8val8.StoreArray((*[8]uint32)(output[i:i+8]))// use the scalar implementation for the last <= 7 elementsfillConstantScalar(output[i:],val)
We can go one step further by conditionally compiling const hasAVX2 = true
when GOAMD64 is set to v3 or higher (i.e. the amd64.v3 build tag is
set). As a practical example from Debian Code Search, we currently need the
following checks / dispatches:
In regular (non-SIMD) bitpacking, integers are stored on disk one after
the other, padded to a full byte, as a byte is the smallest addressable unit
when reading data from disk. For example, if you bitpack only one 3 bit int,
you will end up with 5 bits of padding.
SIMD bitpacking works like regular bitpacking, but processes 8 uint32
little-endian values at the same time, leveraging the AVX instruction
set. The following
illustration shows the order in which 3-bit integers are decoded from disk:
The scalar implementation uses an array of 8 uint64 to process 8 values at a
time:
funcbitunpack256v32(input[]byte,dest[]uint32,bitWidthint)(readint)mask:=uint64(1)<<bitWidth-1orig:=len(input)varbitsuintvaracc[8]uint64// accumulator: current+next bitsforop:=0;op<len(dest);ifbits<uint(bitWidth)// read 8 more uint32sfori:=range8acc[i] =uint64(binary.LittleEndian.Uint32(input))<<bitsinput=input[4:]bits+=32fori:=range8dest[op]=uint32(acc[i]&mask)op++acc[i]>>=bitWidthbits-=uint(bitWidth)returnorig-len(input)
The SIMD version also processes 8 values, but without a for i := range 8 loop!
One difference is that we no longer have the luxury of using uint64 for acc
(holding rest and current bits); because AVX2 registers only fit 8 uint32 (not
8 uint64). Instead, we split acc into rest8 and cur8.
funcbitunpack256v32(fullinput[]byte,fulldest[]uint32,bitWidthint)(readint)dest:=fulldest[:256]ifbitWidth==0clear(dest)return0n:=32*int(bitWidth)input:=fullinput[:n]// tell the Go compiler how long the input ismask8:=archsimd.BroadcastUint32x8(uint32(1)<<bitWidth-1)bitWidth8:=archsimd.BroadcastUint32x8(uint32(bitWidth))varbitsuintpos:=0// var acc [8]uint64varrest8archsimd.Uint32x8varcur8archsimd.Uint32x8forop:=0;op<256;op+=8ifbits<uint(bitWidth)// read 8 more uint32s// acc[i] = uint64(binary.LittleEndian.Uint32(input)) << bitsnext:=archsimd.LoadUint8x32(input[pos:pos+32]).ReshapeToUint32s()pos+=32// input = input[4:]cur8=rest8.Or(next.ShiftAllLeft(uint64(bits)))// acc[i] >>= bitWidthrest8=next.ShiftAllRight(uint64(uint(bitWidth)-bits))bits+=32elsecur8=rest8// acc[i] >>= bitWidthrest8=rest8.ShiftRight(bitWidth8)// dest[op] = uint32(acc[i] & mask)cur8.And(mask8).Store(dest[op:op+8])bits-=uint(bitWidth)returnn
The SIMD version benchmarks about 3x as fast as the scalar version.
Another significant speedup is to use generics for bit width
specialization for this SIMD kernel so that
bitWidth becomes a compile-time constant and the compiler can generate better
code.
Positional Popcount
For my TurboPFor encoder, I implemented the same techniques as described above:
These changes are sufficient to roughly match the cgo performance, but then
Claude Fable 5 found another 2x speed-up on top of that!
The key observation is that once encoding blocks is fast, the preceding step of
scanning the input values to decide which block type to use becomes the
bottleneck. Here is the encoder s main encode function, which first does one
pass over the input values (scan) and then prices all different block types at
all relevant bit widths (requires fast access to the scan histogram):
func(be*BlockEncoder)encode(dest[]byte,vals[]uint32,layoutblockLayout)[]bytevarstatsstatsscan(&stats,vals)// gathers statistics from every value in valsbitWidth:=bits.Len32(stats.or)ifstats.or==stats.andreturnbe.encodeConstant(dest,vals,bitWidth)n:=len(vals)// bitpacking is the default, unless we find a more efficient block type.bestType:=blockBitpackingbestB:=bitWidthbest:=priceBitpack(n,bitWidth,layout)// Walk from high bitWidths to low: to break ties, we prefer// the encoding with fewer exceptions (for faster decoding).forb:=bitWidth-1;b>=0;b--// up to 32 iterationsnex:=int(stats.cnt[b])size:=priceBitpackExceptions(n,b,bitWidth,nex,layout)ifsize<bestbestType=blockBitpackingExceptionsbestB=bbest=size// Over-approximate the number of VB bytes.vb:=nex+// exceptions using 1, 2, 3, 4, or 5 VB bytesint(stats.cnt[b+7]+// exceptions using 2, 3, 4, or 5 VB bytesstats.cnt[b+14]+// exceptions using 3, 4, or 5 VB bytesstats.cnt[b+19]+// exceptions using 4 or 5 VB bytesstats.cnt[b+24])// exceptions using 5 VB bytessize=headerBytes+headerExBytes+payloadBytes(n,b,layout)+vb+nexifsize<bestbestType=blockBitpackingVBExceptionsbestB=bbest=sizeswitchbestTypecaseblockBitpacking:returnbe.encodeBitpack(dest,vals,layout,bitWidth)caseblockBitpackingExceptions:returnbe.encodeBitpackExc(dest,vals,layout,bestB,bitWidth-bestB)caseblockBitpackingVBExceptions:returnbe.encodeBitpackVBExc(dest,vals,layout,bestB,int(stats.cnt[bestB]))default:panic("BUG: bestType not implemented")
I ll show you a slightly shortened version of scan, the function which is the bottleneck:
typestatsstruct// cnt[n] = how many values where bits.Len32(val)>n,// i.e. how many exceptions are required for bitWidth=n.// Padded so that cnt[b+24] is always in bounds.cnt[32+24]uint32funcscan(output*stats,vals[]uint32)for_,val:=rangevalsforb:=rangebits.Len32(val)output.cnt[b]++// b bits are not enough to store val
Let s consider the following 3 example values to understand the resulting cnt:
input
input (bin)
bits.Len32
23
0b0000010111
5
5
0b0000000101
3
666
0b1010011010
10
The resulting cnt exception count histogram would contain (cnt shortened to c):
c[0]
c[1]
c[2]
c[3]
c[4]
c[5]
c[6]
c[7]
c[8]
c[9]
c[10]
3
3
3
2
2
1
1
1
1
1
0
In words, this means that at bit width 10, we could encode all the values
without any exceptions.
But most values do not need 10 bits, so a bit width of 5 would be more
efficient, but requires storing one exception. Encoding at bit width 4 requires
2 exceptions, and so on.
The scan function above is intentionally kept simple for illustration. We can
make it faster by moving the per-bit-width loop outside the per-element
loop.
The fast version still needs about 12 instructions per value. With SIMD, we can
reduce this to by 8x to only 1.5 instructions per value!
The trick: smear masks enable positional popcount
The trick is to turn each input value into its smear mask (imagine taking the
first 1 bit and smearing it across the remaining positions). Here are the smear
masks for our example:
input
input (bin)
bits.Len32
smear mask
23
0b0000010111
5
0b0000011111
5
0b0000000101
3
0b0000000111
666
0b1010011010
10
0b1111111111
Turning a value into its smear mask is computationally cheap:
Go implements BitLen(x) (functions like bits.Len32) by calculating 32 - LZCNT(x). We can calculate the smear mask of a value with ^uint32(0) >> LZCNT(x), i.e. starting with a 32-one-bits mask and shifting it by the number
of leading zeros.
Now, to obtain e.g. cnt[4], we can count the 1 bits at bit position 4 of all
input values.
The POPCNT instruction counts bits very efficiently, but it counts one bits
within a register, so it counts rows, not columns. Counting columns is called
Positional Population Count.
I found the following papers that describe positional popcount with SIMD:
Positional Popcount: a visual explanation
To understand the AVX512 implementation of positional popcount, I found it most
helpful to visualize an AVX512 register (512 bits, i.e. 64 bytes). The graphic
below uses the Uint64x8 layout, meaning it divides the register into 8 lanes
of 64 bits (= 8 bytes) each.
This illustration shows the whole process: how uint32s are loaded into an
AVX512 register (all 4 of its bytes, in sequence) and where we end up, i.e. the
32 positional popcounts:
Let s break down this process into its individual steps.
First, we turn each loaded value into its smear mask as explained above.
The VPOPCNTB vector instruction calculates POPCNT (1 byte) of 64 bytes at
once, but first we need to shuffle the bytes inside the register: in load
order, we have a full uint32 (4 bytes), followed by another uint32, per
lane. First, we permute the bytes (VPERMB) such that all the first bytes of
each value end up in one lane ( transpose the bytes ):
Next, we transpose the bits using the GF2P8AFFINEQB instruction, which
sounds scary but turns out to be quite flexible for bit manipulation of all
kinds. The GF2P8AFFINEQB instruction is also the star of the show in Go s
Green Tea Garbage Collector (2025). Here is the
bit transpose, shown in the AVX512 register layout (see below for a different
layout):
I found it easier to understand the transpose step when arranging the 8 bytes of
lane 0 from top-to-bottom (instead of left-to-right), because then it looks like
a 90 degree clockwise rotation:
Now we can use VPOPCNTB to count the bits in all 64 bytes at once:
After all loop iterations (processing 16 values each) are done, we add the two
groups (first 8 values, second 8 values) to obtain the 32 exception counts:
Positional Popcount: Go SIMD
Here is the Go code that implements what I described visually above:
funcscanSIMD(output*stats,vals[]uint32)ones16:=archsimd.BroadcastUint32x16(^uint32(0))// 16 32-one-bits masksshuffle:=archsimd.LoadUint8x64Array(&scanShuffle)units:=archsimd.LoadUint8x64Array(&scanUnits)varaccarchsimd.Uint8x64idx:=0for;idx+16<=len(vals);idx+=16v:=archsimd.LoadUint32x16(vals[idx:idx+16])// Replace all values with their smear masks.smear:=ones16.ShiftRight(v.LeadingZeros()).ReshapeToUint8s()// Transpose: shuffle the bytes, then transpose the bits.matrices:=smear.Permute(shuffle).ReshapeToUint64s()transposed:=units.GaloisFieldAffineTransform(matrices,0)// Popcount 64 bytes at once into the accumulator.acc=acc.Add(transposed.OnesCount())// Store the accumulator into output.cnt:// Widen the two groups of byte counts to uint16 lanes (so that// 128+128 = 256 fits), fold them into cnt[b] for b=0..31,// then widen again to the uint32 lanes of output.cnt.sum:=acc.GetLo().ExtendToUint16().Add(acc.GetHi().ExtendToUint16())sum.GetLo().ExtendToUint32().Store(output.cnt[0:16])sum.GetHi().ExtendToUint32().Store(output.cnt[16:32])// scalar tail for the 0..15 remaining valuesfor_,val:=rangevals[idx:]forb:=rangebits.Len32(val)output.cnt[b]++
Go even faster?
The SIMD optimizations I showed above beat the cgo TurboPFor library that Debian
Code Search used before. When comparing apples to apples, i.e. backporting the
AVX512 kernels and positional popcount technique to C TurboPFor, Go benchmarks a
little slower at 1.4x C.
Could we make my Go TurboPFor implementation even faster, to truly match the C
speed?
Yes! But also no. Let me explain:
We could use more SIMD instructions to remove all code that still processes
one value at a time. For example, in my encoder s encodeBitpackVBExc
function. Or we could price all bit widths concurrently in encode. Or in
the decoder s exception apply code path.
But all of these SIMD instructions
make understanding (and changing) the code harder, so I am cautious regarding
which ones I introduce.
A big part of the performance gap is due to Go s bounds
checks. While it costs
performance, bounds checking is great for safety, so I will not turn off
bounds checking. The Go compiler eliminates a number of bounds checks when it
understands it s safe to do so. One optimization avenue could be to make the
prove pass in the Go compiler smarter to eliminate more bounds checks.
When doing mid-stack inlining (proposal
#19348)
(2017), Go sometimes needs to put NOP instructions into the binary so that
it can attach inlining markers. For dispatch-bound functions, these extra
NOPs can measurable slow down execution.
The Go compiler currently allows specifying the architecture (GOARCH=amd64)
and microarchitecture (GOAMD64=v3), but not a specific CPU architecture
(like AMD Zen 4). Therefore, CPU-specific workarounds for one vendor affect
all the generated code. The specific one I encountered in my code is that the
Go compiler emits XORL CX,CX before every POPCNT to break a
false-output-dependency from the Intel Sandy Bridge Skylake era, which is
unnecessary on AMD Zen CPUs.
I suspect that Go intentionally does not offer this level of customizability.
After all of the above points are addressed, what remains is better code
generation in specific cases. To illustrate what I mean, consider the example
of incrementing a loop variable, where Go re-derives an index every time:
Go: POPCNTL; ADDQ DI,CX; LEAQ (base)(CX*4) (3 instructions)
clang: popcnt; lea rax,[rax+4*rdi] (2 instructions)
Depending on the specific case, improving the compiler might be easy or
prohibitively complex. Often, such improvements are hard to measure conclusively.
Conclusion
Go s SIMD support makes available in Go code without having to resort to cgo
or assembly a powerful part of modern CPUs which allows speeding up the kind
of computation that TurboPFor needs by an order of magnitude!
I found it very valuable to use a coding agent (Claude Code, with Opus 5 and
Fable 5 in this case) to help with the many tedious parts of such performance
work (and still it took me weeks!). The LLM can read objdump output much faster
than I can, can see patterns and correlations I might never identify, never
becomes frustrated after a compiler error or runtime panic, and never runs out
of patience to run one more experiment, as long as I give it measurable and
reachable goals.
The performance of the SIMD code which one can get from the Go compiler is
pretty close to what a good C compiler like clang provides. The CPU performance
counters show value decoding speeds of 7 instructions/cycle (IPC) on a machine
where the maximum is 8 IPC.
To me, SIMD support is a very welcome addition to Go.