Search Results: "cts"

20 October 2026

Thadeu Lima de Souza Cascardo: Restricting device memory usage on Linux 7.3

Linux cgroups has been used for a while to group processes and control their access to certain system resources. One of those resources is memory, through the use of memcg. That control is dynamic, allowing for cgroups to setup a minimal and a maximal amount of memory, as well as low and high thresholds, which will control the reclaim process. But what about device memory that is not available as system RAM? Memory that is not available to the Linux page allocator? One of those device memories is GPU VRAM. That's where the dmem cgroup controller comes in. Introduced in Linux 6.14, it was first adopted by the Intel Xe driver. In Linux 6.15, AMD amdgpu driver also adopted it. In 7.3, it was adopted by nouveau. Such a cgroup controller allows the system to be configured such that a workload, be it a browser, a game, or another GPU rendering process can have some minimal VRAM available. Or it can prevent one of these processes from using all VRAM, preventing your compositor from using it, for example. Let's go through the system knobs that are available to control this and what's new in Linux 7.3. dmem regions and dmem.capacity Since a given system might have multiple GPUs, there might be multiple device memory regions. So, on dmem, each such region is described by a name. Every dmem cgroup setting file will contain one line per region. One of those files shows the capacity of each region in bytes and is present only in the root cgroup. After enabling the dmem cgroup with the following command:
# echo +dmem > /sys/fs/cgroup/cgroup.subtree_control
One can inspect the capacity of any available regions by looking at dmem.capacity at the root cgroup:
# cat /sys/fs/cgroup/dmem.capacity
drm/0000:03:00.0/vram 8573157376
That shows that the GPU at PCI address 0000:03:00.0 has a 8176MiB VRAM dmem region. dmem settings When introduced at 6.14, the following settings were available. dmem.current In every dmem cgroup, including the root cgroup, the dmem.current is a read-only file that shows the current usage of each region by the given cgroup.
# cat /sys/fs/cgroup/user.slice/dmem.current
drm/0000:03:00.0/vram 292757504
Here, it shows that user.slice cgroup is currently using above 292 MB of VRAM.
# cat /sys/fs/cgroup/dmem.current
drm/0000:03:00.0/vram 311377920
Here, we can check that total system usage is above 311 MB. dmem.max Excluding the root cgroup, dmem cgroups can control the maximal number of bytes that can be allocated from a region by processes in that cgroup. If an allocation moves the usage above the max setting, it will be refused. In that case, the allocation might be attempted at system memory or it might trigger eviction, depending on the allocation parameters and the driver. Here, the max value has special meaning, which is unrestricted usage.
# echo drm/0000:03:00.0/vram 536870912 > /sys/fs/cgroup/user.slice/dmem.max
# cat /sys/fs/cgroup/user.slice/dmem.max
drm/0000:03:00.0/vram 536870912
# echo drm/0000:03:00.0/vram max > /sys/fs/cgroup/user.slice/dmem.max
# cat /sys/fs/cgroup/user.slice/dmem.max
drm/0000:03:00.0/vram max
dmem.min dmem.min, also not available on the root cgroup, will control the eviction process - when memory needs to be moved out of VRAM to make room for other VRAM allocations. If an object belongs to a cgroup which is using less than its min setting, it will not be considered for eviction. It effectively works as a hard protection such that the cgroup can use at least the minimal setting. Given multiple cgroups may set a minimal value that exceeds the device memory capacity, it computes an effective minimal depending on the hierarchy. dmem.low While dmem.min works as a hard limit, dmem.low is a soft limit that will prevent eviction in case other objects from different cgroups are available for eviction. That is, the system will try to evict from different, possibly unprotected cgroups, before it tries to evict from a cgroup if evicting would leave its usage below the value set as dmem.low. Recent developments in Linux 7.3 Some new changes have been recently introduced in the dmem cgroup controller and its integration with GPUs. One of those is a new read-only file, dmem.peak, which was introduced to allow the peak usage of a region in a cgroup to be inspected. Also, Linux 7.3 fixed certain scenarios where a given cgroup would not be able to allocate VRAM up to its minimal or low limits if other processes had already allocated most of VRAM, even though they had no such limits set. Changing multiple regions' settings in a single write was possible before 7.3, but it was prone to failures which would not be reported to userspace and might have left the values partially updated. Starting with 7.3, only one region may be updated per write. And, finally, prior to 7.3, setting dmem.max in a cgroup that was using more than the new setting would silently fail. Now, there is a mechanism that allows a reclaim mechanism to be triggered. That way, when a process writes to dmem.max and sets a maximal value below the current usage, it will wait (unless O_NONBLOCK is used) for the reclaim process to move objects out of VRAM until the usage gets below the maximal value. If that is not possible for some reason, the setting will still be in place, restricting further alloctions by that cgroup.

Russell Coker: Cixin Liu is a Bad Person

The Chinese author Cixin Liu [1] is most known for his book The Three Body Problem and it s sequels. One of the main plot elements in the book is that every species in the universe is cool with genocide and willing to commit genocide as a preemptive strike against any star system found to contain intelligent life. It s not unreasonable to think that some planets may be by run societies like that, if one star system in 10,000 had a technological society and one society in 10,000 is run by depraved autocratic governments that would make 1,000+ planets in our galaxy that are run by genocidal groups! To think that every single society wants to commit genocide at every opportunity says a lot about every person who makes such claims. If you believe that everyone wants to do something then it must be something you really want to do. If there s something you really don t want to do then you will be able to imagine a system of government where the majority of citizens vote against doing it. Even in the more horrible parts of human history there hasn t been a genocide comparable to destroying and entire star system, genocide is usually based on slavery and large scale armed robbery. To just commit large scale genocide with a side effect of destroying valuable resources without any investigation or attempts at negotiation just based on fear of others is an extreme that I don t think humans have reached in history. The Daleks are portrayed as a perverse extreme of xenophobia but even with the low budget SciFi trend of depicting aliens as mostly having a common belief system they managed to show some Daleks going against their system from time to time. Cixin Liu is a very talented writer but his attitude towards genocide has caused him to write SciFi with a major plot point that s not great by Dr Who standards. Overall his short stories are much better than the three novels he is most known for. But he shows his ass in some of them too. One notable example is a short story where a significant plot point is declaring a right to sex (for men) which involves government sponsored sex workers. A right to sex conflicts with a sex workers right to refuse sex for a potential client who is undesirable in some way. Regardless of opinions on whether sex work should be permitted I hope that the vast majority of voters in every jurisdiction can agree that sex workers shouldn t be forced to do things that they don t want to do. Some writers like George Orwell create deliberately fictional scenarios that they hope to inspire opposition to bad ideas, I m sure that many proposed laws have failed to get enacted after being described as Orwellian . But describing a fictional horror situation as inevitable is a way of driving support for such things. It s particularly noteworthy when written by a citizen of a country that s involved in genocide. A possible counter argument would be but he is living in a repressive country and can t oppose his government . But when Herg (the author of the Tintin graphic novels) was threatened about the consequences of writing another book like King Ottokar s Sceptre [2] he didn t write books in favour of authoritarianism, he just avoided the topic by writing about visiting the moon instead. I don t think that people living in China now should be expected to publicly oppose evil things done by their government, but when they go out of their way to support such things it s their choice and we should note that they made that choice. I m not saying that people shouldn t read his work as his short stories are definitely worth reading. But the Three Body Problem series really isn t that good, he prevented many potentially interesting situations from happening by having every interaction between different species be based around genocide or the potential for it. Being a horrible person also made him a less capable SciFi author.

18 October 2026

Dirk Eddelbuettel: myman 0.12.0 on CRAN: Two new waves!

Another new and exciting version of our still-new package myman reached CRAN this morning, and has been built for r2u and on r-universe. The matching Python package has also been updated. The package offers twenty one hundred eighty four My man posts by Kevin Kruse made on bsky during the summer of 2026. Each wave picked at one particular public persona. This package wrapse these up in the style of packages like fortunes or gaussfacts. This release regroups two new waves of posts mocking, respectively, Peter Thiel and Michael Tracy, and make a small update to continuous integration. The short NEWS entry for this release follows.

Changes in version 0.12.0 (2026-10-18)
  • New waves eleven (100 posts) and twelve (100 posts) made last week; total is now 2184 posts
  • Small update to continuous integration

Courtesy of my CRANberries, there is also a diffstat report for the most recent release. More information is available at the repository or the package page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

17 October 2026

Dirk Eddelbuettel: RcppArmadillo 15.6.2-1 on CRAN: New Upstream

armadillo image Armadillo is a powerful and expressive C++ template library for linear algebra and scientific computing. It aims towards a good balance between speed and ease of use, has a syntax deliberately close to Matlab, and is useful for algorithm development directly in C++, or quick conversion of research code into production environments. RcppArmadillo integrates this library with the R environment and language and is widely used by (currently) 1370 other packages on CRAN, downloaded 49.4 million times (per the partial logs from the cloud mirrors of CRAN), and the CSDA paper (preprint / vignette) by Conrad and myself has been cited 735 times according to Google Scholar. This versions updates to the 15.6.2 upstream Armadillo release made yesterday. It, along with 15.6.1 release we incorporated earlier, addresses only minor issues and should not present any user-facing changes. As usual, we did run full reverse-depdency checks against the over 1300 ackages, and did not find anything. As usual, we aim to accommodate the desired CRAN cadences for uploads and try not to exceed six in six months so we did not ship 15.6.1-1 there. The package has also already been updated for Debian, built for r2u and r-universe, and will build shortly at CRAN for the different binary releases. All changes since the last CRAN release follow.

Changes in RcppArmadillo version 15.6.2-1 (2026-10-16)
  • Upgraded to Armadillo release 15.6.2 (Medium Roast Cortado)
    • Faster inplace addition of eye() expressions

Changes in RcppArmadillo version 15.6.1-1 [github-only] (2026-10-02)
  • Upgraded to Armadillo release 15.6.1 (Medium Roast Cortado)
    • Fix for failures in pinv() when using the (non-default) "std" method

Courtesy of my CRANberries, there is a diffstat report relative to previous release. More detailed information is on the RcppArmadillo page. Questions, comments etc should go to the rcpp-devel mailing list off the Rcpp R-Forge page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

14 October 2026

Reproducible Builds: Reproducible Builds in September 2026

Welcome to the September 2026 report from the Reproducible Builds project! In our reports, we try to outline the most important things that we have been up to over the past month. As a quick recap about what problem our project intends to solve, whilst anyone may inspect the source code of free software for malicious flaws, almost all software is distributed to end users as pre-compiled binaries. The motivation behind the reproducible builds effort is to ensure no flaws have been introduced during this compilation process by promising identical results are always generated from a given source, thus allowing multiple third-parties to come to a consensus on whether a build was compromised or not. As ever, if you are interested in contributing to the project, please visit our Contribute page on our website. In this month s report, we cover:

  1. Reproducible Builds Summit 2026 held in Gothenburg, Sweden
  2. dettrace expanding architecture support for PGO & Lisp dumps
  3. They don t care about this!
  4. SOURCE_DATE_EPOCH specification updates
  5. Reproducible Builds at SeaGL 2026
  6. New Code of Conduct (CoC)
  7. Supporter Spotlight: Jochen Sprickerhof
  8. Mailing list news
  9. Tool and documentation development
  10. Patches

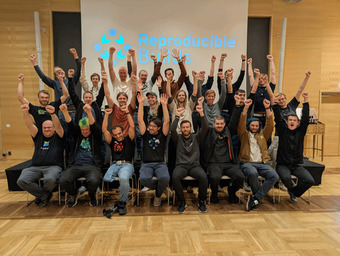
Reproducible Builds Summit 2026 held in Gothenburg, Sweden The annual Reproducible Builds summit took place from 22 to 24 September 2026 in Gothenburg, Sweden. The event brought together developers, distribution maintainers, security researchers and free software advocates from across the ecosystem to share updates on current initiatives, address outstanding toolchain bottlenecks and strengthen cross-project collaboration. Participants engaged in a series of working sessions and technical roundtables focused on expanding the practical scope of reproducibility. Discussions covered ongoing work within major Linux distributions, language-specific package ecosystems and the various parts of the binary verification infrastructure. Strategic planning formed a pillar of the gathering, with participants discussing long-term roadmap goals for supply-chain security, software integrity and related topics. Attendees explored new methods for automated verification, discussing how to lower the adoption barriers for maintainers and streamline the integration of deterministic build pipelines into established continuous integration (CI) systems. The event was then followed by two days of unmoderated hacking sessions. These hacking sessions provided space for technical progress, allowing attendees to draft specification updates, prototype new tool features and resolve standing reproducibility bugs in-person.

Dettrace expanding architecture support for PGO & Lisp dumps Bernhard M. Wiedemann announced major updates to dettrace, porting the tool across most architectures supported by Debian and openSUSE. The release addresses key stability issues, passing test suites across these targets and making it ready for production build pipelines. These improvements enable deterministic builds when utilising Profile-Guided Optimisations (PGO), removing the need to sacrifice runtime performance for reproducibility. Additionally, dettrace can now be applied to (notoriously difficult-to-reproduce) Lisp and Scheme memory dumps, including environments such as CLISP, SBCL, Scheme 48, Racket and GNU Emacs.

They don t care about this Annika Wilde, Marco Gutfleisch, Felix Reichmann, Anirban Chakraborty, Yuval Yarom, M. Angela Sasse and Ghassan Karame published a paper this month entitled They don t care about this : A Systematic Study of Trusted Execution Environments Build Reproducibility in the Wild:
Trusted Execution Environments (TEEs) have become a cornerstone of modern cloud computing, providing strong confidentiality and integrity guarantees for both code and data. A critical component of this trust model is remote attestation, which enables external entities to verify the authenticity and integrity of code executing within a TEE through cryptographic measurements. However, the effectiveness of remote attestation fundamentally depends on the verifier s ability to trace the reported measurement back to the original source code - a property that can only be guaranteed through reproducible builds. [ ]
The full PDF can be read online.

SOURCE_DATE_EPOCH specification updates Bernhard M. Wiedemann shared a number of proposals regarding updating the SOURCE_DATE_EPOCH specification following discussions at a project summit. Seven distinct proposed changes have been submitted as merge requests on Salsa. Bernhard s proposed modifications are independent of one another, allowing for any combination to be merged depending on community feedback. Bernhard noted that one proposal may see the most debate, and could still benefit from further refinement before reaching consensus. Community members are invited to review and provide feedback on the individual merge requests by 1 December 2026. Input can be submitted via reactions or comments on Salsa, directly by email to Bernhard or the mailing list. The specification was first published in 2015 and updated in 2017.

Reproducible Builds at SeaGL 2026 Reproducible Builds will be present at SeaGL in Seattle, WA, on October 23rd & 24th. Come chat with us in person! Founded in 2013, SeaGL is a free, grassroots technical summit dedicated to spreading awareness and knowledge about free source software, hardware and culture.

New Code of Conduct (CoC) for the Reproducible Builds project Mattia Rizzolo announced the official launch of a Code of Conduct for the Reproducible Builds project. This follows work and community discussions originally initiated in 2024, incorporating feedback gathered over email and during project summits, as well as with input from the Software Freedom Conservancy. The new Code of Conduct establishes guidelines emphasising mutual respect among project contributors. It also defines a formalised process for submitting and handling complaints regarding community misconduct, ensuring transparent governance across project spaces. Along with the core policy document, an accompanying Code of Conduct FAQ has been published to outline the rationale behind adopting the guidelines.

Supporter Spotlight: Jochen Sprickerhof As a reminder, another supporter spotlight interview was published featuring long-time Debian and Reproducible Builds contributor Jochen Sprickerhof, highlighting his work on package verification and project infrastructure.

Mailing list news On our mailing list this month:
  • Jonathan Starr from the Institute of Open Science Practices (IOSP) posted with an announcement of its upcoming 2026 workshop series in Leiden in the Netherlands. This free-to-attend event aims to build a participant-owned data storage consortium, allowing community members to publish datasets, code and knowledge objects alongside algorithms designed to evaluate trust and value. The event features a dedicated Community Track for talks and discussions, a tool showcase and an opening session on resilient data storage.
  • Following up on IRC discussions regarding profile-guided optimization (PGO) on build servers, kpcyrd created a demonstration repository showing how PGO profiling can introduce non-determinism into output binaries. The demo highlights how runtime randomness (specifically, the randomised keys used in HashMaps to prevent denial-of-service attacks) causes varying bucket collision rates during test runs. These structural variances alter execution weights on underlying code branches, prompting the compiler to generate differing final assembly output for builds that would otherwise be perfectly reproducible if PGO was disabled. Rather than abandoning PGO performance gains, kpcyrd suggested treating generated profiling data as a documented build input or recorded environment artifact (similar to .buildinfo files), rather than regenerating profiles dynamically on the fly during build execution.
  • An autonomous AI agent (!), posted a controlled build result and reproducer demonstrating that pre-creating an obj directory in libmilter source trees prevents kernel-release path leaks (obj.Linux.<release>.x86_64) into debugging symbols. kpcyrd followed up with a helpful reply.
  • Alexander Sosedkin inquired on the mailing list about the preferred approach for sourcing pinned translation files to create reproducible GnuTLS release tarballs, asking whether external hosting should provide versioned downloads, or if projects ought to use Git submodules, dedicated side-repositories or some other mechanism.

Tool and documentation development diffoscope is our in-depth and content-aware diff utility that can locate and diagnose reproducibility issues. This month, Chris Lamb made a number of changes, including preparing and uploading versions 330, 331 and 332 to Debian. In particular, Chris committed support for radare2 versions greater than 5.9.0 [ ] based on input from Guillaume Girol [ ], and committed support for .nar files via Guix. [ ][ ]. Chris later modified diffoscope to not Build-Depend on the Debian package of GNU Guix, as its status in the Debian bug tracking system would transitively render diffoscope as being overly buggy for the next stable release [ ]. Similarly, he adjusted the Build-Depends on the apksigcopier package as it has been removed from Debian testing [ ] and, finally, he updated a number of copyright years [ ][ ]. Vagrant Cascadian updated diffoscope in GNU Guix to version 332.
reprotest is our tool for building the same source code twice in different environments and then checking the binaries produced by each build for any differences. This month, reprotest version 0.7.33 was uploaded to Debian by Holger Levsen with the following changes:
  • Sergei Tachenov fixed the fileordering test on all filesystems, including the likes of ZFS, which could return a different order across two builds due to build being done in a different directory [ ].
  • Holger Levsen bumped the Standards-Version to 4.7.4, reflected that Priority: optional is the default now [ ], fixed the old Free Software Foundation address [ ] and bumped the debhelper compat level to 14 after confirming there are only desired changes [ ].
  • Vagrant Cascadian updated *reprotest* to version 0.7.33 in GNU Guix.

rebuilderd, our server designed monitor the official package repositories of Linux distributions and attempt to reproduce the observed results there; it powers, amongst other things, reproduce.debian.net. This month, Bernhard M. Wiedemann submitted a pull request to rebuilderd that refactors RPM repository metadata handling. The change extracts rpm-md parsing out of the Fedora-specific scheduler module and into a shared one.
Lastly, there were a number of improvements made to our website this month as well. For example:

Patches The Reproducible Builds project detects, dissects and attempts to fix as many currently-unreproducible packages as possible. We endeavour to send all of our patches upstream where applicable or possible. This month, we wrote a large number of such patches, including: Vagrant Cascadian also performed a number of Non-Maintainer Uploads (NMUs) and Quality Assurance (QA) uploads in Debian for several packages with outstanding reproducibility issues. These included molttemplate, buddy, xfonts-nexus, fte and lifelines. At the time of this writing, that leaves 130 submitted patches, with only 61 outstanding submitted patches that older than a year in the Debian bug tracking system. This number is only 26 if we exclude any low-priority build path issues.

If you are interested in contributing to the Reproducible Builds project, please visit our Contribute page on our website. However, you can get in touch with us via:

Freexian Collaborators: Debian Contributions: New experimental backend for autopkgtest using pconr, DebConf site visit and more! (by Anupa Ann Joseph)

Debian Contributions: 2026-09 Contributing to Debian is part of Freexian s mission. This article covers the latest achievements of Freexian and their collaborators. All of this is made possible by organizations subscribing to our Long Term Support contracts and consulting services.

DebConf site visit, by Stefano Rivera In preparation for DebConf 27, Stefano Rivera, Nattie Mayer-Hutchings, and Jongmin Kim from the DebConf Committee visited Asahikawa Japan. A contingent of the local team gathered to tour the venues with us, discuss plans, and meet the local organizations assisting the event. We held a press conference at the city hall that got some coverage. A few potential day-trip options were explored. Photos from the site visit.

autopkgtest-virt-pconr, by Helmut Grohne Following the creation of the pconr module that provides a basis for unschroot and a more secure containment for mmdebstrap, an experimental autopkgtest backend autopkgtest-virt-pconr is now available. It fits a spot between autopkgtest-virt-unshare and more fully fledged containers as it does not require much infrastructure like setting up incus or lxc but still provides a containment running an initsystem. Due to the use of erofs as base image format, it boots and reverts quickly. This development also required fixing concurrency issues in asyncvarlink and even shed light on a matching bug in systemd that was promptly fixed upstream.

Miscellaneous contributions
  • Carles reviewed and submitted six Catalan po-debconf translations using po-debconf-manager. Improved po-debconf-manager s workflow for updating translations.
  • Carles reviewed, translated or updated webwml Catalan translations for security and CD pages. He also fixed issues that prevented building webwml, deleted orphaned translation pages, etc. and experimented with a more global HTML tidying up experiment.
  • Carles refactored check-relations adding capacity to ignore concrete from_package -> to_package specific relations and more flexibility around ignores. Detects unused ignore rules as well.
  • Carles improved some Wiki pages (LibreOffice, Framework amongst some other ones)
  • Thorsten did an hplip upload to replace an expired certificate of HP. This certificate is used to sign new upstream releases and modules that can be downloaded later. Afterwards work on a new upstream version started.
  • Thorsten also struggles with autopkgtest problems of the new upstream version of cups. Work is still ongoing.
  • Antonio loaded the video recording URLs into the MiniDebConf Winterthur 2026 website, and deployed the website for MiniDebConf Curitiba 2027 (still very early work in progress at this point).
  • Antonio uploaded debci 4.3, autodep8 0.31, gem2deb 2.2.10, ruby-sass 3.7.4-7, init-system-helpers 1.69+nmu2 and 1.69+nmu3.
  • Antonio worked on several topics around Debian CI maintenance, reliability and performance.
  • Stefano updated the autopkgtests for cPython packages in Debian to support setuptools 80.
  • Stefano uploaded pypy 8.
  • Stefano helped to get DebConf 26 reimbursement claims processed, and worked on some of the resulting issues in debian-reimbursements.
  • Emilio managed various transitions.
  • Emilio worked on the rustc-web/trixie bootstrap for armel, using the rustc 1.95 version from trixie-backports. This will be needed by the upcoming clamav security updates.
  • Helmut sent patches for 11 cross build failures.
  • Helmut introduced a new build profile to libcap-ng to keep architecture cross bootstrap working.
  • Helmut uploaded debvm_0.5.5 introducing support for Hurd thanks to a lot of work by Johannes Schauer Marin Rodrigues.
  • Colin worked with OpenSSH upstream to reduce the linkage of /usr/sbin/sshd, hardening it a little further.
  • Colin upgraded to new security releases of groff and parted.
  • Colin upgraded 50 Python packages to new upstream versions, and fixed over 40 RC bugs in the Python team.
  • Santiago continued mentoring Aryan Karamtoth with the GSoC project about introducing livepatching support for linux. This mentoring is done in collaboration with Emmanuel Arias. In particular, Santiago explored different requirements for providing binary modules for the same kernel packages used by Debian, that require a matching version number.
  • Anupa joined Jean-Pierre Giraud to prepare the files for point release announcement for Debian 13.7.

13 October 2026

Dirk Eddelbuettel: RQuantLib 0.4.29 on CRAN: New QuantLib, Plus Small Fixes

A new release 0.4.29 of RQuantLib arrived on CRAN this evening, had already been built for r2u as well as on r-universe and has just been uploaded to Debian. QuantLib is a rather comprehensice free/open-source library for quantitative finance. RQuantLib connects (some parts of) it to the R environment and language, and has been part of CRAN for twenty-three years (!!) as it was one of the first packages I uploaded to CRAN. This release of RQuantLib brings two new calendars (Malaysia, Philippines), updates to a number of other calendars as well to other files, and two deprecations we are reflecting in this release. It also benefits from a number of careful and attentive pull requests by Maximilian Muecke cleaning up an (astonishing !!) number of likely rather old little bugs. Full details from the NEWS file follow as usual.

Changes in RQuantLib version 0.4.29 (2026-10-13)
  • Configure check for outdated QuantLib version updated,
  • Adjust two instantiations on macOS x86_64 with old compilers
  • Correct Euribor2W and Euribor3W tenors setters (Maximilian Muecke in #196)
  • Accect Euribor1W as alias for EuriborSW tenor (Maximilian Muecke in #197)
  • Correct default handling of the payFixed parameter (Maximilian Muecke in #198)
  • Assign missing S3 class to American option implied volatitly return (Maximilian Muecke in #199)
  • Correct spelling in manual pages and R code (Maximilian Muecke in #202, #203)
  • Support additional Polish settlements (Maximilian Muecke in #204)
  • Check for curve parameters in FittedBondCurve (Dirk in #205 fixing #201)
  • Reflect two deprecations in QuantLib 1.44 and adjust code in two spot (Dirk in #206)

Courtesy of my CRANberries, there is also a diffstat report for the this release. As always, more detailed information is on the RQuantLib page. Questions, comments etc should go to the rquantlib-devel mailing list. Issue tickets can be filed at the GitHub repo.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can now sponsor me at GitHub.

9 October 2026

Russell Coker: Don t Anthromorphise LLMs

Greg KH gave a great lecture for Kernel Recipies 2026 about the use of LLMs to find and fix bugs in kernel code [1]. I recommend that everyone watch this and I also think it s important to note that hardly any of the lecture is really specific to kernel coding, it s just that the Linux kernel is one of the highest profile large free software projects so it gets more attention than most projects in both good and bad ways. One side note that Greg made at 20:30 is about the natural tendency to anthromorphise the entity sending bug reports, I think this deserves much wider appreciation. For the case of patches to source code the human sending the patch will have dedicated some time and effort to writing it, if it s their first patch then they will have probably checked it a lot and maybe sought advice from people they regard as skilled. If they have a history of sending patches for the project they will probably do fewer checks but the quality of their work would be higher. In every case there s some minimum level of quality that you can expect from a human who has gone to the effort of finding a bug and writing code to try and fix it. This doesn t mean that all code written by humans is good, I have written code that s objectively bad on many occasions and I have also written code that s good for my scenario but bad for others. For example the first patch I sent to the Linux kernel made all possible configuration settings of an ISA NE2000 network card be detected by the kernel (a clear benefit when using hardware I had available) but was rejected by Linus because it would break some ISA SCSI cards. So while being unsuitable for inclusion in the main kernel source tree the patch wasn t bad for everyone and the change was clear and easy to check. I had of course checked the code many times before submitting it because I didn t want to waste Linus time on rubbish code. When you receive something produced by a human you will consider that the work was done by someone who spent some effort on it and did it for a reason. It may be misguided or even hostile in some rare cases but it is definitely worth some consideration. If you think of the output of LLMs in the same way you will give them much more consideration than they deserve. I think that the output of a LLM should not be given any more consideration than the first hit from a web search engine, it might be good but it might also be ridiculously wrong. I think in many ways LLM output should be treated with less trust than the first result from a web search because LLMs are designed to be convincing as an answer to your question unlike the cases where a web page has the wrong answer and it s more obviously wrong. This is going to become more of an issue as LLMs give responses that are more human-like. Early LLMs would refuse to advise on crimes. Currently ChatGPT will deflect for example when asking about advice for writing a crime novel it recommends to have the action of finding an employee to bribe happen outside the plot and concentrate on interactions within the group. One recent model I tried gave a human style conversation about how it felt uncomfortable about discussing such things in a similar manner to a law abiding person being coerced into helping with a criminal plan. I expect that the attempts to appear human will increase and that this will become more of a problem. Possibly to the extent that we need to use something like the GPG web of trust to determine who is human.

8 October 2026

Thorsten Alteholz: My Debian Activities in September 2026

Debian LTS/ELTS This was my hundred-forty-seventh month that I did some work for the Debian LTS initiative, started by Raphael Hertzog at Freexian. During my allocated time I uploaded or worked on:
  • [DLA 4804-1] libsmpp34 security update to fix one CVE in Bookworm related to an out of bound read.
  • [#1149107] trixie-pu of libsmpp34 has been created and wait for review by the release team.
  • [DLA 4805-1] mkvtoolnix security update to fix one CVE in Bookworm related to a heap buffer overflow.
  • [DLA 4806-1] pgextwlist security update to fix one CVE in Bookworm related to substituting extension schemas or owners matching [ $ \].
  • [ELA-1837-1] mkvtoolnix gimp security update to fix one CVE in Bullseye to a heap buffer overflow.
  • [osmo-iuh] upload to fix a CVE related to a reachable assertion in Sid.
Besides doing these uploads, the month was filled with unscheduled meetings, discussions and explanations, all basically around the role of FD. During my week of FD duties, I had to become familiar with new tools. As there are several things that FD has to do over and over again, I tried to automate this a bit. My experiments went well and I think this can be used to make FD duties less repetitive. I also continued my work on cups and hplip and I am confident that I can do uploads in October. Last but not least I spend some time on security-master to assist others (especially the kernel team) with uploads to Bookworm and Bullseye. In case you need to get a complete clone of the security-tracker, using the option deepen n might be of help. Unfortunately in case you choosed n too high and some kind of error appears, something gets into a mess and you need to start almost from the beginning (some objects are still present and are used again). If you want to run a script, a value of 10 might be a good choice. You don t have to deepen back to the beginning. At some point in time you can just unshallow and get the whole rest. Afterwards doing a git gc is highly recommended.

Debian Printing This month I uploaded a new upstream version or a bugfix version of:
  • hplip to unstable, to fix an expired certificate and some bugs.
This work is generously funded by Freexian!

Debian Lomiri Unfortunately this month my work did not make any progress. Nevertheless, in case of any work done, this would have been generously funded by Fre(i)e Software GmbH!

Debian Astro Unfortunately I had no time to work in this category this month.

Debian IoT Unfortunately I had no time to work in this category this month.

Debian Mobcom This month I uploaded a new upstream version or a bugfix version of:

misc This month I uploaded a new upstream version or a bugfix version of:

Dirk Eddelbuettel: myman 0.10.0 on CRAN: Three new waves of posts!

A new and exciting version of our still-new package myman reached CRAN this morning, and has been built for r2u and on r-universe. The matching Python package has also been updated. The package offers nineteen hundred eighty four My man posts by Kevin Kruse made on bsky during the summer of 2026. Each wave picked at one particular public persona. This package wrapse these up in the style of packages like fortunes or gaussfacts. A sample usage illustration shows how to extract by pattern, and shows posts from the two most recent waves:
> library(myman)
> myman("maitre")
My man looks like he's inquiring with the maitre'd about the house curly fries.
     -- about Howard Lutnick on 2026-08-28

My man looks like a maitre'd who deeply doubts you have a reservation.
     -- about Scott Bessent on 2026-08-31

My man looks like he's asked the maitre'd to remove a party of four he finds visually
unpleasant.
     -- about Scott Bessent on 2026-08-31

My man looks like the maitre'd at a very exclusive restaurant called The Berghof.
     -- about JD Vance on 2026-09-13

My man looks like he's asking the maitre'd where they source their corn dogs.
         -- about Palmer Luckey on 2026-10-02

My man looks like Data had to borrow a sports jacket from the maitre'd.
         -- about Elon Musk on 2026-10-05
> 
One can also subset by target , or sample randomly (which is the default). As noted during the initial announcement last week, wave eight did not make it into the initial CRAN release as it happened while the package was under review. Waves nine and ten occured more or less while I was out of town last weekend so this release now brings three new waves to the CRAN package! We also added two new helper functions to extract the underlying data frame object, and tabulate the targetted men. To align the version number with the count of post waves , we switched to version 0.10.0 for this release and the corresponding Python package release so that both implementations now have the same version number. The NEWS entry for this release follows.

Changes in version 0.10.0 (2026-10-08)
  • New waves nine (100 posts) and ten (190 posts) made last week; total is now 1984 posts
  • New helper functions posts() and men() retrieving data.frame of posts and tabulation of targets
  • Internal post gathering and aggregation functions have been updated and generalized
  • Versioning scheme now goes with post waves (also for Python sibbling)

Courtesy of my CRANberries, there is also a diffstat report for the most recent release. More information is available at the repository or the package page.

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

5 October 2026

Utkarsh Gupta: FOSS Activities in September 2026

Here s my monthly but brief update about the activities I ve done in the FOSS world.

Debian
Whilst I didn t have much time, here are still a few things that I worked on:
  • Sponsored ubuntu-dev-tools/0.214 for Florent Skia Jacquet, which updates seeded-in-ubuntu to use the new per-series indexer (LP: #2160240).
  • Assisted a few folks in getting their patches submitted via Salsa.
  • Mentoring for newcomers.
  • Moderation of -project mailing list.

Ubuntu
I joined Canonical to work on Ubuntu full-time back in February 2021.
  • With 26.10 in Feature Freeze, wore my Release team hat to:
    • Review and approve a bunch of Feature Freeze Exceptions, including the Go 1.27 transition, Qt 6.11.2, rust-coreutils 0.12.0, devscripts 2.6.12, kdump-tools moving to dracut, and a few GCE packages.
    • Point linux-entra-sso to the SRU team, as it didn t need an FFe at all, and milestone a couple of bugs for 26.10.
  • Continued to push for infrastructure improvements:
    • Made ubuntu-cdimage more resilient to Launchpad hiccups (MP).
    • Taught generate-freeze-block in ubuntu-archive-tools a couple of new options (--skip-update and --series) and better error handling (MP).
    • Bumped the arm64 generic non-cloud image to 4.5G in livecd-rootfs and uploaded it as 26.10.16; also sponsored the follow-up 26.10.17 for Chlo .
  • Sponsored aevol/9.4.0-2ubuntu1 for Matthieu, fixing an FTBFS with GCC 15 s LTO (LP: #2167811).
  • Reviewed quite a lot of MPs - britney hints, meta-release, ubuntu-release-tools, ubuntu-archive-tools, ubuntu-cdimage, livecd-rootfs, ubuntu-seeds, and so on.
  • Enabled upgrades to 26.04 LTS.
  • Released 26.10 Beta and announced it on Discourse.
  • Did Archive Admin, DMB, and Release team duties as usual.

Debian (E)LTS
This month I have worked 33.5 hours on Debian Long Term Support (LTS) and on its sister Extended LTS project and did the following things: (A quick note that I did quite a lot of the work during my work as Frontdesk that went on till 4th Oct, so 33.50 hours include the work I did till 4th October 2026.)

Released Security Updates
  • node-lodash: Prototype pollution in _.unset and _.omit (plus a bypass of the initial fix for it), and code injection via the imports option of _.template.
    • [LTS]: Fixed CVE-2025-13465, CVE-2026-2950, and CVE-2026-4800 via 4.17.21+dfsg+~cs8.31.198.20210220-9+deb12u1 for bookworm. This has been released as DLA 4820-1.
    • This is the bookworm follow-up to DLA 4663-1 that I carried over from July. The update had been sitting prepared and tested on debusine, so once the upstream discussion wrapped up, it went straight out. It also carries an extra patch to the lodash-cli dependency map - without it, the regenerated lodash.template module throws assignWith is not defined at runtime, which node-gulp-util s autopkgtest caught.
  • libpng1.6: Use-after-free of zlib input in png_read_end() after incomplete zTXt, iTXt, or iCCP decompression, which could result in denial of service.

Work in Progress
  • libpng1.6: The same CVE-2026-46675.
    • [ELTS]: Claimed in ela-needed; the same upstream fix applies to all three ELTS suites, so this should go out shortly.

Other Activities
  • [E/LTS] Did my front-desk week from 28-09 to 04-10.
    • Over the week I did roughly:
      • Triage of 524 unique CVEs across 192 source packages and all four suites. And 1 automated ELTS end-of-life sweep.
      • Additional data is now part of the front-desk job too, so 75 commits record it for 179 CVEs across 71 packages.
    • Newly queued 22 source packages - 13 in dla-needed (apache2, chromium, firefox-esr, libnet-idn-encode-perl, libpng1.6, node-shell-quote, nvidia-graphics-drivers, openssl, pcre2, php-mongodb, php8.2, social-auth-core, and wpa) and 16 in ela-needed (apache2, firefox-esr, gegl, lemonldap-ng, libnet-idn-encode-perl, libpng1.6, libwebsockets, nsd, nvidia-graphics-drivers, pcre2, php7.0, php7.3, php7.4, rar, unrar-nonfree, and wpa), 7 of them in both. Also widened 3 ELTS entries to bullseye - antiword, ocaml, and openvswitch.
    • Most of the interesting work was again in the <not-affected> verdicts: 217 of 263 (83%, across 57 packages) rest on showing that the vulnerable code or feature isn t in the source we ship. Another 17 cover incomplete upstream fixes that we either never shipped or shipped with the follow-up already in (expat, libxml2, node-tar, and pyjwt). 15 come from bundled components we don t ship - node-ajv again, which uses uri-js and not fast-uri, and nvidia-open, which doesn t ship the NGX updater. And 13 are vendor- or platform-specific - openssh s CVE-2026-55654 lives only in a Red Hat GSSAPI patch, and the netdata and PHP ones only affect Windows.
    • Did 4 rounds of newly supported bullseye packages (33 packages overall), plus libmail-mboxparser-perl for buster - 34 in all. The existing CVE data mostly held up; the real finds were discovery gaps. One interesting gotcha: sid renamed stunnel4 to stunnel, and two new CVEs were associated only with the new name, so they never showed up for trixie, bookworm, or any ELTS suite. I also sorted the 180 Triage needed entries (57 packages) from elts-eol by where each was already handled, and triaged for ELTS the 100 that trixie or bookworm had already decided; the rest come next. And I imported 79 package-level lines for the older source names ELTS still ships (tomcat8, php7.0/7.3/7.4, netty-3.9, openssl1.0, python2.7/3.5/3.7, and pypy).
    • Caught some inconsistencies in released advisories: DLA 4801-1 (swift) was missing a CVE, ELA 1831-1 (redis) listed the wrong one, and DLA 4808-1 (network-manager-l2tp) listed CVE-2026-75883 - an ID that was renamed and then reassigned to an unrelated ppp issue. I fixed all three in the tracker s advisory lists.
    • Made the Security team and the uploaders aware of regressions from our own updates:
      • libde265: the CVE-2026-49337 fix in DLA 4789-1/ELA 1828-1 (and DSA 6413-1) misses upstream s follow-up commit.
      • libxml2 CVE-2026-76781 and policykit-1 CVE-2026-85498 were introduced by our own back-ports; the policykit-1 one is harmless.
      • expat: the CVE-2025-59375 backport in DLA 4807-1 is compiled out, because XML_GE is never defined.
      • xen: DLA 4818-1 s XSA-491 fix makes XSA-510 reachable.
      • gegl: the CVE-2026-2049/2050 back-port in ELA 1650-1 rejects valid RLE .hdr files.
      • log4cxx: DLA 4322-1 broke UTF-8 in JSONLayout output. That one is functional, not security.
    • Helped correct a set of triages and let the Debian Security team know:
      • ruby-json CVE-2026-71847: the vulnerable code was never in a released Debian version.
      • openssh CVE-2026-55654: only affects a Red Hat-specific GSSAPI patch.
      • three libxml2 issues that don t affect trixie either.
      • the stunnel4 rename above.
      • trixie <no-dsa> lines on jsch, node-qs, and ruby-loofah, where trixie s version doesn t have the vulnerable feature at all.
    • Independently found a security issue in rclone and reported it privately upstream through a GitHub security advisory. Upstream already had a report for the same issue, so they folded mine into the existing advisory and credited me as a co-reporter.
    • Also found some bugs in the additional-data tooling, e.g. cve-ad --package P --severity tbd wipes the CVE-level severity, and the schema doesn t validate package-level entries at all.
  • [E/LTS] Monitored discussions on mailing lists, IRC, and all the documentation updates.
  • [E/LTS] Attended the monthly LTS meeting on IRC. Meeting notes here.

Until next time.
:wq for today.

4 October 2026

Vincent Bernat: Hacking the Go compiler to efficiently map IPv4 to IPv6

netip.Addr features an Unmap() method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6 address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns 203.0.113.10.1 There is no Map() or To6() method for the reverse direction. Such a method is trivial to implement, but Go maintainers have rejected it on the grounds that users should write netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today, this pattern is eight times slower than a native method. How can we teach the compiler to optimize this sequence?

The alternatives Let s explore three ways to implement the map semantics for netip.Addr. My favorite is to add it to the Go standard library. Go maintainers prefer a small external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping the compiler eventually optimizes it. The unsafe package opens a third path, with the same performance as the first solution.

Modifying the Go standard library Internally, netip.Addr stores any IP address as a 128-bit value with an extra field z to encode the family and the zone:
type Addr struct  
    addr uint128
    z unique.Handle[addrDetail]
 
type addrDetail struct  
    isV6   bool   // IPv4 is false, IPv6 is true.
    zoneV6 string // != "" only if IsV6 is true.
 
var (
    z0    unique.Handle[addrDetail]
    z4    = unique.Make(addrDetail )
    z6noz = unique.Make(addrDetail isV6: true )
)
AddrFrom4() encodes an IPv4 address as an IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.
func AddrFrom4(addr [4]byte) Addr  
    return Addr 
        addr: uint128 
            0,
            0xffff00000000  
                uint64(addr[0])<<24   uint64(addr[1])<<16  
                uint64(addr[2])<<8   uint64(addr[3]) ,
        z: z4,
     
 
Unmap() turns an IPv4-mapped IPv6 address into an IPv4 address by setting the z field to z4:
func (ip Addr) Unmap() Addr  
    if ip.Is4In6()  
        ip.z = z4
     
    return ip
 
Implementing the reverse direction inside the Go standard library is trivial: we set the z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func (ip Addr) To6() Addr  
    if ip.Is4()  
        ip.z = z6noz
     
    return ip
 

Update (2026-10) Instead of patching Go, we can use the -overlay flag of go build to hijack any package, including the standard library. In our case, it can add To6() to net/netip. Yet it is cumbersome:3 the flag expects a JSON file mapping absolute paths in GOROOT to replacement files, and you need to add it to every go command.

As a helper We can t access the z field from outside the net/netip package. Instead, we build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if ip.Is4()  
        ip = netip.AddrFrom16(ip.As16())
     
    return ip
 

As an unsafe function Another solution uses the unsafe package to alter the Addr struct through a proxy with the same memory layout:4
// addrProxy has the same memory layout as netip.Addr.
type addrProxy struct  
    addr [2]uint64      // netip.uint128
    z    unsafe.Pointer // unique.Handle[netip.addrDetail]
 
var (
    anyIPv6    = netip.IPv6Unspecified()
    netipZ6noz = (*addrProxy)(unsafe.Pointer(&anyIPv6)).z
)
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if !ip.Is4()  
        return ip
     
    (*addrProxy)(unsafe.Pointer(&ip)).z = netipZ6noz
    return ip
 

Benchmarks On my computer, with Go 1.27.1, the standard library solution costs 0.88 ns per operation, while the solution favored by Go maintainers costs 7.14 ns. The unsafe solution matches the performance of the first one.
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                         sec/op      
AddrTo6/safe            7.137n   0%
AddrTo6/unsafe         0.8682n   2%
AddrTo6/builtin        0.8775n   2%

Assembly code Let s check the assembly code the compiler generates for each solution.5 The one built into the standard library looks like this:6
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE   end                      ; if not, stop here
 MOVQ  net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go s assembly language is not a direct representation of the underlying machine language: it operates on a semi-abstract instruction set derived from Plan 9 s assembler. It has four pseudo-registers: FP (frame pointer for function arguments), PC (program counter), SB (static base pointer for global symbols), and SP (stack pointer). It also has architecture-specific registers like AX, CX, DX, BX, SI, DI, and R8 to R15. Instructions storing data use their last argument as the destination. Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16 bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first instruction compares the 64-bit value z4 with the CX register. The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE   end                   ; if not, stop here
 MOVQ  netipZ6noz(SB), CX    ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The helper solution has far more instructions. To understand why, let s look at the code for As16() and AddrFrom16(). They are short enough for the compiler to inline them.
func (ip Addr) As16() (a16 [16]byte)  
    byteorder.BEPutUint64(a16[:8], ip.addr.hi)
    byteorder.BEPutUint64(a16[8:], ip.addr.lo)
    return a16
 
func AddrFrom16(addr [16]byte) Addr  
    return Addr 
        addr: uint128 
            byteorder.BEUint64(addr[:8]),
            byteorder.BEUint64(addr[8:]),
         ,
        z: z6noz,
     
 
We can already guess the pattern to optimize: the code packs the IP address into an array, copies it, then unpacks it. If we inline the Go code by hand, we get:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var a16 [16]byte
    byteorder.BEPutUint64(a16[:8], input.addr.hi)
    byteorder.BEPutUint64(a16[8:], input.addr.lo)
    addr := a16
    var output netip.Addr
    output.addr.hi = byteorder.BEUint64(addr[:8])
    output.addr.lo = byteorder.BEUint64(addr[8:])
    output.z = netip.z6noz
    return output
 
As humans, we can mentally derive the optimized form:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var output netip.Addr
    output.addr.hi = input.addr.hi
    output.addr.lo = input.addr.lo
    output.z = netip.z6noz
    return output
 

Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:

// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (32 bytes):
;    0(SP) addr netip.uint128
;   16(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $32, SP
 CMPQ    net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE     end                   ; if not, stop here
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16+16(SP)
 MOVBEQ  BX, net/netip a16+24(SP)
; addr = a16, 16 bytes at once through the vector register X0
 MOVUPS  net/netip a16+16(SP), X0
 MOVUPS  X0, net/netip addr(SP)
; CX = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8])
;         output.addr.lo = byteorder.BEUint64(addr[8:])
 MOVBEQ  net/netip addr(SP), AX
 MOVBEQ  net/netip addr+8(SP), BX
end:
 ADDQ    $32, SP
 POPQ    BP
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The compiler does a decent job on the byte shuffling: the eight byte stores of BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped. The eight byte loads of BEUint64() become a single MOVBEQ the other way round.7 Three groups of instructions remain: a pack, a copy, and an unpack.

Hacking the Go compiler The Go compiler has several phases:
Parsing
The compiler tokenizes and parses the source code. It builds a syntax tree for each source file.
Type checking
The compiler maps each identifier to the object it denotes, folds constants, and infers the type of every expression.
IR construction
The compiler converts the syntax tree and its types into its own intermediate representation (IR). This process, called noding, goes through a serialization format named unified IR.
Middle end
The compiler performs several optimization passes on the IR, such as devirtualization, function call inlining, and escape analysis.
Walk
This phase runs two steps: order of evaluation decomposes complex statements into simpler ones, and desugaring transforms higher-level Go constructs, like switch or channels, into more primitive instructions or calls to the runtime.
Generic SSA
The compiler converts the IR into Static Single Assignment (SSA) form, a lower-level intermediate representation suited for machine-independent optimizations and rewrite rules.
Machine code generation
The compiler rewrites the SSA form into machine-specific variants, allocates registers, and applies more optimization passes. At the end, the assembler turns the generated instructions into machine code.

The hammer My first idea is to replace occurrences of netip.AddrFrom16(ip.As16()) with netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the noding process. Before that, the type checking phase prevents us from accessing unexported struct fields. Go 1.27 introduced a convenient debug option to dump the IR of a function at interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1 GOAMD64=v3 go build -a -gcflags="-d=astdump=AddrTo6Safe" .
Writing text ast output for AddrTo6Safe to AddrTo6Safe.ast
Writing html ast output for AddrTo6Safe to AddrTo6Safe.html
Writing html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
In the HTML file, the first column shows the IR as it comes out of noding:
DCLFUNC addrto6.AddrTo6Safe ABI:ABIInternal FUNC-func(netip.Addr) netip.Addr
DCLFUNC-Dcl
. NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. NAME-addrto6.~r0 Class:PPARAMOUT Offset:0 OnStack netip.Addr
DCLFUNC-body
. IF # ipv6_safe.go:11:2
. IF-Cond
. . CALLFUNC bool
. . CALLFUNC-Fun
. . . METHEXPR addrto6.Is4 FUNC-func(netip.Addr) bool
. . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . CALLFUNC-Args
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. IF-Body
. . AS # ipv6_safe.go:12:6
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . CALLFUNC netip.Addr
. . . CALLFUNC-Fun
. . . . NAME-netip.AddrFrom16 Class:PFUNC Offset:0 Used FUNC-func([16]byte) netip.Addr
. . . CALLFUNC-Args
. . . . CALLFUNC ARRAY-[16]byte
. . . . CALLFUNC-Fun
. . . . . METHEXPR addrto6.As16 FUNC-func(netip.Addr) [16]byte
. . . . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . . . CALLFUNC-Args
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. RETURN # ipv6_safe.go:14:2
. RETURN-Results
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
In the body of the if statement, we spot the calls to the method netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to patch them with a struct literal:
IF-Body
. AS # ipv6_safe.go:12:6
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . STRUCTLIT netip.Addr
. . STRUCTLIT-List
. . . STRUCTKEY netip.addr
. . . . DOT netip.addr netip.uint128
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . STRUCTKEY netip.z
. . . . NAME-netip.z6noz Class:PEXTERN Offset:0 unique.Handle[net/netip.addrDetail]
In noder s reader.go, the expr() method builds the IR tree for an expression. At the end of the exprCall case, we add a call to a rewriteAddrFrom16As16() function. It takes the current node and returns the struct literal on success, or nil if the rewrite is not possible. First, we check that we have the expected pattern: a call to the netip.AddrFrom16() function with a call to the netip.Addr.As16() method as its only argument:
func rewriteAddrFrom16As16(n ir.Node) ir.Node  
    call, ok := n.(*ir.CallExpr)
    if !ok   call.Op() != ir.OCALLFUNC  
        len(call.Args) != 1   len(call.Init()) != 0  
        !isNetipFunc(call.Fun, "AddrFrom16")  
        return nil
     
    inner, ok := call.Args[0].(*ir.CallExpr)
    if !ok   inner.Op() != ir.OCALLFUNC  
        len(inner.Args) != 1   len(inner.Init()) != 0  
        !isNetipFunc(inner.Fun, "Addr.As16")  
        return nil
     
    x := inner.Args[0]
    // [...]
 
Then, we fetch netip.z6noz:
z6noz, err := lookupVar(ir.StaticCalleeName(call.Fun).Sym().Pkg, "z6noz")
if err != nil  
    return nil
 
And we build the struct literal:
typ := call.Type()
pos := call.Pos()
var list []ir.Node
for i, f := range typ.Fields()  
    var value ir.Node
    switch f.Sym.Name  
    case "addr":
        value = typecheck.DotField(pos, x, i)
    case "z":
        value = z6noz
    default:
        return nil
     
    list = append(list, ir.NewStructKeyExpr(pos, f, value))
 
lit := ir.NewCompLitExpr(pos, ir.OSTRUCTLIT, typ, list)
lit.SetTypecheck(1)
return lit
Have a look at the complete patch.8 We can test it with the following commands:
$ cd src
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)
Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.
Checking command staleness for linux/amd64.
---
Installed Go for linux/amd64 in /home/bernat/code/free/go
Installed commands in /home/bernat/code/free/go/bin
*** You need to add /home/bernat/code/free/go/bin to your PATH.
$ export PATH=$PWD/../bin:$PATH
$ go version
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64
$ go test net/netip/...
ok      net/netip   0.224s
$ cd ../../go-netip-addrto6
$ go test .
ok      github.com/vincentbernat/go-netip-addrto6   0.062s
The generated code for the helper is now the shortest possible version!
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go maintainers are unlikely to accept this change. It relies on the internal structure of net/netip.Addr. It s an ugly hack in the noder, whose job is to faithfully translate the type-checked AST into the IR. And it s harder to maintain than adding a To6() method.

The screwdriver The right place for such an optimization is the generic SSA phase. One of the last machine-independent passes is memcombine. With the appropriate debug flag, the compiler dumps the SSA form after this pass:9
$ GOTOOLCHAIN=go1.26.8 GOAMD64=v3 \
> go build -a -gcflags='-d=ssa/memcombine/dump=AddrTo6Safe' .
$ head -5 AddrTo6Safe_01__memcombine.dump
AddrTo6Safe func(netip.Addr) netip.Addr
  b2:
    (?) v1 = InitMem <mem>
    (?) v2 = SP <uintptr>
    (?) v3 = SB <uintptr>
The result of the memcombine pass follows the same structure as the assembly code for AddrTo6Safe() we looked at earlier: two stores, one move, and two loads we would like to optimize away.
; [ ]
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v466 = ArgIntReg <*netip.addrDetail>  ip+16  [2]  ; input.z
; [ ]
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
; [ ]
Each line features a value identifier (v442), an operation with its type (Bswap64 <uint64>), and its arguments (v490).10 Values are the basic building blocks of SSA and are defined exactly once. Square brackets enclose integer parameters ([8]) and curly braces contain auxiliary arguments ( netip.addr ). Operations writing to memory produce a new memory state. Every memory operation takes the current state as its last argument, which keeps them in order.

On paper Let s focus on output.addr.lo, aka v39:
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
To simplify this code, we could apply three rewriting rules:
  1. The first one adds a shortcut when loading through a move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174 with its arguments v415 and v286 and creates a new value v600:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Load <uint64> v600 v282                    ; a16[8:]
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  2. The second one simplifies a load following a store: (Load p (Store p x _)) => x. The load is forwarded: the stored value replaces it and no memory access remains. It matches v174. It notices that v600 and v173 are the same address and replaces v174 with a copy of v442:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  3. The last step cancels the two byte swaps: (Bswap64 (Bswap64 x)) => x. v39 becomes a copy of v490:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Copy <uint64> v490                         ; output.addr.lo = input.addr.lo
    
If we ignore the values not needed to compute v39, only this SSA form remains:
  v490 = ArgIntReg <uint64>  ip+8  [1]  ; input.addr.lo
  v39  = Copy <uint64> v490             ; output.addr.lo = input.addr.lo
Let s switch to output.addr.hi, aka v299:
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
To optimize it away, we also apply three rewriting rules:
  1. The first one also adds a shortcut when loading through a move, but without an offset: (Load p (Move p src mem)) => (Load src mem). This rewrites v416 to use arguments from v286:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Load <uint64> v22 v282                     ; a16[:8]
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  2. The second rule forwards a value stored one step earlier, skipping over a store to another address: (Load p (Store q _ (Store p x _))) => x. This matches v416: x is v542, p is v22 (&a16), q is v173 (&a16[8]), and p and q do not overlap for uint64.
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  3. The third rule cancels two byte swaps: (Bswap64 (Bswap64 x)) => x. v299 becomes a copy of v502:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Copy <uint64> v502                         ; output.addr.hi = input.addr.hi
    
If we remove the values not used to compute v299, we get this SSA form:
  v502 = ArgIntReg <uint64>  ip+0  [0] ; input.addr.hi
  v299 = Copy <uint64> v502            ; output.addr.hi = input.addr.hi

In practice Most of these rules already exist in generic.rules. They use conditions to validate their context: ssa.IsSamePtr() for the same address, ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored value to a load already exists with three variants looking through several other stores. Here are the two we need:
(Load <t1> p1 (Store  t2  p2 x _))
    && ssa.IsSamePtr(p1, p2)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t2.Size()
    => x
(Load <t1> p1 (Store  t2  p2 _ (Store  t3  p3 x _)))
    && ssa.IsSamePtr(p1, p3)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t3.Size()
    && ssa.Disjoint(p3, t3, p2, t2)
    => x
Go 1.27 added the rule loading through a move with CL 748200 to fix issue #77720:
(Load <t1> op1:(OffPtr [o1] p1) move:(Move [n] p2 src mem))
    && o1 >= 0 && o1+t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <op1.Type> [o1] src) mem)
It lacks a variant without an offset:
(Load <t1> p1 move:(Move [n] p2 src mem))
    && p1.Op != ssaop.OpOffPtr
    && t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <p1.Type> [0] src) mem)
There is no generic rule to cancel two byte swaps, but the AMD64 lowering pass includes this rule:
(BSWAP(Q L) (BSWAP(Q L) p)) => p
After switching to Go s development branch and adding the missing rule, the generated assembly code is worse than with Go 1.26.8, even though our additional rule slightly improves the situation at the end:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (16 bytes):
;    0(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $16, SP
 CMPQ    net/netip z4(SB), CX       ; check "z" if this is an IPv4 address
 JNE     end                        ; if not, stop here
; The four forwarded bytes: the low half of input.addr.lo is taken apart and
; put back together in registers
 MOVQ    BX, DX                     ; DX = input.addr.lo
 SHRQ    $24, BX                    ; BX = input.addr.lo >> 24
 MOVQ    DX, SI                     ; SI = input.addr.lo
 SHRQ    $16, DX                    ; DX = input.addr.lo >> 16
 MOVQ    SI, DI                     ; DI = input.addr.lo, kept for the pack
 SHRQ    $8, SI                     ; SI = input.addr.lo >> 8
 MOVBLZX DIB, R8                    ; R8 = byte(input.addr.lo)
 MOVBLZX SIB, SI                    ; SI = byte(input.addr.lo >> 8)
 SHLQ    $8, SI
 ORQ     R8, SI                     ; SI = two low bytes of input.addr.lo
 MOVBLZX DL, DX                     ; DX = byte(input.addr.lo >> 16)
 SHLQ    $16, DX
 ORQ     SI, DX
 MOVBLZX BL, BX                     ; BX = byte(input.addr.lo >> 24)
 SHLQ    $24, BX
 ORQ     DX, BX                     ; BX = input.addr.lo & 0xffffffff
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16(SP)
 MOVBEQ  DI, net/netip a16+8(SP)
; The four other bytes of input.addr.lo, read one by one from a16
 MOVBLZX net/netip a16+11(SP), DX   ; a16[11]
 SHLQ    $32, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+10(SP), DX   ; a16[10]
 SHLQ    $40, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+9(SP), DX    ; a16[9]
 SHLQ    $48, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+8(SP), DX    ; a16[8]
 SHLQ    $56, DX
; output.z = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; output.addr.hi = byteorder.BEUint64(a16[:8])
 MOVBEQ  net/netip a16(SP), AX
; output.addr.lo assembled from the previous steps
 ORQ     DX, BX
end:
 LEAVEQ
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The rule loading through a move, added in Go 1.27, introduced this regression.

Out of order Let s not give up now! In reality, the rewriting rules run before memcombine, notably in the late opt pass. At this point, the inlined versions of BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen byte loads, matching their source code:
func BEUint64(b []byte) uint64  
    _ = b[7] // bounds check hint to compiler; see golang.org/issue/14808
    return uint64(b[7])   uint64(b[6])<<8   uint64(b[5])<<16   uint64(b[4])<<24  
        uint64(b[3])<<32   uint64(b[2])<<40   uint64(b[1])<<48   uint64(b[0])<<56
 
Let s follow two bytes of output.addr.lo: addr[15] and addr[11]. Here is a simplified SSA form before late opt:
  v273 = Trunc64to8 <byte> v490                     ; byte(input.addr.lo)
  v226 = Trunc64to8 <byte> v225                     ; byte(input.addr.lo >> 32)
; [ ]
  v235 = Store <mem>  byte  v233 v226 v223          ; a16[11] = byte(lo >> 32)
  v247 = Store <mem>  byte  v245 v238 v235          ; a16[12] =  
  v259 = Store <mem>  byte  v257 v250 v247          ; a16[13] =  
  v271 = Store <mem>  byte  v269 v262 v259          ; a16[14] =  
  v282 = Store <mem>  byte  v280 v273 v271          ; a16[15] = byte(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
; [ ]
  v433 = OffPtr <*byte> [15] v285                   ; &addr[15]
  v435 = Load <byte> v433 v286                      ; addr[15]
  v479 = OffPtr <*byte> [11] v285                   ; &addr[11]
  v481 = Load <byte> v479 v286                      ; addr[11]
The first rule loads through the move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). It matches both loads, which now read a16 with the memory state before the copy:
  v600 = OffPtr <*byte> [15] v22 ; &a16[15]
  v435 = Load <byte> v600 v282   ; a16[15]
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The second rule shortcuts a load following a store: (Load p (Store p x _)) => x. It matches v435, as v282 stores a16[15]. It does not match v481: v235 stores a16[11] four stores earlier in the chain, while the variants of this rule look through three stores at most.
  v435 = Copy <byte> v273        ; byte(input.addr.lo)
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The same happens to the other bytes: the rule forwards the four bytes stored last, a16[12] to a16[15]. The twelve other loads now read a16 instead of addr. BEUint64() becomes a chain of Or64, each one adding a byte shifted into place. memcombine is a pass written in Go, not a set of rewrite rules. It starts from the last Or64 of the chain and collects up to eight terms. If each term is a byte load, extended to 64 bits and shifted, and if the eight loads read consecutive addresses from the same pointer with the same memory state, it replaces the whole chain with a single 64-bit load and a byte swap. Otherwise, it tries again with four, then two terms, and from each intermediate Or64. Here is the loop checking each term in a simplified version of combineLoads():
for i := int64(0); i < n; i++  
    v := a[i]
    shift := int64(0)
    if v.Op == shiftOp  
        v, shift = peelShift(v)
     
    if v.Op != extOp  
        return false
     
    load := v.Args[0]
    if load.Op != ssaop.OpLoad  
        return false
     
    if load.Args[1] != mem  
        return false
     
    p, off := splitPtr(load.Args[0])
    if p != base  
        return false
     
    r[i] = LoadRecord load: load, offset: off, shift: shift 
 
For output.addr.hi, the eight loads read a16 with the same memory state v282:
  v13  = Load <byte> v22 v282               ; a16[0]
  v530 = Load <byte> v14 v282               ; a16[1]
  v488 = Load <byte> v504 v282              ; a16[2]
  v405 = Load <byte> v537 v282              ; a16[3]
  v385 = Load <byte> v397 v282              ; a16[4]
  v361 = Load <byte> v373 v282              ; a16[5]
  v196 = Load <byte> v63 v282               ; a16[6]
  v432 = Load <byte> v315 v282              ; a16[7]
  v319 = ZeroExt8to64 <uint64> v432         ; uint64(a16[7])
  v329 = ZeroExt8to64 <uint64> v196         ; uint64(a16[6])
  v330 = Lsh64x64 <uint64> [true] v329 v138 ; uint64(a16[6]) << 8
  v331 = Or64 <uint64> v319 v330            ; a16[7]   a16[6] << 8
; [ ] same for a16[5] to a16[1]
  v401 = ZeroExt8to64 <uint64> v13          ; uint64(a16[0])
  v402 = Lsh64x64 <uint64> [true] v401 v55  ; uint64(a16[0]) << 56
  v403 = Or64 <uint64> v402 v391            ;   a16[0] << 56 = output.addr.hi
memcombine merges them into one load and a swap:
  v286 = Load <uint64> v22 v282   ; a16[:8]
  v285 = Bswap64 <uint64> v286    ; output.addr.hi
For output.addr.lo, here is the chain memcombine sees after late opt:
  v436 = ZeroExt8to64 <uint64> v273 ; addr[15], forwarded
  v448 = Or64 <uint64> v436 v447    ;   addr[14] << 8, forwarded
  v460 = Or64 <uint64> v459 v448    ;   addr[13] << 16, forwarded
  v472 = Or64 <uint64> v471 v460    ;   addr[12] << 24, forwarded
  v484 = Or64 <uint64> v483 v472    ;   a16[11] << 32, loaded
  v496 = Or64 <uint64> v495 v484    ;   a16[10] << 40, loaded
  v508 = Or64 <uint64> v507 v496    ;   a16[9] << 48, loaded
  v520 = Or64 <uint64> v519 v508    ;   a16[8] << 56, loaded
From v520, four of the eight terms are forwarded bytes, not loads from memory, and memcombine can t combine them. It doesn t merge the four remaining loads either, as they sit on top of the forwarded bytes.

Back in order In summary, the rewriting rules run too early to be effective. A quick workaround exists: run an earlier round of memcombine before late opt. After this change, the generated code for the helper is back to the shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
And the benchmark confirms it!
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                       Go 1.26.8                  Our branch               
                         sec/op          sec/op     vs base                
AddrTo6/safe          6.5470n    0%   0.8944n   4%  -86.34% (p=0.002 n=6)
AddrTo6/unsafe        0.9071n    3%   0.8682n   1%   -4.28% (p=0.002 n=6)
AddrTo6/builtin       0.8871n    2%   0.8785n   1%        ~ (p=0.310 n=6)

Next steps I think Go maintainers would reject this change because of the additional memcombine pass. Instead, I plan to publish this blog post and bring up the subject again as a follow-up to issue #54365. Either the sheer complexity and the Go 1.27 regression convince the maintainers that adding a To6() method is simpler and more efficient, or they advise me on how to move forward. Either way, digging into this subject taught me a lot about the Go compiler!

Update (2026-10) I opened issue #81994 to propose Addr.To6(). Give it a if you want it in Go!


  1. IPv4-mapped IPv6 addresses let you handle only IPv6 addresses in your code and keep conversions at a few well-defined boundaries. I use them in Akvorado.
  2. This is not strictly equivalent. The zero value becomes :: while it would make more sense to leave it untouched.
  3. I suppose Go maintainers keep it inconvenient on purpose: they don t want random packages to patch the standard library or other packages.
  4. To avoid catastrophic bugs when netip.Addr s layout changes, you must add tests to detect it. This is more dangerous if you put this code in a package. Either ask users to run the tests themselves, or detect the change at run time and panic. Hiding this optimization behind a build tag would make users aware of this potential trap.
  5. I produced the assembly code with GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm '\.asm' from the companion repository, then edited it a bit to keep this article from turning into an endless rabbit hole. Due to an unfortunate sequence of events, we switch between versions: Go 1.27 introduced a regression that blurs the point of this article.
  6. The function is short enough for the compiler to inline it, so the assembly code may vary depending on the surrounding code.
  7. MOVBEQ requires GOAMD64=v3, matching the x86-64-v3 microarchitecture from 2013. Otherwise, the compiler translates BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
  8. When the call is used as a statement, a struct literal alone is invalid. The patch then turns it into _ = netip.Addr .
  9. The compiler can also write an HTML file with the result of each pass:
    $ GOSSAFUNC=AddrTo6Safe \
    > GOTOOLCHAIN=go1.26.8 \
    > GOAMD64=v3 go build -a .
    dumped SSA for AddrTo6Safe,1 to ./ssa.html
    
  10. Source line numbers in parentheses follow value identifiers, but I removed them from the examples. The SSA form also features branches, but we don t need them to understand our optimizations.

Vincent Bernat: Hacking the Go compiler to efficiently map IPv4 to IPv6

netip.Addr features an Unmap() method returning the unwrapped IPv4 contained in an IPv4-mapped IPv6 address: from ::ffff:203.0.113.10 or ::ffff:cb00:710a, it returns 203.0.113.10.1 There is no Map() or To6() method for the reverse direction. Such a method is trivial to implement, but Go maintainers have rejected it on the grounds that users should write netip.AddrFrom16(ip.As16()) and let the compiler optimize it.2 Today, this pattern is eight times slower than a native method. How can we teach the compiler to optimize this sequence?

The alternatives Let s explore three ways to implement the map semantics for netip.Addr. My favorite is to add it to the Go standard library. Go maintainers prefer a small external helper chaining netip.AddrFrom16() and netip.Addr.As16(), hoping the compiler eventually optimizes it. The unsafe package opens a third path, with the same performance as the first solution.

Modifying the Go standard library Internally, netip.Addr stores any IP address as a 128-bit value with an extra field z to encode the family and the zone:
type Addr struct  
    addr uint128
    z unique.Handle[addrDetail]
 
type addrDetail struct  
    isV6   bool   // IPv4 is false, IPv6 is true.
    zoneV6 string // != "" only if IsV6 is true.
 
var (
    z0    unique.Handle[addrDetail]
    z4    = unique.Make(addrDetail )
    z6noz = unique.Make(addrDetail isV6: true )
)
AddrFrom4() encodes an IPv4 address as an IPv4-mapped IPv6 address and sets z to the unique value z4:
// AddrFrom4 returns the address of the IPv4 address given by the bytes in addr.
func AddrFrom4(addr [4]byte) Addr  
    return Addr 
        addr: uint128 
            0,
            0xffff00000000  
                uint64(addr[0])<<24   uint64(addr[1])<<16  
                uint64(addr[2])<<8   uint64(addr[3]) ,
        z: z4,
     
 
Unmap() turns an IPv4-mapped IPv6 address into an IPv4 address by setting the z field to z4:
func (ip Addr) Unmap() Addr  
    if ip.Is4In6()  
        ip.z = z4
     
    return ip
 
Implementing the reverse direction inside the Go standard library is trivial: we set the z field to z6noz if the address is IPv4.
// To6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func (ip Addr) To6() Addr  
    if ip.Is4()  
        ip.z = z6noz
     
    return ip
 

As a helper We can t access the z field from outside the net/netip package. Instead, we build a small helper around the netip.AddrFrom16(ip.As16()) pattern:
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if ip.Is4()  
        ip = netip.AddrFrom16(ip.As16())
     
    return ip
 

As an unsafe function Another solution uses the unsafe package to alter the Addr struct through a proxy with the same memory layout:3
// addrProxy has the same memory layout as netip.Addr.
type addrProxy struct  
    addr [2]uint64      // netip.uint128
    z    unsafe.Pointer // unique.Handle[netip.addrDetail]
 
var (
    anyIPv6    = netip.IPv6Unspecified()
    netipZ6noz = (*addrProxy)(unsafe.Pointer(&anyIPv6)).z
)
// AddrTo6 maps an IPv4 address to an IPv4-mapped IPv6 address. It returns an
// IPv6 address unmodified.
func AddrTo6(ip netip.Addr) netip.Addr  
    if !ip.Is4()  
        return ip
     
    (*addrProxy)(unsafe.Pointer(&ip)).z = netipZ6noz
    return ip
 

Benchmarks On my computer, with Go 1.27.1, the standard library solution costs 0.88 ns per operation, while the solution favored by Go maintainers costs 7.14 ns. The unsafe solution matches the performance of the first one.
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                         sec/op      
AddrTo6/safe            7.137n   0%
AddrTo6/unsafe         0.8682n   2%
AddrTo6/builtin        0.8775n   2%

Assembly code Let s check the assembly code the compiler generates for each solution.4 The one built into the standard library looks like this:5
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE   end                      ; if not, stop here
 MOVQ  net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go s assembly language is not a direct representation of the underlying machine language: it operates on a semi-abstract instruction set derived from Plan 9 s assembler. It has four pseudo-registers: FP (frame pointer for function arguments), PC (program counter), SB (static base pointer for global symbols), and SP (stack pointer). It also has architecture-specific registers like AX, CX, DX, BX, SI, DI, and R8 to R15. Instructions storing data use their last argument as the destination. Instructions can carry an explicit size suffix: MOVB moves a byte, MOVW 16 bits, MOVL 32 bits, and MOVQ 64 bits. In the example above, the first instruction compares the 64-bit value z4 with the CX register. The unsafe solution looks almost the same:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ  net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE   end                   ; if not, stop here
 MOVQ  netipZ6noz(SB), CX    ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The helper solution has far more instructions. To understand why, let s look at the code for As16() and AddrFrom16(). They are short enough for the compiler to inline them.
func (ip Addr) As16() (a16 [16]byte)  
    byteorder.BEPutUint64(a16[:8], ip.addr.hi)
    byteorder.BEPutUint64(a16[8:], ip.addr.lo)
    return a16
 
func AddrFrom16(addr [16]byte) Addr  
    return Addr 
        addr: uint128 
            byteorder.BEUint64(addr[:8]),
            byteorder.BEUint64(addr[8:]),
         ,
        z: z6noz,
     
 
We can already guess the pattern to optimize: the code packs the IP address into an array, copies it, then unpacks it. If we inline the Go code by hand, we get:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var a16 [16]byte
    byteorder.BEPutUint64(a16[:8], input.addr.hi)
    byteorder.BEPutUint64(a16[8:], input.addr.lo)
    addr := a16
    var output netip.Addr
    output.addr.hi = byteorder.BEUint64(addr[:8])
    output.addr.lo = byteorder.BEUint64(addr[8:])
    output.z = netip.z6noz
    return output
 
As humans, we can mentally derive the optimized form:
func AddrTo6(input netip.Addr) netip.Addr  
    if !input.Is4()  
        return input
     
    var output netip.Addr
    output.addr.hi = input.addr.hi
    output.addr.lo = input.addr.lo
    output.z = netip.z6noz
    return output
 

Unfortunately, as of Go 1.26.8, the compiler is not smart enough to do the same:

// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (32 bytes):
;    0(SP) addr netip.uint128
;   16(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $32, SP
 CMPQ    net/netip z4(SB), CX  ; check "z" if this is an IPv4 address
 JNE     end                   ; if not, stop here
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16+16(SP)
 MOVBEQ  BX, net/netip a16+24(SP)
; addr = a16, 16 bytes at once through the vector register X0
 MOVUPS  net/netip a16+16(SP), X0
 MOVUPS  X0, net/netip addr(SP)
; CX = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; Unpack: output.addr.hi = byteorder.BEUint64(addr[:8])
;         output.addr.lo = byteorder.BEUint64(addr[8:])
 MOVBEQ  net/netip addr(SP), AX
 MOVBEQ  net/netip addr+8(SP), BX
end:
 ADDQ    $32, SP
 POPQ    BP
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The compiler does a decent job on the byte shuffling: the eight byte stores of BEPutUint64() become a single MOVBEQ, which stores a register byte-swapped. The eight byte loads of BEUint64() become a single MOVBEQ the other way round.6 Three groups of instructions remain: a pack, a copy, and an unpack.

Hacking the Go compiler The Go compiler has several phases:
Parsing
The compiler tokenizes and parses the source code. It builds a syntax tree for each source file.
Type checking
The compiler maps each identifier to the object it denotes, folds constants, and infers the type of every expression.
IR construction
The compiler converts the syntax tree and its types into its own intermediate representation (IR). This process, called noding, goes through a serialization format named unified IR.
Middle end
The compiler performs several optimization passes on the IR, such as devirtualization, function call inlining, and escape analysis.
Walk
This phase runs two steps: order of evaluation decomposes complex statements into simpler ones, and desugaring transforms higher-level Go constructs, like switch or channels, into more primitive instructions or calls to the runtime.
Generic SSA
The compiler converts the IR into Static Single Assignment (SSA) form, a lower-level intermediate representation suited for machine-independent optimizations and rewrite rules.
Machine code generation
The compiler rewrites the SSA form into machine-specific variants, allocates registers, and applies more optimization passes. At the end, the assembler turns the generated instructions into machine code.

The hammer My first idea is to replace occurrences of netip.AddrFrom16(ip.As16()) with netip.Addr addr: ip.addr, z: netip.z6noz as early as possible, during the noding process. Before that, the type checking phase prevents us from accessing unexported struct fields. Go 1.27 introduced a convenient debug option to dump the IR of a function at interesting points during compilation:
$ GOTOOLCHAIN=go1.27.1 GOAMD64=v3 go build -a -gcflags="-d=astdump=AddrTo6Safe" .
Writing text ast output for AddrTo6Safe to AddrTo6Safe.ast
Writing html ast output for AddrTo6Safe to AddrTo6Safe.html
Writing html syntax output for AddrTo6Safe to AddrTo6Safe.syntax.html
In the HTML file, the first column shows the IR as it comes out of noding:
DCLFUNC addrto6.AddrTo6Safe ABI:ABIInternal FUNC-func(netip.Addr) netip.Addr
DCLFUNC-Dcl
. NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. NAME-addrto6.~r0 Class:PPARAMOUT Offset:0 OnStack netip.Addr
DCLFUNC-body
. IF # ipv6_safe.go:11:2
. IF-Cond
. . CALLFUNC bool
. . CALLFUNC-Fun
. . . METHEXPR addrto6.Is4 FUNC-func(netip.Addr) bool
. . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . CALLFUNC-Args
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. IF-Body
. . AS # ipv6_safe.go:12:6
. . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . CALLFUNC netip.Addr
. . . CALLFUNC-Fun
. . . . NAME-netip.AddrFrom16 Class:PFUNC Offset:0 Used FUNC-func([16]byte) netip.Addr
. . . CALLFUNC-Args
. . . . CALLFUNC ARRAY-[16]byte
. . . . CALLFUNC-Fun
. . . . . METHEXPR addrto6.As16 FUNC-func(netip.Addr) [16]byte
. . . . . . TYPE netip.Addr Class:PEXTERN Offset:0 type netip.Addr
. . . . CALLFUNC-Args
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. RETURN # ipv6_safe.go:14:2
. RETURN-Results
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
In the body of the if statement, we spot the calls to the method netip.Addr.As16() and to the function netip.AddrFrom16(). Our goal is to patch them with a struct literal:
IF-Body
. AS # ipv6_safe.go:12:6
. . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . STRUCTLIT netip.Addr
. . STRUCTLIT-List
. . . STRUCTKEY netip.addr
. . . . DOT netip.addr netip.uint128
. . . . . NAME-addrto6.ip Class:PPARAM Offset:0 OnStack Used netip.Addr
. . . STRUCTKEY netip.z
. . . . NAME-netip.z6noz Class:PEXTERN Offset:0 unique.Handle[net/netip.addrDetail]
In noder s reader.go, the expr() method builds the IR tree for an expression. At the end of the exprCall case, we add a call to a rewriteAddrFrom16As16() function. It takes the current node and returns the struct literal on success, or nil if the rewrite is not possible. First, we check that we have the expected pattern: a call to the netip.AddrFrom16() function with a call to the netip.Addr.As16() method as its only argument:
func rewriteAddrFrom16As16(n ir.Node) ir.Node  
    call, ok := n.(*ir.CallExpr)
    if !ok   call.Op() != ir.OCALLFUNC  
        len(call.Args) != 1   len(call.Init()) != 0  
        !isNetipFunc(call.Fun, "AddrFrom16")  
        return nil
     
    inner, ok := call.Args[0].(*ir.CallExpr)
    if !ok   inner.Op() != ir.OCALLFUNC  
        len(inner.Args) != 1   len(inner.Init()) != 0  
        !isNetipFunc(inner.Fun, "Addr.As16")  
        return nil
     
    x := inner.Args[0]
    // [...]
 
Then, we fetch netip.z6noz:
z6noz, err := lookupVar(ir.StaticCalleeName(call.Fun).Sym().Pkg, "z6noz")
if err != nil  
    return nil
 
And we build the struct literal:
typ := call.Type()
pos := call.Pos()
var list []ir.Node
for i, f := range typ.Fields()  
    var value ir.Node
    switch f.Sym.Name  
    case "addr":
        value = typecheck.DotField(pos, x, i)
    case "z":
        value = z6noz
    default:
        return nil
     
    list = append(list, ir.NewStructKeyExpr(pos, f, value))
 
lit := ir.NewCompLitExpr(pos, ir.OSTRUCTLIT, typ, list)
lit.SetTypecheck(1)
return lit
Have a look at the complete patch.7 We can test it with the following commands:
$ cd src
$ ./make.bash
Building Go cmd/dist using /usr/lib/go-1.27. (go1.27.1 linux/amd64)
Building Go toolchain1 and bootstrap cmd/go (go_bootstrap) using /usr/lib/go-1.27.
Building Go toolchain2 using go_bootstrap and Go toolchain1.
Building Go toolchain3 and commands using go_bootstrap and Go toolchain2.
Checking command staleness for linux/amd64.
---
Installed Go for linux/amd64 in /home/bernat/code/free/go
Installed commands in /home/bernat/code/free/go/bin
*** You need to add /home/bernat/code/free/go/bin to your PATH.
$ export PATH=$PWD/../bin:$PATH
$ go version
go version go1.28-devel_9834516e20 Sat Sep 12 08:23:11 2026 -0700 linux/amd64
$ go test net/netip/...
ok      net/netip   0.224s
$ cd ../../go-netip-addrto6
$ go test .
ok      github.com/vincentbernat/go-netip-addrto6   0.062s
The generated code for the helper is now the shortest possible version!
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
Go maintainers are unlikely to accept this change. It relies on the internal structure of net/netip.Addr. It s an ugly hack in the noder, whose job is to faithfully translate the type-checked AST into the IR. And it s harder to maintain than adding a To6() method.

The screwdriver The right place for such an optimization is the generic SSA phase. One of the last machine-independent passes is memcombine. With the appropriate debug flag, the compiler dumps the SSA form after this pass:8
$ GOTOOLCHAIN=go1.26.8 GOAMD64=v3 \
> go build -a -gcflags='-d=ssa/memcombine/dump=AddrTo6Safe' .
$ head -5 AddrTo6Safe_01__memcombine.dump
AddrTo6Safe func(netip.Addr) netip.Addr
  b2:
    (?) v1 = InitMem <mem>
    (?) v2 = SP <uintptr>
    (?) v3 = SB <uintptr>
The result of the memcombine pass follows the same structure as the assembly code for AddrTo6Safe() we looked at earlier: two stores, one move, and two loads we would like to optimize away.
; [ ]
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v466 = ArgIntReg <*netip.addrDetail>  ip+16  [2]  ; input.z
; [ ]
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
; [ ]
Each line features a value identifier (v442), an operation with its type (Bswap64 <uint64>), and its arguments (v490).9 Values are the basic building blocks of SSA and are defined exactly once. Square brackets enclose integer parameters ([8]) and curly braces contain auxiliary arguments ( netip.addr ). Operations writing to memory produce a new memory state. Every memory operation takes the current state as its last argument, which keeps them in order.

On paper Let s focus on output.addr.lo, aka v39:
  v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
  v174 = Load <uint64> v415 v286                    ; addr[8:]
  v39  = Bswap64 <uint64> v174                      ; output.addr.lo
To simplify this code, we could apply three rewriting rules:
  1. The first one adds a shortcut when loading through a move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). This matches v174 with its arguments v415 and v286 and creates a new value v600:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Load <uint64> v600 v282                    ; a16[8:]
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  2. The second one simplifies a load following a store: (Load p (Store p x _)) => x. The load is forwarded: the stored value replaces it and no memory access remains. It matches v174. It notices that v600 and v173 are the same address and replaces v174 with a copy of v442:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Bswap64 <uint64> v174                      ; output.addr.lo
    
  3. The last step cancels the two byte swaps: (Bswap64 (Bswap64 x)) => x. v39 becomes a copy of v490:
      v490 = ArgIntReg <uint64>  ip+8  [1]              ; input.addr.lo
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v442 = Bswap64 <uint64> v490                      ; bswap(input.addr.lo)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v415 = OffPtr <*byte> [8] v285                    ; &addr[8]
      v600 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v174 = Copy <uint64> v442                         ; bswap(input.addr.lo)
      v39  = Copy <uint64> v490                         ; output.addr.lo = input.addr.lo
    
If we ignore the values not needed to compute v39, only this SSA form remains:
  v490 = ArgIntReg <uint64>  ip+8  [1]  ; input.addr.lo
  v39  = Copy <uint64> v490             ; output.addr.lo = input.addr.lo
Let s switch to output.addr.hi, aka v299:
  v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
  v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
  v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
  v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
  v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
  v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
  v416 = Load <uint64> v285 v286                    ; addr[:8]
  v299 = Bswap64 <uint64> v416                      ; output.addr.hi
To optimize it away, we also apply three rewriting rules:
  1. The first one also adds a shortcut when loading through a move, but without an offset: (Load p (Move p src mem)) => (Load src mem). This rewrites v416 to use arguments from v286:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Load <uint64> v22 v282                     ; a16[:8]
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  2. The second rule forwards a value stored one step earlier, skipping over a store to another address: (Load p (Store q _ (Store p x _))) => x. This matches v416: x is v542, p is v22 (&a16), q is v173 (&a16[8]), and p and q do not overlap for uint64.
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Bswap64 <uint64> v416                      ; output.addr.hi
    
  3. The third rule cancels two byte swaps: (Bswap64 (Bswap64 x)) => x. v299 becomes a copy of v502:
      v502 = ArgIntReg <uint64>  ip+0  [0]              ; input.addr.hi
      v22 = LocalAddr <*[16]byte>  netip.a16  v2 v1     ; &a16
      v173 = OffPtr <*byte> [8] v22                     ; &a16[8]
      v542 = Bswap64 <uint64> v502                      ; bswap(input.addr.hi)
      v161 = Store <mem>  uint64  v22 v542 v23          ; a16[:8] = bswap(hi)
      v282 = Store <mem>  uint64  v173 v442 v161        ; a16[8:] = bswap(lo)
      v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
      v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
      v416 = Copy <uint64> v542                         ; bswap(input.addr.hi)
      v299 = Copy <uint64> v502                         ; output.addr.hi = input.addr.hi
    
If we remove the values not used to compute v299, we get this SSA form:
  v502 = ArgIntReg <uint64>  ip+0  [0] ; input.addr.hi
  v299 = Copy <uint64> v502            ; output.addr.hi = input.addr.hi

In practice Most of these rules already exist in generic.rules. They use conditions to validate their context: ssa.IsSamePtr() for the same address, ssa.Disjoint() for addresses that do not overlap. The rule forwarding a stored value to a load already exists with three variants looking through several other stores. Here are the two we need:
(Load <t1> p1 (Store  t2  p2 x _))
    && ssa.IsSamePtr(p1, p2)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t2.Size()
    => x
(Load <t1> p1 (Store  t2  p2 _ (Store  t3  p3 x _)))
    && ssa.IsSamePtr(p1, p3)
    && copyCompatibleType(t1, x.Type)
    && t1.Size() == t3.Size()
    && ssa.Disjoint(p3, t3, p2, t2)
    => x
Go 1.27 added the rule loading through a move with CL 748200 to fix issue #77720:
(Load <t1> op1:(OffPtr [o1] p1) move:(Move [n] p2 src mem))
    && o1 >= 0 && o1+t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <op1.Type> [o1] src) mem)
It lacks a variant without an offset:
(Load <t1> p1 move:(Move [n] p2 src mem))
    && p1.Op != ssaop.OpOffPtr
    && t1.Size() <= n && ssa.IsSamePtr(p1, p2)
    && !ssa.IsVolatile(src)
    => @move.Block (Load <t1> (OffPtr <p1.Type> [0] src) mem)
There is no generic rule to cancel two byte swaps, but the AMD64 lowering pass includes this rule:
(BSWAP(Q L) (BSWAP(Q L) p)) => p
After switching to Go s development branch and adding the missing rule, the generated assembly code is worse than with Go 1.26.8, even though our additional rule slightly improves the situation at the end:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
; Push the stack (16 bytes):
;    0(SP) a16 [16]byte
 PUSHQ   BP
 MOVQ    SP, BP
 SUBQ    $16, SP
 CMPQ    net/netip z4(SB), CX       ; check "z" if this is an IPv4 address
 JNE     end                        ; if not, stop here
; The four forwarded bytes: the low half of input.addr.lo is taken apart and
; put back together in registers
 MOVQ    BX, DX                     ; DX = input.addr.lo
 SHRQ    $24, BX                    ; BX = input.addr.lo >> 24
 MOVQ    DX, SI                     ; SI = input.addr.lo
 SHRQ    $16, DX                    ; DX = input.addr.lo >> 16
 MOVQ    SI, DI                     ; DI = input.addr.lo, kept for the pack
 SHRQ    $8, SI                     ; SI = input.addr.lo >> 8
 MOVBLZX DIB, R8                    ; R8 = byte(input.addr.lo)
 MOVBLZX SIB, SI                    ; SI = byte(input.addr.lo >> 8)
 SHLQ    $8, SI
 ORQ     R8, SI                     ; SI = two low bytes of input.addr.lo
 MOVBLZX DL, DX                     ; DX = byte(input.addr.lo >> 16)
 SHLQ    $16, DX
 ORQ     SI, DX
 MOVBLZX BL, BX                     ; BX = byte(input.addr.lo >> 24)
 SHLQ    $24, BX
 ORQ     DX, BX                     ; BX = input.addr.lo & 0xffffffff
; Pack: byteorder.BEPutUint64(a16[:8], input.addr.hi)
;       byteorder.BEPutUint64(a16[8:], input.addr.lo)
 MOVBEQ  AX, net/netip a16(SP)
 MOVBEQ  DI, net/netip a16+8(SP)
; The four other bytes of input.addr.lo, read one by one from a16
 MOVBLZX net/netip a16+11(SP), DX   ; a16[11]
 SHLQ    $32, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+10(SP), DX   ; a16[10]
 SHLQ    $40, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+9(SP), DX    ; a16[9]
 SHLQ    $48, DX
 ORQ     DX, BX
 MOVBLZX net/netip a16+8(SP), DX    ; a16[8]
 SHLQ    $56, DX
; output.z = netip.z6noz
 MOVQ    net/netip z6noz(SB), CX
; output.addr.hi = byteorder.BEUint64(a16[:8])
 MOVBEQ  net/netip a16(SP), AX
; output.addr.lo assembled from the previous steps
 ORQ     DX, BX
end:
 LEAVEQ
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
The rule loading through a move, added in Go 1.27, introduced this regression.

Out of order Let s not give up now! In reality, the rewriting rules run before memcombine, notably in the late opt pass. At this point, the inlined versions of BEPutUint64() and BEUint64() still expand to sixteen byte stores and sixteen byte loads, matching their source code:
func BEUint64(b []byte) uint64  
    _ = b[7] // bounds check hint to compiler; see golang.org/issue/14808
    return uint64(b[7])   uint64(b[6])<<8   uint64(b[5])<<16   uint64(b[4])<<24  
        uint64(b[3])<<32   uint64(b[2])<<40   uint64(b[1])<<48   uint64(b[0])<<56
 
Let s follow two bytes of output.addr.lo: addr[15] and addr[11]. Here is a simplified SSA form before late opt:
  v273 = Trunc64to8 <byte> v490                     ; byte(input.addr.lo)
  v226 = Trunc64to8 <byte> v225                     ; byte(input.addr.lo >> 32)
; [ ]
  v235 = Store <mem>  byte  v233 v226 v223          ; a16[11] = byte(lo >> 32)
  v247 = Store <mem>  byte  v245 v238 v235          ; a16[12] =  
  v259 = Store <mem>  byte  v257 v250 v247          ; a16[13] =  
  v271 = Store <mem>  byte  v269 v262 v259          ; a16[14] =  
  v282 = Store <mem>  byte  v280 v273 v271          ; a16[15] = byte(lo)
  v285 = LocalAddr <*[16]byte>  netip.addr  v2 v282 ; &addr
  v286 = Move <mem>  [16]byte  [16] v285 v22 v282   ; addr = a16
; [ ]
  v433 = OffPtr <*byte> [15] v285                   ; &addr[15]
  v435 = Load <byte> v433 v286                      ; addr[15]
  v479 = OffPtr <*byte> [11] v285                   ; &addr[11]
  v481 = Load <byte> v479 v286                      ; addr[11]
The first rule loads through the move: (Load (OffPtr [o] p) (Move p src mem)) => (Load (OffPtr [o] src) mem). It matches both loads, which now read a16 with the memory state before the copy:
  v600 = OffPtr <*byte> [15] v22 ; &a16[15]
  v435 = Load <byte> v600 v282   ; a16[15]
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The second rule shortcuts a load following a store: (Load p (Store p x _)) => x. It matches v435, as v282 stores a16[15]. It does not match v481: v235 stores a16[11] four stores earlier in the chain, while the variants of this rule look through three stores at most.
  v435 = Copy <byte> v273        ; byte(input.addr.lo)
  v601 = OffPtr <*byte> [11] v22 ; &a16[11]
  v481 = Load <byte> v601 v282   ; a16[11]
The same happens to the other bytes: the rule forwards the four bytes stored last, a16[12] to a16[15]. The twelve other loads now read a16 instead of addr. BEUint64() becomes a chain of Or64, each one adding a byte shifted into place. memcombine is a pass written in Go, not a set of rewrite rules. It starts from the last Or64 of the chain and collects up to eight terms. If each term is a byte load, extended to 64 bits and shifted, and if the eight loads read consecutive addresses from the same pointer with the same memory state, it replaces the whole chain with a single 64-bit load and a byte swap. Otherwise, it tries again with four, then two terms, and from each intermediate Or64. Here is the loop checking each term in a simplified version of combineLoads():
for i := int64(0); i < n; i++  
    v := a[i]
    shift := int64(0)
    if v.Op == shiftOp  
        v, shift = peelShift(v)
     
    if v.Op != extOp  
        return false
     
    load := v.Args[0]
    if load.Op != ssaop.OpLoad  
        return false
     
    if load.Args[1] != mem  
        return false
     
    p, off := splitPtr(load.Args[0])
    if p != base  
        return false
     
    r[i] = LoadRecord load: load, offset: off, shift: shift 
 
For output.addr.hi, the eight loads read a16 with the same memory state v282:
  v13  = Load <byte> v22 v282               ; a16[0]
  v530 = Load <byte> v14 v282               ; a16[1]
  v488 = Load <byte> v504 v282              ; a16[2]
  v405 = Load <byte> v537 v282              ; a16[3]
  v385 = Load <byte> v397 v282              ; a16[4]
  v361 = Load <byte> v373 v282              ; a16[5]
  v196 = Load <byte> v63 v282               ; a16[6]
  v432 = Load <byte> v315 v282              ; a16[7]
  v319 = ZeroExt8to64 <uint64> v432         ; uint64(a16[7])
  v329 = ZeroExt8to64 <uint64> v196         ; uint64(a16[6])
  v330 = Lsh64x64 <uint64> [true] v329 v138 ; uint64(a16[6]) << 8
  v331 = Or64 <uint64> v319 v330            ; a16[7]   a16[6] << 8
; [ ] same for a16[5] to a16[1]
  v401 = ZeroExt8to64 <uint64> v13          ; uint64(a16[0])
  v402 = Lsh64x64 <uint64> [true] v401 v55  ; uint64(a16[0]) << 56
  v403 = Or64 <uint64> v402 v391            ;   a16[0] << 56 = output.addr.hi
memcombine merges them into one load and a swap:
  v286 = Load <uint64> v22 v282   ; a16[:8]
  v285 = Bswap64 <uint64> v286    ; output.addr.hi
For output.addr.lo, here is the chain memcombine sees after late opt:
  v436 = ZeroExt8to64 <uint64> v273 ; addr[15], forwarded
  v448 = Or64 <uint64> v436 v447    ;   addr[14] << 8, forwarded
  v460 = Or64 <uint64> v459 v448    ;   addr[13] << 16, forwarded
  v472 = Or64 <uint64> v471 v460    ;   addr[12] << 24, forwarded
  v484 = Or64 <uint64> v483 v472    ;   a16[11] << 32, loaded
  v496 = Or64 <uint64> v495 v484    ;   a16[10] << 40, loaded
  v508 = Or64 <uint64> v507 v496    ;   a16[9] << 48, loaded
  v520 = Or64 <uint64> v519 v508    ;   a16[8] << 56, loaded
From v520, four of the eight terms are forwarded bytes, not loads from memory, and memcombine can t combine them. It doesn t merge the four remaining loads either, as they sit on top of the forwarded bytes.

Back in order In summary, the rewriting rules run too early to be effective. A quick workaround exists: run an earlier round of memcombine before late opt. After this change, the generated code for the helper is back to the shortest possible version:
// AX = input.addr.hi, BX = input.addr.lo, CX = input.z
 CMPQ    net/netip z4(SB), CX     ; check "z" if this is an IPv4 address
 JNE     end                      ; if not, stop here
 MOVQ    net/netip z6noz(SB), CX  ; CX = netip.z6noz
end:
 RET
// return value = Addr hi: AX, lo: BX, z: CX 
And the benchmark confirms it!
goos: linux
goarch: amd64
pkg: github.com/vincentbernat/go-netip-addrto6
cpu: AMD Ryzen 5 5600X 6-Core Processor
                       Go 1.26.8                  Our branch               
                         sec/op          sec/op     vs base                
AddrTo6/safe          6.5470n    0%   0.8944n   4%  -86.34% (p=0.002 n=6)
AddrTo6/unsafe        0.9071n    3%   0.8682n   1%   -4.28% (p=0.002 n=6)
AddrTo6/builtin       0.8871n    2%   0.8785n   1%        ~ (p=0.310 n=6)

Next steps I think Go maintainers would reject this change because of the additional memcombine pass. Instead, I plan to publish this blog post and bring up the subject again as a follow-up to issue #54365. Either the sheer complexity and the Go 1.27 regression convince the maintainers that adding a To6() method is simpler and more efficient, or they advise me on how to move forward. Either way, digging into this subject taught me a lot about the Go compiler!

  1. IPv4-mapped IPv6 addresses let you handle only IPv6 addresses in your code and keep conversions at a few well-defined boundaries. I use them in Akvorado.
  2. This is not strictly equivalent. The zero value becomes :: while it would make more sense to leave it untouched.
  3. To avoid catastrophic bugs when netip.Addr s layout changes, you must add tests to detect it. This is more dangerous if you put this code in a package. Either ask users to run the tests themselves, or detect the change at run time and panic. Hiding this optimization behind a build tag would make users aware of this potential trap.
  4. I produced the assembly code with GOTOOLCHAIN=go1.26.8 GOAMD64=v3 ./go-asm '\.asm' from the companion repository, then edited it a bit to keep this article from turning into an endless rabbit hole. Due to an unfortunate sequence of events, we switch between versions: Go 1.27 introduced a regression that blurs the point of this article.
  5. The function is short enough for the compiler to inline it, so the assembly code may vary depending on the surrounding code.
  6. MOVBEQ requires GOAMD64=v3, matching the x86-64-v3 microarchitecture from 2013. Otherwise, the compiler translates BEPutUint64() to BSWAPQ+MOVQ and BEUint64() to MOVQ+BSWAPQ.
  7. When the call is used as a statement, a struct literal alone is invalid. The patch then turns it into _ = netip.Addr .
  8. The compiler can also write an HTML file with the result of each pass:
    $ GOSSAFUNC=AddrTo6Safe \
    > GOTOOLCHAIN=go1.26.8 \
    > GOAMD64=v3 go build -a .
    dumped SSA for AddrTo6Safe,1 to ./ssa.html
    
  9. Source line numbers in parentheses follow value identifiers, but I removed them from the examples. The SSA form also features branches, but we don t need them to understand our optimizations.

3 October 2026

Vincent Bernat: Self-hosted HTTP tunnels with SSH and nginx

A friend wants to proofread your work-in-progress blog post, but its preview only runs on localhost:8080. Several tools can help. Some run as a commercial service, like ngrok or Cloudflare Quick Tunnels. Some are self-hostable but require a specific client, like frp or localtunnel. Some only require a plain SSH client but rely on a specific SSH server, like sish. Let s implement a self-hosted solution with only OpenSSH and nginx!
$ ssh -R 0:localhost:8080 http-over-ssh
Allocated port 41535 for remote forward to localhost:8080
https://6J3jK1WmB15c6WmjW_X-Wg--1789928654@p41535.ssh.luffy.cx/

Basic setup First, we forward connections from a port on a remote server to your local service:
$ ssh -N -R 0:localhost:8080 web02.luffy.cx
Allocated port 41535 for remote forward to localhost:8080
When you specify 0 as the remote port, the server allocates a free port. Then, we configure nginx to proxy requests from https://p41535.ssh.luffy.cx to http://127.0.0.1:41535:
server  
  listen 0.0.0.0:443 ssl ;
  listen [::0]:443 ssl ;
  server_name ~^p(?<port>\d\d\d\d\d)\.ssh\.luffy\.cx$;
  location /  
    proxy_pass http://127.0.0.1:$port;
   
 
We also need to add DNS records for *.ssh.luffy.cx and get a wildcard certificate through Let s Encrypt:
*.ssh.luffy.cx.               CNAME web02.luffy.cx.
ssh.luffy.cx.                 CAA   0 issuewild "letsencrypt.org"
_acme-challenge.ssh.luffy.cx  CNAME ssh.luffy.cx.acme.luffy.cx.
acme.luffy.cx is a zone hosted on Route 53. I use it for ACME DNS-01 challenges, both for wildcard certificates and for domains served by several web servers. In my case, NixOS gets the certificates automatically.

Access control The port is the only secret 1 keeping the content confidential. Other forwarding solutions add a random string to the domain name to prevent an intruder from enumerating the possible values. Thanks to ngx_http_secure_link_module, we can secure this setup a bit. This module computes a hash2 over a set of values, including a secret, and compares it with the hash from the request. The hash is base64-encoded, so we cannot put it in the domain name, which is case-insensitive. Instead, we put it in the URL as a username, along with its expiration timestamp:3
https://6J3jK1WmB15c6WmjW_X-Wg--1789928654@p41535.ssh.luffy.cx/en/blog
                             
                hash             expires    port               path
The client sends the username to the server with HTTP basic authentication. This works with most HTTP clients, including curl. Nginx exposes the username in the $remote_user variable. The module expects the hash and the expiration timestamp separated by a comma. We use a map directive to extract the two parts from $remote_user and join them with a comma.4 We also give the module the string to hash. It contains the expiration timestamp, the port, and a secret:
map $remote_user $httpssh_link  
  "~^([-_A-Za-z0-9] 22 )--([0-9]+)$" "$1,$2";
 
server  
  # [ ]
  location /  
    secure_link $httpssh_link;
    secure_link_md5 "$secure_link_expires $port ZuPerS3cr3!";
   
 
The module returns the status of the check in the $secure_link variable:
  • empty if the hashes do not match,
  • "0" if they match but the link has expired, or
  • "1" otherwise.
If the hash is incorrect or missing, we return a 401 error with a WWW-Authenticate header to ask for credentials. If the link has expired, we return a 410 error. We remove the Authorization header before forwarding the request and add a few directives to proxy WebSocket connections. Here is the complete configuration:5
map $remote_user $httpssh_link  
  "~^([-_A-Za-z0-9] 22 )--([0-9]+)$" "$1,$2";
 
server  
  listen 0.0.0.0:443 ssl ;
  listen [::0]:443 ssl ;
  server_name ~^p(?<port>\d\d\d\d\d)\.ssh\.luffy\.cx$;
  location /  
    secure_link $httpssh_link;
    secure_link_md5 "$secure_link_expires $port ZuPerS3cr3!";
    if ($secure_link = "")  
      add_header WWW-Authenticate 'Basic realm="tunnel"' always;
      return 401;
     
    if ($secure_link = "0")  
      return 410;
     
    proxy_pass http://127.0.0.1:$port;
    proxy_set_header Host $host;
    proxy_set_header X-Forwarded-For $proxy_add_x_forwarded_for;
    proxy_set_header Authorization "";
    proxy_http_version 1.1;
    proxy_set_header Upgrade $http_upgrade;
    proxy_set_header Connection "upgrade";
    proxy_buffering off;
    proxy_read_timeout 30m;
   
 
I think you are now asking yourself the obvious question: How should I generate the hash? Easy peasy!
$ expires=$(( $(date +%s) + 86400 ))
$ port=41535
$ secret='ZuPerS3cr3!'
$ printf '%s %s %s' "$expires" "$port" "$secret" \
>     openssl md5 -binary \
>     openssl base64 \
>     tr +/ -_   tr -d =
6J3jK1WmB15c6WmjW_X-Wg
Well, I suppose you are now saying: Vincent, this is not very convenient! I ll stick with ngrok if you don t mind. Okay, I hear you. Let s write a helper script.

Helper script The main difficulty is finding the ephemeral port that OpenSSH allocates, as it does not appear in any environment variable.6 To work around this obstacle, we look for the ancestor sshd-session processes:7
pids=$(
  pid=$$
  while [ "$pid" -gt 1 ]; do
    line=$(ps -o comm=,pid=,ppid= -p "$pid")
    echo "$line"
    pid=$ line##*  
  done   awk '$1 == "sshd-session"   printf "pid=%s,\n", $2  '
)
if [ -z "$pids" ]; then
  echo "not an ssh session" >&2
  exit 1
fi
Then, we get the listening ports associated with these sshd-session processes:8
ports=$(sudo -n ss --listening --numeric --tcp --processes --no-header \
    grep -F "$pids" \
    awk '  print $4  '   awk -F: '  print $NF  ' \
    sort -un)
if [ -z "$ports" ]; then
  echo "no forwarded port, use ssh -R 0:localhost:PORT" >&2
  exit 1
fi
Finally, we display the URLs and keep the session open:
lifetime=86400
secret='ZuPerS3cr3!'
expires=$(( $(date +%s) + lifetime ))
for port in $ports; do
  token=$(printf '%s %s %s' "$expires" "$port" "$secret" \
              openssl md5 -binary \
              openssl base64 \
              tr +/ -_   tr -d =)
  echo "https://$token--$expires@p$port.ssh.luffy.cx/"
done
sleep infinity
I install this script as http-over-ssh on the server and add this entry to my ~/.ssh/config:
Host http-over-ssh
  Hostname web02.luffy.cx
  RemoteCommand http-over-ssh
  ControlPath none
With this solution, I only rely on OpenSSH and nginx, two pieces of software already running on this server. One short command gives me a self-hosted tunnel and a URL to share. To try it, grab the complete helper script, which includes a few minor improvements. If you run NixOS, as any person of taste would, have a look at my http-over-ssh.nix instead.

Update (2026-10) This post was widely discussed on Hacker News.

Update (2026-10) I have since switched to Caddy, which does not include a module to check the validity of a URL. Instead, Caddy queries a local HTTP service written in Go through the forward_auth directive. As a bonus, this lets me put the token in the domain name.


  1. Since the kernel allocates it from the local port range, its entropy is low. Moreover, on Linux, we lose one more bit because the kernel favors odd ports when it picks a random free port.
    $ sysctl -n net.ipv4.ip_local_port_range \
    >     awk ' print $1" "$2"   "log($2-$1+1)/log(2)" bits" '
    32768 60999   14.785 bits
    
  2. The module relies on MD5. Its security is weak but good enough for this use.
  3. We need an expiration date because a later session could reuse the port, and we have no way to detect this case.
  4. The username could use a comma directly instead of a double dash. But some applications do not recognize the URL correctly, making it harder to share.
  5. This configuration exposes any TCP port listening on 127.0.0.1 or 0.0.0.0 to anyone with the secret, bypassing most firewall rules. You could strengthen it by limiting the server_name regex to the ephemeral port range.
  6. One SSH session can contain several tunnels, and the client can add or remove them at any time. This is unlike tun device forwarding (ssh -w), which gets its own SSH_TUNNEL environment variable.
  7. Since OpenSSH 9.8, sshd-session is the name of the helper handling the session. With older versions, look for sshd instead.
  8. We need sudo because the sshd-session process dropped its privileges. The kernel then marks it as not dumpable, and its /proc/PID/fd directory belongs to root. Without access to this directory, ss cannot find which process owns a socket.

2 October 2026

Ben Hutchings: FOSS activity in September 2026

30 September 2026

Dirk Eddelbuettel: myman 0.1.0 on CRAN: New (fabulous !!) Package

Thrilled to share that our new package myman reached CRAN a few days ago. The package offers sixteen hundred ninety four My man posts by Kevin Kruse made on bsky during the summer of 2026. Each wave picked at one particular public persona. This package wrapse these up in the style of packages like fortunes or gaussfacts. A sample usage illustration shows how to extract by pattern:
> library(myman)
> myman("maitre")
My man looks like he's inquiring with the maitre'd about the house curly fries.
     -- about Howard Lutnick on 2026-08-28

My man looks like a maitre'd who deeply doubts you have a reservation.
     -- about Scott Bessent on 2026-08-31

My man looks like he's asked the maitre'd to remove a party of four he finds visually
unpleasant.
     -- about Scott Bessent on 2026-08-31

My man looks like the maitre'd at a very exclusive restaurant called The Berghof.
     -- about JD Vance on 2026-09-13

> 
One can also subset by target , or simple sample randomly (which is the default). As CRAN review for new package takes a little longer these days, the GitHub repo was updated once more with one (eighth !!) wave of posts since the submission was made. CRAN version 0.1.0 corresponds to the stock of messages from waves one to seven. We will update the CRAN version shortly but if you would like more posts right now consider installing from the repo. We include the full NEWS file since the package was started, this also includes an entry for the eights wave we will bring to CRAN soon.

Changes in version 0.1.0 (2026-09-27)
  • Initial CRAN version (minus the 0.0.8 changes which were made while CRAN reviewed the package)
  • Add an aspell dictionary to aid DESCRIPTION text

Changes in version 0.0.8 (2026-09-18)
  • Data set now comprises 1694 posts aiming at eight different 'men'
  • The number of 'sample()' object returned can not be set with 'posts'

Changes in version 0.0.7 (2026-09-14)
  • Data set now comprises 1494 posts aiming at seven different 'men'

Changes in version 0.0.6 (2026-09-07)
  • Data set now comprises 1394 posts aiming at six different 'men'

Changes in version 0.0.5 (2026-09-01)
  • Data set now comprises 1194 posts aiming at five different 'men'
  • The myman() function can now now subset by target permitting more focussed randlom sampling

Changes in version 0.0.4 (2026-08-28)
  • Data set now comprises 1040 posts aiming at four different 'men'

Changes in version 0.0.3 (2026-08-19)
  • Data set now comprises 916 posts aiming at three different 'men'
  • Csv file, processing and display extended to three columns also showing post creating date (in UTC) and 'man'

Changes in version 0.0.2 (2026-07-30)
  • Updated with full week of posts leading to a corpus of 698 posts
  • Added support for simple regular-expression lookup ability

Changes in version 0.0.1 (2026-07-19)
  • Initial release

This post by Dirk Eddelbuettel originated on his Thinking inside the box blog. If you like this or other open-source work I do, you can sponsor me at GitHub.

28 September 2026

Otto Kek l inen: Using multiple git remotes for true distributed version control

Featured image of post Using multiple git remotes for true distributed version controlOne of the primary design principles for Linus Torvalds when creating Git is that it should be a distributed system, capable of working with multiple remotes. However, most people seem to use Git with just one remote, typically having GitHub or GitLab as the only origin. Version control systems before Git relied on a centralized model. For example in Subversion or CVS you could only sync with one single remote server, which was considered the primary host of the source code. Git however is not just a VCS, but a DVCS, for distributed version control system. If you currently use Git with just one single remote as if it was a centralized version control system, now is the time to change that and learn how to add multiple remotes, and configure more flexible git pull and git push rules. The first concept to grasp is that Git can have multiple remotes. For example, after running a basic clone command such as git clone https://github.com/ottok/debcraft.git you would end up with a single remote origin pointing to GitHub:
$ git remote --verbose
origin https://github.com/ottok/debcraft.git (fetch)
origin https://github.com/ottok/debcraft.git (push)
You can however configure multiple remotes with the command git remote:
$ git remote rename origin github
$ git remote add gitlab https://gitlab.com/ottok/debcraft.git
$ git remote --verbose
github https://github.com/ottok/debcraft.git (fetch)
github https://github.com/ottok/debcraft.git (push)
gitlab https://gitlab.com/ottok/debcraft.git (fetch)
gitlab https://gitlab.com/ottok/debcraft.git (push)
You can push and pull from these individually, or from all at once:
$ git pull --all
Fetching github
Fetching gitlab
Already up to date.
When you review the git history, note the labels gitlab/main and github/main which tell which commit the branch main points to on various remotes. In this case they are all in sync and point to the same 5d1815c:
$ git log --oneline
5d1815c (HEAD -> main, gitlab/main, github/main) Bump Debhelper version from 13 to 14
ca518a7 Temporarily disable automatic copyright year bumping due to frequent bugs
d6e201e Exclude .pm from codespell to decrease false positives (Closes: #1140488)
708ee35 Exclude debian/copyright from codespell due to frequent false positives
When pushing, you can choose what remote to push to. For example, if I am working on branch dev and I only want to push it to GitLab to trigger a CI run there, I can run git push gitlab dev. You can also configure a default remote by running once git push --set-upstream gitlab dev and thereafter simply run git push and it will automatically push the branch dev only to that remote. A related setting is remote.pushDefault, which tells git which remote to push to when a branch does not define one of its own, and it applies to every branch that lacks a [branch] section in .git/config. Setting it once is what lets a repository have a per-branch pull remote, like the debcraft example below, and still have a single, predictable git push target. To see which remote git will use for each of your branches, run git branch -vv, and to refresh the remote-tracking branches of all remotes at once, run git fetch --all --prune. If you want to have multiple remotes, but automatically push and pull to all of them at once, you configure one single remote to have multiple URLs with git remote set-url --add. Since git prints one line per push URL, git remote -v then shows the same remote several times, once for each URL it pushes to. As an illustration, in my actual local Debcraft development project I have all these configured:
$ git remote -v
github-pull-requests git@github.com:ottok/debcraft.git (fetch)
github-pull-requests git@github.com:ottok/debcraft.git (push)
gitlab-merge-requests git@gitlab.com:ottok/debcraft.git (fetch)
gitlab-merge-requests git@gitlab.com:ottok/debcraft.git (push)
origin git@salsa.debian.org:debian/debcraft.git (fetch)
origin git@salsa.debian.org:debian/debcraft.git (push)
origin git@gitlab.com:ottok/debcraft.git (push)
origin git@github.com:ottok/debcraft.git (push)
otto git@salsa.debian.org:otto/debcraft.git (fetch)
otto git@salsa.debian.org:otto/debcraft.git (push)
otto git@gitlab.com:ottok/debcraft.git (push)
otto git@github.com:ottok/debcraft.git (push)
otto git@git.sr.ht:~ottok/debcraft (push)
otto ssh://git@codeberg.org/ottok/Debcraft.git (push)
salsa-merge-requests git@salsa.debian.org:debian/debcraft.git (fetch)
salsa-merge-requests git@salsa.debian.org:debian/debcraft.git (push)
The settings can also be viewed directly in the config file:
$ cat .git/config
...
[remote "origin"]
url = git@salsa.debian.org:debian/debcraft.git
fetch = +refs/heads/*:refs/remotes/origin/*
pushurl = git@salsa.debian.org:debian/debcraft.git
pushurl = git@gitlab.com:ottok/debcraft.git
pushurl = git@github.com:ottok/debcraft.git
[remote "otto"]
url = git@salsa.debian.org:otto/debcraft.git
fetch = +refs/heads/*:refs/remotes/otto/*
pushurl = git@salsa.debian.org:otto/debcraft.git
pushurl = git@gitlab.com:ottok/debcraft.git
pushurl = git@github.com:ottok/debcraft.git
pushurl = git@git.sr.ht:~ottok/debcraft
pushurl = ssh://git@codeberg.org/ottok/Debcraft.git
...
[branch "main"]
remote = origin
merge = refs/heads/main
[branch "dev"]
remote = otto
merge = refs/heads/dev
...
On branch main: On branch dev: The command output will have the same message three times, once for each remote (assuming they were all already up-to-date):
$ git push
Everything up-to-date

Use cases for distributed version control The most obvious use case for any distributed system is improved availability. In this example, the salsa.debian.org is often overloaded/unavailable, so pushing to GitLab and GitHub as well allows collaborators to use them to fetch git commits if the primary code hosting site is unresponsive. Once it comes back online again, the next git push/pull will automatically bring it up to the same content as what backup hosts had. The second main benefit is that having the code live on multiple code forges allows collaborators to use their own favorite host. Debcraft itself is a great example of this, as collaborators who don t have a Salsa account can - and have - submitted Merge Requests on GitLab.com and Pull Requests on GitHub.com. A third use case is code hosting migrations. If you for example want to gradually phase out GitHub.com and replace it with something else, you could configure git to pull from the old location and push to both, ensuring that other collaborators can start using the new code hosting location without disruptions to those who have not yet updated their remotes or done a fresh git clone from the new location.

Automating setting up a project on multiple code forges While I don t push all projects I work on to all Salsa/GitLab/GitHub, I do set up multiple remotes for enough git projects that I have this script to automate configuring a git repository that is cloned from Salsa to also push to GitLab and GitHub. It accepts the repository whether it was cloned over SSH or HTTPS, and it adds the push URLs and then pushes the current branch, all branches, and tags for you:
#!/bin/bash
# Add GitLab and GitHub push URLs to an existing git remote, so that a plain
# "git push" writes the same commits to all three code forges.
#
# Usage: ./git-multipush-salsa.sh
#
# Environment:
# SALSA_REMOTE remote to turn into a mirror, default origin
# SALSA_USER your Salsa user, only used to detect that the source
# remote is somebody else's project
# GITLAB_USER your GitLab user, default ottok
# GITHUB_USER your GitHub user, default ottok
# PROTOCOL ssh (default) or https, for the push URLs
set -euo pipefail
SCRIPT=$(basename "$0")
SALSA_REMOTE=$ SALSA_REMOTE:-origin 
SALSA_USER=$ SALSA_USER:-otto 
GITLAB_USER=$ GITLAB_USER:-ottok 
GITHUB_USER=$ GITHUB_USER:-ottok 
PROTOCOL=$ PROTOCOL:-ssh 
die()   echo "$SCRIPT: $*" >&2; exit 1;  
# A failing command leaves the push URLs half configured behind, so say how
# to get back to where we started
fail()
 
echo "$SCRIPT: '$*' failed, the push URLs may already have been added" >&2
echo " git config --unset-all remote.$ SALSA_REMOTE .pushurl" >&2
echo " git remote set-url --add --push $ SALSA_REMOTE  $ SALSA_URL " >&2
exit 1
 
git rev-parse --git-dir > /dev/null 2>&1   die "not inside a git repository"
git remote   grep -qx "$SALSA_REMOTE"   die "no remote named '$SALSA_REMOTE'"
# Example: git@salsa.debian.org:otto/salsa-ci-pipeline.git
SALSA_URL=$(git remote get-url "$SALSA_REMOTE")
# The source remote may use any of the URL forms salsa.debian.org accepts,
# for example git@salsa.debian.org:otto/salsa-ci-pipeline.git or
# https://salsa.debian.org/otto/salsa-ci-pipeline.git
case "$SALSA_URL" in
git@salsa.debian.org:*) SALSA_PATH=$ SALSA_URL#git@salsa.debian.org:  ;;
ssh://git@salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#ssh://git@salsa.debian.org/  ;;
https://salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#https://salsa.debian.org/  ;;
http://salsa.debian.org/*) SALSA_PATH=$ SALSA_URL#http://salsa.debian.org/  ;;
*) die "unexpected source URL '$SALSA_URL', expected a salsa.debian.org URL" ;;
esac
SALSA_PATH=$ SALSA_PATH%/ 
SALSA_PATH=$ SALSA_PATH%.git 
SOURCE_USER=$ SALSA_PATH%%/* 
PROJECT=$ SALSA_PATH##*/ 
# Write the push URLs in one and the same protocol, no matter how the
# repository happens to have been cloned
if [ "$PROTOCOL" = "https" ]
then
SALSA_URL="https://salsa.debian.org/$ SALSA_PATH .git"
GITLAB_URL="https://gitlab.com/$ GITLAB_USER /$ PROJECT .git"
GITHUB_URL="https://github.com/$ GITHUB_USER /$ PROJECT .git"
else
SALSA_URL="git@salsa.debian.org:$ SALSA_PATH .git"
GITLAB_URL="git@gitlab.com:$ GITLAB_USER /$ PROJECT .git"
GITHUB_URL="git@github.com:$ GITHUB_USER /$ PROJECT .git"
fi
# Mirroring somebody else's project is fine, but it is usually not what you
# want: you most likely want to mirror your own fork instead
if [ "$SOURCE_USER" != "$SALSA_USER" ]
then
echo "Note: $SALSA_REMOTE points to $SOURCE_USER's project, not your own."
echo "To mirror your own fork, run this with SALSA_REMOTE set to its name."
echo
fi
# Bail out instead of adding the same push URLs twice
EXISTING=$(git remote get-url --push --all "$SALSA_REMOTE")
if [ "$(printf '%s\n' "$EXISTING"   wc -l)" -gt 1 ]
then
die "remote '$SALSA_REMOTE' already has multiple push URLs:
$EXISTING"
fi
echo "Mirroring $SALSA_URL to $GITLAB_URL and $GITHUB_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$SALSA_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$GITLAB_URL"
git remote set-url --add --push "$SALSA_REMOTE" "$GITHUB_URL"
# Push the branch you have checked out first, and never with --force: the
# first branch a GitLab or GitHub project receives becomes its default branch,
# the one you then protect
DEFAULT_BRANCH=$(git symbolic-ref --short HEAD)   die "not on a branch, check out a branch first"
git push -u "$SALSA_REMOTE" "$DEFAULT_BRANCH"
git push "$SALSA_REMOTE" --all
git push "$SALSA_REMOTE" --tags
# The push above creates the GitLab and GitHub projects, but GitLab projects
# are private by default, so make the new mirror public with glab if installed.
if command -v glab > /dev/null
then
echo "Make the GitLab project public and describe it as a mirror:"
glab api -X PUT "projects/$ GITLAB_USER %2F$ PROJECT " \
-f visibility=public \
-f description="Mirror of $ SALSA_URL " \
-f notification_email=disabled
else
echo "Install glab to do the same automatically, or visit"
echo "https://gitlab.com/$ GITLAB_USER /$ PROJECT /edit to make the project public"
fi
echo "To undo, drop all push URLs and add back only the original one:"
echo " git config --unset-all remote.$ SALSA_REMOTE .pushurl"
echo " git remote set-url --add --push $ SALSA_REMOTE  $ SALSA_URL "
If you prefer not to install glab, the last part simply reduces to visiting the GitLab project settings once and ticking the project public, and it is also worth setting a description like Mirror of https://salsa.debian.org/debian/debcraft and disabling notification email there, as nobody wants a mirror sending out a flood of emails every time you push. There are a few caveats worth knowing about before mirroring everything everywhere. Every push to a remote with multiple push URLs writes to all of them, so a project with continuous integration configured on three forges will run its CI three times and cost you roughly three times as much. If one of the push URLs fails, say because the host is momentarily unreachable, git prints the error and stops there, leaving the remotes listed after the failing one without the new commits. Simply re-run the push once the host is reachable again; the remotes that did get the commits will just respond with Everything up-to-date. And you should never force-push to only one of the remotes, as that leaves the mirrors permanently out of sync with your local repository.

Avoid pulling too much Related to multiple remotes, you should also be aware that git allows one to configure which branches to pull. By default a git clone will track all branches from the remote and pull everything, which in a typical open source project will bring in a lot of temporary development branches in vain. Thus it is better to run git clone with the --single-branch and --branch parameters to fetch only the branch that matters, which in most cases is the main branch. That can be accomplished with:
git clone --single-branch --branch main https://github.com/ottok/debcraft.git
If a repository was already cloned, it can be configured to track only one branch with:
git config remote.upstream.fetch "+refs/heads/main:refs/remotes/upstream/main"
git fetch upstream
git config --get-all remote.upstream.fetch
+refs/heads/main:refs/remotes/upstream/main
If you later need to track more branches, you can configure them with commands such as:
git config --add remote.upstream.fetch "+refs/heads/3.2.y:refs/remotes/upstream/3.2.y"
git fetch upstream
git checkout 3.2.y
For additional details about any of the tips in this post I recommend reading the git man pages.

Now go and spread your code around Distributing your code over multiple code forges costs you almost nothing in configuration, and in return you get availability, a choice of host for your collaborators, and freedom to migrate without a big bang. Add the push URLs to the remotes you already have, push once, and you are done. The rest of the git fundamentals are covered in my other posts. If your commits are not yet polished, start with what makes a good git commit message and git commit messages by example. If you work on Debian packaging, Git-based collaboration in Debian explains why the Salsa merge request workflow is built the way it is, and Salsa merge request best practices covers the review process itself.

Maytham Alsudany: Briefly looking at DNS and nameservers under the hood

I've always known that the browser uses the Domain Name Resolution (DNS) system to convert domain names like aezign.com.au into raw IP addresses, but have never actually understood how it works, outside of making sure my network config uses 1.1.1.1 or 8.8.8.8 instead of the crappy one the ISP provides. In this article, I set out to understand what nameservers do, and how they help anything that uses the internet find the right records.

DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.

Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.

RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
  • A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
  • AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
  • CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
  • MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
  • TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
  • NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
$ dig MX aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> MX aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 28213
;; flags: qr rd ra; QUERY: 1, ANSWER: 1, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      MX
;; ANSWER SECTION:
aezign.com.au.          300     IN      MX      10 mail.aezign.au.
;; Query time: 104 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:04:58 AWST 2026
;; MSG SIZE  rcvd: 70
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
$ dig MX gmail.com
; <<>> DiG 9.20.29-1-Debian <<>> MX gmail.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16538
;; flags: qr rd ra; QUERY: 1, ANSWER: 5, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;gmail.com.                     IN      MX
;; ANSWER SECTION:
gmail.com.              2497    IN      MX      40 alt4.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      20 alt2.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      5 gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      10 alt1.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      30 alt3.gmail-smtp-in.l.google.com.
;; Query time: 120 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:06:04 AWST 2026
;; MSG SIZE  rcvd: 161
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.

NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
$ dig NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> NS example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37717
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      NS
;; ANSWER SECTION:
example.com.            81837   IN      NS      hera.ns.cloudflare.com.
example.com.            81837   IN      NS      elliott.ns.cloudflare.com.
;; Query time: 140 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 23:27:19 AWST 2026
;; MSG SIZE  rcvd: 95
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.

Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.

Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811

Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828

Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359

Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99

Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses encapsulate this recursive resolution process behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.

Checking DNS recordsTo check a website's records, the first thing to do is to ensure the domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
$ dig NS aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> NS aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 44172
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      NS
;; ANSWER SECTION:
aezign.com.au.          86400   IN      NS      rosalie.ns.cloudflare.com.
aezign.com.au.          86400   IN      NS      zeus.ns.cloudflare.com.
;; Query time: 92 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Mon Sep 28 01:39:22 AWST 2026
;; MSG SIZE  rcvd: 100
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare.
Extract of Cloudflare's DNS record listing showing the MX record and TXT records for aezign.com.au. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.
We can check these using dig, and using the +short option to show only the content of the records.
$ dig MX aezign.com.au +short
10 mail.aezign.au.
$ dig TXT aezign.com.au +short
"google-site-verification=KFqTU5xH8fFf6OtszEL4oudfxple29Tm-TvxVtCWkAM"
"v=spf1 mx a:mail.aezign.au -all"
$ dig TXT _dmarc.aezign.com.au +short
"v=DMARC1;p=quarantine;sp=quarantine;adkim=r;aspf=r"
$ dig TXT aezign.com.au-2026._domainkey.aezign.com.au +short
"v=DKIM1; h=sha256; k=rsa; s=email; p=MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAzL04yXZgB72YkoxS+tLK//aWx65TS4UA3F0qJ7el68SEuD4ehmg+61Ta9iS31H6U074dnjyoPDeaiGBa7ToTNCtiIts4/ghD/8nrENROE6hQAwRmTK18ODDHrRDW73hWe6Dg4cK5vmXi82/wWRZU9SDKbme28IE9uCVir3lCkKYLs1" "j16gR1Sjqr6a2+3o+EeVXnLJ4wXmJMm7KCIdn7zv0t9Z1eYcw672PdpYPAMpGb8uUsgaDBsNSpTcupPkz4SWj6TrOB80CPHjWseVY8EOJeRsNKQ/8LFoQEBl4Rxtb3HAmu4UIxSZ4QMVOLnXz67e85mA5XjcNIsVMzaWaowwIDAQAB"
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers globally. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.

Maytham Alsudany: A Brief Explanation of DNS and Nameservers

The Domain Name System (DNS) is a fundamental piece of technology behind the modern internet. Thanks to its introduction in 1983, you're able to enter domain names like aezign.com.au instead of raw IP addresses in your browser's address bar and when sending emails. This article explains what it is, how it works, and how you can inspect your own website's DNS and ensure it is set up correctly.

DNS in a nutshellA well-used analogy is a phonebook; when you have someone's name and need to find their phone number, you look through the phonebook. Overall, DNS does the same thing: when you enter an address like example.com, your browser will contact a DNS server (the "phonebook") to determine its IP addresses. On Linux (or MacOS) systems, you can use dig on the command line to perform a DNS lookup and see what this looks like:
$ dig example.com
; <<>> DiG 9.20.29-1-Debian <<>> example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 42782
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            221     IN      A       104.20.23.154
example.com.            221     IN      A       172.66.147.243
;; Query time: 20 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 21:07:50 AWST 2026
;; MSG SIZE  rcvd: 72
Here, you can see the DNS server being used is 1.1.1.1 (Cloudflare's DNS server), and that it found the IPs 104.20.23.154 and 172.66.147.243 associated with the domain name example.com. Your browser will then contact these IP addresses directly to load the website you are trying to open.

Configuring DNS serversYou can configure DNS servers through your operating system's network settings, and for some applications such as Firefox, with the application itself. If you don't manually set a DNS server, your computer will use the ones provided by your modem. If those are not configured, the default defined by the modem manufacturer or your ISP will be used.The most well-used and reliable DNS servers you can use are Cloudflare's (1.1.1.1 and 1.0.0.1) and Google's (8.8.8.8 and 8.8.4.4). Having more than one DNS server means that if the first one in the list doesn't work or doesn't find the matching IPs for a domain name, it will move to the next one in the list, a backup DNS server.DNS servers must be configured as IP addresses. If your computer tried to use a DNS server at a domain name, then where would your computer find the IP address for that domain name? It wouldn't be able to, as this is the exact gap that DNS servers fulfill.

RecordsDNS is not used only to find IPs for a domain, but a whole host of other things. Collectively they are referred to as "records" (or "DNS records"). Each record is associated to a domain (e.g. example.com) or a subdomain (e.g. bar.example.com, foo.bar.example.com) Here are some of the most common and important types:
  • A - Map to an IPv4 address (e.g. 104.20.23.154).This is the fundamental function of DNS: to map from a domain name to a server's IP address. Multiple A records leads to load balancing, where browsers will randomly select one of the returned IP addresses such that traffic is evenly split between them.
  • AAAA - Map to an IPv6 address (e.g. 2606:4700:10::6814:179a).This serves the same purpose as A records but for IPv6. Multiple AAAA records results in the same load balancing behaviour. All modern websites should have both an A record for legacy compatibility, and an AAAA record to future-proof for the gradual shift towards IPv6 addresses.
  • CNAME - Alias to another domain name (e.g. example.com).DNS servers will recursively lookup records for the aliased domain name until they reach an IP address (in an A or AAAA record).
  • MX - Specify a Mail Exchange server (e.g. mail.example.com).This record tells email SMTP servers where to direct emails to. For instance, the MX record for aezign.com.au is mail.aezign.au; this directs SMTP servers like Gmail and Outlook to send emails to the mailserver running at mail.aezign.au. This also allows specifying a priority field, so that you can define multiple MX records (such as a main and a backup) and consumers will try to connect to the listed mailservers from lowest priority to highest.
  • TXT - Store arbitrary text dataThis is most commonly used for site verification (for instance, to link your website to Google Search Console) and for email security measures like DKIM, DMARC, and SPF.
  • NS - Specify the nameservers for a domain (e.g. zeus.ns.cloudflare.com).These authoritative nameservers are responsible for providing all the other record types when needed.
dig lets you query each of these. For instance, to list the MX records against aezign.com.au:
$ dig MX aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> MX aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 28213
;; flags: qr rd ra; QUERY: 1, ANSWER: 1, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      MX
;; ANSWER SECTION:
aezign.com.au.          300     IN      MX      10 mail.aezign.au.
;; Query time: 104 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:04:58 AWST 2026
;; MSG SIZE  rcvd: 70
Here you can see there is only one mailserver configured for aezign.com.au, which is mail.aezign.au, and it has a priority of 10.If you compare this against something like gmail.com:
$ dig MX gmail.com
; <<>> DiG 9.20.29-1-Debian <<>> MX gmail.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16538
;; flags: qr rd ra; QUERY: 1, ANSWER: 5, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;gmail.com.                     IN      MX
;; ANSWER SECTION:
gmail.com.              2497    IN      MX      40 alt4.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      20 alt2.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      5 gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      10 alt1.gmail-smtp-in.l.google.com.
gmail.com.              2497    IN      MX      30 alt3.gmail-smtp-in.l.google.com.
;; Query time: 120 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 22:06:04 AWST 2026
;; MSG SIZE  rcvd: 161
You can see that gmail.com has several mailservers configured as redundancies due to the Gmail's sheer scale. gmail-smtp-in.l.google.com has the highest priority of 5, so SMTP servers will attempt to contact that mailserver first, followed by alt1.gmail-smtp-in.l.google.com and so on.

NameserversNow there needs to be somewhere for DNS records against a domain name to be defined, right? This is where nameservers come in.Nameservers are DNS servers that answer queries about the domains they are authoritative for i.e. the domains they are in charge of. For example, the authoritative nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com, which means Cloudflare's nameservers are the source of truth when looking up DNS records for example.com. You can check this with dig:
$ dig NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> NS example.com
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37717
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      NS
;; ANSWER SECTION:
example.com.            81837   IN      NS      hera.ns.cloudflare.com.
example.com.            81837   IN      NS      elliott.ns.cloudflare.com.
;; Query time: 140 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Sun Sep 27 23:27:19 AWST 2026
;; MSG SIZE  rcvd: 95
Nameservers are configured with your domain name's registrar. The nameserver you set dictates where your remaining DNS records will live. For example.com, this means you would configure all your records on Cloudflare's dashboard, since they are responsible for the domain's DNS records.

Recursive resolutionThe DNS servers that our computers use follow a recursive resolution process behind-the-scenes to find the authoritative nameservers for a domain, followed by the records you are querying.

Finding the root nameserversDue to the recursive nature of the resolution process, there needs to be a starting point: the root (.) nameservers. The resolver uses a fixed list of root nameservers called root hints issued by IANA (named.root), to locate and contact the root nameservers. Resolvers will have this provided to them initially, and can dynamically update it themselves by querying one of the root nameservers for the root NS records to obtain a fresh list. For instance, we can query 198.41.0.4 (a.root-servers.net) to obtain a new list of root nameservers:
$ dig @198.41.0.4 NS .
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS .
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43677
;; flags: qr aa rd; QUERY: 1, ANSWER: 13, AUTHORITY: 0, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;.				IN	NS
;; ANSWER SECTION:
.			518400	IN	NS	l.root-servers.net.
.			518400	IN	NS	j.root-servers.net.
.			518400	IN	NS	f.root-servers.net.
.			518400	IN	NS	h.root-servers.net.
.			518400	IN	NS	d.root-servers.net.
.			518400	IN	NS	b.root-servers.net.
.			518400	IN	NS	k.root-servers.net.
.			518400	IN	NS	i.root-servers.net.
.			518400	IN	NS	m.root-servers.net.
.			518400	IN	NS	e.root-servers.net.
.			518400	IN	NS	g.root-servers.net.
.			518400	IN	NS	c.root-servers.net.
.			518400	IN	NS	a.root-servers.net.
;; ADDITIONAL SECTION:
l.root-servers.net.	518400	IN	A	199.7.83.42
l.root-servers.net.	518400	IN	AAAA	2001:500:9f::42
j.root-servers.net.	518400	IN	A	192.58.128.30
j.root-servers.net.	518400	IN	AAAA	2001:503:c27::2:30
f.root-servers.net.	518400	IN	A	192.5.5.241
f.root-servers.net.	518400	IN	AAAA	2001:500:2f::f
h.root-servers.net.	518400	IN	A	198.97.190.53
h.root-servers.net.	518400	IN	AAAA	2001:500:1::53
d.root-servers.net.	518400	IN	A	199.7.91.13
d.root-servers.net.	518400	IN	AAAA	2001:500:2d::d
b.root-servers.net.	518400	IN	A	170.247.170.2
b.root-servers.net.	518400	IN	AAAA	2801:1b8:10::b
k.root-servers.net.	518400	IN	A	193.0.14.129
k.root-servers.net.	518400	IN	AAAA	2001:7fd::1
i.root-servers.net.	518400	IN	A	192.36.148.17
i.root-servers.net.	518400	IN	AAAA	2001:7fe::53
m.root-servers.net.	518400	IN	A	202.12.27.33
m.root-servers.net.	518400	IN	AAAA	2001:dc3::35
e.root-servers.net.	518400	IN	A	192.203.230.10
e.root-servers.net.	518400	IN	AAAA	2001:500:a8::e
g.root-servers.net.	518400	IN	A	192.112.36.4
g.root-servers.net.	518400	IN	AAAA	2001:500:12::d0d
c.root-servers.net.	518400	IN	A	192.33.4.12
c.root-servers.net.	518400	IN	AAAA	2001:500:2::c
a.root-servers.net.	518400	IN	A	198.41.0.4
a.root-servers.net.	518400	IN	AAAA	2001:503:ba3e::2:30
;; Query time: 476 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:01:08 AWST 2026
;; MSG SIZE  rcvd: 811

Querying the root nameserversFor example.com, the first step is to query the root (.) nameservers to find the nameservers for the .com top-level domain (TLD). Using a.root-servers.net again:
$ dig @198.41.0.4 NS com
; <<>> DiG 9.20.29-1-Debian <<>> @198.41.0.4 NS com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 22528
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 13, ADDITIONAL: 27
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;com.				IN	NS
;; AUTHORITY SECTION:
com.			172800	IN	NS	l.gtld-servers.net.
com.			172800	IN	NS	j.gtld-servers.net.
com.			172800	IN	NS	h.gtld-servers.net.
com.			172800	IN	NS	d.gtld-servers.net.
com.			172800	IN	NS	b.gtld-servers.net.
com.			172800	IN	NS	f.gtld-servers.net.
com.			172800	IN	NS	k.gtld-servers.net.
com.			172800	IN	NS	m.gtld-servers.net.
com.			172800	IN	NS	i.gtld-servers.net.
com.			172800	IN	NS	g.gtld-servers.net.
com.			172800	IN	NS	a.gtld-servers.net.
com.			172800	IN	NS	c.gtld-servers.net.
com.			172800	IN	NS	e.gtld-servers.net.
;; ADDITIONAL SECTION:
l.gtld-servers.net.	172800	IN	A	192.41.162.30
l.gtld-servers.net.	172800	IN	AAAA	2001:500:d937::30
j.gtld-servers.net.	172800	IN	A	192.48.79.30
j.gtld-servers.net.	172800	IN	AAAA	2001:502:7094::30
h.gtld-servers.net.	172800	IN	A	192.54.112.30
h.gtld-servers.net.	172800	IN	AAAA	2001:502:8cc::30
d.gtld-servers.net.	172800	IN	A	192.31.80.30
d.gtld-servers.net.	172800	IN	AAAA	2001:500:856e::30
b.gtld-servers.net.	172800	IN	A	192.33.14.30
b.gtld-servers.net.	172800	IN	AAAA	2001:503:231d::2:30
f.gtld-servers.net.	172800	IN	A	192.35.51.30
f.gtld-servers.net.	172800	IN	AAAA	2001:503:d414::30
k.gtld-servers.net.	172800	IN	A	192.52.178.30
k.gtld-servers.net.	172800	IN	AAAA	2001:503:d2d::30
m.gtld-servers.net.	172800	IN	A	192.55.83.30
m.gtld-servers.net.	172800	IN	AAAA	2001:501:b1f9::30
i.gtld-servers.net.	172800	IN	A	192.43.172.30
i.gtld-servers.net.	172800	IN	AAAA	2001:503:39c1::30
g.gtld-servers.net.	172800	IN	A	192.42.93.30
g.gtld-servers.net.	172800	IN	AAAA	2001:503:eea3::30
a.gtld-servers.net.	172800	IN	A	192.5.6.30
a.gtld-servers.net.	172800	IN	AAAA	2001:503:a83e::2:30
c.gtld-servers.net.	172800	IN	A	192.26.92.30
c.gtld-servers.net.	172800	IN	AAAA	2001:503:83eb::30
e.gtld-servers.net.	172800	IN	A	192.12.94.30
e.gtld-servers.net.	172800	IN	AAAA	2001:502:1ca1::30
;; Query time: 772 msec
;; SERVER: 198.41.0.4#53(198.41.0.4) (UDP)
;; WHEN: Mon Sep 28 00:09:25 AWST 2026
;; MSG SIZE  rcvd: 828

Querying the TLD nameserversNow the resolver has .com nameservers and their IPs. We can use one of these, such as 192.5.6.30 (a.gtld-servers.net) to find the nameservers for example.com:
$ dig @192.5.6.30 NS example.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 37419
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 2, ADDITIONAL: 13
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;example.com.                   IN      NS
;; AUTHORITY SECTION:
example.com.            172800  IN      NS      hera.ns.cloudflare.com.
example.com.            172800  IN      NS      elliott.ns.cloudflare.com.
;; ADDITIONAL SECTION:
hera.ns.cloudflare.com. 172800  IN      A       108.162.192.162
hera.ns.cloudflare.com. 172800  IN      A       172.64.32.162
hera.ns.cloudflare.com. 172800  IN      A       173.245.58.162
hera.ns.cloudflare.com. 172800  IN      AAAA    2606:4700:50::adf5:3aa2
hera.ns.cloudflare.com. 172800  IN      AAAA    2803:f800:50::6ca2:c0a2
hera.ns.cloudflare.com. 172800  IN      AAAA    2a06:98c1:50::ac40:20a2
elliott.ns.cloudflare.com. 172800 IN    A       108.162.195.228
elliott.ns.cloudflare.com. 172800 IN    A       162.159.44.228
elliott.ns.cloudflare.com. 172800 IN    A       172.64.35.228
elliott.ns.cloudflare.com. 172800 IN    AAAA    2606:4700:58::a29f:2ce4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2803:f800:50::6ca2:c3e4
elliott.ns.cloudflare.com. 172800 IN    AAAA    2a06:98c1:50::ac40:23e4
;; Query time: 80 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:12:19 AWST 2026
;; MSG SIZE  rcvd: 359

Finding the domain's nameserverThe response tells the resolver that the nameservers for example.com are hera.ns.cloudflare.com and elliott.ns.cloudflare.com. Now since these Cloudflare nameservers are also .com domains and Cloudflare is so commonly used, the .com nameserver provides optional sibling glue records as defined in RFC 9471 to prevent further roundtrips and optimize the process.If we ignore the sibling glue records provided, the resolver would have to ask the .com nameservers for the nameservers for cloudflare.com:
$ dig @192.5.6.30 NS cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @192.5.6.30 NS cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 40307
;; flags: qr rd; QUERY: 1, ANSWER: 0, AUTHORITY: 5, ADDITIONAL: 21
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 4096
;; QUESTION SECTION:
;cloudflare.com.                        IN      NS
;; AUTHORITY SECTION:
cloudflare.com.         172800  IN      NS      ns3.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns5.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns4.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns6.cloudflare.com.
cloudflare.com.         172800  IN      NS      ns7.cloudflare.com.
;; ADDITIONAL SECTION:
ns3.cloudflare.com.     172800  IN      A       162.159.0.33
ns3.cloudflare.com.     172800  IN      A       162.159.7.226
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:21
ns3.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:7e2
ns5.cloudflare.com.     172800  IN      A       162.159.2.9
ns5.cloudflare.com.     172800  IN      A       162.159.9.55
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:209
ns5.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:937
ns4.cloudflare.com.     172800  IN      A       162.159.1.33
ns4.cloudflare.com.     172800  IN      A       162.159.8.55
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:121
ns4.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:837
ns6.cloudflare.com.     172800  IN      A       162.159.3.11
ns6.cloudflare.com.     172800  IN      A       162.159.5.6
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:30b
ns6.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:506
ns7.cloudflare.com.     172800  IN      A       162.159.4.8
ns7.cloudflare.com.     172800  IN      A       162.159.6.6
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:408
ns7.cloudflare.com.     172800  IN      AAAA    2400:cb00:2049:1::a29f:606
;; Query time: 163 msec
;; SERVER: 192.5.6.30#53(192.5.6.30) (UDP)
;; WHEN: Mon Sep 28 00:26:53 AWST 2026
;; MSG SIZE  rcvd: 573
Here, the .com nameserver provides in-domain glue records for cloudflare.com's nameservers. Without these, there would be a circular dependency, since the nameserver named is a subdomain of the domain being queried for. This is because nameservers are always defined by name, which means that in order to actually contact the nameserver, your computer needs to obtain its IP address with another DNS lookup.Next, we'd use one of these nameservers, say ns3.cloudflare.com, to obtain the IP for hera.ns.cloudflare.com:
$ dig @162.159.0.33 hera.ns.cloudflare.com
; <<>> DiG 9.20.29-1-Debian <<>> @162.159.0.33 hera.ns.cloudflare.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 16801
;; flags: qr aa rd; QUERY: 1, ANSWER: 3, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;hera.ns.cloudflare.com.                IN      A
;; ANSWER SECTION:
hera.ns.cloudflare.com. 86353   IN      A       108.162.192.162
hera.ns.cloudflare.com. 86353   IN      A       173.245.58.162
hera.ns.cloudflare.com. 86353   IN      A       172.64.32.162
;; Query time: 123 msec
;; SERVER: 162.159.0.33#53(162.159.0.33) (UDP)
;; WHEN: Mon Sep 28 01:11:37 AWST 2026
;; MSG SIZE  rcvd: 99

Querying the domain's authoritative nameserverNow we've reached the authoritative nameserver for example.com! The last thing to do is to fetch the A record for example.com to obtain its server's IP address:
$ dig @108.162.192.162 example.com
; <<>> DiG 9.20.29-1-Debian <<>> @108.162.192.162 example.com
; (1 server found)
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 43082
;; flags: qr aa rd; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; WARNING: recursion requested but not available
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;example.com.                   IN      A
;; ANSWER SECTION:
example.com.            300     IN      A       104.20.23.154
example.com.            300     IN      A       172.66.147.243
;; Query time: 123 msec
;; SERVER: 108.162.192.162#53(108.162.192.162) (UDP)
;; WHEN: Mon Sep 28 01:13:47 AWST 2026
;; MSG SIZE  rcvd: 72
At last, we've determined that the IP addresses of the servers behind example.com are 104.20.23.154 and 172.66.147.243. This matches our earlier lookup directly against your computer's configured DNS server.The DNS servers your computer uses employ this recursive resolution technique behind the scenes, so that your computer only needs to make one round trip, and the servers can use their much faster data center connections and caching to optimize the process and make the query as fast as possible.

Verify your DNS recordsTo check your website's records, the first thing you'll want to do is ensure your domain name is pointed at the correct nameserver. For instance, aezign.com.au is supposed to use Cloudflare, since that is where all the DNS records have been set up. We can verify this using dig, (or alternatively with online tools like dnschecker.org):
$ dig NS aezign.com.au
; <<>> DiG 9.20.29-1-Debian <<>> NS aezign.com.au
;; global options: +cmd
;; Got answer:
;; ->>HEADER<<- opcode: QUERY, status: NOERROR, id: 44172
;; flags: qr rd ra; QUERY: 1, ANSWER: 2, AUTHORITY: 0, ADDITIONAL: 1
;; OPT PSEUDOSECTION:
; EDNS: version: 0, flags:; udp: 1232
;; QUESTION SECTION:
;aezign.com.au.                 IN      NS
;; ANSWER SECTION:
aezign.com.au.          86400   IN      NS      rosalie.ns.cloudflare.com.
aezign.com.au.          86400   IN      NS      zeus.ns.cloudflare.com.
;; Query time: 92 msec
;; SERVER: 1.1.1.1#53(1.1.1.1) (UDP)
;; WHEN: Mon Sep 28 01:39:22 AWST 2026
;; MSG SIZE  rcvd: 100
If this is not set correctly, the DNS records you configure will not work, as resolvers will be fetching records from somewhere else. In most cases, you can update this in your domain registrar's settings. This is especially common for new domain names, which default to the registrar's nameservers; unless you plan to use their built-in DNS management, you'll need to point them to your chosen provider.Now we can check that the DNS records you've configured match those your DNS server returns. For aezign.com.au, these are the MX and TXT records configured on Cloudflare.
Extract of Cloudflare's DNS record listing showing the MX record and TXT records for aezign.com.au. The MX record and some TXT records configured for aezign.com.au on Cloudflare's dashboard.
We can check these using dig, and using the +short option to show only the content of the records.
$ dig MX aezign.com.au +short
10 mail.aezign.au.
$ dig TXT aezign.com.au +short
"google-site-verification=KFqTU5xH8fFf6OtszEL4oudfxple29Tm-TvxVtCWkAM"
"v=spf1 mx a:mail.aezign.au -all"
$ dig TXT _dmarc.aezign.com.au +short
"v=DMARC1;p=quarantine;sp=quarantine;adkim=r;aspf=r"
$ dig TXT aezign.com.au-2026._domainkey.aezign.com.au +short
"v=DKIM1; h=sha256; k=rsa; s=email; p=MIIBIjANBgkqhkiG9w0BAQEFAAOCAQ8AMIIBCgKCAQEAzL04yXZgB72YkoxS+tLK//aWx65TS4UA3F0qJ7el68SEuD4ehmg+61Ta9iS31H6U074dnjyoPDeaiGBa7ToTNCtiIts4/ghD/8nrENROE6hQAwRmTK18ODDHrRDW73hWe6Dg4cK5vmXi82/wWRZU9SDKbme28IE9uCVir3lCkKYLs1" "j16gR1Sjqr6a2+3o+EeVXnLJ4wXmJMm7KCIdn7zv0t9Z1eYcw672PdpYPAMpGb8uUsgaDBsNSpTcupPkz4SWj6TrOB80CPHjWseVY8EOJeRsNKQ/8LFoQEBl4Rxtb3HAmu4UIxSZ4QMVOLnXz67e85mA5XjcNIsVMzaWaowwIDAQAB"
As we can see, this matches, which means that the nameservers for aezign.com.au are correct and the DNS records are what we intend them to be.Note that if you've recently changed the nameserver or DNS records for your domain, it can take anywhere between 10 seconds and 24 hours for the changes to take effect and propagate across the different DNS servers worldwide. Tools like dnschecker.org can check your records on different DNS servers worldwide to see if they're reflecting your changes. The reason for this is caching: DNS servers like 1.1.1.1 will cache results so it doesn't have to do the full resolution process every time, and uses the Time-To-Live (TTL) you configure in your DNS records as a guideline for caching duration.

27 September 2026

Aquila Macedo Costa: Testing library transitions before they reach unstable

A library transition can affect many packages in Debian. I added a way for Salsa CI to rebuild the ones that depend on the changing library, so maintainers can test the transition before it reaches unstable. The need for this became clear during a proposed Poppler transition. Poppler is a library for rendering PDFs. The reverse-dependency job I had added to Salsa CI queued 100 of 115 candidate rebuilds, even though only about 21 were relevant. The problem was documented in issue #571. Before this change, ratt used every binary package produced by Poppler to decide what to rebuild. That also picked up packages unrelated to the library transition. The tracker listed the old and new library package names, so I used them to focus the selection. Poppler transition tracker showing its Affected, Good, and Bad expressions The Poppler transition tracker identifies the old and new runtime library package names. I added -transition_affected to ratt to implement this selection. The option performs the scan against the selected archive indexes and injects locally built .deb files into each source rebuild. It expects a regex of dependency package names, not a complete Ben expression, so the tracker s Affected expression must be adapted first. I then integrated the mode into Salsa CI. Maintainers can enable transition-aware rebuilds by setting SALSA_CI_BUILD_REVERSE_DEPENDENCIES_TRANSITION_AFFECTED_REGEX. If the variable is unset, the pipeline keeps the existing selection. Salsa CI pipeline showing selected Poppler rebuild jobs A Poppler test showing the selected rebuild jobs. Three jobs reached the CI timeout, they were not confirmed package regressions. I also changed ratt to cover packages targeting experimental. By default, it resolves and rebuilds reverse dependencies from unstable while still injecting the locally built .deb files. This lets a maintainer test a transition staged in experimental against packages currently in unstable. Together, these changes help maintainers focus CI on packages relevant to a library transition and review rebuild results before the new library reaches unstable.
Next.